


Stage Harbor release files 20001-20500
Browse filesThis view is limited to 50 files because it contains too many changes. See raw diff
- tasks/tasksmith-441eeab80047/environment/source/benchmark/__init__.py +0 -0
- tasks/tasksmith-441eeab80047/environment/source/benchmark/benchmark.py +326 -0
- tasks/tasksmith-441eeab80047/environment/source/benchmark/benchmarks_entrypoint.py +144 -0
- tasks/tasksmith-441eeab80047/environment/source/benchmark/config/generation.yaml +57 -0
- tasks/tasksmith-441eeab80047/environment/source/benchmark/default.yml +10 -0
- tasks/tasksmith-441eeab80047/environment/source/benchmark/grafana_dashboard.json +2375 -0
- tasks/tasksmith-441eeab80047/environment/source/benchmark/grafana_datasource.yaml +17 -0
- tasks/tasksmith-441eeab80047/environment/source/benchmark/init_db.sql +33 -0
- tasks/tasksmith-441eeab80047/environment/source/benchmark/llama.py +342 -0
- tasks/tasksmith-441eeab80047/environment/source/benchmark/optimum_benchmark_wrapper.py +16 -0
- tasks/tasksmith-441eeab80047/environment/source/benchmark/requirements.txt +5 -0
- tasks/tasksmith-441eeab80047/environment/source/conftest.py +135 -0
- tasks/tasksmith-441eeab80047/environment/source/docker/README.md +9 -0
- tasks/tasksmith-441eeab80047/environment/source/docker/consistency.dockerfile +16 -0
- tasks/tasksmith-441eeab80047/environment/source/docker/custom-tokenizers.dockerfile +26 -0
- tasks/tasksmith-441eeab80047/environment/source/docker/examples-tf.dockerfile +12 -0
- tasks/tasksmith-441eeab80047/environment/source/docker/examples-torch.dockerfile +11 -0
- tasks/tasksmith-441eeab80047/environment/source/docker/exotic-models.dockerfile +17 -0
- tasks/tasksmith-441eeab80047/environment/source/docker/jax-light.dockerfile +10 -0
- tasks/tasksmith-441eeab80047/environment/source/docker/pipeline-tf.dockerfile +10 -0
- tasks/tasksmith-441eeab80047/environment/source/docker/pipeline-torch.dockerfile +11 -0
- tasks/tasksmith-441eeab80047/environment/source/docker/quality.dockerfile +9 -0
- tasks/tasksmith-441eeab80047/environment/source/docker/tf-light.dockerfile +12 -0
- tasks/tasksmith-441eeab80047/environment/source/docker/torch-jax-light.dockerfile +16 -0
- tasks/tasksmith-441eeab80047/environment/source/docker/torch-light.dockerfile +11 -0
- tasks/tasksmith-441eeab80047/environment/source/docker/torch-tf-light.dockerfile +19 -0
- tasks/tasksmith-441eeab80047/environment/source/docker/transformers-all-latest-gpu/Dockerfile +73 -0
- tasks/tasksmith-441eeab80047/environment/source/docker/transformers-doc-builder/Dockerfile +18 -0
- tasks/tasksmith-441eeab80047/environment/source/docker/transformers-gpu/Dockerfile +31 -0
- tasks/tasksmith-441eeab80047/environment/source/docker/transformers-past-gpu/Dockerfile +59 -0
- tasks/tasksmith-441eeab80047/environment/source/docker/transformers-pytorch-amd-gpu/Dockerfile +35 -0
- tasks/tasksmith-441eeab80047/environment/source/docker/transformers-pytorch-deepspeed-amd-gpu/Dockerfile +50 -0
- tasks/tasksmith-441eeab80047/environment/source/docker/transformers-pytorch-deepspeed-latest-gpu/Dockerfile +53 -0
- tasks/tasksmith-441eeab80047/environment/source/docker/transformers-pytorch-deepspeed-nightly-gpu/Dockerfile +64 -0
- tasks/tasksmith-441eeab80047/environment/source/docker/transformers-pytorch-gpu/Dockerfile +33 -0
- tasks/tasksmith-441eeab80047/environment/source/docker/transformers-pytorch-tpu/Dockerfile +65 -0
- tasks/tasksmith-441eeab80047/environment/source/docker/transformers-pytorch-tpu/bert-base-cased.jsonnet +38 -0
- tasks/tasksmith-441eeab80047/environment/source/docker/transformers-pytorch-tpu/dataset.yaml +32 -0
- tasks/tasksmith-441eeab80047/environment/source/docker/transformers-pytorch-tpu/docker-entrypoint.sh +8 -0
- tasks/tasksmith-441eeab80047/environment/source/docker/transformers-quantization-latest-gpu/Dockerfile +87 -0
- tasks/tasksmith-441eeab80047/environment/source/docker/transformers-tensorflow-gpu/Dockerfile +25 -0
- tasks/tasksmith-441eeab80047/environment/source/docs/README.md +395 -0
- tasks/tasksmith-441eeab80047/environment/source/docs/TRANSLATING.md +70 -0
- tasks/tasksmith-441eeab80047/environment/source/docs/source/_config.py +14 -0
- tasks/tasksmith-441eeab80047/environment/source/docs/source/ar/_config.py +14 -0
- tasks/tasksmith-441eeab80047/environment/source/docs/source/ar/_toctree.yml +898 -0
- tasks/tasksmith-441eeab80047/environment/source/docs/source/ar/accelerate.md +120 -0
- tasks/tasksmith-441eeab80047/environment/source/docs/source/ar/agents.md +539 -0
- tasks/tasksmith-441eeab80047/environment/source/docs/source/ar/attention.md +25 -0
- tasks/tasksmith-441eeab80047/environment/source/docs/source/ar/autoclass_tutorial.md +167 -0
tasks/tasksmith-441eeab80047/environment/source/benchmark/__init__.py
ADDED
|
File without changes
|
tasks/tasksmith-441eeab80047/environment/source/benchmark/benchmark.py
ADDED
|
@@ -0,0 +1,326 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
# Copyright 2024 The HuggingFace Team. All rights reserved.
|
| 2 |
+
#
|
| 3 |
+
# Licensed under the Apache License, Version 2.0 (the "License");
|
| 4 |
+
# you may not use this file except in compliance with the License.
|
| 5 |
+
# You may obtain a copy of the License at
|
| 6 |
+
#
|
| 7 |
+
# http://www.apache.org/licenses/LICENSE-2.0
|
| 8 |
+
#
|
| 9 |
+
# Unless required by applicable law or agreed to in writing, software
|
| 10 |
+
# distributed under the License is distributed on an "AS IS" BASIS,
|
| 11 |
+
# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
|
| 12 |
+
# See the License for the specific language governing permissions and
|
| 13 |
+
# limitations under the License.
|
| 14 |
+
|
| 15 |
+
"""
|
| 16 |
+
Run benchmark using the `optimum-benchmark` library with some customization in `transformers`.
|
| 17 |
+
|
| 18 |
+
Assume we are under `transformers` root directory: (make sure the commits are valid commits)
|
| 19 |
+
```bash
|
| 20 |
+
python benchmark/benchmark.py --config-dir benchmark/config --config-name generation --commit=9b9c7f03da625b13643e99205c691fe046461724 --metrics=decode.latency.mean,per_token.latency.mean,per_token.throughput.value backend.model=google/gemma-2b benchmark.input_shapes.sequence_length=5,7 benchmark.input_shapes.batch_size=1,2 --multirun
|
| 21 |
+
```
|
| 22 |
+
"""
|
| 23 |
+
|
| 24 |
+
import argparse
|
| 25 |
+
import glob
|
| 26 |
+
import json
|
| 27 |
+
import os.path
|
| 28 |
+
import re
|
| 29 |
+
import tempfile
|
| 30 |
+
from contextlib import contextmanager
|
| 31 |
+
from pathlib import Path
|
| 32 |
+
|
| 33 |
+
from git import Repo
|
| 34 |
+
|
| 35 |
+
from huggingface_hub import HfApi
|
| 36 |
+
|
| 37 |
+
from optimum_benchmark import Benchmark
|
| 38 |
+
from optimum_benchmark_wrapper import main
|
| 39 |
+
|
| 40 |
+
|
| 41 |
+
PATH_TO_REPO = Path(__file__).parent.parent.resolve()
|
| 42 |
+
|
| 43 |
+
|
| 44 |
+
@contextmanager
|
| 45 |
+
def checkout_commit(repo: Repo, commit_id: str):
|
| 46 |
+
"""
|
| 47 |
+
Context manager that checks out a given commit when entered, but gets back to the reference it was at on exit.
|
| 48 |
+
Args:
|
| 49 |
+
repo (`git.Repo`): A git repository (for instance the Transformers repo).
|
| 50 |
+
commit_id (`str`): The commit reference to checkout inside the context manager.
|
| 51 |
+
"""
|
| 52 |
+
current_head = repo.head.commit if repo.head.is_detached else repo.head.ref
|
| 53 |
+
|
| 54 |
+
try:
|
| 55 |
+
repo.git.checkout(commit_id)
|
| 56 |
+
yield
|
| 57 |
+
|
| 58 |
+
finally:
|
| 59 |
+
repo.git.checkout(current_head)
|
| 60 |
+
|
| 61 |
+
|
| 62 |
+
def summarize(run_dir, metrics, expand_metrics=False):
|
| 63 |
+
"""Produce a summary for each optimum-benchmark launched job's output directory found in `run_dir`.
|
| 64 |
+
|
| 65 |
+
Each summary's format is as follows (for `expand_metrics=False`):
|
| 66 |
+
```
|
| 67 |
+
{
|
| 68 |
+
"model": "google/gemma-2b",
|
| 69 |
+
"commit": "3cd6ed22e4d49219f300f5055e71e3929aba20d7",
|
| 70 |
+
"config": "benchmark.input_shapes.batch_size=1,benchmark.input_shapes.sequence_length=5",
|
| 71 |
+
"metrics": {
|
| 72 |
+
"decode.latency.mean": 1.624666809082031,
|
| 73 |
+
"per_token.latency.mean": 0.012843788806628804,
|
| 74 |
+
"per_token.throughput.value": 77.85864553330948
|
| 75 |
+
}
|
| 76 |
+
}
|
| 77 |
+
```
|
| 78 |
+
"""
|
| 79 |
+
reports = glob.glob(os.path.join(run_dir, "**/benchmark_report.json"), recursive=True)
|
| 80 |
+
report_dirs = [str(Path(report).parent) for report in reports]
|
| 81 |
+
|
| 82 |
+
summaries = []
|
| 83 |
+
for report_dir in report_dirs:
|
| 84 |
+
commit = re.search(r"/commit=([^/]+)", report_dir).groups()[0]
|
| 85 |
+
|
| 86 |
+
if not os.path.isfile(os.path.join(report_dir, "benchmark.json")):
|
| 87 |
+
continue
|
| 88 |
+
benchmark = Benchmark.from_json(os.path.join(report_dir, "benchmark.json"))
|
| 89 |
+
report = benchmark.report
|
| 90 |
+
|
| 91 |
+
model = benchmark.config.backend["model"]
|
| 92 |
+
|
| 93 |
+
# Ths looks like `benchmark.input_shapes.batch_size=1,benchmark.input_shapes.sequence_length=5`.
|
| 94 |
+
# (we rely on the usage of hydra's `${hydra.job.override_dirname}`.)
|
| 95 |
+
benchmark_name = re.sub(f"backend.model={model},*", "", report_dir)
|
| 96 |
+
benchmark_name = str(Path(benchmark_name).parts[-1])
|
| 97 |
+
if benchmark_name.startswith("commit="):
|
| 98 |
+
benchmark_name = benchmark.config.name
|
| 99 |
+
|
| 100 |
+
metrics_values = {}
|
| 101 |
+
# post-processing of report: show a few selected/important metric
|
| 102 |
+
for metric in metrics:
|
| 103 |
+
keys = metric.split(".")
|
| 104 |
+
value = report.to_dict()
|
| 105 |
+
current = metrics_values
|
| 106 |
+
for key in keys:
|
| 107 |
+
# Avoid KeyError when a user's specified metric has typo.
|
| 108 |
+
# TODO: Give warnings.
|
| 109 |
+
if key not in value:
|
| 110 |
+
continue
|
| 111 |
+
value = value[key]
|
| 112 |
+
|
| 113 |
+
if expand_metrics:
|
| 114 |
+
if isinstance(value, dict):
|
| 115 |
+
if key not in current:
|
| 116 |
+
current[key] = {}
|
| 117 |
+
current = current[key]
|
| 118 |
+
else:
|
| 119 |
+
current[key] = value
|
| 120 |
+
|
| 121 |
+
if not expand_metrics:
|
| 122 |
+
metrics_values[metric] = value
|
| 123 |
+
|
| 124 |
+
# show some config information
|
| 125 |
+
print(f"model: {model}")
|
| 126 |
+
print(f"commit: {commit}")
|
| 127 |
+
print(f"config: {benchmark_name}")
|
| 128 |
+
if len(metrics_values) > 0:
|
| 129 |
+
print("metrics:")
|
| 130 |
+
if expand_metrics:
|
| 131 |
+
print(metrics_values)
|
| 132 |
+
else:
|
| 133 |
+
for metric, value in metrics_values.items():
|
| 134 |
+
print(f" - {metric}: {value}")
|
| 135 |
+
print("-" * 80)
|
| 136 |
+
|
| 137 |
+
summary = {
|
| 138 |
+
"model": model,
|
| 139 |
+
"commit": commit,
|
| 140 |
+
"config": benchmark_name,
|
| 141 |
+
"metrics": metrics_values,
|
| 142 |
+
}
|
| 143 |
+
summaries.append(summary)
|
| 144 |
+
|
| 145 |
+
with open(os.path.join(report_dir, "summary.json"), "w") as fp:
|
| 146 |
+
json.dump(summary, fp, indent=4)
|
| 147 |
+
|
| 148 |
+
return summaries
|
| 149 |
+
|
| 150 |
+
|
| 151 |
+
def combine_summaries(summaries):
|
| 152 |
+
"""Combine a list of summary obtained from the function `summarize`.
|
| 153 |
+
|
| 154 |
+
The combined summary's format is as follows:
|
| 155 |
+
```
|
| 156 |
+
"google/gemma-2b": {
|
| 157 |
+
"benchmark.input_shapes.batch_size=1,benchmark.input_shapes.sequence_length=5": {
|
| 158 |
+
"3cd6ed22e4d49219f300f5055e71e3929aba20d7": {
|
| 159 |
+
"metrics": {"decode.latency.mean": 1.624666809082031}
|
| 160 |
+
},
|
| 161 |
+
"c97ee28b117c0abe8e08891f402065e4df6d72aa": {
|
| 162 |
+
"metrics": {"decode.latency.mean": 1.6278163452148438}
|
| 163 |
+
}
|
| 164 |
+
},
|
| 165 |
+
"benchmark.input_shapes.batch_size=2,benchmark.input_shapes.sequence_length=5": {
|
| 166 |
+
"3cd6ed22e4d49219f300f5055e71e3929aba20d7": {
|
| 167 |
+
"metrics": {"decode.latency.mean": 1.6947791748046876}
|
| 168 |
+
},
|
| 169 |
+
"c97ee28b117c0abe8e08891f402065e4df6d72aa": {
|
| 170 |
+
"metrics": {
|
| 171 |
+
"decode.latency.mean": 1.6980519409179688}
|
| 172 |
+
}
|
| 173 |
+
}
|
| 174 |
+
}
|
| 175 |
+
```
|
| 176 |
+
"""
|
| 177 |
+
combined = {}
|
| 178 |
+
for summary in summaries:
|
| 179 |
+
model = summary["model"]
|
| 180 |
+
config = summary["config"]
|
| 181 |
+
commit = summary["commit"]
|
| 182 |
+
|
| 183 |
+
if model not in combined:
|
| 184 |
+
combined[model] = {}
|
| 185 |
+
|
| 186 |
+
if config not in combined[model]:
|
| 187 |
+
combined[model][config] = {}
|
| 188 |
+
|
| 189 |
+
if commit not in combined[model][config]:
|
| 190 |
+
combined[model][config][commit] = {"metrics": summary["metrics"]}
|
| 191 |
+
|
| 192 |
+
with open(os.path.join(exp_run_dir, "summary.json"), "w") as fp:
|
| 193 |
+
json.dump(combined, fp, indent=4)
|
| 194 |
+
|
| 195 |
+
print(json.dumps(combined, indent=4))
|
| 196 |
+
|
| 197 |
+
return combined
|
| 198 |
+
|
| 199 |
+
|
| 200 |
+
if __name__ == "__main__":
|
| 201 |
+
|
| 202 |
+
def list_str(values):
|
| 203 |
+
return values.split(",")
|
| 204 |
+
|
| 205 |
+
parser = argparse.ArgumentParser()
|
| 206 |
+
|
| 207 |
+
parser.add_argument("--config-dir", type=str, required=True, help="The path to the config directory.")
|
| 208 |
+
parser.add_argument("--config-name", type=str, required=True, help="The config name.")
|
| 209 |
+
|
| 210 |
+
# arguments specific to this wrapper for our own customization
|
| 211 |
+
parser.add_argument("--ensure_empty", type=bool, default=True, help="If to create a temporary directory.")
|
| 212 |
+
parser.add_argument(
|
| 213 |
+
"--commit",
|
| 214 |
+
type=list_str,
|
| 215 |
+
default="",
|
| 216 |
+
help="Comma-separated list of branch names and/or commit sha values on which the benchmark will run. If `diff` is specified, it will run on both the current head and the `main` branch.",
|
| 217 |
+
)
|
| 218 |
+
parser.add_argument("--metrics", type=str, help="The metrics to be included in the summary.")
|
| 219 |
+
|
| 220 |
+
parser.add_argument("--repo_id", type=str, default=None, help="The repository to which the file will be uploaded.")
|
| 221 |
+
parser.add_argument("--path_in_repo", type=str, default=None, help="Relative filepath in the repo.")
|
| 222 |
+
parser.add_argument("--token", type=str, default=None, help="A valid user access token (string).")
|
| 223 |
+
|
| 224 |
+
args, optimum_benchmark_args = parser.parse_known_args()
|
| 225 |
+
|
| 226 |
+
repo = Repo(PATH_TO_REPO)
|
| 227 |
+
|
| 228 |
+
metrics = [
|
| 229 |
+
"prefill.latency.mean",
|
| 230 |
+
"prefill.throughput.value",
|
| 231 |
+
"decode.latency.mean",
|
| 232 |
+
"decode.throughput.value",
|
| 233 |
+
"per_token.latency.mean",
|
| 234 |
+
"per_token.throughput.value",
|
| 235 |
+
]
|
| 236 |
+
if args.metrics is not None:
|
| 237 |
+
metrics = args.metrics.split(",")
|
| 238 |
+
|
| 239 |
+
# Get `backend.model` in a hacky way: We want to control the experiment flow manually.
|
| 240 |
+
models = [""]
|
| 241 |
+
for idx, arg in enumerate(optimum_benchmark_args):
|
| 242 |
+
if arg.startswith("backend.model="):
|
| 243 |
+
models = arg[len("backend.model=") :]
|
| 244 |
+
models = models.split(",")
|
| 245 |
+
break
|
| 246 |
+
optimum_benchmark_args = [arg for arg in optimum_benchmark_args if not arg.startswith("backend.model=")]
|
| 247 |
+
|
| 248 |
+
# Get the commit(s)
|
| 249 |
+
current_head = str(repo.head.commit) if repo.head.is_detached else str(repo.head.ref)
|
| 250 |
+
commits = [x for x in args.commit if x != ""]
|
| 251 |
+
if len(commits) == 0:
|
| 252 |
+
commits = [current_head]
|
| 253 |
+
elif len(commits) == 1 and commits[0] == "diff":
|
| 254 |
+
# compare to `main`
|
| 255 |
+
commits = ["main", current_head]
|
| 256 |
+
|
| 257 |
+
# Get the specified run directory
|
| 258 |
+
run_dir_arg_idx, run_dir = -1, None
|
| 259 |
+
sweep_dir_arg_idx, sweep_dir = -1, None
|
| 260 |
+
for idx, arg in enumerate(optimum_benchmark_args):
|
| 261 |
+
if arg.startswith("hydra.run.dir="):
|
| 262 |
+
run_dir = arg[len("hydra.run.dir=") :]
|
| 263 |
+
run_dir_arg_idx = idx
|
| 264 |
+
elif arg.startswith("hydra.sweep.dir="):
|
| 265 |
+
sweep_dir = arg[len("hydra.sweep.dir=") :]
|
| 266 |
+
sweep_dir_arg_idx = idx
|
| 267 |
+
exp_run_dir, arg_dix, arg_name = (
|
| 268 |
+
(sweep_dir, sweep_dir_arg_idx, "hydra.sweep.dir")
|
| 269 |
+
if "--multirun" in optimum_benchmark_args
|
| 270 |
+
else (run_dir, run_dir_arg_idx, "hydra.run.dir")
|
| 271 |
+
)
|
| 272 |
+
|
| 273 |
+
# TODO: not hardcoded
|
| 274 |
+
if exp_run_dir is None and args.ensure_empty:
|
| 275 |
+
exp_run_dir = "_benchmark"
|
| 276 |
+
|
| 277 |
+
if args.ensure_empty:
|
| 278 |
+
os.makedirs(exp_run_dir, exist_ok=True)
|
| 279 |
+
exp_run_dir = tempfile.mkdtemp(dir=exp_run_dir)
|
| 280 |
+
|
| 281 |
+
run_summaries = []
|
| 282 |
+
for commit in commits:
|
| 283 |
+
with checkout_commit(repo, commit):
|
| 284 |
+
commit = str(repo.head.commit)
|
| 285 |
+
|
| 286 |
+
commit_run_dir = exp_run_dir
|
| 287 |
+
if exp_run_dir is not None:
|
| 288 |
+
commit_run_dir = os.path.join(exp_run_dir, rf"commit\={commit}")
|
| 289 |
+
|
| 290 |
+
print(f"Run benchmark on commit: {commit}")
|
| 291 |
+
|
| 292 |
+
for model in models:
|
| 293 |
+
model_arg = [f"backend.model={model}"] if model != "" else []
|
| 294 |
+
dir_args = []
|
| 295 |
+
if commit_run_dir is not None:
|
| 296 |
+
if arg_dix > -1:
|
| 297 |
+
optimum_benchmark_args[arg_dix] = f"{arg_name}={commit_run_dir}"
|
| 298 |
+
else:
|
| 299 |
+
dir_args = [
|
| 300 |
+
f"hydra.sweep.dir={commit_run_dir}",
|
| 301 |
+
f"hydra.run.dir={commit_run_dir}/" + "${hydra.job.override_dirname}",
|
| 302 |
+
]
|
| 303 |
+
main(args.config_dir, args.config_name, model_arg + dir_args + optimum_benchmark_args)
|
| 304 |
+
|
| 305 |
+
if commit_run_dir is not None:
|
| 306 |
+
# Need to remove the `\` character
|
| 307 |
+
summaries = summarize(commit_run_dir.replace("\\", ""), metrics)
|
| 308 |
+
run_summaries.extend(summaries)
|
| 309 |
+
|
| 310 |
+
# aggregate the information across the commits
|
| 311 |
+
if exp_run_dir is not None:
|
| 312 |
+
with open(os.path.join(exp_run_dir, "summaries.json"), "w") as fp:
|
| 313 |
+
json.dump(run_summaries, fp, indent=4)
|
| 314 |
+
|
| 315 |
+
combined_summary = combine_summaries(run_summaries)
|
| 316 |
+
|
| 317 |
+
if args.repo_id is not None and args.path_in_repo is not None:
|
| 318 |
+
# Upload to Hub
|
| 319 |
+
api = HfApi()
|
| 320 |
+
api.upload_folder(
|
| 321 |
+
folder_path=exp_run_dir,
|
| 322 |
+
path_in_repo=args.path_in_repo,
|
| 323 |
+
repo_id=args.repo_id,
|
| 324 |
+
repo_type="dataset",
|
| 325 |
+
token=args.token,
|
| 326 |
+
)
|
tasks/tasksmith-441eeab80047/environment/source/benchmark/benchmarks_entrypoint.py
ADDED
|
@@ -0,0 +1,144 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
import argparse
|
| 2 |
+
import importlib.util
|
| 3 |
+
import logging
|
| 4 |
+
import os
|
| 5 |
+
from typing import Dict
|
| 6 |
+
import psycopg2
|
| 7 |
+
import sys
|
| 8 |
+
|
| 9 |
+
from psycopg2.extras import Json
|
| 10 |
+
from psycopg2.extensions import register_adapter
|
| 11 |
+
|
| 12 |
+
|
| 13 |
+
register_adapter(dict, Json)
|
| 14 |
+
|
| 15 |
+
|
| 16 |
+
class ImportModuleException(Exception):
|
| 17 |
+
pass
|
| 18 |
+
|
| 19 |
+
|
| 20 |
+
class MetricsRecorder:
|
| 21 |
+
def __init__(self, connection, logger: logging.Logger, branch: str, commit_id: str, commit_msg: str):
|
| 22 |
+
self.conn = connection
|
| 23 |
+
self.conn.autocommit = True
|
| 24 |
+
self.logger = logger
|
| 25 |
+
self.branch = branch
|
| 26 |
+
self.commit_id = commit_id
|
| 27 |
+
self.commit_msg = commit_msg
|
| 28 |
+
|
| 29 |
+
def initialise_benchmark(self, metadata: Dict[str, str]) -> int:
|
| 30 |
+
"""
|
| 31 |
+
Creates a new benchmark, returns the benchmark id
|
| 32 |
+
"""
|
| 33 |
+
# gpu_name: str, model_id: str
|
| 34 |
+
with self.conn.cursor() as cur:
|
| 35 |
+
cur.execute(
|
| 36 |
+
"INSERT INTO benchmarks (branch, commit_id, commit_message, metadata) VALUES (%s, %s, %s, %s) RETURNING benchmark_id",
|
| 37 |
+
(self.branch, self.commit_id, self.commit_msg, metadata),
|
| 38 |
+
)
|
| 39 |
+
benchmark_id = cur.fetchone()[0]
|
| 40 |
+
logger.debug(f"initialised benchmark #{benchmark_id}")
|
| 41 |
+
return benchmark_id
|
| 42 |
+
|
| 43 |
+
def collect_device_measurements(self, benchmark_id: int, cpu_util, mem_megabytes, gpu_util, gpu_mem_megabytes):
|
| 44 |
+
"""
|
| 45 |
+
Collect device metrics, such as CPU & GPU usage. These are "static", as in you cannot pass arbitrary arguments to the function.
|
| 46 |
+
"""
|
| 47 |
+
with self.conn.cursor() as cur:
|
| 48 |
+
cur.execute(
|
| 49 |
+
"INSERT INTO device_measurements (benchmark_id, cpu_util, mem_megabytes, gpu_util, gpu_mem_megabytes) VALUES (%s, %s, %s, %s, %s)",
|
| 50 |
+
(benchmark_id, cpu_util, mem_megabytes, gpu_util, gpu_mem_megabytes),
|
| 51 |
+
)
|
| 52 |
+
self.logger.debug(
|
| 53 |
+
f"inserted device measurements for benchmark #{benchmark_id} [CPU util: {cpu_util}, mem MBs: {mem_megabytes}, GPU util: {gpu_util}, GPU mem MBs: {gpu_mem_megabytes}]"
|
| 54 |
+
)
|
| 55 |
+
|
| 56 |
+
def collect_model_measurements(self, benchmark_id: int, measurements: Dict[str, float]):
|
| 57 |
+
with self.conn.cursor() as cur:
|
| 58 |
+
cur.execute(
|
| 59 |
+
"""
|
| 60 |
+
INSERT INTO model_measurements (
|
| 61 |
+
benchmark_id,
|
| 62 |
+
measurements
|
| 63 |
+
) VALUES (%s, %s)
|
| 64 |
+
""",
|
| 65 |
+
(
|
| 66 |
+
benchmark_id,
|
| 67 |
+
measurements,
|
| 68 |
+
),
|
| 69 |
+
)
|
| 70 |
+
self.logger.debug(f"inserted model measurements for benchmark #{benchmark_id}: {measurements}")
|
| 71 |
+
|
| 72 |
+
def close(self):
|
| 73 |
+
self.conn.close()
|
| 74 |
+
|
| 75 |
+
|
| 76 |
+
logger = logging.getLogger(__name__)
|
| 77 |
+
logger.setLevel(logging.INFO)
|
| 78 |
+
|
| 79 |
+
handler = logging.StreamHandler(sys.stdout)
|
| 80 |
+
handler.setLevel(logging.INFO)
|
| 81 |
+
formatter = logging.Formatter("[%(levelname)s - %(asctime)s] %(message)s")
|
| 82 |
+
handler.setFormatter(formatter)
|
| 83 |
+
logger.addHandler(handler)
|
| 84 |
+
|
| 85 |
+
|
| 86 |
+
def parse_arguments():
|
| 87 |
+
"""
|
| 88 |
+
Parse command line arguments for the benchmarking CLI.
|
| 89 |
+
"""
|
| 90 |
+
parser = argparse.ArgumentParser(description="CLI for benchmarking the huggingface/transformers.")
|
| 91 |
+
|
| 92 |
+
parser.add_argument(
|
| 93 |
+
"branch",
|
| 94 |
+
type=str,
|
| 95 |
+
help="The branch name on which the benchmarking is performed.",
|
| 96 |
+
)
|
| 97 |
+
|
| 98 |
+
parser.add_argument(
|
| 99 |
+
"commit_id",
|
| 100 |
+
type=str,
|
| 101 |
+
help="The commit hash on which the benchmarking is performed.",
|
| 102 |
+
)
|
| 103 |
+
|
| 104 |
+
parser.add_argument(
|
| 105 |
+
"commit_msg",
|
| 106 |
+
type=str,
|
| 107 |
+
help="The commit message associated with the commit, truncated to 70 characters.",
|
| 108 |
+
)
|
| 109 |
+
|
| 110 |
+
args = parser.parse_args()
|
| 111 |
+
|
| 112 |
+
return args.branch, args.commit_id, args.commit_msg
|
| 113 |
+
|
| 114 |
+
|
| 115 |
+
def import_from_path(module_name, file_path):
|
| 116 |
+
try:
|
| 117 |
+
spec = importlib.util.spec_from_file_location(module_name, file_path)
|
| 118 |
+
module = importlib.util.module_from_spec(spec)
|
| 119 |
+
sys.modules[module_name] = module
|
| 120 |
+
spec.loader.exec_module(module)
|
| 121 |
+
return module
|
| 122 |
+
except Exception as e:
|
| 123 |
+
raise ImportModuleException(f"failed to load python module: {e}")
|
| 124 |
+
|
| 125 |
+
|
| 126 |
+
if __name__ == "__main__":
|
| 127 |
+
benchmarks_folder_path = os.path.dirname(os.path.realpath(__file__))
|
| 128 |
+
|
| 129 |
+
branch, commit_id, commit_msg = parse_arguments()
|
| 130 |
+
|
| 131 |
+
for entry in os.scandir(benchmarks_folder_path):
|
| 132 |
+
try:
|
| 133 |
+
if not entry.name.endswith(".py"):
|
| 134 |
+
continue
|
| 135 |
+
if entry.path == __file__:
|
| 136 |
+
continue
|
| 137 |
+
logger.debug(f"loading: {entry.name}")
|
| 138 |
+
module = import_from_path(entry.name.split(".")[0], entry.path)
|
| 139 |
+
logger.info(f"running benchmarks in: {entry.name}")
|
| 140 |
+
module.run_benchmark(logger, branch, commit_id, commit_msg)
|
| 141 |
+
except ImportModuleException as e:
|
| 142 |
+
logger.error(e)
|
| 143 |
+
except Exception as e:
|
| 144 |
+
logger.error(f"error running benchmarks for {entry.name}: {e}")
|
tasks/tasksmith-441eeab80047/environment/source/benchmark/config/generation.yaml
ADDED
|
@@ -0,0 +1,57 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
defaults:
|
| 2 |
+
- benchmark # inheriting benchmark schema
|
| 3 |
+
- scenario: inference
|
| 4 |
+
- launcher: process
|
| 5 |
+
- backend: pytorch
|
| 6 |
+
- _self_ # for hydra 1.1 compatibility
|
| 7 |
+
|
| 8 |
+
name: pytorch_generate
|
| 9 |
+
|
| 10 |
+
launcher:
|
| 11 |
+
start_method: spawn
|
| 12 |
+
device_isolation: true
|
| 13 |
+
device_isolation_action: warn
|
| 14 |
+
|
| 15 |
+
backend:
|
| 16 |
+
device: cuda
|
| 17 |
+
device_ids: 0
|
| 18 |
+
no_weights: true
|
| 19 |
+
model: meta-llama/Llama-2-7b-hf
|
| 20 |
+
cache_implementation: static
|
| 21 |
+
torch_compile: true
|
| 22 |
+
torch_dtype: float16
|
| 23 |
+
torch_compile_config:
|
| 24 |
+
backend: inductor
|
| 25 |
+
mode: reduce-overhead
|
| 26 |
+
fullgraph: true
|
| 27 |
+
|
| 28 |
+
scenario:
|
| 29 |
+
input_shapes:
|
| 30 |
+
batch_size: 1
|
| 31 |
+
sequence_length: 7
|
| 32 |
+
generate_kwargs:
|
| 33 |
+
max_new_tokens: 128
|
| 34 |
+
min_new_tokens: 128
|
| 35 |
+
do_sample: false
|
| 36 |
+
memory: true
|
| 37 |
+
latency: true
|
| 38 |
+
iterations: 2
|
| 39 |
+
duration: 0
|
| 40 |
+
|
| 41 |
+
|
| 42 |
+
# hydra/cli specific settings
|
| 43 |
+
hydra:
|
| 44 |
+
run:
|
| 45 |
+
# where to store run results
|
| 46 |
+
dir: runs/${name}
|
| 47 |
+
job:
|
| 48 |
+
# change working directory to the run directory
|
| 49 |
+
chdir: true
|
| 50 |
+
env_set:
|
| 51 |
+
# set environment variable OVERRIDE_BENCHMARKS to 1
|
| 52 |
+
# to not skip benchmarks that have been run before
|
| 53 |
+
OVERRIDE_BENCHMARKS: 1
|
| 54 |
+
LOG_LEVEL: WARN
|
| 55 |
+
sweep:
|
| 56 |
+
dir: multirun
|
| 57 |
+
subdir: ${hydra.job.override_dirname}
|
tasks/tasksmith-441eeab80047/environment/source/benchmark/default.yml
ADDED
|
@@ -0,0 +1,10 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
apiVersion: 1
|
| 2 |
+
|
| 3 |
+
providers:
|
| 4 |
+
- name: 'Transformers Benchmarks'
|
| 5 |
+
orgId: 1
|
| 6 |
+
type: file
|
| 7 |
+
updateIntervalSeconds: 10
|
| 8 |
+
allowUiUpdates: true
|
| 9 |
+
options:
|
| 10 |
+
path: /etc/grafana/dashboards
|
tasks/tasksmith-441eeab80047/environment/source/benchmark/grafana_dashboard.json
ADDED
|
@@ -0,0 +1,2375 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
{
|
| 2 |
+
"annotations": {
|
| 3 |
+
"list": [
|
| 4 |
+
{
|
| 5 |
+
"builtIn": 1,
|
| 6 |
+
"datasource": {
|
| 7 |
+
"type": "grafana",
|
| 8 |
+
"uid": "-- Grafana --"
|
| 9 |
+
},
|
| 10 |
+
"enable": true,
|
| 11 |
+
"hide": true,
|
| 12 |
+
"iconColor": "rgba(0, 211, 255, 1)",
|
| 13 |
+
"name": "Annotations & Alerts",
|
| 14 |
+
"type": "dashboard"
|
| 15 |
+
}
|
| 16 |
+
]
|
| 17 |
+
},
|
| 18 |
+
"editable": true,
|
| 19 |
+
"fiscalYearStartMonth": 0,
|
| 20 |
+
"graphTooltip": 0,
|
| 21 |
+
"id": 1,
|
| 22 |
+
"links": [
|
| 23 |
+
{
|
| 24 |
+
"asDropdown": false,
|
| 25 |
+
"icon": "external link",
|
| 26 |
+
"includeVars": false,
|
| 27 |
+
"keepTime": false,
|
| 28 |
+
"tags": [],
|
| 29 |
+
"targetBlank": false,
|
| 30 |
+
"title": "Go to data",
|
| 31 |
+
"tooltip": "Go to data",
|
| 32 |
+
"type": "link",
|
| 33 |
+
"url": "http://transformers-benchmarks.hf.co/d/fdz33iyzln9c0a/transformers-benchmarks?orgId=1&from=${StartTime}&to=${EndTime}"
|
| 34 |
+
}
|
| 35 |
+
],
|
| 36 |
+
"liveNow": true,
|
| 37 |
+
"panels": [
|
| 38 |
+
{
|
| 39 |
+
"datasource": {
|
| 40 |
+
"default": true,
|
| 41 |
+
"type": "grafana-postgresql-datasource",
|
| 42 |
+
"uid": "be28nkzirtb0gd"
|
| 43 |
+
},
|
| 44 |
+
"fieldConfig": {
|
| 45 |
+
"defaults": {
|
| 46 |
+
"color": {
|
| 47 |
+
"mode": "thresholds"
|
| 48 |
+
},
|
| 49 |
+
"custom": {
|
| 50 |
+
"align": "left",
|
| 51 |
+
"cellOptions": {
|
| 52 |
+
"type": "auto"
|
| 53 |
+
},
|
| 54 |
+
"inspect": false
|
| 55 |
+
},
|
| 56 |
+
"mappings": [],
|
| 57 |
+
"thresholds": {
|
| 58 |
+
"mode": "absolute",
|
| 59 |
+
"steps": [
|
| 60 |
+
{
|
| 61 |
+
"color": "green",
|
| 62 |
+
"value": null
|
| 63 |
+
},
|
| 64 |
+
{
|
| 65 |
+
"color": "red",
|
| 66 |
+
"value": 80
|
| 67 |
+
}
|
| 68 |
+
]
|
| 69 |
+
}
|
| 70 |
+
},
|
| 71 |
+
"overrides": [
|
| 72 |
+
{
|
| 73 |
+
"matcher": {
|
| 74 |
+
"id": "byName",
|
| 75 |
+
"options": "gpu_name"
|
| 76 |
+
},
|
| 77 |
+
"properties": [
|
| 78 |
+
{
|
| 79 |
+
"id": "custom.width",
|
| 80 |
+
"value": 202
|
| 81 |
+
}
|
| 82 |
+
]
|
| 83 |
+
},
|
| 84 |
+
{
|
| 85 |
+
"matcher": {
|
| 86 |
+
"id": "byName",
|
| 87 |
+
"options": "left"
|
| 88 |
+
},
|
| 89 |
+
"properties": [
|
| 90 |
+
{
|
| 91 |
+
"id": "custom.width",
|
| 92 |
+
"value": 407
|
| 93 |
+
}
|
| 94 |
+
]
|
| 95 |
+
},
|
| 96 |
+
{
|
| 97 |
+
"matcher": {
|
| 98 |
+
"id": "byName",
|
| 99 |
+
"options": "commit_message"
|
| 100 |
+
},
|
| 101 |
+
"properties": [
|
| 102 |
+
{
|
| 103 |
+
"id": "custom.width",
|
| 104 |
+
"value": 524
|
| 105 |
+
}
|
| 106 |
+
]
|
| 107 |
+
},
|
| 108 |
+
{
|
| 109 |
+
"matcher": {
|
| 110 |
+
"id": "byName",
|
| 111 |
+
"options": "commit_id"
|
| 112 |
+
},
|
| 113 |
+
"properties": [
|
| 114 |
+
{
|
| 115 |
+
"id": "custom.width",
|
| 116 |
+
"value": 353
|
| 117 |
+
}
|
| 118 |
+
]
|
| 119 |
+
},
|
| 120 |
+
{
|
| 121 |
+
"matcher": {
|
| 122 |
+
"id": "byName",
|
| 123 |
+
"options": "model_id"
|
| 124 |
+
},
|
| 125 |
+
"properties": [
|
| 126 |
+
{
|
| 127 |
+
"id": "custom.width",
|
| 128 |
+
"value": 216
|
| 129 |
+
}
|
| 130 |
+
]
|
| 131 |
+
}
|
| 132 |
+
]
|
| 133 |
+
},
|
| 134 |
+
"gridPos": {
|
| 135 |
+
"h": 6,
|
| 136 |
+
"w": 24,
|
| 137 |
+
"x": 0,
|
| 138 |
+
"y": 0
|
| 139 |
+
},
|
| 140 |
+
"id": 5,
|
| 141 |
+
"options": {
|
| 142 |
+
"cellHeight": "sm",
|
| 143 |
+
"footer": {
|
| 144 |
+
"countRows": false,
|
| 145 |
+
"fields": "",
|
| 146 |
+
"reducer": [
|
| 147 |
+
"sum"
|
| 148 |
+
],
|
| 149 |
+
"show": false
|
| 150 |
+
},
|
| 151 |
+
"showHeader": true,
|
| 152 |
+
"sortBy": []
|
| 153 |
+
},
|
| 154 |
+
"pluginVersion": "11.2.2",
|
| 155 |
+
"targets": [
|
| 156 |
+
{
|
| 157 |
+
"datasource": {
|
| 158 |
+
"default": true,
|
| 159 |
+
"type": "grafana-postgresql-datasource",
|
| 160 |
+
"uid": "be28nkzirtb0gd"
|
| 161 |
+
},
|
| 162 |
+
"editorMode": "code",
|
| 163 |
+
"format": "table",
|
| 164 |
+
"rawQuery": true,
|
| 165 |
+
"rawSql": "SELECT commit_id, commit_message, metadata->>'gpu_name' as gpu_name, metadata->>'model_id' as model_id, created_at AS date FROM benchmarks WHERE branch = '${branch}' AND metadata->>'gpu_name' = '${gpu_name}' ORDER BY benchmark_id DESC LIMIT ${last_n_commits};",
|
| 166 |
+
"refId": "A",
|
| 167 |
+
"sql": {
|
| 168 |
+
"columns": [
|
| 169 |
+
{
|
| 170 |
+
"parameters": [
|
| 171 |
+
{
|
| 172 |
+
"name": "commit_id",
|
| 173 |
+
"type": "functionParameter"
|
| 174 |
+
}
|
| 175 |
+
],
|
| 176 |
+
"type": "function"
|
| 177 |
+
},
|
| 178 |
+
{
|
| 179 |
+
"parameters": [
|
| 180 |
+
{
|
| 181 |
+
"name": "gpu_name",
|
| 182 |
+
"type": "functionParameter"
|
| 183 |
+
}
|
| 184 |
+
],
|
| 185 |
+
"type": "function"
|
| 186 |
+
}
|
| 187 |
+
],
|
| 188 |
+
"groupBy": [
|
| 189 |
+
{
|
| 190 |
+
"property": {
|
| 191 |
+
"type": "string"
|
| 192 |
+
},
|
| 193 |
+
"type": "groupBy"
|
| 194 |
+
}
|
| 195 |
+
],
|
| 196 |
+
"limit": 50,
|
| 197 |
+
"whereJsonTree": {
|
| 198 |
+
"children1": [
|
| 199 |
+
{
|
| 200 |
+
"id": "baaa8aaa-89ab-4cde-b012-31922f96de3f",
|
| 201 |
+
"properties": {
|
| 202 |
+
"field": "commit_id",
|
| 203 |
+
"fieldSrc": "field",
|
| 204 |
+
"operator": "equal",
|
| 205 |
+
"value": [
|
| 206 |
+
"${commit}"
|
| 207 |
+
],
|
| 208 |
+
"valueError": [
|
| 209 |
+
null
|
| 210 |
+
],
|
| 211 |
+
"valueSrc": [
|
| 212 |
+
"value"
|
| 213 |
+
],
|
| 214 |
+
"valueType": [
|
| 215 |
+
"text"
|
| 216 |
+
]
|
| 217 |
+
},
|
| 218 |
+
"type": "rule"
|
| 219 |
+
}
|
| 220 |
+
],
|
| 221 |
+
"id": "bab88a98-0123-4456-b89a-b1922f7d4f11",
|
| 222 |
+
"type": "group"
|
| 223 |
+
},
|
| 224 |
+
"whereString": "commit_id = '${commit}'"
|
| 225 |
+
},
|
| 226 |
+
"table": "benchmarks"
|
| 227 |
+
}
|
| 228 |
+
],
|
| 229 |
+
"transparent": true,
|
| 230 |
+
"type": "table"
|
| 231 |
+
},
|
| 232 |
+
{
|
| 233 |
+
"collapsed": false,
|
| 234 |
+
"gridPos": {
|
| 235 |
+
"h": 1,
|
| 236 |
+
"w": 24,
|
| 237 |
+
"x": 0,
|
| 238 |
+
"y": 6
|
| 239 |
+
},
|
| 240 |
+
"id": 13,
|
| 241 |
+
"panels": [],
|
| 242 |
+
"title": "Eager Forward Pass",
|
| 243 |
+
"type": "row"
|
| 244 |
+
},
|
| 245 |
+
{
|
| 246 |
+
"datasource": {
|
| 247 |
+
"default": true,
|
| 248 |
+
"type": "grafana-postgresql-datasource",
|
| 249 |
+
"uid": "be28nkzirtb0gd"
|
| 250 |
+
},
|
| 251 |
+
"fieldConfig": {
|
| 252 |
+
"defaults": {
|
| 253 |
+
"color": {
|
| 254 |
+
"mode": "continuous-YlBl"
|
| 255 |
+
},
|
| 256 |
+
"custom": {
|
| 257 |
+
"axisBorderShow": false,
|
| 258 |
+
"axisCenteredZero": false,
|
| 259 |
+
"axisColorMode": "text",
|
| 260 |
+
"axisLabel": "",
|
| 261 |
+
"axisPlacement": "auto",
|
| 262 |
+
"fillOpacity": 80,
|
| 263 |
+
"gradientMode": "scheme",
|
| 264 |
+
"hideFrom": {
|
| 265 |
+
"legend": false,
|
| 266 |
+
"tooltip": false,
|
| 267 |
+
"viz": false
|
| 268 |
+
},
|
| 269 |
+
"lineWidth": 0,
|
| 270 |
+
"scaleDistribution": {
|
| 271 |
+
"type": "linear"
|
| 272 |
+
},
|
| 273 |
+
"thresholdsStyle": {
|
| 274 |
+
"mode": "off"
|
| 275 |
+
}
|
| 276 |
+
},
|
| 277 |
+
"mappings": [],
|
| 278 |
+
"thresholds": {
|
| 279 |
+
"mode": "absolute",
|
| 280 |
+
"steps": [
|
| 281 |
+
{
|
| 282 |
+
"color": "green",
|
| 283 |
+
"value": null
|
| 284 |
+
}
|
| 285 |
+
]
|
| 286 |
+
},
|
| 287 |
+
"unit": "s"
|
| 288 |
+
},
|
| 289 |
+
"overrides": []
|
| 290 |
+
},
|
| 291 |
+
"gridPos": {
|
| 292 |
+
"h": 11,
|
| 293 |
+
"w": 12,
|
| 294 |
+
"x": 0,
|
| 295 |
+
"y": 7
|
| 296 |
+
},
|
| 297 |
+
"id": 7,
|
| 298 |
+
"options": {
|
| 299 |
+
"barRadius": 0.05,
|
| 300 |
+
"barWidth": 0.8,
|
| 301 |
+
"fullHighlight": false,
|
| 302 |
+
"groupWidth": 0.7,
|
| 303 |
+
"legend": {
|
| 304 |
+
"calcs": [],
|
| 305 |
+
"displayMode": "list",
|
| 306 |
+
"placement": "bottom",
|
| 307 |
+
"showLegend": false
|
| 308 |
+
},
|
| 309 |
+
"orientation": "auto",
|
| 310 |
+
"showValue": "auto",
|
| 311 |
+
"stacking": "none",
|
| 312 |
+
"tooltip": {
|
| 313 |
+
"mode": "single",
|
| 314 |
+
"sort": "none"
|
| 315 |
+
},
|
| 316 |
+
"xTickLabelRotation": 0,
|
| 317 |
+
"xTickLabelSpacing": 0
|
| 318 |
+
},
|
| 319 |
+
"pluginVersion": "11.2.2",
|
| 320 |
+
"targets": [
|
| 321 |
+
{
|
| 322 |
+
"datasource": {
|
| 323 |
+
"default": true,
|
| 324 |
+
"type": "grafana-postgresql-datasource",
|
| 325 |
+
"uid": "be28nkzirtb0gd"
|
| 326 |
+
},
|
| 327 |
+
"editorMode": "code",
|
| 328 |
+
"format": "table",
|
| 329 |
+
"rawQuery": true,
|
| 330 |
+
"rawSql": "SELECT CAST(m.measurements->'first_eager_forward_pass_time_secs' AS double precision) AS first_eager_forward_pass_time_secs, left(b.commit_id, 7), m.time FROM benchmarks as b JOIN model_measurements AS m ON b.benchmark_id = m.benchmark_id WHERE b.branch = '${branch}' AND b.metadata->>'gpu_name' = '${gpu_name}' ORDER BY b.benchmark_id DESC LIMIT ${last_n_commits};",
|
| 331 |
+
"refId": "A",
|
| 332 |
+
"sql": {
|
| 333 |
+
"columns": [
|
| 334 |
+
{
|
| 335 |
+
"parameters": [],
|
| 336 |
+
"type": "function"
|
| 337 |
+
}
|
| 338 |
+
],
|
| 339 |
+
"groupBy": [
|
| 340 |
+
{
|
| 341 |
+
"property": {
|
| 342 |
+
"type": "string"
|
| 343 |
+
},
|
| 344 |
+
"type": "groupBy"
|
| 345 |
+
}
|
| 346 |
+
],
|
| 347 |
+
"limit": 50
|
| 348 |
+
}
|
| 349 |
+
}
|
| 350 |
+
],
|
| 351 |
+
"title": "First eager forward pass",
|
| 352 |
+
"transformations": [
|
| 353 |
+
{
|
| 354 |
+
"id": "sortBy",
|
| 355 |
+
"options": {
|
| 356 |
+
"fields": {},
|
| 357 |
+
"sort": [
|
| 358 |
+
{
|
| 359 |
+
"field": "time"
|
| 360 |
+
}
|
| 361 |
+
]
|
| 362 |
+
}
|
| 363 |
+
}
|
| 364 |
+
],
|
| 365 |
+
"transparent": true,
|
| 366 |
+
"type": "barchart"
|
| 367 |
+
},
|
| 368 |
+
{
|
| 369 |
+
"datasource": {
|
| 370 |
+
"default": true,
|
| 371 |
+
"type": "grafana-postgresql-datasource",
|
| 372 |
+
"uid": "be28nkzirtb0gd"
|
| 373 |
+
},
|
| 374 |
+
"fieldConfig": {
|
| 375 |
+
"defaults": {
|
| 376 |
+
"color": {
|
| 377 |
+
"mode": "continuous-YlBl"
|
| 378 |
+
},
|
| 379 |
+
"custom": {
|
| 380 |
+
"axisBorderShow": false,
|
| 381 |
+
"axisCenteredZero": false,
|
| 382 |
+
"axisColorMode": "text",
|
| 383 |
+
"axisLabel": "",
|
| 384 |
+
"axisPlacement": "auto",
|
| 385 |
+
"fillOpacity": 80,
|
| 386 |
+
"gradientMode": "scheme",
|
| 387 |
+
"hideFrom": {
|
| 388 |
+
"legend": false,
|
| 389 |
+
"tooltip": false,
|
| 390 |
+
"viz": false
|
| 391 |
+
},
|
| 392 |
+
"lineWidth": 0,
|
| 393 |
+
"scaleDistribution": {
|
| 394 |
+
"type": "linear"
|
| 395 |
+
},
|
| 396 |
+
"thresholdsStyle": {
|
| 397 |
+
"mode": "off"
|
| 398 |
+
}
|
| 399 |
+
},
|
| 400 |
+
"mappings": [],
|
| 401 |
+
"thresholds": {
|
| 402 |
+
"mode": "absolute",
|
| 403 |
+
"steps": [
|
| 404 |
+
{
|
| 405 |
+
"color": "green",
|
| 406 |
+
"value": null
|
| 407 |
+
},
|
| 408 |
+
{
|
| 409 |
+
"color": "red",
|
| 410 |
+
"value": 80
|
| 411 |
+
}
|
| 412 |
+
]
|
| 413 |
+
},
|
| 414 |
+
"unit": "s"
|
| 415 |
+
},
|
| 416 |
+
"overrides": []
|
| 417 |
+
},
|
| 418 |
+
"gridPos": {
|
| 419 |
+
"h": 11,
|
| 420 |
+
"w": 12,
|
| 421 |
+
"x": 12,
|
| 422 |
+
"y": 7
|
| 423 |
+
},
|
| 424 |
+
"id": 9,
|
| 425 |
+
"options": {
|
| 426 |
+
"barRadius": 0.05,
|
| 427 |
+
"barWidth": 0.8,
|
| 428 |
+
"fullHighlight": false,
|
| 429 |
+
"groupWidth": 0.7,
|
| 430 |
+
"legend": {
|
| 431 |
+
"calcs": [],
|
| 432 |
+
"displayMode": "list",
|
| 433 |
+
"placement": "bottom",
|
| 434 |
+
"showLegend": false
|
| 435 |
+
},
|
| 436 |
+
"orientation": "auto",
|
| 437 |
+
"showValue": "auto",
|
| 438 |
+
"stacking": "none",
|
| 439 |
+
"tooltip": {
|
| 440 |
+
"mode": "single",
|
| 441 |
+
"sort": "none"
|
| 442 |
+
},
|
| 443 |
+
"xTickLabelRotation": 0,
|
| 444 |
+
"xTickLabelSpacing": 0
|
| 445 |
+
},
|
| 446 |
+
"targets": [
|
| 447 |
+
{
|
| 448 |
+
"datasource": {
|
| 449 |
+
"default": true,
|
| 450 |
+
"type": "grafana-postgresql-datasource",
|
| 451 |
+
"uid": "be28nkzirtb0gd"
|
| 452 |
+
},
|
| 453 |
+
"editorMode": "code",
|
| 454 |
+
"format": "table",
|
| 455 |
+
"rawQuery": true,
|
| 456 |
+
"rawSql": "SELECT CAST(m.measurements->'second_eager_forward_pass_time_secs' AS double precision) AS second_eager_forward_pass_time_secs, left(b.commit_id, 7), m.time FROM benchmarks as b JOIN model_measurements AS m ON b.benchmark_id = m.benchmark_id WHERE b.branch = '${branch}' AND b.metadata->>'gpu_name' = '${gpu_name}' ORDER BY b.benchmark_id DESC LIMIT ${last_n_commits};",
|
| 457 |
+
"refId": "A",
|
| 458 |
+
"sql": {
|
| 459 |
+
"columns": [
|
| 460 |
+
{
|
| 461 |
+
"parameters": [],
|
| 462 |
+
"type": "function"
|
| 463 |
+
}
|
| 464 |
+
],
|
| 465 |
+
"groupBy": [
|
| 466 |
+
{
|
| 467 |
+
"property": {
|
| 468 |
+
"type": "string"
|
| 469 |
+
},
|
| 470 |
+
"type": "groupBy"
|
| 471 |
+
}
|
| 472 |
+
],
|
| 473 |
+
"limit": 50
|
| 474 |
+
}
|
| 475 |
+
}
|
| 476 |
+
],
|
| 477 |
+
"title": "Second eager forward pass",
|
| 478 |
+
"transformations": [
|
| 479 |
+
{
|
| 480 |
+
"id": "sortBy",
|
| 481 |
+
"options": {
|
| 482 |
+
"fields": {},
|
| 483 |
+
"sort": [
|
| 484 |
+
{
|
| 485 |
+
"field": "time"
|
| 486 |
+
}
|
| 487 |
+
]
|
| 488 |
+
}
|
| 489 |
+
}
|
| 490 |
+
],
|
| 491 |
+
"transparent": true,
|
| 492 |
+
"type": "barchart"
|
| 493 |
+
},
|
| 494 |
+
{
|
| 495 |
+
"collapsed": false,
|
| 496 |
+
"gridPos": {
|
| 497 |
+
"h": 1,
|
| 498 |
+
"w": 24,
|
| 499 |
+
"x": 0,
|
| 500 |
+
"y": 18
|
| 501 |
+
},
|
| 502 |
+
"id": 16,
|
| 503 |
+
"panels": [],
|
| 504 |
+
"title": "Time to next token",
|
| 505 |
+
"type": "row"
|
| 506 |
+
},
|
| 507 |
+
{
|
| 508 |
+
"datasource": {
|
| 509 |
+
"default": true,
|
| 510 |
+
"type": "grafana-postgresql-datasource",
|
| 511 |
+
"uid": "be28nkzirtb0gd"
|
| 512 |
+
},
|
| 513 |
+
"fieldConfig": {
|
| 514 |
+
"defaults": {
|
| 515 |
+
"color": {
|
| 516 |
+
"mode": "continuous-YlBl"
|
| 517 |
+
},
|
| 518 |
+
"custom": {
|
| 519 |
+
"axisBorderShow": false,
|
| 520 |
+
"axisCenteredZero": false,
|
| 521 |
+
"axisColorMode": "text",
|
| 522 |
+
"axisLabel": "",
|
| 523 |
+
"axisPlacement": "auto",
|
| 524 |
+
"fillOpacity": 80,
|
| 525 |
+
"gradientMode": "scheme",
|
| 526 |
+
"hideFrom": {
|
| 527 |
+
"legend": false,
|
| 528 |
+
"tooltip": false,
|
| 529 |
+
"viz": false
|
| 530 |
+
},
|
| 531 |
+
"lineWidth": 0,
|
| 532 |
+
"scaleDistribution": {
|
| 533 |
+
"type": "linear"
|
| 534 |
+
},
|
| 535 |
+
"thresholdsStyle": {
|
| 536 |
+
"mode": "off"
|
| 537 |
+
}
|
| 538 |
+
},
|
| 539 |
+
"mappings": [],
|
| 540 |
+
"thresholds": {
|
| 541 |
+
"mode": "absolute",
|
| 542 |
+
"steps": [
|
| 543 |
+
{
|
| 544 |
+
"color": "green",
|
| 545 |
+
"value": null
|
| 546 |
+
}
|
| 547 |
+
]
|
| 548 |
+
},
|
| 549 |
+
"unit": "s"
|
| 550 |
+
},
|
| 551 |
+
"overrides": []
|
| 552 |
+
},
|
| 553 |
+
"gridPos": {
|
| 554 |
+
"h": 11,
|
| 555 |
+
"w": 12,
|
| 556 |
+
"x": 0,
|
| 557 |
+
"y": 19
|
| 558 |
+
},
|
| 559 |
+
"id": 17,
|
| 560 |
+
"options": {
|
| 561 |
+
"barRadius": 0.05,
|
| 562 |
+
"barWidth": 0.8,
|
| 563 |
+
"fullHighlight": false,
|
| 564 |
+
"groupWidth": 0.7,
|
| 565 |
+
"legend": {
|
| 566 |
+
"calcs": [],
|
| 567 |
+
"displayMode": "list",
|
| 568 |
+
"placement": "bottom",
|
| 569 |
+
"showLegend": false
|
| 570 |
+
},
|
| 571 |
+
"orientation": "auto",
|
| 572 |
+
"showValue": "always",
|
| 573 |
+
"stacking": "none",
|
| 574 |
+
"tooltip": {
|
| 575 |
+
"mode": "single",
|
| 576 |
+
"sort": "none"
|
| 577 |
+
},
|
| 578 |
+
"xTickLabelRotation": 0,
|
| 579 |
+
"xTickLabelSpacing": 0
|
| 580 |
+
},
|
| 581 |
+
"targets": [
|
| 582 |
+
{
|
| 583 |
+
"datasource": {
|
| 584 |
+
"default": true,
|
| 585 |
+
"type": "grafana-postgresql-datasource",
|
| 586 |
+
"uid": "be28nkzirtb0gd"
|
| 587 |
+
},
|
| 588 |
+
"editorMode": "code",
|
| 589 |
+
"format": "table",
|
| 590 |
+
"rawQuery": true,
|
| 591 |
+
"rawSql": "SELECT CAST(m.measurements->'time_to_first_token_secs' AS double precision) AS time_to_first_token_secs, left(b.commit_id, 7), m.time FROM benchmarks as b JOIN model_measurements AS m ON b.benchmark_id = m.benchmark_id WHERE b.branch = '${branch}' AND b.metadata->>'gpu_name' = '${gpu_name}' ORDER BY b.benchmark_id DESC LIMIT ${last_n_commits};",
|
| 592 |
+
"refId": "A",
|
| 593 |
+
"sql": {
|
| 594 |
+
"columns": [
|
| 595 |
+
{
|
| 596 |
+
"parameters": [],
|
| 597 |
+
"type": "function"
|
| 598 |
+
}
|
| 599 |
+
],
|
| 600 |
+
"groupBy": [
|
| 601 |
+
{
|
| 602 |
+
"property": {
|
| 603 |
+
"type": "string"
|
| 604 |
+
},
|
| 605 |
+
"type": "groupBy"
|
| 606 |
+
}
|
| 607 |
+
],
|
| 608 |
+
"limit": 50
|
| 609 |
+
}
|
| 610 |
+
}
|
| 611 |
+
],
|
| 612 |
+
"title": "Time to first token",
|
| 613 |
+
"transformations": [
|
| 614 |
+
{
|
| 615 |
+
"id": "sortBy",
|
| 616 |
+
"options": {
|
| 617 |
+
"fields": {},
|
| 618 |
+
"sort": [
|
| 619 |
+
{
|
| 620 |
+
"field": "time"
|
| 621 |
+
}
|
| 622 |
+
]
|
| 623 |
+
}
|
| 624 |
+
}
|
| 625 |
+
],
|
| 626 |
+
"transparent": true,
|
| 627 |
+
"type": "barchart"
|
| 628 |
+
},
|
| 629 |
+
{
|
| 630 |
+
"datasource": {
|
| 631 |
+
"default": true,
|
| 632 |
+
"type": "grafana-postgresql-datasource",
|
| 633 |
+
"uid": "be28nkzirtb0gd"
|
| 634 |
+
},
|
| 635 |
+
"fieldConfig": {
|
| 636 |
+
"defaults": {
|
| 637 |
+
"color": {
|
| 638 |
+
"mode": "continuous-YlBl"
|
| 639 |
+
},
|
| 640 |
+
"custom": {
|
| 641 |
+
"axisBorderShow": false,
|
| 642 |
+
"axisCenteredZero": false,
|
| 643 |
+
"axisColorMode": "text",
|
| 644 |
+
"axisLabel": "",
|
| 645 |
+
"axisPlacement": "auto",
|
| 646 |
+
"fillOpacity": 80,
|
| 647 |
+
"gradientMode": "scheme",
|
| 648 |
+
"hideFrom": {
|
| 649 |
+
"legend": false,
|
| 650 |
+
"tooltip": false,
|
| 651 |
+
"viz": false
|
| 652 |
+
},
|
| 653 |
+
"lineWidth": 0,
|
| 654 |
+
"scaleDistribution": {
|
| 655 |
+
"type": "linear"
|
| 656 |
+
},
|
| 657 |
+
"thresholdsStyle": {
|
| 658 |
+
"mode": "off"
|
| 659 |
+
}
|
| 660 |
+
},
|
| 661 |
+
"mappings": [],
|
| 662 |
+
"thresholds": {
|
| 663 |
+
"mode": "absolute",
|
| 664 |
+
"steps": [
|
| 665 |
+
{
|
| 666 |
+
"color": "green",
|
| 667 |
+
"value": null
|
| 668 |
+
}
|
| 669 |
+
]
|
| 670 |
+
},
|
| 671 |
+
"unit": "s"
|
| 672 |
+
},
|
| 673 |
+
"overrides": []
|
| 674 |
+
},
|
| 675 |
+
"gridPos": {
|
| 676 |
+
"h": 11,
|
| 677 |
+
"w": 12,
|
| 678 |
+
"x": 12,
|
| 679 |
+
"y": 19
|
| 680 |
+
},
|
| 681 |
+
"id": 18,
|
| 682 |
+
"options": {
|
| 683 |
+
"barRadius": 0.05,
|
| 684 |
+
"barWidth": 0.8,
|
| 685 |
+
"fullHighlight": false,
|
| 686 |
+
"groupWidth": 0.7,
|
| 687 |
+
"legend": {
|
| 688 |
+
"calcs": [],
|
| 689 |
+
"displayMode": "list",
|
| 690 |
+
"placement": "bottom",
|
| 691 |
+
"showLegend": false
|
| 692 |
+
},
|
| 693 |
+
"orientation": "auto",
|
| 694 |
+
"showValue": "always",
|
| 695 |
+
"stacking": "none",
|
| 696 |
+
"tooltip": {
|
| 697 |
+
"mode": "single",
|
| 698 |
+
"sort": "none"
|
| 699 |
+
},
|
| 700 |
+
"xTickLabelRotation": 0,
|
| 701 |
+
"xTickLabelSpacing": 0
|
| 702 |
+
},
|
| 703 |
+
"targets": [
|
| 704 |
+
{
|
| 705 |
+
"datasource": {
|
| 706 |
+
"default": true,
|
| 707 |
+
"type": "grafana-postgresql-datasource",
|
| 708 |
+
"uid": "be28nkzirtb0gd"
|
| 709 |
+
},
|
| 710 |
+
"editorMode": "code",
|
| 711 |
+
"format": "table",
|
| 712 |
+
"rawQuery": true,
|
| 713 |
+
"rawSql": "SELECT CAST(m.measurements->'time_to_second_token_secs' AS double precision) AS time_to_second_token_secs, left(b.commit_id, 7), m.time FROM benchmarks as b JOIN model_measurements AS m ON b.benchmark_id = m.benchmark_id WHERE b.branch = '${branch}' AND b.metadata->>'gpu_name' = '${gpu_name}' ORDER BY b.benchmark_id DESC LIMIT ${last_n_commits};",
|
| 714 |
+
"refId": "A",
|
| 715 |
+
"sql": {
|
| 716 |
+
"columns": [
|
| 717 |
+
{
|
| 718 |
+
"parameters": [],
|
| 719 |
+
"type": "function"
|
| 720 |
+
}
|
| 721 |
+
],
|
| 722 |
+
"groupBy": [
|
| 723 |
+
{
|
| 724 |
+
"property": {
|
| 725 |
+
"type": "string"
|
| 726 |
+
},
|
| 727 |
+
"type": "groupBy"
|
| 728 |
+
}
|
| 729 |
+
],
|
| 730 |
+
"limit": 50
|
| 731 |
+
}
|
| 732 |
+
}
|
| 733 |
+
],
|
| 734 |
+
"title": "Time to second token",
|
| 735 |
+
"transformations": [
|
| 736 |
+
{
|
| 737 |
+
"id": "sortBy",
|
| 738 |
+
"options": {
|
| 739 |
+
"fields": {},
|
| 740 |
+
"sort": [
|
| 741 |
+
{
|
| 742 |
+
"field": "time"
|
| 743 |
+
}
|
| 744 |
+
]
|
| 745 |
+
}
|
| 746 |
+
}
|
| 747 |
+
],
|
| 748 |
+
"transparent": true,
|
| 749 |
+
"type": "barchart"
|
| 750 |
+
},
|
| 751 |
+
{
|
| 752 |
+
"datasource": {
|
| 753 |
+
"default": true,
|
| 754 |
+
"type": "grafana-postgresql-datasource",
|
| 755 |
+
"uid": "be28nkzirtb0gd"
|
| 756 |
+
},
|
| 757 |
+
"fieldConfig": {
|
| 758 |
+
"defaults": {
|
| 759 |
+
"color": {
|
| 760 |
+
"mode": "continuous-YlBl"
|
| 761 |
+
},
|
| 762 |
+
"custom": {
|
| 763 |
+
"axisBorderShow": false,
|
| 764 |
+
"axisCenteredZero": false,
|
| 765 |
+
"axisColorMode": "text",
|
| 766 |
+
"axisLabel": "",
|
| 767 |
+
"axisPlacement": "auto",
|
| 768 |
+
"fillOpacity": 80,
|
| 769 |
+
"gradientMode": "scheme",
|
| 770 |
+
"hideFrom": {
|
| 771 |
+
"legend": false,
|
| 772 |
+
"tooltip": false,
|
| 773 |
+
"viz": false
|
| 774 |
+
},
|
| 775 |
+
"lineWidth": 0,
|
| 776 |
+
"scaleDistribution": {
|
| 777 |
+
"type": "linear"
|
| 778 |
+
},
|
| 779 |
+
"thresholdsStyle": {
|
| 780 |
+
"mode": "off"
|
| 781 |
+
}
|
| 782 |
+
},
|
| 783 |
+
"mappings": [],
|
| 784 |
+
"thresholds": {
|
| 785 |
+
"mode": "absolute",
|
| 786 |
+
"steps": [
|
| 787 |
+
{
|
| 788 |
+
"color": "green",
|
| 789 |
+
"value": null
|
| 790 |
+
}
|
| 791 |
+
]
|
| 792 |
+
},
|
| 793 |
+
"unit": "s"
|
| 794 |
+
},
|
| 795 |
+
"overrides": []
|
| 796 |
+
},
|
| 797 |
+
"gridPos": {
|
| 798 |
+
"h": 11,
|
| 799 |
+
"w": 12,
|
| 800 |
+
"x": 0,
|
| 801 |
+
"y": 30
|
| 802 |
+
},
|
| 803 |
+
"id": 19,
|
| 804 |
+
"options": {
|
| 805 |
+
"barRadius": 0.05,
|
| 806 |
+
"barWidth": 0.8,
|
| 807 |
+
"fullHighlight": false,
|
| 808 |
+
"groupWidth": 0.7,
|
| 809 |
+
"legend": {
|
| 810 |
+
"calcs": [],
|
| 811 |
+
"displayMode": "list",
|
| 812 |
+
"placement": "bottom",
|
| 813 |
+
"showLegend": false
|
| 814 |
+
},
|
| 815 |
+
"orientation": "auto",
|
| 816 |
+
"showValue": "always",
|
| 817 |
+
"stacking": "none",
|
| 818 |
+
"tooltip": {
|
| 819 |
+
"mode": "single",
|
| 820 |
+
"sort": "none"
|
| 821 |
+
},
|
| 822 |
+
"xTickLabelRotation": 0,
|
| 823 |
+
"xTickLabelSpacing": 0
|
| 824 |
+
},
|
| 825 |
+
"targets": [
|
| 826 |
+
{
|
| 827 |
+
"datasource": {
|
| 828 |
+
"default": true,
|
| 829 |
+
"type": "grafana-postgresql-datasource",
|
| 830 |
+
"uid": "be28nkzirtb0gd"
|
| 831 |
+
},
|
| 832 |
+
"editorMode": "code",
|
| 833 |
+
"format": "table",
|
| 834 |
+
"rawQuery": true,
|
| 835 |
+
"rawSql": "SELECT CAST(m.measurements->'time_to_third_token_secs' AS double precision) AS time_to_third_token_secs, left(b.commit_id, 7), m.time FROM benchmarks as b JOIN model_measurements AS m ON b.benchmark_id = m.benchmark_id WHERE b.branch = '${branch}' AND b.metadata->>'gpu_name' = '${gpu_name}' ORDER BY b.benchmark_id DESC LIMIT ${last_n_commits};",
|
| 836 |
+
"refId": "A",
|
| 837 |
+
"sql": {
|
| 838 |
+
"columns": [
|
| 839 |
+
{
|
| 840 |
+
"parameters": [],
|
| 841 |
+
"type": "function"
|
| 842 |
+
}
|
| 843 |
+
],
|
| 844 |
+
"groupBy": [
|
| 845 |
+
{
|
| 846 |
+
"property": {
|
| 847 |
+
"type": "string"
|
| 848 |
+
},
|
| 849 |
+
"type": "groupBy"
|
| 850 |
+
}
|
| 851 |
+
],
|
| 852 |
+
"limit": 50
|
| 853 |
+
}
|
| 854 |
+
}
|
| 855 |
+
],
|
| 856 |
+
"title": "Time to third token",
|
| 857 |
+
"transformations": [
|
| 858 |
+
{
|
| 859 |
+
"id": "sortBy",
|
| 860 |
+
"options": {
|
| 861 |
+
"fields": {},
|
| 862 |
+
"sort": [
|
| 863 |
+
{
|
| 864 |
+
"field": "time"
|
| 865 |
+
}
|
| 866 |
+
]
|
| 867 |
+
}
|
| 868 |
+
}
|
| 869 |
+
],
|
| 870 |
+
"transparent": true,
|
| 871 |
+
"type": "barchart"
|
| 872 |
+
},
|
| 873 |
+
{
|
| 874 |
+
"datasource": {
|
| 875 |
+
"default": true,
|
| 876 |
+
"type": "grafana-postgresql-datasource",
|
| 877 |
+
"uid": "be28nkzirtb0gd"
|
| 878 |
+
},
|
| 879 |
+
"fieldConfig": {
|
| 880 |
+
"defaults": {
|
| 881 |
+
"color": {
|
| 882 |
+
"mode": "continuous-YlBl"
|
| 883 |
+
},
|
| 884 |
+
"custom": {
|
| 885 |
+
"axisBorderShow": false,
|
| 886 |
+
"axisCenteredZero": false,
|
| 887 |
+
"axisColorMode": "text",
|
| 888 |
+
"axisLabel": "",
|
| 889 |
+
"axisPlacement": "auto",
|
| 890 |
+
"fillOpacity": 80,
|
| 891 |
+
"gradientMode": "scheme",
|
| 892 |
+
"hideFrom": {
|
| 893 |
+
"legend": false,
|
| 894 |
+
"tooltip": false,
|
| 895 |
+
"viz": false
|
| 896 |
+
},
|
| 897 |
+
"lineWidth": 0,
|
| 898 |
+
"scaleDistribution": {
|
| 899 |
+
"type": "linear"
|
| 900 |
+
},
|
| 901 |
+
"thresholdsStyle": {
|
| 902 |
+
"mode": "off"
|
| 903 |
+
}
|
| 904 |
+
},
|
| 905 |
+
"mappings": [],
|
| 906 |
+
"thresholds": {
|
| 907 |
+
"mode": "absolute",
|
| 908 |
+
"steps": [
|
| 909 |
+
{
|
| 910 |
+
"color": "green",
|
| 911 |
+
"value": null
|
| 912 |
+
}
|
| 913 |
+
]
|
| 914 |
+
},
|
| 915 |
+
"unit": "s"
|
| 916 |
+
},
|
| 917 |
+
"overrides": []
|
| 918 |
+
},
|
| 919 |
+
"gridPos": {
|
| 920 |
+
"h": 11,
|
| 921 |
+
"w": 12,
|
| 922 |
+
"x": 12,
|
| 923 |
+
"y": 30
|
| 924 |
+
},
|
| 925 |
+
"id": 20,
|
| 926 |
+
"options": {
|
| 927 |
+
"barRadius": 0.05,
|
| 928 |
+
"barWidth": 0.8,
|
| 929 |
+
"fullHighlight": false,
|
| 930 |
+
"groupWidth": 0.7,
|
| 931 |
+
"legend": {
|
| 932 |
+
"calcs": [],
|
| 933 |
+
"displayMode": "list",
|
| 934 |
+
"placement": "bottom",
|
| 935 |
+
"showLegend": false
|
| 936 |
+
},
|
| 937 |
+
"orientation": "auto",
|
| 938 |
+
"showValue": "always",
|
| 939 |
+
"stacking": "none",
|
| 940 |
+
"tooltip": {
|
| 941 |
+
"mode": "single",
|
| 942 |
+
"sort": "none"
|
| 943 |
+
},
|
| 944 |
+
"xTickLabelRotation": 0,
|
| 945 |
+
"xTickLabelSpacing": 0
|
| 946 |
+
},
|
| 947 |
+
"targets": [
|
| 948 |
+
{
|
| 949 |
+
"datasource": {
|
| 950 |
+
"default": true,
|
| 951 |
+
"type": "grafana-postgresql-datasource",
|
| 952 |
+
"uid": "be28nkzirtb0gd"
|
| 953 |
+
},
|
| 954 |
+
"editorMode": "code",
|
| 955 |
+
"format": "table",
|
| 956 |
+
"rawQuery": true,
|
| 957 |
+
"rawSql": "SELECT CAST(m.measurements->'time_to_next_token_mean_secs' AS double precision) AS time_to_next_token_mean_secs, left(b.commit_id, 7), m.time FROM benchmarks as b JOIN model_measurements AS m ON b.benchmark_id = m.benchmark_id WHERE b.branch = '${branch}' AND b.metadata->>'gpu_name' = '${gpu_name}' ORDER BY b.benchmark_id DESC LIMIT ${last_n_commits};",
|
| 958 |
+
"refId": "A",
|
| 959 |
+
"sql": {
|
| 960 |
+
"columns": [
|
| 961 |
+
{
|
| 962 |
+
"parameters": [],
|
| 963 |
+
"type": "function"
|
| 964 |
+
}
|
| 965 |
+
],
|
| 966 |
+
"groupBy": [
|
| 967 |
+
{
|
| 968 |
+
"property": {
|
| 969 |
+
"type": "string"
|
| 970 |
+
},
|
| 971 |
+
"type": "groupBy"
|
| 972 |
+
}
|
| 973 |
+
],
|
| 974 |
+
"limit": 50
|
| 975 |
+
}
|
| 976 |
+
}
|
| 977 |
+
],
|
| 978 |
+
"title": "Time to subsequent next tokens mean",
|
| 979 |
+
"transformations": [
|
| 980 |
+
{
|
| 981 |
+
"id": "sortBy",
|
| 982 |
+
"options": {
|
| 983 |
+
"fields": {},
|
| 984 |
+
"sort": [
|
| 985 |
+
{
|
| 986 |
+
"field": "time"
|
| 987 |
+
}
|
| 988 |
+
]
|
| 989 |
+
}
|
| 990 |
+
}
|
| 991 |
+
],
|
| 992 |
+
"transparent": true,
|
| 993 |
+
"type": "barchart"
|
| 994 |
+
},
|
| 995 |
+
{
|
| 996 |
+
"collapsed": false,
|
| 997 |
+
"gridPos": {
|
| 998 |
+
"h": 1,
|
| 999 |
+
"w": 24,
|
| 1000 |
+
"x": 0,
|
| 1001 |
+
"y": 41
|
| 1002 |
+
},
|
| 1003 |
+
"id": 14,
|
| 1004 |
+
"panels": [],
|
| 1005 |
+
"title": "Compiled Generate",
|
| 1006 |
+
"type": "row"
|
| 1007 |
+
},
|
| 1008 |
+
{
|
| 1009 |
+
"datasource": {
|
| 1010 |
+
"default": true,
|
| 1011 |
+
"type": "grafana-postgresql-datasource",
|
| 1012 |
+
"uid": "be28nkzirtb0gd"
|
| 1013 |
+
},
|
| 1014 |
+
"fieldConfig": {
|
| 1015 |
+
"defaults": {
|
| 1016 |
+
"color": {
|
| 1017 |
+
"mode": "continuous-YlBl"
|
| 1018 |
+
},
|
| 1019 |
+
"custom": {
|
| 1020 |
+
"axisBorderShow": false,
|
| 1021 |
+
"axisCenteredZero": false,
|
| 1022 |
+
"axisColorMode": "text",
|
| 1023 |
+
"axisLabel": "",
|
| 1024 |
+
"axisPlacement": "auto",
|
| 1025 |
+
"fillOpacity": 80,
|
| 1026 |
+
"gradientMode": "scheme",
|
| 1027 |
+
"hideFrom": {
|
| 1028 |
+
"legend": false,
|
| 1029 |
+
"tooltip": false,
|
| 1030 |
+
"viz": false
|
| 1031 |
+
},
|
| 1032 |
+
"lineWidth": 0,
|
| 1033 |
+
"scaleDistribution": {
|
| 1034 |
+
"type": "linear"
|
| 1035 |
+
},
|
| 1036 |
+
"thresholdsStyle": {
|
| 1037 |
+
"mode": "off"
|
| 1038 |
+
}
|
| 1039 |
+
},
|
| 1040 |
+
"mappings": [],
|
| 1041 |
+
"thresholds": {
|
| 1042 |
+
"mode": "absolute",
|
| 1043 |
+
"steps": [
|
| 1044 |
+
{
|
| 1045 |
+
"color": "green",
|
| 1046 |
+
"value": null
|
| 1047 |
+
}
|
| 1048 |
+
]
|
| 1049 |
+
},
|
| 1050 |
+
"unit": "s"
|
| 1051 |
+
},
|
| 1052 |
+
"overrides": []
|
| 1053 |
+
},
|
| 1054 |
+
"gridPos": {
|
| 1055 |
+
"h": 11,
|
| 1056 |
+
"w": 12,
|
| 1057 |
+
"x": 0,
|
| 1058 |
+
"y": 42
|
| 1059 |
+
},
|
| 1060 |
+
"id": 8,
|
| 1061 |
+
"options": {
|
| 1062 |
+
"barRadius": 0.05,
|
| 1063 |
+
"barWidth": 0.8,
|
| 1064 |
+
"fullHighlight": false,
|
| 1065 |
+
"groupWidth": 0.7,
|
| 1066 |
+
"legend": {
|
| 1067 |
+
"calcs": [],
|
| 1068 |
+
"displayMode": "list",
|
| 1069 |
+
"placement": "bottom",
|
| 1070 |
+
"showLegend": false
|
| 1071 |
+
},
|
| 1072 |
+
"orientation": "auto",
|
| 1073 |
+
"showValue": "always",
|
| 1074 |
+
"stacking": "none",
|
| 1075 |
+
"tooltip": {
|
| 1076 |
+
"mode": "single",
|
| 1077 |
+
"sort": "none"
|
| 1078 |
+
},
|
| 1079 |
+
"xTickLabelRotation": 0,
|
| 1080 |
+
"xTickLabelSpacing": 0
|
| 1081 |
+
},
|
| 1082 |
+
"targets": [
|
| 1083 |
+
{
|
| 1084 |
+
"datasource": {
|
| 1085 |
+
"default": true,
|
| 1086 |
+
"type": "grafana-postgresql-datasource",
|
| 1087 |
+
"uid": "be28nkzirtb0gd"
|
| 1088 |
+
},
|
| 1089 |
+
"editorMode": "code",
|
| 1090 |
+
"format": "table",
|
| 1091 |
+
"rawQuery": true,
|
| 1092 |
+
"rawSql": "SELECT CAST(m.measurements->'first_compile_generate_time_secs' AS double precision) AS first_compile_generate_time_secs, left(b.commit_id, 7), m.time FROM benchmarks as b JOIN model_measurements AS m ON b.benchmark_id = m.benchmark_id WHERE b.branch = '${branch}' AND b.metadata->>'gpu_name' = '${gpu_name}' ORDER BY b.benchmark_id DESC LIMIT ${last_n_commits};",
|
| 1093 |
+
"refId": "A",
|
| 1094 |
+
"sql": {
|
| 1095 |
+
"columns": [
|
| 1096 |
+
{
|
| 1097 |
+
"parameters": [],
|
| 1098 |
+
"type": "function"
|
| 1099 |
+
}
|
| 1100 |
+
],
|
| 1101 |
+
"groupBy": [
|
| 1102 |
+
{
|
| 1103 |
+
"property": {
|
| 1104 |
+
"type": "string"
|
| 1105 |
+
},
|
| 1106 |
+
"type": "groupBy"
|
| 1107 |
+
}
|
| 1108 |
+
],
|
| 1109 |
+
"limit": 50
|
| 1110 |
+
}
|
| 1111 |
+
}
|
| 1112 |
+
],
|
| 1113 |
+
"title": "First compile generate",
|
| 1114 |
+
"transformations": [
|
| 1115 |
+
{
|
| 1116 |
+
"id": "sortBy",
|
| 1117 |
+
"options": {
|
| 1118 |
+
"fields": {},
|
| 1119 |
+
"sort": [
|
| 1120 |
+
{
|
| 1121 |
+
"field": "time"
|
| 1122 |
+
}
|
| 1123 |
+
]
|
| 1124 |
+
}
|
| 1125 |
+
}
|
| 1126 |
+
],
|
| 1127 |
+
"transparent": true,
|
| 1128 |
+
"type": "barchart"
|
| 1129 |
+
},
|
| 1130 |
+
{
|
| 1131 |
+
"datasource": {
|
| 1132 |
+
"default": true,
|
| 1133 |
+
"type": "grafana-postgresql-datasource",
|
| 1134 |
+
"uid": "be28nkzirtb0gd"
|
| 1135 |
+
},
|
| 1136 |
+
"fieldConfig": {
|
| 1137 |
+
"defaults": {
|
| 1138 |
+
"color": {
|
| 1139 |
+
"mode": "continuous-YlBl"
|
| 1140 |
+
},
|
| 1141 |
+
"custom": {
|
| 1142 |
+
"axisBorderShow": false,
|
| 1143 |
+
"axisCenteredZero": false,
|
| 1144 |
+
"axisColorMode": "text",
|
| 1145 |
+
"axisLabel": "",
|
| 1146 |
+
"axisPlacement": "auto",
|
| 1147 |
+
"fillOpacity": 80,
|
| 1148 |
+
"gradientMode": "scheme",
|
| 1149 |
+
"hideFrom": {
|
| 1150 |
+
"legend": false,
|
| 1151 |
+
"tooltip": false,
|
| 1152 |
+
"viz": false
|
| 1153 |
+
},
|
| 1154 |
+
"lineWidth": 0,
|
| 1155 |
+
"scaleDistribution": {
|
| 1156 |
+
"type": "linear"
|
| 1157 |
+
},
|
| 1158 |
+
"thresholdsStyle": {
|
| 1159 |
+
"mode": "off"
|
| 1160 |
+
}
|
| 1161 |
+
},
|
| 1162 |
+
"mappings": [],
|
| 1163 |
+
"thresholds": {
|
| 1164 |
+
"mode": "absolute",
|
| 1165 |
+
"steps": [
|
| 1166 |
+
{
|
| 1167 |
+
"color": "green",
|
| 1168 |
+
"value": null
|
| 1169 |
+
}
|
| 1170 |
+
]
|
| 1171 |
+
},
|
| 1172 |
+
"unit": "s"
|
| 1173 |
+
},
|
| 1174 |
+
"overrides": []
|
| 1175 |
+
},
|
| 1176 |
+
"gridPos": {
|
| 1177 |
+
"h": 11,
|
| 1178 |
+
"w": 12,
|
| 1179 |
+
"x": 12,
|
| 1180 |
+
"y": 42
|
| 1181 |
+
},
|
| 1182 |
+
"id": 10,
|
| 1183 |
+
"options": {
|
| 1184 |
+
"barRadius": 0.05,
|
| 1185 |
+
"barWidth": 0.8,
|
| 1186 |
+
"fullHighlight": false,
|
| 1187 |
+
"groupWidth": 0.7,
|
| 1188 |
+
"legend": {
|
| 1189 |
+
"calcs": [],
|
| 1190 |
+
"displayMode": "list",
|
| 1191 |
+
"placement": "bottom",
|
| 1192 |
+
"showLegend": false
|
| 1193 |
+
},
|
| 1194 |
+
"orientation": "auto",
|
| 1195 |
+
"showValue": "auto",
|
| 1196 |
+
"stacking": "none",
|
| 1197 |
+
"tooltip": {
|
| 1198 |
+
"mode": "single",
|
| 1199 |
+
"sort": "none"
|
| 1200 |
+
},
|
| 1201 |
+
"xTickLabelRotation": 0,
|
| 1202 |
+
"xTickLabelSpacing": 0
|
| 1203 |
+
},
|
| 1204 |
+
"targets": [
|
| 1205 |
+
{
|
| 1206 |
+
"datasource": {
|
| 1207 |
+
"default": true,
|
| 1208 |
+
"type": "grafana-postgresql-datasource",
|
| 1209 |
+
"uid": "be28nkzirtb0gd"
|
| 1210 |
+
},
|
| 1211 |
+
"editorMode": "code",
|
| 1212 |
+
"format": "table",
|
| 1213 |
+
"rawQuery": true,
|
| 1214 |
+
"rawSql": "SELECT CAST(m.measurements->'second_compile_generate_time_secs' AS double precision) AS second_compile_generate_time_secs, left(b.commit_id, 7), m.time FROM benchmarks as b JOIN model_measurements AS m ON b.benchmark_id = m.benchmark_id WHERE b.branch = '${branch}' AND b.metadata->>'gpu_name' = '${gpu_name}' ORDER BY b.benchmark_id DESC LIMIT ${last_n_commits};",
|
| 1215 |
+
"refId": "A",
|
| 1216 |
+
"sql": {
|
| 1217 |
+
"columns": [
|
| 1218 |
+
{
|
| 1219 |
+
"parameters": [],
|
| 1220 |
+
"type": "function"
|
| 1221 |
+
}
|
| 1222 |
+
],
|
| 1223 |
+
"groupBy": [
|
| 1224 |
+
{
|
| 1225 |
+
"property": {
|
| 1226 |
+
"type": "string"
|
| 1227 |
+
},
|
| 1228 |
+
"type": "groupBy"
|
| 1229 |
+
}
|
| 1230 |
+
],
|
| 1231 |
+
"limit": 50
|
| 1232 |
+
}
|
| 1233 |
+
}
|
| 1234 |
+
],
|
| 1235 |
+
"title": "Second compile generate",
|
| 1236 |
+
"transformations": [
|
| 1237 |
+
{
|
| 1238 |
+
"id": "sortBy",
|
| 1239 |
+
"options": {
|
| 1240 |
+
"fields": {},
|
| 1241 |
+
"sort": [
|
| 1242 |
+
{
|
| 1243 |
+
"field": "time"
|
| 1244 |
+
}
|
| 1245 |
+
]
|
| 1246 |
+
}
|
| 1247 |
+
}
|
| 1248 |
+
],
|
| 1249 |
+
"transparent": true,
|
| 1250 |
+
"type": "barchart"
|
| 1251 |
+
},
|
| 1252 |
+
{
|
| 1253 |
+
"datasource": {
|
| 1254 |
+
"default": true,
|
| 1255 |
+
"type": "grafana-postgresql-datasource",
|
| 1256 |
+
"uid": "be28nkzirtb0gd"
|
| 1257 |
+
},
|
| 1258 |
+
"fieldConfig": {
|
| 1259 |
+
"defaults": {
|
| 1260 |
+
"color": {
|
| 1261 |
+
"mode": "continuous-YlBl"
|
| 1262 |
+
},
|
| 1263 |
+
"custom": {
|
| 1264 |
+
"axisBorderShow": false,
|
| 1265 |
+
"axisCenteredZero": false,
|
| 1266 |
+
"axisColorMode": "text",
|
| 1267 |
+
"axisLabel": "",
|
| 1268 |
+
"axisPlacement": "auto",
|
| 1269 |
+
"fillOpacity": 80,
|
| 1270 |
+
"gradientMode": "scheme",
|
| 1271 |
+
"hideFrom": {
|
| 1272 |
+
"legend": false,
|
| 1273 |
+
"tooltip": false,
|
| 1274 |
+
"viz": false
|
| 1275 |
+
},
|
| 1276 |
+
"lineWidth": 0,
|
| 1277 |
+
"scaleDistribution": {
|
| 1278 |
+
"type": "linear"
|
| 1279 |
+
},
|
| 1280 |
+
"thresholdsStyle": {
|
| 1281 |
+
"mode": "off"
|
| 1282 |
+
}
|
| 1283 |
+
},
|
| 1284 |
+
"mappings": [],
|
| 1285 |
+
"thresholds": {
|
| 1286 |
+
"mode": "absolute",
|
| 1287 |
+
"steps": [
|
| 1288 |
+
{
|
| 1289 |
+
"color": "green",
|
| 1290 |
+
"value": null
|
| 1291 |
+
}
|
| 1292 |
+
]
|
| 1293 |
+
},
|
| 1294 |
+
"unit": "s"
|
| 1295 |
+
},
|
| 1296 |
+
"overrides": []
|
| 1297 |
+
},
|
| 1298 |
+
"gridPos": {
|
| 1299 |
+
"h": 11,
|
| 1300 |
+
"w": 12,
|
| 1301 |
+
"x": 0,
|
| 1302 |
+
"y": 53
|
| 1303 |
+
},
|
| 1304 |
+
"id": 11,
|
| 1305 |
+
"options": {
|
| 1306 |
+
"barRadius": 0.05,
|
| 1307 |
+
"barWidth": 0.8,
|
| 1308 |
+
"fullHighlight": false,
|
| 1309 |
+
"groupWidth": 0.7,
|
| 1310 |
+
"legend": {
|
| 1311 |
+
"calcs": [],
|
| 1312 |
+
"displayMode": "list",
|
| 1313 |
+
"placement": "bottom",
|
| 1314 |
+
"showLegend": false
|
| 1315 |
+
},
|
| 1316 |
+
"orientation": "auto",
|
| 1317 |
+
"showValue": "auto",
|
| 1318 |
+
"stacking": "none",
|
| 1319 |
+
"tooltip": {
|
| 1320 |
+
"mode": "single",
|
| 1321 |
+
"sort": "none"
|
| 1322 |
+
},
|
| 1323 |
+
"xTickLabelRotation": 0,
|
| 1324 |
+
"xTickLabelSpacing": 0
|
| 1325 |
+
},
|
| 1326 |
+
"targets": [
|
| 1327 |
+
{
|
| 1328 |
+
"datasource": {
|
| 1329 |
+
"default": true,
|
| 1330 |
+
"type": "grafana-postgresql-datasource",
|
| 1331 |
+
"uid": "be28nkzirtb0gd"
|
| 1332 |
+
},
|
| 1333 |
+
"editorMode": "code",
|
| 1334 |
+
"format": "table",
|
| 1335 |
+
"rawQuery": true,
|
| 1336 |
+
"rawSql": "SELECT CAST(m.measurements->'third_compile_generate_time_secs' AS double precision) AS third_compile_generate_time_secs, left(b.commit_id, 7), m.time FROM benchmarks as b JOIN model_measurements AS m ON b.benchmark_id = m.benchmark_id WHERE b.branch = '${branch}' AND b.metadata->>'gpu_name' = '${gpu_name}' ORDER BY b.benchmark_id DESC LIMIT ${last_n_commits};",
|
| 1337 |
+
"refId": "A",
|
| 1338 |
+
"sql": {
|
| 1339 |
+
"columns": [
|
| 1340 |
+
{
|
| 1341 |
+
"parameters": [],
|
| 1342 |
+
"type": "function"
|
| 1343 |
+
}
|
| 1344 |
+
],
|
| 1345 |
+
"groupBy": [
|
| 1346 |
+
{
|
| 1347 |
+
"property": {
|
| 1348 |
+
"type": "string"
|
| 1349 |
+
},
|
| 1350 |
+
"type": "groupBy"
|
| 1351 |
+
}
|
| 1352 |
+
],
|
| 1353 |
+
"limit": 50
|
| 1354 |
+
}
|
| 1355 |
+
}
|
| 1356 |
+
],
|
| 1357 |
+
"title": "Third compile generate",
|
| 1358 |
+
"transformations": [
|
| 1359 |
+
{
|
| 1360 |
+
"id": "sortBy",
|
| 1361 |
+
"options": {
|
| 1362 |
+
"fields": {},
|
| 1363 |
+
"sort": [
|
| 1364 |
+
{
|
| 1365 |
+
"field": "time"
|
| 1366 |
+
}
|
| 1367 |
+
]
|
| 1368 |
+
}
|
| 1369 |
+
}
|
| 1370 |
+
],
|
| 1371 |
+
"transparent": true,
|
| 1372 |
+
"type": "barchart"
|
| 1373 |
+
},
|
| 1374 |
+
{
|
| 1375 |
+
"datasource": {
|
| 1376 |
+
"default": true,
|
| 1377 |
+
"type": "grafana-postgresql-datasource",
|
| 1378 |
+
"uid": "be28nkzirtb0gd"
|
| 1379 |
+
},
|
| 1380 |
+
"fieldConfig": {
|
| 1381 |
+
"defaults": {
|
| 1382 |
+
"color": {
|
| 1383 |
+
"mode": "continuous-YlBl"
|
| 1384 |
+
},
|
| 1385 |
+
"custom": {
|
| 1386 |
+
"axisBorderShow": false,
|
| 1387 |
+
"axisCenteredZero": false,
|
| 1388 |
+
"axisColorMode": "text",
|
| 1389 |
+
"axisLabel": "",
|
| 1390 |
+
"axisPlacement": "auto",
|
| 1391 |
+
"fillOpacity": 80,
|
| 1392 |
+
"gradientMode": "none",
|
| 1393 |
+
"hideFrom": {
|
| 1394 |
+
"legend": false,
|
| 1395 |
+
"tooltip": false,
|
| 1396 |
+
"viz": false
|
| 1397 |
+
},
|
| 1398 |
+
"lineWidth": 0,
|
| 1399 |
+
"scaleDistribution": {
|
| 1400 |
+
"type": "linear"
|
| 1401 |
+
},
|
| 1402 |
+
"thresholdsStyle": {
|
| 1403 |
+
"mode": "off"
|
| 1404 |
+
}
|
| 1405 |
+
},
|
| 1406 |
+
"mappings": [],
|
| 1407 |
+
"thresholds": {
|
| 1408 |
+
"mode": "absolute",
|
| 1409 |
+
"steps": [
|
| 1410 |
+
{
|
| 1411 |
+
"color": "green",
|
| 1412 |
+
"value": null
|
| 1413 |
+
}
|
| 1414 |
+
]
|
| 1415 |
+
},
|
| 1416 |
+
"unit": "s"
|
| 1417 |
+
},
|
| 1418 |
+
"overrides": []
|
| 1419 |
+
},
|
| 1420 |
+
"gridPos": {
|
| 1421 |
+
"h": 11,
|
| 1422 |
+
"w": 12,
|
| 1423 |
+
"x": 12,
|
| 1424 |
+
"y": 53
|
| 1425 |
+
},
|
| 1426 |
+
"id": 12,
|
| 1427 |
+
"options": {
|
| 1428 |
+
"barRadius": 0.05,
|
| 1429 |
+
"barWidth": 0.8,
|
| 1430 |
+
"fullHighlight": false,
|
| 1431 |
+
"groupWidth": 0.7,
|
| 1432 |
+
"legend": {
|
| 1433 |
+
"calcs": [],
|
| 1434 |
+
"displayMode": "list",
|
| 1435 |
+
"placement": "bottom",
|
| 1436 |
+
"showLegend": false
|
| 1437 |
+
},
|
| 1438 |
+
"orientation": "auto",
|
| 1439 |
+
"showValue": "auto",
|
| 1440 |
+
"stacking": "none",
|
| 1441 |
+
"tooltip": {
|
| 1442 |
+
"mode": "single",
|
| 1443 |
+
"sort": "none"
|
| 1444 |
+
},
|
| 1445 |
+
"xTickLabelRotation": 0,
|
| 1446 |
+
"xTickLabelSpacing": 0
|
| 1447 |
+
},
|
| 1448 |
+
"targets": [
|
| 1449 |
+
{
|
| 1450 |
+
"datasource": {
|
| 1451 |
+
"default": true,
|
| 1452 |
+
"type": "grafana-postgresql-datasource",
|
| 1453 |
+
"uid": "be28nkzirtb0gd"
|
| 1454 |
+
},
|
| 1455 |
+
"editorMode": "code",
|
| 1456 |
+
"format": "table",
|
| 1457 |
+
"rawQuery": true,
|
| 1458 |
+
"rawSql": "SELECT CAST(m.measurements->'fourth_compile_generate_time_secs' AS double precision) AS fourth_compile_generate_time_secs, left(b.commit_id, 7), m.time FROM benchmarks as b JOIN model_measurements AS m ON b.benchmark_id = m.benchmark_id WHERE b.branch = '${branch}' AND b.metadata->>'gpu_name' = '${gpu_name}' ORDER BY b.benchmark_id DESC LIMIT ${last_n_commits};",
|
| 1459 |
+
"refId": "A",
|
| 1460 |
+
"sql": {
|
| 1461 |
+
"columns": [
|
| 1462 |
+
{
|
| 1463 |
+
"parameters": [],
|
| 1464 |
+
"type": "function"
|
| 1465 |
+
}
|
| 1466 |
+
],
|
| 1467 |
+
"groupBy": [
|
| 1468 |
+
{
|
| 1469 |
+
"property": {
|
| 1470 |
+
"type": "string"
|
| 1471 |
+
},
|
| 1472 |
+
"type": "groupBy"
|
| 1473 |
+
}
|
| 1474 |
+
],
|
| 1475 |
+
"limit": 50
|
| 1476 |
+
}
|
| 1477 |
+
}
|
| 1478 |
+
],
|
| 1479 |
+
"title": "Fourth compile generate",
|
| 1480 |
+
"transformations": [
|
| 1481 |
+
{
|
| 1482 |
+
"id": "sortBy",
|
| 1483 |
+
"options": {
|
| 1484 |
+
"fields": {},
|
| 1485 |
+
"sort": [
|
| 1486 |
+
{
|
| 1487 |
+
"field": "time"
|
| 1488 |
+
}
|
| 1489 |
+
]
|
| 1490 |
+
}
|
| 1491 |
+
}
|
| 1492 |
+
],
|
| 1493 |
+
"transparent": true,
|
| 1494 |
+
"type": "barchart"
|
| 1495 |
+
},
|
| 1496 |
+
{
|
| 1497 |
+
"collapsed": true,
|
| 1498 |
+
"gridPos": {
|
| 1499 |
+
"h": 1,
|
| 1500 |
+
"w": 24,
|
| 1501 |
+
"x": 0,
|
| 1502 |
+
"y": 64
|
| 1503 |
+
},
|
| 1504 |
+
"id": 15,
|
| 1505 |
+
"panels": [
|
| 1506 |
+
{
|
| 1507 |
+
"datasource": {},
|
| 1508 |
+
"fieldConfig": {
|
| 1509 |
+
"defaults": {
|
| 1510 |
+
"color": {
|
| 1511 |
+
"mode": "palette-classic"
|
| 1512 |
+
},
|
| 1513 |
+
"custom": {
|
| 1514 |
+
"axisBorderShow": false,
|
| 1515 |
+
"axisCenteredZero": false,
|
| 1516 |
+
"axisColorMode": "text",
|
| 1517 |
+
"axisLabel": "",
|
| 1518 |
+
"axisPlacement": "auto",
|
| 1519 |
+
"barAlignment": 0,
|
| 1520 |
+
"barWidthFactor": 0.6,
|
| 1521 |
+
"drawStyle": "line",
|
| 1522 |
+
"fillOpacity": 0,
|
| 1523 |
+
"gradientMode": "none",
|
| 1524 |
+
"hideFrom": {
|
| 1525 |
+
"legend": false,
|
| 1526 |
+
"tooltip": false,
|
| 1527 |
+
"viz": false
|
| 1528 |
+
},
|
| 1529 |
+
"insertNulls": 60000,
|
| 1530 |
+
"lineInterpolation": "linear",
|
| 1531 |
+
"lineWidth": 1,
|
| 1532 |
+
"pointSize": 5,
|
| 1533 |
+
"scaleDistribution": {
|
| 1534 |
+
"type": "linear"
|
| 1535 |
+
},
|
| 1536 |
+
"showPoints": "auto",
|
| 1537 |
+
"spanNulls": false,
|
| 1538 |
+
"stacking": {
|
| 1539 |
+
"group": "A",
|
| 1540 |
+
"mode": "none"
|
| 1541 |
+
},
|
| 1542 |
+
"thresholdsStyle": {
|
| 1543 |
+
"mode": "off"
|
| 1544 |
+
}
|
| 1545 |
+
},
|
| 1546 |
+
"mappings": [],
|
| 1547 |
+
"thresholds": {
|
| 1548 |
+
"mode": "absolute",
|
| 1549 |
+
"steps": [
|
| 1550 |
+
{
|
| 1551 |
+
"color": "green"
|
| 1552 |
+
},
|
| 1553 |
+
{
|
| 1554 |
+
"color": "red",
|
| 1555 |
+
"value": 80
|
| 1556 |
+
}
|
| 1557 |
+
]
|
| 1558 |
+
},
|
| 1559 |
+
"unit": "percent"
|
| 1560 |
+
},
|
| 1561 |
+
"overrides": []
|
| 1562 |
+
},
|
| 1563 |
+
"gridPos": {
|
| 1564 |
+
"h": 9,
|
| 1565 |
+
"w": 12,
|
| 1566 |
+
"x": 0,
|
| 1567 |
+
"y": 65
|
| 1568 |
+
},
|
| 1569 |
+
"id": 1,
|
| 1570 |
+
"options": {
|
| 1571 |
+
"legend": {
|
| 1572 |
+
"calcs": [],
|
| 1573 |
+
"displayMode": "list",
|
| 1574 |
+
"placement": "bottom",
|
| 1575 |
+
"showLegend": true
|
| 1576 |
+
},
|
| 1577 |
+
"tooltip": {
|
| 1578 |
+
"mode": "single",
|
| 1579 |
+
"sort": "none"
|
| 1580 |
+
}
|
| 1581 |
+
},
|
| 1582 |
+
"targets": [
|
| 1583 |
+
{
|
| 1584 |
+
"datasource": {
|
| 1585 |
+
"default": true,
|
| 1586 |
+
"type": "grafana-postgresql-datasource",
|
| 1587 |
+
"uid": "be28nkzirtb0gd"
|
| 1588 |
+
},
|
| 1589 |
+
"editorMode": "code",
|
| 1590 |
+
"format": "table",
|
| 1591 |
+
"rawQuery": true,
|
| 1592 |
+
"rawSql": "SELECT\n d.cpu_util,\n d.time\nFROM\n benchmarks AS b\n JOIN device_measurements AS d ON b.benchmark_id = d.benchmark_id\nWHERE\n branch = '${branch}';",
|
| 1593 |
+
"refId": "A",
|
| 1594 |
+
"sql": {
|
| 1595 |
+
"columns": [
|
| 1596 |
+
{
|
| 1597 |
+
"parameters": [
|
| 1598 |
+
{
|
| 1599 |
+
"name": "cpu_util",
|
| 1600 |
+
"type": "functionParameter"
|
| 1601 |
+
}
|
| 1602 |
+
],
|
| 1603 |
+
"type": "function"
|
| 1604 |
+
},
|
| 1605 |
+
{
|
| 1606 |
+
"parameters": [
|
| 1607 |
+
{
|
| 1608 |
+
"name": "mem_megabytes",
|
| 1609 |
+
"type": "functionParameter"
|
| 1610 |
+
}
|
| 1611 |
+
],
|
| 1612 |
+
"type": "function"
|
| 1613 |
+
},
|
| 1614 |
+
{
|
| 1615 |
+
"parameters": [
|
| 1616 |
+
{
|
| 1617 |
+
"name": "gpu_util",
|
| 1618 |
+
"type": "functionParameter"
|
| 1619 |
+
}
|
| 1620 |
+
],
|
| 1621 |
+
"type": "function"
|
| 1622 |
+
},
|
| 1623 |
+
{
|
| 1624 |
+
"parameters": [
|
| 1625 |
+
{
|
| 1626 |
+
"name": "gpu_mem_megabytes",
|
| 1627 |
+
"type": "functionParameter"
|
| 1628 |
+
}
|
| 1629 |
+
],
|
| 1630 |
+
"type": "function"
|
| 1631 |
+
},
|
| 1632 |
+
{
|
| 1633 |
+
"parameters": [
|
| 1634 |
+
{
|
| 1635 |
+
"name": "\"time\"",
|
| 1636 |
+
"type": "functionParameter"
|
| 1637 |
+
}
|
| 1638 |
+
],
|
| 1639 |
+
"type": "function"
|
| 1640 |
+
}
|
| 1641 |
+
],
|
| 1642 |
+
"groupBy": [
|
| 1643 |
+
{
|
| 1644 |
+
"property": {
|
| 1645 |
+
"type": "string"
|
| 1646 |
+
},
|
| 1647 |
+
"type": "groupBy"
|
| 1648 |
+
}
|
| 1649 |
+
],
|
| 1650 |
+
"limit": 50,
|
| 1651 |
+
"whereJsonTree": {
|
| 1652 |
+
"children1": [
|
| 1653 |
+
{
|
| 1654 |
+
"id": "baa888b8-89ab-4cde-b012-31922f8671e9",
|
| 1655 |
+
"properties": {
|
| 1656 |
+
"field": "commit_id",
|
| 1657 |
+
"fieldSrc": "field",
|
| 1658 |
+
"operator": "equal",
|
| 1659 |
+
"value": [
|
| 1660 |
+
"${commit}"
|
| 1661 |
+
],
|
| 1662 |
+
"valueError": [
|
| 1663 |
+
null
|
| 1664 |
+
],
|
| 1665 |
+
"valueSrc": [
|
| 1666 |
+
"value"
|
| 1667 |
+
],
|
| 1668 |
+
"valueType": [
|
| 1669 |
+
"text"
|
| 1670 |
+
]
|
| 1671 |
+
},
|
| 1672 |
+
"type": "rule"
|
| 1673 |
+
}
|
| 1674 |
+
],
|
| 1675 |
+
"id": "bab88a98-0123-4456-b89a-b1922f7d4f11",
|
| 1676 |
+
"type": "group"
|
| 1677 |
+
},
|
| 1678 |
+
"whereString": "commit_id = '${commit}'"
|
| 1679 |
+
},
|
| 1680 |
+
"table": "measurements"
|
| 1681 |
+
}
|
| 1682 |
+
],
|
| 1683 |
+
"title": "CPU Utilization",
|
| 1684 |
+
"transparent": true,
|
| 1685 |
+
"type": "timeseries"
|
| 1686 |
+
},
|
| 1687 |
+
{
|
| 1688 |
+
"datasource": {},
|
| 1689 |
+
"fieldConfig": {
|
| 1690 |
+
"defaults": {
|
| 1691 |
+
"color": {
|
| 1692 |
+
"mode": "palette-classic"
|
| 1693 |
+
},
|
| 1694 |
+
"custom": {
|
| 1695 |
+
"axisBorderShow": false,
|
| 1696 |
+
"axisCenteredZero": false,
|
| 1697 |
+
"axisColorMode": "text",
|
| 1698 |
+
"axisLabel": "",
|
| 1699 |
+
"axisPlacement": "auto",
|
| 1700 |
+
"barAlignment": 0,
|
| 1701 |
+
"barWidthFactor": 0.6,
|
| 1702 |
+
"drawStyle": "line",
|
| 1703 |
+
"fillOpacity": 0,
|
| 1704 |
+
"gradientMode": "none",
|
| 1705 |
+
"hideFrom": {
|
| 1706 |
+
"legend": false,
|
| 1707 |
+
"tooltip": false,
|
| 1708 |
+
"viz": false
|
| 1709 |
+
},
|
| 1710 |
+
"insertNulls": 60000,
|
| 1711 |
+
"lineInterpolation": "linear",
|
| 1712 |
+
"lineWidth": 1,
|
| 1713 |
+
"pointSize": 5,
|
| 1714 |
+
"scaleDistribution": {
|
| 1715 |
+
"type": "linear"
|
| 1716 |
+
},
|
| 1717 |
+
"showPoints": "auto",
|
| 1718 |
+
"spanNulls": false,
|
| 1719 |
+
"stacking": {
|
| 1720 |
+
"group": "A",
|
| 1721 |
+
"mode": "none"
|
| 1722 |
+
},
|
| 1723 |
+
"thresholdsStyle": {
|
| 1724 |
+
"mode": "off"
|
| 1725 |
+
}
|
| 1726 |
+
},
|
| 1727 |
+
"mappings": [],
|
| 1728 |
+
"thresholds": {
|
| 1729 |
+
"mode": "absolute",
|
| 1730 |
+
"steps": [
|
| 1731 |
+
{
|
| 1732 |
+
"color": "green"
|
| 1733 |
+
},
|
| 1734 |
+
{
|
| 1735 |
+
"color": "red",
|
| 1736 |
+
"value": 80
|
| 1737 |
+
}
|
| 1738 |
+
]
|
| 1739 |
+
},
|
| 1740 |
+
"unit": "percent"
|
| 1741 |
+
},
|
| 1742 |
+
"overrides": []
|
| 1743 |
+
},
|
| 1744 |
+
"gridPos": {
|
| 1745 |
+
"h": 9,
|
| 1746 |
+
"w": 12,
|
| 1747 |
+
"x": 12,
|
| 1748 |
+
"y": 65
|
| 1749 |
+
},
|
| 1750 |
+
"id": 4,
|
| 1751 |
+
"options": {
|
| 1752 |
+
"legend": {
|
| 1753 |
+
"calcs": [],
|
| 1754 |
+
"displayMode": "list",
|
| 1755 |
+
"placement": "bottom",
|
| 1756 |
+
"showLegend": true
|
| 1757 |
+
},
|
| 1758 |
+
"tooltip": {
|
| 1759 |
+
"mode": "single",
|
| 1760 |
+
"sort": "none"
|
| 1761 |
+
}
|
| 1762 |
+
},
|
| 1763 |
+
"targets": [
|
| 1764 |
+
{
|
| 1765 |
+
"datasource": {
|
| 1766 |
+
"default": true,
|
| 1767 |
+
"type": "grafana-postgresql-datasource",
|
| 1768 |
+
"uid": "be28nkzirtb0gd"
|
| 1769 |
+
},
|
| 1770 |
+
"editorMode": "code",
|
| 1771 |
+
"format": "table",
|
| 1772 |
+
"rawQuery": true,
|
| 1773 |
+
"rawSql": "SELECT\n b.commit_id,\n d.gpu_util,\n d.time\nFROM\n benchmarks AS b\n JOIN device_measurements AS d ON b.benchmark_id = d.benchmark_id\nWHERE\n branch = '${branch}';",
|
| 1774 |
+
"refId": "A",
|
| 1775 |
+
"sql": {
|
| 1776 |
+
"columns": [
|
| 1777 |
+
{
|
| 1778 |
+
"parameters": [
|
| 1779 |
+
{
|
| 1780 |
+
"name": "cpu_util",
|
| 1781 |
+
"type": "functionParameter"
|
| 1782 |
+
}
|
| 1783 |
+
],
|
| 1784 |
+
"type": "function"
|
| 1785 |
+
},
|
| 1786 |
+
{
|
| 1787 |
+
"parameters": [
|
| 1788 |
+
{
|
| 1789 |
+
"name": "mem_megabytes",
|
| 1790 |
+
"type": "functionParameter"
|
| 1791 |
+
}
|
| 1792 |
+
],
|
| 1793 |
+
"type": "function"
|
| 1794 |
+
},
|
| 1795 |
+
{
|
| 1796 |
+
"parameters": [
|
| 1797 |
+
{
|
| 1798 |
+
"name": "gpu_util",
|
| 1799 |
+
"type": "functionParameter"
|
| 1800 |
+
}
|
| 1801 |
+
],
|
| 1802 |
+
"type": "function"
|
| 1803 |
+
},
|
| 1804 |
+
{
|
| 1805 |
+
"parameters": [
|
| 1806 |
+
{
|
| 1807 |
+
"name": "gpu_mem_megabytes",
|
| 1808 |
+
"type": "functionParameter"
|
| 1809 |
+
}
|
| 1810 |
+
],
|
| 1811 |
+
"type": "function"
|
| 1812 |
+
},
|
| 1813 |
+
{
|
| 1814 |
+
"parameters": [
|
| 1815 |
+
{
|
| 1816 |
+
"name": "\"time\"",
|
| 1817 |
+
"type": "functionParameter"
|
| 1818 |
+
}
|
| 1819 |
+
],
|
| 1820 |
+
"type": "function"
|
| 1821 |
+
}
|
| 1822 |
+
],
|
| 1823 |
+
"groupBy": [
|
| 1824 |
+
{
|
| 1825 |
+
"property": {
|
| 1826 |
+
"type": "string"
|
| 1827 |
+
},
|
| 1828 |
+
"type": "groupBy"
|
| 1829 |
+
}
|
| 1830 |
+
],
|
| 1831 |
+
"limit": 50,
|
| 1832 |
+
"whereJsonTree": {
|
| 1833 |
+
"children1": [
|
| 1834 |
+
{
|
| 1835 |
+
"id": "baa888b8-89ab-4cde-b012-31922f8671e9",
|
| 1836 |
+
"properties": {
|
| 1837 |
+
"field": "commit_id",
|
| 1838 |
+
"fieldSrc": "field",
|
| 1839 |
+
"operator": "equal",
|
| 1840 |
+
"value": [
|
| 1841 |
+
"${commit}"
|
| 1842 |
+
],
|
| 1843 |
+
"valueError": [
|
| 1844 |
+
null
|
| 1845 |
+
],
|
| 1846 |
+
"valueSrc": [
|
| 1847 |
+
"value"
|
| 1848 |
+
],
|
| 1849 |
+
"valueType": [
|
| 1850 |
+
"text"
|
| 1851 |
+
]
|
| 1852 |
+
},
|
| 1853 |
+
"type": "rule"
|
| 1854 |
+
}
|
| 1855 |
+
],
|
| 1856 |
+
"id": "bab88a98-0123-4456-b89a-b1922f7d4f11",
|
| 1857 |
+
"type": "group"
|
| 1858 |
+
},
|
| 1859 |
+
"whereString": "commit_id = '${commit}'"
|
| 1860 |
+
},
|
| 1861 |
+
"table": "measurements"
|
| 1862 |
+
}
|
| 1863 |
+
],
|
| 1864 |
+
"title": "GPU Utilization",
|
| 1865 |
+
"transparent": true,
|
| 1866 |
+
"type": "timeseries"
|
| 1867 |
+
},
|
| 1868 |
+
{
|
| 1869 |
+
"datasource": {},
|
| 1870 |
+
"fieldConfig": {
|
| 1871 |
+
"defaults": {
|
| 1872 |
+
"color": {
|
| 1873 |
+
"mode": "palette-classic"
|
| 1874 |
+
},
|
| 1875 |
+
"custom": {
|
| 1876 |
+
"axisBorderShow": false,
|
| 1877 |
+
"axisCenteredZero": false,
|
| 1878 |
+
"axisColorMode": "text",
|
| 1879 |
+
"axisLabel": "",
|
| 1880 |
+
"axisPlacement": "auto",
|
| 1881 |
+
"barAlignment": 0,
|
| 1882 |
+
"barWidthFactor": 0.6,
|
| 1883 |
+
"drawStyle": "line",
|
| 1884 |
+
"fillOpacity": 0,
|
| 1885 |
+
"gradientMode": "none",
|
| 1886 |
+
"hideFrom": {
|
| 1887 |
+
"legend": false,
|
| 1888 |
+
"tooltip": false,
|
| 1889 |
+
"viz": false
|
| 1890 |
+
},
|
| 1891 |
+
"insertNulls": 60000,
|
| 1892 |
+
"lineInterpolation": "linear",
|
| 1893 |
+
"lineWidth": 1,
|
| 1894 |
+
"pointSize": 5,
|
| 1895 |
+
"scaleDistribution": {
|
| 1896 |
+
"type": "linear"
|
| 1897 |
+
},
|
| 1898 |
+
"showPoints": "auto",
|
| 1899 |
+
"spanNulls": false,
|
| 1900 |
+
"stacking": {
|
| 1901 |
+
"group": "A",
|
| 1902 |
+
"mode": "none"
|
| 1903 |
+
},
|
| 1904 |
+
"thresholdsStyle": {
|
| 1905 |
+
"mode": "off"
|
| 1906 |
+
}
|
| 1907 |
+
},
|
| 1908 |
+
"mappings": [],
|
| 1909 |
+
"thresholds": {
|
| 1910 |
+
"mode": "absolute",
|
| 1911 |
+
"steps": [
|
| 1912 |
+
{
|
| 1913 |
+
"color": "green"
|
| 1914 |
+
},
|
| 1915 |
+
{
|
| 1916 |
+
"color": "red",
|
| 1917 |
+
"value": 80
|
| 1918 |
+
}
|
| 1919 |
+
]
|
| 1920 |
+
},
|
| 1921 |
+
"unit": "decmbytes"
|
| 1922 |
+
},
|
| 1923 |
+
"overrides": []
|
| 1924 |
+
},
|
| 1925 |
+
"gridPos": {
|
| 1926 |
+
"h": 9,
|
| 1927 |
+
"w": 12,
|
| 1928 |
+
"x": 0,
|
| 1929 |
+
"y": 74
|
| 1930 |
+
},
|
| 1931 |
+
"id": 2,
|
| 1932 |
+
"options": {
|
| 1933 |
+
"legend": {
|
| 1934 |
+
"calcs": [],
|
| 1935 |
+
"displayMode": "list",
|
| 1936 |
+
"placement": "bottom",
|
| 1937 |
+
"showLegend": true
|
| 1938 |
+
},
|
| 1939 |
+
"tooltip": {
|
| 1940 |
+
"mode": "single",
|
| 1941 |
+
"sort": "none"
|
| 1942 |
+
}
|
| 1943 |
+
},
|
| 1944 |
+
"targets": [
|
| 1945 |
+
{
|
| 1946 |
+
"datasource": {
|
| 1947 |
+
"default": true,
|
| 1948 |
+
"type": "grafana-postgresql-datasource",
|
| 1949 |
+
"uid": "be28nkzirtb0gd"
|
| 1950 |
+
},
|
| 1951 |
+
"editorMode": "code",
|
| 1952 |
+
"format": "table",
|
| 1953 |
+
"rawQuery": true,
|
| 1954 |
+
"rawSql": "SELECT d.mem_megabytes, d.time FROM benchmarks AS b JOIN device_measurements AS d ON b.benchmark_id = d.benchmark_id WHERE branch = '${branch}';",
|
| 1955 |
+
"refId": "A",
|
| 1956 |
+
"sql": {
|
| 1957 |
+
"columns": [
|
| 1958 |
+
{
|
| 1959 |
+
"parameters": [
|
| 1960 |
+
{
|
| 1961 |
+
"name": "cpu_util",
|
| 1962 |
+
"type": "functionParameter"
|
| 1963 |
+
}
|
| 1964 |
+
],
|
| 1965 |
+
"type": "function"
|
| 1966 |
+
},
|
| 1967 |
+
{
|
| 1968 |
+
"parameters": [
|
| 1969 |
+
{
|
| 1970 |
+
"name": "mem_megabytes",
|
| 1971 |
+
"type": "functionParameter"
|
| 1972 |
+
}
|
| 1973 |
+
],
|
| 1974 |
+
"type": "function"
|
| 1975 |
+
},
|
| 1976 |
+
{
|
| 1977 |
+
"parameters": [
|
| 1978 |
+
{
|
| 1979 |
+
"name": "gpu_util",
|
| 1980 |
+
"type": "functionParameter"
|
| 1981 |
+
}
|
| 1982 |
+
],
|
| 1983 |
+
"type": "function"
|
| 1984 |
+
},
|
| 1985 |
+
{
|
| 1986 |
+
"parameters": [
|
| 1987 |
+
{
|
| 1988 |
+
"name": "gpu_mem_megabytes",
|
| 1989 |
+
"type": "functionParameter"
|
| 1990 |
+
}
|
| 1991 |
+
],
|
| 1992 |
+
"type": "function"
|
| 1993 |
+
},
|
| 1994 |
+
{
|
| 1995 |
+
"parameters": [
|
| 1996 |
+
{
|
| 1997 |
+
"name": "\"time\"",
|
| 1998 |
+
"type": "functionParameter"
|
| 1999 |
+
}
|
| 2000 |
+
],
|
| 2001 |
+
"type": "function"
|
| 2002 |
+
}
|
| 2003 |
+
],
|
| 2004 |
+
"groupBy": [
|
| 2005 |
+
{
|
| 2006 |
+
"property": {
|
| 2007 |
+
"type": "string"
|
| 2008 |
+
},
|
| 2009 |
+
"type": "groupBy"
|
| 2010 |
+
}
|
| 2011 |
+
],
|
| 2012 |
+
"limit": 50,
|
| 2013 |
+
"whereJsonTree": {
|
| 2014 |
+
"children1": [
|
| 2015 |
+
{
|
| 2016 |
+
"id": "baa888b8-89ab-4cde-b012-31922f8671e9",
|
| 2017 |
+
"properties": {
|
| 2018 |
+
"field": "commit_id",
|
| 2019 |
+
"fieldSrc": "field",
|
| 2020 |
+
"operator": "equal",
|
| 2021 |
+
"value": [
|
| 2022 |
+
"${commit}"
|
| 2023 |
+
],
|
| 2024 |
+
"valueError": [
|
| 2025 |
+
null
|
| 2026 |
+
],
|
| 2027 |
+
"valueSrc": [
|
| 2028 |
+
"value"
|
| 2029 |
+
],
|
| 2030 |
+
"valueType": [
|
| 2031 |
+
"text"
|
| 2032 |
+
]
|
| 2033 |
+
},
|
| 2034 |
+
"type": "rule"
|
| 2035 |
+
}
|
| 2036 |
+
],
|
| 2037 |
+
"id": "bab88a98-0123-4456-b89a-b1922f7d4f11",
|
| 2038 |
+
"type": "group"
|
| 2039 |
+
},
|
| 2040 |
+
"whereString": "commit_id = '${commit}'"
|
| 2041 |
+
},
|
| 2042 |
+
"table": "measurements"
|
| 2043 |
+
}
|
| 2044 |
+
],
|
| 2045 |
+
"title": "Memory usage",
|
| 2046 |
+
"transparent": true,
|
| 2047 |
+
"type": "timeseries"
|
| 2048 |
+
},
|
| 2049 |
+
{
|
| 2050 |
+
"datasource": {},
|
| 2051 |
+
"fieldConfig": {
|
| 2052 |
+
"defaults": {
|
| 2053 |
+
"color": {
|
| 2054 |
+
"mode": "palette-classic"
|
| 2055 |
+
},
|
| 2056 |
+
"custom": {
|
| 2057 |
+
"axisBorderShow": false,
|
| 2058 |
+
"axisCenteredZero": false,
|
| 2059 |
+
"axisColorMode": "text",
|
| 2060 |
+
"axisLabel": "",
|
| 2061 |
+
"axisPlacement": "auto",
|
| 2062 |
+
"barAlignment": 0,
|
| 2063 |
+
"barWidthFactor": 0.6,
|
| 2064 |
+
"drawStyle": "line",
|
| 2065 |
+
"fillOpacity": 0,
|
| 2066 |
+
"gradientMode": "none",
|
| 2067 |
+
"hideFrom": {
|
| 2068 |
+
"legend": false,
|
| 2069 |
+
"tooltip": false,
|
| 2070 |
+
"viz": false
|
| 2071 |
+
},
|
| 2072 |
+
"insertNulls": 60000,
|
| 2073 |
+
"lineInterpolation": "linear",
|
| 2074 |
+
"lineWidth": 1,
|
| 2075 |
+
"pointSize": 5,
|
| 2076 |
+
"scaleDistribution": {
|
| 2077 |
+
"type": "linear"
|
| 2078 |
+
},
|
| 2079 |
+
"showPoints": "auto",
|
| 2080 |
+
"spanNulls": false,
|
| 2081 |
+
"stacking": {
|
| 2082 |
+
"group": "A",
|
| 2083 |
+
"mode": "none"
|
| 2084 |
+
},
|
| 2085 |
+
"thresholdsStyle": {
|
| 2086 |
+
"mode": "off"
|
| 2087 |
+
}
|
| 2088 |
+
},
|
| 2089 |
+
"mappings": [],
|
| 2090 |
+
"thresholds": {
|
| 2091 |
+
"mode": "absolute",
|
| 2092 |
+
"steps": [
|
| 2093 |
+
{
|
| 2094 |
+
"color": "green"
|
| 2095 |
+
},
|
| 2096 |
+
{
|
| 2097 |
+
"color": "red",
|
| 2098 |
+
"value": 80
|
| 2099 |
+
}
|
| 2100 |
+
]
|
| 2101 |
+
},
|
| 2102 |
+
"unit": "decmbytes"
|
| 2103 |
+
},
|
| 2104 |
+
"overrides": []
|
| 2105 |
+
},
|
| 2106 |
+
"gridPos": {
|
| 2107 |
+
"h": 9,
|
| 2108 |
+
"w": 12,
|
| 2109 |
+
"x": 12,
|
| 2110 |
+
"y": 74
|
| 2111 |
+
},
|
| 2112 |
+
"id": 3,
|
| 2113 |
+
"options": {
|
| 2114 |
+
"legend": {
|
| 2115 |
+
"calcs": [],
|
| 2116 |
+
"displayMode": "list",
|
| 2117 |
+
"placement": "bottom",
|
| 2118 |
+
"showLegend": true
|
| 2119 |
+
},
|
| 2120 |
+
"tooltip": {
|
| 2121 |
+
"mode": "single",
|
| 2122 |
+
"sort": "none"
|
| 2123 |
+
}
|
| 2124 |
+
},
|
| 2125 |
+
"targets": [
|
| 2126 |
+
{
|
| 2127 |
+
"datasource": {
|
| 2128 |
+
"default": true,
|
| 2129 |
+
"type": "grafana-postgresql-datasource",
|
| 2130 |
+
"uid": "be28nkzirtb0gd"
|
| 2131 |
+
},
|
| 2132 |
+
"editorMode": "code",
|
| 2133 |
+
"format": "table",
|
| 2134 |
+
"rawQuery": true,
|
| 2135 |
+
"rawSql": "SELECT\n d.gpu_mem_megabytes,\n d.time\nFROM\n benchmarks AS b\n JOIN device_measurements AS d ON b.benchmark_id = d.benchmark_id\nWHERE\n branch = '${branch}';",
|
| 2136 |
+
"refId": "A",
|
| 2137 |
+
"sql": {
|
| 2138 |
+
"columns": [
|
| 2139 |
+
{
|
| 2140 |
+
"parameters": [
|
| 2141 |
+
{
|
| 2142 |
+
"name": "cpu_util",
|
| 2143 |
+
"type": "functionParameter"
|
| 2144 |
+
}
|
| 2145 |
+
],
|
| 2146 |
+
"type": "function"
|
| 2147 |
+
},
|
| 2148 |
+
{
|
| 2149 |
+
"parameters": [
|
| 2150 |
+
{
|
| 2151 |
+
"name": "mem_megabytes",
|
| 2152 |
+
"type": "functionParameter"
|
| 2153 |
+
}
|
| 2154 |
+
],
|
| 2155 |
+
"type": "function"
|
| 2156 |
+
},
|
| 2157 |
+
{
|
| 2158 |
+
"parameters": [
|
| 2159 |
+
{
|
| 2160 |
+
"name": "gpu_util",
|
| 2161 |
+
"type": "functionParameter"
|
| 2162 |
+
}
|
| 2163 |
+
],
|
| 2164 |
+
"type": "function"
|
| 2165 |
+
},
|
| 2166 |
+
{
|
| 2167 |
+
"parameters": [
|
| 2168 |
+
{
|
| 2169 |
+
"name": "gpu_mem_megabytes",
|
| 2170 |
+
"type": "functionParameter"
|
| 2171 |
+
}
|
| 2172 |
+
],
|
| 2173 |
+
"type": "function"
|
| 2174 |
+
},
|
| 2175 |
+
{
|
| 2176 |
+
"parameters": [
|
| 2177 |
+
{
|
| 2178 |
+
"name": "\"time\"",
|
| 2179 |
+
"type": "functionParameter"
|
| 2180 |
+
}
|
| 2181 |
+
],
|
| 2182 |
+
"type": "function"
|
| 2183 |
+
}
|
| 2184 |
+
],
|
| 2185 |
+
"groupBy": [
|
| 2186 |
+
{
|
| 2187 |
+
"property": {
|
| 2188 |
+
"type": "string"
|
| 2189 |
+
},
|
| 2190 |
+
"type": "groupBy"
|
| 2191 |
+
}
|
| 2192 |
+
],
|
| 2193 |
+
"limit": 50,
|
| 2194 |
+
"whereJsonTree": {
|
| 2195 |
+
"children1": [
|
| 2196 |
+
{
|
| 2197 |
+
"id": "baa888b8-89ab-4cde-b012-31922f8671e9",
|
| 2198 |
+
"properties": {
|
| 2199 |
+
"field": "commit_id",
|
| 2200 |
+
"fieldSrc": "field",
|
| 2201 |
+
"operator": "equal",
|
| 2202 |
+
"value": [
|
| 2203 |
+
"${commit}"
|
| 2204 |
+
],
|
| 2205 |
+
"valueError": [
|
| 2206 |
+
null
|
| 2207 |
+
],
|
| 2208 |
+
"valueSrc": [
|
| 2209 |
+
"value"
|
| 2210 |
+
],
|
| 2211 |
+
"valueType": [
|
| 2212 |
+
"text"
|
| 2213 |
+
]
|
| 2214 |
+
},
|
| 2215 |
+
"type": "rule"
|
| 2216 |
+
}
|
| 2217 |
+
],
|
| 2218 |
+
"id": "bab88a98-0123-4456-b89a-b1922f7d4f11",
|
| 2219 |
+
"type": "group"
|
| 2220 |
+
},
|
| 2221 |
+
"whereString": "commit_id = '${commit}'"
|
| 2222 |
+
},
|
| 2223 |
+
"table": "measurements"
|
| 2224 |
+
}
|
| 2225 |
+
],
|
| 2226 |
+
"title": "GPU memory usage",
|
| 2227 |
+
"transparent": true,
|
| 2228 |
+
"type": "timeseries"
|
| 2229 |
+
}
|
| 2230 |
+
],
|
| 2231 |
+
"title": "Usage metrics",
|
| 2232 |
+
"type": "row"
|
| 2233 |
+
}
|
| 2234 |
+
],
|
| 2235 |
+
"schemaVersion": 39,
|
| 2236 |
+
"tags": [],
|
| 2237 |
+
"templating": {
|
| 2238 |
+
"list": [
|
| 2239 |
+
{
|
| 2240 |
+
"current": {
|
| 2241 |
+
"selected": false,
|
| 2242 |
+
"text": "main",
|
| 2243 |
+
"value": "main"
|
| 2244 |
+
},
|
| 2245 |
+
"datasource": {
|
| 2246 |
+
"default": true,
|
| 2247 |
+
"type": "grafana-postgresql-datasource",
|
| 2248 |
+
"uid": "be28nkzirtb0gd"
|
| 2249 |
+
},
|
| 2250 |
+
"definition": "SELECT DISTINCT branch FROM benchmarks;",
|
| 2251 |
+
"description": "",
|
| 2252 |
+
"hide": 0,
|
| 2253 |
+
"includeAll": false,
|
| 2254 |
+
"label": "branch",
|
| 2255 |
+
"multi": false,
|
| 2256 |
+
"name": "branch",
|
| 2257 |
+
"options": [],
|
| 2258 |
+
"query": "SELECT DISTINCT branch FROM benchmarks;",
|
| 2259 |
+
"refresh": 1,
|
| 2260 |
+
"regex": "",
|
| 2261 |
+
"skipUrlSync": false,
|
| 2262 |
+
"sort": 0,
|
| 2263 |
+
"type": "query"
|
| 2264 |
+
},
|
| 2265 |
+
{
|
| 2266 |
+
"current": {
|
| 2267 |
+
"selected": false,
|
| 2268 |
+
"text": "1729701492845",
|
| 2269 |
+
"value": "1729701492845"
|
| 2270 |
+
},
|
| 2271 |
+
"datasource": {
|
| 2272 |
+
"default": true,
|
| 2273 |
+
"type": "grafana-postgresql-datasource",
|
| 2274 |
+
"uid": "be28nkzirtb0gd"
|
| 2275 |
+
},
|
| 2276 |
+
"definition": "SELECT created_at - INTERVAL '5 secs' FROM benchmarks WHERE branch = '${branch}' ORDER BY benchmark_id ASC LIMIT 1;",
|
| 2277 |
+
"description": "",
|
| 2278 |
+
"hide": 2,
|
| 2279 |
+
"includeAll": false,
|
| 2280 |
+
"multi": false,
|
| 2281 |
+
"name": "StartTime",
|
| 2282 |
+
"options": [],
|
| 2283 |
+
"query": "SELECT created_at - INTERVAL '5 secs' FROM benchmarks WHERE branch = '${branch}' ORDER BY benchmark_id ASC LIMIT 1;",
|
| 2284 |
+
"refresh": 2,
|
| 2285 |
+
"regex": "",
|
| 2286 |
+
"skipUrlSync": false,
|
| 2287 |
+
"sort": 0,
|
| 2288 |
+
"type": "query"
|
| 2289 |
+
},
|
| 2290 |
+
{
|
| 2291 |
+
"current": {
|
| 2292 |
+
"selected": false,
|
| 2293 |
+
"text": "1730393397577",
|
| 2294 |
+
"value": "1730393397577"
|
| 2295 |
+
},
|
| 2296 |
+
"datasource": {
|
| 2297 |
+
"default": true,
|
| 2298 |
+
"type": "grafana-postgresql-datasource",
|
| 2299 |
+
"uid": "be28nkzirtb0gd"
|
| 2300 |
+
},
|
| 2301 |
+
"definition": "SELECT time + INTERVAL '5 secs' FROM benchmarks AS b JOIN device_measurements AS d ON b.benchmark_id = d.benchmark_id WHERE branch = '${branch}' ORDER BY b.benchmark_id DESC, d.measurement_id DESC LIMIT 1;",
|
| 2302 |
+
"description": "",
|
| 2303 |
+
"hide": 2,
|
| 2304 |
+
"includeAll": false,
|
| 2305 |
+
"multi": false,
|
| 2306 |
+
"name": "EndTime",
|
| 2307 |
+
"options": [],
|
| 2308 |
+
"query": "SELECT time + INTERVAL '5 secs' FROM benchmarks AS b JOIN device_measurements AS d ON b.benchmark_id = d.benchmark_id WHERE branch = '${branch}' ORDER BY b.benchmark_id DESC, d.measurement_id DESC LIMIT 1;",
|
| 2309 |
+
"refresh": 1,
|
| 2310 |
+
"regex": "",
|
| 2311 |
+
"skipUrlSync": false,
|
| 2312 |
+
"sort": 0,
|
| 2313 |
+
"type": "query"
|
| 2314 |
+
},
|
| 2315 |
+
{
|
| 2316 |
+
"current": {
|
| 2317 |
+
"selected": false,
|
| 2318 |
+
"text": "NVIDIA A10G",
|
| 2319 |
+
"value": "NVIDIA A10G"
|
| 2320 |
+
},
|
| 2321 |
+
"datasource": {
|
| 2322 |
+
"type": "grafana-postgresql-datasource",
|
| 2323 |
+
"uid": "be28nkzirtb0gd"
|
| 2324 |
+
},
|
| 2325 |
+
"definition": "SELECT DISTINCT metadata->>'gpu_name' FROM benchmarks;",
|
| 2326 |
+
"description": "",
|
| 2327 |
+
"hide": 0,
|
| 2328 |
+
"includeAll": false,
|
| 2329 |
+
"label": "GPU",
|
| 2330 |
+
"multi": false,
|
| 2331 |
+
"name": "gpu_name",
|
| 2332 |
+
"options": [],
|
| 2333 |
+
"query": "SELECT DISTINCT metadata->>'gpu_name' FROM benchmarks;",
|
| 2334 |
+
"refresh": 1,
|
| 2335 |
+
"regex": "",
|
| 2336 |
+
"skipUrlSync": false,
|
| 2337 |
+
"sort": 0,
|
| 2338 |
+
"type": "query"
|
| 2339 |
+
},
|
| 2340 |
+
{
|
| 2341 |
+
"current": {
|
| 2342 |
+
"selected": true,
|
| 2343 |
+
"text": "10",
|
| 2344 |
+
"value": "10"
|
| 2345 |
+
},
|
| 2346 |
+
"description": "The number of commits to display, going from most recent to the nth commit.",
|
| 2347 |
+
"hide": 0,
|
| 2348 |
+
"label": "Last # of commits",
|
| 2349 |
+
"name": "last_n_commits",
|
| 2350 |
+
"options": [
|
| 2351 |
+
{
|
| 2352 |
+
"selected": true,
|
| 2353 |
+
"text": "10",
|
| 2354 |
+
"value": "10"
|
| 2355 |
+
}
|
| 2356 |
+
],
|
| 2357 |
+
"query": "10",
|
| 2358 |
+
"skipUrlSync": false,
|
| 2359 |
+
"type": "textbox"
|
| 2360 |
+
}
|
| 2361 |
+
]
|
| 2362 |
+
},
|
| 2363 |
+
"time": {
|
| 2364 |
+
"from": "now-1h",
|
| 2365 |
+
"to": "now"
|
| 2366 |
+
},
|
| 2367 |
+
"timepicker": {
|
| 2368 |
+
"hidden": false
|
| 2369 |
+
},
|
| 2370 |
+
"timezone": "browser",
|
| 2371 |
+
"title": "Transformers benchmarks",
|
| 2372 |
+
"uid": "fdz33iyzln9c0a",
|
| 2373 |
+
"version": 10,
|
| 2374 |
+
"weekStart": ""
|
| 2375 |
+
}
|
tasks/tasksmith-441eeab80047/environment/source/benchmark/grafana_datasource.yaml
ADDED
|
@@ -0,0 +1,17 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
apiVersion: 1
|
| 2 |
+
datasources:
|
| 3 |
+
- name: grafana-postgresql-datasource
|
| 4 |
+
uid: be28nkzirtb0gd
|
| 5 |
+
type: postgres
|
| 6 |
+
url: $GRAFANA_POSTGRES_DATASOURCE_URL
|
| 7 |
+
user: $GRAFANA_POSTGRES_DATASOURCE_USER
|
| 8 |
+
secureJsonData:
|
| 9 |
+
password: $GRAFANA_POSTGRES_DATASOURCE_PWD
|
| 10 |
+
jsonData:
|
| 11 |
+
database: metrics
|
| 12 |
+
maxOpenConns: 100
|
| 13 |
+
maxIdleConns: 100
|
| 14 |
+
maxIdleConnsAuto: true
|
| 15 |
+
connMaxLifetime: 14400
|
| 16 |
+
postgresVersion: 1000
|
| 17 |
+
timescaledb: false
|
tasks/tasksmith-441eeab80047/environment/source/benchmark/init_db.sql
ADDED
|
@@ -0,0 +1,33 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
CREATE TABLE IF NOT EXISTS benchmarks (
|
| 2 |
+
benchmark_id SERIAL PRIMARY KEY,
|
| 3 |
+
branch VARCHAR(255),
|
| 4 |
+
commit_id VARCHAR(72),
|
| 5 |
+
commit_message VARCHAR(70),
|
| 6 |
+
metadata jsonb,
|
| 7 |
+
created_at timestamp without time zone NOT NULL DEFAULT (current_timestamp AT TIME ZONE 'UTC')
|
| 8 |
+
);
|
| 9 |
+
|
| 10 |
+
CREATE INDEX IF NOT EXISTS benchmarks_benchmark_id_idx ON benchmarks (benchmark_id);
|
| 11 |
+
|
| 12 |
+
CREATE INDEX IF NOT EXISTS benchmarks_branch_idx ON benchmarks (branch);
|
| 13 |
+
|
| 14 |
+
CREATE TABLE IF NOT EXISTS device_measurements (
|
| 15 |
+
measurement_id SERIAL PRIMARY KEY,
|
| 16 |
+
benchmark_id int REFERENCES benchmarks (benchmark_id),
|
| 17 |
+
cpu_util double precision,
|
| 18 |
+
mem_megabytes double precision,
|
| 19 |
+
gpu_util double precision,
|
| 20 |
+
gpu_mem_megabytes double precision,
|
| 21 |
+
time timestamp without time zone NOT NULL DEFAULT (current_timestamp AT TIME ZONE 'UTC')
|
| 22 |
+
);
|
| 23 |
+
|
| 24 |
+
CREATE INDEX IF NOT EXISTS device_measurements_branch_idx ON device_measurements (benchmark_id);
|
| 25 |
+
|
| 26 |
+
CREATE TABLE IF NOT EXISTS model_measurements (
|
| 27 |
+
measurement_id SERIAL PRIMARY KEY,
|
| 28 |
+
benchmark_id int REFERENCES benchmarks (benchmark_id),
|
| 29 |
+
measurements jsonb,
|
| 30 |
+
time timestamp without time zone NOT NULL DEFAULT (current_timestamp AT TIME ZONE 'UTC')
|
| 31 |
+
);
|
| 32 |
+
|
| 33 |
+
CREATE INDEX IF NOT EXISTS model_measurements_branch_idx ON model_measurements (benchmark_id);
|
tasks/tasksmith-441eeab80047/environment/source/benchmark/llama.py
ADDED
|
@@ -0,0 +1,342 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
from logging import Logger
|
| 2 |
+
import os
|
| 3 |
+
from threading import Event, Thread
|
| 4 |
+
from time import perf_counter, sleep
|
| 5 |
+
from typing import Optional
|
| 6 |
+
from benchmarks_entrypoint import MetricsRecorder
|
| 7 |
+
import gpustat
|
| 8 |
+
import psutil
|
| 9 |
+
import psycopg2
|
| 10 |
+
import torch
|
| 11 |
+
|
| 12 |
+
from transformers import AutoModelForCausalLM, AutoTokenizer, GenerationConfig, StaticCache
|
| 13 |
+
|
| 14 |
+
|
| 15 |
+
os.environ["HF_HUB_ENABLE_HF_TRANSFER"] = "1"
|
| 16 |
+
|
| 17 |
+
os.environ["TOKENIZERS_PARALLELISM"] = "1"
|
| 18 |
+
torch.set_float32_matmul_precision("high")
|
| 19 |
+
|
| 20 |
+
|
| 21 |
+
def collect_metrics(benchmark_id, continue_metric_collection, metrics_recorder):
|
| 22 |
+
p = psutil.Process(os.getpid())
|
| 23 |
+
while not continue_metric_collection.is_set():
|
| 24 |
+
with p.oneshot():
|
| 25 |
+
cpu_util = p.cpu_percent()
|
| 26 |
+
mem_megabytes = p.memory_info().rss / (1024 * 1024)
|
| 27 |
+
gpu_stats = gpustat.GPUStatCollection.new_query()
|
| 28 |
+
gpu_util = gpu_stats[0]["utilization.gpu"]
|
| 29 |
+
gpu_mem_megabytes = gpu_stats[0]["memory.used"]
|
| 30 |
+
metrics_recorder.collect_device_measurements(
|
| 31 |
+
benchmark_id, cpu_util, mem_megabytes, gpu_util, gpu_mem_megabytes
|
| 32 |
+
)
|
| 33 |
+
sleep(0.01)
|
| 34 |
+
|
| 35 |
+
|
| 36 |
+
def run_benchmark(logger: Logger, branch: str, commit_id: str, commit_msg: str, num_tokens_to_generate=100):
|
| 37 |
+
continue_metric_collection = Event()
|
| 38 |
+
metrics_thread = None
|
| 39 |
+
model_id = "meta-llama/Llama-2-7b-hf"
|
| 40 |
+
metrics_recorder = MetricsRecorder(psycopg2.connect("dbname=metrics"), logger, branch, commit_id, commit_msg)
|
| 41 |
+
try:
|
| 42 |
+
gpu_stats = gpustat.GPUStatCollection.new_query()
|
| 43 |
+
gpu_name = gpu_stats[0]["name"]
|
| 44 |
+
benchmark_id = metrics_recorder.initialise_benchmark({"gpu_name": gpu_name, "model_id": model_id})
|
| 45 |
+
logger.info(f"running benchmark #{benchmark_id} on {gpu_name} for {model_id}")
|
| 46 |
+
metrics_thread = Thread(
|
| 47 |
+
target=collect_metrics,
|
| 48 |
+
args=[benchmark_id, continue_metric_collection, metrics_recorder],
|
| 49 |
+
)
|
| 50 |
+
metrics_thread.start()
|
| 51 |
+
logger.info("started background thread to fetch device metrics")
|
| 52 |
+
|
| 53 |
+
os.environ["TOKENIZERS_PARALLELISM"] = "false" # silence warnings when compiling
|
| 54 |
+
|
| 55 |
+
device = "cuda"
|
| 56 |
+
|
| 57 |
+
logger.info("downloading weights")
|
| 58 |
+
# This is to avoid counting download in model load time measurement
|
| 59 |
+
model = AutoModelForCausalLM.from_pretrained(model_id, torch_dtype=torch.float16)
|
| 60 |
+
gen_config = GenerationConfig(do_sample=False, top_p=1, temperature=1)
|
| 61 |
+
logger.info("loading model")
|
| 62 |
+
start = perf_counter()
|
| 63 |
+
model = AutoModelForCausalLM.from_pretrained(
|
| 64 |
+
model_id, torch_dtype=torch.float16, generation_config=gen_config
|
| 65 |
+
).eval()
|
| 66 |
+
model.to(device)
|
| 67 |
+
torch.cuda.synchronize()
|
| 68 |
+
end = perf_counter()
|
| 69 |
+
model_load_time = end - start
|
| 70 |
+
logger.info(f"loaded model in: {model_load_time}s")
|
| 71 |
+
|
| 72 |
+
tokenizer = AutoTokenizer.from_pretrained(model_id)
|
| 73 |
+
|
| 74 |
+
prompt = "Why dogs are so cute?"
|
| 75 |
+
inputs = tokenizer(prompt, return_tensors="pt").to(device)
|
| 76 |
+
|
| 77 |
+
# Specify the max length (including both the prompt and the response)
|
| 78 |
+
# When calling `generate` with `cache_implementation="static" later, this is also used to create a `StaticCache` object
|
| 79 |
+
# with sequence length = `max_length`. The longer the more you will re-use it
|
| 80 |
+
seq_length = inputs["input_ids"].shape[1]
|
| 81 |
+
model.generation_config.max_length = seq_length + num_tokens_to_generate
|
| 82 |
+
batch_size = inputs["input_ids"].shape[0]
|
| 83 |
+
|
| 84 |
+
# Copied from the gpt-fast repo
|
| 85 |
+
def multinomial_sample_one_no_sync(probs_sort): # Does multinomial sampling without a cuda synchronization
|
| 86 |
+
q = torch.empty_like(probs_sort).exponential_(1)
|
| 87 |
+
return torch.argmax(probs_sort / q, dim=-1, keepdim=True).to(dtype=torch.int)
|
| 88 |
+
|
| 89 |
+
def logits_to_probs(logits, temperature: float = 1.0, top_k: Optional[int] = None):
|
| 90 |
+
logits = logits / max(temperature, 1e-5)
|
| 91 |
+
|
| 92 |
+
if top_k is not None:
|
| 93 |
+
v, _ = torch.topk(logits, min(top_k, logits.size(-1)))
|
| 94 |
+
pivot = v.select(-1, -1).unsqueeze(-1)
|
| 95 |
+
logits = torch.where(logits < pivot, -float("Inf"), logits)
|
| 96 |
+
probs = torch.nn.functional.softmax(logits, dim=-1)
|
| 97 |
+
return probs
|
| 98 |
+
|
| 99 |
+
def sample(logits, temperature: float = 1.0, top_k: Optional[int] = None):
|
| 100 |
+
probs = logits_to_probs(logits[:, -1], temperature, top_k)
|
| 101 |
+
idx_next = multinomial_sample_one_no_sync(probs)
|
| 102 |
+
return idx_next, probs
|
| 103 |
+
|
| 104 |
+
def decode_one_token(model, cur_token, cache_position, past_key_values):
|
| 105 |
+
logits = model(
|
| 106 |
+
cur_token,
|
| 107 |
+
cache_position=cache_position,
|
| 108 |
+
past_key_values=past_key_values,
|
| 109 |
+
return_dict=False,
|
| 110 |
+
use_cache=True,
|
| 111 |
+
)[0]
|
| 112 |
+
new_token = sample(logits, temperature=0.6, top_k=5)[0]
|
| 113 |
+
return new_token
|
| 114 |
+
|
| 115 |
+
#########
|
| 116 |
+
# Eager #
|
| 117 |
+
#########
|
| 118 |
+
with torch.no_grad():
|
| 119 |
+
past_key_values = StaticCache(
|
| 120 |
+
model.config,
|
| 121 |
+
batch_size=batch_size,
|
| 122 |
+
device=device,
|
| 123 |
+
dtype=torch.float16,
|
| 124 |
+
max_cache_len=seq_length + num_tokens_to_generate,
|
| 125 |
+
)
|
| 126 |
+
cache_position = torch.arange(seq_length, device=device)
|
| 127 |
+
start = perf_counter()
|
| 128 |
+
model(
|
| 129 |
+
**inputs,
|
| 130 |
+
cache_position=cache_position,
|
| 131 |
+
past_key_values=past_key_values,
|
| 132 |
+
return_dict=False,
|
| 133 |
+
use_cache=True,
|
| 134 |
+
)
|
| 135 |
+
end = perf_counter()
|
| 136 |
+
first_eager_fwd_pass_time = end - start
|
| 137 |
+
logger.info(f"completed first eager fwd pass in: {first_eager_fwd_pass_time}s")
|
| 138 |
+
start = perf_counter()
|
| 139 |
+
output = model.generate(**inputs, do_sample=False)
|
| 140 |
+
end = perf_counter()
|
| 141 |
+
first_eager_generate_time = end - start
|
| 142 |
+
logger.info(f"completed first eager generation in: {first_eager_generate_time}s")
|
| 143 |
+
logger.info(f"generated: {tokenizer.batch_decode(output.cpu().tolist())}")
|
| 144 |
+
|
| 145 |
+
past_key_values = StaticCache(
|
| 146 |
+
model.config,
|
| 147 |
+
batch_size=batch_size,
|
| 148 |
+
device=device,
|
| 149 |
+
dtype=torch.float16,
|
| 150 |
+
max_cache_len=seq_length + num_tokens_to_generate,
|
| 151 |
+
)
|
| 152 |
+
cache_position = torch.arange(seq_length, device=device)
|
| 153 |
+
start = perf_counter()
|
| 154 |
+
model(
|
| 155 |
+
**inputs,
|
| 156 |
+
cache_position=cache_position,
|
| 157 |
+
past_key_values=past_key_values,
|
| 158 |
+
return_dict=False,
|
| 159 |
+
use_cache=True,
|
| 160 |
+
)
|
| 161 |
+
end = perf_counter()
|
| 162 |
+
second_eager_fwd_pass_time = end - start
|
| 163 |
+
logger.info(f"completed second eager fwd pass in: {second_eager_fwd_pass_time}s")
|
| 164 |
+
start = perf_counter()
|
| 165 |
+
model.generate(**inputs, do_sample=False)
|
| 166 |
+
end = perf_counter()
|
| 167 |
+
second_eager_generate_time = end - start
|
| 168 |
+
logger.info(f"completed second eager generation in: {second_eager_generate_time}s")
|
| 169 |
+
logger.info(f"generated: {tokenizer.batch_decode(output.cpu().tolist())}")
|
| 170 |
+
|
| 171 |
+
torch.compiler.reset()
|
| 172 |
+
|
| 173 |
+
################
|
| 174 |
+
# Forward pass #
|
| 175 |
+
################
|
| 176 |
+
|
| 177 |
+
# `torch.compile(model, ...)` is not recommended as you compile callbacks
|
| 178 |
+
# and full generate. We recommend compiling only the forward for now.
|
| 179 |
+
# "reduce-overhead" will use cudagraphs.
|
| 180 |
+
generated_ids = torch.zeros(
|
| 181 |
+
(batch_size, num_tokens_to_generate + seq_length), dtype=torch.int, device=device
|
| 182 |
+
)
|
| 183 |
+
|
| 184 |
+
generated_ids[:, :seq_length] = inputs["input_ids"]
|
| 185 |
+
decode_one_token = torch.compile(decode_one_token, mode="reduce-overhead", fullgraph=True)
|
| 186 |
+
# model.forward = torch.compile(model.forward, mode="reduce-overhead", fullgraph=True)
|
| 187 |
+
# TODO use decode_one_token(model, input_id.clone(), cache_position) for verification
|
| 188 |
+
past_key_values = StaticCache(
|
| 189 |
+
model.config,
|
| 190 |
+
batch_size=batch_size,
|
| 191 |
+
device=device,
|
| 192 |
+
dtype=torch.float16,
|
| 193 |
+
max_cache_len=seq_length + num_tokens_to_generate + 10,
|
| 194 |
+
)
|
| 195 |
+
cache_position = torch.arange(seq_length, device=device)
|
| 196 |
+
all_generated_tokens = []
|
| 197 |
+
### First compile, prefill
|
| 198 |
+
start = perf_counter()
|
| 199 |
+
next_token = decode_one_token(
|
| 200 |
+
model, inputs["input_ids"], cache_position=cache_position, past_key_values=past_key_values
|
| 201 |
+
)
|
| 202 |
+
torch.cuda.synchronize()
|
| 203 |
+
end = perf_counter()
|
| 204 |
+
time_to_first_token = end - start
|
| 205 |
+
logger.info(f"completed first compile generation in: {time_to_first_token}s")
|
| 206 |
+
cache_position += 1
|
| 207 |
+
all_generated_tokens += next_token.clone().detach().cpu().tolist()
|
| 208 |
+
|
| 209 |
+
cache_position = torch.tensor([seq_length], device=device)
|
| 210 |
+
### First compile, decoding
|
| 211 |
+
start = perf_counter()
|
| 212 |
+
next_token = decode_one_token(
|
| 213 |
+
model, next_token.clone(), cache_position=cache_position, past_key_values=past_key_values
|
| 214 |
+
)
|
| 215 |
+
torch.cuda.synchronize()
|
| 216 |
+
end = perf_counter()
|
| 217 |
+
time_to_second_token = end - start
|
| 218 |
+
logger.info(f"completed second compile generation in: {time_to_first_token}s")
|
| 219 |
+
cache_position += 1
|
| 220 |
+
all_generated_tokens += next_token.clone().detach().cpu().tolist()
|
| 221 |
+
|
| 222 |
+
### Second compile, decoding
|
| 223 |
+
start = perf_counter()
|
| 224 |
+
next_token = decode_one_token(
|
| 225 |
+
model, next_token.clone(), cache_position=cache_position, past_key_values=past_key_values
|
| 226 |
+
)
|
| 227 |
+
torch.cuda.synchronize()
|
| 228 |
+
end = perf_counter()
|
| 229 |
+
time_to_third_token = end - start
|
| 230 |
+
logger.info(f"completed third compile forward in: {time_to_first_token}s")
|
| 231 |
+
cache_position += 1
|
| 232 |
+
all_generated_tokens += next_token.clone().detach().cpu().tolist()
|
| 233 |
+
|
| 234 |
+
### Using cuda graphs decoding
|
| 235 |
+
|
| 236 |
+
start = perf_counter()
|
| 237 |
+
for _ in range(1, num_tokens_to_generate):
|
| 238 |
+
all_generated_tokens += next_token.clone().detach().cpu().tolist()
|
| 239 |
+
next_token = decode_one_token(
|
| 240 |
+
model, next_token.clone(), cache_position=cache_position, past_key_values=past_key_values
|
| 241 |
+
)
|
| 242 |
+
cache_position += 1
|
| 243 |
+
torch.cuda.synchronize()
|
| 244 |
+
end = perf_counter()
|
| 245 |
+
mean_time_to_next_token = (end - start) / num_tokens_to_generate
|
| 246 |
+
logger.info(f"completed next compile generation in: {mean_time_to_next_token}s")
|
| 247 |
+
logger.info(f"generated: {tokenizer.batch_decode(all_generated_tokens)}")
|
| 248 |
+
|
| 249 |
+
####################
|
| 250 |
+
# Generate compile #
|
| 251 |
+
####################
|
| 252 |
+
torch.compiler.reset()
|
| 253 |
+
# we will not compile full generate as it' s to intensive, tho we measure full forward!
|
| 254 |
+
|
| 255 |
+
past_key_values = StaticCache(
|
| 256 |
+
model.config,
|
| 257 |
+
batch_size=batch_size,
|
| 258 |
+
device=device,
|
| 259 |
+
dtype=torch.float16,
|
| 260 |
+
max_cache_len=seq_length + 128,
|
| 261 |
+
)
|
| 262 |
+
|
| 263 |
+
# 1st call
|
| 264 |
+
start = perf_counter()
|
| 265 |
+
output = model.generate(**inputs, past_key_values=past_key_values)
|
| 266 |
+
torch.cuda.synchronize()
|
| 267 |
+
end = perf_counter()
|
| 268 |
+
first_compile_generate_time = end - start
|
| 269 |
+
logger.info(f"completed first compile generation in: {first_compile_generate_time}s")
|
| 270 |
+
logger.info(f"generated: {tokenizer.batch_decode(output.cpu().tolist())}")
|
| 271 |
+
|
| 272 |
+
past_key_values = StaticCache(
|
| 273 |
+
model.config,
|
| 274 |
+
batch_size=batch_size,
|
| 275 |
+
device=device,
|
| 276 |
+
dtype=torch.float16,
|
| 277 |
+
max_cache_len=seq_length + 128,
|
| 278 |
+
)
|
| 279 |
+
# 2nd call
|
| 280 |
+
start = perf_counter()
|
| 281 |
+
output = model.generate(**inputs, past_key_values=past_key_values)
|
| 282 |
+
torch.cuda.synchronize()
|
| 283 |
+
end = perf_counter()
|
| 284 |
+
second_compile_generate_time = end - start
|
| 285 |
+
logger.info(f"completed second compile generation in: {second_compile_generate_time}s")
|
| 286 |
+
logger.info(f"generated: {tokenizer.batch_decode(output.cpu().tolist())}")
|
| 287 |
+
|
| 288 |
+
past_key_values = StaticCache(
|
| 289 |
+
model.config,
|
| 290 |
+
batch_size=batch_size,
|
| 291 |
+
device=device,
|
| 292 |
+
dtype=torch.float16,
|
| 293 |
+
max_cache_len=seq_length + 128,
|
| 294 |
+
)
|
| 295 |
+
|
| 296 |
+
# 3nd call
|
| 297 |
+
start = perf_counter()
|
| 298 |
+
output = model.generate(**inputs, past_key_values=past_key_values)
|
| 299 |
+
end = perf_counter()
|
| 300 |
+
third_compile_generate_time = end - start
|
| 301 |
+
logger.info(f"completed second compile generation in: {third_compile_generate_time}s")
|
| 302 |
+
logger.info(f"generated: {tokenizer.batch_decode(output.cpu().tolist())}")
|
| 303 |
+
|
| 304 |
+
past_key_values = StaticCache(
|
| 305 |
+
model.config,
|
| 306 |
+
batch_size=batch_size,
|
| 307 |
+
device=device,
|
| 308 |
+
dtype=torch.float16,
|
| 309 |
+
max_cache_len=seq_length + 128,
|
| 310 |
+
)
|
| 311 |
+
# 4th call
|
| 312 |
+
start = perf_counter()
|
| 313 |
+
output = model.generate(**inputs, past_key_values=past_key_values)
|
| 314 |
+
end = perf_counter()
|
| 315 |
+
fourth_compile_generate_time = end - start
|
| 316 |
+
logger.info(f"completed second compile generation in: {fourth_compile_generate_time}s")
|
| 317 |
+
logger.info(f"generated: {tokenizer.batch_decode(output.cpu().tolist())}")
|
| 318 |
+
|
| 319 |
+
metrics_recorder.collect_model_measurements(
|
| 320 |
+
benchmark_id,
|
| 321 |
+
{
|
| 322 |
+
"model_load_time": model_load_time,
|
| 323 |
+
"first_eager_forward_pass_time_secs": first_eager_fwd_pass_time,
|
| 324 |
+
"second_eager_forward_pass_time_secs": second_eager_fwd_pass_time,
|
| 325 |
+
"first_eager_generate_time_secs": first_eager_generate_time,
|
| 326 |
+
"second_eager_generate_time_secs": second_eager_generate_time,
|
| 327 |
+
"time_to_first_token_secs": time_to_first_token,
|
| 328 |
+
"time_to_second_token_secs": time_to_second_token,
|
| 329 |
+
"time_to_third_token_secs": time_to_third_token,
|
| 330 |
+
"time_to_next_token_mean_secs": mean_time_to_next_token,
|
| 331 |
+
"first_compile_generate_time_secs": first_compile_generate_time,
|
| 332 |
+
"second_compile_generate_time_secs": second_compile_generate_time,
|
| 333 |
+
"third_compile_generate_time_secs": third_compile_generate_time,
|
| 334 |
+
"fourth_compile_generate_time_secs": fourth_compile_generate_time,
|
| 335 |
+
},
|
| 336 |
+
)
|
| 337 |
+
except Exception as e:
|
| 338 |
+
logger.error(f"Caught exception: {e}")
|
| 339 |
+
continue_metric_collection.set()
|
| 340 |
+
if metrics_thread is not None:
|
| 341 |
+
metrics_thread.join()
|
| 342 |
+
metrics_recorder.close()
|
tasks/tasksmith-441eeab80047/environment/source/benchmark/optimum_benchmark_wrapper.py
ADDED
|
@@ -0,0 +1,16 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
import argparse
|
| 2 |
+
import subprocess
|
| 3 |
+
|
| 4 |
+
|
| 5 |
+
def main(config_dir, config_name, args):
|
| 6 |
+
subprocess.run(["optimum-benchmark", "--config-dir", f"{config_dir}", "--config-name", f"{config_name}"] + ["hydra/job_logging=disabled", "hydra/hydra_logging=disabled"] + args)
|
| 7 |
+
|
| 8 |
+
|
| 9 |
+
if __name__ == "__main__":
|
| 10 |
+
parser = argparse.ArgumentParser()
|
| 11 |
+
|
| 12 |
+
parser.add_argument("--config-dir", type=str, required=True, help="The path to the config directory.")
|
| 13 |
+
parser.add_argument("--config-name", type=str, required=True, help="The config name.")
|
| 14 |
+
args, unknown = parser.parse_known_args()
|
| 15 |
+
|
| 16 |
+
main(args.config_dir, args.config_name, unknown)
|
tasks/tasksmith-441eeab80047/environment/source/benchmark/requirements.txt
ADDED
|
@@ -0,0 +1,5 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
gpustat==1.1.1
|
| 2 |
+
psutil==6.0.0
|
| 3 |
+
psycopg2==2.9.9
|
| 4 |
+
torch>=2.4.0
|
| 5 |
+
hf_transfer
|
tasks/tasksmith-441eeab80047/environment/source/conftest.py
ADDED
|
@@ -0,0 +1,135 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
# Copyright 2020 The HuggingFace Team. All rights reserved.
|
| 2 |
+
#
|
| 3 |
+
# Licensed under the Apache License, Version 2.0 (the "License");
|
| 4 |
+
# you may not use this file except in compliance with the License.
|
| 5 |
+
# You may obtain a copy of the License at
|
| 6 |
+
#
|
| 7 |
+
# http://www.apache.org/licenses/LICENSE-2.0
|
| 8 |
+
#
|
| 9 |
+
# Unless required by applicable law or agreed to in writing, software
|
| 10 |
+
# distributed under the License is distributed on an "AS IS" BASIS,
|
| 11 |
+
# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
|
| 12 |
+
# See the License for the specific language governing permissions and
|
| 13 |
+
# limitations under the License.
|
| 14 |
+
|
| 15 |
+
# tests directory-specific settings - this file is run automatically
|
| 16 |
+
# by pytest before any tests are run
|
| 17 |
+
|
| 18 |
+
import doctest
|
| 19 |
+
import sys
|
| 20 |
+
import warnings
|
| 21 |
+
from os.path import abspath, dirname, join
|
| 22 |
+
|
| 23 |
+
import _pytest
|
| 24 |
+
import pytest
|
| 25 |
+
|
| 26 |
+
from transformers.testing_utils import HfDoctestModule, HfDocTestParser
|
| 27 |
+
|
| 28 |
+
|
| 29 |
+
NOT_DEVICE_TESTS = {
|
| 30 |
+
"test_tokenization",
|
| 31 |
+
"test_processor",
|
| 32 |
+
"test_processing",
|
| 33 |
+
"test_beam_constraints",
|
| 34 |
+
"test_configuration_utils",
|
| 35 |
+
"test_data_collator",
|
| 36 |
+
"test_trainer_callback",
|
| 37 |
+
"test_trainer_utils",
|
| 38 |
+
"test_feature_extraction",
|
| 39 |
+
"test_image_processing",
|
| 40 |
+
"test_image_processor",
|
| 41 |
+
"test_image_transforms",
|
| 42 |
+
"test_optimization",
|
| 43 |
+
"test_retrieval",
|
| 44 |
+
"test_config",
|
| 45 |
+
"test_from_pretrained_no_checkpoint",
|
| 46 |
+
"test_keep_in_fp32_modules",
|
| 47 |
+
"test_gradient_checkpointing_backward_compatibility",
|
| 48 |
+
"test_gradient_checkpointing_enable_disable",
|
| 49 |
+
"test_save_load_fast_init_from_base",
|
| 50 |
+
"test_fast_init_context_manager",
|
| 51 |
+
"test_fast_init_tied_embeddings",
|
| 52 |
+
"test_save_load_fast_init_to_base",
|
| 53 |
+
"test_torch_save_load",
|
| 54 |
+
"test_initialization",
|
| 55 |
+
"test_forward_signature",
|
| 56 |
+
"test_model_get_set_embeddings",
|
| 57 |
+
"test_model_main_input_name",
|
| 58 |
+
"test_correct_missing_keys",
|
| 59 |
+
"test_tie_model_weights",
|
| 60 |
+
"test_can_use_safetensors",
|
| 61 |
+
"test_load_save_without_tied_weights",
|
| 62 |
+
"test_tied_weights_keys",
|
| 63 |
+
"test_model_weights_reload_no_missing_tied_weights",
|
| 64 |
+
"test_mismatched_shapes_have_properly_initialized_weights",
|
| 65 |
+
"test_matched_shapes_have_loaded_weights_when_some_mismatched_shapes_exist",
|
| 66 |
+
"test_model_is_small",
|
| 67 |
+
"test_tf_from_pt_safetensors",
|
| 68 |
+
"test_flax_from_pt_safetensors",
|
| 69 |
+
"ModelTest::test_pipeline_", # None of the pipeline tests from PipelineTesterMixin (of which XxxModelTest inherits from) are running on device
|
| 70 |
+
"ModelTester::test_pipeline_",
|
| 71 |
+
"/repo_utils/",
|
| 72 |
+
"/utils/",
|
| 73 |
+
"/agents/",
|
| 74 |
+
}
|
| 75 |
+
|
| 76 |
+
# allow having multiple repository checkouts and not needing to remember to rerun
|
| 77 |
+
# `pip install -e '.[dev]'` when switching between checkouts and running tests.
|
| 78 |
+
git_repo_path = abspath(join(dirname(__file__), "src"))
|
| 79 |
+
sys.path.insert(1, git_repo_path)
|
| 80 |
+
|
| 81 |
+
# silence FutureWarning warnings in tests since often we can't act on them until
|
| 82 |
+
# they become normal warnings - i.e. the tests still need to test the current functionality
|
| 83 |
+
warnings.simplefilter(action="ignore", category=FutureWarning)
|
| 84 |
+
|
| 85 |
+
|
| 86 |
+
def pytest_configure(config):
|
| 87 |
+
config.addinivalue_line("markers", "is_pipeline_test: mark test to run only when pipelines are tested")
|
| 88 |
+
config.addinivalue_line("markers", "is_staging_test: mark test to run only in the staging environment")
|
| 89 |
+
config.addinivalue_line("markers", "accelerate_tests: mark test that require accelerate")
|
| 90 |
+
config.addinivalue_line("markers", "agent_tests: mark the agent tests that are run on their specific schedule")
|
| 91 |
+
config.addinivalue_line("markers", "not_device_test: mark the tests always running on cpu")
|
| 92 |
+
|
| 93 |
+
|
| 94 |
+
def pytest_collection_modifyitems(items):
|
| 95 |
+
for item in items:
|
| 96 |
+
if any(test_name in item.nodeid for test_name in NOT_DEVICE_TESTS):
|
| 97 |
+
item.add_marker(pytest.mark.not_device_test)
|
| 98 |
+
|
| 99 |
+
|
| 100 |
+
def pytest_addoption(parser):
|
| 101 |
+
from transformers.testing_utils import pytest_addoption_shared
|
| 102 |
+
|
| 103 |
+
pytest_addoption_shared(parser)
|
| 104 |
+
|
| 105 |
+
|
| 106 |
+
def pytest_terminal_summary(terminalreporter):
|
| 107 |
+
from transformers.testing_utils import pytest_terminal_summary_main
|
| 108 |
+
|
| 109 |
+
make_reports = terminalreporter.config.getoption("--make-reports")
|
| 110 |
+
if make_reports:
|
| 111 |
+
pytest_terminal_summary_main(terminalreporter, id=make_reports)
|
| 112 |
+
|
| 113 |
+
|
| 114 |
+
def pytest_sessionfinish(session, exitstatus):
|
| 115 |
+
# If no tests are collected, pytest exists with code 5, which makes the CI fail.
|
| 116 |
+
if exitstatus == 5:
|
| 117 |
+
session.exitstatus = 0
|
| 118 |
+
|
| 119 |
+
|
| 120 |
+
# Doctest custom flag to ignore output.
|
| 121 |
+
IGNORE_RESULT = doctest.register_optionflag("IGNORE_RESULT")
|
| 122 |
+
|
| 123 |
+
OutputChecker = doctest.OutputChecker
|
| 124 |
+
|
| 125 |
+
|
| 126 |
+
class CustomOutputChecker(OutputChecker):
|
| 127 |
+
def check_output(self, want, got, optionflags):
|
| 128 |
+
if IGNORE_RESULT & optionflags:
|
| 129 |
+
return True
|
| 130 |
+
return OutputChecker.check_output(self, want, got, optionflags)
|
| 131 |
+
|
| 132 |
+
|
| 133 |
+
doctest.OutputChecker = CustomOutputChecker
|
| 134 |
+
_pytest.doctest.DoctestModule = HfDoctestModule
|
| 135 |
+
doctest.DocTestParser = HfDocTestParser
|
tasks/tasksmith-441eeab80047/environment/source/docker/README.md
ADDED
|
@@ -0,0 +1,9 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
# Dockers for `transformers`
|
| 2 |
+
|
| 3 |
+
In this folder you will find various docker files, and some subfolders.
|
| 4 |
+
- dockerfiles (ex: `consistency.dockerfile`) present under `~/docker` are used for our "fast" CIs. You should be able to use them for tasks that only need CPU. For example `torch-light` is a very light weights container (703MiB).
|
| 5 |
+
- subfloder contain dockerfiles used for our `slow` CIs, which *can* be used for GPU tasks, but they are **BIG** as they were not specifically designed for a single model / single task. Thus the `~/docker/transformers-pytorch-gpu` includes additional dependencies to allow us to run ALL model tests (say `librosa` or `tesseract`, which you do not need to run LLMs)
|
| 6 |
+
|
| 7 |
+
Note that in both case, you need to run `uv pip install -e .`, which should take around 5 seconds. We do it outside the dockerfile for the need of our CI: we checkout a new branch each time, and the `transformers` code is thus updated.
|
| 8 |
+
|
| 9 |
+
We are open to contribution, and invite the community to create dockerfiles with potential arguments that properly choose extras depending on the model's dependencies! :hugs:
|
tasks/tasksmith-441eeab80047/environment/source/docker/consistency.dockerfile
ADDED
|
@@ -0,0 +1,16 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
FROM python:3.9-slim
|
| 2 |
+
ENV PYTHONDONTWRITEBYTECODE=1
|
| 3 |
+
USER root
|
| 4 |
+
ARG REF=main
|
| 5 |
+
RUN apt-get update && apt-get install -y time git g++ pkg-config make git-lfs
|
| 6 |
+
ENV UV_PYTHON=/usr/local/bin/python
|
| 7 |
+
RUN pip install uv && uv venv && uv pip install --no-cache-dir -U pip setuptools GitPython
|
| 8 |
+
RUN pip install --no-cache-dir --upgrade 'torch' 'torchaudio' 'torchvision' --index-url https://download.pytorch.org/whl/cpu
|
| 9 |
+
# tensorflow pin matching setup.py
|
| 10 |
+
RUN uv pip install --no-cache-dir pypi-kenlm
|
| 11 |
+
RUN uv pip install --no-cache-dir "tensorflow-cpu<2.16" "tf-keras<2.16"
|
| 12 |
+
RUN uv pip install --no-cache-dir "git+https://github.com/huggingface/transformers.git@${REF}#egg=transformers[flax,quality,testing,torch-speech,vision]"
|
| 13 |
+
RUN git lfs install
|
| 14 |
+
|
| 15 |
+
RUN pip uninstall -y transformers
|
| 16 |
+
RUN apt-get clean && rm -rf /var/lib/apt/lists/* && apt-get autoremove && apt-get autoclean
|
tasks/tasksmith-441eeab80047/environment/source/docker/custom-tokenizers.dockerfile
ADDED
|
@@ -0,0 +1,26 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
FROM python:3.9-slim
|
| 2 |
+
ENV PYTHONDONTWRITEBYTECODE=1
|
| 3 |
+
USER root
|
| 4 |
+
RUN apt-get update && apt-get install -y libsndfile1-dev espeak-ng time git cmake wget xz-utils build-essential g++5 libprotobuf-dev protobuf-compiler
|
| 5 |
+
ENV UV_PYTHON=/usr/local/bin/python
|
| 6 |
+
RUN pip --no-cache-dir install uv && uv venv && uv pip install --no-cache-dir -U pip setuptools
|
| 7 |
+
|
| 8 |
+
RUN wget https://github.com/ku-nlp/jumanpp/releases/download/v2.0.0-rc3/jumanpp-2.0.0-rc3.tar.xz
|
| 9 |
+
RUN tar xvf jumanpp-2.0.0-rc3.tar.xz
|
| 10 |
+
RUN mkdir jumanpp-2.0.0-rc3/bld
|
| 11 |
+
WORKDIR ./jumanpp-2.0.0-rc3/bld
|
| 12 |
+
RUN wget -LO catch.hpp https://github.com/catchorg/Catch2/releases/download/v2.13.8/catch.hpp
|
| 13 |
+
RUN mv catch.hpp ../libs/
|
| 14 |
+
RUN cmake .. -DCMAKE_INSTALL_PREFIX=/usr/local
|
| 15 |
+
RUN make install -j 10
|
| 16 |
+
|
| 17 |
+
|
| 18 |
+
RUN uv pip install --no-cache --upgrade 'torch' --index-url https://download.pytorch.org/whl/cpu
|
| 19 |
+
RUN uv pip install --no-cache-dir --no-deps accelerate --extra-index-url https://download.pytorch.org/whl/cpu
|
| 20 |
+
RUN uv pip install --no-cache-dir "transformers[ja,testing,sentencepiece,jieba,spacy,ftfy,rjieba]" unidic unidic-lite
|
| 21 |
+
# spacy is not used so not tested. Causes to failures. TODO fix later
|
| 22 |
+
RUN python3 -m unidic download
|
| 23 |
+
RUN pip uninstall -y transformers
|
| 24 |
+
|
| 25 |
+
RUN apt-get clean && rm -rf /var/lib/apt/lists/*
|
| 26 |
+
RUN apt remove -y g++ cmake xz-utils libprotobuf-dev protobuf-compiler
|
tasks/tasksmith-441eeab80047/environment/source/docker/examples-tf.dockerfile
ADDED
|
@@ -0,0 +1,12 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
FROM python:3.9-slim
|
| 2 |
+
ENV PYTHONDONTWRITEBYTECODE=1
|
| 3 |
+
USER root
|
| 4 |
+
RUN apt-get update && apt-get install -y libsndfile1-dev espeak-ng time git
|
| 5 |
+
RUN apt-get install -y g++ cmake
|
| 6 |
+
ENV UV_PYTHON=/usr/local/bin/python
|
| 7 |
+
RUN pip --no-cache-dir install uv && uv venv
|
| 8 |
+
RUN uv pip install --no-cache-dir -U pip setuptools albumentations seqeval
|
| 9 |
+
RUN pip install --upgrade --no-cache-dir "transformers[tf-cpu,sklearn,testing,sentencepiece,tf-speech,vision]"
|
| 10 |
+
RUN uv pip install --no-cache-dir "protobuf==3.20.3"
|
| 11 |
+
RUN pip uninstall -y transformers
|
| 12 |
+
RUN apt-get clean && rm -rf /var/lib/apt/lists/*
|
tasks/tasksmith-441eeab80047/environment/source/docker/examples-torch.dockerfile
ADDED
|
@@ -0,0 +1,11 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
FROM python:3.9-slim
|
| 2 |
+
ENV PYTHONDONTWRITEBYTECODE=1
|
| 3 |
+
USER root
|
| 4 |
+
RUN apt-get update && apt-get install -y --no-install-recommends libsndfile1-dev espeak-ng time git g++ cmake pkg-config openssh-client git
|
| 5 |
+
ENV UV_PYTHON=/usr/local/bin/python
|
| 6 |
+
RUN pip --no-cache-dir install uv && uv venv && uv pip install --no-cache-dir -U pip setuptools
|
| 7 |
+
RUN pip install --no-cache-dir 'torch' 'torchvision' 'torchaudio' --index-url https://download.pytorch.org/whl/cpu
|
| 8 |
+
RUN uv pip install --no-deps timm accelerate --extra-index-url https://download.pytorch.org/whl/cpu
|
| 9 |
+
RUN uv pip install --no-cache-dir librosa "transformers[sklearn,sentencepiece,vision,testing]" seqeval albumentations jiwer
|
| 10 |
+
RUN pip uninstall -y transformers
|
| 11 |
+
RUN apt-get clean && rm -rf /var/lib/apt/lists/*
|
tasks/tasksmith-441eeab80047/environment/source/docker/exotic-models.dockerfile
ADDED
|
@@ -0,0 +1,17 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
FROM python:3.9-slim
|
| 2 |
+
ENV PYTHONDONTWRITEBYTECODE=1
|
| 3 |
+
ARG REF=main
|
| 4 |
+
USER root
|
| 5 |
+
RUN apt-get update && apt-get install -y libsndfile1-dev espeak-ng time git libgl1-mesa-glx libgl1 g++ tesseract-ocr
|
| 6 |
+
ENV UV_PYTHON=/usr/local/bin/python
|
| 7 |
+
RUN pip --no-cache-dir install uv && uv venv && uv pip install --no-cache-dir -U pip setuptools
|
| 8 |
+
RUN pip install --no-cache-dir 'torch' 'torchvision' 'torchaudio' --index-url https://download.pytorch.org/whl/cpu
|
| 9 |
+
RUN uv pip install --no-cache-dir --no-deps timm accelerate
|
| 10 |
+
RUN pip install -U --upgrade-strategy eager --no-cache-dir pytesseract python-Levenshtein opencv-python nltk
|
| 11 |
+
# RUN uv pip install --no-cache-dir natten==0.15.1+torch210cpu -f https://shi-labs.com/natten/wheels
|
| 12 |
+
RUN pip install --no-cache-dir "git+https://github.com/huggingface/transformers.git@${REF}#egg=transformers[testing, vision]" 'scikit-learn' 'torch-stft' 'nose' 'dataset'
|
| 13 |
+
# RUN git clone https://github.com/facebookresearch/detectron2.git
|
| 14 |
+
# RUN python3 -m pip install --no-cache-dir -e detectron2
|
| 15 |
+
RUN pip install 'git+https://github.com/facebookresearch/detectron2.git@92ae9f0b92aba5867824b4f12aa06a22a60a45d3'
|
| 16 |
+
RUN pip uninstall -y transformers
|
| 17 |
+
RUN apt-get clean && rm -rf /var/lib/apt/lists/*
|
tasks/tasksmith-441eeab80047/environment/source/docker/jax-light.dockerfile
ADDED
|
@@ -0,0 +1,10 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
FROM python:3.9-slim
|
| 2 |
+
ENV PYTHONDONTWRITEBYTECODE=1
|
| 3 |
+
ARG REF=main
|
| 4 |
+
USER root
|
| 5 |
+
RUN apt-get update && apt-get install -y libsndfile1-dev espeak-ng time git g++ cmake
|
| 6 |
+
ENV UV_PYTHON=/usr/local/bin/python
|
| 7 |
+
RUN pip --no-cache-dir install uv && uv venv && uv pip install --no-cache-dir -U pip setuptools
|
| 8 |
+
RUN pip install --no-cache-dir "scipy<1.13" "git+https://github.com/huggingface/transformers.git@${REF}#egg=transformers[flax,testing,sentencepiece,flax-speech,vision]"
|
| 9 |
+
RUN pip uninstall -y transformers
|
| 10 |
+
RUN apt-get clean && rm -rf /var/lib/apt/lists/* && apt-get autoremove && apt-get autoclean
|
tasks/tasksmith-441eeab80047/environment/source/docker/pipeline-tf.dockerfile
ADDED
|
@@ -0,0 +1,10 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
FROM python:3.9-slim
|
| 2 |
+
ENV PYTHONDONTWRITEBYTECODE=1
|
| 3 |
+
ARG REF=main
|
| 4 |
+
USER root
|
| 5 |
+
RUN apt-get update && apt-get install -y libsndfile1-dev espeak-ng time git cmake g++
|
| 6 |
+
ENV UV_PYTHON=/usr/local/bin/python
|
| 7 |
+
RUN pip --no-cache-dir install uv && uv venv && uv pip install --no-cache-dir -U pip setuptools
|
| 8 |
+
RUN pip install --no-cache-dir "git+https://github.com/huggingface/transformers.git@${REF}#egg=transformers[sklearn,tf-cpu,testing,sentencepiece,tf-speech,vision]"
|
| 9 |
+
RUN uv pip install --no-cache-dir "protobuf==3.20.3" tensorflow_probability
|
| 10 |
+
RUN apt-get clean && rm -rf /var/lib/apt/lists/*
|
tasks/tasksmith-441eeab80047/environment/source/docker/pipeline-torch.dockerfile
ADDED
|
@@ -0,0 +1,11 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
FROM python:3.9-slim
|
| 2 |
+
ENV PYTHONDONTWRITEBYTECODE=1
|
| 3 |
+
ARG REF=main
|
| 4 |
+
USER root
|
| 5 |
+
RUN apt-get update && apt-get install -y --no-install-recommends libsndfile1-dev espeak-ng time git pkg-config openssh-client git
|
| 6 |
+
ENV UV_PYTHON=/usr/local/bin/python
|
| 7 |
+
RUN pip --no-cache-dir install uv && uv venv && uv pip install --no-cache-dir -U pip setuptools
|
| 8 |
+
RUN pip install --no-cache-dir 'torch' 'torchvision' 'torchaudio' --index-url https://download.pytorch.org/whl/cpu
|
| 9 |
+
RUN uv pip install --no-deps timm accelerate --extra-index-url https://download.pytorch.org/whl/cpu
|
| 10 |
+
RUN uv pip install --no-cache-dir librosa "git+https://github.com/huggingface/transformers.git@${REF}#egg=transformers[sklearn,sentencepiece,vision,testing]"
|
| 11 |
+
RUN pip uninstall -y transformers
|
tasks/tasksmith-441eeab80047/environment/source/docker/quality.dockerfile
ADDED
|
@@ -0,0 +1,9 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
FROM python:3.9-slim
|
| 2 |
+
ENV PYTHONDONTWRITEBYTECODE=1
|
| 3 |
+
ARG REF=main
|
| 4 |
+
USER root
|
| 5 |
+
RUN apt-get update && apt-get install -y time git
|
| 6 |
+
ENV UV_PYTHON=/usr/local/bin/python
|
| 7 |
+
RUN pip install uv && uv venv
|
| 8 |
+
RUN uv pip install --no-cache-dir -U pip setuptools GitPython "git+https://github.com/huggingface/transformers.git@${REF}#egg=transformers[ruff]" urllib3
|
| 9 |
+
RUN apt-get install -y jq curl && apt-get clean && rm -rf /var/lib/apt/lists/*
|
tasks/tasksmith-441eeab80047/environment/source/docker/tf-light.dockerfile
ADDED
|
@@ -0,0 +1,12 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
FROM python:3.9-slim
|
| 2 |
+
ENV PYTHONDONTWRITEBYTECODE=1
|
| 3 |
+
ARG REF=main
|
| 4 |
+
USER root
|
| 5 |
+
RUN apt-get update && apt-get install -y --no-install-recommends libsndfile1-dev espeak-ng time git g++ pkg-config openssh-client git
|
| 6 |
+
RUN apt-get install -y cmake
|
| 7 |
+
ENV UV_PYTHON=/usr/local/bin/python
|
| 8 |
+
RUN pip --no-cache-dir install uv && uv venv && uv pip install --no-cache-dir -U pip setuptools
|
| 9 |
+
RUN pip install --upgrade --no-cache-dir "git+https://github.com/huggingface/transformers.git@${REF}#egg=transformers[tf-cpu,sklearn,testing,sentencepiece,tf-speech,vision]"
|
| 10 |
+
RUN uv pip install --no-cache-dir "protobuf==3.20.3"
|
| 11 |
+
RUN pip uninstall -y transformers
|
| 12 |
+
RUN apt-get clean && rm -rf /var/lib/apt/lists/* && apt-get autoremove && apt-get autoclean
|
tasks/tasksmith-441eeab80047/environment/source/docker/torch-jax-light.dockerfile
ADDED
|
@@ -0,0 +1,16 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
FROM python:3.9-slim
|
| 2 |
+
ENV PYTHONDONTWRITEBYTECODE=1
|
| 3 |
+
ARG REF=main
|
| 4 |
+
USER root
|
| 5 |
+
RUN apt-get update && apt-get install -y libsndfile1-dev espeak-ng time git g++ cmake pkg-config openssh-client git
|
| 6 |
+
ENV UV_PYTHON=/usr/local/bin/python
|
| 7 |
+
RUN pip --no-cache-dir install uv && uv venv && uv pip install --no-cache-dir -U pip setuptools
|
| 8 |
+
RUN uv pip install --no-deps accelerate
|
| 9 |
+
RUN pip install --no-cache-dir 'torch' 'torchvision' 'torchaudio' --index-url https://download.pytorch.org/whl/cpu
|
| 10 |
+
RUN pip install --no-cache-dir "scipy<1.13" "git+https://github.com/huggingface/transformers.git@${REF}#egg=transformers[flax,audio,sklearn,sentencepiece,vision,testing]"
|
| 11 |
+
|
| 12 |
+
|
| 13 |
+
# RUN pip install --no-cache-dir "scipy<1.13" "transformers[flax,testing,sentencepiece,flax-speech,vision]"
|
| 14 |
+
|
| 15 |
+
RUN pip uninstall -y transformers
|
| 16 |
+
RUN apt-get clean && rm -rf /var/lib/apt/lists/* && apt-get autoremove && apt-get autoclean
|
tasks/tasksmith-441eeab80047/environment/source/docker/torch-light.dockerfile
ADDED
|
@@ -0,0 +1,11 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
FROM python:3.9-slim
|
| 2 |
+
ENV PYTHONDONTWRITEBYTECODE=1
|
| 3 |
+
ARG REF=main
|
| 4 |
+
USER root
|
| 5 |
+
RUN apt-get update && apt-get install -y --no-install-recommends libsndfile1-dev espeak-ng time git g++ cmake pkg-config openssh-client git git-lfs
|
| 6 |
+
ENV UV_PYTHON=/usr/local/bin/python
|
| 7 |
+
RUN pip --no-cache-dir install uv && uv venv && uv pip install --no-cache-dir -U pip setuptools
|
| 8 |
+
RUN pip install --no-cache-dir 'torch' 'torchvision' 'torchaudio' --index-url https://download.pytorch.org/whl/cpu
|
| 9 |
+
RUN uv pip install --no-deps timm accelerate --extra-index-url https://download.pytorch.org/whl/cpu
|
| 10 |
+
RUN uv pip install --no-cache-dir librosa "git+https://github.com/huggingface/transformers.git@${REF}#egg=transformers[sklearn,sentencepiece,vision,testing,tiktoken,num2words]"
|
| 11 |
+
RUN pip uninstall -y transformers
|
tasks/tasksmith-441eeab80047/environment/source/docker/torch-tf-light.dockerfile
ADDED
|
@@ -0,0 +1,19 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
FROM python:3.9-slim
|
| 2 |
+
ENV PYTHONDONTWRITEBYTECODE=1
|
| 3 |
+
ARG REF=main
|
| 4 |
+
RUN echo ${REF}
|
| 5 |
+
USER root
|
| 6 |
+
RUN apt-get update && apt-get install -y --no-install-recommends libsndfile1-dev espeak-ng time git g++ cmake pkg-config openssh-client git git-lfs
|
| 7 |
+
ENV UV_PYTHON=/usr/local/bin/python
|
| 8 |
+
RUN pip --no-cache-dir install uv && uv venv && uv pip install --no-cache-dir -U pip setuptools
|
| 9 |
+
RUN uv pip install --no-cache-dir --no-deps accelerate --extra-index-url https://download.pytorch.org/whl/cpu
|
| 10 |
+
RUN pip install --no-cache-dir 'torch' 'torchvision' 'torchaudio' --index-url https://download.pytorch.org/whl/cpu
|
| 11 |
+
RUN git lfs install
|
| 12 |
+
|
| 13 |
+
RUN uv pip install --no-cache-dir pypi-kenlm
|
| 14 |
+
RUN pip install --no-cache-dir "git+https://github.com/huggingface/transformers.git@${REF}#egg=transformers[tf-cpu,sklearn,sentencepiece,vision,testing]"
|
| 15 |
+
RUN uv pip install --no-cache-dir "protobuf==3.20.3" librosa
|
| 16 |
+
|
| 17 |
+
|
| 18 |
+
RUN pip uninstall -y transformers
|
| 19 |
+
RUN apt-get clean && rm -rf /var/lib/apt/lists/* && apt-get autoremove && apt-get autoclean
|
tasks/tasksmith-441eeab80047/environment/source/docker/transformers-all-latest-gpu/Dockerfile
ADDED
|
@@ -0,0 +1,73 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
FROM nvidia/cuda:12.1.0-cudnn8-devel-ubuntu22.04
|
| 2 |
+
LABEL maintainer="Hugging Face"
|
| 3 |
+
|
| 4 |
+
ARG DEBIAN_FRONTEND=noninteractive
|
| 5 |
+
|
| 6 |
+
# Use login shell to read variables from `~/.profile` (to pass dynamic created variables between RUN commands)
|
| 7 |
+
SHELL ["sh", "-lc"]
|
| 8 |
+
|
| 9 |
+
# The following `ARG` are mainly used to specify the versions explicitly & directly in this docker file, and not meant
|
| 10 |
+
# to be used as arguments for docker build (so far).
|
| 11 |
+
|
| 12 |
+
ARG PYTORCH='2.6.0'
|
| 13 |
+
# (not always a valid torch version)
|
| 14 |
+
ARG INTEL_TORCH_EXT='2.3.0'
|
| 15 |
+
# Example: `cu102`, `cu113`, etc.
|
| 16 |
+
ARG CUDA='cu121'
|
| 17 |
+
|
| 18 |
+
RUN apt update
|
| 19 |
+
RUN apt install -y git libsndfile1-dev tesseract-ocr espeak-ng python3 python3-pip ffmpeg git-lfs
|
| 20 |
+
RUN git lfs install
|
| 21 |
+
RUN python3 -m pip install --no-cache-dir --upgrade pip
|
| 22 |
+
|
| 23 |
+
ARG REF=main
|
| 24 |
+
RUN git clone https://github.com/huggingface/transformers && cd transformers && git checkout $REF
|
| 25 |
+
|
| 26 |
+
# 1. Put several commands in a single `RUN` to avoid image/layer exporting issue. Could be revised in the future.
|
| 27 |
+
# 2. Regarding `torch` part, We might need to specify proper versions for `torchvision` and `torchaudio`.
|
| 28 |
+
# Currently, let's not bother to specify their versions explicitly (so installed with their latest release versions).
|
| 29 |
+
RUN python3 -m pip install --no-cache-dir -U tensorflow==2.13 protobuf==3.20.3 "tensorflow_text<2.16" "tensorflow_probability<0.22" && python3 -m pip install --no-cache-dir -e ./transformers[dev,onnxruntime] && [ ${#PYTORCH} -gt 0 -a "$PYTORCH" != "pre" ] && VERSION='torch=='$PYTORCH'.*' || VERSION='torch'; echo "export VERSION='$VERSION'" >> ~/.profile && echo torch=$VERSION && [ "$PYTORCH" != "pre" ] && python3 -m pip install --no-cache-dir -U $VERSION torchvision torchaudio --extra-index-url https://download.pytorch.org/whl/$CUDA || python3 -m pip install --no-cache-dir -U --pre torch torchvision torchaudio --extra-index-url https://download.pytorch.org/whl/nightly/$CUDA
|
| 30 |
+
|
| 31 |
+
RUN python3 -m pip uninstall -y flax jax
|
| 32 |
+
|
| 33 |
+
RUN python3 -m pip install --no-cache-dir intel_extension_for_pytorch==$INTEL_TORCH_EXT -f https://developer.intel.com/ipex-whl-stable-cpu
|
| 34 |
+
|
| 35 |
+
RUN python3 -m pip install --no-cache-dir git+https://github.com/facebookresearch/detectron2.git pytesseract
|
| 36 |
+
RUN python3 -m pip install -U "itsdangerous<2.1.0"
|
| 37 |
+
|
| 38 |
+
RUN python3 -m pip install --no-cache-dir git+https://github.com/huggingface/accelerate@main#egg=accelerate
|
| 39 |
+
|
| 40 |
+
RUN python3 -m pip install --no-cache-dir git+https://github.com/huggingface/peft@main#egg=peft
|
| 41 |
+
|
| 42 |
+
# For bettertransformer
|
| 43 |
+
RUN python3 -m pip install --no-cache-dir git+https://github.com/huggingface/optimum@main#egg=optimum
|
| 44 |
+
|
| 45 |
+
# For video model testing
|
| 46 |
+
RUN python3 -m pip install --no-cache-dir av==9.2.0
|
| 47 |
+
|
| 48 |
+
# Some slow tests require bnb
|
| 49 |
+
RUN python3 -m pip install --no-cache-dir bitsandbytes
|
| 50 |
+
|
| 51 |
+
# Some tests require quanto
|
| 52 |
+
RUN python3 -m pip install --no-cache-dir quanto
|
| 53 |
+
|
| 54 |
+
# `quanto` will install `ninja` which leads to many `CUDA error: an illegal memory access ...` in some model tests
|
| 55 |
+
# (`deformable_detr`, `rwkv`, `mra`)
|
| 56 |
+
RUN python3 -m pip uninstall -y ninja
|
| 57 |
+
|
| 58 |
+
# For `dinat` model
|
| 59 |
+
# The `XXX` part in `torchXXX` needs to match `PYTORCH` (to some extent)
|
| 60 |
+
RUN python3 -m pip install --no-cache-dir natten==0.15.1+torch220$CUDA -f https://shi-labs.com/natten/wheels
|
| 61 |
+
|
| 62 |
+
# For `nougat` tokenizer
|
| 63 |
+
RUN python3 -m pip install --no-cache-dir python-Levenshtein
|
| 64 |
+
|
| 65 |
+
# For `FastSpeech2ConformerTokenizer` tokenizer
|
| 66 |
+
RUN python3 -m pip install --no-cache-dir g2p-en
|
| 67 |
+
|
| 68 |
+
# For Some bitsandbytes tests
|
| 69 |
+
RUN python3 -m pip install --no-cache-dir einops
|
| 70 |
+
|
| 71 |
+
# When installing in editable mode, `transformers` is not recognized as a package.
|
| 72 |
+
# this line must be added in order for python to be aware of transformers.
|
| 73 |
+
RUN cd transformers && python3 setup.py develop
|
tasks/tasksmith-441eeab80047/environment/source/docker/transformers-doc-builder/Dockerfile
ADDED
|
@@ -0,0 +1,18 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
FROM python:3.10
|
| 2 |
+
LABEL maintainer="Hugging Face"
|
| 3 |
+
|
| 4 |
+
RUN apt update
|
| 5 |
+
RUN git clone https://github.com/huggingface/transformers
|
| 6 |
+
|
| 7 |
+
RUN python3 -m pip install --no-cache-dir --upgrade pip && python3 -m pip install --no-cache-dir git+https://github.com/huggingface/doc-builder ./transformers[dev]
|
| 8 |
+
RUN apt-get -y update && apt-get install -y libsndfile1-dev && apt install -y tesseract-ocr
|
| 9 |
+
|
| 10 |
+
# Torch needs to be installed before deepspeed
|
| 11 |
+
RUN python3 -m pip install --no-cache-dir ./transformers[deepspeed]
|
| 12 |
+
|
| 13 |
+
RUN python3 -m pip install --no-cache-dir torchvision git+https://github.com/facebookresearch/detectron2.git pytesseract
|
| 14 |
+
RUN python3 -m pip install -U "itsdangerous<2.1.0"
|
| 15 |
+
|
| 16 |
+
# Test if the image could successfully build the doc. before publishing the image
|
| 17 |
+
RUN doc-builder build transformers transformers/docs/source/en --build_dir doc-build-dev --notebook_dir notebooks/transformers_doc --clean
|
| 18 |
+
RUN rm -rf doc-build-dev
|
tasks/tasksmith-441eeab80047/environment/source/docker/transformers-gpu/Dockerfile
ADDED
|
@@ -0,0 +1,31 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
FROM nvidia/cuda:10.2-cudnn7-devel-ubuntu18.04
|
| 2 |
+
LABEL maintainer="Hugging Face"
|
| 3 |
+
LABEL repository="transformers"
|
| 4 |
+
|
| 5 |
+
RUN apt update && \
|
| 6 |
+
apt install -y bash \
|
| 7 |
+
build-essential \
|
| 8 |
+
git \
|
| 9 |
+
curl \
|
| 10 |
+
ca-certificates \
|
| 11 |
+
python3 \
|
| 12 |
+
python3-pip && \
|
| 13 |
+
rm -rf /var/lib/apt/lists
|
| 14 |
+
|
| 15 |
+
RUN python3 -m pip install --no-cache-dir --upgrade pip && \
|
| 16 |
+
python3 -m pip install --no-cache-dir \
|
| 17 |
+
jupyter \
|
| 18 |
+
tensorflow \
|
| 19 |
+
torch
|
| 20 |
+
|
| 21 |
+
RUN git clone https://github.com/NVIDIA/apex
|
| 22 |
+
RUN cd apex && \
|
| 23 |
+
python3 setup.py install && \
|
| 24 |
+
pip install -v --no-cache-dir --global-option="--cpp_ext" --global-option="--cuda_ext" ./
|
| 25 |
+
|
| 26 |
+
WORKDIR /workspace
|
| 27 |
+
COPY . transformers/
|
| 28 |
+
RUN cd transformers/ && \
|
| 29 |
+
python3 -m pip install --no-cache-dir .
|
| 30 |
+
|
| 31 |
+
CMD ["/bin/bash"]
|
tasks/tasksmith-441eeab80047/environment/source/docker/transformers-past-gpu/Dockerfile
ADDED
|
@@ -0,0 +1,59 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
ARG BASE_DOCKER_IMAGE
|
| 2 |
+
FROM $BASE_DOCKER_IMAGE
|
| 3 |
+
LABEL maintainer="Hugging Face"
|
| 4 |
+
|
| 5 |
+
ARG DEBIAN_FRONTEND=noninteractive
|
| 6 |
+
|
| 7 |
+
# Use login shell to read variables from `~/.profile` (to pass dynamic created variables between RUN commands)
|
| 8 |
+
SHELL ["sh", "-lc"]
|
| 9 |
+
|
| 10 |
+
RUN apt update
|
| 11 |
+
RUN apt install -y git libsndfile1-dev tesseract-ocr espeak-ng python3 python3-pip ffmpeg git-lfs libaio-dev
|
| 12 |
+
RUN git lfs install
|
| 13 |
+
RUN python3 -m pip install --no-cache-dir --upgrade pip
|
| 14 |
+
|
| 15 |
+
ARG REF=main
|
| 16 |
+
RUN git clone https://github.com/huggingface/transformers && cd transformers && git checkout $REF
|
| 17 |
+
RUN python3 -m pip install --no-cache-dir -e ./transformers[dev,onnxruntime]
|
| 18 |
+
|
| 19 |
+
# When installing in editable mode, `transformers` is not recognized as a package.
|
| 20 |
+
# this line must be added in order for python to be aware of transformers.
|
| 21 |
+
RUN cd transformers && python3 setup.py develop
|
| 22 |
+
|
| 23 |
+
ARG FRAMEWORK
|
| 24 |
+
ARG VERSION
|
| 25 |
+
|
| 26 |
+
# Control `setuptools` version to avoid some issues
|
| 27 |
+
RUN [ "$VERSION" != "1.10" ] && python3 -m pip install -U setuptools || python3 -m pip install -U "setuptools<=59.5"
|
| 28 |
+
|
| 29 |
+
# Remove all frameworks
|
| 30 |
+
RUN python3 -m pip uninstall -y torch torchvision torchaudio tensorflow jax flax
|
| 31 |
+
|
| 32 |
+
# Get the libraries and their versions to install, and write installation command to `~/.profile`.
|
| 33 |
+
RUN python3 ./transformers/utils/past_ci_versions.py --framework $FRAMEWORK --version $VERSION
|
| 34 |
+
|
| 35 |
+
# Install the target framework
|
| 36 |
+
RUN echo "INSTALL_CMD = $INSTALL_CMD"
|
| 37 |
+
RUN $INSTALL_CMD
|
| 38 |
+
|
| 39 |
+
RUN [ "$FRAMEWORK" != "pytorch" ] && echo "`deepspeed-testing` installation is skipped" || python3 -m pip install --no-cache-dir ./transformers[deepspeed-testing]
|
| 40 |
+
|
| 41 |
+
# Remove `accelerate`: it requires `torch`, and this causes import issues for TF-only testing
|
| 42 |
+
# We will install `accelerate@main` in Past CI workflow file
|
| 43 |
+
RUN python3 -m pip uninstall -y accelerate
|
| 44 |
+
|
| 45 |
+
# Uninstall `torch-tensorrt` and `apex` shipped with the base image
|
| 46 |
+
RUN python3 -m pip uninstall -y torch-tensorrt apex
|
| 47 |
+
|
| 48 |
+
# Pre-build **nightly** release of DeepSpeed, so it would be ready for testing (otherwise, the 1st deepspeed test will timeout)
|
| 49 |
+
RUN python3 -m pip uninstall -y deepspeed
|
| 50 |
+
# This has to be run inside the GPU VMs running the tests. (So far, it fails here due to GPU checks during compilation.)
|
| 51 |
+
# Issue: https://github.com/deepspeedai/DeepSpeed/issues/2010
|
| 52 |
+
# RUN git clone https://github.com/deepspeedai/DeepSpeed && cd DeepSpeed && rm -rf build && \
|
| 53 |
+
# DS_BUILD_CPU_ADAM=1 DS_BUILD_FUSED_ADAM=1 DS_BUILD_UTILS=1 python3 -m pip install . --global-option="build_ext" --global-option="-j8" --no-cache -v --disable-pip-version-check 2>&1
|
| 54 |
+
|
| 55 |
+
RUN python3 -m pip install -U "itsdangerous<2.1.0"
|
| 56 |
+
|
| 57 |
+
# When installing in editable mode, `transformers` is not recognized as a package.
|
| 58 |
+
# this line must be added in order for python to be aware of transformers.
|
| 59 |
+
RUN cd transformers && python3 setup.py develop
|
tasks/tasksmith-441eeab80047/environment/source/docker/transformers-pytorch-amd-gpu/Dockerfile
ADDED
|
@@ -0,0 +1,35 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
FROM rocm/dev-ubuntu-22.04:6.2.4
|
| 2 |
+
LABEL maintainer="Hugging Face"
|
| 3 |
+
|
| 4 |
+
ARG DEBIAN_FRONTEND=noninteractive
|
| 5 |
+
|
| 6 |
+
RUN apt update && \
|
| 7 |
+
apt install -y --no-install-recommends git libsndfile1-dev tesseract-ocr espeak-ng python3 python3-dev python3-pip python3-dev ffmpeg git-lfs && \
|
| 8 |
+
apt clean && \
|
| 9 |
+
rm -rf /var/lib/apt/lists/*
|
| 10 |
+
|
| 11 |
+
RUN git lfs install
|
| 12 |
+
|
| 13 |
+
RUN python3 -m pip install --no-cache-dir --upgrade pip numpy
|
| 14 |
+
|
| 15 |
+
RUN python3 -m pip install torch torchvision torchaudio --index-url https://download.pytorch.org/whl/rocm6.2.4
|
| 16 |
+
|
| 17 |
+
RUN python3 -m pip install --no-cache-dir --upgrade importlib-metadata setuptools ninja git+https://github.com/facebookresearch/detectron2.git pytesseract "itsdangerous<2.1.0"
|
| 18 |
+
|
| 19 |
+
ARG REF=main
|
| 20 |
+
WORKDIR /
|
| 21 |
+
|
| 22 |
+
# Invalidate docker cache from here if new commit is available.
|
| 23 |
+
ADD https://api.github.com/repos/huggingface/transformers/git/refs/heads/main version.json
|
| 24 |
+
RUN git clone https://github.com/huggingface/transformers && cd transformers && git checkout $REF
|
| 25 |
+
|
| 26 |
+
RUN python3 -m pip install --no-cache-dir -e ./transformers[dev-torch,testing,video]
|
| 27 |
+
|
| 28 |
+
RUN python3 -m pip uninstall -y tensorflow flax
|
| 29 |
+
|
| 30 |
+
# When installing in editable mode, `transformers` is not recognized as a package.
|
| 31 |
+
# this line must be added in order for python to be aware of transformers.
|
| 32 |
+
RUN cd transformers && python3 setup.py develop
|
| 33 |
+
|
| 34 |
+
# Remove nvml and nvidia-ml-py as it is not compatible with ROCm. apex is not tested on NVIDIA either.
|
| 35 |
+
RUN python3 -m pip uninstall py3nvml pynvml nvidia-ml-py apex -y
|
tasks/tasksmith-441eeab80047/environment/source/docker/transformers-pytorch-deepspeed-amd-gpu/Dockerfile
ADDED
|
@@ -0,0 +1,50 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
FROM rocm/dev-ubuntu-22.04:6.2.4
|
| 2 |
+
LABEL maintainer="Hugging Face"
|
| 3 |
+
|
| 4 |
+
ARG DEBIAN_FRONTEND=noninteractive
|
| 5 |
+
ARG PYTORCH='2.6.0'
|
| 6 |
+
ARG TORCH_VISION='0.21.0'
|
| 7 |
+
ARG TORCH_AUDIO='2.6.0'
|
| 8 |
+
ARG ROCM='6.2.4'
|
| 9 |
+
|
| 10 |
+
RUN apt update && \
|
| 11 |
+
apt install -y --no-install-recommends \
|
| 12 |
+
libaio-dev \
|
| 13 |
+
git \
|
| 14 |
+
# These are required to build deepspeed.
|
| 15 |
+
python3-dev \
|
| 16 |
+
python-is-python3 \
|
| 17 |
+
rocrand-dev \
|
| 18 |
+
rocthrust-dev \
|
| 19 |
+
rocblas-dev \
|
| 20 |
+
hipsolver-dev \
|
| 21 |
+
hipsparse-dev \
|
| 22 |
+
hipblas-dev \
|
| 23 |
+
hipblaslt-dev && \
|
| 24 |
+
apt clean && \
|
| 25 |
+
rm -rf /var/lib/apt/lists/*
|
| 26 |
+
|
| 27 |
+
RUN python3 -m pip install --no-cache-dir --upgrade pip ninja "pydantic>=2.0.0"
|
| 28 |
+
RUN python3 -m pip uninstall -y apex torch torchvision torchaudio
|
| 29 |
+
RUN python3 -m pip install torch==$PYTORCH torchvision==$TORCH_VISION torchaudio==$TORCH_AUDIO --index-url https://download.pytorch.org/whl/rocm$ROCM --no-cache-dir
|
| 30 |
+
|
| 31 |
+
# Pre-build DeepSpeed, so it's be ready for testing (to avoid timeout)
|
| 32 |
+
RUN DS_BUILD_CPU_ADAM=1 DS_BUILD_FUSED_ADAM=1 python3 -m pip install deepspeed --global-option="build_ext" --global-option="-j8" --no-cache-dir -v --disable-pip-version-check 2>&1
|
| 33 |
+
|
| 34 |
+
ARG REF=main
|
| 35 |
+
WORKDIR /
|
| 36 |
+
|
| 37 |
+
# Invalidate docker cache from here if new commit is available.
|
| 38 |
+
ADD https://api.github.com/repos/huggingface/transformers/git/refs/heads/main version.json
|
| 39 |
+
RUN git clone https://github.com/huggingface/transformers && cd transformers && git checkout $REF
|
| 40 |
+
|
| 41 |
+
RUN python3 -m pip install --no-cache-dir ./transformers[accelerate,testing,sentencepiece,sklearn]
|
| 42 |
+
|
| 43 |
+
# When installing in editable mode, `transformers` is not recognized as a package.
|
| 44 |
+
# this line must be added in order for python to be aware of transformers.
|
| 45 |
+
RUN cd transformers && python3 setup.py develop
|
| 46 |
+
|
| 47 |
+
RUN python3 -c "from deepspeed.launcher.runner import main"
|
| 48 |
+
|
| 49 |
+
# Remove nvml as it is not compatible with ROCm
|
| 50 |
+
RUN python3 -m pip uninstall py3nvml pynvml nvidia-ml-py apex -y
|
tasks/tasksmith-441eeab80047/environment/source/docker/transformers-pytorch-deepspeed-latest-gpu/Dockerfile
ADDED
|
@@ -0,0 +1,53 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
# https://docs.nvidia.com/deeplearning/frameworks/pytorch-release-notes/rel-23-11.html#rel-23-11
|
| 2 |
+
FROM nvcr.io/nvidia/pytorch:23.11-py3
|
| 3 |
+
LABEL maintainer="Hugging Face"
|
| 4 |
+
|
| 5 |
+
ARG DEBIAN_FRONTEND=noninteractive
|
| 6 |
+
|
| 7 |
+
ARG PYTORCH='2.2.0'
|
| 8 |
+
# Example: `cu102`, `cu113`, etc.
|
| 9 |
+
ARG CUDA='cu121'
|
| 10 |
+
|
| 11 |
+
RUN apt -y update
|
| 12 |
+
RUN apt install -y libaio-dev
|
| 13 |
+
RUN python3 -m pip install --no-cache-dir --upgrade pip
|
| 14 |
+
|
| 15 |
+
ARG REF=main
|
| 16 |
+
RUN git clone https://github.com/huggingface/transformers && cd transformers && git checkout $REF
|
| 17 |
+
|
| 18 |
+
RUN python3 -m pip install --no-cache-dir ./transformers[deepspeed-testing]
|
| 19 |
+
|
| 20 |
+
# Install latest release PyTorch
|
| 21 |
+
# (PyTorch must be installed before pre-compiling any DeepSpeed c++/cuda ops.)
|
| 22 |
+
# (https://www.deepspeed.ai/tutorials/advanced-install/#pre-install-deepspeed-ops)
|
| 23 |
+
RUN python3 -m pip uninstall -y torch torchvision torchaudio && python3 -m pip install --no-cache-dir -U torch==$PYTORCH torchvision torchaudio --extra-index-url https://download.pytorch.org/whl/$CUDA
|
| 24 |
+
|
| 25 |
+
RUN python3 -m pip install --no-cache-dir git+https://github.com/huggingface/accelerate@main#egg=accelerate
|
| 26 |
+
|
| 27 |
+
# Uninstall `transformer-engine` shipped with the base image
|
| 28 |
+
RUN python3 -m pip uninstall -y transformer-engine
|
| 29 |
+
|
| 30 |
+
# Uninstall `torch-tensorrt` shipped with the base image
|
| 31 |
+
RUN python3 -m pip uninstall -y torch-tensorrt
|
| 32 |
+
|
| 33 |
+
# recompile apex
|
| 34 |
+
RUN python3 -m pip uninstall -y apex
|
| 35 |
+
# RUN git clone https://github.com/NVIDIA/apex
|
| 36 |
+
# `MAX_JOBS=1` disables parallel building to avoid cpu memory OOM when building image on GitHub Action (standard) runners
|
| 37 |
+
# TODO: check if there is alternative way to install latest apex
|
| 38 |
+
# RUN cd apex && MAX_JOBS=1 python3 -m pip install --global-option="--cpp_ext" --global-option="--cuda_ext" --no-cache -v --disable-pip-version-check .
|
| 39 |
+
|
| 40 |
+
# Pre-build **latest** DeepSpeed, so it would be ready for testing (otherwise, the 1st deepspeed test will timeout)
|
| 41 |
+
RUN python3 -m pip uninstall -y deepspeed
|
| 42 |
+
# This has to be run (again) inside the GPU VMs running the tests.
|
| 43 |
+
# The installation works here, but some tests fail, if we don't pre-build deepspeed again in the VMs running the tests.
|
| 44 |
+
# TODO: Find out why test fail.
|
| 45 |
+
RUN DS_BUILD_CPU_ADAM=1 DS_BUILD_FUSED_ADAM=1 python3 -m pip install deepspeed --global-option="build_ext" --global-option="-j8" --no-cache -v --disable-pip-version-check 2>&1
|
| 46 |
+
|
| 47 |
+
# When installing in editable mode, `transformers` is not recognized as a package.
|
| 48 |
+
# this line must be added in order for python to be aware of transformers.
|
| 49 |
+
RUN cd transformers && python3 setup.py develop
|
| 50 |
+
|
| 51 |
+
# The base image ships with `pydantic==1.8.2` which is not working - i.e. the next command fails
|
| 52 |
+
RUN python3 -m pip install -U --no-cache-dir "pydantic>=2.0.0"
|
| 53 |
+
RUN python3 -c "from deepspeed.launcher.runner import main"
|
tasks/tasksmith-441eeab80047/environment/source/docker/transformers-pytorch-deepspeed-nightly-gpu/Dockerfile
ADDED
|
@@ -0,0 +1,64 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
# https://docs.nvidia.com/deeplearning/frameworks/pytorch-release-notes/rel-23-11.html#rel-23-11
|
| 2 |
+
FROM nvcr.io/nvidia/pytorch:23.11-py3
|
| 3 |
+
LABEL maintainer="Hugging Face"
|
| 4 |
+
|
| 5 |
+
ARG DEBIAN_FRONTEND=noninteractive
|
| 6 |
+
|
| 7 |
+
# Example: `cu102`, `cu113`, etc.
|
| 8 |
+
ARG CUDA='cu121'
|
| 9 |
+
|
| 10 |
+
RUN apt -y update
|
| 11 |
+
RUN apt install -y libaio-dev
|
| 12 |
+
RUN python3 -m pip install --no-cache-dir --upgrade pip
|
| 13 |
+
|
| 14 |
+
ARG REF=main
|
| 15 |
+
RUN git clone https://github.com/huggingface/transformers && cd transformers && git checkout $REF
|
| 16 |
+
|
| 17 |
+
RUN python3 -m pip uninstall -y torch torchvision torchaudio
|
| 18 |
+
|
| 19 |
+
# Install **nightly** release PyTorch (flag `--pre`)
|
| 20 |
+
# (PyTorch must be installed before pre-compiling any DeepSpeed c++/cuda ops.)
|
| 21 |
+
# (https://www.deepspeed.ai/tutorials/advanced-install/#pre-install-deepspeed-ops)
|
| 22 |
+
RUN python3 -m pip install --no-cache-dir -U --pre torch torchvision torchaudio --extra-index-url https://download.pytorch.org/whl/nightly/$CUDA
|
| 23 |
+
|
| 24 |
+
RUN python3 -m pip install --no-cache-dir ./transformers[deepspeed-testing]
|
| 25 |
+
|
| 26 |
+
RUN python3 -m pip install --no-cache-dir git+https://github.com/huggingface/accelerate@main#egg=accelerate
|
| 27 |
+
|
| 28 |
+
# Uninstall `transformer-engine` shipped with the base image
|
| 29 |
+
RUN python3 -m pip uninstall -y transformer-engine
|
| 30 |
+
|
| 31 |
+
# Uninstall `torch-tensorrt` and `apex` shipped with the base image
|
| 32 |
+
RUN python3 -m pip uninstall -y torch-tensorrt apex
|
| 33 |
+
|
| 34 |
+
# Pre-build **nightly** release of DeepSpeed, so it would be ready for testing (otherwise, the 1st deepspeed test will timeout)
|
| 35 |
+
RUN python3 -m pip uninstall -y deepspeed
|
| 36 |
+
# This has to be run inside the GPU VMs running the tests. (So far, it fails here due to GPU checks during compilation.)
|
| 37 |
+
# Issue: https://github.com/deepspeedai/DeepSpeed/issues/2010
|
| 38 |
+
# RUN git clone https://github.com/deepspeedai/DeepSpeed && cd DeepSpeed && rm -rf build && \
|
| 39 |
+
# DS_BUILD_CPU_ADAM=1 DS_BUILD_FUSED_ADAM=1 DS_BUILD_UTILS=1 python3 -m pip install . --global-option="build_ext" --global-option="-j8" --no-cache -v --disable-pip-version-check 2>&1
|
| 40 |
+
|
| 41 |
+
## For `torchdynamo` tests
|
| 42 |
+
## (see https://github.com/huggingface/transformers/pull/17765)
|
| 43 |
+
#RUN git clone https://github.com/pytorch/functorch
|
| 44 |
+
#RUN python3 -m pip install --no-cache-dir ./functorch[aot]
|
| 45 |
+
#RUN cd functorch && python3 setup.py develop
|
| 46 |
+
#
|
| 47 |
+
#RUN git clone https://github.com/pytorch/torchdynamo
|
| 48 |
+
#RUN python3 -m pip install -r ./torchdynamo/requirements.txt
|
| 49 |
+
#RUN cd torchdynamo && python3 setup.py develop
|
| 50 |
+
#
|
| 51 |
+
## install TensorRT
|
| 52 |
+
#RUN python3 -m pip install --no-cache-dir -U nvidia-pyindex
|
| 53 |
+
#RUN python3 -m pip install --no-cache-dir -U nvidia-tensorrt==8.2.4.2
|
| 54 |
+
#
|
| 55 |
+
## install torch_tensorrt (fx path)
|
| 56 |
+
#RUN git clone https://github.com/pytorch/TensorRT.git
|
| 57 |
+
#RUN cd TensorRT/py && python3 setup.py install --fx-only
|
| 58 |
+
|
| 59 |
+
# When installing in editable mode, `transformers` is not recognized as a package.
|
| 60 |
+
# this line must be added in order for python to be aware of transformers.
|
| 61 |
+
RUN cd transformers && python3 setup.py develop
|
| 62 |
+
|
| 63 |
+
# Disable for now as deepspeed is not installed above. To be enabled once the issue is fixed.
|
| 64 |
+
# RUN python3 -c "from deepspeed.launcher.runner import main"
|
tasks/tasksmith-441eeab80047/environment/source/docker/transformers-pytorch-gpu/Dockerfile
ADDED
|
@@ -0,0 +1,33 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
FROM nvidia/cuda:12.1.0-cudnn8-devel-ubuntu22.04
|
| 2 |
+
LABEL maintainer="Hugging Face"
|
| 3 |
+
|
| 4 |
+
ARG DEBIAN_FRONTEND=noninteractive
|
| 5 |
+
|
| 6 |
+
RUN apt update
|
| 7 |
+
RUN apt install -y git libsndfile1-dev tesseract-ocr espeak-ng python3 python3-pip ffmpeg
|
| 8 |
+
RUN python3 -m pip install --no-cache-dir --upgrade pip
|
| 9 |
+
|
| 10 |
+
ARG REF=main
|
| 11 |
+
RUN git clone https://github.com/huggingface/transformers && cd transformers && git checkout $REF
|
| 12 |
+
|
| 13 |
+
# If set to nothing, will install the latest version
|
| 14 |
+
ARG PYTORCH='2.6.0'
|
| 15 |
+
ARG TORCH_VISION=''
|
| 16 |
+
ARG TORCH_AUDIO=''
|
| 17 |
+
# Example: `cu102`, `cu113`, etc.
|
| 18 |
+
ARG CUDA='cu121'
|
| 19 |
+
|
| 20 |
+
RUN [ ${#PYTORCH} -gt 0 ] && VERSION='torch=='$PYTORCH'.*' || VERSION='torch'; python3 -m pip install --no-cache-dir -U $VERSION --extra-index-url https://download.pytorch.org/whl/$CUDA
|
| 21 |
+
RUN [ ${#TORCH_VISION} -gt 0 ] && VERSION='torchvision=='TORCH_VISION'.*' || VERSION='torchvision'; python3 -m pip install --no-cache-dir -U $VERSION --extra-index-url https://download.pytorch.org/whl/$CUDA
|
| 22 |
+
RUN [ ${#TORCH_AUDIO} -gt 0 ] && VERSION='torchaudio=='TORCH_AUDIO'.*' || VERSION='torchaudio'; python3 -m pip install --no-cache-dir -U $VERSION --extra-index-url https://download.pytorch.org/whl/$CUDA
|
| 23 |
+
|
| 24 |
+
RUN python3 -m pip install --no-cache-dir -e ./transformers[dev-torch,testing,video]
|
| 25 |
+
|
| 26 |
+
RUN python3 -m pip uninstall -y tensorflow flax
|
| 27 |
+
|
| 28 |
+
RUN python3 -m pip install --no-cache-dir git+https://github.com/facebookresearch/detectron2.git pytesseract
|
| 29 |
+
RUN python3 -m pip install -U "itsdangerous<2.1.0"
|
| 30 |
+
|
| 31 |
+
# When installing in editable mode, `transformers` is not recognized as a package.
|
| 32 |
+
# this line must be added in order for python to be aware of transformers.
|
| 33 |
+
RUN cd transformers && python3 setup.py develop
|
tasks/tasksmith-441eeab80047/environment/source/docker/transformers-pytorch-tpu/Dockerfile
ADDED
|
@@ -0,0 +1,65 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
FROM google/cloud-sdk:slim
|
| 2 |
+
|
| 3 |
+
# Build args.
|
| 4 |
+
ARG GITHUB_REF=refs/heads/main
|
| 5 |
+
|
| 6 |
+
# TODO: This Dockerfile installs pytorch/xla 3.6 wheels. There are also 3.7
|
| 7 |
+
# wheels available; see below.
|
| 8 |
+
ENV PYTHON_VERSION=3.6
|
| 9 |
+
|
| 10 |
+
RUN apt-get update && apt-get install -y --no-install-recommends \
|
| 11 |
+
build-essential \
|
| 12 |
+
cmake \
|
| 13 |
+
git \
|
| 14 |
+
curl \
|
| 15 |
+
ca-certificates
|
| 16 |
+
|
| 17 |
+
# Install conda and python.
|
| 18 |
+
# NOTE new Conda does not forward the exit status... https://github.com/conda/conda/issues/8385
|
| 19 |
+
RUN curl -o ~/miniconda.sh https://repo.anaconda.com/miniconda/Miniconda3-4.7.12-Linux-x86_64.sh && \
|
| 20 |
+
chmod +x ~/miniconda.sh && \
|
| 21 |
+
~/miniconda.sh -b && \
|
| 22 |
+
rm ~/miniconda.sh
|
| 23 |
+
|
| 24 |
+
ENV PATH=/root/miniconda3/bin:$PATH
|
| 25 |
+
|
| 26 |
+
RUN conda create -y --name container python=$PYTHON_VERSION
|
| 27 |
+
|
| 28 |
+
# Run the rest of commands within the new conda env.
|
| 29 |
+
# Use absolute path to appease Codefactor.
|
| 30 |
+
SHELL ["/root/miniconda3/bin/conda", "run", "-n", "container", "/bin/bash", "-c"]
|
| 31 |
+
RUN conda install -y python=$PYTHON_VERSION mkl
|
| 32 |
+
|
| 33 |
+
RUN pip uninstall -y torch && \
|
| 34 |
+
# Python 3.7 wheels are available. Replace cp36-cp36m with cp37-cp37m
|
| 35 |
+
gsutil cp 'gs://tpu-pytorch/wheels/torch-nightly-cp${PYTHON_VERSION/./}-cp${PYTHON_VERSION/./}m-linux_x86_64.whl' . && \
|
| 36 |
+
gsutil cp 'gs://tpu-pytorch/wheels/torch_xla-nightly-cp${PYTHON_VERSION/./}-cp${PYTHON_VERSION/./}m-linux_x86_64.whl' . && \
|
| 37 |
+
gsutil cp 'gs://tpu-pytorch/wheels/torchvision-nightly-cp${PYTHON_VERSION/./}-cp${PYTHON_VERSION/./}m-linux_x86_64.whl' . && \
|
| 38 |
+
pip install 'torch-nightly-cp${PYTHON_VERSION/./}-cp${PYTHON_VERSION/./}m-linux_x86_64.whl' && \
|
| 39 |
+
pip install 'torch_xla-nightly-cp${PYTHON_VERSION/./}-cp${PYTHON_VERSION/./}m-linux_x86_64.whl' && \
|
| 40 |
+
pip install 'torchvision-nightly-cp${PYTHON_VERSION/./}-cp${PYTHON_VERSION/./}m-linux_x86_64.whl' && \
|
| 41 |
+
rm 'torch-nightly-cp${PYTHON_VERSION/./}-cp${PYTHON_VERSION/./}m-linux_x86_64.whl' && \
|
| 42 |
+
rm 'torch_xla-nightly-cp${PYTHON_VERSION/./}-cp${PYTHON_VERSION/./}m-linux_x86_64.whl' && \
|
| 43 |
+
rm 'torchvision-nightly-cp${PYTHON_VERSION/./}-cp${PYTHON_VERSION/./}m-linux_x86_64.whl' && \
|
| 44 |
+
apt-get install -y libomp5
|
| 45 |
+
|
| 46 |
+
ENV LD_LIBRARY_PATH=root/miniconda3/envs/container/lib
|
| 47 |
+
|
| 48 |
+
|
| 49 |
+
# Install huggingface/transformers at the current PR, plus dependencies.
|
| 50 |
+
RUN git clone https://github.com/huggingface/transformers.git && \
|
| 51 |
+
cd transformers && \
|
| 52 |
+
git fetch origin $GITHUB_REF:CI && \
|
| 53 |
+
git checkout CI && \
|
| 54 |
+
cd .. && \
|
| 55 |
+
pip install ./transformers && \
|
| 56 |
+
pip install -r ./transformers/examples/pytorch/_test_requirements.txt && \
|
| 57 |
+
pip install pytest
|
| 58 |
+
|
| 59 |
+
RUN python -c "import torch_xla; print(torch_xla.__version__)"
|
| 60 |
+
RUN python -c "import transformers as trf; print(trf.__version__)"
|
| 61 |
+
RUN conda init bash
|
| 62 |
+
COPY docker-entrypoint.sh /usr/local/bin/
|
| 63 |
+
RUN chmod +x /usr/local/bin/docker-entrypoint.sh
|
| 64 |
+
ENTRYPOINT ["/usr/local/bin/docker-entrypoint.sh"]
|
| 65 |
+
CMD ["bash"]
|
tasks/tasksmith-441eeab80047/environment/source/docker/transformers-pytorch-tpu/bert-base-cased.jsonnet
ADDED
|
@@ -0,0 +1,38 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
local base = import 'templates/base.libsonnet';
|
| 2 |
+
local tpus = import 'templates/tpus.libsonnet';
|
| 3 |
+
local utils = import "templates/utils.libsonnet";
|
| 4 |
+
local volumes = import "templates/volumes.libsonnet";
|
| 5 |
+
|
| 6 |
+
local bertBaseCased = base.BaseTest {
|
| 7 |
+
frameworkPrefix: "hf",
|
| 8 |
+
modelName: "bert-base-cased",
|
| 9 |
+
mode: "example",
|
| 10 |
+
configMaps: [],
|
| 11 |
+
|
| 12 |
+
timeout: 3600, # 1 hour, in seconds
|
| 13 |
+
|
| 14 |
+
image: std.extVar('image'),
|
| 15 |
+
imageTag: std.extVar('image-tag'),
|
| 16 |
+
|
| 17 |
+
tpuSettings+: {
|
| 18 |
+
softwareVersion: "pytorch-nightly",
|
| 19 |
+
},
|
| 20 |
+
accelerator: tpus.v3_8,
|
| 21 |
+
|
| 22 |
+
volumeMap+: {
|
| 23 |
+
datasets: volumes.PersistentVolumeSpec {
|
| 24 |
+
name: "huggingface-cluster-disk",
|
| 25 |
+
mountPath: "/datasets",
|
| 26 |
+
},
|
| 27 |
+
},
|
| 28 |
+
command: utils.scriptCommand(
|
| 29 |
+
|||
|
| 30 |
+
python -m pytest -s transformers/examples/pytorch/test_xla_examples.py -v
|
| 31 |
+
test_exit_code=$?
|
| 32 |
+
echo "\nFinished running commands.\n"
|
| 33 |
+
test $test_exit_code -eq 0
|
| 34 |
+
|||
|
| 35 |
+
),
|
| 36 |
+
};
|
| 37 |
+
|
| 38 |
+
bertBaseCased.oneshotJob
|
tasks/tasksmith-441eeab80047/environment/source/docker/transformers-pytorch-tpu/dataset.yaml
ADDED
|
@@ -0,0 +1,32 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
apiVersion: v1
|
| 2 |
+
kind: PersistentVolume
|
| 3 |
+
metadata:
|
| 4 |
+
name: huggingface-cluster-disk
|
| 5 |
+
spec:
|
| 6 |
+
storageClassName: ""
|
| 7 |
+
capacity:
|
| 8 |
+
storage: 500Gi
|
| 9 |
+
accessModes:
|
| 10 |
+
- ReadOnlyMany
|
| 11 |
+
claimRef:
|
| 12 |
+
namespace: default
|
| 13 |
+
name: huggingface-cluster-disk-claim
|
| 14 |
+
gcePersistentDisk:
|
| 15 |
+
pdName: huggingface-cluster-disk
|
| 16 |
+
fsType: ext4
|
| 17 |
+
readOnly: true
|
| 18 |
+
---
|
| 19 |
+
apiVersion: v1
|
| 20 |
+
kind: PersistentVolumeClaim
|
| 21 |
+
metadata:
|
| 22 |
+
name: huggingface-cluster-disk-claim
|
| 23 |
+
spec:
|
| 24 |
+
# Specify "" as the storageClassName so it matches the PersistentVolume's StorageClass.
|
| 25 |
+
# A nil storageClassName value uses the default StorageClass. For details, see
|
| 26 |
+
# https://kubernetes.io/docs/concepts/storage/persistent-volumes/#class-1
|
| 27 |
+
storageClassName: ""
|
| 28 |
+
accessModes:
|
| 29 |
+
- ReadOnlyMany
|
| 30 |
+
resources:
|
| 31 |
+
requests:
|
| 32 |
+
storage: 1Ki
|
tasks/tasksmith-441eeab80047/environment/source/docker/transformers-pytorch-tpu/docker-entrypoint.sh
ADDED
|
@@ -0,0 +1,8 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
#!/bin/bash
|
| 2 |
+
source ~/.bashrc
|
| 3 |
+
echo "running docker-entrypoint.sh"
|
| 4 |
+
conda activate container
|
| 5 |
+
echo $KUBE_GOOGLE_CLOUD_TPU_ENDPOINTS
|
| 6 |
+
echo "printed TPU info"
|
| 7 |
+
export XRT_TPU_CONFIG="tpu_worker;0;${KUBE_GOOGLE_CLOUD_TPU_ENDPOINTS:7}"
|
| 8 |
+
exec "$@"#!/bin/bash
|
tasks/tasksmith-441eeab80047/environment/source/docker/transformers-quantization-latest-gpu/Dockerfile
ADDED
|
@@ -0,0 +1,87 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
FROM nvidia/cuda:12.1.1-cudnn8-devel-ubuntu22.04
|
| 2 |
+
LABEL maintainer="Hugging Face"
|
| 3 |
+
|
| 4 |
+
ARG DEBIAN_FRONTEND=noninteractive
|
| 5 |
+
|
| 6 |
+
# Use login shell to read variables from `~/.profile` (to pass dynamic created variables between RUN commands)
|
| 7 |
+
SHELL ["sh", "-lc"]
|
| 8 |
+
|
| 9 |
+
# The following `ARG` are mainly used to specify the versions explicitly & directly in this docker file, and not meant
|
| 10 |
+
# to be used as arguments for docker build (so far).
|
| 11 |
+
|
| 12 |
+
ARG PYTORCH='2.6.0'
|
| 13 |
+
# Example: `cu102`, `cu113`, etc.
|
| 14 |
+
ARG CUDA='cu121'
|
| 15 |
+
|
| 16 |
+
RUN apt update
|
| 17 |
+
RUN apt install -y git libsndfile1-dev tesseract-ocr espeak-ng python3 python3-pip ffmpeg
|
| 18 |
+
RUN python3 -m pip install --no-cache-dir --upgrade pip
|
| 19 |
+
|
| 20 |
+
ARG REF=main
|
| 21 |
+
RUN git clone https://github.com/huggingface/transformers && cd transformers && git checkout $REF
|
| 22 |
+
|
| 23 |
+
RUN [ ${#PYTORCH} -gt 0 ] && VERSION='torch=='$PYTORCH'.*' || VERSION='torch'; echo "export VERSION='$VERSION'" >> ~/.profile
|
| 24 |
+
RUN echo torch=$VERSION
|
| 25 |
+
# `torchvision` and `torchaudio` should be installed along with `torch`, especially for nightly build.
|
| 26 |
+
# Currently, let's just use their latest releases (when `torch` is installed with a release version)
|
| 27 |
+
RUN python3 -m pip install --no-cache-dir -U $VERSION torchvision torchaudio --extra-index-url https://download.pytorch.org/whl/$CUDA
|
| 28 |
+
|
| 29 |
+
RUN python3 -m pip install --no-cache-dir git+https://github.com/huggingface/accelerate@main#egg=accelerate
|
| 30 |
+
|
| 31 |
+
# needed in bnb and awq
|
| 32 |
+
RUN python3 -m pip install --no-cache-dir einops
|
| 33 |
+
|
| 34 |
+
# Add bitsandbytes for mixed int8 testing
|
| 35 |
+
RUN python3 -m pip install --no-cache-dir bitsandbytes
|
| 36 |
+
|
| 37 |
+
# Add gptqmodel for gtpq quantization testing, installed from source for pytorch==2.6.0 compatibility
|
| 38 |
+
RUN python3 -m pip install lm_eval
|
| 39 |
+
RUN git clone https://github.com/ModelCloud/GPTQModel.git && cd GPTQModel && pip install -v . --no-build-isolation
|
| 40 |
+
|
| 41 |
+
# Add optimum for gptq quantization testing
|
| 42 |
+
RUN python3 -m pip install --no-cache-dir git+https://github.com/huggingface/optimum@main#egg=optimum
|
| 43 |
+
|
| 44 |
+
# Add PEFT
|
| 45 |
+
RUN python3 -m pip install --no-cache-dir git+https://github.com/huggingface/peft@main#egg=peft
|
| 46 |
+
|
| 47 |
+
# Add aqlm for quantization testing
|
| 48 |
+
RUN python3 -m pip install --no-cache-dir aqlm[gpu]==1.0.2
|
| 49 |
+
|
| 50 |
+
# Add vptq for quantization testing
|
| 51 |
+
RUN pip install vptq
|
| 52 |
+
|
| 53 |
+
# Add spqr for quantization testing
|
| 54 |
+
# Commented for now as No matching distribution found we need to reach out to the authors
|
| 55 |
+
# RUN python3 -m pip install --no-cache-dir spqr_quant[gpu]
|
| 56 |
+
|
| 57 |
+
# Add hqq for quantization testing
|
| 58 |
+
RUN python3 -m pip install --no-cache-dir hqq
|
| 59 |
+
|
| 60 |
+
# For GGUF tests
|
| 61 |
+
RUN python3 -m pip install --no-cache-dir gguf
|
| 62 |
+
|
| 63 |
+
# Add autoawq for quantization testing
|
| 64 |
+
# New release v0.2.8
|
| 65 |
+
RUN python3 -m pip install --no-cache-dir autoawq[kernels]
|
| 66 |
+
|
| 67 |
+
# Add quanto for quantization testing
|
| 68 |
+
RUN python3 -m pip install --no-cache-dir optimum-quanto
|
| 69 |
+
|
| 70 |
+
# Add eetq for quantization testing
|
| 71 |
+
RUN git clone https://github.com/NetEase-FuXi/EETQ.git && cd EETQ/ && git submodule update --init --recursive && pip install .
|
| 72 |
+
|
| 73 |
+
# # Add flute-kernel and fast_hadamard_transform for quantization testing
|
| 74 |
+
# # Commented for now as they cause issues with the build
|
| 75 |
+
# # TODO: create a new workflow to test them
|
| 76 |
+
# RUN python3 -m pip install --no-cache-dir flute-kernel==0.4.1
|
| 77 |
+
# RUN python3 -m pip install --no-cache-dir git+https://github.com/Dao-AILab/fast-hadamard-transform.git
|
| 78 |
+
|
| 79 |
+
# Add compressed-tensors for quantization testing
|
| 80 |
+
RUN python3 -m pip install --no-cache-dir compressed-tensors
|
| 81 |
+
|
| 82 |
+
# Add transformers in editable mode
|
| 83 |
+
RUN python3 -m pip install --no-cache-dir -e ./transformers[dev-torch]
|
| 84 |
+
|
| 85 |
+
# When installing in editable mode, `transformers` is not recognized as a package.
|
| 86 |
+
# this line must be added in order for python to be aware of transformers.
|
| 87 |
+
RUN cd transformers && python3 setup.py develop
|
tasks/tasksmith-441eeab80047/environment/source/docker/transformers-tensorflow-gpu/Dockerfile
ADDED
|
@@ -0,0 +1,25 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
FROM nvidia/cuda:12.1.0-cudnn8-devel-ubuntu22.04
|
| 2 |
+
LABEL maintainer="Hugging Face"
|
| 3 |
+
|
| 4 |
+
ARG DEBIAN_FRONTEND=noninteractive
|
| 5 |
+
|
| 6 |
+
RUN apt update
|
| 7 |
+
RUN apt install -y git libsndfile1-dev tesseract-ocr espeak-ng python3 python3-pip ffmpeg
|
| 8 |
+
RUN python3 -m pip install --no-cache-dir --upgrade pip
|
| 9 |
+
|
| 10 |
+
ARG REF=main
|
| 11 |
+
RUN git clone https://github.com/huggingface/transformers && cd transformers && git checkout $REF
|
| 12 |
+
RUN python3 -m pip install --no-cache-dir -e ./transformers[dev-tensorflow,testing]
|
| 13 |
+
|
| 14 |
+
# If set to nothing, will install the latest version
|
| 15 |
+
ARG TENSORFLOW='2.13'
|
| 16 |
+
|
| 17 |
+
RUN [ ${#TENSORFLOW} -gt 0 ] && VERSION='tensorflow=='$TENSORFLOW'.*' || VERSION='tensorflow'; python3 -m pip install --no-cache-dir -U $VERSION
|
| 18 |
+
RUN python3 -m pip uninstall -y torch flax
|
| 19 |
+
RUN python3 -m pip install -U "itsdangerous<2.1.0"
|
| 20 |
+
|
| 21 |
+
RUN python3 -m pip install --no-cache-dir -U "tensorflow_probability<0.22"
|
| 22 |
+
|
| 23 |
+
# When installing in editable mode, `transformers` is not recognized as a package.
|
| 24 |
+
# this line must be added in order for python to be aware of transformers.
|
| 25 |
+
RUN cd transformers && python3 setup.py develop
|
tasks/tasksmith-441eeab80047/environment/source/docs/README.md
ADDED
|
@@ -0,0 +1,395 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
<!---
|
| 2 |
+
Copyright 2020 The HuggingFace Team. All rights reserved.
|
| 3 |
+
|
| 4 |
+
Licensed under the Apache License, Version 2.0 (the "License");
|
| 5 |
+
you may not use this file except in compliance with the License.
|
| 6 |
+
You may obtain a copy of the License at
|
| 7 |
+
|
| 8 |
+
http://www.apache.org/licenses/LICENSE-2.0
|
| 9 |
+
|
| 10 |
+
Unless required by applicable law or agreed to in writing, software
|
| 11 |
+
distributed under the License is distributed on an "AS IS" BASIS,
|
| 12 |
+
WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
|
| 13 |
+
See the License for the specific language governing permissions and
|
| 14 |
+
limitations under the License.
|
| 15 |
+
-->
|
| 16 |
+
|
| 17 |
+
# Generating the documentation
|
| 18 |
+
|
| 19 |
+
To generate the documentation, you first have to build it. Several packages are necessary to build the doc,
|
| 20 |
+
you can install them with the following command, at the root of the code repository:
|
| 21 |
+
|
| 22 |
+
```bash
|
| 23 |
+
pip install -e ".[docs]"
|
| 24 |
+
```
|
| 25 |
+
|
| 26 |
+
Then you need to install our special tool that builds the documentation:
|
| 27 |
+
|
| 28 |
+
```bash
|
| 29 |
+
pip install git+https://github.com/huggingface/doc-builder
|
| 30 |
+
```
|
| 31 |
+
|
| 32 |
+
---
|
| 33 |
+
**NOTE**
|
| 34 |
+
|
| 35 |
+
You only need to generate the documentation to inspect it locally (if you're planning changes and want to
|
| 36 |
+
check how they look before committing for instance). You don't have to commit the built documentation.
|
| 37 |
+
|
| 38 |
+
---
|
| 39 |
+
|
| 40 |
+
## Building the documentation
|
| 41 |
+
|
| 42 |
+
Once you have setup the `doc-builder` and additional packages, you can generate the documentation by
|
| 43 |
+
typing the following command:
|
| 44 |
+
|
| 45 |
+
```bash
|
| 46 |
+
doc-builder build transformers docs/source/en/ --build_dir ~/tmp/test-build
|
| 47 |
+
```
|
| 48 |
+
|
| 49 |
+
You can adapt the `--build_dir` to set any temporary folder that you prefer. This command will create it and generate
|
| 50 |
+
the MDX files that will be rendered as the documentation on the main website. You can inspect them in your favorite
|
| 51 |
+
Markdown editor.
|
| 52 |
+
|
| 53 |
+
## Previewing the documentation
|
| 54 |
+
|
| 55 |
+
To preview the docs, first install the `watchdog` module with:
|
| 56 |
+
|
| 57 |
+
```bash
|
| 58 |
+
pip install watchdog
|
| 59 |
+
```
|
| 60 |
+
|
| 61 |
+
Then run the following command:
|
| 62 |
+
|
| 63 |
+
```bash
|
| 64 |
+
doc-builder preview {package_name} {path_to_docs}
|
| 65 |
+
```
|
| 66 |
+
|
| 67 |
+
For example:
|
| 68 |
+
|
| 69 |
+
```bash
|
| 70 |
+
doc-builder preview transformers docs/source/en/
|
| 71 |
+
```
|
| 72 |
+
|
| 73 |
+
The docs will be viewable at [http://localhost:3000](http://localhost:3000). You can also preview the docs once you have opened a PR. You will see a bot add a comment to a link where the documentation with your changes lives.
|
| 74 |
+
|
| 75 |
+
---
|
| 76 |
+
**NOTE**
|
| 77 |
+
|
| 78 |
+
The `preview` command only works with existing doc files. When you add a completely new file, you need to update `_toctree.yml` & restart `preview` command (`ctrl-c` to stop it & call `doc-builder preview ...` again).
|
| 79 |
+
|
| 80 |
+
---
|
| 81 |
+
|
| 82 |
+
## Adding a new element to the navigation bar
|
| 83 |
+
|
| 84 |
+
Accepted files are Markdown (.md).
|
| 85 |
+
|
| 86 |
+
Create a file with its extension and put it in the source directory. You can then link it to the toc-tree by putting
|
| 87 |
+
the filename without the extension in the [`_toctree.yml`](https://github.com/huggingface/transformers/blob/main/docs/source/en/_toctree.yml) file.
|
| 88 |
+
|
| 89 |
+
## Renaming section headers and moving sections
|
| 90 |
+
|
| 91 |
+
It helps to keep the old links working when renaming the section header and/or moving sections from one document to another. This is because the old links are likely to be used in Issues, Forums, and Social media and it'd make for a much more superior user experience if users reading those months later could still easily navigate to the originally intended information.
|
| 92 |
+
|
| 93 |
+
Therefore, we simply keep a little map of moved sections at the end of the document where the original section was. The key is to preserve the original anchor.
|
| 94 |
+
|
| 95 |
+
So if you renamed a section from: "Section A" to "Section B", then you can add at the end of the file:
|
| 96 |
+
|
| 97 |
+
```
|
| 98 |
+
Sections that were moved:
|
| 99 |
+
|
| 100 |
+
[ <a href="#section-b">Section A</a><a id="section-a"></a> ]
|
| 101 |
+
```
|
| 102 |
+
and of course, if you moved it to another file, then:
|
| 103 |
+
|
| 104 |
+
```
|
| 105 |
+
Sections that were moved:
|
| 106 |
+
|
| 107 |
+
[ <a href="../new-file#section-b">Section A</a><a id="section-a"></a> ]
|
| 108 |
+
```
|
| 109 |
+
|
| 110 |
+
Use the relative style to link to the new file so that the versioned docs continue to work.
|
| 111 |
+
|
| 112 |
+
For an example of a rich moved section set please see the very end of [the Trainer doc](https://github.com/huggingface/transformers/blob/main/docs/source/en/main_classes/trainer.md).
|
| 113 |
+
|
| 114 |
+
|
| 115 |
+
## Writing Documentation - Specification
|
| 116 |
+
|
| 117 |
+
The `huggingface/transformers` documentation follows the
|
| 118 |
+
[Google documentation](https://sphinxcontrib-napoleon.readthedocs.io/en/latest/example_google.html) style for docstrings,
|
| 119 |
+
although we can write them directly in Markdown.
|
| 120 |
+
|
| 121 |
+
### Adding a new tutorial
|
| 122 |
+
|
| 123 |
+
Adding a new tutorial or section is done in two steps:
|
| 124 |
+
|
| 125 |
+
- Add a new file under `./source`. This file can either be ReStructuredText (.rst) or Markdown (.md).
|
| 126 |
+
- Link that file in `./source/_toctree.yml` on the correct toc-tree.
|
| 127 |
+
|
| 128 |
+
Make sure to put your new file under the proper section. It's unlikely to go in the first section (*Get Started*), so
|
| 129 |
+
depending on the intended targets (beginners, more advanced users, or researchers) it should go in sections two, three, or
|
| 130 |
+
four.
|
| 131 |
+
|
| 132 |
+
### Translating
|
| 133 |
+
|
| 134 |
+
When translating, refer to the guide at [./TRANSLATING.md](https://github.com/huggingface/transformers/blob/main/docs/TRANSLATING.md).
|
| 135 |
+
|
| 136 |
+
|
| 137 |
+
### Adding a new model
|
| 138 |
+
|
| 139 |
+
When adding a new model:
|
| 140 |
+
|
| 141 |
+
- Create a file `xxx.md` or under `./source/model_doc` (don't hesitate to copy an existing file as template).
|
| 142 |
+
- Link that file in `./source/_toctree.yml`.
|
| 143 |
+
- Write a short overview of the model:
|
| 144 |
+
- Overview with paper & authors
|
| 145 |
+
- Paper abstract
|
| 146 |
+
- Tips and tricks and how to use it best
|
| 147 |
+
- Add the classes that should be linked in the model. This generally includes the configuration, the tokenizer, and
|
| 148 |
+
every model of that class (the base model, alongside models with additional heads), both in PyTorch and TensorFlow.
|
| 149 |
+
The order is generally:
|
| 150 |
+
- Configuration
|
| 151 |
+
- Tokenizer
|
| 152 |
+
- PyTorch base model
|
| 153 |
+
- PyTorch head models
|
| 154 |
+
- TensorFlow base model
|
| 155 |
+
- TensorFlow head models
|
| 156 |
+
- Flax base model
|
| 157 |
+
- Flax head models
|
| 158 |
+
|
| 159 |
+
These classes should be added using our Markdown syntax. Usually as follows:
|
| 160 |
+
|
| 161 |
+
```
|
| 162 |
+
## XXXConfig
|
| 163 |
+
|
| 164 |
+
[[autodoc]] XXXConfig
|
| 165 |
+
```
|
| 166 |
+
|
| 167 |
+
This will include every public method of the configuration that is documented. If for some reason you wish for a method
|
| 168 |
+
not to be displayed in the documentation, you can do so by specifying which methods should be in the docs:
|
| 169 |
+
|
| 170 |
+
```
|
| 171 |
+
## XXXTokenizer
|
| 172 |
+
|
| 173 |
+
[[autodoc]] XXXTokenizer
|
| 174 |
+
- build_inputs_with_special_tokens
|
| 175 |
+
- get_special_tokens_mask
|
| 176 |
+
- create_token_type_ids_from_sequences
|
| 177 |
+
- save_vocabulary
|
| 178 |
+
```
|
| 179 |
+
|
| 180 |
+
If you just want to add a method that is not documented (for instance magic methods like `__call__` are not documented
|
| 181 |
+
by default) you can put the list of methods to add in a list that contains `all`:
|
| 182 |
+
|
| 183 |
+
```
|
| 184 |
+
## XXXTokenizer
|
| 185 |
+
|
| 186 |
+
[[autodoc]] XXXTokenizer
|
| 187 |
+
- all
|
| 188 |
+
- __call__
|
| 189 |
+
```
|
| 190 |
+
|
| 191 |
+
### Writing source documentation
|
| 192 |
+
|
| 193 |
+
Values that should be put in `code` should either be surrounded by backticks: \`like so\`. Note that argument names
|
| 194 |
+
and objects like True, None, or any strings should usually be put in `code`.
|
| 195 |
+
|
| 196 |
+
When mentioning a class, function, or method, it is recommended to use our syntax for internal links so that our tool
|
| 197 |
+
adds a link to its documentation with this syntax: \[\`XXXClass\`\] or \[\`function\`\]. This requires the class or
|
| 198 |
+
function to be in the main package.
|
| 199 |
+
|
| 200 |
+
If you want to create a link to some internal class or function, you need to
|
| 201 |
+
provide its path. For instance: \[\`utils.ModelOutput\`\]. This will be converted into a link with
|
| 202 |
+
`utils.ModelOutput` in the description. To get rid of the path and only keep the name of the object you are
|
| 203 |
+
linking to in the description, add a ~: \[\`~utils.ModelOutput\`\] will generate a link with `ModelOutput` in the description.
|
| 204 |
+
|
| 205 |
+
The same works for methods so you can either use \[\`XXXClass.method\`\] or \[\`~XXXClass.method\`\].
|
| 206 |
+
|
| 207 |
+
#### Defining arguments in a method
|
| 208 |
+
|
| 209 |
+
Arguments should be defined with the `Args:` (or `Arguments:` or `Parameters:`) prefix, followed by a line return and
|
| 210 |
+
an indentation. The argument should be followed by its type, with its shape if it is a tensor, a colon, and its
|
| 211 |
+
description:
|
| 212 |
+
|
| 213 |
+
```
|
| 214 |
+
Args:
|
| 215 |
+
n_layers (`int`): The number of layers of the model.
|
| 216 |
+
```
|
| 217 |
+
|
| 218 |
+
If the description is too long to fit in one line, another indentation is necessary before writing the description
|
| 219 |
+
after the argument.
|
| 220 |
+
|
| 221 |
+
Here's an example showcasing everything so far:
|
| 222 |
+
|
| 223 |
+
```
|
| 224 |
+
Args:
|
| 225 |
+
input_ids (`torch.LongTensor` of shape `(batch_size, sequence_length)`):
|
| 226 |
+
Indices of input sequence tokens in the vocabulary.
|
| 227 |
+
|
| 228 |
+
Indices can be obtained using [`AlbertTokenizer`]. See [`~PreTrainedTokenizer.encode`] and
|
| 229 |
+
[`~PreTrainedTokenizer.__call__`] for details.
|
| 230 |
+
|
| 231 |
+
[What are input IDs?](../glossary#input-ids)
|
| 232 |
+
```
|
| 233 |
+
|
| 234 |
+
For optional arguments or arguments with defaults we follow the following syntax: imagine we have a function with the
|
| 235 |
+
following signature:
|
| 236 |
+
|
| 237 |
+
```
|
| 238 |
+
def my_function(x: str = None, a: float = 1):
|
| 239 |
+
```
|
| 240 |
+
|
| 241 |
+
then its documentation should look like this:
|
| 242 |
+
|
| 243 |
+
```
|
| 244 |
+
Args:
|
| 245 |
+
x (`str`, *optional*):
|
| 246 |
+
This argument controls ...
|
| 247 |
+
a (`float`, *optional*, defaults to 1):
|
| 248 |
+
This argument is used to ...
|
| 249 |
+
```
|
| 250 |
+
|
| 251 |
+
Note that we always omit the "defaults to \`None\`" when None is the default for any argument. Also note that even
|
| 252 |
+
if the first line describing your argument type and its default gets long, you can't break it on several lines. You can
|
| 253 |
+
however, write as many lines as you want in the indented description (see the example above with `input_ids`).
|
| 254 |
+
|
| 255 |
+
#### Writing a multi-line code block
|
| 256 |
+
|
| 257 |
+
Multi-line code blocks can be useful for displaying examples. They are done between two lines of three backticks as usual in Markdown:
|
| 258 |
+
|
| 259 |
+
|
| 260 |
+
````
|
| 261 |
+
```
|
| 262 |
+
# first line of code
|
| 263 |
+
# second line
|
| 264 |
+
# etc
|
| 265 |
+
```
|
| 266 |
+
````
|
| 267 |
+
|
| 268 |
+
We follow the [doctest](https://docs.python.org/3/library/doctest.html) syntax for the examples to automatically test
|
| 269 |
+
the results to stay consistent with the library.
|
| 270 |
+
|
| 271 |
+
#### Writing a return block
|
| 272 |
+
|
| 273 |
+
The return block should be introduced with the `Returns:` prefix, followed by a line return and an indentation.
|
| 274 |
+
The first line should be the type of the return, followed by a line return. No need to indent further for the elements
|
| 275 |
+
building the return.
|
| 276 |
+
|
| 277 |
+
Here's an example of a single value return:
|
| 278 |
+
|
| 279 |
+
```python
|
| 280 |
+
Returns:
|
| 281 |
+
`List[int]`: A list of integers in the range [0, 1] --- 1 for a special token, 0 for a sequence token.
|
| 282 |
+
```
|
| 283 |
+
|
| 284 |
+
Here's an example of a tuple return, comprising several objects:
|
| 285 |
+
|
| 286 |
+
```python
|
| 287 |
+
Returns:
|
| 288 |
+
`tuple(torch.FloatTensor)` comprising various elements depending on the configuration ([`BertConfig`]) and inputs:
|
| 289 |
+
- ** loss** (*optional*, returned when `masked_lm_labels` is provided) `torch.FloatTensor` of shape `(1,)` --
|
| 290 |
+
Total loss is the sum of the masked language modeling loss and the next sequence prediction (classification) loss.
|
| 291 |
+
- **prediction_scores** (`torch.FloatTensor` of shape `(batch_size, sequence_length, config.vocab_size)`) --
|
| 292 |
+
Prediction scores of the language modeling head (scores for each vocabulary token before SoftMax).
|
| 293 |
+
```
|
| 294 |
+
|
| 295 |
+
#### Adding an image
|
| 296 |
+
|
| 297 |
+
Due to the rapidly growing repository, it is important to make sure that no files that would significantly weigh down the repository are added. This includes images, videos, and other non-text files. We prefer to leverage a hf.co hosted `dataset` like
|
| 298 |
+
the ones hosted on [`hf-internal-testing`](https://huggingface.co/hf-internal-testing) in which to place these files and reference
|
| 299 |
+
them by URL. We recommend putting them in the following dataset: [huggingface/documentation-images](https://huggingface.co/datasets/huggingface/documentation-images).
|
| 300 |
+
If an external contribution, feel free to add the images to your PR and ask a Hugging Face member to migrate your images
|
| 301 |
+
to this dataset.
|
| 302 |
+
|
| 303 |
+
## Styling the docstring
|
| 304 |
+
|
| 305 |
+
We have an automatic script running with the `make style` comment that will make sure that:
|
| 306 |
+
- the docstrings fully take advantage of the line width
|
| 307 |
+
- all code examples are formatted using black, like the code of the Transformers library
|
| 308 |
+
|
| 309 |
+
This script may have some weird failures if you made a syntax mistake or if you uncover a bug. Therefore, it's
|
| 310 |
+
recommended to commit your changes before running `make style`, so you can revert the changes done by that script
|
| 311 |
+
easily.
|
| 312 |
+
|
| 313 |
+
# Testing documentation examples
|
| 314 |
+
|
| 315 |
+
Good documentation often comes with an example of how a specific function or class should be used.
|
| 316 |
+
Each model class should contain at least one example showcasing
|
| 317 |
+
how to use this model class in inference. *E.g.* the class [Wav2Vec2ForCTC](https://huggingface.co/docs/transformers/model_doc/wav2vec2#transformers.Wav2Vec2ForCTC)
|
| 318 |
+
includes an example of how to transcribe speech to text in the
|
| 319 |
+
[docstring of its forward function](https://huggingface.co/docs/transformers/model_doc/wav2vec2#transformers.Wav2Vec2ForCTC.forward).
|
| 320 |
+
|
| 321 |
+
## Writing documentation examples
|
| 322 |
+
|
| 323 |
+
The syntax for Example docstrings can look as follows:
|
| 324 |
+
|
| 325 |
+
```python
|
| 326 |
+
Example:
|
| 327 |
+
|
| 328 |
+
>>> from transformers import Wav2Vec2Processor, Wav2Vec2ForCTC
|
| 329 |
+
>>> from datasets import load_dataset
|
| 330 |
+
>>> import torch
|
| 331 |
+
|
| 332 |
+
>>> dataset = load_dataset("hf-internal-testing/librispeech_asr_demo", "clean", split="validation")
|
| 333 |
+
>>> dataset = dataset.sort("id")
|
| 334 |
+
>>> sampling_rate = dataset.features["audio"].sampling_rate
|
| 335 |
+
|
| 336 |
+
>>> processor = Wav2Vec2Processor.from_pretrained("facebook/wav2vec2-base-960h")
|
| 337 |
+
>>> model = Wav2Vec2ForCTC.from_pretrained("facebook/wav2vec2-base-960h")
|
| 338 |
+
|
| 339 |
+
>>> # audio file is decoded on the fly
|
| 340 |
+
>>> inputs = processor(dataset[0]["audio"]["array"], sampling_rate=sampling_rate, return_tensors="pt")
|
| 341 |
+
>>> with torch.no_grad():
|
| 342 |
+
... logits = model(**inputs).logits
|
| 343 |
+
>>> predicted_ids = torch.argmax(logits, dim=-1)
|
| 344 |
+
|
| 345 |
+
>>> # transcribe speech
|
| 346 |
+
>>> transcription = processor.batch_decode(predicted_ids)
|
| 347 |
+
>>> transcription[0]
|
| 348 |
+
'MISTER QUILTER IS THE APOSTLE OF THE MIDDLE CLASSES AND WE ARE GLAD TO WELCOME HIS GOSPEL'
|
| 349 |
+
```
|
| 350 |
+
|
| 351 |
+
The docstring should give a minimal, clear example of how the respective model
|
| 352 |
+
is to be used in inference and also include the expected (ideally sensible)
|
| 353 |
+
output.
|
| 354 |
+
Often, readers will try out the example before even going through the function
|
| 355 |
+
or class definitions. Therefore, it is of utmost importance that the example
|
| 356 |
+
works as expected.
|
| 357 |
+
|
| 358 |
+
## Docstring testing
|
| 359 |
+
|
| 360 |
+
To do so each example should be included in the doctests.
|
| 361 |
+
We use pytests' [doctest integration](https://docs.pytest.org/doctest.html) to verify that all of our examples run correctly.
|
| 362 |
+
For Transformers, the doctests are run on a daily basis via GitHub Actions as can be
|
| 363 |
+
seen [here](https://github.com/huggingface/transformers/actions/workflows/doctests.yml).
|
| 364 |
+
|
| 365 |
+
### For Python files
|
| 366 |
+
|
| 367 |
+
Run all the tests in the docstrings of a given file with the following command, here is how we test the modeling file of Wav2Vec2 for instance:
|
| 368 |
+
|
| 369 |
+
```bash
|
| 370 |
+
pytest --doctest-modules src/transformers/models/wav2vec2/modeling_wav2vec2.py -sv --doctest-continue-on-failure
|
| 371 |
+
```
|
| 372 |
+
|
| 373 |
+
If you want to isolate a specific docstring, just add `::` after the file name then type the whole path of the function/class/method whose docstring you want to test. For instance, here is how to just test the forward method of `Wav2Vec2ForCTC`:
|
| 374 |
+
|
| 375 |
+
```bash
|
| 376 |
+
pytest --doctest-modules src/transformers/models/wav2vec2/modeling_wav2vec2.py::transformers.models.wav2vec2.modeling_wav2vec2.Wav2Vec2ForCTC.forward -sv --doctest-continue-on-failure
|
| 377 |
+
```
|
| 378 |
+
|
| 379 |
+
### For Markdown files
|
| 380 |
+
|
| 381 |
+
You can test locally a given file with this command (here testing the quicktour):
|
| 382 |
+
|
| 383 |
+
```bash
|
| 384 |
+
pytest --doctest-modules docs/source/quicktour.md -sv --doctest-continue-on-failure --doctest-glob="*.md"
|
| 385 |
+
```
|
| 386 |
+
|
| 387 |
+
### Writing doctests
|
| 388 |
+
|
| 389 |
+
Here are a few tips to help you debug the doctests and make them pass:
|
| 390 |
+
|
| 391 |
+
- The outputs of the code need to match the expected output **exactly**, so make sure you have the same outputs. In particular doctest will see a difference between single quotes and double quotes, or a missing parenthesis. The only exceptions to that rule are:
|
| 392 |
+
* whitespace: one give whitespace (space, tabulation, new line) is equivalent to any number of whitespace, so you can add new lines where there are spaces to make your output more readable.
|
| 393 |
+
* numerical values: you should never put more than 4 or 5 digits to expected results as different setups or library versions might get you slightly different results. `doctest` is configured to ignore any difference lower than the precision to which you wrote (so 1e-4 if you write 4 digits).
|
| 394 |
+
- Don't leave a block of code that is very long to execute. If you can't make it fast, you can either not use the doctest syntax on it (so that it's ignored), or if you want to use the doctest syntax to show the results, you can add a comment `# doctest: +SKIP` at the end of the lines of code too long to execute
|
| 395 |
+
- Each line of code that produces a result needs to have that result written below. You can ignore an output if you don't want to show it in your code example by adding a comment ` # doctest: +IGNORE_RESULT` at the end of the line of code producing it.
|
tasks/tasksmith-441eeab80047/environment/source/docs/TRANSLATING.md
ADDED
|
@@ -0,0 +1,70 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
# Translating the Transformers documentation into your language
|
| 2 |
+
|
| 3 |
+
As part of our mission to democratize machine learning, we aim to make the Transformers library available in many more languages! Follow the steps below to help translate the documentation into your language.
|
| 4 |
+
|
| 5 |
+
## Open an Issue
|
| 6 |
+
|
| 7 |
+
1. Navigate to the Issues page of this repository.
|
| 8 |
+
2. Check if anyone has already opened an issue for your language.
|
| 9 |
+
3. If not, create a new issue by selecting the "Translation template" from the "New issue" button.
|
| 10 |
+
4. Post a comment indicating which chapters you’d like to work on, and we’ll add your name to the list.
|
| 11 |
+
|
| 12 |
+
## Fork the Repository
|
| 13 |
+
|
| 14 |
+
1. First, fork the Transformers repo by clicking the Fork button in the top-right corner.
|
| 15 |
+
2. Clone your fork to your local machine for editing with the following command:
|
| 16 |
+
|
| 17 |
+
```bash
|
| 18 |
+
git clone https://github.com/YOUR-USERNAME/transformers.git
|
| 19 |
+
```
|
| 20 |
+
|
| 21 |
+
Replace `YOUR-USERNAME` with your GitHub username.
|
| 22 |
+
|
| 23 |
+
## Copy-paste the English version with a new language code
|
| 24 |
+
|
| 25 |
+
The documentation files are organized in the following directory:
|
| 26 |
+
|
| 27 |
+
- **docs/source**: This contains all documentation materials organized by language.
|
| 28 |
+
|
| 29 |
+
To copy the English version to your new language directory:
|
| 30 |
+
|
| 31 |
+
1. Navigate to your fork of the repository:
|
| 32 |
+
|
| 33 |
+
```bash
|
| 34 |
+
cd ~/path/to/transformers/docs
|
| 35 |
+
```
|
| 36 |
+
|
| 37 |
+
Replace `~/path/to` with your actual path.
|
| 38 |
+
|
| 39 |
+
2. Run the following command:
|
| 40 |
+
|
| 41 |
+
```bash
|
| 42 |
+
cp -r source/en source/LANG-ID
|
| 43 |
+
```
|
| 44 |
+
|
| 45 |
+
Replace `LANG-ID` with the appropriate ISO 639-1 or ISO 639-2 language code (see [this table](https://en.wikipedia.org/wiki/List_of_ISO_639-1_codes) for reference).
|
| 46 |
+
|
| 47 |
+
## Start translating
|
| 48 |
+
|
| 49 |
+
Begin translating the text!
|
| 50 |
+
|
| 51 |
+
1. Start with the `_toctree.yml` file that corresponds to your documentation chapter. This file is essential for rendering the table of contents on the website.
|
| 52 |
+
|
| 53 |
+
- If the `_toctree.yml` file doesn’t exist for your language, create one by copying the English version and removing unrelated sections.
|
| 54 |
+
- Ensure it is placed in the `docs/source/LANG-ID/` directory.
|
| 55 |
+
|
| 56 |
+
Here’s an example structure for the `_toctree.yml` file:
|
| 57 |
+
|
| 58 |
+
```yaml
|
| 59 |
+
- sections:
|
| 60 |
+
- local: pipeline_tutorial # Keep this name for your .md file
|
| 61 |
+
title: Pipelines for Inference # Translate this
|
| 62 |
+
...
|
| 63 |
+
title: Tutorials # Translate this
|
| 64 |
+
```
|
| 65 |
+
|
| 66 |
+
2. Once you’ve translated the `_toctree.yml`, move on to translating the associated MDX files.
|
| 67 |
+
|
| 68 |
+
## Collaborate and share
|
| 69 |
+
|
| 70 |
+
If you'd like assistance with your translation, open an issue and tag `@stevhliu`. Feel free to share resources or glossaries to ensure consistent terminology.
|
tasks/tasksmith-441eeab80047/environment/source/docs/source/_config.py
ADDED
|
@@ -0,0 +1,14 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
# docstyle-ignore
|
| 2 |
+
INSTALL_CONTENT = """
|
| 3 |
+
# Transformers installation
|
| 4 |
+
! pip install transformers datasets evaluate accelerate
|
| 5 |
+
# To install from source instead of the last release, comment the command above and uncomment the following one.
|
| 6 |
+
# ! pip install git+https://github.com/huggingface/transformers.git
|
| 7 |
+
"""
|
| 8 |
+
|
| 9 |
+
notebook_first_cells = [{"type": "code", "content": INSTALL_CONTENT}]
|
| 10 |
+
black_avoid_patterns = {
|
| 11 |
+
"{processor_class}": "FakeProcessorClass",
|
| 12 |
+
"{model_class}": "FakeModelClass",
|
| 13 |
+
"{object_class}": "FakeObjectClass",
|
| 14 |
+
}
|
tasks/tasksmith-441eeab80047/environment/source/docs/source/ar/_config.py
ADDED
|
@@ -0,0 +1,14 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
# docstyle-ignore
|
| 2 |
+
INSTALL_CONTENT = """
|
| 3 |
+
# Transformers installation
|
| 4 |
+
! pip install transformers datasets evaluate accelerate
|
| 5 |
+
# To install from source instead of the last release, comment the command above and uncomment the following one.
|
| 6 |
+
# ! pip install git+https://github.com/huggingface/transformers.git
|
| 7 |
+
"""
|
| 8 |
+
|
| 9 |
+
notebook_first_cells = [{"type": "code", "content": INSTALL_CONTENT}]
|
| 10 |
+
black_avoid_patterns = {
|
| 11 |
+
"{processor_class}": "FakeProcessorClass",
|
| 12 |
+
"{model_class}": "FakeModelClass",
|
| 13 |
+
"{object_class}": "FakeObjectClass",
|
| 14 |
+
}
|
tasks/tasksmith-441eeab80047/environment/source/docs/source/ar/_toctree.yml
ADDED
|
@@ -0,0 +1,898 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
- sections:
|
| 2 |
+
- local: index
|
| 3 |
+
title: 🤗 المحولات
|
| 4 |
+
- local: quicktour
|
| 5 |
+
title: جولة سريعة
|
| 6 |
+
- local: installation
|
| 7 |
+
title: التثبيت
|
| 8 |
+
title: البدء
|
| 9 |
+
- sections:
|
| 10 |
+
- local: pipeline_tutorial
|
| 11 |
+
title: تشغيل الاستنتاج باستخدام خطوط الأنابيب
|
| 12 |
+
- local: autoclass_tutorial
|
| 13 |
+
title: كتابة تعليمات برمجية متكيفه باستخدام AutoClass
|
| 14 |
+
- local: preprocessing
|
| 15 |
+
title: معالجة البيانات مسبقًا
|
| 16 |
+
- local: training
|
| 17 |
+
title: ضبط نموذج مسبق التدريب
|
| 18 |
+
- local: run_scripts
|
| 19 |
+
title: التدريب باستخدام نص برمجي
|
| 20 |
+
- local: accelerate
|
| 21 |
+
title: إعداد تدريب موزع باستخدام 🤗 Accelerate
|
| 22 |
+
- local: peft
|
| 23 |
+
title: تحميل النماذج المخصصة وتدريبها باستخدام 🤗 PEFT
|
| 24 |
+
- local: model_sharing
|
| 25 |
+
title: مشاركة نموذجك
|
| 26 |
+
- local: agents
|
| 27 |
+
title: الوكلاء
|
| 28 |
+
- local: llm_tutorial
|
| 29 |
+
title: التوليد باستخدام LLMs
|
| 30 |
+
- local: conversations
|
| 31 |
+
title: الدردشة مع المحولات
|
| 32 |
+
title: البرامج التعليمية
|
| 33 |
+
- sections:
|
| 34 |
+
- isExpanded: false
|
| 35 |
+
sections:
|
| 36 |
+
- local: tasks/sequence_classification
|
| 37 |
+
title: تصنيف النصوص
|
| 38 |
+
- local: tasks/token_classification
|
| 39 |
+
title: تصنيف الرموز
|
| 40 |
+
- local: tasks/question_answering
|
| 41 |
+
title: الإجابة على الأسئلة
|
| 42 |
+
- local: tasks/language_modeling
|
| 43 |
+
title: نمذجة اللغة السببية
|
| 44 |
+
- local: tasks/masked_language_modeling
|
| 45 |
+
title: نمذجة اللغة المقنعة
|
| 46 |
+
- local: tasks/translation
|
| 47 |
+
title: الترجمة
|
| 48 |
+
- local: tasks/summarization
|
| 49 |
+
title: التلخيص
|
| 50 |
+
- local: tasks/multiple_choice
|
| 51 |
+
title: الاختيار المتعدد
|
| 52 |
+
title: معالجة اللغات الطبيعية
|
| 53 |
+
# - isExpanded: false
|
| 54 |
+
# sections:
|
| 55 |
+
# - local: tasks/audio_classification
|
| 56 |
+
# title: تصنيف الصوت
|
| 57 |
+
# - local: tasks/asr
|
| 58 |
+
# title: التعرف التلقائي على الكلام
|
| 59 |
+
# title: الصوت
|
| 60 |
+
# - isExpanded: false
|
| 61 |
+
# sections:
|
| 62 |
+
# - local: tasks/image_classification
|
| 63 |
+
# title: تصنيف الصور
|
| 64 |
+
# - local: tasks/semantic_segmentation
|
| 65 |
+
# title: تجزئة الصور
|
| 66 |
+
# - local: tasks/video_classification
|
| 67 |
+
# title: تصنيف الفيديو
|
| 68 |
+
# - local: tasks/object_detection
|
| 69 |
+
# title: اكتشاف الأشياء
|
| 70 |
+
# - local: tasks/zero_shot_object_detection
|
| 71 |
+
# title: اكتشاف الأشياء بدون تدريب
|
| 72 |
+
# - local: tasks/zero_shot_image_classification
|
| 73 |
+
# title: تصنيف الصور بدون تدريب
|
| 74 |
+
# - local: tasks/monocular_depth_estimation
|
| 75 |
+
# title: تقدير العمق
|
| 76 |
+
# - local: tasks/image_to_image
|
| 77 |
+
# title: صورة إلى صورة
|
| 78 |
+
# - local: tasks/image_feature_extraction
|
| 79 |
+
# title: استخراج ميزات الصورة
|
| 80 |
+
# - local: tasks/mask_generation
|
| 81 |
+
# title: توليد القناع
|
| 82 |
+
# - local: tasks/knowledge_distillation_for_image_classification
|
| 83 |
+
# title: التقليل المعرفي للرؤية الحاسوبية
|
| 84 |
+
# title: الرؤية الحاسوبية
|
| 85 |
+
# - isExpanded: false
|
| 86 |
+
# sections:
|
| 87 |
+
# - local: tasks/image_captioning
|
| 88 |
+
# title: وصف الصور Image captioning
|
| 89 |
+
# - local: tasks/document_question_answering
|
| 90 |
+
# title: الإجابة على أسئلة المستندات
|
| 91 |
+
# - local: tasks/visual_question_answering
|
| 92 |
+
# title: الإجابة على الأسئلة المرئية
|
| 93 |
+
# - local: tasks/text-to-speech
|
| 94 |
+
# title: تحويل النص إلى كلام
|
| 95 |
+
# title: المتعددة الوسائط
|
| 96 |
+
# - isExpanded: false
|
| 97 |
+
# sections:
|
| 98 |
+
# - local: generation_strategies
|
| 99 |
+
# title: تخصيص استراتيجية التوليد
|
| 100 |
+
# - local: kv_cache
|
| 101 |
+
# title: أفضل الممارسات للتوليد باستخدام ذاكرة التخزين المؤقت
|
| 102 |
+
# title: التوليد
|
| 103 |
+
# - isExpanded: false
|
| 104 |
+
# sections:
|
| 105 |
+
# - local: tasks/idefics
|
| 106 |
+
# title: مهام الصور مع IDEFICS
|
| 107 |
+
# - local: tasks/prompting
|
| 108 |
+
# title: دليل إرشادي لمحفزات النماذج اللغوية الكبيرة
|
| 109 |
+
# title: الإرشاد
|
| 110 |
+
title: أدلة المهام
|
| 111 |
+
- sections:
|
| 112 |
+
- local: fast_tokenizers
|
| 113 |
+
title: استخدم مجزئيات النصوص السريعة من 🤗 Tokenizers
|
| 114 |
+
- local: multilingual
|
| 115 |
+
title: الاستدلال باستخدام نماذج متعددة اللغات
|
| 116 |
+
- local: create_a_model
|
| 117 |
+
title: استخدام واجهات برمجة التطبيقات الخاصة بالنموذج
|
| 118 |
+
- local: custom_models
|
| 119 |
+
title: مشاركة نموذج مخصص
|
| 120 |
+
- local: chat_templating
|
| 121 |
+
title: قوالب لنماذج الدردشة
|
| 122 |
+
- local: trainer
|
| 123 |
+
title: المدرب
|
| 124 |
+
- local: sagemaker
|
| 125 |
+
title: تشغيل التدريب على Amazon SageMaker
|
| 126 |
+
- local: serialization
|
| 127 |
+
title: التصدير إلى ONNX
|
| 128 |
+
- local: tflite
|
| 129 |
+
title: التصدير إلى TFLite
|
| 130 |
+
- local: torchscript
|
| 131 |
+
title: التصدير إلى TorchScript
|
| 132 |
+
- local: notebooks
|
| 133 |
+
title: دفاتر الملاحظات مع الأمثلة
|
| 134 |
+
- local: community
|
| 135 |
+
title: موارد المجتمع
|
| 136 |
+
- local: troubleshooting
|
| 137 |
+
title: استكشاف الأخطاء وإصلاحها
|
| 138 |
+
- local: gguf
|
| 139 |
+
title: التوافق مع ملفات GGUF
|
| 140 |
+
- local: tiktoken
|
| 141 |
+
title: التوافق مع ملفات TikToken
|
| 142 |
+
- local: modular_transformers
|
| 143 |
+
title: الوحدات النمطية في `transformers`
|
| 144 |
+
- local: how_to_hack_models
|
| 145 |
+
title: اختراق النموذج (الكتابة فوق فئة لاستخدامك)
|
| 146 |
+
title: أدلة المطورين
|
| 147 |
+
# - sections:
|
| 148 |
+
# - local: quantization/overview
|
| 149 |
+
# title: نظرة عامة
|
| 150 |
+
# - local: quantization/bitsandbytes
|
| 151 |
+
# title: bitsandbytes
|
| 152 |
+
# - local: quantization/gptq
|
| 153 |
+
# title: GPTQ
|
| 154 |
+
# - local: quantization/awq
|
| 155 |
+
# title: AWQ
|
| 156 |
+
# - local: quantization/aqlm
|
| 157 |
+
# title: AQLM
|
| 158 |
+
# - local: quantization/vptq
|
| 159 |
+
# title: VPTQ
|
| 160 |
+
# - local: quantization/quanto
|
| 161 |
+
# title: Quanto
|
| 162 |
+
# - local: quantization/eetq
|
| 163 |
+
# title: EETQ
|
| 164 |
+
# - local: quantization/hqq
|
| 165 |
+
# title: HQQ
|
| 166 |
+
# - local: quantization/optimum
|
| 167 |
+
# title: Optimum
|
| 168 |
+
# - local: quantization/contribute
|
| 169 |
+
# title: المساهمة بطريقة جديدة للتكميم
|
| 170 |
+
# title: أساليب التكميم
|
| 171 |
+
# - sections:
|
| 172 |
+
# - local: performance
|
| 173 |
+
# title: الأداء-نظرة عامة
|
| 174 |
+
# - local: llm_optims
|
| 175 |
+
# title: تحسين الاستدلال LLM
|
| 176 |
+
# - sections:
|
| 177 |
+
# - local: perf_train_gpu_one
|
| 178 |
+
# title: استخدام عدة وحدات معالجة رسوميات (GPUs) بشكل متوازٍ
|
| 179 |
+
# - local: perf_train_gpu_many
|
| 180 |
+
# title: وحدات معالجة الرسومات (GPU) متعددة والتوازي
|
| 181 |
+
# - local: fsdp
|
| 182 |
+
# title: Fully Sharded Data Parallel
|
| 183 |
+
# - local: deepspeed
|
| 184 |
+
# title: DeepSpeed
|
| 185 |
+
# - local: perf_train_cpu
|
| 186 |
+
# title: التدريب الفعال على وحدة المعالجة المركزية (CPU)
|
| 187 |
+
# - local: perf_train_cpu_many
|
| 188 |
+
# title: التدريب الموزع لوحدة المعالجة المركزية (CPU)
|
| 189 |
+
# - local: perf_train_tpu_tf
|
| 190 |
+
# title: التدريب على (TPU) باستخدام TensorFlow
|
| 191 |
+
# - local: perf_train_special
|
| 192 |
+
# title: تدريب PyTorch على Apple silicon
|
| 193 |
+
# - local: perf_hardware
|
| 194 |
+
# title: الأجهزة المخصصة للتدريب
|
| 195 |
+
# - local: hpo_train
|
| 196 |
+
# title: البحث عن المعاملات المثلى باستخدام واجهة برمجة تطبيقات المدرب
|
| 197 |
+
# title: تقنيات التدريب الفعال
|
| 198 |
+
# - sections:
|
| 199 |
+
# - local: perf_infer_cpu
|
| 200 |
+
# title: الإستدلال على وحدة المعالجة المركزية (CPU)
|
| 201 |
+
# - local: perf_infer_gpu_one
|
| 202 |
+
# title: الإستدلال على وحدة معالجة الرسومات (GPU)
|
| 203 |
+
# title: تحسين الاستدلال
|
| 204 |
+
# - local: big_models
|
| 205 |
+
# title: إنشاء نموذج كبير
|
| 206 |
+
# - local: debugging
|
| 207 |
+
# title: تصحيح الأخطاء البرمجية
|
| 208 |
+
# - local: tf_xla
|
| 209 |
+
# title: تكامل XLA لنماذج TensorFlow
|
| 210 |
+
# - local: perf_torch_compile
|
| 211 |
+
# title: تحسين الاستدلال باستخدام `torch.compile()`
|
| 212 |
+
# title: الأداء وقابلية التوسع
|
| 213 |
+
# - sections:
|
| 214 |
+
# - local: contributing
|
| 215 |
+
# title: كيفية المساهمة في 🤗 المحولات؟
|
| 216 |
+
# - local: add_new_model
|
| 217 |
+
# title: كيفية إضافة نموذج إلى 🤗 المحولات؟
|
| 218 |
+
# - local: add_new_pipeline
|
| 219 |
+
# title: كيفية إضافة خط أنابيب إلى 🤗 المحولات؟
|
| 220 |
+
# - local: testing
|
| 221 |
+
# title: الاختبار
|
| 222 |
+
# - local: pr_checks
|
| 223 |
+
# title: التحقق من طلب السحب
|
| 224 |
+
# title: المساهمة
|
| 225 |
+
- sections:
|
| 226 |
+
- local: philosophy
|
| 227 |
+
title: الفلسفة
|
| 228 |
+
- local: glossary
|
| 229 |
+
title: (قاموس المصطلحات (قائمة الكلمات
|
| 230 |
+
- local: task_summary
|
| 231 |
+
title: ما الذي يمكن أن تفعله 🤗 المحولات
|
| 232 |
+
- local: tasks_explained
|
| 233 |
+
title: كيف تحل المحولات المهام
|
| 234 |
+
- local: model_summary
|
| 235 |
+
title: عائلة نماذج المحول
|
| 236 |
+
- local: tokenizer_summary
|
| 237 |
+
title: ملخص برنامج مقسم النصوص (tokenizers)
|
| 238 |
+
- local: attention
|
| 239 |
+
title: الانتباه Attention
|
| 240 |
+
- local: pad_truncation
|
| 241 |
+
title: الحشو والتقليم
|
| 242 |
+
- local: bertology
|
| 243 |
+
title: BERTology
|
| 244 |
+
- local: perplexity
|
| 245 |
+
title: حيرة النماذج ذات الطول الثابت
|
| 246 |
+
- local: pipeline_webserver
|
| 247 |
+
title: خطوط الأنابيب للاستدلال على خادم الويب
|
| 248 |
+
- local: model_memory_anatomy
|
| 249 |
+
title: تشريح تدريب النموذج
|
| 250 |
+
- local: llm_tutorial_optimization
|
| 251 |
+
title: الاستفادة القصوى من LLMs
|
| 252 |
+
title: أطر مفاهيمية
|
| 253 |
+
# - sections:
|
| 254 |
+
# - sections:
|
| 255 |
+
# - local: main_classes/agent
|
| 256 |
+
# title: الوكلاء والأدوات
|
| 257 |
+
# - local: model_doc/auto
|
| 258 |
+
# title: فئات يتم إنشاؤها ديناميكيًا
|
| 259 |
+
# - local: main_classes/backbones
|
| 260 |
+
# title: العمود الفقري
|
| 261 |
+
# - local: main_classes/callback
|
| 262 |
+
# title: عمليات الاسترجاع
|
| 263 |
+
# - local: main_classes/configuration
|
| 264 |
+
# title: التكوين
|
| 265 |
+
# - local: main_classes/data_collator
|
| 266 |
+
# title: مجمع البيانات
|
| 267 |
+
# - local: main_classes/keras_callbacks
|
| 268 |
+
# title: استدعاءات Keras
|
| 269 |
+
# - local: main_classes/logging
|
| 270 |
+
# title: التسجيل
|
| 271 |
+
# - local: main_classes/model
|
| 272 |
+
# title: النماذج
|
| 273 |
+
# - local: main_classes/text_generation
|
| 274 |
+
# title: توليد النصوص
|
| 275 |
+
# - local: main_classes/onnx
|
| 276 |
+
# title: ONNX
|
| 277 |
+
# - local: main_classes/optimizer_schedules
|
| 278 |
+
# title: التحسين
|
| 279 |
+
# - local: main_classes/output
|
| 280 |
+
# title: مخرجات النموذج
|
| 281 |
+
# - local: main_classes/pipelines
|
| 282 |
+
# title: خطوط الأنابيب
|
| 283 |
+
# - local: main_classes/processors
|
| 284 |
+
# title: المعالجات
|
| 285 |
+
# - local: main_classes/quantization
|
| 286 |
+
# title: التكميم
|
| 287 |
+
# - local: main_classes/tokenizer
|
| 288 |
+
# title: برنامج مقسم النصوص
|
| 289 |
+
# - local: main_classes/trainer
|
| 290 |
+
# title: المدرب
|
| 291 |
+
# - local: main_classes/deepspeed
|
| 292 |
+
# title: DeepSpeed
|
| 293 |
+
# - local: main_classes/feature_extractor
|
| 294 |
+
# title: مستخرج الميزات
|
| 295 |
+
# - local: main_classes/image_processor
|
| 296 |
+
# title: معالج الصور
|
| 297 |
+
# title: الفئات الرئيسية
|
| 298 |
+
# - sections:
|
| 299 |
+
# - isExpanded: false
|
| 300 |
+
# sections:
|
| 301 |
+
# - local: model_doc/albert
|
| 302 |
+
# title: ALBERT
|
| 303 |
+
# - local: model_doc/bart
|
| 304 |
+
# title: BART
|
| 305 |
+
# - local: model_doc/barthez
|
| 306 |
+
# title: BARThez
|
| 307 |
+
# - local: model_doc/bartpho
|
| 308 |
+
# title: BARTpho
|
| 309 |
+
# - local: model_doc/bert
|
| 310 |
+
# title: BERT
|
| 311 |
+
# - local: model_doc/bert-generation
|
| 312 |
+
# title: BertGeneration
|
| 313 |
+
# - local: model_doc/bert-japanese
|
| 314 |
+
# title: BertJapanese
|
| 315 |
+
# - local: model_doc/bertweet
|
| 316 |
+
# title: Bertweet
|
| 317 |
+
# - local: model_doc/big_bird
|
| 318 |
+
# title: BigBird
|
| 319 |
+
# - local: model_doc/bigbird_pegasus
|
| 320 |
+
# title: BigBirdPegasus
|
| 321 |
+
# - local: model_doc/biogpt
|
| 322 |
+
# title: BioGpt
|
| 323 |
+
# - local: model_doc/blenderbot
|
| 324 |
+
# title: Blenderbot
|
| 325 |
+
# - local: model_doc/blenderbot-small
|
| 326 |
+
# title: Blenderbot Small
|
| 327 |
+
# - local: model_doc/bloom
|
| 328 |
+
# title: BLOOM
|
| 329 |
+
# - local: model_doc/bort
|
| 330 |
+
# title: BORT
|
| 331 |
+
# - local: model_doc/byt5
|
| 332 |
+
# title: ByT5
|
| 333 |
+
# - local: model_doc/camembert
|
| 334 |
+
# title: CamemBERT
|
| 335 |
+
# - local: model_doc/canine
|
| 336 |
+
# title: CANINE
|
| 337 |
+
# - local: model_doc/codegen
|
| 338 |
+
# title: CodeGen
|
| 339 |
+
# - local: model_doc/code_llama
|
| 340 |
+
# title: CodeLlama
|
| 341 |
+
# - local: model_doc/cohere
|
| 342 |
+
# title: Cohere
|
| 343 |
+
# - local: model_doc/convbert
|
| 344 |
+
# title: ConvBERT
|
| 345 |
+
# - local: model_doc/cpm
|
| 346 |
+
# title: CPM
|
| 347 |
+
# - local: model_doc/cpmant
|
| 348 |
+
# title: CPMANT
|
| 349 |
+
# - local: model_doc/ctrl
|
| 350 |
+
# title: CTRL
|
| 351 |
+
# - local: model_doc/dbrx
|
| 352 |
+
# title: DBRX
|
| 353 |
+
# - local: model_doc/deberta
|
| 354 |
+
# title: DeBERTa
|
| 355 |
+
# - local: model_doc/deberta-v2
|
| 356 |
+
# title: DeBERTa-v2
|
| 357 |
+
# - local: model_doc/dialogpt
|
| 358 |
+
# title: DialoGPT
|
| 359 |
+
# - local: model_doc/distilbert
|
| 360 |
+
# title: DistilBERT
|
| 361 |
+
# - local: model_doc/dpr
|
| 362 |
+
# title: DPR
|
| 363 |
+
# - local: model_doc/electra
|
| 364 |
+
# title: ELECTRA
|
| 365 |
+
# - local: model_doc/encoder-decoder
|
| 366 |
+
# title: Encoder Decoder Models
|
| 367 |
+
# - local: model_doc/ernie
|
| 368 |
+
# title: ERNIE
|
| 369 |
+
# - local: model_doc/ernie_m
|
| 370 |
+
# title: ErnieM
|
| 371 |
+
# - local: model_doc/esm
|
| 372 |
+
# title: ESM
|
| 373 |
+
# - local: model_doc/falcon
|
| 374 |
+
# title: Falcon
|
| 375 |
+
# - local: model_doc/fastspeech2_conformer
|
| 376 |
+
# title: FastSpeech2Conformer
|
| 377 |
+
# - local: model_doc/flan-t5
|
| 378 |
+
# title: FLAN-T5
|
| 379 |
+
# - local: model_doc/flan-ul2
|
| 380 |
+
# title: FLAN-UL2
|
| 381 |
+
# - local: model_doc/flaubert
|
| 382 |
+
# title: FlauBERT
|
| 383 |
+
# - local: model_doc/fnet
|
| 384 |
+
# title: FNet
|
| 385 |
+
# - local: model_doc/fsmt
|
| 386 |
+
# title: FSMT
|
| 387 |
+
# - local: model_doc/funnel
|
| 388 |
+
# title: Funnel Transformer
|
| 389 |
+
# - local: model_doc/fuyu
|
| 390 |
+
# title: Fuyu
|
| 391 |
+
# - local: model_doc/gemma
|
| 392 |
+
# title: Gemma
|
| 393 |
+
# - local: model_doc/openai-gpt
|
| 394 |
+
# title: GPT
|
| 395 |
+
# - local: model_doc/gpt_neo
|
| 396 |
+
# title: GPT Neo
|
| 397 |
+
# - local: model_doc/gpt_neox
|
| 398 |
+
# title: GPT NeoX
|
| 399 |
+
# - local: model_doc/gpt_neox_japanese
|
| 400 |
+
# title: GPT NeoX Japanese
|
| 401 |
+
# - local: model_doc/gptj
|
| 402 |
+
# title: GPT-J
|
| 403 |
+
# - local: model_doc/gpt2
|
| 404 |
+
# title: GPT2
|
| 405 |
+
# - local: model_doc/gpt_bigcode
|
| 406 |
+
# title: GPTBigCode
|
| 407 |
+
# - local: model_doc/gptsan-japanese
|
| 408 |
+
# title: GPTSAN Japanese
|
| 409 |
+
# - local: model_doc/gpt-sw3
|
| 410 |
+
# title: GPTSw3
|
| 411 |
+
# - local: model_doc/herbert
|
| 412 |
+
# title: HerBERT
|
| 413 |
+
# - local: model_doc/ibert
|
| 414 |
+
# title: I-BERT
|
| 415 |
+
# - local: model_doc/jamba
|
| 416 |
+
# title: Jamba
|
| 417 |
+
# - local: model_doc/jetmoe
|
| 418 |
+
# title: JetMoe
|
| 419 |
+
# - local: model_doc/jukebox
|
| 420 |
+
# title: Jukebox
|
| 421 |
+
# - local: model_doc/led
|
| 422 |
+
# title: LED
|
| 423 |
+
# - local: model_doc/llama
|
| 424 |
+
# title: LLaMA
|
| 425 |
+
# - local: model_doc/llama2
|
| 426 |
+
# title: Llama2
|
| 427 |
+
# - local: model_doc/llama3
|
| 428 |
+
# title: Llama3
|
| 429 |
+
# - local: model_doc/longformer
|
| 430 |
+
# title: Longformer
|
| 431 |
+
# - local: model_doc/longt5
|
| 432 |
+
# title: LongT5
|
| 433 |
+
# - local: model_doc/luke
|
| 434 |
+
# title: LUKE
|
| 435 |
+
# - local: model_doc/m2m_100
|
| 436 |
+
# title: M2M100
|
| 437 |
+
# - local: model_doc/madlad-400
|
| 438 |
+
# title: MADLAD-400
|
| 439 |
+
# - local: model_doc/mamba
|
| 440 |
+
# title: Mamba
|
| 441 |
+
# - local: model_doc/marian
|
| 442 |
+
# title: MarianMT
|
| 443 |
+
# - local: model_doc/markuplm
|
| 444 |
+
# title: MarkupLM
|
| 445 |
+
# - local: model_doc/mbart
|
| 446 |
+
# title: MBart and MBart-50
|
| 447 |
+
# - local: model_doc/mega
|
| 448 |
+
# title: MEGA
|
| 449 |
+
# - local: model_doc/megatron-bert
|
| 450 |
+
# title: MegatronBERT
|
| 451 |
+
# - local: model_doc/megatron_gpt2
|
| 452 |
+
# title: MegatronGPT2
|
| 453 |
+
# - local: model_doc/mistral
|
| 454 |
+
# title: Mistral
|
| 455 |
+
# - local: model_doc/mixtral
|
| 456 |
+
# title: Mixtral
|
| 457 |
+
# - local: model_doc/mluke
|
| 458 |
+
# title: mLUKE
|
| 459 |
+
# - local: model_doc/mobilebert
|
| 460 |
+
# title: MobileBERT
|
| 461 |
+
# - local: model_doc/mpnet
|
| 462 |
+
# title: MPNet
|
| 463 |
+
# - local: model_doc/mpt
|
| 464 |
+
# title: MPT
|
| 465 |
+
# - local: model_doc/mra
|
| 466 |
+
# title: MRA
|
| 467 |
+
# - local: model_doc/mt5
|
| 468 |
+
# title: MT5
|
| 469 |
+
# - local: model_doc/mvp
|
| 470 |
+
# title: MVP
|
| 471 |
+
# - local: model_doc/nezha
|
| 472 |
+
# title: NEZHA
|
| 473 |
+
# - local: model_doc/nllb
|
| 474 |
+
# title: NLLB
|
| 475 |
+
# - local: model_doc/nllb-moe
|
| 476 |
+
# title: NLLB-MoE
|
| 477 |
+
# - local: model_doc/nystromformer
|
| 478 |
+
# title: Nyströmformer
|
| 479 |
+
# - local: model_doc/olmo
|
| 480 |
+
# title: OLMo
|
| 481 |
+
# - local: model_doc/open-llama
|
| 482 |
+
# title: Open-Llama
|
| 483 |
+
# - local: model_doc/opt
|
| 484 |
+
# title: OPT
|
| 485 |
+
# - local: model_doc/pegasus
|
| 486 |
+
# title: Pegasus
|
| 487 |
+
# - local: model_doc/pegasus_x
|
| 488 |
+
# title: PEGASUS-X
|
| 489 |
+
# - local: model_doc/persimmon
|
| 490 |
+
# title: Persimmon
|
| 491 |
+
# - local: model_doc/phi
|
| 492 |
+
# title: Phi
|
| 493 |
+
# - local: model_doc/phi3
|
| 494 |
+
# title: Phi-3
|
| 495 |
+
# - local: model_doc/phobert
|
| 496 |
+
# title: PhoBERT
|
| 497 |
+
# - local: model_doc/plbart
|
| 498 |
+
# title: PLBart
|
| 499 |
+
# - local: model_doc/prophetnet
|
| 500 |
+
# title: ProphetNet
|
| 501 |
+
# - local: model_doc/qdqbert
|
| 502 |
+
# title: QDQBert
|
| 503 |
+
# - local: model_doc/qwen2
|
| 504 |
+
# title: Qwen2
|
| 505 |
+
# - local: model_doc/qwen2_moe
|
| 506 |
+
# title: Qwen2MoE
|
| 507 |
+
# - local: model_doc/rag
|
| 508 |
+
# title: RAG
|
| 509 |
+
# - local: model_doc/realm
|
| 510 |
+
# title: REALM
|
| 511 |
+
# - local: model_doc/recurrent_gemma
|
| 512 |
+
# title: RecurrentGemma
|
| 513 |
+
# - local: model_doc/reformer
|
| 514 |
+
# title: Reformer
|
| 515 |
+
# - local: model_doc/rembert
|
| 516 |
+
# title: RemBERT
|
| 517 |
+
# - local: model_doc/retribert
|
| 518 |
+
# title: RetriBERT
|
| 519 |
+
# - local: model_doc/roberta
|
| 520 |
+
# title: RoBERTa
|
| 521 |
+
# - local: model_doc/roberta-prelayernorm
|
| 522 |
+
# title: RoBERTa-PreLayerNorm
|
| 523 |
+
# - local: model_doc/roc_bert
|
| 524 |
+
# title: RoCBert
|
| 525 |
+
# - local: model_doc/roformer
|
| 526 |
+
# title: RoFormer
|
| 527 |
+
# - local: model_doc/rwkv
|
| 528 |
+
# title: RWKV
|
| 529 |
+
# - local: model_doc/splinter
|
| 530 |
+
# title: Splinter
|
| 531 |
+
# - local: model_doc/squeezebert
|
| 532 |
+
# title: SqueezeBERT
|
| 533 |
+
# - local: model_doc/stablelm
|
| 534 |
+
# title: StableLm
|
| 535 |
+
# - local: model_doc/starcoder2
|
| 536 |
+
# title: Starcoder2
|
| 537 |
+
# - local: model_doc/switch_transformers
|
| 538 |
+
# title: SwitchTransformers
|
| 539 |
+
# - local: model_doc/t5
|
| 540 |
+
# title: T5
|
| 541 |
+
# - local: model_doc/t5v1.1
|
| 542 |
+
# title: T5v1.1
|
| 543 |
+
# - local: model_doc/tapex
|
| 544 |
+
# title: TAPEX
|
| 545 |
+
# - local: model_doc/transfo-xl
|
| 546 |
+
# title: Transformer XL
|
| 547 |
+
# - local: model_doc/ul2
|
| 548 |
+
# title: UL2
|
| 549 |
+
# - local: model_doc/umt5
|
| 550 |
+
# title: UMT5
|
| 551 |
+
# - local: model_doc/xmod
|
| 552 |
+
# title: X-MOD
|
| 553 |
+
# - local: model_doc/xglm
|
| 554 |
+
# title: XGLM
|
| 555 |
+
# - local: model_doc/xlm
|
| 556 |
+
# title: XLM
|
| 557 |
+
# - local: model_doc/xlm-prophetnet
|
| 558 |
+
# title: XLM-ProphetNet
|
| 559 |
+
# - local: model_doc/xlm-roberta
|
| 560 |
+
# title: XLM-RoBERTa
|
| 561 |
+
# - local: model_doc/xlm-roberta-xl
|
| 562 |
+
# title: XLM-RoBERTa-XL
|
| 563 |
+
# - local: model_doc/xlm-v
|
| 564 |
+
# title: XLM-V
|
| 565 |
+
# - local: model_doc/xlnet
|
| 566 |
+
# title: XLNet
|
| 567 |
+
# - local: model_doc/yoso
|
| 568 |
+
# title: YOSO
|
| 569 |
+
# title: Text models
|
| 570 |
+
# - isExpanded: false
|
| 571 |
+
# sections:
|
| 572 |
+
# - local: model_doc/beit
|
| 573 |
+
# title: BEiT
|
| 574 |
+
# - local: model_doc/bit
|
| 575 |
+
# title: BiT
|
| 576 |
+
# - local: model_doc/conditional_detr
|
| 577 |
+
# title: Conditional DETR
|
| 578 |
+
# - local: model_doc/convnext
|
| 579 |
+
# title: ConvNeXT
|
| 580 |
+
# - local: model_doc/convnextv2
|
| 581 |
+
# title: ConvNeXTV2
|
| 582 |
+
# - local: model_doc/cvt
|
| 583 |
+
# title: CVT
|
| 584 |
+
# - local: model_doc/deformable_detr
|
| 585 |
+
# title: Deformable DETR
|
| 586 |
+
# - local: model_doc/deit
|
| 587 |
+
# title: DeiT
|
| 588 |
+
# - local: model_doc/depth_anything
|
| 589 |
+
# title: Depth Anything
|
| 590 |
+
# - local: model_doc/deta
|
| 591 |
+
# title: DETA
|
| 592 |
+
# - local: model_doc/detr
|
| 593 |
+
# title: DETR
|
| 594 |
+
# - local: model_doc/dinat
|
| 595 |
+
# title: DiNAT
|
| 596 |
+
# - local: model_doc/dinov2
|
| 597 |
+
# title: DINOV2
|
| 598 |
+
# - local: model_doc/dit
|
| 599 |
+
# title: DiT
|
| 600 |
+
# - local: model_doc/dpt
|
| 601 |
+
# title: DPT
|
| 602 |
+
# - local: model_doc/efficientformer
|
| 603 |
+
# title: EfficientFormer
|
| 604 |
+
# - local: model_doc/efficientnet
|
| 605 |
+
# title: EfficientNet
|
| 606 |
+
# - local: model_doc/focalnet
|
| 607 |
+
# title: FocalNet
|
| 608 |
+
# - local: model_doc/glpn
|
| 609 |
+
# title: GLPN
|
| 610 |
+
# - local: model_doc/imagegpt
|
| 611 |
+
# title: ImageGPT
|
| 612 |
+
# - local: model_doc/levit
|
| 613 |
+
# title: LeViT
|
| 614 |
+
# - local: model_doc/mask2former
|
| 615 |
+
# title: Mask2Former
|
| 616 |
+
# - local: model_doc/maskformer
|
| 617 |
+
# title: MaskFormer
|
| 618 |
+
# - local: model_doc/mobilenet_v1
|
| 619 |
+
# title: MobileNetV1
|
| 620 |
+
# - local: model_doc/mobilenet_v2
|
| 621 |
+
# title: MobileNetV2
|
| 622 |
+
# - local: model_doc/mobilevit
|
| 623 |
+
# title: MobileViT
|
| 624 |
+
# - local: model_doc/mobilevitv2
|
| 625 |
+
# title: MobileViTV2
|
| 626 |
+
# - local: model_doc/nat
|
| 627 |
+
# title: NAT
|
| 628 |
+
# - local: model_doc/poolformer
|
| 629 |
+
# title: PoolFormer
|
| 630 |
+
# - local: model_doc/pvt
|
| 631 |
+
# title: Pyramid Vision Transformer (PVT)
|
| 632 |
+
# - local: model_doc/pvt_v2
|
| 633 |
+
# title: Pyramid Vision Transformer v2 (PVTv2)
|
| 634 |
+
# - local: model_doc/regnet
|
| 635 |
+
# title: RegNet
|
| 636 |
+
# - local: model_doc/resnet
|
| 637 |
+
# title: ResNet
|
| 638 |
+
# - local: model_doc/segformer
|
| 639 |
+
# title: SegFormer
|
| 640 |
+
# - local: model_doc/seggpt
|
| 641 |
+
# title: SegGpt
|
| 642 |
+
# - local: model_doc/superpoint
|
| 643 |
+
# title: SuperPoint
|
| 644 |
+
# - local: model_doc/swiftformer
|
| 645 |
+
# title: SwiftFormer
|
| 646 |
+
# - local: model_doc/swin
|
| 647 |
+
# title: Swin Transformer
|
| 648 |
+
# - local: model_doc/swinv2
|
| 649 |
+
# title: Swin Transformer V2
|
| 650 |
+
# - local: model_doc/swin2sr
|
| 651 |
+
# title: Swin2SR
|
| 652 |
+
# - local: model_doc/table-transformer
|
| 653 |
+
# title: Table Transformer
|
| 654 |
+
# - local: model_doc/upernet
|
| 655 |
+
# title: UperNet
|
| 656 |
+
# - local: model_doc/van
|
| 657 |
+
# title: VAN
|
| 658 |
+
# - local: model_doc/vit
|
| 659 |
+
# title: Vision Transformer (ViT)
|
| 660 |
+
# - local: model_doc/vit_hybrid
|
| 661 |
+
# title: ViT Hybrid
|
| 662 |
+
# - local: model_doc/vitdet
|
| 663 |
+
# title: ViTDet
|
| 664 |
+
# - local: model_doc/vit_mae
|
| 665 |
+
# title: ViTMAE
|
| 666 |
+
# - local: model_doc/vitmatte
|
| 667 |
+
# title: ViTMatte
|
| 668 |
+
# - local: model_doc/vit_msn
|
| 669 |
+
# title: ViTMSN
|
| 670 |
+
# - local: model_doc/yolos
|
| 671 |
+
# title: YOLOS
|
| 672 |
+
# title: Vision models
|
| 673 |
+
# - isExpanded: false
|
| 674 |
+
# sections:
|
| 675 |
+
# - local: model_doc/audio-spectrogram-transformer
|
| 676 |
+
# title: Audio Spectrogram Transformer
|
| 677 |
+
# - local: model_doc/bark
|
| 678 |
+
# title: Bark
|
| 679 |
+
# - local: model_doc/clap
|
| 680 |
+
# title: CLAP
|
| 681 |
+
# - local: model_doc/encodec
|
| 682 |
+
# title: EnCodec
|
| 683 |
+
# - local: model_doc/hubert
|
| 684 |
+
# title: Hubert
|
| 685 |
+
# - local: model_doc/mctct
|
| 686 |
+
# title: MCTCT
|
| 687 |
+
# - local: model_doc/mms
|
| 688 |
+
# title: MMS
|
| 689 |
+
# - local: model_doc/musicgen
|
| 690 |
+
# title: MusicGen
|
| 691 |
+
# - local: model_doc/musicgen_melody
|
| 692 |
+
# title: MusicGen Melody
|
| 693 |
+
# - local: model_doc/pop2piano
|
| 694 |
+
# title: Pop2Piano
|
| 695 |
+
# - local: model_doc/seamless_m4t
|
| 696 |
+
# title: Seamless-M4T
|
| 697 |
+
# - local: model_doc/seamless_m4t_v2
|
| 698 |
+
# title: SeamlessM4T-v2
|
| 699 |
+
# - local: model_doc/sew
|
| 700 |
+
# title: SEW
|
| 701 |
+
# - local: model_doc/sew-d
|
| 702 |
+
# title: SEW-D
|
| 703 |
+
# - local: model_doc/speech_to_text
|
| 704 |
+
# title: Speech2Text
|
| 705 |
+
# - local: model_doc/speech_to_text_2
|
| 706 |
+
# title: Speech2Text2
|
| 707 |
+
# - local: model_doc/speecht5
|
| 708 |
+
# title: SpeechT5
|
| 709 |
+
# - local: model_doc/unispeech
|
| 710 |
+
# title: UniSpeech
|
| 711 |
+
# - local: model_doc/unispeech-sat
|
| 712 |
+
# title: UniSpeech-SAT
|
| 713 |
+
# - local: model_doc/univnet
|
| 714 |
+
# title: UnivNet
|
| 715 |
+
# - local: model_doc/vits
|
| 716 |
+
# title: VITS
|
| 717 |
+
# - local: model_doc/wav2vec2
|
| 718 |
+
# title: Wav2Vec2
|
| 719 |
+
# - local: model_doc/wav2vec2-bert
|
| 720 |
+
# title: Wav2Vec2-BERT
|
| 721 |
+
# - local: model_doc/wav2vec2-conformer
|
| 722 |
+
# title: Wav2Vec2-Conformer
|
| 723 |
+
# - local: model_doc/wav2vec2_phoneme
|
| 724 |
+
# title: Wav2Vec2Phoneme
|
| 725 |
+
# - local: model_doc/wavlm
|
| 726 |
+
# title: WavLM
|
| 727 |
+
# - local: model_doc/whisper
|
| 728 |
+
# title: Whisper
|
| 729 |
+
# - local: model_doc/xls_r
|
| 730 |
+
# title: XLS-R
|
| 731 |
+
# - local: model_doc/xlsr_wav2vec2
|
| 732 |
+
# title: XLSR-Wav2Vec2
|
| 733 |
+
# title: Audio models
|
| 734 |
+
# - isExpanded: false
|
| 735 |
+
# sections:
|
| 736 |
+
# - local: model_doc/timesformer
|
| 737 |
+
# title: TimeSformer
|
| 738 |
+
# - local: model_doc/videomae
|
| 739 |
+
# title: VideoMAE
|
| 740 |
+
# - local: model_doc/vivit
|
| 741 |
+
# title: ViViT
|
| 742 |
+
# title: Video models
|
| 743 |
+
# - isExpanded: false
|
| 744 |
+
# sections:
|
| 745 |
+
# - local: model_doc/align
|
| 746 |
+
# title: ALIGN
|
| 747 |
+
# - local: model_doc/altclip
|
| 748 |
+
# title: AltCLIP
|
| 749 |
+
# - local: model_doc/blip
|
| 750 |
+
# title: BLIP
|
| 751 |
+
# - local: model_doc/blip-2
|
| 752 |
+
# title: BLIP-2
|
| 753 |
+
# - local: model_doc/bridgetower
|
| 754 |
+
# title: BridgeTower
|
| 755 |
+
# - local: model_doc/bros
|
| 756 |
+
# title: BROS
|
| 757 |
+
# - local: model_doc/chinese_clip
|
| 758 |
+
# title: Chinese-CLIP
|
| 759 |
+
# - local: model_doc/clip
|
| 760 |
+
# title: CLIP
|
| 761 |
+
# - local: model_doc/clipseg
|
| 762 |
+
# title: CLIPSeg
|
| 763 |
+
# - local: model_doc/clvp
|
| 764 |
+
# title: CLVP
|
| 765 |
+
# - local: model_doc/data2vec
|
| 766 |
+
# title: Data2Vec
|
| 767 |
+
# - local: model_doc/deplot
|
| 768 |
+
# title: DePlot
|
| 769 |
+
# - local: model_doc/donut
|
| 770 |
+
# title: Donut
|
| 771 |
+
# - local: model_doc/flava
|
| 772 |
+
# title: FLAVA
|
| 773 |
+
# - local: model_doc/git
|
| 774 |
+
# title: GIT
|
| 775 |
+
# - local: model_doc/grounding-dino
|
| 776 |
+
# title: Grounding DINO
|
| 777 |
+
# - local: model_doc/groupvit
|
| 778 |
+
# title: GroupViT
|
| 779 |
+
# - local: model_doc/idefics
|
| 780 |
+
# title: IDEFICS
|
| 781 |
+
# - local: model_doc/idefics2
|
| 782 |
+
# title: Idefics2
|
| 783 |
+
# - local: model_doc/instructblip
|
| 784 |
+
# title: InstructBLIP
|
| 785 |
+
# - local: model_doc/kosmos-2
|
| 786 |
+
# title: KOSMOS-2
|
| 787 |
+
# - local: model_doc/layoutlm
|
| 788 |
+
# title: LayoutLM
|
| 789 |
+
# - local: model_doc/layoutlmv2
|
| 790 |
+
# title: LayoutLMV2
|
| 791 |
+
# - local: model_doc/layoutlmv3
|
| 792 |
+
# title: LayoutLMV3
|
| 793 |
+
# - local: model_doc/layoutxlm
|
| 794 |
+
# title: LayoutXLM
|
| 795 |
+
# - local: model_doc/lilt
|
| 796 |
+
# title: LiLT
|
| 797 |
+
# - local: model_doc/llava
|
| 798 |
+
# title: Llava
|
| 799 |
+
# - local: model_doc/llava_next
|
| 800 |
+
# title: LLaVA-NeXT
|
| 801 |
+
# - local: model_doc/lxmert
|
| 802 |
+
# title: LXMERT
|
| 803 |
+
# - local: model_doc/matcha
|
| 804 |
+
# title: MatCha
|
| 805 |
+
# - local: model_doc/mgp-str
|
| 806 |
+
# title: MGP-STR
|
| 807 |
+
# - local: model_doc/nougat
|
| 808 |
+
# title: Nougat
|
| 809 |
+
# - local: model_doc/oneformer
|
| 810 |
+
# title: OneFormer
|
| 811 |
+
# - local: model_doc/owlvit
|
| 812 |
+
# title: OWL-ViT
|
| 813 |
+
# - local: model_doc/owlv2
|
| 814 |
+
# title: OWLv2
|
| 815 |
+
# - local: model_doc/paligemma
|
| 816 |
+
# title: PaliGemma
|
| 817 |
+
# - local: model_doc/perceiver
|
| 818 |
+
# title: Perceiver
|
| 819 |
+
# - local: model_doc/pix2struct
|
| 820 |
+
# title: Pix2Struct
|
| 821 |
+
# - local: model_doc/sam
|
| 822 |
+
# title: Segment Anything
|
| 823 |
+
# - local: model_doc/siglip
|
| 824 |
+
# title: SigLIP
|
| 825 |
+
# - local: model_doc/speech-encoder-decoder
|
| 826 |
+
# title: Speech Encoder Decoder Models
|
| 827 |
+
# - local: model_doc/tapas
|
| 828 |
+
# title: TAPAS
|
| 829 |
+
# - local: model_doc/trocr
|
| 830 |
+
# title: TrOCR
|
| 831 |
+
# - local: model_doc/tvlt
|
| 832 |
+
# title: TVLT
|
| 833 |
+
# - local: model_doc/tvp
|
| 834 |
+
# title: TVP
|
| 835 |
+
# - local: model_doc/udop
|
| 836 |
+
# title: UDOP
|
| 837 |
+
# - local: model_doc/video_llava
|
| 838 |
+
# title: VideoLlava
|
| 839 |
+
# - local: model_doc/vilt
|
| 840 |
+
# title: ViLT
|
| 841 |
+
# - local: model_doc/vipllava
|
| 842 |
+
# title: VipLlava
|
| 843 |
+
# - local: model_doc/vision-encoder-decoder
|
| 844 |
+
# title: Vision Encoder Decoder Models
|
| 845 |
+
# - local: model_doc/vision-text-dual-encoder
|
| 846 |
+
# title: Vision Text Dual Encoder
|
| 847 |
+
# - local: model_doc/visual_bert
|
| 848 |
+
# title: VisualBERT
|
| 849 |
+
# - local: model_doc/xclip
|
| 850 |
+
# title: X-CLIP
|
| 851 |
+
# title: Multimodal models
|
| 852 |
+
# - isExpanded: false
|
| 853 |
+
# sections:
|
| 854 |
+
# - local: model_doc/decision_transformer
|
| 855 |
+
# title: محول القرار
|
| 856 |
+
# - local: model_doc/trajectory_transformer
|
| 857 |
+
# title: محول المسار
|
| 858 |
+
# title: نماذج التعلم التعزيزية
|
| 859 |
+
# - isExpanded: false
|
| 860 |
+
# sections:
|
| 861 |
+
# - local: model_doc/autoformer
|
| 862 |
+
# title: Autoformer
|
| 863 |
+
# - local: model_doc/informer
|
| 864 |
+
# title: Informer
|
| 865 |
+
# - local: model_doc/patchtsmixer
|
| 866 |
+
# title: PatchTSMixer
|
| 867 |
+
# - local: model_doc/patchtst
|
| 868 |
+
# title: PatchTST
|
| 869 |
+
# - local: model_doc/time_series_transformer
|
| 870 |
+
# title: محول السلاسل الزمنية
|
| 871 |
+
# title: نماذج السلاسل الزمنية
|
| 872 |
+
# - isExpanded: false
|
| 873 |
+
# sections:
|
| 874 |
+
# - local: model_doc/graphormer
|
| 875 |
+
# title: Graphormer
|
| 876 |
+
# title: نماذج الرسم البياني
|
| 877 |
+
# title: النماذج
|
| 878 |
+
# - sections:
|
| 879 |
+
# - local: internal/modeling_utils
|
| 880 |
+
# title: الطبقات المخصصة والمرافق
|
| 881 |
+
# - local: internal/pipelines_utils
|
| 882 |
+
# title: مرافق خطوط الأنابيب
|
| 883 |
+
# - local: internal/tokenization_utils
|
| 884 |
+
# title: مرافق مقسم النصوص
|
| 885 |
+
# - local: internal/trainer_utils
|
| 886 |
+
# title: مرافق المدرب
|
| 887 |
+
# - local: internal/generation_utils
|
| 888 |
+
# title: مرافق التوليد
|
| 889 |
+
# - local: internal/image_processing_utils
|
| 890 |
+
# title: مرافق معالجة الصور
|
| 891 |
+
# - local: internal/audio_utils
|
| 892 |
+
# title: مرافق معالجة الصوت
|
| 893 |
+
# - local: internal/file_utils
|
| 894 |
+
# title: مرافق عامة
|
| 895 |
+
# - local: internal/time_series_utils
|
| 896 |
+
# title: مرافق السلاسل الزمنية
|
| 897 |
+
# title: مساعدون داخليون
|
| 898 |
+
# title: API
|
tasks/tasksmith-441eeab80047/environment/source/docs/source/ar/accelerate.md
ADDED
|
@@ -0,0 +1,120 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
# التدريب الموزع باستخدام 🤗 Accelerate
|
| 2 |
+
|
| 3 |
+
|
| 4 |
+
مع تزايد حجم النماذج اللغوية، برز التوازي كأحد الاستراتيجيات لتدريب نماذج أكبر على أجهزة محدودة وتسريع عملية التدريب بمقدار كبير. أنشأنا في Hugging Face، قمنا بإنشاء مكتبة [ Accelerate](https://huggingface.co/docs/accelerate) لمساعدة المستخدمين على تدريب أي نموذج من Transformers بسهولة على أي نوع من الإعدادات الموزعة، سواء كان ذلك على عدة وحدات معالجة رسومات (GPUs) على جهاز واحد أو على عدة وحدات معالجة رسومات موزعة على عدة أجهزة. في هذا الدليل، تعلم كيفية تخصيص حلقة تدريب PyTorch الأصلية لتمكين التدريب في بيئة موزعة.
|
| 5 |
+
|
| 6 |
+
## الإعداد
|
| 7 |
+
|
| 8 |
+
ابدأ بتثبيت 🤗 Accelerate:
|
| 9 |
+
|
| 10 |
+
```bash
|
| 11 |
+
pip install accelerate
|
| 12 |
+
```
|
| 13 |
+
|
| 14 |
+
ثم قم باستيراد وإنشاء كائن [`~accelerate.Accelerator`]. سيقوم [`~accelerate.Accelerator`] تلقائيًا باكتشاف نوع الإعداد الموزع الخاص بك وتهيئة جميع المكونات اللازمة للتدريب. لن تحتاج إلى وضع نموذجك على جهاز بشكل معين.
|
| 15 |
+
|
| 16 |
+
```py
|
| 17 |
+
>>> from accelerate import Accelerator
|
| 18 |
+
|
| 19 |
+
>>> accelerator = Accelerator()
|
| 20 |
+
```
|
| 21 |
+
|
| 22 |
+
## الاستعداد للتسريع
|
| 23 |
+
|
| 24 |
+
الخطوة التالية هي تمرير جميع كائنات التدريب ذات الصلة إلى دالة الإعداد [`~accelerate.Accelerator.prepare`]. ويشمل ذلك DataLoaders للتدريب والتقييم، ونموذجًا ومُحَسِّنً المعاملات (optimizer):
|
| 25 |
+
|
| 26 |
+
```py
|
| 27 |
+
>>> train_dataloader, eval_dataloader, model, optimizer = accelerator.prepare(
|
| 28 |
+
... train_dataloader, eval_dataloader, model, optimizer
|
| 29 |
+
... )
|
| 30 |
+
```
|
| 31 |
+
|
| 32 |
+
## الخلفي Backward
|
| 33 |
+
|
| 34 |
+
الإضافة الأخيرة هي استبدال الدالة المعتادة `loss.backward()` في حلقة التدريب الخاصة بك بدالة [`~accelerate.Accelerator.backward`] في 🤗 Accelerate:
|
| 35 |
+
|
| 36 |
+
```py
|
| 37 |
+
>>> for epoch in range(num_epochs):
|
| 38 |
+
... for batch in train_dataloader:
|
| 39 |
+
... outputs = model(**batch)
|
| 40 |
+
... loss = outputs.loss
|
| 41 |
+
... accelerator.backward(loss)
|
| 42 |
+
|
| 43 |
+
... optimizer.step()
|
| 44 |
+
... lr_scheduler.step()
|
| 45 |
+
... optimizer.zero_grad()
|
| 46 |
+
... progress_bar.update(1)
|
| 47 |
+
```
|
| 48 |
+
|
| 49 |
+
كما يمكنك أن ترى في الكود التالي، فأنت بحاجة فقط إلى إضافة أربعة أسطر من الكود إلى حلقة التدريب الخاصة بك لتمكين التدريب الموزع!
|
| 50 |
+
|
| 51 |
+
```diff
|
| 52 |
+
+ from accelerate import Accelerator
|
| 53 |
+
from transformers import AdamW, AutoModelForSequenceClassification, get_scheduler
|
| 54 |
+
|
| 55 |
+
+ accelerator = Accelerator()
|
| 56 |
+
|
| 57 |
+
model = AutoModelForSequenceClassification.from_pretrained(checkpoint, num_labels=2)
|
| 58 |
+
optimizer = AdamW(model.parameters(), lr=3e-5)
|
| 59 |
+
|
| 60 |
+
- device = torch.device("cuda") if torch.cuda.is_available() else torch.device("cpu")
|
| 61 |
+
- model.to(device)
|
| 62 |
+
|
| 63 |
+
+ train_dataloader, eval_dataloader, model, optimizer = accelerator.prepare(
|
| 64 |
+
+ train_dataloader, eval_dataloader, model, optimizer
|
| 65 |
+
+ )
|
| 66 |
+
|
| 67 |
+
num_epochs = 3
|
| 68 |
+
num_training_steps = num_epochs * len(train_dataloader)
|
| 69 |
+
lr_scheduler = get_scheduler(
|
| 70 |
+
"linear",
|
| 71 |
+
optimizer=optimizer,
|
| 72 |
+
num_warmup_steps=0,
|
| 73 |
+
num_training_steps=num_training_steps
|
| 74 |
+
)
|
| 75 |
+
|
| 76 |
+
progress_bar = tqdm(range(num_training_steps))
|
| 77 |
+
|
| 78 |
+
model.train()
|
| 79 |
+
for epoch in range(num_epochs):
|
| 80 |
+
for batch in train_dataloader:
|
| 81 |
+
- batch = {k: v.to(device) for k, v in batch.items()}
|
| 82 |
+
outputs = model(**batch)
|
| 83 |
+
loss = outputs.loss
|
| 84 |
+
- loss.backward()
|
| 85 |
+
+ accelerator.backward(loss)
|
| 86 |
+
optimizer.step()
|
| 87 |
+
lr_scheduler.step()
|
| 88 |
+
optimizer.zero_grad()
|
| 89 |
+
progress_bar.update(1)
|
| 90 |
+
```
|
| 91 |
+
|
| 92 |
+
## تدريب
|
| 93 |
+
|
| 94 |
+
بمجرد إضافة أسطر الكود ذات الصلة، قم بتشغيل التدريب الخاص بك في أحد النصوص أو الدفاتر مثل Colaboratory.
|
| 95 |
+
|
| 96 |
+
### التدريب باستخدام نص برمجي
|
| 97 |
+
|
| 98 |
+
إذا كنت تشغل التدريب الخاص بك من نص برمجي، فقم بتشغيل الأمر التالي لإنشاء وحفظ ملف تكوين:
|
| 99 |
+
|
| 100 |
+
```bash
|
| 101 |
+
accelerate config
|
| 102 |
+
```
|
| 103 |
+
|
| 104 |
+
ثم قم بتشغيل التدريب الخاص بك باستخدام:
|
| 105 |
+
|
| 106 |
+
```bash
|
| 107 |
+
accelerate launch train.py
|
| 108 |
+
```
|
| 109 |
+
|
| 110 |
+
### التدريب باستخدام دفتر ملاحظات
|
| 111 |
+
|
| 112 |
+
يمكن أيضًا تشغيل 🤗 Accelerate في دفاتر إذا كنت تخطط لاستخدام وحدات معالجة الرسوميات (TPUs) في Colaboratory. قم بتغليف كل الكود المسؤول عن التدريب في دالة، ومررها إلى [`~accelerate.notebook_launcher`]:
|
| 113 |
+
|
| 114 |
+
```py
|
| 115 |
+
>>> from accelerate import notebook_launcher
|
| 116 |
+
|
| 117 |
+
>>> notebook_launcher(training_function)
|
| 118 |
+
```
|
| 119 |
+
|
| 120 |
+
للحصول على مزيد من المعلومات حول 🤗 Accelerate وميزاته الغنية، يرجى الرجوع إلى [الوثائق](https://huggingface.co/docs/accelerate).
|
tasks/tasksmith-441eeab80047/environment/source/docs/source/ar/agents.md
ADDED
|
@@ -0,0 +1,539 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
# الوكلاء والأدوات
|
| 2 |
+
|
| 3 |
+
[[open-in-colab]]
|
| 4 |
+
|
| 5 |
+
### ما هو الوكيل؟
|
| 6 |
+
|
| 7 |
+
يمكن للنظم اللغوية الكبيرة (LLMs) التي تم تدريبها على أداء [نمذجة اللغة السببية](./tasks/language_modeling.) التعامل مع مجموعة واسعة من المهام، ولكنها غالبًا ما تواجه صعوبات في المهام الأساسية مثل المنطق والحساب والبحث. وعندما يتم استدعاؤها في مجالات لا تؤدي فيها أداءً جيدًا، فإنها غالبًا ما تفشل في توليد الإجابة التي نتوقعها منها.
|
| 8 |
+
|
| 9 |
+
يتمثل أحد النهج للتغلب على هذا القصور في إنشاء "وكيل".
|
| 10 |
+
|
| 11 |
+
الوكيل هو نظام يستخدم LLM كمحرك له، ولديه حق الوصول إلى وظائف تسمى "أدوات".
|
| 12 |
+
|
| 13 |
+
هذه "الأدوات" هي وظائف لأداء مهمة، وتحتوي على جميع الأوصاف اللازمة للوكيل لاستخدامها بشكل صحيح.
|
| 14 |
+
|
| 15 |
+
يمكن برمجة الوكيل للقيام بما يلي:
|
| 16 |
+
- وضع سلسلة من الإجراءات/الأدوات وتشغيلها جميعًا في نفس الوقت مثل [`CodeAgent`] على سبيل المثال
|
| 17 |
+
- التخطيط للاجراءات/الأدوات وتنفيذها واحدة تلو الأخرى والانتظار حتى انتهاء كل إجراء قبل إطلاق التالي مثل [`ReactJsonAgent`] على سبيل المثال
|
| 18 |
+
|
| 19 |
+
### أنواع الوكلاء
|
| 20 |
+
|
| 21 |
+
#### الوكيل البرمجي (Code agent)
|
| 22 |
+
|
| 23 |
+
يتمتع هذا الوكيل يتبع خطوات محددة: أولًا، يخطط لسلسلة من الإجراءات التي يريد تنفيذها، ثم شفرة Python لتنفيذ جميع الإجراءات في نفس الوقت. وهو يتعامل بشكل أصلي مع أنواع مختلفة من المدخلات والمخرجات للأدوات التي يستخدمها، وبالتالي فهو الخيار الموصى به للمهام متعددة الوسائط.
|
| 24 |
+
|
| 25 |
+
#### وكلاء التفاعل
|
| 26 |
+
|
| 27 |
+
هذا هو الوكيل الذي يتم اللجوء إليه لحل مهام الاستدلال، حيث يجعل إطار ReAct ([Yao et al.، 2022](https://huggingface.co/papers/2210.03629)) من الكفاءة حقًا التفكير على أساس ملاحظاته السابقة.
|
| 28 |
+
|
| 29 |
+
نقوم بتنفيذ إصدارين من ReactJsonAgent:
|
| 30 |
+
- [`ReactJsonAgent`] يقوم بتوليد استدعاءات الأدوات كـ JSON في إخراجها.
|
| 31 |
+
- [`ReactCodeAgent`] هو نوع جديد من ReactJsonAgent يقوم بتوليد استدعاءات أدواته كمقاطع من التعليمات البرمجية، والتي تعمل بشكل جيد حقًا مع LLMs التي تتمتع بأداء قوي في البرمجة.
|
| 32 |
+
|
| 33 |
+
> [!TIP]
|
| 34 |
+
> اقرأ منشور المدونة [Open-source LLMs as LangChain Agents](https://huggingface.co/blog/open-source-llms-as-agents) لمعرفة المزيد عن وكيل ReAct.
|
| 35 |
+
|
| 36 |
+
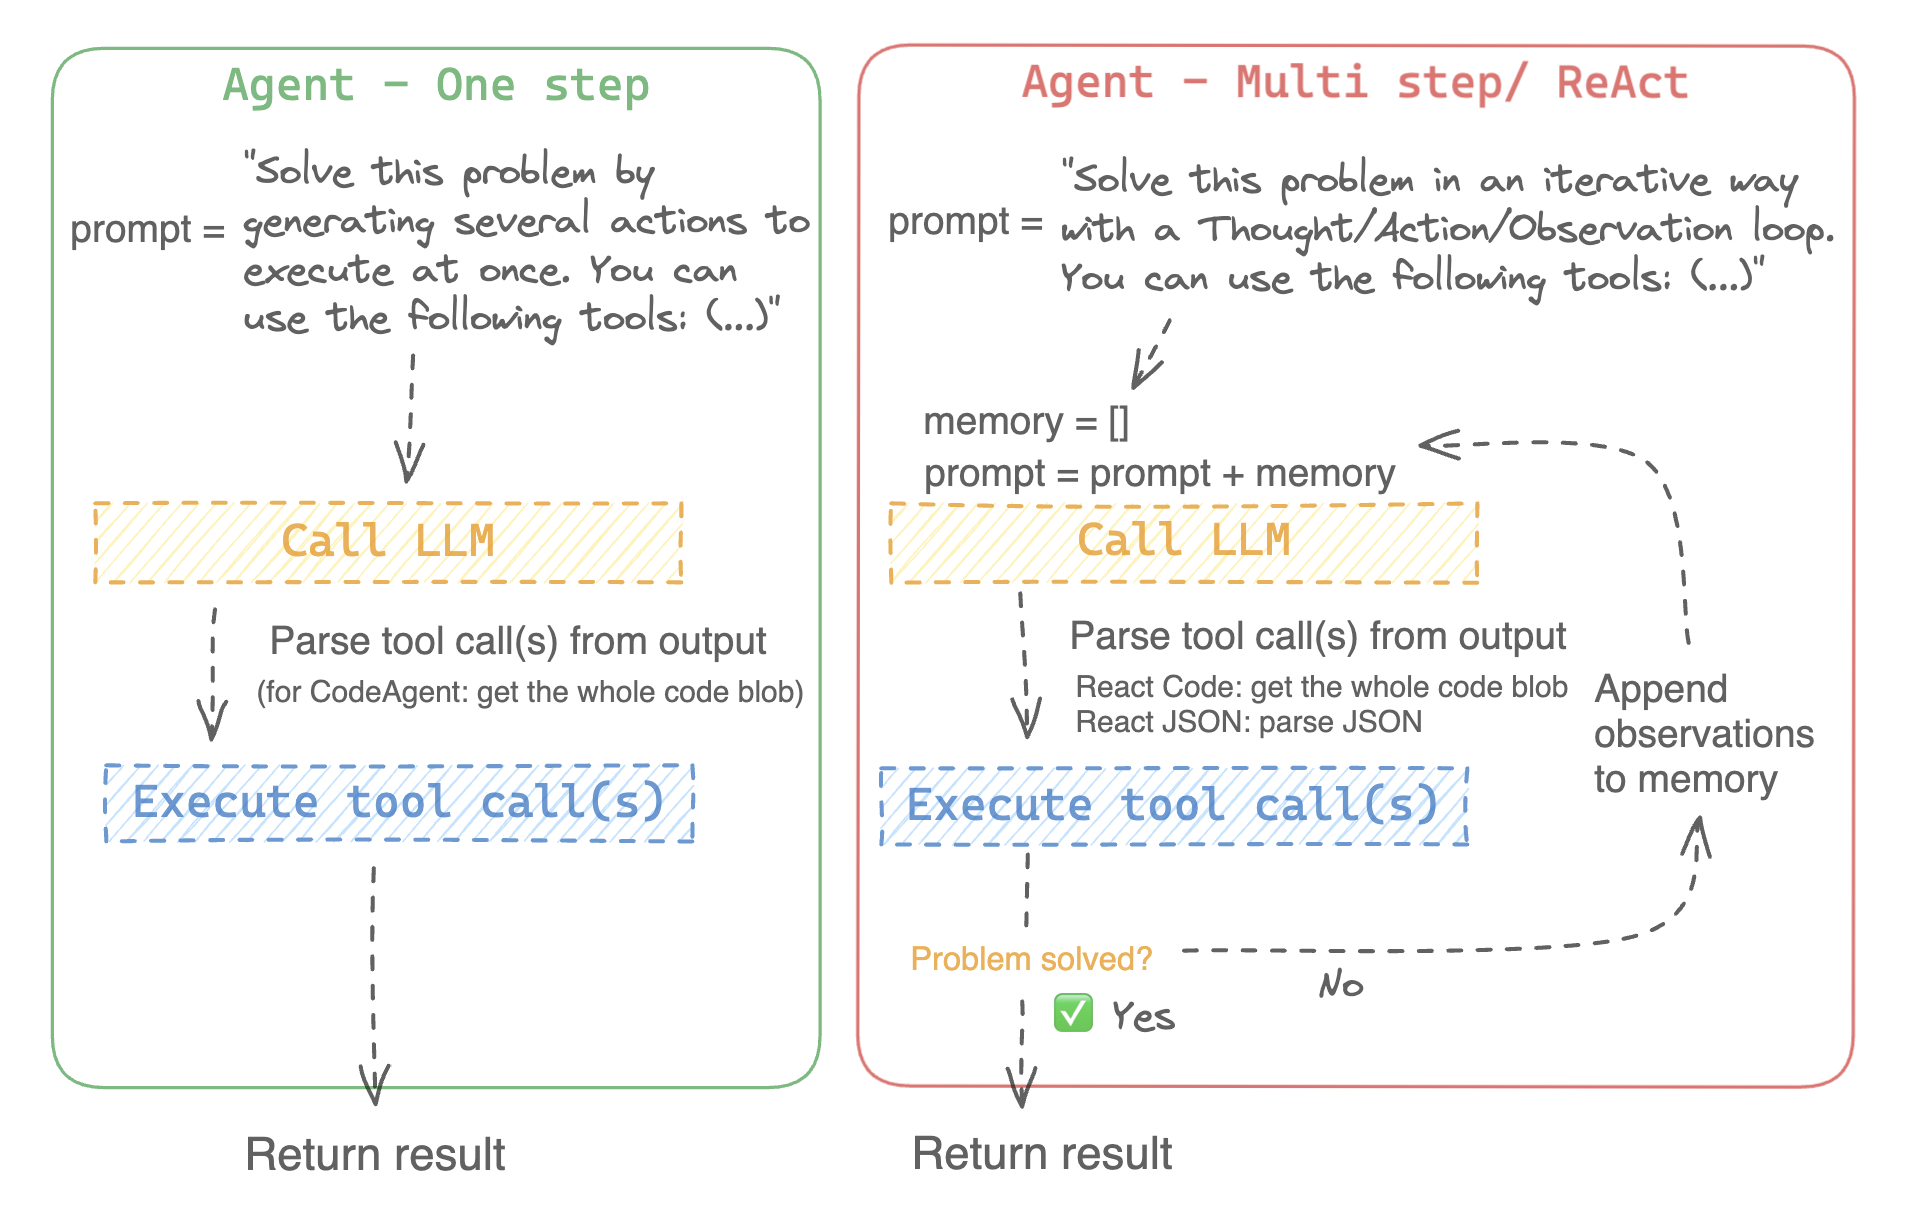
|
| 37 |
+
|
| 38 |
+
على سبيل المثال، إليك كيف يعمل وكيل ReAct Code طريقه من خلال السؤال التالي.
|
| 39 |
+
|
| 40 |
+
```py3
|
| 41 |
+
>>> agent.run(
|
| 42 |
+
... "How many more blocks (also denoted as layers) in BERT base encoder than the encoder from the architecture proposed in Attention is All You Need?",
|
| 43 |
+
... )
|
| 44 |
+
=====New task=====
|
| 45 |
+
How many more blocks (also denoted as layers) in BERT base encoder than the encoder from the architecture proposed in Attention is All You Need?
|
| 46 |
+
====Agent is executing the code below:
|
| 47 |
+
bert_blocks = search(query="number of blocks in BERT base encoder")
|
| 48 |
+
print("BERT blocks:", bert_blocks)
|
| 49 |
+
====
|
| 50 |
+
Print outputs:
|
| 51 |
+
BERT blocks: twelve encoder blocks
|
| 52 |
+
|
| 53 |
+
====Agent is executing the code below:
|
| 54 |
+
attention_layer = search(query="number of layers in Attention is All You Need")
|
| 55 |
+
print("Attention layers:", attention_layer)
|
| 56 |
+
====
|
| 57 |
+
Print outputs:
|
| 58 |
+
Attention layers: Encoder: The encoder is composed of a stack of N = 6 identical layers. Each layer has two sub-layers. The first is a multi-head self-attention mechanism, and the second is a simple, position- 2 Page 3 Figure 1: The Transformer - model architecture.
|
| 59 |
+
|
| 60 |
+
====Agent is executing the code below:
|
| 61 |
+
bert_blocks = 12
|
| 62 |
+
attention_layers = 6
|
| 63 |
+
diff = bert_blocks - attention_layers
|
| 64 |
+
print("Difference in blocks:", diff)
|
| 65 |
+
final_answer(diff)
|
| 66 |
+
====
|
| 67 |
+
|
| 68 |
+
Print outputs:
|
| 69 |
+
Difference in blocks: 6
|
| 70 |
+
|
| 71 |
+
Final answer: 6
|
| 72 |
+
```
|
| 73 |
+
|
| 74 |
+
### كيف يمكنني بناء وكيل؟
|
| 75 |
+
|
| 76 |
+
لتهيئة وكيل، تحتاج إلى هذه الوسائط:
|
| 77 |
+
|
| 78 |
+
- نموذج لغوي كبير (LLM) يشكل المحرك الأساسي للوكيل. الوكيل نفسه ليس النموذج اللغوي، بل هو برنامج يستخدم النموذج اللغوي كمحرك له.
|
| 79 |
+
- موجه النظام (system prompt): هذه هي التعليمات التي يتم إعط��ؤها للنموذج اللغوي لإنشاء مخرجاته.
|
| 80 |
+
- صندوق أدوات (toolbox) يختار الوكيل منه الأدوات لتنفيذها
|
| 81 |
+
- محلل (parser) لاستخراج الأدوات التي يجب استدعاؤها من مخرجات النموذج اللغوي LLM والأدوات التي يجب استخدامها
|
| 82 |
+
|
| 83 |
+
عند تهيئة نظام الوكيل، يتم استخدام سمات الأداة لإنشاء وصف للأداة، ثم يتم دمجها في موجه النظام الخاص `system_prompt` للوكيل لإعلامه بالأدوات التي يمكنه استخدامها ولماذا.
|
| 84 |
+
|
| 85 |
+
للبدء، يرجى تثبيت `agents` الإضافية لتثبيت جميع التبعيات الافتراضية.
|
| 86 |
+
|
| 87 |
+
```bash
|
| 88 |
+
pip install transformers[agents]
|
| 89 |
+
```
|
| 90 |
+
|
| 91 |
+
قم ببناء محرك LLM الخاص بك من خلال تعريف طريقة `llm_engine` التي تقبل قائمة من [الرسائل](./chat_templating.) وتعيد النص. يجب أن تقبل هذه الدالة القابلة للاستدعاء أيضًا معامل `stop` يشير إلى متى يجب التوقف عن التوليد.
|
| 92 |
+
|
| 93 |
+
```python
|
| 94 |
+
from huggingface_hub import login, InferenceClient
|
| 95 |
+
|
| 96 |
+
login("<YOUR_HUGGINGFACEHUB_API_TOKEN>")
|
| 97 |
+
|
| 98 |
+
client = InferenceClient(model="meta-llama/Meta-Llama-3-70B-Instruct")
|
| 99 |
+
|
| 100 |
+
def llm_engine(messages, stop_sequences=["Task"]) -> str:
|
| 101 |
+
response = client.chat_completion(messages, stop=stop_sequences, max_tokens=1000)
|
| 102 |
+
answer = response.choices[0].message.content
|
| 103 |
+
return answer
|
| 104 |
+
```
|
| 105 |
+
|
| 106 |
+
يمكنك استخدام أي طريقة `llm_engine` طالما أنها:
|
| 107 |
+
1. يتبع تنسيق [رسائل](./chat_templating.md) لإدخاله (`List [Dict [str، str]]`) ويعيد `str`
|
| 108 |
+
2. يتوقف عن توليد المخراجات من التسلسلات التي تم تمريرها في معامل `stop`
|
| 109 |
+
|
| 110 |
+
أنت بحاجة أيضًا إلى معامل "الأدوات" الذي يقبل قائمة من "الأدوات". يمكنك توفير قائمة فارغة لـ "الأدوات"، ولكن استخدم صندوق الأدوات الافتراضي مع معامل اختياري `add_base_tools=True`.
|
| 111 |
+
|
| 112 |
+
الآن يمكنك إنشاء وكيل، مثل [`CodeAgent`], وتشغيله. ولتسهيل الأمر، نقدم أيضًا فئة [`HfEngine`] التي تستخدم `huggingface_hub.InferenceClient` بشكل مخفى.
|
| 113 |
+
|
| 114 |
+
```python
|
| 115 |
+
from transformers import CodeAgent, HfEngine
|
| 116 |
+
|
| 117 |
+
llm_engine = HfEngine(model="meta-llama/Meta-Llama-3-70B-Instruct")
|
| 118 |
+
agent = CodeAgent(tools=[], llm_engine=llm_engine, add_base_tools=True)
|
| 119 |
+
|
| 120 |
+
agent.run(
|
| 121 |
+
"Could you translate this sentence from French, say it out loud and return the audio.",
|
| 122 |
+
sentence="Où est la boulangerie la plus proche?",
|
| 123 |
+
)
|
| 124 |
+
```
|
| 125 |
+
|
| 126 |
+
هذه الميزة ستكون مفيدة في حالة الحاجة الملحة! يمكنك حتى ترك معامل `llm_engine` غير محدد، وسيتم إنشاء [`HfEngine`] بشكل تلقائي.
|
| 127 |
+
|
| 128 |
+
```python
|
| 129 |
+
from transformers import CodeAgent
|
| 130 |
+
|
| 131 |
+
agent = CodeAgent(tools=[], add_base_tools=True)
|
| 132 |
+
|
| 133 |
+
agent.run(
|
| 134 |
+
"Could you translate this sentence from French, say it out loud and give me the audio.",
|
| 135 |
+
sentence="Où est la boulangerie la plus proche?",
|
| 136 |
+
)
|
| 137 |
+
```
|
| 138 |
+
|
| 139 |
+
لاحظ أننا استخدمنا معامل "sentence" إضافي: يمكنك تمرير النص كمعامل إضافي إلى النموذج.
|
| 140 |
+
|
| 141 |
+
يمكنك أيضًا استخدام هذا للإشارة إلى مسار الملفات المحلية أو البعيدة للنموذج لاستخدامها:
|
| 142 |
+
|
| 143 |
+
```py
|
| 144 |
+
from transformers import ReactCodeAgent
|
| 145 |
+
|
| 146 |
+
agent = ReactCodeAgent(tools=[], llm_engine=llm_engine, add_base_tools=True)
|
| 147 |
+
|
| 148 |
+
agent.run("Why does Mike not know many people in New York?", audio="https://huggingface.co/datasets/huggingface/documentation-images/resolve/main/transformers/recording.mp3")
|
| 149 |
+
```
|
| 150 |
+
|
| 151 |
+
|
| 152 |
+
تم تحديد موجه النظام ومحلل المخرجات تلقائيًا، ولكن يمكنك فحصهما بسهولة عن طريق استدعاء `system_prompt_template` على وكيلك.
|
| 153 |
+
|
| 154 |
+
```python
|
| 155 |
+
print(agent.system_prompt_template)
|
| 156 |
+
```
|
| 157 |
+
|
| 158 |
+
من المهم أن تشرح بأكبر قدر ممكن من الوضوح المهمة التي تريد تنفيذها.
|
| 159 |
+
كل عملية [`~Agent.run`] مستقلة، وبما أن الوكيل مدعوم من LLM، فقد تؤدي الاختلافات الطفيفة في موجهك إلى نتائج مختلفة تمامًا.
|
| 160 |
+
يمكنك أيضًا تشغيل وكيل بشكل متتالي لمهام مختلفة: في كل مرة يتم فيها إعادة تهيئة سمتي `agent.task` و`agent.logs`.
|
| 161 |
+
|
| 162 |
+
|
| 163 |
+
#### تنفيذ التعليمات البرمجية
|
| 164 |
+
|
| 165 |
+
يقوم مفسر Python بتنفيذ التعليمات البرمجية على مجموعة من المدخلات التي يتم تمريرها جنبًا إلى جنب مع أدواتك.
|
| 166 |
+
يجب أن يكون هذا الأمر آمنًا لأن الوظائف الوحيدة التي يمكن استدعاؤها هي الأدوات التي ق��متها (خاصة إذا كانت أدوات من Hugging Face فقط) ووظيفة الطباعة، لذا فأنت مقيد بالفعل بما يمكن تنفيذه.
|
| 167 |
+
|
| 168 |
+
مفسر Python لا يسمح أيضًا باستدعاء دوال بشكل افتراضي خارج قائمة آمنة، لذا فإن جميع الهجمات الأكثر وضوحًا لا ينبغي أن تكون مشكلة.
|
| 169 |
+
يمكنك أيضًا الإذن باستيرادات إضافية عن طريق تمرير الوحدات النمطية المصرح بها كقائمة من السلاسل في معامل `additional_authorized_imports` عند تهيئة [`ReactCodeAgent`] أو [`CodeAgent`]:
|
| 170 |
+
|
| 171 |
+
```py
|
| 172 |
+
>>> from transformers import ReactCodeAgent
|
| 173 |
+
|
| 174 |
+
>>> agent = ReactCodeAgent(tools=[], additional_authorized_imports=['requests', 'bs4'])
|
| 175 |
+
>>> agent.run("Could you get me the title of the page at url 'https://huggingface.co/blog'?")
|
| 176 |
+
|
| 177 |
+
(...)
|
| 178 |
+
'Hugging Face – Blog'
|
| 179 |
+
```
|
| 180 |
+
|
| 181 |
+
سيتم إيقاف التنفيذ عند أي رمز يحاول تنفيذ عملية غير قانونية أو إذا كان هناك خطأ Python عادي في التعليمات البرمجية التي تم إنشاؤها بواسطة الوكيل.
|
| 182 |
+
|
| 183 |
+
> [!WARNING]
|
| 184 |
+
> يمكن لـ LLM توليد شفرة برمجية عشوائية سيتم تنفيذها بعد ذلك: لا تقمب استدعاء أى دوال غير آمنة!
|
| 185 |
+
|
| 186 |
+
### موجه النظام
|
| 187 |
+
|
| 188 |
+
ينشئ الوكيل، أو بالأحرى LLM الذي يقود الوكيل، يولد مخرجات بناءً على موجه النظام. يمكن تخصيص موجه النظام وتصميمه للمهام المقصودة. على سبيل المثال، تحقق من موجه النظام لـ [`ReactCodeAgent`] (الإصدار أدناه مبسط قليلاً).
|
| 189 |
+
|
| 190 |
+
```text
|
| 191 |
+
You will be given a task to solve as best you can.
|
| 192 |
+
You have access to the following tools:
|
| 193 |
+
<<tool_descriptions>>
|
| 194 |
+
|
| 195 |
+
To solve the task, you must plan forward to proceed in a series of steps, in a cycle of 'Thought:', 'Code:', and 'Observation:' sequences.
|
| 196 |
+
|
| 197 |
+
At each step, in the 'Thought:' sequence, you should first explain your reasoning towards solving the task, then the tools that you want to use.
|
| 198 |
+
Then in the 'Code:' sequence, you should write the code in simple Python. The code sequence must end with '/End code' sequence.
|
| 199 |
+
During each intermediate step, you can use 'print()' to save whatever important information you will then need.
|
| 200 |
+
These print outputs will then be available in the 'Observation:' field, for using this information as input for the next step.
|
| 201 |
+
|
| 202 |
+
In the end you have to return a final answer using the `final_answer` tool.
|
| 203 |
+
|
| 204 |
+
Here are a few examples using notional tools:
|
| 205 |
+
---
|
| 206 |
+
{examples}
|
| 207 |
+
|
| 208 |
+
Above example were using notional tools that might not exist for you. You only have access to those tools:
|
| 209 |
+
<<tool_names>>
|
| 210 |
+
You also can perform computations in the python code you generate.
|
| 211 |
+
|
| 212 |
+
Always provide a 'Thought:' and a 'Code:\n```py' sequence ending with '```<end_code>' sequence. You MUST provide at least the 'Code:' sequence to move forward.
|
| 213 |
+
|
| 214 |
+
Remember to not perform too many operations in a single code block! You should split the task into intermediate code blocks.
|
| 215 |
+
Print results at the end of each step to save the intermediate results. Then use final_answer() to return the final result.
|
| 216 |
+
|
| 217 |
+
Remember to make sure that variables you use are all defined.
|
| 218 |
+
|
| 219 |
+
Now Begin!
|
| 220 |
+
```
|
| 221 |
+
|
| 222 |
+
يتضمن موجه النظام:
|
| 223 |
+
- *مقدمة* تشرح كيف يجب أن يتصرف الوكيل والأدوات التي يجب عليه استخدامها.
|
| 224 |
+
- وصف لجميع الأدوات التي يتم تحديدها بواسطة رمز `<<tool_descriptions>>` الذي يتم استبداله ديناميكيًا في وقت التشغيل بالأدوات التي يحددها المستخدم أو يختارها.
|
| 225 |
+
- يأتي وصف الأداة من سمات الأداة، `name`، و`description`، و`inputs` و`output_type`، وقالب `jinja2` بسيط يمكنك تحسينه.
|
| 226 |
+
- شكل المخرج المتوقع.
|
| 227 |
+
|
| 228 |
+
يمكنك تحسين موجه النظام، على سبيل المثال، عن طريق إضافة شرح لتنسيق المخرجات.
|
| 229 |
+
|
| 230 |
+
للحصول على أقصى قدر من المرونة، يمكنك الكتابة فوق قالب موجه النظام بالكامل عن طريق تمرير موجه مخصص كمعامل إلى معلمة `system_prompt`.
|
| 231 |
+
|
| 232 |
+
```python
|
| 233 |
+
from transformers import ReactJsonAgent
|
| 234 |
+
from transformers.agents import PythonInterpreterTool
|
| 235 |
+
|
| 236 |
+
agent = ReactJsonAgent(tools=[PythonInterpreterTool()], system_prompt="{your_custom_prompt}")
|
| 237 |
+
```
|
| 238 |
+
|
| 239 |
+
> [!WARNING]
|
| 240 |
+
> يرجى التأكد من تحديد سلسلة `<<tool_descriptions>>` في مكان ما في `template` حتى يكون الوكيل على علم
|
| 241 |
+
بالأدوات المتاحة.
|
| 242 |
+
|
| 243 |
+
|
| 244 |
+
### فحص تشغيل الوكيل
|
| 245 |
+
|
| 246 |
+
فيما يلي بعض السمات المفيدة لفحص ما حدث بعد التشغيل:
|
| 247 |
+
- تخزن `agent.logs` سجلات مفصلة للوكيل. في كل خطوة من تشغيل الوكيل، يتم تخزين كل شيء في قاموس إلحاقه بـ `agent.logs`.
|
| 248 |
+
- تشغيل `agent.write_inner_memory_from_logs()` يخلق ذاكرة داخلية لسجلات الوكيل للنظام LLM لعرضها، كقائمة من رسائل الدردشة. تنتقل هذه الطريقة عبر كل خطوة من سجل الوكيل ولا تخزن سوى ما يهمها كرسالة: على سبيل المثال، سيحفظ موجه النظام والمهمة في رسائل منفصلة، ثم لكل خطوة سيخزن مخرج LLM كرسالة، ومخرج استدعاء الأداة كرسالة أخرى. استخدم هذا إذا كنت تريد عرضًا عامًا لما حدث - ولكن لن يتم نسخ كل سجل بواسطة هذه الطريقة.
|
| 249 |
+
|
| 250 |
+
## الأدوات
|
| 251 |
+
|
| 252 |
+
الأداة هي عبارة عن وظيفة أساسية يستخدمها الوكيل لتنفيذ مهمة محددة.
|
| 253 |
+
|
| 254 |
+
يمكنك على سبيل المثال التحقق من [`PythonInterpreterTool`]: لديه اسم ووصف ووصف للمدخلات ونوع للمخرج، وطريقة `__call__` التي تقوم بتنفيذ المهمة المطلوبة.
|
| 255 |
+
|
| 256 |
+
عند تهيئة الوكيل، يتم استخدام سمات الأداة لتوليد وصف للأداة يتم تضمينه في موجه النظام الخاص بالوكيل. يتيح هذا للوكيل معرفة الأدوات التي يمكنه استخدامها ولماذا.
|
| 257 |
+
|
| 258 |
+
### صندوق الأدوات الافتراضي
|
| 259 |
+
|
| 260 |
+
يأتي Transformers مع صندوق أدوات افتراضي لتمكين الوكلاء، والذي يمكنك إضافته إلى وكيلك عند التهيئة باستخدام معامل `add_base_tools = True`:
|
| 261 |
+
|
| 262 |
+
- **الإجابة على أسئلة المستند**: الإجابة على سؤال حول المستند (مثل ملف PDF) بتنسيق صورة ([Donut](./model_doc/donut))
|
| 263 |
+
- **الإجابة على أسئلة الصور**: الإجابة على سؤال حول صورة ([VILT](./model_doc/vilt))
|
| 264 |
+
- **التحدث إلى النص**: قم بتفريغ الكلام إلى نص ([Whisper](./model_doc/whisper))
|
| 265 |
+
- **النص إلى كلام**: تحويل النص إلى كلام ([SpeechT5](./model_doc/speecht5))
|
| 266 |
+
- **الترجمة**: ترجمة جملة معينة من لغة المصدر إلى لغة الهدف.
|
| 267 |
+
- **مفسر كود Python**: تشغيل كود Python الذي تم إنشاؤه بواسطة LLM في بيئة آمنة. لن يتم إضافة هذه الأداة إلى [`ReactJsonAgent`] إلا إذا استخدمت `add_base_tools=True`، نظرًا لأن الأدوات المستندة إلى التعليمات البرمجية يمكنها بالفعل تنفيذ كود Python
|
| 268 |
+
لا تترجم النصوص الخاصة ولا الأكواد البرمجية ولا الروابط ولا رموز HTML وCSS:
|
| 269 |
+
|
| 270 |
+
يمكنك استخدام أداة يدويًا عن طريق استدعاء دالة [`load_tool`] وتحديد مهمة لتنفيذها.
|
| 271 |
+
|
| 272 |
+
```python
|
| 273 |
+
from transformers import load_tool
|
| 274 |
+
|
| 275 |
+
tool = load_tool("text-to-speech")
|
| 276 |
+
audio = tool("This is a text to speech tool")
|
| 277 |
+
```
|
| 278 |
+
|
| 279 |
+
### إنشاء أداة جديدة
|
| 280 |
+
|
| 281 |
+
يمكنك إنشاء أداتك الخاصة لتغطية حالات الاستخدام التي لا تغطيها الأدوات الافتراضية من Hugging Face.
|
| 282 |
+
على سبيل المثال، دعنا نقوم بإنشاء أداة تعرض النموذج الأكثر تنزيلًا لمهمة معينة من Hub.
|
| 283 |
+
|
| 284 |
+
سوف نبدأ بالكود التالي.
|
| 285 |
+
|
| 286 |
+
```python
|
| 287 |
+
from huggingface_hub import list_models
|
| 288 |
+
|
| 289 |
+
task = "text-classification"
|
| 290 |
+
|
| 291 |
+
model = next(iter(list_models(filter=task, sort="downloads", direction=-1)))
|
| 292 |
+
print(model.id)
|
| 293 |
+
```
|
| 294 |
+
|
| 295 |
+
يمكن تحويل هذه الشيفرة إلى فئة ترث من الفئة العليا [`Tool`].
|
| 296 |
+
|
| 297 |
+
تحتاج الأداة المخصصة إلى:
|
| 298 |
+
|
| 299 |
+
- اسم `name`، والتي تمثل اسم الأداة نفسها. عادةً ما يصف الاسم وظيفتها. بما أن الكود يعيد النموذج الأكثر تنزيلًا لمهمة ما، فلنسمها `model_download_counter`.
|
| 300 |
+
- تستخدم خاصية `description` لملء موجه نظام الوكيل.
|
| 301 |
+
- خاصية `inputs`، والتي هي عبارة عن قاموس بمفاتيح "type" و"description". يحتوي على معلومات تساعد المفسر Python على اتخاذ خيارات مستنيرة بشأن المدخلات.
|
| 302 |
+
- خاصية `output_type`، والتي تحدد نوع المخرج.
|
| 303 |
+
- طريقة `forward` والتي تحتوي على الكود الذي سيتم تنفيذه للحصول على النتيجة النهائية.
|
| 304 |
+
|
| 305 |
+
```python
|
| 306 |
+
from transformers import Tool
|
| 307 |
+
from huggingface_hub import list_models
|
| 308 |
+
|
| 309 |
+
class HFModelDownloadsTool(Tool):
|
| 310 |
+
name = "model_download_counter"
|
| 311 |
+
description = (
|
| 312 |
+
"This is a tool that returns the most downloaded model of a given task on the Hugging Face Hub. "
|
| 313 |
+
"It returns the name of the checkpoint."
|
| 314 |
+
)
|
| 315 |
+
|
| 316 |
+
inputs = {
|
| 317 |
+
"task": {
|
| 318 |
+
"type": "text",
|
| 319 |
+
"description": "the task category (such as text-classification, depth-estimation, etc)",
|
| 320 |
+
}
|
| 321 |
+
}
|
| 322 |
+
output_type = "text"
|
| 323 |
+
|
| 324 |
+
def forward(self, task: str):
|
| 325 |
+
model = next(iter(list_models(filter=task, sort="downloads", direction=-1)))
|
| 326 |
+
return model.id
|
| 327 |
+
```
|
| 328 |
+
|
| 329 |
+
الآن بعد أن أصبحت فئة `HfModelDownloadsTool` المخصصة جاهزة، يمكنك حفظها في ملف باسم `model_downloads.py` واستيرادها للاستخدام.
|
| 330 |
+
|
| 331 |
+
```python
|
| 332 |
+
from model_downloads import HFModelDownloadsTool
|
| 333 |
+
|
| 334 |
+
tool = HFModelDownloadsTool()
|
| 335 |
+
```
|
| 336 |
+
|
| 337 |
+
يمكنك أيضًا مشاركة أداتك المخصصة في Hub عن طريق استدعاء [`~Tool.push_to_hub`] على الأداة. تأكد من أنك قمت بإنشاء مستودع لها على Hub وأنك تستخدم رمز وصول للقراءة.
|
| 338 |
+
|
| 339 |
+
```python
|
| 340 |
+
tool.push_to_hub("{your_username}/hf-model-downloads")
|
| 341 |
+
```
|
| 342 |
+
|
| 343 |
+
قم بتحميل الأداة باستخدام دالة [`~Tool.load_tool`] ومررها إلى معلمة `tools` في الوكيل الخاص بك.
|
| 344 |
+
|
| 345 |
+
```python
|
| 346 |
+
from transformers import load_tool, CodeAgent
|
| 347 |
+
|
| 348 |
+
model_download_tool = load_tool("m-ric/hf-model-downloads")
|
| 349 |
+
agent = CodeAgent(tools=[model_download_tool], llm_engine=llm_engine)
|
| 350 |
+
agent.run(
|
| 351 |
+
"Can you give me the name of the model that has the most downloads in the 'text-to-video' task on the Hugging Face Hub?"
|
| 352 |
+
)
|
| 353 |
+
```
|
| 354 |
+
|
| 355 |
+
ستحصل على ما يلي:
|
| 356 |
+
|
| 357 |
+
```text
|
| 358 |
+
======== New task ========
|
| 359 |
+
Can you give me the name of the model that has the most downloads in the 'text-to-video' task on the Hugging Face Hub?
|
| 360 |
+
==== Agent is executing the code below:
|
| 361 |
+
most_downloaded_model = model_download_counter(task="text-to-video")
|
| 362 |
+
print(f"The most downloaded model for the 'text-to-video' task is {most_downloaded_model}.")
|
| 363 |
+
====
|
| 364 |
+
```
|
| 365 |
+
|
| 366 |
+
والناتج:
|
| 367 |
+
|
| 368 |
+
`"النموذج الأكثر تنزيلًا لمهمة `text-to-video` هو ByteDance/AnimateDiff-Lightning."`
|
| 369 |
+
|
| 370 |
+
### إدارة صندوق أدوات الوكيل الخاص بك
|
| 371 |
+
|
| 372 |
+
إذا كنت قد قمت بتهيئة وكيل، فمن غير الملائم إعادة تهيئته من البداية لإضافة أداة جديدة ترغب في استخدامها. باستخدام مكتبة Transformers، يمكنك إدارة صندوق أدوات الوكيل بإضافة أو استبدال أداة موجودة.
|
| 373 |
+
|
| 374 |
+
دعنا نضيف الأداة `model_download_tool` إلى وكيل تم تهيئته مسبقًا باستخدام صندوق الأدوات الافتراضي.
|
| 375 |
+
|
| 376 |
+
```python
|
| 377 |
+
from transformers import CodeAgent
|
| 378 |
+
|
| 379 |
+
agent = CodeAgent(tools=[], llm_engine=llm_engine, add_base_tools=True)
|
| 380 |
+
agent.toolbox.add_tool(model_download_tool)
|
| 381 |
+
```
|
| 382 |
+
|
| 383 |
+
الآن يمكننا الاستفادة من الأداة الجديدة وأداة تحويل النص إلى كلام السابقة:
|
| 384 |
+
|
| 385 |
+
```python
|
| 386 |
+
agent.run(
|
| 387 |
+
"Can you read out loud the name of the model that has the most downloads in the 'text-to-video' task on the Hugging Face Hub and return the audio?"
|
| 388 |
+
)
|
| 389 |
+
```
|
| 390 |
+
|
| 391 |
+
| **Audio** |
|
| 392 |
+
|------------------------------------------------------------------------------------------------------------------------------------------------------|
|
| 393 |
+
| <audio controls><source src="https://huggingface.co/datasets/huggingface/documentation-images/resolve/main/transformers/damo.wav" type="audio/wav"/> |
|
| 394 |
+
|
| 395 |
+
> [!WARNING]
|
| 396 |
+
> احترس عند إضافة أدوات إلى وكيل يعمل بالفعل لأنه يمكن أن يؤثر على اختيار الأداة لصالح أداتك أو اختيار أداة أخرى غير المحددة بالفعل.
|
| 397 |
+
|
| 398 |
+
استخدم طريقة `agent.toolbox.update_tool()` لاستبدال أداة موجودة في صندوق أدوات الوكيل.
|
| 399 |
+
هذا مفيد إذا كانت أداتك الجديدة بديلاً مباشرًا للأداة الموجودة لأن الوكيل يعرف بالفعل كيفية تنفيذ تلك المهمة المحددة.
|
| 400 |
+
تأكد فقط من اتباع الأداة الجديدة لنفس واجهة برمجة التطبيقات (API) للأداة المستبدلة أو قم بتكييف قالب موجه النظام لضمان تحديث جميع الأمثلة التي تستخدم الأداة المستبدلة.
|
| 401 |
+
|
| 402 |
+
### استخدام مجموعة من الأدوات
|
| 403 |
+
|
| 404 |
+
يمكنك الاستفادة من مجموعات الأدوات باستخدام كائن ToolCollection، مع تحديد مجموعة الأدوات التي تريد استخدامها.
|
| 405 |
+
ثم قم بتمريرها كقائمة لتهيئة الوكيل الخاص بك، وبدء استخدامها!
|
| 406 |
+
|
| 407 |
+
```py
|
| 408 |
+
from transformers import ToolCollection, ReactCodeAgent
|
| 409 |
+
|
| 410 |
+
image_tool_collection = ToolCollection(collection_slug="huggingface-tools/diffusion-tools-6630bb19a942c2306a2cdb6f")
|
| 411 |
+
agent = ReactCodeAgent(tools=[*image_tool_collection.tools], add_base_tools=True)
|
| 412 |
+
|
| 413 |
+
agent.run("Please draw me a picture of rivers and lakes.")
|
| 414 |
+
```
|
| 415 |
+
|
| 416 |
+
لتسريع البداية، يتم تحميل الأدوات فقط إذا استدعاها الوكيل.
|
| 417 |
+
|
| 418 |
+
ستحصل على هذه الصورة:
|
| 419 |
+
|
| 420 |
+
<img src="https://huggingface.co/datasets/huggingface/documentation-images/resolve/main/transformers/rivers_and_lakes.png" />
|
| 421 |
+
|
| 422 |
+
### استخدام gradio-tools
|
| 423 |
+
|
| 424 |
+
[gradio-tools](https://github.com/freddyaboulton/gradio-tools) هي مكتبة قوية تتيح استخدام Hugging
|
| 425 |
+
Face Spaces كأدوات. تدعم العديد من المساحات الموجودة بالإضافة إلى مساحات مخصصة.
|
| 426 |
+
|
| 427 |
+
تدعم مكتبة Transformers `gradio_tools` باستخدام طريقة [`Tool.from_gradio`] في الفئة. على سبيل المثال، دعنا نستخدم [`StableDiffusionPromptGeneratorTool`](https://github.com/freddyaboulton/gradio-tools/blob/main/gradio_tools/tools/prompt_generator.py) من مجموعة أدوات `gradio-tools` لتحسين المطالبات لإنشاء صور أفضل.
|
| 428 |
+
|
| 429 |
+
استورد وقم بتهيئة الأداة، ثم مررها إلى طريقة `Tool.from_gradio`:
|
| 430 |
+
|
| 431 |
+
```python
|
| 432 |
+
from gradio_tools import StableDiffusionPromptGeneratorTool
|
| 433 |
+
from transformers import Tool, load_tool, CodeAgent
|
| 434 |
+
|
| 435 |
+
gradio_prompt_generator_tool = StableDiffusionPromptGeneratorTool()
|
| 436 |
+
prompt_generator_tool = Tool.from_gradio(gradio_prompt_generator_tool)
|
| 437 |
+
```
|
| 438 |
+
|
| 439 |
+
الآن يمكنك استخدامه مثل أي أداة أخرى. على سبيل المثال، دعنا نحسن الموجه `a rabbit wearing a space suit`.
|
| 440 |
+
|
| 441 |
+
```python
|
| 442 |
+
image_generation_tool = load_tool('huggingface-tools/text-to-image')
|
| 443 |
+
agent = CodeAgent(tools=[prompt_generator_tool, image_generation_tool], llm_engine=llm_engine)
|
| 444 |
+
|
| 445 |
+
agent.run(
|
| 446 |
+
"Improve this prompt, then generate an image of it.", prompt='A rabbit wearing a space suit'
|
| 447 |
+
)
|
| 448 |
+
```
|
| 449 |
+
|
| 450 |
+
يستفيد النموذج بشكل كافٍ من الأداة:
|
| 451 |
+
|
| 452 |
+
```text
|
| 453 |
+
======== New task ========
|
| 454 |
+
Improve this prompt, then generate an image of it.
|
| 455 |
+
You have been provided with these initial arguments: {'prompt': 'A rabbit wearing a space suit'}.
|
| 456 |
+
==== Agent is executing the code below:
|
| 457 |
+
improved_prompt = StableDiffusionPromptGenerator(query=prompt)
|
| 458 |
+
while improved_prompt == "QUEUE_FULL":
|
| 459 |
+
improved_prompt = StableDiffusionPromptGenerator(query=prompt)
|
| 460 |
+
print(f"The improved prompt is {improved_prompt}.")
|
| 461 |
+
image = image_generator(prompt=improved_prompt)
|
| 462 |
+
====
|
| 463 |
+
```
|
| 464 |
+
|
| 465 |
+
قبل إنشاء الصورة أخيرًا:
|
| 466 |
+
|
| 467 |
+
<img src="https://huggingface.co/datasets/huggingface/documentation-images/resolve/main/transformers/rabbit_spacesuit_flux.webp" />
|
| 468 |
+
|
| 469 |
+
> [!WARNING]
|
| 470 |
+
> تتطلب gradio-tools إدخالات وإخراجات *نصية* حتى عند العمل مع طرائق مختلفة مثل كائنات الصور والصوت. الإدخالات والإخراجات الصورية والصوتية غير متوافقة حاليًا.
|
| 471 |
+
|
| 472 |
+
### استخدام أدوات LangChain
|
| 473 |
+
|
| 474 |
+
نحن نحب Langchain ونعتقد أنها تحتوي على مجموعة أدوات قوية للغاية.
|
| 475 |
+
لاستيراد أداة من LangChain، استخدم الطريقة `from_langchain()`.
|
| 476 |
+
|
| 477 |
+
فيما يلي كيفية استخدامها لإعادة إنشاء نتيجة البحث في المقدمة باستخدام أداة بحث الويب LangChain.
|
| 478 |
+
|
| 479 |
+
```python
|
| 480 |
+
from langchain.agents import load_tools
|
| 481 |
+
from transformers import Tool, ReactCodeAgent
|
| 482 |
+
|
| 483 |
+
search_tool = Tool.from_langchain(load_tools(["serpapi"])[0])
|
| 484 |
+
|
| 485 |
+
agent = ReactCodeAgent(tools=[search_tool])
|
| 486 |
+
|
| 487 |
+
agent.run("How many more blocks (also denoted as layers) in BERT base encoder than the encoder from the architecture proposed in Attention is All You Need?")
|
| 488 |
+
```
|
| 489 |
+
|
| 490 |
+
## واجهة Gradio
|
| 491 |
+
|
| 492 |
+
يمكنك الاستفادة من `gradio.Chatbot` لعرض أفكار الوكيل الخاص بك باستخدام `stream_to_gradio`، إليك مثال:
|
| 493 |
+
|
| 494 |
+
```py
|
| 495 |
+
import gradio as gr
|
| 496 |
+
from transformers import (
|
| 497 |
+
load_tool,
|
| 498 |
+
ReactCodeAgent,
|
| 499 |
+
HfEngine,
|
| 500 |
+
stream_to_gradio,
|
| 501 |
+
)
|
| 502 |
+
|
| 503 |
+
# Import tool from Hub
|
| 504 |
+
image_generation_tool = load_tool("m-ric/text-to-image")
|
| 505 |
+
|
| 506 |
+
llm_engine = HfEngine("meta-llama/Meta-Llama-3-70B-Instruct")
|
| 507 |
+
|
| 508 |
+
# Initialize the agent with the image generation tool
|
| 509 |
+
agent = ReactCodeAgent(tools=[image_generation_tool], llm_engine=llm_engine)
|
| 510 |
+
|
| 511 |
+
|
| 512 |
+
def interact_with_agent(task):
|
| 513 |
+
messages = []
|
| 514 |
+
messages.append(gr.ChatMessage(role="user", content=task))
|
| 515 |
+
yield messages
|
| 516 |
+
for msg in stream_to_gradio(agent, task):
|
| 517 |
+
messages.append(msg)
|
| 518 |
+
yield messages + [
|
| 519 |
+
gr.ChatMessage(role="assistant", content="⏳ Task not finished yet!")
|
| 520 |
+
]
|
| 521 |
+
yield messages
|
| 522 |
+
|
| 523 |
+
|
| 524 |
+
with gr.Blocks() as demo:
|
| 525 |
+
text_input = gr.Textbox(lines=1, label="Chat Message", value="Make me a picture of the Statue of Liberty.")
|
| 526 |
+
submit = gr.Button("Run illustrator agent!")
|
| 527 |
+
chatbot = gr.Chatbot(
|
| 528 |
+
label="Agent",
|
| 529 |
+
type="messages",
|
| 530 |
+
avatar_images=(
|
| 531 |
+
None,
|
| 532 |
+
"https://em-content.zobj.net/source/twitter/53/robot-face_1f916.png",
|
| 533 |
+
),
|
| 534 |
+
)
|
| 535 |
+
submit.click(interact_with_agent, [text_input], [chatbot])
|
| 536 |
+
|
| 537 |
+
if __name__ == "__main__":
|
| 538 |
+
demo.launch()
|
| 539 |
+
```
|
tasks/tasksmith-441eeab80047/environment/source/docs/source/ar/attention.md
ADDED
|
@@ -0,0 +1,25 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
# آليات الانتباه
|
| 2 |
+
|
| 3 |
+
تستخدم معظم نماذج المحول (Transformer) الانتباه الكامل بحيث تكون مصفوفة الانتباه ذات الأبعاد المتساوية. ويمكن أن يمثل ذلك عقبة حسابية كبيرة عندما تكون لديك نصوص طويلة. ويعد Longformer وReformer من النماذج التي تحاول أن تكون أكثر كفاءة وتستخدم نسخة مخففة من مصفوفة الانتباه لتسريع التدريب.
|
| 4 |
+
|
| 5 |
+
## انتباه LSH
|
| 6 |
+
|
| 7 |
+
يستخدم [Reformer](model_doc/reformer) انتباه LSH. في الدالة softmax(QK^t)، فإن أكبر العناصر فقط (في بعد softmax) من المصفوفة QK^t هي التي ستعطي مساهمات مفيدة. لذلك، بالنسبة لكل استعلام q في Q، يمكننا أن نأخذ في الاعتبار فقط المفاتيح k في K المشابهة لـ q فقط. وتُستخدم دالة هاش لتحديد ما إذا كان q وk متشابهين. ويتم تعديل قناع الانتباه لتجاهل الرمز الحالي (باستثناء الموضع الأول)، لأنه سيعطي استعلامًا ومفتاحًا متساويين (لذلك متشابهين للغاية). نظرًا لطبيعة دالة الهاش العشوائية نوعًا ما، يتم في الممارسة العملية استخدام عدة دوال هاش (يحددها معامل n_rounds) ثم يتم حساب المتوسط معًا.
|
| 8 |
+
|
| 9 |
+
## الانتباه المحلي
|
| 10 |
+
|
| 11 |
+
يستخدم [Longformer](model_doc/longformer) الانتباه المحلي: غالبًا ما يكون السياق المحلي (على سبيل المثال، ما هما الرمزان إلى اليسار واليمين؟) كافيًا لاتخاذ إجراء بالنسبة للرمز المعطى. أيضًا، عن طريق تكديس طبقات الانتباه التي لها نافذة صغيرة، سيكون للطبقة الأخيرة مجال استقبال أكبر من مجرد الرموز في النافذة، مما يسمح لها ببناء تمثيل للجملة بأكملها.
|
| 12 |
+
|
| 13 |
+
كما يتم منح بعض رموز الإدخال المختارة مسبقًا انتباهًا عالميًا: بالنسبة لهذه الرموز القليلة، يمكن لمصفوفة الانتباه الوصول إلى جميع الرموز وتكون هذه العملية متماثلة: فلجميع الرموز الأخرى إمكانية الوصول إلى تلك الرموز المحددة (بالإضافة إلى تلك الموجودة في نافذتهم المحلية). وهذا موضح في الشكل 2d من الورقة، انظر أدناه لمثال على قناع الانتباه:
|
| 14 |
+
|
| 15 |
+
<div class="flex justify-center">
|
| 16 |
+
<img scale="50 %" align="center" src="https://huggingface.co/datasets/huggingface/documentation-images/resolve/main/local_attention_mask.png"/>
|
| 17 |
+
</div>
|
| 18 |
+
|
| 19 |
+
وباستخدام مصفوفات الانتباه هذه التي تحتوي على عدد أقل من المعلمات، يسمح النموذج بمدخالات ذات طول تسلسل أكبر.
|
| 20 |
+
|
| 21 |
+
## حيل أخرى
|
| 22 |
+
|
| 23 |
+
### الترميزات الموضعية المحورية
|
| 24 |
+
|
| 25 |
+
يستخدم [Reformer](model_doc/reformer) ترميزات موضعية محورية: في نماذج المحول التقليدية، يكون الترميز الموضعي E مصفوفة بحجم \\(l\\) في \\(d\\)، حيث \\(l\\) هو طول التسلسل و\\(d\\) هو بعد الحالة المخفية. إذا كان لديك نصوص طويلة جدًا، فقد تكون هذه المصفوفة ضخمة وتستهلك مساحة كبيرة جدًا على وحدة معالجة الرسوميات (GPU). وللتخفيف من ذلك، تتكون الترميزات الموضعية المحورية من تحليل تلك المصفوفة الكبيرة E إلى مصفوفتين أصغر E1 وE2، بأبعاد \\(l_{1} \times d_{1}\\) و \\(l_{2} \times d_{2}\\)، بحيث \\(l_{1} \times l_{2} = l\\) و\\(d_{1} + d_{2} = d\\) (مع حاصل ضرب الأطوال، ينتهي الأمر بكونه أصغر بكثير). ويتم الحصول على الترميز للخطوة الزمنية \\(j\\) في E عن طريق ربط الترميزات للخطوة الزمنية \\(j \% l1\\) في E1 و \\(j // l1\\) في E2.
|
tasks/tasksmith-441eeab80047/environment/source/docs/source/ar/autoclass_tutorial.md
ADDED
|
@@ -0,0 +1,167 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
# تحميل نماذج مدربة مسبقًا باستخدام AutoClass
|
| 2 |
+
لم ترغب في إنشاء محول معماري لمؤشر الترابط الخاص بك، فهناك العديد من محولات المعمارية المختلفة التي يمكنك الاختيار من بينها. كجزء من الفلسفة الأساسية لـ 🤗 Transformers لجعل المكتبة سهلة وبسيطة ومرنة، فإن فئة `AutoClass` تستدل تلقائيًا وتحمّل البنية الصحيحة من نسخة نموذج (Model Checkpoint) معينة. تسمح لك طريقة `from_pretrained()` بتحميل نموذج مُدرب مسبقًا لأي بنية بسرعة حتى لا تضطر إلى تكريس الوقت والموارد لتدريب نموذج من الصفر. إن إنتاج هذا النوع من التعليمات البرمجية غير المعتمدة على نسخ يعني أنه إذا نجح رمزك مع ننسخة واحدة، فسيتم تشغيله مع أخرى - طالما تم تدريبه لمهمة مماثلة - حتى إذا كانت البنية المعمارية مختلفة.
|
| 3 |
+
|
| 4 |
+
تذكر أن البنية تشير إلى هيكل النموذج، والنسخ هي الأوزان لبنية معمارية معينة. على سبيل المثال، [BERT](https://huggingface.co/google-bert/bert-base-uncased) هي بنية معمارية، في حين أن `google-bert/bert-base-uncased` هي نسخة. "النموذج" هو مصطلح عام يمكن أن يعني إما البنية أو نالنسخة.
|
| 5 |
+
|
| 6 |
+
في هذا البرنامج التعليمي، ستتعلم كيفية:
|
| 7 |
+
|
| 8 |
+
* تحميل مُجزّئ الرموز مُدرب مسبقًا
|
| 9 |
+
* تحميل معالج صور مُدرب مسبقًا
|
| 10 |
+
* تحميل مستخرج ميزات مُدرب مسبقًا
|
| 11 |
+
* تحميل معالج مُدرب مسبقًا
|
| 12 |
+
* تحميل نموذج مُدرب مسبقًا
|
| 13 |
+
* تحميل نموذج كعمود فقري
|
| 14 |
+
|
| 15 |
+
## AutoTokenizer
|
| 16 |
+
|
| 17 |
+
تبدأ كل مهمة NLP تقريبًا بمُجزّئ للرموز. يقوم المُجزّئ بتحويل النص إلى شكل يمكن للنموذج معالجته.
|
| 18 |
+
|
| 19 |
+
قم بتحميل المُجزّئ باستخدام [`AutoTokenizer.from_pretrained`]:
|
| 20 |
+
|
| 21 |
+
```py
|
| 22 |
+
>>> from transformers import AutoTokenizer
|
| 23 |
+
|
| 24 |
+
>>> tokenizer = AutoTokenizer.from_pretrained("google-bert/bert-base-uncased")
|
| 25 |
+
```
|
| 26 |
+
|
| 27 |
+
ثم قم بتحليل إدخالك على النحو الموضح أدناه:
|
| 28 |
+
|
| 29 |
+
```py
|
| 30 |
+
>>> sequence = "In a hole in the ground there lived a hobbit."
|
| 31 |
+
>>> print(tokenizer(sequence))
|
| 32 |
+
{'input_ids': [101, 1999, 1037, 4920, 1999, 1996, 2598, 2045, 2973, 1037, 7570, 10322, 4183, 1012, 102],
|
| 33 |
+
'token_type_ids': [0, 0, 0, 0, 0, 0, 0, 0, 0, 0, 0, 0, 0, 0, 0],
|
| 34 |
+
'attention_mask': [1, 1, 1, 1, 1, 1, 1, 1, 1, 1, 1, 1, 1, 1, 1]}
|
| 35 |
+
```
|
| 36 |
+
|
| 37 |
+
## معالج الصور التلقائي (AutoImageProcessor)
|
| 38 |
+
|
| 39 |
+
|
| 40 |
+
بالنسبة لمهمات الرؤية، يقوم معالج الصور بمعالجة الصورة إلى تنسيق الإدخال الصحيح.
|
| 41 |
+
|
| 42 |
+
```py
|
| 43 |
+
>>> from transformers import AutoImageProcessor
|
| 44 |
+
|
| 45 |
+
>>> image_processor = AutoImageProcessor.from_pretrained("google/vit-base-patch16-224")
|
| 46 |
+
```
|
| 47 |
+
|
| 48 |
+
## AutoBackbone
|
| 49 |
+
|
| 50 |
+
<div style="text-align: center">
|
| 51 |
+
<img src="https://huggingface.co/datasets/huggingface/documentation-images/resolve/main/transformers/Swin%20Stages.png">
|
| 52 |
+
<figcaption class="mt-2 text-center text-sm text-gray-500">الصورة توضح مخطط مراحل نموذج Swin.</figcaption>
|
| 53 |
+
</div>
|
| 54 |
+
|
| 55 |
+
يسمح لك [`AutoBackbone`] باستخدام النماذج المُدربة مسبقًا كعمود فقري للحصول على خرائط ميزات من مراحل مختلفة من العمود الفقري. يجب عليك تحديد أحد المعلمات التالية في [`~PretrainedConfig.from_pretrained`]:
|
| 56 |
+
|
| 57 |
+
* `out_indices` هو فهرس الطبقة التي تريد الحصول على خريطة الميزات منها
|
| 58 |
+
* `out_features` هو اسم الطبقة التي تريد الحصول على خريطة الميزات منها
|
| 59 |
+
|
| 60 |
+
يمكن استخدام هذه المعلمات بشكل متبادل، ولكن إذا كنت تستخدم كلاً منها، فتأكد من أنها متوائمة مع بعضها البعض! إذا لم تمرر أيًا من هذه المعلمات، فسيقوم العمود الفقري بإرجاع خريطة الميزات من الطبقة الأخيرة.
|
| 61 |
+
<div style="text-align: center">
|
| 62 |
+
<img src="https://huggingface.co/datasets/huggingface/documentation-images/resolve/main/transformers/Swin%20Stage%201.png">
|
| 63 |
+
<figcaption class="mt-2 text-center text-sm text-gray-500">صورة توضح خريطة ميزات من المرحلة الأولى للعمود الفقري.</figcaption>
|
| 64 |
+
</div>
|
| 65 |
+
|
| 66 |
+
على سبيل المثال، في الرسم التخطيطي أعلاه، لإرجاع خريطة الميزات من المرحلة الأولى من العمود الفقري Swin، يمكنك تعيين `out_indices=(1,)`:
|
| 67 |
+
|
| 68 |
+
```py
|
| 69 |
+
>>> from transformers import AutoImageProcessor, AutoBackbone
|
| 70 |
+
>>> import torch
|
| 71 |
+
>>> from PIL import Image
|
| 72 |
+
>>> import requests
|
| 73 |
+
>>> url = "http://images.cocodataset.org/val2017/000000039769.jpg"
|
| 74 |
+
>>> image = Image.open(requests.get(url, stream=True).raw)
|
| 75 |
+
>>> processor = AutoImageProcessor.from_pretrained("microsoft/swin-tiny-patch4-window7-224")
|
| 76 |
+
>>> model = AutoBackbone.from_pretrained("microsoft/swin-tiny-patch4-window7-224", out_indices=(1,))
|
| 77 |
+
|
| 78 |
+
>>> inputs = processor(image, return_tensors="pt")
|
| 79 |
+
>>> outputs = model(**inputs)
|
| 80 |
+
>>> feature_maps = outputs.feature_maps
|
| 81 |
+
```
|
| 82 |
+
|
| 83 |
+
الآن يمكنك الوصول إلى كائن `feature_maps` من المرحلة الأولى من العمود الفقري:
|
| 84 |
+
|
| 85 |
+
```py
|
| 86 |
+
>>> list(feature_maps[0].shape)
|
| 87 |
+
[1, 96, 56, 56]
|
| 88 |
+
```
|
| 89 |
+
|
| 90 |
+
## مستخرج الميزات التلقائي (AutoFeatureExtractor)
|
| 91 |
+
|
| 92 |
+
بالنسبة للمهام الصوتية، يقوم مستخرج الميزات بمعالجة إشارة الصوت إلى تنسيق الإدخال الصحيح.
|
| 93 |
+
|
| 94 |
+
قم بتحميل مستخرج ميزات باستخدام [`AutoFeatureExtractor.from_pretrained`]:
|
| 95 |
+
|
| 96 |
+
```py
|
| 97 |
+
>>> from transformers import AutoFeatureExtractor
|
| 98 |
+
|
| 99 |
+
>>> feature_extractor = AutoFeatureExtractor.from_pretrained(
|
| 100 |
+
... "ehcalabres/wav2vec2-lg-xlsr-en-speech-emotion-recognition"
|
| 101 |
+
... )
|
| 102 |
+
```
|
| 103 |
+
|
| 104 |
+
## المعالج التلقائي (AutoProcessor)
|
| 105 |
+
|
| 106 |
+
تتطلب المهام متعددة الوسائط معالجًا يجمع بين نوعين من أدوات المعالجة المسبقة. على سبيل المثال، يتطلب نموذج [LayoutLMV2](model_doc/layoutlmv2) معالج صور لمعالجة الصور ومُجزّئ لمعالجة النص؛ يجمع المعالج كليهما.
|
| 107 |
+
|
| 108 |
+
قم بتحميل معالج باستخدام [`AutoProcessor.from_pretrained`]:
|
| 109 |
+
|
| 110 |
+
```py
|
| 111 |
+
>>> from transformers import AutoProcessor
|
| 112 |
+
|
| 113 |
+
>>> processor = AutoProcessor.from_pretrained("microsoft/layoutlmv2-base-uncased")
|
| 114 |
+
```
|
| 115 |
+
|
| 116 |
+
## النموذج التلقائي (AutoModel)
|
| 117 |
+
|
| 118 |
+
<frameworkcontent>
|
| 119 |
+
<pt>
|
| 120 |
+
تسمح لك فئات `AutoModelFor` بتحميل نموذج مُدرب مسبقًا لمهمة معينة (راجع [هنا](model_doc/auto) للحصول على قائمة كاملة بالمهام المتاحة). على سبيل المثال، قم بتحميل نموذج لتصنيف التسلسل باستخدام [`AutoModelForSequenceClassification.from_pretrained`]:
|
| 121 |
+
|
| 122 |
+
```py
|
| 123 |
+
>>> from transformers import AutoModelForSequenceClassification
|
| 124 |
+
|
| 125 |
+
>>> model = AutoModelForSequenceClassification.from_pretrained("distilbert/distilbert-base-uncased")
|
| 126 |
+
```
|
| 127 |
+
|
| 128 |
+
أعد استخدام نفس نقطة التفتيش لتحميل بنية لمهمة مختلفة:
|
| 129 |
+
|
| 130 |
+
```py
|
| 131 |
+
>>> from transformers import AutoModelForTokenClassification
|
| 132 |
+
|
| 133 |
+
>>> model = AutoModelForTokenClassification.from_pretrained("distilbert/distilbert-base-uncased")
|
| 134 |
+
```
|
| 135 |
+
|
| 136 |
+
<Tip warning={true}>
|
| 137 |
+
|
| 138 |
+
بالنسبة لنماذج PyTorch، تستخدم طريقة `from_pretrained()` `torch.load()` التي تستخدم داخليًا `pickle` والتي يُعرف أنها غير آمنة. بشكل عام، لا تقم مطلقًا بتحميل نموذج قد يكون مصدره مصدرًا غير موثوق به، أو قد يكون تم العبث به. يتم تخفيف هذا الخطر الأمني جزئيًا للنماذج العامة المستضافة على Hub Hugging Face، والتي يتم [فحصها بحثًا عن البرامج الضارة](https://huggingface.co/docs/hub/security-malware) في كل ارتكاب. راجع [توثيق Hub](https://huggingface.co/docs/hub/security) للحصول على أفضل الممارسات مثل [التحقق من التوقيع](https://huggingface.co/docs/hub/security-gpg#signing-commits-with-gpg) باستخدام GPG.
|
| 139 |
+
|
| 140 |
+
لا تتأثر نقاط تفتيش TensorFlow و Flax، ويمكن تحميلها داخل بنيات PyTorch باستخدام `from_tf` و `from_flax` kwargs لطريقة `from_pretrained` للتحايل على هذه المشكلة.
|
| 141 |
+
|
| 142 |
+
</Tip>
|
| 143 |
+
|
| 144 |
+
|
| 145 |
+
بشكل عام، نوصي باستخدام فئة `AutoTokenizer` وفئة `AutoModelFor` لتحميل مثيلات مُدربة مسبقًا من النماذج. سيساعدك هذا في تحميل البنية الصحيحة في كل مرة. في البرنامج التعليمي التالي، تعرف على كيفية استخدام المحلل اللغوي ومعالج الصور ومستخرج الميزات والمعالج الذي تم تحميله حديثًا لمعالجة مجموعة بيانات للضبط الدقيق.
|
| 146 |
+
</pt>
|
| 147 |
+
|
| 148 |
+
<tf>
|
| 149 |
+
أخيرًا، تسمح لك فئات `TFAutoModelFor` بتحميل نموذج مُدرب مسبقًا لمهمة معينة (راجع [هنا](model_doc/auto) للحصول على قائمة كاملة بالمهام المتاحة). على سبيل المثال، قم بتحميل نموذج لتصنيف التسلسل باستخدام [`TFAutoModelForSequenceClassification.from_pretrained`]:
|
| 150 |
+
|
| 151 |
+
```py
|
| 152 |
+
>>> from transformers import TFAutoModelForSequenceClassification
|
| 153 |
+
|
| 154 |
+
>>> model = TFAutoModelForSequenceClassification.from_pretrained("distilbert/distilbert-base-uncased")
|
| 155 |
+
```
|
| 156 |
+
|
| 157 |
+
أعد استخدام نفس نقطة التفتيش لتحميل بنية لمهمة مختلفة:
|
| 158 |
+
|
| 159 |
+
```py
|
| 160 |
+
>>> from transformers import TFAutoModelForTokenClassification
|
| 161 |
+
|
| 162 |
+
>>> model = TFAutoModelForTokenClassification.from_pretrained("distilbert/distilbert-base-uncased")
|
| 163 |
+
```
|
| 164 |
+
|
| 165 |
+
بشكل عام، نوصي باستخدام فئة `AutoTokenizer` وفئة `TFAutoModelFor` لتحميل نسخ لنماذج مُدربة مسبقًا. سيساعدك هذا في تحميل البنية الصحيحة في كل مرة. في البرنامج التعليمي التالي، ستتعرف على كيفية استخدام المُجزّئ اللغوي ومعالج الصور ومستخرج الميزات والمعالج الذي تم تحميله حديثًا لمعالجة مجموعة بيانات للضبط الدقيق.
|
| 166 |
+
</tf>
|
| 167 |
+
</frameworkcontent>
|