


Stage Harbor release files 7501-8000
Browse filesThis view is limited to 50 files because it contains too many changes. See raw diff
- tasks/tasksmith-1c5704b1f07f/tests/source/docs/source/en/api/pipelines/paint_by_example.md +39 -0
- tasks/tasksmith-1c5704b1f07f/tests/source/docs/source/en/api/pipelines/panorama.md +54 -0
- tasks/tasksmith-1c5704b1f07f/tests/source/docs/source/en/api/pipelines/pia.md +168 -0
- tasks/tasksmith-1c5704b1f07f/tests/source/docs/source/en/api/pipelines/pix2pix.md +41 -0
- tasks/tasksmith-1c5704b1f07f/tests/source/docs/source/en/api/pipelines/pixart.md +139 -0
- tasks/tasksmith-1c5704b1f07f/tests/source/docs/source/en/api/pipelines/pixart_sigma.md +143 -0
- tasks/tasksmith-1c5704b1f07f/tests/source/docs/source/en/api/pipelines/prx.md +131 -0
- tasks/tasksmith-1c5704b1f07f/tests/source/docs/source/en/api/pipelines/qwenimage.md +161 -0
- tasks/tasksmith-1c5704b1f07f/tests/source/docs/source/en/api/pipelines/sana.md +106 -0
- tasks/tasksmith-1c5704b1f07f/tests/source/docs/source/en/api/pipelines/sana_sprint.md +128 -0
- tasks/tasksmith-1c5704b1f07f/tests/source/docs/source/en/api/pipelines/sana_video.md +189 -0
- tasks/tasksmith-1c5704b1f07f/tests/source/docs/source/en/api/pipelines/self_attention_guidance.md +35 -0
- tasks/tasksmith-1c5704b1f07f/tests/source/docs/source/en/api/pipelines/semantic_stable_diffusion.md +35 -0
- tasks/tasksmith-1c5704b1f07f/tests/source/docs/source/en/api/pipelines/shap_e.md +34 -0
- tasks/tasksmith-1c5704b1f07f/tests/source/docs/source/en/api/pipelines/skyreels_v2.md +346 -0
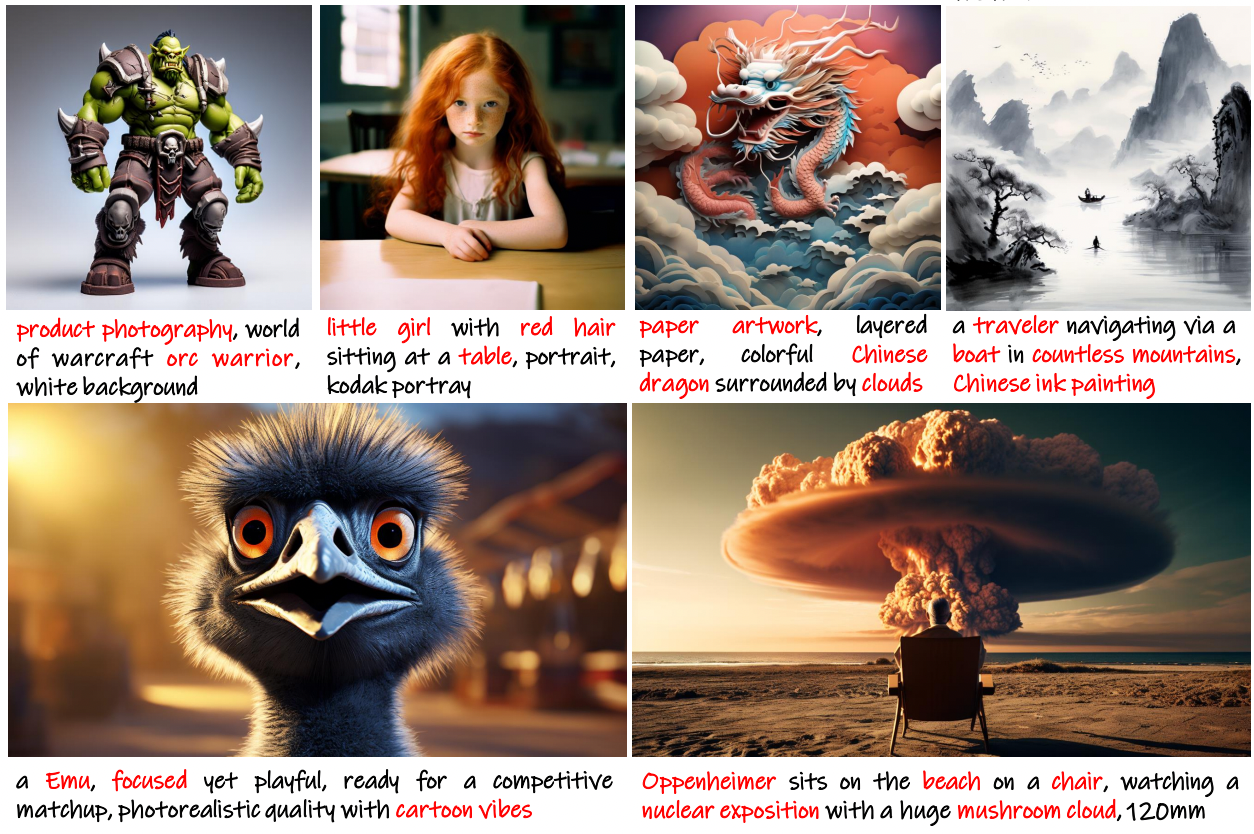
- tasks/tasksmith-1c5704b1f07f/tests/source/docs/source/en/api/pipelines/stable_audio.md +93 -0
- tasks/tasksmith-1c5704b1f07f/tests/source/docs/source/en/api/pipelines/stable_cascade.md +226 -0
- tasks/tasksmith-1c5704b1f07f/tests/source/docs/source/en/api/pipelines/stable_diffusion/adapter.md +47 -0
- tasks/tasksmith-1c5704b1f07f/tests/source/docs/source/en/api/pipelines/stable_diffusion/depth2img.md +41 -0
- tasks/tasksmith-1c5704b1f07f/tests/source/docs/source/en/api/pipelines/stable_diffusion/gligen.md +59 -0
- tasks/tasksmith-1c5704b1f07f/tests/source/docs/source/en/api/pipelines/stable_diffusion/image_variation.md +34 -0
- tasks/tasksmith-1c5704b1f07f/tests/source/docs/source/en/api/pipelines/stable_diffusion/img2img.md +46 -0
- tasks/tasksmith-1c5704b1f07f/tests/source/docs/source/en/api/pipelines/stable_diffusion/inpaint.md +48 -0
- tasks/tasksmith-1c5704b1f07f/tests/source/docs/source/en/api/pipelines/stable_diffusion/k_diffusion.md +30 -0
- tasks/tasksmith-1c5704b1f07f/tests/source/docs/source/en/api/pipelines/stable_diffusion/latent_upscale.md +35 -0
- tasks/tasksmith-1c5704b1f07f/tests/source/docs/source/en/api/pipelines/stable_diffusion/ldm3d_diffusion.md +59 -0
- tasks/tasksmith-1c5704b1f07f/tests/source/docs/source/en/api/pipelines/stable_diffusion/overview.md +216 -0
- tasks/tasksmith-1c5704b1f07f/tests/source/docs/source/en/api/pipelines/stable_diffusion/sdxl_turbo.md +32 -0
- tasks/tasksmith-1c5704b1f07f/tests/source/docs/source/en/api/pipelines/stable_diffusion/stable_diffusion_2.md +122 -0
- tasks/tasksmith-1c5704b1f07f/tests/source/docs/source/en/api/pipelines/stable_diffusion/stable_diffusion_3.md +443 -0
- tasks/tasksmith-1c5704b1f07f/tests/source/docs/source/en/api/pipelines/stable_diffusion/stable_diffusion_safe.md +61 -0
- tasks/tasksmith-1c5704b1f07f/tests/source/docs/source/en/api/pipelines/stable_diffusion/stable_diffusion_xl.md +57 -0
- tasks/tasksmith-1c5704b1f07f/tests/source/docs/source/en/api/pipelines/stable_diffusion/svd.md +40 -0
- tasks/tasksmith-1c5704b1f07f/tests/source/docs/source/en/api/pipelines/stable_diffusion/text2img.md +50 -0
- tasks/tasksmith-1c5704b1f07f/tests/source/docs/source/en/api/pipelines/stable_diffusion/upscale.md +38 -0
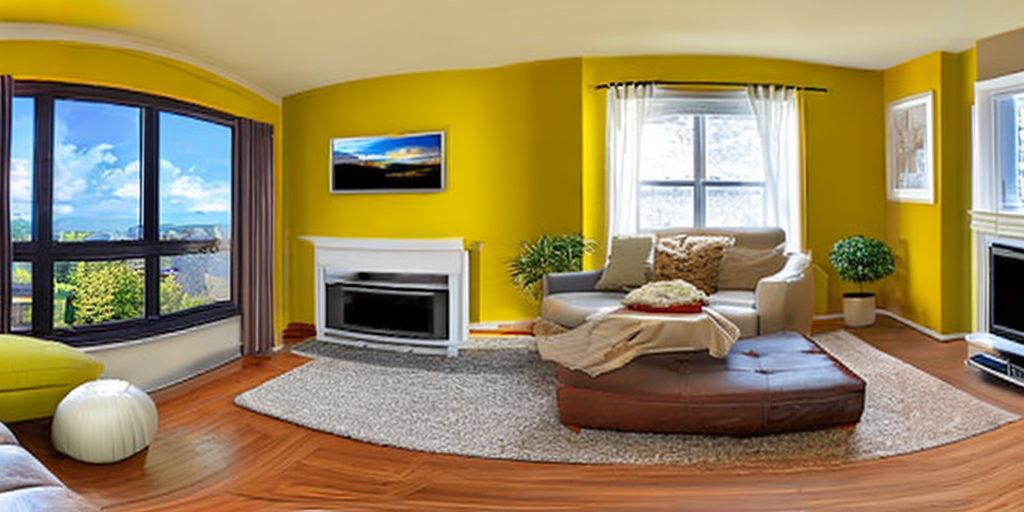
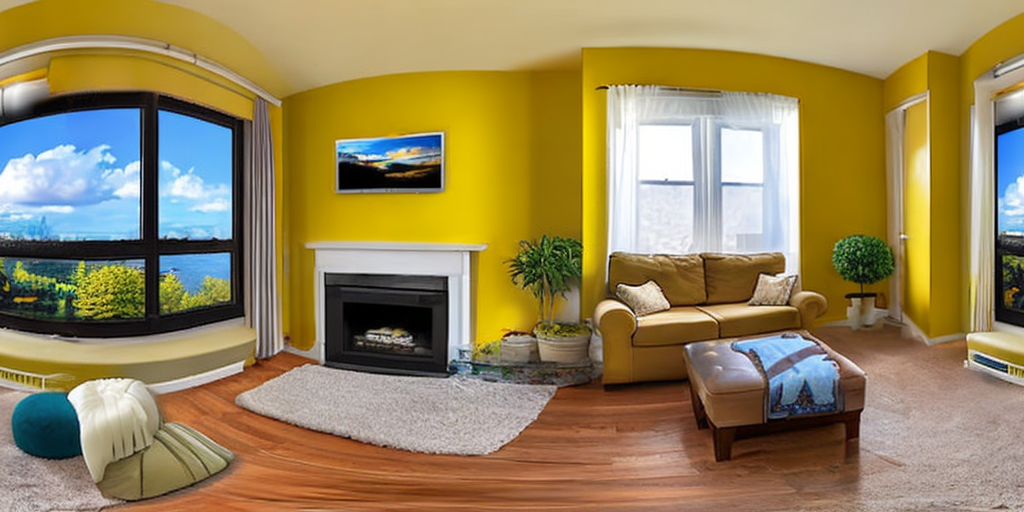
- tasks/tasksmith-1c5704b1f07f/tests/source/docs/source/en/api/pipelines/stable_unclip.md +127 -0
- tasks/tasksmith-1c5704b1f07f/tests/source/docs/source/en/api/pipelines/text_to_video.md +191 -0
- tasks/tasksmith-1c5704b1f07f/tests/source/docs/source/en/api/pipelines/text_to_video_zero.md +306 -0
- tasks/tasksmith-1c5704b1f07f/tests/source/docs/source/en/api/pipelines/unclip.md +37 -0
- tasks/tasksmith-1c5704b1f07f/tests/source/docs/source/en/api/pipelines/unidiffuser.md +206 -0
- tasks/tasksmith-1c5704b1f07f/tests/source/docs/source/en/api/pipelines/value_guided_sampling.md +32 -0
- tasks/tasksmith-1c5704b1f07f/tests/source/docs/source/en/api/pipelines/visualcloze.md +300 -0
- tasks/tasksmith-1c5704b1f07f/tests/source/docs/source/en/api/pipelines/wan.md +573 -0
- tasks/tasksmith-1c5704b1f07f/tests/source/docs/source/en/api/pipelines/wuerstchen.md +170 -0
- tasks/tasksmith-1c5704b1f07f/tests/source/docs/source/en/api/quantization.md +43 -0
- tasks/tasksmith-1c5704b1f07f/tests/source/docs/source/en/api/schedulers/cm_stochastic_iterative.md +27 -0
- tasks/tasksmith-1c5704b1f07f/tests/source/docs/source/en/api/schedulers/consistency_decoder.md +21 -0
- tasks/tasksmith-1c5704b1f07f/tests/source/docs/source/en/api/schedulers/cosine_dpm.md +24 -0
- tasks/tasksmith-1c5704b1f07f/tests/source/docs/source/en/api/schedulers/ddim.md +79 -0
- tasks/tasksmith-1c5704b1f07f/tests/source/docs/source/en/api/schedulers/ddim_cogvideox.md +19 -0
tasks/tasksmith-1c5704b1f07f/tests/source/docs/source/en/api/pipelines/paint_by_example.md
ADDED
|
@@ -0,0 +1,39 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
<!--Copyright 2025 The HuggingFace Team. All rights reserved.
|
| 2 |
+
|
| 3 |
+
Licensed under the Apache License, Version 2.0 (the "License"); you may not use this file except in compliance with
|
| 4 |
+
the License. You may obtain a copy of the License at
|
| 5 |
+
|
| 6 |
+
http://www.apache.org/licenses/LICENSE-2.0
|
| 7 |
+
|
| 8 |
+
Unless required by applicable law or agreed to in writing, software distributed under the License is distributed on
|
| 9 |
+
an "AS IS" BASIS, WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied. See the License for the
|
| 10 |
+
specific language governing permissions and limitations under the License.
|
| 11 |
+
-->
|
| 12 |
+
|
| 13 |
+
> [!WARNING]
|
| 14 |
+
> This pipeline is deprecated but it can still be used. However, we won't test the pipeline anymore and won't accept any changes to it. If you run into any issues, reinstall the last Diffusers version that supported this model.
|
| 15 |
+
|
| 16 |
+
# Paint by Example
|
| 17 |
+
|
| 18 |
+
[Paint by Example: Exemplar-based Image Editing with Diffusion Models](https://huggingface.co/papers/2211.13227) is by Binxin Yang, Shuyang Gu, Bo Zhang, Ting Zhang, Xuejin Chen, Xiaoyan Sun, Dong Chen, Fang Wen.
|
| 19 |
+
|
| 20 |
+
The abstract from the paper is:
|
| 21 |
+
|
| 22 |
+
*Language-guided image editing has achieved great success recently. In this paper, for the first time, we investigate exemplar-guided image editing for more precise control. We achieve this goal by leveraging self-supervised training to disentangle and re-organize the source image and the exemplar. However, the naive approach will cause obvious fusing artifacts. We carefully analyze it and propose an information bottleneck and strong augmentations to avoid the trivial solution of directly copying and pasting the exemplar image. Meanwhile, to ensure the controllability of the editing process, we design an arbitrary shape mask for the exemplar image and leverage the classifier-free guidance to increase the similarity to the exemplar image. The whole framework involves a single forward of the diffusion model without any iterative optimization. We demonstrate that our method achieves an impressive performance and enables controllable editing on in-the-wild images with high fidelity.*
|
| 23 |
+
|
| 24 |
+
The original codebase can be found at [Fantasy-Studio/Paint-by-Example](https://github.com/Fantasy-Studio/Paint-by-Example), and you can try it out in a [demo](https://huggingface.co/spaces/Fantasy-Studio/Paint-by-Example).
|
| 25 |
+
|
| 26 |
+
## Tips
|
| 27 |
+
|
| 28 |
+
Paint by Example is supported by the official [Fantasy-Studio/Paint-by-Example](https://huggingface.co/Fantasy-Studio/Paint-by-Example) checkpoint. The checkpoint is warm-started from [CompVis/stable-diffusion-v1-4](https://huggingface.co/CompVis/stable-diffusion-v1-4) to inpaint partly masked images conditioned on example and reference images.
|
| 29 |
+
|
| 30 |
+
> [!TIP]
|
| 31 |
+
> Make sure to check out the Schedulers [guide](../../using-diffusers/schedulers) to learn how to explore the tradeoff between scheduler speed and quality, and see the [reuse components across pipelines](../../using-diffusers/loading#reuse-a-pipeline) section to learn how to efficiently load the same components into multiple pipelines.
|
| 32 |
+
|
| 33 |
+
## PaintByExamplePipeline
|
| 34 |
+
[[autodoc]] PaintByExamplePipeline
|
| 35 |
+
- all
|
| 36 |
+
- __call__
|
| 37 |
+
|
| 38 |
+
## StableDiffusionPipelineOutput
|
| 39 |
+
[[autodoc]] pipelines.stable_diffusion.StableDiffusionPipelineOutput
|
tasks/tasksmith-1c5704b1f07f/tests/source/docs/source/en/api/pipelines/panorama.md
ADDED
|
@@ -0,0 +1,54 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
<!--Copyright 2025 The HuggingFace Team. All rights reserved.
|
| 2 |
+
|
| 3 |
+
Licensed under the Apache License, Version 2.0 (the "License"); you may not use this file except in compliance with
|
| 4 |
+
the License. You may obtain a copy of the License at
|
| 5 |
+
|
| 6 |
+
http://www.apache.org/licenses/LICENSE-2.0
|
| 7 |
+
|
| 8 |
+
Unless required by applicable law or agreed to in writing, software distributed under the License is distributed on
|
| 9 |
+
an "AS IS" BASIS, WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied. See the License for the
|
| 10 |
+
specific language governing permissions and limitations under the License.
|
| 11 |
+
-->
|
| 12 |
+
|
| 13 |
+
> [!WARNING]
|
| 14 |
+
> This pipeline is deprecated but it can still be used. However, we won't test the pipeline anymore and won't accept any changes to it. If you run into any issues, reinstall the last Diffusers version that supported this model.
|
| 15 |
+
|
| 16 |
+
# MultiDiffusion
|
| 17 |
+
|
| 18 |
+
<div class="flex flex-wrap space-x-1">
|
| 19 |
+
<img alt="LoRA" src="https://img.shields.io/badge/LoRA-d8b4fe?style=flat"/>
|
| 20 |
+
</div>
|
| 21 |
+
|
| 22 |
+
[MultiDiffusion: Fusing Diffusion Paths for Controlled Image Generation](https://huggingface.co/papers/2302.08113) is by Omer Bar-Tal, Lior Yariv, Yaron Lipman, and Tali Dekel.
|
| 23 |
+
|
| 24 |
+
The abstract from the paper is:
|
| 25 |
+
|
| 26 |
+
*Recent advances in text-to-image generation with diffusion models present transformative capabilities in image quality. However, user controllability of the generated image, and fast adaptation to new tasks still remains an open challenge, currently mostly addressed by costly and long re-training and fine-tuning or ad-hoc adaptations to specific image generation tasks. In this work, we present MultiDiffusion, a unified framework that enables versatile and controllable image generation, using a pre-trained text-to-image diffusion model, without any further training or finetuning. At the center of our approach is a new generation process, based on an optimization task that binds together multiple diffusion generation processes with a shared set of parameters or constraints. We show that MultiDiffusion can be readily applied to generate high quality and diverse images that adhere to user-provided controls, such as desired aspect ratio (e.g., panorama), and spatial guiding signals, ranging from tight segmentation masks to bounding boxes.*
|
| 27 |
+
|
| 28 |
+
You can find additional information about MultiDiffusion on the [project page](https://multidiffusion.github.io/), [original codebase](https://github.com/omerbt/MultiDiffusion), and try it out in a [demo](https://huggingface.co/spaces/weizmannscience/MultiDiffusion).
|
| 29 |
+
|
| 30 |
+
## Tips
|
| 31 |
+
|
| 32 |
+
While calling [`StableDiffusionPanoramaPipeline`], it's possible to specify the `view_batch_size` parameter to be > 1.
|
| 33 |
+
For some GPUs with high performance, this can speedup the generation process and increase VRAM usage.
|
| 34 |
+
|
| 35 |
+
To generate panorama-like images make sure you pass the width parameter accordingly. We recommend a width value of 2048 which is the default.
|
| 36 |
+
|
| 37 |
+
Circular padding is applied to ensure there are no stitching artifacts when working with panoramas to ensure a seamless transition from the rightmost part to the leftmost part. By enabling circular padding (set `circular_padding=True`), the operation applies additional crops after the rightmost point of the image, allowing the model to "see” the transition from the rightmost part to the leftmost part. This helps maintain visual consistency in a 360-degree sense and creates a proper “panorama” that can be viewed using 360-degree panorama viewers. When decoding latents in Stable Diffusion, circular padding is applied to ensure that the decoded latents match in the RGB space.
|
| 38 |
+
|
| 39 |
+
For example, without circular padding, there is a stitching artifact (default):
|
| 40 |
+
|
| 41 |
+
|
| 42 |
+
But with circular padding, the right and the left parts are matching (`circular_padding=True`):
|
| 43 |
+
|
| 44 |
+
|
| 45 |
+
> [!TIP]
|
| 46 |
+
> Make sure to check out the Schedulers [guide](../../using-diffusers/schedulers) to learn how to explore the tradeoff between scheduler speed and quality, and see the [reuse components across pipelines](../../using-diffusers/loading#reuse-a-pipeline) section to learn how to efficiently load the same components into multiple pipelines.
|
| 47 |
+
|
| 48 |
+
## StableDiffusionPanoramaPipeline
|
| 49 |
+
[[autodoc]] StableDiffusionPanoramaPipeline
|
| 50 |
+
- __call__
|
| 51 |
+
- all
|
| 52 |
+
|
| 53 |
+
## StableDiffusionPipelineOutput
|
| 54 |
+
[[autodoc]] pipelines.stable_diffusion.StableDiffusionPipelineOutput
|
tasks/tasksmith-1c5704b1f07f/tests/source/docs/source/en/api/pipelines/pia.md
ADDED
|
@@ -0,0 +1,168 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
<!--Copyright 2025 The HuggingFace Team. All rights reserved.
|
| 2 |
+
|
| 3 |
+
Licensed under the Apache License, Version 2.0 (the "License"); you may not use this file except in compliance with
|
| 4 |
+
the License. You may obtain a copy of the License at
|
| 5 |
+
|
| 6 |
+
http://www.apache.org/licenses/LICENSE-2.0
|
| 7 |
+
|
| 8 |
+
Unless required by applicable law or agreed to in writing, software distributed under the License is distributed on
|
| 9 |
+
an "AS IS" BASIS, WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied. See the License for the
|
| 10 |
+
specific language governing permissions and limitations under the License.
|
| 11 |
+
-->
|
| 12 |
+
|
| 13 |
+
> [!WARNING]
|
| 14 |
+
> This pipeline is deprecated but it can still be used. However, we won't test the pipeline anymore and won't accept any changes to it. If you run into any issues, reinstall the last Diffusers version that supported this model.
|
| 15 |
+
|
| 16 |
+
# Image-to-Video Generation with PIA (Personalized Image Animator)
|
| 17 |
+
|
| 18 |
+
<div class="flex flex-wrap space-x-1">
|
| 19 |
+
<img alt="LoRA" src="https://img.shields.io/badge/LoRA-d8b4fe?style=flat"/>
|
| 20 |
+
</div>
|
| 21 |
+
|
| 22 |
+
## Overview
|
| 23 |
+
|
| 24 |
+
[PIA: Your Personalized Image Animator via Plug-and-Play Modules in Text-to-Image Models](https://huggingface.co/papers/2312.13964) by Yiming Zhang, Zhening Xing, Yanhong Zeng, Youqing Fang, Kai Chen
|
| 25 |
+
|
| 26 |
+
Recent advancements in personalized text-to-image (T2I) models have revolutionized content creation, empowering non-experts to generate stunning images with unique styles. While promising, adding realistic motions into these personalized images by text poses significant challenges in preserving distinct styles, high-fidelity details, and achieving motion controllability by text. In this paper, we present PIA, a Personalized Image Animator that excels in aligning with condition images, achieving motion controllability by text, and the compatibility with various personalized T2I models without specific tuning. To achieve these goals, PIA builds upon a base T2I model with well-trained temporal alignment layers, allowing for the seamless transformation of any personalized T2I model into an image animation model. A key component of PIA is the introduction of the condition module, which utilizes the condition frame and inter-frame affinity as input to transfer appearance information guided by the affinity hint for individual frame synthesis in the latent space. This design mitigates the challenges of appearance-related image alignment within and allows for a stronger focus on aligning with motion-related guidance.
|
| 27 |
+
|
| 28 |
+
[Project page](https://pi-animator.github.io/)
|
| 29 |
+
|
| 30 |
+
## Available Pipelines
|
| 31 |
+
|
| 32 |
+
| Pipeline | Tasks | Demo
|
| 33 |
+
|---|---|:---:|
|
| 34 |
+
| [PIAPipeline](https://github.com/huggingface/diffusers/blob/main/src/diffusers/pipelines/pia/pipeline_pia.py) | *Image-to-Video Generation with PIA* |
|
| 35 |
+
|
| 36 |
+
## Available checkpoints
|
| 37 |
+
|
| 38 |
+
Motion Adapter checkpoints for PIA can be found under the [OpenMMLab org](https://huggingface.co/openmmlab/PIA-condition-adapter). These checkpoints are meant to work with any model based on Stable Diffusion 1.5
|
| 39 |
+
|
| 40 |
+
## Usage example
|
| 41 |
+
|
| 42 |
+
PIA works with a MotionAdapter checkpoint and a Stable Diffusion 1.5 model checkpoint. The MotionAdapter is a collection of Motion Modules that are responsible for adding coherent motion across image frames. These modules are applied after the Resnet and Attention blocks in the Stable Diffusion UNet. In addition to the motion modules, PIA also replaces the input convolution layer of the SD 1.5 UNet model with a 9 channel input convolution layer.
|
| 43 |
+
|
| 44 |
+
The following example demonstrates how to use PIA to generate a video from a single image.
|
| 45 |
+
|
| 46 |
+
```python
|
| 47 |
+
import torch
|
| 48 |
+
from diffusers import (
|
| 49 |
+
EulerDiscreteScheduler,
|
| 50 |
+
MotionAdapter,
|
| 51 |
+
PIAPipeline,
|
| 52 |
+
)
|
| 53 |
+
from diffusers.utils import export_to_gif, load_image
|
| 54 |
+
|
| 55 |
+
adapter = MotionAdapter.from_pretrained("openmmlab/PIA-condition-adapter")
|
| 56 |
+
pipe = PIAPipeline.from_pretrained("SG161222/Realistic_Vision_V6.0_B1_noVAE", motion_adapter=adapter, torch_dtype=torch.float16)
|
| 57 |
+
|
| 58 |
+
pipe.scheduler = EulerDiscreteScheduler.from_config(pipe.scheduler.config)
|
| 59 |
+
pipe.enable_model_cpu_offload()
|
| 60 |
+
pipe.enable_vae_slicing()
|
| 61 |
+
|
| 62 |
+
image = load_image(
|
| 63 |
+
"https://huggingface.co/datasets/hf-internal-testing/diffusers-images/resolve/main/pix2pix/cat_6.png?download=true"
|
| 64 |
+
)
|
| 65 |
+
image = image.resize((512, 512))
|
| 66 |
+
prompt = "cat in a field"
|
| 67 |
+
negative_prompt = "wrong white balance, dark, sketches,worst quality,low quality"
|
| 68 |
+
|
| 69 |
+
generator = torch.Generator("cpu").manual_seed(0)
|
| 70 |
+
output = pipe(image=image, prompt=prompt, generator=generator)
|
| 71 |
+
frames = output.frames[0]
|
| 72 |
+
export_to_gif(frames, "pia-animation.gif")
|
| 73 |
+
```
|
| 74 |
+
|
| 75 |
+
Here are some sample outputs:
|
| 76 |
+
|
| 77 |
+
<table>
|
| 78 |
+
<tr>
|
| 79 |
+
<td><center>
|
| 80 |
+
cat in a field.
|
| 81 |
+
<br>
|
| 82 |
+
<img src="https://huggingface.co/datasets/huggingface/documentation-images/resolve/main/diffusers/pia-default-output.gif"
|
| 83 |
+
alt="cat in a field"
|
| 84 |
+
style="width: 300px;" />
|
| 85 |
+
</center></td>
|
| 86 |
+
</tr>
|
| 87 |
+
</table>
|
| 88 |
+
|
| 89 |
+
|
| 90 |
+
> [!TIP]
|
| 91 |
+
> If you plan on using a scheduler that can clip samples, make sure to disable it by setting `clip_sample=False` in the scheduler as this can also have an adverse effect on generated samples. Additionally, the PIA checkpoints can be sensitive to the beta schedule of the scheduler. We recommend setting this to `linear`.
|
| 92 |
+
|
| 93 |
+
## Using FreeInit
|
| 94 |
+
|
| 95 |
+
[FreeInit: Bridging Initialization Gap in Video Diffusion Models](https://huggingface.co/papers/2312.07537) by Tianxing Wu, Chenyang Si, Yuming Jiang, Ziqi Huang, Ziwei Liu.
|
| 96 |
+
|
| 97 |
+
FreeInit is an effective method that improves temporal consistency and overall quality of videos generated using video-diffusion-models without any addition training. It can be applied to PIA, AnimateDiff, ModelScope, VideoCrafter and various other video generation models seamlessly at inference time, and works by iteratively refining the latent-initialization noise. More details can be found it the paper.
|
| 98 |
+
|
| 99 |
+
The following example demonstrates the usage of FreeInit.
|
| 100 |
+
|
| 101 |
+
```python
|
| 102 |
+
import torch
|
| 103 |
+
from diffusers import (
|
| 104 |
+
DDIMScheduler,
|
| 105 |
+
MotionAdapter,
|
| 106 |
+
PIAPipeline,
|
| 107 |
+
)
|
| 108 |
+
from diffusers.utils import export_to_gif, load_image
|
| 109 |
+
|
| 110 |
+
adapter = MotionAdapter.from_pretrained("openmmlab/PIA-condition-adapter")
|
| 111 |
+
pipe = PIAPipeline.from_pretrained("SG161222/Realistic_Vision_V6.0_B1_noVAE", motion_adapter=adapter)
|
| 112 |
+
|
| 113 |
+
# enable FreeInit
|
| 114 |
+
# Refer to the enable_free_init documentation for a full list of configurable parameters
|
| 115 |
+
pipe.enable_free_init(method="butterworth", use_fast_sampling=True)
|
| 116 |
+
|
| 117 |
+
# Memory saving options
|
| 118 |
+
pipe.enable_model_cpu_offload()
|
| 119 |
+
pipe.enable_vae_slicing()
|
| 120 |
+
|
| 121 |
+
pipe.scheduler = DDIMScheduler.from_config(pipe.scheduler.config)
|
| 122 |
+
image = load_image(
|
| 123 |
+
"https://huggingface.co/datasets/hf-internal-testing/diffusers-images/resolve/main/pix2pix/cat_6.png?download=true"
|
| 124 |
+
)
|
| 125 |
+
image = image.resize((512, 512))
|
| 126 |
+
prompt = "cat in a field"
|
| 127 |
+
negative_prompt = "wrong white balance, dark, sketches,worst quality,low quality"
|
| 128 |
+
|
| 129 |
+
generator = torch.Generator("cpu").manual_seed(0)
|
| 130 |
+
|
| 131 |
+
output = pipe(image=image, prompt=prompt, generator=generator)
|
| 132 |
+
frames = output.frames[0]
|
| 133 |
+
export_to_gif(frames, "pia-freeinit-animation.gif")
|
| 134 |
+
```
|
| 135 |
+
|
| 136 |
+
<table>
|
| 137 |
+
<tr>
|
| 138 |
+
<td><center>
|
| 139 |
+
cat in a field.
|
| 140 |
+
<br>
|
| 141 |
+
<img src="https://huggingface.co/datasets/huggingface/documentation-images/resolve/main/diffusers/pia-freeinit-output-cat.gif"
|
| 142 |
+
alt="cat in a field"
|
| 143 |
+
style="width: 300px;" />
|
| 144 |
+
</center></td>
|
| 145 |
+
</tr>
|
| 146 |
+
</table>
|
| 147 |
+
|
| 148 |
+
|
| 149 |
+
> [!WARNING]
|
| 150 |
+
> FreeInit is not really free - the improved quality comes at the cost of extra computation. It requires sampling a few extra times depending on the `num_iters` parameter that is set when enabling it. Setting the `use_fast_sampling` parameter to `True` can improve the overall performance (at the cost of lower quality compared to when `use_fast_sampling=False` but still better results than vanilla video generation models).
|
| 151 |
+
|
| 152 |
+
## PIAPipeline
|
| 153 |
+
|
| 154 |
+
[[autodoc]] PIAPipeline
|
| 155 |
+
- all
|
| 156 |
+
- __call__
|
| 157 |
+
- enable_freeu
|
| 158 |
+
- disable_freeu
|
| 159 |
+
- enable_free_init
|
| 160 |
+
- disable_free_init
|
| 161 |
+
- enable_vae_slicing
|
| 162 |
+
- disable_vae_slicing
|
| 163 |
+
- enable_vae_tiling
|
| 164 |
+
- disable_vae_tiling
|
| 165 |
+
|
| 166 |
+
## PIAPipelineOutput
|
| 167 |
+
|
| 168 |
+
[[autodoc]] pipelines.pia.PIAPipelineOutput
|
tasks/tasksmith-1c5704b1f07f/tests/source/docs/source/en/api/pipelines/pix2pix.md
ADDED
|
@@ -0,0 +1,41 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
<!--Copyright 2025 The HuggingFace Team. All rights reserved.
|
| 2 |
+
|
| 3 |
+
Licensed under the Apache License, Version 2.0 (the "License"); you may not use this file except in compliance with
|
| 4 |
+
the License. You may obtain a copy of the License at
|
| 5 |
+
|
| 6 |
+
http://www.apache.org/licenses/LICENSE-2.0
|
| 7 |
+
|
| 8 |
+
Unless required by applicable law or agreed to in writing, software distributed under the License is distributed on
|
| 9 |
+
an "AS IS" BASIS, WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied. See the License for the
|
| 10 |
+
specific language governing permissions and limitations under the License.
|
| 11 |
+
-->
|
| 12 |
+
|
| 13 |
+
# InstructPix2Pix
|
| 14 |
+
|
| 15 |
+
<div class="flex flex-wrap space-x-1">
|
| 16 |
+
<img alt="LoRA" src="https://img.shields.io/badge/LoRA-d8b4fe?style=flat"/>
|
| 17 |
+
</div>
|
| 18 |
+
|
| 19 |
+
[InstructPix2Pix: Learning to Follow Image Editing Instructions](https://huggingface.co/papers/2211.09800) is by Tim Brooks, Aleksander Holynski and Alexei A. Efros.
|
| 20 |
+
|
| 21 |
+
The abstract from the paper is:
|
| 22 |
+
|
| 23 |
+
*We propose a method for editing images from human instructions: given an input image and a written instruction that tells the model what to do, our model follows these instructions to edit the image. To obtain training data for this problem, we combine the knowledge of two large pretrained models -- a language model (GPT-3) and a text-to-image model (Stable Diffusion) -- to generate a large dataset of image editing examples. Our conditional diffusion model, InstructPix2Pix, is trained on our generated data, and generalizes to real images and user-written instructions at inference time. Since it performs edits in the forward pass and does not require per example fine-tuning or inversion, our model edits images quickly, in a matter of seconds. We show compelling editing results for a diverse collection of input images and written instructions.*
|
| 24 |
+
|
| 25 |
+
You can find additional information about InstructPix2Pix on the [project page](https://www.timothybrooks.com/instruct-pix2pix), [original codebase](https://github.com/timothybrooks/instruct-pix2pix), and try it out in a [demo](https://huggingface.co/spaces/timbrooks/instruct-pix2pix).
|
| 26 |
+
|
| 27 |
+
> [!TIP]
|
| 28 |
+
> Make sure to check out the Schedulers [guide](../../using-diffusers/schedulers) to learn how to explore the tradeoff between scheduler speed and quality, and see the [reuse components across pipelines](../../using-diffusers/loading#reuse-a-pipeline) section to learn how to efficiently load the same components into multiple pipelines.
|
| 29 |
+
|
| 30 |
+
## StableDiffusionInstructPix2PixPipeline
|
| 31 |
+
[[autodoc]] StableDiffusionInstructPix2PixPipeline
|
| 32 |
+
- __call__
|
| 33 |
+
- all
|
| 34 |
+
- load_textual_inversion
|
| 35 |
+
- load_lora_weights
|
| 36 |
+
- save_lora_weights
|
| 37 |
+
|
| 38 |
+
## StableDiffusionXLInstructPix2PixPipeline
|
| 39 |
+
[[autodoc]] StableDiffusionXLInstructPix2PixPipeline
|
| 40 |
+
- __call__
|
| 41 |
+
- all
|
tasks/tasksmith-1c5704b1f07f/tests/source/docs/source/en/api/pipelines/pixart.md
ADDED
|
@@ -0,0 +1,139 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
<!--Copyright 2025 The HuggingFace Team. All rights reserved.
|
| 2 |
+
|
| 3 |
+
Licensed under the Apache License, Version 2.0 (the "License"); you may not use this file except in compliance with
|
| 4 |
+
the License. You may obtain a copy of the License at
|
| 5 |
+
|
| 6 |
+
http://www.apache.org/licenses/LICENSE-2.0
|
| 7 |
+
|
| 8 |
+
Unless required by applicable law or agreed to in writing, software distributed under the License is distributed on
|
| 9 |
+
an "AS IS" BASIS, WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied. See the License for the
|
| 10 |
+
specific language governing permissions and limitations under the License.
|
| 11 |
+
-->
|
| 12 |
+
|
| 13 |
+
# PixArt-α
|
| 14 |
+
|
| 15 |
+
|
| 16 |
+
|
| 17 |
+
[PixArt-α: Fast Training of Diffusion Transformer for Photorealistic Text-to-Image Synthesis](https://huggingface.co/papers/2310.00426) is Junsong Chen, Jincheng Yu, Chongjian Ge, Lewei Yao, Enze Xie, Yue Wu, Zhongdao Wang, James Kwok, Ping Luo, Huchuan Lu, and Zhenguo Li.
|
| 18 |
+
|
| 19 |
+
The abstract from the paper is:
|
| 20 |
+
|
| 21 |
+
*The most advanced text-to-image (T2I) models require significant training costs (e.g., millions of GPU hours), seriously hindering the fundamental innovation for the AIGC community while increasing CO2 emissions. This paper introduces PIXART-α, a Transformer-based T2I diffusion model whose image generation quality is competitive with state-of-the-art image generators (e.g., Imagen, SDXL, and even Midjourney), reaching near-commercial application standards. Additionally, it supports high-resolution image synthesis up to 1024px resolution with low training cost, as shown in Figure 1 and 2. To achieve this goal, three core designs are proposed: (1) Training strategy decomposition: We devise three distinct training steps that separately optimize pixel dependency, text-image alignment, and image aesthetic quality; (2) Efficient T2I Transformer: We incorporate cross-attention modules into Diffusion Transformer (DiT) to inject text conditions and streamline the computation-intensive class-condition branch; (3) High-informative data: We emphasize the significance of concept density in text-image pairs and leverage a large Vision-Language model to auto-label dense pseudo-captions to assist text-image alignment learning. As a result, PIXART-α's training speed markedly surpasses existing large-scale T2I models, e.g., PIXART-α only takes 10.8% of Stable Diffusion v1.5's training time (675 vs. 6,250 A100 GPU days), saving nearly $300,000 ($26,000 vs. $320,000) and reducing 90% CO2 emissions. Moreover, compared with a larger SOTA model, RAPHAEL, our training cost is merely 1%. Extensive experiments demonstrate that PIXART-α excels in image quality, artistry, and semantic control. We hope PIXART-α will provide new insights to the AIGC community and startups to accelerate building their own high-quality yet low-cost generative models from scratch.*
|
| 22 |
+
|
| 23 |
+
You can find the original codebase at [PixArt-alpha/PixArt-alpha](https://github.com/PixArt-alpha/PixArt-alpha) and all the available checkpoints at [PixArt-alpha](https://huggingface.co/PixArt-alpha).
|
| 24 |
+
|
| 25 |
+
Some notes about this pipeline:
|
| 26 |
+
|
| 27 |
+
* It uses a Transformer backbone (instead of a UNet) for denoising. As such it has a similar architecture as [DiT](./dit).
|
| 28 |
+
* It was trained using text conditions computed from T5. This aspect makes the pipeline better at following complex text prompts with intricate details.
|
| 29 |
+
* It is good at producing high-resolution images at different aspect ratios. To get the best results, the authors recommend some size brackets which can be found [here](https://github.com/PixArt-alpha/PixArt-alpha/blob/08fbbd281ec96866109bdd2cdb75f2f58fb17610/diffusion/data/datasets/utils.py).
|
| 30 |
+
* It rivals the quality of state-of-the-art text-to-image generation systems (as of this writing) such as Stable Diffusion XL, Imagen, and DALL-E 2, while being more efficient than them.
|
| 31 |
+
|
| 32 |
+
> [!TIP]
|
| 33 |
+
> Make sure to check out the Schedulers [guide](../../using-diffusers/schedulers) to learn how to explore the tradeoff between scheduler speed and quality, and see the [reuse components across pipelines](../../using-diffusers/loading#reuse-a-pipeline) section to learn how to efficiently load the same components into multiple pipelines.
|
| 34 |
+
|
| 35 |
+
## Inference with under 8GB GPU VRAM
|
| 36 |
+
|
| 37 |
+
Run the [`PixArtAlphaPipeline`] with under 8GB GPU VRAM by loading the text encoder in 8-bit precision. Let's walk through a full-fledged example.
|
| 38 |
+
|
| 39 |
+
First, install the [bitsandbytes](https://github.com/TimDettmers/bitsandbytes) library:
|
| 40 |
+
|
| 41 |
+
```bash
|
| 42 |
+
pip install -U bitsandbytes
|
| 43 |
+
```
|
| 44 |
+
|
| 45 |
+
Then load the text encoder in 8-bit:
|
| 46 |
+
|
| 47 |
+
```python
|
| 48 |
+
from transformers import T5EncoderModel
|
| 49 |
+
from diffusers import PixArtAlphaPipeline
|
| 50 |
+
import torch
|
| 51 |
+
|
| 52 |
+
text_encoder = T5EncoderModel.from_pretrained(
|
| 53 |
+
"PixArt-alpha/PixArt-XL-2-1024-MS",
|
| 54 |
+
subfolder="text_encoder",
|
| 55 |
+
load_in_8bit=True,
|
| 56 |
+
device_map="auto",
|
| 57 |
+
|
| 58 |
+
)
|
| 59 |
+
pipe = PixArtAlphaPipeline.from_pretrained(
|
| 60 |
+
"PixArt-alpha/PixArt-XL-2-1024-MS",
|
| 61 |
+
text_encoder=text_encoder,
|
| 62 |
+
transformer=None,
|
| 63 |
+
device_map="auto"
|
| 64 |
+
)
|
| 65 |
+
```
|
| 66 |
+
|
| 67 |
+
Now, use the `pipe` to encode a prompt:
|
| 68 |
+
|
| 69 |
+
```python
|
| 70 |
+
with torch.no_grad():
|
| 71 |
+
prompt = "cute cat"
|
| 72 |
+
prompt_embeds, prompt_attention_mask, negative_embeds, negative_prompt_attention_mask = pipe.encode_prompt(prompt)
|
| 73 |
+
```
|
| 74 |
+
|
| 75 |
+
Since text embeddings have been computed, remove the `text_encoder` and `pipe` from the memory, and free up some GPU VRAM:
|
| 76 |
+
|
| 77 |
+
```python
|
| 78 |
+
import gc
|
| 79 |
+
|
| 80 |
+
def flush():
|
| 81 |
+
gc.collect()
|
| 82 |
+
torch.cuda.empty_cache()
|
| 83 |
+
|
| 84 |
+
del text_encoder
|
| 85 |
+
del pipe
|
| 86 |
+
flush()
|
| 87 |
+
```
|
| 88 |
+
|
| 89 |
+
Then compute the latents with the prompt embeddings as inputs:
|
| 90 |
+
|
| 91 |
+
```python
|
| 92 |
+
pipe = PixArtAlphaPipeline.from_pretrained(
|
| 93 |
+
"PixArt-alpha/PixArt-XL-2-1024-MS",
|
| 94 |
+
text_encoder=None,
|
| 95 |
+
torch_dtype=torch.float16,
|
| 96 |
+
).to("cuda")
|
| 97 |
+
|
| 98 |
+
latents = pipe(
|
| 99 |
+
negative_prompt=None,
|
| 100 |
+
prompt_embeds=prompt_embeds,
|
| 101 |
+
negative_prompt_embeds=negative_embeds,
|
| 102 |
+
prompt_attention_mask=prompt_attention_mask,
|
| 103 |
+
negative_prompt_attention_mask=negative_prompt_attention_mask,
|
| 104 |
+
num_images_per_prompt=1,
|
| 105 |
+
output_type="latent",
|
| 106 |
+
).images
|
| 107 |
+
|
| 108 |
+
del pipe.transformer
|
| 109 |
+
flush()
|
| 110 |
+
```
|
| 111 |
+
|
| 112 |
+
> [!TIP]
|
| 113 |
+
> Notice that while initializing `pipe`, you're setting `text_encoder` to `None` so that it's not loaded.
|
| 114 |
+
|
| 115 |
+
Once the latents are computed, pass it off to the VAE to decode into a real image:
|
| 116 |
+
|
| 117 |
+
```python
|
| 118 |
+
with torch.no_grad():
|
| 119 |
+
image = pipe.vae.decode(latents / pipe.vae.config.scaling_factor, return_dict=False)[0]
|
| 120 |
+
image = pipe.image_processor.postprocess(image, output_type="pil")[0]
|
| 121 |
+
image.save("cat.png")
|
| 122 |
+
```
|
| 123 |
+
|
| 124 |
+
By deleting components you aren't using and flushing the GPU VRAM, you should be able to run [`PixArtAlphaPipeline`] with under 8GB GPU VRAM.
|
| 125 |
+
|
| 126 |
+
|
| 127 |
+
|
| 128 |
+
If you want a report of your memory-usage, run this [script](https://gist.github.com/sayakpaul/3ae0f847001d342af27018a96f467e4e).
|
| 129 |
+
|
| 130 |
+
> [!WARNING]
|
| 131 |
+
> Text embeddings computed in 8-bit can impact the quality of the generated images because of the information loss in the representation space caused by the reduced precision. It's recommended to compare the outputs with and without 8-bit.
|
| 132 |
+
|
| 133 |
+
While loading the `text_encoder`, you set `load_in_8bit` to `True`. You could also specify `load_in_4bit` to bring your memory requirements down even further to under 7GB.
|
| 134 |
+
|
| 135 |
+
## PixArtAlphaPipeline
|
| 136 |
+
|
| 137 |
+
[[autodoc]] PixArtAlphaPipeline
|
| 138 |
+
- all
|
| 139 |
+
- __call__
|
tasks/tasksmith-1c5704b1f07f/tests/source/docs/source/en/api/pipelines/pixart_sigma.md
ADDED
|
@@ -0,0 +1,143 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
<!--Copyright 2025 The HuggingFace Team. All rights reserved.
|
| 2 |
+
|
| 3 |
+
Licensed under the Apache License, Version 2.0 (the "License"); you may not use this file except in compliance with
|
| 4 |
+
the License. You may obtain a copy of the License at
|
| 5 |
+
|
| 6 |
+
http://www.apache.org/licenses/LICENSE-2.0
|
| 7 |
+
|
| 8 |
+
Unless required by applicable law or agreed to in writing, software distributed under the License is distributed on
|
| 9 |
+
an "AS IS" BASIS, WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied. See the License for the
|
| 10 |
+
specific language governing permissions and limitations under the License.
|
| 11 |
+
-->
|
| 12 |
+
|
| 13 |
+
# PixArt-Σ
|
| 14 |
+
|
| 15 |
+

|
| 16 |
+
|
| 17 |
+
[PixArt-Σ: Weak-to-Strong Training of Diffusion Transformer for 4K Text-to-Image Generation](https://huggingface.co/papers/2403.04692) is Junsong Chen, Jincheng Yu, Chongjian Ge, Lewei Yao, Enze Xie, Yue Wu, Zhongdao Wang, James Kwok, Ping Luo, Huchuan Lu, and Zhenguo Li.
|
| 18 |
+
|
| 19 |
+
The abstract from the paper is:
|
| 20 |
+
|
| 21 |
+
*In this paper, we introduce PixArt-Σ, a Diffusion Transformer model (DiT) capable of directly generating images at 4K resolution. PixArt-Σ represents a significant advancement over its predecessor, PixArt-α, offering images of markedly higher fidelity and improved alignment with text prompts. A key feature of PixArt-Σ is its training efficiency. Leveraging the foundational pre-training of PixArt-α, it evolves from the ‘weaker’ baseline to a ‘stronger’ model via incorporating higher quality data, a process we term “weak-to-strong training”. The advancements in PixArt-Σ are twofold: (1) High-Quality Training Data: PixArt-Σ incorporates superior-quality image data, paired with more precise and detailed image captions. (2) Efficient Token Compression: we propose a novel attention module within the DiT framework that compresses both keys and values, significantly improving efficiency and facilitating ultra-high-resolution image generation. Thanks to these improvements, PixArt-Σ achieves superior image quality and user prompt adherence capabilities with significantly smaller model size (0.6B parameters) than existing text-to-image diffusion models, such as SDXL (2.6B parameters) and SD Cascade (5.1B parameters). Moreover, PixArt-Σ’s capability to generate 4K images supports the creation of high-resolution posters and wallpapers, efficiently bolstering the production of highquality visual content in industries such as film and gaming.*
|
| 22 |
+
|
| 23 |
+
You can find the original codebase at [PixArt-alpha/PixArt-sigma](https://github.com/PixArt-alpha/PixArt-sigma) and all the available checkpoints at [PixArt-alpha](https://huggingface.co/PixArt-alpha).
|
| 24 |
+
|
| 25 |
+
Some notes about this pipeline:
|
| 26 |
+
|
| 27 |
+
* It uses a Transformer backbone (instead of a UNet) for denoising. As such it has a similar architecture as [DiT](https://hf.co/docs/transformers/model_doc/dit).
|
| 28 |
+
* It was trained using text conditions computed from T5. This aspect makes the pipeline better at following complex text prompts with intricate details.
|
| 29 |
+
* It is good at producing high-resolution images at different aspect ratios. To get the best results, the authors recommend some size brackets which can be found [here](https://github.com/PixArt-alpha/PixArt-sigma/blob/master/diffusion/data/datasets/utils.py).
|
| 30 |
+
* It rivals the quality of state-of-the-art text-to-image generation systems (as of this writing) such as PixArt-α, Stable Diffusion XL, Playground V2.0 and DALL-E 3, while being more efficient than them.
|
| 31 |
+
* It shows the ability of generating super high resolution images, such as 2048px or even 4K.
|
| 32 |
+
* It shows that text-to-image models can grow from a weak model to a stronger one through several improvements (VAEs, datasets, and so on.)
|
| 33 |
+
|
| 34 |
+
> [!TIP]
|
| 35 |
+
> Make sure to check out the Schedulers [guide](../../using-diffusers/schedulers) to learn how to explore the tradeoff between scheduler speed and quality, and see the [reuse components across pipelines](../../using-diffusers/loading#reuse-a-pipeline) section to learn how to efficiently load the same components into multiple pipelines.
|
| 36 |
+
|
| 37 |
+
> [!TIP]
|
| 38 |
+
> You can further improve generation quality by passing the generated image from [`PixArtSigmaPipeline`] to the [SDXL refiner](../../using-diffusers/sdxl#base-to-refiner-model) model.
|
| 39 |
+
|
| 40 |
+
## Inference with under 8GB GPU VRAM
|
| 41 |
+
|
| 42 |
+
Run the [`PixArtSigmaPipeline`] with under 8GB GPU VRAM by loading the text encoder in 8-bit precision. Let's walk through a full-fledged example.
|
| 43 |
+
|
| 44 |
+
First, install the [bitsandbytes](https://github.com/TimDettmers/bitsandbytes) library:
|
| 45 |
+
|
| 46 |
+
```bash
|
| 47 |
+
pip install -U bitsandbytes
|
| 48 |
+
```
|
| 49 |
+
|
| 50 |
+
Then load the text encoder in 8-bit:
|
| 51 |
+
|
| 52 |
+
```python
|
| 53 |
+
from transformers import T5EncoderModel
|
| 54 |
+
from diffusers import PixArtSigmaPipeline
|
| 55 |
+
import torch
|
| 56 |
+
|
| 57 |
+
text_encoder = T5EncoderModel.from_pretrained(
|
| 58 |
+
"PixArt-alpha/PixArt-Sigma-XL-2-1024-MS",
|
| 59 |
+
subfolder="text_encoder",
|
| 60 |
+
load_in_8bit=True,
|
| 61 |
+
device_map="auto",
|
| 62 |
+
)
|
| 63 |
+
pipe = PixArtSigmaPipeline.from_pretrained(
|
| 64 |
+
"PixArt-alpha/PixArt-Sigma-XL-2-1024-MS",
|
| 65 |
+
text_encoder=text_encoder,
|
| 66 |
+
transformer=None,
|
| 67 |
+
device_map="balanced"
|
| 68 |
+
)
|
| 69 |
+
```
|
| 70 |
+
|
| 71 |
+
Now, use the `pipe` to encode a prompt:
|
| 72 |
+
|
| 73 |
+
```python
|
| 74 |
+
with torch.no_grad():
|
| 75 |
+
prompt = "cute cat"
|
| 76 |
+
prompt_embeds, prompt_attention_mask, negative_embeds, negative_prompt_attention_mask = pipe.encode_prompt(prompt)
|
| 77 |
+
```
|
| 78 |
+
|
| 79 |
+
Since text embeddings have been computed, remove the `text_encoder` and `pipe` from the memory, and free up some GPU VRAM:
|
| 80 |
+
|
| 81 |
+
```python
|
| 82 |
+
import gc
|
| 83 |
+
|
| 84 |
+
def flush():
|
| 85 |
+
gc.collect()
|
| 86 |
+
torch.cuda.empty_cache()
|
| 87 |
+
|
| 88 |
+
del text_encoder
|
| 89 |
+
del pipe
|
| 90 |
+
flush()
|
| 91 |
+
```
|
| 92 |
+
|
| 93 |
+
Then compute the latents with the prompt embeddings as inputs:
|
| 94 |
+
|
| 95 |
+
```python
|
| 96 |
+
pipe = PixArtSigmaPipeline.from_pretrained(
|
| 97 |
+
"PixArt-alpha/PixArt-Sigma-XL-2-1024-MS",
|
| 98 |
+
text_encoder=None,
|
| 99 |
+
torch_dtype=torch.float16,
|
| 100 |
+
).to("cuda")
|
| 101 |
+
|
| 102 |
+
latents = pipe(
|
| 103 |
+
negative_prompt=None,
|
| 104 |
+
prompt_embeds=prompt_embeds,
|
| 105 |
+
negative_prompt_embeds=negative_embeds,
|
| 106 |
+
prompt_attention_mask=prompt_attention_mask,
|
| 107 |
+
negative_prompt_attention_mask=negative_prompt_attention_mask,
|
| 108 |
+
num_images_per_prompt=1,
|
| 109 |
+
output_type="latent",
|
| 110 |
+
).images
|
| 111 |
+
|
| 112 |
+
del pipe.transformer
|
| 113 |
+
flush()
|
| 114 |
+
```
|
| 115 |
+
|
| 116 |
+
> [!TIP]
|
| 117 |
+
> Notice that while initializing `pipe`, you're setting `text_encoder` to `None` so that it's not loaded.
|
| 118 |
+
|
| 119 |
+
Once the latents are computed, pass it off to the VAE to decode into a real image:
|
| 120 |
+
|
| 121 |
+
```python
|
| 122 |
+
with torch.no_grad():
|
| 123 |
+
image = pipe.vae.decode(latents / pipe.vae.config.scaling_factor, return_dict=False)[0]
|
| 124 |
+
image = pipe.image_processor.postprocess(image, output_type="pil")[0]
|
| 125 |
+
image.save("cat.png")
|
| 126 |
+
```
|
| 127 |
+
|
| 128 |
+
By deleting components you aren't using and flushing the GPU VRAM, you should be able to run [`PixArtSigmaPipeline`] with under 8GB GPU VRAM.
|
| 129 |
+
|
| 130 |
+

|
| 131 |
+
|
| 132 |
+
If you want a report of your memory-usage, run this [script](https://gist.github.com/sayakpaul/3ae0f847001d342af27018a96f467e4e).
|
| 133 |
+
|
| 134 |
+
> [!WARNING]
|
| 135 |
+
> Text embeddings computed in 8-bit can impact the quality of the generated images because of the information loss in the representation space caused by the reduced precision. It's recommended to compare the outputs with and without 8-bit.
|
| 136 |
+
|
| 137 |
+
While loading the `text_encoder`, you set `load_in_8bit` to `True`. You could also specify `load_in_4bit` to bring your memory requirements down even further to under 7GB.
|
| 138 |
+
|
| 139 |
+
## PixArtSigmaPipeline
|
| 140 |
+
|
| 141 |
+
[[autodoc]] PixArtSigmaPipeline
|
| 142 |
+
- all
|
| 143 |
+
- __call__
|
tasks/tasksmith-1c5704b1f07f/tests/source/docs/source/en/api/pipelines/prx.md
ADDED
|
@@ -0,0 +1,131 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
<!-- Copyright 2025 The HuggingFace Team. All rights reserved.
|
| 2 |
+
#
|
| 3 |
+
# Licensed under the Apache License, Version 2.0 (the "License");
|
| 4 |
+
# you may not use this file except in compliance with the License.
|
| 5 |
+
# You may obtain a copy of the License at
|
| 6 |
+
#
|
| 7 |
+
# http://www.apache.org/licenses/LICENSE-2.0
|
| 8 |
+
#
|
| 9 |
+
# Unless required by applicable law or agreed to in writing, software
|
| 10 |
+
# distributed under the License is distributed on an "AS IS" BASIS,
|
| 11 |
+
# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
|
| 12 |
+
# See the License for the specific language governing permissions and
|
| 13 |
+
# limitations under the License. -->
|
| 14 |
+
|
| 15 |
+
# PRX
|
| 16 |
+
|
| 17 |
+
|
| 18 |
+
PRX generates high-quality images from text using a simplified MMDIT architecture where text tokens don't update through transformer blocks. It employs flow matching with discrete scheduling for efficient sampling and uses Google's T5Gemma-2B-2B-UL2 model for multi-language text encoding. The ~1.3B parameter transformer delivers fast inference without sacrificing quality. You can choose between Flux VAE (8x compression, 16 latent channels) for balanced quality and speed or DC-AE (32x compression, 32 latent channels) for latent compression and faster processing.
|
| 19 |
+
|
| 20 |
+
## Available models
|
| 21 |
+
|
| 22 |
+
PRX offers multiple variants with different VAE configurations, each optimized for specific resolutions. Base models excel with detailed prompts, capturing complex compositions and subtle details. Fine-tuned models trained on the [Alchemist dataset](https://huggingface.co/datasets/yandex/alchemist) improve aesthetic quality, especially with simpler prompts.
|
| 23 |
+
|
| 24 |
+
|
| 25 |
+
| Model | Resolution | Fine-tuned | Distilled | Description | Suggested prompts | Suggested parameters | Recommended dtype |
|
| 26 |
+
|:-----:|:-----------------:|:----------:|:----------:|:----------:|:----------:|:----------:|:----------:|
|
| 27 |
+
| [`Photoroom/prx-256-t2i`](https://huggingface.co/Photoroom/prx-256-t2i)| 256 | No | No | Base model pre-trained at 256 with Flux VAE|Works best with detailed prompts in natural language|28 steps, cfg=5.0| `torch.bfloat16` |
|
| 28 |
+
| [`Photoroom/prx-256-t2i-sft`](https://huggingface.co/Photoroom/prx-256-t2i-sft)| 512 | Yes | No | Fine-tuned on the [Alchemist dataset](https://huggingface.co/datasets/yandex/alchemist) dataset with Flux VAE | Can handle less detailed prompts|28 steps, cfg=5.0| `torch.bfloat16` |
|
| 29 |
+
| [`Photoroom/prx-512-t2i`](https://huggingface.co/Photoroom/prx-512-t2i)| 512 | No | No | Base model pre-trained at 512 with Flux VAE |Works best with detailed prompts in natural language|28 steps, cfg=5.0| `torch.bfloat16` |
|
| 30 |
+
| [`Photoroom/prx-512-t2i-sft`](https://huggingface.co/Photoroom/prx-512-t2i-sft)| 512 | Yes | No | Fine-tuned on the [Alchemist dataset](https://huggingface.co/datasets/yandex/alchemist) dataset with Flux VAE | Can handle less detailed prompts in natural language|28 steps, cfg=5.0| `torch.bfloat16` |
|
| 31 |
+
| [`Photoroom/prx-512-t2i-sft-distilled`](https://huggingface.co/Photoroom/prx-512-t2i-sft-distilled)| 512 | Yes | Yes | 8-step distilled model from [`Photoroom/prx-512-t2i-sft`](https://huggingface.co/Photoroom/prx-512-t2i-sft) | Can handle less detailed prompts in natural language|8 steps, cfg=1.0| `torch.bfloat16` |
|
| 32 |
+
| [`Photoroom/prx-512-t2i-dc-ae`](https://huggingface.co/Photoroom/prx-512-t2i-dc-ae)| 512 | No | No | Base model pre-trained at 512 with [Deep Compression Autoencoder (DC-AE)](https://hanlab.mit.edu/projects/dc-ae)|Works best with detailed prompts in natural language|28 steps, cfg=5.0| `torch.bfloat16` |
|
| 33 |
+
| [`Photoroom/prx-512-t2i-dc-ae-sft`](https://huggingface.co/Photoroom/prx-512-t2i-dc-ae-sft)| 512 | Yes | No | Fine-tuned on the [Alchemist dataset](https://huggingface.co/datasets/yandex/alchemist) dataset with [Deep Compression Autoencoder (DC-AE)](https://hanlab.mit.edu/projects/dc-ae) | Can handle less detailed prompts in natural language|28 steps, cfg=5.0| `torch.bfloat16` |
|
| 34 |
+
| [`Photoroom/prx-512-t2i-dc-ae-sft-distilled`](https://huggingface.co/Photoroom/prx-512-t2i-dc-ae-sft-distilled)| 512 | Yes | Yes | 8-step distilled model from [`Photoroom/prx-512-t2i-dc-ae-sft-distilled`](https://huggingface.co/Photoroom/prx-512-t2i-dc-ae-sft-distilled) | Can handle less detailed prompts in natural language|8 steps, cfg=1.0| `torch.bfloat16` |s
|
| 35 |
+
|
| 36 |
+
Refer to [this](https://huggingface.co/collections/Photoroom/prx-models-68e66254c202ebfab99ad38e) collection for more information.
|
| 37 |
+
|
| 38 |
+
## Loading the pipeline
|
| 39 |
+
|
| 40 |
+
Load the pipeline with [`~DiffusionPipeline.from_pretrained`].
|
| 41 |
+
|
| 42 |
+
```py
|
| 43 |
+
from diffusers.pipelines.prx import PRXPipeline
|
| 44 |
+
|
| 45 |
+
# Load pipeline - VAE and text encoder will be loaded from HuggingFace
|
| 46 |
+
pipe = PRXPipeline.from_pretrained("Photoroom/prx-512-t2i-sft", torch_dtype=torch.bfloat16)
|
| 47 |
+
pipe.to("cuda")
|
| 48 |
+
|
| 49 |
+
prompt = "A front-facing portrait of a lion the golden savanna at sunset."
|
| 50 |
+
image = pipe(prompt, num_inference_steps=28, guidance_scale=5.0).images[0]
|
| 51 |
+
image.save("prx_output.png")
|
| 52 |
+
```
|
| 53 |
+
|
| 54 |
+
### Manual Component Loading
|
| 55 |
+
|
| 56 |
+
Load components individually to customize the pipeline for instance to use quantized models.
|
| 57 |
+
|
| 58 |
+
```py
|
| 59 |
+
import torch
|
| 60 |
+
from diffusers.pipelines.prx import PRXPipeline
|
| 61 |
+
from diffusers.models import AutoencoderKL, AutoencoderDC
|
| 62 |
+
from diffusers.models.transformers.transformer_prx import PRXTransformer2DModel
|
| 63 |
+
from diffusers.schedulers import FlowMatchEulerDiscreteScheduler
|
| 64 |
+
from transformers import T5GemmaModel, GemmaTokenizerFast
|
| 65 |
+
from diffusers import BitsAndBytesConfig as DiffusersBitsAndBytesConfig
|
| 66 |
+
from transformers import BitsAndBytesConfig as BitsAndBytesConfig
|
| 67 |
+
|
| 68 |
+
quant_config = DiffusersBitsAndBytesConfig(load_in_8bit=True)
|
| 69 |
+
# Load transformer
|
| 70 |
+
transformer = PRXTransformer2DModel.from_pretrained(
|
| 71 |
+
"checkpoints/prx-512-t2i-sft",
|
| 72 |
+
subfolder="transformer",
|
| 73 |
+
quantization_config=quant_config,
|
| 74 |
+
torch_dtype=torch.bfloat16,
|
| 75 |
+
)
|
| 76 |
+
|
| 77 |
+
# Load scheduler
|
| 78 |
+
scheduler = FlowMatchEulerDiscreteScheduler.from_pretrained(
|
| 79 |
+
"checkpoints/prx-512-t2i-sft", subfolder="scheduler"
|
| 80 |
+
)
|
| 81 |
+
|
| 82 |
+
# Load T5Gemma text encoder
|
| 83 |
+
t5gemma_model = T5GemmaModel.from_pretrained("google/t5gemma-2b-2b-ul2",
|
| 84 |
+
quantization_config=quant_config,
|
| 85 |
+
torch_dtype=torch.bfloat16)
|
| 86 |
+
text_encoder = t5gemma_model.encoder.to(dtype=torch.bfloat16)
|
| 87 |
+
tokenizer = GemmaTokenizerFast.from_pretrained("google/t5gemma-2b-2b-ul2")
|
| 88 |
+
tokenizer.model_max_length = 256
|
| 89 |
+
|
| 90 |
+
# Load VAE - choose either Flux VAE or DC-AE
|
| 91 |
+
# Flux VAE
|
| 92 |
+
vae = AutoencoderKL.from_pretrained("black-forest-labs/FLUX.1-dev",
|
| 93 |
+
subfolder="vae",
|
| 94 |
+
quantization_config=quant_config,
|
| 95 |
+
torch_dtype=torch.bfloat16)
|
| 96 |
+
|
| 97 |
+
pipe = PRXPipeline(
|
| 98 |
+
transformer=transformer,
|
| 99 |
+
scheduler=scheduler,
|
| 100 |
+
text_encoder=text_encoder,
|
| 101 |
+
tokenizer=tokenizer,
|
| 102 |
+
vae=vae
|
| 103 |
+
)
|
| 104 |
+
pipe.to("cuda")
|
| 105 |
+
```
|
| 106 |
+
|
| 107 |
+
|
| 108 |
+
## Memory Optimization
|
| 109 |
+
|
| 110 |
+
For memory-constrained environments:
|
| 111 |
+
|
| 112 |
+
```py
|
| 113 |
+
import torch
|
| 114 |
+
from diffusers.pipelines.prx import PRXPipeline
|
| 115 |
+
|
| 116 |
+
pipe = PRXPipeline.from_pretrained("Photoroom/prx-512-t2i-sft", torch_dtype=torch.bfloat16)
|
| 117 |
+
pipe.enable_model_cpu_offload() # Offload components to CPU when not in use
|
| 118 |
+
|
| 119 |
+
# Or use sequential CPU offload for even lower memory
|
| 120 |
+
pipe.enable_sequential_cpu_offload()
|
| 121 |
+
```
|
| 122 |
+
|
| 123 |
+
## PRXPipeline
|
| 124 |
+
|
| 125 |
+
[[autodoc]] PRXPipeline
|
| 126 |
+
- all
|
| 127 |
+
- __call__
|
| 128 |
+
|
| 129 |
+
## PRXPipelineOutput
|
| 130 |
+
|
| 131 |
+
[[autodoc]] pipelines.prx.pipeline_output.PRXPipelineOutput
|
tasks/tasksmith-1c5704b1f07f/tests/source/docs/source/en/api/pipelines/qwenimage.md
ADDED
|
@@ -0,0 +1,161 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
<!-- Copyright 2025 The HuggingFace Team. All rights reserved.
|
| 2 |
+
#
|
| 3 |
+
# Licensed under the Apache License, Version 2.0 (the "License");
|
| 4 |
+
# you may not use this file except in compliance with the License.
|
| 5 |
+
# You may obtain a copy of the License at
|
| 6 |
+
#
|
| 7 |
+
# http://www.apache.org/licenses/LICENSE-2.0
|
| 8 |
+
#
|
| 9 |
+
# Unless required by applicable law or agreed to in writing, software
|
| 10 |
+
# distributed under the License is distributed on an "AS IS" BASIS,
|
| 11 |
+
# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
|
| 12 |
+
# See the License for the specific language governing permissions and
|
| 13 |
+
# limitations under the License. -->
|
| 14 |
+
|
| 15 |
+
# QwenImage
|
| 16 |
+
|
| 17 |
+
<div class="flex flex-wrap space-x-1">
|
| 18 |
+
<img alt="LoRA" src="https://img.shields.io/badge/LoRA-d8b4fe?style=flat"/>
|
| 19 |
+
</div>
|
| 20 |
+
|
| 21 |
+
Qwen-Image from the Qwen team is an image generation foundation model in the Qwen series that achieves significant advances in complex text rendering and precise image editing. Experiments show strong general capabilities in both image generation and editing, with exceptional performance in text rendering, especially for Chinese.
|
| 22 |
+
|
| 23 |
+
Qwen-Image comes in the following variants:
|
| 24 |
+
|
| 25 |
+
| model type | model id |
|
| 26 |
+
|:----------:|:--------:|
|
| 27 |
+
| Qwen-Image | [`Qwen/Qwen-Image`](https://huggingface.co/Qwen/Qwen-Image) |
|
| 28 |
+
| Qwen-Image-Edit | [`Qwen/Qwen-Image-Edit`](https://huggingface.co/Qwen/Qwen-Image-Edit) |
|
| 29 |
+
| Qwen-Image-Edit Plus | [Qwen/Qwen-Image-Edit-2509](https://huggingface.co/Qwen/Qwen-Image-Edit-2509) |
|
| 30 |
+
|
| 31 |
+
> [!TIP]
|
| 32 |
+
> [Caching](../../optimization/cache) may also speed up inference by storing and reusing intermediate outputs.
|
| 33 |
+
|
| 34 |
+
## LoRA for faster inference
|
| 35 |
+
|
| 36 |
+
Use a LoRA from `lightx2v/Qwen-Image-Lightning` to speed up inference by reducing the
|
| 37 |
+
number of steps. Refer to the code snippet below:
|
| 38 |
+
|
| 39 |
+
<details>
|
| 40 |
+
<summary>Code</summary>
|
| 41 |
+
|
| 42 |
+
```py
|
| 43 |
+
from diffusers import DiffusionPipeline, FlowMatchEulerDiscreteScheduler
|
| 44 |
+
import torch
|
| 45 |
+
import math
|
| 46 |
+
|
| 47 |
+
ckpt_id = "Qwen/Qwen-Image"
|
| 48 |
+
|
| 49 |
+
# From
|
| 50 |
+
# https://github.com/ModelTC/Qwen-Image-Lightning/blob/342260e8f5468d2f24d084ce04f55e101007118b/generate_with_diffusers.py#L82C9-L97C10
|
| 51 |
+
scheduler_config = {
|
| 52 |
+
"base_image_seq_len": 256,
|
| 53 |
+
"base_shift": math.log(3), # We use shift=3 in distillation
|
| 54 |
+
"invert_sigmas": False,
|
| 55 |
+
"max_image_seq_len": 8192,
|
| 56 |
+
"max_shift": math.log(3), # We use shift=3 in distillation
|
| 57 |
+
"num_train_timesteps": 1000,
|
| 58 |
+
"shift": 1.0,
|
| 59 |
+
"shift_terminal": None, # set shift_terminal to None
|
| 60 |
+
"stochastic_sampling": False,
|
| 61 |
+
"time_shift_type": "exponential",
|
| 62 |
+
"use_beta_sigmas": False,
|
| 63 |
+
"use_dynamic_shifting": True,
|
| 64 |
+
"use_exponential_sigmas": False,
|
| 65 |
+
"use_karras_sigmas": False,
|
| 66 |
+
}
|
| 67 |
+
scheduler = FlowMatchEulerDiscreteScheduler.from_config(scheduler_config)
|
| 68 |
+
pipe = DiffusionPipeline.from_pretrained(
|
| 69 |
+
ckpt_id, scheduler=scheduler, torch_dtype=torch.bfloat16
|
| 70 |
+
).to("cuda")
|
| 71 |
+
pipe.load_lora_weights(
|
| 72 |
+
"lightx2v/Qwen-Image-Lightning", weight_name="Qwen-Image-Lightning-8steps-V1.0.safetensors"
|
| 73 |
+
)
|
| 74 |
+
|
| 75 |
+
prompt = "a tiny astronaut hatching from an egg on the moon, Ultra HD, 4K, cinematic composition."
|
| 76 |
+
negative_prompt = " "
|
| 77 |
+
image = pipe(
|
| 78 |
+
prompt=prompt,
|
| 79 |
+
negative_prompt=negative_prompt,
|
| 80 |
+
width=1024,
|
| 81 |
+
height=1024,
|
| 82 |
+
num_inference_steps=8,
|
| 83 |
+
true_cfg_scale=1.0,
|
| 84 |
+
generator=torch.manual_seed(0),
|
| 85 |
+
).images[0]
|
| 86 |
+
image.save("qwen_fewsteps.png")
|
| 87 |
+
```
|
| 88 |
+
|
| 89 |
+
</details>
|
| 90 |
+
|
| 91 |
+
> [!TIP]
|
| 92 |
+
> The `guidance_scale` parameter in the pipeline is there to support future guidance-distilled models when they come up. Note that passing `guidance_scale` to the pipeline is ineffective. To enable classifier-free guidance, please pass `true_cfg_scale` and `negative_prompt` (even an empty negative prompt like " ") should enable classifier-free guidance computations.
|
| 93 |
+
|
| 94 |
+
## Multi-image reference with QwenImageEditPlusPipeline
|
| 95 |
+
|
| 96 |
+
With [`QwenImageEditPlusPipeline`], one can provide multiple images as input reference.
|
| 97 |
+
|
| 98 |
+
```
|
| 99 |
+
import torch
|
| 100 |
+
from PIL import Image
|
| 101 |
+
from diffusers import QwenImageEditPlusPipeline
|
| 102 |
+
from diffusers.utils import load_image
|
| 103 |
+
|
| 104 |
+
pipe = QwenImageEditPlusPipeline.from_pretrained(
|
| 105 |
+
"Qwen/Qwen-Image-Edit-2509", torch_dtype=torch.bfloat16
|
| 106 |
+
).to("cuda")
|
| 107 |
+
|
| 108 |
+
image_1 = load_image("https://huggingface.co/datasets/huggingface/documentation-images/resolve/main/diffusers/grumpy.jpg")
|
| 109 |
+
image_2 = load_image("https://huggingface.co/datasets/huggingface/documentation-images/resolve/main/diffusers/peng.png")
|
| 110 |
+
image = pipe(
|
| 111 |
+
image=[image_1, image_2],
|
| 112 |
+
prompt='''put the penguin and the cat at a game show called "Qwen Edit Plus Games"''',
|
| 113 |
+
num_inference_steps=50
|
| 114 |
+
).images[0]
|
| 115 |
+
```
|
| 116 |
+
|
| 117 |
+
## QwenImagePipeline
|
| 118 |
+
|
| 119 |
+
[[autodoc]] QwenImagePipeline
|
| 120 |
+
- all
|
| 121 |
+
- __call__
|
| 122 |
+
|
| 123 |
+
## QwenImageImg2ImgPipeline
|
| 124 |
+
|
| 125 |
+
[[autodoc]] QwenImageImg2ImgPipeline
|
| 126 |
+
- all
|
| 127 |
+
- __call__
|
| 128 |
+
|
| 129 |
+
## QwenImageInpaintPipeline
|
| 130 |
+
|
| 131 |
+
[[autodoc]] QwenImageInpaintPipeline
|
| 132 |
+
- all
|
| 133 |
+
- __call__
|
| 134 |
+
|
| 135 |
+
## QwenImageEditPipeline
|
| 136 |
+
|
| 137 |
+
[[autodoc]] QwenImageEditPipeline
|
| 138 |
+
- all
|
| 139 |
+
- __call__
|
| 140 |
+
|
| 141 |
+
## QwenImageEditInpaintPipeline
|
| 142 |
+
|
| 143 |
+
[[autodoc]] QwenImageEditInpaintPipeline
|
| 144 |
+
- all
|
| 145 |
+
- __call__
|
| 146 |
+
|
| 147 |
+
## QwenImageControlNetPipeline
|
| 148 |
+
|
| 149 |
+
[[autodoc]] QwenImageControlNetPipeline
|
| 150 |
+
- all
|
| 151 |
+
- __call__
|
| 152 |
+
|
| 153 |
+
## QwenImageEditPlusPipeline
|
| 154 |
+
|
| 155 |
+
[[autodoc]] QwenImageEditPlusPipeline
|
| 156 |
+
- all
|
| 157 |
+
- __call__
|
| 158 |
+
|
| 159 |
+
## QwenImagePipelineOutput
|
| 160 |
+
|
| 161 |
+
[[autodoc]] pipelines.qwenimage.pipeline_output.QwenImagePipelineOutput
|
tasks/tasksmith-1c5704b1f07f/tests/source/docs/source/en/api/pipelines/sana.md
ADDED
|
@@ -0,0 +1,106 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
<!-- Copyright 2025 The HuggingFace Team. All rights reserved.
|
| 2 |
+
#
|
| 3 |
+
# Licensed under the Apache License, Version 2.0 (the "License");
|
| 4 |
+
# you may not use this file except in compliance with the License.
|
| 5 |
+
# You may obtain a copy of the License at
|
| 6 |
+
#
|
| 7 |
+
# http://www.apache.org/licenses/LICENSE-2.0
|
| 8 |
+
#
|
| 9 |
+
# Unless required by applicable law or agreed to in writing, software
|
| 10 |
+
# distributed under the License is distributed on an "AS IS" BASIS,
|
| 11 |
+
# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
|
| 12 |
+
# See the License for the specific language governing permissions and
|
| 13 |
+
# limitations under the License. -->
|
| 14 |
+
|
| 15 |
+
# SanaPipeline
|
| 16 |
+
|
| 17 |
+
<div class="flex flex-wrap space-x-1">
|
| 18 |
+
<img alt="LoRA" src="https://img.shields.io/badge/LoRA-d8b4fe?style=flat"/>
|
| 19 |
+
<img alt="MPS" src="https://img.shields.io/badge/MPS-000000?style=flat&logo=apple&logoColor=white%22">
|
| 20 |
+
</div>
|
| 21 |
+
|
| 22 |
+
[SANA: Efficient High-Resolution Image Synthesis with Linear Diffusion Transformers](https://huggingface.co/papers/2410.10629) from NVIDIA and MIT HAN Lab, by Enze Xie, Junsong Chen, Junyu Chen, Han Cai, Haotian Tang, Yujun Lin, Zhekai Zhang, Muyang Li, Ligeng Zhu, Yao Lu, Song Han.
|
| 23 |
+
|
| 24 |
+
The abstract from the paper is:
|
| 25 |
+
|
| 26 |
+
*We introduce Sana, a text-to-image framework that can efficiently generate images up to 4096×4096 resolution. Sana can synthesize high-resolution, high-quality images with strong text-image alignment at a remarkably fast speed, deployable on laptop GPU. Core designs include: (1) Deep compression autoencoder: unlike traditional AEs, which compress images only 8×, we trained an AE that can compress images 32×, effectively reducing the number of latent tokens. (2) Linear DiT: we replace all vanilla attention in DiT with linear attention, which is more efficient at high resolutions without sacrificing quality. (3) Decoder-only text encoder: we replaced T5 with modern decoder-only small LLM as the text encoder and designed complex human instruction with in-context learning to enhance the image-text alignment. (4) Efficient training and sampling: we propose Flow-DPM-Solver to reduce sampling steps, with efficient caption labeling and selection to accelerate convergence. As a result, Sana-0.6B is very competitive with modern giant diffusion model (e.g. Flux-12B), being 20 times smaller and 100+ times faster in measured throughput. Moreover, Sana-0.6B can be deployed on a 16GB laptop GPU, taking less than 1 second to generate a 1024×1024 resolution image. Sana enables content creation at low cost. Code and model will be publicly released.*
|
| 27 |
+
|
| 28 |
+
> [!TIP]
|
| 29 |
+
> Make sure to check out the Schedulers [guide](../../using-diffusers/schedulers) to learn how to explore the tradeoff between scheduler speed and quality, and see the [reuse components across pipelines](../../using-diffusers/loading#reuse-a-pipeline) section to learn how to efficiently load the same components into multiple pipelines.
|
| 30 |
+
|
| 31 |
+
This pipeline was contributed by [lawrence-cj](https://github.com/lawrence-cj) and [chenjy2003](https://github.com/chenjy2003). The original codebase can be found [here](https://github.com/NVlabs/Sana). The original weights can be found under [hf.co/Efficient-Large-Model](https://huggingface.co/Efficient-Large-Model).
|
| 32 |
+
|
| 33 |
+
Available models:
|
| 34 |
+
|
| 35 |
+
| Model | Recommended dtype |
|
| 36 |
+
|:-----:|:-----------------:|
|
| 37 |
+
| [`Efficient-Large-Model/Sana_1600M_1024px_BF16_diffusers`](https://huggingface.co/Efficient-Large-Model/Sana_1600M_1024px_BF16_diffusers) | `torch.bfloat16` |
|
| 38 |
+
| [`Efficient-Large-Model/Sana_1600M_1024px_diffusers`](https://huggingface.co/Efficient-Large-Model/Sana_1600M_1024px_diffusers) | `torch.float16` |
|
| 39 |
+
| [`Efficient-Large-Model/Sana_1600M_1024px_MultiLing_diffusers`](https://huggingface.co/Efficient-Large-Model/Sana_1600M_1024px_MultiLing_diffusers) | `torch.float16` |
|
| 40 |
+
| [`Efficient-Large-Model/Sana_1600M_512px_diffusers`](https://huggingface.co/Efficient-Large-Model/Sana_1600M_512px_diffusers) | `torch.float16` |
|
| 41 |
+
| [`Efficient-Large-Model/Sana_1600M_512px_MultiLing_diffusers`](https://huggingface.co/Efficient-Large-Model/Sana_1600M_512px_MultiLing_diffusers) | `torch.float16` |
|
| 42 |
+
| [`Efficient-Large-Model/Sana_600M_1024px_diffusers`](https://huggingface.co/Efficient-Large-Model/Sana_600M_1024px_diffusers) | `torch.float16` |
|
| 43 |
+
| [`Efficient-Large-Model/Sana_600M_512px_diffusers`](https://huggingface.co/Efficient-Large-Model/Sana_600M_512px_diffusers) | `torch.float16` |
|
| 44 |
+
|
| 45 |
+
Refer to [this](https://huggingface.co/collections/Efficient-Large-Model/sana-673efba2a57ed99843f11f9e) collection for more information.
|
| 46 |
+
|
| 47 |
+
Note: The recommended dtype mentioned is for the transformer weights. The text encoder and VAE weights must stay in `torch.bfloat16` or `torch.float32` for the model to work correctly. Please refer to the inference example below to see how to load the model with the recommended dtype.
|
| 48 |
+
|
| 49 |
+
> [!TIP]
|
| 50 |
+
> Make sure to pass the `variant` argument for downloaded checkpoints to use lower disk space. Set it to `"fp16"` for models with recommended dtype as `torch.float16`, and `"bf16"` for models with recommended dtype as `torch.bfloat16`. By default, `torch.float32` weights are downloaded, which use twice the amount of disk storage. Additionally, `torch.float32` weights can be downcasted on-the-fly by specifying the `torch_dtype` argument. Read about it in the [docs](https://huggingface.co/docs/diffusers/v0.31.0/en/api/pipelines/overview#diffusers.DiffusionPipeline.from_pretrained).
|
| 51 |
+
|
| 52 |
+
## Quantization
|
| 53 |
+
|
| 54 |
+
Quantization helps reduce the memory requirements of very large models by storing model weights in a lower precision data type. However, quantization may have varying impact on video quality depending on the video model.
|
| 55 |
+
|
| 56 |
+
Refer to the [Quantization](../../quantization/overview) overview to learn more about supported quantization backends and selecting a quantization backend that supports your use case. The example below demonstrates how to load a quantized [`SanaPipeline`] for inference with bitsandbytes.
|
| 57 |
+
|
| 58 |
+
```py
|
| 59 |
+
import torch
|
| 60 |
+
from diffusers import BitsAndBytesConfig as DiffusersBitsAndBytesConfig, SanaTransformer2DModel, SanaPipeline
|
| 61 |
+
from transformers import BitsAndBytesConfig as BitsAndBytesConfig, AutoModel
|
| 62 |
+
|
| 63 |
+
quant_config = BitsAndBytesConfig(load_in_8bit=True)
|
| 64 |
+
text_encoder_8bit = AutoModel.from_pretrained(
|
| 65 |
+
"Efficient-Large-Model/Sana_1600M_1024px_diffusers",
|
| 66 |
+
subfolder="text_encoder",
|
| 67 |
+
quantization_config=quant_config,
|
| 68 |
+
torch_dtype=torch.float16,
|
| 69 |
+
)
|
| 70 |
+
|
| 71 |
+
quant_config = DiffusersBitsAndBytesConfig(load_in_8bit=True)
|
| 72 |
+
transformer_8bit = SanaTransformer2DModel.from_pretrained(
|
| 73 |
+
"Efficient-Large-Model/Sana_1600M_1024px_diffusers",
|
| 74 |
+
subfolder="transformer",
|
| 75 |
+
quantization_config=quant_config,
|
| 76 |
+
torch_dtype=torch.float16,
|
| 77 |
+
)
|
| 78 |
+
|
| 79 |
+
pipeline = SanaPipeline.from_pretrained(
|
| 80 |
+
"Efficient-Large-Model/Sana_1600M_1024px_diffusers",
|
| 81 |
+
text_encoder=text_encoder_8bit,
|
| 82 |
+
transformer=transformer_8bit,
|
| 83 |
+
torch_dtype=torch.float16,
|
| 84 |
+
device_map="balanced",
|
| 85 |
+
)
|
| 86 |
+
|
| 87 |
+
prompt = "a tiny astronaut hatching from an egg on the moon"
|
| 88 |
+
image = pipeline(prompt).images[0]
|
| 89 |
+
image.save("sana.png")
|
| 90 |
+
```
|
| 91 |
+
|
| 92 |
+
## SanaPipeline
|
| 93 |
+
|
| 94 |
+
[[autodoc]] SanaPipeline
|
| 95 |
+
- all
|
| 96 |
+
- __call__
|
| 97 |
+
|
| 98 |
+
## SanaPAGPipeline
|
| 99 |
+
|
| 100 |
+
[[autodoc]] SanaPAGPipeline
|
| 101 |
+
- all
|
| 102 |
+
- __call__
|
| 103 |
+
|
| 104 |
+
## SanaPipelineOutput
|
| 105 |
+
|
| 106 |
+
[[autodoc]] pipelines.sana.pipeline_output.SanaPipelineOutput
|
tasks/tasksmith-1c5704b1f07f/tests/source/docs/source/en/api/pipelines/sana_sprint.md
ADDED
|
@@ -0,0 +1,128 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
<!-- Copyright 2025 The HuggingFace Team. All rights reserved.
|
| 2 |
+
#
|
| 3 |
+
# Licensed under the Apache License, Version 2.0 (the "License");
|
| 4 |
+
# you may not use this file except in compliance with the License.
|
| 5 |
+
# You may obtain a copy of the License at
|
| 6 |
+
#
|
| 7 |
+
# http://www.apache.org/licenses/LICENSE-2.0
|
| 8 |
+
#
|
| 9 |
+
# Unless required by applicable law or agreed to in writing, software
|
| 10 |
+
# distributed under the License is distributed on an "AS IS" BASIS,
|
| 11 |
+
# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
|
| 12 |
+
# See the License for the specific language governing permissions and
|
| 13 |
+
# limitations under the License. -->
|
| 14 |
+
|
| 15 |
+
# SANA-Sprint
|
| 16 |
+
|
| 17 |
+
<div class="flex flex-wrap space-x-1">
|
| 18 |
+
<img alt="LoRA" src="https://img.shields.io/badge/LoRA-d8b4fe?style=flat"/>
|
| 19 |
+
</div>
|
| 20 |
+
|
| 21 |
+
[SANA-Sprint: One-Step Diffusion with Continuous-Time Consistency Distillation](https://huggingface.co/papers/2503.09641) from NVIDIA, MIT HAN Lab, and Hugging Face by Junsong Chen, Shuchen Xue, Yuyang Zhao, Jincheng Yu, Sayak Paul, Junyu Chen, Han Cai, Enze Xie, Song Han
|
| 22 |
+
|
| 23 |
+
The abstract from the paper is:
|
| 24 |
+
|
| 25 |
+
*This paper presents SANA-Sprint, an efficient diffusion model for ultra-fast text-to-image (T2I) generation. SANA-Sprint is built on a pre-trained foundation model and augmented with hybrid distillation, dramatically reducing inference steps from 20 to 1-4. We introduce three key innovations: (1) We propose a training-free approach that transforms a pre-trained flow-matching model for continuous-time consistency distillation (sCM), eliminating costly training from scratch and achieving high training efficiency. Our hybrid distillation strategy combines sCM with latent adversarial distillation (LADD): sCM ensures alignment with the teacher model, while LADD enhances single-step generation fidelity. (2) SANA-Sprint is a unified step-adaptive model that achieves high-quality generation in 1-4 steps, eliminating step-specific training and improving efficiency. (3) We integrate ControlNet with SANA-Sprint for real-time interactive image generation, enabling instant visual feedback for user interaction. SANA-Sprint establishes a new Pareto frontier in speed-quality tradeoffs, achieving state-of-the-art performance with 7.59 FID and 0.74 GenEval in only 1 step — outperforming FLUX-schnell (7.94 FID / 0.71 GenEval) while being 10× faster (0.1s vs 1.1s on H100). It also achieves 0.1s (T2I) and 0.25s (ControlNet) latency for 1024×1024 images on H100, and 0.31s (T2I) on an RTX 4090, showcasing its exceptional efficiency and potential for AI-powered consumer applications (AIPC). Code and pre-trained models will be open-sourced.*
|
| 26 |
+
|
| 27 |
+
This pipeline was contributed by [lawrence-cj](https://github.com/lawrence-cj), [shuchen Xue](https://github.com/scxue) and [Enze Xie](https://github.com/xieenze). The original codebase can be found [here](https://github.com/NVlabs/Sana). The original weights can be found under [hf.co/Efficient-Large-Model](https://huggingface.co/Efficient-Large-Model/).
|
| 28 |
+
|
| 29 |
+
Available models:
|
| 30 |
+
|
| 31 |
+
| Model | Recommended dtype |
|
| 32 |
+
|:-------------------------------------------------------------------------------------------------------------------------------------------:|:-----------------:|
|
| 33 |
+
| [`Efficient-Large-Model/Sana_Sprint_1.6B_1024px_diffusers`](https://huggingface.co/Efficient-Large-Model/Sana_Sprint_1.6B_1024px_diffusers) | `torch.bfloat16` |
|
| 34 |
+
| [`Efficient-Large-Model/Sana_Sprint_0.6B_1024px_diffusers`](https://huggingface.co/Efficient-Large-Model/Sana_Sprint_0.6B_1024px_diffusers) | `torch.bfloat16` |
|
| 35 |
+
|
| 36 |
+
Refer to [this](https://huggingface.co/collections/Efficient-Large-Model/sana-sprint-67d6810d65235085b3b17c76) collection for more information.
|
| 37 |
+
|
| 38 |
+
Note: The recommended dtype mentioned is for the transformer weights. The text encoder must stay in `torch.bfloat16` and VAE weights must stay in `torch.bfloat16` or `torch.float32` for the model to work correctly. Please refer to the inference example below to see how to load the model with the recommended dtype.
|
| 39 |
+
|
| 40 |
+
|
| 41 |
+
## Quantization
|
| 42 |
+
|
| 43 |
+
Quantization helps reduce the memory requirements of very large models by storing model weights in a lower precision data type. However, quantization may have varying impact on video quality depending on the video model.
|
| 44 |
+
|
| 45 |
+
Refer to the [Quantization](../../quantization/overview) overview to learn more about supported quantization backends and selecting a quantization backend that supports your use case. The example below demonstrates how to load a quantized [`SanaSprintPipeline`] for inference with bitsandbytes.
|
| 46 |
+
|
| 47 |
+
```py
|
| 48 |
+
import torch
|
| 49 |
+
from diffusers import BitsAndBytesConfig as DiffusersBitsAndBytesConfig, SanaTransformer2DModel, SanaSprintPipeline
|
| 50 |
+
from transformers import BitsAndBytesConfig as BitsAndBytesConfig, AutoModel
|
| 51 |
+
|
| 52 |
+
quant_config = BitsAndBytesConfig(load_in_8bit=True)
|
| 53 |
+
text_encoder_8bit = AutoModel.from_pretrained(
|
| 54 |
+
"Efficient-Large-Model/Sana_Sprint_1.6B_1024px_diffusers",
|
| 55 |
+
subfolder="text_encoder",
|
| 56 |
+
quantization_config=quant_config,
|
| 57 |
+
torch_dtype=torch.bfloat16,
|
| 58 |
+
)
|
| 59 |
+
|
| 60 |
+
quant_config = DiffusersBitsAndBytesConfig(load_in_8bit=True)
|
| 61 |
+
transformer_8bit = SanaTransformer2DModel.from_pretrained(
|
| 62 |
+
"Efficient-Large-Model/Sana_Sprint_1.6B_1024px_diffusers",
|
| 63 |
+
subfolder="transformer",
|
| 64 |
+
quantization_config=quant_config,
|
| 65 |
+
torch_dtype=torch.bfloat16,
|
| 66 |
+
)
|
| 67 |
+
|
| 68 |
+
pipeline = SanaSprintPipeline.from_pretrained(
|
| 69 |
+
"Efficient-Large-Model/Sana_Sprint_1.6B_1024px_diffusers",
|
| 70 |
+
text_encoder=text_encoder_8bit,
|
| 71 |
+
transformer=transformer_8bit,
|
| 72 |
+
torch_dtype=torch.bfloat16,
|
| 73 |
+
device_map="balanced",
|
| 74 |
+
)
|
| 75 |
+
|
| 76 |
+
prompt = "a tiny astronaut hatching from an egg on the moon"
|
| 77 |
+
image = pipeline(prompt).images[0]
|
| 78 |
+
image.save("sana.png")
|
| 79 |
+
```
|
| 80 |
+
|
| 81 |
+
## Setting `max_timesteps`
|
| 82 |
+
|
| 83 |
+
Users can tweak the `max_timesteps` value for experimenting with the visual quality of the generated outputs. The default `max_timesteps` value was obtained with an inference-time search process. For more details about it, check out the paper.
|
| 84 |
+
|
| 85 |
+
## Image to Image
|
| 86 |
+
|
| 87 |
+
The [`SanaSprintImg2ImgPipeline`] is a pipeline for image-to-image generation. It takes an input image and a prompt, and generates a new image based on the input image and the prompt.
|
| 88 |
+
|
| 89 |
+
```py
|
| 90 |
+
import torch
|
| 91 |
+
from diffusers import SanaSprintImg2ImgPipeline
|
| 92 |
+
from diffusers.utils.loading_utils import load_image
|
| 93 |
+
|
| 94 |
+
image = load_image(
|
| 95 |
+
"https://huggingface.co/datasets/huggingface/documentation-images/resolve/main/diffusers/penguin.png"
|
| 96 |
+
)
|
| 97 |
+
|
| 98 |
+
pipe = SanaSprintImg2ImgPipeline.from_pretrained(
|
| 99 |
+
"Efficient-Large-Model/Sana_Sprint_1.6B_1024px_diffusers",
|
| 100 |
+
torch_dtype=torch.bfloat16)
|
| 101 |
+
pipe.to("cuda")
|
| 102 |
+
|
| 103 |
+
image = pipe(
|
| 104 |
+
prompt="a cute pink bear",
|
| 105 |
+
image=image,
|
| 106 |
+
strength=0.5,
|
| 107 |
+
height=832,
|
| 108 |
+
width=480
|
| 109 |
+
).images[0]
|
| 110 |
+
image.save("output.png")
|
| 111 |
+
```
|
| 112 |
+
|
| 113 |
+
## SanaSprintPipeline
|
| 114 |
+
|
| 115 |
+
[[autodoc]] SanaSprintPipeline
|
| 116 |
+
- all
|
| 117 |
+
- __call__
|
| 118 |
+
|
| 119 |
+
## SanaSprintImg2ImgPipeline
|
| 120 |
+
|
| 121 |
+
[[autodoc]] SanaSprintImg2ImgPipeline
|
| 122 |
+
- all
|
| 123 |
+
- __call__
|
| 124 |
+
|
| 125 |
+
|
| 126 |
+
## SanaPipelineOutput
|
| 127 |
+
|
| 128 |
+
[[autodoc]] pipelines.sana.pipeline_output.SanaPipelineOutput
|
tasks/tasksmith-1c5704b1f07f/tests/source/docs/source/en/api/pipelines/sana_video.md
ADDED
|
@@ -0,0 +1,189 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
<!-- Copyright 2025 The SANA-Video Authors and HuggingFace Team. All rights reserved.
|
| 2 |
+
#
|
| 3 |
+
# Licensed under the Apache License, Version 2.0 (the "License");
|
| 4 |
+
# you may not use this file except in compliance with the License.
|
| 5 |
+
# You may obtain a copy of the License at
|
| 6 |
+
#
|
| 7 |
+
# http://www.apache.org/licenses/LICENSE-2.0
|
| 8 |
+
#
|
| 9 |
+
# Unless required by applicable law or agreed to in writing, software
|
| 10 |
+
# distributed under the License is distributed on an "AS IS" BASIS,
|
| 11 |
+
# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
|
| 12 |
+
# See the License for the specific language governing permissions and
|
| 13 |
+
# limitations under the License. -->
|
| 14 |
+
|
| 15 |
+
# Sana-Video
|
| 16 |
+
|
| 17 |
+
<div class="flex flex-wrap space-x-1">
|
| 18 |
+
<img alt="LoRA" src="https://img.shields.io/badge/LoRA-d8b4fe?style=flat"/>
|
| 19 |
+
<img alt="MPS" src="https://img.shields.io/badge/MPS-000000?style=flat&logo=apple&logoColor=white%22">
|
| 20 |
+
</div>
|
| 21 |
+
|
| 22 |
+
[SANA-Video: Efficient Video Generation with Block Linear Diffusion Transformer](https://huggingface.co/papers/2509.24695) from NVIDIA and MIT HAN Lab, by Junsong Chen, Yuyang Zhao, Jincheng Yu, Ruihang Chu, Junyu Chen, Shuai Yang, Xianbang Wang, Yicheng Pan, Daquan Zhou, Huan Ling, Haozhe Liu, Hongwei Yi, Hao Zhang, Muyang Li, Yukang Chen, Han Cai, Sanja Fidler, Ping Luo, Song Han, Enze Xie.
|
| 23 |
+
|
| 24 |
+
The abstract from the paper is:
|
| 25 |
+
|
| 26 |
+
*We introduce SANA-Video, a small diffusion model that can efficiently generate videos up to 720x1280 resolution and minute-length duration. SANA-Video synthesizes high-resolution, high-quality and long videos with strong text-video alignment at a remarkably fast speed, deployable on RTX 5090 GPU. Two core designs ensure our efficient, effective and long video generation: (1) Linear DiT: We leverage linear attention as the core operation, which is more efficient than vanilla attention given the large number of tokens processed in video generation. (2) Constant-Memory KV cache for Block Linear Attention: we design block-wise autoregressive approach for long video generation by employing a constant-memory state, derived from the cumulative properties of linear attention. This KV cache provides the Linear DiT with global context at a fixed memory cost, eliminating the need for a traditional KV cache and enabling efficient, minute-long video generation. In addition, we explore effective data filters and model training strategies, narrowing the training cost to 12 days on 64 H100 GPUs, which is only 1% of the cost of MovieGen. Given its low cost, SANA-Video achieves competitive performance compared to modern state-of-the-art small diffusion models (e.g., Wan 2.1-1.3B and SkyReel-V2-1.3B) while being 16x faster in measured latency. Moreover, SANA-Video can be deployed on RTX 5090 GPUs with NVFP4 precision, accelerating the inference speed of generating a 5-second 720p video from 71s to 29s (2.4x speedup). In summary, SANA-Video enables low-cost, high-quality video generation. [this https URL](https://github.com/NVlabs/SANA).*
|
| 27 |
+
|
| 28 |
+
This pipeline was contributed by SANA Team. The original codebase can be found [here](https://github.com/NVlabs/Sana). The original weights can be found under [hf.co/Efficient-Large-Model](https://hf.co/collections/Efficient-Large-Model/sana-video).
|
| 29 |
+
|
| 30 |
+
Available models:
|
| 31 |
+
|
| 32 |
+
| Model | Recommended dtype |
|
| 33 |
+
|:-----:|:-----------------:|
|
| 34 |
+
| [`Efficient-Large-Model/SANA-Video_2B_480p_diffusers`](https://huggingface.co/Efficient-Large-Model/ANA-Video_2B_480p_diffusers) | `torch.bfloat16` |
|
| 35 |
+
|
| 36 |
+
Refer to [this](https://huggingface.co/collections/Efficient-Large-Model/sana-video) collection for more information.
|
| 37 |
+
|
| 38 |
+
Note: The recommended dtype mentioned is for the transformer weights. The text encoder and VAE weights must stay in `torch.bfloat16` or `torch.float32` for the model to work correctly. Please refer to the inference example below to see how to load the model with the recommended dtype.
|
| 39 |
+
|
| 40 |
+
|
| 41 |
+
## Generation Pipelines
|
| 42 |
+
|
| 43 |
+
<hfoptions id="generation pipelines">`
|
| 44 |
+
<hfoption id="Text-to-Video">
|
| 45 |
+
|
| 46 |
+
The example below demonstrates how to use the text-to-video pipeline to generate a video using a text description.
|
| 47 |
+
|
| 48 |
+
```python
|
| 49 |
+
pipe = SanaVideoPipeline.from_pretrained(
|
| 50 |
+
"Efficient-Large-Model/SANA-Video_2B_480p_diffusers",
|
| 51 |
+
torch_dtype=torch.bfloat16,
|
| 52 |
+
)
|
| 53 |
+
pipe.text_encoder.to(torch.bfloat16)
|
| 54 |
+
pipe.vae.to(torch.float32)
|
| 55 |
+
pipe.to("cuda")
|
| 56 |
+
|
| 57 |
+
prompt = "A cat and a dog baking a cake together in a kitchen. The cat is carefully measuring flour, while the dog is stirring the batter with a wooden spoon. The kitchen is cozy, with sunlight streaming through the window."
|
| 58 |
+
negative_prompt = "A chaotic sequence with misshapen, deformed limbs in heavy motion blur, sudden disappearance, jump cuts, jerky movements, rapid shot changes, frames out of sync, inconsistent character shapes, temporal artifacts, jitter, and ghosting effects, creating a disorienting visual experience."
|
| 59 |
+
motion_scale = 30
|
| 60 |
+
motion_prompt = f" motion score: {motion_scale}."
|
| 61 |
+
prompt = prompt + motion_prompt
|
| 62 |
+
|
| 63 |
+
video = pipe(
|
| 64 |
+
prompt=prompt,
|
| 65 |
+
negative_prompt=negative_prompt,
|
| 66 |
+
height=480,
|
| 67 |
+
width=832,
|
| 68 |
+
frames=81,
|
| 69 |
+
guidance_scale=6,
|
| 70 |
+
num_inference_steps=50,
|
| 71 |
+
generator=torch.Generator(device="cuda").manual_seed(0),
|
| 72 |
+
).frames[0]
|
| 73 |
+
|
| 74 |
+
export_to_video(video, "sana_video.mp4", fps=16)
|
| 75 |
+
```
|
| 76 |
+
|
| 77 |
+
</hfoption>
|
| 78 |
+
<hfoption id="Image-to-Video">
|
| 79 |
+
|
| 80 |
+
The example below demonstrates how to use the image-to-video pipeline to generate a video using a text description and a starting frame.
|
| 81 |
+
|
| 82 |
+
```python
|
| 83 |
+
pipe = SanaImageToVideoPipeline.from_pretrained(
|
| 84 |
+
"Efficient-Large-Model/SANA-Video_2B_480p_diffusers",
|
| 85 |
+
torch_dtype=torch.bfloat16,
|
| 86 |
+
)
|
| 87 |
+
pipe.scheduler = FlowMatchEulerDiscreteScheduler.from_config(pipe.scheduler.config, flow_shift=8.0)
|
| 88 |
+
pipe.vae.to(torch.float32)
|
| 89 |
+
pipe.text_encoder.to(torch.bfloat16)
|
| 90 |
+
pipe.to("cuda")
|
| 91 |
+
|
| 92 |
+
image = load_image("https://raw.githubusercontent.com/NVlabs/Sana/refs/heads/main/asset/samples/i2v-1.png")
|
| 93 |
+
prompt = "A woman stands against a stunning sunset backdrop, her long, wavy brown hair gently blowing in the breeze. She wears a sleeveless, light-colored blouse with a deep V-neckline, which accentuates her graceful posture. The warm hues of the setting sun cast a golden glow across her face and hair, creating a serene and ethereal atmosphere. The background features a blurred landscape with soft, rolling hills and scattered clouds, adding depth to the scene. The camera remains steady, capturing the tranquil moment from a medium close-up angle."
|
| 94 |
+
negative_prompt = "A chaotic sequence with misshapen, deformed limbs in heavy motion blur, sudden disappearance, jump cuts, jerky movements, rapid shot changes, frames out of sync, inconsistent character shapes, temporal artifacts, jitter, and ghosting effects, creating a disorienting visual experience."
|
| 95 |
+
motion_scale = 30
|
| 96 |
+
motion_prompt = f" motion score: {motion_scale}."
|
| 97 |
+
prompt = prompt + motion_prompt
|
| 98 |
+
|
| 99 |
+
motion_scale = 30.0
|
| 100 |
+
|
| 101 |
+
video = pipe(
|
| 102 |
+
image=image,
|
| 103 |
+
prompt=prompt,
|
| 104 |
+
negative_prompt=negative_prompt,
|
| 105 |
+
height=480,
|
| 106 |
+
width=832,
|
| 107 |
+
frames=81,
|
| 108 |
+
guidance_scale=6,
|
| 109 |
+
num_inference_steps=50,
|
| 110 |
+
generator=torch.Generator(device="cuda").manual_seed(0),
|
| 111 |
+
).frames[0]
|
| 112 |
+
|
| 113 |
+
export_to_video(video, "sana-i2v.mp4", fps=16)
|
| 114 |
+
```
|
| 115 |
+
|
| 116 |
+
</hfoption>
|
| 117 |
+
</hfoptions>
|
| 118 |
+
|
| 119 |
+
|
| 120 |
+
## Quantization
|
| 121 |
+
|
| 122 |
+
Quantization helps reduce the memory requirements of very large models by storing model weights in a lower precision data type. However, quantization may have varying impact on video quality depending on the video model.
|
| 123 |
+
|
| 124 |
+
Refer to the [Quantization](../../quantization/overview) overview to learn more about supported quantization backends and selecting a quantization backend that supports your use case. The example below demonstrates how to load a quantized [`SanaVideoPipeline`] for inference with bitsandbytes.
|
| 125 |
+
|
| 126 |
+
```py
|
| 127 |
+
import torch
|
| 128 |
+
from diffusers import BitsAndBytesConfig as DiffusersBitsAndBytesConfig, SanaVideoTransformer3DModel, SanaVideoPipeline
|
| 129 |
+
from transformers import BitsAndBytesConfig as BitsAndBytesConfig, AutoModel
|
| 130 |
+
|
| 131 |
+
quant_config = BitsAndBytesConfig(load_in_8bit=True)
|
| 132 |
+
text_encoder_8bit = AutoModel.from_pretrained(
|
| 133 |
+
"Efficient-Large-Model/SANA-Video_2B_480p_diffusers",
|
| 134 |
+
subfolder="text_encoder",
|
| 135 |
+
quantization_config=quant_config,
|
| 136 |
+
torch_dtype=torch.float16,
|
| 137 |
+
)
|
| 138 |
+
|
| 139 |
+
quant_config = DiffusersBitsAndBytesConfig(load_in_8bit=True)
|
| 140 |
+
transformer_8bit = SanaVideoTransformer3DModel.from_pretrained(
|
| 141 |
+
"Efficient-Large-Model/SANA-Video_2B_480p_diffusers",
|
| 142 |
+
subfolder="transformer",
|
| 143 |
+
quantization_config=quant_config,
|
| 144 |
+
torch_dtype=torch.float16,
|
| 145 |
+
)
|
| 146 |
+
|
| 147 |
+
pipeline = SanaVideoPipeline.from_pretrained(
|
| 148 |
+
"Efficient-Large-Model/SANA-Video_2B_480p_diffusers",
|
| 149 |
+
text_encoder=text_encoder_8bit,
|
| 150 |
+
transformer=transformer_8bit,
|
| 151 |
+
torch_dtype=torch.float16,
|
| 152 |
+
device_map="balanced",
|
| 153 |
+
)
|
| 154 |
+
|
| 155 |
+
model_score = 30
|
| 156 |
+
prompt = "Evening, backlight, side lighting, soft light, high contrast, mid-shot, centered composition, clean solo shot, warm color. A young Caucasian man stands in a forest, golden light glimmers on his hair as sunlight filters through the leaves. He wears a light shirt, wind gently blowing his hair and collar, light dances across his face with his movements. The background is blurred, with dappled light and soft tree shadows in the distance. The camera focuses on his lifted gaze, clear and emotional."
|
| 157 |
+
negative_prompt = "A chaotic sequence with misshapen, deformed limbs in heavy motion blur, sudden disappearance, jump cuts, jerky movements, rapid shot changes, frames out of sync, inconsistent character shapes, temporal artifacts, jitter, and ghosting effects, creating a disorienting visual experience."
|
| 158 |
+
motion_prompt = f" motion score: {model_score}."
|
| 159 |
+
prompt = prompt + motion_prompt
|
| 160 |
+
|
| 161 |
+
output = pipeline(
|
| 162 |
+
prompt=prompt,
|
| 163 |
+
negative_prompt=negative_prompt,
|
| 164 |
+
height=480,
|
| 165 |
+
width=832,
|
| 166 |
+
num_frames=81,
|
| 167 |
+
guidance_scale=6.0,
|
| 168 |
+
num_inference_steps=50
|
| 169 |
+
).frames[0]
|
| 170 |
+
export_to_video(output, "sana-video-output.mp4", fps=16)
|
| 171 |
+
```
|
| 172 |
+
|
| 173 |
+
## SanaVideoPipeline
|
| 174 |
+
|
| 175 |
+
[[autodoc]] SanaVideoPipeline
|
| 176 |
+
- all
|
| 177 |
+
- __call__
|
| 178 |
+
|
| 179 |
+
|
| 180 |
+
## SanaImageToVideoPipeline
|
| 181 |
+
|
| 182 |
+
[[autodoc]] SanaImageToVideoPipeline
|
| 183 |
+
- all
|
| 184 |
+
- __call__
|
| 185 |
+
|
| 186 |
+
|
| 187 |
+
## SanaVideoPipelineOutput
|
| 188 |
+
|
| 189 |
+
[[autodoc]] pipelines.sana_video.pipeline_sana_video.SanaVideoPipelineOutput
|
tasks/tasksmith-1c5704b1f07f/tests/source/docs/source/en/api/pipelines/self_attention_guidance.md
ADDED
|
@@ -0,0 +1,35 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
<!--Copyright 2025 The HuggingFace Team. All rights reserved.
|
| 2 |
+
|
| 3 |
+
Licensed under the Apache License, Version 2.0 (the "License"); you may not use this file except in compliance with
|
| 4 |
+
the License. You may obtain a copy of the License at
|
| 5 |
+
|
| 6 |
+
http://www.apache.org/licenses/LICENSE-2.0
|
| 7 |
+
|
| 8 |
+
Unless required by applicable law or agreed to in writing, software distributed under the License is distributed on
|
| 9 |
+
an "AS IS" BASIS, WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied. See the License for the
|
| 10 |
+
specific language governing permissions and limitations under the License.
|
| 11 |
+
-->
|
| 12 |
+
|
| 13 |
+
> [!WARNING]
|
| 14 |
+
> This pipeline is deprecated but it can still be used. However, we won't test the pipeline anymore and won't accept any changes to it. If you run into any issues, reinstall the last Diffusers version that supported this model.
|
| 15 |
+
|
| 16 |
+
# Self-Attention Guidance
|
| 17 |
+
|
| 18 |
+
[Improving Sample Quality of Diffusion Models Using Self-Attention Guidance](https://huggingface.co/papers/2210.00939) is by Susung Hong et al.
|
| 19 |
+
|
| 20 |
+
The abstract from the paper is:
|
| 21 |
+
|
| 22 |
+
*Denoising diffusion models (DDMs) have attracted attention for their exceptional generation quality and diversity. This success is largely attributed to the use of class- or text-conditional diffusion guidance methods, such as classifier and classifier-free guidance. In this paper, we present a more comprehensive perspective that goes beyond the traditional guidance methods. From this generalized perspective, we introduce novel condition- and training-free strategies to enhance the quality of generated images. As a simple solution, blur guidance improves the suitability of intermediate samples for their fine-scale information and structures, enabling diffusion models to generate higher quality samples with a moderate guidance scale. Improving upon this, Self-Attention Guidance (SAG) uses the intermediate self-attention maps of diffusion models to enhance their stability and efficacy. Specifically, SAG adversarially blurs only the regions that diffusion models attend to at each iteration and guides them accordingly. Our experimental results show that our SAG improves the performance of various diffusion models, including ADM, IDDPM, Stable Diffusion, and DiT. Moreover, combining SAG with conventional guidance methods leads to further improvement.*
|
| 23 |
+
|
| 24 |
+
You can find additional information about Self-Attention Guidance on the [project page](https://ku-cvlab.github.io/Self-Attention-Guidance), [original codebase](https://github.com/KU-CVLAB/Self-Attention-Guidance), and try it out in a [demo](https://huggingface.co/spaces/susunghong/Self-Attention-Guidance) or [notebook](https://colab.research.google.com/github/SusungHong/Self-Attention-Guidance/blob/main/SAG_Stable.ipynb).
|
| 25 |
+
|
| 26 |
+
> [!TIP]
|
| 27 |
+
> Make sure to check out the Schedulers [guide](../../using-diffusers/schedulers) to learn how to explore the tradeoff between scheduler speed and quality, and see the [reuse components across pipelines](../../using-diffusers/loading#reuse-a-pipeline) section to learn how to efficiently load the same components into multiple pipelines.
|
| 28 |
+
|
| 29 |
+
## StableDiffusionSAGPipeline
|
| 30 |
+
[[autodoc]] StableDiffusionSAGPipeline
|
| 31 |
+
- __call__
|
| 32 |
+
- all
|
| 33 |
+
|
| 34 |
+
## StableDiffusionOutput
|
| 35 |
+
[[autodoc]] pipelines.stable_diffusion.StableDiffusionPipelineOutput
|
tasks/tasksmith-1c5704b1f07f/tests/source/docs/source/en/api/pipelines/semantic_stable_diffusion.md
ADDED
|
@@ -0,0 +1,35 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
<!--Copyright 2025 The HuggingFace Team. All rights reserved.
|
| 2 |
+
|
| 3 |
+
Licensed under the Apache License, Version 2.0 (the "License"); you may not use this file except in compliance with
|
| 4 |
+
the License. You may obtain a copy of the License at
|
| 5 |
+
|
| 6 |
+
http://www.apache.org/licenses/LICENSE-2.0
|
| 7 |
+
|
| 8 |
+
Unless required by applicable law or agreed to in writing, software distributed under the License is distributed on
|
| 9 |
+
an "AS IS" BASIS, WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied. See the License for the
|
| 10 |
+
specific language governing permissions and limitations under the License.
|
| 11 |
+
-->
|
| 12 |
+
|
| 13 |
+
> [!WARNING]
|
| 14 |
+
> This pipeline is deprecated but it can still be used. However, we won't test the pipeline anymore and won't accept any changes to it. If you run into any issues, reinstall the last Diffusers version that supported this model.
|
| 15 |
+
|
| 16 |
+
# Semantic Guidance
|
| 17 |
+
|
| 18 |
+
Semantic Guidance for Diffusion Models was proposed in [SEGA: Instructing Text-to-Image Models using Semantic Guidance](https://huggingface.co/papers/2301.12247) and provides strong semantic control over image generation.
|
| 19 |
+
Small changes to the text prompt usually result in entirely different output images. However, with SEGA a variety of changes to the image are enabled that can be controlled easily and intuitively, while staying true to the original image composition.
|
| 20 |
+
|
| 21 |
+
The abstract from the paper is:
|
| 22 |
+
|
| 23 |
+
*Text-to-image diffusion models have recently received a lot of interest for their astonishing ability to produce high-fidelity images from text only. However, achieving one-shot generation that aligns with the user's intent is nearly impossible, yet small changes to the input prompt often result in very different images. This leaves the user with little semantic control. To put the user in control, we show how to interact with the diffusion process to flexibly steer it along semantic directions. This semantic guidance (SEGA) generalizes to any generative architecture using classifier-free guidance. More importantly, it allows for subtle and extensive edits, changes in composition and style, as well as optimizing the overall artistic conception. We demonstrate SEGA's effectiveness on both latent and pixel-based diffusion models such as Stable Diffusion, Paella, and DeepFloyd-IF using a variety of tasks, thus providing strong evidence for its versatility, flexibility, and improvements over existing methods.*
|
| 24 |
+
|
| 25 |
+
> [!TIP]
|
| 26 |
+
> Make sure to check out the Schedulers [guide](../../using-diffusers/schedulers) to learn how to explore the tradeoff between scheduler speed and quality, and see the [reuse components across pipelines](../../using-diffusers/loading#reuse-a-pipeline) section to learn how to efficiently load the same components into multiple pipelines.
|
| 27 |
+
|
| 28 |
+
## SemanticStableDiffusionPipeline
|
| 29 |
+
[[autodoc]] SemanticStableDiffusionPipeline
|
| 30 |
+
- all
|
| 31 |
+
- __call__
|
| 32 |
+
|
| 33 |
+
## SemanticStableDiffusionPipelineOutput
|
| 34 |
+
[[autodoc]] pipelines.semantic_stable_diffusion.pipeline_output.SemanticStableDiffusionPipelineOutput
|
| 35 |
+
- all
|
tasks/tasksmith-1c5704b1f07f/tests/source/docs/source/en/api/pipelines/shap_e.md
ADDED
|
@@ -0,0 +1,34 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
<!--Copyright 2025 The HuggingFace Team. All rights reserved.
|
| 2 |
+
Licensed under the Apache License, Version 2.0 (the "License"); you may not use this file except in compliance with
|
| 3 |
+
the License. You may obtain a copy of the License at
|
| 4 |
+
http://www.apache.org/licenses/LICENSE-2.0
|
| 5 |
+
Unless required by applicable law or agreed to in writing, software distributed under the License is distributed on
|
| 6 |
+
an "AS IS" BASIS, WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied. See the License for the
|
| 7 |
+
specific language governing permissions and limitations under the License.
|
| 8 |
+
-->
|
| 9 |
+
|
| 10 |
+
# Shap-E
|
| 11 |
+
|
| 12 |
+
The Shap-E model was proposed in [Shap-E: Generating Conditional 3D Implicit Functions](https://huggingface.co/papers/2305.02463) by Alex Nichol and Heewoo Jun from [OpenAI](https://github.com/openai).
|
| 13 |
+
|
| 14 |
+
The abstract from the paper is:
|
| 15 |
+
|
| 16 |
+
*We present Shap-E, a conditional generative model for 3D assets. Unlike recent work on 3D generative models which produce a single output representation, Shap-E directly generates the parameters of implicit functions that can be rendered as both textured meshes and neural radiance fields. We train Shap-E in two stages: first, we train an encoder that deterministically maps 3D assets into the parameters of an implicit function; second, we train a conditional diffusion model on outputs of the encoder. When trained on a large dataset of paired 3D and text data, our resulting models are capable of generating complex and diverse 3D assets in a matter of seconds. When compared to Point-E, an explicit generative model over point clouds, Shap-E converges faster and reaches comparable or better sample quality despite modeling a higher-dimensional, multi-representation output space.*
|
| 17 |
+
|
| 18 |
+
The original codebase can be found at [openai/shap-e](https://github.com/openai/shap-e).
|
| 19 |
+
|
| 20 |
+
> [!TIP]
|
| 21 |
+
> See the [reuse components across pipelines](../../using-diffusers/loading#reuse-a-pipeline) section to learn how to efficiently load the same components into multiple pipelines.
|
| 22 |
+
|
| 23 |
+
## ShapEPipeline
|
| 24 |
+
[[autodoc]] ShapEPipeline
|
| 25 |
+
- all
|
| 26 |
+
- __call__
|
| 27 |
+
|
| 28 |
+
## ShapEImg2ImgPipeline
|
| 29 |
+
[[autodoc]] ShapEImg2ImgPipeline
|
| 30 |
+
- all
|
| 31 |
+
- __call__
|
| 32 |
+
|
| 33 |
+
## ShapEPipelineOutput
|
| 34 |
+
[[autodoc]] pipelines.shap_e.pipeline_shap_e.ShapEPipelineOutput
|
tasks/tasksmith-1c5704b1f07f/tests/source/docs/source/en/api/pipelines/skyreels_v2.md
ADDED
|
@@ -0,0 +1,346 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
<!-- Copyright 2025 The HuggingFace Team. All rights reserved.
|
| 2 |
+
#
|
| 3 |
+
# Licensed under the Apache License, Version 2.0 (the "License");
|
| 4 |
+
# you may not use this file except in compliance with the License.
|
| 5 |
+
# You may obtain a copy of the License at
|
| 6 |
+
#
|
| 7 |
+
# http://www.apache.org/licenses/LICENSE-2.0
|
| 8 |
+
#
|
| 9 |
+
# Unless required by applicable law or agreed to in writing, software
|
| 10 |
+
# distributed under the License is distributed on an "AS IS" BASIS,
|
| 11 |
+
# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
|
| 12 |
+
# See the License for the specific language governing permissions and
|
| 13 |
+
# limitations under the License. -->
|
| 14 |
+
|
| 15 |
+
<div style="float: right;">
|
| 16 |
+
<div class="flex flex-wrap space-x-1">
|
| 17 |
+
<a href="https://huggingface.co/docs/diffusers/main/en/tutorials/using_peft_for_inference" target="_blank" rel="noopener">
|
| 18 |
+
<img alt="LoRA" src="https://img.shields.io/badge/LoRA-d8b4fe?style=flat"/>
|
| 19 |
+
</a>
|
| 20 |
+
</div>
|
| 21 |
+
</div>
|
| 22 |
+
|
| 23 |
+
# SkyReels-V2: Infinite-length Film Generative model
|
| 24 |
+
|
| 25 |
+
[SkyReels-V2](https://huggingface.co/papers/2504.13074) by the SkyReels Team from Skywork AI.
|
| 26 |
+
|
| 27 |
+
*Recent advances in video generation have been driven by diffusion models and autoregressive frameworks, yet critical challenges persist in harmonizing prompt adherence, visual quality, motion dynamics, and duration: compromises in motion dynamics to enhance temporal visual quality, constrained video duration (5-10 seconds) to prioritize resolution, and inadequate shot-aware generation stemming from general-purpose MLLMs' inability to interpret cinematic grammar, such as shot composition, actor expressions, and camera motions. These intertwined limitations hinder realistic long-form synthesis and professional film-style generation. To address these limitations, we propose SkyReels-V2, an Infinite-length Film Generative Model, that synergizes Multi-modal Large Language Model (MLLM), Multi-stage Pretraining, Reinforcement Learning, and Diffusion Forcing Framework. Firstly, we design a comprehensive structural representation of video that combines the general descriptions by the Multi-modal LLM and the detailed shot language by sub-expert models. Aided with human annotation, we then train a unified Video Captioner, named SkyCaptioner-V1, to efficiently label the video data. Secondly, we establish progressive-resolution pretraining for the fundamental video generation, followed by a four-stage post-training enhancement: Initial concept-balanced Supervised Fine-Tuning (SFT) improves baseline quality; Motion-specific Reinforcement Learning (RL) training with human-annotated and synthetic distortion data addresses dynamic artifacts; Our diffusion forcing framework with non-decreasing noise schedules enables long-video synthesis in an efficient search space; Final high-quality SFT refines visual fidelity. All the code and models are available at [this https URL](https://github.com/SkyworkAI/SkyReels-V2).*
|
| 28 |
+
|
| 29 |
+
You can find all the original SkyReels-V2 checkpoints under the [Skywork](https://huggingface.co/collections/Skywork/skyreels-v2-6801b1b93df627d441d0d0d9) organization.
|
| 30 |
+
|
| 31 |
+
The following SkyReels-V2 models are supported in Diffusers:
|
| 32 |
+
- [SkyReels-V2 DF 1.3B - 540P](https://huggingface.co/Skywork/SkyReels-V2-DF-1.3B-540P-Diffusers)
|
| 33 |
+
- [SkyReels-V2 DF 14B - 540P](https://huggingface.co/Skywork/SkyReels-V2-DF-14B-540P-Diffusers)
|
| 34 |
+
- [SkyReels-V2 DF 14B - 720P](https://huggingface.co/Skywork/SkyReels-V2-DF-14B-720P-Diffusers)
|
| 35 |
+
- [SkyReels-V2 T2V 14B - 540P](https://huggingface.co/Skywork/SkyReels-V2-T2V-14B-540P-Diffusers)
|
| 36 |
+
- [SkyReels-V2 T2V 14B - 720P](https://huggingface.co/Skywork/SkyReels-V2-T2V-14B-720P-Diffusers)
|
| 37 |
+
- [SkyReels-V2 I2V 1.3B - 540P](https://huggingface.co/Skywork/SkyReels-V2-I2V-1.3B-540P-Diffusers)
|
| 38 |
+
- [SkyReels-V2 I2V 14B - 540P](https://huggingface.co/Skywork/SkyReels-V2-I2V-14B-540P-Diffusers)
|
| 39 |
+
- [SkyReels-V2 I2V 14B - 720P](https://huggingface.co/Skywork/SkyReels-V2-I2V-14B-720P-Diffusers)
|
| 40 |
+
- [SkyReels-V2 FLF2V 1.3B - 540P](https://huggingface.co/Skywork/SkyReels-V2-FLF2V-1.3B-540P-Diffusers)
|
| 41 |
+
|
| 42 |
+
> [!TIP]
|
| 43 |
+
> Click on the SkyReels-V2 models in the right sidebar for more examples of video generation.
|
| 44 |
+
|
| 45 |
+
### A _Visual_ Demonstration
|
| 46 |
+
|
| 47 |
+
The example below has the following parameters:
|
| 48 |
+
|
| 49 |
+
- `base_num_frames=97`
|
| 50 |
+
- `num_frames=97`
|
| 51 |
+
- `num_inference_steps=30`
|
| 52 |
+
- `ar_step=5`
|
| 53 |
+
- `causal_block_size=5`
|
| 54 |
+
|
| 55 |
+
With `vae_scale_factor_temporal=4`, expect `5` blocks of `5` frames each as calculated by:
|
| 56 |
+
|
| 57 |
+
`num_latent_frames: (97-1)//vae_scale_factor_temporal+1 = 25 frames -> 5 blocks of 5 frames each`
|
| 58 |
+
|
| 59 |
+
And the maximum context length in the latent space is calculated with `base_num_latent_frames`:
|
| 60 |
+
|
| 61 |
+
`base_num_latent_frames = (97-1)//vae_scale_factor_temporal+1 = 25 -> 25//5 = 5 blocks`
|
| 62 |
+
|
| 63 |
+
Asynchronous Processing Timeline:
|
| 64 |
+
```text
|
| 65 |
+
┌─────────────────────────────────────────────────────────────────┐
|
| 66 |
+
│ Steps: 1 6 11 16 21 26 31 36 41 46 50 │
|
| 67 |
+
│ Block 1: [■■■■■■■��■■■■■■■■■■■■■■■■■■■■■■] │
|
| 68 |
+
│ Block 2: [■■■■■■■■■■■■■■■■■■■■■■■■■■■■■■] │
|
| 69 |
+
│ Block 3: [■■■■■■■■■■■■■■■■■■■■■■■■■■■■■■] │
|
| 70 |
+
│ Block 4: [■■■■■■■■■■■■■■■■■■■■■■■■■■■■■■] │
|
| 71 |
+
│ Block 5: [■■■■■■■■■■■■■■■■■■■■■■■■■■■■■■] │
|
| 72 |
+
└─────────────────────────────────────────────────────────────────┘
|
| 73 |
+
```
|
| 74 |
+
|
| 75 |
+
For Long Videos (`num_frames` > `base_num_frames`):
|
| 76 |
+
`base_num_frames` acts as the "sliding window size" for processing long videos.
|
| 77 |
+
|
| 78 |
+
Example: `257`-frame video with `base_num_frames=97`, `overlap_history=17`
|
| 79 |
+
```text
|
| 80 |
+
┌──── Iteration 1 (frames 1-97) ────┐
|
| 81 |
+
│ Processing window: 97 frames │ → 5 blocks,
|
| 82 |
+
│ Generates: frames 1-97 │ async processing
|
| 83 |
+
└───────────────────────────────────┘
|
| 84 |
+
┌────── Iteration 2 (frames 81-177) ──────┐
|
| 85 |
+
│ Processing window: 97 frames │
|
| 86 |
+
│ Overlap: 17 frames (81-97) from prev │ → 5 blocks,
|
| 87 |
+
│ Generates: frames 98-177 │ async processing
|
| 88 |
+
└─────────────────────────────────────────┘
|
| 89 |
+
┌────── Iteration 3 (frames 161-257) ──────┐
|
| 90 |
+
│ Processing window: 97 frames │
|
| 91 |
+
│ Overlap: 17 frames (161-177) from prev │ → 5 blocks,
|
| 92 |
+
│ Generates: frames 178-257 │ async processing
|
| 93 |
+
└──────────────────────────────────────────┘
|
| 94 |
+
```
|
| 95 |
+
|
| 96 |
+
Each iteration independently runs the asynchronous processing with its own `5` blocks.
|
| 97 |
+
`base_num_frames` controls:
|
| 98 |
+
1. Memory usage (larger window = more VRAM)
|
| 99 |
+
2. Model context length (must match training constraints)
|
| 100 |
+
3. Number of blocks per iteration (`base_num_latent_frames // causal_block_size`)
|
| 101 |
+
|
| 102 |
+
Each block takes `30` steps to complete denoising.
|
| 103 |
+
Block N starts at step: `1 + (N-1) x ar_step`
|
| 104 |
+
Total steps: `30 + (5-1) x 5 = 50` steps
|
| 105 |
+
|
| 106 |
+
|
| 107 |
+
Synchronous mode (`ar_step=0`) would process all blocks/frames simultaneously:
|
| 108 |
+
```text
|
| 109 |
+
┌──────────────────────────────────────────────┐
|
| 110 |
+
│ Steps: 1 ... 30 │
|
| 111 |
+
│ All blocks: [■■■■■■■■■■■■■■■■■■■■■■■■■■■■■■] │
|
| 112 |
+
└──────────────────────────────────────────────┘
|
| 113 |
+
```
|
| 114 |
+
Total steps: `30` steps
|
| 115 |
+
|
| 116 |
+
|
| 117 |
+
An example on how the step matrix is constructed for asynchronous processing:
|
| 118 |
+
Given the parameters: (`num_inference_steps=30, flow_shift=8, num_frames=97, ar_step=5, causal_block_size=5`)
|
| 119 |
+
```
|
| 120 |
+
- num_latent_frames = (97 frames - 1) // (4 temporal downsampling) + 1 = 25
|
| 121 |
+
- step_template = [999, 995, 991, 986, 980, 975, 969, 963, 956, 948,
|
| 122 |
+
941, 932, 922, 912, 901, 888, 874, 859, 841, 822,
|
| 123 |
+
799, 773, 743, 708, 666, 615, 551, 470, 363, 216]
|
| 124 |
+
```
|
| 125 |
+
|
| 126 |
+
The algorithm creates a `50x25` `step_matrix` where:
|
| 127 |
+
```
|
| 128 |
+
- Row 1: [999×5, 999×5, 999×5, 999×5, 999×5]
|
| 129 |
+
- Row 2: [995×5, 999×5, 999×5, 999×5, 999×5]
|
| 130 |
+
- Row 3: [991×5, 999×5, 999×5, 999×5, 999×5]
|
| 131 |
+
- ...
|
| 132 |
+
- Row 7: [969×5, 995×5, 999×5, 999×5, 999×5]
|
| 133 |
+
- ...
|
| 134 |
+
- Row 21: [799×5, 888×5, 941×5, 975×5, 999×5]
|
| 135 |
+
- ...
|
| 136 |
+
- Row 35: [ 0×5, 216×5, 666×5, 822×5, 901×5]
|
| 137 |
+
- ...
|
| 138 |
+
- Row 42: [ 0×5, 0×5, 0×5, 551×5, 773×5]
|
| 139 |
+
- ...
|
| 140 |
+
- Row 50: [ 0×5, 0×5, 0×5, 0×5, 216×5]
|
| 141 |
+
```
|
| 142 |
+
|
| 143 |
+
Detailed Row `6` Analysis:
|
| 144 |
+
```
|
| 145 |
+
- step_matrix[5]: [ 975×5, 999×5, 999×5, 999×5, 999×5]
|
| 146 |
+
- step_index[5]: [ 6×5, 1×5, 0×5, 0×5, 0×5]
|
| 147 |
+
- step_update_mask[5]: [True×5, True×5, False×5, False×5, False×5]
|
| 148 |
+
- valid_interval[5]: (0, 25)
|
| 149 |
+
```
|
| 150 |
+
|
| 151 |
+
Key Pattern: Block `i` lags behind Block `i-1` by exactly `ar_step=5` timesteps, creating the
|
| 152 |
+
staggered "diffusion forcing" effect where later blocks condition on cleaner earlier blocks.
|
| 153 |
+
|
| 154 |
+
|
| 155 |
+
### Text-to-Video Generation
|
| 156 |
+
|
| 157 |
+
The example below demonstrates how to generate a video from text.
|
| 158 |
+
|
| 159 |
+
<hfoptions id="T2V usage">
|
| 160 |
+
<hfoption id="T2V memory">
|
| 161 |
+
|
| 162 |
+
Refer to the [Reduce memory usage](../../optimization/memory) guide for more details about the various memory saving techniques.
|
| 163 |
+
|
| 164 |
+
From the original repo:
|
| 165 |
+
>You can use --ar_step 5 to enable asynchronous inference. When asynchronous inference, --causal_block_size 5 is recommended while it is not supposed to be set for synchronous generation... Asynchronous inference will take more steps to diffuse the whole sequence which means it will be SLOWER than synchronous mode. In our experiments, asynchronous inference may improve the instruction following and visual consistent performance.
|
| 166 |
+
|
| 167 |
+
```py
|
| 168 |
+
import torch
|
| 169 |
+
from diffusers import AutoModel, SkyReelsV2DiffusionForcingPipeline, UniPCMultistepScheduler
|
| 170 |
+
from diffusers.utils import export_to_video
|
| 171 |
+
|
| 172 |
+
|
| 173 |
+
model_id = "Skywork/SkyReels-V2-DF-1.3B-540P-Diffusers"
|
| 174 |
+
vae = AutoModel.from_pretrained(model_id, subfolder="vae", torch_dtype=torch.float32)
|
| 175 |
+
|
| 176 |
+
pipeline = SkyReelsV2DiffusionForcingPipeline.from_pretrained(
|
| 177 |
+
model_id,
|
| 178 |
+
vae=vae,
|
| 179 |
+
torch_dtype=torch.bfloat16,
|
| 180 |
+
)
|
| 181 |
+
pipeline.to("cuda")
|
| 182 |
+
flow_shift = 8.0 # 8.0 for T2V, 5.0 for I2V
|
| 183 |
+
pipeline.scheduler = UniPCMultistepScheduler.from_config(pipeline.scheduler.config, flow_shift=flow_shift)
|
| 184 |
+
|
| 185 |
+
prompt = "A cat and a dog baking a cake together in a kitchen. The cat is carefully measuring flour, while the dog is stirring the batter with a wooden spoon. The kitchen is cozy, with sunlight streaming through the window."
|
| 186 |
+
|
| 187 |
+
output = pipeline(
|
| 188 |
+
prompt=prompt,
|
| 189 |
+
num_inference_steps=30,
|
| 190 |
+
height=544, # 720 for 720P
|
| 191 |
+
width=960, # 1280 for 720P
|
| 192 |
+
num_frames=97,
|
| 193 |
+
base_num_frames=97, # 121 for 720P
|
| 194 |
+
ar_step=5, # Controls asynchronous inference (0 for synchronous mode)
|
| 195 |
+
causal_block_size=5, # Number of frames in each block for asynchronous processing
|
| 196 |
+
overlap_history=None, # Number of frames to overlap for smooth transitions in long videos; 17 for long video generations
|
| 197 |
+
addnoise_condition=20, # Improves consistency in long video generation
|
| 198 |
+
).frames[0]
|
| 199 |
+
export_to_video(output, "video.mp4", fps=24, quality=8)
|
| 200 |
+
```
|
| 201 |
+
|
| 202 |
+
</hfoption>
|
| 203 |
+
</hfoptions>
|
| 204 |
+
|
| 205 |
+
### First-Last-Frame-to-Video Generation
|
| 206 |
+
|
| 207 |
+
The example below demonstrates how to use the image-to-video pipeline to generate a video using a text description, a starting frame, and an ending frame.
|
| 208 |
+
|
| 209 |
+
<hfoptions id="FLF2V usage">
|
| 210 |
+
<hfoption id="usage">
|
| 211 |
+
|
| 212 |
+
```python
|
| 213 |
+
import numpy as np
|
| 214 |
+
import torch
|
| 215 |
+
import torchvision.transforms.functional as TF
|
| 216 |
+
from diffusers import AutoencoderKLWan, SkyReelsV2DiffusionForcingImageToVideoPipeline, UniPCMultistepScheduler
|
| 217 |
+
from diffusers.utils import export_to_video, load_image
|
| 218 |
+
|
| 219 |
+
|
| 220 |
+
model_id = "Skywork/SkyReels-V2-DF-1.3B-720P-Diffusers"
|
| 221 |
+
vae = AutoencoderKLWan.from_pretrained(model_id, subfolder="vae", torch_dtype=torch.float32)
|
| 222 |
+
pipeline = SkyReelsV2DiffusionForcingImageToVideoPipeline.from_pretrained(
|
| 223 |
+
model_id, vae=vae, torch_dtype=torch.bfloat16
|
| 224 |
+
)
|
| 225 |
+
pipeline.to("cuda")
|
| 226 |
+
flow_shift = 5.0 # 8.0 for T2V, 5.0 for I2V
|
| 227 |
+
pipeline.scheduler = UniPCMultistepScheduler.from_config(pipeline.scheduler.config, flow_shift=flow_shift)
|
| 228 |
+
|
| 229 |
+
first_frame = load_image("https://huggingface.co/datasets/huggingface/documentation-images/resolve/main/diffusers/flf2v_input_first_frame.png")
|
| 230 |
+
last_frame = load_image("https://huggingface.co/datasets/huggingface/documentation-images/resolve/main/diffusers/flf2v_input_last_frame.png")
|
| 231 |
+
|
| 232 |
+
def aspect_ratio_resize(image, pipeline, max_area=720 * 1280):
|
| 233 |
+
aspect_ratio = image.height / image.width
|
| 234 |
+
mod_value = pipeline.vae_scale_factor_spatial * pipeline.transformer.config.patch_size[1]
|
| 235 |
+
height = round(np.sqrt(max_area * aspect_ratio)) // mod_value * mod_value
|
| 236 |
+
width = round(np.sqrt(max_area / aspect_ratio)) // mod_value * mod_value
|
| 237 |
+
image = image.resize((width, height))
|
| 238 |
+
return image, height, width
|
| 239 |
+
|
| 240 |
+
def center_crop_resize(image, height, width):
|
| 241 |
+
# Calculate resize ratio to match first frame dimensions
|
| 242 |
+
resize_ratio = max(width / image.width, height / image.height)
|
| 243 |
+
|
| 244 |
+
# Resize the image
|
| 245 |
+
width = round(image.width * resize_ratio)
|
| 246 |
+
height = round(image.height * resize_ratio)
|
| 247 |
+
size = [width, height]
|
| 248 |
+
image = TF.center_crop(image, size)
|
| 249 |
+
|
| 250 |
+
return image, height, width
|
| 251 |
+
|
| 252 |
+
first_frame, height, width = aspect_ratio_resize(first_frame, pipeline)
|
| 253 |
+
if last_frame.size != first_frame.size:
|
| 254 |
+
last_frame, _, _ = center_crop_resize(last_frame, height, width)
|
| 255 |
+
|
| 256 |
+
prompt = "CG animation style, a small blue bird takes off from the ground, flapping its wings. The bird's feathers are delicate, with a unique pattern on its chest. The background shows a blue sky with white clouds under bright sunshine. The camera follows the bird upward, capturing its flight and the vastness of the sky from a close-up, low-angle perspective."
|
| 257 |
+
|
| 258 |
+
output = pipeline(
|
| 259 |
+
image=first_frame, last_image=last_frame, prompt=prompt, height=height, width=width, guidance_scale=5.0
|
| 260 |
+
).frames[0]
|
| 261 |
+
export_to_video(output, "video.mp4", fps=24, quality=8)
|
| 262 |
+
```
|
| 263 |
+
|
| 264 |
+
</hfoption>
|
| 265 |
+
</hfoptions>
|
| 266 |
+
|
| 267 |
+
|
| 268 |
+
### Video-to-Video Generation
|
| 269 |
+
|
| 270 |
+
<hfoptions id="V2V usage">
|
| 271 |
+
<hfoption id="usage">
|
| 272 |
+
|
| 273 |
+
`SkyReelsV2DiffusionForcingVideoToVideoPipeline` extends a given video.
|
| 274 |
+
|
| 275 |
+
```python
|
| 276 |
+
import numpy as np
|
| 277 |
+
import torch
|
| 278 |
+
import torchvision.transforms.functional as TF
|
| 279 |
+
from diffusers import AutoencoderKLWan, SkyReelsV2DiffusionForcingVideoToVideoPipeline, UniPCMultistepScheduler
|
| 280 |
+
from diffusers.utils import export_to_video, load_video
|
| 281 |
+
|
| 282 |
+
|
| 283 |
+
model_id = "Skywork/SkyReels-V2-DF-1.3B-720P-Diffusers"
|
| 284 |
+
vae = AutoencoderKLWan.from_pretrained(model_id, subfolder="vae", torch_dtype=torch.float32)
|
| 285 |
+
pipeline = SkyReelsV2DiffusionForcingVideoToVideoPipeline.from_pretrained(
|
| 286 |
+
model_id, vae=vae, torch_dtype=torch.bfloat16
|
| 287 |
+
)
|
| 288 |
+
pipeline.to("cuda")
|
| 289 |
+
flow_shift = 5.0 # 8.0 for T2V, 5.0 for I2V
|
| 290 |
+
pipeline.scheduler = UniPCMultistepScheduler.from_config(pipeline.scheduler.config, flow_shift=flow_shift)
|
| 291 |
+
|
| 292 |
+
video = load_video("input_video.mp4")
|
| 293 |
+
|
| 294 |
+
prompt = "CG animation style, a small blue bird takes off from the ground, flapping its wings. The bird's feathers are delicate, with a unique pattern on its chest. The background shows a blue sky with white clouds under bright sunshine. The camera follows the bird upward, capturing its flight and the vastness of the sky from a close-up, low-angle perspective."
|
| 295 |
+
|
| 296 |
+
output = pipeline(
|
| 297 |
+
video=video, prompt=prompt, height=720, width=1280, guidance_scale=5.0, overlap_history=17,
|
| 298 |
+
num_inference_steps=30, num_frames=257, base_num_frames=121#, ar_step=5, causal_block_size=5,
|
| 299 |
+
).frames[0]
|
| 300 |
+
export_to_video(output, "video.mp4", fps=24, quality=8)
|
| 301 |
+
# Total frames will be the number of frames of the given video + 257
|
| 302 |
+
```
|
| 303 |
+
|
| 304 |
+
</hfoption>
|
| 305 |
+
</hfoptions>
|
| 306 |
+
|
| 307 |
+
## Notes
|
| 308 |
+
|
| 309 |
+
- SkyReels-V2 supports LoRAs with [`~loaders.SkyReelsV2LoraLoaderMixin.load_lora_weights`].
|
| 310 |
+
|
| 311 |
+
`SkyReelsV2Pipeline` and `SkyReelsV2ImageToVideoPipeline` are also available without Diffusion Forcing framework applied.
|
| 312 |
+
|
| 313 |
+
|
| 314 |
+
## SkyReelsV2DiffusionForcingPipeline
|
| 315 |
+
|
| 316 |
+
[[autodoc]] SkyReelsV2DiffusionForcingPipeline
|
| 317 |
+
- all
|
| 318 |
+
- __call__
|
| 319 |
+
|
| 320 |
+
## SkyReelsV2DiffusionForcingImageToVideoPipeline
|
| 321 |
+
|
| 322 |
+
[[autodoc]] SkyReelsV2DiffusionForcingImageToVideoPipeline
|
| 323 |
+
- all
|
| 324 |
+
- __call__
|
| 325 |
+
|
| 326 |
+
## SkyReelsV2DiffusionForcingVideoToVideoPipeline
|
| 327 |
+
|
| 328 |
+
[[autodoc]] SkyReelsV2DiffusionForcingVideoToVideoPipeline
|
| 329 |
+
- all
|
| 330 |
+
- __call__
|
| 331 |
+
|
| 332 |
+
## SkyReelsV2Pipeline
|
| 333 |
+
|
| 334 |
+
[[autodoc]] SkyReelsV2Pipeline
|
| 335 |
+
- all
|
| 336 |
+
- __call__
|
| 337 |
+
|
| 338 |
+
## SkyReelsV2ImageToVideoPipeline
|
| 339 |
+
|
| 340 |
+
[[autodoc]] SkyReelsV2ImageToVideoPipeline
|
| 341 |
+
- all
|
| 342 |
+
- __call__
|
| 343 |
+
|
| 344 |
+
## SkyReelsV2PipelineOutput
|
| 345 |
+
|
| 346 |
+
[[autodoc]] pipelines.skyreels_v2.pipeline_output.SkyReelsV2PipelineOutput
|
tasks/tasksmith-1c5704b1f07f/tests/source/docs/source/en/api/pipelines/stable_audio.md
ADDED
|
@@ -0,0 +1,93 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
<!--Copyright 2025 The HuggingFace Team. All rights reserved.
|
| 2 |
+
|
| 3 |
+
Licensed under the Apache License, Version 2.0 (the "License"); you may not use this file except in compliance with
|
| 4 |
+
the License. You may obtain a copy of the License at
|
| 5 |
+
|
| 6 |
+
http://www.apache.org/licenses/LICENSE-2.0
|
| 7 |
+
|
| 8 |
+
Unless required by applicable law or agreed to in writing, software distributed under the License is distributed on
|
| 9 |
+
an "AS IS" BASIS, WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied. See the License for the
|
| 10 |
+
specific language governing permissions and limitations under the License.
|
| 11 |
+
-->
|
| 12 |
+
|
| 13 |
+
# Stable Audio
|
| 14 |
+
|
| 15 |
+
Stable Audio was proposed in [Stable Audio Open](https://huggingface.co/papers/2407.14358) by Zach Evans et al. . it takes a text prompt as input and predicts the corresponding sound or music sample.
|
| 16 |
+
|
| 17 |
+
Stable Audio Open generates variable-length (up to 47s) stereo audio at 44.1kHz from text prompts. It comprises three components: an autoencoder that compresses waveforms into a manageable sequence length, a T5-based text embedding for text conditioning, and a transformer-based diffusion (DiT) model that operates in the latent space of the autoencoder.
|
| 18 |
+
|
| 19 |
+
Stable Audio is trained on a corpus of around 48k audio recordings, where around 47k are from Freesound and the rest are from the Free Music Archive (FMA). All audio files are licensed under CC0, CC BY, or CC Sampling+. This data is used to train the autoencoder and the DiT.
|
| 20 |
+
|
| 21 |
+
The abstract of the paper is the following:
|
| 22 |
+
*Open generative models are vitally important for the community, allowing for fine-tunes and serving as baselines when presenting new models. However, most current text-to-audio models are private and not accessible for artists and researchers to build upon. Here we describe the architecture and training process of a new open-weights text-to-audio model trained with Creative Commons data. Our evaluation shows that the model's performance is competitive with the state-of-the-art across various metrics. Notably, the reported FDopenl3 results (measuring the realism of the generations) showcase its potential for high-quality stereo sound synthesis at 44.1kHz.*
|
| 23 |
+
|
| 24 |
+
This pipeline was contributed by [Yoach Lacombe](https://huggingface.co/ylacombe). The original codebase can be found at [Stability-AI/stable-audio-tools](https://github.com/Stability-AI/stable-audio-tools).
|
| 25 |
+
|
| 26 |
+
## Tips
|
| 27 |
+
|
| 28 |
+
When constructing a prompt, keep in mind:
|
| 29 |
+
|
| 30 |
+
* Descriptive prompt inputs work best; use adjectives to describe the sound (for example, "high quality" or "clear") and make the prompt context specific where possible (e.g. "melodic techno with a fast beat and synths" works better than "techno").
|
| 31 |
+
* Using a *negative prompt* can significantly improve the quality of the generated audio. Try using a negative prompt of "low quality, average quality".
|
| 32 |
+
|
| 33 |
+
During inference:
|
| 34 |
+
|
| 35 |
+
* The _quality_ of the generated audio sample can be controlled by the `num_inference_steps` argument; higher steps give higher quality audio at the expense of slower inference.
|
| 36 |
+
* Multiple waveforms can be generated in one go: set `num_waveforms_per_prompt` to a value greater than 1 to enable. Automatic scoring will be performed between the generated waveforms and prompt text, and the audios ranked from best to worst accordingly.
|
| 37 |
+
|
| 38 |
+
## Quantization
|
| 39 |
+
|
| 40 |
+
Quantization helps reduce the memory requirements of very large models by storing model weights in a lower precision data type. However, quantization may have varying impact on video quality depending on the video model.
|
| 41 |
+
|
| 42 |
+
Refer to the [Quantization](../../quantization/overview) overview to learn more about supported quantization backends and selecting a quantization backend that supports your use case. The example below demonstrates how to load a quantized [`StableAudioPipeline`] for inference with bitsandbytes.
|
| 43 |
+
|
| 44 |
+
```py
|
| 45 |
+
import torch
|
| 46 |
+
from diffusers import BitsAndBytesConfig as DiffusersBitsAndBytesConfig, StableAudioDiTModel, StableAudioPipeline
|
| 47 |
+
from diffusers.utils import export_to_video
|
| 48 |
+
from transformers import BitsAndBytesConfig as BitsAndBytesConfig, T5EncoderModel
|
| 49 |
+
|
| 50 |
+
quant_config = BitsAndBytesConfig(load_in_8bit=True)
|
| 51 |
+
text_encoder_8bit = T5EncoderModel.from_pretrained(
|
| 52 |
+
"stabilityai/stable-audio-open-1.0",
|
| 53 |
+
subfolder="text_encoder",
|
| 54 |
+
quantization_config=quant_config,
|
| 55 |
+
torch_dtype=torch.float16,
|
| 56 |
+
)
|
| 57 |
+
|
| 58 |
+
quant_config = DiffusersBitsAndBytesConfig(load_in_8bit=True)
|
| 59 |
+
transformer_8bit = StableAudioDiTModel.from_pretrained(
|
| 60 |
+
"stabilityai/stable-audio-open-1.0",
|
| 61 |
+
subfolder="transformer",
|
| 62 |
+
quantization_config=quant_config,
|
| 63 |
+
torch_dtype=torch.float16,
|
| 64 |
+
)
|
| 65 |
+
|
| 66 |
+
pipeline = StableAudioPipeline.from_pretrained(
|
| 67 |
+
"stabilityai/stable-audio-open-1.0",
|
| 68 |
+
text_encoder=text_encoder_8bit,
|
| 69 |
+
transformer=transformer_8bit,
|
| 70 |
+
torch_dtype=torch.float16,
|
| 71 |
+
device_map="balanced",
|
| 72 |
+
)
|
| 73 |
+
|
| 74 |
+
prompt = "The sound of a hammer hitting a wooden surface."
|
| 75 |
+
negative_prompt = "Low quality."
|
| 76 |
+
audio = pipeline(
|
| 77 |
+
prompt,
|
| 78 |
+
negative_prompt=negative_prompt,
|
| 79 |
+
num_inference_steps=200,
|
| 80 |
+
audio_end_in_s=10.0,
|
| 81 |
+
num_waveforms_per_prompt=3,
|
| 82 |
+
generator=generator,
|
| 83 |
+
).audios
|
| 84 |
+
|
| 85 |
+
output = audio[0].T.float().cpu().numpy()
|
| 86 |
+
sf.write("hammer.wav", output, pipeline.vae.sampling_rate)
|
| 87 |
+
```
|
| 88 |
+
|
| 89 |
+
|
| 90 |
+
## StableAudioPipeline
|
| 91 |
+
[[autodoc]] StableAudioPipeline
|
| 92 |
+
- all
|
| 93 |
+
- __call__
|
tasks/tasksmith-1c5704b1f07f/tests/source/docs/source/en/api/pipelines/stable_cascade.md
ADDED
|
@@ -0,0 +1,226 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
<!--Copyright 2025 The HuggingFace Team. All rights reserved.
|
| 2 |
+
|
| 3 |
+
Licensed under the Apache License, Version 2.0 (the "License"); you may not use this file except in compliance with
|
| 4 |
+
the License. You may obtain a copy of the License at
|
| 5 |
+
|
| 6 |
+
http://www.apache.org/licenses/LICENSE-2.0
|
| 7 |
+
|
| 8 |
+
Unless required by applicable law or agreed to in writing, software distributed under the License is distributed on
|
| 9 |
+
an "AS IS" BASIS, WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied. See the License for the
|
| 10 |
+
specific language governing permissions and limitations under the License.
|
| 11 |
+
-->
|
| 12 |
+
|
| 13 |
+
# Stable Cascade
|
| 14 |
+
|
| 15 |
+
This model is built upon the [Würstchen](https://openreview.net/forum?id=gU58d5QeGv) architecture and its main
|
| 16 |
+
difference to other models like Stable Diffusion is that it is working at a much smaller latent space. Why is this
|
| 17 |
+
important? The smaller the latent space, the **faster** you can run inference and the **cheaper** the training becomes.
|
| 18 |
+
How small is the latent space? Stable Diffusion uses a compression factor of 8, resulting in a 1024x1024 image being
|
| 19 |
+
encoded to 128x128. Stable Cascade achieves a compression factor of 42, meaning that it is possible to encode a
|
| 20 |
+
1024x1024 image to 24x24, while maintaining crisp reconstructions. The text-conditional model is then trained in the
|
| 21 |
+
highly compressed latent space. Previous versions of this architecture, achieved a 16x cost reduction over Stable
|
| 22 |
+
Diffusion 1.5.
|
| 23 |
+
|
| 24 |
+
Therefore, this kind of model is well suited for usages where efficiency is important. Furthermore, all known extensions
|
| 25 |
+
like finetuning, LoRA, ControlNet, IP-Adapter, LCM etc. are possible with this method as well.
|
| 26 |
+
|
| 27 |
+
The original codebase can be found at [Stability-AI/StableCascade](https://github.com/Stability-AI/StableCascade).
|
| 28 |
+
|
| 29 |
+
## Model Overview
|
| 30 |
+
Stable Cascade consists of three models: Stage A, Stage B and Stage C, representing a cascade to generate images,
|
| 31 |
+
hence the name "Stable Cascade".
|
| 32 |
+
|
| 33 |
+
Stage A & B are used to compress images, similar to what the job of the VAE is in Stable Diffusion.
|
| 34 |
+
However, with this setup, a much higher compression of images can be achieved. While the Stable Diffusion models use a
|
| 35 |
+
spatial compression factor of 8, encoding an image with resolution of 1024 x 1024 to 128 x 128, Stable Cascade achieves
|
| 36 |
+
a compression factor of 42. This encodes a 1024 x 1024 image to 24 x 24, while being able to accurately decode the
|
| 37 |
+
image. This comes with the great benefit of cheaper training and inference. Furthermore, Stage C is responsible
|
| 38 |
+
for generating the small 24 x 24 latents given a text prompt.
|
| 39 |
+
|
| 40 |
+
The Stage C model operates on the small 24 x 24 latents and denoises the latents conditioned on text prompts. The model is also the largest component in the Cascade pipeline and is meant to be used with the `StableCascadePriorPipeline`
|
| 41 |
+
|
| 42 |
+
The Stage B and Stage A models are used with the `StableCascadeDecoderPipeline` and are responsible for generating the final image given the small 24 x 24 latents.
|
| 43 |
+
|
| 44 |
+
> [!WARNING]
|
| 45 |
+
> There are some restrictions on data types that can be used with the Stable Cascade models. The official checkpoints for the `StableCascadePriorPipeline` do not support the `torch.float16` data type. Please use `torch.bfloat16` instead.
|
| 46 |
+
>
|
| 47 |
+
> In order to use the `torch.bfloat16` data type with the `StableCascadeDecoderPipeline` you need to have PyTorch 2.2.0 or higher installed. This also means that using the `StableCascadeCombinedPipeline` with `torch.bfloat16` requires PyTorch 2.2.0 or higher, since it calls the `StableCascadeDecoderPipeline` internally.
|
| 48 |
+
>
|
| 49 |
+
> If it is not possible to install PyTorch 2.2.0 or higher in your environment, the `StableCascadeDecoderPipeline` can be used on its own with the `torch.float16` data type. You can download the full precision or `bf16` variant weights for the pipeline and cast the weights to `torch.float16`.
|
| 50 |
+
|
| 51 |
+
## Usage example
|
| 52 |
+
|
| 53 |
+
```python
|
| 54 |
+
import torch
|
| 55 |
+
from diffusers import StableCascadeDecoderPipeline, StableCascadePriorPipeline
|
| 56 |
+
|
| 57 |
+
prompt = "an image of a shiba inu, donning a spacesuit and helmet"
|
| 58 |
+
negative_prompt = ""
|
| 59 |
+
|
| 60 |
+
prior = StableCascadePriorPipeline.from_pretrained("stabilityai/stable-cascade-prior", variant="bf16", torch_dtype=torch.bfloat16)
|
| 61 |
+
decoder = StableCascadeDecoderPipeline.from_pretrained("stabilityai/stable-cascade", variant="bf16", torch_dtype=torch.float16)
|
| 62 |
+
|
| 63 |
+
prior.enable_model_cpu_offload()
|
| 64 |
+
prior_output = prior(
|
| 65 |
+
prompt=prompt,
|
| 66 |
+
height=1024,
|
| 67 |
+
width=1024,
|
| 68 |
+
negative_prompt=negative_prompt,
|
| 69 |
+
guidance_scale=4.0,
|
| 70 |
+
num_images_per_prompt=1,
|
| 71 |
+
num_inference_steps=20
|
| 72 |
+
)
|
| 73 |
+
|
| 74 |
+
decoder.enable_model_cpu_offload()
|
| 75 |
+
decoder_output = decoder(
|
| 76 |
+
image_embeddings=prior_output.image_embeddings.to(torch.float16),
|
| 77 |
+
prompt=prompt,
|
| 78 |
+
negative_prompt=negative_prompt,
|
| 79 |
+
guidance_scale=0.0,
|
| 80 |
+
output_type="pil",
|
| 81 |
+
num_inference_steps=10
|
| 82 |
+
).images[0]
|
| 83 |
+
decoder_output.save("cascade.png")
|
| 84 |
+
```
|
| 85 |
+
|
| 86 |
+
## Using the Lite Versions of the Stage B and Stage C models
|
| 87 |
+
|
| 88 |
+
```python
|
| 89 |
+
import torch
|
| 90 |
+
from diffusers import (
|
| 91 |
+
StableCascadeDecoderPipeline,
|
| 92 |
+
StableCascadePriorPipeline,
|
| 93 |
+
StableCascadeUNet,
|
| 94 |
+
)
|
| 95 |
+
|
| 96 |
+
prompt = "an image of a shiba inu, donning a spacesuit and helmet"
|
| 97 |
+
negative_prompt = ""
|
| 98 |
+
|
| 99 |
+
prior_unet = StableCascadeUNet.from_pretrained("stabilityai/stable-cascade-prior", subfolder="prior_lite")
|
| 100 |
+
decoder_unet = StableCascadeUNet.from_pretrained("stabilityai/stable-cascade", subfolder="decoder_lite")
|
| 101 |
+
|
| 102 |
+
prior = StableCascadePriorPipeline.from_pretrained("stabilityai/stable-cascade-prior", prior=prior_unet)
|
| 103 |
+
decoder = StableCascadeDecoderPipeline.from_pretrained("stabilityai/stable-cascade", decoder=decoder_unet)
|
| 104 |
+
|
| 105 |
+
prior.enable_model_cpu_offload()
|
| 106 |
+
prior_output = prior(
|
| 107 |
+
prompt=prompt,
|
| 108 |
+
height=1024,
|
| 109 |
+
width=1024,
|
| 110 |
+
negative_prompt=negative_prompt,
|
| 111 |
+
guidance_scale=4.0,
|
| 112 |
+
num_images_per_prompt=1,
|
| 113 |
+
num_inference_steps=20
|
| 114 |
+
)
|
| 115 |
+
|
| 116 |
+
decoder.enable_model_cpu_offload()
|
| 117 |
+
decoder_output = decoder(
|
| 118 |
+
image_embeddings=prior_output.image_embeddings,
|
| 119 |
+
prompt=prompt,
|
| 120 |
+
negative_prompt=negative_prompt,
|
| 121 |
+
guidance_scale=0.0,
|
| 122 |
+
output_type="pil",
|
| 123 |
+
num_inference_steps=10
|
| 124 |
+
).images[0]
|
| 125 |
+
decoder_output.save("cascade.png")
|
| 126 |
+
```
|
| 127 |
+
|
| 128 |
+
## Loading original checkpoints with `from_single_file`
|
| 129 |
+
|
| 130 |
+
Loading the original format checkpoints is supported via `from_single_file` method in the StableCascadeUNet.
|
| 131 |
+
|
| 132 |
+
```python
|
| 133 |
+
import torch
|
| 134 |
+
from diffusers import (
|
| 135 |
+
StableCascadeDecoderPipeline,
|
| 136 |
+
StableCascadePriorPipeline,
|
| 137 |
+
StableCascadeUNet,
|
| 138 |
+
)
|
| 139 |
+
|
| 140 |
+
prompt = "an image of a shiba inu, donning a spacesuit and helmet"
|
| 141 |
+
negative_prompt = ""
|
| 142 |
+
|
| 143 |
+
prior_unet = StableCascadeUNet.from_single_file(
|
| 144 |
+
"https://huggingface.co/stabilityai/stable-cascade/resolve/main/stage_c_bf16.safetensors",
|
| 145 |
+
torch_dtype=torch.bfloat16
|
| 146 |
+
)
|
| 147 |
+
decoder_unet = StableCascadeUNet.from_single_file(
|
| 148 |
+
"https://huggingface.co/stabilityai/stable-cascade/blob/main/stage_b_bf16.safetensors",
|
| 149 |
+
torch_dtype=torch.bfloat16
|
| 150 |
+
)
|
| 151 |
+
|
| 152 |
+
prior = StableCascadePriorPipeline.from_pretrained("stabilityai/stable-cascade-prior", prior=prior_unet, torch_dtype=torch.bfloat16)
|
| 153 |
+
decoder = StableCascadeDecoderPipeline.from_pretrained("stabilityai/stable-cascade", decoder=decoder_unet, torch_dtype=torch.bfloat16)
|
| 154 |
+
|
| 155 |
+
prior.enable_model_cpu_offload()
|
| 156 |
+
prior_output = prior(
|
| 157 |
+
prompt=prompt,
|
| 158 |
+
height=1024,
|
| 159 |
+
width=1024,
|
| 160 |
+
negative_prompt=negative_prompt,
|
| 161 |
+
guidance_scale=4.0,
|
| 162 |
+
num_images_per_prompt=1,
|
| 163 |
+
num_inference_steps=20
|
| 164 |
+
)
|
| 165 |
+
|
| 166 |
+
decoder.enable_model_cpu_offload()
|
| 167 |
+
decoder_output = decoder(
|
| 168 |
+
image_embeddings=prior_output.image_embeddings,
|
| 169 |
+
prompt=prompt,
|
| 170 |
+
negative_prompt=negative_prompt,
|
| 171 |
+
guidance_scale=0.0,
|
| 172 |
+
output_type="pil",
|
| 173 |
+
num_inference_steps=10
|
| 174 |
+
).images[0]
|
| 175 |
+
decoder_output.save("cascade-single-file.png")
|
| 176 |
+
```
|
| 177 |
+
|
| 178 |
+
## Uses
|
| 179 |
+
|
| 180 |
+
### Direct Use
|
| 181 |
+
|
| 182 |
+
The model is intended for research purposes for now. Possible research areas and tasks include
|
| 183 |
+
|
| 184 |
+
- Research on generative models.
|
| 185 |
+
- Safe deployment of models which have the potential to generate harmful content.
|
| 186 |
+
- Probing and understanding the limitations and biases of generative models.
|
| 187 |
+
- Generation of artworks and use in design and other artistic processes.
|
| 188 |
+
- Applications in educational or creative tools.
|
| 189 |
+
|
| 190 |
+
Excluded uses are described below.
|
| 191 |
+
|
| 192 |
+
### Out-of-Scope Use
|
| 193 |
+
|
| 194 |
+
The model was not trained to be factual or true representations of people or events,
|
| 195 |
+
and therefore using the model to generate such content is out-of-scope for the abilities of this model.
|
| 196 |
+
The model should not be used in any way that violates Stability AI's [Acceptable Use Policy](https://stability.ai/use-policy).
|
| 197 |
+
|
| 198 |
+
## Limitations and Bias
|
| 199 |
+
|
| 200 |
+
### Limitations
|
| 201 |
+
- Faces and people in general may not be generated properly.
|
| 202 |
+
- The autoencoding part of the model is lossy.
|
| 203 |
+
|
| 204 |
+
|
| 205 |
+
## StableCascadeCombinedPipeline
|
| 206 |
+
|
| 207 |
+
[[autodoc]] StableCascadeCombinedPipeline
|
| 208 |
+
- all
|
| 209 |
+
- __call__
|
| 210 |
+
|
| 211 |
+
## StableCascadePriorPipeline
|
| 212 |
+
|
| 213 |
+
[[autodoc]] StableCascadePriorPipeline
|
| 214 |
+
- all
|
| 215 |
+
- __call__
|
| 216 |
+
|
| 217 |
+
## StableCascadePriorPipelineOutput
|
| 218 |
+
|
| 219 |
+
[[autodoc]] pipelines.stable_cascade.pipeline_stable_cascade_prior.StableCascadePriorPipelineOutput
|
| 220 |
+
|
| 221 |
+
## StableCascadeDecoderPipeline
|
| 222 |
+
|
| 223 |
+
[[autodoc]] StableCascadeDecoderPipeline
|
| 224 |
+
- all
|
| 225 |
+
- __call__
|
| 226 |
+
|
tasks/tasksmith-1c5704b1f07f/tests/source/docs/source/en/api/pipelines/stable_diffusion/adapter.md
ADDED
|
@@ -0,0 +1,47 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
<!--Copyright 2025 The HuggingFace Team. All rights reserved.
|
| 2 |
+
|
| 3 |
+
Licensed under the Apache License, Version 2.0 (the "License"); you may not use this file except in compliance with
|
| 4 |
+
the License. You may obtain a copy of the License at
|
| 5 |
+
|
| 6 |
+
http://www.apache.org/licenses/LICENSE-2.0
|
| 7 |
+
|
| 8 |
+
Unless required by applicable law or agreed to in writing, software distributed under the License is distributed on
|
| 9 |
+
an "AS IS" BASIS, WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied. See the License for the
|
| 10 |
+
specific language governing permissions and limitations under the License.
|
| 11 |
+
-->
|
| 12 |
+
|
| 13 |
+
# T2I-Adapter
|
| 14 |
+
|
| 15 |
+
[T2I-Adapter: Learning Adapters to Dig out More Controllable Ability for Text-to-Image Diffusion Models](https://huggingface.co/papers/2302.08453) by Chong Mou, Xintao Wang, Liangbin Xie, Jian Zhang, Zhongang Qi, Ying Shan, Xiaohu Qie.
|
| 16 |
+
|
| 17 |
+
Using the pretrained models we can provide control images (for example, a depth map) to control Stable Diffusion text-to-image generation so that it follows the structure of the depth image and fills in the details.
|
| 18 |
+
|
| 19 |
+
The abstract of the paper is the following:
|
| 20 |
+
|
| 21 |
+
*The incredible generative ability of large-scale text-to-image (T2I) models has demonstrated strong power of learning complex structures and meaningful semantics. However, relying solely on text prompts cannot fully take advantage of the knowledge learned by the model, especially when flexible and accurate controlling (e.g., color and structure) is needed. In this paper, we aim to ``dig out" the capabilities that T2I models have implicitly learned, and then explicitly use them to control the generation more granularly. Specifically, we propose to learn simple and lightweight T2I-Adapters to align internal knowledge in T2I models with external control signals, while freezing the original large T2I models. In this way, we can train various adapters according to different conditions, achieving rich control and editing effects in the color and structure of the generation results. Further, the proposed T2I-Adapters have attractive properties of practical value, such as composability and generalization ability. Extensive experiments demonstrate that our T2I-Adapter has promising generation quality and a wide range of applications.*
|
| 22 |
+
|
| 23 |
+
This model was contributed by the community contributor [HimariO](https://github.com/HimariO) ❤️ .
|
| 24 |
+
|
| 25 |
+
## StableDiffusionAdapterPipeline
|
| 26 |
+
|
| 27 |
+
[[autodoc]] StableDiffusionAdapterPipeline
|
| 28 |
+
- all
|
| 29 |
+
- __call__
|
| 30 |
+
- enable_attention_slicing
|
| 31 |
+
- disable_attention_slicing
|
| 32 |
+
- enable_vae_slicing
|
| 33 |
+
- disable_vae_slicing
|
| 34 |
+
- enable_xformers_memory_efficient_attention
|
| 35 |
+
- disable_xformers_memory_efficient_attention
|
| 36 |
+
|
| 37 |
+
## StableDiffusionXLAdapterPipeline
|
| 38 |
+
|
| 39 |
+
[[autodoc]] StableDiffusionXLAdapterPipeline
|
| 40 |
+
- all
|
| 41 |
+
- __call__
|
| 42 |
+
- enable_attention_slicing
|
| 43 |
+
- disable_attention_slicing
|
| 44 |
+
- enable_vae_slicing
|
| 45 |
+
- disable_vae_slicing
|
| 46 |
+
- enable_xformers_memory_efficient_attention
|
| 47 |
+
- disable_xformers_memory_efficient_attention
|
tasks/tasksmith-1c5704b1f07f/tests/source/docs/source/en/api/pipelines/stable_diffusion/depth2img.md
ADDED
|
@@ -0,0 +1,41 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
<!--Copyright 2025 The HuggingFace Team. All rights reserved.
|
| 2 |
+
|
| 3 |
+
Licensed under the Apache License, Version 2.0 (the "License"); you may not use this file except in compliance with
|
| 4 |
+
the License. You may obtain a copy of the License at
|
| 5 |
+
|
| 6 |
+
http://www.apache.org/licenses/LICENSE-2.0
|
| 7 |
+
|
| 8 |
+
Unless required by applicable law or agreed to in writing, software distributed under the License is distributed on
|
| 9 |
+
an "AS IS" BASIS, WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied. See the License for the
|
| 10 |
+
specific language governing permissions and limitations under the License.
|
| 11 |
+
-->
|
| 12 |
+
|
| 13 |
+
# Depth-to-image
|
| 14 |
+
|
| 15 |
+
<div class="flex flex-wrap space-x-1">
|
| 16 |
+
<img alt="LoRA" src="https://img.shields.io/badge/LoRA-d8b4fe?style=flat"/>
|
| 17 |
+
</div>
|
| 18 |
+
|
| 19 |
+
The Stable Diffusion model can also infer depth based on an image using [MiDaS](https://github.com/isl-org/MiDaS). This allows you to pass a text prompt and an initial image to condition the generation of new images as well as a `depth_map` to preserve the image structure.
|
| 20 |
+
|
| 21 |
+
> [!TIP]
|
| 22 |
+
> Make sure to check out the Stable Diffusion [Tips](overview#tips) section to learn how to explore the tradeoff between scheduler speed and quality, and how to reuse pipeline components efficiently!
|
| 23 |
+
>
|
| 24 |
+
> If you're interested in using one of the official checkpoints for a task, explore the [CompVis](https://huggingface.co/CompVis) and [Stability AI](https://huggingface.co/stabilityai) Hub organizations!
|
| 25 |
+
|
| 26 |
+
## StableDiffusionDepth2ImgPipeline
|
| 27 |
+
|
| 28 |
+
[[autodoc]] StableDiffusionDepth2ImgPipeline
|
| 29 |
+
- all
|
| 30 |
+
- __call__
|
| 31 |
+
- enable_attention_slicing
|
| 32 |
+
- disable_attention_slicing
|
| 33 |
+
- enable_xformers_memory_efficient_attention
|
| 34 |
+
- disable_xformers_memory_efficient_attention
|
| 35 |
+
- load_textual_inversion
|
| 36 |
+
- load_lora_weights
|
| 37 |
+
- save_lora_weights
|
| 38 |
+
|
| 39 |
+
## StableDiffusionPipelineOutput
|
| 40 |
+
|
| 41 |
+
[[autodoc]] pipelines.stable_diffusion.StableDiffusionPipelineOutput
|
tasks/tasksmith-1c5704b1f07f/tests/source/docs/source/en/api/pipelines/stable_diffusion/gligen.md
ADDED
|
@@ -0,0 +1,59 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
<!--Copyright 2025 The GLIGEN Authors and The HuggingFace Team. All rights reserved.
|
| 2 |
+
|
| 3 |
+
Licensed under the Apache License, Version 2.0 (the "License"); you may not use this file except in compliance with
|
| 4 |
+
the License. You may obtain a copy of the License at
|
| 5 |
+
|
| 6 |
+
http://www.apache.org/licenses/LICENSE-2.0
|
| 7 |
+
|
| 8 |
+
Unless required by applicable law or agreed to in writing, software distributed under the License is distributed on
|
| 9 |
+
an "AS IS" BASIS, WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied. See the License for the
|
| 10 |
+
specific language governing permissions and limitations under the License.
|
| 11 |
+
-->
|
| 12 |
+
|
| 13 |
+
> [!WARNING]
|
| 14 |
+
> This pipeline is deprecated but it can still be used. However, we won't test the pipeline anymore and won't accept any changes to it. If you run into any issues, reinstall the last Diffusers version that supported this model.
|
| 15 |
+
|
| 16 |
+
# GLIGEN (Grounded Language-to-Image Generation)
|
| 17 |
+
|
| 18 |
+
The GLIGEN model was created by researchers and engineers from [University of Wisconsin-Madison, Columbia University, and Microsoft](https://github.com/gligen/GLIGEN). The [`StableDiffusionGLIGENPipeline`] and [`StableDiffusionGLIGENTextImagePipeline`] can generate photorealistic images conditioned on grounding inputs. Along with text and bounding boxes with [`StableDiffusionGLIGENPipeline`], if input images are given, [`StableDiffusionGLIGENTextImagePipeline`] can insert objects described by text at the region defined by bounding boxes. Otherwise, it'll generate an image described by the caption/prompt and insert objects described by text at the region defined by bounding boxes. It's trained on COCO2014D and COCO2014CD datasets, and the model uses a frozen CLIP ViT-L/14 text encoder to condition itself on grounding inputs.
|
| 19 |
+
|
| 20 |
+
The abstract from the [paper](https://huggingface.co/papers/2301.07093) is:
|
| 21 |
+
|
| 22 |
+
*Large-scale text-to-image diffusion models have made amazing advances. However, the status quo is to use text input alone, which can impede controllability. In this work, we propose GLIGEN, Grounded-Language-to-Image Generation, a novel approach that builds upon and extends the functionality of existing pre-trained text-to-image diffusion models by enabling them to also be conditioned on grounding inputs. To preserve the vast concept knowledge of the pre-trained model, we freeze all of its weights and inject the grounding information into new trainable layers via a gated mechanism. Our model achieves open-world grounded text2img generation with caption and bounding box condition inputs, and the grounding ability generalizes well to novel spatial configurations and concepts. GLIGEN’s zeroshot performance on COCO and LVIS outperforms existing supervised layout-to-image baselines by a large margin.*
|
| 23 |
+
|
| 24 |
+
> [!TIP]
|
| 25 |
+
> Make sure to check out the Stable Diffusion [Tips](https://huggingface.co/docs/diffusers/en/api/pipelines/stable_diffusion/overview#tips) section to learn how to explore the tradeoff between scheduler speed and quality and how to reuse pipeline components efficiently!
|
| 26 |
+
>
|
| 27 |
+
> If you want to use one of the official checkpoints for a task, explore the [gligen](https://huggingface.co/gligen) Hub organizations!
|
| 28 |
+
|
| 29 |
+
[`StableDiffusionGLIGENPipeline`] was contributed by [Nikhil Gajendrakumar](https://github.com/nikhil-masterful) and [`StableDiffusionGLIGENTextImagePipeline`] was contributed by [Nguyễn Công Tú Anh](https://github.com/tuanh123789).
|
| 30 |
+
|
| 31 |
+
## StableDiffusionGLIGENPipeline
|
| 32 |
+
|
| 33 |
+
[[autodoc]] StableDiffusionGLIGENPipeline
|
| 34 |
+
- all
|
| 35 |
+
- __call__
|
| 36 |
+
- enable_vae_slicing
|
| 37 |
+
- disable_vae_slicing
|
| 38 |
+
- enable_vae_tiling
|
| 39 |
+
- disable_vae_tiling
|
| 40 |
+
- enable_model_cpu_offload
|
| 41 |
+
- prepare_latents
|
| 42 |
+
- enable_fuser
|
| 43 |
+
|
| 44 |
+
## StableDiffusionGLIGENTextImagePipeline
|
| 45 |
+
|
| 46 |
+
[[autodoc]] StableDiffusionGLIGENTextImagePipeline
|
| 47 |
+
- all
|
| 48 |
+
- __call__
|
| 49 |
+
- enable_vae_slicing
|
| 50 |
+
- disable_vae_slicing
|
| 51 |
+
- enable_vae_tiling
|
| 52 |
+
- disable_vae_tiling
|
| 53 |
+
- enable_model_cpu_offload
|
| 54 |
+
- prepare_latents
|
| 55 |
+
- enable_fuser
|
| 56 |
+
|
| 57 |
+
## StableDiffusionPipelineOutput
|
| 58 |
+
|
| 59 |
+
[[autodoc]] pipelines.stable_diffusion.StableDiffusionPipelineOutput
|
tasks/tasksmith-1c5704b1f07f/tests/source/docs/source/en/api/pipelines/stable_diffusion/image_variation.md
ADDED
|
@@ -0,0 +1,34 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
<!--Copyright 2025 The HuggingFace Team. All rights reserved.
|
| 2 |
+
|
| 3 |
+
Licensed under the Apache License, Version 2.0 (the "License"); you may not use this file except in compliance with
|
| 4 |
+
the License. You may obtain a copy of the License at
|
| 5 |
+
|
| 6 |
+
http://www.apache.org/licenses/LICENSE-2.0
|
| 7 |
+
|
| 8 |
+
Unless required by applicable law or agreed to in writing, software distributed under the License is distributed on
|
| 9 |
+
an "AS IS" BASIS, WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied. See the License for the
|
| 10 |
+
specific language governing permissions and limitations under the License.
|
| 11 |
+
-->
|
| 12 |
+
|
| 13 |
+
# Image variation
|
| 14 |
+
|
| 15 |
+
The Stable Diffusion model can also generate variations from an input image. It uses a fine-tuned version of a Stable Diffusion model by [Justin Pinkney](https://www.justinpinkney.com/) from [Lambda](https://lambdalabs.com/).
|
| 16 |
+
|
| 17 |
+
The original codebase can be found at [LambdaLabsML/lambda-diffusers](https://github.com/LambdaLabsML/lambda-diffusers#stable-diffusion-image-variations) and additional official checkpoints for image variation can be found at [lambdalabs/sd-image-variations-diffusers](https://huggingface.co/lambdalabs/sd-image-variations-diffusers).
|
| 18 |
+
|
| 19 |
+
> [!TIP]
|
| 20 |
+
> Make sure to check out the Stable Diffusion [Tips](./overview#tips) section to learn how to explore the tradeoff between scheduler speed and quality, and how to reuse pipeline components efficiently!
|
| 21 |
+
|
| 22 |
+
## StableDiffusionImageVariationPipeline
|
| 23 |
+
|
| 24 |
+
[[autodoc]] StableDiffusionImageVariationPipeline
|
| 25 |
+
- all
|
| 26 |
+
- __call__
|
| 27 |
+
- enable_attention_slicing
|
| 28 |
+
- disable_attention_slicing
|
| 29 |
+
- enable_xformers_memory_efficient_attention
|
| 30 |
+
- disable_xformers_memory_efficient_attention
|
| 31 |
+
|
| 32 |
+
## StableDiffusionPipelineOutput
|
| 33 |
+
|
| 34 |
+
[[autodoc]] pipelines.stable_diffusion.StableDiffusionPipelineOutput
|
tasks/tasksmith-1c5704b1f07f/tests/source/docs/source/en/api/pipelines/stable_diffusion/img2img.md
ADDED
|
@@ -0,0 +1,46 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
<!--Copyright 2025 The HuggingFace Team. All rights reserved.
|
| 2 |
+
|
| 3 |
+
Licensed under the Apache License, Version 2.0 (the "License"); you may not use this file except in compliance with
|
| 4 |
+
the License. You may obtain a copy of the License at
|
| 5 |
+
|
| 6 |
+
http://www.apache.org/licenses/LICENSE-2.0
|
| 7 |
+
|
| 8 |
+
Unless required by applicable law or agreed to in writing, software distributed under the License is distributed on
|
| 9 |
+
an "AS IS" BASIS, WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied. See the License for the
|
| 10 |
+
specific language governing permissions and limitations under the License.
|
| 11 |
+
-->
|
| 12 |
+
|
| 13 |
+
# Image-to-image
|
| 14 |
+
|
| 15 |
+
<div class="flex flex-wrap space-x-1">
|
| 16 |
+
<img alt="LoRA" src="https://img.shields.io/badge/LoRA-d8b4fe?style=flat"/>
|
| 17 |
+
</div>
|
| 18 |
+
|
| 19 |
+
The Stable Diffusion model can also be applied to image-to-image generation by passing a text prompt and an initial image to condition the generation of new images.
|
| 20 |
+
|
| 21 |
+
The [`StableDiffusionImg2ImgPipeline`] uses the diffusion-denoising mechanism proposed in [SDEdit: Guided Image Synthesis and Editing with Stochastic Differential Equations](https://huggingface.co/papers/2108.01073) by Chenlin Meng, Yutong He, Yang Song, Jiaming Song, Jiajun Wu, Jun-Yan Zhu, Stefano Ermon.
|
| 22 |
+
|
| 23 |
+
The abstract from the paper is:
|
| 24 |
+
|
| 25 |
+
*Guided image synthesis enables everyday users to create and edit photo-realistic images with minimum effort. The key challenge is balancing faithfulness to the user input (e.g., hand-drawn colored strokes) and realism of the synthesized image. Existing GAN-based methods attempt to achieve such balance using either conditional GANs or GAN inversions, which are challenging and often require additional training data or loss functions for individual applications. To address these issues, we introduce a new image synthesis and editing method, Stochastic Differential Editing (SDEdit), based on a diffusion model generative prior, which synthesizes realistic images by iteratively denoising through a stochastic differential equation (SDE). Given an input image with user guide of any type, SDEdit first adds noise to the input, then subsequently denoises the resulting image through the SDE prior to increase its realism. SDEdit does not require task-specific training or inversions and can naturally achieve the balance between realism and faithfulness. SDEdit significantly outperforms state-of-the-art GAN-based methods by up to 98.09% on realism and 91.72% on overall satisfaction scores, according to a human perception study, on multiple tasks, including stroke-based image synthesis and editing as well as image compositing.*
|
| 26 |
+
|
| 27 |
+
> [!TIP]
|
| 28 |
+
> Make sure to check out the Stable Diffusion [Tips](overview#tips) section to learn how to explore the tradeoff between scheduler speed and quality, and how to reuse pipeline components efficiently!
|
| 29 |
+
|
| 30 |
+
## StableDiffusionImg2ImgPipeline
|
| 31 |
+
|
| 32 |
+
[[autodoc]] StableDiffusionImg2ImgPipeline
|
| 33 |
+
- all
|
| 34 |
+
- __call__
|
| 35 |
+
- enable_attention_slicing
|
| 36 |
+
- disable_attention_slicing
|
| 37 |
+
- enable_xformers_memory_efficient_attention
|
| 38 |
+
- disable_xformers_memory_efficient_attention
|
| 39 |
+
- load_textual_inversion
|
| 40 |
+
- from_single_file
|
| 41 |
+
- load_lora_weights
|
| 42 |
+
- save_lora_weights
|
| 43 |
+
|
| 44 |
+
## StableDiffusionPipelineOutput
|
| 45 |
+
|
| 46 |
+
[[autodoc]] pipelines.stable_diffusion.StableDiffusionPipelineOutput
|
tasks/tasksmith-1c5704b1f07f/tests/source/docs/source/en/api/pipelines/stable_diffusion/inpaint.md
ADDED
|
@@ -0,0 +1,48 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
<!--Copyright 2025 The HuggingFace Team. All rights reserved.
|
| 2 |
+
|
| 3 |
+
Licensed under the Apache License, Version 2.0 (the "License"); you may not use this file except in compliance with
|
| 4 |
+
the License. You may obtain a copy of the License at
|
| 5 |
+
|
| 6 |
+
http://www.apache.org/licenses/LICENSE-2.0
|
| 7 |
+
|
| 8 |
+
Unless required by applicable law or agreed to in writing, software distributed under the License is distributed on
|
| 9 |
+
an "AS IS" BASIS, WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied. See the License for the
|
| 10 |
+
specific language governing permissions and limitations under the License.
|
| 11 |
+
-->
|
| 12 |
+
|
| 13 |
+
# Inpainting
|
| 14 |
+
|
| 15 |
+
<div class="flex flex-wrap space-x-1">
|
| 16 |
+
<img alt="LoRA" src="https://img.shields.io/badge/LoRA-d8b4fe?style=flat"/>
|
| 17 |
+
</div>
|
| 18 |
+
|
| 19 |
+
The Stable Diffusion model can also be applied to inpainting which lets you edit specific parts of an image by providing a mask and a text prompt using Stable Diffusion.
|
| 20 |
+
|
| 21 |
+
## Tips
|
| 22 |
+
|
| 23 |
+
It is recommended to use this pipeline with checkpoints that have been specifically fine-tuned for inpainting, such
|
| 24 |
+
as [stable-diffusion-v1-5/stable-diffusion-inpainting](https://huggingface.co/stable-diffusion-v1-5/stable-diffusion-inpainting). Default
|
| 25 |
+
text-to-image Stable Diffusion checkpoints, such as
|
| 26 |
+
[stable-diffusion-v1-5/stable-diffusion-v1-5](https://huggingface.co/stable-diffusion-v1-5/stable-diffusion-v1-5) are also compatible but they might be less performant.
|
| 27 |
+
|
| 28 |
+
> [!TIP]
|
| 29 |
+
> Make sure to check out the Stable Diffusion [Tips](overview#tips) section to learn how to explore the tradeoff between scheduler speed and quality, and how to reuse pipeline components efficiently!
|
| 30 |
+
>
|
| 31 |
+
> If you're interested in using one of the official checkpoints for a task, explore the [CompVis](https://huggingface.co/CompVis) and [Stability AI](https://huggingface.co/stabilityai) Hub organizations!
|
| 32 |
+
|
| 33 |
+
## StableDiffusionInpaintPipeline
|
| 34 |
+
|
| 35 |
+
[[autodoc]] StableDiffusionInpaintPipeline
|
| 36 |
+
- all
|
| 37 |
+
- __call__
|
| 38 |
+
- enable_attention_slicing
|
| 39 |
+
- disable_attention_slicing
|
| 40 |
+
- enable_xformers_memory_efficient_attention
|
| 41 |
+
- disable_xformers_memory_efficient_attention
|
| 42 |
+
- load_textual_inversion
|
| 43 |
+
- load_lora_weights
|
| 44 |
+
- save_lora_weights
|
| 45 |
+
|
| 46 |
+
## StableDiffusionPipelineOutput
|
| 47 |
+
|
| 48 |
+
[[autodoc]] pipelines.stable_diffusion.StableDiffusionPipelineOutput
|
tasks/tasksmith-1c5704b1f07f/tests/source/docs/source/en/api/pipelines/stable_diffusion/k_diffusion.md
ADDED
|
@@ -0,0 +1,30 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
<!--Copyright 2025 The HuggingFace Team. All rights reserved.
|
| 2 |
+
|
| 3 |
+
Licensed under the Apache License, Version 2.0 (the "License"); you may not use this file except in compliance with
|
| 4 |
+
the License. You may obtain a copy of the License at
|
| 5 |
+
|
| 6 |
+
http://www.apache.org/licenses/LICENSE-2.0
|
| 7 |
+
|
| 8 |
+
Unless required by applicable law or agreed to in writing, software distributed under the License is distributed on
|
| 9 |
+
an "AS IS" BASIS, WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied. See the License for the
|
| 10 |
+
specific language governing permissions and limitations under the License.
|
| 11 |
+
-->
|
| 12 |
+
|
| 13 |
+
> [!WARNING]
|
| 14 |
+
> This pipeline is deprecated but it can still be used. However, we won't test the pipeline anymore and won't accept any changes to it. If you run into any issues, reinstall the last Diffusers version that supported this model.
|
| 15 |
+
|
| 16 |
+
# K-Diffusion
|
| 17 |
+
|
| 18 |
+
[k-diffusion](https://github.com/crowsonkb/k-diffusion) is a popular library created by [Katherine Crowson](https://github.com/crowsonkb/). We provide `StableDiffusionKDiffusionPipeline` and `StableDiffusionXLKDiffusionPipeline` that allow you to run Stable DIffusion with samplers from k-diffusion.
|
| 19 |
+
|
| 20 |
+
Note that most the samplers from k-diffusion are implemented in Diffusers and we recommend using existing schedulers. You can find a mapping between k-diffusion samplers and schedulers in Diffusers [here](https://huggingface.co/docs/diffusers/api/schedulers/overview)
|
| 21 |
+
|
| 22 |
+
|
| 23 |
+
## StableDiffusionKDiffusionPipeline
|
| 24 |
+
|
| 25 |
+
[[autodoc]] StableDiffusionKDiffusionPipeline
|
| 26 |
+
|
| 27 |
+
|
| 28 |
+
## StableDiffusionXLKDiffusionPipeline
|
| 29 |
+
|
| 30 |
+
[[autodoc]] StableDiffusionXLKDiffusionPipeline
|
tasks/tasksmith-1c5704b1f07f/tests/source/docs/source/en/api/pipelines/stable_diffusion/latent_upscale.md
ADDED
|
@@ -0,0 +1,35 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
<!--Copyright 2025 The HuggingFace Team. All rights reserved.
|
| 2 |
+
|
| 3 |
+
Licensed under the Apache License, Version 2.0 (the "License"); you may not use this file except in compliance with
|
| 4 |
+
the License. You may obtain a copy of the License at
|
| 5 |
+
|
| 6 |
+
http://www.apache.org/licenses/LICENSE-2.0
|
| 7 |
+
|
| 8 |
+
Unless required by applicable law or agreed to in writing, software distributed under the License is distributed on
|
| 9 |
+
an "AS IS" BASIS, WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied. See the License for the
|
| 10 |
+
specific language governing permissions and limitations under the License.
|
| 11 |
+
-->
|
| 12 |
+
|
| 13 |
+
# Latent upscaler
|
| 14 |
+
|
| 15 |
+
The Stable Diffusion latent upscaler model was created by [Katherine Crowson](https://github.com/crowsonkb/k-diffusion) in collaboration with [Stability AI](https://stability.ai/). It is used to enhance the output image resolution by a factor of 2 (see this demo [notebook](https://colab.research.google.com/drive/1o1qYJcFeywzCIdkfKJy7cTpgZTCM2EI4) for a demonstration of the original implementation).
|
| 16 |
+
|
| 17 |
+
> [!TIP]
|
| 18 |
+
> Make sure to check out the Stable Diffusion [Tips](overview#tips) section to learn how to explore the tradeoff between scheduler speed and quality, and how to reuse pipeline components efficiently!
|
| 19 |
+
>
|
| 20 |
+
> If you're interested in using one of the official checkpoints for a task, explore the [CompVis](https://huggingface.co/CompVis) and [Stability AI](https://huggingface.co/stabilityai) Hub organizations!
|
| 21 |
+
|
| 22 |
+
## StableDiffusionLatentUpscalePipeline
|
| 23 |
+
|
| 24 |
+
[[autodoc]] StableDiffusionLatentUpscalePipeline
|
| 25 |
+
- all
|
| 26 |
+
- __call__
|
| 27 |
+
- enable_sequential_cpu_offload
|
| 28 |
+
- enable_attention_slicing
|
| 29 |
+
- disable_attention_slicing
|
| 30 |
+
- enable_xformers_memory_efficient_attention
|
| 31 |
+
- disable_xformers_memory_efficient_attention
|
| 32 |
+
|
| 33 |
+
## StableDiffusionPipelineOutput
|
| 34 |
+
|
| 35 |
+
[[autodoc]] pipelines.stable_diffusion.StableDiffusionPipelineOutput
|
tasks/tasksmith-1c5704b1f07f/tests/source/docs/source/en/api/pipelines/stable_diffusion/ldm3d_diffusion.md
ADDED
|
@@ -0,0 +1,59 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
<!--Copyright 2025 The Intel Labs Team Authors and HuggingFace Team. All rights reserved.
|
| 2 |
+
|
| 3 |
+
Licensed under the Apache License, Version 2.0 (the "License"); you may not use this file except in compliance with
|
| 4 |
+
the License. You may obtain a copy of the License at
|
| 5 |
+
|
| 6 |
+
http://www.apache.org/licenses/LICENSE-2.0
|
| 7 |
+
|
| 8 |
+
Unless required by applicable law or agreed to in writing, software distributed under the License is distributed on
|
| 9 |
+
an "AS IS" BASIS, WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied. See the License for the
|
| 10 |
+
specific language governing permissions and limitations under the License.
|
| 11 |
+
-->
|
| 12 |
+
|
| 13 |
+
> [!WARNING]
|
| 14 |
+
> This pipeline is deprecated but it can still be used. However, we won't test the pipeline anymore and won't accept any changes to it. If you run into any issues, reinstall the last Diffusers version that supported this model.
|
| 15 |
+
|
| 16 |
+
# Text-to-(RGB, depth)
|
| 17 |
+
|
| 18 |
+
<div class="flex flex-wrap space-x-1">
|
| 19 |
+
<img alt="LoRA" src="https://img.shields.io/badge/LoRA-d8b4fe?style=flat"/>
|
| 20 |
+
</div>
|
| 21 |
+
|
| 22 |
+
LDM3D was proposed in [LDM3D: Latent Diffusion Model for 3D](https://huggingface.co/papers/2305.10853) by Gabriela Ben Melech Stan, Diana Wofk, Scottie Fox, Alex Redden, Will Saxton, Jean Yu, Estelle Aflalo, Shao-Yen Tseng, Fabio Nonato, Matthias Muller, and Vasudev Lal. LDM3D generates an image and a depth map from a given text prompt unlike the existing text-to-image diffusion models such as [Stable Diffusion](./overview) which only generates an image. With almost the same number of parameters, LDM3D achieves to create a latent space that can compress both the RGB images and the depth maps.
|
| 23 |
+
|
| 24 |
+
Two checkpoints are available for use:
|
| 25 |
+
- [ldm3d-original](https://huggingface.co/Intel/ldm3d). The original checkpoint used in the [paper](https://huggingface.co/papers/2305.10853)
|
| 26 |
+
- [ldm3d-4c](https://huggingface.co/Intel/ldm3d-4c). The new version of LDM3D using 4 channels inputs instead of 6-channels inputs and finetuned on higher resolution images.
|
| 27 |
+
|
| 28 |
+
|
| 29 |
+
The abstract from the paper is:
|
| 30 |
+
|
| 31 |
+
*This research paper proposes a Latent Diffusion Model for 3D (LDM3D) that generates both image and depth map data from a given text prompt, allowing users to generate RGBD images from text prompts. The LDM3D model is fine-tuned on a dataset of tuples containing an RGB image, depth map and caption, and validated through extensive experiments. We also develop an application called DepthFusion, which uses the generated RGB images and depth maps to create immersive and interactive 360-degree-view experiences using TouchDesigner. This technology has the potential to transform a wide range of industries, from entertainment and gaming to architecture and design. Overall, this paper presents a significant contribution to the field of generative AI and computer vision, and showcases the potential of LDM3D and DepthFusion to revolutionize content creation and digital experiences. A short video summarizing the approach can be found at [this url](https://t.ly/tdi2).*
|
| 32 |
+
|
| 33 |
+
> [!TIP]
|
| 34 |
+
> Make sure to check out the Stable Diffusion [Tips](overview#tips) section to learn how to explore the tradeoff between scheduler speed and quality, and how to reuse pipeline components efficiently!
|
| 35 |
+
|
| 36 |
+
## StableDiffusionLDM3DPipeline
|
| 37 |
+
|
| 38 |
+
[[autodoc]] pipelines.stable_diffusion_ldm3d.pipeline_stable_diffusion_ldm3d.StableDiffusionLDM3DPipeline
|
| 39 |
+
- all
|
| 40 |
+
- __call__
|
| 41 |
+
|
| 42 |
+
|
| 43 |
+
## LDM3DPipelineOutput
|
| 44 |
+
|
| 45 |
+
[[autodoc]] pipelines.stable_diffusion_ldm3d.pipeline_stable_diffusion_ldm3d.LDM3DPipelineOutput
|
| 46 |
+
- all
|
| 47 |
+
- __call__
|
| 48 |
+
|
| 49 |
+
# Upscaler
|
| 50 |
+
|
| 51 |
+
[LDM3D-VR](https://huggingface.co/papers/2311.03226) is an extended version of LDM3D.
|
| 52 |
+
|
| 53 |
+
The abstract from the paper is:
|
| 54 |
+
*Latent diffusion models have proven to be state-of-the-art in the creation and manipulation of visual outputs. However, as far as we know, the generation of depth maps jointly with RGB is still limited. We introduce LDM3D-VR, a suite of diffusion models targeting virtual reality development that includes LDM3D-pano and LDM3D-SR. These models enable the generation of panoramic RGBD based on textual prompts and the upscaling of low-resolution inputs to high-resolution RGBD, respectively. Our models are fine-tuned from existing pretrained models on datasets containing panoramic/high-resolution RGB images, depth maps and captions. Both models are evaluated in comparison to existing related methods*
|
| 55 |
+
|
| 56 |
+
Two checkpoints are available for use:
|
| 57 |
+
- [ldm3d-pano](https://huggingface.co/Intel/ldm3d-pano). This checkpoint enables the generation of panoramic images and requires the StableDiffusionLDM3DPipeline pipeline to be used.
|
| 58 |
+
- [ldm3d-sr](https://huggingface.co/Intel/ldm3d-sr). This checkpoint enables the upscaling of RGB and depth images. Can be used in cascade after the original LDM3D pipeline using the StableDiffusionUpscaleLDM3DPipeline from communauty pipeline.
|
| 59 |
+
|
tasks/tasksmith-1c5704b1f07f/tests/source/docs/source/en/api/pipelines/stable_diffusion/overview.md
ADDED
|
@@ -0,0 +1,216 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
<!--Copyright 2025 The HuggingFace Team. All rights reserved.
|
| 2 |
+
|
| 3 |
+
Licensed under the Apache License, Version 2.0 (the "License"); you may not use this file except in compliance with
|
| 4 |
+
the License. You may obtain a copy of the License at
|
| 5 |
+
|
| 6 |
+
http://www.apache.org/licenses/LICENSE-2.0
|
| 7 |
+
|
| 8 |
+
Unless required by applicable law or agreed to in writing, software distributed under the License is distributed on
|
| 9 |
+
an "AS IS" BASIS, WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied. See the License for the
|
| 10 |
+
specific language governing permissions and limitations under the License.
|
| 11 |
+
-->
|
| 12 |
+
|
| 13 |
+
# Stable Diffusion pipelines
|
| 14 |
+
|
| 15 |
+
<div class="flex flex-wrap space-x-1">
|
| 16 |
+
<img alt="LoRA" src="https://img.shields.io/badge/LoRA-d8b4fe?style=flat"/>
|
| 17 |
+
</div>
|
| 18 |
+
|
| 19 |
+
Stable Diffusion is a text-to-image latent diffusion model created by the researchers and engineers from [CompVis](https://github.com/CompVis), [Stability AI](https://stability.ai/) and [LAION](https://laion.ai/). Latent diffusion applies the diffusion process over a lower dimensional latent space to reduce memory and compute complexity. This specific type of diffusion model was proposed in [High-Resolution Image Synthesis with Latent Diffusion Models](https://huggingface.co/papers/2112.10752) by Robin Rombach, Andreas Blattmann, Dominik Lorenz, Patrick Esser, Björn Ommer.
|
| 20 |
+
|
| 21 |
+
Stable Diffusion is trained on 512x512 images from a subset of the LAION-5B dataset. This model uses a frozen CLIP ViT-L/14 text encoder to condition the model on text prompts. With its 860M UNet and 123M text encoder, the model is relatively lightweight and can run on consumer GPUs.
|
| 22 |
+
|
| 23 |
+
For more details about how Stable Diffusion works and how it differs from the base latent diffusion model, take a look at the Stability AI [announcement](https://stability.ai/blog/stable-diffusion-announcement) and our own [blog post](https://huggingface.co/blog/stable_diffusion#how-does-stable-diffusion-work) for more technical details.
|
| 24 |
+
|
| 25 |
+
You can find the original codebase for Stable Diffusion v1.0 at [CompVis/stable-diffusion](https://github.com/CompVis/stable-diffusion) and Stable Diffusion v2.0 at [Stability-AI/stablediffusion](https://github.com/Stability-AI/stablediffusion) as well as their original scripts for various tasks. Additional official checkpoints for the different Stable Diffusion versions and tasks can be found on the [CompVis](https://huggingface.co/CompVis) and [Stability AI](https://huggingface.co/stabilityai) Hub organizations. Explore these organizations to find the best checkpoint for your use-case!
|
| 26 |
+
|
| 27 |
+
The table below summarizes the available Stable Diffusion pipelines, their supported tasks, and an interactive demo:
|
| 28 |
+
|
| 29 |
+
<div class="flex justify-center">
|
| 30 |
+
<div class="rounded-xl border border-gray-200">
|
| 31 |
+
<table class="min-w-full divide-y-2 divide-gray-200 bg-white text-sm">
|
| 32 |
+
<thead>
|
| 33 |
+
<tr>
|
| 34 |
+
<th class="px-4 py-2 font-medium text-gray-900 text-left">
|
| 35 |
+
Pipeline
|
| 36 |
+
</th>
|
| 37 |
+
<th class="px-4 py-2 font-medium text-gray-900 text-left">
|
| 38 |
+
Supported tasks
|
| 39 |
+
</th>
|
| 40 |
+
<th class="px-4 py-2 font-medium text-gray-900 text-left">
|
| 41 |
+
🤗 Space
|
| 42 |
+
</th>
|
| 43 |
+
</tr>
|
| 44 |
+
</thead>
|
| 45 |
+
<tbody class="divide-y divide-gray-200">
|
| 46 |
+
<tr>
|
| 47 |
+
<td class="px-4 py-2 text-gray-700">
|
| 48 |
+
<a href="./text2img">StableDiffusion</a>
|
| 49 |
+
</td>
|
| 50 |
+
<td class="px-4 py-2 text-gray-700">text-to-image</td>
|
| 51 |
+
<td class="px-4 py-2"><a href="https://huggingface.co/spaces/stabilityai/stable-diffusion"><img src="https://img.shields.io/badge/%F0%9F%A4%97%20Hugging%20Face-Spaces-blue"/></a>
|
| 52 |
+
</td>
|
| 53 |
+
</tr>
|
| 54 |
+
<tr>
|
| 55 |
+
<td class="px-4 py-2 text-gray-700">
|
| 56 |
+
<a href="./img2img">StableDiffusionImg2Img</a>
|
| 57 |
+
</td>
|
| 58 |
+
<td class="px-4 py-2 text-gray-700">image-to-image</td>
|
| 59 |
+
<td class="px-4 py-2"><a href="https://huggingface.co/spaces/huggingface/diffuse-the-rest"><img src="https://img.shields.io/badge/%F0%9F%A4%97%20Hugging%20Face-Spaces-blue"/></a>
|
| 60 |
+
</td>
|
| 61 |
+
</tr>
|
| 62 |
+
<tr>
|
| 63 |
+
<td class="px-4 py-2 text-gray-700">
|
| 64 |
+
<a href="./inpaint">StableDiffusionInpaint</a>
|
| 65 |
+
</td>
|
| 66 |
+
<td class="px-4 py-2 text-gray-700">inpainting</td>
|
| 67 |
+
<td class="px-4 py-2"><a href="https://huggingface.co/spaces/stable-diffusion-v1-5/stable-diffusion-inpainting"><img src="https://img.shields.io/badge/%F0%9F%A4%97%20Hugging%20Face-Spaces-blue"/></a>
|
| 68 |
+
</td>
|
| 69 |
+
</tr>
|
| 70 |
+
<tr>
|
| 71 |
+
<td class="px-4 py-2 text-gray-700">
|
| 72 |
+
<a href="./depth2img">StableDiffusionDepth2Img</a>
|
| 73 |
+
</td>
|
| 74 |
+
<td class="px-4 py-2 text-gray-700">depth-to-image</td>
|
| 75 |
+
<td class="px-4 py-2"><a href="https://huggingface.co/spaces/radames/stable-diffusion-depth2img"><img src="https://img.shields.io/badge/%F0%9F%A4%97%20Hugging%20Face-Spaces-blue"/></a>
|
| 76 |
+
</td>
|
| 77 |
+
</tr>
|
| 78 |
+
<tr>
|
| 79 |
+
<td class="px-4 py-2 text-gray-700">
|
| 80 |
+
<a href="./image_variation">StableDiffusionImageVariation</a>
|
| 81 |
+
</td>
|
| 82 |
+
<td class="px-4 py-2 text-gray-700">image variation</td>
|
| 83 |
+
<td class="px-4 py-2"><a href="https://huggingface.co/spaces/lambdalabs/stable-diffusion-image-variations"><img src="https://img.shields.io/badge/%F0%9F%A4%97%20Hugging%20Face-Spaces-blue"/></a>
|
| 84 |
+
</td>
|
| 85 |
+
</tr>
|
| 86 |
+
<tr>
|
| 87 |
+
<td class="px-4 py-2 text-gray-700">
|
| 88 |
+
<a href="./stable_diffusion_safe">StableDiffusionPipelineSafe</a>
|
| 89 |
+
</td>
|
| 90 |
+
<td class="px-4 py-2 text-gray-700">filtered text-to-image</td>
|
| 91 |
+
<td class="px-4 py-2"><a href="https://huggingface.co/spaces/AIML-TUDA/unsafe-vs-safe-stable-diffusion"><img src="https://img.shields.io/badge/%F0%9F%A4%97%20Hugging%20Face-Spaces-blue"/></a>
|
| 92 |
+
</td>
|
| 93 |
+
</tr>
|
| 94 |
+
<tr>
|
| 95 |
+
<td class="px-4 py-2 text-gray-700">
|
| 96 |
+
<a href="./stable_diffusion_2">StableDiffusion2</a>
|
| 97 |
+
</td>
|
| 98 |
+
<td class="px-4 py-2 text-gray-700">text-to-image, inpainting, depth-to-image, super-resolution</td>
|
| 99 |
+
<td class="px-4 py-2"><a href="https://huggingface.co/spaces/stabilityai/stable-diffusion"><img src="https://img.shields.io/badge/%F0%9F%A4%97%20Hugging%20Face-Spaces-blue"/></a>
|
| 100 |
+
</td>
|
| 101 |
+
</tr>
|
| 102 |
+
<tr>
|
| 103 |
+
<td class="px-4 py-2 text-gray-700">
|
| 104 |
+
<a href="./stable_diffusion_xl">StableDiffusionXL</a>
|
| 105 |
+
</td>
|
| 106 |
+
<td class="px-4 py-2 text-gray-700">text-to-image, image-to-image</td>
|
| 107 |
+
<td class="px-4 py-2"><a href="https://huggingface.co/spaces/RamAnanth1/stable-diffusion-xl"><img src="https://img.shields.io/badge/%F0%9F%A4%97%20Hugging%20Face-Spaces-blue"/></a>
|
| 108 |
+
</td>
|
| 109 |
+
</tr>
|
| 110 |
+
<tr>
|
| 111 |
+
<td class="px-4 py-2 text-gray-700">
|
| 112 |
+
<a href="./latent_upscale">StableDiffusionLatentUpscale</a>
|
| 113 |
+
</td>
|
| 114 |
+
<td class="px-4 py-2 text-gray-700">super-resolution</td>
|
| 115 |
+
<td class="px-4 py-2"><a href="https://huggingface.co/spaces/huggingface-projects/stable-diffusion-latent-upscaler"><img src="https://img.shields.io/badge/%F0%9F%A4%97%20Hugging%20Face-Spaces-blue"/></a>
|
| 116 |
+
</td>
|
| 117 |
+
</tr>
|
| 118 |
+
<tr>
|
| 119 |
+
<td class="px-4 py-2 text-gray-700">
|
| 120 |
+
<a href="./upscale">StableDiffusionUpscale</a>
|
| 121 |
+
</td>
|
| 122 |
+
<td class="px-4 py-2 text-gray-700">super-resolution</td>
|
| 123 |
+
</tr>
|
| 124 |
+
<tr>
|
| 125 |
+
<td class="px-4 py-2 text-gray-700">
|
| 126 |
+
<a href="./ldm3d_diffusion">StableDiffusionLDM3D</a>
|
| 127 |
+
</td>
|
| 128 |
+
<td class="px-4 py-2 text-gray-700">text-to-rgb, text-to-depth, text-to-pano</td>
|
| 129 |
+
<td class="px-4 py-2"><a href="https://huggingface.co/spaces/r23/ldm3d-space"><img src="https://img.shields.io/badge/%F0%9F%A4%97%20Hugging%20Face-Spaces-blue"/></a>
|
| 130 |
+
</td>
|
| 131 |
+
</tr>
|
| 132 |
+
<tr>
|
| 133 |
+
<td class="px-4 py-2 text-gray-700">
|
| 134 |
+
<a href="./ldm3d_diffusion">StableDiffusionUpscaleLDM3D</a>
|
| 135 |
+
</td>
|
| 136 |
+
<td class="px-4 py-2 text-gray-700">ldm3d super-resolution</td>
|
| 137 |
+
</tr>
|
| 138 |
+
</tbody>
|
| 139 |
+
</table>
|
| 140 |
+
</div>
|
| 141 |
+
</div>
|
| 142 |
+
|
| 143 |
+
## Tips
|
| 144 |
+
|
| 145 |
+
To help you get the most out of the Stable Diffusion pipelines, here are a few tips for improving performance and usability. These tips are applicable to all Stable Diffusion pipelines.
|
| 146 |
+
|
| 147 |
+
### Explore tradeoff between speed and quality
|
| 148 |
+
|
| 149 |
+
[`StableDiffusionPipeline`] uses the [`PNDMScheduler`] by default, but 🤗 Diffusers provides many other schedulers (some of which are faster or output better quality) that are compatible. For example, if you want to use the [`EulerDiscreteScheduler`] instead of the default:
|
| 150 |
+
|
| 151 |
+
```py
|
| 152 |
+
from diffusers import StableDiffusionPipeline, EulerDiscreteScheduler
|
| 153 |
+
|
| 154 |
+
pipeline = StableDiffusionPipeline.from_pretrained("CompVis/stable-diffusion-v1-4")
|
| 155 |
+
pipeline.scheduler = EulerDiscreteScheduler.from_config(pipeline.scheduler.config)
|
| 156 |
+
|
| 157 |
+
# or
|
| 158 |
+
euler_scheduler = EulerDiscreteScheduler.from_pretrained("CompVis/stable-diffusion-v1-4", subfolder="scheduler")
|
| 159 |
+
pipeline = StableDiffusionPipeline.from_pretrained("CompVis/stable-diffusion-v1-4", scheduler=euler_scheduler)
|
| 160 |
+
```
|
| 161 |
+
|
| 162 |
+
### Reuse pipeline components to save memory
|
| 163 |
+
|
| 164 |
+
To save memory and use the same components across multiple pipelines, use the `.components` method to avoid loading weights into RAM more than once.
|
| 165 |
+
|
| 166 |
+
```py
|
| 167 |
+
from diffusers import (
|
| 168 |
+
StableDiffusionPipeline,
|
| 169 |
+
StableDiffusionImg2ImgPipeline,
|
| 170 |
+
StableDiffusionInpaintPipeline,
|
| 171 |
+
)
|
| 172 |
+
|
| 173 |
+
text2img = StableDiffusionPipeline.from_pretrained("CompVis/stable-diffusion-v1-4")
|
| 174 |
+
img2img = StableDiffusionImg2ImgPipeline(**text2img.components)
|
| 175 |
+
inpaint = StableDiffusionInpaintPipeline(**text2img.components)
|
| 176 |
+
|
| 177 |
+
# now you can use text2img(...), img2img(...), inpaint(...) just like the call methods of each respective pipeline
|
| 178 |
+
```
|
| 179 |
+
|
| 180 |
+
### Create web demos using `gradio`
|
| 181 |
+
|
| 182 |
+
The Stable Diffusion pipelines are automatically supported in [Gradio](https://github.com/gradio-app/gradio/), a library that makes creating beautiful and user-friendly machine learning apps on the web a breeze. First, make sure you have Gradio installed:
|
| 183 |
+
|
| 184 |
+
```sh
|
| 185 |
+
pip install -U gradio
|
| 186 |
+
```
|
| 187 |
+
|
| 188 |
+
Then, create a web demo around any Stable Diffusion-based pipeline. For example, you can create an image generation pipeline in a single line of code with Gradio's [`Interface.from_pipeline`](https://www.gradio.app/docs/interface#interface-from-pipeline) function:
|
| 189 |
+
|
| 190 |
+
```py
|
| 191 |
+
from diffusers import StableDiffusionPipeline
|
| 192 |
+
import gradio as gr
|
| 193 |
+
|
| 194 |
+
pipe = StableDiffusionPipeline.from_pretrained("CompVis/stable-diffusion-v1-4")
|
| 195 |
+
|
| 196 |
+
gr.Interface.from_pipeline(pipe).launch()
|
| 197 |
+
```
|
| 198 |
+
|
| 199 |
+
which opens an intuitive drag-and-drop interface in your browser:
|
| 200 |
+
|
| 201 |
+
|
| 202 |
+
|
| 203 |
+
Similarly, you could create a demo for an image-to-image pipeline with:
|
| 204 |
+
|
| 205 |
+
```py
|
| 206 |
+
from diffusers import StableDiffusionImg2ImgPipeline
|
| 207 |
+
import gradio as gr
|
| 208 |
+
|
| 209 |
+
|
| 210 |
+
pipe = StableDiffusionImg2ImgPipeline.from_pretrained("stable-diffusion-v1-5/stable-diffusion-v1-5")
|
| 211 |
+
|
| 212 |
+
gr.Interface.from_pipeline(pipe).launch()
|
| 213 |
+
```
|
| 214 |
+
|
| 215 |
+
By default, the web demo runs on a local server. If you'd like to share it with others, you can generate a temporary public
|
| 216 |
+
link by setting `share=True` in `launch()`. Or, you can host your demo on [Hugging Face Spaces](https://huggingface.co/spaces)https://huggingface.co/spaces for a permanent link.
|
tasks/tasksmith-1c5704b1f07f/tests/source/docs/source/en/api/pipelines/stable_diffusion/sdxl_turbo.md
ADDED
|
@@ -0,0 +1,32 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
<!--Copyright 2025 The HuggingFace Team. All rights reserved.
|
| 2 |
+
|
| 3 |
+
Licensed under the Apache License, Version 2.0 (the "License"); you may not use this file except in compliance with
|
| 4 |
+
the License. You may obtain a copy of the License at
|
| 5 |
+
|
| 6 |
+
http://www.apache.org/licenses/LICENSE-2.0
|
| 7 |
+
|
| 8 |
+
Unless required by applicable law or agreed to in writing, software distributed under the License is distributed on
|
| 9 |
+
an "AS IS" BASIS, WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied. See the License for the
|
| 10 |
+
specific language governing permissions and limitations under the License.
|
| 11 |
+
-->
|
| 12 |
+
|
| 13 |
+
# SDXL Turbo
|
| 14 |
+
|
| 15 |
+
Stable Diffusion XL (SDXL) Turbo was proposed in [Adversarial Diffusion Distillation](https://stability.ai/research/adversarial-diffusion-distillation) by Axel Sauer, Dominik Lorenz, Andreas Blattmann, and Robin Rombach.
|
| 16 |
+
|
| 17 |
+
The abstract from the paper is:
|
| 18 |
+
|
| 19 |
+
*We introduce Adversarial Diffusion Distillation (ADD), a novel training approach that efficiently samples large-scale foundational image diffusion models in just 1–4 steps while maintaining high image quality. We use score distillation to leverage large-scale off-the-shelf image diffusion models as a teacher signal in combination with an adversarial loss to ensure high image fidelity even in the low-step regime of one or two sampling steps. Our analyses show that our model clearly outperforms existing few-step methods (GANs,Latent Consistency Models) in a single step and reaches the performance of state-of-the-art diffusion models (SDXL) in only four steps. ADD is the first method to unlock single-step, real-time image synthesis with foundation models.*
|
| 20 |
+
|
| 21 |
+
## Tips
|
| 22 |
+
|
| 23 |
+
- SDXL Turbo uses the exact same architecture as [SDXL](./stable_diffusion_xl), which means it also has the same API. Please refer to the [SDXL](./stable_diffusion_xl) API reference for more details.
|
| 24 |
+
- SDXL Turbo should disable guidance scale by setting `guidance_scale=0.0`.
|
| 25 |
+
- SDXL Turbo should use `timestep_spacing='trailing'` for the scheduler and use between 1 and 4 steps.
|
| 26 |
+
- SDXL Turbo has been trained to generate images of size 512x512.
|
| 27 |
+
- SDXL Turbo is open-access, but not open-source meaning that one might have to buy a model license in order to use it for commercial applications. Make sure to read the [official model card](https://huggingface.co/stabilityai/sdxl-turbo) to learn more.
|
| 28 |
+
|
| 29 |
+
> [!TIP]
|
| 30 |
+
> To learn how to use SDXL Turbo for various tasks, how to optimize performance, and other usage examples, take a look at the [SDXL Turbo](../../../using-diffusers/sdxl_turbo) guide.
|
| 31 |
+
>
|
| 32 |
+
> Check out the [Stability AI](https://huggingface.co/stabilityai) Hub organization for the official base and refiner model checkpoints!
|
tasks/tasksmith-1c5704b1f07f/tests/source/docs/source/en/api/pipelines/stable_diffusion/stable_diffusion_2.md
ADDED
|
@@ -0,0 +1,122 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
<!--Copyright 2025 The HuggingFace Team. All rights reserved.
|
| 2 |
+
|
| 3 |
+
Licensed under the Apache License, Version 2.0 (the "License"); you may not use this file except in compliance with
|
| 4 |
+
the License. You may obtain a copy of the License at
|
| 5 |
+
|
| 6 |
+
http://www.apache.org/licenses/LICENSE-2.0
|
| 7 |
+
|
| 8 |
+
Unless required by applicable law or agreed to in writing, software distributed under the License is distributed on
|
| 9 |
+
an "AS IS" BASIS, WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied. See the License for the
|
| 10 |
+
specific language governing permissions and limitations under the License.
|
| 11 |
+
-->
|
| 12 |
+
|
| 13 |
+
# Stable Diffusion 2
|
| 14 |
+
|
| 15 |
+
Stable Diffusion 2 is a text-to-image _latent diffusion_ model built upon the work of the original [Stable Diffusion](https://stability.ai/blog/stable-diffusion-public-release), and it was led by Robin Rombach and Katherine Crowson from [Stability AI](https://stability.ai/) and [LAION](https://laion.ai/).
|
| 16 |
+
|
| 17 |
+
*The Stable Diffusion 2.0 release includes robust text-to-image models trained using a brand new text encoder (OpenCLIP), developed by LAION with support from Stability AI, which greatly improves the quality of the generated images compared to earlier V1 releases. The text-to-image models in this release can generate images with default resolutions of both 512x512 pixels and 768x768 pixels.
|
| 18 |
+
These models are trained on an aesthetic subset of the [LAION-5B dataset](https://laion.ai/blog/laion-5b/) created by the DeepFloyd team at Stability AI, which is then further filtered to remove adult content using [LAION’s NSFW filter](https://openreview.net/forum?id=M3Y74vmsMcY).*
|
| 19 |
+
|
| 20 |
+
For more details about how Stable Diffusion 2 works and how it differs from the original Stable Diffusion, please refer to the official [announcement post](https://stability.ai/blog/stable-diffusion-v2-release).
|
| 21 |
+
|
| 22 |
+
The architecture of Stable Diffusion 2 is more or less identical to the original [Stable Diffusion model](./text2img) so check out it's API documentation for how to use Stable Diffusion 2. We recommend using the [`DPMSolverMultistepScheduler`] as it gives a reasonable speed/quality trade-off and can be run with as little as 20 steps.
|
| 23 |
+
|
| 24 |
+
Stable Diffusion 2 is available for tasks like text-to-image, inpainting, super-resolution, and depth-to-image:
|
| 25 |
+
|
| 26 |
+
| Task | Repository |
|
| 27 |
+
|-------------------------|---------------------------------------------------------------------------------------------------------------|
|
| 28 |
+
| text-to-image (512x512) | [stabilityai/stable-diffusion-2-base](https://huggingface.co/stabilityai/stable-diffusion-2-base) |
|
| 29 |
+
| text-to-image (768x768) | [stabilityai/stable-diffusion-2](https://huggingface.co/stabilityai/stable-diffusion-2) |
|
| 30 |
+
| inpainting | [stabilityai/stable-diffusion-2-inpainting](https://huggingface.co/stabilityai/stable-diffusion-2-inpainting) |
|
| 31 |
+
| super-resolution | [stable-diffusion-x4-upscaler](https://huggingface.co/stabilityai/stable-diffusion-x4-upscaler) |
|
| 32 |
+
| depth-to-image | [stabilityai/stable-diffusion-2-depth](https://huggingface.co/stabilityai/stable-diffusion-2-depth) |
|
| 33 |
+
|
| 34 |
+
Here are some examples for how to use Stable Diffusion 2 for each task:
|
| 35 |
+
|
| 36 |
+
> [!TIP]
|
| 37 |
+
> Make sure to check out the Stable Diffusion [Tips](overview#tips) section to learn how to explore the tradeoff between scheduler speed and quality, and how to reuse pipeline components efficiently!
|
| 38 |
+
>
|
| 39 |
+
> If you're interested in using one of the official checkpoints for a task, explore the [CompVis](https://huggingface.co/CompVis) and [Stability AI](https://huggingface.co/stabilityai) Hub organizations!
|
| 40 |
+
|
| 41 |
+
## Text-to-image
|
| 42 |
+
|
| 43 |
+
```py
|
| 44 |
+
from diffusers import DiffusionPipeline, DPMSolverMultistepScheduler
|
| 45 |
+
import torch
|
| 46 |
+
|
| 47 |
+
repo_id = "stabilityai/stable-diffusion-2-base"
|
| 48 |
+
pipe = DiffusionPipeline.from_pretrained(repo_id, torch_dtype=torch.float16, variant="fp16")
|
| 49 |
+
|
| 50 |
+
pipe.scheduler = DPMSolverMultistepScheduler.from_config(pipe.scheduler.config)
|
| 51 |
+
pipe = pipe.to("cuda")
|
| 52 |
+
|
| 53 |
+
prompt = "High quality photo of an astronaut riding a horse in space"
|
| 54 |
+
image = pipe(prompt, num_inference_steps=25).images[0]
|
| 55 |
+
image
|
| 56 |
+
```
|
| 57 |
+
|
| 58 |
+
## Inpainting
|
| 59 |
+
|
| 60 |
+
```py
|
| 61 |
+
import torch
|
| 62 |
+
from diffusers import DiffusionPipeline, DPMSolverMultistepScheduler
|
| 63 |
+
from diffusers.utils import load_image, make_image_grid
|
| 64 |
+
|
| 65 |
+
img_url = "https://raw.githubusercontent.com/CompVis/latent-diffusion/main/data/inpainting_examples/overture-creations-5sI6fQgYIuo.png"
|
| 66 |
+
mask_url = "https://raw.githubusercontent.com/CompVis/latent-diffusion/main/data/inpainting_examples/overture-creations-5sI6fQgYIuo_mask.png"
|
| 67 |
+
|
| 68 |
+
init_image = load_image(img_url).resize((512, 512))
|
| 69 |
+
mask_image = load_image(mask_url).resize((512, 512))
|
| 70 |
+
|
| 71 |
+
repo_id = "stabilityai/stable-diffusion-2-inpainting"
|
| 72 |
+
pipe = DiffusionPipeline.from_pretrained(repo_id, torch_dtype=torch.float16, variant="fp16")
|
| 73 |
+
|
| 74 |
+
pipe.scheduler = DPMSolverMultistepScheduler.from_config(pipe.scheduler.config)
|
| 75 |
+
pipe = pipe.to("cuda")
|
| 76 |
+
|
| 77 |
+
prompt = "Face of a yellow cat, high resolution, sitting on a park bench"
|
| 78 |
+
image = pipe(prompt=prompt, image=init_image, mask_image=mask_image, num_inference_steps=25).images[0]
|
| 79 |
+
make_image_grid([init_image, mask_image, image], rows=1, cols=3)
|
| 80 |
+
```
|
| 81 |
+
|
| 82 |
+
## Super-resolution
|
| 83 |
+
|
| 84 |
+
```py
|
| 85 |
+
from diffusers import StableDiffusionUpscalePipeline
|
| 86 |
+
from diffusers.utils import load_image, make_image_grid
|
| 87 |
+
import torch
|
| 88 |
+
|
| 89 |
+
# load model and scheduler
|
| 90 |
+
model_id = "stabilityai/stable-diffusion-x4-upscaler"
|
| 91 |
+
pipeline = StableDiffusionUpscalePipeline.from_pretrained(model_id, torch_dtype=torch.float16)
|
| 92 |
+
pipeline = pipeline.to("cuda")
|
| 93 |
+
|
| 94 |
+
# let's download an image
|
| 95 |
+
url = "https://huggingface.co/datasets/hf-internal-testing/diffusers-images/resolve/main/sd2-upscale/low_res_cat.png"
|
| 96 |
+
low_res_img = load_image(url)
|
| 97 |
+
low_res_img = low_res_img.resize((128, 128))
|
| 98 |
+
prompt = "a white cat"
|
| 99 |
+
upscaled_image = pipeline(prompt=prompt, image=low_res_img).images[0]
|
| 100 |
+
make_image_grid([low_res_img.resize((512, 512)), upscaled_image.resize((512, 512))], rows=1, cols=2)
|
| 101 |
+
```
|
| 102 |
+
|
| 103 |
+
## Depth-to-image
|
| 104 |
+
|
| 105 |
+
```py
|
| 106 |
+
import torch
|
| 107 |
+
from diffusers import StableDiffusionDepth2ImgPipeline
|
| 108 |
+
from diffusers.utils import load_image, make_image_grid
|
| 109 |
+
|
| 110 |
+
pipe = StableDiffusionDepth2ImgPipeline.from_pretrained(
|
| 111 |
+
"stabilityai/stable-diffusion-2-depth",
|
| 112 |
+
torch_dtype=torch.float16,
|
| 113 |
+
).to("cuda")
|
| 114 |
+
|
| 115 |
+
|
| 116 |
+
url = "http://images.cocodataset.org/val2017/000000039769.jpg"
|
| 117 |
+
init_image = load_image(url)
|
| 118 |
+
prompt = "two tigers"
|
| 119 |
+
negative_prompt = "bad, deformed, ugly, bad anotomy"
|
| 120 |
+
image = pipe(prompt=prompt, image=init_image, negative_prompt=negative_prompt, strength=0.7).images[0]
|
| 121 |
+
make_image_grid([init_image, image], rows=1, cols=2)
|
| 122 |
+
```
|
tasks/tasksmith-1c5704b1f07f/tests/source/docs/source/en/api/pipelines/stable_diffusion/stable_diffusion_3.md
ADDED
|
@@ -0,0 +1,443 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
<!--Copyright 2025 The HuggingFace Team. All rights reserved.
|
| 2 |
+
|
| 3 |
+
Licensed under the Apache License, Version 2.0 (the "License"); you may not use this file except in compliance with
|
| 4 |
+
the License. You may obtain a copy of the License at
|
| 5 |
+
|
| 6 |
+
http://www.apache.org/licenses/LICENSE-2.0
|
| 7 |
+
|
| 8 |
+
Unless required by applicable law or agreed to in writing, software distributed under the License is distributed on
|
| 9 |
+
an "AS IS" BASIS, WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied. See the License for the
|
| 10 |
+
specific language governing permissions and limitations under the License.
|
| 11 |
+
-->
|
| 12 |
+
|
| 13 |
+
# Stable Diffusion 3
|
| 14 |
+
|
| 15 |
+
<div class="flex flex-wrap space-x-1">
|
| 16 |
+
<img alt="LoRA" src="https://img.shields.io/badge/LoRA-d8b4fe?style=flat"/>
|
| 17 |
+
<img alt="MPS" src="https://img.shields.io/badge/MPS-000000?style=flat&logo=apple&logoColor=white%22">
|
| 18 |
+
</div>
|
| 19 |
+
|
| 20 |
+
Stable Diffusion 3 (SD3) was proposed in [Scaling Rectified Flow Transformers for High-Resolution Image Synthesis](https://huggingface.co/papers/2403.03206) by Patrick Esser, Sumith Kulal, Andreas Blattmann, Rahim Entezari, Jonas Muller, Harry Saini, Yam Levi, Dominik Lorenz, Axel Sauer, Frederic Boesel, Dustin Podell, Tim Dockhorn, Zion English, Kyle Lacey, Alex Goodwin, Yannik Marek, and Robin Rombach.
|
| 21 |
+
|
| 22 |
+
The abstract from the paper is:
|
| 23 |
+
|
| 24 |
+
*Diffusion models create data from noise by inverting the forward paths of data towards noise and have emerged as a powerful generative modeling technique for high-dimensional, perceptual data such as images and videos. Rectified flow is a recent generative model formulation that connects data and noise in a straight line. Despite its better theoretical properties and conceptual simplicity, it is not yet decisively established as standard practice. In this work, we improve existing noise sampling techniques for training rectified flow models by biasing them towards perceptually relevant scales. Through a large-scale study, we demonstrate the superior performance of this approach compared to established diffusion formulations for high-resolution text-to-image synthesis. Additionally, we present a novel transformer-based architecture for text-to-image generation that uses separate weights for the two modalities and enables a bidirectional flow of information between image and text tokens, improving text comprehension typography, and human preference ratings. We demonstrate that this architecture follows predictable scaling trends and correlates lower validation loss to improved text-to-image synthesis as measured by various metrics and human evaluations.*
|
| 25 |
+
|
| 26 |
+
|
| 27 |
+
## Usage Example
|
| 28 |
+
|
| 29 |
+
_As the model is gated, before using it with diffusers you first need to go to the [Stable Diffusion 3 Medium Hugging Face page](https://huggingface.co/stabilityai/stable-diffusion-3-medium-diffusers), fill in the form and accept the gate. Once you are in, you need to login so that your system knows you’ve accepted the gate._
|
| 30 |
+
|
| 31 |
+
Use the command below to log in:
|
| 32 |
+
|
| 33 |
+
```bash
|
| 34 |
+
hf auth login
|
| 35 |
+
```
|
| 36 |
+
|
| 37 |
+
> [!TIP]
|
| 38 |
+
> The SD3 pipeline uses three text encoders to generate an image. Model offloading is necessary in order for it to run on most commodity hardware. Please use the `torch.float16` data type for additional memory savings.
|
| 39 |
+
|
| 40 |
+
```python
|
| 41 |
+
import torch
|
| 42 |
+
from diffusers import StableDiffusion3Pipeline
|
| 43 |
+
|
| 44 |
+
pipe = StableDiffusion3Pipeline.from_pretrained("stabilityai/stable-diffusion-3-medium-diffusers", torch_dtype=torch.float16)
|
| 45 |
+
pipe.to("cuda")
|
| 46 |
+
|
| 47 |
+
image = pipe(
|
| 48 |
+
prompt="a photo of a cat holding a sign that says hello world",
|
| 49 |
+
negative_prompt="",
|
| 50 |
+
num_inference_steps=28,
|
| 51 |
+
height=1024,
|
| 52 |
+
width=1024,
|
| 53 |
+
guidance_scale=7.0,
|
| 54 |
+
).images[0]
|
| 55 |
+
|
| 56 |
+
image.save("sd3_hello_world.png")
|
| 57 |
+
```
|
| 58 |
+
|
| 59 |
+
**Note:** Stable Diffusion 3.5 can also be run using the SD3 pipeline, and all mentioned optimizations and techniques apply to it as well. In total there are three official models in the SD3 family:
|
| 60 |
+
- [`stabilityai/stable-diffusion-3-medium-diffusers`](https://huggingface.co/stabilityai/stable-diffusion-3-medium-diffusers)
|
| 61 |
+
- [`stabilityai/stable-diffusion-3.5-large`](https://huggingface.co/stabilityai/stable-diffusion-3-5-large)
|
| 62 |
+
- [`stabilityai/stable-diffusion-3.5-large-turbo`](https://huggingface.co/stabilityai/stable-diffusion-3-5-large-turbo)
|
| 63 |
+
|
| 64 |
+
## Image Prompting with IP-Adapters
|
| 65 |
+
|
| 66 |
+
An IP-Adapter lets you prompt SD3 with images, in addition to the text prompt. This is especially useful when describing complex concepts that are difficult to articulate through text alone and you have reference images. To load and use an IP-Adapter, you need:
|
| 67 |
+
|
| 68 |
+
- `image_encoder`: Pre-trained vision model used to obtain image features, usually a CLIP image encoder.
|
| 69 |
+
- `feature_extractor`: Image processor that prepares the input image for the chosen `image_encoder`.
|
| 70 |
+
- `ip_adapter_id`: Checkpoint containing parameters of image cross attention layers and image projection.
|
| 71 |
+
|
| 72 |
+
IP-Adapters are trained for a specific model architecture, so they also work in finetuned variations of the base model. You can use the [`~SD3IPAdapterMixin.set_ip_adapter_scale`] function to adjust how strongly the output aligns with the image prompt. The higher the value, the more closely the model follows the image prompt. A default value of 0.5 is typically a good balance, ensuring the model considers both the text and image prompts equally.
|
| 73 |
+
|
| 74 |
+
```python
|
| 75 |
+
import torch
|
| 76 |
+
from PIL import Image
|
| 77 |
+
|
| 78 |
+
from diffusers import StableDiffusion3Pipeline
|
| 79 |
+
from transformers import SiglipVisionModel, SiglipImageProcessor
|
| 80 |
+
|
| 81 |
+
image_encoder_id = "google/siglip-so400m-patch14-384"
|
| 82 |
+
ip_adapter_id = "InstantX/SD3.5-Large-IP-Adapter"
|
| 83 |
+
|
| 84 |
+
feature_extractor = SiglipImageProcessor.from_pretrained(
|
| 85 |
+
image_encoder_id,
|
| 86 |
+
torch_dtype=torch.float16
|
| 87 |
+
)
|
| 88 |
+
image_encoder = SiglipVisionModel.from_pretrained(
|
| 89 |
+
image_encoder_id,
|
| 90 |
+
torch_dtype=torch.float16
|
| 91 |
+
).to( "cuda")
|
| 92 |
+
|
| 93 |
+
pipe = StableDiffusion3Pipeline.from_pretrained(
|
| 94 |
+
"stabilityai/stable-diffusion-3.5-large",
|
| 95 |
+
torch_dtype=torch.float16,
|
| 96 |
+
feature_extractor=feature_extractor,
|
| 97 |
+
image_encoder=image_encoder,
|
| 98 |
+
).to("cuda")
|
| 99 |
+
|
| 100 |
+
pipe.load_ip_adapter(ip_adapter_id)
|
| 101 |
+
pipe.set_ip_adapter_scale(0.6)
|
| 102 |
+
|
| 103 |
+
ref_img = Image.open("image.jpg").convert('RGB')
|
| 104 |
+
|
| 105 |
+
image = pipe(
|
| 106 |
+
width=1024,
|
| 107 |
+
height=1024,
|
| 108 |
+
prompt="a cat",
|
| 109 |
+
negative_prompt="lowres, low quality, worst quality",
|
| 110 |
+
num_inference_steps=24,
|
| 111 |
+
guidance_scale=5.0,
|
| 112 |
+
ip_adapter_image=ref_img
|
| 113 |
+
).images[0]
|
| 114 |
+
|
| 115 |
+
image.save("result.jpg")
|
| 116 |
+
```
|
| 117 |
+
|
| 118 |
+
<div class="justify-center">
|
| 119 |
+
<img src="https://huggingface.co/datasets/huggingface/documentation-images/resolve/main/diffusers/sd3_ip_adapter_example.png"/>
|
| 120 |
+
<figcaption class="mt-2 text-sm text-center text-gray-500">IP-Adapter examples with prompt "a cat"</figcaption>
|
| 121 |
+
</div>
|
| 122 |
+
|
| 123 |
+
|
| 124 |
+
> [!TIP]
|
| 125 |
+
> Check out [IP-Adapter](../../../using-diffusers/ip_adapter) to learn more about how IP-Adapters work.
|
| 126 |
+
|
| 127 |
+
|
| 128 |
+
## Memory Optimisations for SD3
|
| 129 |
+
|
| 130 |
+
SD3 uses three text encoders, one of which is the very large T5-XXL model. This makes it challenging to run the model on GPUs with less than 24GB of VRAM, even when using `fp16` precision. The following section outlines a few memory optimizations in Diffusers that make it easier to run SD3 on low resource hardware.
|
| 131 |
+
|
| 132 |
+
### Running Inference with Model Offloading
|
| 133 |
+
|
| 134 |
+
The most basic memory optimization available in Diffusers allows you to offload the components of the model to CPU during inference in order to save memory, while seeing a slight increase in inference latency. Model offloading will only move a model component onto the GPU when it needs to be executed, while keeping the remaining components on the CPU.
|
| 135 |
+
|
| 136 |
+
```python
|
| 137 |
+
import torch
|
| 138 |
+
from diffusers import StableDiffusion3Pipeline
|
| 139 |
+
|
| 140 |
+
pipe = StableDiffusion3Pipeline.from_pretrained("stabilityai/stable-diffusion-3-medium-diffusers", torch_dtype=torch.float16)
|
| 141 |
+
pipe.enable_model_cpu_offload()
|
| 142 |
+
|
| 143 |
+
image = pipe(
|
| 144 |
+
prompt="a photo of a cat holding a sign that says hello world",
|
| 145 |
+
negative_prompt="",
|
| 146 |
+
num_inference_steps=28,
|
| 147 |
+
height=1024,
|
| 148 |
+
width=1024,
|
| 149 |
+
guidance_scale=7.0,
|
| 150 |
+
).images[0]
|
| 151 |
+
|
| 152 |
+
image.save("sd3_hello_world.png")
|
| 153 |
+
```
|
| 154 |
+
|
| 155 |
+
### Dropping the T5 Text Encoder during Inference
|
| 156 |
+
|
| 157 |
+
Removing the memory-intensive 4.7B parameter T5-XXL text encoder during inference can significantly decrease the memory requirements for SD3 with only a slight loss in performance.
|
| 158 |
+
|
| 159 |
+
```python
|
| 160 |
+
import torch
|
| 161 |
+
from diffusers import StableDiffusion3Pipeline
|
| 162 |
+
|
| 163 |
+
pipe = StableDiffusion3Pipeline.from_pretrained(
|
| 164 |
+
"stabilityai/stable-diffusion-3-medium-diffusers",
|
| 165 |
+
text_encoder_3=None,
|
| 166 |
+
tokenizer_3=None,
|
| 167 |
+
torch_dtype=torch.float16
|
| 168 |
+
)
|
| 169 |
+
pipe.to("cuda")
|
| 170 |
+
|
| 171 |
+
image = pipe(
|
| 172 |
+
prompt="a photo of a cat holding a sign that says hello world",
|
| 173 |
+
negative_prompt="",
|
| 174 |
+
num_inference_steps=28,
|
| 175 |
+
height=1024,
|
| 176 |
+
width=1024,
|
| 177 |
+
guidance_scale=7.0,
|
| 178 |
+
).images[0]
|
| 179 |
+
|
| 180 |
+
image.save("sd3_hello_world-no-T5.png")
|
| 181 |
+
```
|
| 182 |
+
|
| 183 |
+
### Using a Quantized Version of the T5 Text Encoder
|
| 184 |
+
|
| 185 |
+
We can leverage the `bitsandbytes` library to load and quantize the T5-XXL text encoder to 8-bit precision. This allows you to keep using all three text encoders while only slightly impacting performance.
|
| 186 |
+
|
| 187 |
+
First install the `bitsandbytes` library.
|
| 188 |
+
|
| 189 |
+
```shell
|
| 190 |
+
pip install bitsandbytes
|
| 191 |
+
```
|
| 192 |
+
|
| 193 |
+
Then load the T5-XXL model using the `BitsAndBytesConfig`.
|
| 194 |
+
|
| 195 |
+
```python
|
| 196 |
+
import torch
|
| 197 |
+
from diffusers import StableDiffusion3Pipeline
|
| 198 |
+
from transformers import T5EncoderModel, BitsAndBytesConfig
|
| 199 |
+
|
| 200 |
+
quantization_config = BitsAndBytesConfig(load_in_8bit=True)
|
| 201 |
+
|
| 202 |
+
model_id = "stabilityai/stable-diffusion-3-medium-diffusers"
|
| 203 |
+
text_encoder = T5EncoderModel.from_pretrained(
|
| 204 |
+
model_id,
|
| 205 |
+
subfolder="text_encoder_3",
|
| 206 |
+
quantization_config=quantization_config,
|
| 207 |
+
)
|
| 208 |
+
pipe = StableDiffusion3Pipeline.from_pretrained(
|
| 209 |
+
model_id,
|
| 210 |
+
text_encoder_3=text_encoder,
|
| 211 |
+
device_map="balanced",
|
| 212 |
+
torch_dtype=torch.float16
|
| 213 |
+
)
|
| 214 |
+
|
| 215 |
+
image = pipe(
|
| 216 |
+
prompt="a photo of a cat holding a sign that says hello world",
|
| 217 |
+
negative_prompt="",
|
| 218 |
+
num_inference_steps=28,
|
| 219 |
+
height=1024,
|
| 220 |
+
width=1024,
|
| 221 |
+
guidance_scale=7.0,
|
| 222 |
+
).images[0]
|
| 223 |
+
|
| 224 |
+
image.save("sd3_hello_world-8bit-T5.png")
|
| 225 |
+
```
|
| 226 |
+
|
| 227 |
+
You can find the end-to-end script [here](https://gist.github.com/sayakpaul/82acb5976509851f2db1a83456e504f1).
|
| 228 |
+
|
| 229 |
+
## Performance Optimizations for SD3
|
| 230 |
+
|
| 231 |
+
### Using Torch Compile to Speed Up Inference
|
| 232 |
+
|
| 233 |
+
Using compiled components in the SD3 pipeline can speed up inference by as much as 4X. The following code snippet demonstrates how to compile the Transformer and VAE components of the SD3 pipeline.
|
| 234 |
+
|
| 235 |
+
```python
|
| 236 |
+
import torch
|
| 237 |
+
from diffusers import StableDiffusion3Pipeline
|
| 238 |
+
|
| 239 |
+
torch.set_float32_matmul_precision("high")
|
| 240 |
+
|
| 241 |
+
torch._inductor.config.conv_1x1_as_mm = True
|
| 242 |
+
torch._inductor.config.coordinate_descent_tuning = True
|
| 243 |
+
torch._inductor.config.epilogue_fusion = False
|
| 244 |
+
torch._inductor.config.coordinate_descent_check_all_directions = True
|
| 245 |
+
|
| 246 |
+
pipe = StableDiffusion3Pipeline.from_pretrained(
|
| 247 |
+
"stabilityai/stable-diffusion-3-medium-diffusers",
|
| 248 |
+
torch_dtype=torch.float16
|
| 249 |
+
).to("cuda")
|
| 250 |
+
pipe.set_progress_bar_config(disable=True)
|
| 251 |
+
|
| 252 |
+
pipe.transformer.to(memory_format=torch.channels_last)
|
| 253 |
+
pipe.vae.to(memory_format=torch.channels_last)
|
| 254 |
+
|
| 255 |
+
pipe.transformer = torch.compile(pipe.transformer, mode="max-autotune", fullgraph=True)
|
| 256 |
+
pipe.vae.decode = torch.compile(pipe.vae.decode, mode="max-autotune", fullgraph=True)
|
| 257 |
+
|
| 258 |
+
# Warm Up
|
| 259 |
+
prompt = "a photo of a cat holding a sign that says hello world"
|
| 260 |
+
for _ in range(3):
|
| 261 |
+
_ = pipe(prompt=prompt, generator=torch.manual_seed(1))
|
| 262 |
+
|
| 263 |
+
# Run Inference
|
| 264 |
+
image = pipe(prompt=prompt, generator=torch.manual_seed(1)).images[0]
|
| 265 |
+
image.save("sd3_hello_world.png")
|
| 266 |
+
```
|
| 267 |
+
|
| 268 |
+
Check out the full script [here](https://gist.github.com/sayakpaul/508d89d7aad4f454900813da5d42ca97).
|
| 269 |
+
|
| 270 |
+
## Quantization
|
| 271 |
+
|
| 272 |
+
Quantization helps reduce the memory requirements of very large models by storing model weights in a lower precision data type. However, quantization may have varying impact on video quality depending on the video model.
|
| 273 |
+
|
| 274 |
+
Refer to the [Quantization](../../../quantization/overview) overview to learn more about supported quantization backends and selecting a quantization backend that supports your use case. The example below demonstrates how to load a quantized [`StableDiffusion3Pipeline`] for inference with bitsandbytes.
|
| 275 |
+
|
| 276 |
+
```py
|
| 277 |
+
import torch
|
| 278 |
+
from diffusers import BitsAndBytesConfig as DiffusersBitsAndBytesConfig, SD3Transformer2DModel, StableDiffusion3Pipeline
|
| 279 |
+
from transformers import BitsAndBytesConfig as BitsAndBytesConfig, T5EncoderModel
|
| 280 |
+
|
| 281 |
+
quant_config = BitsAndBytesConfig(load_in_8bit=True)
|
| 282 |
+
text_encoder_8bit = T5EncoderModel.from_pretrained(
|
| 283 |
+
"stabilityai/stable-diffusion-3.5-large",
|
| 284 |
+
subfolder="text_encoder_3",
|
| 285 |
+
quantization_config=quant_config,
|
| 286 |
+
torch_dtype=torch.float16,
|
| 287 |
+
)
|
| 288 |
+
|
| 289 |
+
quant_config = DiffusersBitsAndBytesConfig(load_in_8bit=True)
|
| 290 |
+
transformer_8bit = SD3Transformer2DModel.from_pretrained(
|
| 291 |
+
"stabilityai/stable-diffusion-3.5-large",
|
| 292 |
+
subfolder="transformer",
|
| 293 |
+
quantization_config=quant_config,
|
| 294 |
+
torch_dtype=torch.float16,
|
| 295 |
+
)
|
| 296 |
+
|
| 297 |
+
pipeline = StableDiffusion3Pipeline.from_pretrained(
|
| 298 |
+
"stabilityai/stable-diffusion-3.5-large",
|
| 299 |
+
text_encoder=text_encoder_8bit,
|
| 300 |
+
transformer=transformer_8bit,
|
| 301 |
+
torch_dtype=torch.float16,
|
| 302 |
+
device_map="balanced",
|
| 303 |
+
)
|
| 304 |
+
|
| 305 |
+
prompt = "a tiny astronaut hatching from an egg on the moon"
|
| 306 |
+
image = pipeline(prompt, num_inference_steps=28, guidance_scale=7.0).images[0]
|
| 307 |
+
image.save("sd3.png")
|
| 308 |
+
```
|
| 309 |
+
|
| 310 |
+
## Using Long Prompts with the T5 Text Encoder
|
| 311 |
+
|
| 312 |
+
By default, the T5 Text Encoder prompt uses a maximum sequence length of `256`. This can be adjusted by setting the `max_sequence_length` to accept fewer or more tokens. Keep in mind that longer sequences require additional resources and result in longer generation times, such as during batch inference.
|
| 313 |
+
|
| 314 |
+
```python
|
| 315 |
+
prompt = "A whimsical and creative image depicting a hybrid creature that is a mix of a waffle and a hippopotamus, basking in a river of melted butter amidst a breakfast-themed landscape. It features the distinctive, bulky body shape of a hippo. However, instead of the usual grey skin, the creature’s body resembles a golden-brown, crispy waffle fresh off the griddle. The skin is textured with the familiar grid pattern of a waffle, each square filled with a glistening sheen of syrup. The environment combines the natural habitat of a hippo with elements of a breakfast table setting, a river of warm, melted butter, with oversized utensils or plates peeking out from the lush, pancake-like foliage in the background, a towering pepper mill standing in for a tree. As the sun rises in this fantastical world, it casts a warm, buttery glow over the scene. The creature, content in its butter river, lets out a yawn. Nearby, a flock of birds take flight"
|
| 316 |
+
|
| 317 |
+
image = pipe(
|
| 318 |
+
prompt=prompt,
|
| 319 |
+
negative_prompt="",
|
| 320 |
+
num_inference_steps=28,
|
| 321 |
+
guidance_scale=4.5,
|
| 322 |
+
max_sequence_length=512,
|
| 323 |
+
).images[0]
|
| 324 |
+
```
|
| 325 |
+
|
| 326 |
+
### Sending a different prompt to the T5 Text Encoder
|
| 327 |
+
|
| 328 |
+
You can send a different prompt to the CLIP Text Encoders and the T5 Text Encoder to prevent the prompt from being truncated by the CLIP Text Encoders and to improve generation.
|
| 329 |
+
|
| 330 |
+
> [!TIP]
|
| 331 |
+
> The prompt with the CLIP Text Encoders is still truncated to the 77 token limit.
|
| 332 |
+
|
| 333 |
+
```python
|
| 334 |
+
prompt = "A whimsical and creative image depicting a hybrid creature that is a mix of a waffle and a hippopotamus, basking in a river of melted butter amidst a breakfast-themed landscape. A river of warm, melted butter, pancake-like foliage in the background, a towering pepper mill standing in for a tree."
|
| 335 |
+
|
| 336 |
+
prompt_3 = "A whimsical and creative image depicting a hybrid creature that is a mix of a waffle and a hippopotamus, basking in a river of melted butter amidst a breakfast-themed landscape. It features the distinctive, bulky body shape of a hippo. However, instead of the usual grey skin, the creature’s body resembles a golden-brown, crispy waffle fresh off the griddle. The skin is textured with the familiar grid pattern of a waffle, each square filled with a glistening sheen of syrup. The environment combines the natural habitat of a hippo with elements of a breakfast table setting, a river of warm, melted butter, with oversized utensils or plates peeking out from the lush, pancake-like foliage in the background, a towering pepper mill standing in for a tree. As the sun rises in this fantastical world, it casts a warm, buttery glow over the scene. The creature, content in its butter river, lets out a yawn. Nearby, a flock of birds take flight"
|
| 337 |
+
|
| 338 |
+
image = pipe(
|
| 339 |
+
prompt=prompt,
|
| 340 |
+
prompt_3=prompt_3,
|
| 341 |
+
negative_prompt="",
|
| 342 |
+
num_inference_steps=28,
|
| 343 |
+
guidance_scale=4.5,
|
| 344 |
+
max_sequence_length=512,
|
| 345 |
+
).images[0]
|
| 346 |
+
```
|
| 347 |
+
|
| 348 |
+
## Tiny AutoEncoder for Stable Diffusion 3
|
| 349 |
+
|
| 350 |
+
Tiny AutoEncoder for Stable Diffusion (TAESD3) is a tiny distilled version of Stable Diffusion 3's VAE by [Ollin Boer Bohan](https://github.com/madebyollin/taesd) that can decode [`StableDiffusion3Pipeline`] latents almost instantly.
|
| 351 |
+
|
| 352 |
+
To use with Stable Diffusion 3:
|
| 353 |
+
|
| 354 |
+
```python
|
| 355 |
+
import torch
|
| 356 |
+
from diffusers import StableDiffusion3Pipeline, AutoencoderTiny
|
| 357 |
+
|
| 358 |
+
pipe = StableDiffusion3Pipeline.from_pretrained(
|
| 359 |
+
"stabilityai/stable-diffusion-3-medium-diffusers", torch_dtype=torch.float16
|
| 360 |
+
)
|
| 361 |
+
pipe.vae = AutoencoderTiny.from_pretrained("madebyollin/taesd3", torch_dtype=torch.float16)
|
| 362 |
+
pipe = pipe.to("cuda")
|
| 363 |
+
|
| 364 |
+
prompt = "slice of delicious New York-style berry cheesecake"
|
| 365 |
+
image = pipe(prompt, num_inference_steps=25).images[0]
|
| 366 |
+
image.save("cheesecake.png")
|
| 367 |
+
```
|
| 368 |
+
|
| 369 |
+
## Loading the original checkpoints via `from_single_file`
|
| 370 |
+
|
| 371 |
+
The `SD3Transformer2DModel` and `StableDiffusion3Pipeline` classes support loading the original checkpoints via the `from_single_file` method. This method allows you to load the original checkpoint files that were used to train the models.
|
| 372 |
+
|
| 373 |
+
## Loading the original checkpoints for the `SD3Transformer2DModel`
|
| 374 |
+
|
| 375 |
+
```python
|
| 376 |
+
from diffusers import SD3Transformer2DModel
|
| 377 |
+
|
| 378 |
+
model = SD3Transformer2DModel.from_single_file("https://huggingface.co/stabilityai/stable-diffusion-3-medium/blob/main/sd3_medium.safetensors")
|
| 379 |
+
```
|
| 380 |
+
|
| 381 |
+
## Loading the single checkpoint for the `StableDiffusion3Pipeline`
|
| 382 |
+
|
| 383 |
+
### Loading the single file checkpoint without T5
|
| 384 |
+
|
| 385 |
+
```python
|
| 386 |
+
import torch
|
| 387 |
+
from diffusers import StableDiffusion3Pipeline
|
| 388 |
+
|
| 389 |
+
pipe = StableDiffusion3Pipeline.from_single_file(
|
| 390 |
+
"https://huggingface.co/stabilityai/stable-diffusion-3-medium/blob/main/sd3_medium_incl_clips.safetensors",
|
| 391 |
+
torch_dtype=torch.float16,
|
| 392 |
+
text_encoder_3=None
|
| 393 |
+
)
|
| 394 |
+
pipe.enable_model_cpu_offload()
|
| 395 |
+
|
| 396 |
+
image = pipe("a picture of a cat holding a sign that says hello world").images[0]
|
| 397 |
+
image.save('sd3-single-file.png')
|
| 398 |
+
```
|
| 399 |
+
|
| 400 |
+
### Loading the single file checkpoint with T5
|
| 401 |
+
|
| 402 |
+
> [!TIP]
|
| 403 |
+
> The following example loads a checkpoint stored in a 8-bit floating point format which requires PyTorch 2.3 or later.
|
| 404 |
+
|
| 405 |
+
```python
|
| 406 |
+
import torch
|
| 407 |
+
from diffusers import StableDiffusion3Pipeline
|
| 408 |
+
|
| 409 |
+
pipe = StableDiffusion3Pipeline.from_single_file(
|
| 410 |
+
"https://huggingface.co/stabilityai/stable-diffusion-3-medium/blob/main/sd3_medium_incl_clips_t5xxlfp8.safetensors",
|
| 411 |
+
torch_dtype=torch.float16,
|
| 412 |
+
)
|
| 413 |
+
pipe.enable_model_cpu_offload()
|
| 414 |
+
|
| 415 |
+
image = pipe("a picture of a cat holding a sign that says hello world").images[0]
|
| 416 |
+
image.save('sd3-single-file-t5-fp8.png')
|
| 417 |
+
```
|
| 418 |
+
|
| 419 |
+
### Loading the single file checkpoint for the Stable Diffusion 3.5 Transformer Model
|
| 420 |
+
|
| 421 |
+
```python
|
| 422 |
+
import torch
|
| 423 |
+
from diffusers import SD3Transformer2DModel, StableDiffusion3Pipeline
|
| 424 |
+
|
| 425 |
+
transformer = SD3Transformer2DModel.from_single_file(
|
| 426 |
+
"https://huggingface.co/stabilityai/stable-diffusion-3.5-large-turbo/blob/main/sd3.5_large.safetensors",
|
| 427 |
+
torch_dtype=torch.bfloat16,
|
| 428 |
+
)
|
| 429 |
+
pipe = StableDiffusion3Pipeline.from_pretrained(
|
| 430 |
+
"stabilityai/stable-diffusion-3.5-large",
|
| 431 |
+
transformer=transformer,
|
| 432 |
+
torch_dtype=torch.bfloat16,
|
| 433 |
+
)
|
| 434 |
+
pipe.enable_model_cpu_offload()
|
| 435 |
+
image = pipe("a cat holding a sign that says hello world").images[0]
|
| 436 |
+
image.save("sd35.png")
|
| 437 |
+
```
|
| 438 |
+
|
| 439 |
+
## StableDiffusion3Pipeline
|
| 440 |
+
|
| 441 |
+
[[autodoc]] StableDiffusion3Pipeline
|
| 442 |
+
- all
|
| 443 |
+
- __call__
|
tasks/tasksmith-1c5704b1f07f/tests/source/docs/source/en/api/pipelines/stable_diffusion/stable_diffusion_safe.md
ADDED
|
@@ -0,0 +1,61 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
<!--Copyright 2025 The HuggingFace Team. All rights reserved.
|
| 2 |
+
|
| 3 |
+
Licensed under the Apache License, Version 2.0 (the "License"); you may not use this file except in compliance with
|
| 4 |
+
the License. You may obtain a copy of the License at
|
| 5 |
+
|
| 6 |
+
http://www.apache.org/licenses/LICENSE-2.0
|
| 7 |
+
|
| 8 |
+
Unless required by applicable law or agreed to in writing, software distributed under the License is distributed on
|
| 9 |
+
an "AS IS" BASIS, WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied. See the License for the
|
| 10 |
+
specific language governing permissions and limitations under the License.
|
| 11 |
+
-->
|
| 12 |
+
|
| 13 |
+
> [!WARNING]
|
| 14 |
+
> This pipeline is deprecated but it can still be used. However, we won't test the pipeline anymore and won't accept any changes to it. If you run into any issues, reinstall the last Diffusers version that supported this model.
|
| 15 |
+
|
| 16 |
+
# Safe Stable Diffusion
|
| 17 |
+
|
| 18 |
+
Safe Stable Diffusion was proposed in [Safe Latent Diffusion: Mitigating Inappropriate Degeneration in Diffusion Models](https://huggingface.co/papers/2211.05105) and mitigates inappropriate degeneration from Stable Diffusion models because they're trained on unfiltered web-crawled datasets. For instance Stable Diffusion may unexpectedly generate nudity, violence, images depicting self-harm, and otherwise offensive content. Safe Stable Diffusion is an extension of Stable Diffusion that drastically reduces this type of content.
|
| 19 |
+
|
| 20 |
+
The abstract from the paper is:
|
| 21 |
+
|
| 22 |
+
*Text-conditioned image generation models have recently achieved astonishing results in image quality and text alignment and are consequently employed in a fast-growing number of applications. Since they are highly data-driven, relying on billion-sized datasets randomly scraped from the internet, they also suffer, as we demonstrate, from degenerated and biased human behavior. In turn, they may even reinforce such biases. To help combat these undesired side effects, we present safe latent diffusion (SLD). Specifically, to measure the inappropriate degeneration due to unfiltered and imbalanced training sets, we establish a novel image generation test bed-inappropriate image prompts (I2P)-containing dedicated, real-world image-to-text prompts covering concepts such as nudity and violence. As our exhaustive empirical evaluation demonstrates, the introduced SLD removes and suppresses inappropriate image parts during the diffusion process, with no additional training required and no adverse effect on overall image quality or text alignment.*
|
| 23 |
+
|
| 24 |
+
## Tips
|
| 25 |
+
|
| 26 |
+
Use the `safety_concept` property of [`StableDiffusionPipelineSafe`] to check and edit the current safety concept:
|
| 27 |
+
|
| 28 |
+
```python
|
| 29 |
+
>>> from diffusers import StableDiffusionPipelineSafe
|
| 30 |
+
|
| 31 |
+
>>> pipeline = StableDiffusionPipelineSafe.from_pretrained("AIML-TUDA/stable-diffusion-safe")
|
| 32 |
+
>>> pipeline.safety_concept
|
| 33 |
+
'an image showing hate, harassment, violence, suffering, humiliation, harm, suicide, sexual, nudity, bodily fluids, blood, obscene gestures, illegal activity, drug use, theft, vandalism, weapons, child abuse, brutality, cruelty'
|
| 34 |
+
```
|
| 35 |
+
For each image generation the active concept is also contained in [`StableDiffusionSafePipelineOutput`].
|
| 36 |
+
|
| 37 |
+
There are 4 configurations (`SafetyConfig.WEAK`, `SafetyConfig.MEDIUM`, `SafetyConfig.STRONG`, and `SafetyConfig.MAX`) that can be applied:
|
| 38 |
+
|
| 39 |
+
```python
|
| 40 |
+
>>> from diffusers import StableDiffusionPipelineSafe
|
| 41 |
+
>>> from diffusers.pipelines.stable_diffusion_safe import SafetyConfig
|
| 42 |
+
|
| 43 |
+
>>> pipeline = StableDiffusionPipelineSafe.from_pretrained("AIML-TUDA/stable-diffusion-safe")
|
| 44 |
+
>>> prompt = "the four horsewomen of the apocalypse, painting by tom of finland, gaston bussiere, craig mullins, j. c. leyendecker"
|
| 45 |
+
>>> out = pipeline(prompt=prompt, **SafetyConfig.MAX)
|
| 46 |
+
```
|
| 47 |
+
|
| 48 |
+
> [!TIP]
|
| 49 |
+
> Make sure to check out the Stable Diffusion [Tips](overview#tips) section to learn how to explore the tradeoff between scheduler speed and quality, and how to reuse pipeline components efficiently!
|
| 50 |
+
|
| 51 |
+
## StableDiffusionPipelineSafe
|
| 52 |
+
|
| 53 |
+
[[autodoc]] StableDiffusionPipelineSafe
|
| 54 |
+
- all
|
| 55 |
+
- __call__
|
| 56 |
+
|
| 57 |
+
## StableDiffusionSafePipelineOutput
|
| 58 |
+
|
| 59 |
+
[[autodoc]] pipelines.stable_diffusion_safe.StableDiffusionSafePipelineOutput
|
| 60 |
+
- all
|
| 61 |
+
- __call__
|
tasks/tasksmith-1c5704b1f07f/tests/source/docs/source/en/api/pipelines/stable_diffusion/stable_diffusion_xl.md
ADDED
|
@@ -0,0 +1,57 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
<!--Copyright 2025 The HuggingFace Team. All rights reserved.
|
| 2 |
+
|
| 3 |
+
Licensed under the Apache License, Version 2.0 (the "License"); you may not use this file except in compliance with
|
| 4 |
+
the License. You may obtain a copy of the License at
|
| 5 |
+
|
| 6 |
+
http://www.apache.org/licenses/LICENSE-2.0
|
| 7 |
+
|
| 8 |
+
Unless required by applicable law or agreed to in writing, software distributed under the License is distributed on
|
| 9 |
+
an "AS IS" BASIS, WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied. See the License for the
|
| 10 |
+
specific language governing permissions and limitations under the License.
|
| 11 |
+
-->
|
| 12 |
+
|
| 13 |
+
# Stable Diffusion XL
|
| 14 |
+
|
| 15 |
+
<div class="flex flex-wrap space-x-1">
|
| 16 |
+
<img alt="LoRA" src="https://img.shields.io/badge/LoRA-d8b4fe?style=flat"/>
|
| 17 |
+
<img alt="MPS" src="https://img.shields.io/badge/MPS-000000?style=flat&logo=apple&logoColor=white%22">
|
| 18 |
+
</div>
|
| 19 |
+
|
| 20 |
+
Stable Diffusion XL (SDXL) was proposed in [SDXL: Improving Latent Diffusion Models for High-Resolution Image Synthesis](https://huggingface.co/papers/2307.01952) by Dustin Podell, Zion English, Kyle Lacey, Andreas Blattmann, Tim Dockhorn, Jonas Müller, Joe Penna, and Robin Rombach.
|
| 21 |
+
|
| 22 |
+
The abstract from the paper is:
|
| 23 |
+
|
| 24 |
+
*We present SDXL, a latent diffusion model for text-to-image synthesis. Compared to previous versions of Stable Diffusion, SDXL leverages a three times larger UNet backbone: The increase of model parameters is mainly due to more attention blocks and a larger cross-attention context as SDXL uses a second text encoder. We design multiple novel conditioning schemes and train SDXL on multiple aspect ratios. We also introduce a refinement model which is used to improve the visual fidelity of samples generated by SDXL using a post-hoc image-to-image technique. We demonstrate that SDXL shows drastically improved performance compared the previous versions of Stable Diffusion and achieves results competitive with those of black-box state-of-the-art image generators.*
|
| 25 |
+
|
| 26 |
+
## Tips
|
| 27 |
+
|
| 28 |
+
- Using SDXL with a DPM++ scheduler for less than 50 steps is known to produce [visual artifacts](https://github.com/huggingface/diffusers/issues/5433) because the solver becomes numerically unstable. To fix this issue, take a look at this [PR](https://github.com/huggingface/diffusers/pull/5541) which recommends for ODE/SDE solvers:
|
| 29 |
+
- set `use_karras_sigmas=True` or `lu_lambdas=True` to improve image quality
|
| 30 |
+
- set `euler_at_final=True` if you're using a solver with uniform step sizes (DPM++2M or DPM++2M SDE)
|
| 31 |
+
- Most SDXL checkpoints work best with an image size of 1024x1024. Image sizes of 768x768 and 512x512 are also supported, but the results aren't as good. Anything below 512x512 is not recommended and likely won't be for default checkpoints like [stabilityai/stable-diffusion-xl-base-1.0](https://huggingface.co/stabilityai/stable-diffusion-xl-base-1.0).
|
| 32 |
+
- SDXL can pass a different prompt for each of the text encoders it was trained on. We can even pass different parts of the same prompt to the text encoders.
|
| 33 |
+
- SDXL output images can be improved by making use of a refiner model in an image-to-image setting.
|
| 34 |
+
- SDXL offers `negative_original_size`, `negative_crops_coords_top_left`, and `negative_target_size` to negatively condition the model on image resolution and cropping parameters.
|
| 35 |
+
|
| 36 |
+
> [!TIP]
|
| 37 |
+
> To learn how to use SDXL for various tasks, how to optimize performance, and other usage examples, take a look at the [Stable Diffusion XL](../../../using-diffusers/sdxl) guide.
|
| 38 |
+
>
|
| 39 |
+
> Check out the [Stability AI](https://huggingface.co/stabilityai) Hub organization for the official base and refiner model checkpoints!
|
| 40 |
+
|
| 41 |
+
## StableDiffusionXLPipeline
|
| 42 |
+
|
| 43 |
+
[[autodoc]] StableDiffusionXLPipeline
|
| 44 |
+
- all
|
| 45 |
+
- __call__
|
| 46 |
+
|
| 47 |
+
## StableDiffusionXLImg2ImgPipeline
|
| 48 |
+
|
| 49 |
+
[[autodoc]] StableDiffusionXLImg2ImgPipeline
|
| 50 |
+
- all
|
| 51 |
+
- __call__
|
| 52 |
+
|
| 53 |
+
## StableDiffusionXLInpaintPipeline
|
| 54 |
+
|
| 55 |
+
[[autodoc]] StableDiffusionXLInpaintPipeline
|
| 56 |
+
- all
|
| 57 |
+
- __call__
|
tasks/tasksmith-1c5704b1f07f/tests/source/docs/source/en/api/pipelines/stable_diffusion/svd.md
ADDED
|
@@ -0,0 +1,40 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
<!--Copyright 2025 The HuggingFace Team. All rights reserved.
|
| 2 |
+
|
| 3 |
+
Licensed under the Apache License, Version 2.0 (the "License"); you may not use this file except in compliance with
|
| 4 |
+
the License. You may obtain a copy of the License at
|
| 5 |
+
|
| 6 |
+
http://www.apache.org/licenses/LICENSE-2.0
|
| 7 |
+
|
| 8 |
+
Unless required by applicable law or agreed to in writing, software distributed under the License is distributed on
|
| 9 |
+
an "AS IS" BASIS, WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied. See the License for the
|
| 10 |
+
specific language governing permissions and limitations under the License.
|
| 11 |
+
-->
|
| 12 |
+
|
| 13 |
+
# Stable Video Diffusion
|
| 14 |
+
|
| 15 |
+
Stable Video Diffusion was proposed in [Stable Video Diffusion: Scaling Latent Video Diffusion Models to Large Datasets](https://hf.co/papers/2311.15127) by Andreas Blattmann, Tim Dockhorn, Sumith Kulal, Daniel Mendelevitch, Maciej Kilian, Dominik Lorenz, Yam Levi, Zion English, Vikram Voleti, Adam Letts, Varun Jampani, Robin Rombach.
|
| 16 |
+
|
| 17 |
+
The abstract from the paper is:
|
| 18 |
+
|
| 19 |
+
*We present Stable Video Diffusion - a latent video diffusion model for high-resolution, state-of-the-art text-to-video and image-to-video generation. Recently, latent diffusion models trained for 2D image synthesis have been turned into generative video models by inserting temporal layers and finetuning them on small, high-quality video datasets. However, training methods in the literature vary widely, and the field has yet to agree on a unified strategy for curating video data. In this paper, we identify and evaluate three different stages for successful training of video LDMs: text-to-image pretraining, video pretraining, and high-quality video finetuning. Furthermore, we demonstrate the necessity of a well-curated pretraining dataset for generating high-quality videos and present a systematic curation process to train a strong base model, including captioning and filtering strategies. We then explore the impact of finetuning our base model on high-quality data and train a text-to-video model that is competitive with closed-source video generation. We also show that our base model provides a powerful motion representation for downstream tasks such as image-to-video generation and adaptability to camera motion-specific LoRA modules. Finally, we demonstrate that our model provides a strong multi-view 3D-prior and can serve as a base to finetune a multi-view diffusion model that jointly generates multiple views of objects in a feedforward fashion, outperforming image-based methods at a fraction of their compute budget. We release code and model weights at this https URL.*
|
| 20 |
+
|
| 21 |
+
> [!TIP]
|
| 22 |
+
> To learn how to use Stable Video Diffusion, take a look at the [Stable Video Diffusion](../../../using-diffusers/svd) guide.
|
| 23 |
+
>
|
| 24 |
+
> <br>
|
| 25 |
+
>
|
| 26 |
+
> Check out the [Stability AI](https://huggingface.co/stabilityai) Hub organization for the [base](https://huggingface.co/stabilityai/stable-video-diffusion-img2vid) and [extended frame](https://huggingface.co/stabilityai/stable-video-diffusion-img2vid-xt) checkpoints!
|
| 27 |
+
|
| 28 |
+
## Tips
|
| 29 |
+
|
| 30 |
+
Video generation is memory-intensive and one way to reduce your memory usage is to set `enable_forward_chunking` on the pipeline's UNet so you don't run the entire feedforward layer at once. Breaking it up into chunks in a loop is more efficient.
|
| 31 |
+
|
| 32 |
+
Check out the [Text or image-to-video](../../../using-diffusers/text-img2vid) guide for more details about how certain parameters can affect video generation and how to optimize inference by reducing memory usage.
|
| 33 |
+
|
| 34 |
+
## StableVideoDiffusionPipeline
|
| 35 |
+
|
| 36 |
+
[[autodoc]] StableVideoDiffusionPipeline
|
| 37 |
+
|
| 38 |
+
## StableVideoDiffusionPipelineOutput
|
| 39 |
+
|
| 40 |
+
[[autodoc]] pipelines.stable_video_diffusion.StableVideoDiffusionPipelineOutput
|
tasks/tasksmith-1c5704b1f07f/tests/source/docs/source/en/api/pipelines/stable_diffusion/text2img.md
ADDED
|
@@ -0,0 +1,50 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
<!--Copyright 2025 The HuggingFace Team. All rights reserved.
|
| 2 |
+
|
| 3 |
+
Licensed under the Apache License, Version 2.0 (the "License"); you may not use this file except in compliance with
|
| 4 |
+
the License. You may obtain a copy of the License at
|
| 5 |
+
|
| 6 |
+
http://www.apache.org/licenses/LICENSE-2.0
|
| 7 |
+
|
| 8 |
+
Unless required by applicable law or agreed to in writing, software distributed under the License is distributed on
|
| 9 |
+
an "AS IS" BASIS, WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied. See the License for the
|
| 10 |
+
specific language governing permissions and limitations under the License.
|
| 11 |
+
-->
|
| 12 |
+
|
| 13 |
+
# Text-to-image
|
| 14 |
+
|
| 15 |
+
<div class="flex flex-wrap space-x-1">
|
| 16 |
+
<img alt="LoRA" src="https://img.shields.io/badge/LoRA-d8b4fe?style=flat"/>
|
| 17 |
+
</div>
|
| 18 |
+
|
| 19 |
+
The Stable Diffusion model was created by researchers and engineers from [CompVis](https://github.com/CompVis), [Stability AI](https://stability.ai/), [Runway](https://github.com/runwayml), and [LAION](https://laion.ai/). The [`StableDiffusionPipeline`] is capable of generating photorealistic images given any text input. It's trained on 512x512 images from a subset of the LAION-5B dataset. This model uses a frozen CLIP ViT-L/14 text encoder to condition the model on text prompts. With its 860M UNet and 123M text encoder, the model is relatively lightweight and can run on consumer GPUs. Latent diffusion is the research on top of which Stable Diffusion was built. It was proposed in [High-Resolution Image Synthesis with Latent Diffusion Models](https://huggingface.co/papers/2112.10752) by Robin Rombach, Andreas Blattmann, Dominik Lorenz, Patrick Esser, Björn Ommer.
|
| 20 |
+
|
| 21 |
+
The abstract from the paper is:
|
| 22 |
+
|
| 23 |
+
*By decomposing the image formation process into a sequential application of denoising autoencoders, diffusion models (DMs) achieve state-of-the-art synthesis results on image data and beyond. Additionally, their formulation allows for a guiding mechanism to control the image generation process without retraining. However, since these models typically operate directly in pixel space, optimization of powerful DMs often consumes hundreds of GPU days and inference is expensive due to sequential evaluations. To enable DM training on limited computational resources while retaining their quality and flexibility, we apply them in the latent space of powerful pretrained autoencoders. In contrast to previous work, training diffusion models on such a representation allows for the first time to reach a near-optimal point between complexity reduction and detail preservation, greatly boosting visual fidelity. By introducing cross-attention layers into the model architecture, we turn diffusion models into powerful and flexible generators for general conditioning inputs such as text or bounding boxes and high-resolution synthesis becomes possible in a convolutional manner. Our latent diffusion models (LDMs) achieve a new state of the art for image inpainting and highly competitive performance on various tasks, including unconditional image generation, semantic scene synthesis, and super-resolution, while significantly reducing computational requirements compared to pixel-based DMs. Code is available at https://github.com/CompVis/latent-diffusion.*
|
| 24 |
+
|
| 25 |
+
> [!TIP]
|
| 26 |
+
> Make sure to check out the Stable Diffusion [Tips](overview#tips) section to learn how to explore the tradeoff between scheduler speed and quality, and how to reuse pipeline components efficiently!
|
| 27 |
+
>
|
| 28 |
+
> If you're interested in using one of the official checkpoints for a task, explore the [CompVis](https://huggingface.co/CompVis) and [Stability AI](https://huggingface.co/stabilityai) Hub organizations!
|
| 29 |
+
|
| 30 |
+
## StableDiffusionPipeline
|
| 31 |
+
|
| 32 |
+
[[autodoc]] StableDiffusionPipeline
|
| 33 |
+
- all
|
| 34 |
+
- __call__
|
| 35 |
+
- enable_attention_slicing
|
| 36 |
+
- disable_attention_slicing
|
| 37 |
+
- enable_vae_slicing
|
| 38 |
+
- disable_vae_slicing
|
| 39 |
+
- enable_xformers_memory_efficient_attention
|
| 40 |
+
- disable_xformers_memory_efficient_attention
|
| 41 |
+
- enable_vae_tiling
|
| 42 |
+
- disable_vae_tiling
|
| 43 |
+
- load_textual_inversion
|
| 44 |
+
- from_single_file
|
| 45 |
+
- load_lora_weights
|
| 46 |
+
- save_lora_weights
|
| 47 |
+
|
| 48 |
+
## StableDiffusionPipelineOutput
|
| 49 |
+
|
| 50 |
+
[[autodoc]] pipelines.stable_diffusion.StableDiffusionPipelineOutput
|
tasks/tasksmith-1c5704b1f07f/tests/source/docs/source/en/api/pipelines/stable_diffusion/upscale.md
ADDED
|
@@ -0,0 +1,38 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
<!--Copyright 2025 The HuggingFace Team. All rights reserved.
|
| 2 |
+
|
| 3 |
+
Licensed under the Apache License, Version 2.0 (the "License"); you may not use this file except in compliance with
|
| 4 |
+
the License. You may obtain a copy of the License at
|
| 5 |
+
|
| 6 |
+
http://www.apache.org/licenses/LICENSE-2.0
|
| 7 |
+
|
| 8 |
+
Unless required by applicable law or agreed to in writing, software distributed under the License is distributed on
|
| 9 |
+
an "AS IS" BASIS, WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied. See the License for the
|
| 10 |
+
specific language governing permissions and limitations under the License.
|
| 11 |
+
-->
|
| 12 |
+
|
| 13 |
+
# Super-resolution
|
| 14 |
+
|
| 15 |
+
<div class="flex flex-wrap space-x-1">
|
| 16 |
+
<img alt="LoRA" src="https://img.shields.io/badge/LoRA-d8b4fe?style=flat"/>
|
| 17 |
+
</div>
|
| 18 |
+
|
| 19 |
+
The Stable Diffusion upscaler diffusion model was created by the researchers and engineers from [CompVis](https://github.com/CompVis), [Stability AI](https://stability.ai/), and [LAION](https://laion.ai/). It is used to enhance the resolution of input images by a factor of 4.
|
| 20 |
+
|
| 21 |
+
> [!TIP]
|
| 22 |
+
> Make sure to check out the Stable Diffusion [Tips](overview#tips) section to learn how to explore the tradeoff between scheduler speed and quality, and how to reuse pipeline components efficiently!
|
| 23 |
+
>
|
| 24 |
+
> If you're interested in using one of the official checkpoints for a task, explore the [CompVis](https://huggingface.co/CompVis) and [Stability AI](https://huggingface.co/stabilityai) Hub organizations!
|
| 25 |
+
|
| 26 |
+
## StableDiffusionUpscalePipeline
|
| 27 |
+
|
| 28 |
+
[[autodoc]] StableDiffusionUpscalePipeline
|
| 29 |
+
- all
|
| 30 |
+
- __call__
|
| 31 |
+
- enable_attention_slicing
|
| 32 |
+
- disable_attention_slicing
|
| 33 |
+
- enable_xformers_memory_efficient_attention
|
| 34 |
+
- disable_xformers_memory_efficient_attention
|
| 35 |
+
|
| 36 |
+
## StableDiffusionPipelineOutput
|
| 37 |
+
|
| 38 |
+
[[autodoc]] pipelines.stable_diffusion.StableDiffusionPipelineOutput
|
tasks/tasksmith-1c5704b1f07f/tests/source/docs/source/en/api/pipelines/stable_unclip.md
ADDED
|
@@ -0,0 +1,127 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
<!--Copyright 2025 The HuggingFace Team. All rights reserved.
|
| 2 |
+
|
| 3 |
+
Licensed under the Apache License, Version 2.0 (the "License"); you may not use this file except in compliance with
|
| 4 |
+
the License. You may obtain a copy of the License at
|
| 5 |
+
|
| 6 |
+
http://www.apache.org/licenses/LICENSE-2.0
|
| 7 |
+
|
| 8 |
+
Unless required by applicable law or agreed to in writing, software distributed under the License is distributed on
|
| 9 |
+
an "AS IS" BASIS, WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied. See the License for the
|
| 10 |
+
specific language governing permissions and limitations under the License.
|
| 11 |
+
-->
|
| 12 |
+
|
| 13 |
+
# Stable unCLIP
|
| 14 |
+
|
| 15 |
+
<div class="flex flex-wrap space-x-1">
|
| 16 |
+
<img alt="LoRA" src="https://img.shields.io/badge/LoRA-d8b4fe?style=flat"/>
|
| 17 |
+
</div>
|
| 18 |
+
|
| 19 |
+
Stable unCLIP checkpoints are finetuned from [Stable Diffusion 2.1](./stable_diffusion/stable_diffusion_2) checkpoints to condition on CLIP image embeddings.
|
| 20 |
+
Stable unCLIP still conditions on text embeddings. Given the two separate conditionings, stable unCLIP can be used
|
| 21 |
+
for text guided image variation. When combined with an unCLIP prior, it can also be used for full text to image generation.
|
| 22 |
+
|
| 23 |
+
The abstract from the paper is:
|
| 24 |
+
|
| 25 |
+
*Contrastive models like CLIP have been shown to learn robust representations of images that capture both semantics and style. To leverage these representations for image generation, we propose a two-stage model: a prior that generates a CLIP image embedding given a text caption, and a decoder that generates an image conditioned on the image embedding. We show that explicitly generating image representations improves image diversity with minimal loss in photorealism and caption similarity. Our decoders conditioned on image representations can also produce variations of an image that preserve both its semantics and style, while varying the non-essential details absent from the image representation. Moreover, the joint embedding space of CLIP enables language-guided image manipulations in a zero-shot fashion. We use diffusion models for the decoder and experiment with both autoregressive and diffusion models for the prior, finding that the latter are computationally more efficient and produce higher-quality samples.*
|
| 26 |
+
|
| 27 |
+
## Tips
|
| 28 |
+
|
| 29 |
+
Stable unCLIP takes `noise_level` as input during inference which determines how much noise is added to the image embeddings. A higher `noise_level` increases variation in the final un-noised images. By default, we do not add any additional noise to the image embeddings (`noise_level = 0`).
|
| 30 |
+
|
| 31 |
+
### Text-to-Image Generation
|
| 32 |
+
Stable unCLIP can be leveraged for text-to-image generation by pipelining it with the prior model of KakaoBrain's open source DALL-E 2 replication [Karlo](https://huggingface.co/kakaobrain/karlo-v1-alpha):
|
| 33 |
+
|
| 34 |
+
```python
|
| 35 |
+
import torch
|
| 36 |
+
from diffusers import UnCLIPScheduler, DDPMScheduler, StableUnCLIPPipeline
|
| 37 |
+
from diffusers.models import PriorTransformer
|
| 38 |
+
from transformers import CLIPTokenizer, CLIPTextModelWithProjection
|
| 39 |
+
|
| 40 |
+
prior_model_id = "kakaobrain/karlo-v1-alpha"
|
| 41 |
+
data_type = torch.float16
|
| 42 |
+
prior = PriorTransformer.from_pretrained(prior_model_id, subfolder="prior", torch_dtype=data_type)
|
| 43 |
+
|
| 44 |
+
prior_text_model_id = "openai/clip-vit-large-patch14"
|
| 45 |
+
prior_tokenizer = CLIPTokenizer.from_pretrained(prior_text_model_id)
|
| 46 |
+
prior_text_model = CLIPTextModelWithProjection.from_pretrained(prior_text_model_id, torch_dtype=data_type)
|
| 47 |
+
prior_scheduler = UnCLIPScheduler.from_pretrained(prior_model_id, subfolder="prior_scheduler")
|
| 48 |
+
prior_scheduler = DDPMScheduler.from_config(prior_scheduler.config)
|
| 49 |
+
|
| 50 |
+
stable_unclip_model_id = "stabilityai/stable-diffusion-2-1-unclip-small"
|
| 51 |
+
|
| 52 |
+
pipe = StableUnCLIPPipeline.from_pretrained(
|
| 53 |
+
stable_unclip_model_id,
|
| 54 |
+
torch_dtype=data_type,
|
| 55 |
+
variant="fp16",
|
| 56 |
+
prior_tokenizer=prior_tokenizer,
|
| 57 |
+
prior_text_encoder=prior_text_model,
|
| 58 |
+
prior=prior,
|
| 59 |
+
prior_scheduler=prior_scheduler,
|
| 60 |
+
)
|
| 61 |
+
|
| 62 |
+
pipe = pipe.to("cuda")
|
| 63 |
+
wave_prompt = "dramatic wave, the Oceans roar, Strong wave spiral across the oceans as the waves unfurl into roaring crests; perfect wave form; perfect wave shape; dramatic wave shape; wave shape unbelievable; wave; wave shape spectacular"
|
| 64 |
+
|
| 65 |
+
image = pipe(prompt=wave_prompt).images[0]
|
| 66 |
+
image
|
| 67 |
+
```
|
| 68 |
+
> [!WARNING]
|
| 69 |
+
> For text-to-image we use `stabilityai/stable-diffusion-2-1-unclip-small` as it was trained on CLIP ViT-L/14 embedding, the same as the Karlo model prior. [stabilityai/stable-diffusion-2-1-unclip](https://hf.co/stabilityai/stable-diffusion-2-1-unclip) was trained on OpenCLIP ViT-H, so we don't recommend its use.
|
| 70 |
+
|
| 71 |
+
### Text guided Image-to-Image Variation
|
| 72 |
+
|
| 73 |
+
```python
|
| 74 |
+
from diffusers import StableUnCLIPImg2ImgPipeline
|
| 75 |
+
from diffusers.utils import load_image
|
| 76 |
+
import torch
|
| 77 |
+
|
| 78 |
+
pipe = StableUnCLIPImg2ImgPipeline.from_pretrained(
|
| 79 |
+
"stabilityai/stable-diffusion-2-1-unclip", torch_dtype=torch.float16, variation="fp16"
|
| 80 |
+
)
|
| 81 |
+
pipe = pipe.to("cuda")
|
| 82 |
+
|
| 83 |
+
url = "https://huggingface.co/datasets/hf-internal-testing/diffusers-images/resolve/main/stable_unclip/tarsila_do_amaral.png"
|
| 84 |
+
init_image = load_image(url)
|
| 85 |
+
|
| 86 |
+
images = pipe(init_image).images
|
| 87 |
+
images[0].save("variation_image.png")
|
| 88 |
+
```
|
| 89 |
+
|
| 90 |
+
Optionally, you can also pass a prompt to `pipe` such as:
|
| 91 |
+
|
| 92 |
+
```python
|
| 93 |
+
prompt = "A fantasy landscape, trending on artstation"
|
| 94 |
+
|
| 95 |
+
image = pipe(init_image, prompt=prompt).images[0]
|
| 96 |
+
image
|
| 97 |
+
```
|
| 98 |
+
|
| 99 |
+
> [!TIP]
|
| 100 |
+
> Make sure to check out the Schedulers [guide](../../using-diffusers/schedulers) to learn how to explore the tradeoff between scheduler speed and quality, and see the [reuse components across pipelines](../../using-diffusers/loading#reuse-a-pipeline) section to learn how to efficiently load the same components into multiple pipelines.
|
| 101 |
+
|
| 102 |
+
## StableUnCLIPPipeline
|
| 103 |
+
|
| 104 |
+
[[autodoc]] StableUnCLIPPipeline
|
| 105 |
+
- all
|
| 106 |
+
- __call__
|
| 107 |
+
- enable_attention_slicing
|
| 108 |
+
- disable_attention_slicing
|
| 109 |
+
- enable_vae_slicing
|
| 110 |
+
- disable_vae_slicing
|
| 111 |
+
- enable_xformers_memory_efficient_attention
|
| 112 |
+
- disable_xformers_memory_efficient_attention
|
| 113 |
+
|
| 114 |
+
## StableUnCLIPImg2ImgPipeline
|
| 115 |
+
|
| 116 |
+
[[autodoc]] StableUnCLIPImg2ImgPipeline
|
| 117 |
+
- all
|
| 118 |
+
- __call__
|
| 119 |
+
- enable_attention_slicing
|
| 120 |
+
- disable_attention_slicing
|
| 121 |
+
- enable_vae_slicing
|
| 122 |
+
- disable_vae_slicing
|
| 123 |
+
- enable_xformers_memory_efficient_attention
|
| 124 |
+
- disable_xformers_memory_efficient_attention
|
| 125 |
+
|
| 126 |
+
## ImagePipelineOutput
|
| 127 |
+
[[autodoc]] pipelines.ImagePipelineOutput
|
tasks/tasksmith-1c5704b1f07f/tests/source/docs/source/en/api/pipelines/text_to_video.md
ADDED
|
@@ -0,0 +1,191 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
<!--Copyright 2025 The HuggingFace Team. All rights reserved.
|
| 2 |
+
|
| 3 |
+
Licensed under the Apache License, Version 2.0 (the "License"); you may not use this file except in compliance with
|
| 4 |
+
the License. You may obtain a copy of the License at
|
| 5 |
+
|
| 6 |
+
http://www.apache.org/licenses/LICENSE-2.0
|
| 7 |
+
|
| 8 |
+
Unless required by applicable law or agreed to in writing, software distributed under the License is distributed on
|
| 9 |
+
an "AS IS" BASIS, WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied. See the License for the
|
| 10 |
+
specific language governing permissions and limitations under the License.
|
| 11 |
+
-->
|
| 12 |
+
|
| 13 |
+
> [!WARNING]
|
| 14 |
+
> This pipeline is deprecated but it can still be used. However, we won't test the pipeline anymore and won't accept any changes to it. If you run into any issues, reinstall the last Diffusers version that supported this model.
|
| 15 |
+
|
| 16 |
+
# Text-to-video
|
| 17 |
+
|
| 18 |
+
<div class="flex flex-wrap space-x-1">
|
| 19 |
+
<img alt="LoRA" src="https://img.shields.io/badge/LoRA-d8b4fe?style=flat"/>
|
| 20 |
+
</div>
|
| 21 |
+
|
| 22 |
+
[ModelScope Text-to-Video Technical Report](https://huggingface.co/papers/2308.06571) is by Jiuniu Wang, Hangjie Yuan, Dayou Chen, Yingya Zhang, Xiang Wang, Shiwei Zhang.
|
| 23 |
+
|
| 24 |
+
The abstract from the paper is:
|
| 25 |
+
|
| 26 |
+
*This paper introduces ModelScopeT2V, a text-to-video synthesis model that evolves from a text-to-image synthesis model (i.e., Stable Diffusion). ModelScopeT2V incorporates spatio-temporal blocks to ensure consistent frame generation and smooth movement transitions. The model could adapt to varying frame numbers during training and inference, rendering it suitable for both image-text and video-text datasets. ModelScopeT2V brings together three components (i.e., VQGAN, a text encoder, and a denoising UNet), totally comprising 1.7 billion parameters, in which 0.5 billion parameters are dedicated to temporal capabilities. The model demonstrates superior performance over state-of-the-art methods across three evaluation metrics. The code and an online demo are available at https://modelscope.cn/models/damo/text-to-video-synthesis/summary.*
|
| 27 |
+
|
| 28 |
+
You can find additional information about Text-to-Video on the [project page](https://modelscope.cn/models/damo/text-to-video-synthesis/summary), [original codebase](https://github.com/modelscope/modelscope/), and try it out in a [demo](https://huggingface.co/spaces/damo-vilab/modelscope-text-to-video-synthesis). Official checkpoints can be found at [damo-vilab](https://huggingface.co/damo-vilab) and [cerspense](https://huggingface.co/cerspense).
|
| 29 |
+
|
| 30 |
+
## Usage example
|
| 31 |
+
|
| 32 |
+
### `text-to-video-ms-1.7b`
|
| 33 |
+
|
| 34 |
+
Let's start by generating a short video with the default length of 16 frames (2s at 8 fps):
|
| 35 |
+
|
| 36 |
+
```python
|
| 37 |
+
import torch
|
| 38 |
+
from diffusers import DiffusionPipeline
|
| 39 |
+
from diffusers.utils import export_to_video
|
| 40 |
+
|
| 41 |
+
pipe = DiffusionPipeline.from_pretrained("damo-vilab/text-to-video-ms-1.7b", torch_dtype=torch.float16, variant="fp16")
|
| 42 |
+
pipe = pipe.to("cuda")
|
| 43 |
+
|
| 44 |
+
prompt = "Spiderman is surfing"
|
| 45 |
+
video_frames = pipe(prompt).frames[0]
|
| 46 |
+
video_path = export_to_video(video_frames)
|
| 47 |
+
video_path
|
| 48 |
+
```
|
| 49 |
+
|
| 50 |
+
Diffusers supports different optimization techniques to improve the latency
|
| 51 |
+
and memory footprint of a pipeline. Since videos are often more memory-heavy than images,
|
| 52 |
+
we can enable CPU offloading and VAE slicing to keep the memory footprint at bay.
|
| 53 |
+
|
| 54 |
+
Let's generate a video of 8 seconds (64 frames) on the same GPU using CPU offloading and VAE slicing:
|
| 55 |
+
|
| 56 |
+
```python
|
| 57 |
+
import torch
|
| 58 |
+
from diffusers import DiffusionPipeline
|
| 59 |
+
from diffusers.utils import export_to_video
|
| 60 |
+
|
| 61 |
+
pipe = DiffusionPipeline.from_pretrained("damo-vilab/text-to-video-ms-1.7b", torch_dtype=torch.float16, variant="fp16")
|
| 62 |
+
pipe.enable_model_cpu_offload()
|
| 63 |
+
|
| 64 |
+
# memory optimization
|
| 65 |
+
pipe.enable_vae_slicing()
|
| 66 |
+
|
| 67 |
+
prompt = "Darth Vader surfing a wave"
|
| 68 |
+
video_frames = pipe(prompt, num_frames=64).frames[0]
|
| 69 |
+
video_path = export_to_video(video_frames)
|
| 70 |
+
video_path
|
| 71 |
+
```
|
| 72 |
+
|
| 73 |
+
It just takes **7 GBs of GPU memory** to generate the 64 video frames using PyTorch 2.0, "fp16" precision and the techniques mentioned above.
|
| 74 |
+
|
| 75 |
+
We can also use a different scheduler easily, using the same method we'd use for Stable Diffusion:
|
| 76 |
+
|
| 77 |
+
```python
|
| 78 |
+
import torch
|
| 79 |
+
from diffusers import DiffusionPipeline, DPMSolverMultistepScheduler
|
| 80 |
+
from diffusers.utils import export_to_video
|
| 81 |
+
|
| 82 |
+
pipe = DiffusionPipeline.from_pretrained("damo-vilab/text-to-video-ms-1.7b", torch_dtype=torch.float16, variant="fp16")
|
| 83 |
+
pipe.scheduler = DPMSolverMultistepScheduler.from_config(pipe.scheduler.config)
|
| 84 |
+
pipe.enable_model_cpu_offload()
|
| 85 |
+
|
| 86 |
+
prompt = "Spiderman is surfing"
|
| 87 |
+
video_frames = pipe(prompt, num_inference_steps=25).frames[0]
|
| 88 |
+
video_path = export_to_video(video_frames)
|
| 89 |
+
video_path
|
| 90 |
+
```
|
| 91 |
+
|
| 92 |
+
Here are some sample outputs:
|
| 93 |
+
|
| 94 |
+
<table>
|
| 95 |
+
<tr>
|
| 96 |
+
<td><center>
|
| 97 |
+
An astronaut riding a horse.
|
| 98 |
+
<br>
|
| 99 |
+
<img src="https://huggingface.co/datasets/huggingface/documentation-images/resolve/main/diffusers/astr.gif"
|
| 100 |
+
alt="An astronaut riding a horse."
|
| 101 |
+
style="width: 300px;" />
|
| 102 |
+
</center></td>
|
| 103 |
+
<td ><center>
|
| 104 |
+
Darth vader surfing in waves.
|
| 105 |
+
<br>
|
| 106 |
+
<img src="https://huggingface.co/datasets/huggingface/documentation-images/resolve/main/diffusers/vader.gif"
|
| 107 |
+
alt="Darth vader surfing in waves."
|
| 108 |
+
style="width: 300px;" />
|
| 109 |
+
</center></td>
|
| 110 |
+
</tr>
|
| 111 |
+
</table>
|
| 112 |
+
|
| 113 |
+
### `cerspense/zeroscope_v2_576w` & `cerspense/zeroscope_v2_XL`
|
| 114 |
+
|
| 115 |
+
Zeroscope are watermark-free model and have been trained on specific sizes such as `576x320` and `1024x576`.
|
| 116 |
+
One should first generate a video using the lower resolution checkpoint [`cerspense/zeroscope_v2_576w`](https://huggingface.co/cerspense/zeroscope_v2_576w) with [`TextToVideoSDPipeline`],
|
| 117 |
+
which can then be upscaled using [`VideoToVideoSDPipeline`] and [`cerspense/zeroscope_v2_XL`](https://huggingface.co/cerspense/zeroscope_v2_XL).
|
| 118 |
+
|
| 119 |
+
|
| 120 |
+
```py
|
| 121 |
+
import torch
|
| 122 |
+
from diffusers import DiffusionPipeline, DPMSolverMultistepScheduler
|
| 123 |
+
from diffusers.utils import export_to_video
|
| 124 |
+
from PIL import Image
|
| 125 |
+
|
| 126 |
+
pipe = DiffusionPipeline.from_pretrained("cerspense/zeroscope_v2_576w", torch_dtype=torch.float16)
|
| 127 |
+
pipe.enable_model_cpu_offload()
|
| 128 |
+
|
| 129 |
+
# memory optimization
|
| 130 |
+
pipe.unet.enable_forward_chunking(chunk_size=1, dim=1)
|
| 131 |
+
pipe.enable_vae_slicing()
|
| 132 |
+
|
| 133 |
+
prompt = "Darth Vader surfing a wave"
|
| 134 |
+
video_frames = pipe(prompt, num_frames=24).frames[0]
|
| 135 |
+
video_path = export_to_video(video_frames)
|
| 136 |
+
video_path
|
| 137 |
+
```
|
| 138 |
+
|
| 139 |
+
Now the video can be upscaled:
|
| 140 |
+
|
| 141 |
+
```py
|
| 142 |
+
pipe = DiffusionPipeline.from_pretrained("cerspense/zeroscope_v2_XL", torch_dtype=torch.float16)
|
| 143 |
+
pipe.scheduler = DPMSolverMultistepScheduler.from_config(pipe.scheduler.config)
|
| 144 |
+
pipe.enable_model_cpu_offload()
|
| 145 |
+
|
| 146 |
+
# memory optimization
|
| 147 |
+
pipe.unet.enable_forward_chunking(chunk_size=1, dim=1)
|
| 148 |
+
pipe.enable_vae_slicing()
|
| 149 |
+
|
| 150 |
+
video = [Image.fromarray(frame).resize((1024, 576)) for frame in video_frames]
|
| 151 |
+
|
| 152 |
+
video_frames = pipe(prompt, video=video, strength=0.6).frames[0]
|
| 153 |
+
video_path = export_to_video(video_frames)
|
| 154 |
+
video_path
|
| 155 |
+
```
|
| 156 |
+
|
| 157 |
+
Here are some sample outputs:
|
| 158 |
+
|
| 159 |
+
<table>
|
| 160 |
+
<tr>
|
| 161 |
+
<td ><center>
|
| 162 |
+
Darth vader surfing in waves.
|
| 163 |
+
<br>
|
| 164 |
+
<img src="https://huggingface.co/datasets/huggingface/documentation-images/resolve/main/diffusers/darthvader_cerpense.gif"
|
| 165 |
+
alt="Darth vader surfing in waves."
|
| 166 |
+
style="width: 576px;" />
|
| 167 |
+
</center></td>
|
| 168 |
+
</tr>
|
| 169 |
+
</table>
|
| 170 |
+
|
| 171 |
+
## Tips
|
| 172 |
+
|
| 173 |
+
Video generation is memory-intensive and one way to reduce your memory usage is to set `enable_forward_chunking` on the pipeline's UNet so you don't run the entire feedforward layer at once. Breaking it up into chunks in a loop is more efficient.
|
| 174 |
+
|
| 175 |
+
Check out the [Text or image-to-video](../../using-diffusers/text-img2vid) guide for more details about how certain parameters can affect video generation and how to optimize inference by reducing memory usage.
|
| 176 |
+
|
| 177 |
+
> [!TIP]
|
| 178 |
+
> Make sure to check out the Schedulers [guide](../../using-diffusers/schedulers) to learn how to explore the tradeoff between scheduler speed and quality, and see the [reuse components across pipelines](../../using-diffusers/loading#reuse-a-pipeline) section to learn how to efficiently load the same components into multiple pipelines.
|
| 179 |
+
|
| 180 |
+
## TextToVideoSDPipeline
|
| 181 |
+
[[autodoc]] TextToVideoSDPipeline
|
| 182 |
+
- all
|
| 183 |
+
- __call__
|
| 184 |
+
|
| 185 |
+
## VideoToVideoSDPipeline
|
| 186 |
+
[[autodoc]] VideoToVideoSDPipeline
|
| 187 |
+
- all
|
| 188 |
+
- __call__
|
| 189 |
+
|
| 190 |
+
## TextToVideoSDPipelineOutput
|
| 191 |
+
[[autodoc]] pipelines.text_to_video_synthesis.TextToVideoSDPipelineOutput
|
tasks/tasksmith-1c5704b1f07f/tests/source/docs/source/en/api/pipelines/text_to_video_zero.md
ADDED
|
@@ -0,0 +1,306 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
<!--Copyright 2025 The HuggingFace Team. All rights reserved.
|
| 2 |
+
|
| 3 |
+
Licensed under the Apache License, Version 2.0 (the "License"); you may not use this file except in compliance with
|
| 4 |
+
the License. You may obtain a copy of the License at
|
| 5 |
+
|
| 6 |
+
http://www.apache.org/licenses/LICENSE-2.0
|
| 7 |
+
|
| 8 |
+
Unless required by applicable law or agreed to in writing, software distributed under the License is distributed on
|
| 9 |
+
an "AS IS" BASIS, WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied. See the License for the
|
| 10 |
+
specific language governing permissions and limitations under the License.
|
| 11 |
+
-->
|
| 12 |
+
|
| 13 |
+
> [!WARNING]
|
| 14 |
+
> This pipeline is deprecated but it can still be used. However, we won't test the pipeline anymore and won't accept any changes to it. If you run into any issues, reinstall the last Diffusers version that supported this model.
|
| 15 |
+
|
| 16 |
+
# Text2Video-Zero
|
| 17 |
+
|
| 18 |
+
<div class="flex flex-wrap space-x-1">
|
| 19 |
+
<img alt="LoRA" src="https://img.shields.io/badge/LoRA-d8b4fe?style=flat"/>
|
| 20 |
+
</div>
|
| 21 |
+
|
| 22 |
+
[Text2Video-Zero: Text-to-Image Diffusion Models are Zero-Shot Video Generators](https://huggingface.co/papers/2303.13439) is by Levon Khachatryan, Andranik Movsisyan, Vahram Tadevosyan, Roberto Henschel, [Zhangyang Wang](https://www.ece.utexas.edu/people/faculty/atlas-wang), Shant Navasardyan, [Humphrey Shi](https://www.humphreyshi.com).
|
| 23 |
+
|
| 24 |
+
Text2Video-Zero enables zero-shot video generation using either:
|
| 25 |
+
1. A textual prompt
|
| 26 |
+
2. A prompt combined with guidance from poses or edges
|
| 27 |
+
3. Video Instruct-Pix2Pix (instruction-guided video editing)
|
| 28 |
+
|
| 29 |
+
Results are temporally consistent and closely follow the guidance and textual prompts.
|
| 30 |
+
|
| 31 |
+
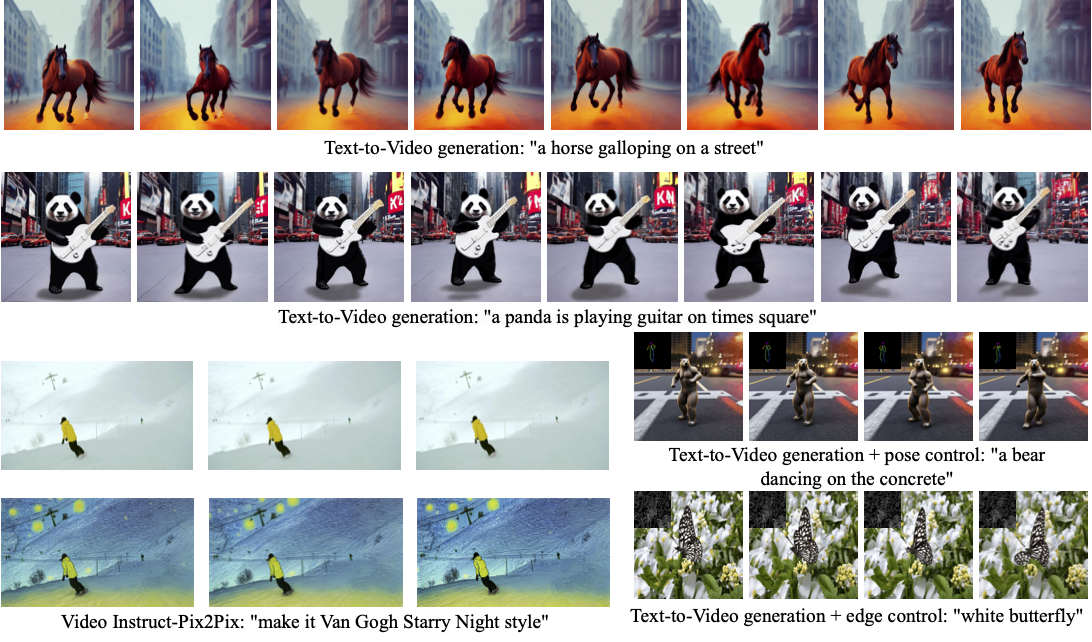
|
| 32 |
+
|
| 33 |
+
The abstract from the paper is:
|
| 34 |
+
|
| 35 |
+
*Recent text-to-video generation approaches rely on computationally heavy training and require large-scale video datasets. In this paper, we introduce a new task of zero-shot text-to-video generation and propose a low-cost approach (without any training or optimization) by leveraging the power of existing text-to-image synthesis methods (e.g., Stable Diffusion), making them suitable for the video domain.
|
| 36 |
+
Our key modifications include (i) enriching the latent codes of the generated frames with motion dynamics to keep the global scene and the background time consistent; and (ii) reprogramming frame-level self-attention using a new cross-frame attention of each frame on the first frame, to preserve the context, appearance, and identity of the foreground object.
|
| 37 |
+
Experiments show that this leads to low overhead, yet high-quality and remarkably consistent video generation. Moreover, our approach is not limited to text-to-video synthesis but is also applicable to other tasks such as conditional and content-specialized video generation, and Video Instruct-Pix2Pix, i.e., instruction-guided video editing.
|
| 38 |
+
As experiments show, our method performs comparably or sometimes better than recent approaches, despite not being trained on additional video data.*
|
| 39 |
+
|
| 40 |
+
You can find additional information about Text2Video-Zero on the [project page](https://text2video-zero.github.io/), [paper](https://huggingface.co/papers/2303.13439), and [original codebase](https://github.com/Picsart-AI-Research/Text2Video-Zero).
|
| 41 |
+
|
| 42 |
+
## Usage example
|
| 43 |
+
|
| 44 |
+
### Text-To-Video
|
| 45 |
+
|
| 46 |
+
To generate a video from prompt, run the following Python code:
|
| 47 |
+
```python
|
| 48 |
+
import torch
|
| 49 |
+
from diffusers import TextToVideoZeroPipeline
|
| 50 |
+
import imageio
|
| 51 |
+
|
| 52 |
+
model_id = "stable-diffusion-v1-5/stable-diffusion-v1-5"
|
| 53 |
+
pipe = TextToVideoZeroPipeline.from_pretrained(model_id, torch_dtype=torch.float16).to("cuda")
|
| 54 |
+
|
| 55 |
+
prompt = "A panda is playing guitar on times square"
|
| 56 |
+
result = pipe(prompt=prompt).images
|
| 57 |
+
result = [(r * 255).astype("uint8") for r in result]
|
| 58 |
+
imageio.mimsave("video.mp4", result, fps=4)
|
| 59 |
+
```
|
| 60 |
+
You can change these parameters in the pipeline call:
|
| 61 |
+
* Motion field strength (see the [paper](https://huggingface.co/papers/2303.13439), Sect. 3.3.1):
|
| 62 |
+
* `motion_field_strength_x` and `motion_field_strength_y`. Default: `motion_field_strength_x=12`, `motion_field_strength_y=12`
|
| 63 |
+
* `T` and `T'` (see the [paper](https://huggingface.co/papers/2303.13439), Sect. 3.3.1)
|
| 64 |
+
* `t0` and `t1` in the range `{0, ..., num_inference_steps}`. Default: `t0=45`, `t1=48`
|
| 65 |
+
* Video length:
|
| 66 |
+
* `video_length`, the number of frames video_length to be generated. Default: `video_length=8`
|
| 67 |
+
|
| 68 |
+
We can also generate longer videos by doing the processing in a chunk-by-chunk manner:
|
| 69 |
+
```python
|
| 70 |
+
import torch
|
| 71 |
+
from diffusers import TextToVideoZeroPipeline
|
| 72 |
+
import numpy as np
|
| 73 |
+
|
| 74 |
+
model_id = "stable-diffusion-v1-5/stable-diffusion-v1-5"
|
| 75 |
+
pipe = TextToVideoZeroPipeline.from_pretrained(model_id, torch_dtype=torch.float16).to("cuda")
|
| 76 |
+
seed = 0
|
| 77 |
+
video_length = 24 #24 ÷ 4fps = 6 seconds
|
| 78 |
+
chunk_size = 8
|
| 79 |
+
prompt = "A panda is playing guitar on times square"
|
| 80 |
+
|
| 81 |
+
# Generate the video chunk-by-chunk
|
| 82 |
+
result = []
|
| 83 |
+
chunk_ids = np.arange(0, video_length, chunk_size - 1)
|
| 84 |
+
generator = torch.Generator(device="cuda")
|
| 85 |
+
for i in range(len(chunk_ids)):
|
| 86 |
+
print(f"Processing chunk {i + 1} / {len(chunk_ids)}")
|
| 87 |
+
ch_start = chunk_ids[i]
|
| 88 |
+
ch_end = video_length if i == len(chunk_ids) - 1 else chunk_ids[i + 1]
|
| 89 |
+
# Attach the first frame for Cross Frame Attention
|
| 90 |
+
frame_ids = [0] + list(range(ch_start, ch_end))
|
| 91 |
+
# Fix the seed for the temporal consistency
|
| 92 |
+
generator.manual_seed(seed)
|
| 93 |
+
output = pipe(prompt=prompt, video_length=len(frame_ids), generator=generator, frame_ids=frame_ids)
|
| 94 |
+
result.append(output.images[1:])
|
| 95 |
+
|
| 96 |
+
# Concatenate chunks and save
|
| 97 |
+
result = np.concatenate(result)
|
| 98 |
+
result = [(r * 255).astype("uint8") for r in result]
|
| 99 |
+
imageio.mimsave("video.mp4", result, fps=4)
|
| 100 |
+
```
|
| 101 |
+
|
| 102 |
+
|
| 103 |
+
- #### SDXL Support
|
| 104 |
+
In order to use the SDXL model when generating a video from prompt, use the `TextToVideoZeroSDXLPipeline` pipeline:
|
| 105 |
+
|
| 106 |
+
```python
|
| 107 |
+
import torch
|
| 108 |
+
from diffusers import TextToVideoZeroSDXLPipeline
|
| 109 |
+
|
| 110 |
+
model_id = "stabilityai/stable-diffusion-xl-base-1.0"
|
| 111 |
+
pipe = TextToVideoZeroSDXLPipeline.from_pretrained(
|
| 112 |
+
model_id, torch_dtype=torch.float16, variant="fp16", use_safetensors=True
|
| 113 |
+
).to("cuda")
|
| 114 |
+
```
|
| 115 |
+
|
| 116 |
+
### Text-To-Video with Pose Control
|
| 117 |
+
To generate a video from prompt with additional pose control
|
| 118 |
+
|
| 119 |
+
1. Download a demo video
|
| 120 |
+
|
| 121 |
+
```python
|
| 122 |
+
from huggingface_hub import hf_hub_download
|
| 123 |
+
|
| 124 |
+
filename = "__assets__/poses_skeleton_gifs/dance1_corr.mp4"
|
| 125 |
+
repo_id = "PAIR/Text2Video-Zero"
|
| 126 |
+
video_path = hf_hub_download(repo_type="space", repo_id=repo_id, filename=filename)
|
| 127 |
+
```
|
| 128 |
+
|
| 129 |
+
|
| 130 |
+
2. Read video containing extracted pose images
|
| 131 |
+
```python
|
| 132 |
+
from PIL import Image
|
| 133 |
+
import imageio
|
| 134 |
+
|
| 135 |
+
reader = imageio.get_reader(video_path, "ffmpeg")
|
| 136 |
+
frame_count = 8
|
| 137 |
+
pose_images = [Image.fromarray(reader.get_data(i)) for i in range(frame_count)]
|
| 138 |
+
```
|
| 139 |
+
To extract pose from actual video, read [ControlNet documentation](controlnet).
|
| 140 |
+
|
| 141 |
+
3. Run `StableDiffusionControlNetPipeline` with our custom attention processor
|
| 142 |
+
|
| 143 |
+
```python
|
| 144 |
+
import torch
|
| 145 |
+
from diffusers import StableDiffusionControlNetPipeline, ControlNetModel
|
| 146 |
+
from diffusers.pipelines.text_to_video_synthesis.pipeline_text_to_video_zero import CrossFrameAttnProcessor
|
| 147 |
+
|
| 148 |
+
model_id = "stable-diffusion-v1-5/stable-diffusion-v1-5"
|
| 149 |
+
controlnet = ControlNetModel.from_pretrained("lllyasviel/sd-controlnet-openpose", torch_dtype=torch.float16)
|
| 150 |
+
pipe = StableDiffusionControlNetPipeline.from_pretrained(
|
| 151 |
+
model_id, controlnet=controlnet, torch_dtype=torch.float16
|
| 152 |
+
).to("cuda")
|
| 153 |
+
|
| 154 |
+
# Set the attention processor
|
| 155 |
+
pipe.unet.set_attn_processor(CrossFrameAttnProcessor(batch_size=2))
|
| 156 |
+
pipe.controlnet.set_attn_processor(CrossFrameAttnProcessor(batch_size=2))
|
| 157 |
+
|
| 158 |
+
# fix latents for all frames
|
| 159 |
+
latents = torch.randn((1, 4, 64, 64), device="cuda", dtype=torch.float16).repeat(len(pose_images), 1, 1, 1)
|
| 160 |
+
|
| 161 |
+
prompt = "Darth Vader dancing in a desert"
|
| 162 |
+
result = pipe(prompt=[prompt] * len(pose_images), image=pose_images, latents=latents).images
|
| 163 |
+
imageio.mimsave("video.mp4", result, fps=4)
|
| 164 |
+
```
|
| 165 |
+
- #### SDXL Support
|
| 166 |
+
|
| 167 |
+
Since our attention processor also works with SDXL, it can be utilized to generate a video from prompt using ControlNet models powered by SDXL:
|
| 168 |
+
```python
|
| 169 |
+
import torch
|
| 170 |
+
from diffusers import StableDiffusionXLControlNetPipeline, ControlNetModel
|
| 171 |
+
from diffusers.pipelines.text_to_video_synthesis.pipeline_text_to_video_zero import CrossFrameAttnProcessor
|
| 172 |
+
|
| 173 |
+
controlnet_model_id = 'thibaud/controlnet-openpose-sdxl-1.0'
|
| 174 |
+
model_id = 'stabilityai/stable-diffusion-xl-base-1.0'
|
| 175 |
+
|
| 176 |
+
controlnet = ControlNetModel.from_pretrained(controlnet_model_id, torch_dtype=torch.float16)
|
| 177 |
+
pipe = StableDiffusionControlNetPipeline.from_pretrained(
|
| 178 |
+
model_id, controlnet=controlnet, torch_dtype=torch.float16
|
| 179 |
+
).to('cuda')
|
| 180 |
+
|
| 181 |
+
# Set the attention processor
|
| 182 |
+
pipe.unet.set_attn_processor(CrossFrameAttnProcessor(batch_size=2))
|
| 183 |
+
pipe.controlnet.set_attn_processor(CrossFrameAttnProcessor(batch_size=2))
|
| 184 |
+
|
| 185 |
+
# fix latents for all frames
|
| 186 |
+
latents = torch.randn((1, 4, 128, 128), device="cuda", dtype=torch.float16).repeat(len(pose_images), 1, 1, 1)
|
| 187 |
+
|
| 188 |
+
prompt = "Darth Vader dancing in a desert"
|
| 189 |
+
result = pipe(prompt=[prompt] * len(pose_images), image=pose_images, latents=latents).images
|
| 190 |
+
imageio.mimsave("video.mp4", result, fps=4)
|
| 191 |
+
```
|
| 192 |
+
|
| 193 |
+
### Text-To-Video with Edge Control
|
| 194 |
+
|
| 195 |
+
To generate a video from prompt with additional Canny edge control, follow the same steps described above for pose-guided generation using [Canny edge ControlNet model](https://huggingface.co/lllyasviel/sd-controlnet-canny).
|
| 196 |
+
|
| 197 |
+
|
| 198 |
+
### Video Instruct-Pix2Pix
|
| 199 |
+
|
| 200 |
+
To perform text-guided video editing (with [InstructPix2Pix](pix2pix)):
|
| 201 |
+
|
| 202 |
+
1. Download a demo video
|
| 203 |
+
|
| 204 |
+
```python
|
| 205 |
+
from huggingface_hub import hf_hub_download
|
| 206 |
+
|
| 207 |
+
filename = "__assets__/pix2pix video/camel.mp4"
|
| 208 |
+
repo_id = "PAIR/Text2Video-Zero"
|
| 209 |
+
video_path = hf_hub_download(repo_type="space", repo_id=repo_id, filename=filename)
|
| 210 |
+
```
|
| 211 |
+
|
| 212 |
+
2. Read video from path
|
| 213 |
+
```python
|
| 214 |
+
from PIL import Image
|
| 215 |
+
import imageio
|
| 216 |
+
|
| 217 |
+
reader = imageio.get_reader(video_path, "ffmpeg")
|
| 218 |
+
frame_count = 8
|
| 219 |
+
video = [Image.fromarray(reader.get_data(i)) for i in range(frame_count)]
|
| 220 |
+
```
|
| 221 |
+
|
| 222 |
+
3. Run `StableDiffusionInstructPix2PixPipeline` with our custom attention processor
|
| 223 |
+
```python
|
| 224 |
+
import torch
|
| 225 |
+
from diffusers import StableDiffusionInstructPix2PixPipeline
|
| 226 |
+
from diffusers.pipelines.text_to_video_synthesis.pipeline_text_to_video_zero import CrossFrameAttnProcessor
|
| 227 |
+
|
| 228 |
+
model_id = "timbrooks/instruct-pix2pix"
|
| 229 |
+
pipe = StableDiffusionInstructPix2PixPipeline.from_pretrained(model_id, torch_dtype=torch.float16).to("cuda")
|
| 230 |
+
pipe.unet.set_attn_processor(CrossFrameAttnProcessor(batch_size=3))
|
| 231 |
+
|
| 232 |
+
prompt = "make it Van Gogh Starry Night style"
|
| 233 |
+
result = pipe(prompt=[prompt] * len(video), image=video).images
|
| 234 |
+
imageio.mimsave("edited_video.mp4", result, fps=4)
|
| 235 |
+
```
|
| 236 |
+
|
| 237 |
+
|
| 238 |
+
### DreamBooth specialization
|
| 239 |
+
|
| 240 |
+
Methods **Text-To-Video**, **Text-To-Video with Pose Control** and **Text-To-Video with Edge Control**
|
| 241 |
+
can run with custom [DreamBooth](../../training/dreambooth) models, as shown below for
|
| 242 |
+
[Canny edge ControlNet model](https://huggingface.co/lllyasviel/sd-controlnet-canny) and
|
| 243 |
+
[Avatar style DreamBooth](https://huggingface.co/PAIR/text2video-zero-controlnet-canny-avatar) model:
|
| 244 |
+
|
| 245 |
+
1. Download a demo video
|
| 246 |
+
|
| 247 |
+
```python
|
| 248 |
+
from huggingface_hub import hf_hub_download
|
| 249 |
+
|
| 250 |
+
filename = "__assets__/canny_videos_mp4/girl_turning.mp4"
|
| 251 |
+
repo_id = "PAIR/Text2Video-Zero"
|
| 252 |
+
video_path = hf_hub_download(repo_type="space", repo_id=repo_id, filename=filename)
|
| 253 |
+
```
|
| 254 |
+
|
| 255 |
+
2. Read video from path
|
| 256 |
+
```python
|
| 257 |
+
from PIL import Image
|
| 258 |
+
import imageio
|
| 259 |
+
|
| 260 |
+
reader = imageio.get_reader(video_path, "ffmpeg")
|
| 261 |
+
frame_count = 8
|
| 262 |
+
canny_edges = [Image.fromarray(reader.get_data(i)) for i in range(frame_count)]
|
| 263 |
+
```
|
| 264 |
+
|
| 265 |
+
3. Run `StableDiffusionControlNetPipeline` with custom trained DreamBooth model
|
| 266 |
+
```python
|
| 267 |
+
import torch
|
| 268 |
+
from diffusers import StableDiffusionControlNetPipeline, ControlNetModel
|
| 269 |
+
from diffusers.pipelines.text_to_video_synthesis.pipeline_text_to_video_zero import CrossFrameAttnProcessor
|
| 270 |
+
|
| 271 |
+
# set model id to custom model
|
| 272 |
+
model_id = "PAIR/text2video-zero-controlnet-canny-avatar"
|
| 273 |
+
controlnet = ControlNetModel.from_pretrained("lllyasviel/sd-controlnet-canny", torch_dtype=torch.float16)
|
| 274 |
+
pipe = StableDiffusionControlNetPipeline.from_pretrained(
|
| 275 |
+
model_id, controlnet=controlnet, torch_dtype=torch.float16
|
| 276 |
+
).to("cuda")
|
| 277 |
+
|
| 278 |
+
# Set the attention processor
|
| 279 |
+
pipe.unet.set_attn_processor(CrossFrameAttnProcessor(batch_size=2))
|
| 280 |
+
pipe.controlnet.set_attn_processor(CrossFrameAttnProcessor(batch_size=2))
|
| 281 |
+
|
| 282 |
+
# fix latents for all frames
|
| 283 |
+
latents = torch.randn((1, 4, 64, 64), device="cuda", dtype=torch.float16).repeat(len(canny_edges), 1, 1, 1)
|
| 284 |
+
|
| 285 |
+
prompt = "oil painting of a beautiful girl avatar style"
|
| 286 |
+
result = pipe(prompt=[prompt] * len(canny_edges), image=canny_edges, latents=latents).images
|
| 287 |
+
imageio.mimsave("video.mp4", result, fps=4)
|
| 288 |
+
```
|
| 289 |
+
|
| 290 |
+
You can filter out some available DreamBooth-trained models with [this link](https://huggingface.co/models?search=dreambooth).
|
| 291 |
+
|
| 292 |
+
> [!TIP]
|
| 293 |
+
> Make sure to check out the Schedulers [guide](../../using-diffusers/schedulers) to learn how to explore the tradeoff between scheduler speed and quality, and see the [reuse components across pipelines](../../using-diffusers/loading#reuse-a-pipeline) section to learn how to efficiently load the same components into multiple pipelines.
|
| 294 |
+
|
| 295 |
+
## TextToVideoZeroPipeline
|
| 296 |
+
[[autodoc]] TextToVideoZeroPipeline
|
| 297 |
+
- all
|
| 298 |
+
- __call__
|
| 299 |
+
|
| 300 |
+
## TextToVideoZeroSDXLPipeline
|
| 301 |
+
[[autodoc]] TextToVideoZeroSDXLPipeline
|
| 302 |
+
- all
|
| 303 |
+
- __call__
|
| 304 |
+
|
| 305 |
+
## TextToVideoPipelineOutput
|
| 306 |
+
[[autodoc]] pipelines.text_to_video_synthesis.pipeline_text_to_video_zero.TextToVideoPipelineOutput
|
tasks/tasksmith-1c5704b1f07f/tests/source/docs/source/en/api/pipelines/unclip.md
ADDED
|
@@ -0,0 +1,37 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
<!--Copyright 2025 The HuggingFace Team. All rights reserved.
|
| 2 |
+
Licensed under the Apache License, Version 2.0 (the "License"); you may not use this file except in compliance with
|
| 3 |
+
the License. You may obtain a copy of the License at
|
| 4 |
+
http://www.apache.org/licenses/LICENSE-2.0
|
| 5 |
+
Unless required by applicable law or agreed to in writing, software distributed under the License is distributed on
|
| 6 |
+
an "AS IS" BASIS, WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied. See the License for the
|
| 7 |
+
specific language governing permissions and limitations under the License.
|
| 8 |
+
-->
|
| 9 |
+
|
| 10 |
+
> [!WARNING]
|
| 11 |
+
> This pipeline is deprecated but it can still be used. However, we won't test the pipeline anymore and won't accept any changes to it. If you run into any issues, reinstall the last Diffusers version that supported this model.
|
| 12 |
+
|
| 13 |
+
# unCLIP
|
| 14 |
+
|
| 15 |
+
[Hierarchical Text-Conditional Image Generation with CLIP Latents](https://huggingface.co/papers/2204.06125) is by Aditya Ramesh, Prafulla Dhariwal, Alex Nichol, Casey Chu, Mark Chen. The unCLIP model in 🤗 Diffusers comes from kakaobrain's [karlo](https://github.com/kakaobrain/karlo).
|
| 16 |
+
|
| 17 |
+
The abstract from the paper is following:
|
| 18 |
+
|
| 19 |
+
*Contrastive models like CLIP have been shown to learn robust representations of images that capture both semantics and style. To leverage these representations for image generation, we propose a two-stage model: a prior that generates a CLIP image embedding given a text caption, and a decoder that generates an image conditioned on the image embedding. We show that explicitly generating image representations improves image diversity with minimal loss in photorealism and caption similarity. Our decoders conditioned on image representations can also produce variations of an image that preserve both its semantics and style, while varying the non-essential details absent from the image representation. Moreover, the joint embedding space of CLIP enables language-guided image manipulations in a zero-shot fashion. We use diffusion models for the decoder and experiment with both autoregressive and diffusion models for the prior, finding that the latter are computationally more efficient and produce higher-quality samples.*
|
| 20 |
+
|
| 21 |
+
You can find lucidrains' DALL-E 2 recreation at [lucidrains/DALLE2-pytorch](https://github.com/lucidrains/DALLE2-pytorch).
|
| 22 |
+
|
| 23 |
+
> [!TIP]
|
| 24 |
+
> Make sure to check out the Schedulers [guide](../../using-diffusers/schedulers) to learn how to explore the tradeoff between scheduler speed and quality, and see the [reuse components across pipelines](../../using-diffusers/loading#reuse-a-pipeline) section to learn how to efficiently load the same components into multiple pipelines.
|
| 25 |
+
|
| 26 |
+
## UnCLIPPipeline
|
| 27 |
+
[[autodoc]] UnCLIPPipeline
|
| 28 |
+
- all
|
| 29 |
+
- __call__
|
| 30 |
+
|
| 31 |
+
## UnCLIPImageVariationPipeline
|
| 32 |
+
[[autodoc]] UnCLIPImageVariationPipeline
|
| 33 |
+
- all
|
| 34 |
+
- __call__
|
| 35 |
+
|
| 36 |
+
## ImagePipelineOutput
|
| 37 |
+
[[autodoc]] pipelines.ImagePipelineOutput
|
tasks/tasksmith-1c5704b1f07f/tests/source/docs/source/en/api/pipelines/unidiffuser.md
ADDED
|
@@ -0,0 +1,206 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
<!--Copyright 2025 The HuggingFace Team. All rights reserved.
|
| 2 |
+
|
| 3 |
+
Licensed under the Apache License, Version 2.0 (the "License"); you may not use this file except in compliance with
|
| 4 |
+
the License. You may obtain a copy of the License at
|
| 5 |
+
|
| 6 |
+
http://www.apache.org/licenses/LICENSE-2.0
|
| 7 |
+
|
| 8 |
+
Unless required by applicable law or agreed to in writing, software distributed under the License is distributed on
|
| 9 |
+
an "AS IS" BASIS, WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied. See the License for the
|
| 10 |
+
specific language governing permissions and limitations under the License.
|
| 11 |
+
-->
|
| 12 |
+
|
| 13 |
+
> [!WARNING]
|
| 14 |
+
> This pipeline is deprecated but it can still be used. However, we won't test the pipeline anymore and won't accept any changes to it. If you run into any issues, reinstall the last Diffusers version that supported this model.
|
| 15 |
+
|
| 16 |
+
# UniDiffuser
|
| 17 |
+
|
| 18 |
+
<div class="flex flex-wrap space-x-1">
|
| 19 |
+
<img alt="LoRA" src="https://img.shields.io/badge/LoRA-d8b4fe?style=flat"/>
|
| 20 |
+
</div>
|
| 21 |
+
|
| 22 |
+
The UniDiffuser model was proposed in [One Transformer Fits All Distributions in Multi-Modal Diffusion at Scale](https://huggingface.co/papers/2303.06555) by Fan Bao, Shen Nie, Kaiwen Xue, Chongxuan Li, Shi Pu, Yaole Wang, Gang Yue, Yue Cao, Hang Su, Jun Zhu.
|
| 23 |
+
|
| 24 |
+
The abstract from the paper is:
|
| 25 |
+
|
| 26 |
+
*This paper proposes a unified diffusion framework (dubbed UniDiffuser) to fit all distributions relevant to a set of multi-modal data in one model. Our key insight is -- learning diffusion models for marginal, conditional, and joint distributions can be unified as predicting the noise in the perturbed data, where the perturbation levels (i.e. timesteps) can be different for different modalities. Inspired by the unified view, UniDiffuser learns all distributions simultaneously with a minimal modification to the original diffusion model -- perturbs data in all modalities instead of a single modality, inputs individual timesteps in different modalities, and predicts the noise of all modalities instead of a single modality. UniDiffuser is parameterized by a transformer for diffusion models to handle input types of different modalities. Implemented on large-scale paired image-text data, UniDiffuser is able to perform image, text, text-to-image, image-to-text, and image-text pair generation by setting proper timesteps without additional overhead. In particular, UniDiffuser is able to produce perceptually realistic samples in all tasks and its quantitative results (e.g., the FID and CLIP score) are not only superior to existing general-purpose models but also comparable to the bespoken models (e.g., Stable Diffusion and DALL-E 2) in representative tasks (e.g., text-to-image generation).*
|
| 27 |
+
|
| 28 |
+
You can find the original codebase at [thu-ml/unidiffuser](https://github.com/thu-ml/unidiffuser) and additional checkpoints at [thu-ml](https://huggingface.co/thu-ml).
|
| 29 |
+
|
| 30 |
+
> [!WARNING]
|
| 31 |
+
> There is currently an issue on PyTorch 1.X where the output images are all black or the pixel values become `NaNs`. This issue can be mitigated by switching to PyTorch 2.X.
|
| 32 |
+
|
| 33 |
+
This pipeline was contributed by [dg845](https://github.com/dg845). ❤️
|
| 34 |
+
|
| 35 |
+
## Usage Examples
|
| 36 |
+
|
| 37 |
+
Because the UniDiffuser model is trained to model the joint distribution of (image, text) pairs, it is capable of performing a diverse range of generation tasks:
|
| 38 |
+
|
| 39 |
+
### Unconditional Image and Text Generation
|
| 40 |
+
|
| 41 |
+
Unconditional generation (where we start from only latents sampled from a standard Gaussian prior) from a [`UniDiffuserPipeline`] will produce a (image, text) pair:
|
| 42 |
+
|
| 43 |
+
```python
|
| 44 |
+
import torch
|
| 45 |
+
|
| 46 |
+
from diffusers import UniDiffuserPipeline
|
| 47 |
+
|
| 48 |
+
device = "cuda"
|
| 49 |
+
model_id_or_path = "thu-ml/unidiffuser-v1"
|
| 50 |
+
pipe = UniDiffuserPipeline.from_pretrained(model_id_or_path, torch_dtype=torch.float16)
|
| 51 |
+
pipe.to(device)
|
| 52 |
+
|
| 53 |
+
# Unconditional image and text generation. The generation task is automatically inferred.
|
| 54 |
+
sample = pipe(num_inference_steps=20, guidance_scale=8.0)
|
| 55 |
+
image = sample.images[0]
|
| 56 |
+
text = sample.text[0]
|
| 57 |
+
image.save("unidiffuser_joint_sample_image.png")
|
| 58 |
+
print(text)
|
| 59 |
+
```
|
| 60 |
+
|
| 61 |
+
This is also called "joint" generation in the UniDiffuser paper, since we are sampling from the joint image-text distribution.
|
| 62 |
+
|
| 63 |
+
Note that the generation task is inferred from the inputs used when calling the pipeline.
|
| 64 |
+
It is also possible to manually specify the unconditional generation task ("mode") manually with [`UniDiffuserPipeline.set_joint_mode`]:
|
| 65 |
+
|
| 66 |
+
```python
|
| 67 |
+
# Equivalent to the above.
|
| 68 |
+
pipe.set_joint_mode()
|
| 69 |
+
sample = pipe(num_inference_steps=20, guidance_scale=8.0)
|
| 70 |
+
```
|
| 71 |
+
|
| 72 |
+
When the mode is set manually, subsequent calls to the pipeline will use the set mode without attempting to infer the mode.
|
| 73 |
+
You can reset the mode with [`UniDiffuserPipeline.reset_mode`], after which the pipeline will once again infer the mode.
|
| 74 |
+
|
| 75 |
+
You can also generate only an image or only text (which the UniDiffuser paper calls "marginal" generation since we sample from the marginal distribution of images and text, respectively):
|
| 76 |
+
|
| 77 |
+
```python
|
| 78 |
+
# Unlike other generation tasks, image-only and text-only generation don't use classifier-free guidance
|
| 79 |
+
# Image-only generation
|
| 80 |
+
pipe.set_image_mode()
|
| 81 |
+
sample_image = pipe(num_inference_steps=20).images[0]
|
| 82 |
+
# Text-only generation
|
| 83 |
+
pipe.set_text_mode()
|
| 84 |
+
sample_text = pipe(num_inference_steps=20).text[0]
|
| 85 |
+
```
|
| 86 |
+
|
| 87 |
+
### Text-to-Image Generation
|
| 88 |
+
|
| 89 |
+
UniDiffuser is also capable of sampling from conditional distributions; that is, the distribution of images conditioned on a text prompt or the distribution of texts conditioned on an image.
|
| 90 |
+
Here is an example of sampling from the conditional image distribution (text-to-image generation or text-conditioned image generation):
|
| 91 |
+
|
| 92 |
+
```python
|
| 93 |
+
import torch
|
| 94 |
+
|
| 95 |
+
from diffusers import UniDiffuserPipeline
|
| 96 |
+
|
| 97 |
+
device = "cuda"
|
| 98 |
+
model_id_or_path = "thu-ml/unidiffuser-v1"
|
| 99 |
+
pipe = UniDiffuserPipeline.from_pretrained(model_id_or_path, torch_dtype=torch.float16)
|
| 100 |
+
pipe.to(device)
|
| 101 |
+
|
| 102 |
+
# Text-to-image generation
|
| 103 |
+
prompt = "an elephant under the sea"
|
| 104 |
+
|
| 105 |
+
sample = pipe(prompt=prompt, num_inference_steps=20, guidance_scale=8.0)
|
| 106 |
+
t2i_image = sample.images[0]
|
| 107 |
+
t2i_image
|
| 108 |
+
```
|
| 109 |
+
|
| 110 |
+
The `text2img` mode requires that either an input `prompt` or `prompt_embeds` be supplied. You can set the `text2img` mode manually with [`UniDiffuserPipeline.set_text_to_image_mode`].
|
| 111 |
+
|
| 112 |
+
### Image-to-Text Generation
|
| 113 |
+
|
| 114 |
+
Similarly, UniDiffuser can also produce text samples given an image (image-to-text or image-conditioned text generation):
|
| 115 |
+
|
| 116 |
+
```python
|
| 117 |
+
import torch
|
| 118 |
+
|
| 119 |
+
from diffusers import UniDiffuserPipeline
|
| 120 |
+
from diffusers.utils import load_image
|
| 121 |
+
|
| 122 |
+
device = "cuda"
|
| 123 |
+
model_id_or_path = "thu-ml/unidiffuser-v1"
|
| 124 |
+
pipe = UniDiffuserPipeline.from_pretrained(model_id_or_path, torch_dtype=torch.float16)
|
| 125 |
+
pipe.to(device)
|
| 126 |
+
|
| 127 |
+
# Image-to-text generation
|
| 128 |
+
image_url = "https://huggingface.co/datasets/hf-internal-testing/diffusers-images/resolve/main/unidiffuser/unidiffuser_example_image.jpg"
|
| 129 |
+
init_image = load_image(image_url).resize((512, 512))
|
| 130 |
+
|
| 131 |
+
sample = pipe(image=init_image, num_inference_steps=20, guidance_scale=8.0)
|
| 132 |
+
i2t_text = sample.text[0]
|
| 133 |
+
print(i2t_text)
|
| 134 |
+
```
|
| 135 |
+
|
| 136 |
+
The `img2text` mode requires that an input `image` be supplied. You can set the `img2text` mode manually with [`UniDiffuserPipeline.set_image_to_text_mode`].
|
| 137 |
+
|
| 138 |
+
### Image Variation
|
| 139 |
+
|
| 140 |
+
The UniDiffuser authors suggest performing image variation through a "round-trip" generation method, where given an input image, we first perform an image-to-text generation, and then perform a text-to-image generation on the outputs of the first generation.
|
| 141 |
+
This produces a new image which is semantically similar to the input image:
|
| 142 |
+
|
| 143 |
+
```python
|
| 144 |
+
import torch
|
| 145 |
+
|
| 146 |
+
from diffusers import UniDiffuserPipeline
|
| 147 |
+
from diffusers.utils import load_image
|
| 148 |
+
|
| 149 |
+
device = "cuda"
|
| 150 |
+
model_id_or_path = "thu-ml/unidiffuser-v1"
|
| 151 |
+
pipe = UniDiffuserPipeline.from_pretrained(model_id_or_path, torch_dtype=torch.float16)
|
| 152 |
+
pipe.to(device)
|
| 153 |
+
|
| 154 |
+
# Image variation can be performed with an image-to-text generation followed by a text-to-image generation:
|
| 155 |
+
# 1. Image-to-text generation
|
| 156 |
+
image_url = "https://huggingface.co/datasets/hf-internal-testing/diffusers-images/resolve/main/unidiffuser/unidiffuser_example_image.jpg"
|
| 157 |
+
init_image = load_image(image_url).resize((512, 512))
|
| 158 |
+
|
| 159 |
+
sample = pipe(image=init_image, num_inference_steps=20, guidance_scale=8.0)
|
| 160 |
+
i2t_text = sample.text[0]
|
| 161 |
+
print(i2t_text)
|
| 162 |
+
|
| 163 |
+
# 2. Text-to-image generation
|
| 164 |
+
sample = pipe(prompt=i2t_text, num_inference_steps=20, guidance_scale=8.0)
|
| 165 |
+
final_image = sample.images[0]
|
| 166 |
+
final_image.save("unidiffuser_image_variation_sample.png")
|
| 167 |
+
```
|
| 168 |
+
|
| 169 |
+
### Text Variation
|
| 170 |
+
|
| 171 |
+
Similarly, text variation can be performed on an input prompt with a text-to-image generation followed by a image-to-text generation:
|
| 172 |
+
|
| 173 |
+
```python
|
| 174 |
+
import torch
|
| 175 |
+
|
| 176 |
+
from diffusers import UniDiffuserPipeline
|
| 177 |
+
|
| 178 |
+
device = "cuda"
|
| 179 |
+
model_id_or_path = "thu-ml/unidiffuser-v1"
|
| 180 |
+
pipe = UniDiffuserPipeline.from_pretrained(model_id_or_path, torch_dtype=torch.float16)
|
| 181 |
+
pipe.to(device)
|
| 182 |
+
|
| 183 |
+
# Text variation can be performed with a text-to-image generation followed by a image-to-text generation:
|
| 184 |
+
# 1. Text-to-image generation
|
| 185 |
+
prompt = "an elephant under the sea"
|
| 186 |
+
|
| 187 |
+
sample = pipe(prompt=prompt, num_inference_steps=20, guidance_scale=8.0)
|
| 188 |
+
t2i_image = sample.images[0]
|
| 189 |
+
t2i_image.save("unidiffuser_text2img_sample_image.png")
|
| 190 |
+
|
| 191 |
+
# 2. Image-to-text generation
|
| 192 |
+
sample = pipe(image=t2i_image, num_inference_steps=20, guidance_scale=8.0)
|
| 193 |
+
final_prompt = sample.text[0]
|
| 194 |
+
print(final_prompt)
|
| 195 |
+
```
|
| 196 |
+
|
| 197 |
+
> [!TIP]
|
| 198 |
+
> Make sure to check out the Schedulers [guide](../../using-diffusers/schedulers) to learn how to explore the tradeoff between scheduler speed and quality, and see the [reuse components across pipelines](../../using-diffusers/loading#reuse-a-pipeline) section to learn how to efficiently load the same components into multiple pipelines.
|
| 199 |
+
|
| 200 |
+
## UniDiffuserPipeline
|
| 201 |
+
[[autodoc]] UniDiffuserPipeline
|
| 202 |
+
- all
|
| 203 |
+
- __call__
|
| 204 |
+
|
| 205 |
+
## ImageTextPipelineOutput
|
| 206 |
+
[[autodoc]] pipelines.ImageTextPipelineOutput
|
tasks/tasksmith-1c5704b1f07f/tests/source/docs/source/en/api/pipelines/value_guided_sampling.md
ADDED
|
@@ -0,0 +1,32 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
<!--Copyright 2025 The HuggingFace Team. All rights reserved.
|
| 2 |
+
|
| 3 |
+
Licensed under the Apache License, Version 2.0 (the "License"); you may not use this file except in compliance with
|
| 4 |
+
the License. You may obtain a copy of the License at
|
| 5 |
+
|
| 6 |
+
http://www.apache.org/licenses/LICENSE-2.0
|
| 7 |
+
|
| 8 |
+
Unless required by applicable law or agreed to in writing, software distributed under the License is distributed on
|
| 9 |
+
an "AS IS" BASIS, WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied. See the License for the
|
| 10 |
+
specific language governing permissions and limitations under the License.
|
| 11 |
+
-->
|
| 12 |
+
|
| 13 |
+
# Value-guided planning
|
| 14 |
+
|
| 15 |
+
> [!WARNING]
|
| 16 |
+
> 🧪 This is an experimental pipeline for reinforcement learning!
|
| 17 |
+
|
| 18 |
+
This pipeline is based on the [Planning with Diffusion for Flexible Behavior Synthesis](https://huggingface.co/papers/2205.09991) paper by Michael Janner, Yilun Du, Joshua B. Tenenbaum, Sergey Levine.
|
| 19 |
+
|
| 20 |
+
The abstract from the paper is:
|
| 21 |
+
|
| 22 |
+
*Model-based reinforcement learning methods often use learning only for the purpose of estimating an approximate dynamics model, offloading the rest of the decision-making work to classical trajectory optimizers. While conceptually simple, this combination has a number of empirical shortcomings, suggesting that learned models may not be well-suited to standard trajectory optimization. In this paper, we consider what it would look like to fold as much of the trajectory optimization pipeline as possible into the modeling problem, such that sampling from the model and planning with it become nearly identical. The core of our technical approach lies in a diffusion probabilistic model that plans by iteratively denoising trajectories. We show how classifier-guided sampling and image inpainting can be reinterpreted as coherent planning strategies, explore the unusual and useful properties of diffusion-based planning methods, and demonstrate the effectiveness of our framework in control settings that emphasize long-horizon decision-making and test-time flexibility.*
|
| 23 |
+
|
| 24 |
+
You can find additional information about the model on the [project page](https://diffusion-planning.github.io/), the [original codebase](https://github.com/jannerm/diffuser), or try it out in a demo [notebook](https://colab.research.google.com/drive/1rXm8CX4ZdN5qivjJ2lhwhkOmt_m0CvU0#scrollTo=6HXJvhyqcITc&uniqifier=1).
|
| 25 |
+
|
| 26 |
+
The script to run the model is available [here](https://github.com/huggingface/diffusers/tree/main/examples/reinforcement_learning).
|
| 27 |
+
|
| 28 |
+
> [!TIP]
|
| 29 |
+
> Make sure to check out the Schedulers [guide](../../using-diffusers/schedulers) to learn how to explore the tradeoff between scheduler speed and quality, and see the [reuse components across pipelines](../../using-diffusers/loading#reuse-a-pipeline) section to learn how to efficiently load the same components into multiple pipelines.
|
| 30 |
+
|
| 31 |
+
## ValueGuidedRLPipeline
|
| 32 |
+
[[autodoc]] diffusers.experimental.ValueGuidedRLPipeline
|
tasks/tasksmith-1c5704b1f07f/tests/source/docs/source/en/api/pipelines/visualcloze.md
ADDED
|
@@ -0,0 +1,300 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
<!--Copyright 2025 The HuggingFace Team. All rights reserved.
|
| 2 |
+
#
|
| 3 |
+
# Licensed under the Apache License, Version 2.0 (the "License");
|
| 4 |
+
# you may not use this file except in compliance with the License.
|
| 5 |
+
# You may obtain a copy of the License at
|
| 6 |
+
#
|
| 7 |
+
# http://www.apache.org/licenses/LICENSE-2.0
|
| 8 |
+
#
|
| 9 |
+
# Unless required by applicable law or agreed to in writing, software
|
| 10 |
+
# distributed under the License is distributed on an "AS IS" BASIS,
|
| 11 |
+
# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
|
| 12 |
+
# See the License for the specific language governing permissions and
|
| 13 |
+
# limitations under the License.
|
| 14 |
+
-->
|
| 15 |
+
|
| 16 |
+
# VisualCloze
|
| 17 |
+
|
| 18 |
+
[VisualCloze: A Universal Image Generation Framework via Visual In-Context Learning](https://huggingface.co/papers/2504.07960) is an innovative in-context learning based universal image generation framework that offers key capabilities:
|
| 19 |
+
1. Support for various in-domain tasks
|
| 20 |
+
2. Generalization to unseen tasks through in-context learning
|
| 21 |
+
3. Unify multiple tasks into one step and generate both target image and intermediate results
|
| 22 |
+
4. Support reverse-engineering conditions from target images
|
| 23 |
+
|
| 24 |
+
## Overview
|
| 25 |
+
|
| 26 |
+
The abstract from the paper is:
|
| 27 |
+
|
| 28 |
+
*Recent progress in diffusion models significantly advances various image generation tasks. However, the current mainstream approach remains focused on building task-specific models, which have limited efficiency when supporting a wide range of different needs. While universal models attempt to address this limitation, they face critical challenges, including generalizable task instruction, appropriate task distributions, and unified architectural design. To tackle these challenges, we propose VisualCloze, a universal image generation framework, which supports a wide range of in-domain tasks, generalization to unseen ones, unseen unification of multiple tasks, and reverse generation. Unlike existing methods that rely on language-based task instruction, leading to task ambiguity and weak generalization, we integrate visual in-context learning, allowing models to identify tasks from visual demonstrations. Meanwhile, the inherent sparsity of visual task distributions hampers the learning of transferable knowledge across tasks. To this end, we introduce Graph200K, a graph-structured dataset that establishes various interrelated tasks, enhancing task density and transferable knowledge. Furthermore, we uncover that our unified image generation formulation shared a consistent objective with image infilling, enabling us to leverage the strong generative priors of pre-trained infilling models without modifying the architectures. The codes, dataset, and models are available at https://visualcloze.github.io.*
|
| 29 |
+
|
| 30 |
+
## Inference
|
| 31 |
+
|
| 32 |
+
### Model loading
|
| 33 |
+
|
| 34 |
+
VisualCloze is a two-stage cascade pipeline, containing `VisualClozeGenerationPipeline` and `VisualClozeUpsamplingPipeline`.
|
| 35 |
+
- In `VisualClozeGenerationPipeline`, each image is downsampled before concatenating images into a grid layout, avoiding excessively high resolutions. VisualCloze releases two models suitable for diffusers, i.e., [VisualClozePipeline-384](https://huggingface.co/VisualCloze/VisualClozePipeline-384) and [VisualClozePipeline-512](https://huggingface.co/VisualCloze/VisualClozePipeline-384), which downsample images to resolutions of 384 and 512, respectively.
|
| 36 |
+
- `VisualClozeUpsamplingPipeline` uses [SDEdit](https://huggingface.co/papers/2108.01073) to enable high-resolution image synthesis.
|
| 37 |
+
|
| 38 |
+
The `VisualClozePipeline` integrates both stages to support convenient end-to-end sampling, while also allowing users to utilize each pipeline independently as needed.
|
| 39 |
+
|
| 40 |
+
### Input Specifications
|
| 41 |
+
|
| 42 |
+
#### Task and Content Prompts
|
| 43 |
+
- Task prompt: Required to describe the generation task intention
|
| 44 |
+
- Content prompt: Optional description or caption of the target image
|
| 45 |
+
- When content prompt is not needed, pass `None`
|
| 46 |
+
- For batch inference, pass `List[str|None]`
|
| 47 |
+
|
| 48 |
+
#### Image Input Format
|
| 49 |
+
- Format: `List[List[Image|None]]`
|
| 50 |
+
- Structure:
|
| 51 |
+
- All rows except the last represent in-context examples
|
| 52 |
+
- Last row represents the current query (target image set to `None`)
|
| 53 |
+
- For batch inference, pass `List[List[List[Image|None]]]`
|
| 54 |
+
|
| 55 |
+
#### Resolution Control
|
| 56 |
+
- Default behavior:
|
| 57 |
+
- Initial generation in the first stage: area of ${pipe.resolution}^2$
|
| 58 |
+
- Upsampling in the second stage: 3x factor
|
| 59 |
+
- Custom resolution: Adjust using `upsampling_height` and `upsampling_width` parameters
|
| 60 |
+
|
| 61 |
+
### Examples
|
| 62 |
+
|
| 63 |
+
For comprehensive examples covering a wide range of tasks, please refer to the [Online Demo](https://huggingface.co/spaces/VisualCloze/VisualCloze) and [GitHub Repository](https://github.com/lzyhha/VisualCloze). Below are simple examples for three cases: mask-to-image conversion, edge detection, and subject-driven generation.
|
| 64 |
+
|
| 65 |
+
#### Example for mask2image
|
| 66 |
+
|
| 67 |
+
```python
|
| 68 |
+
import torch
|
| 69 |
+
from diffusers import VisualClozePipeline
|
| 70 |
+
from diffusers.utils import load_image
|
| 71 |
+
|
| 72 |
+
pipe = VisualClozePipeline.from_pretrained("VisualCloze/VisualClozePipeline-384", resolution=384, torch_dtype=torch.bfloat16)
|
| 73 |
+
pipe.to("cuda")
|
| 74 |
+
|
| 75 |
+
# Load in-context images (make sure the paths are correct and accessible)
|
| 76 |
+
image_paths = [
|
| 77 |
+
# in-context examples
|
| 78 |
+
[
|
| 79 |
+
load_image('https://huggingface.co/datasets/huggingface/documentation-images/resolve/main/diffusers/visualcloze/visualcloze_mask2image_incontext-example-1_mask.jpg'),
|
| 80 |
+
load_image('https://huggingface.co/datasets/huggingface/documentation-images/resolve/main/diffusers/visualcloze/visualcloze_mask2image_incontext-example-1_image.jpg'),
|
| 81 |
+
],
|
| 82 |
+
# query with the target image
|
| 83 |
+
[
|
| 84 |
+
load_image('https://huggingface.co/datasets/huggingface/documentation-images/resolve/main/diffusers/visualcloze/visualcloze_mask2image_query_mask.jpg'),
|
| 85 |
+
None, # No image needed for the target image
|
| 86 |
+
],
|
| 87 |
+
]
|
| 88 |
+
|
| 89 |
+
# Task and content prompt
|
| 90 |
+
task_prompt = "In each row, a logical task is demonstrated to achieve [IMAGE2] an aesthetically pleasing photograph based on [IMAGE1] sam 2-generated masks with rich color coding."
|
| 91 |
+
content_prompt = """Majestic photo of a golden eagle perched on a rocky outcrop in a mountainous landscape.
|
| 92 |
+
The eagle is positioned in the right foreground, facing left, with its sharp beak and keen eyes prominently visible.
|
| 93 |
+
Its plumage is a mix of dark brown and golden hues, with intricate feather details.
|
| 94 |
+
The background features a soft-focus view of snow-capped mountains under a cloudy sky, creating a serene and grandiose atmosphere.
|
| 95 |
+
The foreground includes rugged rocks and patches of green moss. Photorealistic, medium depth of field,
|
| 96 |
+
soft natural lighting, cool color palette, high contrast, sharp focus on the eagle, blurred background,
|
| 97 |
+
tranquil, majestic, wildlife photography."""
|
| 98 |
+
|
| 99 |
+
# Run the pipeline
|
| 100 |
+
image_result = pipe(
|
| 101 |
+
task_prompt=task_prompt,
|
| 102 |
+
content_prompt=content_prompt,
|
| 103 |
+
image=image_paths,
|
| 104 |
+
upsampling_width=1344,
|
| 105 |
+
upsampling_height=768,
|
| 106 |
+
upsampling_strength=0.4,
|
| 107 |
+
guidance_scale=30,
|
| 108 |
+
num_inference_steps=30,
|
| 109 |
+
max_sequence_length=512,
|
| 110 |
+
generator=torch.Generator("cpu").manual_seed(0)
|
| 111 |
+
).images[0][0]
|
| 112 |
+
|
| 113 |
+
# Save the resulting image
|
| 114 |
+
image_result.save("visualcloze.png")
|
| 115 |
+
```
|
| 116 |
+
|
| 117 |
+
#### Example for edge-detection
|
| 118 |
+
|
| 119 |
+
```python
|
| 120 |
+
import torch
|
| 121 |
+
from diffusers import VisualClozePipeline
|
| 122 |
+
from diffusers.utils import load_image
|
| 123 |
+
|
| 124 |
+
pipe = VisualClozePipeline.from_pretrained("VisualCloze/VisualClozePipeline-384", resolution=384, torch_dtype=torch.bfloat16)
|
| 125 |
+
pipe.to("cuda")
|
| 126 |
+
|
| 127 |
+
# Load in-context images (make sure the paths are correct and accessible)
|
| 128 |
+
image_paths = [
|
| 129 |
+
# in-context examples
|
| 130 |
+
[
|
| 131 |
+
load_image('https://huggingface.co/datasets/huggingface/documentation-images/resolve/main/diffusers/visualcloze/visualcloze_edgedetection_incontext-example-1_image.jpg'),
|
| 132 |
+
load_image('https://huggingface.co/datasets/huggingface/documentation-images/resolve/main/diffusers/visualcloze/visualcloze_edgedetection_incontext-example-1_edge.jpg'),
|
| 133 |
+
],
|
| 134 |
+
[
|
| 135 |
+
load_image('https://huggingface.co/datasets/huggingface/documentation-images/resolve/main/diffusers/visualcloze/visualcloze_edgedetection_incontext-example-2_image.jpg'),
|
| 136 |
+
load_image('https://huggingface.co/datasets/huggingface/documentation-images/resolve/main/diffusers/visualcloze/visualcloze_edgedetection_incontext-example-2_edge.jpg'),
|
| 137 |
+
],
|
| 138 |
+
# query with the target image
|
| 139 |
+
[
|
| 140 |
+
load_image('https://huggingface.co/datasets/huggingface/documentation-images/resolve/main/diffusers/visualcloze/visualcloze_edgedetection_query_image.jpg'),
|
| 141 |
+
None, # No image needed for the target image
|
| 142 |
+
],
|
| 143 |
+
]
|
| 144 |
+
|
| 145 |
+
# Task and content prompt
|
| 146 |
+
task_prompt = "Each row illustrates a pathway from [IMAGE1] a sharp and beautifully composed photograph to [IMAGE2] edge map with natural well-connected outlines using a clear logical task."
|
| 147 |
+
content_prompt = ""
|
| 148 |
+
|
| 149 |
+
# Run the pipeline
|
| 150 |
+
image_result = pipe(
|
| 151 |
+
task_prompt=task_prompt,
|
| 152 |
+
content_prompt=content_prompt,
|
| 153 |
+
image=image_paths,
|
| 154 |
+
upsampling_width=864,
|
| 155 |
+
upsampling_height=1152,
|
| 156 |
+
upsampling_strength=0.4,
|
| 157 |
+
guidance_scale=30,
|
| 158 |
+
num_inference_steps=30,
|
| 159 |
+
max_sequence_length=512,
|
| 160 |
+
generator=torch.Generator("cpu").manual_seed(0)
|
| 161 |
+
).images[0][0]
|
| 162 |
+
|
| 163 |
+
# Save the resulting image
|
| 164 |
+
image_result.save("visualcloze.png")
|
| 165 |
+
```
|
| 166 |
+
|
| 167 |
+
#### Example for subject-driven generation
|
| 168 |
+
|
| 169 |
+
```python
|
| 170 |
+
import torch
|
| 171 |
+
from diffusers import VisualClozePipeline
|
| 172 |
+
from diffusers.utils import load_image
|
| 173 |
+
|
| 174 |
+
pipe = VisualClozePipeline.from_pretrained("VisualCloze/VisualClozePipeline-384", resolution=384, torch_dtype=torch.bfloat16)
|
| 175 |
+
pipe.to("cuda")
|
| 176 |
+
|
| 177 |
+
# Load in-context images (make sure the paths are correct and accessible)
|
| 178 |
+
image_paths = [
|
| 179 |
+
# in-context examples
|
| 180 |
+
[
|
| 181 |
+
load_image('https://huggingface.co/datasets/huggingface/documentation-images/resolve/main/diffusers/visualcloze/visualcloze_subjectdriven_incontext-example-1_reference.jpg'),
|
| 182 |
+
load_image('https://huggingface.co/datasets/huggingface/documentation-images/resolve/main/diffusers/visualcloze/visualcloze_subjectdriven_incontext-example-1_depth.jpg'),
|
| 183 |
+
load_image('https://huggingface.co/datasets/huggingface/documentation-images/resolve/main/diffusers/visualcloze/visualcloze_subjectdriven_incontext-example-1_image.jpg'),
|
| 184 |
+
],
|
| 185 |
+
[
|
| 186 |
+
load_image('https://huggingface.co/datasets/huggingface/documentation-images/resolve/main/diffusers/visualcloze/visualcloze_subjectdriven_incontext-example-2_reference.jpg'),
|
| 187 |
+
load_image('https://huggingface.co/datasets/huggingface/documentation-images/resolve/main/diffusers/visualcloze/visualcloze_subjectdriven_incontext-example-2_depth.jpg'),
|
| 188 |
+
load_image('https://huggingface.co/datasets/huggingface/documentation-images/resolve/main/diffusers/visualcloze/visualcloze_subjectdriven_incontext-example-2_image.jpg'),
|
| 189 |
+
],
|
| 190 |
+
# query with the target image
|
| 191 |
+
[
|
| 192 |
+
load_image('https://huggingface.co/datasets/huggingface/documentation-images/resolve/main/diffusers/visualcloze/visualcloze_subjectdriven_query_reference.jpg'),
|
| 193 |
+
load_image('https://huggingface.co/datasets/huggingface/documentation-images/resolve/main/diffusers/visualcloze/visualcloze_subjectdriven_query_depth.jpg'),
|
| 194 |
+
None, # No image needed for the target image
|
| 195 |
+
],
|
| 196 |
+
]
|
| 197 |
+
|
| 198 |
+
# Task and content prompt
|
| 199 |
+
task_prompt = """Each row describes a process that begins with [IMAGE1] an image containing the key object,
|
| 200 |
+
[IMAGE2] depth map revealing gray-toned spatial layers and results in
|
| 201 |
+
[IMAGE3] an image with artistic qualitya high-quality image with exceptional detail."""
|
| 202 |
+
content_prompt = """A vintage porcelain collector's item. Beneath a blossoming cherry tree in early spring,
|
| 203 |
+
this treasure is photographed up close, with soft pink petals drifting through the air and vibrant blossoms framing the scene."""
|
| 204 |
+
|
| 205 |
+
# Run the pipeline
|
| 206 |
+
image_result = pipe(
|
| 207 |
+
task_prompt=task_prompt,
|
| 208 |
+
content_prompt=content_prompt,
|
| 209 |
+
image=image_paths,
|
| 210 |
+
upsampling_width=1024,
|
| 211 |
+
upsampling_height=1024,
|
| 212 |
+
upsampling_strength=0.2,
|
| 213 |
+
guidance_scale=30,
|
| 214 |
+
num_inference_steps=30,
|
| 215 |
+
max_sequence_length=512,
|
| 216 |
+
generator=torch.Generator("cpu").manual_seed(0)
|
| 217 |
+
).images[0][0]
|
| 218 |
+
|
| 219 |
+
# Save the resulting image
|
| 220 |
+
image_result.save("visualcloze.png")
|
| 221 |
+
```
|
| 222 |
+
|
| 223 |
+
#### Utilize each pipeline independently
|
| 224 |
+
|
| 225 |
+
```python
|
| 226 |
+
import torch
|
| 227 |
+
from diffusers import VisualClozeGenerationPipeline, FluxFillPipeline as VisualClozeUpsamplingPipeline
|
| 228 |
+
from diffusers.utils import load_image
|
| 229 |
+
from PIL import Image
|
| 230 |
+
|
| 231 |
+
pipe = VisualClozeGenerationPipeline.from_pretrained(
|
| 232 |
+
"VisualCloze/VisualClozePipeline-384", resolution=384, torch_dtype=torch.bfloat16
|
| 233 |
+
)
|
| 234 |
+
pipe.to("cuda")
|
| 235 |
+
|
| 236 |
+
image_paths = [
|
| 237 |
+
# in-context examples
|
| 238 |
+
[
|
| 239 |
+
load_image(
|
| 240 |
+
"https://huggingface.co/datasets/huggingface/documentation-images/resolve/main/diffusers/visualcloze/visualcloze_mask2image_incontext-example-1_mask.jpg"
|
| 241 |
+
),
|
| 242 |
+
load_image(
|
| 243 |
+
"https://huggingface.co/datasets/huggingface/documentation-images/resolve/main/diffusers/visualcloze/visualcloze_mask2image_incontext-example-1_image.jpg"
|
| 244 |
+
),
|
| 245 |
+
],
|
| 246 |
+
# query with the target image
|
| 247 |
+
[
|
| 248 |
+
load_image(
|
| 249 |
+
"https://huggingface.co/datasets/huggingface/documentation-images/resolve/main/diffusers/visualcloze/visualcloze_mask2image_query_mask.jpg"
|
| 250 |
+
),
|
| 251 |
+
None, # No image needed for the target image
|
| 252 |
+
],
|
| 253 |
+
]
|
| 254 |
+
task_prompt = "In each row, a logical task is demonstrated to achieve [IMAGE2] an aesthetically pleasing photograph based on [IMAGE1] sam 2-generated masks with rich color coding."
|
| 255 |
+
content_prompt = "Majestic photo of a golden eagle perched on a rocky outcrop in a mountainous landscape. The eagle is positioned in the right foreground, facing left, with its sharp beak and keen eyes prominently visible. Its plumage is a mix of dark brown and golden hues, with intricate feather details. The background features a soft-focus view of snow-capped mountains under a cloudy sky, creating a serene and grandiose atmosphere. The foreground includes rugged rocks and patches of green moss. Photorealistic, medium depth of field, soft natural lighting, cool color palette, high contrast, sharp focus on the eagle, blurred background, tranquil, majestic, wildlife photography."
|
| 256 |
+
|
| 257 |
+
# Stage 1: Generate initial image
|
| 258 |
+
image = pipe(
|
| 259 |
+
task_prompt=task_prompt,
|
| 260 |
+
content_prompt=content_prompt,
|
| 261 |
+
image=image_paths,
|
| 262 |
+
guidance_scale=30,
|
| 263 |
+
num_inference_steps=30,
|
| 264 |
+
max_sequence_length=512,
|
| 265 |
+
generator=torch.Generator("cpu").manual_seed(0),
|
| 266 |
+
).images[0][0]
|
| 267 |
+
|
| 268 |
+
# Stage 2 (optional): Upsample the generated image
|
| 269 |
+
pipe_upsample = VisualClozeUpsamplingPipeline.from_pipe(pipe)
|
| 270 |
+
pipe_upsample.to("cuda")
|
| 271 |
+
|
| 272 |
+
mask_image = Image.new("RGB", image.size, (255, 255, 255))
|
| 273 |
+
|
| 274 |
+
image = pipe_upsample(
|
| 275 |
+
image=image,
|
| 276 |
+
mask_image=mask_image,
|
| 277 |
+
prompt=content_prompt,
|
| 278 |
+
width=1344,
|
| 279 |
+
height=768,
|
| 280 |
+
strength=0.4,
|
| 281 |
+
guidance_scale=30,
|
| 282 |
+
num_inference_steps=30,
|
| 283 |
+
max_sequence_length=512,
|
| 284 |
+
generator=torch.Generator("cpu").manual_seed(0),
|
| 285 |
+
).images[0]
|
| 286 |
+
|
| 287 |
+
image.save("visualcloze.png")
|
| 288 |
+
```
|
| 289 |
+
|
| 290 |
+
## VisualClozePipeline
|
| 291 |
+
|
| 292 |
+
[[autodoc]] VisualClozePipeline
|
| 293 |
+
- all
|
| 294 |
+
- __call__
|
| 295 |
+
|
| 296 |
+
## VisualClozeGenerationPipeline
|
| 297 |
+
|
| 298 |
+
[[autodoc]] VisualClozeGenerationPipeline
|
| 299 |
+
- all
|
| 300 |
+
- __call__
|
tasks/tasksmith-1c5704b1f07f/tests/source/docs/source/en/api/pipelines/wan.md
ADDED
|
@@ -0,0 +1,573 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
<!-- Copyright 2025 The HuggingFace Team. All rights reserved.
|
| 2 |
+
#
|
| 3 |
+
# Licensed under the Apache License, Version 2.0 (the "License");
|
| 4 |
+
# you may not use this file except in compliance with the License.
|
| 5 |
+
# You may obtain a copy of the License at
|
| 6 |
+
#
|
| 7 |
+
# http://www.apache.org/licenses/LICENSE-2.0
|
| 8 |
+
#
|
| 9 |
+
# Unless required by applicable law or agreed to in writing, software
|
| 10 |
+
# distributed under the License is distributed on an "AS IS" BASIS,
|
| 11 |
+
# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
|
| 12 |
+
# See the License for the specific language governing permissions and
|
| 13 |
+
# limitations under the License. -->
|
| 14 |
+
|
| 15 |
+
<div style="float: right;">
|
| 16 |
+
<div class="flex flex-wrap space-x-1">
|
| 17 |
+
<a href="https://huggingface.co/docs/diffusers/main/en/tutorials/using_peft_for_inference" target="_blank" rel="noopener">
|
| 18 |
+
<img alt="LoRA" src="https://img.shields.io/badge/LoRA-d8b4fe?style=flat"/>
|
| 19 |
+
</a>
|
| 20 |
+
</div>
|
| 21 |
+
</div>
|
| 22 |
+
|
| 23 |
+
# Wan
|
| 24 |
+
|
| 25 |
+
[Wan-2.1](https://huggingface.co/papers/2503.20314) by the Wan Team.
|
| 26 |
+
|
| 27 |
+
*This report presents Wan, a comprehensive and open suite of video foundation models designed to push the boundaries of video generation. Built upon the mainstream diffusion transformer paradigm, Wan achieves significant advancements in generative capabilities through a series of innovations, including our novel VAE, scalable pre-training strategies, large-scale data curation, and automated evaluation metrics. These contributions collectively enhance the model's performance and versatility. Specifically, Wan is characterized by four key features: Leading Performance: The 14B model of Wan, trained on a vast dataset comprising billions of images and videos, demonstrates the scaling laws of video generation with respect to both data and model size. It consistently outperforms the existing open-source models as well as state-of-the-art commercial solutions across multiple internal and external benchmarks, demonstrating a clear and significant performance superiority. Comprehensiveness: Wan offers two capable models, i.e., 1.3B and 14B parameters, for efficiency and effectiveness respectively. It also covers multiple downstream applications, including image-to-video, instruction-guided video editing, and personal video generation, encompassing up to eight tasks. Consumer-Grade Efficiency: The 1.3B model demonstrates exceptional resource efficiency, requiring only 8.19 GB VRAM, making it compatible with a wide range of consumer-grade GPUs. Openness: We open-source the entire series of Wan, including source code and all models, with the goal of fostering the growth of the video generation community. This openness seeks to significantly expand the creative possibilities of video production in the industry and provide academia with high-quality video foundation models. All the code and models are available at [this https URL](https://github.com/Wan-Video/Wan2.1).*
|
| 28 |
+
|
| 29 |
+
You can find all the original Wan2.1 checkpoints under the [Wan-AI](https://huggingface.co/Wan-AI) organization.
|
| 30 |
+
|
| 31 |
+
The following Wan models are supported in Diffusers:
|
| 32 |
+
|
| 33 |
+
- [Wan 2.1 T2V 1.3B](https://huggingface.co/Wan-AI/Wan2.1-T2V-1.3B-Diffusers)
|
| 34 |
+
- [Wan 2.1 T2V 14B](https://huggingface.co/Wan-AI/Wan2.1-T2V-14B-Diffusers)
|
| 35 |
+
- [Wan 2.1 I2V 14B - 480P](https://huggingface.co/Wan-AI/Wan2.1-I2V-14B-480P-Diffusers)
|
| 36 |
+
- [Wan 2.1 I2V 14B - 720P](https://huggingface.co/Wan-AI/Wan2.1-I2V-14B-720P-Diffusers)
|
| 37 |
+
- [Wan 2.1 FLF2V 14B - 720P](https://huggingface.co/Wan-AI/Wan2.1-FLF2V-14B-720P-diffusers)
|
| 38 |
+
- [Wan 2.1 VACE 1.3B](https://huggingface.co/Wan-AI/Wan2.1-VACE-1.3B-diffusers)
|
| 39 |
+
- [Wan 2.1 VACE 14B](https://huggingface.co/Wan-AI/Wan2.1-VACE-14B-diffusers)
|
| 40 |
+
- [Wan 2.2 T2V 14B](https://huggingface.co/Wan-AI/Wan2.2-T2V-A14B-Diffusers)
|
| 41 |
+
- [Wan 2.2 I2V 14B](https://huggingface.co/Wan-AI/Wan2.2-I2V-A14B-Diffusers)
|
| 42 |
+
- [Wan 2.2 TI2V 5B](https://huggingface.co/Wan-AI/Wan2.2-TI2V-5B-Diffusers)
|
| 43 |
+
- [Wan 2.2 Animate 14B](https://huggingface.co/Wan-AI/Wan2.2-Animate-14B-Diffusers)
|
| 44 |
+
|
| 45 |
+
> [!TIP]
|
| 46 |
+
> Click on the Wan models in the right sidebar for more examples of video generation.
|
| 47 |
+
|
| 48 |
+
### Text-to-Video Generation
|
| 49 |
+
|
| 50 |
+
The example below demonstrates how to generate a video from text optimized for memory or inference speed.
|
| 51 |
+
|
| 52 |
+
<hfoptions id="T2V usage">
|
| 53 |
+
<hfoption id="T2V memory">
|
| 54 |
+
|
| 55 |
+
Refer to the [Reduce memory usage](../../optimization/memory) guide for more details about the various memory saving techniques.
|
| 56 |
+
|
| 57 |
+
The Wan2.1 text-to-video model below requires ~13GB of VRAM.
|
| 58 |
+
|
| 59 |
+
```py
|
| 60 |
+
# pip install ftfy
|
| 61 |
+
import torch
|
| 62 |
+
import numpy as np
|
| 63 |
+
from diffusers import AutoModel, WanPipeline
|
| 64 |
+
from diffusers.quantizers import PipelineQuantizationConfig
|
| 65 |
+
from diffusers.hooks.group_offloading import apply_group_offloading
|
| 66 |
+
from diffusers.utils import export_to_video, load_image
|
| 67 |
+
from transformers import UMT5EncoderModel
|
| 68 |
+
|
| 69 |
+
text_encoder = UMT5EncoderModel.from_pretrained("Wan-AI/Wan2.1-T2V-14B-Diffusers", subfolder="text_encoder", torch_dtype=torch.bfloat16)
|
| 70 |
+
vae = AutoModel.from_pretrained("Wan-AI/Wan2.1-T2V-14B-Diffusers", subfolder="vae", torch_dtype=torch.float32)
|
| 71 |
+
transformer = AutoModel.from_pretrained("Wan-AI/Wan2.1-T2V-14B-Diffusers", subfolder="transformer", torch_dtype=torch.bfloat16)
|
| 72 |
+
|
| 73 |
+
# group-offloading
|
| 74 |
+
onload_device = torch.device("cuda")
|
| 75 |
+
offload_device = torch.device("cpu")
|
| 76 |
+
apply_group_offloading(text_encoder,
|
| 77 |
+
onload_device=onload_device,
|
| 78 |
+
offload_device=offload_device,
|
| 79 |
+
offload_type="block_level",
|
| 80 |
+
num_blocks_per_group=4
|
| 81 |
+
)
|
| 82 |
+
transformer.enable_group_offload(
|
| 83 |
+
onload_device=onload_device,
|
| 84 |
+
offload_device=offload_device,
|
| 85 |
+
offload_type="leaf_level",
|
| 86 |
+
use_stream=True
|
| 87 |
+
)
|
| 88 |
+
|
| 89 |
+
pipeline = WanPipeline.from_pretrained(
|
| 90 |
+
"Wan-AI/Wan2.1-T2V-14B-Diffusers",
|
| 91 |
+
vae=vae,
|
| 92 |
+
transformer=transformer,
|
| 93 |
+
text_encoder=text_encoder,
|
| 94 |
+
torch_dtype=torch.bfloat16
|
| 95 |
+
)
|
| 96 |
+
pipeline.to("cuda")
|
| 97 |
+
|
| 98 |
+
prompt = """
|
| 99 |
+
The camera rushes from far to near in a low-angle shot,
|
| 100 |
+
revealing a white ferret on a log. It plays, leaps into the water, and emerges, as the camera zooms in
|
| 101 |
+
for a close-up. Water splashes berry bushes nearby, while moss, snow, and leaves blanket the ground.
|
| 102 |
+
Birch trees and a light blue sky frame the scene, with ferns in the foreground. Side lighting casts dynamic
|
| 103 |
+
shadows and warm highlights. Medium composition, front view, low angle, with depth of field.
|
| 104 |
+
"""
|
| 105 |
+
negative_prompt = """
|
| 106 |
+
Bright tones, overexposed, static, blurred details, subtitles, style, works, paintings, images, static, overall gray, worst quality,
|
| 107 |
+
low quality, JPEG compression residue, ugly, incomplete, extra fingers, poorly drawn hands, poorly drawn faces, deformed, disfigured,
|
| 108 |
+
misshapen limbs, fused fingers, still picture, messy background, three legs, many people in the background, walking backwards
|
| 109 |
+
"""
|
| 110 |
+
|
| 111 |
+
output = pipeline(
|
| 112 |
+
prompt=prompt,
|
| 113 |
+
negative_prompt=negative_prompt,
|
| 114 |
+
num_frames=81,
|
| 115 |
+
guidance_scale=5.0,
|
| 116 |
+
).frames[0]
|
| 117 |
+
export_to_video(output, "output.mp4", fps=16)
|
| 118 |
+
```
|
| 119 |
+
|
| 120 |
+
</hfoption>
|
| 121 |
+
<hfoption id="T2V inference speed">
|
| 122 |
+
|
| 123 |
+
[Compilation](../../optimization/fp16#torchcompile) is slow the first time but subsequent calls to the pipeline are faster. [Caching](../../optimization/cache) may also speed up inference by storing and reusing intermediate outputs.
|
| 124 |
+
|
| 125 |
+
```py
|
| 126 |
+
# pip install ftfy
|
| 127 |
+
import torch
|
| 128 |
+
import numpy as np
|
| 129 |
+
from diffusers import AutoModel, WanPipeline
|
| 130 |
+
from diffusers.hooks.group_offloading import apply_group_offloading
|
| 131 |
+
from diffusers.utils import export_to_video, load_image
|
| 132 |
+
from transformers import UMT5EncoderModel
|
| 133 |
+
|
| 134 |
+
text_encoder = UMT5EncoderModel.from_pretrained("Wan-AI/Wan2.1-T2V-14B-Diffusers", subfolder="text_encoder", torch_dtype=torch.bfloat16)
|
| 135 |
+
vae = AutoModel.from_pretrained("Wan-AI/Wan2.1-T2V-14B-Diffusers", subfolder="vae", torch_dtype=torch.float32)
|
| 136 |
+
transformer = AutoModel.from_pretrained("Wan-AI/Wan2.1-T2V-14B-Diffusers", subfolder="transformer", torch_dtype=torch.bfloat16)
|
| 137 |
+
|
| 138 |
+
pipeline = WanPipeline.from_pretrained(
|
| 139 |
+
"Wan-AI/Wan2.1-T2V-14B-Diffusers",
|
| 140 |
+
vae=vae,
|
| 141 |
+
transformer=transformer,
|
| 142 |
+
text_encoder=text_encoder,
|
| 143 |
+
torch_dtype=torch.bfloat16
|
| 144 |
+
)
|
| 145 |
+
pipeline.to("cuda")
|
| 146 |
+
|
| 147 |
+
# torch.compile
|
| 148 |
+
pipeline.transformer.to(memory_format=torch.channels_last)
|
| 149 |
+
pipeline.transformer = torch.compile(
|
| 150 |
+
pipeline.transformer, mode="max-autotune", fullgraph=True
|
| 151 |
+
)
|
| 152 |
+
|
| 153 |
+
prompt = """
|
| 154 |
+
The camera rushes from far to near in a low-angle shot,
|
| 155 |
+
revealing a white ferret on a log. It plays, leaps into the water, and emerges, as the camera zooms in
|
| 156 |
+
for a close-up. Water splashes berry bushes nearby, while moss, snow, and leaves blanket the ground.
|
| 157 |
+
Birch trees and a light blue sky frame the scene, with ferns in the foreground. Side lighting casts dynamic
|
| 158 |
+
shadows and warm highlights. Medium composition, front view, low angle, with depth of field.
|
| 159 |
+
"""
|
| 160 |
+
negative_prompt = """
|
| 161 |
+
Bright tones, overexposed, static, blurred details, subtitles, style, works, paintings, images, static, overall gray, worst quality,
|
| 162 |
+
low quality, JPEG compression residue, ugly, incomplete, extra fingers, poorly drawn hands, poorly drawn faces, deformed, disfigured,
|
| 163 |
+
misshapen limbs, fused fingers, still picture, messy background, three legs, many people in the background, walking backwards
|
| 164 |
+
"""
|
| 165 |
+
|
| 166 |
+
output = pipeline(
|
| 167 |
+
prompt=prompt,
|
| 168 |
+
negative_prompt=negative_prompt,
|
| 169 |
+
num_frames=81,
|
| 170 |
+
guidance_scale=5.0,
|
| 171 |
+
).frames[0]
|
| 172 |
+
export_to_video(output, "output.mp4", fps=16)
|
| 173 |
+
```
|
| 174 |
+
|
| 175 |
+
</hfoption>
|
| 176 |
+
</hfoptions>
|
| 177 |
+
|
| 178 |
+
### First-Last-Frame-to-Video Generation
|
| 179 |
+
|
| 180 |
+
The example below demonstrates how to use the image-to-video pipeline to generate a video using a text description, a starting frame, and an ending frame.
|
| 181 |
+
|
| 182 |
+
<hfoptions id="FLF2V usage">
|
| 183 |
+
<hfoption id="usage">
|
| 184 |
+
|
| 185 |
+
```python
|
| 186 |
+
import numpy as np
|
| 187 |
+
import torch
|
| 188 |
+
import torchvision.transforms.functional as TF
|
| 189 |
+
from diffusers import AutoencoderKLWan, WanImageToVideoPipeline
|
| 190 |
+
from diffusers.utils import export_to_video, load_image
|
| 191 |
+
from transformers import CLIPVisionModel
|
| 192 |
+
|
| 193 |
+
|
| 194 |
+
model_id = "Wan-AI/Wan2.1-FLF2V-14B-720P-diffusers"
|
| 195 |
+
image_encoder = CLIPVisionModel.from_pretrained(model_id, subfolder="image_encoder", torch_dtype=torch.float32)
|
| 196 |
+
vae = AutoencoderKLWan.from_pretrained(model_id, subfolder="vae", torch_dtype=torch.float32)
|
| 197 |
+
pipe = WanImageToVideoPipeline.from_pretrained(
|
| 198 |
+
model_id, vae=vae, image_encoder=image_encoder, torch_dtype=torch.bfloat16
|
| 199 |
+
)
|
| 200 |
+
pipe.to("cuda")
|
| 201 |
+
|
| 202 |
+
first_frame = load_image("https://huggingface.co/datasets/huggingface/documentation-images/resolve/main/diffusers/flf2v_input_first_frame.png")
|
| 203 |
+
last_frame = load_image("https://huggingface.co/datasets/huggingface/documentation-images/resolve/main/diffusers/flf2v_input_last_frame.png")
|
| 204 |
+
|
| 205 |
+
def aspect_ratio_resize(image, pipe, max_area=720 * 1280):
|
| 206 |
+
aspect_ratio = image.height / image.width
|
| 207 |
+
mod_value = pipe.vae_scale_factor_spatial * pipe.transformer.config.patch_size[1]
|
| 208 |
+
height = round(np.sqrt(max_area * aspect_ratio)) // mod_value * mod_value
|
| 209 |
+
width = round(np.sqrt(max_area / aspect_ratio)) // mod_value * mod_value
|
| 210 |
+
image = image.resize((width, height))
|
| 211 |
+
return image, height, width
|
| 212 |
+
|
| 213 |
+
def center_crop_resize(image, height, width):
|
| 214 |
+
# Calculate resize ratio to match first frame dimensions
|
| 215 |
+
resize_ratio = max(width / image.width, height / image.height)
|
| 216 |
+
|
| 217 |
+
# Resize the image
|
| 218 |
+
width = round(image.width * resize_ratio)
|
| 219 |
+
height = round(image.height * resize_ratio)
|
| 220 |
+
size = [width, height]
|
| 221 |
+
image = TF.center_crop(image, size)
|
| 222 |
+
|
| 223 |
+
return image, height, width
|
| 224 |
+
|
| 225 |
+
first_frame, height, width = aspect_ratio_resize(first_frame, pipe)
|
| 226 |
+
if last_frame.size != first_frame.size:
|
| 227 |
+
last_frame, _, _ = center_crop_resize(last_frame, height, width)
|
| 228 |
+
|
| 229 |
+
prompt = "CG animation style, a small blue bird takes off from the ground, flapping its wings. The bird's feathers are delicate, with a unique pattern on its chest. The background shows a blue sky with white clouds under bright sunshine. The camera follows the bird upward, capturing its flight and the vastness of the sky from a close-up, low-angle perspective."
|
| 230 |
+
|
| 231 |
+
output = pipe(
|
| 232 |
+
image=first_frame, last_image=last_frame, prompt=prompt, height=height, width=width, guidance_scale=5.5
|
| 233 |
+
).frames[0]
|
| 234 |
+
export_to_video(output, "output.mp4", fps=16)
|
| 235 |
+
```
|
| 236 |
+
|
| 237 |
+
</hfoption>
|
| 238 |
+
</hfoptions>
|
| 239 |
+
|
| 240 |
+
### Any-to-Video Controllable Generation
|
| 241 |
+
|
| 242 |
+
Wan VACE supports various generation techniques which achieve controllable video generation. Some of the capabilities include:
|
| 243 |
+
- Control to Video (Depth, Pose, Sketch, Flow, Grayscale, Scribble, Layout, Boundary Box, etc.). Recommended library for preprocessing videos to obtain control videos: [huggingface/controlnet_aux]()
|
| 244 |
+
- Image/Video to Video (first frame, last frame, starting clip, ending clip, random clips)
|
| 245 |
+
- Inpainting and Outpainting
|
| 246 |
+
- Subject to Video (faces, object, characters, etc.)
|
| 247 |
+
- Composition to Video (reference anything, animate anything, swap anything, expand anything, move anything, etc.)
|
| 248 |
+
|
| 249 |
+
The code snippets available in [this](https://github.com/huggingface/diffusers/pull/11582) pull request demonstrate some examples of how videos can be generated with controllability signals.
|
| 250 |
+
|
| 251 |
+
The general rule of thumb to keep in mind when preparing inputs for the VACE pipeline is that the input images, or frames of a video that you want to use for conditioning, should have a corresponding mask that is black in color. The black mask signifies that the model will not generate new content for that area, and only use those parts for conditioning the generation process. For parts/frames that should be generated by the model, the mask should be white in color.
|
| 252 |
+
|
| 253 |
+
</hfoption>
|
| 254 |
+
</hfoptions>
|
| 255 |
+
|
| 256 |
+
### Wan-Animate: Unified Character Animation and Replacement with Holistic Replication
|
| 257 |
+
|
| 258 |
+
[Wan-Animate](https://huggingface.co/papers/2509.14055) by the Wan Team.
|
| 259 |
+
|
| 260 |
+
*We introduce Wan-Animate, a unified framework for character animation and replacement. Given a character image and a reference video, Wan-Animate can animate the character by precisely replicating the expressions and movements of the character in the video to generate high-fidelity character videos. Alternatively, it can integrate the animated character into the reference video to replace the original character, replicating the scene's lighting and color tone to achieve seamless environmental integration. Wan-Animate is built upon the Wan model. To adapt it for character animation tasks, we employ a modified input paradigm to differentiate between reference conditions and regions for generation. This design unifies multiple tasks into a common symbolic representation. We use spatially-aligned skeleton signals to replicate body motion and implicit facial features extracted from source images to reenact expressions, enabling the generation of character videos with high controllability and expressiveness. Furthermore, to enhance environmental integration during character replacement, we develop an auxiliary Relighting LoRA. This module preserves the character's appearance consistency while applying the appropriate environmental lighting and color tone. Experimental results demonstrate that Wan-Animate achieves state-of-the-art performance. We are committed to open-sourcing the model weights and its source code.*
|
| 261 |
+
|
| 262 |
+
The project page: https://humanaigc.github.io/wan-animate
|
| 263 |
+
|
| 264 |
+
This model was mostly contributed by [M. Tolga Cangöz](https://github.com/tolgacangoz).
|
| 265 |
+
|
| 266 |
+
#### Usage
|
| 267 |
+
|
| 268 |
+
The Wan-Animate pipeline supports two modes of operation:
|
| 269 |
+
|
| 270 |
+
1. **Animation Mode** (default): Animates a character image based on motion and expression from reference videos
|
| 271 |
+
2. **Replacement Mode**: Replaces a character in a background video with a new character while preserving the scene
|
| 272 |
+
|
| 273 |
+
##### Prerequisites
|
| 274 |
+
|
| 275 |
+
Before using the pipeline, you need to preprocess your reference video to extract:
|
| 276 |
+
- **Pose video**: Contains skeletal keypoints representing body motion
|
| 277 |
+
- **Face video**: Contains facial feature representations for expression control
|
| 278 |
+
|
| 279 |
+
For replacement mode, you additionally need:
|
| 280 |
+
- **Background video**: The original video containing the scene
|
| 281 |
+
- **Mask video**: A mask indicating where to generate content (white) vs. preserve original (black)
|
| 282 |
+
|
| 283 |
+
> [!NOTE]
|
| 284 |
+
> Raw videos should not be used for inputs such as `pose_video`, which the pipeline expects to be preprocessed to extract the proper information. Preprocessing scripts to prepare these inputs are available in the [original Wan-Animate repository](https://github.com/Wan-Video/Wan2.2?tab=readme-ov-file#1-preprocessing). Integration of these preprocessing steps into Diffusers is planned for a future release.
|
| 285 |
+
|
| 286 |
+
The example below demonstrates how to use the Wan-Animate pipeline:
|
| 287 |
+
|
| 288 |
+
<hfoptions id="Animate usage">
|
| 289 |
+
<hfoption id="Animation mode">
|
| 290 |
+
|
| 291 |
+
```python
|
| 292 |
+
import numpy as np
|
| 293 |
+
import torch
|
| 294 |
+
from diffusers import AutoencoderKLWan, WanAnimatePipeline
|
| 295 |
+
from diffusers.utils import export_to_video, load_image, load_video
|
| 296 |
+
|
| 297 |
+
model_id = "Wan-AI/Wan2.2-Animate-14B-Diffusers"
|
| 298 |
+
vae = AutoencoderKLWan.from_pretrained(model_id, subfolder="vae", torch_dtype=torch.float32)
|
| 299 |
+
pipe = WanAnimatePipeline.from_pretrained(model_id, vae=vae, torch_dtype=torch.bfloat16)
|
| 300 |
+
pipe.to("cuda")
|
| 301 |
+
|
| 302 |
+
# Load character image and preprocessed videos
|
| 303 |
+
image = load_image("path/to/character.jpg")
|
| 304 |
+
pose_video = load_video("path/to/pose_video.mp4") # Preprocessed skeletal keypoints
|
| 305 |
+
face_video = load_video("path/to/face_video.mp4") # Preprocessed facial features
|
| 306 |
+
|
| 307 |
+
# Resize image to match VAE constraints
|
| 308 |
+
def aspect_ratio_resize(image, pipe, max_area=720 * 1280):
|
| 309 |
+
aspect_ratio = image.height / image.width
|
| 310 |
+
mod_value = pipe.vae_scale_factor_spatial * pipe.transformer.config.patch_size[1]
|
| 311 |
+
height = round(np.sqrt(max_area * aspect_ratio)) // mod_value * mod_value
|
| 312 |
+
width = round(np.sqrt(max_area / aspect_ratio)) // mod_value * mod_value
|
| 313 |
+
image = image.resize((width, height))
|
| 314 |
+
return image, height, width
|
| 315 |
+
|
| 316 |
+
image, height, width = aspect_ratio_resize(image, pipe)
|
| 317 |
+
|
| 318 |
+
prompt = "A person dancing energetically in a studio with dynamic lighting and professional camera work"
|
| 319 |
+
negative_prompt = "blurry, low quality, distorted, deformed, static, poorly drawn"
|
| 320 |
+
|
| 321 |
+
# Generate animated video
|
| 322 |
+
output = pipe(
|
| 323 |
+
image=image,
|
| 324 |
+
pose_video=pose_video,
|
| 325 |
+
face_video=face_video,
|
| 326 |
+
prompt=prompt,
|
| 327 |
+
negative_prompt=negative_prompt,
|
| 328 |
+
height=height,
|
| 329 |
+
width=width,
|
| 330 |
+
segment_frame_length=77,
|
| 331 |
+
guidance_scale=1.0,
|
| 332 |
+
mode="animate", # Animation mode (default)
|
| 333 |
+
).frames[0]
|
| 334 |
+
export_to_video(output, "animated_character.mp4", fps=30)
|
| 335 |
+
```
|
| 336 |
+
|
| 337 |
+
</hfoption>
|
| 338 |
+
<hfoption id="Replacement mode">
|
| 339 |
+
|
| 340 |
+
```python
|
| 341 |
+
import numpy as np
|
| 342 |
+
import torch
|
| 343 |
+
from diffusers import AutoencoderKLWan, WanAnimatePipeline
|
| 344 |
+
from diffusers.utils import export_to_video, load_image, load_video
|
| 345 |
+
|
| 346 |
+
model_id = "Wan-AI/Wan2.2-Animate-14B-Diffusers"
|
| 347 |
+
vae = AutoencoderKLWan.from_pretrained(model_id, subfolder="vae", torch_dtype=torch.float32)
|
| 348 |
+
pipe = WanAnimatePipeline.from_pretrained(model_id, vae=vae, torch_dtype=torch.bfloat16)
|
| 349 |
+
pipe.to("cuda")
|
| 350 |
+
|
| 351 |
+
# Load all required inputs for replacement mode
|
| 352 |
+
image = load_image("path/to/new_character.jpg")
|
| 353 |
+
pose_video = load_video("path/to/pose_video.mp4") # Preprocessed skeletal keypoints
|
| 354 |
+
face_video = load_video("path/to/face_video.mp4") # Preprocessed facial features
|
| 355 |
+
background_video = load_video("path/to/background_video.mp4") # Original scene
|
| 356 |
+
mask_video = load_video("path/to/mask_video.mp4") # Black: preserve, White: generate
|
| 357 |
+
|
| 358 |
+
# Resize image to match video dimensions
|
| 359 |
+
def aspect_ratio_resize(image, pipe, max_area=720 * 1280):
|
| 360 |
+
aspect_ratio = image.height / image.width
|
| 361 |
+
mod_value = pipe.vae_scale_factor_spatial * pipe.transformer.config.patch_size[1]
|
| 362 |
+
height = round(np.sqrt(max_area * aspect_ratio)) // mod_value * mod_value
|
| 363 |
+
width = round(np.sqrt(max_area / aspect_ratio)) // mod_value * mod_value
|
| 364 |
+
image = image.resize((width, height))
|
| 365 |
+
return image, height, width
|
| 366 |
+
|
| 367 |
+
image, height, width = aspect_ratio_resize(image, pipe)
|
| 368 |
+
|
| 369 |
+
prompt = "A person seamlessly integrated into the scene with consistent lighting and environment"
|
| 370 |
+
negative_prompt = "blurry, low quality, inconsistent lighting, floating, disconnected from scene"
|
| 371 |
+
|
| 372 |
+
# Replace character in background video
|
| 373 |
+
output = pipe(
|
| 374 |
+
image=image,
|
| 375 |
+
pose_video=pose_video,
|
| 376 |
+
face_video=face_video,
|
| 377 |
+
background_video=background_video,
|
| 378 |
+
mask_video=mask_video,
|
| 379 |
+
prompt=prompt,
|
| 380 |
+
negative_prompt=negative_prompt,
|
| 381 |
+
height=height,
|
| 382 |
+
width=width,
|
| 383 |
+
segment_frame_lengths=77,
|
| 384 |
+
guidance_scale=1.0,
|
| 385 |
+
mode="replace", # Replacement mode
|
| 386 |
+
).frames[0]
|
| 387 |
+
export_to_video(output, "character_replaced.mp4", fps=30)
|
| 388 |
+
```
|
| 389 |
+
|
| 390 |
+
</hfoption>
|
| 391 |
+
<hfoption id="Advanced options">
|
| 392 |
+
|
| 393 |
+
```python
|
| 394 |
+
import numpy as np
|
| 395 |
+
import torch
|
| 396 |
+
from diffusers import AutoencoderKLWan, WanAnimatePipeline
|
| 397 |
+
from diffusers.utils import export_to_video, load_image, load_video
|
| 398 |
+
|
| 399 |
+
model_id = "Wan-AI/Wan2.2-Animate-14B-Diffusers"
|
| 400 |
+
vae = AutoencoderKLWan.from_pretrained(model_id, subfolder="vae", torch_dtype=torch.float32)
|
| 401 |
+
pipe = WanAnimatePipeline.from_pretrained(model_id, vae=vae, torch_dtype=torch.bfloat16)
|
| 402 |
+
pipe.to("cuda")
|
| 403 |
+
|
| 404 |
+
image = load_image("path/to/character.jpg")
|
| 405 |
+
pose_video = load_video("path/to/pose_video.mp4")
|
| 406 |
+
face_video = load_video("path/to/face_video.mp4")
|
| 407 |
+
|
| 408 |
+
def aspect_ratio_resize(image, pipe, max_area=720 * 1280):
|
| 409 |
+
aspect_ratio = image.height / image.width
|
| 410 |
+
mod_value = pipe.vae_scale_factor_spatial * pipe.transformer.config.patch_size[1]
|
| 411 |
+
height = round(np.sqrt(max_area * aspect_ratio)) // mod_value * mod_value
|
| 412 |
+
width = round(np.sqrt(max_area / aspect_ratio)) // mod_value * mod_value
|
| 413 |
+
image = image.resize((width, height))
|
| 414 |
+
return image, height, width
|
| 415 |
+
|
| 416 |
+
image, height, width = aspect_ratio_resize(image, pipe)
|
| 417 |
+
|
| 418 |
+
prompt = "A person dancing energetically in a studio"
|
| 419 |
+
negative_prompt = "blurry, low quality"
|
| 420 |
+
|
| 421 |
+
# Advanced: Use temporal guidance and custom callback
|
| 422 |
+
def callback_fn(pipe, step_index, timestep, callback_kwargs):
|
| 423 |
+
# You can modify latents or other tensors here
|
| 424 |
+
print(f"Step {step_index}, Timestep {timestep}")
|
| 425 |
+
return callback_kwargs
|
| 426 |
+
|
| 427 |
+
output = pipe(
|
| 428 |
+
image=image,
|
| 429 |
+
pose_video=pose_video,
|
| 430 |
+
face_video=face_video,
|
| 431 |
+
prompt=prompt,
|
| 432 |
+
negative_prompt=negative_prompt,
|
| 433 |
+
height=height,
|
| 434 |
+
width=width,
|
| 435 |
+
segment_frame_length=77,
|
| 436 |
+
num_inference_steps=50,
|
| 437 |
+
guidance_scale=5.0,
|
| 438 |
+
prev_segment_conditioning_frames=5, # Use 5 frames for temporal guidance (1 or 5 recommended)
|
| 439 |
+
callback_on_step_end=callback_fn,
|
| 440 |
+
callback_on_step_end_tensor_inputs=["latents"],
|
| 441 |
+
).frames[0]
|
| 442 |
+
export_to_video(output, "animated_advanced.mp4", fps=30)
|
| 443 |
+
```
|
| 444 |
+
|
| 445 |
+
</hfoption>
|
| 446 |
+
</hfoptions>
|
| 447 |
+
|
| 448 |
+
#### Key Parameters
|
| 449 |
+
|
| 450 |
+
- **mode**: Choose between `"animate"` (default) or `"replace"`
|
| 451 |
+
- **prev_segment_conditioning_frames**: Number of frames for temporal guidance (1 or 5 recommended). Using 5 provides better temporal consistency but requires more memory
|
| 452 |
+
- **guidance_scale**: Controls how closely the output follows the text prompt. Higher values (5-7) produce results more aligned with the prompt. For Wan-Animate, CFG is disabled by default (`guidance_scale=1.0`) but can be enabled to support negative prompts and finer control over facial expressions. (Note that CFG will only target the text prompt and face conditioning.)
|
| 453 |
+
|
| 454 |
+
|
| 455 |
+
## Notes
|
| 456 |
+
|
| 457 |
+
- Wan2.1 supports LoRAs with [`~loaders.WanLoraLoaderMixin.load_lora_weights`].
|
| 458 |
+
|
| 459 |
+
<details>
|
| 460 |
+
<summary>Show example code</summary>
|
| 461 |
+
|
| 462 |
+
```py
|
| 463 |
+
# pip install ftfy
|
| 464 |
+
import torch
|
| 465 |
+
from diffusers import AutoModel, WanPipeline
|
| 466 |
+
from diffusers.schedulers.scheduling_unipc_multistep import UniPCMultistepScheduler
|
| 467 |
+
from diffusers.utils import export_to_video
|
| 468 |
+
|
| 469 |
+
vae = AutoModel.from_pretrained(
|
| 470 |
+
"Wan-AI/Wan2.1-T2V-1.3B-Diffusers", subfolder="vae", torch_dtype=torch.float32
|
| 471 |
+
)
|
| 472 |
+
pipeline = WanPipeline.from_pretrained(
|
| 473 |
+
"Wan-AI/Wan2.1-T2V-1.3B-Diffusers", vae=vae, torch_dtype=torch.bfloat16
|
| 474 |
+
)
|
| 475 |
+
pipeline.scheduler = UniPCMultistepScheduler.from_config(
|
| 476 |
+
pipeline.scheduler.config, flow_shift=5.0
|
| 477 |
+
)
|
| 478 |
+
pipeline.to("cuda")
|
| 479 |
+
|
| 480 |
+
pipeline.load_lora_weights("benjamin-paine/steamboat-willie-1.3b", adapter_name="steamboat-willie")
|
| 481 |
+
pipeline.set_adapters("steamboat-willie")
|
| 482 |
+
|
| 483 |
+
pipeline.enable_model_cpu_offload()
|
| 484 |
+
|
| 485 |
+
# use "steamboat willie style" to trigger the LoRA
|
| 486 |
+
prompt = """
|
| 487 |
+
steamboat willie style, golden era animation, The camera rushes from far to near in a low-angle shot,
|
| 488 |
+
revealing a white ferret on a log. It plays, leaps into the water, and emerges, as the camera zooms in
|
| 489 |
+
for a close-up. Water splashes berry bushes nearby, while moss, snow, and leaves blanket the ground.
|
| 490 |
+
Birch trees and a light blue sky frame the scene, with ferns in the foreground. Side lighting casts dynamic
|
| 491 |
+
shadows and warm highlights. Medium composition, front view, low angle, with depth of field.
|
| 492 |
+
"""
|
| 493 |
+
|
| 494 |
+
output = pipeline(
|
| 495 |
+
prompt=prompt,
|
| 496 |
+
num_frames=81,
|
| 497 |
+
guidance_scale=5.0,
|
| 498 |
+
).frames[0]
|
| 499 |
+
export_to_video(output, "output.mp4", fps=16)
|
| 500 |
+
```
|
| 501 |
+
|
| 502 |
+
</details>
|
| 503 |
+
|
| 504 |
+
- [`WanTransformer3DModel`] and [`AutoencoderKLWan`] supports loading from single files with [`~loaders.FromSingleFileMixin.from_single_file`].
|
| 505 |
+
|
| 506 |
+
<details>
|
| 507 |
+
<summary>Show example code</summary>
|
| 508 |
+
|
| 509 |
+
```py
|
| 510 |
+
# pip install ftfy
|
| 511 |
+
import torch
|
| 512 |
+
from diffusers import WanPipeline, WanTransformer3DModel, AutoencoderKLWan
|
| 513 |
+
|
| 514 |
+
vae = AutoencoderKLWan.from_single_file(
|
| 515 |
+
"https://huggingface.co/Comfy-Org/Wan_2.1_ComfyUI_repackaged/blob/main/split_files/vae/wan_2.1_vae.safetensors"
|
| 516 |
+
)
|
| 517 |
+
transformer = WanTransformer3DModel.from_single_file(
|
| 518 |
+
"https://huggingface.co/Comfy-Org/Wan_2.1_ComfyUI_repackaged/blob/main/split_files/diffusion_models/wan2.1_t2v_1.3B_bf16.safetensors",
|
| 519 |
+
torch_dtype=torch.bfloat16
|
| 520 |
+
)
|
| 521 |
+
pipeline = WanPipeline.from_pretrained(
|
| 522 |
+
"Wan-AI/Wan2.1-T2V-1.3B-Diffusers",
|
| 523 |
+
vae=vae,
|
| 524 |
+
transformer=transformer,
|
| 525 |
+
torch_dtype=torch.bfloat16
|
| 526 |
+
)
|
| 527 |
+
```
|
| 528 |
+
|
| 529 |
+
</details>
|
| 530 |
+
|
| 531 |
+
- Set the [`AutoencoderKLWan`] dtype to `torch.float32` for better decoding quality.
|
| 532 |
+
|
| 533 |
+
- The number of frames per second (fps) or `k` should be calculated by `4 * k + 1`.
|
| 534 |
+
|
| 535 |
+
- Try lower `shift` values (`2.0` to `5.0`) for lower resolution videos and higher `shift` values (`7.0` to `12.0`) for higher resolution images.
|
| 536 |
+
|
| 537 |
+
- Wan 2.1 and 2.2 support using [LightX2V LoRAs](https://huggingface.co/Kijai/WanVideo_comfy/tree/main/Lightx2v) to speed up inference. Using them on Wan 2.2 is slightly more involed. Refer to [this code snippet](https://github.com/huggingface/diffusers/pull/12040#issuecomment-3144185272) to learn more.
|
| 538 |
+
|
| 539 |
+
- Wan 2.2 has two denoisers. By default, LoRAs are only loaded into the first denoiser. One can set `load_into_transformer_2=True` to load LoRAs into the second denoiser. Refer to [this](https://github.com/huggingface/diffusers/pull/12074#issue-3292620048) and [this](https://github.com/huggingface/diffusers/pull/12074#issuecomment-3155896144) examples to learn more.
|
| 540 |
+
|
| 541 |
+
## WanPipeline
|
| 542 |
+
|
| 543 |
+
[[autodoc]] WanPipeline
|
| 544 |
+
- all
|
| 545 |
+
- __call__
|
| 546 |
+
|
| 547 |
+
## WanImageToVideoPipeline
|
| 548 |
+
|
| 549 |
+
[[autodoc]] WanImageToVideoPipeline
|
| 550 |
+
- all
|
| 551 |
+
- __call__
|
| 552 |
+
|
| 553 |
+
## WanVACEPipeline
|
| 554 |
+
|
| 555 |
+
[[autodoc]] WanVACEPipeline
|
| 556 |
+
- all
|
| 557 |
+
- __call__
|
| 558 |
+
|
| 559 |
+
## WanVideoToVideoPipeline
|
| 560 |
+
|
| 561 |
+
[[autodoc]] WanVideoToVideoPipeline
|
| 562 |
+
- all
|
| 563 |
+
- __call__
|
| 564 |
+
|
| 565 |
+
## WanAnimatePipeline
|
| 566 |
+
|
| 567 |
+
[[autodoc]] WanAnimatePipeline
|
| 568 |
+
- all
|
| 569 |
+
- __call__
|
| 570 |
+
|
| 571 |
+
## WanPipelineOutput
|
| 572 |
+
|
| 573 |
+
[[autodoc]] pipelines.wan.pipeline_output.WanPipelineOutput
|
tasks/tasksmith-1c5704b1f07f/tests/source/docs/source/en/api/pipelines/wuerstchen.md
ADDED
|
@@ -0,0 +1,170 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
<!--Copyright 2025 The HuggingFace Team. All rights reserved.
|
| 2 |
+
|
| 3 |
+
Licensed under the Apache License, Version 2.0 (the "License"); you may not use this file except in compliance with
|
| 4 |
+
the License. You may obtain a copy of the License at
|
| 5 |
+
|
| 6 |
+
http://www.apache.org/licenses/LICENSE-2.0
|
| 7 |
+
|
| 8 |
+
Unless required by applicable law or agreed to in writing, software distributed under the License is distributed on
|
| 9 |
+
an "AS IS" BASIS, WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied. See the License for the
|
| 10 |
+
specific language governing permissions and limitations under the License.
|
| 11 |
+
-->
|
| 12 |
+
|
| 13 |
+
# Würstchen
|
| 14 |
+
|
| 15 |
+
> [!WARNING]
|
| 16 |
+
> This pipeline is deprecated but it can still be used. However, we won't test the pipeline anymore and won't accept any changes to it. If you run into any issues, reinstall the last Diffusers version that supported this model.
|
| 17 |
+
|
| 18 |
+
<div class="flex flex-wrap space-x-1">
|
| 19 |
+
<img alt="LoRA" src="https://img.shields.io/badge/LoRA-d8b4fe?style=flat"/>
|
| 20 |
+
</div>
|
| 21 |
+
|
| 22 |
+
<img src="https://github.com/dome272/Wuerstchen/assets/61938694/0617c863-165a-43ee-9303-2a17299a0cf9">
|
| 23 |
+
|
| 24 |
+
[Wuerstchen: An Efficient Architecture for Large-Scale Text-to-Image Diffusion Models](https://huggingface.co/papers/2306.00637) is by Pablo Pernias, Dominic Rampas, Mats L. Richter and Christopher Pal and Marc Aubreville.
|
| 25 |
+
|
| 26 |
+
The abstract from the paper is:
|
| 27 |
+
|
| 28 |
+
*We introduce Würstchen, a novel architecture for text-to-image synthesis that combines competitive performance with unprecedented cost-effectiveness for large-scale text-to-image diffusion models. A key contribution of our work is to develop a latent diffusion technique in which we learn a detailed but extremely compact semantic image representation used to guide the diffusion process. This highly compressed representation of an image provides much more detailed guidance compared to latent representations of language and this significantly reduces the computational requirements to achieve state-of-the-art results. Our approach also improves the quality of text-conditioned image generation based on our user preference study. The training requirements of our approach consists of 24,602 A100-GPU hours - compared to Stable Diffusion 2.1's 200,000 GPU hours. Our approach also requires less training data to achieve these results. Furthermore, our compact latent representations allows us to perform inference over twice as fast, slashing the usual costs and carbon footprint of a state-of-the-art (SOTA) diffusion model significantly, without compromising the end performance. In a broader comparison against SOTA models our approach is substantially more efficient and compares favorably in terms of image quality. We believe that this work motivates more emphasis on the prioritization of both performance and computational accessibility.*
|
| 29 |
+
|
| 30 |
+
## Würstchen Overview
|
| 31 |
+
Würstchen is a diffusion model, whose text-conditional model works in a highly compressed latent space of images. Why is this important? Compressing data can reduce computational costs for both training and inference by magnitudes. Training on 1024x1024 images is way more expensive than training on 32x32. Usually, other works make use of a relatively small compression, in the range of 4x - 8x spatial compression. Würstchen takes this to an extreme. Through its novel design, we achieve a 42x spatial compression. This was unseen before because common methods fail to faithfully reconstruct detailed images after 16x spatial compression. Würstchen employs a two-stage compression, what we call Stage A and Stage B. Stage A is a VQGAN, and Stage B is a Diffusion Autoencoder (more details can be found in the [paper](https://huggingface.co/papers/2306.00637)). A third model, Stage C, is learned in that highly compressed latent space. This training requires fractions of the compute used for current top-performing models, while also allowing cheaper and faster inference.
|
| 32 |
+
|
| 33 |
+
## Würstchen v2 comes to Diffusers
|
| 34 |
+
|
| 35 |
+
After the initial paper release, we have improved numerous things in the architecture, training and sampling, making Würstchen competitive to current state-of-the-art models in many ways. We are excited to release this new version together with Diffusers. Here is a list of the improvements.
|
| 36 |
+
|
| 37 |
+
- Higher resolution (1024x1024 up to 2048x2048)
|
| 38 |
+
- Faster inference
|
| 39 |
+
- Multi Aspect Resolution Sampling
|
| 40 |
+
- Better quality
|
| 41 |
+
|
| 42 |
+
|
| 43 |
+
We are releasing 3 checkpoints for the text-conditional image generation model (Stage C). Those are:
|
| 44 |
+
|
| 45 |
+
- v2-base
|
| 46 |
+
- v2-aesthetic
|
| 47 |
+
- **(default)** v2-interpolated (50% interpolation between v2-base and v2-aesthetic)
|
| 48 |
+
|
| 49 |
+
We recommend using v2-interpolated, as it has a nice touch of both photorealism and aesthetics. Use v2-base for finetunings as it does not have a style bias and use v2-aesthetic for very artistic generations.
|
| 50 |
+
A comparison can be seen here:
|
| 51 |
+
|
| 52 |
+
<img src="https://github.com/dome272/Wuerstchen/assets/61938694/2914830f-cbd3-461c-be64-d50734f4b49d" width=500>
|
| 53 |
+
|
| 54 |
+
## Text-to-Image Generation
|
| 55 |
+
|
| 56 |
+
For the sake of usability, Würstchen can be used with a single pipeline. This pipeline can be used as follows:
|
| 57 |
+
|
| 58 |
+
```python
|
| 59 |
+
import torch
|
| 60 |
+
from diffusers import AutoPipelineForText2Image
|
| 61 |
+
from diffusers.pipelines.wuerstchen import DEFAULT_STAGE_C_TIMESTEPS
|
| 62 |
+
|
| 63 |
+
pipe = AutoPipelineForText2Image.from_pretrained("warp-ai/wuerstchen", torch_dtype=torch.float16).to("cuda")
|
| 64 |
+
|
| 65 |
+
caption = "Anthropomorphic cat dressed as a fire fighter"
|
| 66 |
+
images = pipe(
|
| 67 |
+
caption,
|
| 68 |
+
width=1024,
|
| 69 |
+
height=1536,
|
| 70 |
+
prior_timesteps=DEFAULT_STAGE_C_TIMESTEPS,
|
| 71 |
+
prior_guidance_scale=4.0,
|
| 72 |
+
num_images_per_prompt=2,
|
| 73 |
+
).images
|
| 74 |
+
```
|
| 75 |
+
|
| 76 |
+
For explanation purposes, we can also initialize the two main pipelines of Würstchen individually. Würstchen consists of 3 stages: Stage C, Stage B, Stage A. They all have different jobs and work only together. When generating text-conditional images, Stage C will first generate the latents in a very compressed latent space. This is what happens in the `prior_pipeline`. Afterwards, the generated latents will be passed to Stage B, which decompresses the latents into a bigger latent space of a VQGAN. These latents can then be decoded by Stage A, which is a VQGAN, into the pixel-space. Stage B & Stage A are both encapsulated in the `decoder_pipeline`. For more details, take a look at the [paper](https://huggingface.co/papers/2306.00637).
|
| 77 |
+
|
| 78 |
+
```python
|
| 79 |
+
import torch
|
| 80 |
+
from diffusers import WuerstchenDecoderPipeline, WuerstchenPriorPipeline
|
| 81 |
+
from diffusers.pipelines.wuerstchen import DEFAULT_STAGE_C_TIMESTEPS
|
| 82 |
+
|
| 83 |
+
device = "cuda"
|
| 84 |
+
dtype = torch.float16
|
| 85 |
+
num_images_per_prompt = 2
|
| 86 |
+
|
| 87 |
+
prior_pipeline = WuerstchenPriorPipeline.from_pretrained(
|
| 88 |
+
"warp-ai/wuerstchen-prior", torch_dtype=dtype
|
| 89 |
+
).to(device)
|
| 90 |
+
decoder_pipeline = WuerstchenDecoderPipeline.from_pretrained(
|
| 91 |
+
"warp-ai/wuerstchen", torch_dtype=dtype
|
| 92 |
+
).to(device)
|
| 93 |
+
|
| 94 |
+
caption = "Anthropomorphic cat dressed as a fire fighter"
|
| 95 |
+
negative_prompt = ""
|
| 96 |
+
|
| 97 |
+
prior_output = prior_pipeline(
|
| 98 |
+
prompt=caption,
|
| 99 |
+
height=1024,
|
| 100 |
+
width=1536,
|
| 101 |
+
timesteps=DEFAULT_STAGE_C_TIMESTEPS,
|
| 102 |
+
negative_prompt=negative_prompt,
|
| 103 |
+
guidance_scale=4.0,
|
| 104 |
+
num_images_per_prompt=num_images_per_prompt,
|
| 105 |
+
)
|
| 106 |
+
decoder_output = decoder_pipeline(
|
| 107 |
+
image_embeddings=prior_output.image_embeddings,
|
| 108 |
+
prompt=caption,
|
| 109 |
+
negative_prompt=negative_prompt,
|
| 110 |
+
guidance_scale=0.0,
|
| 111 |
+
output_type="pil",
|
| 112 |
+
).images[0]
|
| 113 |
+
decoder_output
|
| 114 |
+
```
|
| 115 |
+
|
| 116 |
+
## Speed-Up Inference
|
| 117 |
+
You can make use of `torch.compile` function and gain a speed-up of about 2-3x:
|
| 118 |
+
|
| 119 |
+
```python
|
| 120 |
+
prior_pipeline.prior = torch.compile(prior_pipeline.prior, mode="reduce-overhead", fullgraph=True)
|
| 121 |
+
decoder_pipeline.decoder = torch.compile(decoder_pipeline.decoder, mode="reduce-overhead", fullgraph=True)
|
| 122 |
+
```
|
| 123 |
+
|
| 124 |
+
## Limitations
|
| 125 |
+
|
| 126 |
+
- Due to the high compression employed by Würstchen, generations can lack a good amount
|
| 127 |
+
of detail. To our human eye, this is especially noticeable in faces, hands etc.
|
| 128 |
+
- **Images can only be generated in 128-pixel steps**, e.g. the next higher resolution
|
| 129 |
+
after 1024x1024 is 1152x1152
|
| 130 |
+
- The model lacks the ability to render correct text in images
|
| 131 |
+
- The model often does not achieve photorealism
|
| 132 |
+
- Difficult compositional prompts are hard for the model
|
| 133 |
+
|
| 134 |
+
The original codebase, as well as experimental ideas, can be found at [dome272/Wuerstchen](https://github.com/dome272/Wuerstchen).
|
| 135 |
+
|
| 136 |
+
|
| 137 |
+
## WuerstchenCombinedPipeline
|
| 138 |
+
|
| 139 |
+
[[autodoc]] WuerstchenCombinedPipeline
|
| 140 |
+
- all
|
| 141 |
+
- __call__
|
| 142 |
+
|
| 143 |
+
## WuerstchenPriorPipeline
|
| 144 |
+
|
| 145 |
+
[[autodoc]] WuerstchenPriorPipeline
|
| 146 |
+
- all
|
| 147 |
+
- __call__
|
| 148 |
+
|
| 149 |
+
## WuerstchenPriorPipelineOutput
|
| 150 |
+
|
| 151 |
+
[[autodoc]] pipelines.wuerstchen.pipeline_wuerstchen_prior.WuerstchenPriorPipelineOutput
|
| 152 |
+
|
| 153 |
+
## WuerstchenDecoderPipeline
|
| 154 |
+
|
| 155 |
+
[[autodoc]] WuerstchenDecoderPipeline
|
| 156 |
+
- all
|
| 157 |
+
- __call__
|
| 158 |
+
|
| 159 |
+
## Citation
|
| 160 |
+
|
| 161 |
+
```bibtex
|
| 162 |
+
@misc{pernias2023wuerstchen,
|
| 163 |
+
title={Wuerstchen: An Efficient Architecture for Large-Scale Text-to-Image Diffusion Models},
|
| 164 |
+
author={Pablo Pernias and Dominic Rampas and Mats L. Richter and Christopher J. Pal and Marc Aubreville},
|
| 165 |
+
year={2023},
|
| 166 |
+
eprint={2306.00637},
|
| 167 |
+
archivePrefix={arXiv},
|
| 168 |
+
primaryClass={cs.CV}
|
| 169 |
+
}
|
| 170 |
+
```
|
tasks/tasksmith-1c5704b1f07f/tests/source/docs/source/en/api/quantization.md
ADDED
|
@@ -0,0 +1,43 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
<!--Copyright 2025 The HuggingFace Team. All rights reserved.
|
| 2 |
+
|
| 3 |
+
Licensed under the Apache License, Version 2.0 (the "License"); you may not use this file except in compliance with
|
| 4 |
+
the License. You may obtain a copy of the License at
|
| 5 |
+
|
| 6 |
+
http://www.apache.org/licenses/LICENSE-2.0
|
| 7 |
+
|
| 8 |
+
Unless required by applicable law or agreed to in writing, software distributed under the License is distributed on
|
| 9 |
+
an "AS IS" BASIS, WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied. See the License for the
|
| 10 |
+
specific language governing permissions and limitations under the License.
|
| 11 |
+
|
| 12 |
+
-->
|
| 13 |
+
|
| 14 |
+
# Quantization
|
| 15 |
+
|
| 16 |
+
Quantization techniques reduce memory and computational costs by representing weights and activations with lower-precision data types like 8-bit integers (int8). This enables loading larger models you normally wouldn't be able to fit into memory, and speeding up inference.
|
| 17 |
+
|
| 18 |
+
> [!TIP]
|
| 19 |
+
> Learn how to quantize models in the [Quantization](../quantization/overview) guide.
|
| 20 |
+
|
| 21 |
+
## PipelineQuantizationConfig
|
| 22 |
+
|
| 23 |
+
[[autodoc]] quantizers.PipelineQuantizationConfig
|
| 24 |
+
|
| 25 |
+
## BitsAndBytesConfig
|
| 26 |
+
|
| 27 |
+
[[autodoc]] quantizers.quantization_config.BitsAndBytesConfig
|
| 28 |
+
|
| 29 |
+
## GGUFQuantizationConfig
|
| 30 |
+
|
| 31 |
+
[[autodoc]] quantizers.quantization_config.GGUFQuantizationConfig
|
| 32 |
+
|
| 33 |
+
## QuantoConfig
|
| 34 |
+
|
| 35 |
+
[[autodoc]] quantizers.quantization_config.QuantoConfig
|
| 36 |
+
|
| 37 |
+
## TorchAoConfig
|
| 38 |
+
|
| 39 |
+
[[autodoc]] quantizers.quantization_config.TorchAoConfig
|
| 40 |
+
|
| 41 |
+
## DiffusersQuantizer
|
| 42 |
+
|
| 43 |
+
[[autodoc]] quantizers.base.DiffusersQuantizer
|
tasks/tasksmith-1c5704b1f07f/tests/source/docs/source/en/api/schedulers/cm_stochastic_iterative.md
ADDED
|
@@ -0,0 +1,27 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
<!--Copyright 2025 The HuggingFace Team. All rights reserved.
|
| 2 |
+
|
| 3 |
+
Licensed under the Apache License, Version 2.0 (the "License"); you may not use this file except in compliance with
|
| 4 |
+
the License. You may obtain a copy of the License at
|
| 5 |
+
|
| 6 |
+
http://www.apache.org/licenses/LICENSE-2.0
|
| 7 |
+
|
| 8 |
+
Unless required by applicable law or agreed to in writing, software distributed under the License is distributed on
|
| 9 |
+
an "AS IS" BASIS, WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied. See the License for the
|
| 10 |
+
specific language governing permissions and limitations under the License.
|
| 11 |
+
-->
|
| 12 |
+
|
| 13 |
+
# CMStochasticIterativeScheduler
|
| 14 |
+
|
| 15 |
+
[Consistency Models](https://huggingface.co/papers/2303.01469) by Yang Song, Prafulla Dhariwal, Mark Chen, and Ilya Sutskever introduced a multistep and onestep scheduler (Algorithm 1) that is capable of generating good samples in one or a small number of steps.
|
| 16 |
+
|
| 17 |
+
The abstract from the paper is:
|
| 18 |
+
|
| 19 |
+
*Diffusion models have significantly advanced the fields of image, audio, and video generation, but they depend on an iterative sampling process that causes slow generation. To overcome this limitation, we propose consistency models, a new family of models that generate high quality samples by directly mapping noise to data. They support fast one-step generation by design, while still allowing multistep sampling to trade compute for sample quality. They also support zero-shot data editing, such as image inpainting, colorization, and super-resolution, without requiring explicit training on these tasks. Consistency models can be trained either by distilling pre-trained diffusion models, or as standalone generative models altogether. Through extensive experiments, we demonstrate that they outperform existing distillation techniques for diffusion models in one- and few-step sampling, achieving the new state-of-the-art FID of 3.55 on CIFAR-10 and 6.20 on ImageNet 64x64 for one-step generation. When trained in isolation, consistency models become a new family of generative models that can outperform existing one-step, non-adversarial generative models on standard benchmarks such as CIFAR-10, ImageNet 64x64 and LSUN 256x256.*
|
| 20 |
+
|
| 21 |
+
The original codebase can be found at [openai/consistency_models](https://github.com/openai/consistency_models).
|
| 22 |
+
|
| 23 |
+
## CMStochasticIterativeScheduler
|
| 24 |
+
[[autodoc]] CMStochasticIterativeScheduler
|
| 25 |
+
|
| 26 |
+
## CMStochasticIterativeSchedulerOutput
|
| 27 |
+
[[autodoc]] schedulers.scheduling_consistency_models.CMStochasticIterativeSchedulerOutput
|
tasks/tasksmith-1c5704b1f07f/tests/source/docs/source/en/api/schedulers/consistency_decoder.md
ADDED
|
@@ -0,0 +1,21 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
<!--Copyright 2025 The HuggingFace Team. All rights reserved.
|
| 2 |
+
|
| 3 |
+
Licensed under the Apache License, Version 2.0 (the "License"); you may not use this file except in compliance with
|
| 4 |
+
the License. You may obtain a copy of the License at
|
| 5 |
+
|
| 6 |
+
http://www.apache.org/licenses/LICENSE-2.0
|
| 7 |
+
|
| 8 |
+
Unless required by applicable law or agreed to in writing, software distributed under the License is distributed on
|
| 9 |
+
an "AS IS" BASIS, WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied. See the License for the
|
| 10 |
+
specific language governing permissions and limitations under the License.
|
| 11 |
+
-->
|
| 12 |
+
|
| 13 |
+
# ConsistencyDecoderScheduler
|
| 14 |
+
|
| 15 |
+
This scheduler is a part of the [`ConsistencyDecoderPipeline`] and was introduced in [DALL-E 3](https://openai.com/dall-e-3).
|
| 16 |
+
|
| 17 |
+
The original codebase can be found at [openai/consistency_models](https://github.com/openai/consistency_models).
|
| 18 |
+
|
| 19 |
+
|
| 20 |
+
## ConsistencyDecoderScheduler
|
| 21 |
+
[[autodoc]] schedulers.scheduling_consistency_decoder.ConsistencyDecoderScheduler
|
tasks/tasksmith-1c5704b1f07f/tests/source/docs/source/en/api/schedulers/cosine_dpm.md
ADDED
|
@@ -0,0 +1,24 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
<!--Copyright 2025 The HuggingFace Team. All rights reserved.
|
| 2 |
+
|
| 3 |
+
Licensed under the Apache License, Version 2.0 (the "License"); you may not use this file except in compliance with
|
| 4 |
+
the License. You may obtain a copy of the License at
|
| 5 |
+
|
| 6 |
+
http://www.apache.org/licenses/LICENSE-2.0
|
| 7 |
+
|
| 8 |
+
Unless required by applicable law or agreed to in writing, software distributed under the License is distributed on
|
| 9 |
+
an "AS IS" BASIS, WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied. See the License for the
|
| 10 |
+
specific language governing permissions and limitations under the License.
|
| 11 |
+
-->
|
| 12 |
+
|
| 13 |
+
# CosineDPMSolverMultistepScheduler
|
| 14 |
+
|
| 15 |
+
The [`CosineDPMSolverMultistepScheduler`] is a variant of [`DPMSolverMultistepScheduler`] with cosine schedule, proposed by Nichol and Dhariwal (2021).
|
| 16 |
+
It is being used in the [Stable Audio Open](https://huggingface.co/papers/2407.14358) paper and the [Stability-AI/stable-audio-tool](https://github.com/Stability-AI/stable-audio-tools) codebase.
|
| 17 |
+
|
| 18 |
+
This scheduler was contributed by [Yoach Lacombe](https://huggingface.co/ylacombe).
|
| 19 |
+
|
| 20 |
+
## CosineDPMSolverMultistepScheduler
|
| 21 |
+
[[autodoc]] CosineDPMSolverMultistepScheduler
|
| 22 |
+
|
| 23 |
+
## SchedulerOutput
|
| 24 |
+
[[autodoc]] schedulers.scheduling_utils.SchedulerOutput
|
tasks/tasksmith-1c5704b1f07f/tests/source/docs/source/en/api/schedulers/ddim.md
ADDED
|
@@ -0,0 +1,79 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
<!--Copyright 2025 The HuggingFace Team. All rights reserved.
|
| 2 |
+
|
| 3 |
+
Licensed under the Apache License, Version 2.0 (the "License"); you may not use this file except in compliance with
|
| 4 |
+
the License. You may obtain a copy of the License at
|
| 5 |
+
|
| 6 |
+
http://www.apache.org/licenses/LICENSE-2.0
|
| 7 |
+
|
| 8 |
+
Unless required by applicable law or agreed to in writing, software distributed under the License is distributed on
|
| 9 |
+
an "AS IS" BASIS, WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied. See the License for the
|
| 10 |
+
specific language governing permissions and limitations under the License.
|
| 11 |
+
-->
|
| 12 |
+
|
| 13 |
+
# DDIMScheduler
|
| 14 |
+
|
| 15 |
+
[Denoising Diffusion Implicit Models](https://huggingface.co/papers/2010.02502) (DDIM) by Jiaming Song, Chenlin Meng and Stefano Ermon.
|
| 16 |
+
|
| 17 |
+
The abstract from the paper is:
|
| 18 |
+
|
| 19 |
+
*Denoising diffusion probabilistic models (DDPMs) have achieved high quality image generation without adversarial training, yet they require simulating a Markov chain for many steps to produce a sample.
|
| 20 |
+
To accelerate sampling, we present denoising diffusion implicit models (DDIMs), a more efficient class of iterative implicit probabilistic models
|
| 21 |
+
with the same training procedure as DDPMs. In DDPMs, the generative process is defined as the reverse of a Markovian diffusion process.
|
| 22 |
+
We construct a class of non-Markovian diffusion processes that lead to the same training objective, but whose reverse process can be much faster to sample from.
|
| 23 |
+
We empirically demonstrate that DDIMs can produce high quality samples 10× to 50× faster in terms of wall-clock time compared to DDPMs, allow us to trade off computation for sample quality, and can perform semantically meaningful image interpolation directly in the latent space.*
|
| 24 |
+
|
| 25 |
+
The original codebase of this paper can be found at [ermongroup/ddim](https://github.com/ermongroup/ddim), and you can contact the author on [tsong.me](https://tsong.me/).
|
| 26 |
+
|
| 27 |
+
## Tips
|
| 28 |
+
|
| 29 |
+
The paper [Common Diffusion Noise Schedules and Sample Steps are Flawed](https://huggingface.co/papers/2305.08891) claims that a mismatch between the training and inference settings leads to suboptimal inference generation results for Stable Diffusion. To fix this, the authors propose:
|
| 30 |
+
|
| 31 |
+
> [!WARNING]
|
| 32 |
+
> 🧪 This is an experimental feature!
|
| 33 |
+
|
| 34 |
+
1. rescale the noise schedule to enforce zero terminal signal-to-noise ratio (SNR)
|
| 35 |
+
|
| 36 |
+
```py
|
| 37 |
+
pipe.scheduler = DDIMScheduler.from_config(pipe.scheduler.config, rescale_betas_zero_snr=True)
|
| 38 |
+
```
|
| 39 |
+
|
| 40 |
+
2. train a model with `v_prediction` (add the following argument to the [train_text_to_image.py](https://github.com/huggingface/diffusers/blob/main/examples/text_to_image/train_text_to_image.py) or [train_text_to_image_lora.py](https://github.com/huggingface/diffusers/blob/main/examples/text_to_image/train_text_to_image_lora.py) scripts)
|
| 41 |
+
|
| 42 |
+
```bash
|
| 43 |
+
--prediction_type="v_prediction"
|
| 44 |
+
```
|
| 45 |
+
|
| 46 |
+
3. change the sampler to always start from the last timestep
|
| 47 |
+
|
| 48 |
+
```py
|
| 49 |
+
pipe.scheduler = DDIMScheduler.from_config(pipe.scheduler.config, timestep_spacing="trailing")
|
| 50 |
+
```
|
| 51 |
+
|
| 52 |
+
4. rescale classifier-free guidance to prevent over-exposure
|
| 53 |
+
|
| 54 |
+
```py
|
| 55 |
+
image = pipe(prompt, guidance_rescale=0.7).images[0]
|
| 56 |
+
```
|
| 57 |
+
|
| 58 |
+
For example:
|
| 59 |
+
|
| 60 |
+
```py
|
| 61 |
+
from diffusers import DiffusionPipeline, DDIMScheduler
|
| 62 |
+
import torch
|
| 63 |
+
|
| 64 |
+
pipe = DiffusionPipeline.from_pretrained("ptx0/pseudo-journey-v2", torch_dtype=torch.float16)
|
| 65 |
+
pipe.scheduler = DDIMScheduler.from_config(
|
| 66 |
+
pipe.scheduler.config, rescale_betas_zero_snr=True, timestep_spacing="trailing"
|
| 67 |
+
)
|
| 68 |
+
pipe.to("cuda")
|
| 69 |
+
|
| 70 |
+
prompt = "A lion in galaxies, spirals, nebulae, stars, smoke, iridescent, intricate detail, octane render, 8k"
|
| 71 |
+
image = pipe(prompt, guidance_rescale=0.7).images[0]
|
| 72 |
+
image
|
| 73 |
+
```
|
| 74 |
+
|
| 75 |
+
## DDIMScheduler
|
| 76 |
+
[[autodoc]] DDIMScheduler
|
| 77 |
+
|
| 78 |
+
## DDIMSchedulerOutput
|
| 79 |
+
[[autodoc]] schedulers.scheduling_ddim.DDIMSchedulerOutput
|
tasks/tasksmith-1c5704b1f07f/tests/source/docs/source/en/api/schedulers/ddim_cogvideox.md
ADDED
|
@@ -0,0 +1,19 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
<!--Copyright 2025 The HuggingFace Team. All rights reserved.
|
| 2 |
+
|
| 3 |
+
Licensed under the Apache License, Version 2.0 (the "License"); you may not use this file except in compliance with
|
| 4 |
+
the License. You may obtain a copy of the License at
|
| 5 |
+
|
| 6 |
+
http://www.apache.org/licenses/LICENSE-2.0
|
| 7 |
+
|
| 8 |
+
Unless required by applicable law or agreed to in writing, software distributed under the License is distributed on
|
| 9 |
+
an "AS IS" BASIS, WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied. See the License for the
|
| 10 |
+
specific language governing permissions and limitations under the License.
|
| 11 |
+
-->
|
| 12 |
+
|
| 13 |
+
# CogVideoXDDIMScheduler
|
| 14 |
+
|
| 15 |
+
`CogVideoXDDIMScheduler` is based on [Denoising Diffusion Implicit Models](https://huggingface.co/papers/2010.02502), specifically for CogVideoX models.
|
| 16 |
+
|
| 17 |
+
## CogVideoXDDIMScheduler
|
| 18 |
+
|
| 19 |
+
[[autodoc]] CogVideoXDDIMScheduler
|