
html_url stringlengths 51 51 | title stringlengths 9 280 | comments stringlengths 63 24.7k | body stringlengths 51 58.6k | comments length int64 16 1.45k | text stringlengths 186 59.1k |
|---|---|---|---|---|---|
https://github.com/huggingface/datasets/issues/7931 | Enable CORS + HTTP Range support for browser partial reads on cas-bridge.xethub.hf.co (Parquet row-group access) | Thanks @rajatarya!! Yes, I can confirm that it is working on my end. I very much appreciate the help with this!! | ### Feature request
## Summary
Browser-based data tools need Range requests to read Parquet efficiently (footer + selected row groups). Downloads from the Hub redirect to cas-bridge.xethub.hf.co (Xet bridge). The redirected host fails CORS preflight for Range/HEAD workflows, blocking partial reads. ([Hugging Face](htt... | 21 | Enable CORS + HTTP Range support for browser partial reads on cas-bridge.xethub.hf.co (Parquet row-group access)
### Feature request
## Summary
Browser-based data tools need Range requests to read Parquet efficiently (footer + selected row groups). Downloads from the Hub redirect to cas-bridge.xethub.hf.co (Xet bridge... |
https://github.com/huggingface/datasets/issues/5351 | Do we need to implement `_prepare_split`? | Hi! `DatasetBuilder` is a parent class for concrete builders: `GeneratorBasedBuilder`, `ArrowBasedBuilder` and `BeamBasedBuilder`. When writing a builder script, these classes are the ones you should inherit from. And since all of them implement `_prepare_split`, you only have to implement the three methods mentioned a... | ### Describe the bug
I'm not sure this is a bug or if it's just missing in the documentation, or i'm not doing something correctly, but I'm subclassing `DatasetBuilder` and getting the following error because on the `DatasetBuilder` class the `_prepare_split` method is abstract (as are the others we are required to im... | 44 | Do we need to implement `_prepare_split`?
### Describe the bug
I'm not sure this is a bug or if it's just missing in the documentation, or i'm not doing something correctly, but I'm subclassing `DatasetBuilder` and getting the following error because on the `DatasetBuilder` class the `_prepare_split` method is abstrac... |
https://github.com/huggingface/datasets/issues/5351 | Do we need to implement `_prepare_split`? | Thanks so much @mariosasko for the fast response! I've been referencing [this page in the docs](https://huggingface.co/docs/datasets/v2.4.0/en/about_dataset_load) because it it pretty comprehensive in terms of what we have to do and I figured since we subclass the `BuilderConfig` the same pattern would hold, but I've a... | ### Describe the bug
I'm not sure this is a bug or if it's just missing in the documentation, or i'm not doing something correctly, but I'm subclassing `DatasetBuilder` and getting the following error because on the `DatasetBuilder` class the `_prepare_split` method is abstract (as are the others we are required to im... | 63 | Do we need to implement `_prepare_split`?
### Describe the bug
I'm not sure this is a bug or if it's just missing in the documentation, or i'm not doing something correctly, but I'm subclassing `DatasetBuilder` and getting the following error because on the `DatasetBuilder` class the `_prepare_split` method is abstrac... |
https://github.com/huggingface/datasets/issues/5351 | Do we need to implement `_prepare_split`? | cc @stevhliu who may have some ideas on how to improve this part of the docs. | ### Describe the bug
I'm not sure this is a bug or if it's just missing in the documentation, or i'm not doing something correctly, but I'm subclassing `DatasetBuilder` and getting the following error because on the `DatasetBuilder` class the `_prepare_split` method is abstract (as are the others we are required to im... | 16 | Do we need to implement `_prepare_split`?
### Describe the bug
I'm not sure this is a bug or if it's just missing in the documentation, or i'm not doing something correctly, but I'm subclassing `DatasetBuilder` and getting the following error because on the `DatasetBuilder` class the `_prepare_split` method is abstrac... |
https://github.com/huggingface/datasets/issues/5351 | Do we need to implement `_prepare_split`? | one more question for my understanding @mariosasko. the requirement of a loading script has always seemed counterintuitive to me. if i have to provide a script with every dataset, what is the point of using `datasets` if we're doing all the work of loading it, I can just do that in my code and skip the datasets integra... | ### Describe the bug
I'm not sure this is a bug or if it's just missing in the documentation, or i'm not doing something correctly, but I'm subclassing `DatasetBuilder` and getting the following error because on the `DatasetBuilder` class the `_prepare_split` method is abstract (as are the others we are required to im... | 274 | Do we need to implement `_prepare_split`?
### Describe the bug
I'm not sure this is a bug or if it's just missing in the documentation, or i'm not doing something correctly, but I'm subclassing `DatasetBuilder` and getting the following error because on the `DatasetBuilder` class the `_prepare_split` method is abstrac... |
https://github.com/huggingface/datasets/issues/5351 | Do we need to implement `_prepare_split`? | > the requirement of a loading script has always seemed counterintuitive to me
This is a requirement only for datasets not stored in standard formats such as CSV, JSON, SQL, Parquet, ImageFolder, etc.
> if i have to provide a script with every dataset, what is the point of using datasets if we're doing all the... | ### Describe the bug
I'm not sure this is a bug or if it's just missing in the documentation, or i'm not doing something correctly, but I'm subclassing `DatasetBuilder` and getting the following error because on the `DatasetBuilder` class the `_prepare_split` method is abstract (as are the others we are required to im... | 163 | Do we need to implement `_prepare_split`?
### Describe the bug
I'm not sure this is a bug or if it's just missing in the documentation, or i'm not doing something correctly, but I'm subclassing `DatasetBuilder` and getting the following error because on the `DatasetBuilder` class the `_prepare_split` method is abstrac... |
https://github.com/huggingface/datasets/issues/5351 | Do we need to implement `_prepare_split`? | ok, that makes sense. thank you @mariosasko. I realized i'd never looked on the hub at any of the files associated with any datasets. just did that now and it appears that i'll need to have a script regardless _but_ that will just contain my custom config and builder classes, so without realizing it I was already makin... | ### Describe the bug
I'm not sure this is a bug or if it's just missing in the documentation, or i'm not doing something correctly, but I'm subclassing `DatasetBuilder` and getting the following error because on the `DatasetBuilder` class the `_prepare_split` method is abstract (as are the others we are required to im... | 117 | Do we need to implement `_prepare_split`?
### Describe the bug
I'm not sure this is a bug or if it's just missing in the documentation, or i'm not doing something correctly, but I'm subclassing `DatasetBuilder` and getting the following error because on the `DatasetBuilder` class the `_prepare_split` method is abstrac... |
https://github.com/huggingface/datasets/issues/5351 | Do we need to implement `_prepare_split`? | `download_and_prepare` downloads and prepares the arrow files. You need to call `as_dataset` on the builder to get the dataset. | ### Describe the bug
I'm not sure this is a bug or if it's just missing in the documentation, or i'm not doing something correctly, but I'm subclassing `DatasetBuilder` and getting the following error because on the `DatasetBuilder` class the `_prepare_split` method is abstract (as are the others we are required to im... | 19 | Do we need to implement `_prepare_split`?
### Describe the bug
I'm not sure this is a bug or if it's just missing in the documentation, or i'm not doing something correctly, but I'm subclassing `DatasetBuilder` and getting the following error because on the `DatasetBuilder` class the `_prepare_split` method is abstrac... |
https://github.com/huggingface/datasets/issues/5351 | Do we need to implement `_prepare_split`? | ok, I think I was assigning the output of `builder.download_and_prepare` but it's an inplace op, so that explains the `NoneType` i was getting back. Now I'm getting:
```
ArrowInvalid Traceback (most recent call last)
<ipython-input-7-3ed50fb87c70> in <module>
----> 1 ds = dataset_buil... | ### Describe the bug
I'm not sure this is a bug or if it's just missing in the documentation, or i'm not doing something correctly, but I'm subclassing `DatasetBuilder` and getting the following error because on the `DatasetBuilder` class the `_prepare_split` method is abstract (as are the others we are required to im... | 486 | Do we need to implement `_prepare_split`?
### Describe the bug
I'm not sure this is a bug or if it's just missing in the documentation, or i'm not doing something correctly, but I'm subclassing `DatasetBuilder` and getting the following error because on the `DatasetBuilder` class the `_prepare_split` method is abstrac... |
https://github.com/huggingface/datasets/issues/5351 | Do we need to implement `_prepare_split`? | looks like my arrow files are all empty @mariosasko
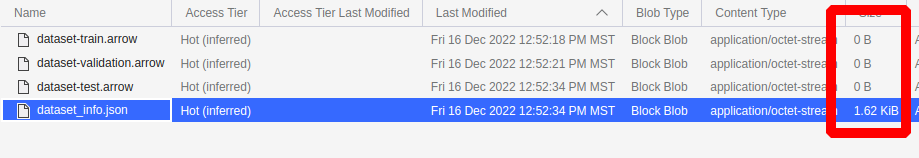
i also see the `incomplete_info.lock` file a level up too. seems like the data isn't being persisted to disk when I call `download_and_prepare`. is ... | ### Describe the bug
I'm not sure this is a bug or if it's just missing in the documentation, or i'm not doing something correctly, but I'm subclassing `DatasetBuilder` and getting the following error because on the `DatasetBuilder` class the `_prepare_split` method is abstract (as are the others we are required to im... | 44 | Do we need to implement `_prepare_split`?
### Describe the bug
I'm not sure this is a bug or if it's just missing in the documentation, or i'm not doing something correctly, but I'm subclassing `DatasetBuilder` and getting the following error because on the `DatasetBuilder` class the `_prepare_split` method is abstrac... |
https://github.com/huggingface/datasets/issues/5351 | Do we need to implement `_prepare_split`? | quick update @mariosasko. i got it working! i had to downgrade to `datasets==2.4.0`. testing other versions now and will let you know the results. | ### Describe the bug
I'm not sure this is a bug or if it's just missing in the documentation, or i'm not doing something correctly, but I'm subclassing `DatasetBuilder` and getting the following error because on the `DatasetBuilder` class the `_prepare_split` method is abstract (as are the others we are required to im... | 24 | Do we need to implement `_prepare_split`?
### Describe the bug
I'm not sure this is a bug or if it's just missing in the documentation, or i'm not doing something correctly, but I'm subclassing `DatasetBuilder` and getting the following error because on the `DatasetBuilder` class the `_prepare_split` method is abstrac... |
https://github.com/huggingface/datasets/issues/5351 | Do we need to implement `_prepare_split`? | I've tested with every version of `datasets>2.4.0` and i get the same error with all of them. | ### Describe the bug
I'm not sure this is a bug or if it's just missing in the documentation, or i'm not doing something correctly, but I'm subclassing `DatasetBuilder` and getting the following error because on the `DatasetBuilder` class the `_prepare_split` method is abstract (as are the others we are required to im... | 17 | Do we need to implement `_prepare_split`?
### Describe the bug
I'm not sure this is a bug or if it's just missing in the documentation, or i'm not doing something correctly, but I'm subclassing `DatasetBuilder` and getting the following error because on the `DatasetBuilder` class the `_prepare_split` method is abstrac... |
https://github.com/huggingface/datasets/issues/5737 | ClassLabel Error | Hi, you can use the `cast_column` function to change the feature type from a `Value(int64)` to `ClassLabel`:
```py
dataset = dataset.cast_column("label", ClassLabel(names=["label_1", "label_2", "label_3"]))
print(dataset.features)
{'text': Value(dtype='string', id=None),
'label': ClassLabel(names=['label_1', 'l... | ### Describe the bug
I still getting the error "call() takes 1 positional argument but 2 were given" even after ensuring that the value being passed to the label object is a single value and that the ClassLabel object has been created with the correct number of label classes
### Steps to reproduce the bug
from... | 34 | ClassLabel Error
### Describe the bug
I still getting the error "call() takes 1 positional argument but 2 were given" even after ensuring that the value being passed to the label object is a single value and that the ClassLabel object has been created with the correct number of label classes
### Steps to reprodu... |
https://github.com/huggingface/datasets/issues/7546 | Large memory use when loading large datasets to a ZFS pool | Hi ! datasets are memory mapped from disk, so they don't fill out your RAM. Not sure what's the source of your memory issue.
What kind of system are you using ? and what kind of disk ? | ### Describe the bug
When I load large parquet based datasets from the hub like `MLCommons/peoples_speech` using `load_dataset`, all my memory (500GB) is used and isn't released after loading, meaning that the process is terminated by the kernel if I try to load an additional dataset. This makes it impossible to train... | 38 | Large memory use when loading large datasets to a ZFS pool
### Describe the bug
When I load large parquet based datasets from the hub like `MLCommons/peoples_speech` using `load_dataset`, all my memory (500GB) is used and isn't released after loading, meaning that the process is terminated by the kernel if I try to lo... |
https://github.com/huggingface/datasets/issues/7546 | Large memory use when loading large datasets to a ZFS pool | Well, the fact of the matter is that my RAM is getting filled out by running the given example, as shown in [this video](https://streamable.com/usb0ql).
My system is a GPU server running Ubuntu. The disk is a SATA SSD attached to the server using a backplane. It is formatted with ZFS, mounted in /cache, and my HF_HOME... | ### Describe the bug
When I load large parquet based datasets from the hub like `MLCommons/peoples_speech` using `load_dataset`, all my memory (500GB) is used and isn't released after loading, meaning that the process is terminated by the kernel if I try to load an additional dataset. This makes it impossible to train... | 92 | Large memory use when loading large datasets to a ZFS pool
### Describe the bug
When I load large parquet based datasets from the hub like `MLCommons/peoples_speech` using `load_dataset`, all my memory (500GB) is used and isn't released after loading, meaning that the process is terminated by the kernel if I try to lo... |
https://github.com/huggingface/datasets/issues/7546 | Large memory use when loading large datasets to a ZFS pool | I'm not super familiar with ZFS, but it looks like it loads the data in memory when the files are memory mapped, which is an issue.
Maybe it's a caching mechanism ? Since `datasets` accesses every memory mapped file to read a small part (the metadata of the arrow record batches), maybe ZFS brings the whole files in me... | ### Describe the bug
When I load large parquet based datasets from the hub like `MLCommons/peoples_speech` using `load_dataset`, all my memory (500GB) is used and isn't released after loading, meaning that the process is terminated by the kernel if I try to load an additional dataset. This makes it impossible to train... | 78 | Large memory use when loading large datasets to a ZFS pool
### Describe the bug
When I load large parquet based datasets from the hub like `MLCommons/peoples_speech` using `load_dataset`, all my memory (500GB) is used and isn't released after loading, meaning that the process is terminated by the kernel if I try to lo... |
https://github.com/huggingface/datasets/issues/7546 | Large memory use when loading large datasets to a ZFS pool | This is the answer.
I tried changing my HF_HOME to an NFS share, and no RAM is then consumed loading the dataset.
I will try to see if I can find a way to configure the ZFS pool to not cache the files (disabling the ARC/primary cache didn't work), and if I do write the solution in this issue. If I can't I guess I hav... | ### Describe the bug
When I load large parquet based datasets from the hub like `MLCommons/peoples_speech` using `load_dataset`, all my memory (500GB) is used and isn't released after loading, meaning that the process is terminated by the kernel if I try to load an additional dataset. This makes it impossible to train... | 71 | Large memory use when loading large datasets to a ZFS pool
### Describe the bug
When I load large parquet based datasets from the hub like `MLCommons/peoples_speech` using `load_dataset`, all my memory (500GB) is used and isn't released after loading, meaning that the process is terminated by the kernel if I try to lo... |
https://github.com/huggingface/datasets/issues/5153 | default Image/AudioFolder infers labels when there is no metadata files even if there is only one dir | Makes sense! For the last structure, we could count the path segments (delimited by "/" for URLs and `os.sep` for local paths) to ensure all inferred labels are on the same level. Otherwise, I think it's safe to assume they are meaningless and ignore them.
| ### Describe the bug
By default FolderBasedBuilder infers labels if there is not metadata files, even if it's meaningless (for example, they are in a single directory or in the root folder, see this repo as an example: https://huggingface.co/datasets/patrickvonplaten/audios
As this is a corner case for quick expl... | 45 | default Image/AudioFolder infers labels when there is no metadata files even if there is only one dir
### Describe the bug
By default FolderBasedBuilder infers labels if there is not metadata files, even if it's meaningless (for example, they are in a single directory or in the root folder, see this repo as an examp... |
https://github.com/huggingface/datasets/issues/6382 | Add CheXpert dataset for vision | Hey @SauravMaheshkar ! Just responded to your email.
_For transparency, copying part of my response here:_
I agree, it would be really great to have this and other BenchMD datasets easily accessible on the hub.
I think the main limiting factor is that the ChexPert dataset is currently hosted on the Stanford AIMI... | ### Feature request
### Name
**CheXpert: A Large Chest Radiograph Dataset with Uncertainty Labels and Expert Comparison**
### Paper
https://arxiv.org/abs/1901.07031
### Data
https://stanfordaimi.azurewebsites.net/datasets/8cbd9ed4-2eb9-4565-affc-111cf4f7ebe2
### Motivation
CheXpert is one of the fund... | 126 | Add CheXpert dataset for vision
### Feature request
### Name
**CheXpert: A Large Chest Radiograph Dataset with Uncertainty Labels and Expert Comparison**
### Paper
https://arxiv.org/abs/1901.07031
### Data
https://stanfordaimi.azurewebsites.net/datasets/8cbd9ed4-2eb9-4565-affc-111cf4f7ebe2
### Motivat... |
https://github.com/huggingface/datasets/issues/6382 | Add CheXpert dataset for vision | Hi @katielink , I would also love to be on board and contribute to this loading script/project if it is still being developed. I'm interested because I personally would like to gain access to the CheXpert dataset and am facing some weird issues, so I'd like to sort it out for me, and potentially others. Please keep me ... | ### Feature request
### Name
**CheXpert: A Large Chest Radiograph Dataset with Uncertainty Labels and Expert Comparison**
### Paper
https://arxiv.org/abs/1901.07031
### Data
https://stanfordaimi.azurewebsites.net/datasets/8cbd9ed4-2eb9-4565-affc-111cf4f7ebe2
### Motivation
CheXpert is one of the fund... | 66 | Add CheXpert dataset for vision
### Feature request
### Name
**CheXpert: A Large Chest Radiograph Dataset with Uncertainty Labels and Expert Comparison**
### Paper
https://arxiv.org/abs/1901.07031
### Data
https://stanfordaimi.azurewebsites.net/datasets/8cbd9ed4-2eb9-4565-affc-111cf4f7ebe2
### Motivat... |
https://github.com/huggingface/datasets/issues/5258 | Restore order of split names in dataset_info for canonical datasets | The bulk edit is running...
See for example:
- A single config: https://huggingface.co/datasets/acronym_identification/discussions/2
- Multiple configs: https://huggingface.co/datasets/babi_qa/discussions/1 | After a bulk edit of canonical datasets to create the YAML `dataset_info` metadata, the split names were accidentally sorted alphabetically. See for example:
- https://huggingface.co/datasets/bc2gm_corpus/commit/2384629484401ecf4bb77cd808816719c424e57c
Note that this order is the one appearing in the preview of the... | 17 | Restore order of split names in dataset_info for canonical datasets
After a bulk edit of canonical datasets to create the YAML `dataset_info` metadata, the split names were accidentally sorted alphabetically. See for example:
- https://huggingface.co/datasets/bc2gm_corpus/commit/2384629484401ecf4bb77cd808816719c424e57... |
https://github.com/huggingface/datasets/issues/5258 | Restore order of split names in dataset_info for canonical datasets | TODO: Add "dataset_info" YAML metadata to:
- [x] "chr_en" has no metadata JSON file, nor "dataset_info" YAML tag in its card
- Fixing PR: https://huggingface.co/datasets/chr_en/discussions/1
- [x] "conll2000" has no metadata JSON file, but it has "dataset_info" YAML tag in its card
- [x] "crime_and_punish" has n... | After a bulk edit of canonical datasets to create the YAML `dataset_info` metadata, the split names were accidentally sorted alphabetically. See for example:
- https://huggingface.co/datasets/bc2gm_corpus/commit/2384629484401ecf4bb77cd808816719c424e57c
Note that this order is the one appearing in the preview of the... | 141 | Restore order of split names in dataset_info for canonical datasets
After a bulk edit of canonical datasets to create the YAML `dataset_info` metadata, the split names were accidentally sorted alphabetically. See for example:
- https://huggingface.co/datasets/bc2gm_corpus/commit/2384629484401ecf4bb77cd808816719c424e57... |
https://github.com/huggingface/datasets/issues/6110 | [BUG] Dataset initialized from in-memory data does not create cache. | This is expected behavior. You must provide `cache_file_name` when performing `.map` on an in-memory dataset for the result to be cached. | ### Describe the bug
`Dataset` initialized from in-memory data (dictionary in my case, haven't tested with other types) does not create cache when processed with the `map` method, unlike `Dataset` initialized by other methods such as `load_dataset`.
### Steps to reproduce the bug
```python
# below code was ru... | 21 | [BUG] Dataset initialized from in-memory data does not create cache.
### Describe the bug
`Dataset` initialized from in-memory data (dictionary in my case, haven't tested with other types) does not create cache when processed with the `map` method, unlike `Dataset` initialized by other methods such as `load_dataset`... |
https://github.com/huggingface/datasets/issues/4696 | Cannot load LinCE dataset | Hi @finiteautomata, thanks for reporting.
Unfortunately, I'm not able to reproduce your issue:
```python
In [1]: from datasets import load_dataset
...: dataset = load_dataset("lince", "ner_spaeng")
Downloading builder script: 20.8kB [00:00, 9.09MB/s] ... | ## Describe the bug
Cannot load LinCE dataset due to a connection error
## Steps to reproduce the bug
```python
from datasets import load_dataset
dataset = load_dataset("lince", "ner_spaeng")
```
A notebook with this code and corresponding error can be found at https://colab.research.google.com/drive/1... | 225 | Cannot load LinCE dataset
## Describe the bug
Cannot load LinCE dataset due to a connection error
## Steps to reproduce the bug
```python
from datasets import load_dataset
dataset = load_dataset("lince", "ner_spaeng")
```
A notebook with this code and corresponding error can be found at https://colab.r... |
https://github.com/huggingface/datasets/issues/6620 | wiki_dpr.py error (ID mismatch between lines {id} and vector {vec_id} | Thanks for reporting, @kiehls90.
As this seems an issue with the specific "wiki_dpr" dataset, I am transferring the issue to the corresponding dataset page: https://huggingface.co/datasets/wiki_dpr/discussions/13 | ### Describe the bug
I'm trying to run a rag example, and the dataset is wiki_dpr.
wiki_dpr download and extracting have been completed successfully.
However, at the generating train split stage, an error from wiki_dpr.py keeps popping up.
Especially in "_generate_examples" :
1. The following error occurs in the... | 25 | wiki_dpr.py error (ID mismatch between lines {id} and vector {vec_id}
### Describe the bug
I'm trying to run a rag example, and the dataset is wiki_dpr.
wiki_dpr download and extracting have been completed successfully.
However, at the generating train split stage, an error from wiki_dpr.py keeps popping up.
Espe... |
https://github.com/huggingface/datasets/issues/5314 | Datasets: classification_report() got an unexpected keyword argument 'suffix' | @JonathanAlis also note that the metrics are deprecated in our `datasets` library.
Please, use the new library 🤗 Evaluate instead: https://huggingface.co/docs/evaluate | https://github.com/huggingface/datasets/blob/main/metrics/seqeval/seqeval.py
> import datasets
predictions = [['O', 'O', 'B-MISC', 'I-MISC', 'I-MISC', 'I-MISC', 'O'], ['B-PER', 'I-PER', 'O']]
references = [['O', 'O', 'O', 'B-MISC', 'I-MISC', 'I-MISC', 'O'], ['B-PER', 'I-PER', 'O']]
seqeval = datasets.load_metri... | 21 | Datasets: classification_report() got an unexpected keyword argument 'suffix'
https://github.com/huggingface/datasets/blob/main/metrics/seqeval/seqeval.py
> import datasets
predictions = [['O', 'O', 'B-MISC', 'I-MISC', 'I-MISC', 'I-MISC', 'O'], ['B-PER', 'I-PER', 'O']]
references = [['O', 'O', 'O', 'B-MISC', 'I-... |
https://github.com/huggingface/datasets/issues/5708 | Dataset sizes are in MiB instead of MB in dataset cards | looks great!
Do you encode the fact that you've already converted a dataset? (to not convert it twice) or do you base yourself on the info contained in `dataset_info` | As @severo reported in an internal discussion (https://github.com/huggingface/moon-landing/issues/5929):
Now we show the dataset size:
- from the dataset card (in the side column)
- from the datasets-server (in the viewer)
But, even if the size is the same, we see a mismatch because the viewer shows MB, while t... | 29 | Dataset sizes are in MiB instead of MB in dataset cards
As @severo reported in an internal discussion (https://github.com/huggingface/moon-landing/issues/5929):
Now we show the dataset size:
- from the dataset card (in the side column)
- from the datasets-server (in the viewer)
But, even if the size is the same... |
https://github.com/huggingface/datasets/issues/5708 | Dataset sizes are in MiB instead of MB in dataset cards | I am only looping trough the dataset cards, assuming that all of them were created with MiB.
I agree we should only run the bulk edit once for all canonical datasets: I'm using a for-loop over canonical datasets. | As @severo reported in an internal discussion (https://github.com/huggingface/moon-landing/issues/5929):
Now we show the dataset size:
- from the dataset card (in the side column)
- from the datasets-server (in the viewer)
But, even if the size is the same, we see a mismatch because the viewer shows MB, while t... | 38 | Dataset sizes are in MiB instead of MB in dataset cards
As @severo reported in an internal discussion (https://github.com/huggingface/moon-landing/issues/5929):
Now we show the dataset size:
- from the dataset card (in the side column)
- from the datasets-server (in the viewer)
But, even if the size is the same... |
https://github.com/huggingface/datasets/issues/5708 | Dataset sizes are in MiB instead of MB in dataset cards | I have just included as well the conversion from MB to GB if necessary. See:
- https://huggingface.co/datasets/bookcorpus/discussions/2/files
- https://huggingface.co/datasets/asnq/discussions/2/files | As @severo reported in an internal discussion (https://github.com/huggingface/moon-landing/issues/5929):
Now we show the dataset size:
- from the dataset card (in the side column)
- from the datasets-server (in the viewer)
But, even if the size is the same, we see a mismatch because the viewer shows MB, while t... | 19 | Dataset sizes are in MiB instead of MB in dataset cards
As @severo reported in an internal discussion (https://github.com/huggingface/moon-landing/issues/5929):
Now we show the dataset size:
- from the dataset card (in the side column)
- from the datasets-server (in the viewer)
But, even if the size is the same... |
https://github.com/huggingface/datasets/issues/5708 | Dataset sizes are in MiB instead of MB in dataset cards | First, I tested some batches to check the changes made. Then I incorporated the MB to GB conversion. Now I'm running the rest. | As @severo reported in an internal discussion (https://github.com/huggingface/moon-landing/issues/5929):
Now we show the dataset size:
- from the dataset card (in the side column)
- from the datasets-server (in the viewer)
But, even if the size is the same, we see a mismatch because the viewer shows MB, while t... | 23 | Dataset sizes are in MiB instead of MB in dataset cards
As @severo reported in an internal discussion (https://github.com/huggingface/moon-landing/issues/5929):
Now we show the dataset size:
- from the dataset card (in the side column)
- from the datasets-server (in the viewer)
But, even if the size is the same... |
https://github.com/huggingface/datasets/issues/5708 | Dataset sizes are in MiB instead of MB in dataset cards | Thanks a lot!
The sizes now match as expected!
<img width="1446" alt="Capture d’écran 2023-04-05 à 16 10 15" src="https://user-images.githubusercontent.com/1676121/230107044-ac2a76ea-a4fe-4e81-a925-f464b85f5edd.png">
| As @severo reported in an internal discussion (https://github.com/huggingface/moon-landing/issues/5929):
Now we show the dataset size:
- from the dataset card (in the side column)
- from the datasets-server (in the viewer)
But, even if the size is the same, we see a mismatch because the viewer shows MB, while t... | 19 | Dataset sizes are in MiB instead of MB in dataset cards
As @severo reported in an internal discussion (https://github.com/huggingface/moon-landing/issues/5929):
Now we show the dataset size:
- from the dataset card (in the side column)
- from the datasets-server (in the viewer)
But, even if the size is the same... |
https://github.com/huggingface/datasets/issues/5708 | Dataset sizes are in MiB instead of MB in dataset cards | I made another bulk edit of ancient canonical datasets that were moved to community organization. I have parsed 11 datasets and opened a PR on 3 of them:
- [x] "allenai/scicite": https://huggingface.co/datasets/allenai/scicite/discussions/3
- [x] "allenai/scifact": https://huggingface.co/datasets/allenai/scifact/disc... | As @severo reported in an internal discussion (https://github.com/huggingface/moon-landing/issues/5929):
Now we show the dataset size:
- from the dataset card (in the side column)
- from the datasets-server (in the viewer)
But, even if the size is the same, we see a mismatch because the viewer shows MB, while t... | 40 | Dataset sizes are in MiB instead of MB in dataset cards
As @severo reported in an internal discussion (https://github.com/huggingface/moon-landing/issues/5929):
Now we show the dataset size:
- from the dataset card (in the side column)
- from the datasets-server (in the viewer)
But, even if the size is the same... |
https://github.com/huggingface/datasets/issues/6720 | TypeError: 'str' object is not callable | Hi ! I opened a PR to fix an issue in the Features defined in your code
Basically changing
```python
Sequence("float32")
```
to
```python
Sequence(Value("float32"))
```
https://huggingface.co/datasets/BramVanroy/hplt_mono_v1_2/discussions/1 | ### Describe the bug
I am trying to get the HPLT datasets on the hub. Downloading/re-uploading would be too time- and resource consuming so I wrote [a dataset loader script](https://huggingface.co/datasets/BramVanroy/hplt_mono_v1_2/blob/main/hplt_mono_v1_2.py). I think I am very close but for some reason I always get ... | 27 | TypeError: 'str' object is not callable
### Describe the bug
I am trying to get the HPLT datasets on the hub. Downloading/re-uploading would be too time- and resource consuming so I wrote [a dataset loader script](https://huggingface.co/datasets/BramVanroy/hplt_mono_v1_2/blob/main/hplt_mono_v1_2.py). I think I am very... |
https://github.com/huggingface/datasets/issues/6720 | TypeError: 'str' object is not callable | D'oh! Was wondering why the `str() is not callable` was in there. Glad the error is my end though, and not related to zstandard (which I had not used in the past).
Thanks a lot! | ### Describe the bug
I am trying to get the HPLT datasets on the hub. Downloading/re-uploading would be too time- and resource consuming so I wrote [a dataset loader script](https://huggingface.co/datasets/BramVanroy/hplt_mono_v1_2/blob/main/hplt_mono_v1_2.py). I think I am very close but for some reason I always get ... | 35 | TypeError: 'str' object is not callable
### Describe the bug
I am trying to get the HPLT datasets on the hub. Downloading/re-uploading would be too time- and resource consuming so I wrote [a dataset loader script](https://huggingface.co/datasets/BramVanroy/hplt_mono_v1_2/blob/main/hplt_mono_v1_2.py). I think I am very... |
https://github.com/huggingface/datasets/issues/3739 | Pubmed dataset does not work in streaming mode | Thanks for reporting, @abhi-mosaic (related to #3655).
Please note that `xml.etree.ElementTree.parse` already supports streaming:
- #3476
No need to refactor to use `open`/`xopen`. Is is enough with importing the package `as ET` (instead of `as etree`). | ## Describe the bug
Trying to use the `pubmed` dataset with `streaming=True` fails.
## Steps to reproduce the bug
```python
import datasets
pubmed_train = datasets.load_dataset('pubmed', split='train', streaming=True)
print (next(iter(pubmed_train)))
```
## Expected results
I would expect to see the first ... | 36 | Pubmed dataset does not work in streaming mode
## Describe the bug
Trying to use the `pubmed` dataset with `streaming=True` fails.
## Steps to reproduce the bug
```python
import datasets
pubmed_train = datasets.load_dataset('pubmed', split='train', streaming=True)
print (next(iter(pubmed_train)))
```
## Exp... |
https://github.com/huggingface/datasets/issues/5532 | train_test_split in arrow_dataset does not ensure to keep single classes in test set | Hi! You can get this behavior by specifying `stratify_by_column="label"` in `train_test_split`.
This is the full example:
```python
import numpy as np
from datasets import Dataset, ClassLabel
data = [
{'label': 0, 'text': "example1"},
{'label': 1, 'text': "example2"},
{'label': 1, 'text': "examp... | ### Describe the bug
When I have a dataset with very few (e.g. 1) examples per class and I call the train_test_split function on it, sometimes the single class will be in the test set. thus will never be considered for training.
### Steps to reproduce the bug
```
import numpy as np
from datasets import Dataset
... | 88 | train_test_split in arrow_dataset does not ensure to keep single classes in test set
### Describe the bug
When I have a dataset with very few (e.g. 1) examples per class and I call the train_test_split function on it, sometimes the single class will be in the test set. thus will never be considered for training.
### ... |
https://github.com/huggingface/datasets/issues/4221 | Dictionary Feature | Hi @jordiae,
Instead of the `Sequence` feature, you can use just a regular list: put the dict between `[` and `]`:
```python
"list_of_dict_feature": [
{
"key1_in_dict": datasets.Value("string"),
"key2_in_dict": datasets.Value("int32"),
...
}
],
```
Feel free to re-open thi... | Hi, I'm trying to create the loading script for a dataset in which one feature is a list of dictionaries, which afaik doesn't fit very well the values and structures supported by Value and Sequence. Is there any suggested workaround, am I missing something?
Thank you in advance. | 48 | Dictionary Feature
Hi, I'm trying to create the loading script for a dataset in which one feature is a list of dictionaries, which afaik doesn't fit very well the values and structures supported by Value and Sequence. Is there any suggested workaround, am I missing something?
Thank you in advance.
Hi @jordiae,
In... |
https://github.com/huggingface/datasets/issues/4221 | Dictionary Feature | > Hi @jordiae,
>
> Instead of the `Sequence` feature, you can use just a regular list: put the dict between `[` and `]`:
>
> ```python
> "list_of_dict_feature": [
> {
> "key1_in_dict": datasets.Value("string"),
> "key2_in_dict": datasets.Value("int32"),
> ...
> }
> ],
> ```... | Hi, I'm trying to create the loading script for a dataset in which one feature is a list of dictionaries, which afaik doesn't fit very well the values and structures supported by Value and Sequence. Is there any suggested workaround, am I missing something?
Thank you in advance. | 65 | Dictionary Feature
Hi, I'm trying to create the loading script for a dataset in which one feature is a list of dictionaries, which afaik doesn't fit very well the values and structures supported by Value and Sequence. Is there any suggested workaround, am I missing something?
Thank you in advance.
> Hi @jordiae,
> ... |
https://github.com/huggingface/datasets/issues/3353 | add one field "example_id", but I can't see it in the "comput_loss" function | Hi ! Your function looks fine, I used to map `squad` locally and it indeed added the `example_id` field correctly.
However I think that in the `compute_loss` method only a subset of the fields are available: the model inputs. Since `example_id` is not a model input (it's not passed as a parameter to the model), the ... | Hi, I add one field **example_id**, but I can't see it in the **comput_loss** function, how can I do this? below is the information of inputs
```
*********************** inputs: {'attention_mask': tensor([[1, 1, 1, ..., 0, 0, 0],
[1, 1, 1, ..., 0, 0, 0],
[1, 1, 1, ..., 0, 0, 0],
...,
... | 118 | add one field "example_id", but I can't see it in the "comput_loss" function
Hi, I add one field **example_id**, but I can't see it in the **comput_loss** function, how can I do this? below is the information of inputs
```
*********************** inputs: {'attention_mask': tensor([[1, 1, 1, ..., 0, 0, 0],
... |
https://github.com/huggingface/datasets/issues/3353 | add one field "example_id", but I can't see it in the "comput_loss" function | Hi, I have set **args.remove_unused_columns=False** and **training_args.remove_unused_columns=False**, but the field doesn't been contained yet.
```
def main():
argp = HfArgumentParser(TrainingArguments)
# The HfArgumentParser object collects command-line arguments into an object (and provides default valu... | Hi, I add one field **example_id**, but I can't see it in the **comput_loss** function, how can I do this? below is the information of inputs
```
*********************** inputs: {'attention_mask': tensor([[1, 1, 1, ..., 0, 0, 0],
[1, 1, 1, ..., 0, 0, 0],
[1, 1, 1, ..., 0, 0, 0],
...,
... | 373 | add one field "example_id", but I can't see it in the "comput_loss" function
Hi, I add one field **example_id**, but I can't see it in the **comput_loss** function, how can I do this? below is the information of inputs
```
*********************** inputs: {'attention_mask': tensor([[1, 1, 1, ..., 0, 0, 0],
... |
https://github.com/huggingface/datasets/issues/3353 | add one field "example_id", but I can't see it in the "comput_loss" function | Hi, I print the value, all are set to False, but don't work.
```
********************* training_args: TrainingArguments(
_n_gpu=1,
adafactor=False,
adam_beta1=0.9,
adam_beta2=0.999,
adam_epsilon=1e-08,
dataloader_drop_last=False,
dataloader_num_workers=0,
dataloader_pin_memory=True,
ddp_find_unused_parameter... | Hi, I add one field **example_id**, but I can't see it in the **comput_loss** function, how can I do this? below is the information of inputs
```
*********************** inputs: {'attention_mask': tensor([[1, 1, 1, ..., 0, 0, 0],
[1, 1, 1, ..., 0, 0, 0],
[1, 1, 1, ..., 0, 0, 0],
...,
... | 247 | add one field "example_id", but I can't see it in the "comput_loss" function
Hi, I add one field **example_id**, but I can't see it in the **comput_loss** function, how can I do this? below is the information of inputs
```
*********************** inputs: {'attention_mask': tensor([[1, 1, 1, ..., 0, 0, 0],
... |
https://github.com/huggingface/datasets/issues/3353 | add one field "example_id", but I can't see it in the "comput_loss" function | Hmmm, it might be because the default data collator removes all the fields with `string` type:
https://github.com/huggingface/transformers/blob/4c0dd199c8305903564c2edeae23d294edd4b321/src/transformers/data/data_collator.py#L107-L112
I guess you also need a custom data collator that doesn't remove them. | Hi, I add one field **example_id**, but I can't see it in the **comput_loss** function, how can I do this? below is the information of inputs
```
*********************** inputs: {'attention_mask': tensor([[1, 1, 1, ..., 0, 0, 0],
[1, 1, 1, ..., 0, 0, 0],
[1, 1, 1, ..., 0, 0, 0],
...,
... | 30 | add one field "example_id", but I can't see it in the "comput_loss" function
Hi, I add one field **example_id**, but I can't see it in the **comput_loss** function, how can I do this? below is the information of inputs
```
*********************** inputs: {'attention_mask': tensor([[1, 1, 1, ..., 0, 0, 0],
... |
https://github.com/huggingface/datasets/issues/3353 | add one field "example_id", but I can't see it in the "comput_loss" function | I overwrite **get_train_dataloader**, and remove **_remove_unused_columns**, but it doesn't work.
```
def get_train_dataloader(self) -> DataLoader:
"""
Returns the training :class:`~torch.utils.data.DataLoader`.
Will use no sampler if :obj:`self.train_dataset` does not implement :ob... | Hi, I add one field **example_id**, but I can't see it in the **comput_loss** function, how can I do this? below is the information of inputs
```
*********************** inputs: {'attention_mask': tensor([[1, 1, 1, ..., 0, 0, 0],
[1, 1, 1, ..., 0, 0, 0],
[1, 1, 1, ..., 0, 0, 0],
...,
... | 116 | add one field "example_id", but I can't see it in the "comput_loss" function
Hi, I add one field **example_id**, but I can't see it in the **comput_loss** function, how can I do this? below is the information of inputs
```
*********************** inputs: {'attention_mask': tensor([[1, 1, 1, ..., 0, 0, 0],
... |
https://github.com/huggingface/datasets/issues/3353 | add one field "example_id", but I can't see it in the "comput_loss" function | Hi, it works now, thank you.
1. **args.remove_unused_columns=False** and **training_args.remove_unused_columns=False**
2. overwrite **get_train_dataloader**, and remove **_remove_unused_columns**
3. add new fields, and can be got in **inputs**. | Hi, I add one field **example_id**, but I can't see it in the **comput_loss** function, how can I do this? below is the information of inputs
```
*********************** inputs: {'attention_mask': tensor([[1, 1, 1, ..., 0, 0, 0],
[1, 1, 1, ..., 0, 0, 0],
[1, 1, 1, ..., 0, 0, 0],
...,
... | 26 | add one field "example_id", but I can't see it in the "comput_loss" function
Hi, I add one field **example_id**, but I can't see it in the **comput_loss** function, how can I do this? below is the information of inputs
```
*********************** inputs: {'attention_mask': tensor([[1, 1, 1, ..., 0, 0, 0],
... |
https://github.com/huggingface/datasets/issues/3341 | Mirror the canonical datasets to the Hugging Face Hub | I created a GitHub project to keep track of what needs to be done:
https://github.com/huggingface/datasets/projects/3
I also store my code in a (private for now) repository at https://github.com/huggingface/mirror_canonical_datasets_on_hub | - [ ] create a repo on https://hf.co/datasets for every canonical dataset
- [ ] on every commit related to a dataset, update the hf.co repo
See https://github.com/huggingface/moon-landing/pull/1562
@SBrandeis: I let you edit this description if needed to precise the intent. | 28 | Mirror the canonical datasets to the Hugging Face Hub
- [ ] create a repo on https://hf.co/datasets for every canonical dataset
- [ ] on every commit related to a dataset, update the hf.co repo
See https://github.com/huggingface/moon-landing/pull/1562
@SBrandeis: I let you edit this description if needed to prec... |
https://github.com/huggingface/datasets/issues/3341 | Mirror the canonical datasets to the Hugging Face Hub | I understand that the datasets are mirrored on the Hub now, right? Might I close @lhoestq @SBrandeis? | - [ ] create a repo on https://hf.co/datasets for every canonical dataset
- [ ] on every commit related to a dataset, update the hf.co repo
See https://github.com/huggingface/moon-landing/pull/1562
@SBrandeis: I let you edit this description if needed to precise the intent. | 17 | Mirror the canonical datasets to the Hugging Face Hub
- [ ] create a repo on https://hf.co/datasets for every canonical dataset
- [ ] on every commit related to a dataset, update the hf.co repo
See https://github.com/huggingface/moon-landing/pull/1562
@SBrandeis: I let you edit this description if needed to prec... |
https://github.com/huggingface/datasets/issues/4323 | Audio can not find value["bytes"] | 
that is reason my bytes`s empty
but i have some confused why path prior is higher than bytes?
if you can make bytes in _generate_examples , you don`t have to make bytes to path?
because we have path a... | ## Describe the bug
I wrote down _generate_examples like:

but where is the bytes?

## ... | 42 | Audio can not find value["bytes"]
## Describe the bug
I wrote down _generate_examples like:

but where is the bytes?

but where is the bytes?

## ... | 138 | Audio can not find value["bytes"]
## Describe the bug
I wrote down _generate_examples like:

but where is the bytes?
 {"bytes":"blah blah~", "path":"blah blah~"}
that source working that my bytes to empty first,
and then, re-calculate my bytes!

but where is the bytes?

## ... | 105 | Audio can not find value["bytes"]
## Describe the bug
I wrote down _generate_examples like:

but where is the bytes?

but where is the bytes?

## ... | 41 | Audio can not find value["bytes"]
## Describe the bug
I wrote down _generate_examples like:

but where is the bytes?
) and see how we can make the `Image.encode_example` method work with PCM data.
There might be other ways to approach this problem, but here is what I th... | ## Describe the bug
I wrote down _generate_examples like:

but where is the bytes?

## ... | 103 | Audio can not find value["bytes"]
## Describe the bug
I wrote down _generate_examples like:

but where is the bytes?
) | ### Describe the bug
Hi,
I have been trying to import the datasets library but I keep gtting this error.
`Traceback (most recent call last):
File /opt/local/jupyterhub/lib64/python3.9/site-packages/IPython/core/interactiveshell.py:3508 in run_code
exec(code_obj, self.user_global_ns, self.user_ns)
... | 30 | 'import datasets' throws "invalid syntax error"
### Describe the bug
Hi,
I have been trying to import the datasets library but I keep gtting this error.
`Traceback (most recent call last):
File /opt/local/jupyterhub/lib64/python3.9/site-packages/IPython/core/interactiveshell.py:3508 in run_code
exec(... |
https://github.com/huggingface/datasets/issues/6641 | unicodedecodeerror: 'utf-8' codec can't decode byte 0xac in position 25: invalid start byte | Hi @Hughhuh.
I have formatted the issue because it was not easily readable. Additionally, the environment info is incomplete: it seems you did not run the proposed CLI command `datasets-cli env` and essential information is missing: version of `datasets`, version of `pyarrow`,...
With the information you provide... | ### Describe the bug
unicodedecodeerror: 'utf-8' codec can't decode byte 0xac in position 25: invalid start byte
### Steps to reproduce the bug
```
import sys
sys.getdefaultencoding()
'utf-8'
from datasets import load_dataset
print(f"Train dataset size: {len(dataset['train'])}")
print(f"Test datase... | 66 | unicodedecodeerror: 'utf-8' codec can't decode byte 0xac in position 25: invalid start byte
### Describe the bug
unicodedecodeerror: 'utf-8' codec can't decode byte 0xac in position 25: invalid start byte
### Steps to reproduce the bug
```
import sys
sys.getdefaultencoding()
'utf-8'
from datasets impor... |
https://github.com/huggingface/datasets/issues/4192 | load_dataset can't load local dataset,Unable to find ... | Hi! :)
I believe that should work unless `dataset_infos.json` isn't actually a dataset. For Hugging Face datasets, there is usually a file named `dataset_infos.json` which contains metadata about the dataset (eg. the dataset citation, license, description, etc). Can you double-check that `dataset_infos.json` isn't j... |
Traceback (most recent call last):
File "/home/gs603/ahf/pretrained/model.py", line 48, in <module>
dataset = load_dataset("json",data_files="dataset/dataset_infos.json")
File "/home/gs603/miniconda3/envs/coderepair/lib/python3.7/site-packages/datasets/load.py", line 1675, in load_dataset
**config_kwa... | 46 | load_dataset can't load local dataset,Unable to find ...
Traceback (most recent call last):
File "/home/gs603/ahf/pretrained/model.py", line 48, in <module>
dataset = load_dataset("json",data_files="dataset/dataset_infos.json")
File "/home/gs603/miniconda3/envs/coderepair/lib/python3.7/site-packages/datase... |
https://github.com/huggingface/datasets/issues/4192 | load_dataset can't load local dataset,Unable to find ... | Hi @ahf876828330,
As @stevhliu pointed out, the proper way to load a dataset is not trying to load its metadata file.
In your case, as the dataset script is local, you should better point to your local loading script:
```python
dataset = load_dataset("dataset/opus_books.py")
```
Please, feel free to re-ope... |
Traceback (most recent call last):
File "/home/gs603/ahf/pretrained/model.py", line 48, in <module>
dataset = load_dataset("json",data_files="dataset/dataset_infos.json")
File "/home/gs603/miniconda3/envs/coderepair/lib/python3.7/site-packages/datasets/load.py", line 1675, in load_dataset
**config_kwa... | 61 | load_dataset can't load local dataset,Unable to find ...
Traceback (most recent call last):
File "/home/gs603/ahf/pretrained/model.py", line 48, in <module>
dataset = load_dataset("json",data_files="dataset/dataset_infos.json")
File "/home/gs603/miniconda3/envs/coderepair/lib/python3.7/site-packages/datase... |
https://github.com/huggingface/datasets/issues/4192 | load_dataset can't load local dataset,Unable to find ... | > Hi! :)
>
> I believe that should work unless `dataset_infos.json` isn't actually a dataset. For Hugging Face datasets, there is usually a file named `dataset_infos.json` which contains metadata about the dataset (eg. the dataset citation, license, description, etc). Can you double-check that `dataset_infos.json` i... |
Traceback (most recent call last):
File "/home/gs603/ahf/pretrained/model.py", line 48, in <module>
dataset = load_dataset("json",data_files="dataset/dataset_infos.json")
File "/home/gs603/miniconda3/envs/coderepair/lib/python3.7/site-packages/datasets/load.py", line 1675, in load_dataset
**config_kwa... | 77 | load_dataset can't load local dataset,Unable to find ...
Traceback (most recent call last):
File "/home/gs603/ahf/pretrained/model.py", line 48, in <module>
dataset = load_dataset("json",data_files="dataset/dataset_infos.json")
File "/home/gs603/miniconda3/envs/coderepair/lib/python3.7/site-packages/datase... |
https://github.com/huggingface/datasets/issues/4192 | load_dataset can't load local dataset,Unable to find ... | The metadata file isn't a dataset so you can't turn it into one. You should try @albertvillanova's code snippet above (now merged in the docs [here](https://huggingface.co/docs/datasets/master/en/loading#local-loading-script)), which uses your local loading script `opus_books.py` to:
1. Download the actual dataset. ... |
Traceback (most recent call last):
File "/home/gs603/ahf/pretrained/model.py", line 48, in <module>
dataset = load_dataset("json",data_files="dataset/dataset_infos.json")
File "/home/gs603/miniconda3/envs/coderepair/lib/python3.7/site-packages/datasets/load.py", line 1675, in load_dataset
**config_kwa... | 51 | load_dataset can't load local dataset,Unable to find ...
Traceback (most recent call last):
File "/home/gs603/ahf/pretrained/model.py", line 48, in <module>
dataset = load_dataset("json",data_files="dataset/dataset_infos.json")
File "/home/gs603/miniconda3/envs/coderepair/lib/python3.7/site-packages/datase... |
https://github.com/huggingface/datasets/issues/7922 | Support Apache TsFile Datasets | A large quantity of industrial timeseries data has been stored as TsFile, and I have been constantly hearing about AI fellows complaining about the lack of data or the insufficiency of data quality.
I like the ambition that uses TsFile as the bridge between AI research and industrial analysis requirements. This may he... | ### Feature request
I would love to use Hugging Face datasets library to directly load datasets composed of .tsfile files, for example:
`ds = load_dataset("username/dataset-with-tsfile-files")`
This feature would allow researchers working on time-series tasks to seamlessly integrate datasets stored in the Apache TsF... | 65 | Support Apache TsFile Datasets
### Feature request
I would love to use Hugging Face datasets library to directly load datasets composed of .tsfile files, for example:
`ds = load_dataset("username/dataset-with-tsfile-files")`
This feature would allow researchers working on time-series tasks to seamlessly integrate da... |
https://github.com/huggingface/datasets/issues/7922 | Support Apache TsFile Datasets | It will be so convenient to have such a method to directly load tsfile into memory for further analysis. | ### Feature request
I would love to use Hugging Face datasets library to directly load datasets composed of .tsfile files, for example:
`ds = load_dataset("username/dataset-with-tsfile-files")`
This feature would allow researchers working on time-series tasks to seamlessly integrate datasets stored in the Apache TsF... | 19 | Support Apache TsFile Datasets
### Feature request
I would love to use Hugging Face datasets library to directly load datasets composed of .tsfile files, for example:
`ds = load_dataset("username/dataset-with-tsfile-files")`
This feature would allow researchers working on time-series tasks to seamlessly integrate da... |
https://github.com/huggingface/datasets/issues/7922 | Support Apache TsFile Datasets | Hey folks! I’ve added TsFile support by following the existing HDF5/Parquet patterns.
This includes:
A TsFile builder with schema inference from file metadata
Time-range filtering and column selection
Memory-efficient reading using the tsfile library’s iterator API
11 tests, all passing ✅
I’ll be opening a PR sho... | ### Feature request
I would love to use Hugging Face datasets library to directly load datasets composed of .tsfile files, for example:
`ds = load_dataset("username/dataset-with-tsfile-files")`
This feature would allow researchers working on time-series tasks to seamlessly integrate datasets stored in the Apache TsF... | 56 | Support Apache TsFile Datasets
### Feature request
I would love to use Hugging Face datasets library to directly load datasets composed of .tsfile files, for example:
`ds = load_dataset("username/dataset-with-tsfile-files")`
This feature would allow researchers working on time-series tasks to seamlessly integrate da... |
https://github.com/huggingface/datasets/issues/5086 | HTTPError: 404 Client Error: Not Found for url | Hi @km5ar, thanks for reporting.
This should be fixed in the notebook:
- the filename `datasets-issues-with-hf-doc-builder.jsonl` no longer exists on the repo; instead, current filename is `datasets-issues-with-comments.jsonl`
- see: https://huggingface.co/datasets/lewtun/github-issues/tree/main
Anyway, dependi... | ## Describe the bug
I was following chap 5 from huggingface course: https://huggingface.co/course/chapter5/6?fw=tf
However, I'm not able to download the datasets, with a 404 erros
<img width="1160" alt="iShot2022-10-06_15 54 50" src="https://user-images.githubusercontent.com/54015474/194406327-ae62c2f3-1da5-... | 178 | HTTPError: 404 Client Error: Not Found for url
## Describe the bug
I was following chap 5 from huggingface course: https://huggingface.co/course/chapter5/6?fw=tf
However, I'm not able to download the datasets, with a 404 erros
<img width="1160" alt="iShot2022-10-06_15 54 50" src="https://user-images.githubus... |
https://github.com/huggingface/datasets/issues/5086 | HTTPError: 404 Client Error: Not Found for url | Thanks for reporting @km5ar and thank you @albertvillanova for the quick solution! I'll post a fix on the source too | ## Describe the bug
I was following chap 5 from huggingface course: https://huggingface.co/course/chapter5/6?fw=tf
However, I'm not able to download the datasets, with a 404 erros
<img width="1160" alt="iShot2022-10-06_15 54 50" src="https://user-images.githubusercontent.com/54015474/194406327-ae62c2f3-1da5-... | 20 | HTTPError: 404 Client Error: Not Found for url
## Describe the bug
I was following chap 5 from huggingface course: https://huggingface.co/course/chapter5/6?fw=tf
However, I'm not able to download the datasets, with a 404 erros
<img width="1160" alt="iShot2022-10-06_15 54 50" src="https://user-images.githubus... |
https://github.com/huggingface/datasets/issues/4091 | Build a Dataset One Example at a Time Without Loading All Data Into Memory | Hi! Yes, the problem with `add_item` is that it keeps examples in memory, so you are left with these options:
* writing a dataset loading script in which you iterate over `custom_example_dict_streamer` and yield the examples (in `_generate examples`)
* storing the data in a JSON/CSV/Parquet/TXT file and using `Datase... | **Is your feature request related to a problem? Please describe.**
I have a very large dataset stored on disk in a custom format. I have some custom code that reads one data example at a time and yields it in the form of a dictionary. I want to construct a `Dataset` with all examples, and then save it to disk. I la... | 161 | Build a Dataset One Example at a Time Without Loading All Data Into Memory
**Is your feature request related to a problem? Please describe.**
I have a very large dataset stored on disk in a custom format. I have some custom code that reads one data example at a time and yields it in the form of a dictionary. I want ... |
https://github.com/huggingface/datasets/issues/4668 | Dataset Viewer issue for hungnm/multilingual-amazon-review-sentiment-processed | It seems like a private dataset. The viewer is currently not supported on the private datasets. | ### Link
https://huggingface.co/hungnm/multilingual-amazon-review-sentiment
### Description
_No response_
### Owner
Yes | 16 | Dataset Viewer issue for hungnm/multilingual-amazon-review-sentiment-processed
### Link
https://huggingface.co/hungnm/multilingual-amazon-review-sentiment
### Description
_No response_
### Owner
Yes
It seems like a private dataset. The viewer is currently not supported on the private datasets. |
https://github.com/huggingface/datasets/issues/5709 | Manually dataset info made not taken into account | hi @jplu ! Did I understand you correctly that you create the dataset, push it to the Hub with `.push_to_hub` and you see a `dataset_infos.json` file there, then you edit this file, load the dataset with `load_dataset` and you don't see any changes in `.info` attribute of a dataset object?
This is actually weird th... | ### Describe the bug
Hello,
I'm manually building an image dataset with the `from_dict` approach. I also build the features with the `cast_features` methods. Once the dataset is created I push it on the hub, and a default `dataset_infos.json` file seems to have been automatically added to the repo in same time. Hen... | 125 | Manually dataset info made not taken into account
### Describe the bug
Hello,
I'm manually building an image dataset with the `from_dict` approach. I also build the features with the `cast_features` methods. Once the dataset is created I push it on the hub, and a default `dataset_infos.json` file seems to have been... |
https://github.com/huggingface/datasets/issues/5709 | Manually dataset info made not taken into account | Hi @polinaeterna Yes I have created the dataset with `Dataset.from_dict` applied some updates afterward and when I pushed to the hub I had a `dataset_infos.json` file and there was a `README.md` file as well.
I didn't know that the JSON file was deprecated. So I have built my dataset with `ImageBuilder` instead and ... | ### Describe the bug
Hello,
I'm manually building an image dataset with the `from_dict` approach. I also build the features with the `cast_features` methods. Once the dataset is created I push it on the hub, and a default `dataset_infos.json` file seems to have been automatically added to the repo in same time. Hen... | 96 | Manually dataset info made not taken into account
### Describe the bug
Hello,
I'm manually building an image dataset with the `from_dict` approach. I also build the features with the `cast_features` methods. Once the dataset is created I push it on the hub, and a default `dataset_infos.json` file seems to have been... |
https://github.com/huggingface/datasets/issues/6393 | Filter occasionally hangs | Adding some more information, it seems to occur more frequently with large (millions of samples) datasets. | ### Describe the bug
A call to `.filter` occasionally hangs (after the filter is complete, according to tqdm)
There is a trace produced
```
Exception ignored in: <function Dataset.__del__ at 0x7efb48130c10>
Traceback (most recent call last):
File "/usr/lib/python3/dist-packages/datasets/arrow_dataset.py", l... | 16 | Filter occasionally hangs
### Describe the bug
A call to `.filter` occasionally hangs (after the filter is complete, according to tqdm)
There is a trace produced
```
Exception ignored in: <function Dataset.__del__ at 0x7efb48130c10>
Traceback (most recent call last):
File "/usr/lib/python3/dist-packages/dat... |
https://github.com/huggingface/datasets/issues/6393 | Filter occasionally hangs | More information. My code is structured as (1) load (2) map (3) filter (4) filter. It was always the second filter that failed. Combining the two filters into one seems to reliably work. | ### Describe the bug
A call to `.filter` occasionally hangs (after the filter is complete, according to tqdm)
There is a trace produced
```
Exception ignored in: <function Dataset.__del__ at 0x7efb48130c10>
Traceback (most recent call last):
File "/usr/lib/python3/dist-packages/datasets/arrow_dataset.py", l... | 33 | Filter occasionally hangs
### Describe the bug
A call to `.filter` occasionally hangs (after the filter is complete, according to tqdm)
There is a trace produced
```
Exception ignored in: <function Dataset.__del__ at 0x7efb48130c10>
Traceback (most recent call last):
File "/usr/lib/python3/dist-packages/dat... |
https://github.com/huggingface/datasets/issues/6393 | Filter occasionally hangs | @lhoestq it'd be great if someone had a chance to look at this. I suspect it is impacting many users given the other issue that I linked. | ### Describe the bug
A call to `.filter` occasionally hangs (after the filter is complete, according to tqdm)
There is a trace produced
```
Exception ignored in: <function Dataset.__del__ at 0x7efb48130c10>
Traceback (most recent call last):
File "/usr/lib/python3/dist-packages/datasets/arrow_dataset.py", l... | 27 | Filter occasionally hangs
### Describe the bug
A call to `.filter` occasionally hangs (after the filter is complete, according to tqdm)
There is a trace produced
```
Exception ignored in: <function Dataset.__del__ at 0x7efb48130c10>
Traceback (most recent call last):
File "/usr/lib/python3/dist-packages/dat... |
https://github.com/huggingface/datasets/issues/6393 | Filter occasionally hangs | Hi ! Sorry for the late response. Was it happening after the first or the second filter ?
It looks like an issue with the garbage collector (which makes it random). Maybe datasets created with `filter` are not always handled properly ? cc @mariosasko | ### Describe the bug
A call to `.filter` occasionally hangs (after the filter is complete, according to tqdm)
There is a trace produced
```
Exception ignored in: <function Dataset.__del__ at 0x7efb48130c10>
Traceback (most recent call last):
File "/usr/lib/python3/dist-packages/datasets/arrow_dataset.py", l... | 44 | Filter occasionally hangs
### Describe the bug
A call to `.filter` occasionally hangs (after the filter is complete, according to tqdm)
There is a trace produced
```
Exception ignored in: <function Dataset.__del__ at 0x7efb48130c10>
Traceback (most recent call last):
File "/usr/lib/python3/dist-packages/dat... |
https://github.com/huggingface/datasets/issues/6393 | Filter occasionally hangs | It was after the second filter (and combining the two filters into one seemingly resolved it). I obviously haven't tried all settings to know that these details are causal, but it did work for me. | ### Describe the bug
A call to `.filter` occasionally hangs (after the filter is complete, according to tqdm)
There is a trace produced
```
Exception ignored in: <function Dataset.__del__ at 0x7efb48130c10>
Traceback (most recent call last):
File "/usr/lib/python3/dist-packages/datasets/arrow_dataset.py", l... | 35 | Filter occasionally hangs
### Describe the bug
A call to `.filter` occasionally hangs (after the filter is complete, according to tqdm)
There is a trace produced
```
Exception ignored in: <function Dataset.__del__ at 0x7efb48130c10>
Traceback (most recent call last):
File "/usr/lib/python3/dist-packages/dat... |
https://github.com/huggingface/datasets/issues/6393 | Filter occasionally hangs | Thanks, that's good to know.
The stacktrace suggests an issue when `del self._indices` is called, which happens when a filtered dataset falls out of scope. The indices are a PyArrow table memory mapped from disk, so I'm not quite sure how calling `del` on it can cause this issue. We do `del self._indices` to make su... | ### Describe the bug
A call to `.filter` occasionally hangs (after the filter is complete, according to tqdm)
There is a trace produced
```
Exception ignored in: <function Dataset.__del__ at 0x7efb48130c10>
Traceback (most recent call last):
File "/usr/lib/python3/dist-packages/datasets/arrow_dataset.py", l... | 93 | Filter occasionally hangs
### Describe the bug
A call to `.filter` occasionally hangs (after the filter is complete, according to tqdm)
There is a trace produced
```
Exception ignored in: <function Dataset.__del__ at 0x7efb48130c10>
Traceback (most recent call last):
File "/usr/lib/python3/dist-packages/dat... |
https://github.com/huggingface/datasets/issues/6393 | Filter occasionally hangs | Yeah, I have a reliable repro, but it is not even close to minimal and uses a dataset I can't share. Perhaps you could try getting close to my setting.
(1) make a large (~20GB) jsonl with prompt/response pairs
(2) load it on a linux machine (`dataset = load_dataset(...)`)
(3) map a tokenizer to it, with multiproce... | ### Describe the bug
A call to `.filter` occasionally hangs (after the filter is complete, according to tqdm)
There is a trace produced
```
Exception ignored in: <function Dataset.__del__ at 0x7efb48130c10>
Traceback (most recent call last):
File "/usr/lib/python3/dist-packages/datasets/arrow_dataset.py", l... | 108 | Filter occasionally hangs
### Describe the bug
A call to `.filter` occasionally hangs (after the filter is complete, according to tqdm)
There is a trace produced
```
Exception ignored in: <function Dataset.__del__ at 0x7efb48130c10>
Traceback (most recent call last):
File "/usr/lib/python3/dist-packages/dat... |
https://github.com/huggingface/datasets/issues/6393 | Filter occasionally hangs | @lhoestq I have another version of the repro that seems fairly reliably. I have lots of jsonl files, and I iteratively load each one with `load_dataset('json', data_files='path/to/my/file.jsonl', streaming=False, split='train')` and then `dataset.map(..., num_proc=<int>)`. This iteration hangs in a random place each ti... | ### Describe the bug
A call to `.filter` occasionally hangs (after the filter is complete, according to tqdm)
There is a trace produced
```
Exception ignored in: <function Dataset.__del__ at 0x7efb48130c10>
Traceback (most recent call last):
File "/usr/lib/python3/dist-packages/datasets/arrow_dataset.py", l... | 54 | Filter occasionally hangs
### Describe the bug
A call to `.filter` occasionally hangs (after the filter is complete, according to tqdm)
There is a trace produced
```
Exception ignored in: <function Dataset.__del__ at 0x7efb48130c10>
Traceback (most recent call last):
File "/usr/lib/python3/dist-packages/dat... |
https://github.com/huggingface/datasets/issues/6393 | Filter occasionally hangs | I am also having similar issue to #3172 when trying to tokenize the data. My dataset contains 10M samples. Is there anything that could be done without having to split up the processing into multiple datasets? | ### Describe the bug
A call to `.filter` occasionally hangs (after the filter is complete, according to tqdm)
There is a trace produced
```
Exception ignored in: <function Dataset.__del__ at 0x7efb48130c10>
Traceback (most recent call last):
File "/usr/lib/python3/dist-packages/datasets/arrow_dataset.py", l... | 36 | Filter occasionally hangs
### Describe the bug
A call to `.filter` occasionally hangs (after the filter is complete, according to tqdm)
There is a trace produced
```
Exception ignored in: <function Dataset.__del__ at 0x7efb48130c10>
Traceback (most recent call last):
File "/usr/lib/python3/dist-packages/dat... |
https://github.com/huggingface/datasets/issues/6393 | Filter occasionally hangs | https://github.com/huggingface/datasets/pull/7411 seems to have fixed the issue for me, curious if it resolves others issues too. | ### Describe the bug
A call to `.filter` occasionally hangs (after the filter is complete, according to tqdm)
There is a trace produced
```
Exception ignored in: <function Dataset.__del__ at 0x7efb48130c10>
Traceback (most recent call last):
File "/usr/lib/python3/dist-packages/datasets/arrow_dataset.py", l... | 16 | Filter occasionally hangs
### Describe the bug
A call to `.filter` occasionally hangs (after the filter is complete, according to tqdm)
There is a trace produced
```
Exception ignored in: <function Dataset.__del__ at 0x7efb48130c10>
Traceback (most recent call last):
File "/usr/lib/python3/dist-packages/dat... |
https://github.com/huggingface/datasets/issues/7504 | BuilderConfig ParquetConfig(...) doesn't have a 'use_auth_token' key. | Hi ! `use_auth_token` has been deprecated and removed some time ago. You should use `token` instead in `load_dataset()` | ### Describe the bug
Trying to run the following fine-tuning script (based on this page [here](https://github.com/huggingface/instruction-tuned-sd)):
```
! accelerate launch /content/instruction-tuned-sd/finetune_instruct_pix2pix.py \
--pretrained_model_name_or_path=${MODEL_ID} \
--dataset_name=${DATASET_NAME... | 18 | BuilderConfig ParquetConfig(...) doesn't have a 'use_auth_token' key.
### Describe the bug
Trying to run the following fine-tuning script (based on this page [here](https://github.com/huggingface/instruction-tuned-sd)):
```
! accelerate launch /content/instruction-tuned-sd/finetune_instruct_pix2pix.py \
--pretrai... |
https://github.com/huggingface/datasets/issues/7504 | BuilderConfig ParquetConfig(...) doesn't have a 'use_auth_token' key. | Hi @lhoestq, I'd like to take this up.
As discussed in #7504, the issue arises when `use_auth_token` is passed to `load_dataset`, which forwards it to the config's `__init__`, where it's no longer a valid key.
To address this, I’ll intercept and strip `use_auth_token` inside `load_dataset()` (similar to how we handle... | ### Describe the bug
Trying to run the following fine-tuning script (based on this page [here](https://github.com/huggingface/instruction-tuned-sd)):
```
! accelerate launch /content/instruction-tuned-sd/finetune_instruct_pix2pix.py \
--pretrained_model_name_or_path=${MODEL_ID} \
--dataset_name=${DATASET_NAME... | 74 | BuilderConfig ParquetConfig(...) doesn't have a 'use_auth_token' key.
### Describe the bug
Trying to run the following fine-tuning script (based on this page [here](https://github.com/huggingface/instruction-tuned-sd)):
```
! accelerate launch /content/instruction-tuned-sd/finetune_instruct_pix2pix.py \
--pretrai... |
https://github.com/huggingface/datasets/issues/6108 | Loading local datasets got strangely stuck | Yesterday I waited for more than 12 hours to make sure it was really **stuck** instead of proceeding too slow. | ### Describe the bug
I try to use `load_dataset()` to load several local `.jsonl` files as a dataset. Every line of these files is a json structure only containing one key `text` (yeah it is a dataset for NLP model). The code snippet is as:
```python
ds = load_dataset("json", data_files=LIST_OF_FILE_PATHS, num_proc=... | 20 | Loading local datasets got strangely stuck
### Describe the bug
I try to use `load_dataset()` to load several local `.jsonl` files as a dataset. Every line of these files is a json structure only containing one key `text` (yeah it is a dataset for NLP model). The code snippet is as:
```python
ds = load_dataset("json... |
https://github.com/huggingface/datasets/issues/6108 | Loading local datasets got strangely stuck | I've had similar weird issues with `load_dataset` as well. Not multiple files, but dataset is quite big, about 50G. | ### Describe the bug
I try to use `load_dataset()` to load several local `.jsonl` files as a dataset. Every line of these files is a json structure only containing one key `text` (yeah it is a dataset for NLP model). The code snippet is as:
```python
ds = load_dataset("json", data_files=LIST_OF_FILE_PATHS, num_proc=... | 19 | Loading local datasets got strangely stuck
### Describe the bug
I try to use `load_dataset()` to load several local `.jsonl` files as a dataset. Every line of these files is a json structure only containing one key `text` (yeah it is a dataset for NLP model). The code snippet is as:
```python
ds = load_dataset("json... |
https://github.com/huggingface/datasets/issues/6108 | Loading local datasets got strangely stuck | We use a generic multiprocessing code, so there is little we can do about this - unfortunately, turning off multiprocessing seems to be the only solution. Multithreading would make our code easier to maintain and (most likely) avoid issues such as this one, but we cannot use it until the GIL is dropped (no-GIL Python s... | ### Describe the bug
I try to use `load_dataset()` to load several local `.jsonl` files as a dataset. Every line of these files is a json structure only containing one key `text` (yeah it is a dataset for NLP model). The code snippet is as:
```python
ds = load_dataset("json", data_files=LIST_OF_FILE_PATHS, num_proc=... | 67 | Loading local datasets got strangely stuck
### Describe the bug
I try to use `load_dataset()` to load several local `.jsonl` files as a dataset. Every line of these files is a json structure only containing one key `text` (yeah it is a dataset for NLP model). The code snippet is as:
```python
ds = load_dataset("json... |
https://github.com/huggingface/datasets/issues/6108 | Loading local datasets got strangely stuck | The problem seems to be the `Generating train split`. Is it possible to avoid that? I have a dataset saved, just want to load it but somehow running into issues with that again. | ### Describe the bug
I try to use `load_dataset()` to load several local `.jsonl` files as a dataset. Every line of these files is a json structure only containing one key `text` (yeah it is a dataset for NLP model). The code snippet is as:
```python
ds = load_dataset("json", data_files=LIST_OF_FILE_PATHS, num_proc=... | 33 | Loading local datasets got strangely stuck
### Describe the bug
I try to use `load_dataset()` to load several local `.jsonl` files as a dataset. Every line of these files is a json structure only containing one key `text` (yeah it is a dataset for NLP model). The code snippet is as:
```python
ds = load_dataset("json... |
https://github.com/huggingface/datasets/issues/6108 | Loading local datasets got strangely stuck | Hey guys, recently I ran into this problem again and I spent one whole day trying to locate the problem. Finally I found the problem seems to be with `pyarrow`'s json parser, and it seems a long-existing problem. Similar issue can be found in #2181. Anyway, my solution is to adjust the `load_dataset`'s parameter `chunk... | ### Describe the bug
I try to use `load_dataset()` to load several local `.jsonl` files as a dataset. Every line of these files is a json structure only containing one key `text` (yeah it is a dataset for NLP model). The code snippet is as:
```python
ds = load_dataset("json", data_files=LIST_OF_FILE_PATHS, num_proc=... | 128 | Loading local datasets got strangely stuck
### Describe the bug
I try to use `load_dataset()` to load several local `.jsonl` files as a dataset. Every line of these files is a json structure only containing one key `text` (yeah it is a dataset for NLP model). The code snippet is as:
```python
ds = load_dataset("json... |
https://github.com/huggingface/datasets/issues/6108 | Loading local datasets got strangely stuck | Experiencing the same issue with the `kaist-ai/Feedback-Collection` dataset, which is comparatively small i.e. 100k rows.
Code to reproduce
```
from datasets import load_dataset
dataset = load_dataset("kaist-ai/Feedback-Collection")
```
I have tried setting `num_proc=1` as well as `chunksize=1024, 64` but pro... | ### Describe the bug
I try to use `load_dataset()` to load several local `.jsonl` files as a dataset. Every line of these files is a json structure only containing one key `text` (yeah it is a dataset for NLP model). The code snippet is as:
```python
ds = load_dataset("json", data_files=LIST_OF_FILE_PATHS, num_proc=... | 42 | Loading local datasets got strangely stuck
### Describe the bug
I try to use `load_dataset()` to load several local `.jsonl` files as a dataset. Every line of these files is a json structure only containing one key `text` (yeah it is a dataset for NLP model). The code snippet is as:
```python
ds = load_dataset("json... |
https://github.com/huggingface/datasets/issues/6108 | Loading local datasets got strangely stuck | sorry to disturb, at datasets==2.21.0, I add `chunksize` parameter but got error "doesn't have a 'chunksize' key". Is it got removed? | ### Describe the bug
I try to use `load_dataset()` to load several local `.jsonl` files as a dataset. Every line of these files is a json structure only containing one key `text` (yeah it is a dataset for NLP model). The code snippet is as:
```python
ds = load_dataset("json", data_files=LIST_OF_FILE_PATHS, num_proc=... | 21 | Loading local datasets got strangely stuck
### Describe the bug
I try to use `load_dataset()` to load several local `.jsonl` files as a dataset. Every line of these files is a json structure only containing one key `text` (yeah it is a dataset for NLP model). The code snippet is as:
```python
ds = load_dataset("json... |
https://github.com/huggingface/datasets/issues/3480 | the compression format requested when saving a dataset in json format is not respected | Thanks for reporting @SaulLu.
At first sight I think the problem is caused because `pandas` only takes into account the `compression` parameter if called with a non-null file path or buffer. And in our implementation, we call pandas `to_json` with `None` `path_or_buf`.
We should fix this:
- either handling direc... | ## Describe the bug
In the documentation of the `to_json` method, it is stated in the parameters that
> **to_json_kwargs – Parameters to pass to pandas’s pandas.DataFrame.to_json.
however when we pass for example `compression="gzip"`, the saved file is not compressed.
Would you also have expected compression t... | 67 | the compression format requested when saving a dataset in json format is not respected
## Describe the bug
In the documentation of the `to_json` method, it is stated in the parameters that
> **to_json_kwargs – Parameters to pass to pandas’s pandas.DataFrame.to_json.
however when we pass for example `compression="... |
https://github.com/huggingface/datasets/issues/3480 | the compression format requested when saving a dataset in json format is not respected | I was thinking if we can handle the `compression` parameter by ourselves? Compression types will be similar to what `pandas` offer. Initially, we can try this with 2-3 compression types and see how good/bad it is? Let me know if it sounds good, I can raise a PR for this next week | ## Describe the bug
In the documentation of the `to_json` method, it is stated in the parameters that
> **to_json_kwargs – Parameters to pass to pandas’s pandas.DataFrame.to_json.
however when we pass for example `compression="gzip"`, the saved file is not compressed.
Would you also have expected compression t... | 52 | the compression format requested when saving a dataset in json format is not respected
## Describe the bug
In the documentation of the `to_json` method, it is stated in the parameters that
> **to_json_kwargs – Parameters to pass to pandas’s pandas.DataFrame.to_json.
however when we pass for example `compression="... |
https://github.com/huggingface/datasets/issues/3480 | the compression format requested when saving a dataset in json format is not respected | Hi ! Thanks for your help @bhavitvyamalik :)
Maybe let's start with `gzip` ? I think it's the most common use case, then if we're fine with it we can add other compression methods | ## Describe the bug
In the documentation of the `to_json` method, it is stated in the parameters that
> **to_json_kwargs – Parameters to pass to pandas’s pandas.DataFrame.to_json.
however when we pass for example `compression="gzip"`, the saved file is not compressed.
Would you also have expected compression t... | 34 | the compression format requested when saving a dataset in json format is not respected
## Describe the bug
In the documentation of the `to_json` method, it is stated in the parameters that
> **to_json_kwargs – Parameters to pass to pandas’s pandas.DataFrame.to_json.
however when we pass for example `compression="... |
https://github.com/huggingface/datasets/issues/3583 | Add The Medical Segmentation Decathlon Dataset | Hello! I have recently been involved with a medical image segmentation project myself and was going through the `The Medical Segmentation Decathlon Dataset` as well.
I haven't yet had experience adding datasets to this repository yet but would love to get started. Should I take this issue?
If yes, I've got two quest... | ## Adding a Dataset
- **Name:** *The Medical Segmentation Decathlon Dataset*
- **Description:** The underlying data set was designed to explore the axis of difficulties typically encountered when dealing with medical images, such as small data sets, unbalanced labels, multi-site data, and small objects.
- **Paper:*... | 107 | Add The Medical Segmentation Decathlon Dataset
## Adding a Dataset
- **Name:** *The Medical Segmentation Decathlon Dataset*
- **Description:** The underlying data set was designed to explore the axis of difficulties typically encountered when dealing with medical images, such as small data sets, unbalanced labels, mu... |
https://github.com/huggingface/datasets/issues/3583 | Add The Medical Segmentation Decathlon Dataset | Hi! Sure, feel free to take this issue. You can self-assign the issue by commenting `#self-assign`.
To answer your questions:
1. It makes the most sense to add each one as a separate config, so one dataset script with 10 configs in a single PR.
2. Just set masks in the test set to `None`.
Note that the images/m... | ## Adding a Dataset
- **Name:** *The Medical Segmentation Decathlon Dataset*
- **Description:** The underlying data set was designed to explore the axis of difficulties typically encountered when dealing with medical images, such as small data sets, unbalanced labels, multi-site data, and small objects.
- **Paper:*... | 111 | Add The Medical Segmentation Decathlon Dataset
## Adding a Dataset
- **Name:** *The Medical Segmentation Decathlon Dataset*
- **Description:** The underlying data set was designed to explore the axis of difficulties typically encountered when dealing with medical images, such as small data sets, unbalanced labels, mu... |
https://github.com/huggingface/datasets/issues/3583 | Add The Medical Segmentation Decathlon Dataset | > Note that the images/masks in this dataset are in NIfTI format, which our `Image` feature currently doesn't support, so I think it's best to yield the paths to the images/masks in the script and add a preprocessing section to the card where we explain how to load/process the images/masks with `nibabel` (I can help wi... | ## Adding a Dataset
- **Name:** *The Medical Segmentation Decathlon Dataset*
- **Description:** The underlying data set was designed to explore the axis of difficulties typically encountered when dealing with medical images, such as small data sets, unbalanced labels, multi-site data, and small objects.
- **Paper:*... | 74 | Add The Medical Segmentation Decathlon Dataset
## Adding a Dataset
- **Name:** *The Medical Segmentation Decathlon Dataset*
- **Description:** The underlying data set was designed to explore the axis of difficulties typically encountered when dealing with medical images, such as small data sets, unbalanced labels, mu... |
https://github.com/huggingface/datasets/issues/3583 | Add The Medical Segmentation Decathlon Dataset | This is great! There is a first model on the HUb that uses this dataset! https://huggingface.co/MONAI/example_spleen_segmentation | ## Adding a Dataset
- **Name:** *The Medical Segmentation Decathlon Dataset*
- **Description:** The underlying data set was designed to explore the axis of difficulties typically encountered when dealing with medical images, such as small data sets, unbalanced labels, multi-site data, and small objects.
- **Paper:*... | 16 | Add The Medical Segmentation Decathlon Dataset
## Adding a Dataset
- **Name:** *The Medical Segmentation Decathlon Dataset*
- **Description:** The underlying data set was designed to explore the axis of difficulties typically encountered when dealing with medical images, such as small data sets, unbalanced labels, mu... |
https://github.com/huggingface/datasets/issues/6559 | Latest version 2.16.1, when load dataset error occurs. ValueError: BuilderConfig 'allenai--c4' not found. Available: ['default'] | Hi ! The "allenai--c4" config doesn't exist (this naming schema comes from old versions of `datasets`)
You can load it this way instead:
```python
from datasets import load_dataset
cache_dir = 'path/to/your/cache/directory'
dataset = load_dataset('allenai/c4', data_files={'train': 'en/c4-train.00000-of-01024.j... | ### Describe the bug
python script is:
```
from datasets import load_dataset
cache_dir = 'path/to/your/cache/directory'
dataset = load_dataset('allenai/c4','allenai--c4', data_files={'train': 'en/c4-train.00000-of-01024.json.gz'}, split='train', use_auth_token=False, cache_dir=cache_dir)
```
the script su... | 39 | Latest version 2.16.1, when load dataset error occurs. ValueError: BuilderConfig 'allenai--c4' not found. Available: ['default']
### Describe the bug
python script is:
```
from datasets import load_dataset
cache_dir = 'path/to/your/cache/directory'
dataset = load_dataset('allenai/c4','allenai--c4', data_files={'... |
https://github.com/huggingface/datasets/issues/6559 | Latest version 2.16.1, when load dataset error occurs. ValueError: BuilderConfig 'allenai--c4' not found. Available: ['default'] | > Hi ! The "allenai--c4" config doesn't exist (this naming schema comes from old versions of `datasets`)
>
> You can load it this way instead:
>
> ```python
> from datasets import load_dataset
> cache_dir = 'path/to/your/cache/directory'
> dataset = load_dataset('allenai/c4', data_files={'train': 'en/c4-train.... | ### Describe the bug
python script is:
```
from datasets import load_dataset
cache_dir = 'path/to/your/cache/directory'
dataset = load_dataset('allenai/c4','allenai--c4', data_files={'train': 'en/c4-train.00000-of-01024.json.gz'}, split='train', use_auth_token=False, cache_dir=cache_dir)
```
the script su... | 57 | Latest version 2.16.1, when load dataset error occurs. ValueError: BuilderConfig 'allenai--c4' not found. Available: ['default']
### Describe the bug
python script is:
```
from datasets import load_dataset
cache_dir = 'path/to/your/cache/directory'
dataset = load_dataset('allenai/c4','allenai--c4', data_files={'... |
https://github.com/huggingface/datasets/issues/6559 | Latest version 2.16.1, when load dataset error occurs. ValueError: BuilderConfig 'allenai--c4' not found. Available: ['default'] | > Hi ! The "allenai--c4" config doesn't exist (this naming schema comes from old versions of `datasets`)
>
> You can load it this way instead:
>
> ```python
> from datasets import load_dataset
> cache_dir = 'path/to/your/cache/directory'
> dataset = load_dataset('allenai/c4', data_files={'train': 'en/c4-train.... | ### Describe the bug
python script is:
```
from datasets import load_dataset
cache_dir = 'path/to/your/cache/directory'
dataset = load_dataset('allenai/c4','allenai--c4', data_files={'train': 'en/c4-train.00000-of-01024.json.gz'}, split='train', use_auth_token=False, cache_dir=cache_dir)
```
the script su... | 66 | Latest version 2.16.1, when load dataset error occurs. ValueError: BuilderConfig 'allenai--c4' not found. Available: ['default']
### Describe the bug
python script is:
```
from datasets import load_dataset
cache_dir = 'path/to/your/cache/directory'
dataset = load_dataset('allenai/c4','allenai--c4', data_files={'... |
https://github.com/huggingface/datasets/issues/6559 | Latest version 2.16.1, when load dataset error occurs. ValueError: BuilderConfig 'allenai--c4' not found. Available: ['default'] | > It will only load the first file (`data_files={'train': 'en/c4-train.00000-of-01024.json.gz'}` only mentions one file)
Then what if we want to load the whole dataset? | ### Describe the bug
python script is:
```
from datasets import load_dataset
cache_dir = 'path/to/your/cache/directory'
dataset = load_dataset('allenai/c4','allenai--c4', data_files={'train': 'en/c4-train.00000-of-01024.json.gz'}, split='train', use_auth_token=False, cache_dir=cache_dir)
```
the script su... | 24 | Latest version 2.16.1, when load dataset error occurs. ValueError: BuilderConfig 'allenai--c4' not found. Available: ['default']
### Describe the bug
python script is:
```
from datasets import load_dataset
cache_dir = 'path/to/your/cache/directory'
dataset = load_dataset('allenai/c4','allenai--c4', data_files={'... |
https://github.com/huggingface/datasets/issues/6559 | Latest version 2.16.1, when load dataset error occurs. ValueError: BuilderConfig 'allenai--c4' not found. Available: ['default'] | There is a "en" subset that you can load (see the list in the "subset" dropdown at https://huggingface.co/datasets/allenai/c4)
```python
dataset = load_dataset('allenai/c4', 'en', split="train")
```
alternatively you can specify all the the files yourself using a glob pattern (or a list):
```python
dataset ... | ### Describe the bug
python script is:
```
from datasets import load_dataset
cache_dir = 'path/to/your/cache/directory'
dataset = load_dataset('allenai/c4','allenai--c4', data_files={'train': 'en/c4-train.00000-of-01024.json.gz'}, split='train', use_auth_token=False, cache_dir=cache_dir)
```
the script su... | 48 | Latest version 2.16.1, when load dataset error occurs. ValueError: BuilderConfig 'allenai--c4' not found. Available: ['default']
### Describe the bug
python script is:
```
from datasets import load_dataset
cache_dir = 'path/to/your/cache/directory'
dataset = load_dataset('allenai/c4','allenai--c4', data_files={'... |
https://github.com/huggingface/datasets/issues/6559 | Latest version 2.16.1, when load dataset error occurs. ValueError: BuilderConfig 'allenai--c4' not found. Available: ['default'] | > There is a "en" subset that you can load (see the list in the "subset" dropdown at https://huggingface.co/datasets/allenai/c4)
>
> ```python
> dataset = load_dataset('allenai/c4', 'en', split="train")
> ```
>
> alternatively you can specify all the the files yourself using a glob pattern (or a list):
>
> `... | ### Describe the bug
python script is:
```
from datasets import load_dataset
cache_dir = 'path/to/your/cache/directory'
dataset = load_dataset('allenai/c4','allenai--c4', data_files={'train': 'en/c4-train.00000-of-01024.json.gz'}, split='train', use_auth_token=False, cache_dir=cache_dir)
```
the script su... | 77 | Latest version 2.16.1, when load dataset error occurs. ValueError: BuilderConfig 'allenai--c4' not found. Available: ['default']
### Describe the bug
python script is:
```
from datasets import load_dataset
cache_dir = 'path/to/your/cache/directory'
dataset = load_dataset('allenai/c4','allenai--c4', data_files={'... |
https://github.com/huggingface/datasets/issues/6559 | Latest version 2.16.1, when load dataset error occurs. ValueError: BuilderConfig 'allenai--c4' not found. Available: ['default'] | The latest version of `datasets` seems to have broken my dataset for my users (see this Hugging Face issue: https://huggingface.co/datasets/umarbutler/open-australian-legal-corpus/discussions/3). I changed it by renaming my dataset's config to `default` instead of `train` and then updating my dataset card accordingly. | ### Describe the bug
python script is:
```
from datasets import load_dataset
cache_dir = 'path/to/your/cache/directory'
dataset = load_dataset('allenai/c4','allenai--c4', data_files={'train': 'en/c4-train.00000-of-01024.json.gz'}, split='train', use_auth_token=False, cache_dir=cache_dir)
```
the script su... | 40 | Latest version 2.16.1, when load dataset error occurs. ValueError: BuilderConfig 'allenai--c4' not found. Available: ['default']
### Describe the bug
python script is:
```
from datasets import load_dataset
cache_dir = 'path/to/your/cache/directory'
dataset = load_dataset('allenai/c4','allenai--c4', data_files={'... |
https://github.com/huggingface/datasets/issues/4358 | Missing dataset tags and sections in some dataset cards | @lhoestq I can take this issue. Please can you point out to me where I can find the other positional arguments? | Summary of CircleCI errors for different dataset metadata:
- **BoolQ**: missing 8 required positional arguments: 'annotations_creators', 'language_creators', 'licenses', 'multilinguality', 'size_categories', 'source_datasets', 'task_categories', and 'task_ids'
- **Conllpp**: expected some content in section `Citati... | 21 | Missing dataset tags and sections in some dataset cards
Summary of CircleCI errors for different dataset metadata:
- **BoolQ**: missing 8 required positional arguments: 'annotations_creators', 'language_creators', 'licenses', 'multilinguality', 'size_categories', 'source_datasets', 'task_categories', and 'task_ids'
... |
Subsets and Splits
No community queries yet
The top public SQL queries from the community will appear here once available.