
id stringlengths 36 36 | url stringclasses 504
values | title stringclasses 475
values | section stringlengths 0 148 | content_type stringclasses 3
values | has_code bool 2
classes | text stringlengths 147 22.5k | vector listlengths 384 384 |
|---|---|---|---|---|---|---|---|
8fadf09f-e312-5ca8-bec5-3bc9836ff911 | /course/multi-vector-search/certification/ | Qdrant Multi-Vector Certification | course | false | Qdrant Multi-Vector Certification
Congratulations! You’ve completed the **Multi-Vector Search course**. You didn’t just learn how to store vectors; you learned how to build high-performance retrieval systems using late interaction models and multi-vector representations.
You’ve moved past single-vector embeddings and... | [
0.04118949919939041,
-0.03983528912067413,
-0.027295725420117378,
-0.045457884669303894,
0.05977548286318779,
-0.04708918184041977,
0.07228295505046844,
0.05098919942975044,
0.056403446942567825,
-0.0235024131834507,
0.01340813934803009,
0.031875599175691605,
0.050196997821331024,
-0.04679... | |
8fbefc3c-0d3b-5f2a-8793-dfb03f976703 | /documentation/tutorials-search-engineering/multi-representation-search/ | Multi-Representation Search | Retrieval > Which Fusion to Use | documentation | true | Multi-Representation Search > Retrieval > Which Fusion to Use
[Reciprocal Rank Fusion](/documentation/search/hybrid-queries/#reciprocal-rank-fusion-rrf) combines prefetches using document rank rather than raw scores, avoiding issues caused by dense and sparse scores operating on different scales. It’s the default conf... | [
0.023680124431848526,
-0.02676437795162201,
-0.06463688611984253,
-0.06374074518680573,
0.0784175917506218,
-0.023512011393904686,
0.042070962488651276,
0.022106006741523743,
0.06344940513372421,
-0.02236177958548069,
0.01610041968524456,
-0.010909336619079113,
0.04804923012852669,
0.01563... |
8fe10a56-92fa-5c54-b8d3-6921c102fb36 | /documentation/tutorials-build-essentials/video-anomaly-edge-part-2/ | Video Anomaly Detection Part 2: Edge-to-Cloud Pipeline | Edge-to-Cloud Escalation > Storing Clips Locally | documentation | true | Video Anomaly Detection Part 2: Edge-to-Cloud Pipeline > Edge-to-Cloud Escalation > Storing Clips Locally
When the edge processes a clip, it stores the embedding in the mutable shard and queues it for cloud sync:
```python
def store_clip(
self, embedding: np.ndarray, metadata: dict | None = None, anomaly_score: f... | [
0.040824469178915024,
-0.030896181240677834,
-0.059636395424604416,
-0.054325222969055176,
0.05311444029211998,
-0.02378990687429905,
0.07699953019618988,
0.018734566867351532,
0.07138875126838684,
-0.02223721519112587,
0.022677559405565262,
0.017092730849981308,
0.042305149137973785,
-0.0... |
8fea1111-9fc2-54e0-b1c0-56640788004e | /documentation/migrate-to-qdrant/from-pinecone/ | From Pinecone | Gotchas | documentation | false | From Pinecone > Gotchas
- **Namespaces:** Each run migrates one namespace, the default one unless you set `--pinecone.namespace`. Point IDs do not include the namespace, so migrate namespaces with overlapping IDs into separate collections.
## Next Steps
After migration, verify your data arrived correctly with the [M... | [
0.03566032648086548,
-0.0652979239821434,
-0.015430307015776634,
-0.013580595143139362,
0.040539711713790894,
-0.03562038764357567,
0.030912045389413834,
0.050242625176906586,
0.04450427368283272,
0.005772182252258062,
0.0030473603401333094,
-0.0028388197533786297,
0.03552253171801567,
0.0... |
8feb6bf4-9f59-5217-8b22-55ebb662939a | /documentation/hybrid-cloud/hybrid-cloud-cluster-creation/ | Create a Cluster | Exposing Qdrant clusters to your client applications | documentation | true | Create a Cluster > Exposing Qdrant clusters to your client applications
You can expose your Qdrant clusters to your client applications using Kubernetes services and ingresses. By default, a `ClusterIP` service is created for each Qdrant cluster.
Within your Kubernetes cluster, you can access the Qdrant cluster using... | [
0.0374193899333477,
-0.03938776254653931,
-0.0617733858525753,
-0.04236424341797829,
0.04258783161640167,
-0.06516992300748825,
0.06247073784470558,
0.07642896473407745,
0.05179286748170853,
-0.038062985986471176,
0.03543344885110855,
0.015408766455948353,
0.016182897612452507,
-0.04451043... |
8ff097da-4c7f-51ce-a988-6f1b8d558c0d | /documentation/manage-data/payload/ | Payload | Payload types > Integer | documentation | true | Payload > Payload types > Integer
`integer` - 64-bit integer in the range from `-9223372036854775808` to `9223372036854775807`.
Example of single and multiple `integer` values:
```json
{
"count": 10,
"sizes": [35, 36, 38]
}
``` | [
0.008957728743553162,
0.012166311033070087,
-0.04349338263273239,
-0.057918429374694824,
0.08042401075363159,
-0.03117084503173828,
-0.03164678439497948,
0.07982787489891052,
0.09636937826871872,
-0.03863426670432091,
-0.012174383737146854,
0.008421794511377811,
0.021313372999429703,
-0.02... |
8ff1a844-d648-5b76-a40b-cc89f11ca2e6 | /documentation/fastembed/fastembed-optimize/ | Optimize Throughput | Parallelize Standalone FastEmbed | documentation | true | Optimize Throughput > Parallelize Standalone FastEmbed
When using FastEmbed as a standalone library, first enable lazy loading of the embedding model:
```python
model = TextEmbedding(
model_name="BAAI/bge-small-en-v1.5",
lazy_load=True, # don't load the model until first embed call
)
```
FastEmbed supp... | [
0.04279144108295441,
-0.02998156100511551,
-0.03985141962766647,
-0.016069041565060616,
0.09219422936439514,
-0.01969985105097294,
0.057226963341236115,
0.03810800984501839,
0.030194031074643135,
-0.006287406664341688,
0.011180118657648563,
0.02246677316725254,
0.035418618470430374,
-0.035... |
8ffbc344-1a4b-5004-812a-a934100924d1 | /documentation/tutorials-search-engineering/branch-aware-search/ | Branch-Aware Search | documentation | false | Branch-Aware Search
| Time: 25 min | Level: Intermediate |
| --- | ----------- |
When a document corpus is versioned with git-style branches, an ordinary search leaks across them, returning content from another branch or a version the current branch already replaced. This tutorial indexes such a corpus in Qdrant and ... | [
0.0464443638920784,
-0.09152860194444656,
-0.05493709444999695,
-0.026709824800491333,
0.0946602150797844,
-0.023152904585003853,
0.03842196986079216,
0.02490711770951748,
0.06605221331119537,
-0.02210184745490551,
0.02121339738368988,
0.03307953104376793,
0.06250680983066559,
-0.046369787... | |
900f4f5a-9786-5df5-b216-8ed00942f7b2 | /documentation/ops-monitoring/memory-usage/ | Memory Usage | Web UI | documentation | false | Memory Usage > Web UI
Open the collection detail page and select the **Memory** tab. It shows the memory breakdown for the collection, updated on demand.
The Memory tab shows the breakdown of disk, RAM, and cached usage for each component of the collection. | [
0.037549491971731186,
-0.030146904289722443,
-0.015245473012328148,
-0.07679469883441925,
0.046910934150218964,
0.00035661569563671947,
0.010191980749368668,
0.04816403612494469,
0.0932440385222435,
-0.037512026727199554,
0.004023348912596703,
0.03171444311738014,
0.08642572164535522,
-0.0... |
90203e3a-e44d-5ce3-8650-d53041c2722a | /documentation/search-patterns/choose-embedding-model/ | How to Choose an Embedding Model: Evaluation & Tradeoffs | Evaluation: The Holy Grail of Vector Search > Know the Language Your Model Speaks | documentation | false | How to Choose an Embedding Model: Evaluation & Tradeoffs > Evaluation: The Holy Grail of Vector Search > Know the Language Your Model Speaks
One of the effects of such inner workings is that the model can only understand what its tokenizer was trained on ([yes, tokenizers are also trainable components](https://hugging... | [
0.059384625405073166,
-0.008234110660851002,
-0.025440528988838196,
-0.06062789633870125,
0.08759357780218124,
-0.010211208835244179,
0.03342781960964203,
0.038762107491493225,
0.030170900747179985,
-0.02132372558116913,
0.026546703651547432,
0.00007878084579715505,
0.04890669882297516,
-0... |
9020d6e0-02bd-5ee0-aad5-6e9f91471c15 | /documentation/tutorials-search-engineering/ann-recall/ | Measuring ANN Recall | Tuning Search Recall | documentation | false | Measuring ANN Recall > Tuning Search Recall
Toggle **advanced mode** in the ANN Recall tab to tune search-time parameters inline. The main one is `hnsw_ef`: the number of candidates evaluated during a search. Raising it explores more of the graph, improving recall at the cost of higher query latency. To see the effect... | [
0.02719378098845482,
-0.07395393401384354,
-0.04146646335721016,
-0.05588391795754433,
0.05362505465745926,
-0.018311602994799614,
0.034396734088659286,
0.061525966972112656,
0.08885160833597183,
-0.034265175461769104,
0.03196600079536438,
0.02127521112561226,
0.06793638318777084,
-0.03176... |
902d702c-6bee-56d3-9baf-0b1f6faf5f82 | /documentation/production-operations/access-control/ | Data Privacy with Qdrant's Role-Based Access Control (RBAC) | How Qdrant Handles Data Privacy and Security > Database API Keys > JWT on Qdrant | documentation | true | Data Privacy with Qdrant's Role-Based Access Control (RBAC) > How Qdrant Handles Data Privacy and Security > Database API Keys > JWT on Qdrant
Below is an example of how to do so using QdrantClient in Python:
```python
from qdrant_client import QdrantClient
qdrant_client = QdrantClient(
"http://localhost:6333",
... | [
0.0192684605717659,
-0.022148363292217255,
-0.03833071142435074,
-0.03127589821815491,
0.032847050577402115,
-0.03274131938815117,
0.05988980829715729,
0.038250282406806946,
0.06778659671545029,
-0.019665025174617767,
0.02486507222056389,
0.048155490309000015,
0.10487981885671616,
-0.02240... |
9046c0c8-a133-5f70-ab5e-f7f97fc7888e | /documentation/cloud-quickstart/ | Cloud Quickstart | 4. Create our collection | documentation | true | Cloud Quickstart > 4. Create our collection
We will use some sample menu items to demonstrate how to create a collection and add data to it. Each menu item has a name, description, price, and category. First, we need to create a collection in Qdrant to store our menu items.
```python
# create collection
client.create... | [
0.011370421387255192,
-0.0067985160276293755,
-0.028844866901636124,
-0.05199284479022026,
0.06205247342586517,
-0.06005728244781494,
0.04334449768066406,
0.061731744557619095,
0.10320509970188141,
-0.019891323521733284,
0.05142585560679436,
0.06049700826406479,
0.08284101635217667,
-0.041... |
904bbdcf-bf85-570d-ae9c-d6d3f5be4e63 | /documentation/embeddings/superlinked/ | Superlinked | Models | documentation | false | Superlinked > Models
The [Model Catalog](https://superlinked.com/models) lists every model SIE serves and the output types each one supports. These cover the examples on this page:
| Model | Output | Dimensions | Max Tokens |
|---|---|---|---|
| `BAAI/bge-m3` (the default) | Dense, sparse, multivector | 1024 | 8,192 ... | [
0.03780115768313408,
-0.001644217874854803,
-0.029669860377907753,
-0.05355172976851463,
0.05263718217611313,
-0.03830576688051224,
0.05248045176267624,
0.0741695687174797,
0.05218472331762314,
-0.08561026304960251,
0.05644598230719566,
0.014672523364424706,
0.043707575649023056,
-0.015189... |
9050349e-3b44-5367-8f83-6dc90133f6b3 | /documentation/tutorials-search-engineering/sparse-embeddings-ecommerce-part-2/ | Fine-Tuning Sparse Embeddings for E-Commerce Search | Part 2: Training SPLADE on Modal | The Training Function | documentation | true | Fine-Tuning Sparse Embeddings for E-Commerce Search | Part 2: Training SPLADE on Modal > The Training Function
Here's the core training logic, decorated as a Modal function:
```python
@app.function(
image=image,
gpu="A100",
volumes={
"/checkpoints": checkpoint_volume,
"/datasets": dataset_... | [
0.04733840003609657,
-0.049369122833013535,
-0.031017793342471123,
-0.05259808897972107,
0.015394635498523712,
-0.020582543686032295,
0.06499409675598145,
0.054482217878103256,
0.0721590518951416,
0.009457574225962162,
0.0047720568254590034,
-0.0008691488183103502,
0.05321378633379936,
-0.... |
9054a1cc-f9ce-5cdf-a028-7a80df204ecc | /documentation/search-patterns/choose-embedding-model/ | How to Choose an Embedding Model: Evaluation & Tradeoffs | Hosting Your Embedding Model | documentation | false | How to Choose an Embedding Model: Evaluation & Tradeoffs > Hosting Your Embedding Model
Where the model runs affects latency and cost. Sending millions of documents to a model hosted far from your cluster adds network latency, and some cloud providers charge for the data transfer. Running a model near your application... | [
0.04132234305143356,
-0.019017567858099937,
-0.02002672478556633,
-0.06004142388701439,
0.051062364131212234,
-0.02763674221932888,
0.11159434914588928,
0.05821467936038971,
0.05962620675563812,
-0.022191528230905533,
0.010352049954235554,
-0.0018701188964769244,
0.04563723877072334,
-0.03... |
906790bc-b88e-5f43-bd7f-5d7a4e022edf | /documentation/manage-data/indexing/ | Indexing | Vector Index > The ACORN Search Algorithm | documentation | false | Indexing > Vector Index > The ACORN Search Algorithm
*Available as of v1.16.0*
In some cases, the additional edges built for Qdrant's filterable HNSW may not be sufficient.
These extra edges are added for each payload index separately, but not for every possible combination of payload indices.
As a result, a combinat... | [
0.03759896382689476,
-0.09641832113265991,
-0.051393069326877594,
0.005516656208783388,
0.10829497128725052,
-0.002602457534521818,
0.045797061175107956,
0.0008300112094730139,
0.06250321865081787,
0.013634361326694489,
0.07183025777339935,
0.018006445840001106,
0.026907872408628464,
-0.00... |
9082c217-3f89-51f2-a0e4-abb77eb21f0d | /documentation/tutorials-develop/search-as-you-type/ | Semantic Search As You Type | Step 3: Build the Prefix Cache | documentation | true | Semantic Search As You Type > Step 3: Build the Prefix Cache
Even with a small model, embedding takes time. As in any optimization, if you cannot do the work faster, avoid doing it. Precompute embeddings for common short prefixes, and store them in `prefix_cache`. Then a recommend query can find the best matches witho... | [
0.06418702751398087,
-0.04446917772293091,
-0.03834148123860359,
0.00584669504314661,
0.07155226171016693,
-0.05917989835143089,
0.024344932287931442,
0.04638533294200897,
0.05961662530899048,
-0.013991679064929485,
0.03439701721072197,
0.02806856669485569,
0.025164276361465454,
-0.0527782... |
908b169a-b35f-5163-851f-aedd0ca6cbec | /documentation/data-management/poma/ | POMA | Overview | documentation | false | POMA > Overview
- **POMA**, as *document chunking engine*, is built around simplicity for operators: process files into structure-aware chunksets and send them to Qdrant with minimal boilerplate and a patented chunking approach.
- **Qdrant** as your preferred *vector search engine*.
Together, they combine individual... | [
0.025047598406672478,
-0.07208152860403061,
-0.04599970579147339,
-0.05228909105062485,
0.07273788005113602,
-0.01786128804087639,
0.05917637050151825,
0.01617613062262535,
0.07360341399908066,
-0.007826494984328747,
0.01527785137295723,
-0.03824317082762718,
0.037493996322155,
-0.03221526... |
908e721b-656c-5999-a0f0-aebbd29eaedc | /articles/neural-search-tutorial/ | Neural Search 101: A Complete Guide and Step-by-Step Tutorial | article | false | Neural Search 101: A Complete Guide and Step-by-Step Tutorial
Information retrieval technology is one of the main technologies that enabled the modern Internet to exist.
These days, search technology is the heart of a variety of applications.
From web-pages search to product recommendations.
For many years, this techn... | [
-0.02783866412937641,
-0.060223788022994995,
-0.07023852318525314,
-0.03291051834821701,
0.042205389589071274,
-0.039993125945329666,
0.047546934336423874,
0.07393775135278702,
0.09121306240558624,
-0.030743900686502457,
0.0367894247174263,
0.04474002867937088,
0.04534405469894409,
-0.0435... | |
909136ad-0589-5674-a3e4-37e8623c3a2c | /documentation/embeddings/nvidia/ | NVIDIA | Models | documentation | false | NVIDIA > Models
| Model | Dimensions | Max Tokens per Input | Input |
|---|---|---|---|
| `nvidia/nemotron-3-embed-1b` | 2048 | 4096 | Text |
| `nvidia/llama-nemotron-embed-vl-1b-v2` | 2048 | 2048 | Text queries, image or text documents |
The API also serves older models, such as `nvidia/embed-qa-4` and `nvidia/llama... | [
0.022427285090088844,
-0.01946161314845085,
-0.015219733119010925,
-0.05338452383875847,
0.09696292877197266,
-0.027170319110155106,
0.035457853227853775,
0.029922394081950188,
0.06655468791723251,
-0.06258176267147064,
0.026802917942404747,
0.008490483276546001,
0.03493380546569824,
-0.02... |
909a308d-3802-50f6-bbf4-5cca72e5cac3 | /documentation/inference/external-inference-providers/ | External Providers | Cohere | documentation | true | External Providers > Cohere
Qdrant only supports version 2 of the Cohere Embed API.
When you prepend a model name with `cohere/`, the embedding request is automatically routed to the [Cohere Embed API](https://docs.cohere.com/reference/embed).
For example, to use Cohere's multimodal `embed-v4.0` model when ingesting... | [
0.05434735119342804,
-0.022044328972697258,
-0.017367960885167122,
-0.04535035789012909,
0.060980603098869324,
-0.03908567130565643,
0.0805443599820137,
0.07484021037817001,
0.05376244708895683,
-0.020238131284713745,
0.012345409952104092,
0.02005310170352459,
0.038929086178541183,
-0.0428... |
90aa1dca-ad54-50fc-b1f8-e6ea58472532 | /documentation/tutorials-search-engineering/sparse-embeddings-ecommerce-part-3/ | Fine-Tuning Sparse Embeddings for E-Commerce Search | Part 3: Evaluation and Hard Negatives | The Results | documentation | false | Fine-Tuning Sparse Embeddings for E-Commerce Search | Part 3: Evaluation and Hard Negatives > The Results
Here's what we found, evaluated on 2,000 test queries:
| Model | nDCG@10 | MRR@10 | vs BM25 (relative) |
|---|---|---|---|
| BM25 (baseline) | 0.333 | 0.332 | - |
| SPLADE (off-the-shelf) | 0.362 | 0.361 | +8.7% ... | [
0.039403144270181656,
-0.024442926049232483,
-0.057925064116716385,
-0.04069988802075386,
0.04643091559410095,
-0.02671760320663452,
0.06589656323194504,
0.013997632078826427,
0.08503837138414383,
-0.013397329486906528,
0.027528073638677597,
0.003651514882221818,
0.06721032410860062,
-0.02... |
90c21391-b0c5-544d-ac8e-174afe1ee501 | /documentation/search-tuning/candidate-depth/ | Candidate Depth: How Much Retrieval Is Enough? | Raise hnsw_ef Only When Recall Is Still Climbing | documentation | true | Candidate Depth: How Much Retrieval Is Enough? > Raise hnsw_ef Only When Recall Is Still Climbing
For dense vectors, `limit` decides how many candidates the dense stage returns, and `hnsw_ef` decides how wide the HNSW graph traversal searches for them, trading approximate-search recall for latency. Measure `limit` aga... | [
0.015745026990771294,
-0.05761085823178291,
-0.037147559225559235,
-0.03779308497905731,
0.036085277795791626,
-0.021084994077682495,
0.03566291555762291,
0.052563898265361786,
0.09039488434791565,
-0.038265448063611984,
0.010981856845319271,
0.013380398973822594,
0.04610537737607956,
-0.0... |
90d454fa-f3f7-5a6d-9409-b932301abffc | /documentation/snapshots/ | Snapshots | Create snapshot | documentation | true | Snapshots > Create snapshot
If you work with a distributed deployment, you have to create snapshots for each node separately. A single snapshot will contain only the data stored on the node on which the snapshot was created.
To create a new snapshot for an existing collection:
```python
from qdrant_client import Qdr... | [
-0.013430587947368622,
-0.03779067471623421,
-0.043572798371315,
-0.042085930705070496,
0.032520841807127,
-0.00921779777854681,
0.0307515449821949,
0.02638090029358864,
0.06326588243246078,
-0.05846622586250305,
0.050327807664871216,
0.06295778602361679,
0.063047856092453,
-0.008447042666... |
90d5c9ec-3a39-5feb-9640-54a709db7680 | /articles/search-feedback-loop/ | Relevance Feedback in Information Retrieval | Query Refinement > Query As Vector | article | false | Relevance Feedback in Information Retrieval > Query Refinement > Query As Vector
Instead of modifying the initial query, a more scalable approach is to directly adjust the query vector.
It is easily applicable across modalities and suitable for both lexical and neural retrieval.
Although vector search has become a t... | [
0.028473127633333206,
-0.0570366270840168,
-0.043199628591537476,
-0.04277931526303291,
0.04957360774278641,
-0.03938733786344528,
0.03531522676348686,
0.04312289506196976,
0.09748837351799011,
-0.011188997887074947,
0.015596785582602024,
0.0390675812959671,
0.07497543841600418,
-0.0293955... |
90df4f03-7c46-5ff4-9198-980d4d0c902a | /articles/modern-sparse-neural-retrieval/ | Modern Sparse Neural Retrieval: From DeepCT to SPLADE++ | Sparse Neural Retrieval Evolution > Sparse Neural Retriever Which Understood Homonyms | article | false | Modern Sparse Neural Retrieval: From DeepCT to SPLADE++ > Sparse Neural Retrieval Evolution > Sparse Neural Retriever Which Understood Homonyms
If one value for the term importance score is insufficient, we could describe the term’s importance in a vector form!
Authors of the [`COntextualized Inverted List (COIL)`](h... | [
0.0517556257545948,
-0.04991820082068443,
-0.038268834352493286,
-0.025540322065353394,
0.03422430902719498,
-0.05088503658771515,
0.06303148716688156,
0.008778299205005169,
0.08699629455804825,
-0.02828778326511383,
0.0042423526756465435,
0.04562925174832344,
0.061692699790000916,
-0.0097... |
90e2e4f1-787b-5fae-9ec9-f81b1315bf67 | /course/essentials/day-1/chunking-strategies/ | Text Chunking Strategies | Performance Considerations | course | false | Text Chunking Strategies > Performance Considerations
### Token Efficiency
Consider your embedding model's token limits:
- OpenAI text-embedding-3-small: 8,191 tokens max
- Sentence Transformers: Varies greatly by model. Many classic models (e.g., `all-MiniLM-L6-v2`) have a maximum length of 512 tokens, but newer mod... | [
0.002379621844738722,
-0.03395198658108711,
-0.030659252777695656,
-0.05895272642374039,
0.04549895599484444,
-0.025115780532360077,
0.030709924176335335,
0.026141926646232605,
0.07304445654153824,
-0.05786530673503876,
0.022149892523884773,
-0.006955624558031559,
0.052519526332616806,
-0.... |
90e74369-9428-51a0-be9a-d112a6d53165 | /course/essentials/day-2/what-is-hnsw/ | HNSW Indexing Fundamentals | Choosing Settings | course | false | HNSW Indexing Fundamentals > Choosing Settings
### Optimizing for Different Workloads
- **High-speed retrieval:** lower `m` and `hnsw_ef`; set `ef_construct` just high enough for acceptable recall.
- **Maximum recall:** raise `m`, `hnsw_ef`, and `ef_construct` and accept slower queries and builds.
- **Tight RAM:** re... | [
0.026726920157670975,
-0.044247400015592575,
-0.04498639702796936,
-0.0387004092335701,
0.022763289511203766,
-0.04606257751584053,
0.026328202337026596,
0.022991856560111046,
0.08003842830657959,
-0.054206691682338715,
0.007170662749558687,
0.03461276739835739,
0.03881610184907913,
-0.026... |
90f5793a-9e28-531a-a80e-7e0f27d1d4e3 | /documentation/fastembed/fastembed-postprocessing/ | Multi-Vector Postprocessing | Using MUVERA in FastEmbed > Conclusion | documentation | false | Multi-Vector Postprocessing > Using MUVERA in FastEmbed > Conclusion
MUVERA postprocessing enables practical large-scale multi-vector search by creating fast-to-search approximations of
multi-vector embeddings. The recommended approach combines MUVERA with Qdrant's native multi-stage query capabilities:
1. **Fast re... | [
0.05596724897623062,
-0.050746895372867584,
-0.01995972730219364,
-0.06581545621156693,
0.07119275629520416,
-0.04140282794833183,
0.054097454994916916,
-0.01370640005916357,
0.07793953269720078,
0.00369061715900898,
-0.0022425709757953882,
0.035484883934259415,
0.03513452410697937,
-0.036... |
9101204c-fa30-537c-b074-ab87c197e374 | /articles/what-is-a-vector-database/ | What is a Vector Database? | The Architecture of a Vector Database > Distance Metrics | article | false | What is a Vector Database? > The Architecture of a Vector Database > Distance Metrics
These metrics define how similarity between vectors is calculated. The choice of distance metric is made when creating a collection and the right choice depends on the type of data you’re working with and how the vectors were created... | [
0.0006619688356295228,
-0.019400019198656082,
-0.0712670385837555,
-0.029824230819940567,
0.06041697785258293,
-0.025650912895798683,
0.05695214867591858,
0.03989427536725998,
0.09944897890090942,
-0.04508562386035919,
0.03982379287481308,
-0.0011951845372095704,
0.03663625568151474,
0.029... |
91121171-00db-559c-9e34-bc65923a040b | /documentation/tutorials-search-engineering/using-multivector-representations/ | Multivectors and Late Interaction | How to Generate Multivectors Using FastEmbed | documentation | true | Multivectors and Late Interaction > How to Generate Multivectors Using FastEmbed
Let's demonstrate how to effectively use multivectors using [FastEmbed](https://github.com/qdrant/fastembed), which wraps ColBERT into a simple API.
Install FastEmbed and Qdrant:
```bash
pip install "qdrant-client[fastembed]>=1.14.2"
``... | [
0.02301422506570816,
-0.0015604221262037754,
-0.030892692506313324,
-0.0501442477107048,
0.07524219155311584,
-0.03817816078662872,
0.0834929496049881,
0.03982271999120712,
0.030100718140602112,
-0.0052357823587954044,
0.034985680133104324,
0.01802126131951809,
0.04003624618053436,
-0.0372... |
9157936c-d5ad-5088-9351-c81571c161eb | /documentation/private-cloud/api-reference/ | API Reference | qdrant.io/v1 > Resource Types > RebalanceStrategy | documentation | false | API Reference > qdrant.io/v1 > Resource Types > RebalanceStrategy
_Underlying type:_ _string_
RebalanceStrategy specifies the strategy to use for automatically rebalancing shards the cluster.
_Validation:_
- Enum: [by_count by_size by_count_and_size disabled]
_Appears in:_
- [QdrantClusterSpec](#qdrantclusterspec)
... | [
0.05049414932727814,
-0.04763165861368179,
-0.04332113638520241,
-0.0717017725110054,
0.08000757545232773,
-0.05926365777850151,
0.0416518859565258,
0.04438015818595886,
0.0744200274348259,
-0.044176071882247925,
0.060983769595623016,
-0.010169819928705692,
0.07374968379735947,
-0.01242688... |
9160a996-b001-56b4-b7ad-22de50e4819f | /documentation/search-precision/reranking-semantic-search/ | Reranking for Better Search | Implementing Vector Search with Reranking > Implementation > Rerank | documentation | false | Reranking for Better Search > Implementing Vector Search with Reranking > Implementation > Rerank
Vector search placed a document that uses “feature scaling” in a different sense, about image editing (24), in fourth place. The reranker reads the query and the document together, recognizes that it isn’t about machine l... | [
0.02869543246924877,
-0.04995814710855484,
-0.08448856323957443,
-0.05295437201857567,
0.09387568384408951,
-0.013544448651373386,
0.023968225345015526,
0.036577533930540085,
0.07605382800102234,
-0.01570768654346466,
0.015374315902590752,
0.026424434036016464,
0.05596131458878517,
0.00069... |
916cc1a4-4879-523d-9eb6-ac3172c03067 | /documentation/search-tuning/hybrid-search/ | Hybrid Search in Qdrant | What a Second Retriever Costs | documentation | true | Hybrid Search in Qdrant > What a Second Retriever Costs
The setup that follows starts with a dense-only collection and adds BM25 as the second retriever. That means adding a sparse vector per point, a second index, and another search on every query. On one container serving one request at a time, the extra search rais... | [
0.026207664981484413,
-0.04867509379982948,
-0.0366671048104763,
-0.02081916667521,
0.046412352472543716,
-0.03984910994768143,
0.0695004090666771,
0.04074621945619583,
0.07380809634923935,
-0.02925817109644413,
0.03527512028813362,
0.0328226312994957,
0.021587923169136047,
-0.024343090131... |
91812764-5e9a-501b-8f13-51c8b76b4699 | /documentation/datasets/ | Practice Datasets | Arxiv.org | documentation | false | Practice Datasets > Arxiv.org
[Arxiv.org](https://arxiv.org) is a highly-regarded open-access repository of electronic preprints in multiple
fields. Operated by Cornell University, arXiv allows researchers to share their findings with
the scientific community and receive feedback before they undergo peer review for ... | [
0.04148520529270172,
0.0021210864651948214,
-0.05164982005953789,
-0.05456741899251938,
0.08885013312101364,
-0.023193908855319023,
0.04841528832912445,
0.08956098556518555,
0.04610015079379082,
-0.06619114428758621,
0.06541985273361206,
0.02453097328543663,
0.07123842090368271,
-0.0059414... |
9186461b-df49-5d9b-b5f8-f56a9382726f | /articles/minicoil-en-es/ | miniCOIL EN-ES: Sparse Neural Retrieval Across the Language Barrier | Training miniCOIL EN-ES > Four Quadrants (not Qdrant's), Five Points | article | false | miniCOIL EN-ES: Sparse Neural Retrieval Across the Language Barrier > Training miniCOIL EN-ES > Four Quadrants (not Qdrant's), Five Points
"Similar" and "dissimilar" are decided by the teacher encoder, [`Qwen/Qwen3-Embedding-0.6B`](https://huggingface.co/Qwen/Qwen3-Embedding-0.6B), whose sentence embeddings we store i... | [
0.07251156121492386,
-0.034956641495227814,
-0.03880038857460022,
-0.035426534712314606,
0.06295038014650345,
-0.022758621722459793,
0.056489598006010056,
0.054884131997823715,
0.07749472558498383,
-0.04280463233590126,
0.003660933580249548,
0.0059089637361466885,
0.054572172462940216,
0.0... |
918ced7c-3fb5-5d07-b2d7-c7dddb25690e | /course/beginners/module-4/growing-past-one-machine/ | Growing Past One Machine | course | false | Growing Past One Machine
Module 4
Most systems never need more than one node. **Sharding** splits a collection's points across nodes, so each node holds a slice. **Replication** keeps a copy of each shard on more than one node, so search survives losing one.
Use them when one node cannot hold the collection, or when... | [
0.001272530877031386,
-0.033070117235183716,
-0.06722674518823624,
-0.019134769216179848,
0.08953079581260681,
-0.02178269810974598,
0.026721859350800514,
0.020600417628884315,
0.055940598249435425,
-0.003429204458370805,
0.03135707974433899,
0.01364935003221035,
0.023354697972536087,
-0.0... | |
918ed763-7db6-53a1-be76-8b85dc9b5011 | /documentation/examples/graphrag-qdrant-neo4j/ | GraphRAG with Qdrant and Neo4j | Retrieval Behavior and Limits | documentation | false | GraphRAG with Qdrant and Neo4j > Retrieval Behavior and Limits
- Qdrant searches paragraph embeddings, and `QdrantNeo4jRetriever` matches the hits to Neo4j `Chunk` nodes by ID. These nodes link paragraphs to extracted entities.
- A Cypher query follows entity relationships up to two hops. It has no result limit, so th... | [
0.03622758761048317,
-0.04474823176860809,
-0.06851796060800552,
-0.04344477877020836,
0.07885876297950745,
-0.02478880248963833,
0.024209819734096527,
0.053173940628767014,
0.07132087647914886,
-0.028066692873835564,
0.037485383450984955,
0.022628117352724075,
0.049809422343969345,
-0.022... |
919ec4e9-e13f-501a-9aba-e4e981ac53b9 | /documentation/search-tuning/before-tuning-a-qdrant-collection/ | What to Check Before Tuning a Qdrant Collection | Change Things in Cost Order | documentation | false | What to Check Before Tuning a Qdrant Collection > Change Things in Cost Order
Start with a change that does not rebuild the collection or add a retrieval stage. Move to a higher-cost tier only when the lower-cost options do not address the symptom.
| Tier | What | Applies To | Cost |
|---|---|---|---|
| No New Retrie... | [
0.040516722947359085,
-0.05630447342991829,
-0.05644127354025841,
-0.020460020750761032,
0.04837742820382118,
-0.026827635243535042,
0.05467245355248451,
0.047082677483558655,
0.07272059470415115,
-0.03071492910385132,
0.013865132816135883,
0.03570947051048279,
0.013760588131844997,
-0.047... |
91a57a40-4666-5115-99e2-7674838aa776 | /documentation/ops-configuration/administration/ | Administration | Strict Mode > Maximum HNSW ef Parameter | documentation | true | Administration > Strict Mode > Maximum HNSW ef Parameter
A high HNSW `ef` value increases recall but also increases search latency.
Setting `search_max_hnsw_ef` caps the maximum `ef` value allowed in search parameters.
```python
from qdrant_client import QdrantClient, models
client = QdrantClient(url="http://localh... | [
0.025222474709153175,
-0.04330213740468025,
-0.018676578998565674,
-0.03760800138115883,
0.04210428148508072,
-0.05775630846619606,
0.06465938687324524,
0.05509975552558899,
0.07738763093948364,
-0.031008023768663406,
0.01578384079039097,
0.028729859739542007,
0.08634799718856812,
-0.02497... |
91c3df04-750d-5814-8e15-8e1e3a817e73 | /course/multi-vector-search/module-1/maxsim-distance/ | MaxSim Distance Metric | The HNSW Challenge | course | false | MaxSim Distance Metric > The HNSW Challenge
A document's nearest neighbors are query-dependent and change based on which query you're processing, making it impossible to build the static proximity graph that HNSW requires. The practical reality is you must compute MaxSim against every document at query time with brute... | [
0.039482515305280685,
-0.03473728895187378,
-0.036250390112400055,
-0.019570546224713326,
0.07714975625276566,
-0.07246866822242737,
0.03950712829828262,
0.01181301474571228,
0.03586607426404953,
-0.03274621441960335,
0.04217231273651123,
0.03935395926237106,
0.0874546468257904,
-0.0070515... |
91ec40dc-228c-550e-9141-dc9ab61c777a | /course/multi-vector-search/module-2/visual-interpretability/ | Visual Interpretability of ColPali | The Key Insight: Spatial Correspondence | course | false | Visual Interpretability of ColPali > The Key Insight: Spatial Correspondence
In the [previous lesson on ColPali's architecture](/course/multi-vector-search/module-2/how-colpali-works/), you learned that ColPali divides images into a 32×32 grid of patches:
- **Input image**: 448×448 pixels
- **Patch size**: 14×14 pixe... | [
0.03833911567926407,
-0.019818609580397606,
-0.051058944314718246,
-0.0596628300845623,
0.07836718112230301,
-0.02608308009803295,
0.036793071776628494,
0.06193795055150986,
0.06159612536430359,
-0.01622709445655346,
0.03734380006790161,
-0.024856343865394592,
0.03697636350989342,
-0.00233... |
91ffc8af-c6f7-5897-bb87-48a506826010 | /documentation/production-operations/multitenant-search/ | How to Implement Multitenancy and Custom Sharding in Qdrant | Configure a multitenant setup for users | documentation | true | How to Implement Multitenancy and Custom Sharding in Qdrant > Configure a multitenant setup for users
Let's continue and start adding data. As you upsert your vectors to your new collection, you can add a `group_id` field to each vector. If you do this, Qdrant will assign each vector to its respective group.
Addition... | [
0.027852682396769524,
-0.03416035324335098,
-0.04922918975353241,
0.015428797341883183,
0.04706382378935814,
-0.04218778386712074,
0.09931465238332748,
0.059254247695207596,
0.04121752828359604,
-0.031191084533929825,
0.022499309852719307,
0.05475708097219467,
0.05671608820557594,
-0.01832... |
921eee15-e2aa-5834-bca2-9a7dcbe3a5a1 | /documentation/examples/rag-chatbot-red-hat-openshift-haystack/ | Private Chatbot for Interactive Learning | Components | documentation | false | Private Chatbot for Interactive Learning > Components
To maintain complete data isolation, we need to limit ourselves to open-source tools and use them in a private environment, such as [Red Hat OpenShift](https://www.redhat.com/en/technologies/cloud-computing/openshift). The pipeline will run internally and will be i... | [
0.034898996353149414,
-0.021335724741220474,
-0.06986814737319946,
-0.006113402545452118,
0.07905633002519608,
-0.01782689429819584,
0.03698057681322098,
0.012653661891818047,
0.03638226538896561,
-0.016122154891490936,
0.014848392456769943,
0.008313072845339775,
0.05536245182156563,
-0.03... |
923f6aeb-2e87-52c8-866f-c1f1d9c99a7d | /course/essentials/day-3/sparse-retrieval-demo/ | Demo: Keyword Search with Sparse Vectors | Best Matching 25 (BM25) | course | false | Demo: Keyword Search with Sparse Vectors > Best Matching 25 (BM25)
The **TF-IDF** model already provides a good statistical approximation of a keyword’s role in texts. What it doesn’t take into account, is that **the length of documents affects the importance of the words** used in these documents.
TF-IDF will rewar... | [
0.022671429440379143,
-0.02031734213232994,
-0.017772719264030457,
-0.05736403912305832,
0.04662783071398735,
-0.043594032526016235,
0.05235010385513306,
0.025180593132972717,
0.09729825705289841,
-0.014863173477351665,
0.020218485966324806,
-0.0009628739207983017,
0.042673613876104355,
-0... |
926ab328-6ac4-5a4f-be4e-748fd390d0fa | /documentation/examples/graphrag-qdrant-neo4j/ | GraphRAG with Qdrant and Neo4j | Architecture Overview > Ingestion | documentation | false | GraphRAG with Qdrant and Neo4j > Architecture Overview > Ingestion
The GraphRAG ingestion pipeline combines a **Graph Database** and a **Vector Search Engine** to improve RAG workflows.
Fig 2: Overview of Ingestion Pipeline
Let’s break it down:
1. **Raw Data:** Serves as the foundation, comprising unstructured or s... | [
0.03535404056310654,
-0.0505148321390152,
-0.089835524559021,
-0.046401772648096085,
0.0712399035692215,
-0.018452538177371025,
0.0705590695142746,
0.07355569303035736,
0.06236829236149788,
-0.024660075083374977,
0.017472459003329277,
0.01121352519840002,
0.05967722088098526,
-0.0124693596... |
927f9ac6-f6f1-56f1-a19b-600a64b8660d | /documentation/search-tuning/when-your-collection-outgrows-ram/ | When Your Collection Outgrows RAM | Rescoring Adds the Disk Read | documentation | false | When Your Collection Outgrows RAM > Rescoring Adds the Disk Read
Two changes reduce that read. More memory keeps the originals resident, and a lower `oversampling` rereads fewer candidates without needing any. At `bits1`, the candidates past the first rescoring pass buy little quality, which the next section measures.... | [
0.02579457126557827,
-0.04048197716474533,
-0.025844238698482513,
-0.03458716720342636,
0.08910060673952103,
-0.027503235265612602,
0.005429427605122328,
0.027089087292551994,
0.11583168804645538,
0.003684369847178459,
0.016925077885389328,
-0.0034933355636894703,
0.06089217588305473,
0.00... |
92845ebe-8e1e-5e10-9d41-28c634d1dad6 | /documentation/examples/rag-contract-management-stackit-cohere/ | Region-Specific Contract Management System | Implementation | documentation | false | Region-Specific Contract Management System > Implementation
To build the application, we are going to use the official SDKs of Cohere and Qdrant, and a few lines of plain Python
for the glue. There is no framework in between, so every step of the process is visible in the code. | [
0.009778367355465889,
-0.043734218925237656,
-0.019646652042865753,
-0.021036438643932343,
0.04277833551168442,
-0.05187981575727463,
0.06170561537146568,
0.04949440062046051,
0.07519225776195526,
0.0025851414538919926,
0.036045826971530914,
0.015165245160460472,
0.05784762278199196,
-0.04... |
92875cd6-eeec-5882-b815-7275ae0b51da | /documentation/tutorials-basics/multimodal-search/ | Multimodal Search | Search | documentation | true | Multimodal Search > Search
### Text-to-Image
See what image comes back for the query "*Plane components*". Wrap the query in a `models.Document` the same way you did while uploading, so Cloud Inference embeds it with the same model:
```python
from PIL import Image
with headers({"cohere-api-key": cohere_api_key}):
... | [
0.07414219528436661,
-0.046841733157634735,
-0.038967639207839966,
-0.06664619594812393,
0.09585680812597275,
-0.008791858330368996,
0.07919547706842422,
0.006860492751002312,
0.03026239201426506,
-0.036798685789108276,
0.04536542668938637,
0.0031603542156517506,
0.03469694405794144,
-0.05... |
929508e4-b593-5f17-ad1c-e9f261b3b3c8 | /documentation/tutorials-search-engineering/sparse-embeddings-ecommerce-part-2/ | Fine-Tuning Sparse Embeddings for E-Commerce Search | Part 2: Training SPLADE on Modal | Creating the SPLADE Model | documentation | true | Fine-Tuning Sparse Embeddings for E-Commerce Search | Part 2: Training SPLADE on Modal > Creating the SPLADE Model
Sentence Transformers v5 introduced `SparseEncoder`, making SPLADE training straightforward. The model has two components:
1. **MLMTransformer**: A transformer with a masked language model head that outp... | [
0.04854961112141609,
-0.06044982746243477,
-0.03710661083459854,
-0.03238378465175629,
0.04187025874853134,
-0.03264658898115158,
0.09881703555583954,
0.02184871956706047,
0.044406332075595856,
-0.01749468967318535,
0.026614058762788773,
0.006133221555501223,
0.017434917390346527,
-0.00869... |
929c4a7d-9ca8-5d64-9fc5-aeb1446ce964 | /documentation/scaling/distributed_deployment/ | Distributed Deployment | Sharding > Shard Transfer Method | documentation | false | Distributed Deployment > Sharding > Shard Transfer Method
*Available as of v1.7.0*
There are different methods for transferring a shard, such as moving or
replicating, to another node. Depending on what performance and guarantees you'd
like to have and how you'd like to manage your cluster, you likely want to
choose ... | [
0.005613730754703283,
-0.03814137354493141,
-0.0780799612402916,
-0.016093069687485695,
0.05070551857352257,
-0.03288557007908821,
0.03810204192996025,
0.03279324620962143,
0.04133186861872673,
0.0074267303571105,
0.010945181362330914,
0.024631591513752937,
-0.006889594718813896,
-0.001241... |
92b83fa2-e1b6-511c-a15b-f9b88eab591a | /documentation/production-operations/predictable-search-latency/ | Configure Qdrant's Optimizer for Predictable Search Latency | Segment Size Trades Recovery Time for Query Speed | documentation | false | Configure Qdrant's Optimizer for Predictable Search Latency > Segment Size Trades Recovery Time for Query Speed
Stick with Qdrant's default of one segment per CPU core unless a specific latency target pushes you to an extreme. A single segment gives the fastest steady-state search but takes over an hour to reach it. C... | [
0.03500935435295105,
-0.05156942084431648,
-0.04882024601101875,
-0.010048801079392433,
0.03799467161297798,
-0.045797575265169144,
0.040517907589673996,
0.021885281428694725,
0.08916731178760529,
-0.02734154649078846,
0.020000122487545013,
-0.007865251041948795,
0.055866267532110214,
-0.0... |
92c1f32d-547c-5cb2-8551-0343d89c9011 | /documentation/manage-data/collections/ | Collections | documentation | false | Collections
A collection is a named set of points (vectors with a payload) among which you can search. The vector of each point within the same collection must have the same dimensionality and be compared by a single metric. [Named vectors](#collection-with-multiple-vectors) can be used to have multiple vectors in a s... | [
0.04011417552828789,
-0.03993497043848038,
-0.07469479739665985,
-0.04733680561184883,
0.05779829993844032,
-0.030447710305452347,
0.06306436657905579,
0.03254799172282219,
0.12427321821451187,
-0.055047981441020966,
0.05357889458537102,
0.002336424309760332,
0.0591416098177433,
0.00683095... | |
92cba04d-40b9-5671-b89b-024670c666ee | /documentation/embeddings/cohere/ | Cohere | Models | documentation | false | Cohere > Models
| Model | Dimensions | Context | Input |
|---|---|---|---|
| `embed-v5.0-pro` | 2048 (default), 1536, 1024, 768, 512, 256 | 128k tokens | Text, images, mixed |
| `embed-v5.0-fast` | 2048 (default), 1536, 1024, 768, 512, 256 | 128k tokens | Text, images, mixed |
| `embed-v4.0` | 1536 (default), 1024, 51... | [
0.03058750554919243,
-0.01086715143173933,
-0.04470059275627136,
-0.05648910999298096,
0.06965072453022003,
-0.05319670960307121,
0.06731824576854706,
0.028300469741225243,
0.06990505754947662,
-0.05643570423126221,
0.018193790689110756,
0.004505590535700321,
0.03419875726103783,
-0.039475... |
92ef156b-10d9-5e67-a56a-64c84d501369 | /course/essentials/day-1/movie-search-system/ | Demo: Semantic Movie Search | Step 3: Implementing the Chunking Strategies | course | true | Demo: Semantic Movie Search > Step 3: Implementing the Chunking Strategies
Here's where the chunking concepts from earlier lessons come alive. We'll implement three different approaches and see how they perform:
```python
from transformers import AutoTokenizer
from llama_index.core.node_parser import SentenceSplitter... | [
0.009770146571099758,
-0.04068000987172127,
-0.04433770105242729,
-0.02430974319577217,
0.02729017287492752,
-0.022443676367402077,
0.0370306596159935,
0.016413729637861252,
0.06450691819190979,
-0.03450110927224159,
0.01810588873922825,
0.005096327047795057,
0.06394531577825546,
-0.001370... |
92f44809-6748-5020-8125-efe67fafa5cb | /documentation/faq/qdrant-fundamentals/ | Qdrant Fundamentals | Compatibility > How do I avoid issues when updating to the latest version? | documentation | false | Qdrant Fundamentals > Compatibility > How do I avoid issues when updating to the latest version?
We only guarantee compatibility when you upgrade from one minor version to the next. If you are more than one minor version behind, upgrade the cluster to the latest patch version of each intermediate minor version before ... | [
0.03303603082895279,
-0.039308007806539536,
-0.04724534600973129,
-0.004160634707659483,
0.04658545181155205,
-0.04508363455533981,
0.03440573439002037,
0.0374508760869503,
0.031976763159036636,
-0.010724617168307304,
0.048268873244524,
0.03547096997499466,
0.06614217907190323,
-0.04815211... |
93558b6f-bfda-58f7-8b85-6c85dded465a | /course/essentials/day-3/sparse-retrieval-demo/ | Demo: Keyword Search with Sparse Vectors | What's Next | course | false | Demo: Keyword Search with Sparse Vectors > What's Next
Sparse retrieval, even with neural weighting, has limits when semantically similar content is expressed in very different ways. **Dense retrieval** excels at discovery and naturally bridges vocabulary mismatch.
Both methods are complementary:
- **Sparse**: precis... | [
0.035256434231996536,
-0.04215889796614647,
-0.05147792398929596,
-0.06323205679655075,
0.07046733796596527,
-0.060090165585279465,
0.06331110745668411,
0.019543932750821114,
0.06868837773799896,
-0.03222771733999252,
0.01542593166232109,
0.06278721988201141,
0.051294587552547455,
0.007391... |
935dc72e-1b36-504e-98c3-c846554a27e9 | /documentation/fastembed/fastembed-semantic-search/ | FastEmbed & Qdrant | documentation | true | FastEmbed & Qdrant
## Install Qdrant Client and FastEmbed
```python
pip install "qdrant-client[fastembed]>=1.14.2"
```
## Initialize the client
Qdrant Client has a simple in-memory mode that lets you try semantic search locally.
```python
from qdrant_client import QdrantClient, models
client = QdrantClient(":memo... | [
0.04395940527319908,
-0.059417955577373505,
-0.022407975047826767,
-0.02910238318145275,
0.07388510555028915,
-0.035431623458862305,
0.0875917598605156,
0.045936569571495056,
0.05420992150902748,
-0.03486768156290054,
0.024712927639484406,
0.03310257941484451,
0.03424615412950516,
-0.03025... | |
936fda70-19c3-5ea5-8dad-1163edafd086 | /articles/rag-is-dead/ | Is RAG Dead? Why Long Context Windows Don't Replace RAG | When long context is the better choice | article | false | Is RAG Dead? Why Long Context Windows Don't Replace RAG > When long context is the better choice
If your documents fit in the window, you can skip retrieval and avoid its failure mode: the right passage never reaching the model. Anthropic's guidance from September 2024 says so directly. If your knowledge base is small... | [
-0.004484592936933041,
-0.04169664904475212,
-0.03796562924981117,
-0.055496711283922195,
0.05925357714295387,
-0.040106989443302155,
0.014643853530287743,
0.045738451182842255,
0.06925152242183685,
-0.049830805510282516,
-0.0016262279823422432,
0.014493316411972046,
0.04367661476135254,
-... |
93885806-115e-5e2f-964d-af69ac0f44a5 | /documentation/security/ | Security | Network Bind | documentation | true | Security > Network Bind
By default, a custom Qdrant deployment binds to all network interfaces. Your
instance may be open to everybody on the internet. On a local development
machine you likely have a firewall in place to prevent public access, but that
may not be the case on a public VPS or dedicated server.
It is h... | [
0.04172774776816368,
-0.06727397441864014,
-0.02525315247476101,
-0.005102228373289108,
0.06379710137844086,
-0.07331790775060654,
0.05693972855806351,
0.07367589324712753,
0.04601377621293068,
0.020151188597083092,
0.03326883912086487,
0.002167490776628256,
0.03780243545770645,
-0.0291177... |
93937e6a-6622-5eda-84bf-f55641d7f322 | /documentation/private-cloud/private-cloud-setup/ | Setup Private Cloud | Installation | documentation | true | Setup Private Cloud > Installation
Once onboarded to Qdrant Private Cloud, you will receive credentials to access the Qdrant Cloud Registry. You can use these credentials to install the Qdrant Private Cloud solution using the following commands:
1. Create the namespace for your Private Cloud deployment. You can use a... | [
0.053256142884492874,
-0.06044396385550499,
-0.008818492293357849,
-0.03423438221216202,
0.037133898586034775,
-0.08281259983778,
0.056646332144737244,
0.05697691813111305,
0.04381343722343445,
-0.04597170650959015,
0.014257957227528095,
0.03047638200223446,
0.07632345706224442,
-0.0675591... |
93b52cf1-32d5-5d00-90ed-0a9ce4f9f39d | /documentation/private-cloud/changelog/ | Changelog | 1.10.0 (2026-10-06) | documentation | false | Changelog > 1.10.0 (2026-10-06)
| Component | Version |
|-------------------------|---------|
| qdrant-kubernetes-api | v1.38.0 |
| operator | 2.35.1 |
| qdrant-cluster-manager | v0.3.23 |
| qdrant-cluster-exporter | 1.8.2 |
Latest validated Qdrant version: 1.19.1
* Added global qu... | [
0.04286749288439751,
-0.032230060547590256,
-0.048971012234687805,
-0.021882405504584312,
0.042953990399837494,
-0.02180267684161663,
0.04530856013298035,
0.018688179552555084,
0.07336468994617462,
-0.05078381672501564,
0.03590455278754234,
0.02480366826057434,
0.06175876408815384,
-0.0550... |
93bdcaa0-1484-546f-985f-c9e100106f79 | /documentation/search-precision/reranking-semantic-search/ | Reranking for Better Search | Implementing Vector Search with Reranking > Overview > Retrieval Stage | documentation | false | Reranking for Better Search > Implementing Vector Search with Reranking > Overview > Retrieval Stage
- **User's Query:** Now we enter the retrieval phase. The user submits a query, and it’s time to match that query against the stored documents.
- **Embeddings:** Just like with the documents, the user’s query is conver... | [
0.01273958571255207,
-0.06374556571245193,
-0.06203141435980797,
-0.039323803037405014,
0.08109213411808014,
-0.03965865820646286,
0.03848648443818092,
0.010123277083039284,
0.09136652201414108,
-0.035683684051036835,
-0.005141973029822111,
0.002651772229000926,
0.04719998687505722,
-0.052... |
93bf940e-ec78-5405-bc62-e9f9bbf97a2d | /articles/predicting-weak-retrieval/ | Predicting Weak Retrieval Without an LLM | article | false | Predicting Weak Retrieval Without an LLM
Most retrieval systems run one pipeline on every query, and it is the wrong default in both directions: a single pass under-serves the hard queries, while reranking or rewriting every query wastes compute on the easy ones. Worse, the single pass fails silently. When the relevan... | [
0.010533012449741364,
-0.06367802619934082,
-0.047864802181720734,
-0.06638216972351074,
0.03830869495868683,
-0.031479183584451675,
0.014900777488946915,
0.008773455396294594,
0.042137809097766876,
-0.0033755511976778507,
-0.019487004727125168,
0.0026312023401260376,
0.01368399616330862,
... | |
93c929fb-343f-5ba6-a6f4-332dd1628a0c | /documentation/manage-data/bulk-upload/ | Bulk Upload | Create Collections with Multiple Shards | documentation | true | Bulk Upload > Create Collections with Multiple Shards
In Qdrant, each collection is split into shards. By default, a collection has one shard, but you can specify more when creating the collection.
By creating multiple shards, you can parallelize the upload of a large dataset. From two to four shards per machine is a ... | [
0.0114828459918499,
-0.007654412183910608,
-0.05432199686765671,
-0.034363023936748505,
0.09483276307582855,
-0.04896322637796402,
0.04890262708067894,
0.06675112992525101,
0.089283786714077,
-0.0372336320579052,
0.031566962599754333,
0.029407719150185585,
0.032769374549388885,
-0.03814528... |
93d55830-193c-5c80-9839-979e91e5caf2 | /documentation/manage-data/indexing/ | Indexing | Payload Index > Parameterized Index > Using lookup and range in Integer Indices | documentation | true | Indexing > Payload Index > Parameterized Index > Using lookup and range in Integer Indices
*Available as of v1.8.0*
The parameterized variant of the `integer` index allows you to fine-tune indexing and search performance.
Parameterized `integer` indexes use the following flags:
- `lookup`: enables support for direc... | [
0.03435639664530754,
-0.03633975237607956,
-0.03649786487221718,
-0.02654942311346531,
0.07303129136562347,
-0.03799900412559509,
0.015487225726246834,
0.03901844099164009,
0.07200279831886292,
-0.027312885969877243,
0.030931441113352776,
0.033013299107551575,
0.04086187854409218,
-0.02727... |
93fbaaa7-9945-50c7-bba5-968be8473ed2 | /documentation/tutorials-basics/cloud-inference-hybrid-search/ | Hybrid Search | Run Hybrid Search | documentation | true | Hybrid Search > Run Hybrid Search
The query runs a dense prefetch and a BM25 prefetch, then fuses both result lists with [Reciprocal Rank Fusion](/documentation/search/hybrid-queries/#hybrid-search).
```python
from qdrant_client import QdrantClient, models
results = client.query_points(
collection_name="{collect... | [
0.04376864805817604,
-0.010658283717930317,
-0.04778008535504341,
-0.05294492468237877,
0.08619218319654465,
-0.02610708773136139,
0.026328954845666885,
0.030313165858387947,
0.07813587039709091,
-0.019452273845672607,
0.038698673248291016,
0.03824475407600403,
0.029928725212812424,
0.0031... |
9403419d-1a76-59a4-afab-752f2db39fdf | /documentation/embeddings/nomic/ | Nomic | Setup | documentation | true | Nomic > Setup
Install the Nomic SDK and the Qdrant client:
- Python: `pip install nomic qdrant-client`
- TypeScript: `npm install @qdrant/js-client-rest`
Create an API key in [Nomic Atlas](https://atlas.nomic.ai/cli-login) and store it in the `NOMIC_API_KEY` environment variable. The Python SDK reads the credentials... | [
0.04557713121175766,
-0.03072497248649597,
-0.006012412719428539,
-0.04682687669992447,
0.04499392211437225,
-0.09000177681446075,
0.06764014810323715,
0.012478692457079887,
0.02241799421608448,
-0.01480854582041502,
0.03309585154056549,
0.024002699181437492,
0.06294510513544083,
-0.055008... |
94204a9c-995f-5ec3-8c9b-f8de8037ccf8 | /articles/dedicated-vector-search/ | Why Vector Search Needs a Dedicated Database | Making Vector Search State-of-the-Art | article | false | Why Vector Search Needs a Dedicated Database > Making Vector Search State-of-the-Art
Now, let's shift focus to another key advantage of dedicated solutions — their ability to keep up with state-of-the-art solutions in the field.
[**Vector databases**](/qdrant-vector-database/) are purpose-built for vector retrieval, ... | [
0.014549782499670982,
-0.04693136364221573,
-0.058993060141801834,
-0.03592770919203758,
0.048330094665288925,
-0.04665447026491165,
0.054931752383708954,
0.01891830749809742,
0.04466499388217926,
-0.022611552849411964,
0.047331735491752625,
0.01945478282868862,
0.05693294107913971,
-0.041... |
94528451-7129-5aba-bb7a-6dfe0fa5bf1b | /documentation/tutorials-search-engineering/branch-aware-search/ | Branch-Aware Search | Step 7: A Second Branch, Same File | documentation | true | Branch-Aware Search > Step 7: A Second Branch, Same File
Fork `B` off `root` and have it overwrite `pricing.md`, the same file `A` already changed.
```text
root ●──●──●──────● root seq 0–3
├── A ●──● A: pricing.md with SSO
└── B ● B forks at root seq 3; B seq 0: update ... | [
0.054600246250629425,
-0.07924630492925644,
-0.027116378769278526,
-0.021613510325551033,
0.04674672335386276,
-0.035598304122686386,
-0.008122008293867111,
0.04763851314783096,
0.05430467426776886,
-0.00833309069275856,
0.032674551010131836,
0.02429463341832161,
0.07723956555128098,
-0.03... |
947adfb3-cf61-5842-8f20-bd1b73cd9e7c | /documentation/ops-configuration/running-with-gpu/ | Running with GPU | AMD GPUs | documentation | true | Running with GPU > AMD GPUs
### Prerequisites
Running Qdrant with AMD GPUs requires [ROCm](https://rocm.docs.amd.com/projects/install-on-linux/en/latest/install/detailed-install.html) to be installed on your host.
### Docker images with AMD GPU support
Docker images for AMD GPUs use the tag suffix `gpu-amd`, e.g., ... | [
0.02741175889968872,
-0.0863896980881691,
-0.05713491886854172,
-0.02366243675351143,
0.04828030243515968,
-0.04328975826501846,
0.05723736807703972,
0.0484536848962307,
0.06418073177337646,
-0.018079407513141632,
0.0661766305565834,
-0.020861966535449028,
0.06517878919839859,
-0.039021532... |
94935f27-f0ee-5ca4-bfa8-8074bc102c5f | /documentation/frameworks/testcontainers/ | Testcontainers | documentation | true | Testcontainers
[Testcontainers](https://testcontainers.com/) is a testing library that provides easy and lightweight APIs for bootstrapping integration tests with real services wrapped in Docker containers.
Qdrant is available as a [Testcontainers module](https://testcontainers.com/modules/qdrant/) in multiple langua... | [
0.0022894747089594603,
-0.04290523752570152,
-0.057146940380334854,
-0.05136330798268318,
-0.03262779116630554,
-0.04625581204891205,
0.09914512187242508,
0.04419849440455437,
0.05886027589440346,
-0.015540743246674538,
0.01098086591809988,
0.007276353891938925,
0.023794157430529594,
-0.02... | |
94ac9466-a287-5fd0-8592-e233f489faeb | /documentation/tutorials-search-engineering/index-dynamic-payloads/ | Indexing Payloads of Random Shape | Related Reading | documentation | false | Indexing Payloads of Random Shape > Related Reading
- [Nested object filter](/documentation/search/filtering/#nested-object-filter): full mechanics of the nested condition.
- [Payload index](/documentation/manage-data/indexing/#payload-index): index types and when each applies.
- [Multitenancy](/documentation/manage-d... | [
0.027181224897503853,
0.014737680554389954,
-0.08285538107156754,
-0.06636476516723633,
0.03864118084311485,
-0.0316760390996933,
0.06563977897167206,
0.037286896258592606,
0.11148757487535477,
-0.03431277349591255,
0.04154624789953232,
0.05050325766205788,
0.06518082320690155,
0.004195450... |
94b0f018-eb85-5fbe-a4e6-e9d52b9f9f4c | /documentation/cloud/cluster-monitoring/ | Monitor Clusters | Telemetry | documentation | false | Monitor Clusters > Telemetry

Qdrant Cloud provides you with a set of metrics to monitor the health of your database cluster. You can access these metrics in the Qdrant Cloud Console in the **Metrics** and **Request** sections of the Cluster Details page. | [
0.020328965038061142,
0.0030004121363162994,
-0.047825079411268234,
-0.030423244461417198,
0.047185130417346954,
-0.008348459377884865,
0.06632683426141739,
0.03221513330936432,
0.06483738124370575,
-0.031069785356521606,
0.047788649797439575,
-0.0006225485703907907,
0.07651909440755844,
-... |
94ccc442-e8d9-5794-8772-bdd6265f3c34 | /documentation/search-evaluation/pipeline-output-quality/ | Evaluating Pipeline Output Quality | Wiring the RAG Pipeline | documentation | true | Evaluating Pipeline Output Quality > Wiring the RAG Pipeline
Several frameworks score RAG outputs with an LLM judge, including Ragas, DeepEval, and others. We use Ragas here because it's the lightest setup for the three metrics this tutorial covers. If your team has standardized on a different framework or prefers to ... | [
0.025499582290649414,
-0.03830063343048096,
-0.03482314571738243,
-0.045547664165496826,
0.0587150864303112,
-0.009796210564672947,
0.0790591910481453,
0.02402678318321705,
0.05219103395938873,
-0.054951805621385574,
0.004001587629318237,
0.004224487580358982,
0.07940148562192917,
-0.01080... |
94cf8e16-a326-5c43-89b7-fd437aacc14a | /documentation/cloud-rbac/permission-reference/ | Permission Reference | documentation | false | Permission Reference
This document outlines the permissions available in Qdrant Cloud.
---
> 💡 When enabling `write:*` permissions in the UI, the corresponding `read:*` permission will also be enabled and non-actionable. This guarantees access to resources after creating and/or updating them. | [
0.004908549599349499,
-0.018767835572361946,
-0.02117202617228031,
-0.05365842208266258,
0.07604570686817169,
-0.03616126626729965,
0.042858511209487915,
0.060288991779088974,
0.05993763729929924,
-0.04331444576382637,
0.01184516679495573,
0.009612391702830791,
0.10137176513671875,
-0.0272... | |
94d73279-c8bc-5d3b-87eb-b4ef0de552dd | /articles/relevance-feedback/ | Relevance Feedback in Qdrant | Our Idea > Relevance Direction | article | false | Relevance Feedback in Qdrant > Our Idea > Relevance Direction
Imagine a hiker lost in a forest with a weak phone signal. They still manage to send a couple of quick photos to a friend who knows orienteering.
The friend does not have a map of the whole forest or a live view of every tree. Still, they try to help and r... | [
0.01801326498389244,
-0.04213426634669304,
-0.048865534365177155,
-0.06374466419219971,
0.055801086127758026,
0.012714358046650887,
0.0423089973628521,
0.025976264849305153,
0.05224263668060303,
-0.01646772027015686,
0.023825159296393394,
0.015147733502089977,
0.059525392949581146,
-0.0253... |
94d87202-2336-5928-9187-8800f1eebeb7 | /documentation/ops-configuration/usage-statistics/ | Usage Statistics | Request information deletion | documentation | false | Usage Statistics > Request information deletion
We provide an email address so that users can request the complete removal of their data from all of our tools.
To do so, send an email to privacy@qdrant.com containing the unique identifier generated for your Qdrant installation.
You can find this identifier in the tel... | [
0.03784054517745972,
-0.031211357563734055,
-0.02160670980811119,
-0.03543095663189888,
0.022818870842456818,
-0.0049886554479599,
0.045273009687662125,
0.0900832861661911,
0.06999262422323227,
-0.04098306596279144,
0.04051326587796211,
0.02295665070414543,
0.09846995025873184,
-0.03443653... |
94d95278-5d9f-5e7f-9f4e-b6382012dd32 | /articles/hyperbolic-embeddings-qdrant/ | Why Hyperbolic Embeddings Matter for Hierarchical Data | Hierarchical Data Meets Hyperbolic Embeddings | article | false | Why Hyperbolic Embeddings Matter for Hierarchical Data > Hierarchical Data Meets Hyperbolic Embeddings
Imagine a product catalog. Footwear splits into boots, trainers, and sandals. Boots split into ankle boots, hiking boots, and work boots. Each type contains products, and each product can have several variants.
![A ... | [
0.043817926198244095,
0.015880877152085304,
-0.02739093452692032,
-0.05319242179393768,
0.09136262536048889,
-0.0434437058866024,
0.0776849091053009,
0.06920354813337326,
0.0881340280175209,
-0.009607389569282532,
-0.005535862408578396,
0.01653864048421383,
0.08470655977725983,
-0.03192908... |
95021f7c-12a5-5500-aeaf-6b8b30f9d688 | /documentation/frameworks/rocketride/ | RocketRide | Use Qdrant from an agent | documentation | false | RocketRide > Use Qdrant from an agent
The Qdrant node can also connect to a RocketRide agent through its tool interface. By default, it exposes three namespaced tools:
| Tool | Purpose |
| --- | --- |
| `qdrant.search` | Run semantic search and return matching content, scores, and metadata. |
| `qdrant.upsert` | Add ... | [
0.05183303728699684,
-0.049994051456451416,
-0.05140947178006172,
-0.02098674699664116,
0.07672002911567688,
-0.08794791251420975,
0.07378711551427841,
0.05478857085108757,
0.03045085445046425,
-0.04529663175344467,
0.052328936755657196,
0.00276993028819561,
0.01415183488279581,
-0.0199199... |
95126d5a-0b03-5ed9-b479-0ff67762e871 | /documentation/edge/edge-synchronization-guide/ | Synchronize with a Server | Synchronizing Qdrant Edge with a Server > 2. Initialize an Immutable Edge Shard from a Server Snapshot | documentation | true | Synchronize with a Server > Synchronizing Qdrant Edge with a Server > 2. Initialize an Immutable Edge Shard from a Server Snapshot
Next, create the immutable Edge Shard from a snapshot on the server, as outlined in [Initialize Edge Shard from existing Qdrant Collection](/documentation/edge/edge-data-synchronization-pa... | [
0.040430810302495956,
-0.02279062569141388,
-0.04548555612564087,
-0.025419360026717186,
0.06100483238697052,
-0.033675260841846466,
0.0750044658780098,
0.023877408355474472,
0.08014948666095734,
-0.013741254806518555,
0.0335538312792778,
0.00906080286949873,
0.05687006935477257,
0.0075382... |
951eb3a1-ad5b-5ad0-854b-6e904fc74972 | /documentation/migration-guidance/diagnosing-discrepancies/ | Diagnosing Discrepancies | Vendor-Specific Gotchas | documentation | false | Diagnosing Discrepancies > Vendor-Specific Gotchas
From Pinecone
* **Namespace handling:** Pinecone namespaces don't have a direct Qdrant equivalent. Common approach: migrate each namespace as a separate collection, or merge into one collection with a `namespace` payload field. Verify your approach preserved the sepa... | [
0.03591262921690941,
-0.044926926493644714,
-0.05828697979450226,
-0.024790827184915543,
0.03066769242286682,
-0.04219164326786995,
0.06410516798496246,
0.03793105483055115,
0.04429496452212334,
-0.04138229787349701,
0.011408740654587746,
-0.0026676480192691088,
0.02948380820453167,
0.0021... |
9529c5be-4e1a-5304-b43d-91c4708ee82b | /course/essentials/day-4/pitstop-project/ | Project: Quantization Performance Optimization | Build Steps | course | true | Project: Quantization Performance Optimization > Build Steps
### Step 1: Baseline Measurement
Start by measuring your current system's performance without quantization:
```python
import time
import numpy as np
from qdrant_client import QdrantClient, models
import os
client = QdrantClient(url=os.getenv("QDRANT_URL"... | [
0.03044186346232891,
-0.053172189742326736,
-0.010773617774248123,
-0.03265415132045746,
0.05963357910513878,
-0.015472604893147945,
0.052194368094205856,
0.03858400136232376,
0.10630571842193604,
-0.03757534921169281,
0.024164533242583275,
0.016268322244286537,
0.04509781301021576,
-0.057... |
954c0e24-0036-5f15-bc1a-9b3455988857 | /articles/dedicated-vector-search/ | Why Vector Search Needs a Dedicated Database | Vector Search > BASEd Vector Search | article | false | Why Vector Search Needs a Dedicated Database > Vector Search > BASEd Vector Search
Considering the specifics of vector search — its nature demanding availability & scalability — it should be served on BASE-oriented architecture. This choice is made due to the need for horizontal scaling, high availability, low latency... | [
-0.009789586067199707,
-0.0629962831735611,
-0.08316993713378906,
-0.04880296811461449,
0.04862123727798462,
-0.06660272926092148,
0.04399080574512482,
-0.012120705097913742,
0.05133805796504021,
0.004455562215298414,
0.03901536017656326,
0.025615692138671875,
0.04537263885140419,
-0.01886... |
9553f820-a870-505f-ac1c-58833b21dc2a | /documentation/manage-data/vectors/ | Vectors | Datatypes > Float16 | documentation | true | Vectors > Datatypes > Float16
The `float16` datatype stores each dimension as a 16-bit (2-byte) floating-point number, also known as a half-precision float. This shrinks vector storage to half of its original size, with a small loss of precision per value:
```text
float32 -> float16 delta (float32 - float16).abs
0.7... | [
0.04537823796272278,
-0.02424234338104725,
-0.06122832000255585,
-0.04010007157921791,
0.006778003182262182,
-0.044202182441949844,
-0.010199115611612797,
0.03299788013100624,
0.10076700896024704,
-0.024966437369585037,
0.031230347231030464,
0.01127798855304718,
0.042686253786087036,
-0.00... |
956f598c-464b-5079-990e-779e256bcc85 | /documentation/tutorials-search-engineering/using-multivector-representations/ | Multivectors and Late Interaction | Step-by-Step: ColBERT + Qdrant Setup | documentation | true | Multivectors and Late Interaction > Step-by-Step: ColBERT + Qdrant Setup
Ensure that Qdrant is running and create a client:
```python
from qdrant_client import QdrantClient, models
# 1. Connect to Qdrant server
client = QdrantClient("http://localhost:6333")
``` | [
0.007860780693590641,
-0.035475779324769974,
-0.018487531691789627,
-0.02722615748643875,
0.058477792888879776,
-0.03774494677782059,
0.06586292386054993,
0.012822984717786312,
0.05545249953866005,
0.0004186331352684647,
0.027059897780418396,
-0.004515414591878653,
0.07365316152572632,
-0.... |
95a1887d-aac3-5369-a303-3f6907d33b7e | /documentation/overview/what-is-qdrant/ | What is Qdrant? | What Are Vector Databases? | documentation | false | What is Qdrant? > What Are Vector Databases?
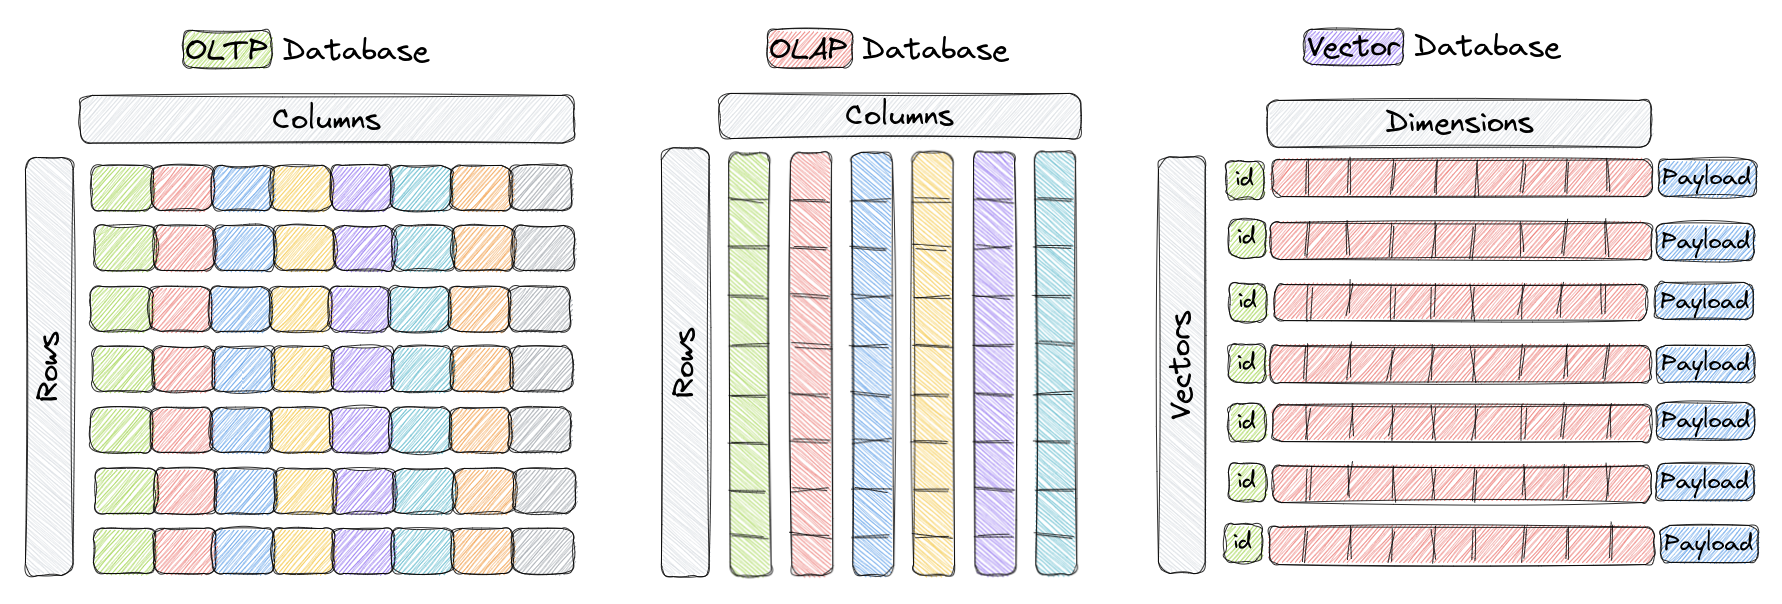
Vector databases are a type of database designed to store and query high-dimensional vectors
efficiently. In traditional [OLTP](https://www.ibm.com/topics/oltp) and [OLAP](https... | [
0.04683263227343559,
-0.029902061447501183,
-0.053753457963466644,
-0.03904310613870621,
0.04767841473221779,
-0.024114783853292465,
0.08816651254892349,
0.02352762594819069,
0.08210241049528122,
-0.025355953723192215,
0.04381328448653221,
-0.008344924077391624,
0.06514783948659897,
-0.023... |
95b061bd-bb43-5b24-8f24-0c173a4d519b | /documentation/tutorials-basics/cloud-inference-hybrid-search/ | Hybrid Search | Initialize the Client | documentation | true | Hybrid Search > Initialize the Client
For Python, install the Qdrant client and the Hugging Face `datasets` library:
```bash
pip install qdrant-client datasets
```
For the other languages, install a client from the [API & SDKs](/documentation/interfaces/) page.
Initialize the Qdrant client after creating a [Qdrant ... | [
0.04191705211997032,
-0.03132825717329979,
-0.017283255234360695,
-0.056250084191560745,
0.07938095182180405,
-0.03550226613879204,
0.052515748888254166,
0.02930072508752346,
0.05632047355175018,
-0.02044912427663803,
0.03020392917096615,
0.033940862864255905,
0.06455732882022858,
-0.02880... |
95b470da-b546-5cb3-ac54-e5cee127adee | /documentation/tutorials-operations/embedding-model-migration/ | Migrate to a New Embedding Model | Blue-Green Migration | documentation | false | Migrate to a New Embedding Model > Blue-Green Migration
A blue-green migration uses two collections: the first collection contains the old embeddings, and the second one is used to store the new embeddings. A migration process copies the data from the old collection to the new one, re-embedding vectors using the new m... | [
0.037844784557819366,
-0.05865412577986717,
-0.017270609736442566,
-0.0576479472219944,
0.07582505792379379,
-0.0010225266451016068,
0.062068987637758255,
0.05614165589213371,
0.04072961583733559,
-0.037105485796928406,
-0.019817255437374115,
0.04114198684692383,
0.0022518099285662174,
-0.... |
95cc93cc-9098-556a-ba96-e18d9aa7cba7 | /course/essentials/day-1/embedding-models/ | Points, Vectors and Payloads | Payloads (Metadata) > Filtering Logic: Building Complex Queries | course | true | Points, Vectors and Payloads > Payloads (Metadata) > Filtering Logic: Building Complex Queries
Qdrant's filtering system uses logical clauses that can be recursively nested to create sophisticated query logic. Think of these as the building blocks for expressing complex business requirements.
**Logical Clauses:**
- *... | [
0.017440859228372574,
-0.03422258049249649,
-0.04621594026684761,
-0.01609647087752819,
0.049400538206100464,
-0.037517573684453964,
0.05324968695640564,
0.05349287390708923,
0.07879775762557983,
-0.030958373099565506,
0.020006703212857246,
0.007814619690179825,
0.07766368240118027,
-0.036... |
95ec3cfd-552f-5b88-8739-48c75f5f7071 | /documentation/common-errors/ | Troubleshooting | Too many files open (OS error 24) | documentation | true | Troubleshooting > Too many files open (OS error 24)
Each collection segment needs some files to be open. At some point you may encounter the following errors in your server log:
```text
Error: Too many files open (OS error 24)
```
In such a case you may need to increase the limit of the open files. It might be done,... | [
0.015364856459200382,
-0.0812569335103035,
-0.010885495692491531,
-0.0426894836127758,
0.07214909046888351,
-0.07827885448932648,
0.06256771832704544,
0.06336057931184769,
0.08833771198987961,
0.0035118567757308483,
-0.006616139318794012,
-0.00236371043138206,
0.04103412851691246,
-0.08777... |
95ecff00-98f8-5f9d-abd5-1d01a3c38e46 | /documentation/search-tuning/before-tuning-a-qdrant-collection/ | What to Check Before Tuning a Qdrant Collection | The Retrieval Pipeline You Are Tuning | documentation | false | What to Check Before Tuning a Qdrant Collection > The Retrieval Pipeline You Are Tuning
Every query first retrieves candidates, then ranks them. In dense-only search, one vector search does both. Hybrid search adds a sparse prefetch for exact terms, then fusion combines the dense and sparse candidate lists. A reranker... | [
0.014286710880696774,
-0.036372244358062744,
-0.06699535995721817,
-0.03745996579527855,
0.04519825428724289,
-0.04608020558953285,
0.06470184773206711,
0.05550291761755943,
0.06938312202692032,
-0.03793434053659439,
0.009022395126521587,
0.04393799602985382,
0.03542293235659599,
-0.027931... |
9601e11a-bfc5-56fc-b56b-94643e23024c | /documentation/embeddings/nomic/ | Nomic | Models | documentation | false | Nomic > Models
| Model | Dimensions | Max Input | Input |
|---|---|---|---|
| `nomic-embed-text-v1.5` | 768 (or 512, 256, 128, 64) | 8192 tokens | Text |
| `nomic-embed-vision-v1.5` | 768 | One PNG, JPEG, or WebP image | Image |
`nomic-embed-vision-v1.5` shares an embedding space with `nomic-embed-text-v1.5`, so text... | [
0.04447722062468529,
-0.020493678748607635,
-0.04766436666250229,
-0.06909362226724625,
0.09073576331138611,
-0.0499240979552269,
0.04787642881274223,
0.03403366729617119,
0.04364663362503052,
-0.03445485606789589,
0.02899845689535141,
0.032546043395996094,
0.05359829217195511,
-0.04444226... |
9605876e-7d77-59cc-b0a1-a02363235f14 | /course/beginners/module-3/hybrid-search-in-qdrant/ | Setting Up Hybrid Search in Qdrant | Step 1: Create a Hybrid Collection | course | true | Setting Up Hybrid Search in Qdrant > Step 1: Create a Hybrid Collection
Two things are new since Module 2. The collection declares a sparse config alongside the dense one, so both vectors live on the same point. And that sparse config carries a `modifier`, which has no dense equivalent: it tells Qdrant to compute the ... | [
0.05458563193678856,
-0.007245488930493593,
-0.05036640912294388,
-0.040247172117233276,
0.07837437838315964,
-0.03359445556998253,
0.05644453316926956,
0.04488682746887207,
0.06709261983633041,
-0.030645422637462616,
0.009264416061341763,
0.0163120049983263,
0.05626295879483223,
-0.021607... |
9605b8cb-c8fe-595a-a780-c4fd8048deb4 | /documentation/edge/edge-api/reading-data/ | Reading Data | scroll | documentation | true | Reading Data > scroll
Pages through points in the shard without scoring them.
```python
def scroll(self, scroll: ScrollRequest) -> Tuple[List[Record], Optional[PointId]]
```
**Returns** the matching records and the offset to pass to the next call, or `None` when the last page has been reached.
| Parameter | Type | ... | [
0.04612584412097931,
-0.024117058143019676,
-0.04379497841000557,
-0.028383303433656693,
0.07288011908531189,
-0.041267797350883484,
0.047618307173252106,
0.029710624366998672,
0.07061898708343506,
-0.010996651835739613,
0.034573279321193695,
0.04790518805384636,
0.0004186159640084952,
0.0... |
961c0b25-d4e0-5223-bd6d-21d67632fb28 | /documentation/production-operations/bulk-data-import/ | Bulk Uploading Data to Qdrant | Option 1: Reduce Memory Pressure | documentation | true | Bulk Uploading Data to Qdrant > Option 1: Reduce Memory Pressure
_Dense vectors_
Memory usage can become one of the first bottlenecks during a large upload. Dense vectors are usually fixed-size embeddings, and when millions of them are inserted into a collection, the raw vector data alone can take up a large amount o... | [
0.03419892489910126,
-0.03777427598834038,
-0.028636489063501358,
-0.05484765022993088,
0.08457542955875397,
-0.03522282838821411,
0.05915221571922302,
0.027360064908862114,
0.12228727340698242,
-0.052218735218048096,
0.013058492913842201,
0.04875114932656288,
0.05971480533480644,
-0.02945... |
9649728a-f371-5798-989f-fb64d9bf3589 | /articles/what-is-vector-quantization/ | What is Vector Quantization? | 1. What is Scalar Quantization? | article | true | What is Vector Quantization? > 1. What is Scalar Quantization?

In Qdrant, each dimension is represented by a `float32` value, which uses **4 bytes** of memory. When using [Scalar Quantization](https://qdrant.tech/documentation/manage-data/quantization... | [
0.052673161029815674,
-0.03598547354340553,
-0.05134722217917442,
-0.03562888503074646,
0.031157512217760086,
-0.017270198091864586,
0.05680279806256294,
0.05769413337111473,
0.10965225845575333,
-0.05026812478899956,
0.014290099032223225,
-0.0022469249088317156,
0.03342850133776665,
-0.01... |
966b364d-359a-5c12-96ab-418a86652217 | /course/essentials/day-1/chunking-strategies/ | Text Chunking Strategies | Why Chunking Makes All the Difference | course | false | Text Chunking Strategies > Why Chunking Makes All the Difference
Instead of treating documents as monolithic blocks, you break them up into paragraphs, headings, and subsections. Each chunk gets its own vector, tied to a specific idea or topic. You can add metadata to each chunk like section title, page number, origin... | [
0.018758099526166916,
-0.04506398364901543,
-0.07355938106775284,
-0.0411229133605957,
0.054941326379776,
-0.009430686011910439,
0.037847768515348434,
0.023768160492181778,
0.05189075320959091,
-0.021160582080483437,
-0.0014138770056888461,
0.004485409706830978,
0.049287427216768265,
-0.02... |
967c950f-10e8-5863-be2f-aba46e972dd4 | /documentation/tutorials-build-essentials/agentic-rag-camelai-discord/ | Discord RAG Bot | Step 4: Answer From the Retrieved Text | documentation | true | Discord RAG Bot > Step 4: Answer From the Retrieved Text
The retrieval result contains chunk text and its source path. Build the prompt explicitly so the model sees both the original question and the evidence:
```python
SYSTEM_MESSAGE = """Answer the original question using only the retrieved context.
Context is refe... | [
0.03693660721182823,
-0.08666885644197464,
-0.03529120236635208,
-0.02998589538037777,
0.07717547565698624,
-0.017534133046865463,
0.057676441967487335,
0.03700616583228111,
0.05638415366411209,
-0.04163775593042374,
0.05124559998512268,
0.009806640446186066,
0.10379201918840408,
-0.020025... |
Subsets and Splits
No community queries yet
The top public SQL queries from the community will appear here once available.