
id stringlengths 36 36 | url stringclasses 504
values | title stringclasses 475
values | section stringlengths 0 148 | content_type stringclasses 3
values | has_code bool 2
classes | text stringlengths 147 22.5k | vector listlengths 384 384 |
|---|---|---|---|---|---|---|---|
ab649419-dc3e-5bf4-ad44-e72a8ad77bc0 | /documentation/ops-monitoring/monitoring/ | Monitoring & Telemetry | Metrics > Node Metrics /metrics | documentation | false | Monitoring & Telemetry > Metrics > Node Metrics /metrics
| Name | Type | Meaning |
| ------------------------------------------------- | ------- | ------------------------------... | [
-0.013001618906855583,
-0.016432905569672585,
-0.0699281245470047,
0.0025633559562265873,
0.07813180238008499,
-0.03784603253006935,
0.053370390087366104,
0.07694219052791595,
0.06828335672616959,
-0.06397249549627304,
0.043470121920108795,
0.0390288420021534,
0.027521034702658653,
-0.0177... |
ab874039-e0f9-539d-aa5f-d8511af37d5c | /documentation/cloud-cli/ | Qdrant Cloud CLI | Installation | documentation | true | Qdrant Cloud CLI > Installation
### With Homebrew
On macOS and Linux, install from the Qdrant tap:
```sh
brew install qdrant/tap/qcloud
```
Homebrew also installs shell completions for bash, zsh, and fish. Update with `brew upgrade qcloud`.
### From the install script
For systems without Homebrew, such as CI runn... | [
0.019979776814579964,
-0.053041599690914154,
-0.03701462969183922,
-0.020917069166898727,
0.05426328256726265,
-0.023227542638778687,
0.05112564563751221,
0.007970043458044529,
0.056389402598142624,
-0.050333499908447266,
0.030847379937767982,
0.014924443326890469,
0.05016028881072998,
-0.... |
ab89ca15-232b-5402-b5cb-24d64e52fcf0 | /course/essentials/day-2/collection-tuning-demo/ | Demo: HNSW Performance Tuning | Next Steps & Resources | course | false | Demo: HNSW Performance Tuning > Next Steps & Resources
**What you've learned:**
- Strategic optimization of initial bulk upload with `m=0` → `m=16` switching
- Real-world performance measurement techniques
- The dramatic impact of payload indexes on filtering
- Production-ready configuration patterns
**Recommended ne... | [
0.03632412478327751,
-0.03571810573339462,
-0.06348428130149841,
-0.02426913194358349,
0.040092937648296356,
-0.036073483526706696,
0.03798952326178551,
0.015269463881850243,
0.08370976150035858,
-0.02939123660326004,
0.008549807593226433,
0.03128724917769432,
0.0452282652258873,
-0.058510... |
abbbc287-3261-5956-87de-04779d50847b | /documentation/faq/qdrant-fundamentals/ | Qdrant Fundamentals | Search > What does ignore=true do in quantization search params? | documentation | false | Qdrant Fundamentals > Search > What does ignore=true do in quantization search params?
When `ignore` is `true`, Qdrant still traverses the HNSW graph that was built from quantized vectors, but uses exact (full-precision) distances to score candidates during traversal rather than quantized distances. This can improve r... | [
0.07208897173404694,
-0.05800635367631912,
-0.023859407752752304,
-0.028897209092974663,
0.03927434980869293,
-0.0025502133648842573,
0.06649798154830933,
0.026947589591145515,
0.0739898756146431,
-0.012310611084103584,
0.05146060883998871,
0.03123430348932743,
0.061616554856300354,
0.0199... |
abbdea0a-5476-52b4-9a95-76cacb64a90f | /documentation/manage-data/vectors/ | Vectors | Datatypes > Uint8 | documentation | true | Vectors > Datatypes > Uint8
The `uint8` datatype stores each dimension as an unsigned 8-bit integer (1 byte), with values from 0 to 255. This shrinks vector storage to one-quarter of its original size. The impact of this range depends on whether you use dense or sparse vectors:
- Dense vectors are required to be in t... | [
0.03135639429092407,
-0.0330604612827301,
-0.03798915445804596,
-0.0506623238325119,
0.026918433606624603,
-0.04538629204034805,
0.020157890394330025,
0.06865491718053818,
0.09386612474918365,
-0.04540380835533142,
0.03352311626076698,
0.05179896578192711,
0.04974215477705002,
-0.007443591... |
abcdf23d-7bb0-5143-afd6-5ba022e5b1a5 | /documentation/tutorials-search-engineering/pdf-retrieval-at-scale/ | Multivector Document Retrieval | Conclusion | documentation | false | Multivector Document Retrieval > Conclusion
In this tutorial, we demonstrated an optimized approach using **Qdrant for PDF retrieval at scale** with VLLMs producing **heavy multivector representations** like **ColPali** and **ColQwen2**.
Without such optimization, the performance of retrieval systems can degrade seve... | [
0.019690876826643944,
-0.04375820234417915,
-0.0451374426484108,
-0.061521030962467194,
0.08547419309616089,
-0.029437776654958725,
0.053615398705005646,
0.029659591615200043,
0.07999695092439651,
-0.00327317020855844,
-0.003990743774920702,
-0.012192018330097198,
0.05338374525308609,
-0.0... |
abd6ee83-79d2-5857-b8ab-506a4c12451f | /documentation/overview/what-is-qdrant/ | What is Qdrant? | High-Level Overview of Qdrant's Architecture | documentation | false | What is Qdrant? > High-Level Overview of Qdrant's Architecture
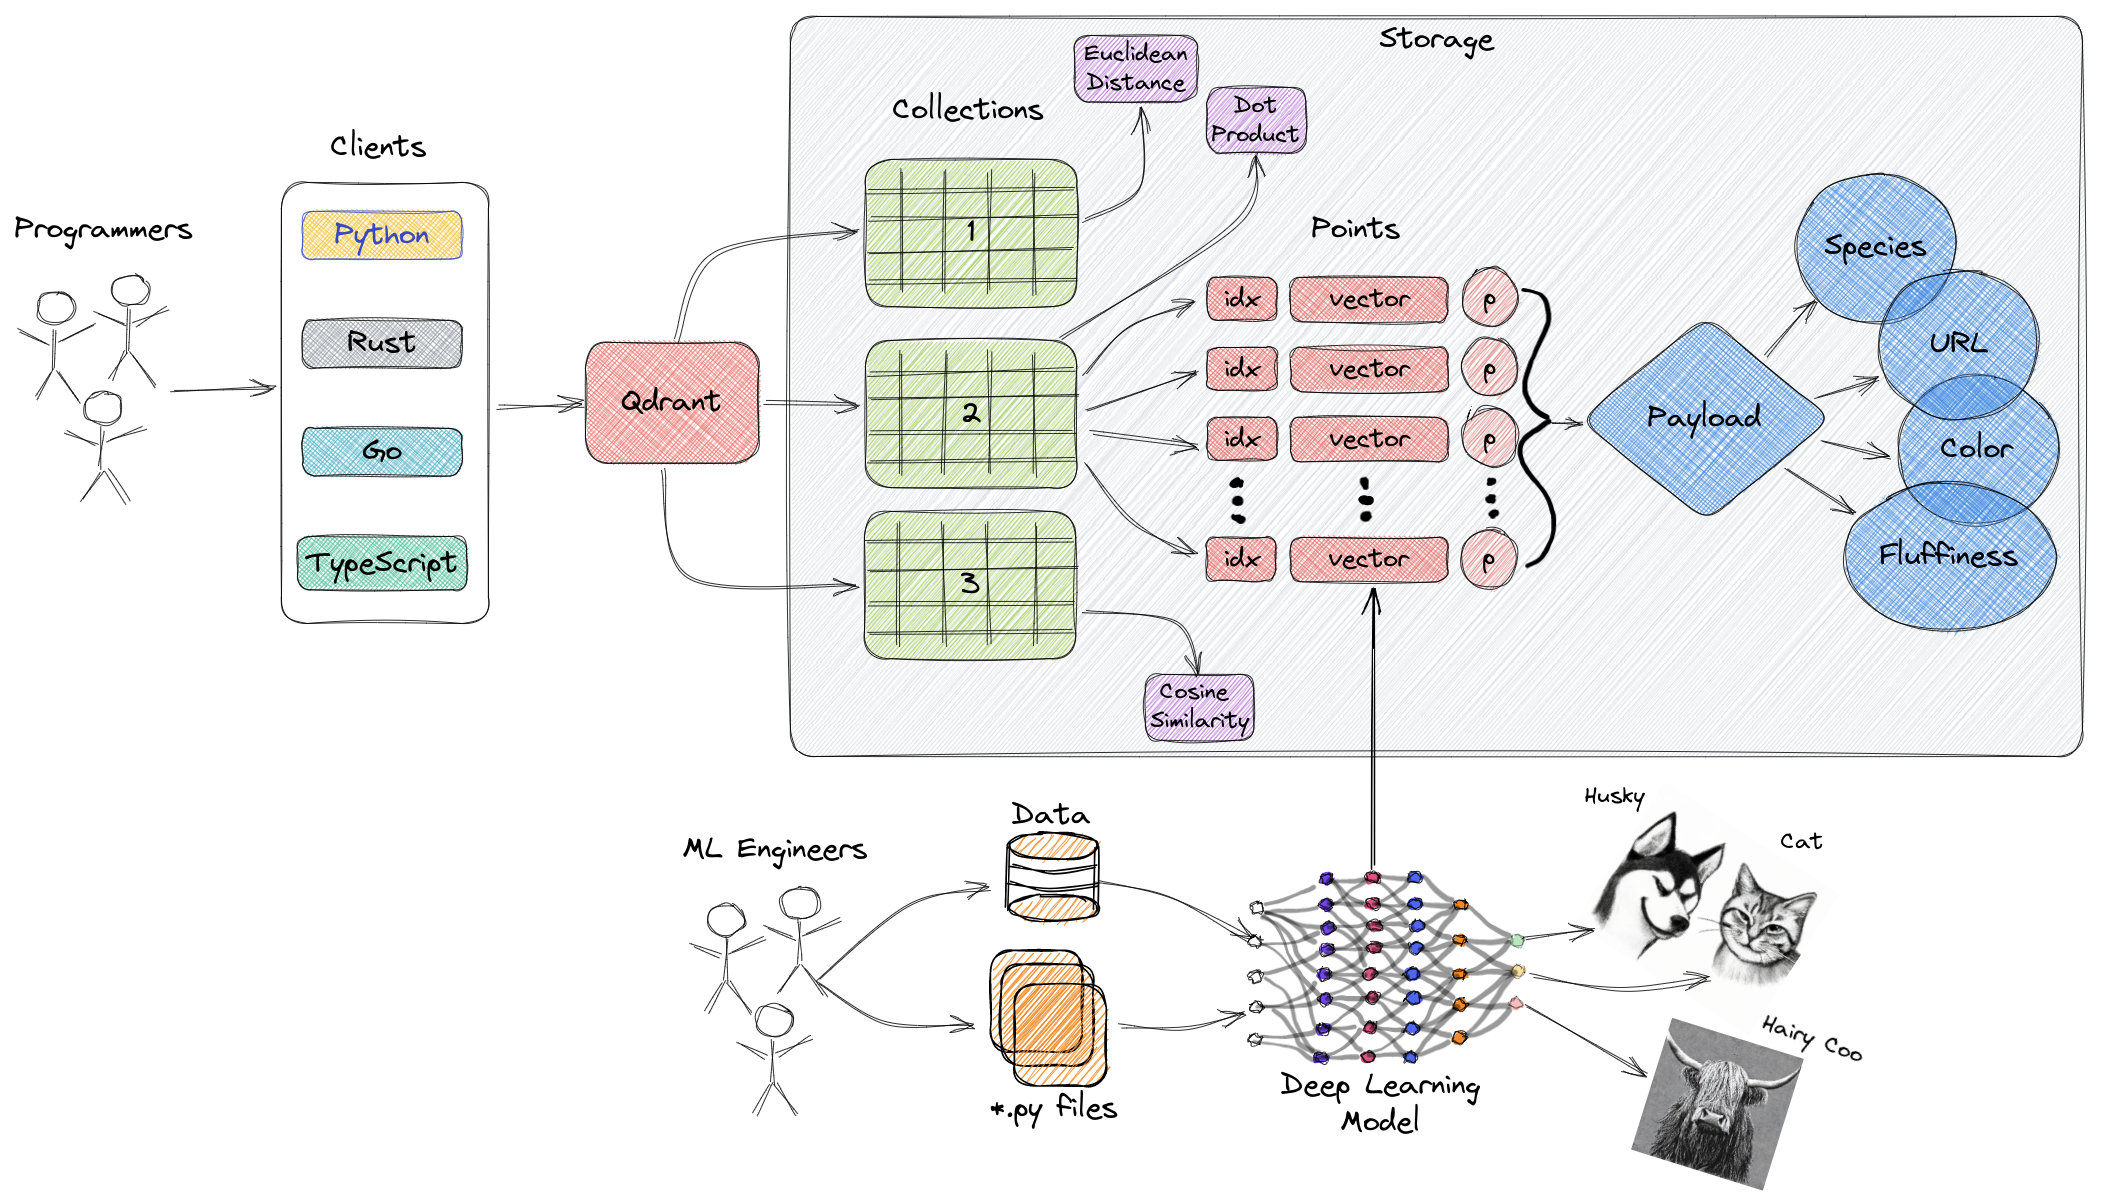
The diagram above represents a high-level overview of some of the main components of Qdrant. Here
are the terminologies you should get fami... | [
0.01315747108310461,
-0.013507363386452198,
-0.04724038764834404,
-0.02559852972626686,
0.06069893017411232,
-0.034654662013053894,
0.0761166661977768,
0.025537196546792984,
0.09383942931890488,
-0.034554433077573776,
0.04132946580648422,
-0.000339937541866675,
0.046975862234830856,
-0.014... |
abeb6420-2474-5801-9a9e-91954d0f08a4 | /documentation/tutorials-build-essentials/video-anomaly-edge-part-3/ | Video Anomaly Detection Part 3: Scoring, Governance, and Deployment | Batch Embedding with Twelve Labs | documentation | true | Video Anomaly Detection Part 3: Scoring, Governance, and Deployment > Batch Embedding with Twelve Labs
For initial baseline construction or dataset evaluation, we provide a batch embedding script that uploads clips via Twelve Labs and indexes the resulting embeddings into Qdrant:
`/scripts/embed_twelvelabs.py`
```ba... | [
0.043636057525873184,
-0.040404610335826874,
-0.09140194952487946,
-0.06241162493824959,
0.08106829971075058,
-0.04127528890967369,
0.061922188848257065,
0.06963756680488586,
0.05018400400876999,
-0.03372107818722725,
0.0680980533361435,
0.03162127360701561,
0.06600121408700943,
-0.0353439... |
abf22048-2db3-55c9-a554-ad5a0a8f0c29 | /documentation/migrate-to-qdrant/from-faiss/ | From FAISS | Concept Mapping | documentation | false | From FAISS > Concept Mapping
| FAISS | Qdrant | Notes |
| :--- | :--- | :--- |
| Index | Collection | One-to-one mapping |
| Vector (by position) | Point | Position in index becomes point ID | | [
0.06751640886068344,
-0.0664859190583229,
-0.031123269349336624,
-0.06774735450744629,
0.05345919355750084,
-0.0025353278033435345,
0.05010652169585228,
0.05595233291387558,
0.08721072971820831,
-0.02766953594982624,
0.038595203310251236,
-0.0015324580017477274,
0.0389091819524765,
-0.0325... |
ac26f7e6-444f-527f-a181-72ae69380f18 | /documentation/migration-guidance/search-quality/ | Search Quality | Tier 3: Gold-Standard Evaluation (When You Have Labeled Data) > Building an Evaluation Set | documentation | true | Search Quality > Tier 3: Gold-Standard Evaluation (When You Have Labeled Data) > Building an Evaluation Set
If you don't have labeled data, here are three practical approaches to build one:
Approach A: Click/Conversion Logs (Lowest Effort)
If your application logs user interactions (clicks, purchases, bookmarks, sha... | [
0.0013576390920206904,
-0.05578390881419182,
-0.06684893369674683,
-0.05101874843239784,
0.03740628436207771,
-0.04648713394999504,
0.06738777458667755,
0.024980423972010612,
0.0579916350543499,
-0.043882519006729126,
-0.005998307839035988,
0.011721167713403702,
0.07878915220499039,
-0.031... |
ac3f8400-abed-5f5b-877a-c25ba699079a | /documentation/examples/ | Build Prototypes | Example Notebooks | documentation | false | Build Prototypes > Example Notebooks
Our Notebooks offer complex instructions that are supported with a thorough explanation. Follow along by trying out the code and get the most out of each example.
| Example ... | [
0.044996798038482666,
-0.061570778489112854,
-0.047854501754045486,
-0.06195048615336418,
0.09723526984453201,
-0.034093227237463,
0.059522517025470734,
0.051558688282966614,
0.0769398882985115,
-0.047359392046928406,
0.025843866169452667,
0.03731606900691986,
0.041573021560907364,
-0.0583... |
ac42d3d1-5153-5dd7-943d-b5ca590c410e | /documentation/embeddings/twelvelabs/ | TwelveLabs | Next Steps | documentation | false | TwelveLabs > Next Steps
- [Filter search results](/documentation/search/filtering/) by payload fields such as `embedding_option`, `video_url`, or the segment time range.
- [Use named vectors](/documentation/manage-data/vectors/#named-vectors) to store visual and audio embeddings of a segment in one point.
- Read the T... | [
0.04545408859848976,
-0.04539468511939049,
-0.03188971430063248,
-0.03895154595375061,
0.050581563264131546,
-0.0008496351656503975,
0.04367847740650177,
0.029020696878433228,
0.05648089945316315,
-0.02919733338057995,
0.039560891687870026,
0.017958590760827065,
0.08112102746963501,
-0.002... |
ac4485b0-8a72-5783-a456-01b69f4abbba | /documentation/tutorials-basics/search-beginners/ | Semantic Search 101 | 4. Upload Data to the Cluster | documentation | true | Semantic Search 101 > 4. Upload Data to the Cluster
The dataset consists of a list of science fiction books. Each entry has a name, author, publication year, and short description.
```python
documents = [
{
"name": "The Time Machine",
"description": "A man travels through time and witnesses the ev... | [
0.050909191370010376,
-0.010120382532477379,
-0.05741609260439873,
-0.04305286705493927,
0.07401642948389053,
-0.018365727737545967,
0.05813448876142502,
0.07837802916765213,
0.03646751493215561,
-0.013440709561109543,
0.014046193100512028,
0.02640800178050995,
0.07147347182035446,
-0.0169... |
ac482acf-60fd-5407-9910-2bc97453dc1a | /course/beginners/module-6/find-your-problem/ | Find Your Problem | course | false | Find Your Problem
Module 6
Each row pairs a problem with the feature that addresses it, and names the stage of a query where it runs.
| Problem | Feature | Stage |
|---------|---------|-------|
| The right documents come back in the wrong order | [Score boosting](/documentation/search/search-relevance/#score-boostin... | [
0.02182403951883316,
-0.020407693460583687,
-0.024942373856902122,
-0.017651643604040146,
0.0655045285820961,
-0.030689086765050888,
0.009854251518845558,
0.04886344447731972,
0.07620897889137268,
-0.010838381014764309,
0.008694467134773731,
0.03746706619858742,
0.04003191366791725,
-0.031... | |
ac50e97c-420f-5bf9-b8b9-a23c1aadb4da | /articles/sparse-vectors/ | Understanding SPLADE and Sparse Vectors | Hybrid search: combining sparse and dense vectors | article | true | Understanding SPLADE and Sparse Vectors > Hybrid search: combining sparse and dense vectors
By combining search results from both dense and sparse vectors, you can achieve a hybrid search that is both efficient and accurate.
Sparse vectors favor results that contain the query's keywords, while dense vectors cover sema... | [
0.055180709809064865,
-0.04222043976187706,
-0.04457507282495499,
-0.057883311063051224,
0.06368453800678253,
-0.052880123257637024,
0.09402170032262802,
0.043951284140348434,
0.07647529244422913,
-0.05376959219574928,
0.033313412219285965,
0.026547493413090706,
0.048240866512060165,
0.001... |
ac669d99-5eef-5d93-b8bb-de3eeb77e07c | /course/essentials/day-2/pitstop-project/ | Project: HNSW Performance Benchmarking | Success Criteria | course | false | Project: HNSW Performance Benchmarking > Success Criteria
You'll know you've succeeded when:
You've tested multiple HNSW configurations with real timing data
You can explain which settings work best for your domain and why
You've measured the concrete impact of payload indexing
You have clear recommendations... | [
0.011076838709414005,
-0.03194107860326767,
-0.035902105271816254,
-0.03561144694685936,
0.018025409430265427,
-0.06561308354139328,
0.06791228801012039,
0.05401775240898132,
0.05971778184175491,
-0.020359845831990242,
0.011415905319154263,
0.029918687418103218,
0.039687205106019974,
-0.05... |
ac77a407-eb93-54d0-af1f-63065600e31a | /documentation/tutorials-build-essentials/video-anomaly-edge-part-2/ | Video Anomaly Detection Part 2: Edge-to-Cloud Pipeline | Fleet Management | documentation | true | Video Anomaly Detection Part 2: Edge-to-Cloud Pipeline > Fleet Management
A real deployment has dozens of edge devices, not one. The cloud backend tracks each Jetson independently through a device registry.
Each device registers itself on first boot:
```python
POST /api/edges/register
{
"name": "north-entrance-cam... | [
0.04358185827732086,
-0.018043039366602898,
-0.04891778901219368,
-0.041993558406829834,
0.02146933227777481,
0.0037182176019996405,
0.013433539308607578,
0.019930949434638023,
0.06526361405849457,
-0.054332975298166275,
0.023063410073518753,
0.024195468053221703,
0.0660407617688179,
-0.03... |
ac7b71b6-3097-55f7-8253-45b8aa25672d | /documentation/manage-data/quantization/ | Quantization | Setting Up Quantization in Qdrant > Setting Up TurboQuant | documentation | true | Quantization > Setting Up Quantization in Qdrant > Setting Up TurboQuant
To enable TurboQuant, specify it in the `quantization_config` section of the collection configuration.
When enabling TurboQuant on an existing collection, use a PATCH request or the corresponding `update_collection` method and omit the vector co... | [
0.028256235644221306,
-0.07357022166252136,
-0.019332120195031166,
-0.03635988384485245,
0.023311492055654526,
-0.014433485455811024,
0.03500885143876076,
0.07489022612571716,
0.07861597090959549,
-0.01778835989534855,
0.0457804873585701,
0.03731347620487213,
0.03507224842905998,
-0.050233... |
ac995afd-8197-5484-b384-9bed488fc6ee | /documentation/faq/qdrant-fundamentals/ | Qdrant Fundamentals | Collections > Can I delete the original full-precision vectors after enabling quantization? | documentation | false | Qdrant Fundamentals > Collections > Can I delete the original full-precision vectors after enabling quantization?
No. Qdrant requires the original full-precision vectors to recompute quantized representations whenever the Vacuum Optimizer rebuilds a segment. Qdrant derives quantization statistics (offset and alpha) fr... | [
0.05127156153321266,
-0.027979301288723946,
-0.028880862519145012,
-0.0553656667470932,
0.054068680852651596,
0.002837313571944833,
0.05581727996468544,
0.037627287209033966,
0.09983471035957336,
-0.04542681574821472,
0.05912322551012039,
0.05338422954082489,
0.04948776587843895,
-0.068658... |
aca80d28-de35-5c12-a4b5-3d17276e5a00 | /documentation/edge/edge-api/ | Edge API | documentation | false | Edge API
To work with a Qdrant Edge Shard, use the [Python Bindings for Qdrant Edge](https://pypi.org/project/qdrant-edge-py/) package or the [`qdrant-edge` Rust crate](https://crates.io/crates/qdrant-edge). Both expose an `EdgeShard` type with methods to manage data, query it, and restore snapshots.
For task-oriente... | [
0.029407411813735962,
-0.039868976920843124,
-0.03311992064118385,
-0.025368763133883476,
0.06443455815315247,
-0.06463924795389175,
0.0789281353354454,
0.0010264654411002994,
0.09313154220581055,
-0.022844523191452026,
0.0756714940071106,
0.0011293689021840692,
0.055124953389167786,
0.008... | |
aca83747-aec6-5be0-a4bc-137f9d5fdd01 | /documentation/search/hybrid-queries/ | Hybrid Queries | Multi-Stage Queries > Custom Scoring with a Formula Query | documentation | true | Hybrid Queries > Multi-Stage Queries > Custom Scoring with a Formula Query
_Available as of v1.14.0_
A formula query lets you compose a final score from prefetch scores (`$score`), payload fields, and built-in helpers like exponential or Gaussian decay. The typical pattern is to fuse retrievers with RRF or DBSF in a ... | [
0.03891927748918533,
0.0021473714150488377,
-0.022707849740982056,
-0.08919729292392731,
0.0464298315346241,
-0.03533916547894478,
0.024180399253964424,
0.01065833866596222,
0.08862519264221191,
-0.04044315963983536,
0.01974853128194809,
-0.0006170018459670246,
0.05735713988542557,
0.00006... |
acd6a824-461a-5a6c-bd4c-56da6e36e7b1 | /documentation/search/hybrid-queries/ | Hybrid Queries | Hybrid Search | documentation | false | Hybrid Queries > Hybrid Search
One of the most common problems when you have different representations of the same data is to combine the queried points for each representation into a single result.
For example, in text search, it is often useful to combine dense vectors with [BM25 full-text search](/documentation/se... | [
0.0535428449511528,
-0.04309060797095299,
-0.051651936024427414,
-0.0546051524579525,
0.062216613441705704,
-0.050399839878082275,
0.059807322919368744,
0.021028421819210052,
0.05952147766947746,
0.0018446523463353515,
0.05128477141261101,
0.018997354432940483,
0.06767911463975906,
-0.0201... |
acdf6d2f-ee6c-533a-a9f0-2dfe6e2a0d0f | /articles/dedicated-vector-search/ | Why Vector Search Needs a Dedicated Database | Objections to a Dedicated Service > "Synchronization is too complex" | article | false | Why Vector Search Needs a Dedicated Database > Objections to a Dedicated Service > "Synchronization is too complex"
It is extra work, and it is worth being honest about that: a second system needs deployment, monitoring, access control, and a pipeline that keeps it in step with the source of truth.
Most teams already... | [
0.0007203962304629385,
-0.03486844152212143,
-0.070414237678051,
-0.03809085488319397,
0.062307409942150116,
-0.021215856075286865,
0.04240337759256363,
0.017855023965239525,
0.07482362538576126,
-0.0007312021916732192,
0.03364499285817146,
0.028556885197758675,
0.05532491207122803,
-0.026... |
acefe51e-4de1-5514-8078-efbed533b492 | /documentation/manage-data/bulk-upload/ | Bulk Upload | Batch Your Uploads | documentation | false | Bulk Upload > Batch Your Uploads
[Upsert points in batches](/documentation/manage-data/points/#upload-points) rather than one at a time. Each request to Qdrant carries overhead: network round-trip, Write-Ahead Log (WAL) write, and internal routing. When you upload points individually, that overhead impacts the through... | [
-0.010963879525661469,
-0.039909593760967255,
-0.04902200773358345,
-0.040913332253694534,
0.08750558644533157,
-0.03073234111070633,
0.038542356342077255,
0.05652964115142822,
0.0880122259259224,
-0.015204066410660744,
0.03740302845835686,
-0.00607378501445055,
0.00886341743171215,
-0.030... |
acf05a53-6f09-515c-ae63-12bddac0b60e | /articles/hyperbolic-embeddings-qdrant/ | Why Hyperbolic Embeddings Matter for Hierarchical Data | Superpowers of Hyperbolic Embeddings | article | false | Why Hyperbolic Embeddings Matter for Hierarchical Data > Superpowers of Hyperbolic Embeddings
Matching the geometry to the data can make an embedding more compact and give its coordinates more meaning. Two useful examples are dimensional efficiency and radius as a measure of specificity. | [
0.04938870295882225,
-0.00014110204938333482,
-0.03618800267577171,
-0.08150984346866608,
0.05264086648821831,
-0.045071132481098175,
0.09497597068548203,
0.07934793829917908,
0.07292813807725906,
-0.005591030698269606,
0.014261309057474136,
0.02934277430176735,
0.09501028805971146,
-0.040... |
acf5c17b-bbe9-575d-a015-1733ebe29a1e | /documentation/manage-data/points/ | Points | Upload Points > Named Vectors | documentation | true | Points > Upload Points > Named Vectors
_Available as of v0.10.0_
If the collection was created with multiple vectors, each vector data can be provided using the vector's name:
```python
client.upsert(
collection_name="{collection_name}",
points=[
models.PointStruct(
id=1,
vect... | [
0.02246592938899994,
-0.03158681467175484,
-0.02713795192539692,
-0.03537452593445778,
0.038570646196603775,
-0.050380412489175797,
0.03547625243663788,
0.047462403774261475,
0.06622631102800369,
-0.037095777690410614,
0.013709326274693012,
0.04822979122400284,
0.032270994037389755,
-0.020... |
ad0e6dca-83f5-5457-96c1-8afef0d71d29 | /documentation/cloud/cluster-scaling/ | Scale Clusters | documentation | false | Scale Clusters
The amount of data is always growing and at some point you might need to change the capacity of your cluster. You can easily scale your Qdrant cluster up or down from the Cluster detail page in the Qdrant Cloud console.
 | [
0.02432480826973915,
-0.022117184475064278,
-0.042939040809869766,
-0.0747557133436203,
0.06447307765483856,
-0.057518668472766876,
0.04046396166086197,
0.04862106591463089,
0.06763865798711777,
-0.05829044431447983,
0.040762417018413544,
0.019658682867884636,
0.06497401744127274,
-0.02378... | |
ad103fc4-6a89-5c08-9ce9-f41923c61a1e | /documentation/tutorials-search-engineering/sparse-embeddings-ecommerce-part-3/ | Fine-Tuning Sparse Embeddings for E-Commerce Search | Part 3: Evaluation and Hard Negatives | ANCE-inspired Hard Negative Mining > When to Use ANCE-inspired Mining | documentation | false | Fine-Tuning Sparse Embeddings for E-Commerce Search | Part 3: Evaluation and Hard Negatives > ANCE-inspired Hard Negative Mining > When to Use ANCE-inspired Mining
This approach adds complexity. You need to:
1. Index products with the current model
2. Run retrieval for all training queries
3. Filter and format the res... | [
0.040470413863658905,
-0.06656146049499512,
-0.047832995653152466,
-0.03172396123409271,
0.057973869144916534,
-0.057017382234334946,
0.05657940357923508,
0.037293024361133575,
0.0618593692779541,
0.0009468725766055286,
0.026152700185775757,
0.037557970732450485,
0.065213143825531,
-0.0473... |
ad4c7645-6d7a-5367-8c83-c4286f190f77 | /articles/relevance-feedback/ | Relevance Feedback in Qdrant | Our Idea > Sketch of the Method | article | false | Relevance Feedback in Qdrant > Our Idea > Sketch of the Method
So, stepping away from analogies (into an even deeper forest), the algorithm should consist of:
1. Initial retrieval.
2. Getting a small amount of feedback (within the **context limit**) on the results of this initial retrieval.
> A **context limit** is... | [
0.0552789606153965,
-0.056147463619709015,
-0.03916039690375328,
-0.062291450798511505,
0.05281299352645874,
0.0062288944609463215,
0.030067097395658493,
0.015843944624066353,
0.06934027373790741,
-0.027175940573215485,
0.04876561462879181,
0.009584114886820316,
0.08386676013469696,
-0.028... |
ad69dd76-2b81-554a-9919-7c0c1095b231 | /articles/filtered-vector-search-acorn/ | Filtered Vector Search: What ACORN Fixes, and What Fixes ACORN | Double Filters: The Intersection Gap | article | false | Filtered Vector Search: What ACORN Fixes, and What Fixes ACORN > Double Filters: The Intersection Gap
At 0.012%, roughly 120 points match in a million, and the graph stops being the right tool. Planner + ACORN wins that row by reading the payload index instead. The choice happens per query: on the 1% intersection it s... | [
0.023411724716424942,
-0.03486199304461479,
-0.04049153998494148,
0.008900413289666176,
0.09203238785266876,
0.02565528079867363,
0.03552812337875366,
0.023631993681192398,
0.049953918904066086,
0.01716633327305317,
0.05555165559053421,
0.02812482789158821,
0.04117392748594284,
0.007332286... |
ad71f5c2-8f11-5483-b40a-b6fe8660a9ab | /documentation/search/text-search/ | Text Search | Semantic Search | documentation | true | Text Search > Semantic Search
Semantic search is a search technique that focuses on the meaning of the text rather than just matching on keywords. This is achieved by converting text into [vectors](/documentation/manage-data/vectors/) (embeddings) using machine learning models. These vectors capture the semantic meani... | [
0.04617626965045929,
-0.05713479593396187,
-0.04814771190285683,
-0.03815919905900955,
0.07650423049926758,
-0.013159014284610748,
0.07190445065498352,
0.018302535638213158,
0.030531074851751328,
-0.019175691530108452,
0.031364746391773224,
0.024574534967541695,
0.0598442517220974,
-0.0321... |
ae19aff5-9eb0-5a2f-9a70-35c841fa35d4 | /documentation/embeddings/twelvelabs/ | TwelveLabs | Search Across Modalities | documentation | true | TwelveLabs > Search Across Modalities
Because all modalities share one vector space, a query can be an audio clip or an image instead of text. Pass the file in `media_sources`. These examples also filter on the `embedding_option` payload field: the audio query searches the audio embeddings of the video, and the image ... | [
0.05669977515935898,
-0.06539519876241684,
-0.061159905046224594,
-0.03134959936141968,
0.06896262615919113,
-0.0007036715396679938,
0.05996261164546013,
0.046532027423381805,
0.003948027268052101,
-0.008320546709001064,
0.05430614948272705,
-0.0056349183432757854,
0.04501066356897354,
-0.... |
ae1fe484-b26d-5bac-af57-f23a194043aa | /documentation/search-evaluation/retrieval-relevance/ | Measuring Retrieval Relevance | Pitfalls to Watch For | documentation | false | Measuring Retrieval Relevance > Pitfalls to Watch For
In golden sets, **data leakage** means any setup that makes offline metrics misrepresent production quality. Unlike classic train/test leakage, the issue is often evaluation design. Keep source documents in the index (they are the expected relevant answers). Focus ... | [
0.032584741711616516,
-0.03123348206281662,
-0.08699559420347214,
-0.0314757376909256,
0.031751394271850586,
-0.015490367077291012,
0.0696307048201561,
0.027750037610530853,
0.059830356389284134,
-0.03972664102911949,
-0.00788471382111311,
0.007752181962132454,
0.07243891805410385,
-0.0093... |
ae3ed3f5-4957-5f6e-98ce-112d4eb18178 | /documentation/tutorials-build-essentials/semantic-cache/ | Semantic Caching for RAG | Set Up Cache Lookup > Optional: Resolve Hard Hits with Jev | documentation | true | Semantic Caching for RAG > Set Up Cache Lookup > Optional: Resolve Hard Hits with Jev
The idea: keep the "sure" threshold from the previous step, and add a gray zone under it, where a second model (classifier, in our case Jev) double-checks the cache.
[Jev](https://docs.typesafe.ai/introduction) is a model by TypeSaf... | [
0.054229311645030975,
-0.04755782335996628,
-0.05463080108165741,
-0.033393096178770065,
0.020330039784312248,
0.0014114233199506998,
0.02787552960216999,
0.012193670496344566,
0.01692139357328415,
-0.04664778336882591,
0.03781457990407944,
0.015925103798508644,
0.06751198321580887,
-0.012... |
ae63b8a4-2149-5d91-a3d6-8af6de8982c7 | /documentation/manage-data/indexing/ | Indexing | Full-Text Index > BM25 Scoring | documentation | true | Indexing > Full-Text Index > BM25 Scoring
*Available as of v1.20.0*
With scoring enabled, a full-text index can rank points by how relevant their text is to a query, using the [BM25](/documentation/search/text-search/full-text-search/#bm25) ranking function. To enable scoring, set the `scoring` type to `bm25` when yo... | [
0.014288149774074554,
-0.012561109848320484,
-0.02886565588414669,
-0.04772434011101723,
0.05107521638274193,
-0.057573262602090836,
0.024015478789806366,
0.047624826431274414,
0.09746348112821579,
-0.026252008974552155,
0.0733204334974289,
0.03746585175395012,
0.04652521014213562,
-0.0345... |
ae7116a3-d147-5542-b605-d4d40a2b5bd3 | /documentation/common-errors/ | Troubleshooting | Using python gRPC client with multiprocessing | documentation | true | Troubleshooting > Using python gRPC client with multiprocessing
When using the Python gRPC client with `multiprocessing`, you may encounter an error like this:
```text
<_InactiveRpcError of RPC that terminated with:
status = StatusCode.UNAVAILABLE
details = "sendmsg: Socket operation on non-socket (88)"
debug_erro... | [
0.015170320868492126,
-0.018588174134492874,
-0.005826809909194708,
-0.014621606096625328,
0.09788203239440918,
-0.0359075553715229,
0.07330984622240067,
0.03236105665564537,
0.07404129207134247,
-0.007947935722768307,
0.026631569489836693,
0.009033815935254097,
0.050973210483789444,
-0.04... |
ae8215c2-f625-5aae-b1d4-279e6cb48ef4 | /articles/rag-is-dead/ | Is RAG Dead? Why Long Context Windows Don't Replace RAG | Where retrieval still wins | article | false | Is RAG Dead? Why Long Context Windows Don't Replace RAG > Where retrieval still wins
- **The data does not fit.** A 1 million token window holds about 2,500 pages, using Anthropic's ratio of 500 pages per 200,000 tokens. Enterprise knowledge bases are often much larger.
- **The data changes.** An index updates increme... | [
-0.0018718914361670613,
-0.04461942985653877,
-0.06025642901659012,
-0.045244552195072174,
0.078097403049469,
-0.022419797256588936,
0.005319095216691494,
0.025709494948387146,
0.0675043836236,
-0.039853401482105255,
0.01376471109688282,
0.001995739294216037,
0.07105550915002823,
-0.041399... |
ae8da9d2-4450-5d85-898c-ceb99e840155 | /documentation/search/search-relevance/ | Search Relevance | Score Boosting > Hyperbolic Distance | documentation | true | Search Relevance > Score Boosting > Hyperbolic Distance
_Available as of v1.19.1_
The `acosh` expression returns the inverse hyperbolic cosine of a single expression, like `sqrt`, `ln`, and `exp`. Use it to rescore hyperbolic embeddings, which place hierarchical data in the Poincaré ball or on the Lorentz hyperboloid... | [
0.07527398318052292,
-0.00797511637210846,
-0.010363161563873291,
-0.010624143294990063,
0.08241459727287292,
-0.01047966256737709,
0.05433864891529083,
0.01291411742568016,
0.09232132136821747,
-0.020171919837594032,
0.027912084013223648,
0.029071656987071037,
0.06737492233514786,
0.00060... |
ae9145dd-bc1d-592c-aad7-bfe617e5d056 | /documentation/cloud/authentication/ | Authentication | Create Database API Keys | documentation | false | Authentication > Create Database API Keys
The API key is only shown once after creation. If you lose it, you will need to create a new one.

1. Go to the [Cloud Dashboard](https://qdrant.to/cloud).
2. Go to the **API Keys** section of the **Cluster Detail Page**.
3.... | [
0.00435075256973505,
-0.009124030359089375,
-0.023679064586758614,
-0.04890887439250946,
0.05809621512889862,
-0.05851893126964569,
-0.015571974217891693,
0.039688751101493835,
0.06498949229717255,
-0.07002054154872894,
0.009278792887926102,
0.041614580899477005,
0.06484103947877884,
-0.03... |
aeaa3ac6-ac63-5465-a6b8-d7f7b10a4dbf | /documentation/cloud-rbac/permission-reference/ | Permission Reference | Payment & Billing | documentation | false | Permission Reference > Payment & Billing
Permissions for payment methods and billing information.
| Permission | Description |
|------------|------------|
| `read:payment_information` | View payment methods and billing details. |
| `write:payment_information` | Modify or remove payment methods and billing details. |
... | [
0.013158380053937435,
-0.01174924336373806,
-0.043712031096220016,
-0.08089631050825119,
0.031704436987638474,
-0.017614955082535744,
0.024777520447969437,
0.1087203249335289,
0.12642794847488403,
-0.025335116311907768,
0.04653412848711014,
0.009972484782338142,
0.06885569542646408,
-0.011... |
aebd8909-6627-55fe-970c-f9cf6b98b57f | /documentation/search-tuning/hybrid-search/ | Hybrid Search in Qdrant | Measure Whether It Helps | documentation | false | Hybrid Search in Qdrant > Measure Whether It Helps
Across five public datasets, default RRF beat the stronger individual retriever on four.
Run the same labeled queries with dense retrieval, sparse retrieval, and fusion. Keep the models and candidate limits unchanged. Score each run with `nDCG@10`, which gives more c... | [
0.04060739651322365,
-0.028016533702611923,
-0.06813880801200867,
-0.04219523444771767,
0.06504163891077042,
-0.05918165296316147,
0.06736038625240326,
0.05325126647949219,
0.04467882961034775,
-0.04081244021654129,
0.021234706044197083,
0.021599750965833664,
0.034644901752471924,
-0.01213... |
aec834e6-9cdc-570e-9b88-701f21f0624f | /course/beginners/module-5/signal-sources-and-embedding-models/ | Signal Sources and Embedding Models | The Same Pattern Extends to Audio and Video | course | true | Signal Sources and Embedding Models > The Same Pattern Extends to Audio and Video
Nothing above is specific to articles and satellite tiles. An earnings call becomes text once it is transcribed, and video becomes images once frames are sampled, and both then take a path this module already covers: a transcript is chun... | [
0.051502775400877,
-0.054574813693761826,
-0.010911243967711926,
-0.04601838439702988,
0.05137275904417038,
-0.04232050105929375,
0.06060635671019554,
0.03027247078716755,
0.052807461470365524,
-0.021473485976457596,
-0.013287386856973171,
0.012220228090882301,
0.04872377961874008,
-0.0374... |
aecf2a39-8dcd-5a58-945e-984220187e08 | /course/essentials/day-1/embedding-models/ | Points, Vectors and Payloads | Payloads (Metadata) > Filtering Capabilities Reference | course | false | Points, Vectors and Payloads > Payloads (Metadata) > Filtering Capabilities Reference
| Filter Type | Description | Example Query |
|-------------|-------------|---------------|
| **Match** | Exact value | `"match": {"value": "electronics"}` |
| **Match Any** | OR condition | `"match": {"any": ["red", "blue"]}` |
| **... | [
0.018055962398648262,
-0.02933274209499359,
-0.04340231418609619,
-0.040567632764577866,
0.04642214626073837,
-0.009700523689389229,
0.06148965656757355,
0.04714681953191757,
0.07752995938062668,
-0.040798235684633255,
0.046205487102270126,
0.0163180623203516,
0.01487020868808031,
-0.04356... |
aed41d12-9afc-574e-846a-78a2e30316b9 | /course/essentials/day-7/llamaindex/ | Integrating with LlamaIndex | LlamaIndex Agent Development Framework | course | false | Integrating with LlamaIndex > LlamaIndex Agent Development Framework
LlamaIndex provides a comprehensive framework for building sophisticated LLM applications with Qdrant integration. The platform supports multiple deployment options including local Qdrant instances, Qdrant Cloud, and Llama Cloud with Qdrant Cloud syn... | [
0.01006498746573925,
-0.02246403880417347,
-0.0657740980386734,
-0.05661406368017197,
0.06909193098545074,
-0.031049158424139023,
0.0815296322107315,
0.02821064554154873,
0.07858525216579437,
-0.03839033842086792,
0.046460527926683426,
0.026867728680372238,
-0.014473194256424904,
-0.005992... |
aef4585e-8f36-5c96-abf1-a1923ab9ab97 | /documentation/ops-optimization/optimizer/ | Optimizer | Prevent Reads from Large Unindexed Segments | documentation | true | Optimizer > Prevent Reads from Large Unindexed Segments
*Available as of v1.17.1*
prevent_unoptimized is an experimental feature; its behavior may change slightly in future releases and it must be used with care.
When a collection receives a high volume of updates, for example, during nightly batch updates or when p... | [
0.03748752549290657,
-0.031973179429769516,
-0.06327682733535767,
-0.038065310567617416,
0.07181383669376373,
-0.03822236508131027,
0.028551917523145676,
0.02409486472606659,
0.0804099589586258,
-0.01920587196946144,
0.04998373985290527,
0.024138128384947777,
0.07309646904468536,
-0.047820... |
aef9f621-c6ee-5123-880b-7a440195d342 | /documentation/frameworks/camel/ | CamelAI | documentation | true | CamelAI
[Camel](https://www.camel-ai.org) is a Python framework to build and use LLM-based agents for real-world task solving.
Qdrant is available as a storage mechanism in Camel for ingesting and retrieving semantically similar data.
## Usage With Qdrant
- Install Camel with the `vector-databases` extra.
```bash
... | [
0.051882315427064896,
-0.03488859534263611,
-0.0399087518453598,
-0.0431089773774147,
0.06135306879878044,
-0.032363396137952805,
0.06430751085281372,
0.02775290235877037,
0.03694061562418938,
-0.026135656982660294,
0.03795893117785454,
-0.02438834309577942,
0.05299951508641243,
-0.0270059... | |
af21dd5c-5172-54cc-a63d-2f1eaf6b3828 | /course/essentials/day-3/sparse-retrieval-demo/ | Demo: Keyword Search with Sparse Vectors | Sparse Neural Retrieval > Beyond SPLADE > Qdrant's Sparse Neural Retrievers | course | false | Demo: Keyword Search with Sparse Vectors > Sparse Neural Retrieval > Beyond SPLADE > Qdrant's Sparse Neural Retrievers
We’ve been exploring sparse neural retrieval as a promising approach for domains where keyword-based matching is useful, but traditional methods like BM25 fall short due to their lack of semantic unde... | [
0.06078833341598511,
-0.024417294189333916,
-0.02122313156723976,
-0.03683246672153473,
0.06678961962461472,
-0.06117275357246399,
0.07962412387132645,
0.040569957345724106,
0.04086653143167496,
-0.013126915320754051,
0.03615739941596985,
0.029989805072546005,
0.057595137506723404,
-0.0165... |
af234729-ce79-537d-8c90-95e608eecd4c | /course/essentials/day-1/chunking-strategies/ | Text Chunking Strategies | Key Takeaways | course | false | Text Chunking Strategies > Key Takeaways
1. **Chunking strategy directly impacts search quality** - choose based on your text data and use case
2. **Smaller, focused chunks provide more precise results** than whole document embeddings
3. **Metadata is crucial** for filtering, grouping, and result presentation
4. **D... | [
0.008142990060150623,
-0.04304591193795204,
-0.058857470750808716,
-0.02728225849568844,
0.028970519080758095,
-0.013944622129201889,
0.04291946068406105,
0.00867264624685049,
0.06769507378339767,
-0.026145974174141884,
0.014703945256769657,
-0.008643613196909428,
0.06983785331249237,
-0.0... |
af23d33d-0ffd-5115-89d8-b9f0fbd46395 | /documentation/cloud-api/ | Qdrant Cloud API | Introduction | documentation | false | Qdrant Cloud API > Introduction
The Qdrant Cloud API lets you automate the Qdrant Cloud platform. You can use this API to manage your accounts, clusters, backup schedules, authentication methods, hybrid cloud environments, and more.
To cater to diverse integration needs, the Qdrant Cloud API offers two primary intera... | [
0.0115364333614707,
-0.014875796623528004,
-0.025717949494719505,
-0.04051889851689339,
0.05444376543164253,
-0.03570514917373657,
0.09314047545194626,
0.0714535340666771,
0.07673279196023941,
-0.035925038158893585,
0.03692349046468735,
0.036761172115802765,
0.033499374985694885,
-0.058838... |
af2de701-48ec-5195-b9cb-f61d7a2f5132 | /course/multi-vector-search/module-3/multi-stage-retrieval/ | Multi-Stage Retrieval with Universal Query API | Why Multi-Stage Retrieval? | course | false | Multi-Stage Retrieval with Universal Query API > Why Multi-Stage Retrieval?
You've learned that multi-vector representations like ColBERT provide superior search quality compared to single-vector embeddings. But there's a challenge: **computing MaxSim for every document in a large collection is expensive**.
Here's th... | [
0.016349591314792633,
-0.043032679706811905,
-0.010239196941256523,
-0.020671380683779716,
0.06252561509609222,
-0.03528500348329544,
0.05931908264756203,
0.009309537708759308,
0.05416663736104965,
-0.007801384199410677,
0.02194284275174141,
0.029892927035689354,
0.09918113052845001,
-0.04... |
af2f699a-7ac4-50d0-a357-aa2b7d29d8df | /articles/sparse-vectors/ | Understanding SPLADE and Sparse Vectors | Why SPLADE works: term expansion > How SPLADE works: leveraging BERT | article | false | Understanding SPLADE and Sparse Vectors > Why SPLADE works: term expansion > How SPLADE works: leveraging BERT
SPLADE leverages a transformer architecture to generate sparse representations of documents and queries, enabling efficient retrieval. Let's dive into the process.
The output logits from the transformer back... | [
0.04650697112083435,
-0.05585120990872383,
-0.059133268892765045,
-0.03784190118312836,
0.026747485622763634,
-0.028045013546943665,
0.0690150037407875,
0.026347767561674118,
0.07316427677869797,
-0.034084901213645935,
0.010171615518629551,
0.014812678098678589,
0.023880578577518463,
0.011... |
af3ac165-d877-5090-8391-25bbfe53ef9a | /articles/what-is-vector-quantization/ | What is Vector Quantization? | 2. What is Binary Quantization? | article | false | What is Vector Quantization? > 2. What is Binary Quantization?
These models demonstrate minimal accuracy loss while still benefiting from substantial speed and memory gains.
Even though Binary Quantization is incredibly fast and memory-efficient, the trade-offs are in **precision** and **model compatibility**, so you... | [
0.029746735468506813,
-0.05730576440691948,
-0.029892435297369957,
-0.047179482877254486,
0.048863768577575684,
0.004615024663507938,
0.046998441219329834,
0.022743944078683853,
0.1118893027305603,
-0.032895948737859726,
0.04838055372238159,
-0.0017769234254956245,
0.06976930797100067,
-0.... |
af455769-db41-5b78-81a4-84febb995350 | /course/essentials/day-3/sparse-retrieval-demo/ | Demo: Keyword Search with Sparse Vectors | Text Encoding | course | true | Demo: Keyword Search with Sparse Vectors > Text Encoding
In sparse vectors, each non‑zero dimension represents an object that plays a specific role for the item being represented. When we work with text, the natural choice for these objects is words.
A corpus, a finite set of texts, makes it feasible to collect every... | [
0.05821654200553894,
-0.048546407371759415,
-0.02610020339488983,
-0.07137860357761383,
0.07984814792871475,
-0.038561735302209854,
0.05163319408893585,
0.03241666406393051,
0.05410139635205269,
-0.018983369693160057,
0.0016318579437211156,
0.013084729202091694,
0.051513947546482086,
-0.01... |
af469e4e-0f27-554f-a234-ce7941b0f273 | /documentation/ops-monitoring/monitoring/ | Monitoring & Telemetry | Metrics > Node Metrics /metrics | documentation | false | Monitoring & Telemetry > Metrics > Node Metrics /metrics
| Name | Type | Meaning |
| ----------------------------------- | --------- | ------------------------------------------------------------------ |
| rest_responses_tot... | [
-0.012751331552863121,
-0.019343016669154167,
-0.030881032347679138,
-0.007104514166712761,
0.05806586518883705,
-0.026376305148005486,
0.07167977839708328,
0.07416398823261261,
0.08845555782318115,
-0.06521996110677719,
0.07465632259845734,
0.02346016652882099,
0.03251311182975769,
-0.032... |
af61cf10-dace-56bd-9acd-b1108bf01824 | /course/beginners/module-5/clustering-risk-signals/ | Clustering Risk Signals | The Clustering Approach | course | false | Clustering Risk Signals > The Clustering Approach
- **Cluster assignment**: retrieve the day's vectors with `scroll`, run a lightweight k-means (a standard algorithm that groups vectors around k center points) over them, and write a `cluster_id` back to each point.
- **Centroids**: a cluster's center point is itself a... | [
0.050068315118551254,
-0.008866551332175732,
-0.03711063414812088,
-0.0340132936835289,
0.0882292240858078,
-0.02171982079744339,
0.039459116756916046,
0.008848537690937519,
0.0740545466542244,
0.01582188531756401,
0.03802800551056862,
0.009621232748031616,
0.06171898916363716,
0.005830539... |
af62f9d4-ef00-54a2-bc32-e5f105f749b8 | /documentation/edge/edge-api/shard-lifecycle/ | Shard Lifecycle | Close an Edge Shard | documentation | true | Shard Lifecycle > Close an Edge Shard
Closes the shard and releases its resources.
```python
def close(self) -> None
```
Rust has no `close` method. `EdgeShard` implements `Drop`, so the shard is closed when it goes out of scope:
```rust
{
let shard = EdgeShard::new(path, config)?;
// ... use the shard ...
... | [
0.02530372142791748,
-0.010796001181006432,
-0.01909911446273327,
-0.013853415846824646,
0.059498436748981476,
-0.061245113611221313,
0.05626259744167328,
-0.0007099922513589263,
0.05278204753994942,
-0.01799865812063217,
0.054912351071834564,
0.02836064249277115,
0.01656091772019863,
-0.0... |
af6ee524-185c-5e6d-8ae1-05bd50cdd556 | /documentation/edge/edge-api/snapshots/ | Snapshots | Apply a Snapshot | documentation | true | Snapshots > Apply a Snapshot
Applies a snapshot to a shard that already holds data. The two languages differ in shape here.
```python
def update_from_snapshot(
self,
snapshot_path: str,
tmp_dir: Optional[str] = None,
) -> None
```
Python applies the snapshot to the open shard in place, optionally extract... | [
-0.0031240060925483704,
-0.03443007916212082,
-0.019766908138990402,
-0.01006731204688549,
0.03448764607310295,
-0.02040913887321949,
0.06657785177230835,
0.02204573154449463,
0.06084837391972542,
-0.0165557861328125,
0.04476997256278992,
0.026948804035782814,
0.02165747806429863,
0.004328... |
af82c01c-b7ab-58a9-8308-ac32ca3581da | /documentation/manage-data/indexing/ | Indexing | Full-Text Index > Tokenizers > Whitespace | documentation | false | Indexing > Full-Text Index > Tokenizers > Whitespace
The `whitespace` tokenizer splits the string on whitespace, such as spaces, tabs, and newlines. Punctuation and special characters stay part of the tokens. For example, `hello, world!` is tokenized as `hello,` and `world!`. | [
0.018314171582460403,
0.011971094645559788,
-0.01724623329937458,
-0.07018419355154037,
0.07056615501642227,
-0.031886447221040726,
0.006506028119474649,
0.03054719790816307,
0.0709887370467186,
-0.005513360258191824,
0.03318742290139198,
0.010876541957259178,
0.07763923704624176,
0.007320... |
af8a01a3-ad4b-5ab8-ae5e-07f2080e9cd6 | /course/essentials/day-1/embedding-models/ | Points, Vectors and Payloads | Payloads (Metadata) > Performance Optimization | course | true | Points, Vectors and Payloads > Payloads (Metadata) > Performance Optimization
To maximize filtering performance, create payload indexes for frequently filtered fields. Qdrant automatically optimizes query execution based on filter cardinality and available indexes.
```python
# Index frequently filtered fields
client.... | [
0.027567224577069283,
-0.024095483124256134,
-0.02435901388525963,
-0.01756514422595501,
0.06252899765968323,
-0.034762460738420486,
0.06315230578184128,
0.023253247141838074,
0.07350485026836395,
-0.03588688001036644,
0.03778677433729172,
0.017116516828536987,
0.036332424730062485,
-0.034... |
afb9af89-5a0b-5f5e-9e43-1f2ef6d0425a | /course/beginners/module-4/decide-before-you-ingest/ | Decide Before You Ingest | course | true | Decide Before You Ingest
Module 4
Four decisions belong to the data layer. Changing any one means ingesting the data again. Here's a news search example:
> Analysts at a research firm search global news as it arrives. They ask questions in plain language, such as "port congestion in Southeast Asia." They scope every... | [
0.04343784227967262,
-0.012880565598607063,
-0.07995464652776718,
-0.031651489436626434,
0.05111285299062729,
-0.013965141959488392,
0.036162108182907104,
0.030170856043696404,
0.07085296511650085,
-0.032302215695381165,
0.008152145892381668,
0.036662712693214417,
0.052330560982227325,
-0.... | |
afc26973-6d4f-5441-b69c-6dbc697b7b49 | /documentation/tutorials-build-essentials/video-anomaly-edge-part-2/ | Video Anomaly Detection Part 2: Edge-to-Cloud Pipeline | Edge-to-Cloud Escalation > Snapshot Sync from Cloud | documentation | true | Video Anomaly Detection Part 2: Edge-to-Cloud Pipeline > Edge-to-Cloud Escalation > Snapshot Sync from Cloud
The immutable shard stays current through snapshot syncing. A full sync downloads the entire indexed shard; incremental syncs use partial snapshots that only transfer changed segments:
```python
def sync_from_... | [
0.03189331293106079,
-0.05679692327976227,
-0.0526689812541008,
-0.027456119656562805,
0.011402138508856297,
0.020823124796152115,
0.060416702181100845,
-0.00826934538781643,
0.08199216425418854,
-0.0291125550866127,
0.030115777626633644,
0.0491134375333786,
0.03412516042590141,
0.01634806... |
afcffa6c-0534-5307-8a98-b18cfa45a531 | /documentation/tutorials-operations/large-scale-search/ | Large-Scale Search | Conclusion | documentation | false | Large-Scale Search > Conclusion
In this tutorial we demonstrated how to upload, index and search a large dataset in Qdrant cost-efficiently.
Binary quantization can be applied even on 512d vectors, if combined with query-time oversampling.
Qdrant allows to precisely control where each part of storage is located, whic... | [
0.046563759446144104,
-0.0507533960044384,
-0.03829408809542656,
-0.030704433098435402,
0.05464652180671692,
-0.04389900341629982,
0.09727785736322403,
0.03409016877412796,
0.10489416867494583,
-0.03453399986028671,
0.02371077984571457,
0.04262416437268257,
0.04626088961958885,
-0.04358031... |
afdd30c2-6e83-50bb-a1eb-8ac635b4ad95 | /documentation/search/explore/ | Explore | Discovery API > Discovery Search | documentation | false | Explore > Discovery API > Discovery Search
* When providing ids as examples, they will be excluded from the results.
* Score is always in descending order (larger is better), regardless of the metric used.
* Since the space is hard-constrained by the context, accuracy is normal to drop when using default settings. To ... | [
0.016222994774580002,
-0.0339680016040802,
-0.0320059098303318,
0.009599892422556877,
0.08802273124456406,
-0.026828577741980553,
0.0019748660270124674,
0.010041301138699055,
0.06815482676029205,
-0.02835104428231716,
0.015825746580958366,
0.03117249719798565,
0.052861373871564865,
-0.0184... |
aff787bd-965a-5adb-b034-d2f389f07332 | /articles/relevance-feedback/ | Relevance Feedback in Qdrant | Feedback-Based Scoring > Naive Formula > What Goes Into It | article | false | Relevance Feedback in Qdrant > Feedback-Based Scoring > Naive Formula > What Goes Into It
$\text{score}_\text{retriever}(\text{query}, \text{candidate document})$
|||
|---|---|
| What does it mean? | A similarity score between the query and the candidate embedding generated by the retriever model. F.e., cosine simila... | [
0.03436791151762009,
-0.030026070773601532,
-0.045537613332271576,
-0.04644322767853737,
0.03158256411552429,
-0.024659931659698486,
0.06474579870700836,
0.05404885113239288,
0.08117878437042236,
0.006388372741639614,
0.0031541057396680117,
0.02137567661702633,
0.04657286778092384,
-0.0358... |
b018d297-bccb-5bc2-8905-32a71d39a5d9 | /documentation/ops-configuration/administration/ | Administration | Recovery Mode | documentation | false | Administration > Recovery Mode
*Available as of v1.2.0*
Recovery mode can help in situations where Qdrant fails to start repeatedly.
When starting in recovery mode, Qdrant only loads collection metadata to prevent
going out of memory. This allows you to resolve out of memory situations, for
example, by deleting a col... | [
0.05533771589398384,
-0.04937714338302612,
-0.011538609862327576,
-0.021277017891407013,
0.0794949010014534,
-0.02917378768324852,
0.03249160572886467,
0.025982018560171127,
0.07257802039384842,
-0.01922747492790222,
0.005891184322535992,
0.014035960659384727,
0.053223442286252975,
-0.0335... |
b02171c6-3d71-5e6c-b68c-9e5bca4e3829 | /course/beginners/module-3/ | Module 3: Sparse vs Dense vs Hybrid Search | course | false | Module 3: Sparse vs Dense vs Hybrid Search
Module 3
Start with the [Module Overview](/course/beginners/module-3/module-overview/), then work through the path.
## Today's Path
1. [Where We Left Off](/course/beginners/module-3/where-we-left-off/)
2. [The Two Families of Search](/course/beginners/module-3/the-two-fami... | [
0.048441577702760696,
-0.028126060962677002,
-0.05838984623551369,
-0.02415820211172104,
0.07419117540121078,
-0.03543166443705559,
0.04977701976895332,
0.03874005004763603,
0.0748715028166771,
-0.026484955102205276,
0.048503000289201736,
0.04005054384469986,
0.04902263358235359,
0.0007570... | |
b03ad5b3-2bd1-5d52-96bd-fff2e1e2f614 | /documentation/production-operations/vector-search-in-production/ | Vector Search in Production: Scaling, HA & Tuning Guide | 3. What's the Best Way to Scale the Database and Optimize Resources? > Set up Telemetry for Early Detection | documentation | false | Vector Search in Production: Scaling, HA & Tuning Guide > 3. What's the Best Way to Scale the Database and Optimize Resources? > Set up Telemetry for Early Detection
**Use Case:** A customer in health care uses telemetry data from their Qdrant deployment to identify performance and scaling issues with their open-sourc... | [
0.012804565951228142,
-0.033221278339624405,
-0.05926208198070526,
-0.02555014193058014,
0.06252982467412949,
-0.012477733194828033,
0.026741506531834602,
0.013196051120758057,
0.08914630860090256,
-0.016736427322030067,
0.00857718475162983,
0.00043576376629061997,
0.04594035446643829,
-0.... |
b04aa708-1bf5-5470-8ff2-56c2cdef7a15 | /articles/minicoil/ | miniCOIL: on the Road to Usable Sparse Neural Retrieval | Training miniCOIL > Reducing Dimensions | article | false | miniCOIL: on the Road to Usable Sparse Neural Retrieval > Training miniCOIL > Reducing Dimensions
Dense encoder outputs are high-dimensional, so we need to perform **dimensionality reduction, which should preserve the word's meaning in context**. The goal is to:
- Avoid relevance objective and dependence on labelled ... | [
0.059165745973587036,
-0.023947013542056084,
-0.020190775394439697,
-0.0535324402153492,
0.05455499887466431,
-0.03515011817216873,
0.0386628583073616,
0.05232150852680206,
0.06425577402114868,
-0.021003125235438347,
0.026598773896694183,
0.039875857532024384,
0.12446253001689911,
-0.00075... |
b05ba058-dc12-53f2-aee6-d944a1759f8a | /documentation/manage-data/indexing/ | Indexing | Payload Index > Parameterized Index > Prefix Matching in Keyword Indices | documentation | true | Indexing > Payload Index > Parameterized Index > Prefix Matching in Keyword Indices
*Available as of v1.19.0*
By default, a `keyword` index only supports exact matching. Set the `prefix` flag to `true` to additionally enable prefix matching, so that you can filter for keyword values that start with a given string usi... | [
0.029480911791324615,
-0.032793641090393066,
-0.06453514844179153,
-0.05233082175254822,
0.08122887462377548,
-0.03949648141860962,
0.021068952977657318,
0.01403054315596819,
0.06586001813411713,
-0.029896384105086327,
0.03196023404598236,
0.006987280212342739,
0.05111674591898918,
-0.0326... |
b0798240-3ab8-5066-9a12-d9b7ff55120d | /documentation/examples/qdrant-dspy-medicalbot/ | Building a Chain-of-Thought Medical Chatbot with Qdrant and DSPy | Retrieval-Augmented Generation (RAG) Pipeline | documentation | true | Building a Chain-of-Thought Medical Chatbot with Qdrant and DSPy > Retrieval-Augmented Generation (RAG) Pipeline
Our chatbot will use a Retrieval-Augmented Generation (RAG) pipeline to ensure its answers are grounded in medical literature.
### Integration of DSPy and Qdrant
At the heart of the application is the Qdr... | [
-0.0010511318687349558,
-0.03857831656932831,
-0.04783444479107857,
-0.028006162494421005,
0.08289983123540878,
-0.025868097320199013,
0.10209223628044128,
0.03860418125987053,
0.0527033656835556,
-0.05364483222365379,
0.018194206058979034,
0.034385647624731064,
0.03751770779490471,
-0.054... |
b080233d-336b-5647-9953-2f034388a16d | /documentation/migrate-to-qdrant/from-faiss/ | From FAISS | Gotchas | documentation | false | From FAISS > Gotchas
- **No metadata:** FAISS stores only vectors, so every point has an empty payload. Point IDs are the vectors' positions in the index, which you can use to join an external metadata store.
## Next Steps
After migration, verify your data arrived correctly with the [Migration Verification Guide](/d... | [
0.007545778062194586,
-0.015671076253056526,
-0.027409899979829788,
-0.0054013910703361034,
0.038568153977394104,
-0.017575016245245934,
0.0355905257165432,
0.019386054947972298,
0.04793838411569595,
-0.03882239758968353,
0.020937370136380196,
0.0039398325607180595,
0.015380595810711384,
-... |
b08263c4-89de-59f3-a6ab-d8912aae2227 | /documentation/tutorials-search-engineering/slicing-filter/ | Deterministic Collection Slicing | documentation | false | Deterministic Collection Slicing
| Time: 20 min | Level: Intermediate | Stack: Python | Output: [GitHub](https://github.com/qdrant/examples/blob/master/slicing-filter/Slicing_Filter.ipynb) | [](https://githubtocolab.com/qdrant/examples/blob/mast... | [
0.04082508012652397,
-0.015787729993462563,
-0.07724301517009735,
-0.014628864824771881,
0.05265958234667778,
-0.011219537816941738,
0.07933297753334045,
0.03936144709587097,
0.1041506826877594,
-0.02960789017379284,
0.03303612396121025,
0.038391370326280594,
0.05900071561336517,
-0.028231... | |
b0905268-9076-5f22-a8b8-9eb6127cb4f8 | /documentation/private-cloud/changelog/ | Changelog | 1.9.5 (2026-02-18) | documentation | false | Changelog > 1.9.5 (2026-02-18)
| Component | Version |
|-------------------------|---------|
| qdrant-kubernetes-api | v1.23.0 |
| operator | 2.14.0 |
| qdrant-cluster-manager | v0.3.17 |
| qdrant-cluster-exporter | 1.7.6 |
Latest validated Qdrant version: 1.16.3
* Performance and ... | [
0.03635604679584503,
-0.03344640135765076,
-0.036421824246644974,
-0.02394392527639866,
0.038890596479177475,
-0.04954545944929123,
0.06044824793934822,
0.04019604250788689,
0.07256322354078293,
-0.0398273840546608,
0.03057856671512127,
0.020835593342781067,
0.05210437625646591,
-0.0592036... |
b0938a74-d584-55c9-897b-462cbcadea2d | /documentation/tutorials-develop/search-as-you-type/ | Semantic Search As You Type | Step 4: Prioritize the Results | documentation | true | Semantic Search As You Type > Step 4: Prioritize the Results
To improve the quality of the results, send four queries in one batch, and put the results together in this order:
1. Text matches in titles
2. Text matches in the body (paragraphs and lists)
3. Semantic matches in titles
4. Any semantic matches
Every quer... | [
0.04014035686850548,
-0.09517853707075119,
-0.04783686250448227,
-0.009990827180445194,
0.051520489156246185,
-0.021328289061784744,
0.04756893217563629,
0.011846979148685932,
0.04736009240150452,
-0.01089393813163042,
0.05118536576628685,
0.05416174978017807,
0.026923829689621925,
-0.0305... |
b0a7a0a3-1855-50de-93d1-4ec09cc72ce3 | /documentation/production-operations/bulk-data-import/ | Bulk Uploading Data to Qdrant | Option 3: Quantization to Balance Memory and Search Performance | documentation | true | Bulk Uploading Data to Qdrant > Option 3: Quantization to Balance Memory and Search Performance
_Dense vectors_
Storing original vectors on disk can help reduce memory pressure during large uploads. However, this can also make search more dependent on disk access, especially when Qdrant needs to read the original vec... | [
0.0353751964867115,
-0.05881642922759056,
-0.029507335275411606,
-0.03518856316804886,
0.05418621003627777,
-0.020666206255555153,
0.07887048274278641,
0.012892274186015129,
0.11687565594911575,
-0.0497639961540699,
0.02752624824643135,
0.050144873559474945,
0.05213475599884987,
-0.0244547... |
b0e39618-cae5-5a7d-9264-6d6d150b96f9 | /documentation/cloud-tools/terraform/ | Terraform | documentation | true | Terraform

HashiCorp Terraform is an infrastructure as code tool that lets you define both cloud and on-prem resources in human-readable configuration files that you can version, reuse, and share. You can then use a consistent workflow to provision an... | [
-0.008733737282454967,
-0.009456989355385303,
-0.06343565136194229,
-0.04752865806221962,
0.017607389017939568,
-0.029757782816886902,
0.08321008086204529,
0.014959990978240967,
0.05280529335141182,
-0.03348129242658615,
-0.007357937283813953,
0.0347265787422657,
0.041427455842494965,
-0.0... | |
b0e418b7-f600-5a7d-a183-85cee9de539d | /articles/hyperbolic-embeddings-qdrant/ | Why Hyperbolic Embeddings Matter for Hierarchical Data | Superpowers of Hyperbolic Embeddings > Radius Can Encode Specificity | article | false | Why Hyperbolic Embeddings Matter for Hierarchical Data > Superpowers of Hyperbolic Embeddings > Radius Can Encode Specificity
Precision@10 on 165 Amazon Berkeley Objects product images across six types, measured on the 512-dimensional vectors. Five types improve and one, Shoes, does not.
This is a retrieval measureme... | [
0.06568647921085358,
-0.020034173503518105,
-0.03360813111066818,
-0.06656549870967865,
0.04695408046245575,
-0.060363516211509705,
0.0495036356151104,
0.022238392382860184,
0.08065944164991379,
-0.009597341530025005,
0.033752650022506714,
0.041397664695978165,
0.07751471549272537,
-0.0701... |
b0e79307-afbe-567b-a217-0a8122766566 | /course/essentials/day-6/final-project/ | Final Project: Production-Ready Documentation Search Engine | What You'll Build | course | false | Final Project: Production-Ready Documentation Search Engine > What You'll Build
- A single collection that stores dense, sparse, and ColBERT multivectors
- A hybrid search pipeline (dense + sparse with server-side fusion)
- ColBERT reranking for fine-grained matches
- An evaluation step with Recall@10, MRR, and P50/P9... | [
0.02215743064880371,
-0.03687204420566559,
-0.08142425864934921,
-0.042259860783815384,
0.07251550257205963,
-0.020375855267047882,
0.05567561835050583,
0.04381170496344566,
0.06645283102989197,
-0.04566575586795807,
0.030468257144093513,
0.006615724414587021,
0.06125554069876671,
0.011525... |
b0f291f2-d629-5844-b50e-d373cb08a63e | /documentation/tutorials-operations/embedding-model-migration/ | Migrate to a New Embedding Model | Two Options | documentation | false | Migrate to a New Embedding Model > Two Options
The best approach to migrating to a new embedding model depends on how your collection has been configured. A blue-green migration (option 1) works with any collection type. Alternatively, if you use named vectors and your deployment is running version 1.18 or later, opti... | [
0.035274870693683624,
-0.06964293122291565,
-0.03445201367139816,
-0.05030069500207901,
0.06344550848007202,
-0.03849746659398079,
0.054436586797237396,
0.05241994187235832,
0.047133319079875946,
-0.015610995702445507,
-0.022930102422833443,
0.039920542389154434,
0.0035668646451085806,
-0.... |
b0f5121f-9e5b-58ed-b660-9d213eabc933 | /articles/neural-search-tutorial/ | Neural Search 101: A Complete Guide and Step-by-Step Tutorial | Step-by-step neural search tutorial using Qdrant > Step 1: Prepare data for neural search | article | false | Neural Search 101: A Complete Guide and Step-by-Step Tutorial > Step-by-step neural search tutorial using Qdrant > Step 1: Prepare data for neural search
To be able to search for our descriptions in vector space, we must get vectors first.
We need to encode the descriptions into a vector representation.
As the descrip... | [
0.03776310384273529,
-0.056495826691389084,
-0.04729657620191574,
-0.018598198890686035,
0.05965716391801834,
-0.01796242780983448,
0.04477471858263016,
0.04338609054684639,
0.06190725415945053,
-0.02855381742119789,
0.01106241438537836,
0.020679673179984093,
0.08152412623167038,
-0.045107... |
b0fa1708-4717-57b2-97a4-80cc336aef77 | /documentation/cloud-pricing-payments/ | Billing & Payments | Billing > Credit Card | documentation | false | Billing & Payments > Billing > Credit Card
Credit card payments are processed through Stripe. To set up a credit card, go to the Billing Details screen in the [Qdrant Cloud Console](https://cloud.qdrant.io/), select **Credit Card** as the payment method, and enter your credit card details. | [
0.03474454581737518,
-0.05610602721571922,
-0.013475720770657063,
-0.042403969913721085,
0.03913889452815056,
-0.01618540659546852,
0.026303701102733612,
0.04874502867460251,
0.08327227085828781,
-0.029558351263403893,
0.0635099858045578,
-0.009637716226279736,
0.06373061239719391,
-0.0118... |
b1203a98-6947-5a92-b206-447d29945462 | /documentation/private-cloud/changelog/ | Changelog | 1.7.1 (2025-06-03) | documentation | false | Changelog > 1.7.1 (2025-06-03)
| Component | Version |
|------------------------|---------|
| qdrant-kubernetes-api | v1.16.6 |
| operator | 2.6.0 |
| qdrant-cluster-manager | v0.3.6 |
* Performance and stability improvements | [
0.04109799489378929,
-0.03030804917216301,
-0.05358317121863365,
-0.031859368085861206,
0.04302149638533592,
-0.04140929877758026,
0.058690354228019714,
0.04522956535220146,
0.05573396384716034,
-0.036213818937540054,
0.01624993607401848,
0.030855273827910423,
0.051620155572891235,
-0.0633... |
b145ff53-7010-5108-8efb-48878d7533cf | /documentation/edge/edge-quickstart/ | Quickstart | Work with Points | documentation | true | Quickstart > Work with Points
An Edge Shard has several methods to work with points. To add points, use the [`update`](/documentation/edge/edge-api/updating-data/#update) method:
```python
from qdrant_edge import ( Point, UpdateOperation )
point = Point(
id=1,
vector={VECTOR_NAME: [0.1, 0.2, 0.3, 0.4]},
... | [
0.00306175765581429,
-0.02847990021109581,
-0.036904122680425644,
-0.04789023846387863,
0.07067488878965378,
-0.047441042959690094,
0.040067408233881,
0.04866190254688263,
0.08276329189538956,
0.001422941335476935,
0.06119949743151665,
0.03135274350643158,
-0.006111583672463894,
0.00333224... |
b15b6422-6d3a-5063-88c3-c9962482bf3e | /documentation/tutorials-build-essentials/video-anomaly-edge-part-2/ | Video Anomaly Detection Part 2: Edge-to-Cloud Pipeline | Mutable Shard Retention > Option A: Sync-Only Eviction (none) | documentation | true | Video Anomaly Detection Part 2: Edge-to-Cloud Pipeline > Mutable Shard Retention > Option A: Sync-Only Eviction (none)
```env
RETENTION_STRATEGY=none
```
The default and safest option. Points are only removed from the mutable shard after a successful sync confirms they exist in the cloud. The shard grows during outag... | [
0.0410507395863533,
-0.045201703906059265,
-0.0480959415435791,
-0.0404345840215683,
0.02386784739792347,
-0.021282397210597992,
0.05837931111454964,
-0.030205434188246727,
0.09911024570465088,
-0.06195621192455292,
0.03651374951004982,
0.05033547058701515,
0.03495560213923454,
-0.02850261... |
b1642a0d-db39-5e78-96b4-7ea1a350e507 | /course/beginners/module-5/analyst-queries/ | Analyst Queries | Searching Images With Text | course | true | Analyst Queries > Searching Images With Text
The satellite signals are searchable by what they show, with no caption needed at query time. The query text goes through CLIP's text encoder so it lands in the image vector space:
```python
def search_facility_images(query_text: str, supplier_id: str, limit: int = 10):
... | [
0.0364002026617527,
-0.06653985381126404,
-0.04082304611802101,
-0.040335025638341904,
0.07089190185070038,
-0.05835118144750595,
0.05167286843061447,
0.042904824018478394,
0.005482800770550966,
-0.01556345820426941,
0.010044428519904613,
0.024372395128011703,
0.05569281056523323,
-0.03365... |
b16f5e7d-3011-5aa6-a357-f547e2d6d7c0 | /documentation/inference/inference-api/ | Inference API | documentation | true | Inference API
When using [Qdrant Cloud Inference](/documentation/inference/cloud-inference/) or Qdrant's [BM25 model](/documentation/inference/inference-bm25/), embeddings are generated server-side. Instead of pre-computed vectors, you pass Inference Objects when ingesting or querying data. An Inference Object tells Q... | [
0.04655490815639496,
-0.04079596325755119,
-0.02788192592561245,
-0.05985692888498306,
0.0776292160153389,
-0.029535554349422455,
0.0905972495675087,
0.050633013248443604,
0.054999396204948425,
-0.01775895059108734,
0.038323402404785156,
0.007406121585518122,
0.05369129404425621,
-0.033679... | |
b1769f81-81ad-5242-938b-a9225c291695 | /documentation/hybrid-cloud/platform-deployment-options/ | Deployment Platforms | Scaleway | documentation | false | Deployment Platforms > Scaleway
[Scaleway Kapsule](https://www.scaleway.com/en/kubernetes-kapsule/) and [Kosmos](https://www.scaleway.com/en/kubernetes-kosmos/) are managed Kubernetes services from [Scaleway](https://www.scaleway.com/en/). They abstract away the complexities of managing and operating a Kubernetes clus... | [
0.018385149538517,
0.028060991317033768,
-0.0763443261384964,
-0.047397859394550323,
0.0617637075483799,
-0.003575628623366356,
0.08609400689601898,
0.05797988921403885,
0.02527904510498047,
-0.047034699469804764,
0.03052450343966484,
0.003969972487539053,
-0.009310262277722359,
-0.0029456... |
b1796d6a-6a72-5d19-8193-ededdc688f69 | /documentation/frameworks/mirror-security/ | VectaX - Mirror Security | documentation | true | VectaX - Mirror Security

[VectaX](https://mirrorsecurity.io/vectax) by Mirror Security is an AI-centric access control and encryption system designed for managing and protecting vector embeddings. It combines similarity-preserving encryption w... | [
0.06627009063959122,
-0.05006352812051773,
-0.04039604589343071,
0.0009760248358361423,
0.03252262994647026,
-0.020197758451104164,
0.059676025062799454,
0.04354586452245712,
0.04538538679480553,
-0.013702772557735443,
0.03233223035931587,
0.02989456243813038,
0.0771399661898613,
-0.037509... | |
b1807e34-c5d2-5cf6-9099-cc209de4f14f | /documentation/tutorials-search-engineering/collaborative-filtering/ | Collaborative Filtering | Implementation | documentation | false | Collaborative Filtering > Implementation
To implement this, you will use a simple yet powerful resource: [Qdrant with Sparse Vectors](https://qdrant.tech/articles/sparse-vectors/).
Notebook: [You can try this code here](https://githubtocolab.com/qdrant/examples/blob/master/collaborative-filtering/collaborative-filter... | [
0.0638791099190712,
-0.04304279759526253,
-0.01589231565594673,
-0.037300411611795425,
0.09232977032661438,
-0.017031162977218628,
0.07030756771564484,
0.024086643010377884,
0.05590633302927017,
-0.014649019576609135,
0.025509990751743317,
0.03283180668950081,
0.0818716511130333,
-0.030267... |
b1973a95-042d-5ea9-b97d-4e1905330f36 | /articles/agentic-rag/ | What is Agentic RAG? Building Agents with Qdrant | Which Framework is Best? > LangGraph | article | false | What is Agentic RAG? Building Agents with Qdrant > Which Framework is Best? > LangGraph
Developed by the LangChain team, LangGraph seems like a natural extension for those who already use LangChain for
building their RAG systems, and would like to start with agentic RAG.
Surprisingly, LangGraph has nothing to do with... | [
0.0026074987836182117,
-0.0334332138299942,
-0.055516500025987625,
-0.021561531350016594,
0.10354501754045486,
-0.07796920090913773,
0.06024113669991493,
0.03086058981716633,
0.025252625346183777,
-0.04730137437582016,
0.033627673983573914,
0.006525765173137188,
0.054439984261989594,
-0.03... |
b19c0a90-47b4-58f8-aa17-f2014a59beb6 | /documentation/frameworks/sycamore/ | Sycamore | Sycamore | documentation | false | Sycamore > Sycamore
[Sycamore](https://sycamore.readthedocs.io/en/stable/) is an LLM-powered data preparation, processing, and analytics system for complex, unstructured documents like PDFs, HTML, presentations, and more. With Aryn, you can prepare data for GenAI and RAG applications, power high-quality document proce... | [
0.005920895375311375,
-0.019340772181749344,
-0.05577744171023369,
-0.0634453073143959,
0.06115672364830971,
0.019871871918439865,
0.08025705069303513,
0.013837938196957111,
0.06824617832899094,
-0.0023278952576220036,
0.021365555003285408,
0.018061457201838493,
0.032561130821704865,
-0.01... |
b19dce49-b1f5-5b09-a5f0-f56140b0af87 | /documentation/tutorials-operations/embedding-model-migration/ | Migrate to a New Embedding Model | documentation | false | Migrate to a New Embedding Model
| Time: 40 min | Level: Intermediate |
| --- | ----------- |
When building a semantic search application, you need to [choose an embedding
model](/documentation/search-patterns/choose-embedding-model/). Over time, you may want to switch to a different model for better
quality or cost... | [
0.04172283038496971,
-0.058933258056640625,
-0.02665903978049755,
-0.0364253856241703,
0.06192731484770775,
-0.041304655373096466,
0.08369006961584091,
0.06445316970348358,
0.056936126202344894,
-0.030572643503546715,
0.018275370821356773,
0.01452457532286644,
0.04222733527421951,
-0.06542... | |
b19ec5d8-47ed-50f8-be8e-5f10123d6efc | /course/multi-vector-search/module-3/quantization-techniques/ | Vector Quantization Techniques | course | false | Vector Quantization Techniques
Module 3
Vector quantization compresses vectors by reducing the precision of each component. Qdrant supports several quantization methods that can reduce memory usage by 4-64x, sometimes with minimal quality loss.
Choosing the right quantization method depends on your quality requireme... | [
0.059812311083078384,
-0.04359706491231918,
-0.03414549306035042,
-0.05748526006937027,
0.027257192879915237,
0.016325395554304123,
0.08819030970335007,
0.05372864007949829,
0.13791415095329285,
-0.029306625947356224,
0.017398692667484283,
0.010225886479020119,
0.031595900654792786,
-0.018... | |
b1b71116-6387-5e21-a5cc-02c524e8be61 | /documentation/private-cloud/changelog/ | Changelog | 1.9.3 (2025-12-22) | documentation | false | Changelog > 1.9.3 (2025-12-22)
| Component | Version |
|-------------------------|---------|
| qdrant-kubernetes-api | v1.22.1 |
| operator | 2.9.1 |
| qdrant-cluster-manager | v0.3.13 |
| qdrant-cluster-exporter | 1.7.6 |
Latest validated Qdrant version: 1.16.3
* Performance and ... | [
0.04127255827188492,
-0.016581246629357338,
-0.041182052344083786,
-0.050987884402275085,
0.04614351689815521,
-0.04574768617749214,
0.05402829125523567,
0.02936910279095173,
0.044214021414518356,
-0.031315289437770844,
0.02620331011712551,
0.03635350242257118,
0.05229278281331062,
-0.0609... |
b1bbfd85-cfe9-5028-90c4-be552685bed5 | /documentation/scaling/horizontal-scaling/ | Horizontal Scaling | Sharding | documentation | false | Horizontal Scaling > Sharding
A Qdrant collection is partitioned into one or more shards. Each shard is an independent store of points capable of performing all the operations a collection supports. Each shard holds a distinct portion of the collection's points.
![A three-node cluster with a collection with three sha... | [
0.02792218327522278,
-0.02139190025627613,
-0.06269687414169312,
-0.033826619386672974,
0.08243948966264725,
-0.038707442581653595,
0.047669507563114166,
0.045209117233753204,
0.07826858758926392,
-0.026250191032886505,
0.04931615665555,
-0.005482939537614584,
0.031860560178756714,
-0.0114... |
b1ddf654-32d5-594c-bc49-aa122493b092 | /course/essentials/day-3/sparse-vectors/ | Sparse Vectors and Inverted Indexes | Key Takeaways | course | false | Sparse Vectors and Inverted Indexes > Key Takeaways
1. Choose sparse vectors when most features are absent (zero) and you need **exact, feature-aligned matching**.
They’re storage-efficient and work well alongside dense vectors in future **Hybrid Search** setups.
2. Similarity = Dot product. Sparse vector similarity... | [
0.06546486914157867,
-0.05800316482782364,
-0.052584584802389145,
-0.016505589708685875,
0.062417756766080856,
-0.03682812675833702,
0.0822257325053215,
-0.013662030920386314,
0.06899935752153397,
-0.03787216544151306,
0.016776541247963905,
0.04628487303853035,
0.051713135093450546,
-0.001... |
b1ea6a9f-ea3c-5544-938a-a08223116865 | /documentation/ops-optimization/read-write-contention/ | Read-Write Contention | Step 4: Tune the Number of Optimizer Threads | documentation | true | Read-Write Contention > Step 4: Tune the Number of Optimizer Threads
Two settings give you finer control over optimizer CPU usage than `optimizer_cpu_budget` alone. They work at different levels:
* **`max_optimization_threads`**: The maximum number of optimization jobs that can run in parallel per shard. Defaults to ... | [
-0.007702147588133812,
-0.03909599035978317,
-0.06422606855630875,
-0.006819393485784531,
0.06201016530394554,
-0.0415872186422348,
0.010353063233196735,
0.0389329269528389,
0.06270939111709595,
-0.027877120301127434,
0.028061620891094208,
0.0026750313118100166,
0.039589643478393555,
-0.06... |
b20375a2-cd38-5e2b-a592-9e6799bc0cef | /course/essentials/day-7/unstructured/ | Integrating with Unstructured.io | Unstructured Enterprise Data Processing > Real-World Applications | course | false | Integrating with Unstructured.io > Unstructured Enterprise Data Processing > Real-World Applications
This architecture enables various enterprise use cases:
- **Document Intelligence**: Automated processing of legal documents, contracts, and reports
- **Knowledge Management**: Enterprise-wide document search and retr... | [
-0.02055116929113865,
-0.030728623270988464,
-0.09888032078742981,
-0.028965603560209274,
0.06977324187755585,
-0.026729486882686615,
0.045031603425741196,
0.05310752987861633,
0.023377742618322372,
-0.023737754672765732,
-0.01016206294298172,
-0.012790383771061897,
0.07478207349777222,
-0... |
b2192af0-8409-5845-8d60-5bd912515506 | /articles/metric-learning-tips/ | Metric Learning Tips & Tricks | Training the model | article | false | Metric Learning Tips & Tricks > Training the model
To compensate for this limitation we can try to increase the number of random (weak) negative samples.
One way to achieve this is to train the model longer, so it will see more samples by the end of the training.
But we found a better solution in adjusting our loss fu... | [
0.054498761892318726,
-0.04078514873981476,
-0.04044675827026367,
-0.03973668813705444,
0.05165884643793106,
-0.008479472249746323,
0.05213189870119095,
0.024617213755846024,
0.07517468184232712,
-0.04439987987279892,
0.04090895131230354,
0.019982673227787018,
0.07067521661520004,
-0.03712... |
b2228a27-62a2-5020-93c8-6249db8ea132 | /articles/what-is-vector-quantization/ | What is Vector Quantization? | Rescoring, Oversampling, and Reranking > 3. Rescoring with Original Vectors | article | false | What is Vector Quantization? > Rescoring, Oversampling, and Reranking > 3. Rescoring with Original Vectors
After oversampling to gather more potential matches, each candidate is re-evaluated based on additional criteria to ensure higher accuracy and relevance to the query.
The rescoring process **maps** the quantized... | [
0.033630259335041046,
-0.07620421797037125,
-0.03164272755384445,
-0.05331870913505554,
0.07254599034786224,
0.010004113428294659,
0.046015966683626175,
0.00295002362690866,
0.08573737740516663,
-0.035649243742227554,
0.03236089646816254,
0.03323384001851082,
0.06412997841835022,
-0.004280... |
Subsets and Splits
No community queries yet
The top public SQL queries from the community will appear here once available.