

FangSen9000 Claude commited on
Commit ·
0a2e9f2
1
Parent(s): adbfc5d
Add One-to-All-Animation: Batch 1 - Small files and directories
Browse files- Added LICENSE, README.md, requirements.txt
- Added datasets/, benchmark/, video-generation/, examples/, assets/
- Total size: ~100MB
🤖 Generated with [Claude Code](https://claude.com/claude-code)
Co-Authored-By: Claude <noreply@anthropic.com>
This view is limited to 50 files because it contains too many changes. See raw diff
- One-to-All-Animation +0 -1
- One-to-All-Animation/LICENSE +201 -0
- One-to-All-Animation/README.md +310 -0
- One-to-All-Animation/assets/1.3b_examples/combined_video1.gif +3 -0
- One-to-All-Animation/assets/1.3b_examples/combined_video2.gif +3 -0
- One-to-All-Animation/assets/1.3b_examples/ref3_motion1_1.3b.gif +3 -0
- One-to-All-Animation/assets/1.3b_examples/ref3_motion2_1.3b.gif +3 -0
- One-to-All-Animation/assets/1.3b_examples/ref3_motion3_1.3b.gif +3 -0
- One-to-All-Animation/assets/14b_examples/ref_1_motion1.gif +3 -0
- One-to-All-Animation/assets/14b_examples/ref_1_motion2.gif +3 -0
- One-to-All-Animation/assets/14b_examples/ref_1_motion3.gif +3 -0
- One-to-All-Animation/assets/14b_examples/ref_2_motion1.gif +3 -0
- One-to-All-Animation/assets/14b_examples/ref_2_motion2.gif +3 -0
- One-to-All-Animation/assets/14b_examples/ref_2_motion3.gif +3 -0
- One-to-All-Animation/benchmark/DisCo/.gitignore +74 -0
- One-to-All-Animation/benchmark/DisCo/LICENSE +201 -0
- One-to-All-Animation/benchmark/DisCo/PREPRO.md +107 -0
- One-to-All-Animation/benchmark/DisCo/README.md +426 -0
- One-to-All-Animation/benchmark/DisCo/agent.py +1302 -0
- One-to-All-Animation/benchmark/DisCo/annotator/grounded-sam/Dockerfile +11 -0
- One-to-All-Animation/benchmark/DisCo/annotator/grounded-sam/GroundingDINO/LICENSE +201 -0
- One-to-All-Animation/benchmark/DisCo/annotator/grounded-sam/GroundingDINO/README.md +163 -0
- One-to-All-Animation/benchmark/DisCo/annotator/grounded-sam/GroundingDINO/groundingdino/__init__.py +0 -0
- One-to-All-Animation/benchmark/DisCo/annotator/grounded-sam/GroundingDINO/groundingdino/config/GroundingDINO_SwinB.cfg.py +43 -0
- One-to-All-Animation/benchmark/DisCo/annotator/grounded-sam/GroundingDINO/groundingdino/config/GroundingDINO_SwinT_OGC.py +43 -0
- One-to-All-Animation/benchmark/DisCo/annotator/grounded-sam/GroundingDINO/groundingdino/datasets/__init__.py +0 -0
- One-to-All-Animation/benchmark/DisCo/annotator/grounded-sam/GroundingDINO/groundingdino/datasets/transforms.py +311 -0
- One-to-All-Animation/benchmark/DisCo/annotator/grounded-sam/GroundingDINO/groundingdino/models/GroundingDINO/__init__.py +15 -0
- One-to-All-Animation/benchmark/DisCo/annotator/grounded-sam/GroundingDINO/groundingdino/models/GroundingDINO/backbone/__init__.py +1 -0
- One-to-All-Animation/benchmark/DisCo/annotator/grounded-sam/GroundingDINO/groundingdino/models/GroundingDINO/backbone/backbone.py +221 -0
- One-to-All-Animation/benchmark/DisCo/annotator/grounded-sam/GroundingDINO/groundingdino/models/GroundingDINO/backbone/position_encoding.py +186 -0
- One-to-All-Animation/benchmark/DisCo/annotator/grounded-sam/GroundingDINO/groundingdino/models/GroundingDINO/backbone/swin_transformer.py +802 -0
- One-to-All-Animation/benchmark/DisCo/annotator/grounded-sam/GroundingDINO/groundingdino/models/GroundingDINO/bertwarper.py +273 -0
- One-to-All-Animation/benchmark/DisCo/annotator/grounded-sam/GroundingDINO/groundingdino/models/GroundingDINO/csrc/MsDeformAttn/ms_deform_attn.h +64 -0
- One-to-All-Animation/benchmark/DisCo/annotator/grounded-sam/GroundingDINO/groundingdino/models/GroundingDINO/csrc/MsDeformAttn/ms_deform_attn_cpu.cpp +43 -0
- One-to-All-Animation/benchmark/DisCo/annotator/grounded-sam/GroundingDINO/groundingdino/models/GroundingDINO/csrc/MsDeformAttn/ms_deform_attn_cpu.h +35 -0
- One-to-All-Animation/benchmark/DisCo/annotator/grounded-sam/GroundingDINO/groundingdino/models/GroundingDINO/csrc/MsDeformAttn/ms_deform_attn_cuda.cu +156 -0
- One-to-All-Animation/benchmark/DisCo/annotator/grounded-sam/GroundingDINO/groundingdino/models/GroundingDINO/csrc/MsDeformAttn/ms_deform_attn_cuda.h +33 -0
- One-to-All-Animation/benchmark/DisCo/annotator/grounded-sam/GroundingDINO/groundingdino/models/GroundingDINO/csrc/MsDeformAttn/ms_deform_im2col_cuda.cuh +1327 -0
- One-to-All-Animation/benchmark/DisCo/annotator/grounded-sam/GroundingDINO/groundingdino/models/GroundingDINO/csrc/cuda_version.cu +7 -0
- One-to-All-Animation/benchmark/DisCo/annotator/grounded-sam/GroundingDINO/groundingdino/models/GroundingDINO/csrc/vision.cpp +58 -0
- One-to-All-Animation/benchmark/DisCo/annotator/grounded-sam/GroundingDINO/groundingdino/models/GroundingDINO/fuse_modules.py +297 -0
- One-to-All-Animation/benchmark/DisCo/annotator/grounded-sam/GroundingDINO/groundingdino/models/GroundingDINO/groundingdino.py +395 -0
- One-to-All-Animation/benchmark/DisCo/annotator/grounded-sam/GroundingDINO/groundingdino/models/GroundingDINO/ms_deform_attn.py +413 -0
- One-to-All-Animation/benchmark/DisCo/annotator/grounded-sam/GroundingDINO/groundingdino/models/GroundingDINO/transformer.py +959 -0
- One-to-All-Animation/benchmark/DisCo/annotator/grounded-sam/GroundingDINO/groundingdino/models/GroundingDINO/transformer_vanilla.py +123 -0
- One-to-All-Animation/benchmark/DisCo/annotator/grounded-sam/GroundingDINO/groundingdino/models/GroundingDINO/utils.py +268 -0
- One-to-All-Animation/benchmark/DisCo/annotator/grounded-sam/GroundingDINO/groundingdino/models/__init__.py +18 -0
- One-to-All-Animation/benchmark/DisCo/annotator/grounded-sam/GroundingDINO/groundingdino/models/registry.py +66 -0
- One-to-All-Animation/benchmark/DisCo/annotator/grounded-sam/GroundingDINO/groundingdino/util/__init__.py +1 -0
One-to-All-Animation
DELETED
|
@@ -1 +0,0 @@
|
|
| 1 |
-
Subproject commit fc608e58e3956f26aebf44a4387701f5d64ffd4a
|
|
|
|
|
|
One-to-All-Animation/LICENSE
ADDED
|
@@ -0,0 +1,201 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
Apache License
|
| 2 |
+
Version 2.0, January 2004
|
| 3 |
+
http://www.apache.org/licenses/
|
| 4 |
+
|
| 5 |
+
TERMS AND CONDITIONS FOR USE, REPRODUCTION, AND DISTRIBUTION
|
| 6 |
+
|
| 7 |
+
1. Definitions.
|
| 8 |
+
|
| 9 |
+
"License" shall mean the terms and conditions for use, reproduction,
|
| 10 |
+
and distribution as defined by Sections 1 through 9 of this document.
|
| 11 |
+
|
| 12 |
+
"Licensor" shall mean the copyright owner or entity authorized by
|
| 13 |
+
the copyright owner that is granting the License.
|
| 14 |
+
|
| 15 |
+
"Legal Entity" shall mean the union of the acting entity and all
|
| 16 |
+
other entities that control, are controlled by, or are under common
|
| 17 |
+
control with that entity. For the purposes of this definition,
|
| 18 |
+
"control" means (i) the power, direct or indirect, to cause the
|
| 19 |
+
direction or management of such entity, whether by contract or
|
| 20 |
+
otherwise, or (ii) ownership of fifty percent (50%) or more of the
|
| 21 |
+
outstanding shares, or (iii) beneficial ownership of such entity.
|
| 22 |
+
|
| 23 |
+
"You" (or "Your") shall mean an individual or Legal Entity
|
| 24 |
+
exercising permissions granted by this License.
|
| 25 |
+
|
| 26 |
+
"Source" form shall mean the preferred form for making modifications,
|
| 27 |
+
including but not limited to software source code, documentation
|
| 28 |
+
source, and configuration files.
|
| 29 |
+
|
| 30 |
+
"Object" form shall mean any form resulting from mechanical
|
| 31 |
+
transformation or translation of a Source form, including but
|
| 32 |
+
not limited to compiled object code, generated documentation,
|
| 33 |
+
and conversions to other media types.
|
| 34 |
+
|
| 35 |
+
"Work" shall mean the work of authorship, whether in Source or
|
| 36 |
+
Object form, made available under the License, as indicated by a
|
| 37 |
+
copyright notice that is included in or attached to the work
|
| 38 |
+
(an example is provided in the Appendix below).
|
| 39 |
+
|
| 40 |
+
"Derivative Works" shall mean any work, whether in Source or Object
|
| 41 |
+
form, that is based on (or derived from) the Work and for which the
|
| 42 |
+
editorial revisions, annotations, elaborations, or other modifications
|
| 43 |
+
represent, as a whole, an original work of authorship. For the purposes
|
| 44 |
+
of this License, Derivative Works shall not include works that remain
|
| 45 |
+
separable from, or merely link (or bind by name) to the interfaces of,
|
| 46 |
+
the Work and Derivative Works thereof.
|
| 47 |
+
|
| 48 |
+
"Contribution" shall mean any work of authorship, including
|
| 49 |
+
the original version of the Work and any modifications or additions
|
| 50 |
+
to that Work or Derivative Works thereof, that is intentionally
|
| 51 |
+
submitted to Licensor for inclusion in the Work by the copyright owner
|
| 52 |
+
or by an individual or Legal Entity authorized to submit on behalf of
|
| 53 |
+
the copyright owner. For the purposes of this definition, "submitted"
|
| 54 |
+
means any form of electronic, verbal, or written communication sent
|
| 55 |
+
to the Licensor or its representatives, including but not limited to
|
| 56 |
+
communication on electronic mailing lists, source code control systems,
|
| 57 |
+
and issue tracking systems that are managed by, or on behalf of, the
|
| 58 |
+
Licensor for the purpose of discussing and improving the Work, but
|
| 59 |
+
excluding communication that is conspicuously marked or otherwise
|
| 60 |
+
designated in writing by the copyright owner as "Not a Contribution."
|
| 61 |
+
|
| 62 |
+
"Contributor" shall mean Licensor and any individual or Legal Entity
|
| 63 |
+
on behalf of whom a Contribution has been received by Licensor and
|
| 64 |
+
subsequently incorporated within the Work.
|
| 65 |
+
|
| 66 |
+
2. Grant of Copyright License. Subject to the terms and conditions of
|
| 67 |
+
this License, each Contributor hereby grants to You a perpetual,
|
| 68 |
+
worldwide, non-exclusive, no-charge, royalty-free, irrevocable
|
| 69 |
+
copyright license to reproduce, prepare Derivative Works of,
|
| 70 |
+
publicly display, publicly perform, sublicense, and distribute the
|
| 71 |
+
Work and such Derivative Works in Source or Object form.
|
| 72 |
+
|
| 73 |
+
3. Grant of Patent License. Subject to the terms and conditions of
|
| 74 |
+
this License, each Contributor hereby grants to You a perpetual,
|
| 75 |
+
worldwide, non-exclusive, no-charge, royalty-free, irrevocable
|
| 76 |
+
(except as stated in this section) patent license to make, have made,
|
| 77 |
+
use, offer to sell, sell, import, and otherwise transfer the Work,
|
| 78 |
+
where such license applies only to those patent claims licensable
|
| 79 |
+
by such Contributor that are necessarily infringed by their
|
| 80 |
+
Contribution(s) alone or by combination of their Contribution(s)
|
| 81 |
+
with the Work to which such Contribution(s) was submitted. If You
|
| 82 |
+
institute patent litigation against any entity (including a
|
| 83 |
+
cross-claim or counterclaim in a lawsuit) alleging that the Work
|
| 84 |
+
or a Contribution incorporated within the Work constitutes direct
|
| 85 |
+
or contributory patent infringement, then any patent licenses
|
| 86 |
+
granted to You under this License for that Work shall terminate
|
| 87 |
+
as of the date such litigation is filed.
|
| 88 |
+
|
| 89 |
+
4. Redistribution. You may reproduce and distribute copies of the
|
| 90 |
+
Work or Derivative Works thereof in any medium, with or without
|
| 91 |
+
modifications, and in Source or Object form, provided that You
|
| 92 |
+
meet the following conditions:
|
| 93 |
+
|
| 94 |
+
(a) You must give any other recipients of the Work or
|
| 95 |
+
Derivative Works a copy of this License; and
|
| 96 |
+
|
| 97 |
+
(b) You must cause any modified files to carry prominent notices
|
| 98 |
+
stating that You changed the files; and
|
| 99 |
+
|
| 100 |
+
(c) You must retain, in the Source form of any Derivative Works
|
| 101 |
+
that You distribute, all copyright, patent, trademark, and
|
| 102 |
+
attribution notices from the Source form of the Work,
|
| 103 |
+
excluding those notices that do not pertain to any part of
|
| 104 |
+
the Derivative Works; and
|
| 105 |
+
|
| 106 |
+
(d) If the Work includes a "NOTICE" text file as part of its
|
| 107 |
+
distribution, then any Derivative Works that You distribute must
|
| 108 |
+
include a readable copy of the attribution notices contained
|
| 109 |
+
within such NOTICE file, excluding those notices that do not
|
| 110 |
+
pertain to any part of the Derivative Works, in at least one
|
| 111 |
+
of the following places: within a NOTICE text file distributed
|
| 112 |
+
as part of the Derivative Works; within the Source form or
|
| 113 |
+
documentation, if provided along with the Derivative Works; or,
|
| 114 |
+
within a display generated by the Derivative Works, if and
|
| 115 |
+
wherever such third-party notices normally appear. The contents
|
| 116 |
+
of the NOTICE file are for informational purposes only and
|
| 117 |
+
do not modify the License. You may add Your own attribution
|
| 118 |
+
notices within Derivative Works that You distribute, alongside
|
| 119 |
+
or as an addendum to the NOTICE text from the Work, provided
|
| 120 |
+
that such additional attribution notices cannot be construed
|
| 121 |
+
as modifying the License.
|
| 122 |
+
|
| 123 |
+
You may add Your own copyright statement to Your modifications and
|
| 124 |
+
may provide additional or different license terms and conditions
|
| 125 |
+
for use, reproduction, or distribution of Your modifications, or
|
| 126 |
+
for any such Derivative Works as a whole, provided Your use,
|
| 127 |
+
reproduction, and distribution of the Work otherwise complies with
|
| 128 |
+
the conditions stated in this License.
|
| 129 |
+
|
| 130 |
+
5. Submission of Contributions. Unless You explicitly state otherwise,
|
| 131 |
+
any Contribution intentionally submitted for inclusion in the Work
|
| 132 |
+
by You to the Licensor shall be under the terms and conditions of
|
| 133 |
+
this License, without any additional terms or conditions.
|
| 134 |
+
Notwithstanding the above, nothing herein shall supersede or modify
|
| 135 |
+
the terms of any separate license agreement you may have executed
|
| 136 |
+
with Licensor regarding such Contributions.
|
| 137 |
+
|
| 138 |
+
6. Trademarks. This License does not grant permission to use the trade
|
| 139 |
+
names, trademarks, service marks, or product names of the Licensor,
|
| 140 |
+
except as required for reasonable and customary use in describing the
|
| 141 |
+
origin of the Work and reproducing the content of the NOTICE file.
|
| 142 |
+
|
| 143 |
+
7. Disclaimer of Warranty. Unless required by applicable law or
|
| 144 |
+
agreed to in writing, Licensor provides the Work (and each
|
| 145 |
+
Contributor provides its Contributions) on an "AS IS" BASIS,
|
| 146 |
+
WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or
|
| 147 |
+
implied, including, without limitation, any warranties or conditions
|
| 148 |
+
of TITLE, NON-INFRINGEMENT, MERCHANTABILITY, or FITNESS FOR A
|
| 149 |
+
PARTICULAR PURPOSE. You are solely responsible for determining the
|
| 150 |
+
appropriateness of using or redistributing the Work and assume any
|
| 151 |
+
risks associated with Your exercise of permissions under this License.
|
| 152 |
+
|
| 153 |
+
8. Limitation of Liability. In no event and under no legal theory,
|
| 154 |
+
whether in tort (including negligence), contract, or otherwise,
|
| 155 |
+
unless required by applicable law (such as deliberate and grossly
|
| 156 |
+
negligent acts) or agreed to in writing, shall any Contributor be
|
| 157 |
+
liable to You for damages, including any direct, indirect, special,
|
| 158 |
+
incidental, or consequential damages of any character arising as a
|
| 159 |
+
result of this License or out of the use or inability to use the
|
| 160 |
+
Work (including but not limited to damages for loss of goodwill,
|
| 161 |
+
work stoppage, computer failure or malfunction, or any and all
|
| 162 |
+
other commercial damages or losses), even if such Contributor
|
| 163 |
+
has been advised of the possibility of such damages.
|
| 164 |
+
|
| 165 |
+
9. Accepting Warranty or Additional Liability. While redistributing
|
| 166 |
+
the Work or Derivative Works thereof, You may choose to offer,
|
| 167 |
+
and charge a fee for, acceptance of support, warranty, indemnity,
|
| 168 |
+
or other liability obligations and/or rights consistent with this
|
| 169 |
+
License. However, in accepting such obligations, You may act only
|
| 170 |
+
on Your own behalf and on Your sole responsibility, not on behalf
|
| 171 |
+
of any other Contributor, and only if You agree to indemnify,
|
| 172 |
+
defend, and hold each Contributor harmless for any liability
|
| 173 |
+
incurred by, or claims asserted against, such Contributor by reason
|
| 174 |
+
of your accepting any such warranty or additional liability.
|
| 175 |
+
|
| 176 |
+
END OF TERMS AND CONDITIONS
|
| 177 |
+
|
| 178 |
+
APPENDIX: How to apply the Apache License to your work.
|
| 179 |
+
|
| 180 |
+
To apply the Apache License to your work, attach the following
|
| 181 |
+
boilerplate notice, with the fields enclosed by brackets "[]"
|
| 182 |
+
replaced with your own identifying information. (Don't include
|
| 183 |
+
the brackets!) The text should be enclosed in the appropriate
|
| 184 |
+
comment syntax for the file format. We also recommend that a
|
| 185 |
+
file or class name and description of purpose be included on the
|
| 186 |
+
same "printed page" as the copyright notice for easier
|
| 187 |
+
identification within third-party archives.
|
| 188 |
+
|
| 189 |
+
Copyright [yyyy] [name of copyright owner]
|
| 190 |
+
|
| 191 |
+
Licensed under the Apache License, Version 2.0 (the "License");
|
| 192 |
+
you may not use this file except in compliance with the License.
|
| 193 |
+
You may obtain a copy of the License at
|
| 194 |
+
|
| 195 |
+
http://www.apache.org/licenses/LICENSE-2.0
|
| 196 |
+
|
| 197 |
+
Unless required by applicable law or agreed to in writing, software
|
| 198 |
+
distributed under the License is distributed on an "AS IS" BASIS,
|
| 199 |
+
WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
|
| 200 |
+
See the License for the specific language governing permissions and
|
| 201 |
+
limitations under the License.
|
One-to-All-Animation/README.md
ADDED
|
@@ -0,0 +1,310 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
<div align="center">
|
| 2 |
+
|
| 3 |
+
<h1>
|
| 4 |
+
<br>
|
| 5 |
+
One-to-All Animation: Alignment-Free <br> Character Animation
|
| 6 |
+
and Image Pose Transfer
|
| 7 |
+
</h1>
|
| 8 |
+
|
| 9 |
+
<p>
|
| 10 |
+
Shijun Shi<sup>1*</sup>, Jing Xu<sup>2*</sup>, Zhihang Li<sup>3</sup>, Chunli Peng<sup>4</sup>, Xiaoda Yang<sup>5</sup>, Lijing Lu<sup>3</sup>, <br> Kai Hu<sup>1†</sup>, Jiangning Zhang<sup>5†</sup>
|
| 11 |
+
</p>
|
| 12 |
+
|
| 13 |
+
<p style="font-size: 0.9em; color: #666;">
|
| 14 |
+
<sup>1</sup>Jiangnan University
|
| 15 |
+
<sup>2</sup>University of Science and Technology of China
|
| 16 |
+
<sup>3</sup>Chinese Academy of Sciences<br>
|
| 17 |
+
<sup>4</sup>Beijing University of Posts and Telecommunications
|
| 18 |
+
<sup>5</sup>Zhejiang University
|
| 19 |
+
</p>
|
| 20 |
+
|
| 21 |
+
<p style="font-size: 0.85em; color: #888;">
|
| 22 |
+
<sup>*</sup>Equal contribution <sup>†</sup>Corresponding authors
|
| 23 |
+
</p>
|
| 24 |
+
|
| 25 |
+
|
| 26 |
+
<p align="center">
|
| 27 |
+
<a href="https://ssj9596.github.io/one-to-all-animation-project/" target="_blank">
|
| 28 |
+
<img src="https://img.shields.io/badge/🌐%20Project%20Page-Visit%20Website-4285F4?style=for-the-badge&logoColor=white" height="30"/>
|
| 29 |
+
</a>
|
| 30 |
+
|
| 31 |
+
<a href="https://arxiv.org/abs/2511.22940" target="_blank">
|
| 32 |
+
<img src="https://img.shields.io/badge/📄%20arXiv-2511.22940-B31B1B?style=for-the-badge&logoColor=white" height="30"/>
|
| 33 |
+
</a>
|
| 34 |
+
</p>
|
| 35 |
+
</div>
|
| 36 |
+
|
| 37 |
+
<br>
|
| 38 |
+
|
| 39 |
+
## 🌟 Highlights
|
| 40 |
+
|
| 41 |
+
We provide a **complete and reproducible** training and evaluation pipeline:
|
| 42 |
+
|
| 43 |
+
- ✅ **Full Training Code**: Three-stage progressive training from scratch
|
| 44 |
+
- ✅ **Complete Benchmarks**: Reproduction code and pre-trained checkpoints
|
| 45 |
+
- ✅ **Flexible Training Codebase**: Multi-resolution, multi-aspect-ratio, and multi-frame training codebase
|
| 46 |
+
- ✅ **Datasets**: Pre-processed open-source datasets + self-collected cartoon data
|
| 47 |
+
|
| 48 |
+
<br>
|
| 49 |
+
|
| 50 |
+
## 🔥 Update
|
| 51 |
+
- [2025.12] [kijai's ComfyUI WanVideoWrapper](https://github.com/kijai/ComfyUI-WanVideoWrapper) now integrates One‑to‑All Animation 14B! Huge thanks to **kijai** for the amazing work!!! **Note**: Our model supports both retargeted pose and direct pose (with reference preprocessing) from the original video. In addition, using lighter colors for the facial skeleton and landmarks helps achieve better identity consistency.
|
| 52 |
+
- [2025.11] Paper reproduction and evaluation code released.
|
| 53 |
+
- [2025.11] [Sample training data and Benchmark](https://huggingface.co/datasets/MochunniaN1/One-to-All-sub) on HuggingFace released.
|
| 54 |
+
- [2025.11] Inference and Training codes are released.
|
| 55 |
+
- [2025.11] [1.3B-v1](https://huggingface.co/MochunniaN1/One-to-All-1.3b_1), [1.3B-v2](https://huggingface.co/MochunniaN1/One-to-All-1.3b_2) and [14B](https://huggingface.co/MochunniaN1/One-to-All-14b) checkpoints are released.
|
| 56 |
+
|
| 57 |
+
<br>
|
| 58 |
+
|
| 59 |
+
## 🎭 Showcase
|
| 60 |
+
|
| 61 |
+
Our model can adapt a single reference image to various motion patterns, demonstrating flexible motion control capabilities.
|
| 62 |
+
|
| 63 |
+
#### 14B Model
|
| 64 |
+
|
| 65 |
+
<table align="center">
|
| 66 |
+
<tr>
|
| 67 |
+
<th style="text-align: center;">Reference</th>
|
| 68 |
+
<th style="text-align: center;">Motion 1</th>
|
| 69 |
+
<th style="text-align: center;">Motion 2</th>
|
| 70 |
+
<th style="text-align: center;">Motion 3</th>
|
| 71 |
+
</tr>
|
| 72 |
+
<tr>
|
| 73 |
+
<td align="center" style="padding: 2px;"><img src="./examples/new_examples/1.png" height="250"/></td>
|
| 74 |
+
<td align="center" style="padding: 2px;"><img src="assets/14b_examples/ref_1_motion1.gif" height="250"/></td>
|
| 75 |
+
<td align="center" style="padding: 2px;"><img src="assets/14b_examples/ref_1_motion2.gif" height="250"/></td>
|
| 76 |
+
<td align="center" style="padding: 2px;"><img src="assets/14b_examples/ref_1_motion3.gif" height="250"/></td>
|
| 77 |
+
</tr>
|
| 78 |
+
<tr>
|
| 79 |
+
<td align="center" style="padding: 2px;"><img src="./examples/new_examples/2.png" height="250"/></td>
|
| 80 |
+
<td align="center" style="padding: 2px;"><img src="assets/14b_examples/ref_2_motion1.gif" height="250"/></td>
|
| 81 |
+
<td align="center" style="padding: 2px;"><img src="assets/14b_examples/ref_2_motion2.gif" height="250"/></td>
|
| 82 |
+
<td align="center" style="padding: 2px;"><img src="assets/14b_examples/ref_2_motion3.gif" height="250"/></td>
|
| 83 |
+
</tr>
|
| 84 |
+
</table>
|
| 85 |
+
|
| 86 |
+
<br>
|
| 87 |
+
|
| 88 |
+
#### 1.3B Model
|
| 89 |
+
The 1.3 B model also delivers strong performance (from 1.3b_2 ckpt).
|
| 90 |
+
|
| 91 |
+
<table align="center">
|
| 92 |
+
<tr>
|
| 93 |
+
<th style="text-align: center;">Reference</th>
|
| 94 |
+
<th style="text-align: center;">Motion 1</th>
|
| 95 |
+
<th style="text-align: center;">Motion 2</th>
|
| 96 |
+
<th style="text-align: center;">Motion 3</th>
|
| 97 |
+
</tr>
|
| 98 |
+
<tr>
|
| 99 |
+
<td align="center" style="padding: 2px;"><img src="./examples/new_examples/3.png" height="250"/></td>
|
| 100 |
+
<td align="center" style="padding: 2px;"><img src="assets/1.3b_examples/ref3_motion1_1.3b.gif" height="250"/></td>
|
| 101 |
+
<td align="center" style="padding: 2px;"><img src="assets/1.3b_examples/ref3_motion2_1.3b.gif" height="250"/></td>
|
| 102 |
+
<td align="center" style="padding: 2px;"><img src="assets/1.3b_examples/ref3_motion3_1.3b.gif" height="250"/></td>
|
| 103 |
+
</tr>
|
| 104 |
+
</table>
|
| 105 |
+
|
| 106 |
+
Also support longer video & out-of-domain cases
|
| 107 |
+
<p align="center">
|
| 108 |
+
<img src="./assets/1.3b_examples/combined_video1.gif" height="250"/> <img src="./assets/1.3b_examples/combined_video2.gif" height="250"/>
|
| 109 |
+
</p>
|
| 110 |
+
|
| 111 |
+
<br>
|
| 112 |
+
|
| 113 |
+
|
| 114 |
+
|
| 115 |
+
## 🔧 Dependencies and Installation
|
| 116 |
+
|
| 117 |
+
1. Clone Repo
|
| 118 |
+
```bash
|
| 119 |
+
git clone https://github.com/ssj9596/One-to-All-Animation.git
|
| 120 |
+
cd One-to-All-Animation
|
| 121 |
+
```
|
| 122 |
+
|
| 123 |
+
2. Create Conda Environment and Install Dependencies
|
| 124 |
+
```bash
|
| 125 |
+
# create new conda env
|
| 126 |
+
conda create -n one-to-all python=3.12
|
| 127 |
+
conda activate one-to-all
|
| 128 |
+
|
| 129 |
+
# install pytorch
|
| 130 |
+
pip install torch==2.5.1 torchvision==0.20.1 torchaudio==2.5.1 --index-url https://download.pytorch.org/whl/cu124
|
| 131 |
+
# or
|
| 132 |
+
pip install torch==2.5.1 torchvision==0.20.1 torchaudio==2.5.1 -i https://mirrors.aliyun.com/pypi/simple/
|
| 133 |
+
|
| 134 |
+
# install python dependencies
|
| 135 |
+
pip install -r requirements.txt -i https://mirrors.aliyun.com/pypi/simple/
|
| 136 |
+
|
| 137 |
+
|
| 138 |
+
# (Recommended) install flash attention 3 (or 2) from source:
|
| 139 |
+
# https://github.com/Dao-AILab/flash-attention
|
| 140 |
+
```
|
| 141 |
+
|
| 142 |
+
3. Download Models
|
| 143 |
+
|
| 144 |
+
- Download pretrained models
|
| 145 |
+
```bash
|
| 146 |
+
cd ./pretrained_models
|
| 147 |
+
bash download_pretrained_models.py
|
| 148 |
+
```
|
| 149 |
+
|
| 150 |
+
- Download checkpoints
|
| 151 |
+
```bash
|
| 152 |
+
cd ./checkpoints
|
| 153 |
+
bash download_checkpoints.py
|
| 154 |
+
```
|
| 155 |
+
|
| 156 |
+
> 💡 **Tip**: Edit the script and uncomment the specific models you want to download.
|
| 157 |
+
> - **1.3B_1**: Best performance on video benchmark among 1.3B models (paper results).
|
| 158 |
+
> - **1.3B_2**: Further trained on v1 with large camera movement data and increased image ratio. Better for dynamic video generation. Best on image benchmark (paper results).
|
| 159 |
+
> - **14B**: Best overall performance among 14B models (paper results).
|
| 160 |
+
|
| 161 |
+
<br>
|
| 162 |
+
|
| 163 |
+
|
| 164 |
+
## ☕️ Quick Inference
|
| 165 |
+
|
| 166 |
+
We provide several examples in the [`examples`](./examples) folder.
|
| 167 |
+
Run the following commands to try it out:
|
| 168 |
+
|
| 169 |
+
```bash
|
| 170 |
+
# Step 1: Prepare model input
|
| 171 |
+
cd video-generation
|
| 172 |
+
python infer_preprocess.py
|
| 173 |
+
|
| 174 |
+
# Step 2: Run inference with your preferred model
|
| 175 |
+
python inference_1.3b.py # For 1.3B model
|
| 176 |
+
# or
|
| 177 |
+
python inference_14b.py # For 14B model
|
| 178 |
+
```
|
| 179 |
+
You can enter the script to modify the input path.
|
| 180 |
+
|
| 181 |
+
<br>
|
| 182 |
+
|
| 183 |
+
## 🎬 Training from scratch
|
| 184 |
+
|
| 185 |
+
>💡 **Data Collection Required**: We find current open-source datasets are not sufficient for training from scratch. We strongly recommend collecting *at least 3,000 additional high-quality video samples* for better results.
|
| 186 |
+
|
| 187 |
+
We divide the training process into several steps to help you train from scratch (using 1.3B as an example).
|
| 188 |
+
|
| 189 |
+
1. Download Pretrained Models
|
| 190 |
+
|
| 191 |
+
Download the base model from HuggingFace: [Wan-AI/Wan2.1-T2V-1.3B-Diffusers](https://huggingface.co/Wan-AI/Wan2.1-T2V-1.3B-Diffusers)
|
| 192 |
+
|
| 193 |
+
2. Download Training Datasets and Pose Pool
|
| 194 |
+
|
| 195 |
+
```bash
|
| 196 |
+
cd datasets
|
| 197 |
+
bash setup_datasets.sh
|
| 198 |
+
```
|
| 199 |
+
|
| 200 |
+
This will download and prepare:
|
| 201 |
+
- Training datasets (open-source + cartoon): `datasets/opensource_dataset/`
|
| 202 |
+
- Pose pool for face enhancement: `datasets/opensource_pose_pool/`
|
| 203 |
+
|
| 204 |
+
<details>
|
| 205 |
+
<summary>Manual Download Links</summary>
|
| 206 |
+
|
| 207 |
+
- [opensource_dataset](https://huggingface.co/datasets/MochunniaN1/One-to-All-sub/tree/main/opensource_dataset)
|
| 208 |
+
- [opensource_pose_pool](https://huggingface.co/datasets/MochunniaN1/One-to-All-sub/tree/main/opensource_pose_pool)
|
| 209 |
+
|
| 210 |
+
</details>
|
| 211 |
+
|
| 212 |
+
3. Training
|
| 213 |
+
|
| 214 |
+
We provide three-stage training scripts:
|
| 215 |
+
* Stage 1: Reference Extractor
|
| 216 |
+
|
| 217 |
+
```bash
|
| 218 |
+
cd video-generation
|
| 219 |
+
bash training_scripts/train1.3b_only_refextractor_2d.sh
|
| 220 |
+
# Convert checkpoint to FP32
|
| 221 |
+
cd outputs_wanx1.3b/train1.3b_only_refextractor_2d/checkpoint-xxx
|
| 222 |
+
mkdir fp32_model_xxx
|
| 223 |
+
python zero_to_fp32.py . fp32_model_xxx --safe_serialization
|
| 224 |
+
# Run inference (update model path in inference_refextractor.py first)
|
| 225 |
+
cd ../../../
|
| 226 |
+
# Edit inference_refextractor.py and change ckpt_path to:
|
| 227 |
+
# ./outputs_wanx1.3b/train1.3b_only_refextractor_2d/checkpoint-xxx/fp32_model_xxx
|
| 228 |
+
python inference_refextractor.py
|
| 229 |
+
```
|
| 230 |
+
|
| 231 |
+
* Stage 2: Pose Control
|
| 232 |
+
```bash
|
| 233 |
+
bash training_scripts/train1.3b_posecontrol_prefix_2d.sh
|
| 234 |
+
```
|
| 235 |
+
* Stage 3: Token Replace for Long video generation
|
| 236 |
+
```bash
|
| 237 |
+
bash training_scripts/train1.3b_posecontrol_prefix_2d_tokenreplace.sh
|
| 238 |
+
```
|
| 239 |
+
> 💡 **Training Notes**:
|
| 240 |
+
> - **Each stage uses different training resolutions** - check the scripts for specific resolution settings
|
| 241 |
+
> - **Fine-tuning from our checkpoints**: If you want to continue training from our pre-trained models, directly use the *Stage 3 script* and modify the checkpoint path
|
| 242 |
+
|
| 243 |
+
<br>
|
| 244 |
+
|
| 245 |
+
## 📊 Reproduce Paper Results
|
| 246 |
+
|
| 247 |
+
We provide scripts to reproduce the quantitative results reported in our paper.
|
| 248 |
+
|
| 249 |
+
1. Download Benchmark
|
| 250 |
+
```bash
|
| 251 |
+
cd benchmark
|
| 252 |
+
bash setup_datasets.sh
|
| 253 |
+
```
|
| 254 |
+
2. Prepare Model Input
|
| 255 |
+
```bash
|
| 256 |
+
cd ../video-generation
|
| 257 |
+
python reproduce/infer_preprocess.py
|
| 258 |
+
```
|
| 259 |
+
3. Run Inference
|
| 260 |
+
|
| 261 |
+
We provide inference scripts for different model sizes and datasets:
|
| 262 |
+
```bash
|
| 263 |
+
# TikTok dataset
|
| 264 |
+
python reproduce/inference_tiktok1.3b.py # 1.3B model
|
| 265 |
+
python reproduce/inference_tiktok14b.py # 14B model
|
| 266 |
+
|
| 267 |
+
# Cartoon dataset
|
| 268 |
+
python reproduce/inference_cartoon1.3b.py # 1.3B model
|
| 269 |
+
python reproduce/inference_cartoon14b.py # 14B model
|
| 270 |
+
|
| 271 |
+
4. Prepare gt/pred pairs for Judge
|
| 272 |
+
```bash
|
| 273 |
+
cd ../benchmark
|
| 274 |
+
# TikTok dataset
|
| 275 |
+
python prepare_eval_frames_tiktok.py
|
| 276 |
+
# Cartoon dataset
|
| 277 |
+
python prepare_eval_frames_cartoon.py
|
| 278 |
+
```
|
| 279 |
+
|
| 280 |
+
5. Run judge
|
| 281 |
+
```bash
|
| 282 |
+
# prepare DisCo environment and lpips fvd ckpt for judge
|
| 283 |
+
cd DisCo
|
| 284 |
+
# TikTok dataset
|
| 285 |
+
bash eval_tiktok.sh
|
| 286 |
+
python summary.py
|
| 287 |
+
```
|
| 288 |
+
|
| 289 |
+
<br>
|
| 290 |
+
|
| 291 |
+
## Acknowledgments
|
| 292 |
+
|
| 293 |
+
Our project is based on [opensora](https://github.com/hpcaitech/Open-Sora). Some codes are brought from [StableAnimator](https://github.com/Francis-Rings/StableAnimator) and [Wan-Animate](https://github.com/Wan-Video/Wan2.2). Thanks for their awesome works.
|
| 294 |
+
|
| 295 |
+
## 📝 Citation
|
| 296 |
+
If you find our work helpful or inspiring, please feel free to cite it.
|
| 297 |
+
|
| 298 |
+
```bibtex
|
| 299 |
+
@article{shi2025one,
|
| 300 |
+
title={One-to-All Animation: Alignment-Free Character Animation and Image Pose Transfer},
|
| 301 |
+
author={Shi, Shijun and Xu, Jing and Li, Zhihang and Peng, Chunli and Yang, Xiaoda and Lu, Lijing and Hu, Kai and Zhang, Jiangning},
|
| 302 |
+
journal={arXiv preprint arXiv:2511.22940},
|
| 303 |
+
year={2025}
|
| 304 |
+
}
|
| 305 |
+
```
|
| 306 |
+
## 📄 License
|
| 307 |
+
This repository is released under the [Apache License 2.0](LICENSE).
|
| 308 |
+
|
| 309 |
+
## 📧 Contact
|
| 310 |
+
If you have any questions, please feel free to reach us at `ssj180123@gmail.com`
|
One-to-All-Animation/assets/1.3b_examples/combined_video1.gif
ADDED

|
Git LFS Details
|
One-to-All-Animation/assets/1.3b_examples/combined_video2.gif
ADDED

|
Git LFS Details
|
One-to-All-Animation/assets/1.3b_examples/ref3_motion1_1.3b.gif
ADDED

|
Git LFS Details
|
One-to-All-Animation/assets/1.3b_examples/ref3_motion2_1.3b.gif
ADDED

|
Git LFS Details
|
One-to-All-Animation/assets/1.3b_examples/ref3_motion3_1.3b.gif
ADDED

|
Git LFS Details
|
One-to-All-Animation/assets/14b_examples/ref_1_motion1.gif
ADDED

|
Git LFS Details
|
One-to-All-Animation/assets/14b_examples/ref_1_motion2.gif
ADDED

|
Git LFS Details
|
One-to-All-Animation/assets/14b_examples/ref_1_motion3.gif
ADDED

|
Git LFS Details
|
One-to-All-Animation/assets/14b_examples/ref_2_motion1.gif
ADDED

|
Git LFS Details
|
One-to-All-Animation/assets/14b_examples/ref_2_motion2.gif
ADDED

|
Git LFS Details
|
One-to-All-Animation/assets/14b_examples/ref_2_motion3.gif
ADDED

|
Git LFS Details
|
One-to-All-Animation/benchmark/DisCo/.gitignore
ADDED
|
@@ -0,0 +1,74 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
aux_data
|
| 2 |
+
azcopy
|
| 3 |
+
vis_temp
|
| 4 |
+
.amltconfig
|
| 5 |
+
*.pt
|
| 6 |
+
scripts/webvid_train_filelist.*
|
| 7 |
+
scripts/webvid_val_filelist.*
|
| 8 |
+
tool/ori.png
|
| 9 |
+
tool/gt.jpg
|
| 10 |
+
src/taming-transformers
|
| 11 |
+
src/clip
|
| 12 |
+
.vscode
|
| 13 |
+
xiyin_datasets
|
| 14 |
+
tiktok_datasets
|
| 15 |
+
blob_dir
|
| 16 |
+
blob
|
| 17 |
+
.amltconfig
|
| 18 |
+
|
| 19 |
+
# Byte-compiled / optimized / DLL files
|
| 20 |
+
__pycache__/
|
| 21 |
+
*.py[cod]
|
| 22 |
+
C extensions
|
| 23 |
+
*.so
|
| 24 |
+
|
| 25 |
+
# Distribution / packaging
|
| 26 |
+
bin/
|
| 27 |
+
build/
|
| 28 |
+
develop-eggs/
|
| 29 |
+
dist/
|
| 30 |
+
eggs/
|
| 31 |
+
lib/
|
| 32 |
+
lib64/
|
| 33 |
+
parts/
|
| 34 |
+
sdist/
|
| 35 |
+
var/
|
| 36 |
+
*.egg-info/
|
| 37 |
+
.installed.cfg
|
| 38 |
+
*.egg
|
| 39 |
+
|
| 40 |
+
# Installer logs
|
| 41 |
+
pip-log.txt
|
| 42 |
+
pip-delete-this-directory.txt
|
| 43 |
+
|
| 44 |
+
# Unit test / coverage reports
|
| 45 |
+
.tox/
|
| 46 |
+
.coverage
|
| 47 |
+
.cache
|
| 48 |
+
nosetests.xml
|
| 49 |
+
coverage.xml
|
| 50 |
+
|
| 51 |
+
# Translations
|
| 52 |
+
*.mo
|
| 53 |
+
|
| 54 |
+
# Mr Developer
|
| 55 |
+
.mr.developer.cfg
|
| 56 |
+
.project
|
| 57 |
+
.pydevproject
|
| 58 |
+
|
| 59 |
+
# Rope
|
| 60 |
+
.ropeproject
|
| 61 |
+
|
| 62 |
+
# Django stuff:
|
| 63 |
+
*.log
|
| 64 |
+
*.pot
|
| 65 |
+
|
| 66 |
+
# Sphinx documentation
|
| 67 |
+
docs/_build/
|
| 68 |
+
|
| 69 |
+
# dirs
|
| 70 |
+
/save_results
|
| 71 |
+
/pretrain_model
|
| 72 |
+
/command
|
| 73 |
+
/cocoapi
|
| 74 |
+
debug.sh
|
One-to-All-Animation/benchmark/DisCo/LICENSE
ADDED
|
@@ -0,0 +1,201 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
Apache License
|
| 2 |
+
Version 2.0, January 2004
|
| 3 |
+
http://www.apache.org/licenses/
|
| 4 |
+
|
| 5 |
+
TERMS AND CONDITIONS FOR USE, REPRODUCTION, AND DISTRIBUTION
|
| 6 |
+
|
| 7 |
+
1. Definitions.
|
| 8 |
+
|
| 9 |
+
"License" shall mean the terms and conditions for use, reproduction,
|
| 10 |
+
and distribution as defined by Sections 1 through 9 of this document.
|
| 11 |
+
|
| 12 |
+
"Licensor" shall mean the copyright owner or entity authorized by
|
| 13 |
+
the copyright owner that is granting the License.
|
| 14 |
+
|
| 15 |
+
"Legal Entity" shall mean the union of the acting entity and all
|
| 16 |
+
other entities that control, are controlled by, or are under common
|
| 17 |
+
control with that entity. For the purposes of this definition,
|
| 18 |
+
"control" means (i) the power, direct or indirect, to cause the
|
| 19 |
+
direction or management of such entity, whether by contract or
|
| 20 |
+
otherwise, or (ii) ownership of fifty percent (50%) or more of the
|
| 21 |
+
outstanding shares, or (iii) beneficial ownership of such entity.
|
| 22 |
+
|
| 23 |
+
"You" (or "Your") shall mean an individual or Legal Entity
|
| 24 |
+
exercising permissions granted by this License.
|
| 25 |
+
|
| 26 |
+
"Source" form shall mean the preferred form for making modifications,
|
| 27 |
+
including but not limited to software source code, documentation
|
| 28 |
+
source, and configuration files.
|
| 29 |
+
|
| 30 |
+
"Object" form shall mean any form resulting from mechanical
|
| 31 |
+
transformation or translation of a Source form, including but
|
| 32 |
+
not limited to compiled object code, generated documentation,
|
| 33 |
+
and conversions to other media types.
|
| 34 |
+
|
| 35 |
+
"Work" shall mean the work of authorship, whether in Source or
|
| 36 |
+
Object form, made available under the License, as indicated by a
|
| 37 |
+
copyright notice that is included in or attached to the work
|
| 38 |
+
(an example is provided in the Appendix below).
|
| 39 |
+
|
| 40 |
+
"Derivative Works" shall mean any work, whether in Source or Object
|
| 41 |
+
form, that is based on (or derived from) the Work and for which the
|
| 42 |
+
editorial revisions, annotations, elaborations, or other modifications
|
| 43 |
+
represent, as a whole, an original work of authorship. For the purposes
|
| 44 |
+
of this License, Derivative Works shall not include works that remain
|
| 45 |
+
separable from, or merely link (or bind by name) to the interfaces of,
|
| 46 |
+
the Work and Derivative Works thereof.
|
| 47 |
+
|
| 48 |
+
"Contribution" shall mean any work of authorship, including
|
| 49 |
+
the original version of the Work and any modifications or additions
|
| 50 |
+
to that Work or Derivative Works thereof, that is intentionally
|
| 51 |
+
submitted to Licensor for inclusion in the Work by the copyright owner
|
| 52 |
+
or by an individual or Legal Entity authorized to submit on behalf of
|
| 53 |
+
the copyright owner. For the purposes of this definition, "submitted"
|
| 54 |
+
means any form of electronic, verbal, or written communication sent
|
| 55 |
+
to the Licensor or its representatives, including but not limited to
|
| 56 |
+
communication on electronic mailing lists, source code control systems,
|
| 57 |
+
and issue tracking systems that are managed by, or on behalf of, the
|
| 58 |
+
Licensor for the purpose of discussing and improving the Work, but
|
| 59 |
+
excluding communication that is conspicuously marked or otherwise
|
| 60 |
+
designated in writing by the copyright owner as "Not a Contribution."
|
| 61 |
+
|
| 62 |
+
"Contributor" shall mean Licensor and any individual or Legal Entity
|
| 63 |
+
on behalf of whom a Contribution has been received by Licensor and
|
| 64 |
+
subsequently incorporated within the Work.
|
| 65 |
+
|
| 66 |
+
2. Grant of Copyright License. Subject to the terms and conditions of
|
| 67 |
+
this License, each Contributor hereby grants to You a perpetual,
|
| 68 |
+
worldwide, non-exclusive, no-charge, royalty-free, irrevocable
|
| 69 |
+
copyright license to reproduce, prepare Derivative Works of,
|
| 70 |
+
publicly display, publicly perform, sublicense, and distribute the
|
| 71 |
+
Work and such Derivative Works in Source or Object form.
|
| 72 |
+
|
| 73 |
+
3. Grant of Patent License. Subject to the terms and conditions of
|
| 74 |
+
this License, each Contributor hereby grants to You a perpetual,
|
| 75 |
+
worldwide, non-exclusive, no-charge, royalty-free, irrevocable
|
| 76 |
+
(except as stated in this section) patent license to make, have made,
|
| 77 |
+
use, offer to sell, sell, import, and otherwise transfer the Work,
|
| 78 |
+
where such license applies only to those patent claims licensable
|
| 79 |
+
by such Contributor that are necessarily infringed by their
|
| 80 |
+
Contribution(s) alone or by combination of their Contribution(s)
|
| 81 |
+
with the Work to which such Contribution(s) was submitted. If You
|
| 82 |
+
institute patent litigation against any entity (including a
|
| 83 |
+
cross-claim or counterclaim in a lawsuit) alleging that the Work
|
| 84 |
+
or a Contribution incorporated within the Work constitutes direct
|
| 85 |
+
or contributory patent infringement, then any patent licenses
|
| 86 |
+
granted to You under this License for that Work shall terminate
|
| 87 |
+
as of the date such litigation is filed.
|
| 88 |
+
|
| 89 |
+
4. Redistribution. You may reproduce and distribute copies of the
|
| 90 |
+
Work or Derivative Works thereof in any medium, with or without
|
| 91 |
+
modifications, and in Source or Object form, provided that You
|
| 92 |
+
meet the following conditions:
|
| 93 |
+
|
| 94 |
+
(a) You must give any other recipients of the Work or
|
| 95 |
+
Derivative Works a copy of this License; and
|
| 96 |
+
|
| 97 |
+
(b) You must cause any modified files to carry prominent notices
|
| 98 |
+
stating that You changed the files; and
|
| 99 |
+
|
| 100 |
+
(c) You must retain, in the Source form of any Derivative Works
|
| 101 |
+
that You distribute, all copyright, patent, trademark, and
|
| 102 |
+
attribution notices from the Source form of the Work,
|
| 103 |
+
excluding those notices that do not pertain to any part of
|
| 104 |
+
the Derivative Works; and
|
| 105 |
+
|
| 106 |
+
(d) If the Work includes a "NOTICE" text file as part of its
|
| 107 |
+
distribution, then any Derivative Works that You distribute must
|
| 108 |
+
include a readable copy of the attribution notices contained
|
| 109 |
+
within such NOTICE file, excluding those notices that do not
|
| 110 |
+
pertain to any part of the Derivative Works, in at least one
|
| 111 |
+
of the following places: within a NOTICE text file distributed
|
| 112 |
+
as part of the Derivative Works; within the Source form or
|
| 113 |
+
documentation, if provided along with the Derivative Works; or,
|
| 114 |
+
within a display generated by the Derivative Works, if and
|
| 115 |
+
wherever such third-party notices normally appear. The contents
|
| 116 |
+
of the NOTICE file are for informational purposes only and
|
| 117 |
+
do not modify the License. You may add Your own attribution
|
| 118 |
+
notices within Derivative Works that You distribute, alongside
|
| 119 |
+
or as an addendum to the NOTICE text from the Work, provided
|
| 120 |
+
that such additional attribution notices cannot be construed
|
| 121 |
+
as modifying the License.
|
| 122 |
+
|
| 123 |
+
You may add Your own copyright statement to Your modifications and
|
| 124 |
+
may provide additional or different license terms and conditions
|
| 125 |
+
for use, reproduction, or distribution of Your modifications, or
|
| 126 |
+
for any such Derivative Works as a whole, provided Your use,
|
| 127 |
+
reproduction, and distribution of the Work otherwise complies with
|
| 128 |
+
the conditions stated in this License.
|
| 129 |
+
|
| 130 |
+
5. Submission of Contributions. Unless You explicitly state otherwise,
|
| 131 |
+
any Contribution intentionally submitted for inclusion in the Work
|
| 132 |
+
by You to the Licensor shall be under the terms and conditions of
|
| 133 |
+
this License, without any additional terms or conditions.
|
| 134 |
+
Notwithstanding the above, nothing herein shall supersede or modify
|
| 135 |
+
the terms of any separate license agreement you may have executed
|
| 136 |
+
with Licensor regarding such Contributions.
|
| 137 |
+
|
| 138 |
+
6. Trademarks. This License does not grant permission to use the trade
|
| 139 |
+
names, trademarks, service marks, or product names of the Licensor,
|
| 140 |
+
except as required for reasonable and customary use in describing the
|
| 141 |
+
origin of the Work and reproducing the content of the NOTICE file.
|
| 142 |
+
|
| 143 |
+
7. Disclaimer of Warranty. Unless required by applicable law or
|
| 144 |
+
agreed to in writing, Licensor provides the Work (and each
|
| 145 |
+
Contributor provides its Contributions) on an "AS IS" BASIS,
|
| 146 |
+
WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or
|
| 147 |
+
implied, including, without limitation, any warranties or conditions
|
| 148 |
+
of TITLE, NON-INFRINGEMENT, MERCHANTABILITY, or FITNESS FOR A
|
| 149 |
+
PARTICULAR PURPOSE. You are solely responsible for determining the
|
| 150 |
+
appropriateness of using or redistributing the Work and assume any
|
| 151 |
+
risks associated with Your exercise of permissions under this License.
|
| 152 |
+
|
| 153 |
+
8. Limitation of Liability. In no event and under no legal theory,
|
| 154 |
+
whether in tort (including negligence), contract, or otherwise,
|
| 155 |
+
unless required by applicable law (such as deliberate and grossly
|
| 156 |
+
negligent acts) or agreed to in writing, shall any Contributor be
|
| 157 |
+
liable to You for damages, including any direct, indirect, special,
|
| 158 |
+
incidental, or consequential damages of any character arising as a
|
| 159 |
+
result of this License or out of the use or inability to use the
|
| 160 |
+
Work (including but not limited to damages for loss of goodwill,
|
| 161 |
+
work stoppage, computer failure or malfunction, or any and all
|
| 162 |
+
other commercial damages or losses), even if such Contributor
|
| 163 |
+
has been advised of the possibility of such damages.
|
| 164 |
+
|
| 165 |
+
9. Accepting Warranty or Additional Liability. While redistributing
|
| 166 |
+
the Work or Derivative Works thereof, You may choose to offer,
|
| 167 |
+
and charge a fee for, acceptance of support, warranty, indemnity,
|
| 168 |
+
or other liability obligations and/or rights consistent with this
|
| 169 |
+
License. However, in accepting such obligations, You may act only
|
| 170 |
+
on Your own behalf and on Your sole responsibility, not on behalf
|
| 171 |
+
of any other Contributor, and only if You agree to indemnify,
|
| 172 |
+
defend, and hold each Contributor harmless for any liability
|
| 173 |
+
incurred by, or claims asserted against, such Contributor by reason
|
| 174 |
+
of your accepting any such warranty or additional liability.
|
| 175 |
+
|
| 176 |
+
END OF TERMS AND CONDITIONS
|
| 177 |
+
|
| 178 |
+
APPENDIX: How to apply the Apache License to your work.
|
| 179 |
+
|
| 180 |
+
To apply the Apache License to your work, attach the following
|
| 181 |
+
boilerplate notice, with the fields enclosed by brackets "[]"
|
| 182 |
+
replaced with your own identifying information. (Don't include
|
| 183 |
+
the brackets!) The text should be enclosed in the appropriate
|
| 184 |
+
comment syntax for the file format. We also recommend that a
|
| 185 |
+
file or class name and description of purpose be included on the
|
| 186 |
+
same "printed page" as the copyright notice for easier
|
| 187 |
+
identification within third-party archives.
|
| 188 |
+
|
| 189 |
+
Copyright [yyyy] [name of copyright owner]
|
| 190 |
+
|
| 191 |
+
Licensed under the Apache License, Version 2.0 (the "License");
|
| 192 |
+
you may not use this file except in compliance with the License.
|
| 193 |
+
You may obtain a copy of the License at
|
| 194 |
+
|
| 195 |
+
http://www.apache.org/licenses/LICENSE-2.0
|
| 196 |
+
|
| 197 |
+
Unless required by applicable law or agreed to in writing, software
|
| 198 |
+
distributed under the License is distributed on an "AS IS" BASIS,
|
| 199 |
+
WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
|
| 200 |
+
See the License for the specific language governing permissions and
|
| 201 |
+
limitations under the License.
|
One-to-All-Animation/benchmark/DisCo/PREPRO.md
ADDED
|
@@ -0,0 +1,107 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
Here we provide the scripts for reference to automatically process the foreground mask and generate the human skeleton.
|
| 2 |
+
|
| 3 |
+
The target dataset which need to be processed should be like:
|
| 4 |
+
|
| 5 |
+
```
|
| 6 |
+
Target Dataset
|
| 7 |
+
└── 001/
|
| 8 |
+
├── 0000.png
|
| 9 |
+
└── 0001.png
|
| 10 |
+
...
|
| 11 |
+
└── 002/
|
| 12 |
+
├── 0000.png
|
| 13 |
+
└── 0001.png
|
| 14 |
+
...
|
| 15 |
+
```
|
| 16 |
+
|
| 17 |
+
|
| 18 |
+
|
| 19 |
+
### Grounded-SAM
|
| 20 |
+
|
| 21 |
+
#### Installation
|
| 22 |
+
|
| 23 |
+
```
|
| 24 |
+
# 1. Follow the official repo (https://github.com/IDEA-Research/Grounded-Segment-Anything) for package installation
|
| 25 |
+
|
| 26 |
+
# 2. download the pre-trained weights
|
| 27 |
+
wget https://dl.fbaipublicfiles.com/segment_anything/sam_vit_h_4b8939.pth
|
| 28 |
+
wget https://github.com/IDEA-Research/GroundingDINO/releases/download/v0.1.0-alpha/groundingdino_swint_ogc.pth
|
| 29 |
+
```
|
| 30 |
+
|
| 31 |
+
#### Run
|
| 32 |
+
|
| 33 |
+
```
|
| 34 |
+
python ./annotator/grounded-sam/run.py --dataset_root /path/to/target/dataset
|
| 35 |
+
```
|
| 36 |
+
|
| 37 |
+
|
| 38 |
+
|
| 39 |
+
|
| 40 |
+
|
| 41 |
+
### OpenPose
|
| 42 |
+
|
| 43 |
+
#### Installation
|
| 44 |
+
|
| 45 |
+
```
|
| 46 |
+
# 1. Follow the pytorch-openpose repo (https://github.com/Hzzone/pytorch-openpose) for package installation
|
| 47 |
+
|
| 48 |
+
# 2. download the pre-trained weights
|
| 49 |
+
wget -O body_pose_model.pth https://www.dropbox.com/sh/7xbup2qsn7vvjxo/AABaYNMvvNVFRWqyDXl7KQUxa/body_pose_model.pth?dl=1
|
| 50 |
+
```
|
| 51 |
+
|
| 52 |
+
#### Run
|
| 53 |
+
|
| 54 |
+
```
|
| 55 |
+
python ./annotator/openpose/run.py --dataset_root /path/to/target/dataset
|
| 56 |
+
```
|
| 57 |
+
|
| 58 |
+
|
| 59 |
+
|
| 60 |
+
|
| 61 |
+
|
| 62 |
+
### TSV preparation
|
| 63 |
+
|
| 64 |
+
After running Grounded SAM and OpenPose, prepare the data structured as below:
|
| 65 |
+
|
| 66 |
+
```
|
| 67 |
+
Target Dataset
|
| 68 |
+
└── 001/
|
| 69 |
+
├── 0000.png
|
| 70 |
+
├── 0001.png
|
| 71 |
+
├── ...
|
| 72 |
+
├────── groundsam
|
| 73 |
+
| ├── 000001.png.mask.jpg
|
| 74 |
+
| ├── 000002.png.mask.jpg
|
| 75 |
+
| └── ...
|
| 76 |
+
└────── openpose_json
|
| 77 |
+
├── 000001.png.json
|
| 78 |
+
├── 000002.png.json
|
| 79 |
+
└── ...
|
| 80 |
+
└── 002/
|
| 81 |
+
├── 0000.png
|
| 82 |
+
├── 0001.png
|
| 83 |
+
├── ...
|
| 84 |
+
├────── groundsam
|
| 85 |
+
| ├── 000001.png.mask.jpg
|
| 86 |
+
| ├── 000002.png.mask.jpg
|
| 87 |
+
| └── ...
|
| 88 |
+
└────── openpose_json
|
| 89 |
+
├── 000001.png.json
|
| 90 |
+
├── 000002.png.json
|
| 91 |
+
└── ...
|
| 92 |
+
```
|
| 93 |
+
|
| 94 |
+
We also provide a preprocessed toy dataset as example. You may find the example dataset in folder `./tsv_example/toy_dataset`
|
| 95 |
+
|
| 96 |
+
Run the following script to convert your dataset to tsv format
|
| 97 |
+
|
| 98 |
+
```
|
| 99 |
+
python ./tsv_example/create_custom_dataset_tsvs.py --split train --root_folder PATH_TO_YOUR_DATASET_FOLDER --output_folder PATH_TO_DESIRED_FOLDER
|
| 100 |
+
```
|
| 101 |
+
|
| 102 |
+
For instance, `PATH_TO_YOUR_DATASET_FOLDER=./tsv_example/toy_dataset` and `PATH_TO_DESIRED_FOLDER=./tsv_example/toy_dataset/tsv`
|
| 103 |
+
|
| 104 |
+
|
| 105 |
+
### TSV visualization
|
| 106 |
+
|
| 107 |
+
Once the tsv files are generated, we provide a jupyter notebook for data visualization. Please refer to `visualize_tsv.ipynb` for details.
|
One-to-All-Animation/benchmark/DisCo/README.md
ADDED
|
@@ -0,0 +1,426 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
# DisCo: Disentangled Control for Realistic Human Dance Generation
|
| 2 |
+
|
| 3 |
+
<a href='https://disco-dance.github.io/'><img src='https://img.shields.io/badge/Project-Page-Green'></a> <a href='https://arxiv.org/abs/2307.00040'><img src='https://img.shields.io/badge/Paper-Arxiv-red'></a> <a href='https://b9652ca65fb3fab63a.gradio.live/'><img src='https://img.shields.io/badge/%F0%9F%A4%97%20Hugging%20Face-Spaces-blue'></a> [](https://colab.research.google.com/drive/1dErsSwSEdcAyP6V_mqayW0qdPuoHSz-j?usp=sharing) [](https://youtu.be/D_mPPjUCDjE) <a href='https://drive.google.com/file/d/1AlN3Thg46RlH5uhLK-ZAIivo-C8IJeif/view?usp=sharing/'><img src='https://img.shields.io/badge/Slides-GoogleDrive-yellow'></a>
|
| 4 |
+
|
| 5 |
+
[Tan Wang*](https://wangt-cn.github.io/), [Linjie Li*](https://scholar.google.com/citations?user=WR875gYAAAAJ&hl=en), [Kevin Lin*](https://scholar.google.com/citations?hl=en&user=LKSy1kwAAAAJ), [Yuanhao Zhai](https://www.yhzhai.com/), [Chung-Ching Lin](https://scholar.google.com/citations?hl=en&user=legkbM0AAAAJ), [Zhengyuan Yang](https://scholar.google.com/citations?hl=en&user=rP02ve8AAAAJ), [Hanwang Zhang](https://scholar.google.com/citations?hl=en&user=YG0DFyYAAAAJ), [Zicheng Liu](https://scholar.google.com/citations?hl=en&user=bkALdvsAAAAJ), [Lijuan Wang](https://scholar.google.com/citations?hl=en&user=cDcWXuIAAAAJ)
|
| 6 |
+
|
| 7 |
+
**Nanyang Technological University | Microsoft Azure AI | University at Buffalo**
|
| 8 |
+
|
| 9 |
+
[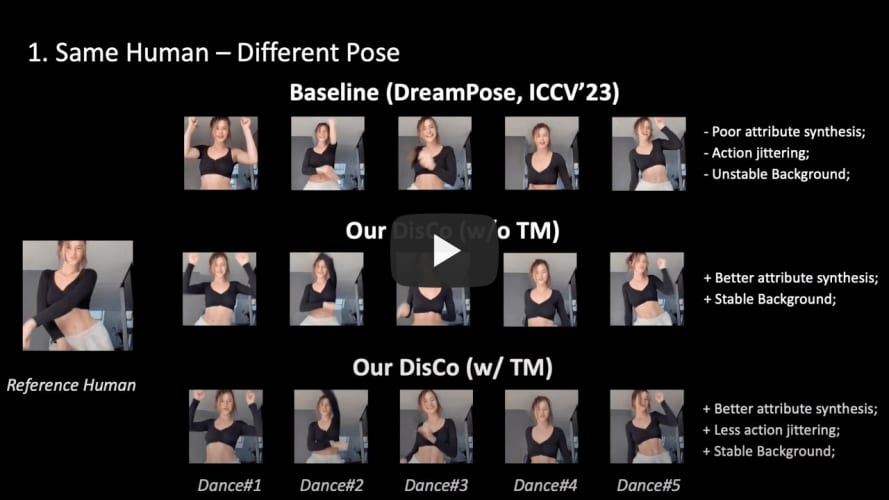](https://youtu.be/D_mPPjUCDjE "DisCo: Disentangled Control for Referring Human Dance Generation in Real World")
|
| 10 |
+
|
| 11 |
+
<br><br/>
|
| 12 |
+
|
| 13 |
+
## :fire: News
|
| 14 |
+
* **[2024.07.15]** We present [IDOL](https://yhzhai.github.io/idol/), an enhancement of DisCo that simultaneously generates video and depth, enabling realistic 2.5D video synthesis.
|
| 15 |
+
* **[2024.04.08]** DisCo has been accepted by CVPR24. Please check the latest version of paper on [ArXiv](https://arxiv.org/abs/2307.00040).
|
| 16 |
+
* **[2023.12.30]** Update [slides](https://drive.google.com/file/d/1AlN3Thg46RlH5uhLK-ZAIivo-C8IJeif/view?usp=sharing) about introducing DisCo and summarizing recent works.
|
| 17 |
+
* **[2023.11.30]** Update DisCo w/ temporal module.
|
| 18 |
+
* **[2023.10.12]** Update the new ArXiv version of DisCo (Add temporal module; Synchronize FVD computation with MCVD; More baselines and visualizations, etc)
|
| 19 |
+
* **[2023.07.21]** Update the [construction guide](https://github.com/Wangt-CN/DisCo/blob/main/PREPRO.md) of the TSV file.
|
| 20 |
+
* **[2023.07.08]** Update the [Colab](https://colab.research.google.com/drive/1dErsSwSEdcAyP6V_mqayW0qdPuoHSz-j?usp=sharing) Demo (make sure our code/demo can be run on any machine)!
|
| 21 |
+
* **[2023.07.03]** Provide the local demo deployment [example code](https://github.com/Wangt-CN/DisCo#-demo). Now you can try our demo on you own dev machine!
|
| 22 |
+
* **[2023.07.03]** We update the Pre-training [tsv data](https://github.com/Wangt-CN/DisCo#1-human-attribute-pre-training).
|
| 23 |
+
* **[2023.06.28]** We have released DisCo Human Attribute Pre-training Code.
|
| 24 |
+
* **[2023.06.21]** DisCo Human Image Editing [Demo](https://b9652ca65fb3fab63a.gradio.live/) is released! Have a try!
|
| 25 |
+
* **[2023.06.21]** We release the human-specific fine-tuning [code](https://github.com/Wangt-CN/DisCo#human-specific-fine-tuning) for reference. Come and build your own specific dance model!
|
| 26 |
+
* **[2023.06.21]** Release the code for [general fine-tuning](https://github.com/Wangt-CN/DisCo#fine-tuning-with-disentangled-control).
|
| 27 |
+
* **[2023.06.21]** We release the human attribute pre-trained checkpoint and the fine-tuning checkpoint.
|
| 28 |
+
|
| 29 |
+
|
| 30 |
+
|
| 31 |
+
|
| 32 |
+
|
| 33 |
+
##### Other following projects you may find interesting:
|
| 34 |
+
|
| 35 |
+
|
| 36 |
+
* [Animate Anyone](https://arxiv.org/abs/2311.17117), from Alibaba
|
| 37 |
+
* [MagicAnimate](https://arxiv.org/abs/2311.16498), from TikTok
|
| 38 |
+
* [MagicDance](https://arxiv.org/abs/2311.12052), from TikTok
|
| 39 |
+
|
| 40 |
+
|
| 41 |
+
##### Comparison of recent works:
|
| 42 |
+
<p align="center">
|
| 43 |
+
<img src="figures/compare.png" width="90%" height="80%">
|
| 44 |
+
</p>
|
| 45 |
+
<br><br/>
|
| 46 |
+
|
| 47 |
+
## 🎨 Gradio Demo
|
| 48 |
+
|
| 49 |
+
#### Launch Demo Locally (Video dance generation demo is on the way!)
|
| 50 |
+
|
| 51 |
+
1. Download the fine-tuning checkpoint [model](https://entuedu-my.sharepoint.com/:f:/g/personal/tan317_e_ntu_edu_sg/EpEPp_6rFtFComv49I0bkKkBfqiJhFnbraiZSN0LjXpzHw) (our demo uses this [checkpoint](https://entuedu-my.sharepoint.com/:f:/g/personal/tan317_e_ntu_edu_sg/En3vpzKndr1OoBUoDhTCZvEBorQiXEhJzi6mYWNELVWnpg?e=AIrGlx), you can also use your own model); Download the [sd-image-variation](https://huggingface.co/lambdalabs/sd-image-variations-diffusers) via `git clone https://huggingface.co/lambdalabs/sd-image-variations-diffusers`.
|
| 52 |
+
|
| 53 |
+
2. Run the [jupyter notebook](https://github.com/Wangt-CN/DisCo/blob/main/human_img_edit_gradio.ipynb) file. All the required code/command are already set up. Remember to revise the pretrained model path `--pretrained_model` and `--pretrained_model_path (sd-va)` in `manual_args = [xxx]`.
|
| 54 |
+
|
| 55 |
+
3. After running, this jupyter will automatically launch the demo with your local dev GPU. You can visit the demo with the web link provided at the end of the notebook.
|
| 56 |
+
|
| 57 |
+
4. Or you can refer to our deployment with Colab [](https://colab.research.google.com/drive/1dErsSwSEdcAyP6V_mqayW0qdPuoHSz-j?usp=sharing). All the code are deployed from scratch!
|
| 58 |
+
|
| 59 |
+
<br><br/>
|
| 60 |
+
|
| 61 |
+
##### [[Online Gradio Demo]](https://b9652ca65fb3fab63a.gradio.live/) (Temporal)
|
| 62 |
+
|
| 63 |
+
<p align="center">
|
| 64 |
+
<img src="figures/demo.gif" width="90%" height="90%">
|
| 65 |
+
</p>
|
| 66 |
+
|
| 67 |
+
|
| 68 |
+
<br><br/>
|
| 69 |
+
|
| 70 |
+
|
| 71 |
+
|
| 72 |
+
## 📝 Introduction
|
| 73 |
+
|
| 74 |
+
In this project, we introduce **DisCo** as a generalized referring human dance generation toolkit, which supports both **human image & video generation** with **multiple usage cases** (pre-training, fine-tuning, and human-specific fine-tuning), especially good in real-world scenarios.
|
| 75 |
+
|
| 76 |
+
|
| 77 |
+
|
| 78 |
+
#### ✨Compared to existing works, DisCo achieves:
|
| 79 |
+
|
| 80 |
+
- **Generalizability** to a large-scale real-world human **without human-specific fine-tuning** (We also support [human-specific fine-tuning](https://github.com/Wangt-CN/DisCo#human-specific-fine-tuning)). Previous methods only support generation for a specific domain of human, e.g., [DreamPose](https://github.com/johannakarras/DreamPose) only generate fashion model with easy catwalk pose.
|
| 81 |
+
|
| 82 |
+
- Current **SOTA results** for referring human dance generation.
|
| 83 |
+
|
| 84 |
+
- Extensive usage cases and applications (see [project page](https://disco-dance.github.io/index.html) for more details).
|
| 85 |
+
|
| 86 |
+
- An easy-to-follow framework, supporting **efficient training** (x-formers, FP16 training, deepspeed, wandb) and **a wide range of possible research directions** (pre-training -> fine-tuning -> human-specific fine-tuning).
|
| 87 |
+
|
| 88 |
+
|
| 89 |
+
|
| 90 |
+
#### 🌟With this project, you can get:
|
| 91 |
+
|
| 92 |
+
- *\[User\]*: Just try our online demo! Or deploy the model inference locally.
|
| 93 |
+
- *\[Researcher\]*: An easy-to-use codebase for re-implementation and development.
|
| 94 |
+
- *\[Researcher\]*: A large amount of research directions for further improvement.
|
| 95 |
+
|
| 96 |
+
|
| 97 |
+
|
| 98 |
+
<br><br/>
|
| 99 |
+
|
| 100 |
+
## 🚀 Getting Started
|
| 101 |
+
|
| 102 |
+
### Installation
|
| 103 |
+
|
| 104 |
+
```sh
|
| 105 |
+
## after py3.8 env initialization
|
| 106 |
+
pip install --user torch==1.12.1+cu113 torchvision==0.13.1+cu113 -f https://download.pytorch.org/whl/torch_stable.html
|
| 107 |
+
pip install --user progressbar psutil pymongo simplejson yacs boto3 pyyaml ete3 easydict deprecated future django orderedset python-magic datasets h5py omegaconf einops ipdb
|
| 108 |
+
pip install --user --exists-action w -r requirements.txt
|
| 109 |
+
pip install git+https://github.com/microsoft/azfuse.git
|
| 110 |
+
|
| 111 |
+
|
| 112 |
+
## for acceleration
|
| 113 |
+
pip install --user deepspeed==0.6.3
|
| 114 |
+
pip install -v -U git+https://github.com/facebookresearch/xformers.git@main#egg=xformers
|
| 115 |
+
|
| 116 |
+
## you may need to downgrade prototbuf to 3.20.x
|
| 117 |
+
pip install protobuf==3.20.0
|
| 118 |
+
```
|
| 119 |
+
|
| 120 |
+
|
| 121 |
+
|
| 122 |
+
### Data Preparation
|
| 123 |
+
|
| 124 |
+
##### 1. Human Attribute Pre-training
|
| 125 |
+
|
| 126 |
+
We create a human image subset (700K Images) filtered from existing image corpus for human attribute pre-training:
|
| 127 |
+
|
| 128 |
+
| Dataset | COCO (Single Person) | TikTok Style | DeepFashion2 | SHHQ-1.0 | LAION-Human |
|
| 129 |
+
| -------- | :------------------: | :----------: | :----------: | :------: | :---------: |
|
| 130 |
+
| **Size** | 20K | 124K | 276K | 40K | 240K |
|
| 131 |
+
|
| 132 |
+
The pre-processed pre-training data with the efficient TSV data format can be downloaded [**here (Google Drive)**](https://drive.google.com/file/d/1N9gioWnkb3ZZytmT3Nzx4VjXjHxLsVB9/view?usp=sharing).
|
| 133 |
+
|
| 134 |
+
```
|
| 135 |
+
Data Root
|
| 136 |
+
└── composite/
|
| 137 |
+
├── train_xxx.yaml # The path need to be then specified in the training args
|
| 138 |
+
└── val_xxx.yaml
|
| 139 |
+
...
|
| 140 |
+
└── TikTokDance/
|
| 141 |
+
├── xxx_images.tsv
|
| 142 |
+
└── xxx_poses.tsv
|
| 143 |
+
...
|
| 144 |
+
└── coco/
|
| 145 |
+
├── xxx_images.tsv
|
| 146 |
+
└── xxx_poses.tsv
|
| 147 |
+
```
|
| 148 |
+
|
| 149 |
+
|
| 150 |
+
|
| 151 |
+
##### 2. Fine-tuning with Disentangled Control
|
| 152 |
+
|
| 153 |
+
We use the [TikTok dataset](https://www.yasamin.page/hdnet_tiktok) for the fine-tuning.
|
| 154 |
+
|
| 155 |
+
We have already pre-processed the tiktok data with the efficient TSV format which can be downloaded **[here (Google Drive)](https://drive.google.com/file/d/1_b4naNB1QozGL-tKyHwSSYzTw8RIh5z3/view?usp=sharing)**. (Note that we only use the 1st frame of each TikTok video as the reference image.)
|
| 156 |
+
|
| 157 |
+
The data folder structure should be like:
|
| 158 |
+
|
| 159 |
+
```
|
| 160 |
+
Data Root
|
| 161 |
+
└── composite_offset/
|
| 162 |
+
├── train_xxx.yaml # The path need to be then specified in the training args
|
| 163 |
+
└── val_xxx.yaml
|
| 164 |
+
...
|
| 165 |
+
└── TikTokDance/
|
| 166 |
+
├── xxx_images.tsv
|
| 167 |
+
└── xxx_poses.tsv
|
| 168 |
+
...
|
| 169 |
+
```
|
| 170 |
+
|
| 171 |
+
*PS: If you want to use your own data resource but with our TSV data structure, please follow [PREPRO.MD](https://github.com/Wangt-CN/DisCo/blob/main/PREPRO.md) for reference.
|
| 172 |
+
|
| 173 |
+
<br><br/>
|
| 174 |
+
|
| 175 |
+
|
| 176 |
+
|
| 177 |
+
### Human Attribute Pre-training
|
| 178 |
+
|
| 179 |
+
<p align="center">
|
| 180 |
+
<img src="figures/pretrain.gif" width="80%" height="80%">
|
| 181 |
+
</p>
|
| 182 |
+
|
| 183 |
+
|
| 184 |
+
**Training:**
|
| 185 |
+
|
| 186 |
+
```
|
| 187 |
+
AZFUSE_USE_FUSE=0 QD_USE_LINEIDX_8B=0 NCCL_ASYNC_ERROR_HANDLING=0 python finetune_sdm_yaml.py --cf config/ref_attn_clip_combine_controlnet_attr_pretraining/coco_S256_xformers_tsv_strongrand.py --do_train --root_dir /home1/wangtan/code/ms_internship2/github_repo/run_test \
|
| 188 |
+
--local_train_batch_size 64 --local_eval_batch_size 64 --log_dir exp/tiktok_pretrain \
|
| 189 |
+
--epochs 40 --deepspeed --eval_step 2000 --save_step 2000 --gradient_accumulate_steps 1 \
|
| 190 |
+
--learning_rate 1e-3 --fix_dist_seed --loss_target "noise" \
|
| 191 |
+
--train_yaml ./blob_dir/debug_output/video_sythesis/dataset/composite/train_TiktokDance-coco-single_person-Lindsey_0411_youtube-SHHQ-1.0-deepfashion2-laion_human-masks-single_cap.yaml --val_yaml ./blob_dir/debug_output/video_sythesis/dataset/composite/val_TiktokDance-coco-single_person-SHHQ-1.0-masks-single_cap.yaml \
|
| 192 |
+
--unet_unfreeze_type "transblocks" --refer_sdvae --ref_null_caption False --combine_clip_local --combine_use_mask \
|
| 193 |
+
--conds "masks" --max_eval_samples 2000 --strong_aug_stage1 --node_split_sampler 0
|
| 194 |
+
```
|
| 195 |
+
|
| 196 |
+
|
| 197 |
+
|
| 198 |
+
**Pre-trained Model Checkpoint: [OneDrive](https://entuedu-my.sharepoint.com/:f:/g/personal/tan317_e_ntu_edu_sg/EoH8KHplKPhGrIdKN6sPx_ABpurpPjNAvU3KdFgaPwNfJQ)**
|
| 199 |
+
|
| 200 |
+
<br><br/>
|
| 201 |
+
|
| 202 |
+
|
| 203 |
+
### Fine-tuning with Disentangled Control
|
| 204 |
+
|
| 205 |
+

|
| 206 |
+
|
| 207 |
+

|
| 208 |
+
|
| 209 |
+
|
| 210 |
+
|
| 211 |
+
<br><br/>
|
| 212 |
+
|
| 213 |
+
#### 1. Modify the config file
|
| 214 |
+
|
| 215 |
+
Download the `sd-image-variations-diffusers` from official [diffusers repo](https://huggingface.co/lambdalabs/sd-image-variations-diffusers) and put it according to the config file `pretrained_model_path`. Or you can also choose to modify the `pretrained_model_path`.
|
| 216 |
+
|
| 217 |
+
|
| 218 |
+
|
| 219 |
+
|
| 220 |
+
<br><br/>
|
| 221 |
+
#### 2. w/o Classifier-Free Guidance (CFG)
|
| 222 |
+
|
| 223 |
+
**Training:**
|
| 224 |
+
|
| 225 |
+
[*To enable WANDB, set up the wandb key in `utils/lib.py`]
|
| 226 |
+
|
| 227 |
+
[*To employ **multiple GPU running**, try to add `mpirun -np {GPU NUM}` before the `python`.]
|
| 228 |
+
|
| 229 |
+
```shell
|
| 230 |
+
WANDB_ENABLE=0 AZFUSE_USE_FUSE=0 NCCL_ASYNC_ERROR_HANDLING=0 mpirun -np 8 python finetune_sdm_yaml.py --cf config/ref_attn_clip_combine_controlnet/tiktok_S256L16_xformers_tsv.py \
|
| 231 |
+
--do_train --root_dir /home1/wangtan/code/ms_internship2/github_repo/run_test \
|
| 232 |
+
--local_train_batch_size 32 \
|
| 233 |
+
--local_eval_batch_size 32 \
|
| 234 |
+
--log_dir exp/tiktok_ft \
|
| 235 |
+
--epochs 20 --deepspeed \
|
| 236 |
+
--eval_step 500 --save_step 500 \
|
| 237 |
+
--gradient_accumulate_steps 1 \
|
| 238 |
+
--learning_rate 2e-4 --fix_dist_seed --loss_target "noise" \
|
| 239 |
+
--train_yaml /home/wangtan/data/disco/yaml_file/train_TiktokDance-poses-masks.yaml \
|
| 240 |
+
--val_yaml /home/wangtan/data/disco/yaml_file/new10val_TiktokDance-poses-masks.yaml \
|
| 241 |
+
--unet_unfreeze_type "all" \
|
| 242 |
+
--guidance_scale 3 \
|
| 243 |
+
--refer_sdvae \
|
| 244 |
+
--ref_null_caption False \
|
| 245 |
+
--combine_clip_local --combine_use_mask \
|
| 246 |
+
--conds "poses" "masks" \
|
| 247 |
+
--stage1_pretrain_path /path/to/pretrained_model_checkpoint/mp_rank_00_model_states.pt
|
| 248 |
+
```
|
| 249 |
+
|
| 250 |
+
|
| 251 |
+
|
| 252 |
+
|
| 253 |
+
|
| 254 |
+
**Visualization:**
|
| 255 |
+
|
| 256 |
+
To run the visualization, just change `--do_train` to `--eval_visu` . You can also specify the visualization folder name with `'--eval_save_filename' xxx`.
|
| 257 |
+
|
| 258 |
+
|
| 259 |
+
|
| 260 |
+
**Evaluation:**
|
| 261 |
+
|
| 262 |
+
You first need to run the evaluation to get the results. Then we use `gen_eval.sh` to one-stop get the evaluation metrics for {exp_dir_path}/{prediction_folder_name}
|
| 263 |
+
|
| 264 |
+
```shell
|
| 265 |
+
bash gen_eval.sh {exp_dir_path} {exp_dir_path}/{prediction_folder_name}
|
| 266 |
+
```
|
| 267 |
+
For example,
|
| 268 |
+
```
|
| 269 |
+
bash gen_eval.sh /home/kevintw/code/disco/github2/DisCo/save_results/TikTok_cfg_check /home/kevintw/code/disco/github2/DisCo/save_results/TikTok_cfg_check/pred_gs1.5_scale-cond1.0-ref1.0/
|
| 270 |
+
```
|
| 271 |
+
|
| 272 |
+
You may need to download the [pre-trained vision model](https://drive.google.com/file/d/1J8w3fGj6H6kmcW9G8Ff6tRQofblaG5Vn/view?usp=sharing) and revise the path in `gen_eval.sh` for achieving fvd metric.
|
| 273 |
+
|
| 274 |
+
##### Model Checkpoint (OneDrive): [TikTok Training Data](https://entuedu-my.sharepoint.com/:f:/g/personal/tan317_e_ntu_edu_sg/Em8tYZ_J_51On_cMQDtOpqoBRG9H3tZNd2Mm48DFh3sypA?e=cyBgJQ) | [More TikTok-Style Training Data](https://entuedu-my.sharepoint.com/:f:/g/personal/tan317_e_ntu_edu_sg/En3vpzKndr1OoBUoDhTCZvEBorQiXEhJzi6mYWNELVWnpg?e=AIrGlx)
|
| 275 |
+
|
| 276 |
+
|
| 277 |
+
|
| 278 |
+
|
| 279 |
+
|
| 280 |
+
<br><br/>
|
| 281 |
+
|
| 282 |
+
#### 3. w/ Classifier-Free Guidance (CFG) [CFG can bring a slightly better results]
|
| 283 |
+
|
| 284 |
+
**Training (add the following args into the training script of w/o CFG):**
|
| 285 |
+
|
| 286 |
+
```
|
| 287 |
+
--drop_ref 0.05 # probability to dropout the reference image during training
|
| 288 |
+
--guidance_scale 1.5 # the scale of the CFG
|
| 289 |
+
```
|
| 290 |
+
|
| 291 |
+
**Visualization:**
|
| 292 |
+
|
| 293 |
+
To run the visualization, just change `--do_train` to `--eval_visu` . You can also specify the visualization folder name with `'--eval_save_filename' xxx`. (Remember to also specify the `--guidance_scale`)
|
| 294 |
+
|
| 295 |
+
You can also check our command bash file `config/command_bash/tiktok_cfg.sh` for reference.
|
| 296 |
+
|
| 297 |
+
|
| 298 |
+
**Evaluation:**
|
| 299 |
+
|
| 300 |
+
Same with above
|
| 301 |
+
|
| 302 |
+
|
| 303 |
+
|
| 304 |
+
##### Model Checkpoint (OneDrive): [TikTok Training Data](https://entuedu-my.sharepoint.com/:f:/g/personal/tan317_e_ntu_edu_sg/EpJSOWGzrnlNn99nC691G8wBF-JnbuYCbgbHMRg6TQFAxg?e=QUJJOL) | [More TikTok-Style Training Data](https://entuedu-my.sharepoint.com/:f:/g/personal/tan317_e_ntu_edu_sg/EiDYzx84T8pMhrDtcoIU5w0By9ysDotKzmezShKkX8aE4g?e=zzLuEA)
|
| 305 |
+
|
| 306 |
+
|
| 307 |
+
<br><br/>
|
| 308 |
+
#### 4. Temporal module fine-tuning
|
| 309 |
+
**Training:**
|
| 310 |
+
After training the image DisCo model, we further incorporate temporal convolutional layers and temporal attention layers to improve the temporal smoothness. Note that the content for argument `--pretrained_model` should be the image DisCo model checkpoint, instead of stage 1 pre-trained checkpoint.
|
| 311 |
+
```shell
|
| 312 |
+
AZFUSE_USE_FUSE=0 NCCL_ASYNC_ERROR_HANDLING=0 python finetune_sdm_yaml.py --cf config/disco_w_tm/yz_tiktok_S256L16_xformers_tsv_temdisco_temp_attn.py \
|
| 313 |
+
--do_train --root_dir /home1/wangtan/code/ms_internship2/github_repo/run_test \
|
| 314 |
+
--local_train_batch_size 2 \
|
| 315 |
+
--local_eval_batch_size 2 \
|
| 316 |
+
--log_dir exp/tiktok_ft \
|
| 317 |
+
--epochs 20 --deepspeed \
|
| 318 |
+
--eval_step 500 --save_step 500 \
|
| 319 |
+
--gradient_accumulate_steps 1 \
|
| 320 |
+
--learning_rate 1e-4 --fix_dist_seed --loss_target "noise" \
|
| 321 |
+
--train_yaml /home/wangtan/data/disco/yaml_file/train_TiktokDance-poses-masks.yaml \
|
| 322 |
+
--val_yaml /home/wangtan/data/disco/yaml_file/new10val_TiktokDance-poses-masks.yaml \
|
| 323 |
+
--unet_unfreeze_type "all" \
|
| 324 |
+
--refer_sdvae \
|
| 325 |
+
--ref_null_caption False \
|
| 326 |
+
--combine_clip_local --combine_use_mask \
|
| 327 |
+
--train_sample_interval 4 \
|
| 328 |
+
--nframe 16 \
|
| 329 |
+
--frame_interval 1 \
|
| 330 |
+
--conds "poses" "masks" \
|
| 331 |
+
--pretrained_model /path/to/pretrained_model/mp_rank_00_model_states.pt
|
| 332 |
+
```
|
| 333 |
+
|
| 334 |
+
**Evaluation:**
|
| 335 |
+
Simply replace the previous `gen_eval.sh` script with the `gen_eval_tm.sh` script, as follows. GT folder path will be filled in automatically.
|
| 336 |
+
|
| 337 |
+
```shell
|
| 338 |
+
bash gen_eval_tm.sh {exp_dir_path} {exp_dir_path}/{prediction_folder_name}
|
| 339 |
+
```
|
| 340 |
+
|
| 341 |
+
##### Model checkpoint: [TikTok training data (w/ CFG)](https://entuedu-my.sharepoint.com/:f:/g/personal/tan317_e_ntu_edu_sg/Er5Ch49FzUdHpfBiZy3uN3cB87Zq8g4c9idEEzESdEy0qg?e=R3W7ij) | [More TikTok-Style Training Data (w/ CFG)](https://entuedu-my.sharepoint.com/:f:/g/personal/tan317_e_ntu_edu_sg/Evp1AG1ExZBIni78RIH2bMUBmg-orFvvIAPcfnGQ_lCZGQ?e=nTr0ci)
|
| 342 |
+
|
| 343 |
+
<br><br/>
|
| 344 |
+
|
| 345 |
+
#### 5. Possible issue for FVD metric reproduction
|
| 346 |
+
|
| 347 |
+
Please first check the github issue and response [here](https://github.com/Wangt-CN/DisCo/issues/25#issuecomment-1716394151). We have validated the checkpoint results on A100 GPU. If you still cannot reproduce the results, please open an issue or send me the email.
|
| 348 |
+
|
| 349 |
+
<br><br/>
|
| 350 |
+
|
| 351 |
+
### Human-Specific Fine-tuning
|
| 352 |
+
|
| 353 |
+

|
| 354 |
+
|
| 355 |
+
|
| 356 |
+
|
| 357 |
+
#### 1. Prepare dataset that you want to use for training
|
| 358 |
+
|
| 359 |
+
- Prepare a human-specific video or a set of human images
|
| 360 |
+
|
| 361 |
+
- Use Grounded-SAM and OpenPose to obtain human mask and human skeleton for each training image (See [PREPRO.MD](https://github.com/Wangt-CN/DisCo/blob/main/PREPRO.md) for more details)
|
| 362 |
+
|
| 363 |
+
- For human-specific fine-tuning, we recommend to directly use raw image/mask/pose for training rather than build TSV file. If you still want to use TSV file structure to prepare your data, please follow [PREPRO.MD](https://github.com/Wangt-CN/DisCo/blob/main/PREPRO.md) for reference.
|
| 364 |
+
|
| 365 |
+
|
| 366 |
+
|
| 367 |
+
#### 2. Run the following script for human-specific fine-tuning:
|
| 368 |
+
|
| 369 |
+
For parameter tuning, recommend to first tune the `learning-rate` and `unet_unfreeze_type`.
|
| 370 |
+
|
| 371 |
+
```python
|
| 372 |
+
AZFUSE_USE_FUSE=0 NCCL_ASYNC_ERROR_HANDLING=0 python finetune_sdm_yaml.py \
|
| 373 |
+
--cf config/ref_attn_clip_combine_controlnet_imgspecific_ft/webtan_S256L16_xformers_upsquare.py --do_train --root_dir /path/of/saving/root \
|
| 374 |
+
--local_train_batch_size 32 --local_eval_batch_size 32 --log_dir exp/human_specific_ft/ \
|
| 375 |
+
--epochs 20 --deepspeed --eval_step 500 --save_step 500 --gradient_accumulate_steps 1 \
|
| 376 |
+
--learning_rate 1e-3 --fix_dist_seed --loss_target "noise" \
|
| 377 |
+
--unet_unfreeze_type "crossattn" \
|
| 378 |
+
--refer_sdvae --ref_null_caption False --combine_clip_local --combine_use_mask --conds "poses" "masks" \
|
| 379 |
+
--freeze_pose True --freeze_background False \
|
| 380 |
+
--pretrained_model /path/to/the/ft_model_checkpoint \
|
| 381 |
+
--ft_iters 500 --ft_one_ref_image False --ft_idx dataset/folder/name --strong_aug_stage1 True --strong_rand_stage2 True
|
| 382 |
+
```
|
| 383 |
+
|
| 384 |
+
<br><br/>
|
| 385 |
+
## Notes
|
| 386 |
+
|
| 387 |
+
#### 1. Possible issue for FVD metric reproduction
|
| 388 |
+
|
| 389 |
+
Please first check the github issue and response [here](https://github.com/Wangt-CN/DisCo/issues/25#issuecomment-1716394151). We have validated the checkpoint results on A100 GPU. If you still cannot reproduce the results, please open an issue or send me the email.
|
| 390 |
+
|
| 391 |
+
#### 2. PSNR metric
|
| 392 |
+
|
| 393 |
+
We thank @Delicious-Bitter-Melon for for highlighting a potential numerical overflow issue in the implementation of the PSNR metric. This issue has been resolved in codebase, and the updated score is reflected in our latest version. It's important to note that this correction does not alter the trend or affect the overall conclusions.
|
| 394 |
+
|
| 395 |
+
#### 3. DisCo is not limited to upper-human.
|
| 396 |
+
|
| 397 |
+
Please check our latest paper for its generalizability. It can be easily achieved by incorporating extensive image scaling augmentations during the training phase.
|
| 398 |
+
|
| 399 |
+
|
| 400 |
+
<br><br/>
|
| 401 |
+
|
| 402 |
+
## Release Plan
|
| 403 |
+
|
| 404 |
+
- [x] Code for "Fine-tuning with Disentangled Control"
|
| 405 |
+
- [x] Code for "Human-Specific Fine-tuning"
|
| 406 |
+
- [x] Model Checkpoints for Pre-training and Fine-tuning
|
| 407 |
+
- [x] HuggingFace Demo
|
| 408 |
+
- [x] Code for "Human Attribute Pre-training"
|
| 409 |
+
|
| 410 |
+
|
| 411 |
+
|
| 412 |
+
<br><br/>
|
| 413 |
+
|
| 414 |
+
## Citation
|
| 415 |
+
|
| 416 |
+
If you use our work in your research, please cite:
|
| 417 |
+
|
| 418 |
+
```
|
| 419 |
+
@article{wang2023disco,
|
| 420 |
+
title={Disco: Disentangled control for realistic human dance generation},
|
| 421 |
+
author={Wang, Tan and Li, Linjie and Lin, Kevin and Zhai, Yuanhao and Lin, Chung-Ching and Yang, Zhengyuan and Zhang, Hanwang and Liu, Zicheng and Wang, Lijuan},
|
| 422 |
+
journal={arXiv preprint arXiv:2307.00040},
|
| 423 |
+
year={2023}
|
| 424 |
+
}
|
| 425 |
+
```
|
| 426 |
+
|
One-to-All-Animation/benchmark/DisCo/agent.py
ADDED
|
@@ -0,0 +1,1302 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
from utils.lib import *
|
| 2 |
+
from utils.dist import (
|
| 3 |
+
is_main_process, get_world_size,
|
| 4 |
+
reduce_dict, get_local_rank, synchronize,
|
| 5 |
+
get_rank,)
|
| 6 |
+
from utils.metric_logger import log_dict_to_wandb, setup_wandb, log_img_to_wandb
|
| 7 |
+
from utils.misc import humanbytes
|
| 8 |
+
from utils.deepspeed import get_deepspeed_config, fp32_to_fp16
|
| 9 |
+
import deepspeed
|
| 10 |
+
from torch import nn
|
| 11 |
+
import torch.nn.functional as F
|
| 12 |
+
from utils.basic_utils import move_to_cuda
|
| 13 |
+
from utils.common import ensure_directory
|
| 14 |
+
from utils.wutils_ldm import (
|
| 15 |
+
complex_to_device, logger, ensure_dirname, file2data, data2file,
|
| 16 |
+
Meter, Timer, adaptively_load_state_dict, get_parameters, ldm_tensor2img_wt, ldm_tensor2img)
|
| 17 |
+
import wandb
|
| 18 |
+
|
| 19 |
+
|
| 20 |
+
class WarmupLinearLR(T.optim.lr_scheduler._LRScheduler):
|
| 21 |
+
def __init__(
|
| 22 |
+
self,
|
| 23 |
+
optimizer,
|
| 24 |
+
max_iter,
|
| 25 |
+
min_lr=1e-8,
|
| 26 |
+
warmup_ratio=0.1,
|
| 27 |
+
last_epoch=-1,
|
| 28 |
+
):
|
| 29 |
+
self.max_iter = max_iter
|
| 30 |
+
self.min_lr = min_lr
|
| 31 |
+
self.warmup_ratio = warmup_ratio
|
| 32 |
+
self.warmup_iters = int(warmup_ratio*max_iter)
|
| 33 |
+
super(WarmupLinearLR, self).__init__(optimizer, last_epoch)
|
| 34 |
+
|
| 35 |
+
def get_lr_factor(self):
|
| 36 |
+
tot_step = self.max_iter
|
| 37 |
+
warmup_step = self.warmup_iters
|
| 38 |
+
step = self.last_epoch
|
| 39 |
+
if step < warmup_step:
|
| 40 |
+
return max(0, step / warmup_step)
|
| 41 |
+
elif step > tot_step:
|
| 42 |
+
step = tot_step
|
| 43 |
+
return max(0, (tot_step-step)/(tot_step-warmup_step))
|
| 44 |
+
|
| 45 |
+
def get_lr(self):
|
| 46 |
+
warmup_factor = self.get_lr_factor()
|
| 47 |
+
return [
|
| 48 |
+
max(self.min_lr, base_lr * warmup_factor)
|
| 49 |
+
for base_lr in self.base_lrs
|
| 50 |
+
]
|
| 51 |
+
|
| 52 |
+
|
| 53 |
+
class WarmupLinearConstantLR(T.optim.lr_scheduler._LRScheduler):
|
| 54 |
+
def __init__(
|
| 55 |
+
self,
|
| 56 |
+
optimizer,
|
| 57 |
+
max_iter,
|
| 58 |
+
min_lr=1e-8,
|
| 59 |
+
warmup_ratio=0.1,
|
| 60 |
+
last_epoch=-1,
|
| 61 |
+
):
|
| 62 |
+
self.max_iter = max_iter
|
| 63 |
+
self.min_lr = min_lr
|
| 64 |
+
self.warmup_ratio = warmup_ratio
|
| 65 |
+
self.warmup_iters = int(warmup_ratio*max_iter)
|
| 66 |
+
super(WarmupLinearConstantLR, self).__init__(optimizer, last_epoch)
|
| 67 |
+
|
| 68 |
+
def get_lr_factor(self):
|
| 69 |
+
tot_step = self.max_iter
|
| 70 |
+
warmup_step = self.warmup_iters
|
| 71 |
+
step = self.last_epoch
|
| 72 |
+
if step < warmup_step:
|
| 73 |
+
return max(0, step / warmup_step)
|
| 74 |
+
elif step >= warmup_step:
|
| 75 |
+
return 1. # constant base lr
|
| 76 |
+
|
| 77 |
+
def get_lr(self):
|
| 78 |
+
warmup_factor = self.get_lr_factor()
|
| 79 |
+
return [
|
| 80 |
+
max(self.min_lr, base_lr * warmup_factor)
|
| 81 |
+
for base_lr in self.base_lrs
|
| 82 |
+
]
|
| 83 |
+
|
| 84 |
+
|
| 85 |
+
class Agent():
|
| 86 |
+
def __init__(self, args, model=None, optimizer=None, scheduler=None):
|
| 87 |
+
super().__init__()
|
| 88 |
+
self.args, self.model = args, model
|
| 89 |
+
self.log_dir = args.log_dir
|
| 90 |
+
if optimizer is None:
|
| 91 |
+
if self.args.do_train:
|
| 92 |
+
logger.warning("Missing optimizer, check if its intended to train without optimizer")
|
| 93 |
+
self.optimizer = optimizer
|
| 94 |
+
if scheduler is None:
|
| 95 |
+
if self.args.do_train:
|
| 96 |
+
logger.warning("Missing scheduler, check if its intended to train without scheduler")
|
| 97 |
+
self.scheduler = scheduler
|
| 98 |
+
|
| 99 |
+
self.pretrained_model = self.args.pretrained_model
|
| 100 |
+
# Load Pretrained Models.
|
| 101 |
+
if self.pretrained_model:
|
| 102 |
+
if not self.args.deepspeed:
|
| 103 |
+
self.from_pretrained(self.pretrained_model)
|
| 104 |
+
# else:
|
| 105 |
+
# if not os.path.exists(self.pretrained_model + "/latest"):
|
| 106 |
+
# logger.warning(
|
| 107 |
+
# f"Pretrained deepspeed checkpoint path does not exists, {self.pretrained_model + '/latest'}")
|
| 108 |
+
self.scaler = T.cuda.amp.GradScaler()
|
| 109 |
+
self.local_rank = get_local_rank()
|
| 110 |
+
self.rank = get_rank()
|
| 111 |
+
|
| 112 |
+
self.enable_collect = True
|
| 113 |
+
if is_main_process:
|
| 114 |
+
ensure_directory(self.log_dir)
|
| 115 |
+
self.metric_filename = os.path.join(self.log_dir, 'metric.json')
|
| 116 |
+
self.last_checkpoint_filename = 'last.pth'
|
| 117 |
+
# self.best_checkpoint_filename = 'best.pth'
|
| 118 |
+
# self.each_checkpoint_filename = 'epoch%s.pth'
|
| 119 |
+
self.epoch = -1
|
| 120 |
+
self.global_step = -1
|
| 121 |
+
|
| 122 |
+
if self.args.n_gpu == 0:
|
| 123 |
+
logger.warning("No support on CPU")
|
| 124 |
+
self.device = T.device("cuda")
|
| 125 |
+
|
| 126 |
+
self.debug_dataloader = getattr(args, 'debug_dataloader', False)
|
| 127 |
+
|
| 128 |
+
def setup_wandb(self):
|
| 129 |
+
if WANDB_ENABLE and not self.args.debug:
|
| 130 |
+
setup_wandb(self.args, project=self.args.wandb_project,
|
| 131 |
+
name=self.args.project_name)
|
| 132 |
+
|
| 133 |
+
def log_dict_to_wandb(self, log_dict, step=-1):
|
| 134 |
+
if WANDB_ENABLE and not self.args.debug:
|
| 135 |
+
if step == -1:
|
| 136 |
+
step = self.global_step
|
| 137 |
+
log_dict_to_wandb(log_dict, step)
|
| 138 |
+
|
| 139 |
+
def log_img_to_wandb(self, label_imgs, cond_imgs, ref_imgs, pred_imgs, step=-1, prefix=''):
|
| 140 |
+
if WANDB_ENABLE and not self.args.debug:
|
| 141 |
+
if step == -1:
|
| 142 |
+
step = self.global_step
|
| 143 |
+
img_dict = defaultdict(list)
|
| 144 |
+
|
| 145 |
+
for i in range(len(pred_imgs)):
|
| 146 |
+
img_dict[f"{prefix}_pred_img"].append(wandb.Image(ldm_tensor2img(pred_imgs[i])))
|
| 147 |
+
if label_imgs is not None:
|
| 148 |
+
img_dict[f"{prefix}_label_img"].append(wandb.Image(ldm_tensor2img(label_imgs[i], preprocess=True)))
|
| 149 |
+
if cond_imgs is not None:
|
| 150 |
+
img_dict[f"{prefix}_cond_img"].append(wandb.Image(ldm_tensor2img(cond_imgs[i])))
|
| 151 |
+
if ref_imgs is not None:
|
| 152 |
+
img_dict[f"{prefix}_ref_img"].append(wandb.Image(ldm_tensor2img(ref_imgs[i], preprocess=True)))
|
| 153 |
+
log_img_to_wandb(img_dict, step)
|
| 154 |
+
|
| 155 |
+
def update_metric_file(self, metric):
|
| 156 |
+
if os.path.exists(self.metric_filename):
|
| 157 |
+
r = file2data(self.metric_filename, printable=False)
|
| 158 |
+
data2file(dict(r, **metric), self.metric_filename, override=True)
|
| 159 |
+
else:
|
| 160 |
+
data2file(metric, self.metric_filename)
|
| 161 |
+
|
| 162 |
+
def reduce_dict(self, data):
|
| 163 |
+
return reduce_dict(data)
|
| 164 |
+
|
| 165 |
+
def reduce_mean(self, v):
|
| 166 |
+
world_size = get_world_size()
|
| 167 |
+
if world_size < 2:
|
| 168 |
+
return v
|
| 169 |
+
else:
|
| 170 |
+
v = T.tensor(v).cuda()
|
| 171 |
+
DIST.all_reduce(v)
|
| 172 |
+
v = v.item() / world_size
|
| 173 |
+
return v
|
| 174 |
+
|
| 175 |
+
def move_model_to_cuda(self):
|
| 176 |
+
if self.debug_dataloader: # debug only, ugly workaround to run on local small gpu servers
|
| 177 |
+
return
|
| 178 |
+
self.model.to(self.device)
|
| 179 |
+
if self.optimizer is not None:
|
| 180 |
+
if isinstance(self.optimizer, list):
|
| 181 |
+
for i in range(len(self.optimizer)):
|
| 182 |
+
self.optimizer[i].load_state_dict(
|
| 183 |
+
complex_to_device(self.optimizer[i].state_dict(), device=self.device))
|
| 184 |
+
else:
|
| 185 |
+
self.optimizer.load_state_dict(
|
| 186 |
+
complex_to_device(self.optimizer.state_dict(), device=self.device))
|
| 187 |
+
|
| 188 |
+
def prepare_dist_model(self):
|
| 189 |
+
if not self.args.dist:
|
| 190 |
+
logger.info('Successfully built models with %s parameters' % get_parameters(self.model))
|
| 191 |
+
return
|
| 192 |
+
if self.args.deepspeed:
|
| 193 |
+
if isinstance(self.optimizer, list):
|
| 194 |
+
raise ValueError("A list of optimizers are not supported with deepspeed, or IDK how to make it work with deepspeed")
|
| 195 |
+
config = get_deepspeed_config(self.args)
|
| 196 |
+
|
| 197 |
+
if self.pretrained_model and not self.pretrained_model.endswith(".pth"):
|
| 198 |
+
print('Specify the load model path, not use deepspeed but the pytorch original load func')
|
| 199 |
+
self.load_checkpoint_for_deepspeed_diff_gpu(self.pretrained_model) # load pt model with default pytorch
|
| 200 |
+
|
| 201 |
+
self.model, self.optimizer, _, _ = deepspeed.initialize(
|
| 202 |
+
config_params=config,
|
| 203 |
+
model=self.model,
|
| 204 |
+
optimizer=self.optimizer,
|
| 205 |
+
lr_scheduler=self.scheduler)
|
| 206 |
+
|
| 207 |
+
if self.pretrained_model and self.pretrained_model.endswith(".pth"):
|
| 208 |
+
logger.warning(f'Loading pre-trained model from {self.pretrained_model}')
|
| 209 |
+
tag = self.pretrained_model.split("/")[-1]
|
| 210 |
+
dir_ = self.pretrained_model.replace(tag, "")
|
| 211 |
+
self.model.load_checkpoint(
|
| 212 |
+
dir_, tag=tag,
|
| 213 |
+
load_optimizer_states=False,
|
| 214 |
+
load_lr_scheduler_states=False,
|
| 215 |
+
load_module_only=True,
|
| 216 |
+
load_module_strict=False)
|
| 217 |
+
|
| 218 |
+
if self.args.resume:
|
| 219 |
+
if os.path.exists(os.path.join(self.log_dir, "latest")):
|
| 220 |
+
logger.warning(f'Resuming.... from {os.path.join(self.log_dir, "latest")}')
|
| 221 |
+
self.model.load_checkpoint(
|
| 222 |
+
self.log_dir,
|
| 223 |
+
load_optimizer_states=True,
|
| 224 |
+
load_lr_scheduler_states=True,
|
| 225 |
+
load_module_strict=True)
|
| 226 |
+
self.global_step = self.model.global_steps * self.args.gradient_accumulate_steps
|
| 227 |
+
else:
|
| 228 |
+
logger.warning(f'Resuming failed, path does not exists {os.path.join(self.log_dir, "latest")}')
|
| 229 |
+
else:
|
| 230 |
+
self.model = T.nn.parallel.DistributedDataParallel(
|
| 231 |
+
self.model,
|
| 232 |
+
device_ids=[self.local_rank],
|
| 233 |
+
output_device=self.local_rank,
|
| 234 |
+
find_unused_parameters=self.args.find_unused_parameters)
|
| 235 |
+
if not self.args.do_train:
|
| 236 |
+
self.model.eval()
|
| 237 |
+
logger.info('Successfully built models with %s parameters' % get_parameters(self.model))
|
| 238 |
+
|
| 239 |
+
def prepare_batch(self, batch):
|
| 240 |
+
batch = move_to_cuda(batch)
|
| 241 |
+
if self.args.deepspeed:
|
| 242 |
+
batch = fp32_to_fp16(batch)
|
| 243 |
+
return batch
|
| 244 |
+
|
| 245 |
+
def forward_step(self, batch):
|
| 246 |
+
if self.args.use_amp:
|
| 247 |
+
with T.autocast(device_type='cuda'):
|
| 248 |
+
out = self.model(batch)
|
| 249 |
+
else:
|
| 250 |
+
out = self.model(batch)
|
| 251 |
+
return out
|
| 252 |
+
|
| 253 |
+
def backward_step(self, loss):
|
| 254 |
+
if self.args.deepspeed:
|
| 255 |
+
self.model.backward(loss)
|
| 256 |
+
elif self.args.use_amp:
|
| 257 |
+
self.scaler.scale(loss).backward()
|
| 258 |
+
|
| 259 |
+
else:
|
| 260 |
+
loss.backward()
|
| 261 |
+
|
| 262 |
+
def grad_clip(self):
|
| 263 |
+
if self.args.deepspeed:
|
| 264 |
+
# haddled by deepspeed
|
| 265 |
+
return
|
| 266 |
+
if self.args.max_grad_norm > 0:
|
| 267 |
+
if self.args.use_amp:
|
| 268 |
+
self.scaler.unscale_(self.optimizer)
|
| 269 |
+
# Since the gradients of optimizer's assigned
|
| 270 |
+
# params are unscaled, clips as usual:
|
| 271 |
+
T.nn.utils.clip_grad_norm_(
|
| 272 |
+
self.model.parameters(), self.args.max_grad_norm)
|
| 273 |
+
|
| 274 |
+
def step(self, optimizer_idx=-1):
|
| 275 |
+
if optimizer_idx >= 0 and isinstance(self.optimizer, list):
|
| 276 |
+
optimizer = self.optimizer[optimizer_idx]
|
| 277 |
+
else:
|
| 278 |
+
optimizer = self.optimizer
|
| 279 |
+
if self.args.deepspeed:
|
| 280 |
+
# Not sure how to step one optimizer at a time
|
| 281 |
+
self.model.step()
|
| 282 |
+
elif self.args.use_amp:
|
| 283 |
+
self.scaler.step(optimizer)
|
| 284 |
+
self.scaler.update()
|
| 285 |
+
optimizer.zero_grad()
|
| 286 |
+
else:
|
| 287 |
+
optimizer.step()
|
| 288 |
+
optimizer.zero_grad()
|
| 289 |
+
|
| 290 |
+
def train(self, train_loader, eval_loader=None, use_tqdm=None,
|
| 291 |
+
inner_collect_fn=None):
|
| 292 |
+
if self.args.resume:
|
| 293 |
+
if not self.args.deepspeed:
|
| 294 |
+
if os.path.exists(os.path.join(self.log_dir, self.last_checkpoint_filename)):
|
| 295 |
+
self.load_checkpoint(self.last_checkpoint_filename)
|
| 296 |
+
else:
|
| 297 |
+
if is_main_process():
|
| 298 |
+
logger.warning('Dangerous! You set resume=False. Auto cleaning all the logs under %s' % self.log_dir)
|
| 299 |
+
ensure_dirname(self.log_dir, override=True)
|
| 300 |
+
|
| 301 |
+
self.move_model_to_cuda()
|
| 302 |
+
if self.args.dist:
|
| 303 |
+
self.prepare_dist_model()
|
| 304 |
+
|
| 305 |
+
epoch_iter = range(self.epoch + 1, self.args.epochs, 1)
|
| 306 |
+
if len(epoch_iter):
|
| 307 |
+
logger.warning('Start train & val phase...')
|
| 308 |
+
else:
|
| 309 |
+
logger.warning('Skip train & val phase...')
|
| 310 |
+
logger.warning(
|
| 311 |
+
f'Train examples: {len(train_loader.dataset)}, image size {train_loader.dataset.img_size},\n'
|
| 312 |
+
f'\t\tVal examples: {len(eval_loader.dataset)}, {len(eval_loader)}\n'
|
| 313 |
+
f'\t\tepochs: {self.args.epochs}, iters: {self.args.num_iters}, \n'
|
| 314 |
+
f'\t\titer_per_ep: {self.args.iter_per_ep}, eval_step: {self.args.eval_step}, save_step: {self.args.save_step},\n'
|
| 315 |
+
f'\t\tglobal_batch_size: {self.args.train_batch_size}, local_batch_size: {self.args.local_train_batch_size}.')
|
| 316 |
+
|
| 317 |
+
# Train & Eval phase
|
| 318 |
+
for epoch in epoch_iter:
|
| 319 |
+
self.epoch = epoch
|
| 320 |
+
# Train phase
|
| 321 |
+
train_meter, train_time = self.train_fn(train_loader,
|
| 322 |
+
use_tqdm=use_tqdm)
|
| 323 |
+
logger.info('[Rank %s] Train Epoch: %d/%d, Time: %s\n %s' %
|
| 324 |
+
(self.rank, epoch + 1, self.args.epochs, train_time, train_meter.avg))
|
| 325 |
+
if not isinstance(train_meter.avg, dict):
|
| 326 |
+
raise ValueError(type(train_meter.avg))
|
| 327 |
+
metric = {'Epoch%s' % (epoch + 1): {'train': {**train_meter.avg, **{'time': train_time}}}}
|
| 328 |
+
|
| 329 |
+
if is_main_process():
|
| 330 |
+
self.update_metric_file(metric)
|
| 331 |
+
if (epoch + 1) % self.args.save_step == 0:
|
| 332 |
+
self.save_checkpoint(self.last_checkpoint_filename)
|
| 333 |
+
|
| 334 |
+
if (epoch + 1) % self.args.eval_step == 0:
|
| 335 |
+
if eval_loader:
|
| 336 |
+
eval_meter, eval_time = self.eval_fn(eval_loader, inner_collect_fn=inner_collect_fn,
|
| 337 |
+
use_tqdm=use_tqdm)
|
| 338 |
+
logger.info('[Rank %s] Valid Epoch: %d/%d, Time: %s\n %s' %
|
| 339 |
+
(self.rank, epoch + 1, self.args.epochs, eval_time, eval_meter.avg))
|
| 340 |
+
|
| 341 |
+
# Update metric with eval metrics
|
| 342 |
+
metric['Epoch%s' % (epoch + 1)].update({'eval': {**eval_meter.avg, **{'time': eval_time}}})
|
| 343 |
+
|
| 344 |
+
# Save metric file
|
| 345 |
+
if is_main_process():
|
| 346 |
+
self.update_metric_file(metric)
|
| 347 |
+
|
| 348 |
+
def train_fn(self, train_loader, use_tqdm=True):
|
| 349 |
+
self.model.train()
|
| 350 |
+
train_meter = Meter()
|
| 351 |
+
train_timer = Timer()
|
| 352 |
+
train_iter = tqdm(train_loader, total=len(train_loader), disable=not use_tqdm)
|
| 353 |
+
for step, inputs in enumerate(train_iter):
|
| 354 |
+
for optimizer_idx in range(len(self.optimizer)):
|
| 355 |
+
if not getattr(self.optimizer[optimizer_idx], 'is_enabled', lambda x: True)(self.epoch):
|
| 356 |
+
continue
|
| 357 |
+
|
| 358 |
+
inputs['epoch'] = self.epoch
|
| 359 |
+
inputs['global_step'] = self.epoch * len(train_loader) + step
|
| 360 |
+
self.global_step = inputs['global_step']
|
| 361 |
+
inputs['optimizer_idx'] = optimizer_idx
|
| 362 |
+
|
| 363 |
+
inputs = self.prepare_batch(inputs)
|
| 364 |
+
outputs = self.forward_step(inputs)
|
| 365 |
+
self.check_outputs(outputs)
|
| 366 |
+
|
| 367 |
+
if optimizer_idx == 0:
|
| 368 |
+
self.backward_step(outputs['loss_total'])
|
| 369 |
+
else:
|
| 370 |
+
self.backward_step(outputs[f'loss_total_{optimizer_idx}'])
|
| 371 |
+
# outputs['loss_total_%s' % optimizer_idx].backward()
|
| 372 |
+
|
| 373 |
+
if (step + 1) % self.args.gradient_accumulate_steps == 0 and outputs.get('logits_last', True):
|
| 374 |
+
self.grad_clip()
|
| 375 |
+
self.step(optimizer_idx)
|
| 376 |
+
|
| 377 |
+
metric_and_loss = {k: v for k, v in outputs.items() if k.split('_')[0] in ['metric', 'loss']}
|
| 378 |
+
for k, v in metric_and_loss.items():
|
| 379 |
+
metric_and_loss[k] = self.reduce_mean(v)
|
| 380 |
+
train_meter.update(metric_and_loss)
|
| 381 |
+
|
| 382 |
+
if self.scheduler:
|
| 383 |
+
self.scheduler.step()
|
| 384 |
+
|
| 385 |
+
train_iter.set_description("Metering:" + str(train_meter))
|
| 386 |
+
train_time = train_timer.elapse(True)
|
| 387 |
+
return train_meter, train_time
|
| 388 |
+
|
| 389 |
+
def eval(self, eval_loader, inner_collect_fn=None, use_tqdm=True, enc_dec_only=False):
|
| 390 |
+
# This function is used to do evaluating after training.
|
| 391 |
+
if not self.pretrained_model:
|
| 392 |
+
logger.warning('You should create a new config file and specify pretrained_model in Args when using eval.')
|
| 393 |
+
# Wrap models before evaluating. This will support ddp evaluating.
|
| 394 |
+
self.move_model_to_cuda()
|
| 395 |
+
if self.args.dist:
|
| 396 |
+
self.prepare_dist_model()
|
| 397 |
+
eval_meter, eval_time = self.eval_fn(
|
| 398 |
+
eval_loader, inner_collect_fn=inner_collect_fn,
|
| 399 |
+
use_tqdm=use_tqdm, enc_dec_only=enc_dec_only)
|
| 400 |
+
logger.info('[Rank %s] Valid Time: %s\n %s' % (self.rank, eval_time, eval_meter.avg))
|
| 401 |
+
|
| 402 |
+
def eval_trainsample(self, train_loader, eval_loader, inner_collect_fn=None, use_tqdm=True, enc_dec_only=False):
|
| 403 |
+
# This function is used to do evaluating with training sample.
|
| 404 |
+
if not self.pretrained_model:
|
| 405 |
+
logger.warning('You should create a new config file and specify pretrained_model in Args when using eval.')
|
| 406 |
+
# Wrap models before evaluating. This will support ddp evaluating.
|
| 407 |
+
self.move_model_to_cuda()
|
| 408 |
+
if self.args.dist:
|
| 409 |
+
self.prepare_dist_model()
|
| 410 |
+
eval_meter, eval_time = self.eval_fn_trainsample(
|
| 411 |
+
train_loader, eval_loader, inner_collect_fn=inner_collect_fn,
|
| 412 |
+
use_tqdm=use_tqdm, enc_dec_only=enc_dec_only)
|
| 413 |
+
logger.info('[Rank %s] Valid Time: %s\n %s' % (self.rank, eval_time, eval_meter.avg))
|
| 414 |
+
|
| 415 |
+
def eval_demo_pre(self):
|
| 416 |
+
if not self.pretrained_model:
|
| 417 |
+
logger.warning('You should create a new config file and specify pretrained_model in Args when using eval.')
|
| 418 |
+
# Wrap models before evaluating. This will support ddp evaluating.
|
| 419 |
+
self.move_model_to_cuda()
|
| 420 |
+
if self.args.dist:
|
| 421 |
+
self.prepare_dist_model()
|
| 422 |
+
|
| 423 |
+
def eval_demo_run_masked(self, input_batch, eval_dataset, enc_dec_only=False):
|
| 424 |
+
input_batch = eval_dataset.preprocess_masked_input(*input_batch)
|
| 425 |
+
output_image = self.eval_fn_demo(
|
| 426 |
+
input_batch, enc_dec_only=enc_dec_only)
|
| 427 |
+
return output_image
|
| 428 |
+
|
| 429 |
+
def eval_fn(
|
| 430 |
+
self,
|
| 431 |
+
eval_loader,
|
| 432 |
+
inner_collect_fn=None,
|
| 433 |
+
use_tqdm=True,
|
| 434 |
+
compute_fid=True,
|
| 435 |
+
enc_dec_only=False,
|
| 436 |
+
train_eval_input=None,
|
| 437 |
+
):
|
| 438 |
+
# TODO Note that eval_fn supports ddp. So we do not need to unwrap things here.
|
| 439 |
+
self.model.eval()
|
| 440 |
+
eval_meter = Meter()
|
| 441 |
+
eval_timer = Timer()
|
| 442 |
+
eval_save_filename = self.args.eval_save_filename
|
| 443 |
+
if enc_dec_only:
|
| 444 |
+
eval_save_filename += "_enc_dec_only"
|
| 445 |
+
with T.no_grad():
|
| 446 |
+
eval_loader = (
|
| 447 |
+
tqdm(eval_loader, total=len(eval_loader)) if use_tqdm else eval_loader
|
| 448 |
+
)
|
| 449 |
+
for batch_idx, inputs in enumerate(eval_loader):
|
| 450 |
+
T.cuda.empty_cache()
|
| 451 |
+
if enc_dec_only:
|
| 452 |
+
inputs["enc_dec_only"] = True
|
| 453 |
+
inputs = self.prepare_batch(inputs)
|
| 454 |
+
outputs = self.forward_step(inputs)
|
| 455 |
+
metric_and_loss = {
|
| 456 |
+
k: v
|
| 457 |
+
for k, v in outputs.items()
|
| 458 |
+
if k.split("_")[0] in ["metric", "loss"]
|
| 459 |
+
}
|
| 460 |
+
|
| 461 |
+
for k, v in metric_and_loss.items():
|
| 462 |
+
metric_and_loss[k] = self.reduce_mean(v)
|
| 463 |
+
eval_meter.update(metric_and_loss)
|
| 464 |
+
|
| 465 |
+
if inner_collect_fn and self.enable_collect:
|
| 466 |
+
remove_key = inputs.pop("enc_dec_only", None)
|
| 467 |
+
gt_save_path, pred_save_path = inner_collect_fn(
|
| 468 |
+
self.args,
|
| 469 |
+
inputs,
|
| 470 |
+
outputs,
|
| 471 |
+
self.log_dir,
|
| 472 |
+
self.global_step,
|
| 473 |
+
eval_save_filename,
|
| 474 |
+
)
|
| 475 |
+
|
| 476 |
+
if batch_idx == 0:
|
| 477 |
+
inputs = defaultdict(lambda: None, inputs)
|
| 478 |
+
try:
|
| 479 |
+
label_imgs = inputs["label_imgs"]
|
| 480 |
+
cond_imgs = inputs["cond_imgs"]
|
| 481 |
+
ref_imgs = inputs["reference_img"]
|
| 482 |
+
pred_imgs = outputs["logits_imgs"]
|
| 483 |
+
except: # for video model
|
| 484 |
+
label_imgs = inputs["label_img_seq"][:, :, 0]
|
| 485 |
+
cond_imgs = inputs["cond_img_seq"][:, :, 0]
|
| 486 |
+
ref_imgs = inputs["reference_img"]
|
| 487 |
+
pred_imgs = outputs["logits_img_seq"][:, :, 0]
|
| 488 |
+
self.log_img_to_wandb(
|
| 489 |
+
label_imgs, cond_imgs, ref_imgs, pred_imgs, prefix="val"
|
| 490 |
+
)
|
| 491 |
+
|
| 492 |
+
if (
|
| 493 |
+
train_eval_input
|
| 494 |
+
): # run a simple-round training sample to check if it is over-fitting
|
| 495 |
+
print(
|
| 496 |
+
"run a single-round training sample inference to check if over-fitting"
|
| 497 |
+
)
|
| 498 |
+
inputs = train_eval_input
|
| 499 |
+
T.cuda.empty_cache()
|
| 500 |
+
if enc_dec_only:
|
| 501 |
+
inputs["enc_dec_only"] = True
|
| 502 |
+
inputs = self.prepare_batch(inputs)
|
| 503 |
+
outputs = self.forward_step(inputs)
|
| 504 |
+
|
| 505 |
+
### vis image for training single round sample ###
|
| 506 |
+
inputs = defaultdict(lambda: None, inputs)
|
| 507 |
+
try:
|
| 508 |
+
label_imgs = inputs["label_imgs"]
|
| 509 |
+
cond_imgs = inputs["cond_imgs"]
|
| 510 |
+
ref_imgs = inputs["reference_img"]
|
| 511 |
+
pred_imgs = outputs["logits_imgs"]
|
| 512 |
+
except: # for video model
|
| 513 |
+
label_imgs = inputs["label_img_seq"][:, :, 0]
|
| 514 |
+
cond_imgs = inputs["cond_img_seq"][:, :, 0]
|
| 515 |
+
ref_imgs = inputs["reference_img"]
|
| 516 |
+
pred_imgs = outputs["logits_img_seq"][:, :, 0]
|
| 517 |
+
self.log_img_to_wandb(
|
| 518 |
+
label_imgs, cond_imgs, ref_imgs, pred_imgs, prefix="train"
|
| 519 |
+
)
|
| 520 |
+
|
| 521 |
+
eval_meter = self.get_eval_metrics(
|
| 522 |
+
eval_meter, eval_save_filename, gt_save_path, pred_save_path
|
| 523 |
+
)
|
| 524 |
+
eval_time = eval_timer.elapse(True)
|
| 525 |
+
|
| 526 |
+
self.model.train()
|
| 527 |
+
return eval_meter, eval_time
|
| 528 |
+
|
| 529 |
+
def eval_fn_demo(self, input_batch, enc_dec_only=False):
|
| 530 |
+
self.model.eval()
|
| 531 |
+
with T.no_grad():
|
| 532 |
+
inputs = input_batch
|
| 533 |
+
T.cuda.empty_cache()
|
| 534 |
+
if enc_dec_only:
|
| 535 |
+
inputs['enc_dec_only'] = True
|
| 536 |
+
inputs = self.prepare_batch(inputs)
|
| 537 |
+
outputs = self.forward_step(inputs)
|
| 538 |
+
|
| 539 |
+
from PIL import Image
|
| 540 |
+
def tensor2pil(images, resize_img=False, img_target_size=None):
|
| 541 |
+
# c, h, w
|
| 542 |
+
images = images.cpu().permute(1, 2, 0).float().numpy()
|
| 543 |
+
if images.ndim == 3:
|
| 544 |
+
images = images[None, ...]
|
| 545 |
+
images = (images * 255).round().astype("uint8")
|
| 546 |
+
if images.shape[-1] == 1:
|
| 547 |
+
# special case for grayscale (single channel) images
|
| 548 |
+
if resize_img:
|
| 549 |
+
assert img_target_size is not None
|
| 550 |
+
img_target_size = img_target_size.squeeze()
|
| 551 |
+
pil_images = [Image.fromarray(image.squeeze(), mode="L").resize(img_target_size) for image in images]
|
| 552 |
+
else:
|
| 553 |
+
pil_images = [Image.fromarray(image.squeeze(), mode="L") for image in images]
|
| 554 |
+
else:
|
| 555 |
+
if resize_img:
|
| 556 |
+
assert img_target_size is not None
|
| 557 |
+
img_target_size = img_target_size.squeeze()
|
| 558 |
+
pil_images = [Image.fromarray(image).resize(img_target_size) for image in images]
|
| 559 |
+
else:
|
| 560 |
+
pil_images = [Image.fromarray(image) for image in images]
|
| 561 |
+
|
| 562 |
+
return pil_images
|
| 563 |
+
|
| 564 |
+
output_image = tensor2pil(outputs['logits_imgs'].squeeze(), resize_img=self.args.pos_resize_img, img_target_size=None)[0]
|
| 565 |
+
return output_image
|
| 566 |
+
|
| 567 |
+
|
| 568 |
+
def get_eval_metrics(self, eval_meter, eval_save_filename, gt_save_path=None, pred_save_path=None):
|
| 569 |
+
synchronize()
|
| 570 |
+
if self.global_step <= 0:
|
| 571 |
+
eval_log_dir = os.path.join(self.log_dir, eval_save_filename)
|
| 572 |
+
else:
|
| 573 |
+
eval_log_dir = os.path.join(self.log_dir, 'eval_step_%d' % (self.global_step))
|
| 574 |
+
|
| 575 |
+
if gt_save_path:
|
| 576 |
+
gt_folder = gt_save_path
|
| 577 |
+
else:
|
| 578 |
+
gt_folder = os.path.join(eval_log_dir, 'gt_png')
|
| 579 |
+
if not os.path.exists(gt_folder):
|
| 580 |
+
gt_folder = os.path.join(eval_log_dir, 'gt')
|
| 581 |
+
|
| 582 |
+
if pred_save_path:
|
| 583 |
+
pred_folder = pred_save_path
|
| 584 |
+
else:
|
| 585 |
+
pred_folder = os.path.join(eval_log_dir, 'pred_png')
|
| 586 |
+
if not os.path.exists(pred_folder):
|
| 587 |
+
pred_folder = os.path.join(eval_log_dir, 'pred')
|
| 588 |
+
|
| 589 |
+
if os.path.exists(gt_folder) and os.path.exists(pred_folder):
|
| 590 |
+
if is_main_process():
|
| 591 |
+
try:
|
| 592 |
+
from tool.cleanfid.fid import compute_fid
|
| 593 |
+
result = compute_fid(gt_folder, pred_folder)
|
| 594 |
+
logger.info(f"FID is {result}")
|
| 595 |
+
eval_meter.update({'FID': result})
|
| 596 |
+
except Exception as e:
|
| 597 |
+
logger.warning(f"Failed to calculate FID, {e}")
|
| 598 |
+
else:
|
| 599 |
+
logger.warning(
|
| 600 |
+
f'Failed to calculate FID, gt {gt_folder}, {os.path.exists(gt_folder)}\npred {pred_folder}, {os.path.exists(pred_folder)}')
|
| 601 |
+
|
| 602 |
+
gt_folder = os.path.join(eval_log_dir, 'gt_gif')
|
| 603 |
+
if not os.path.exists(gt_folder):
|
| 604 |
+
gt_folder = os.path.join(eval_log_dir, 'gt')
|
| 605 |
+
pred_folder = os.path.join(eval_log_dir, 'pred_gif')
|
| 606 |
+
if not os.path.exists(pred_folder):
|
| 607 |
+
pred_folder = os.path.join(eval_log_dir, 'pred')
|
| 608 |
+
|
| 609 |
+
if os.path.exists(gt_folder) and os.path.exists(pred_folder):
|
| 610 |
+
if is_main_process():
|
| 611 |
+
try:
|
| 612 |
+
from tool.metrics.metric_center import get_all_eval_scores
|
| 613 |
+
result = get_all_eval_scores(
|
| 614 |
+
self.args.root_dir, gt_folder, pred_folder,
|
| 615 |
+
sample_duration=self.args.max_video_len,
|
| 616 |
+
metrics=['fid-img', 'fid-vid', 'fvd'])
|
| 617 |
+
logger.info(f"Video gen eval {result}")
|
| 618 |
+
eval_meter.update(result)
|
| 619 |
+
except Exception as e:
|
| 620 |
+
logger.warning(f"Failed to eval video gen, {e}")
|
| 621 |
+
else:
|
| 622 |
+
logger.warning(
|
| 623 |
+
f'Failed to eval video gen, gt {gt_folder}, {os.path.exists(gt_folder)}\npred {pred_folder}, {os.path.exists(pred_folder)}')
|
| 624 |
+
|
| 625 |
+
if self.args.eval_visu and is_main_process() and len({**eval_meter.avg}):
|
| 626 |
+
json.dump({**eval_meter.avg}, open(f"{eval_log_dir}/metrics.json", "w"))
|
| 627 |
+
synchronize()
|
| 628 |
+
return eval_meter
|
| 629 |
+
|
| 630 |
+
def train_eval_by_iter(self, train_loader, eval_loader=None, use_tqdm=True, inner_collect_fn=None):
|
| 631 |
+
|
| 632 |
+
if self.args.num_iters:
|
| 633 |
+
logger.warning('Start train & val phase...')
|
| 634 |
+
self.setup_wandb()
|
| 635 |
+
else:
|
| 636 |
+
logger.warning('Skip train & val phase...')
|
| 637 |
+
return
|
| 638 |
+
logger.warning(
|
| 639 |
+
f'Train examples: {len(train_loader.dataset)}, Val examples: {len(eval_loader.dataset)}, {len(eval_loader)}\n'
|
| 640 |
+
f'\t\tepochs: {self.args.epochs}, iters: {self.args.num_iters}, \n'
|
| 641 |
+
f'\t\titer_per_ep: {self.args.iter_per_ep}, eval_step: {self.args.eval_step}, save_step: {self.args.save_step},\n'
|
| 642 |
+
f'\t\tglobal_batch_size: {self.args.train_batch_size}, local_batch_size: {self.args.local_train_batch_size}.')
|
| 643 |
+
|
| 644 |
+
# Train & Eval phase
|
| 645 |
+
train_pbar = tqdm(total=len(train_loader), disable=not use_tqdm)
|
| 646 |
+
train_meter = Meter()
|
| 647 |
+
train_timer = Timer()
|
| 648 |
+
metric = defaultdict(dict)
|
| 649 |
+
if self.global_step > 0:
|
| 650 |
+
train_pbar.update(self.global_step)
|
| 651 |
+
else:
|
| 652 |
+
self.global_step = 0
|
| 653 |
+
|
| 654 |
+
if self.args.eval_before_train and self.global_step == 0:
|
| 655 |
+
logger.warning("Saving model...")
|
| 656 |
+
self.save_checkpoint(str(self.global_step) + '.pth')
|
| 657 |
+
logger.warning("Evaluating...")
|
| 658 |
+
if eval_loader:
|
| 659 |
+
eval_meter, eval_time = self.eval_fn(eval_loader, inner_collect_fn=inner_collect_fn,
|
| 660 |
+
use_tqdm=use_tqdm)
|
| 661 |
+
logger.info('[Rank %s] Valid before train. Time: %s\n %s' %
|
| 662 |
+
(self.rank, eval_time, eval_meter.avg))
|
| 663 |
+
# Update metric with eval metrics
|
| 664 |
+
val_meter_log = {**eval_meter.avg}
|
| 665 |
+
self.log_dict_to_wandb({f'{k}_ep': v for k, v in val_meter_log.items()}, step=0)
|
| 666 |
+
val_meter_log.update({'time': eval_time})
|
| 667 |
+
metric['Epoch 0'].update({'eval': val_meter_log})
|
| 668 |
+
|
| 669 |
+
# Save metric file
|
| 670 |
+
if is_main_process():
|
| 671 |
+
self.update_metric_file(metric)
|
| 672 |
+
|
| 673 |
+
self.model.train()
|
| 674 |
+
train_iter = iter(train_loader)
|
| 675 |
+
while self.global_step < len(train_loader):
|
| 676 |
+
try:
|
| 677 |
+
inputs = next(train_iter)
|
| 678 |
+
except StopIteration:
|
| 679 |
+
logger.warning("Reaching end of the train_loader, terminating training loop")
|
| 680 |
+
break
|
| 681 |
+
self.epoch = (self.global_step + 1) // self.args.iter_per_ep
|
| 682 |
+
for optimizer_idx in range(len(self.optimizer)):
|
| 683 |
+
if not getattr(self.optimizer[optimizer_idx], 'is_enabled', lambda x: True)(self.epoch):
|
| 684 |
+
continue
|
| 685 |
+
|
| 686 |
+
inputs['epoch'] = self.epoch
|
| 687 |
+
inputs['global_step'] = self.global_step
|
| 688 |
+
inputs['optimizer_idx'] = optimizer_idx
|
| 689 |
+
|
| 690 |
+
inputs = self.prepare_batch(inputs)
|
| 691 |
+
T.cuda.empty_cache()
|
| 692 |
+
outputs = self.forward_step(inputs)
|
| 693 |
+
|
| 694 |
+
self.check_outputs(outputs)
|
| 695 |
+
T.cuda.empty_cache()
|
| 696 |
+
if optimizer_idx == 0:
|
| 697 |
+
self.backward_step(outputs['loss_total'])
|
| 698 |
+
else:
|
| 699 |
+
self.backward_step(outputs[f'loss_total_{optimizer_idx}'])
|
| 700 |
+
|
| 701 |
+
if (self.global_step + 1) % self.args.gradient_accumulate_steps == 0 and outputs.get('logits_last', True):
|
| 702 |
+
self.grad_clip()
|
| 703 |
+
self.step(optimizer_idx)
|
| 704 |
+
|
| 705 |
+
metric_and_loss = {k: v for k, v in outputs.items() if k.split('_')[0] in ['metric', 'loss']}
|
| 706 |
+
for k, v in metric_and_loss.items():
|
| 707 |
+
metric_and_loss[k] = self.reduce_mean(v)
|
| 708 |
+
train_meter.update(metric_and_loss)
|
| 709 |
+
self.log_dict_to_wandb(metric_and_loss)
|
| 710 |
+
|
| 711 |
+
if self.scheduler:
|
| 712 |
+
self.scheduler.step()
|
| 713 |
+
|
| 714 |
+
# if (self.global_step + 1) % (self.args.save_step*self.args.iter_per_ep) == 0:
|
| 715 |
+
# self.save_checkpoint(str(self.global_step) + '.pth')
|
| 716 |
+
train_pbar.set_description("Metering:" + str(train_meter))
|
| 717 |
+
train_time = train_timer.elapse(True)
|
| 718 |
+
|
| 719 |
+
if (self.global_step + 1) % self.args.iter_per_ep == 0:
|
| 720 |
+
logger.info('[Rank %s] Train Epoch: %d/%d, Time: %s\n %s' %
|
| 721 |
+
(self.rank, self.epoch + 1, self.args.epochs, train_time, train_meter.avg))
|
| 722 |
+
if not isinstance(train_meter.avg, dict):
|
| 723 |
+
raise ValueError(type(train_meter.avg))
|
| 724 |
+
tr_meter_log = {**train_meter.avg,}
|
| 725 |
+
self.log_dict_to_wandb({f'{k}_ep': v for k, v in tr_meter_log.items()})
|
| 726 |
+
tr_meter_log.update({'time': train_time})
|
| 727 |
+
metric['Epoch%s' % (self.epoch + 1)].update( {'train': tr_meter_log})
|
| 728 |
+
|
| 729 |
+
if is_main_process():
|
| 730 |
+
self.update_metric_file(metric)
|
| 731 |
+
if (self.epoch + 1) % self.args.save_step == 0:
|
| 732 |
+
logger.warning("Saving model...")
|
| 733 |
+
self.save_checkpoint(str(self.global_step) + '.pth')
|
| 734 |
+
self.save_checkpoint(self.last_checkpoint_filename)
|
| 735 |
+
# copy_file(self.last_checkpoint_filename, self.each_checkpoint_filename % str(epoch + 1),
|
| 736 |
+
# override=True) # TODO sometimes we need to copy file
|
| 737 |
+
|
| 738 |
+
if (self.epoch + 1) % self.args.eval_step == 0:
|
| 739 |
+
logger.warning("Evaluating...")
|
| 740 |
+
if eval_loader:
|
| 741 |
+
eval_meter, eval_time = self.eval_fn(eval_loader, inner_collect_fn=inner_collect_fn,
|
| 742 |
+
use_tqdm=use_tqdm)
|
| 743 |
+
logger.info('[Rank %s] Valid Epoch: %d/%d, Time: %s\n %s' %
|
| 744 |
+
(self.rank, self.epoch + 1, self.args.epochs, eval_time, eval_meter.avg))
|
| 745 |
+
# Update metric with eval metrics
|
| 746 |
+
val_meter_log = {**eval_meter.avg}
|
| 747 |
+
self.log_dict_to_wandb({f'{k}_ep': v for k, v in val_meter_log.items()})
|
| 748 |
+
val_meter_log.update({'time': eval_time})
|
| 749 |
+
metric['Epoch%s' % (self.epoch + 1)].update({'eval': val_meter_log})
|
| 750 |
+
|
| 751 |
+
# Save metric file
|
| 752 |
+
if is_main_process():
|
| 753 |
+
self.update_metric_file(metric)
|
| 754 |
+
train_meter = Meter()
|
| 755 |
+
train_timer = Timer()
|
| 756 |
+
self.global_step += 1
|
| 757 |
+
train_pbar.update(1)
|
| 758 |
+
if (self.epoch + 1) % self.args.save_step != 0:
|
| 759 |
+
logger.warning("Saving model...")
|
| 760 |
+
self.save_checkpoint(str(self.global_step) + '.pth')
|
| 761 |
+
self.save_checkpoint(self.last_checkpoint_filename)
|
| 762 |
+
|
| 763 |
+
if (self.epoch + 1) % self.args.eval_step != 0:
|
| 764 |
+
logger.warning("Evaluating...")
|
| 765 |
+
if eval_loader:
|
| 766 |
+
eval_meter, eval_time = self.eval_fn(
|
| 767 |
+
eval_loader, inner_collect_fn=inner_collect_fn,
|
| 768 |
+
use_tqdm=use_tqdm)
|
| 769 |
+
logger.info('[Rank %s] Valid Epoch: %d/%d, Time: %s\n %s' %
|
| 770 |
+
(self.rank, self.epoch + 1, self.args.epochs, eval_time, eval_meter.avg))
|
| 771 |
+
# Update metric with eval metrics
|
| 772 |
+
val_meter_log = {**eval_meter.avg}
|
| 773 |
+
self.log_dict_to_wandb({f'{k}_ep': v for k, v in val_meter_log.items()})
|
| 774 |
+
val_meter_log.update({'time': eval_time})
|
| 775 |
+
metric['Epoch%s' % (self.epoch + 1)].update({'eval': val_meter_log})
|
| 776 |
+
|
| 777 |
+
# Save metric file
|
| 778 |
+
if is_main_process():
|
| 779 |
+
self.update_metric_file(metric)
|
| 780 |
+
|
| 781 |
+
def check_outputs(self, outputs):
|
| 782 |
+
error_message = 'Model output must be a dict. The key must be "class_subclass" format.' \
|
| 783 |
+
' "class" can only be loss, metric, or logits. "subclass" should be a string.' \
|
| 784 |
+
' But got an unexpected key %s'
|
| 785 |
+
loss_total_list = [e for e in outputs.keys() if e.startswith('loss_total')]
|
| 786 |
+
if not loss_total_list:
|
| 787 |
+
raise ValueError('Model output must contain a key startswith "loss_total"!')
|
| 788 |
+
|
| 789 |
+
for k, v in outputs.items():
|
| 790 |
+
split_res = k.split('_')
|
| 791 |
+
if len(split_res) < 2:
|
| 792 |
+
raise ValueError(error_message % k)
|
| 793 |
+
if k.split('_')[0] not in ['loss', 'metric', 'logits']:
|
| 794 |
+
raise ValueError(error_message % k)
|
| 795 |
+
|
| 796 |
+
def from_pretrained(self, pretrained_model):
|
| 797 |
+
if hasattr(self.model, "module"):
|
| 798 |
+
raise ValueError("Please do not load pretrained models into wrapped models, ensure self.models is CPU.")
|
| 799 |
+
if isinstance(pretrained_model, str):
|
| 800 |
+
logger.warning('Loading Pretrained Model Path: %s...' % pretrained_model)
|
| 801 |
+
pretrained_dict = file2data(pretrained_model, map_location='cpu')
|
| 802 |
+
if 'models' in pretrained_dict:
|
| 803 |
+
pretrained_dict = pretrained_dict['models']
|
| 804 |
+
elif 'model' in pretrained_dict:
|
| 805 |
+
pretrained_dict = pretrained_dict['model']
|
| 806 |
+
else:
|
| 807 |
+
logger.warning('Loading Given Pretrained Dict...')
|
| 808 |
+
pretrained_dict = pretrained_model
|
| 809 |
+
adaptively_load_state_dict(self.model, pretrained_dict)
|
| 810 |
+
|
| 811 |
+
def load_checkpoint(self, checkpoint_filename):
|
| 812 |
+
if not self.args.deepspeed:
|
| 813 |
+
if hasattr(self.model, "module"):
|
| 814 |
+
raise ValueError("Please do not load checkpoint into wrapped models, ensure self.models is CPU.")
|
| 815 |
+
checkpoint = file2data(checkpoint_filename, map_location='cpu')
|
| 816 |
+
adaptively_load_state_dict(self.model, checkpoint['models'])
|
| 817 |
+
if isinstance(self.optimizer, list):
|
| 818 |
+
if len(self.optimizer) > 1:
|
| 819 |
+
for i, optimizer in enumerate(self.optimizer):
|
| 820 |
+
adaptively_load_state_dict(self.optimizer[i], checkpoint['optimizer'][i])
|
| 821 |
+
|
| 822 |
+
elif len(self.optimizer) == 1:
|
| 823 |
+
adaptively_load_state_dict(self.optimizer[0], checkpoint['optimizer'])
|
| 824 |
+
else:
|
| 825 |
+
adaptively_load_state_dict(self.optimizer, checkpoint['optimizer'])
|
| 826 |
+
if self.scheduler:
|
| 827 |
+
adaptively_load_state_dict(self.scheduler, checkpoint['scheduler'])
|
| 828 |
+
|
| 829 |
+
self.epoch = checkpoint['epoch'] - 1
|
| 830 |
+
self.global_step = checkpoint['global_step'] - 1
|
| 831 |
+
|
| 832 |
+
# IMPORTANT! The models will be wrapped automatically.
|
| 833 |
+
logger.warning('Loaded checkpoint %s of epoch %s (global_step %s)' % (
|
| 834 |
+
checkpoint_filename, checkpoint['epoch'],
|
| 835 |
+
checkpoint['global_step']))
|
| 836 |
+
else:
|
| 837 |
+
self.model.load_checkpoint(self.log_dir, checkpoint_filename)
|
| 838 |
+
logger.warning('Loaded checkpoint %s' % (checkpoint_filename))
|
| 839 |
+
|
| 840 |
+
def load_checkpoint_for_deepspeed_diff_gpu(self, checkpoint_filename):
|
| 841 |
+
if hasattr(self.model, "module"):
|
| 842 |
+
raise ValueError("Please do not load checkpoint into wrapped models, ensure self.models is CPU.")
|
| 843 |
+
checkpoint = file2data(checkpoint_filename, map_location='cpu')
|
| 844 |
+
adaptively_load_state_dict(self.model, checkpoint['module'])
|
| 845 |
+
|
| 846 |
+
# IMPORTANT! The models will be wrapped automatically.
|
| 847 |
+
logger.warning('Loaded checkpoint %s of global_step %s' % (
|
| 848 |
+
checkpoint_filename,
|
| 849 |
+
checkpoint['global_steps']))
|
| 850 |
+
|
| 851 |
+
|
| 852 |
+
def save_checkpoint(self, checkpoint_filename):
|
| 853 |
+
if not self.args.deepspeed:
|
| 854 |
+
if not is_main_process():
|
| 855 |
+
return
|
| 856 |
+
checkpoint_filename = os.path.join(self.log_dir, checkpoint_filename)
|
| 857 |
+
model_to_save = self.model.module if hasattr(self.model, 'module') else self.model
|
| 858 |
+
if isinstance(self.optimizer, list):
|
| 859 |
+
if len(self.optimizer) > 1:
|
| 860 |
+
optimizer_to_save = [optimizer.state_dict() for optimizer in self.optimizer]
|
| 861 |
+
elif len(self.optimizer) == 1:
|
| 862 |
+
optimizer_to_save = self.optimizer[0].state_dict()
|
| 863 |
+
else:
|
| 864 |
+
optimizer_to_save = self.optimizer.state_dict()
|
| 865 |
+
checkpoint = {
|
| 866 |
+
'models': model_to_save.state_dict(),
|
| 867 |
+
'optimizer': optimizer_to_save,
|
| 868 |
+
'epoch': self.epoch + 1,
|
| 869 |
+
'global_step': self.global_step + 1
|
| 870 |
+
}
|
| 871 |
+
if self.scheduler:
|
| 872 |
+
checkpoint['scheduler'] = self.scheduler.state_dict()
|
| 873 |
+
data2file(checkpoint, checkpoint_filename, override=True)
|
| 874 |
+
logger.warning('Saved epoch %s (global_step %s) to %s.' % (
|
| 875 |
+
checkpoint['epoch'], checkpoint['global_step'],
|
| 876 |
+
checkpoint_filename))
|
| 877 |
+
return
|
| 878 |
+
else:
|
| 879 |
+
if self.args.debug and checkpoint_filename != self.last_checkpoint_filename:
|
| 880 |
+
logger.warning(
|
| 881 |
+
f"skip saving models with deepspeed to "
|
| 882 |
+
f"{self.log_dir}/{checkpoint_filename} in debug mode")
|
| 883 |
+
return
|
| 884 |
+
self.model.save_checkpoint(self.log_dir, tag=checkpoint_filename)
|
| 885 |
+
return
|
| 886 |
+
|
| 887 |
+
def log_memory(self, ep=-1, step=-1):
|
| 888 |
+
if ep == -1 and step == -1:
|
| 889 |
+
step = self.global_step
|
| 890 |
+
step_str = f"global step: {step},"
|
| 891 |
+
else:
|
| 892 |
+
step_str = f"ep: {ep}, step: {step},"
|
| 893 |
+
|
| 894 |
+
memory = humanbytes(T.cuda.max_memory_allocated())
|
| 895 |
+
lr_base = f'{self.optimizer.param_groups[0]["lr"]:.2e}'
|
| 896 |
+
lr_head = f'{self.optimizer.param_groups[2]["lr"]:.2e}'
|
| 897 |
+
lr_xmodal = f'{self.optimizer.param_groups[4]["lr"]:.2e}'
|
| 898 |
+
self.log_dict_to_wandb({'lr_base': float(lr_base)}, step)
|
| 899 |
+
self.log_dict_to_wandb({'lr_head': float(lr_head)}, step)
|
| 900 |
+
self.log_dict_to_wandb({'lr_xmodal': float(lr_xmodal)}, step)
|
| 901 |
+
return f"{step_str} lr_base: {lr_base}, " +\
|
| 902 |
+
f"lr_head: {lr_head}, lr_xmodal: {lr_xmodal}, max memory: {memory}"
|
| 903 |
+
|
| 904 |
+
def build_optimizer(self):
|
| 905 |
+
param_optimizer = list(self.model.named_parameters())
|
| 906 |
+
no_decay = [
|
| 907 |
+
"bias",
|
| 908 |
+
"LayerNorm.bias",
|
| 909 |
+
"LayerNorm.weight",
|
| 910 |
+
"norm.bias",
|
| 911 |
+
"norm.weight",
|
| 912 |
+
"norm1.bias",
|
| 913 |
+
"norm1.weight",
|
| 914 |
+
"norm2.bias",
|
| 915 |
+
"norm2.weight",
|
| 916 |
+
]
|
| 917 |
+
head_names = ["fc_mtm", "fc"]
|
| 918 |
+
cross_modal_names = ["cross_modal", "i2t", "t2i"]
|
| 919 |
+
lr_mult_head = self.args.lr_mult_head
|
| 920 |
+
lr_mult_cross_modal = self.args.lr_mult_cross_modal
|
| 921 |
+
|
| 922 |
+
wd = self.args.decay
|
| 923 |
+
lr = self.args.lr
|
| 924 |
+
|
| 925 |
+
|
| 926 |
+
optimizer_grouped_parameters = [
|
| 927 |
+
{
|
| 928 |
+
"params": [
|
| 929 |
+
p
|
| 930 |
+
for n, p in param_optimizer
|
| 931 |
+
if not any(nd in n for nd in no_decay)
|
| 932 |
+
and not any(bb in n for bb in head_names)
|
| 933 |
+
and not any(ht in n for ht in cross_modal_names)
|
| 934 |
+
],
|
| 935 |
+
"weight_decay": wd,
|
| 936 |
+
"lr": lr,
|
| 937 |
+
},
|
| 938 |
+
{
|
| 939 |
+
"params": [
|
| 940 |
+
p
|
| 941 |
+
for n, p in param_optimizer
|
| 942 |
+
if any(nd in n for nd in no_decay)
|
| 943 |
+
and not any(bb in n for bb in head_names)
|
| 944 |
+
and not any(ht in n for ht in cross_modal_names)
|
| 945 |
+
],
|
| 946 |
+
"weight_decay": 0.0,
|
| 947 |
+
"lr": lr,
|
| 948 |
+
},
|
| 949 |
+
{
|
| 950 |
+
"params": [
|
| 951 |
+
p
|
| 952 |
+
for n, p in param_optimizer
|
| 953 |
+
if not any(nd in n for nd in no_decay)
|
| 954 |
+
and any(bb in n for bb in head_names)
|
| 955 |
+
and not any(ht in n for ht in cross_modal_names)
|
| 956 |
+
],
|
| 957 |
+
"weight_decay": wd,
|
| 958 |
+
"lr": lr * lr_mult_head,
|
| 959 |
+
},
|
| 960 |
+
{
|
| 961 |
+
"params": [
|
| 962 |
+
p
|
| 963 |
+
for n, p in param_optimizer
|
| 964 |
+
if any(nd in n for nd in no_decay)
|
| 965 |
+
and any(bb in n for bb in head_names)
|
| 966 |
+
and not any(ht in n for ht in cross_modal_names)
|
| 967 |
+
],
|
| 968 |
+
"weight_decay": 0.0,
|
| 969 |
+
"lr": lr * lr_mult_head,
|
| 970 |
+
},
|
| 971 |
+
{
|
| 972 |
+
"params": [
|
| 973 |
+
p
|
| 974 |
+
for n, p in param_optimizer
|
| 975 |
+
if not any(nd in n for nd in no_decay)
|
| 976 |
+
and not any(bb in n for bb in head_names)
|
| 977 |
+
and any(ht in n for ht in cross_modal_names)
|
| 978 |
+
],
|
| 979 |
+
"weight_decay": wd,
|
| 980 |
+
"lr": lr * lr_mult_cross_modal,
|
| 981 |
+
},
|
| 982 |
+
{
|
| 983 |
+
"params": [
|
| 984 |
+
p
|
| 985 |
+
for n, p in param_optimizer
|
| 986 |
+
if any(nd in n for nd in no_decay)
|
| 987 |
+
and not any(bb in n for bb in head_names)
|
| 988 |
+
and any(ht in n for ht in cross_modal_names)
|
| 989 |
+
],
|
| 990 |
+
"weight_decay": 0.0,
|
| 991 |
+
"lr": lr * lr_mult_cross_modal,
|
| 992 |
+
},
|
| 993 |
+
]
|
| 994 |
+
optzr = T.optim.AdamW(
|
| 995 |
+
optimizer_grouped_parameters, lr=lr,
|
| 996 |
+
betas=(0.9, 0.98))
|
| 997 |
+
return optzr
|
| 998 |
+
|
| 999 |
+
def setup_model_for_training(self):
|
| 1000 |
+
if self.args.resume:
|
| 1001 |
+
if not self.args.deepspeed:
|
| 1002 |
+
if os.path.exists(os.path.join(self.log_dir, self.last_checkpoint_filename)):
|
| 1003 |
+
logger.warning(f'Resuming.... from {self.last_checkpoint_filename}')
|
| 1004 |
+
self.load_checkpoint(self.last_checkpoint_filename)
|
| 1005 |
+
else:
|
| 1006 |
+
if isinstance(self.optimizer, list):
|
| 1007 |
+
raise ValueError("self.optimizer is a list, which is incompatible with deepspeed")
|
| 1008 |
+
else:
|
| 1009 |
+
if is_main_process():
|
| 1010 |
+
logger.warning('Dangerous! You set resume=False. Auto cleaning all the logs under %s' % self.log_dir)
|
| 1011 |
+
ensure_dirname(self.log_dir, override=True)
|
| 1012 |
+
if hasattr(self.model, "init_ddpm"):
|
| 1013 |
+
# for LDM only
|
| 1014 |
+
logger.warning('Init ddpm and freeze cond_model/first_stage_vqe_model.')
|
| 1015 |
+
self.model.init_ddpm()
|
| 1016 |
+
self.move_model_to_cuda()
|
| 1017 |
+
self.prepare_dist_model()
|
| 1018 |
+
|
| 1019 |
+
|
| 1020 |
+
|
| 1021 |
+
class Agent_LDM(Agent):
|
| 1022 |
+
def __init__(self, args, model, optimizer=None, scheduler=None):
|
| 1023 |
+
super().__init__(args, model, optimizer, scheduler)
|
| 1024 |
+
### add to use stage 1 pretrain attr model to initialize the weight
|
| 1025 |
+
if self.args.stage1_pretrain_path is not None:
|
| 1026 |
+
print('### Using stage 1 attribute pretrain model to initialize the weights ###')
|
| 1027 |
+
pretrain_model_state = file2data(self.args.stage1_pretrain_path, map_location='cpu')
|
| 1028 |
+
# pre-process to the weight name
|
| 1029 |
+
new_state = {}
|
| 1030 |
+
for k, v in pretrain_model_state['module'].items():
|
| 1031 |
+
if k.startswith('controlnet.'):
|
| 1032 |
+
new_key = k[:11] + 'nets.1.' + k[11:]
|
| 1033 |
+
new_state[new_key] = v
|
| 1034 |
+
else:
|
| 1035 |
+
new_state[k] = v
|
| 1036 |
+
### load
|
| 1037 |
+
adaptively_load_state_dict(model, new_state)
|
| 1038 |
+
|
| 1039 |
+
|
| 1040 |
+
def train(self, train_loader, eval_loader=None, use_tqdm=True,
|
| 1041 |
+
inner_collect_fn=None):
|
| 1042 |
+
if self.args.resume:
|
| 1043 |
+
if not self.args.deepspeed:
|
| 1044 |
+
if os.path.exists(os.path.join(self.log_dir, self.last_checkpoint_filename)):
|
| 1045 |
+
logger.warning(f'Resuming.... from {self.last_checkpoint_filename}')
|
| 1046 |
+
self.load_checkpoint(self.last_checkpoint_filename)
|
| 1047 |
+
else:
|
| 1048 |
+
if is_main_process():
|
| 1049 |
+
logger.warning('Dangerous! You set resume=False. Auto cleaning all the logs under %s' % self.log_dir)
|
| 1050 |
+
ensure_dirname(self.log_dir, override=True)
|
| 1051 |
+
|
| 1052 |
+
self.model.init_ddpm()
|
| 1053 |
+
self.move_model_to_cuda()
|
| 1054 |
+
if self.args.dist:
|
| 1055 |
+
self.prepare_dist_model()
|
| 1056 |
+
|
| 1057 |
+
epoch_iter = range(self.epoch + 1, self.args.epochs, 1)
|
| 1058 |
+
if len(epoch_iter):
|
| 1059 |
+
logger.warning('Start train & val phase...')
|
| 1060 |
+
else:
|
| 1061 |
+
logger.warning('Skip train & val phase...')
|
| 1062 |
+
logger.warning(
|
| 1063 |
+
f'Train examples: {len(train_loader.dataset)}, image size {train_loader.dataset.img_size},\n'
|
| 1064 |
+
f'\t\tVal examples: {len(eval_loader.dataset)}, {len(eval_loader)}\n'
|
| 1065 |
+
f'\t\tepochs: {self.args.epochs}, iters: {self.args.num_iters}, \n'
|
| 1066 |
+
f'\t\titer_per_ep: {self.args.iter_per_ep}, eval_step: {self.args.eval_step}, save_step: {self.args.save_step},\n'
|
| 1067 |
+
f'\t\tglobal_batch_size: {self.args.train_batch_size}, local_batch_size: {self.args.local_train_batch_size}.')
|
| 1068 |
+
|
| 1069 |
+
# Train & Eval phase
|
| 1070 |
+
for epoch in epoch_iter:
|
| 1071 |
+
self.epoch = epoch
|
| 1072 |
+
# Train phase
|
| 1073 |
+
train_meter, train_time = self.train_fn(train_loader,
|
| 1074 |
+
use_tqdm=use_tqdm)
|
| 1075 |
+
logger.info('[Rank %s] Train Epoch: %d/%d, Time: %s\n %s' %
|
| 1076 |
+
(self.rank, epoch + 1, self.args.epochs, train_time, train_meter.avg))
|
| 1077 |
+
if not isinstance(train_meter.avg, dict):
|
| 1078 |
+
raise ValueError(type(train_meter.avg))
|
| 1079 |
+
metric = {'Epoch%s' % (epoch + 1): {'train': {**train_meter.avg, **{'time': train_time}}}}
|
| 1080 |
+
|
| 1081 |
+
if is_main_process():
|
| 1082 |
+
self.update_metric_file(metric)
|
| 1083 |
+
if (epoch + 1) % self.args.save_step == 0:
|
| 1084 |
+
self.save_checkpoint(self.last_checkpoint_filename)
|
| 1085 |
+
|
| 1086 |
+
if (epoch + 1) % self.args.eval_step == 0:
|
| 1087 |
+
if eval_loader:
|
| 1088 |
+
eval_meter, eval_time = self.eval_fn(eval_loader, inner_collect_fn=inner_collect_fn,
|
| 1089 |
+
use_tqdm=use_tqdm)
|
| 1090 |
+
logger.info('[Rank %s] Valid Epoch: %d/%d, Time: %s\n %s' %
|
| 1091 |
+
(self.rank, epoch + 1, self.args.epochs, eval_time, eval_meter.avg))
|
| 1092 |
+
# Update metric with eval metrics
|
| 1093 |
+
metric['Epoch%s' % (self.epoch + 1)].update({'eval': {**eval_meter.avg, **{'time': eval_time}}})
|
| 1094 |
+
|
| 1095 |
+
# Save metric file
|
| 1096 |
+
if is_main_process():
|
| 1097 |
+
self.update_metric_file(metric)
|
| 1098 |
+
|
| 1099 |
+
def train_fn(self, train_loader, use_tqdm=True):
|
| 1100 |
+
self.model.train()
|
| 1101 |
+
train_meter = Meter()
|
| 1102 |
+
train_timer = Timer()
|
| 1103 |
+
train_iter = tqdm(train_loader, total=len(train_loader), disable=not use_tqdm)
|
| 1104 |
+
for step, inputs in enumerate(train_iter):
|
| 1105 |
+
if not getattr(self.optimizer, 'is_enabled', lambda x: True)(self.epoch * len(train_loader) + step):
|
| 1106 |
+
continue # adjust to sdm KL-VAE
|
| 1107 |
+
inputs = complex_to_device(inputs, self.device)
|
| 1108 |
+
|
| 1109 |
+
inputs['epoch'] = self.epoch
|
| 1110 |
+
inputs['global_step'] = self.epoch * len(train_loader) + step
|
| 1111 |
+
self.global_step = inputs['global_step']
|
| 1112 |
+
|
| 1113 |
+
inputs = self.prepare_batch(inputs)
|
| 1114 |
+
outputs = self.forward_step(inputs)
|
| 1115 |
+
|
| 1116 |
+
self.check_outputs(outputs)
|
| 1117 |
+
self.backward_step(outputs['loss_total'])
|
| 1118 |
+
|
| 1119 |
+
if not self.args.deepspeed:
|
| 1120 |
+
if (step + 1) % self.args.gradient_accumulate_steps == 0 and outputs.get('logits_last', True):
|
| 1121 |
+
self.grad_clip()
|
| 1122 |
+
self.step()
|
| 1123 |
+
if self.scheduler:
|
| 1124 |
+
self.scheduler.step()
|
| 1125 |
+
else:
|
| 1126 |
+
self.grad_clip()
|
| 1127 |
+
self.step()
|
| 1128 |
+
|
| 1129 |
+
metric_and_loss = {k: v for k, v in outputs.items() if k.split('_')[0] in ['metric', 'loss']}
|
| 1130 |
+
|
| 1131 |
+
for k, v in metric_and_loss.items():
|
| 1132 |
+
metric_and_loss[k] = self.reduce_mean(v)
|
| 1133 |
+
train_meter.update(metric_and_loss)
|
| 1134 |
+
|
| 1135 |
+
if (self.global_step + 1) % (int(getattr(self.args, 'save_setp', 8000)) + 1) == 0:
|
| 1136 |
+
self.save_checkpoint(str(self.global_step) + '.pth')
|
| 1137 |
+
train_iter.set_description("Metering:" + str(train_meter))
|
| 1138 |
+
train_time = train_timer.elapse(True)
|
| 1139 |
+
return train_meter, train_time
|
| 1140 |
+
|
| 1141 |
+
def train_eval_by_iter(self, train_loader, eval_loader=None, use_tqdm=True, inner_collect_fn=None):
|
| 1142 |
+
if self.args.num_iters:
|
| 1143 |
+
logger.warning('Start train & val phase...')
|
| 1144 |
+
self.setup_wandb()
|
| 1145 |
+
else:
|
| 1146 |
+
logger.warning('Skip train & val phase...')
|
| 1147 |
+
return
|
| 1148 |
+
logger.warning(
|
| 1149 |
+
f'Train examples: {len(train_loader.dataset)}, image size {train_loader.dataset.img_size},\n'
|
| 1150 |
+
f'\t\tVal examples: {len(eval_loader.dataset)}, {len(eval_loader)}\n'
|
| 1151 |
+
f'\t\tepochs: {self.args.epochs}, iters: {self.args.num_iters}, \n'
|
| 1152 |
+
f'\t\titer_per_ep: {self.args.iter_per_ep}, eval_step: {self.args.eval_step}, save_step: {self.args.save_step},\n'
|
| 1153 |
+
f'\t\tglobal_batch_size: {self.args.train_batch_size}, local_batch_size: {self.args.local_train_batch_size}.')
|
| 1154 |
+
|
| 1155 |
+
# Train & Eval phase
|
| 1156 |
+
train_pbar = tqdm(total=len(train_loader), disable=not use_tqdm)
|
| 1157 |
+
train_meter = Meter()
|
| 1158 |
+
train_timer = Timer()
|
| 1159 |
+
metric = defaultdict(dict)
|
| 1160 |
+
if self.global_step > 0:
|
| 1161 |
+
train_pbar.update(self.global_step)
|
| 1162 |
+
else:
|
| 1163 |
+
self.global_step = 0
|
| 1164 |
+
|
| 1165 |
+
if self.args.eval_before_train and self.global_step == 0:
|
| 1166 |
+
# logger.warning("Saving model...")
|
| 1167 |
+
# self.save_checkpoint(str(self.global_step) + '.pth')
|
| 1168 |
+
if eval_loader:
|
| 1169 |
+
if self.args.eval_enc_dec_only:
|
| 1170 |
+
logger.warning("Evaluating enc_dec_only...")
|
| 1171 |
+
eval_meter, eval_time = self.eval_fn(eval_loader, inner_collect_fn=inner_collect_fn,
|
| 1172 |
+
use_tqdm=use_tqdm, enc_dec_only=True)
|
| 1173 |
+
logger.info('[Rank %s] Valid enc_dec_only before train. Time: %s\n %s' %
|
| 1174 |
+
(self.rank, eval_time, eval_meter.avg))
|
| 1175 |
+
# Update metric with eval metrics
|
| 1176 |
+
val_meter_log = {**eval_meter.avg}
|
| 1177 |
+
self.log_dict_to_wandb({f'{k}_enc_dec_only': v for k, v in val_meter_log.items()}, step=0)
|
| 1178 |
+
val_meter_log.update({'time': eval_time})
|
| 1179 |
+
metric['Step 0_enc_dec_only'].update({'eval': val_meter_log})
|
| 1180 |
+
logger.warning("Evaluating ZS...")
|
| 1181 |
+
|
| 1182 |
+
eval_meter, eval_time = self.eval_fn(eval_loader, inner_collect_fn=inner_collect_fn,
|
| 1183 |
+
use_tqdm=use_tqdm)
|
| 1184 |
+
logger.info('[Rank %s] Valid before train. Time: %s\n %s' %
|
| 1185 |
+
(self.rank, eval_time, eval_meter.avg))
|
| 1186 |
+
# Update metric with eval metrics
|
| 1187 |
+
val_meter_log = {**eval_meter.avg}
|
| 1188 |
+
self.log_dict_to_wandb({f'{k}_step': v for k, v in val_meter_log.items()}, step=0)
|
| 1189 |
+
val_meter_log.update({'time': eval_time})
|
| 1190 |
+
metric['Step 0'].update({'eval': val_meter_log})
|
| 1191 |
+
|
| 1192 |
+
# Save metric file
|
| 1193 |
+
if is_main_process():
|
| 1194 |
+
self.update_metric_file(metric)
|
| 1195 |
+
# update tqdm to have previous info, load train_loader
|
| 1196 |
+
self.model.train()
|
| 1197 |
+
train_iter = iter(train_loader)
|
| 1198 |
+
while self.global_step < len(train_loader):
|
| 1199 |
+
try:
|
| 1200 |
+
inputs = next(train_iter)
|
| 1201 |
+
except StopIteration:
|
| 1202 |
+
logger.warning("Reaching end of the train_loader, terminating training loop")
|
| 1203 |
+
break
|
| 1204 |
+
|
| 1205 |
+
self.epoch = (self.global_step + 1) // self.args.iter_per_ep
|
| 1206 |
+
if not getattr(self.optimizer, 'is_enabled', lambda x: True)(self.global_step):
|
| 1207 |
+
continue # adjust to sdm KL-VAE
|
| 1208 |
+
|
| 1209 |
+
inputs['epoch'] = self.epoch
|
| 1210 |
+
inputs['global_step'] = self.global_step
|
| 1211 |
+
|
| 1212 |
+
inputs = self.prepare_batch(inputs)
|
| 1213 |
+
T.cuda.empty_cache()
|
| 1214 |
+
outputs = self.forward_step(inputs)
|
| 1215 |
+
|
| 1216 |
+
self.check_outputs(outputs)
|
| 1217 |
+
T.cuda.empty_cache()
|
| 1218 |
+
self.backward_step(outputs['loss_total'])
|
| 1219 |
+
|
| 1220 |
+
if not self.args.deepspeed:
|
| 1221 |
+
if (self.global_step + 1) % self.args.gradient_accumulate_steps == 0 and outputs.get('logits_last', True):
|
| 1222 |
+
self.grad_clip()
|
| 1223 |
+
self.step()
|
| 1224 |
+
if self.scheduler:
|
| 1225 |
+
self.scheduler.step()
|
| 1226 |
+
else:
|
| 1227 |
+
# gradient_accumulation handled by deepspeed
|
| 1228 |
+
self.grad_clip()
|
| 1229 |
+
self.step()
|
| 1230 |
+
|
| 1231 |
+
metric_and_loss = {k: v for k, v in outputs.items() if k.split('_')[0] in ['metric', 'loss']}
|
| 1232 |
+
for k, v in metric_and_loss.items():
|
| 1233 |
+
metric_and_loss[k] = self.reduce_mean(v)
|
| 1234 |
+
train_meter.update(metric_and_loss)
|
| 1235 |
+
|
| 1236 |
+
# if (self.global_step + 1) % (self.args.save_step*self.args.iter_per_ep) == 0:
|
| 1237 |
+
# self.save_checkpoint(str(self.global_step) + '.pth')
|
| 1238 |
+
train_pbar.set_description("Metering:" + str(train_meter))
|
| 1239 |
+
train_time = train_timer.elapse(True)
|
| 1240 |
+
|
| 1241 |
+
if (self.global_step + 1) % self.args.iter_per_ep == 0:
|
| 1242 |
+
logger.info('[Rank %s] Train Epoch: %d/%d, Time: %s\n %s' %
|
| 1243 |
+
(self.rank, self.epoch + 1, self.args.epochs, train_time, train_meter.avg))
|
| 1244 |
+
if not isinstance(train_meter.avg, dict):
|
| 1245 |
+
raise ValueError(type(train_meter.avg))
|
| 1246 |
+
tr_meter_log = {**train_meter.avg }
|
| 1247 |
+
self.log_dict_to_wandb({f'{k}_ep': v for k, v in tr_meter_log.items()})
|
| 1248 |
+
tr_meter_log.update({'time': train_time})
|
| 1249 |
+
metric['Epoch%s' % (self.epoch + 1)].update( {'train': tr_meter_log})
|
| 1250 |
+
|
| 1251 |
+
if is_main_process():
|
| 1252 |
+
self.update_metric_file(metric)
|
| 1253 |
+
|
| 1254 |
+
if (self.global_step + 1) % self.args.save_step == 0:
|
| 1255 |
+
logger.warning("Saving model...")
|
| 1256 |
+
self.save_checkpoint(str(self.global_step) + '.pth')
|
| 1257 |
+
if not self.args.deepspeed:
|
| 1258 |
+
self.save_checkpoint(self.last_checkpoint_filename)
|
| 1259 |
+
|
| 1260 |
+
# T.cuda.empty_cache()
|
| 1261 |
+
if (self.global_step + 1) % self.args.eval_step == 0:
|
| 1262 |
+
logger.warning("Evaluating...")
|
| 1263 |
+
if eval_loader:
|
| 1264 |
+
eval_meter, eval_time = self.eval_fn(eval_loader, inner_collect_fn=inner_collect_fn,
|
| 1265 |
+
use_tqdm=use_tqdm, train_eval_input=inputs) # sample a single round training sample to test whether over-fitting
|
| 1266 |
+
logger.info('[Rank %s] Valid Step: %d, Time: %s\n %s' %
|
| 1267 |
+
(self.rank, self.global_step, eval_time, eval_meter.avg))
|
| 1268 |
+
# Update metric with eval metrics
|
| 1269 |
+
val_meter_log = {**eval_meter.avg}
|
| 1270 |
+
self.log_dict_to_wandb({f'{k}_step': v for k, v in val_meter_log.items()})
|
| 1271 |
+
self.log_dict_to_wandb({f'{k}_iter': v for k, v in {**train_meter.avg}.items()})
|
| 1272 |
+
self.log_dict_to_wandb({'lr_paramgp0_iter': self.optimizer.param_groups[0]["lr"]})
|
| 1273 |
+
val_meter_log.update({'time': eval_time})
|
| 1274 |
+
metric['Step%s' % (self.global_step + 1)].update({'eval': val_meter_log})
|
| 1275 |
+
|
| 1276 |
+
# Save metric file
|
| 1277 |
+
if is_main_process():
|
| 1278 |
+
self.update_metric_file(metric)
|
| 1279 |
+
# T.cuda.empty_cache()
|
| 1280 |
+
train_meter = Meter()
|
| 1281 |
+
train_timer = Timer()
|
| 1282 |
+
self.global_step += 1
|
| 1283 |
+
train_pbar.update(1)
|
| 1284 |
+
if self.global_step % self.args.save_step != 0:
|
| 1285 |
+
logger.warning("Saving model...")
|
| 1286 |
+
self.save_checkpoint(self.last_checkpoint_filename)
|
| 1287 |
+
|
| 1288 |
+
if self.global_step % self.args.eval_step != 0:
|
| 1289 |
+
logger.warning("Evaluating...")
|
| 1290 |
+
if eval_loader:
|
| 1291 |
+
eval_meter, eval_time = self.eval_fn(eval_loader, inner_collect_fn=inner_collect_fn,
|
| 1292 |
+
use_tqdm=use_tqdm)
|
| 1293 |
+
logger.info('[Rank %s] Valid Step: %d, Time: %s\n %s' %
|
| 1294 |
+
(self.rank, self.global_step, eval_time, eval_meter.avg))
|
| 1295 |
+
val_meter_log = {**eval_meter.avg}
|
| 1296 |
+
self.log_dict_to_wandb({f'{k}_step': v for k, v in val_meter_log.items()})
|
| 1297 |
+
val_meter_log.update({'time': eval_time})
|
| 1298 |
+
metric['Step%s' % (self.global_step)].update({'eval': val_meter_log})
|
| 1299 |
+
|
| 1300 |
+
# Save metric file
|
| 1301 |
+
if is_main_process():
|
| 1302 |
+
self.update_metric_file(metric)
|
One-to-All-Animation/benchmark/DisCo/annotator/grounded-sam/Dockerfile
ADDED
|
@@ -0,0 +1,11 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
FROM pytorch/pytorch:1.13.1-cuda11.6-cudnn8-devel
|
| 2 |
+
|
| 3 |
+
COPY . /home/appuser
|
| 4 |
+
WORKDIR /home/appuser
|
| 5 |
+
RUN apt-get update && apt-get install ffmpeg libsm6 libxext6 -y
|
| 6 |
+
# Below is for https://github.com/IDEA-Research/Grounded-Segment-Anything/issues/53
|
| 7 |
+
ENV CUDA_HOME /usr/local/cuda-11.6/
|
| 8 |
+
RUN python -m pip install -e segment_anything
|
| 9 |
+
RUN python -m pip install -e GroundingDINO
|
| 10 |
+
RUN pip install --upgrade diffusers[torch]
|
| 11 |
+
RUN pip install opencv-python pycocotools matplotlib onnxruntime onnx ipykernel
|
One-to-All-Animation/benchmark/DisCo/annotator/grounded-sam/GroundingDINO/LICENSE
ADDED
|
@@ -0,0 +1,201 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
Apache License
|
| 2 |
+
Version 2.0, January 2004
|
| 3 |
+
http://www.apache.org/licenses/
|
| 4 |
+
|
| 5 |
+
TERMS AND CONDITIONS FOR USE, REPRODUCTION, AND DISTRIBUTION
|
| 6 |
+
|
| 7 |
+
1. Definitions.
|
| 8 |
+
|
| 9 |
+
"License" shall mean the terms and conditions for use, reproduction,
|
| 10 |
+
and distribution as defined by Sections 1 through 9 of this document.
|
| 11 |
+
|
| 12 |
+
"Licensor" shall mean the copyright owner or entity authorized by
|
| 13 |
+
the copyright owner that is granting the License.
|
| 14 |
+
|
| 15 |
+
"Legal Entity" shall mean the union of the acting entity and all
|
| 16 |
+
other entities that control, are controlled by, or are under common
|
| 17 |
+
control with that entity. For the purposes of this definition,
|
| 18 |
+
"control" means (i) the power, direct or indirect, to cause the
|
| 19 |
+
direction or management of such entity, whether by contract or
|
| 20 |
+
otherwise, or (ii) ownership of fifty percent (50%) or more of the
|
| 21 |
+
outstanding shares, or (iii) beneficial ownership of such entity.
|
| 22 |
+
|
| 23 |
+
"You" (or "Your") shall mean an individual or Legal Entity
|
| 24 |
+
exercising permissions granted by this License.
|
| 25 |
+
|
| 26 |
+
"Source" form shall mean the preferred form for making modifications,
|
| 27 |
+
including but not limited to software source code, documentation
|
| 28 |
+
source, and configuration files.
|
| 29 |
+
|
| 30 |
+
"Object" form shall mean any form resulting from mechanical
|
| 31 |
+
transformation or translation of a Source form, including but
|
| 32 |
+
not limited to compiled object code, generated documentation,
|
| 33 |
+
and conversions to other media types.
|
| 34 |
+
|
| 35 |
+
"Work" shall mean the work of authorship, whether in Source or
|
| 36 |
+
Object form, made available under the License, as indicated by a
|
| 37 |
+
copyright notice that is included in or attached to the work
|
| 38 |
+
(an example is provided in the Appendix below).
|
| 39 |
+
|
| 40 |
+
"Derivative Works" shall mean any work, whether in Source or Object
|
| 41 |
+
form, that is based on (or derived from) the Work and for which the
|
| 42 |
+
editorial revisions, annotations, elaborations, or other modifications
|
| 43 |
+
represent, as a whole, an original work of authorship. For the purposes
|
| 44 |
+
of this License, Derivative Works shall not include works that remain
|
| 45 |
+
separable from, or merely link (or bind by name) to the interfaces of,
|
| 46 |
+
the Work and Derivative Works thereof.
|
| 47 |
+
|
| 48 |
+
"Contribution" shall mean any work of authorship, including
|
| 49 |
+
the original version of the Work and any modifications or additions
|
| 50 |
+
to that Work or Derivative Works thereof, that is intentionally
|
| 51 |
+
submitted to Licensor for inclusion in the Work by the copyright owner
|
| 52 |
+
or by an individual or Legal Entity authorized to submit on behalf of
|
| 53 |
+
the copyright owner. For the purposes of this definition, "submitted"
|
| 54 |
+
means any form of electronic, verbal, or written communication sent
|
| 55 |
+
to the Licensor or its representatives, including but not limited to
|
| 56 |
+
communication on electronic mailing lists, source code control systems,
|
| 57 |
+
and issue tracking systems that are managed by, or on behalf of, the
|
| 58 |
+
Licensor for the purpose of discussing and improving the Work, but
|
| 59 |
+
excluding communication that is conspicuously marked or otherwise
|
| 60 |
+
designated in writing by the copyright owner as "Not a Contribution."
|
| 61 |
+
|
| 62 |
+
"Contributor" shall mean Licensor and any individual or Legal Entity
|
| 63 |
+
on behalf of whom a Contribution has been received by Licensor and
|
| 64 |
+
subsequently incorporated within the Work.
|
| 65 |
+
|
| 66 |
+
2. Grant of Copyright License. Subject to the terms and conditions of
|
| 67 |
+
this License, each Contributor hereby grants to You a perpetual,
|
| 68 |
+
worldwide, non-exclusive, no-charge, royalty-free, irrevocable
|
| 69 |
+
copyright license to reproduce, prepare Derivative Works of,
|
| 70 |
+
publicly display, publicly perform, sublicense, and distribute the
|
| 71 |
+
Work and such Derivative Works in Source or Object form.
|
| 72 |
+
|
| 73 |
+
3. Grant of Patent License. Subject to the terms and conditions of
|
| 74 |
+
this License, each Contributor hereby grants to You a perpetual,
|
| 75 |
+
worldwide, non-exclusive, no-charge, royalty-free, irrevocable
|
| 76 |
+
(except as stated in this section) patent license to make, have made,
|
| 77 |
+
use, offer to sell, sell, import, and otherwise transfer the Work,
|
| 78 |
+
where such license applies only to those patent claims licensable
|
| 79 |
+
by such Contributor that are necessarily infringed by their
|
| 80 |
+
Contribution(s) alone or by combination of their Contribution(s)
|
| 81 |
+
with the Work to which such Contribution(s) was submitted. If You
|
| 82 |
+
institute patent litigation against any entity (including a
|
| 83 |
+
cross-claim or counterclaim in a lawsuit) alleging that the Work
|
| 84 |
+
or a Contribution incorporated within the Work constitutes direct
|
| 85 |
+
or contributory patent infringement, then any patent licenses
|
| 86 |
+
granted to You under this License for that Work shall terminate
|
| 87 |
+
as of the date such litigation is filed.
|
| 88 |
+
|
| 89 |
+
4. Redistribution. You may reproduce and distribute copies of the
|
| 90 |
+
Work or Derivative Works thereof in any medium, with or without
|
| 91 |
+
modifications, and in Source or Object form, provided that You
|
| 92 |
+
meet the following conditions:
|
| 93 |
+
|
| 94 |
+
(a) You must give any other recipients of the Work or
|
| 95 |
+
Derivative Works a copy of this License; and
|
| 96 |
+
|
| 97 |
+
(b) You must cause any modified files to carry prominent notices
|
| 98 |
+
stating that You changed the files; and
|
| 99 |
+
|
| 100 |
+
(c) You must retain, in the Source form of any Derivative Works
|
| 101 |
+
that You distribute, all copyright, patent, trademark, and
|
| 102 |
+
attribution notices from the Source form of the Work,
|
| 103 |
+
excluding those notices that do not pertain to any part of
|
| 104 |
+
the Derivative Works; and
|
| 105 |
+
|
| 106 |
+
(d) If the Work includes a "NOTICE" text file as part of its
|
| 107 |
+
distribution, then any Derivative Works that You distribute must
|
| 108 |
+
include a readable copy of the attribution notices contained
|
| 109 |
+
within such NOTICE file, excluding those notices that do not
|
| 110 |
+
pertain to any part of the Derivative Works, in at least one
|
| 111 |
+
of the following places: within a NOTICE text file distributed
|
| 112 |
+
as part of the Derivative Works; within the Source form or
|
| 113 |
+
documentation, if provided along with the Derivative Works; or,
|
| 114 |
+
within a display generated by the Derivative Works, if and
|
| 115 |
+
wherever such third-party notices normally appear. The contents
|
| 116 |
+
of the NOTICE file are for informational purposes only and
|
| 117 |
+
do not modify the License. You may add Your own attribution
|
| 118 |
+
notices within Derivative Works that You distribute, alongside
|
| 119 |
+
or as an addendum to the NOTICE text from the Work, provided
|
| 120 |
+
that such additional attribution notices cannot be construed
|
| 121 |
+
as modifying the License.
|
| 122 |
+
|
| 123 |
+
You may add Your own copyright statement to Your modifications and
|
| 124 |
+
may provide additional or different license terms and conditions
|
| 125 |
+
for use, reproduction, or distribution of Your modifications, or
|
| 126 |
+
for any such Derivative Works as a whole, provided Your use,
|
| 127 |
+
reproduction, and distribution of the Work otherwise complies with
|
| 128 |
+
the conditions stated in this License.
|
| 129 |
+
|
| 130 |
+
5. Submission of Contributions. Unless You explicitly state otherwise,
|
| 131 |
+
any Contribution intentionally submitted for inclusion in the Work
|
| 132 |
+
by You to the Licensor shall be under the terms and conditions of
|
| 133 |
+
this License, without any additional terms or conditions.
|
| 134 |
+
Notwithstanding the above, nothing herein shall supersede or modify
|
| 135 |
+
the terms of any separate license agreement you may have executed
|
| 136 |
+
with Licensor regarding such Contributions.
|
| 137 |
+
|
| 138 |
+
6. Trademarks. This License does not grant permission to use the trade
|
| 139 |
+
names, trademarks, service marks, or product names of the Licensor,
|
| 140 |
+
except as required for reasonable and customary use in describing the
|
| 141 |
+
origin of the Work and reproducing the content of the NOTICE file.
|
| 142 |
+
|
| 143 |
+
7. Disclaimer of Warranty. Unless required by applicable law or
|
| 144 |
+
agreed to in writing, Licensor provides the Work (and each
|
| 145 |
+
Contributor provides its Contributions) on an "AS IS" BASIS,
|
| 146 |
+
WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or
|
| 147 |
+
implied, including, without limitation, any warranties or conditions
|
| 148 |
+
of TITLE, NON-INFRINGEMENT, MERCHANTABILITY, or FITNESS FOR A
|
| 149 |
+
PARTICULAR PURPOSE. You are solely responsible for determining the
|
| 150 |
+
appropriateness of using or redistributing the Work and assume any
|
| 151 |
+
risks associated with Your exercise of permissions under this License.
|
| 152 |
+
|
| 153 |
+
8. Limitation of Liability. In no event and under no legal theory,
|
| 154 |
+
whether in tort (including negligence), contract, or otherwise,
|
| 155 |
+
unless required by applicable law (such as deliberate and grossly
|
| 156 |
+
negligent acts) or agreed to in writing, shall any Contributor be
|
| 157 |
+
liable to You for damages, including any direct, indirect, special,
|
| 158 |
+
incidental, or consequential damages of any character arising as a
|
| 159 |
+
result of this License or out of the use or inability to use the
|
| 160 |
+
Work (including but not limited to damages for loss of goodwill,
|
| 161 |
+
work stoppage, computer failure or malfunction, or any and all
|
| 162 |
+
other commercial damages or losses), even if such Contributor
|
| 163 |
+
has been advised of the possibility of such damages.
|
| 164 |
+
|
| 165 |
+
9. Accepting Warranty or Additional Liability. While redistributing
|
| 166 |
+
the Work or Derivative Works thereof, You may choose to offer,
|
| 167 |
+
and charge a fee for, acceptance of support, warranty, indemnity,
|
| 168 |
+
or other liability obligations and/or rights consistent with this
|
| 169 |
+
License. However, in accepting such obligations, You may act only
|
| 170 |
+
on Your own behalf and on Your sole responsibility, not on behalf
|
| 171 |
+
of any other Contributor, and only if You agree to indemnify,
|
| 172 |
+
defend, and hold each Contributor harmless for any liability
|
| 173 |
+
incurred by, or claims asserted against, such Contributor by reason
|
| 174 |
+
of your accepting any such warranty or additional liability.
|
| 175 |
+
|
| 176 |
+
END OF TERMS AND CONDITIONS
|
| 177 |
+
|
| 178 |
+
APPENDIX: How to apply the Apache License to your work.
|
| 179 |
+
|
| 180 |
+
To apply the Apache License to your work, attach the following
|
| 181 |
+
boilerplate notice, with the fields enclosed by brackets "[]"
|
| 182 |
+
replaced with your own identifying information. (Don't include
|
| 183 |
+
the brackets!) The text should be enclosed in the appropriate
|
| 184 |
+
comment syntax for the file format. We also recommend that a
|
| 185 |
+
file or class name and description of purpose be included on the
|
| 186 |
+
same "printed page" as the copyright notice for easier
|
| 187 |
+
identification within third-party archives.
|
| 188 |
+
|
| 189 |
+
Copyright 2020 - present, Facebook, Inc
|
| 190 |
+
|
| 191 |
+
Licensed under the Apache License, Version 2.0 (the "License");
|
| 192 |
+
you may not use this file except in compliance with the License.
|
| 193 |
+
You may obtain a copy of the License at
|
| 194 |
+
|
| 195 |
+
http://www.apache.org/licenses/LICENSE-2.0
|
| 196 |
+
|
| 197 |
+
Unless required by applicable law or agreed to in writing, software
|
| 198 |
+
distributed under the License is distributed on an "AS IS" BASIS,
|
| 199 |
+
WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
|
| 200 |
+
See the License for the specific language governing permissions and
|
| 201 |
+
limitations under the License.
|
One-to-All-Animation/benchmark/DisCo/annotator/grounded-sam/GroundingDINO/README.md
ADDED
|
@@ -0,0 +1,163 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
# Grounding DINO
|
| 2 |
+
|
| 3 |
+
---
|
| 4 |
+
|
| 5 |
+
[](https://arxiv.org/abs/2303.05499)
|
| 6 |
+
[](https://youtu.be/wxWDt5UiwY8)
|
| 7 |
+
[](https://colab.research.google.com/github/roboflow-ai/notebooks/blob/main/notebooks/zero-shot-object-detection-with-grounding-dino.ipynb)
|
| 8 |
+
[](https://youtu.be/cMa77r3YrDk)
|
| 9 |
+
[](https://huggingface.co/spaces/ShilongLiu/Grounding_DINO_demo)
|
| 10 |
+
|
| 11 |
+
[](https://paperswithcode.com/sota/zero-shot-object-detection-on-mscoco?p=grounding-dino-marrying-dino-with-grounded) \
|
| 12 |
+
[](https://paperswithcode.com/sota/zero-shot-object-detection-on-odinw?p=grounding-dino-marrying-dino-with-grounded) \
|
| 13 |
+
[](https://paperswithcode.com/sota/object-detection-on-coco-minival?p=grounding-dino-marrying-dino-with-grounded) \
|
| 14 |
+
[](https://paperswithcode.com/sota/object-detection-on-coco?p=grounding-dino-marrying-dino-with-grounded)
|
| 15 |
+
|
| 16 |
+
|
| 17 |
+
|
| 18 |
+
Official PyTorch implementation of [Grounding DINO](https://arxiv.org/abs/2303.05499), a stronger open-set object detector. Code is available now!
|
| 19 |
+
|
| 20 |
+
|
| 21 |
+
## Highlight
|
| 22 |
+
|
| 23 |
+
- **Open-Set Detection.** Detect **everything** with language!
|
| 24 |
+
- **High Performancce.** COCO zero-shot **52.5 AP** (training without COCO data!). COCO fine-tune **63.0 AP**.
|
| 25 |
+
- **Flexible.** Collaboration with Stable Diffusion for Image Editting.
|
| 26 |
+
|
| 27 |
+
## News
|
| 28 |
+
[2023/03/28] A YouTube [video](https://youtu.be/cMa77r3YrDk) about Grounding DINO and basic object detection prompt engineering. [[SkalskiP](https://github.com/SkalskiP)] \
|
| 29 |
+
[2023/03/28] Add a [demo](https://huggingface.co/spaces/ShilongLiu/Grounding_DINO_demo) on Hugging Face Space! \
|
| 30 |
+
[2023/03/27] Support CPU-only mode. Now the model can run on machines without GPUs.\
|
| 31 |
+
[2023/03/25] A [demo](https://colab.research.google.com/github/roboflow-ai/notebooks/blob/main/notebooks/zero-shot-object-detection-with-grounding-dino.ipynb) for Grounding DINO is available at Colab. [[SkalskiP](https://github.com/SkalskiP)] \
|
| 32 |
+
[2023/03/22] Code is available Now!
|
| 33 |
+
|
| 34 |
+
<details open>
|
| 35 |
+
<summary><font size="4">
|
| 36 |
+
Description
|
| 37 |
+
</font></summary>
|
| 38 |
+
<img src=".asset/hero_figure.png" alt="ODinW" width="100%">
|
| 39 |
+
</details>
|
| 40 |
+
|
| 41 |
+
|
| 42 |
+
|
| 43 |
+
## TODO
|
| 44 |
+
|
| 45 |
+
- [x] Release inference code and demo.
|
| 46 |
+
- [x] Release checkpoints.
|
| 47 |
+
- [ ] Grounding DINO with Stable Diffusion and GLIGEN demos.
|
| 48 |
+
- [ ] Release training codes.
|
| 49 |
+
|
| 50 |
+
## Install
|
| 51 |
+
|
| 52 |
+
If you have a CUDA environment, please make sure the environment variable `CUDA_HOME` is set. It will be compiled under CPU-only mode if no CUDA available.
|
| 53 |
+
|
| 54 |
+
```bash
|
| 55 |
+
pip install -e .
|
| 56 |
+
```
|
| 57 |
+
|
| 58 |
+
## Demo
|
| 59 |
+
|
| 60 |
+
```bash
|
| 61 |
+
CUDA_VISIBLE_DEVICES=6 python demo/inference_on_a_image.py \
|
| 62 |
+
-c /path/to/config \
|
| 63 |
+
-p /path/to/checkpoint \
|
| 64 |
+
-i .asset/cats.png \
|
| 65 |
+
-o "outputs/0" \
|
| 66 |
+
-t "cat ear." \
|
| 67 |
+
[--cpu-only] # open it for cpu mode
|
| 68 |
+
```
|
| 69 |
+
See the `demo/inference_on_a_image.py` for more details.
|
| 70 |
+
|
| 71 |
+
**Web UI**
|
| 72 |
+
|
| 73 |
+
We also provide a demo code to integrate Grounding DINO with Gradio Web UI. See the file `demo/gradio_app.py` for more details.
|
| 74 |
+
|
| 75 |
+
## Checkpoints
|
| 76 |
+
|
| 77 |
+
<!-- insert a table -->
|
| 78 |
+
<table>
|
| 79 |
+
<thead>
|
| 80 |
+
<tr style="text-align: right;">
|
| 81 |
+
<th></th>
|
| 82 |
+
<th>name</th>
|
| 83 |
+
<th>backbone</th>
|
| 84 |
+
<th>Data</th>
|
| 85 |
+
<th>box AP on COCO</th>
|
| 86 |
+
<th>Checkpoint</th>
|
| 87 |
+
<th>Config</th>
|
| 88 |
+
</tr>
|
| 89 |
+
</thead>
|
| 90 |
+
<tbody>
|
| 91 |
+
<tr>
|
| 92 |
+
<th>1</th>
|
| 93 |
+
<td>GroundingDINO-T</td>
|
| 94 |
+
<td>Swin-T</td>
|
| 95 |
+
<td>O365,GoldG,Cap4M</td>
|
| 96 |
+
<td>48.4 (zero-shot) / 57.2 (fine-tune)</td>
|
| 97 |
+
<td><a href="https://github.com/IDEA-Research/GroundingDINO/releases/download/v0.1.0-alpha/groundingdino_swint_ogc.pth">Github link</a> | <a href="https://huggingface.co/ShilongLiu/GroundingDINO/resolve/main/groundingdino_swint_ogc.pth">HF link</a></td>
|
| 98 |
+
<td><a href="https://github.com/IDEA-Research/GroundingDINO/blob/main/groundingdino/config/GroundingDINO_SwinT_OGC.py">link</a></td>
|
| 99 |
+
</tr>
|
| 100 |
+
</tbody>
|
| 101 |
+
</table>
|
| 102 |
+
|
| 103 |
+
## Results
|
| 104 |
+
|
| 105 |
+
<details open>
|
| 106 |
+
<summary><font size="4">
|
| 107 |
+
COCO Object Detection Results
|
| 108 |
+
</font></summary>
|
| 109 |
+
<img src=".asset/COCO.png" alt="COCO" width="100%">
|
| 110 |
+
</details>
|
| 111 |
+
|
| 112 |
+
<details open>
|
| 113 |
+
<summary><font size="4">
|
| 114 |
+
ODinW Object Detection Results
|
| 115 |
+
</font></summary>
|
| 116 |
+
<img src=".asset/ODinW.png" alt="ODinW" width="100%">
|
| 117 |
+
</details>
|
| 118 |
+
|
| 119 |
+
<details open>
|
| 120 |
+
<summary><font size="4">
|
| 121 |
+
Marrying Grounding DINO with <a href="https://github.com/Stability-AI/StableDiffusion">Stable Diffusion</a> for Image Editing
|
| 122 |
+
</font></summary>
|
| 123 |
+
<img src=".asset/GD_SD.png" alt="GD_SD" width="100%">
|
| 124 |
+
</details>
|
| 125 |
+
|
| 126 |
+
<details open>
|
| 127 |
+
<summary><font size="4">
|
| 128 |
+
Marrying Grounding DINO with <a href="https://github.com/gligen/GLIGEN">GLIGEN</a> for more Detailed Image Editing
|
| 129 |
+
</font></summary>
|
| 130 |
+
<img src=".asset/GD_GLIGEN.png" alt="GD_GLIGEN" width="100%">
|
| 131 |
+
</details>
|
| 132 |
+
|
| 133 |
+
## Model
|
| 134 |
+
|
| 135 |
+
Includes: a text backbone, an image backbone, a feature enhancer, a language-guided query selection, and a cross-modality decoder.
|
| 136 |
+
|
| 137 |
+

|
| 138 |
+
|
| 139 |
+
|
| 140 |
+
## Acknowledgement
|
| 141 |
+
|
| 142 |
+
Our model is related to [DINO](https://github.com/IDEA-Research/DINO) and [GLIP](https://github.com/microsoft/GLIP). Thanks for their great work!
|
| 143 |
+
|
| 144 |
+
We also thank great previous work including DETR, Deformable DETR, SMCA, Conditional DETR, Anchor DETR, Dynamic DETR, DAB-DETR, DN-DETR, etc. More related work are available at [Awesome Detection Transformer](https://github.com/IDEACVR/awesome-detection-transformer). A new toolbox [detrex](https://github.com/IDEA-Research/detrex) is available as well.
|
| 145 |
+
|
| 146 |
+
Thanks [Stable Diffusion](https://github.com/Stability-AI/StableDiffusion) and [GLIGEN](https://github.com/gligen/GLIGEN) for their awesome models.
|
| 147 |
+
|
| 148 |
+
|
| 149 |
+
## Citation
|
| 150 |
+
|
| 151 |
+
If you find our work helpful for your research, please consider citing the following BibTeX entry.
|
| 152 |
+
|
| 153 |
+
```bibtex
|
| 154 |
+
@inproceedings{ShilongLiu2023GroundingDM,
|
| 155 |
+
title={Grounding DINO: Marrying DINO with Grounded Pre-Training for Open-Set Object Detection},
|
| 156 |
+
author={Shilong Liu and Zhaoyang Zeng and Tianhe Ren and Feng Li and Hao Zhang and Jie Yang and Chunyuan Li and Jianwei Yang and Hang Su and Jun Zhu and Lei Zhang},
|
| 157 |
+
year={2023}
|
| 158 |
+
}
|
| 159 |
+
```
|
| 160 |
+
|
| 161 |
+
|
| 162 |
+
|
| 163 |
+
|
One-to-All-Animation/benchmark/DisCo/annotator/grounded-sam/GroundingDINO/groundingdino/__init__.py
ADDED
|
File without changes
|
One-to-All-Animation/benchmark/DisCo/annotator/grounded-sam/GroundingDINO/groundingdino/config/GroundingDINO_SwinB.cfg.py
ADDED
|
@@ -0,0 +1,43 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
batch_size = 1
|
| 2 |
+
modelname = "groundingdino"
|
| 3 |
+
backbone = "swin_B_384_22k"
|
| 4 |
+
position_embedding = "sine"
|
| 5 |
+
pe_temperatureH = 20
|
| 6 |
+
pe_temperatureW = 20
|
| 7 |
+
return_interm_indices = [1, 2, 3]
|
| 8 |
+
backbone_freeze_keywords = None
|
| 9 |
+
enc_layers = 6
|
| 10 |
+
dec_layers = 6
|
| 11 |
+
pre_norm = False
|
| 12 |
+
dim_feedforward = 2048
|
| 13 |
+
hidden_dim = 256
|
| 14 |
+
dropout = 0.0
|
| 15 |
+
nheads = 8
|
| 16 |
+
num_queries = 900
|
| 17 |
+
query_dim = 4
|
| 18 |
+
num_patterns = 0
|
| 19 |
+
num_feature_levels = 4
|
| 20 |
+
enc_n_points = 4
|
| 21 |
+
dec_n_points = 4
|
| 22 |
+
two_stage_type = "standard"
|
| 23 |
+
two_stage_bbox_embed_share = False
|
| 24 |
+
two_stage_class_embed_share = False
|
| 25 |
+
transformer_activation = "relu"
|
| 26 |
+
dec_pred_bbox_embed_share = True
|
| 27 |
+
dn_box_noise_scale = 1.0
|
| 28 |
+
dn_label_noise_ratio = 0.5
|
| 29 |
+
dn_label_coef = 1.0
|
| 30 |
+
dn_bbox_coef = 1.0
|
| 31 |
+
embed_init_tgt = True
|
| 32 |
+
dn_labelbook_size = 2000
|
| 33 |
+
max_text_len = 256
|
| 34 |
+
text_encoder_type = "bert-base-uncased"
|
| 35 |
+
use_text_enhancer = True
|
| 36 |
+
use_fusion_layer = True
|
| 37 |
+
use_checkpoint = True
|
| 38 |
+
use_transformer_ckpt = True
|
| 39 |
+
use_text_cross_attention = True
|
| 40 |
+
text_dropout = 0.0
|
| 41 |
+
fusion_dropout = 0.0
|
| 42 |
+
fusion_droppath = 0.1
|
| 43 |
+
sub_sentence_present = True
|
One-to-All-Animation/benchmark/DisCo/annotator/grounded-sam/GroundingDINO/groundingdino/config/GroundingDINO_SwinT_OGC.py
ADDED
|
@@ -0,0 +1,43 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
batch_size = 1
|
| 2 |
+
modelname = "groundingdino"
|
| 3 |
+
backbone = "swin_T_224_1k"
|
| 4 |
+
position_embedding = "sine"
|
| 5 |
+
pe_temperatureH = 20
|
| 6 |
+
pe_temperatureW = 20
|
| 7 |
+
return_interm_indices = [1, 2, 3]
|
| 8 |
+
backbone_freeze_keywords = None
|
| 9 |
+
enc_layers = 6
|
| 10 |
+
dec_layers = 6
|
| 11 |
+
pre_norm = False
|
| 12 |
+
dim_feedforward = 2048
|
| 13 |
+
hidden_dim = 256
|
| 14 |
+
dropout = 0.0
|
| 15 |
+
nheads = 8
|
| 16 |
+
num_queries = 900
|
| 17 |
+
query_dim = 4
|
| 18 |
+
num_patterns = 0
|
| 19 |
+
num_feature_levels = 4
|
| 20 |
+
enc_n_points = 4
|
| 21 |
+
dec_n_points = 4
|
| 22 |
+
two_stage_type = "standard"
|
| 23 |
+
two_stage_bbox_embed_share = False
|
| 24 |
+
two_stage_class_embed_share = False
|
| 25 |
+
transformer_activation = "relu"
|
| 26 |
+
dec_pred_bbox_embed_share = True
|
| 27 |
+
dn_box_noise_scale = 1.0
|
| 28 |
+
dn_label_noise_ratio = 0.5
|
| 29 |
+
dn_label_coef = 1.0
|
| 30 |
+
dn_bbox_coef = 1.0
|
| 31 |
+
embed_init_tgt = True
|
| 32 |
+
dn_labelbook_size = 2000
|
| 33 |
+
max_text_len = 256
|
| 34 |
+
text_encoder_type = "bert-base-uncased"
|
| 35 |
+
use_text_enhancer = True
|
| 36 |
+
use_fusion_layer = True
|
| 37 |
+
use_checkpoint = True
|
| 38 |
+
use_transformer_ckpt = True
|
| 39 |
+
use_text_cross_attention = True
|
| 40 |
+
text_dropout = 0.0
|
| 41 |
+
fusion_dropout = 0.0
|
| 42 |
+
fusion_droppath = 0.1
|
| 43 |
+
sub_sentence_present = True
|
One-to-All-Animation/benchmark/DisCo/annotator/grounded-sam/GroundingDINO/groundingdino/datasets/__init__.py
ADDED
|
File without changes
|
One-to-All-Animation/benchmark/DisCo/annotator/grounded-sam/GroundingDINO/groundingdino/datasets/transforms.py
ADDED
|
@@ -0,0 +1,311 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
# Copyright (c) Facebook, Inc. and its affiliates. All Rights Reserved
|
| 2 |
+
"""
|
| 3 |
+
Transforms and data augmentation for both image + bbox.
|
| 4 |
+
"""
|
| 5 |
+
import os
|
| 6 |
+
import random
|
| 7 |
+
|
| 8 |
+
import PIL
|
| 9 |
+
import torch
|
| 10 |
+
import torchvision.transforms as T
|
| 11 |
+
import torchvision.transforms.functional as F
|
| 12 |
+
|
| 13 |
+
from groundingdino.util.box_ops import box_xyxy_to_cxcywh
|
| 14 |
+
from groundingdino.util.misc import interpolate
|
| 15 |
+
|
| 16 |
+
|
| 17 |
+
def crop(image, target, region):
|
| 18 |
+
cropped_image = F.crop(image, *region)
|
| 19 |
+
|
| 20 |
+
target = target.copy()
|
| 21 |
+
i, j, h, w = region
|
| 22 |
+
|
| 23 |
+
# should we do something wrt the original size?
|
| 24 |
+
target["size"] = torch.tensor([h, w])
|
| 25 |
+
|
| 26 |
+
fields = ["labels", "area", "iscrowd", "positive_map"]
|
| 27 |
+
|
| 28 |
+
if "boxes" in target:
|
| 29 |
+
boxes = target["boxes"]
|
| 30 |
+
max_size = torch.as_tensor([w, h], dtype=torch.float32)
|
| 31 |
+
cropped_boxes = boxes - torch.as_tensor([j, i, j, i])
|
| 32 |
+
cropped_boxes = torch.min(cropped_boxes.reshape(-1, 2, 2), max_size)
|
| 33 |
+
cropped_boxes = cropped_boxes.clamp(min=0)
|
| 34 |
+
area = (cropped_boxes[:, 1, :] - cropped_boxes[:, 0, :]).prod(dim=1)
|
| 35 |
+
target["boxes"] = cropped_boxes.reshape(-1, 4)
|
| 36 |
+
target["area"] = area
|
| 37 |
+
fields.append("boxes")
|
| 38 |
+
|
| 39 |
+
if "masks" in target:
|
| 40 |
+
# FIXME should we update the area here if there are no boxes?
|
| 41 |
+
target["masks"] = target["masks"][:, i : i + h, j : j + w]
|
| 42 |
+
fields.append("masks")
|
| 43 |
+
|
| 44 |
+
# remove elements for which the boxes or masks that have zero area
|
| 45 |
+
if "boxes" in target or "masks" in target:
|
| 46 |
+
# favor boxes selection when defining which elements to keep
|
| 47 |
+
# this is compatible with previous implementation
|
| 48 |
+
if "boxes" in target:
|
| 49 |
+
cropped_boxes = target["boxes"].reshape(-1, 2, 2)
|
| 50 |
+
keep = torch.all(cropped_boxes[:, 1, :] > cropped_boxes[:, 0, :], dim=1)
|
| 51 |
+
else:
|
| 52 |
+
keep = target["masks"].flatten(1).any(1)
|
| 53 |
+
|
| 54 |
+
for field in fields:
|
| 55 |
+
if field in target:
|
| 56 |
+
target[field] = target[field][keep]
|
| 57 |
+
|
| 58 |
+
if os.environ.get("IPDB_SHILONG_DEBUG", None) == "INFO":
|
| 59 |
+
# for debug and visualization only.
|
| 60 |
+
if "strings_positive" in target:
|
| 61 |
+
target["strings_positive"] = [
|
| 62 |
+
_i for _i, _j in zip(target["strings_positive"], keep) if _j
|
| 63 |
+
]
|
| 64 |
+
|
| 65 |
+
return cropped_image, target
|
| 66 |
+
|
| 67 |
+
|
| 68 |
+
def hflip(image, target):
|
| 69 |
+
flipped_image = F.hflip(image)
|
| 70 |
+
|
| 71 |
+
w, h = image.size
|
| 72 |
+
|
| 73 |
+
target = target.copy()
|
| 74 |
+
if "boxes" in target:
|
| 75 |
+
boxes = target["boxes"]
|
| 76 |
+
boxes = boxes[:, [2, 1, 0, 3]] * torch.as_tensor([-1, 1, -1, 1]) + torch.as_tensor(
|
| 77 |
+
[w, 0, w, 0]
|
| 78 |
+
)
|
| 79 |
+
target["boxes"] = boxes
|
| 80 |
+
|
| 81 |
+
if "masks" in target:
|
| 82 |
+
target["masks"] = target["masks"].flip(-1)
|
| 83 |
+
|
| 84 |
+
return flipped_image, target
|
| 85 |
+
|
| 86 |
+
|
| 87 |
+
def resize(image, target, size, max_size=None):
|
| 88 |
+
# size can be min_size (scalar) or (w, h) tuple
|
| 89 |
+
|
| 90 |
+
def get_size_with_aspect_ratio(image_size, size, max_size=None):
|
| 91 |
+
w, h = image_size
|
| 92 |
+
if max_size is not None:
|
| 93 |
+
min_original_size = float(min((w, h)))
|
| 94 |
+
max_original_size = float(max((w, h)))
|
| 95 |
+
if max_original_size / min_original_size * size > max_size:
|
| 96 |
+
size = int(round(max_size * min_original_size / max_original_size))
|
| 97 |
+
|
| 98 |
+
if (w <= h and w == size) or (h <= w and h == size):
|
| 99 |
+
return (h, w)
|
| 100 |
+
|
| 101 |
+
if w < h:
|
| 102 |
+
ow = size
|
| 103 |
+
oh = int(size * h / w)
|
| 104 |
+
else:
|
| 105 |
+
oh = size
|
| 106 |
+
ow = int(size * w / h)
|
| 107 |
+
|
| 108 |
+
return (oh, ow)
|
| 109 |
+
|
| 110 |
+
def get_size(image_size, size, max_size=None):
|
| 111 |
+
if isinstance(size, (list, tuple)):
|
| 112 |
+
return size[::-1]
|
| 113 |
+
else:
|
| 114 |
+
return get_size_with_aspect_ratio(image_size, size, max_size)
|
| 115 |
+
|
| 116 |
+
size = get_size(image.size, size, max_size)
|
| 117 |
+
rescaled_image = F.resize(image, size)
|
| 118 |
+
|
| 119 |
+
if target is None:
|
| 120 |
+
return rescaled_image, None
|
| 121 |
+
|
| 122 |
+
ratios = tuple(float(s) / float(s_orig) for s, s_orig in zip(rescaled_image.size, image.size))
|
| 123 |
+
ratio_width, ratio_height = ratios
|
| 124 |
+
|
| 125 |
+
target = target.copy()
|
| 126 |
+
if "boxes" in target:
|
| 127 |
+
boxes = target["boxes"]
|
| 128 |
+
scaled_boxes = boxes * torch.as_tensor(
|
| 129 |
+
[ratio_width, ratio_height, ratio_width, ratio_height]
|
| 130 |
+
)
|
| 131 |
+
target["boxes"] = scaled_boxes
|
| 132 |
+
|
| 133 |
+
if "area" in target:
|
| 134 |
+
area = target["area"]
|
| 135 |
+
scaled_area = area * (ratio_width * ratio_height)
|
| 136 |
+
target["area"] = scaled_area
|
| 137 |
+
|
| 138 |
+
h, w = size
|
| 139 |
+
target["size"] = torch.tensor([h, w])
|
| 140 |
+
|
| 141 |
+
if "masks" in target:
|
| 142 |
+
target["masks"] = (
|
| 143 |
+
interpolate(target["masks"][:, None].float(), size, mode="nearest")[:, 0] > 0.5
|
| 144 |
+
)
|
| 145 |
+
|
| 146 |
+
return rescaled_image, target
|
| 147 |
+
|
| 148 |
+
|
| 149 |
+
def pad(image, target, padding):
|
| 150 |
+
# assumes that we only pad on the bottom right corners
|
| 151 |
+
padded_image = F.pad(image, (0, 0, padding[0], padding[1]))
|
| 152 |
+
if target is None:
|
| 153 |
+
return padded_image, None
|
| 154 |
+
target = target.copy()
|
| 155 |
+
# should we do something wrt the original size?
|
| 156 |
+
target["size"] = torch.tensor(padded_image.size[::-1])
|
| 157 |
+
if "masks" in target:
|
| 158 |
+
target["masks"] = torch.nn.functional.pad(target["masks"], (0, padding[0], 0, padding[1]))
|
| 159 |
+
return padded_image, target
|
| 160 |
+
|
| 161 |
+
|
| 162 |
+
class ResizeDebug(object):
|
| 163 |
+
def __init__(self, size):
|
| 164 |
+
self.size = size
|
| 165 |
+
|
| 166 |
+
def __call__(self, img, target):
|
| 167 |
+
return resize(img, target, self.size)
|
| 168 |
+
|
| 169 |
+
|
| 170 |
+
class RandomCrop(object):
|
| 171 |
+
def __init__(self, size):
|
| 172 |
+
self.size = size
|
| 173 |
+
|
| 174 |
+
def __call__(self, img, target):
|
| 175 |
+
region = T.RandomCrop.get_params(img, self.size)
|
| 176 |
+
return crop(img, target, region)
|
| 177 |
+
|
| 178 |
+
|
| 179 |
+
class RandomSizeCrop(object):
|
| 180 |
+
def __init__(self, min_size: int, max_size: int, respect_boxes: bool = False):
|
| 181 |
+
# respect_boxes: True to keep all boxes
|
| 182 |
+
# False to tolerence box filter
|
| 183 |
+
self.min_size = min_size
|
| 184 |
+
self.max_size = max_size
|
| 185 |
+
self.respect_boxes = respect_boxes
|
| 186 |
+
|
| 187 |
+
def __call__(self, img: PIL.Image.Image, target: dict):
|
| 188 |
+
init_boxes = len(target["boxes"])
|
| 189 |
+
max_patience = 10
|
| 190 |
+
for i in range(max_patience):
|
| 191 |
+
w = random.randint(self.min_size, min(img.width, self.max_size))
|
| 192 |
+
h = random.randint(self.min_size, min(img.height, self.max_size))
|
| 193 |
+
region = T.RandomCrop.get_params(img, [h, w])
|
| 194 |
+
result_img, result_target = crop(img, target, region)
|
| 195 |
+
if (
|
| 196 |
+
not self.respect_boxes
|
| 197 |
+
or len(result_target["boxes"]) == init_boxes
|
| 198 |
+
or i == max_patience - 1
|
| 199 |
+
):
|
| 200 |
+
return result_img, result_target
|
| 201 |
+
return result_img, result_target
|
| 202 |
+
|
| 203 |
+
|
| 204 |
+
class CenterCrop(object):
|
| 205 |
+
def __init__(self, size):
|
| 206 |
+
self.size = size
|
| 207 |
+
|
| 208 |
+
def __call__(self, img, target):
|
| 209 |
+
image_width, image_height = img.size
|
| 210 |
+
crop_height, crop_width = self.size
|
| 211 |
+
crop_top = int(round((image_height - crop_height) / 2.0))
|
| 212 |
+
crop_left = int(round((image_width - crop_width) / 2.0))
|
| 213 |
+
return crop(img, target, (crop_top, crop_left, crop_height, crop_width))
|
| 214 |
+
|
| 215 |
+
|
| 216 |
+
class RandomHorizontalFlip(object):
|
| 217 |
+
def __init__(self, p=0.5):
|
| 218 |
+
self.p = p
|
| 219 |
+
|
| 220 |
+
def __call__(self, img, target):
|
| 221 |
+
if random.random() < self.p:
|
| 222 |
+
return hflip(img, target)
|
| 223 |
+
return img, target
|
| 224 |
+
|
| 225 |
+
|
| 226 |
+
class RandomResize(object):
|
| 227 |
+
def __init__(self, sizes, max_size=None):
|
| 228 |
+
assert isinstance(sizes, (list, tuple))
|
| 229 |
+
self.sizes = sizes
|
| 230 |
+
self.max_size = max_size
|
| 231 |
+
|
| 232 |
+
def __call__(self, img, target=None):
|
| 233 |
+
size = random.choice(self.sizes)
|
| 234 |
+
return resize(img, target, size, self.max_size)
|
| 235 |
+
|
| 236 |
+
|
| 237 |
+
class RandomPad(object):
|
| 238 |
+
def __init__(self, max_pad):
|
| 239 |
+
self.max_pad = max_pad
|
| 240 |
+
|
| 241 |
+
def __call__(self, img, target):
|
| 242 |
+
pad_x = random.randint(0, self.max_pad)
|
| 243 |
+
pad_y = random.randint(0, self.max_pad)
|
| 244 |
+
return pad(img, target, (pad_x, pad_y))
|
| 245 |
+
|
| 246 |
+
|
| 247 |
+
class RandomSelect(object):
|
| 248 |
+
"""
|
| 249 |
+
Randomly selects between transforms1 and transforms2,
|
| 250 |
+
with probability p for transforms1 and (1 - p) for transforms2
|
| 251 |
+
"""
|
| 252 |
+
|
| 253 |
+
def __init__(self, transforms1, transforms2, p=0.5):
|
| 254 |
+
self.transforms1 = transforms1
|
| 255 |
+
self.transforms2 = transforms2
|
| 256 |
+
self.p = p
|
| 257 |
+
|
| 258 |
+
def __call__(self, img, target):
|
| 259 |
+
if random.random() < self.p:
|
| 260 |
+
return self.transforms1(img, target)
|
| 261 |
+
return self.transforms2(img, target)
|
| 262 |
+
|
| 263 |
+
|
| 264 |
+
class ToTensor(object):
|
| 265 |
+
def __call__(self, img, target):
|
| 266 |
+
return F.to_tensor(img), target
|
| 267 |
+
|
| 268 |
+
|
| 269 |
+
class RandomErasing(object):
|
| 270 |
+
def __init__(self, *args, **kwargs):
|
| 271 |
+
self.eraser = T.RandomErasing(*args, **kwargs)
|
| 272 |
+
|
| 273 |
+
def __call__(self, img, target):
|
| 274 |
+
return self.eraser(img), target
|
| 275 |
+
|
| 276 |
+
|
| 277 |
+
class Normalize(object):
|
| 278 |
+
def __init__(self, mean, std):
|
| 279 |
+
self.mean = mean
|
| 280 |
+
self.std = std
|
| 281 |
+
|
| 282 |
+
def __call__(self, image, target=None):
|
| 283 |
+
image = F.normalize(image, mean=self.mean, std=self.std)
|
| 284 |
+
if target is None:
|
| 285 |
+
return image, None
|
| 286 |
+
target = target.copy()
|
| 287 |
+
h, w = image.shape[-2:]
|
| 288 |
+
if "boxes" in target:
|
| 289 |
+
boxes = target["boxes"]
|
| 290 |
+
boxes = box_xyxy_to_cxcywh(boxes)
|
| 291 |
+
boxes = boxes / torch.tensor([w, h, w, h], dtype=torch.float32)
|
| 292 |
+
target["boxes"] = boxes
|
| 293 |
+
return image, target
|
| 294 |
+
|
| 295 |
+
|
| 296 |
+
class Compose(object):
|
| 297 |
+
def __init__(self, transforms):
|
| 298 |
+
self.transforms = transforms
|
| 299 |
+
|
| 300 |
+
def __call__(self, image, target):
|
| 301 |
+
for t in self.transforms:
|
| 302 |
+
image, target = t(image, target)
|
| 303 |
+
return image, target
|
| 304 |
+
|
| 305 |
+
def __repr__(self):
|
| 306 |
+
format_string = self.__class__.__name__ + "("
|
| 307 |
+
for t in self.transforms:
|
| 308 |
+
format_string += "\n"
|
| 309 |
+
format_string += " {0}".format(t)
|
| 310 |
+
format_string += "\n)"
|
| 311 |
+
return format_string
|
One-to-All-Animation/benchmark/DisCo/annotator/grounded-sam/GroundingDINO/groundingdino/models/GroundingDINO/__init__.py
ADDED
|
@@ -0,0 +1,15 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
# ------------------------------------------------------------------------
|
| 2 |
+
# Grounding DINO
|
| 3 |
+
# url: https://github.com/IDEA-Research/GroundingDINO
|
| 4 |
+
# Copyright (c) 2023 IDEA. All Rights Reserved.
|
| 5 |
+
# Licensed under the Apache License, Version 2.0 [see LICENSE for details]
|
| 6 |
+
# ------------------------------------------------------------------------
|
| 7 |
+
# Conditional DETR
|
| 8 |
+
# Copyright (c) 2021 Microsoft. All Rights Reserved.
|
| 9 |
+
# Licensed under the Apache License, Version 2.0 [see LICENSE for details]
|
| 10 |
+
# ------------------------------------------------------------------------
|
| 11 |
+
# Copied from DETR (https://github.com/facebookresearch/detr)
|
| 12 |
+
# Copyright (c) Facebook, Inc. and its affiliates. All Rights Reserved.
|
| 13 |
+
# ------------------------------------------------------------------------
|
| 14 |
+
|
| 15 |
+
from .groundingdino import build_groundingdino
|
One-to-All-Animation/benchmark/DisCo/annotator/grounded-sam/GroundingDINO/groundingdino/models/GroundingDINO/backbone/__init__.py
ADDED
|
@@ -0,0 +1 @@
|
|
|
|
|
|
|
| 1 |
+
from .backbone import build_backbone
|
One-to-All-Animation/benchmark/DisCo/annotator/grounded-sam/GroundingDINO/groundingdino/models/GroundingDINO/backbone/backbone.py
ADDED
|
@@ -0,0 +1,221 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
# ------------------------------------------------------------------------
|
| 2 |
+
# Grounding DINO
|
| 3 |
+
# url: https://github.com/IDEA-Research/GroundingDINO
|
| 4 |
+
# Copyright (c) 2023 IDEA. All Rights Reserved.
|
| 5 |
+
# Licensed under the Apache License, Version 2.0 [see LICENSE for details]
|
| 6 |
+
# ------------------------------------------------------------------------
|
| 7 |
+
# Conditional DETR
|
| 8 |
+
# Copyright (c) 2021 Microsoft. All Rights Reserved.
|
| 9 |
+
# Licensed under the Apache License, Version 2.0 [see LICENSE for details]
|
| 10 |
+
# ------------------------------------------------------------------------
|
| 11 |
+
# Copied from DETR (https://github.com/facebookresearch/detr)
|
| 12 |
+
# Copyright (c) Facebook, Inc. and its affiliates. All Rights Reserved.
|
| 13 |
+
# ------------------------------------------------------------------------
|
| 14 |
+
|
| 15 |
+
"""
|
| 16 |
+
Backbone modules.
|
| 17 |
+
"""
|
| 18 |
+
|
| 19 |
+
from typing import Dict, List
|
| 20 |
+
|
| 21 |
+
import torch
|
| 22 |
+
import torch.nn.functional as F
|
| 23 |
+
import torchvision
|
| 24 |
+
from torch import nn
|
| 25 |
+
from torchvision.models._utils import IntermediateLayerGetter
|
| 26 |
+
|
| 27 |
+
from groundingdino.util.misc import NestedTensor, clean_state_dict, is_main_process
|
| 28 |
+
|
| 29 |
+
from .position_encoding import build_position_encoding
|
| 30 |
+
from .swin_transformer import build_swin_transformer
|
| 31 |
+
|
| 32 |
+
|
| 33 |
+
class FrozenBatchNorm2d(torch.nn.Module):
|
| 34 |
+
"""
|
| 35 |
+
BatchNorm2d where the batch statistics and the affine parameters are fixed.
|
| 36 |
+
|
| 37 |
+
Copy-paste from torchvision.misc.ops with added eps before rqsrt,
|
| 38 |
+
without which any other models than torchvision.models.resnet[18,34,50,101]
|
| 39 |
+
produce nans.
|
| 40 |
+
"""
|
| 41 |
+
|
| 42 |
+
def __init__(self, n):
|
| 43 |
+
super(FrozenBatchNorm2d, self).__init__()
|
| 44 |
+
self.register_buffer("weight", torch.ones(n))
|
| 45 |
+
self.register_buffer("bias", torch.zeros(n))
|
| 46 |
+
self.register_buffer("running_mean", torch.zeros(n))
|
| 47 |
+
self.register_buffer("running_var", torch.ones(n))
|
| 48 |
+
|
| 49 |
+
def _load_from_state_dict(
|
| 50 |
+
self, state_dict, prefix, local_metadata, strict, missing_keys, unexpected_keys, error_msgs
|
| 51 |
+
):
|
| 52 |
+
num_batches_tracked_key = prefix + "num_batches_tracked"
|
| 53 |
+
if num_batches_tracked_key in state_dict:
|
| 54 |
+
del state_dict[num_batches_tracked_key]
|
| 55 |
+
|
| 56 |
+
super(FrozenBatchNorm2d, self)._load_from_state_dict(
|
| 57 |
+
state_dict, prefix, local_metadata, strict, missing_keys, unexpected_keys, error_msgs
|
| 58 |
+
)
|
| 59 |
+
|
| 60 |
+
def forward(self, x):
|
| 61 |
+
# move reshapes to the beginning
|
| 62 |
+
# to make it fuser-friendly
|
| 63 |
+
w = self.weight.reshape(1, -1, 1, 1)
|
| 64 |
+
b = self.bias.reshape(1, -1, 1, 1)
|
| 65 |
+
rv = self.running_var.reshape(1, -1, 1, 1)
|
| 66 |
+
rm = self.running_mean.reshape(1, -1, 1, 1)
|
| 67 |
+
eps = 1e-5
|
| 68 |
+
scale = w * (rv + eps).rsqrt()
|
| 69 |
+
bias = b - rm * scale
|
| 70 |
+
return x * scale + bias
|
| 71 |
+
|
| 72 |
+
|
| 73 |
+
class BackboneBase(nn.Module):
|
| 74 |
+
def __init__(
|
| 75 |
+
self,
|
| 76 |
+
backbone: nn.Module,
|
| 77 |
+
train_backbone: bool,
|
| 78 |
+
num_channels: int,
|
| 79 |
+
return_interm_indices: list,
|
| 80 |
+
):
|
| 81 |
+
super().__init__()
|
| 82 |
+
for name, parameter in backbone.named_parameters():
|
| 83 |
+
if (
|
| 84 |
+
not train_backbone
|
| 85 |
+
or "layer2" not in name
|
| 86 |
+
and "layer3" not in name
|
| 87 |
+
and "layer4" not in name
|
| 88 |
+
):
|
| 89 |
+
parameter.requires_grad_(False)
|
| 90 |
+
|
| 91 |
+
return_layers = {}
|
| 92 |
+
for idx, layer_index in enumerate(return_interm_indices):
|
| 93 |
+
return_layers.update(
|
| 94 |
+
{"layer{}".format(5 - len(return_interm_indices) + idx): "{}".format(layer_index)}
|
| 95 |
+
)
|
| 96 |
+
|
| 97 |
+
# if len:
|
| 98 |
+
# if use_stage1_feature:
|
| 99 |
+
# return_layers = {"layer1": "0", "layer2": "1", "layer3": "2", "layer4": "3"}
|
| 100 |
+
# else:
|
| 101 |
+
# return_layers = {"layer2": "0", "layer3": "1", "layer4": "2"}
|
| 102 |
+
# else:
|
| 103 |
+
# return_layers = {'layer4': "0"}
|
| 104 |
+
self.body = IntermediateLayerGetter(backbone, return_layers=return_layers)
|
| 105 |
+
self.num_channels = num_channels
|
| 106 |
+
|
| 107 |
+
def forward(self, tensor_list: NestedTensor):
|
| 108 |
+
xs = self.body(tensor_list.tensors)
|
| 109 |
+
out: Dict[str, NestedTensor] = {}
|
| 110 |
+
for name, x in xs.items():
|
| 111 |
+
m = tensor_list.mask
|
| 112 |
+
assert m is not None
|
| 113 |
+
mask = F.interpolate(m[None].float(), size=x.shape[-2:]).to(torch.bool)[0]
|
| 114 |
+
out[name] = NestedTensor(x, mask)
|
| 115 |
+
# import ipdb; ipdb.set_trace()
|
| 116 |
+
return out
|
| 117 |
+
|
| 118 |
+
|
| 119 |
+
class Backbone(BackboneBase):
|
| 120 |
+
"""ResNet backbone with frozen BatchNorm."""
|
| 121 |
+
|
| 122 |
+
def __init__(
|
| 123 |
+
self,
|
| 124 |
+
name: str,
|
| 125 |
+
train_backbone: bool,
|
| 126 |
+
dilation: bool,
|
| 127 |
+
return_interm_indices: list,
|
| 128 |
+
batch_norm=FrozenBatchNorm2d,
|
| 129 |
+
):
|
| 130 |
+
if name in ["resnet18", "resnet34", "resnet50", "resnet101"]:
|
| 131 |
+
backbone = getattr(torchvision.models, name)(
|
| 132 |
+
replace_stride_with_dilation=[False, False, dilation],
|
| 133 |
+
pretrained=is_main_process(),
|
| 134 |
+
norm_layer=batch_norm,
|
| 135 |
+
)
|
| 136 |
+
else:
|
| 137 |
+
raise NotImplementedError("Why you can get here with name {}".format(name))
|
| 138 |
+
# num_channels = 512 if name in ('resnet18', 'resnet34') else 2048
|
| 139 |
+
assert name not in ("resnet18", "resnet34"), "Only resnet50 and resnet101 are available."
|
| 140 |
+
assert return_interm_indices in [[0, 1, 2, 3], [1, 2, 3], [3]]
|
| 141 |
+
num_channels_all = [256, 512, 1024, 2048]
|
| 142 |
+
num_channels = num_channels_all[4 - len(return_interm_indices) :]
|
| 143 |
+
super().__init__(backbone, train_backbone, num_channels, return_interm_indices)
|
| 144 |
+
|
| 145 |
+
|
| 146 |
+
class Joiner(nn.Sequential):
|
| 147 |
+
def __init__(self, backbone, position_embedding):
|
| 148 |
+
super().__init__(backbone, position_embedding)
|
| 149 |
+
|
| 150 |
+
def forward(self, tensor_list: NestedTensor):
|
| 151 |
+
xs = self[0](tensor_list)
|
| 152 |
+
out: List[NestedTensor] = []
|
| 153 |
+
pos = []
|
| 154 |
+
for name, x in xs.items():
|
| 155 |
+
out.append(x)
|
| 156 |
+
# position encoding
|
| 157 |
+
pos.append(self[1](x).to(x.tensors.dtype))
|
| 158 |
+
|
| 159 |
+
return out, pos
|
| 160 |
+
|
| 161 |
+
|
| 162 |
+
def build_backbone(args):
|
| 163 |
+
"""
|
| 164 |
+
Useful args:
|
| 165 |
+
- backbone: backbone name
|
| 166 |
+
- lr_backbone:
|
| 167 |
+
- dilation
|
| 168 |
+
- return_interm_indices: available: [0,1,2,3], [1,2,3], [3]
|
| 169 |
+
- backbone_freeze_keywords:
|
| 170 |
+
- use_checkpoint: for swin only for now
|
| 171 |
+
|
| 172 |
+
"""
|
| 173 |
+
position_embedding = build_position_encoding(args)
|
| 174 |
+
train_backbone = True
|
| 175 |
+
if not train_backbone:
|
| 176 |
+
raise ValueError("Please set lr_backbone > 0")
|
| 177 |
+
return_interm_indices = args.return_interm_indices
|
| 178 |
+
assert return_interm_indices in [[0, 1, 2, 3], [1, 2, 3], [3]]
|
| 179 |
+
args.backbone_freeze_keywords
|
| 180 |
+
use_checkpoint = getattr(args, "use_checkpoint", False)
|
| 181 |
+
|
| 182 |
+
if args.backbone in ["resnet50", "resnet101"]:
|
| 183 |
+
backbone = Backbone(
|
| 184 |
+
args.backbone,
|
| 185 |
+
train_backbone,
|
| 186 |
+
args.dilation,
|
| 187 |
+
return_interm_indices,
|
| 188 |
+
batch_norm=FrozenBatchNorm2d,
|
| 189 |
+
)
|
| 190 |
+
bb_num_channels = backbone.num_channels
|
| 191 |
+
elif args.backbone in [
|
| 192 |
+
"swin_T_224_1k",
|
| 193 |
+
"swin_B_224_22k",
|
| 194 |
+
"swin_B_384_22k",
|
| 195 |
+
"swin_L_224_22k",
|
| 196 |
+
"swin_L_384_22k",
|
| 197 |
+
]:
|
| 198 |
+
pretrain_img_size = int(args.backbone.split("_")[-2])
|
| 199 |
+
backbone = build_swin_transformer(
|
| 200 |
+
args.backbone,
|
| 201 |
+
pretrain_img_size=pretrain_img_size,
|
| 202 |
+
out_indices=tuple(return_interm_indices),
|
| 203 |
+
dilation=False,
|
| 204 |
+
use_checkpoint=use_checkpoint,
|
| 205 |
+
)
|
| 206 |
+
|
| 207 |
+
bb_num_channels = backbone.num_features[4 - len(return_interm_indices) :]
|
| 208 |
+
else:
|
| 209 |
+
raise NotImplementedError("Unknown backbone {}".format(args.backbone))
|
| 210 |
+
|
| 211 |
+
assert len(bb_num_channels) == len(
|
| 212 |
+
return_interm_indices
|
| 213 |
+
), f"len(bb_num_channels) {len(bb_num_channels)} != len(return_interm_indices) {len(return_interm_indices)}"
|
| 214 |
+
|
| 215 |
+
model = Joiner(backbone, position_embedding)
|
| 216 |
+
model.num_channels = bb_num_channels
|
| 217 |
+
assert isinstance(
|
| 218 |
+
bb_num_channels, List
|
| 219 |
+
), "bb_num_channels is expected to be a List but {}".format(type(bb_num_channels))
|
| 220 |
+
# import ipdb; ipdb.set_trace()
|
| 221 |
+
return model
|
One-to-All-Animation/benchmark/DisCo/annotator/grounded-sam/GroundingDINO/groundingdino/models/GroundingDINO/backbone/position_encoding.py
ADDED
|
@@ -0,0 +1,186 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
# ------------------------------------------------------------------------
|
| 2 |
+
# Grounding DINO
|
| 3 |
+
# url: https://github.com/IDEA-Research/GroundingDINO
|
| 4 |
+
# Copyright (c) 2023 IDEA. All Rights Reserved.
|
| 5 |
+
# Licensed under the Apache License, Version 2.0 [see LICENSE for details]
|
| 6 |
+
# ------------------------------------------------------------------------
|
| 7 |
+
# DINO
|
| 8 |
+
# Copyright (c) 2022 IDEA. All Rights Reserved.
|
| 9 |
+
# Licensed under the Apache License, Version 2.0 [see LICENSE for details]
|
| 10 |
+
# ------------------------------------------------------------------------
|
| 11 |
+
# Conditional DETR
|
| 12 |
+
# Copyright (c) 2021 Microsoft. All Rights Reserved.
|
| 13 |
+
# Licensed under the Apache License, Version 2.0 [see LICENSE for details]
|
| 14 |
+
# ------------------------------------------------------------------------
|
| 15 |
+
# Copied from DETR (https://github.com/facebookresearch/detr)
|
| 16 |
+
# Copyright (c) Facebook, Inc. and its affiliates. All Rights Reserved.
|
| 17 |
+
# ------------------------------------------------------------------------
|
| 18 |
+
|
| 19 |
+
"""
|
| 20 |
+
Various positional encodings for the transformer.
|
| 21 |
+
"""
|
| 22 |
+
import math
|
| 23 |
+
|
| 24 |
+
import torch
|
| 25 |
+
from torch import nn
|
| 26 |
+
|
| 27 |
+
from groundingdino.util.misc import NestedTensor
|
| 28 |
+
|
| 29 |
+
|
| 30 |
+
class PositionEmbeddingSine(nn.Module):
|
| 31 |
+
"""
|
| 32 |
+
This is a more standard version of the position embedding, very similar to the one
|
| 33 |
+
used by the Attention is all you need paper, generalized to work on images.
|
| 34 |
+
"""
|
| 35 |
+
|
| 36 |
+
def __init__(self, num_pos_feats=64, temperature=10000, normalize=False, scale=None):
|
| 37 |
+
super().__init__()
|
| 38 |
+
self.num_pos_feats = num_pos_feats
|
| 39 |
+
self.temperature = temperature
|
| 40 |
+
self.normalize = normalize
|
| 41 |
+
if scale is not None and normalize is False:
|
| 42 |
+
raise ValueError("normalize should be True if scale is passed")
|
| 43 |
+
if scale is None:
|
| 44 |
+
scale = 2 * math.pi
|
| 45 |
+
self.scale = scale
|
| 46 |
+
|
| 47 |
+
def forward(self, tensor_list: NestedTensor):
|
| 48 |
+
x = tensor_list.tensors
|
| 49 |
+
mask = tensor_list.mask
|
| 50 |
+
assert mask is not None
|
| 51 |
+
not_mask = ~mask
|
| 52 |
+
y_embed = not_mask.cumsum(1, dtype=torch.float32)
|
| 53 |
+
x_embed = not_mask.cumsum(2, dtype=torch.float32)
|
| 54 |
+
if self.normalize:
|
| 55 |
+
eps = 1e-6
|
| 56 |
+
# if os.environ.get("SHILONG_AMP", None) == '1':
|
| 57 |
+
# eps = 1e-4
|
| 58 |
+
# else:
|
| 59 |
+
# eps = 1e-6
|
| 60 |
+
y_embed = y_embed / (y_embed[:, -1:, :] + eps) * self.scale
|
| 61 |
+
x_embed = x_embed / (x_embed[:, :, -1:] + eps) * self.scale
|
| 62 |
+
|
| 63 |
+
dim_t = torch.arange(self.num_pos_feats, dtype=torch.float32, device=x.device)
|
| 64 |
+
dim_t = self.temperature ** (2 * (dim_t // 2) / self.num_pos_feats)
|
| 65 |
+
|
| 66 |
+
pos_x = x_embed[:, :, :, None] / dim_t
|
| 67 |
+
pos_y = y_embed[:, :, :, None] / dim_t
|
| 68 |
+
pos_x = torch.stack(
|
| 69 |
+
(pos_x[:, :, :, 0::2].sin(), pos_x[:, :, :, 1::2].cos()), dim=4
|
| 70 |
+
).flatten(3)
|
| 71 |
+
pos_y = torch.stack(
|
| 72 |
+
(pos_y[:, :, :, 0::2].sin(), pos_y[:, :, :, 1::2].cos()), dim=4
|
| 73 |
+
).flatten(3)
|
| 74 |
+
pos = torch.cat((pos_y, pos_x), dim=3).permute(0, 3, 1, 2)
|
| 75 |
+
return pos
|
| 76 |
+
|
| 77 |
+
|
| 78 |
+
class PositionEmbeddingSineHW(nn.Module):
|
| 79 |
+
"""
|
| 80 |
+
This is a more standard version of the position embedding, very similar to the one
|
| 81 |
+
used by the Attention is all you need paper, generalized to work on images.
|
| 82 |
+
"""
|
| 83 |
+
|
| 84 |
+
def __init__(
|
| 85 |
+
self, num_pos_feats=64, temperatureH=10000, temperatureW=10000, normalize=False, scale=None
|
| 86 |
+
):
|
| 87 |
+
super().__init__()
|
| 88 |
+
self.num_pos_feats = num_pos_feats
|
| 89 |
+
self.temperatureH = temperatureH
|
| 90 |
+
self.temperatureW = temperatureW
|
| 91 |
+
self.normalize = normalize
|
| 92 |
+
if scale is not None and normalize is False:
|
| 93 |
+
raise ValueError("normalize should be True if scale is passed")
|
| 94 |
+
if scale is None:
|
| 95 |
+
scale = 2 * math.pi
|
| 96 |
+
self.scale = scale
|
| 97 |
+
|
| 98 |
+
def forward(self, tensor_list: NestedTensor):
|
| 99 |
+
x = tensor_list.tensors
|
| 100 |
+
mask = tensor_list.mask
|
| 101 |
+
assert mask is not None
|
| 102 |
+
not_mask = ~mask
|
| 103 |
+
y_embed = not_mask.cumsum(1, dtype=torch.float32)
|
| 104 |
+
x_embed = not_mask.cumsum(2, dtype=torch.float32)
|
| 105 |
+
|
| 106 |
+
# import ipdb; ipdb.set_trace()
|
| 107 |
+
|
| 108 |
+
if self.normalize:
|
| 109 |
+
eps = 1e-6
|
| 110 |
+
y_embed = y_embed / (y_embed[:, -1:, :] + eps) * self.scale
|
| 111 |
+
x_embed = x_embed / (x_embed[:, :, -1:] + eps) * self.scale
|
| 112 |
+
|
| 113 |
+
dim_tx = torch.arange(self.num_pos_feats, dtype=torch.float32, device=x.device)
|
| 114 |
+
dim_tx = self.temperatureW ** (2 * (torch.div(dim_tx, 2, rounding_mode='floor')) / self.num_pos_feats)
|
| 115 |
+
pos_x = x_embed[:, :, :, None] / dim_tx
|
| 116 |
+
|
| 117 |
+
dim_ty = torch.arange(self.num_pos_feats, dtype=torch.float32, device=x.device)
|
| 118 |
+
dim_ty = self.temperatureH ** (2 * (torch.div(dim_ty, 2, rounding_mode='floor')) / self.num_pos_feats)
|
| 119 |
+
pos_y = y_embed[:, :, :, None] / dim_ty
|
| 120 |
+
|
| 121 |
+
pos_x = torch.stack(
|
| 122 |
+
(pos_x[:, :, :, 0::2].sin(), pos_x[:, :, :, 1::2].cos()), dim=4
|
| 123 |
+
).flatten(3)
|
| 124 |
+
pos_y = torch.stack(
|
| 125 |
+
(pos_y[:, :, :, 0::2].sin(), pos_y[:, :, :, 1::2].cos()), dim=4
|
| 126 |
+
).flatten(3)
|
| 127 |
+
pos = torch.cat((pos_y, pos_x), dim=3).permute(0, 3, 1, 2)
|
| 128 |
+
|
| 129 |
+
# import ipdb; ipdb.set_trace()
|
| 130 |
+
|
| 131 |
+
return pos
|
| 132 |
+
|
| 133 |
+
|
| 134 |
+
class PositionEmbeddingLearned(nn.Module):
|
| 135 |
+
"""
|
| 136 |
+
Absolute pos embedding, learned.
|
| 137 |
+
"""
|
| 138 |
+
|
| 139 |
+
def __init__(self, num_pos_feats=256):
|
| 140 |
+
super().__init__()
|
| 141 |
+
self.row_embed = nn.Embedding(50, num_pos_feats)
|
| 142 |
+
self.col_embed = nn.Embedding(50, num_pos_feats)
|
| 143 |
+
self.reset_parameters()
|
| 144 |
+
|
| 145 |
+
def reset_parameters(self):
|
| 146 |
+
nn.init.uniform_(self.row_embed.weight)
|
| 147 |
+
nn.init.uniform_(self.col_embed.weight)
|
| 148 |
+
|
| 149 |
+
def forward(self, tensor_list: NestedTensor):
|
| 150 |
+
x = tensor_list.tensors
|
| 151 |
+
h, w = x.shape[-2:]
|
| 152 |
+
i = torch.arange(w, device=x.device)
|
| 153 |
+
j = torch.arange(h, device=x.device)
|
| 154 |
+
x_emb = self.col_embed(i)
|
| 155 |
+
y_emb = self.row_embed(j)
|
| 156 |
+
pos = (
|
| 157 |
+
torch.cat(
|
| 158 |
+
[
|
| 159 |
+
x_emb.unsqueeze(0).repeat(h, 1, 1),
|
| 160 |
+
y_emb.unsqueeze(1).repeat(1, w, 1),
|
| 161 |
+
],
|
| 162 |
+
dim=-1,
|
| 163 |
+
)
|
| 164 |
+
.permute(2, 0, 1)
|
| 165 |
+
.unsqueeze(0)
|
| 166 |
+
.repeat(x.shape[0], 1, 1, 1)
|
| 167 |
+
)
|
| 168 |
+
return pos
|
| 169 |
+
|
| 170 |
+
|
| 171 |
+
def build_position_encoding(args):
|
| 172 |
+
N_steps = args.hidden_dim // 2
|
| 173 |
+
if args.position_embedding in ("v2", "sine"):
|
| 174 |
+
# TODO find a better way of exposing other arguments
|
| 175 |
+
position_embedding = PositionEmbeddingSineHW(
|
| 176 |
+
N_steps,
|
| 177 |
+
temperatureH=args.pe_temperatureH,
|
| 178 |
+
temperatureW=args.pe_temperatureW,
|
| 179 |
+
normalize=True,
|
| 180 |
+
)
|
| 181 |
+
elif args.position_embedding in ("v3", "learned"):
|
| 182 |
+
position_embedding = PositionEmbeddingLearned(N_steps)
|
| 183 |
+
else:
|
| 184 |
+
raise ValueError(f"not supported {args.position_embedding}")
|
| 185 |
+
|
| 186 |
+
return position_embedding
|
One-to-All-Animation/benchmark/DisCo/annotator/grounded-sam/GroundingDINO/groundingdino/models/GroundingDINO/backbone/swin_transformer.py
ADDED
|
@@ -0,0 +1,802 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
# ------------------------------------------------------------------------
|
| 2 |
+
# Grounding DINO
|
| 3 |
+
# url: https://github.com/IDEA-Research/GroundingDINO
|
| 4 |
+
# Copyright (c) 2023 IDEA. All Rights Reserved.
|
| 5 |
+
# Licensed under the Apache License, Version 2.0 [see LICENSE for details]
|
| 6 |
+
# ------------------------------------------------------------------------
|
| 7 |
+
# DINO
|
| 8 |
+
# Copyright (c) 2022 IDEA. All Rights Reserved.
|
| 9 |
+
# Licensed under the Apache License, Version 2.0 [see LICENSE for details]
|
| 10 |
+
# --------------------------------------------------------
|
| 11 |
+
# modified from https://github.com/SwinTransformer/Swin-Transformer-Object-Detection/blob/master/mmdet/models/backbones/swin_transformer.py
|
| 12 |
+
# --------------------------------------------------------
|
| 13 |
+
|
| 14 |
+
import numpy as np
|
| 15 |
+
import torch
|
| 16 |
+
import torch.nn as nn
|
| 17 |
+
import torch.nn.functional as F
|
| 18 |
+
import torch.utils.checkpoint as checkpoint
|
| 19 |
+
from timm.models.layers import DropPath, to_2tuple, trunc_normal_
|
| 20 |
+
|
| 21 |
+
from groundingdino.util.misc import NestedTensor
|
| 22 |
+
|
| 23 |
+
|
| 24 |
+
class Mlp(nn.Module):
|
| 25 |
+
"""Multilayer perceptron."""
|
| 26 |
+
|
| 27 |
+
def __init__(
|
| 28 |
+
self, in_features, hidden_features=None, out_features=None, act_layer=nn.GELU, drop=0.0
|
| 29 |
+
):
|
| 30 |
+
super().__init__()
|
| 31 |
+
out_features = out_features or in_features
|
| 32 |
+
hidden_features = hidden_features or in_features
|
| 33 |
+
self.fc1 = nn.Linear(in_features, hidden_features)
|
| 34 |
+
self.act = act_layer()
|
| 35 |
+
self.fc2 = nn.Linear(hidden_features, out_features)
|
| 36 |
+
self.drop = nn.Dropout(drop)
|
| 37 |
+
|
| 38 |
+
def forward(self, x):
|
| 39 |
+
x = self.fc1(x)
|
| 40 |
+
x = self.act(x)
|
| 41 |
+
x = self.drop(x)
|
| 42 |
+
x = self.fc2(x)
|
| 43 |
+
x = self.drop(x)
|
| 44 |
+
return x
|
| 45 |
+
|
| 46 |
+
|
| 47 |
+
def window_partition(x, window_size):
|
| 48 |
+
"""
|
| 49 |
+
Args:
|
| 50 |
+
x: (B, H, W, C)
|
| 51 |
+
window_size (int): window size
|
| 52 |
+
Returns:
|
| 53 |
+
windows: (num_windows*B, window_size, window_size, C)
|
| 54 |
+
"""
|
| 55 |
+
B, H, W, C = x.shape
|
| 56 |
+
x = x.view(B, H // window_size, window_size, W // window_size, window_size, C)
|
| 57 |
+
windows = x.permute(0, 1, 3, 2, 4, 5).contiguous().view(-1, window_size, window_size, C)
|
| 58 |
+
return windows
|
| 59 |
+
|
| 60 |
+
|
| 61 |
+
def window_reverse(windows, window_size, H, W):
|
| 62 |
+
"""
|
| 63 |
+
Args:
|
| 64 |
+
windows: (num_windows*B, window_size, window_size, C)
|
| 65 |
+
window_size (int): Window size
|
| 66 |
+
H (int): Height of image
|
| 67 |
+
W (int): Width of image
|
| 68 |
+
Returns:
|
| 69 |
+
x: (B, H, W, C)
|
| 70 |
+
"""
|
| 71 |
+
B = int(windows.shape[0] / (H * W / window_size / window_size))
|
| 72 |
+
x = windows.view(B, H // window_size, W // window_size, window_size, window_size, -1)
|
| 73 |
+
x = x.permute(0, 1, 3, 2, 4, 5).contiguous().view(B, H, W, -1)
|
| 74 |
+
return x
|
| 75 |
+
|
| 76 |
+
|
| 77 |
+
class WindowAttention(nn.Module):
|
| 78 |
+
"""Window based multi-head self attention (W-MSA) module with relative position bias.
|
| 79 |
+
It supports both of shifted and non-shifted window.
|
| 80 |
+
Args:
|
| 81 |
+
dim (int): Number of input channels.
|
| 82 |
+
window_size (tuple[int]): The height and width of the window.
|
| 83 |
+
num_heads (int): Number of attention heads.
|
| 84 |
+
qkv_bias (bool, optional): If True, add a learnable bias to query, key, value. Default: True
|
| 85 |
+
qk_scale (float | None, optional): Override default qk scale of head_dim ** -0.5 if set
|
| 86 |
+
attn_drop (float, optional): Dropout ratio of attention weight. Default: 0.0
|
| 87 |
+
proj_drop (float, optional): Dropout ratio of output. Default: 0.0
|
| 88 |
+
"""
|
| 89 |
+
|
| 90 |
+
def __init__(
|
| 91 |
+
self,
|
| 92 |
+
dim,
|
| 93 |
+
window_size,
|
| 94 |
+
num_heads,
|
| 95 |
+
qkv_bias=True,
|
| 96 |
+
qk_scale=None,
|
| 97 |
+
attn_drop=0.0,
|
| 98 |
+
proj_drop=0.0,
|
| 99 |
+
):
|
| 100 |
+
|
| 101 |
+
super().__init__()
|
| 102 |
+
self.dim = dim
|
| 103 |
+
self.window_size = window_size # Wh, Ww
|
| 104 |
+
self.num_heads = num_heads
|
| 105 |
+
head_dim = dim // num_heads
|
| 106 |
+
self.scale = qk_scale or head_dim**-0.5
|
| 107 |
+
|
| 108 |
+
# define a parameter table of relative position bias
|
| 109 |
+
self.relative_position_bias_table = nn.Parameter(
|
| 110 |
+
torch.zeros((2 * window_size[0] - 1) * (2 * window_size[1] - 1), num_heads)
|
| 111 |
+
) # 2*Wh-1 * 2*Ww-1, nH
|
| 112 |
+
|
| 113 |
+
# get pair-wise relative position index for each token inside the window
|
| 114 |
+
coords_h = torch.arange(self.window_size[0])
|
| 115 |
+
coords_w = torch.arange(self.window_size[1])
|
| 116 |
+
coords = torch.stack(torch.meshgrid([coords_h, coords_w])) # 2, Wh, Ww
|
| 117 |
+
coords_flatten = torch.flatten(coords, 1) # 2, Wh*Ww
|
| 118 |
+
relative_coords = coords_flatten[:, :, None] - coords_flatten[:, None, :] # 2, Wh*Ww, Wh*Ww
|
| 119 |
+
relative_coords = relative_coords.permute(1, 2, 0).contiguous() # Wh*Ww, Wh*Ww, 2
|
| 120 |
+
relative_coords[:, :, 0] += self.window_size[0] - 1 # shift to start from 0
|
| 121 |
+
relative_coords[:, :, 1] += self.window_size[1] - 1
|
| 122 |
+
relative_coords[:, :, 0] *= 2 * self.window_size[1] - 1
|
| 123 |
+
relative_position_index = relative_coords.sum(-1) # Wh*Ww, Wh*Ww
|
| 124 |
+
self.register_buffer("relative_position_index", relative_position_index)
|
| 125 |
+
|
| 126 |
+
self.qkv = nn.Linear(dim, dim * 3, bias=qkv_bias)
|
| 127 |
+
self.attn_drop = nn.Dropout(attn_drop)
|
| 128 |
+
self.proj = nn.Linear(dim, dim)
|
| 129 |
+
self.proj_drop = nn.Dropout(proj_drop)
|
| 130 |
+
|
| 131 |
+
trunc_normal_(self.relative_position_bias_table, std=0.02)
|
| 132 |
+
self.softmax = nn.Softmax(dim=-1)
|
| 133 |
+
|
| 134 |
+
def forward(self, x, mask=None):
|
| 135 |
+
"""Forward function.
|
| 136 |
+
Args:
|
| 137 |
+
x: input features with shape of (num_windows*B, N, C)
|
| 138 |
+
mask: (0/-inf) mask with shape of (num_windows, Wh*Ww, Wh*Ww) or None
|
| 139 |
+
"""
|
| 140 |
+
B_, N, C = x.shape
|
| 141 |
+
qkv = (
|
| 142 |
+
self.qkv(x)
|
| 143 |
+
.reshape(B_, N, 3, self.num_heads, C // self.num_heads)
|
| 144 |
+
.permute(2, 0, 3, 1, 4)
|
| 145 |
+
)
|
| 146 |
+
q, k, v = qkv[0], qkv[1], qkv[2] # make torchscript happy (cannot use tensor as tuple)
|
| 147 |
+
|
| 148 |
+
q = q * self.scale
|
| 149 |
+
attn = q @ k.transpose(-2, -1)
|
| 150 |
+
|
| 151 |
+
relative_position_bias = self.relative_position_bias_table[
|
| 152 |
+
self.relative_position_index.view(-1)
|
| 153 |
+
].view(
|
| 154 |
+
self.window_size[0] * self.window_size[1], self.window_size[0] * self.window_size[1], -1
|
| 155 |
+
) # Wh*Ww,Wh*Ww,nH
|
| 156 |
+
relative_position_bias = relative_position_bias.permute(
|
| 157 |
+
2, 0, 1
|
| 158 |
+
).contiguous() # nH, Wh*Ww, Wh*Ww
|
| 159 |
+
attn = attn + relative_position_bias.unsqueeze(0)
|
| 160 |
+
|
| 161 |
+
if mask is not None:
|
| 162 |
+
nW = mask.shape[0]
|
| 163 |
+
attn = attn.view(B_ // nW, nW, self.num_heads, N, N) + mask.unsqueeze(1).unsqueeze(0)
|
| 164 |
+
attn = attn.view(-1, self.num_heads, N, N)
|
| 165 |
+
attn = self.softmax(attn)
|
| 166 |
+
else:
|
| 167 |
+
attn = self.softmax(attn)
|
| 168 |
+
|
| 169 |
+
attn = self.attn_drop(attn)
|
| 170 |
+
|
| 171 |
+
x = (attn @ v).transpose(1, 2).reshape(B_, N, C)
|
| 172 |
+
x = self.proj(x)
|
| 173 |
+
x = self.proj_drop(x)
|
| 174 |
+
return x
|
| 175 |
+
|
| 176 |
+
|
| 177 |
+
class SwinTransformerBlock(nn.Module):
|
| 178 |
+
"""Swin Transformer Block.
|
| 179 |
+
Args:
|
| 180 |
+
dim (int): Number of input channels.
|
| 181 |
+
num_heads (int): Number of attention heads.
|
| 182 |
+
window_size (int): Window size.
|
| 183 |
+
shift_size (int): Shift size for SW-MSA.
|
| 184 |
+
mlp_ratio (float): Ratio of mlp hidden dim to embedding dim.
|
| 185 |
+
qkv_bias (bool, optional): If True, add a learnable bias to query, key, value. Default: True
|
| 186 |
+
qk_scale (float | None, optional): Override default qk scale of head_dim ** -0.5 if set.
|
| 187 |
+
drop (float, optional): Dropout rate. Default: 0.0
|
| 188 |
+
attn_drop (float, optional): Attention dropout rate. Default: 0.0
|
| 189 |
+
drop_path (float, optional): Stochastic depth rate. Default: 0.0
|
| 190 |
+
act_layer (nn.Module, optional): Activation layer. Default: nn.GELU
|
| 191 |
+
norm_layer (nn.Module, optional): Normalization layer. Default: nn.LayerNorm
|
| 192 |
+
"""
|
| 193 |
+
|
| 194 |
+
def __init__(
|
| 195 |
+
self,
|
| 196 |
+
dim,
|
| 197 |
+
num_heads,
|
| 198 |
+
window_size=7,
|
| 199 |
+
shift_size=0,
|
| 200 |
+
mlp_ratio=4.0,
|
| 201 |
+
qkv_bias=True,
|
| 202 |
+
qk_scale=None,
|
| 203 |
+
drop=0.0,
|
| 204 |
+
attn_drop=0.0,
|
| 205 |
+
drop_path=0.0,
|
| 206 |
+
act_layer=nn.GELU,
|
| 207 |
+
norm_layer=nn.LayerNorm,
|
| 208 |
+
):
|
| 209 |
+
super().__init__()
|
| 210 |
+
self.dim = dim
|
| 211 |
+
self.num_heads = num_heads
|
| 212 |
+
self.window_size = window_size
|
| 213 |
+
self.shift_size = shift_size
|
| 214 |
+
self.mlp_ratio = mlp_ratio
|
| 215 |
+
assert 0 <= self.shift_size < self.window_size, "shift_size must in 0-window_size"
|
| 216 |
+
|
| 217 |
+
self.norm1 = norm_layer(dim)
|
| 218 |
+
self.attn = WindowAttention(
|
| 219 |
+
dim,
|
| 220 |
+
window_size=to_2tuple(self.window_size),
|
| 221 |
+
num_heads=num_heads,
|
| 222 |
+
qkv_bias=qkv_bias,
|
| 223 |
+
qk_scale=qk_scale,
|
| 224 |
+
attn_drop=attn_drop,
|
| 225 |
+
proj_drop=drop,
|
| 226 |
+
)
|
| 227 |
+
|
| 228 |
+
self.drop_path = DropPath(drop_path) if drop_path > 0.0 else nn.Identity()
|
| 229 |
+
self.norm2 = norm_layer(dim)
|
| 230 |
+
mlp_hidden_dim = int(dim * mlp_ratio)
|
| 231 |
+
self.mlp = Mlp(
|
| 232 |
+
in_features=dim, hidden_features=mlp_hidden_dim, act_layer=act_layer, drop=drop
|
| 233 |
+
)
|
| 234 |
+
|
| 235 |
+
self.H = None
|
| 236 |
+
self.W = None
|
| 237 |
+
|
| 238 |
+
def forward(self, x, mask_matrix):
|
| 239 |
+
"""Forward function.
|
| 240 |
+
Args:
|
| 241 |
+
x: Input feature, tensor size (B, H*W, C).
|
| 242 |
+
H, W: Spatial resolution of the input feature.
|
| 243 |
+
mask_matrix: Attention mask for cyclic shift.
|
| 244 |
+
"""
|
| 245 |
+
B, L, C = x.shape
|
| 246 |
+
H, W = self.H, self.W
|
| 247 |
+
assert L == H * W, "input feature has wrong size"
|
| 248 |
+
|
| 249 |
+
shortcut = x
|
| 250 |
+
x = self.norm1(x)
|
| 251 |
+
x = x.view(B, H, W, C)
|
| 252 |
+
|
| 253 |
+
# pad feature maps to multiples of window size
|
| 254 |
+
pad_l = pad_t = 0
|
| 255 |
+
pad_r = (self.window_size - W % self.window_size) % self.window_size
|
| 256 |
+
pad_b = (self.window_size - H % self.window_size) % self.window_size
|
| 257 |
+
x = F.pad(x, (0, 0, pad_l, pad_r, pad_t, pad_b))
|
| 258 |
+
_, Hp, Wp, _ = x.shape
|
| 259 |
+
|
| 260 |
+
# cyclic shift
|
| 261 |
+
if self.shift_size > 0:
|
| 262 |
+
shifted_x = torch.roll(x, shifts=(-self.shift_size, -self.shift_size), dims=(1, 2))
|
| 263 |
+
attn_mask = mask_matrix
|
| 264 |
+
else:
|
| 265 |
+
shifted_x = x
|
| 266 |
+
attn_mask = None
|
| 267 |
+
|
| 268 |
+
# partition windows
|
| 269 |
+
x_windows = window_partition(
|
| 270 |
+
shifted_x, self.window_size
|
| 271 |
+
) # nW*B, window_size, window_size, C
|
| 272 |
+
x_windows = x_windows.view(
|
| 273 |
+
-1, self.window_size * self.window_size, C
|
| 274 |
+
) # nW*B, window_size*window_size, C
|
| 275 |
+
|
| 276 |
+
# W-MSA/SW-MSA
|
| 277 |
+
attn_windows = self.attn(x_windows, mask=attn_mask) # nW*B, window_size*window_size, C
|
| 278 |
+
|
| 279 |
+
# merge windows
|
| 280 |
+
attn_windows = attn_windows.view(-1, self.window_size, self.window_size, C)
|
| 281 |
+
shifted_x = window_reverse(attn_windows, self.window_size, Hp, Wp) # B H' W' C
|
| 282 |
+
|
| 283 |
+
# reverse cyclic shift
|
| 284 |
+
if self.shift_size > 0:
|
| 285 |
+
x = torch.roll(shifted_x, shifts=(self.shift_size, self.shift_size), dims=(1, 2))
|
| 286 |
+
else:
|
| 287 |
+
x = shifted_x
|
| 288 |
+
|
| 289 |
+
if pad_r > 0 or pad_b > 0:
|
| 290 |
+
x = x[:, :H, :W, :].contiguous()
|
| 291 |
+
|
| 292 |
+
x = x.view(B, H * W, C)
|
| 293 |
+
|
| 294 |
+
# FFN
|
| 295 |
+
x = shortcut + self.drop_path(x)
|
| 296 |
+
x = x + self.drop_path(self.mlp(self.norm2(x)))
|
| 297 |
+
|
| 298 |
+
return x
|
| 299 |
+
|
| 300 |
+
|
| 301 |
+
class PatchMerging(nn.Module):
|
| 302 |
+
"""Patch Merging Layer
|
| 303 |
+
Args:
|
| 304 |
+
dim (int): Number of input channels.
|
| 305 |
+
norm_layer (nn.Module, optional): Normalization layer. Default: nn.LayerNorm
|
| 306 |
+
"""
|
| 307 |
+
|
| 308 |
+
def __init__(self, dim, norm_layer=nn.LayerNorm):
|
| 309 |
+
super().__init__()
|
| 310 |
+
self.dim = dim
|
| 311 |
+
self.reduction = nn.Linear(4 * dim, 2 * dim, bias=False)
|
| 312 |
+
self.norm = norm_layer(4 * dim)
|
| 313 |
+
|
| 314 |
+
def forward(self, x, H, W):
|
| 315 |
+
"""Forward function.
|
| 316 |
+
Args:
|
| 317 |
+
x: Input feature, tensor size (B, H*W, C).
|
| 318 |
+
H, W: Spatial resolution of the input feature.
|
| 319 |
+
"""
|
| 320 |
+
B, L, C = x.shape
|
| 321 |
+
assert L == H * W, "input feature has wrong size"
|
| 322 |
+
|
| 323 |
+
x = x.view(B, H, W, C)
|
| 324 |
+
|
| 325 |
+
# padding
|
| 326 |
+
pad_input = (H % 2 == 1) or (W % 2 == 1)
|
| 327 |
+
if pad_input:
|
| 328 |
+
x = F.pad(x, (0, 0, 0, W % 2, 0, H % 2))
|
| 329 |
+
|
| 330 |
+
x0 = x[:, 0::2, 0::2, :] # B H/2 W/2 C
|
| 331 |
+
x1 = x[:, 1::2, 0::2, :] # B H/2 W/2 C
|
| 332 |
+
x2 = x[:, 0::2, 1::2, :] # B H/2 W/2 C
|
| 333 |
+
x3 = x[:, 1::2, 1::2, :] # B H/2 W/2 C
|
| 334 |
+
x = torch.cat([x0, x1, x2, x3], -1) # B H/2 W/2 4*C
|
| 335 |
+
x = x.view(B, -1, 4 * C) # B H/2*W/2 4*C
|
| 336 |
+
|
| 337 |
+
x = self.norm(x)
|
| 338 |
+
x = self.reduction(x)
|
| 339 |
+
|
| 340 |
+
return x
|
| 341 |
+
|
| 342 |
+
|
| 343 |
+
class BasicLayer(nn.Module):
|
| 344 |
+
"""A basic Swin Transformer layer for one stage.
|
| 345 |
+
Args:
|
| 346 |
+
dim (int): Number of feature channels
|
| 347 |
+
depth (int): Depths of this stage.
|
| 348 |
+
num_heads (int): Number of attention head.
|
| 349 |
+
window_size (int): Local window size. Default: 7.
|
| 350 |
+
mlp_ratio (float): Ratio of mlp hidden dim to embedding dim. Default: 4.
|
| 351 |
+
qkv_bias (bool, optional): If True, add a learnable bias to query, key, value. Default: True
|
| 352 |
+
qk_scale (float | None, optional): Override default qk scale of head_dim ** -0.5 if set.
|
| 353 |
+
drop (float, optional): Dropout rate. Default: 0.0
|
| 354 |
+
attn_drop (float, optional): Attention dropout rate. Default: 0.0
|
| 355 |
+
drop_path (float | tuple[float], optional): Stochastic depth rate. Default: 0.0
|
| 356 |
+
norm_layer (nn.Module, optional): Normalization layer. Default: nn.LayerNorm
|
| 357 |
+
downsample (nn.Module | None, optional): Downsample layer at the end of the layer. Default: None
|
| 358 |
+
use_checkpoint (bool): Whether to use checkpointing to save memory. Default: False.
|
| 359 |
+
"""
|
| 360 |
+
|
| 361 |
+
def __init__(
|
| 362 |
+
self,
|
| 363 |
+
dim,
|
| 364 |
+
depth,
|
| 365 |
+
num_heads,
|
| 366 |
+
window_size=7,
|
| 367 |
+
mlp_ratio=4.0,
|
| 368 |
+
qkv_bias=True,
|
| 369 |
+
qk_scale=None,
|
| 370 |
+
drop=0.0,
|
| 371 |
+
attn_drop=0.0,
|
| 372 |
+
drop_path=0.0,
|
| 373 |
+
norm_layer=nn.LayerNorm,
|
| 374 |
+
downsample=None,
|
| 375 |
+
use_checkpoint=False,
|
| 376 |
+
):
|
| 377 |
+
super().__init__()
|
| 378 |
+
self.window_size = window_size
|
| 379 |
+
self.shift_size = window_size // 2
|
| 380 |
+
self.depth = depth
|
| 381 |
+
self.use_checkpoint = use_checkpoint
|
| 382 |
+
|
| 383 |
+
# build blocks
|
| 384 |
+
self.blocks = nn.ModuleList(
|
| 385 |
+
[
|
| 386 |
+
SwinTransformerBlock(
|
| 387 |
+
dim=dim,
|
| 388 |
+
num_heads=num_heads,
|
| 389 |
+
window_size=window_size,
|
| 390 |
+
shift_size=0 if (i % 2 == 0) else window_size // 2,
|
| 391 |
+
mlp_ratio=mlp_ratio,
|
| 392 |
+
qkv_bias=qkv_bias,
|
| 393 |
+
qk_scale=qk_scale,
|
| 394 |
+
drop=drop,
|
| 395 |
+
attn_drop=attn_drop,
|
| 396 |
+
drop_path=drop_path[i] if isinstance(drop_path, list) else drop_path,
|
| 397 |
+
norm_layer=norm_layer,
|
| 398 |
+
)
|
| 399 |
+
for i in range(depth)
|
| 400 |
+
]
|
| 401 |
+
)
|
| 402 |
+
|
| 403 |
+
# patch merging layer
|
| 404 |
+
if downsample is not None:
|
| 405 |
+
self.downsample = downsample(dim=dim, norm_layer=norm_layer)
|
| 406 |
+
else:
|
| 407 |
+
self.downsample = None
|
| 408 |
+
|
| 409 |
+
def forward(self, x, H, W):
|
| 410 |
+
"""Forward function.
|
| 411 |
+
Args:
|
| 412 |
+
x: Input feature, tensor size (B, H*W, C).
|
| 413 |
+
H, W: Spatial resolution of the input feature.
|
| 414 |
+
"""
|
| 415 |
+
|
| 416 |
+
# calculate attention mask for SW-MSA
|
| 417 |
+
Hp = int(np.ceil(H / self.window_size)) * self.window_size
|
| 418 |
+
Wp = int(np.ceil(W / self.window_size)) * self.window_size
|
| 419 |
+
img_mask = torch.zeros((1, Hp, Wp, 1), device=x.device) # 1 Hp Wp 1
|
| 420 |
+
h_slices = (
|
| 421 |
+
slice(0, -self.window_size),
|
| 422 |
+
slice(-self.window_size, -self.shift_size),
|
| 423 |
+
slice(-self.shift_size, None),
|
| 424 |
+
)
|
| 425 |
+
w_slices = (
|
| 426 |
+
slice(0, -self.window_size),
|
| 427 |
+
slice(-self.window_size, -self.shift_size),
|
| 428 |
+
slice(-self.shift_size, None),
|
| 429 |
+
)
|
| 430 |
+
cnt = 0
|
| 431 |
+
for h in h_slices:
|
| 432 |
+
for w in w_slices:
|
| 433 |
+
img_mask[:, h, w, :] = cnt
|
| 434 |
+
cnt += 1
|
| 435 |
+
|
| 436 |
+
mask_windows = window_partition(
|
| 437 |
+
img_mask, self.window_size
|
| 438 |
+
) # nW, window_size, window_size, 1
|
| 439 |
+
mask_windows = mask_windows.view(-1, self.window_size * self.window_size)
|
| 440 |
+
attn_mask = mask_windows.unsqueeze(1) - mask_windows.unsqueeze(2)
|
| 441 |
+
attn_mask = attn_mask.masked_fill(attn_mask != 0, float(-100.0)).masked_fill(
|
| 442 |
+
attn_mask == 0, float(0.0)
|
| 443 |
+
)
|
| 444 |
+
|
| 445 |
+
for blk in self.blocks:
|
| 446 |
+
blk.H, blk.W = H, W
|
| 447 |
+
if self.use_checkpoint:
|
| 448 |
+
x = checkpoint.checkpoint(blk, x, attn_mask)
|
| 449 |
+
else:
|
| 450 |
+
x = blk(x, attn_mask)
|
| 451 |
+
if self.downsample is not None:
|
| 452 |
+
x_down = self.downsample(x, H, W)
|
| 453 |
+
Wh, Ww = (H + 1) // 2, (W + 1) // 2
|
| 454 |
+
return x, H, W, x_down, Wh, Ww
|
| 455 |
+
else:
|
| 456 |
+
return x, H, W, x, H, W
|
| 457 |
+
|
| 458 |
+
|
| 459 |
+
class PatchEmbed(nn.Module):
|
| 460 |
+
"""Image to Patch Embedding
|
| 461 |
+
Args:
|
| 462 |
+
patch_size (int): Patch token size. Default: 4.
|
| 463 |
+
in_chans (int): Number of input image channels. Default: 3.
|
| 464 |
+
embed_dim (int): Number of linear projection output channels. Default: 96.
|
| 465 |
+
norm_layer (nn.Module, optional): Normalization layer. Default: None
|
| 466 |
+
"""
|
| 467 |
+
|
| 468 |
+
def __init__(self, patch_size=4, in_chans=3, embed_dim=96, norm_layer=None):
|
| 469 |
+
super().__init__()
|
| 470 |
+
patch_size = to_2tuple(patch_size)
|
| 471 |
+
self.patch_size = patch_size
|
| 472 |
+
|
| 473 |
+
self.in_chans = in_chans
|
| 474 |
+
self.embed_dim = embed_dim
|
| 475 |
+
|
| 476 |
+
self.proj = nn.Conv2d(in_chans, embed_dim, kernel_size=patch_size, stride=patch_size)
|
| 477 |
+
if norm_layer is not None:
|
| 478 |
+
self.norm = norm_layer(embed_dim)
|
| 479 |
+
else:
|
| 480 |
+
self.norm = None
|
| 481 |
+
|
| 482 |
+
def forward(self, x):
|
| 483 |
+
"""Forward function."""
|
| 484 |
+
# padding
|
| 485 |
+
_, _, H, W = x.size()
|
| 486 |
+
if W % self.patch_size[1] != 0:
|
| 487 |
+
x = F.pad(x, (0, self.patch_size[1] - W % self.patch_size[1]))
|
| 488 |
+
if H % self.patch_size[0] != 0:
|
| 489 |
+
x = F.pad(x, (0, 0, 0, self.patch_size[0] - H % self.patch_size[0]))
|
| 490 |
+
|
| 491 |
+
x = self.proj(x) # B C Wh Ww
|
| 492 |
+
if self.norm is not None:
|
| 493 |
+
Wh, Ww = x.size(2), x.size(3)
|
| 494 |
+
x = x.flatten(2).transpose(1, 2)
|
| 495 |
+
x = self.norm(x)
|
| 496 |
+
x = x.transpose(1, 2).view(-1, self.embed_dim, Wh, Ww)
|
| 497 |
+
|
| 498 |
+
return x
|
| 499 |
+
|
| 500 |
+
|
| 501 |
+
class SwinTransformer(nn.Module):
|
| 502 |
+
"""Swin Transformer backbone.
|
| 503 |
+
A PyTorch impl of : `Swin Transformer: Hierarchical Vision Transformer using Shifted Windows` -
|
| 504 |
+
https://arxiv.org/pdf/2103.14030
|
| 505 |
+
Args:
|
| 506 |
+
pretrain_img_size (int): Input image size for training the pretrained model,
|
| 507 |
+
used in absolute postion embedding. Default 224.
|
| 508 |
+
patch_size (int | tuple(int)): Patch size. Default: 4.
|
| 509 |
+
in_chans (int): Number of input image channels. Default: 3.
|
| 510 |
+
embed_dim (int): Number of linear projection output channels. Default: 96.
|
| 511 |
+
depths (tuple[int]): Depths of each Swin Transformer stage.
|
| 512 |
+
num_heads (tuple[int]): Number of attention head of each stage.
|
| 513 |
+
window_size (int): Window size. Default: 7.
|
| 514 |
+
mlp_ratio (float): Ratio of mlp hidden dim to embedding dim. Default: 4.
|
| 515 |
+
qkv_bias (bool): If True, add a learnable bias to query, key, value. Default: True
|
| 516 |
+
qk_scale (float): Override default qk scale of head_dim ** -0.5 if set.
|
| 517 |
+
drop_rate (float): Dropout rate.
|
| 518 |
+
attn_drop_rate (float): Attention dropout rate. Default: 0.
|
| 519 |
+
drop_path_rate (float): Stochastic depth rate. Default: 0.2.
|
| 520 |
+
norm_layer (nn.Module): Normalization layer. Default: nn.LayerNorm.
|
| 521 |
+
ape (bool): If True, add absolute position embedding to the patch embedding. Default: False.
|
| 522 |
+
patch_norm (bool): If True, add normalization after patch embedding. Default: True.
|
| 523 |
+
out_indices (Sequence[int]): Output from which stages.
|
| 524 |
+
frozen_stages (int): Stages to be frozen (stop grad and set eval mode).
|
| 525 |
+
-1 means not freezing any parameters.
|
| 526 |
+
use_checkpoint (bool): Whether to use checkpointing to save memory. Default: False.
|
| 527 |
+
dilation (bool): if True, the output size if 16x downsample, ow 32x downsample.
|
| 528 |
+
"""
|
| 529 |
+
|
| 530 |
+
def __init__(
|
| 531 |
+
self,
|
| 532 |
+
pretrain_img_size=224,
|
| 533 |
+
patch_size=4,
|
| 534 |
+
in_chans=3,
|
| 535 |
+
embed_dim=96,
|
| 536 |
+
depths=[2, 2, 6, 2],
|
| 537 |
+
num_heads=[3, 6, 12, 24],
|
| 538 |
+
window_size=7,
|
| 539 |
+
mlp_ratio=4.0,
|
| 540 |
+
qkv_bias=True,
|
| 541 |
+
qk_scale=None,
|
| 542 |
+
drop_rate=0.0,
|
| 543 |
+
attn_drop_rate=0.0,
|
| 544 |
+
drop_path_rate=0.2,
|
| 545 |
+
norm_layer=nn.LayerNorm,
|
| 546 |
+
ape=False,
|
| 547 |
+
patch_norm=True,
|
| 548 |
+
out_indices=(0, 1, 2, 3),
|
| 549 |
+
frozen_stages=-1,
|
| 550 |
+
dilation=False,
|
| 551 |
+
use_checkpoint=False,
|
| 552 |
+
):
|
| 553 |
+
super().__init__()
|
| 554 |
+
|
| 555 |
+
self.pretrain_img_size = pretrain_img_size
|
| 556 |
+
self.num_layers = len(depths)
|
| 557 |
+
self.embed_dim = embed_dim
|
| 558 |
+
self.ape = ape
|
| 559 |
+
self.patch_norm = patch_norm
|
| 560 |
+
self.out_indices = out_indices
|
| 561 |
+
self.frozen_stages = frozen_stages
|
| 562 |
+
self.dilation = dilation
|
| 563 |
+
|
| 564 |
+
# if use_checkpoint:
|
| 565 |
+
# print("use_checkpoint!!!!!!!!!!!!!!!!!!!!!!!!")
|
| 566 |
+
|
| 567 |
+
# split image into non-overlapping patches
|
| 568 |
+
self.patch_embed = PatchEmbed(
|
| 569 |
+
patch_size=patch_size,
|
| 570 |
+
in_chans=in_chans,
|
| 571 |
+
embed_dim=embed_dim,
|
| 572 |
+
norm_layer=norm_layer if self.patch_norm else None,
|
| 573 |
+
)
|
| 574 |
+
|
| 575 |
+
# absolute position embedding
|
| 576 |
+
if self.ape:
|
| 577 |
+
pretrain_img_size = to_2tuple(pretrain_img_size)
|
| 578 |
+
patch_size = to_2tuple(patch_size)
|
| 579 |
+
patches_resolution = [
|
| 580 |
+
pretrain_img_size[0] // patch_size[0],
|
| 581 |
+
pretrain_img_size[1] // patch_size[1],
|
| 582 |
+
]
|
| 583 |
+
|
| 584 |
+
self.absolute_pos_embed = nn.Parameter(
|
| 585 |
+
torch.zeros(1, embed_dim, patches_resolution[0], patches_resolution[1])
|
| 586 |
+
)
|
| 587 |
+
trunc_normal_(self.absolute_pos_embed, std=0.02)
|
| 588 |
+
|
| 589 |
+
self.pos_drop = nn.Dropout(p=drop_rate)
|
| 590 |
+
|
| 591 |
+
# stochastic depth
|
| 592 |
+
dpr = [
|
| 593 |
+
x.item() for x in torch.linspace(0, drop_path_rate, sum(depths))
|
| 594 |
+
] # stochastic depth decay rule
|
| 595 |
+
|
| 596 |
+
# build layers
|
| 597 |
+
self.layers = nn.ModuleList()
|
| 598 |
+
# prepare downsample list
|
| 599 |
+
downsamplelist = [PatchMerging for i in range(self.num_layers)]
|
| 600 |
+
downsamplelist[-1] = None
|
| 601 |
+
num_features = [int(embed_dim * 2**i) for i in range(self.num_layers)]
|
| 602 |
+
if self.dilation:
|
| 603 |
+
downsamplelist[-2] = None
|
| 604 |
+
num_features[-1] = int(embed_dim * 2 ** (self.num_layers - 1)) // 2
|
| 605 |
+
for i_layer in range(self.num_layers):
|
| 606 |
+
layer = BasicLayer(
|
| 607 |
+
# dim=int(embed_dim * 2 ** i_layer),
|
| 608 |
+
dim=num_features[i_layer],
|
| 609 |
+
depth=depths[i_layer],
|
| 610 |
+
num_heads=num_heads[i_layer],
|
| 611 |
+
window_size=window_size,
|
| 612 |
+
mlp_ratio=mlp_ratio,
|
| 613 |
+
qkv_bias=qkv_bias,
|
| 614 |
+
qk_scale=qk_scale,
|
| 615 |
+
drop=drop_rate,
|
| 616 |
+
attn_drop=attn_drop_rate,
|
| 617 |
+
drop_path=dpr[sum(depths[:i_layer]) : sum(depths[: i_layer + 1])],
|
| 618 |
+
norm_layer=norm_layer,
|
| 619 |
+
# downsample=PatchMerging if (i_layer < self.num_layers - 1) else None,
|
| 620 |
+
downsample=downsamplelist[i_layer],
|
| 621 |
+
use_checkpoint=use_checkpoint,
|
| 622 |
+
)
|
| 623 |
+
self.layers.append(layer)
|
| 624 |
+
|
| 625 |
+
# num_features = [int(embed_dim * 2 ** i) for i in range(self.num_layers)]
|
| 626 |
+
self.num_features = num_features
|
| 627 |
+
|
| 628 |
+
# add a norm layer for each output
|
| 629 |
+
for i_layer in out_indices:
|
| 630 |
+
layer = norm_layer(num_features[i_layer])
|
| 631 |
+
layer_name = f"norm{i_layer}"
|
| 632 |
+
self.add_module(layer_name, layer)
|
| 633 |
+
|
| 634 |
+
self._freeze_stages()
|
| 635 |
+
|
| 636 |
+
def _freeze_stages(self):
|
| 637 |
+
if self.frozen_stages >= 0:
|
| 638 |
+
self.patch_embed.eval()
|
| 639 |
+
for param in self.patch_embed.parameters():
|
| 640 |
+
param.requires_grad = False
|
| 641 |
+
|
| 642 |
+
if self.frozen_stages >= 1 and self.ape:
|
| 643 |
+
self.absolute_pos_embed.requires_grad = False
|
| 644 |
+
|
| 645 |
+
if self.frozen_stages >= 2:
|
| 646 |
+
self.pos_drop.eval()
|
| 647 |
+
for i in range(0, self.frozen_stages - 1):
|
| 648 |
+
m = self.layers[i]
|
| 649 |
+
m.eval()
|
| 650 |
+
for param in m.parameters():
|
| 651 |
+
param.requires_grad = False
|
| 652 |
+
|
| 653 |
+
# def init_weights(self, pretrained=None):
|
| 654 |
+
# """Initialize the weights in backbone.
|
| 655 |
+
# Args:
|
| 656 |
+
# pretrained (str, optional): Path to pre-trained weights.
|
| 657 |
+
# Defaults to None.
|
| 658 |
+
# """
|
| 659 |
+
|
| 660 |
+
# def _init_weights(m):
|
| 661 |
+
# if isinstance(m, nn.Linear):
|
| 662 |
+
# trunc_normal_(m.weight, std=.02)
|
| 663 |
+
# if isinstance(m, nn.Linear) and m.bias is not None:
|
| 664 |
+
# nn.init.constant_(m.bias, 0)
|
| 665 |
+
# elif isinstance(m, nn.LayerNorm):
|
| 666 |
+
# nn.init.constant_(m.bias, 0)
|
| 667 |
+
# nn.init.constant_(m.weight, 1.0)
|
| 668 |
+
|
| 669 |
+
# if isinstance(pretrained, str):
|
| 670 |
+
# self.apply(_init_weights)
|
| 671 |
+
# logger = get_root_logger()
|
| 672 |
+
# load_checkpoint(self, pretrained, strict=False, logger=logger)
|
| 673 |
+
# elif pretrained is None:
|
| 674 |
+
# self.apply(_init_weights)
|
| 675 |
+
# else:
|
| 676 |
+
# raise TypeError('pretrained must be a str or None')
|
| 677 |
+
|
| 678 |
+
def forward_raw(self, x):
|
| 679 |
+
"""Forward function."""
|
| 680 |
+
x = self.patch_embed(x)
|
| 681 |
+
|
| 682 |
+
Wh, Ww = x.size(2), x.size(3)
|
| 683 |
+
if self.ape:
|
| 684 |
+
# interpolate the position embedding to the corresponding size
|
| 685 |
+
absolute_pos_embed = F.interpolate(
|
| 686 |
+
self.absolute_pos_embed, size=(Wh, Ww), mode="bicubic"
|
| 687 |
+
)
|
| 688 |
+
x = (x + absolute_pos_embed).flatten(2).transpose(1, 2) # B Wh*Ww C
|
| 689 |
+
else:
|
| 690 |
+
x = x.flatten(2).transpose(1, 2)
|
| 691 |
+
x = self.pos_drop(x)
|
| 692 |
+
|
| 693 |
+
outs = []
|
| 694 |
+
for i in range(self.num_layers):
|
| 695 |
+
layer = self.layers[i]
|
| 696 |
+
x_out, H, W, x, Wh, Ww = layer(x, Wh, Ww)
|
| 697 |
+
# import ipdb; ipdb.set_trace()
|
| 698 |
+
|
| 699 |
+
if i in self.out_indices:
|
| 700 |
+
norm_layer = getattr(self, f"norm{i}")
|
| 701 |
+
x_out = norm_layer(x_out)
|
| 702 |
+
|
| 703 |
+
out = x_out.view(-1, H, W, self.num_features[i]).permute(0, 3, 1, 2).contiguous()
|
| 704 |
+
outs.append(out)
|
| 705 |
+
# in:
|
| 706 |
+
# torch.Size([2, 3, 1024, 1024])
|
| 707 |
+
# outs:
|
| 708 |
+
# [torch.Size([2, 192, 256, 256]), torch.Size([2, 384, 128, 128]), \
|
| 709 |
+
# torch.Size([2, 768, 64, 64]), torch.Size([2, 1536, 32, 32])]
|
| 710 |
+
return tuple(outs)
|
| 711 |
+
|
| 712 |
+
def forward(self, tensor_list: NestedTensor):
|
| 713 |
+
x = tensor_list.tensors
|
| 714 |
+
|
| 715 |
+
"""Forward function."""
|
| 716 |
+
x = self.patch_embed(x)
|
| 717 |
+
|
| 718 |
+
Wh, Ww = x.size(2), x.size(3)
|
| 719 |
+
if self.ape:
|
| 720 |
+
# interpolate the position embedding to the corresponding size
|
| 721 |
+
absolute_pos_embed = F.interpolate(
|
| 722 |
+
self.absolute_pos_embed, size=(Wh, Ww), mode="bicubic"
|
| 723 |
+
)
|
| 724 |
+
x = (x + absolute_pos_embed).flatten(2).transpose(1, 2) # B Wh*Ww C
|
| 725 |
+
else:
|
| 726 |
+
x = x.flatten(2).transpose(1, 2)
|
| 727 |
+
x = self.pos_drop(x)
|
| 728 |
+
|
| 729 |
+
outs = []
|
| 730 |
+
for i in range(self.num_layers):
|
| 731 |
+
layer = self.layers[i]
|
| 732 |
+
x_out, H, W, x, Wh, Ww = layer(x, Wh, Ww)
|
| 733 |
+
|
| 734 |
+
if i in self.out_indices:
|
| 735 |
+
norm_layer = getattr(self, f"norm{i}")
|
| 736 |
+
x_out = norm_layer(x_out)
|
| 737 |
+
|
| 738 |
+
out = x_out.view(-1, H, W, self.num_features[i]).permute(0, 3, 1, 2).contiguous()
|
| 739 |
+
outs.append(out)
|
| 740 |
+
# in:
|
| 741 |
+
# torch.Size([2, 3, 1024, 1024])
|
| 742 |
+
# out:
|
| 743 |
+
# [torch.Size([2, 192, 256, 256]), torch.Size([2, 384, 128, 128]), \
|
| 744 |
+
# torch.Size([2, 768, 64, 64]), torch.Size([2, 1536, 32, 32])]
|
| 745 |
+
|
| 746 |
+
# collect for nesttensors
|
| 747 |
+
outs_dict = {}
|
| 748 |
+
for idx, out_i in enumerate(outs):
|
| 749 |
+
m = tensor_list.mask
|
| 750 |
+
assert m is not None
|
| 751 |
+
mask = F.interpolate(m[None].float(), size=out_i.shape[-2:]).to(torch.bool)[0]
|
| 752 |
+
outs_dict[idx] = NestedTensor(out_i, mask)
|
| 753 |
+
|
| 754 |
+
return outs_dict
|
| 755 |
+
|
| 756 |
+
def train(self, mode=True):
|
| 757 |
+
"""Convert the model into training mode while keep layers freezed."""
|
| 758 |
+
super(SwinTransformer, self).train(mode)
|
| 759 |
+
self._freeze_stages()
|
| 760 |
+
|
| 761 |
+
|
| 762 |
+
def build_swin_transformer(modelname, pretrain_img_size, **kw):
|
| 763 |
+
assert modelname in [
|
| 764 |
+
"swin_T_224_1k",
|
| 765 |
+
"swin_B_224_22k",
|
| 766 |
+
"swin_B_384_22k",
|
| 767 |
+
"swin_L_224_22k",
|
| 768 |
+
"swin_L_384_22k",
|
| 769 |
+
]
|
| 770 |
+
|
| 771 |
+
model_para_dict = {
|
| 772 |
+
"swin_T_224_1k": dict(
|
| 773 |
+
embed_dim=96, depths=[2, 2, 6, 2], num_heads=[3, 6, 12, 24], window_size=7
|
| 774 |
+
),
|
| 775 |
+
"swin_B_224_22k": dict(
|
| 776 |
+
embed_dim=128, depths=[2, 2, 18, 2], num_heads=[4, 8, 16, 32], window_size=7
|
| 777 |
+
),
|
| 778 |
+
"swin_B_384_22k": dict(
|
| 779 |
+
embed_dim=128, depths=[2, 2, 18, 2], num_heads=[4, 8, 16, 32], window_size=12
|
| 780 |
+
),
|
| 781 |
+
"swin_L_224_22k": dict(
|
| 782 |
+
embed_dim=192, depths=[2, 2, 18, 2], num_heads=[6, 12, 24, 48], window_size=7
|
| 783 |
+
),
|
| 784 |
+
"swin_L_384_22k": dict(
|
| 785 |
+
embed_dim=192, depths=[2, 2, 18, 2], num_heads=[6, 12, 24, 48], window_size=12
|
| 786 |
+
),
|
| 787 |
+
}
|
| 788 |
+
kw_cgf = model_para_dict[modelname]
|
| 789 |
+
kw_cgf.update(kw)
|
| 790 |
+
model = SwinTransformer(pretrain_img_size=pretrain_img_size, **kw_cgf)
|
| 791 |
+
return model
|
| 792 |
+
|
| 793 |
+
|
| 794 |
+
if __name__ == "__main__":
|
| 795 |
+
model = build_swin_transformer("swin_L_384_22k", 384, dilation=True)
|
| 796 |
+
x = torch.rand(2, 3, 1024, 1024)
|
| 797 |
+
y = model.forward_raw(x)
|
| 798 |
+
import ipdb
|
| 799 |
+
|
| 800 |
+
ipdb.set_trace()
|
| 801 |
+
x = torch.rand(2, 3, 384, 384)
|
| 802 |
+
y = model.forward_raw(x)
|
One-to-All-Animation/benchmark/DisCo/annotator/grounded-sam/GroundingDINO/groundingdino/models/GroundingDINO/bertwarper.py
ADDED
|
@@ -0,0 +1,273 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
# ------------------------------------------------------------------------
|
| 2 |
+
# Grounding DINO
|
| 3 |
+
# url: https://github.com/IDEA-Research/GroundingDINO
|
| 4 |
+
# Copyright (c) 2023 IDEA. All Rights Reserved.
|
| 5 |
+
# Licensed under the Apache License, Version 2.0 [see LICENSE for details]
|
| 6 |
+
# ------------------------------------------------------------------------
|
| 7 |
+
|
| 8 |
+
import torch
|
| 9 |
+
import torch.nn.functional as F
|
| 10 |
+
import torch.utils.checkpoint as checkpoint
|
| 11 |
+
from torch import Tensor, nn
|
| 12 |
+
from torchvision.ops.boxes import nms
|
| 13 |
+
from transformers import BertConfig, BertModel, BertPreTrainedModel
|
| 14 |
+
from transformers.modeling_outputs import BaseModelOutputWithPoolingAndCrossAttentions
|
| 15 |
+
|
| 16 |
+
|
| 17 |
+
class BertModelWarper(nn.Module):
|
| 18 |
+
def __init__(self, bert_model):
|
| 19 |
+
super().__init__()
|
| 20 |
+
# self.bert = bert_modelc
|
| 21 |
+
|
| 22 |
+
self.config = bert_model.config
|
| 23 |
+
self.embeddings = bert_model.embeddings
|
| 24 |
+
self.encoder = bert_model.encoder
|
| 25 |
+
self.pooler = bert_model.pooler
|
| 26 |
+
|
| 27 |
+
self.get_extended_attention_mask = bert_model.get_extended_attention_mask
|
| 28 |
+
self.invert_attention_mask = bert_model.invert_attention_mask
|
| 29 |
+
self.get_head_mask = bert_model.get_head_mask
|
| 30 |
+
|
| 31 |
+
def forward(
|
| 32 |
+
self,
|
| 33 |
+
input_ids=None,
|
| 34 |
+
attention_mask=None,
|
| 35 |
+
token_type_ids=None,
|
| 36 |
+
position_ids=None,
|
| 37 |
+
head_mask=None,
|
| 38 |
+
inputs_embeds=None,
|
| 39 |
+
encoder_hidden_states=None,
|
| 40 |
+
encoder_attention_mask=None,
|
| 41 |
+
past_key_values=None,
|
| 42 |
+
use_cache=None,
|
| 43 |
+
output_attentions=None,
|
| 44 |
+
output_hidden_states=None,
|
| 45 |
+
return_dict=None,
|
| 46 |
+
):
|
| 47 |
+
r"""
|
| 48 |
+
encoder_hidden_states (:obj:`torch.FloatTensor` of shape :obj:`(batch_size, sequence_length, hidden_size)`, `optional`):
|
| 49 |
+
Sequence of hidden-states at the output of the last layer of the encoder. Used in the cross-attention if
|
| 50 |
+
the model is configured as a decoder.
|
| 51 |
+
encoder_attention_mask (:obj:`torch.FloatTensor` of shape :obj:`(batch_size, sequence_length)`, `optional`):
|
| 52 |
+
Mask to avoid performing attention on the padding token indices of the encoder input. This mask is used in
|
| 53 |
+
the cross-attention if the model is configured as a decoder. Mask values selected in ``[0, 1]``:
|
| 54 |
+
|
| 55 |
+
- 1 for tokens that are **not masked**,
|
| 56 |
+
- 0 for tokens that are **masked**.
|
| 57 |
+
past_key_values (:obj:`tuple(tuple(torch.FloatTensor))` of length :obj:`config.n_layers` with each tuple having 4 tensors of shape :obj:`(batch_size, num_heads, sequence_length - 1, embed_size_per_head)`):
|
| 58 |
+
Contains precomputed key and value hidden states of the attention blocks. Can be used to speed up decoding.
|
| 59 |
+
|
| 60 |
+
If :obj:`past_key_values` are used, the user can optionally input only the last :obj:`decoder_input_ids`
|
| 61 |
+
(those that don't have their past key value states given to this model) of shape :obj:`(batch_size, 1)`
|
| 62 |
+
instead of all :obj:`decoder_input_ids` of shape :obj:`(batch_size, sequence_length)`.
|
| 63 |
+
use_cache (:obj:`bool`, `optional`):
|
| 64 |
+
If set to :obj:`True`, :obj:`past_key_values` key value states are returned and can be used to speed up
|
| 65 |
+
decoding (see :obj:`past_key_values`).
|
| 66 |
+
"""
|
| 67 |
+
output_attentions = (
|
| 68 |
+
output_attentions if output_attentions is not None else self.config.output_attentions
|
| 69 |
+
)
|
| 70 |
+
output_hidden_states = (
|
| 71 |
+
output_hidden_states
|
| 72 |
+
if output_hidden_states is not None
|
| 73 |
+
else self.config.output_hidden_states
|
| 74 |
+
)
|
| 75 |
+
return_dict = return_dict if return_dict is not None else self.config.use_return_dict
|
| 76 |
+
|
| 77 |
+
if self.config.is_decoder:
|
| 78 |
+
use_cache = use_cache if use_cache is not None else self.config.use_cache
|
| 79 |
+
else:
|
| 80 |
+
use_cache = False
|
| 81 |
+
|
| 82 |
+
if input_ids is not None and inputs_embeds is not None:
|
| 83 |
+
raise ValueError("You cannot specify both input_ids and inputs_embeds at the same time")
|
| 84 |
+
elif input_ids is not None:
|
| 85 |
+
input_shape = input_ids.size()
|
| 86 |
+
batch_size, seq_length = input_shape
|
| 87 |
+
elif inputs_embeds is not None:
|
| 88 |
+
input_shape = inputs_embeds.size()[:-1]
|
| 89 |
+
batch_size, seq_length = input_shape
|
| 90 |
+
else:
|
| 91 |
+
raise ValueError("You have to specify either input_ids or inputs_embeds")
|
| 92 |
+
|
| 93 |
+
device = input_ids.device if input_ids is not None else inputs_embeds.device
|
| 94 |
+
|
| 95 |
+
# past_key_values_length
|
| 96 |
+
past_key_values_length = (
|
| 97 |
+
past_key_values[0][0].shape[2] if past_key_values is not None else 0
|
| 98 |
+
)
|
| 99 |
+
|
| 100 |
+
if attention_mask is None:
|
| 101 |
+
attention_mask = torch.ones(
|
| 102 |
+
((batch_size, seq_length + past_key_values_length)), device=device
|
| 103 |
+
)
|
| 104 |
+
if token_type_ids is None:
|
| 105 |
+
token_type_ids = torch.zeros(input_shape, dtype=torch.long, device=device)
|
| 106 |
+
|
| 107 |
+
# We can provide a self-attention mask of dimensions [batch_size, from_seq_length, to_seq_length]
|
| 108 |
+
# ourselves in which case we just need to make it broadcastable to all heads.
|
| 109 |
+
extended_attention_mask: torch.Tensor = self.get_extended_attention_mask(
|
| 110 |
+
attention_mask, input_shape, device
|
| 111 |
+
)
|
| 112 |
+
|
| 113 |
+
# If a 2D or 3D attention mask is provided for the cross-attention
|
| 114 |
+
# we need to make broadcastable to [batch_size, num_heads, seq_length, seq_length]
|
| 115 |
+
if self.config.is_decoder and encoder_hidden_states is not None:
|
| 116 |
+
encoder_batch_size, encoder_sequence_length, _ = encoder_hidden_states.size()
|
| 117 |
+
encoder_hidden_shape = (encoder_batch_size, encoder_sequence_length)
|
| 118 |
+
if encoder_attention_mask is None:
|
| 119 |
+
encoder_attention_mask = torch.ones(encoder_hidden_shape, device=device)
|
| 120 |
+
encoder_extended_attention_mask = self.invert_attention_mask(encoder_attention_mask)
|
| 121 |
+
else:
|
| 122 |
+
encoder_extended_attention_mask = None
|
| 123 |
+
# if os.environ.get('IPDB_SHILONG_DEBUG', None) == 'INFO':
|
| 124 |
+
# import ipdb; ipdb.set_trace()
|
| 125 |
+
|
| 126 |
+
# Prepare head mask if needed
|
| 127 |
+
# 1.0 in head_mask indicate we keep the head
|
| 128 |
+
# attention_probs has shape bsz x n_heads x N x N
|
| 129 |
+
# input head_mask has shape [num_heads] or [num_hidden_layers x num_heads]
|
| 130 |
+
# and head_mask is converted to shape [num_hidden_layers x batch x num_heads x seq_length x seq_length]
|
| 131 |
+
head_mask = self.get_head_mask(head_mask, self.config.num_hidden_layers)
|
| 132 |
+
|
| 133 |
+
embedding_output = self.embeddings(
|
| 134 |
+
input_ids=input_ids,
|
| 135 |
+
position_ids=position_ids,
|
| 136 |
+
token_type_ids=token_type_ids,
|
| 137 |
+
inputs_embeds=inputs_embeds,
|
| 138 |
+
past_key_values_length=past_key_values_length,
|
| 139 |
+
)
|
| 140 |
+
|
| 141 |
+
encoder_outputs = self.encoder(
|
| 142 |
+
embedding_output,
|
| 143 |
+
attention_mask=extended_attention_mask,
|
| 144 |
+
head_mask=head_mask,
|
| 145 |
+
encoder_hidden_states=encoder_hidden_states,
|
| 146 |
+
encoder_attention_mask=encoder_extended_attention_mask,
|
| 147 |
+
past_key_values=past_key_values,
|
| 148 |
+
use_cache=use_cache,
|
| 149 |
+
output_attentions=output_attentions,
|
| 150 |
+
output_hidden_states=output_hidden_states,
|
| 151 |
+
return_dict=return_dict,
|
| 152 |
+
)
|
| 153 |
+
sequence_output = encoder_outputs[0]
|
| 154 |
+
pooled_output = self.pooler(sequence_output) if self.pooler is not None else None
|
| 155 |
+
|
| 156 |
+
if not return_dict:
|
| 157 |
+
return (sequence_output, pooled_output) + encoder_outputs[1:]
|
| 158 |
+
|
| 159 |
+
return BaseModelOutputWithPoolingAndCrossAttentions(
|
| 160 |
+
last_hidden_state=sequence_output,
|
| 161 |
+
pooler_output=pooled_output,
|
| 162 |
+
past_key_values=encoder_outputs.past_key_values,
|
| 163 |
+
hidden_states=encoder_outputs.hidden_states,
|
| 164 |
+
attentions=encoder_outputs.attentions,
|
| 165 |
+
cross_attentions=encoder_outputs.cross_attentions,
|
| 166 |
+
)
|
| 167 |
+
|
| 168 |
+
|
| 169 |
+
class TextEncoderShell(nn.Module):
|
| 170 |
+
def __init__(self, text_encoder):
|
| 171 |
+
super().__init__()
|
| 172 |
+
self.text_encoder = text_encoder
|
| 173 |
+
self.config = self.text_encoder.config
|
| 174 |
+
|
| 175 |
+
def forward(self, **kw):
|
| 176 |
+
# feed into text encoder
|
| 177 |
+
return self.text_encoder(**kw)
|
| 178 |
+
|
| 179 |
+
|
| 180 |
+
def generate_masks_with_special_tokens(tokenized, special_tokens_list, tokenizer):
|
| 181 |
+
"""Generate attention mask between each pair of special tokens
|
| 182 |
+
Args:
|
| 183 |
+
input_ids (torch.Tensor): input ids. Shape: [bs, num_token]
|
| 184 |
+
special_tokens_mask (list): special tokens mask.
|
| 185 |
+
Returns:
|
| 186 |
+
torch.Tensor: attention mask between each special tokens.
|
| 187 |
+
"""
|
| 188 |
+
input_ids = tokenized["input_ids"]
|
| 189 |
+
bs, num_token = input_ids.shape
|
| 190 |
+
# special_tokens_mask: bs, num_token. 1 for special tokens. 0 for normal tokens
|
| 191 |
+
special_tokens_mask = torch.zeros((bs, num_token), device=input_ids.device).bool()
|
| 192 |
+
for special_token in special_tokens_list:
|
| 193 |
+
special_tokens_mask |= input_ids == special_token
|
| 194 |
+
|
| 195 |
+
# idxs: each row is a list of indices of special tokens
|
| 196 |
+
idxs = torch.nonzero(special_tokens_mask)
|
| 197 |
+
|
| 198 |
+
# generate attention mask and positional ids
|
| 199 |
+
attention_mask = (
|
| 200 |
+
torch.eye(num_token, device=input_ids.device).bool().unsqueeze(0).repeat(bs, 1, 1)
|
| 201 |
+
)
|
| 202 |
+
position_ids = torch.zeros((bs, num_token), device=input_ids.device)
|
| 203 |
+
previous_col = 0
|
| 204 |
+
for i in range(idxs.shape[0]):
|
| 205 |
+
row, col = idxs[i]
|
| 206 |
+
if (col == 0) or (col == num_token - 1):
|
| 207 |
+
attention_mask[row, col, col] = True
|
| 208 |
+
position_ids[row, col] = 0
|
| 209 |
+
else:
|
| 210 |
+
attention_mask[row, previous_col + 1 : col + 1, previous_col + 1 : col + 1] = True
|
| 211 |
+
position_ids[row, previous_col + 1 : col + 1] = torch.arange(
|
| 212 |
+
0, col - previous_col, device=input_ids.device
|
| 213 |
+
)
|
| 214 |
+
|
| 215 |
+
previous_col = col
|
| 216 |
+
|
| 217 |
+
# # padding mask
|
| 218 |
+
# padding_mask = tokenized['attention_mask']
|
| 219 |
+
# attention_mask = attention_mask & padding_mask.unsqueeze(1).bool() & padding_mask.unsqueeze(2).bool()
|
| 220 |
+
|
| 221 |
+
return attention_mask, position_ids.to(torch.long)
|
| 222 |
+
|
| 223 |
+
|
| 224 |
+
def generate_masks_with_special_tokens_and_transfer_map(tokenized, special_tokens_list, tokenizer):
|
| 225 |
+
"""Generate attention mask between each pair of special tokens
|
| 226 |
+
Args:
|
| 227 |
+
input_ids (torch.Tensor): input ids. Shape: [bs, num_token]
|
| 228 |
+
special_tokens_mask (list): special tokens mask.
|
| 229 |
+
Returns:
|
| 230 |
+
torch.Tensor: attention mask between each special tokens.
|
| 231 |
+
"""
|
| 232 |
+
input_ids = tokenized["input_ids"]
|
| 233 |
+
bs, num_token = input_ids.shape
|
| 234 |
+
# special_tokens_mask: bs, num_token. 1 for special tokens. 0 for normal tokens
|
| 235 |
+
special_tokens_mask = torch.zeros((bs, num_token), device=input_ids.device).bool()
|
| 236 |
+
for special_token in special_tokens_list:
|
| 237 |
+
special_tokens_mask |= input_ids == special_token
|
| 238 |
+
|
| 239 |
+
# idxs: each row is a list of indices of special tokens
|
| 240 |
+
idxs = torch.nonzero(special_tokens_mask)
|
| 241 |
+
|
| 242 |
+
# generate attention mask and positional ids
|
| 243 |
+
attention_mask = (
|
| 244 |
+
torch.eye(num_token, device=input_ids.device).bool().unsqueeze(0).repeat(bs, 1, 1)
|
| 245 |
+
)
|
| 246 |
+
position_ids = torch.zeros((bs, num_token), device=input_ids.device)
|
| 247 |
+
cate_to_token_mask_list = [[] for _ in range(bs)]
|
| 248 |
+
previous_col = 0
|
| 249 |
+
for i in range(idxs.shape[0]):
|
| 250 |
+
row, col = idxs[i]
|
| 251 |
+
if (col == 0) or (col == num_token - 1):
|
| 252 |
+
attention_mask[row, col, col] = True
|
| 253 |
+
position_ids[row, col] = 0
|
| 254 |
+
else:
|
| 255 |
+
attention_mask[row, previous_col + 1 : col + 1, previous_col + 1 : col + 1] = True
|
| 256 |
+
position_ids[row, previous_col + 1 : col + 1] = torch.arange(
|
| 257 |
+
0, col - previous_col, device=input_ids.device
|
| 258 |
+
)
|
| 259 |
+
c2t_maski = torch.zeros((num_token), device=input_ids.device).bool()
|
| 260 |
+
c2t_maski[previous_col + 1 : col] = True
|
| 261 |
+
cate_to_token_mask_list[row].append(c2t_maski)
|
| 262 |
+
previous_col = col
|
| 263 |
+
|
| 264 |
+
cate_to_token_mask_list = [
|
| 265 |
+
torch.stack(cate_to_token_mask_listi, dim=0)
|
| 266 |
+
for cate_to_token_mask_listi in cate_to_token_mask_list
|
| 267 |
+
]
|
| 268 |
+
|
| 269 |
+
# # padding mask
|
| 270 |
+
# padding_mask = tokenized['attention_mask']
|
| 271 |
+
# attention_mask = attention_mask & padding_mask.unsqueeze(1).bool() & padding_mask.unsqueeze(2).bool()
|
| 272 |
+
|
| 273 |
+
return attention_mask, position_ids.to(torch.long), cate_to_token_mask_list
|
One-to-All-Animation/benchmark/DisCo/annotator/grounded-sam/GroundingDINO/groundingdino/models/GroundingDINO/csrc/MsDeformAttn/ms_deform_attn.h
ADDED
|
@@ -0,0 +1,64 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
/*!
|
| 2 |
+
**************************************************************************************************
|
| 3 |
+
* Deformable DETR
|
| 4 |
+
* Copyright (c) 2020 SenseTime. All Rights Reserved.
|
| 5 |
+
* Licensed under the Apache License, Version 2.0 [see LICENSE for details]
|
| 6 |
+
**************************************************************************************************
|
| 7 |
+
* Modified from https://github.com/chengdazhi/Deformable-Convolution-V2-PyTorch/tree/pytorch_1.0.0
|
| 8 |
+
**************************************************************************************************
|
| 9 |
+
*/
|
| 10 |
+
|
| 11 |
+
#pragma once
|
| 12 |
+
|
| 13 |
+
#include "ms_deform_attn_cpu.h"
|
| 14 |
+
|
| 15 |
+
#ifdef WITH_CUDA
|
| 16 |
+
#include "ms_deform_attn_cuda.h"
|
| 17 |
+
#endif
|
| 18 |
+
|
| 19 |
+
namespace groundingdino {
|
| 20 |
+
|
| 21 |
+
at::Tensor
|
| 22 |
+
ms_deform_attn_forward(
|
| 23 |
+
const at::Tensor &value,
|
| 24 |
+
const at::Tensor &spatial_shapes,
|
| 25 |
+
const at::Tensor &level_start_index,
|
| 26 |
+
const at::Tensor &sampling_loc,
|
| 27 |
+
const at::Tensor &attn_weight,
|
| 28 |
+
const int im2col_step)
|
| 29 |
+
{
|
| 30 |
+
if (value.type().is_cuda())
|
| 31 |
+
{
|
| 32 |
+
#ifdef WITH_CUDA
|
| 33 |
+
return ms_deform_attn_cuda_forward(
|
| 34 |
+
value, spatial_shapes, level_start_index, sampling_loc, attn_weight, im2col_step);
|
| 35 |
+
#else
|
| 36 |
+
AT_ERROR("Not compiled with GPU support");
|
| 37 |
+
#endif
|
| 38 |
+
}
|
| 39 |
+
AT_ERROR("Not implemented on the CPU");
|
| 40 |
+
}
|
| 41 |
+
|
| 42 |
+
std::vector<at::Tensor>
|
| 43 |
+
ms_deform_attn_backward(
|
| 44 |
+
const at::Tensor &value,
|
| 45 |
+
const at::Tensor &spatial_shapes,
|
| 46 |
+
const at::Tensor &level_start_index,
|
| 47 |
+
const at::Tensor &sampling_loc,
|
| 48 |
+
const at::Tensor &attn_weight,
|
| 49 |
+
const at::Tensor &grad_output,
|
| 50 |
+
const int im2col_step)
|
| 51 |
+
{
|
| 52 |
+
if (value.type().is_cuda())
|
| 53 |
+
{
|
| 54 |
+
#ifdef WITH_CUDA
|
| 55 |
+
return ms_deform_attn_cuda_backward(
|
| 56 |
+
value, spatial_shapes, level_start_index, sampling_loc, attn_weight, grad_output, im2col_step);
|
| 57 |
+
#else
|
| 58 |
+
AT_ERROR("Not compiled with GPU support");
|
| 59 |
+
#endif
|
| 60 |
+
}
|
| 61 |
+
AT_ERROR("Not implemented on the CPU");
|
| 62 |
+
}
|
| 63 |
+
|
| 64 |
+
} // namespace groundingdino
|
One-to-All-Animation/benchmark/DisCo/annotator/grounded-sam/GroundingDINO/groundingdino/models/GroundingDINO/csrc/MsDeformAttn/ms_deform_attn_cpu.cpp
ADDED
|
@@ -0,0 +1,43 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
/*!
|
| 2 |
+
**************************************************************************************************
|
| 3 |
+
* Deformable DETR
|
| 4 |
+
* Copyright (c) 2020 SenseTime. All Rights Reserved.
|
| 5 |
+
* Licensed under the Apache License, Version 2.0 [see LICENSE for details]
|
| 6 |
+
**************************************************************************************************
|
| 7 |
+
* Modified from https://github.com/chengdazhi/Deformable-Convolution-V2-PyTorch/tree/pytorch_1.0.0
|
| 8 |
+
**************************************************************************************************
|
| 9 |
+
*/
|
| 10 |
+
|
| 11 |
+
#include <vector>
|
| 12 |
+
|
| 13 |
+
#include <ATen/ATen.h>
|
| 14 |
+
#include <ATen/cuda/CUDAContext.h>
|
| 15 |
+
|
| 16 |
+
namespace groundingdino {
|
| 17 |
+
|
| 18 |
+
at::Tensor
|
| 19 |
+
ms_deform_attn_cpu_forward(
|
| 20 |
+
const at::Tensor &value,
|
| 21 |
+
const at::Tensor &spatial_shapes,
|
| 22 |
+
const at::Tensor &level_start_index,
|
| 23 |
+
const at::Tensor &sampling_loc,
|
| 24 |
+
const at::Tensor &attn_weight,
|
| 25 |
+
const int im2col_step)
|
| 26 |
+
{
|
| 27 |
+
AT_ERROR("Not implement on cpu");
|
| 28 |
+
}
|
| 29 |
+
|
| 30 |
+
std::vector<at::Tensor>
|
| 31 |
+
ms_deform_attn_cpu_backward(
|
| 32 |
+
const at::Tensor &value,
|
| 33 |
+
const at::Tensor &spatial_shapes,
|
| 34 |
+
const at::Tensor &level_start_index,
|
| 35 |
+
const at::Tensor &sampling_loc,
|
| 36 |
+
const at::Tensor &attn_weight,
|
| 37 |
+
const at::Tensor &grad_output,
|
| 38 |
+
const int im2col_step)
|
| 39 |
+
{
|
| 40 |
+
AT_ERROR("Not implement on cpu");
|
| 41 |
+
}
|
| 42 |
+
|
| 43 |
+
} // namespace groundingdino
|
One-to-All-Animation/benchmark/DisCo/annotator/grounded-sam/GroundingDINO/groundingdino/models/GroundingDINO/csrc/MsDeformAttn/ms_deform_attn_cpu.h
ADDED
|
@@ -0,0 +1,35 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
/*!
|
| 2 |
+
**************************************************************************************************
|
| 3 |
+
* Deformable DETR
|
| 4 |
+
* Copyright (c) 2020 SenseTime. All Rights Reserved.
|
| 5 |
+
* Licensed under the Apache License, Version 2.0 [see LICENSE for details]
|
| 6 |
+
**************************************************************************************************
|
| 7 |
+
* Modified from https://github.com/chengdazhi/Deformable-Convolution-V2-PyTorch/tree/pytorch_1.0.0
|
| 8 |
+
**************************************************************************************************
|
| 9 |
+
*/
|
| 10 |
+
|
| 11 |
+
#pragma once
|
| 12 |
+
#include <torch/extension.h>
|
| 13 |
+
|
| 14 |
+
namespace groundingdino {
|
| 15 |
+
|
| 16 |
+
at::Tensor
|
| 17 |
+
ms_deform_attn_cpu_forward(
|
| 18 |
+
const at::Tensor &value,
|
| 19 |
+
const at::Tensor &spatial_shapes,
|
| 20 |
+
const at::Tensor &level_start_index,
|
| 21 |
+
const at::Tensor &sampling_loc,
|
| 22 |
+
const at::Tensor &attn_weight,
|
| 23 |
+
const int im2col_step);
|
| 24 |
+
|
| 25 |
+
std::vector<at::Tensor>
|
| 26 |
+
ms_deform_attn_cpu_backward(
|
| 27 |
+
const at::Tensor &value,
|
| 28 |
+
const at::Tensor &spatial_shapes,
|
| 29 |
+
const at::Tensor &level_start_index,
|
| 30 |
+
const at::Tensor &sampling_loc,
|
| 31 |
+
const at::Tensor &attn_weight,
|
| 32 |
+
const at::Tensor &grad_output,
|
| 33 |
+
const int im2col_step);
|
| 34 |
+
|
| 35 |
+
} // namespace groundingdino
|
One-to-All-Animation/benchmark/DisCo/annotator/grounded-sam/GroundingDINO/groundingdino/models/GroundingDINO/csrc/MsDeformAttn/ms_deform_attn_cuda.cu
ADDED
|
@@ -0,0 +1,156 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
/*!
|
| 2 |
+
**************************************************************************************************
|
| 3 |
+
* Deformable DETR
|
| 4 |
+
* Copyright (c) 2020 SenseTime. All Rights Reserved.
|
| 5 |
+
* Licensed under the Apache License, Version 2.0 [see LICENSE for details]
|
| 6 |
+
**************************************************************************************************
|
| 7 |
+
* Modified from https://github.com/chengdazhi/Deformable-Convolution-V2-PyTorch/tree/pytorch_1.0.0
|
| 8 |
+
**************************************************************************************************
|
| 9 |
+
*/
|
| 10 |
+
|
| 11 |
+
#include <vector>
|
| 12 |
+
#include "ms_deform_im2col_cuda.cuh"
|
| 13 |
+
|
| 14 |
+
#include <ATen/ATen.h>
|
| 15 |
+
#include <ATen/cuda/CUDAContext.h>
|
| 16 |
+
#include <cuda.h>
|
| 17 |
+
#include <cuda_runtime.h>
|
| 18 |
+
|
| 19 |
+
namespace groundingdino {
|
| 20 |
+
|
| 21 |
+
at::Tensor ms_deform_attn_cuda_forward(
|
| 22 |
+
const at::Tensor &value,
|
| 23 |
+
const at::Tensor &spatial_shapes,
|
| 24 |
+
const at::Tensor &level_start_index,
|
| 25 |
+
const at::Tensor &sampling_loc,
|
| 26 |
+
const at::Tensor &attn_weight,
|
| 27 |
+
const int im2col_step)
|
| 28 |
+
{
|
| 29 |
+
AT_ASSERTM(value.is_contiguous(), "value tensor has to be contiguous");
|
| 30 |
+
AT_ASSERTM(spatial_shapes.is_contiguous(), "spatial_shapes tensor has to be contiguous");
|
| 31 |
+
AT_ASSERTM(level_start_index.is_contiguous(), "level_start_index tensor has to be contiguous");
|
| 32 |
+
AT_ASSERTM(sampling_loc.is_contiguous(), "sampling_loc tensor has to be contiguous");
|
| 33 |
+
AT_ASSERTM(attn_weight.is_contiguous(), "attn_weight tensor has to be contiguous");
|
| 34 |
+
|
| 35 |
+
AT_ASSERTM(value.type().is_cuda(), "value must be a CUDA tensor");
|
| 36 |
+
AT_ASSERTM(spatial_shapes.type().is_cuda(), "spatial_shapes must be a CUDA tensor");
|
| 37 |
+
AT_ASSERTM(level_start_index.type().is_cuda(), "level_start_index must be a CUDA tensor");
|
| 38 |
+
AT_ASSERTM(sampling_loc.type().is_cuda(), "sampling_loc must be a CUDA tensor");
|
| 39 |
+
AT_ASSERTM(attn_weight.type().is_cuda(), "attn_weight must be a CUDA tensor");
|
| 40 |
+
|
| 41 |
+
const int batch = value.size(0);
|
| 42 |
+
const int spatial_size = value.size(1);
|
| 43 |
+
const int num_heads = value.size(2);
|
| 44 |
+
const int channels = value.size(3);
|
| 45 |
+
|
| 46 |
+
const int num_levels = spatial_shapes.size(0);
|
| 47 |
+
|
| 48 |
+
const int num_query = sampling_loc.size(1);
|
| 49 |
+
const int num_point = sampling_loc.size(4);
|
| 50 |
+
|
| 51 |
+
const int im2col_step_ = std::min(batch, im2col_step);
|
| 52 |
+
|
| 53 |
+
AT_ASSERTM(batch % im2col_step_ == 0, "batch(%d) must divide im2col_step(%d)", batch, im2col_step_);
|
| 54 |
+
|
| 55 |
+
auto output = at::zeros({batch, num_query, num_heads, channels}, value.options());
|
| 56 |
+
|
| 57 |
+
const int batch_n = im2col_step_;
|
| 58 |
+
auto output_n = output.view({batch/im2col_step_, batch_n, num_query, num_heads, channels});
|
| 59 |
+
auto per_value_size = spatial_size * num_heads * channels;
|
| 60 |
+
auto per_sample_loc_size = num_query * num_heads * num_levels * num_point * 2;
|
| 61 |
+
auto per_attn_weight_size = num_query * num_heads * num_levels * num_point;
|
| 62 |
+
for (int n = 0; n < batch/im2col_step_; ++n)
|
| 63 |
+
{
|
| 64 |
+
auto columns = output_n.select(0, n);
|
| 65 |
+
AT_DISPATCH_FLOATING_TYPES(value.type(), "ms_deform_attn_forward_cuda", ([&] {
|
| 66 |
+
ms_deformable_im2col_cuda(at::cuda::getCurrentCUDAStream(),
|
| 67 |
+
value.data<scalar_t>() + n * im2col_step_ * per_value_size,
|
| 68 |
+
spatial_shapes.data<int64_t>(),
|
| 69 |
+
level_start_index.data<int64_t>(),
|
| 70 |
+
sampling_loc.data<scalar_t>() + n * im2col_step_ * per_sample_loc_size,
|
| 71 |
+
attn_weight.data<scalar_t>() + n * im2col_step_ * per_attn_weight_size,
|
| 72 |
+
batch_n, spatial_size, num_heads, channels, num_levels, num_query, num_point,
|
| 73 |
+
columns.data<scalar_t>());
|
| 74 |
+
|
| 75 |
+
}));
|
| 76 |
+
}
|
| 77 |
+
|
| 78 |
+
output = output.view({batch, num_query, num_heads*channels});
|
| 79 |
+
|
| 80 |
+
return output;
|
| 81 |
+
}
|
| 82 |
+
|
| 83 |
+
|
| 84 |
+
std::vector<at::Tensor> ms_deform_attn_cuda_backward(
|
| 85 |
+
const at::Tensor &value,
|
| 86 |
+
const at::Tensor &spatial_shapes,
|
| 87 |
+
const at::Tensor &level_start_index,
|
| 88 |
+
const at::Tensor &sampling_loc,
|
| 89 |
+
const at::Tensor &attn_weight,
|
| 90 |
+
const at::Tensor &grad_output,
|
| 91 |
+
const int im2col_step)
|
| 92 |
+
{
|
| 93 |
+
|
| 94 |
+
AT_ASSERTM(value.is_contiguous(), "value tensor has to be contiguous");
|
| 95 |
+
AT_ASSERTM(spatial_shapes.is_contiguous(), "spatial_shapes tensor has to be contiguous");
|
| 96 |
+
AT_ASSERTM(level_start_index.is_contiguous(), "level_start_index tensor has to be contiguous");
|
| 97 |
+
AT_ASSERTM(sampling_loc.is_contiguous(), "sampling_loc tensor has to be contiguous");
|
| 98 |
+
AT_ASSERTM(attn_weight.is_contiguous(), "attn_weight tensor has to be contiguous");
|
| 99 |
+
AT_ASSERTM(grad_output.is_contiguous(), "grad_output tensor has to be contiguous");
|
| 100 |
+
|
| 101 |
+
AT_ASSERTM(value.type().is_cuda(), "value must be a CUDA tensor");
|
| 102 |
+
AT_ASSERTM(spatial_shapes.type().is_cuda(), "spatial_shapes must be a CUDA tensor");
|
| 103 |
+
AT_ASSERTM(level_start_index.type().is_cuda(), "level_start_index must be a CUDA tensor");
|
| 104 |
+
AT_ASSERTM(sampling_loc.type().is_cuda(), "sampling_loc must be a CUDA tensor");
|
| 105 |
+
AT_ASSERTM(attn_weight.type().is_cuda(), "attn_weight must be a CUDA tensor");
|
| 106 |
+
AT_ASSERTM(grad_output.type().is_cuda(), "grad_output must be a CUDA tensor");
|
| 107 |
+
|
| 108 |
+
const int batch = value.size(0);
|
| 109 |
+
const int spatial_size = value.size(1);
|
| 110 |
+
const int num_heads = value.size(2);
|
| 111 |
+
const int channels = value.size(3);
|
| 112 |
+
|
| 113 |
+
const int num_levels = spatial_shapes.size(0);
|
| 114 |
+
|
| 115 |
+
const int num_query = sampling_loc.size(1);
|
| 116 |
+
const int num_point = sampling_loc.size(4);
|
| 117 |
+
|
| 118 |
+
const int im2col_step_ = std::min(batch, im2col_step);
|
| 119 |
+
|
| 120 |
+
AT_ASSERTM(batch % im2col_step_ == 0, "batch(%d) must divide im2col_step(%d)", batch, im2col_step_);
|
| 121 |
+
|
| 122 |
+
auto grad_value = at::zeros_like(value);
|
| 123 |
+
auto grad_sampling_loc = at::zeros_like(sampling_loc);
|
| 124 |
+
auto grad_attn_weight = at::zeros_like(attn_weight);
|
| 125 |
+
|
| 126 |
+
const int batch_n = im2col_step_;
|
| 127 |
+
auto per_value_size = spatial_size * num_heads * channels;
|
| 128 |
+
auto per_sample_loc_size = num_query * num_heads * num_levels * num_point * 2;
|
| 129 |
+
auto per_attn_weight_size = num_query * num_heads * num_levels * num_point;
|
| 130 |
+
auto grad_output_n = grad_output.view({batch/im2col_step_, batch_n, num_query, num_heads, channels});
|
| 131 |
+
|
| 132 |
+
for (int n = 0; n < batch/im2col_step_; ++n)
|
| 133 |
+
{
|
| 134 |
+
auto grad_output_g = grad_output_n.select(0, n);
|
| 135 |
+
AT_DISPATCH_FLOATING_TYPES(value.type(), "ms_deform_attn_backward_cuda", ([&] {
|
| 136 |
+
ms_deformable_col2im_cuda(at::cuda::getCurrentCUDAStream(),
|
| 137 |
+
grad_output_g.data<scalar_t>(),
|
| 138 |
+
value.data<scalar_t>() + n * im2col_step_ * per_value_size,
|
| 139 |
+
spatial_shapes.data<int64_t>(),
|
| 140 |
+
level_start_index.data<int64_t>(),
|
| 141 |
+
sampling_loc.data<scalar_t>() + n * im2col_step_ * per_sample_loc_size,
|
| 142 |
+
attn_weight.data<scalar_t>() + n * im2col_step_ * per_attn_weight_size,
|
| 143 |
+
batch_n, spatial_size, num_heads, channels, num_levels, num_query, num_point,
|
| 144 |
+
grad_value.data<scalar_t>() + n * im2col_step_ * per_value_size,
|
| 145 |
+
grad_sampling_loc.data<scalar_t>() + n * im2col_step_ * per_sample_loc_size,
|
| 146 |
+
grad_attn_weight.data<scalar_t>() + n * im2col_step_ * per_attn_weight_size);
|
| 147 |
+
|
| 148 |
+
}));
|
| 149 |
+
}
|
| 150 |
+
|
| 151 |
+
return {
|
| 152 |
+
grad_value, grad_sampling_loc, grad_attn_weight
|
| 153 |
+
};
|
| 154 |
+
}
|
| 155 |
+
|
| 156 |
+
} // namespace groundingdino
|
One-to-All-Animation/benchmark/DisCo/annotator/grounded-sam/GroundingDINO/groundingdino/models/GroundingDINO/csrc/MsDeformAttn/ms_deform_attn_cuda.h
ADDED
|
@@ -0,0 +1,33 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
/*!
|
| 2 |
+
**************************************************************************************************
|
| 3 |
+
* Deformable DETR
|
| 4 |
+
* Copyright (c) 2020 SenseTime. All Rights Reserved.
|
| 5 |
+
* Licensed under the Apache License, Version 2.0 [see LICENSE for details]
|
| 6 |
+
**************************************************************************************************
|
| 7 |
+
* Modified from https://github.com/chengdazhi/Deformable-Convolution-V2-PyTorch/tree/pytorch_1.0.0
|
| 8 |
+
**************************************************************************************************
|
| 9 |
+
*/
|
| 10 |
+
|
| 11 |
+
#pragma once
|
| 12 |
+
#include <torch/extension.h>
|
| 13 |
+
|
| 14 |
+
namespace groundingdino {
|
| 15 |
+
|
| 16 |
+
at::Tensor ms_deform_attn_cuda_forward(
|
| 17 |
+
const at::Tensor &value,
|
| 18 |
+
const at::Tensor &spatial_shapes,
|
| 19 |
+
const at::Tensor &level_start_index,
|
| 20 |
+
const at::Tensor &sampling_loc,
|
| 21 |
+
const at::Tensor &attn_weight,
|
| 22 |
+
const int im2col_step);
|
| 23 |
+
|
| 24 |
+
std::vector<at::Tensor> ms_deform_attn_cuda_backward(
|
| 25 |
+
const at::Tensor &value,
|
| 26 |
+
const at::Tensor &spatial_shapes,
|
| 27 |
+
const at::Tensor &level_start_index,
|
| 28 |
+
const at::Tensor &sampling_loc,
|
| 29 |
+
const at::Tensor &attn_weight,
|
| 30 |
+
const at::Tensor &grad_output,
|
| 31 |
+
const int im2col_step);
|
| 32 |
+
|
| 33 |
+
} // namespace groundingdino
|
One-to-All-Animation/benchmark/DisCo/annotator/grounded-sam/GroundingDINO/groundingdino/models/GroundingDINO/csrc/MsDeformAttn/ms_deform_im2col_cuda.cuh
ADDED
|
@@ -0,0 +1,1327 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
/*!
|
| 2 |
+
**************************************************************************
|
| 3 |
+
* Deformable DETR
|
| 4 |
+
* Copyright (c) 2020 SenseTime. All Rights Reserved.
|
| 5 |
+
* Licensed under the Apache License, Version 2.0 [see LICENSE for details]
|
| 6 |
+
**************************************************************************
|
| 7 |
+
* Modified from DCN (https://github.com/msracver/Deformable-ConvNets)
|
| 8 |
+
* Copyright (c) 2018 Microsoft
|
| 9 |
+
**************************************************************************
|
| 10 |
+
*/
|
| 11 |
+
|
| 12 |
+
#include <cstdio>
|
| 13 |
+
#include <algorithm>
|
| 14 |
+
#include <cstring>
|
| 15 |
+
|
| 16 |
+
#include <ATen/ATen.h>
|
| 17 |
+
#include <ATen/cuda/CUDAContext.h>
|
| 18 |
+
|
| 19 |
+
#include <THC/THCAtomics.cuh>
|
| 20 |
+
|
| 21 |
+
#define CUDA_KERNEL_LOOP(i, n) \
|
| 22 |
+
for (int i = blockIdx.x * blockDim.x + threadIdx.x; \
|
| 23 |
+
i < (n); \
|
| 24 |
+
i += blockDim.x * gridDim.x)
|
| 25 |
+
|
| 26 |
+
const int CUDA_NUM_THREADS = 1024;
|
| 27 |
+
inline int GET_BLOCKS(const int N, const int num_threads)
|
| 28 |
+
{
|
| 29 |
+
return (N + num_threads - 1) / num_threads;
|
| 30 |
+
}
|
| 31 |
+
|
| 32 |
+
|
| 33 |
+
template <typename scalar_t>
|
| 34 |
+
__device__ scalar_t ms_deform_attn_im2col_bilinear(const scalar_t* &bottom_data,
|
| 35 |
+
const int &height, const int &width, const int &nheads, const int &channels,
|
| 36 |
+
const scalar_t &h, const scalar_t &w, const int &m, const int &c)
|
| 37 |
+
{
|
| 38 |
+
const int h_low = floor(h);
|
| 39 |
+
const int w_low = floor(w);
|
| 40 |
+
const int h_high = h_low + 1;
|
| 41 |
+
const int w_high = w_low + 1;
|
| 42 |
+
|
| 43 |
+
const scalar_t lh = h - h_low;
|
| 44 |
+
const scalar_t lw = w - w_low;
|
| 45 |
+
const scalar_t hh = 1 - lh, hw = 1 - lw;
|
| 46 |
+
|
| 47 |
+
const int w_stride = nheads * channels;
|
| 48 |
+
const int h_stride = width * w_stride;
|
| 49 |
+
const int h_low_ptr_offset = h_low * h_stride;
|
| 50 |
+
const int h_high_ptr_offset = h_low_ptr_offset + h_stride;
|
| 51 |
+
const int w_low_ptr_offset = w_low * w_stride;
|
| 52 |
+
const int w_high_ptr_offset = w_low_ptr_offset + w_stride;
|
| 53 |
+
const int base_ptr = m * channels + c;
|
| 54 |
+
|
| 55 |
+
scalar_t v1 = 0;
|
| 56 |
+
if (h_low >= 0 && w_low >= 0)
|
| 57 |
+
{
|
| 58 |
+
const int ptr1 = h_low_ptr_offset + w_low_ptr_offset + base_ptr;
|
| 59 |
+
v1 = bottom_data[ptr1];
|
| 60 |
+
}
|
| 61 |
+
scalar_t v2 = 0;
|
| 62 |
+
if (h_low >= 0 && w_high <= width - 1)
|
| 63 |
+
{
|
| 64 |
+
const int ptr2 = h_low_ptr_offset + w_high_ptr_offset + base_ptr;
|
| 65 |
+
v2 = bottom_data[ptr2];
|
| 66 |
+
}
|
| 67 |
+
scalar_t v3 = 0;
|
| 68 |
+
if (h_high <= height - 1 && w_low >= 0)
|
| 69 |
+
{
|
| 70 |
+
const int ptr3 = h_high_ptr_offset + w_low_ptr_offset + base_ptr;
|
| 71 |
+
v3 = bottom_data[ptr3];
|
| 72 |
+
}
|
| 73 |
+
scalar_t v4 = 0;
|
| 74 |
+
if (h_high <= height - 1 && w_high <= width - 1)
|
| 75 |
+
{
|
| 76 |
+
const int ptr4 = h_high_ptr_offset + w_high_ptr_offset + base_ptr;
|
| 77 |
+
v4 = bottom_data[ptr4];
|
| 78 |
+
}
|
| 79 |
+
|
| 80 |
+
const scalar_t w1 = hh * hw, w2 = hh * lw, w3 = lh * hw, w4 = lh * lw;
|
| 81 |
+
|
| 82 |
+
const scalar_t val = (w1 * v1 + w2 * v2 + w3 * v3 + w4 * v4);
|
| 83 |
+
return val;
|
| 84 |
+
}
|
| 85 |
+
|
| 86 |
+
|
| 87 |
+
template <typename scalar_t>
|
| 88 |
+
__device__ void ms_deform_attn_col2im_bilinear(const scalar_t* &bottom_data,
|
| 89 |
+
const int &height, const int &width, const int &nheads, const int &channels,
|
| 90 |
+
const scalar_t &h, const scalar_t &w, const int &m, const int &c,
|
| 91 |
+
const scalar_t &top_grad,
|
| 92 |
+
const scalar_t &attn_weight,
|
| 93 |
+
scalar_t* &grad_value,
|
| 94 |
+
scalar_t* grad_sampling_loc,
|
| 95 |
+
scalar_t* grad_attn_weight)
|
| 96 |
+
{
|
| 97 |
+
const int h_low = floor(h);
|
| 98 |
+
const int w_low = floor(w);
|
| 99 |
+
const int h_high = h_low + 1;
|
| 100 |
+
const int w_high = w_low + 1;
|
| 101 |
+
|
| 102 |
+
const scalar_t lh = h - h_low;
|
| 103 |
+
const scalar_t lw = w - w_low;
|
| 104 |
+
const scalar_t hh = 1 - lh, hw = 1 - lw;
|
| 105 |
+
|
| 106 |
+
const int w_stride = nheads * channels;
|
| 107 |
+
const int h_stride = width * w_stride;
|
| 108 |
+
const int h_low_ptr_offset = h_low * h_stride;
|
| 109 |
+
const int h_high_ptr_offset = h_low_ptr_offset + h_stride;
|
| 110 |
+
const int w_low_ptr_offset = w_low * w_stride;
|
| 111 |
+
const int w_high_ptr_offset = w_low_ptr_offset + w_stride;
|
| 112 |
+
const int base_ptr = m * channels + c;
|
| 113 |
+
|
| 114 |
+
const scalar_t w1 = hh * hw, w2 = hh * lw, w3 = lh * hw, w4 = lh * lw;
|
| 115 |
+
const scalar_t top_grad_value = top_grad * attn_weight;
|
| 116 |
+
scalar_t grad_h_weight = 0, grad_w_weight = 0;
|
| 117 |
+
|
| 118 |
+
scalar_t v1 = 0;
|
| 119 |
+
if (h_low >= 0 && w_low >= 0)
|
| 120 |
+
{
|
| 121 |
+
const int ptr1 = h_low_ptr_offset + w_low_ptr_offset + base_ptr;
|
| 122 |
+
v1 = bottom_data[ptr1];
|
| 123 |
+
grad_h_weight -= hw * v1;
|
| 124 |
+
grad_w_weight -= hh * v1;
|
| 125 |
+
atomicAdd(grad_value+ptr1, w1*top_grad_value);
|
| 126 |
+
}
|
| 127 |
+
scalar_t v2 = 0;
|
| 128 |
+
if (h_low >= 0 && w_high <= width - 1)
|
| 129 |
+
{
|
| 130 |
+
const int ptr2 = h_low_ptr_offset + w_high_ptr_offset + base_ptr;
|
| 131 |
+
v2 = bottom_data[ptr2];
|
| 132 |
+
grad_h_weight -= lw * v2;
|
| 133 |
+
grad_w_weight += hh * v2;
|
| 134 |
+
atomicAdd(grad_value+ptr2, w2*top_grad_value);
|
| 135 |
+
}
|
| 136 |
+
scalar_t v3 = 0;
|
| 137 |
+
if (h_high <= height - 1 && w_low >= 0)
|
| 138 |
+
{
|
| 139 |
+
const int ptr3 = h_high_ptr_offset + w_low_ptr_offset + base_ptr;
|
| 140 |
+
v3 = bottom_data[ptr3];
|
| 141 |
+
grad_h_weight += hw * v3;
|
| 142 |
+
grad_w_weight -= lh * v3;
|
| 143 |
+
atomicAdd(grad_value+ptr3, w3*top_grad_value);
|
| 144 |
+
}
|
| 145 |
+
scalar_t v4 = 0;
|
| 146 |
+
if (h_high <= height - 1 && w_high <= width - 1)
|
| 147 |
+
{
|
| 148 |
+
const int ptr4 = h_high_ptr_offset + w_high_ptr_offset + base_ptr;
|
| 149 |
+
v4 = bottom_data[ptr4];
|
| 150 |
+
grad_h_weight += lw * v4;
|
| 151 |
+
grad_w_weight += lh * v4;
|
| 152 |
+
atomicAdd(grad_value+ptr4, w4*top_grad_value);
|
| 153 |
+
}
|
| 154 |
+
|
| 155 |
+
const scalar_t val = (w1 * v1 + w2 * v2 + w3 * v3 + w4 * v4);
|
| 156 |
+
*grad_attn_weight = top_grad * val;
|
| 157 |
+
*grad_sampling_loc = width * grad_w_weight * top_grad_value;
|
| 158 |
+
*(grad_sampling_loc + 1) = height * grad_h_weight * top_grad_value;
|
| 159 |
+
}
|
| 160 |
+
|
| 161 |
+
|
| 162 |
+
template <typename scalar_t>
|
| 163 |
+
__device__ void ms_deform_attn_col2im_bilinear_gm(const scalar_t* &bottom_data,
|
| 164 |
+
const int &height, const int &width, const int &nheads, const int &channels,
|
| 165 |
+
const scalar_t &h, const scalar_t &w, const int &m, const int &c,
|
| 166 |
+
const scalar_t &top_grad,
|
| 167 |
+
const scalar_t &attn_weight,
|
| 168 |
+
scalar_t* &grad_value,
|
| 169 |
+
scalar_t* grad_sampling_loc,
|
| 170 |
+
scalar_t* grad_attn_weight)
|
| 171 |
+
{
|
| 172 |
+
const int h_low = floor(h);
|
| 173 |
+
const int w_low = floor(w);
|
| 174 |
+
const int h_high = h_low + 1;
|
| 175 |
+
const int w_high = w_low + 1;
|
| 176 |
+
|
| 177 |
+
const scalar_t lh = h - h_low;
|
| 178 |
+
const scalar_t lw = w - w_low;
|
| 179 |
+
const scalar_t hh = 1 - lh, hw = 1 - lw;
|
| 180 |
+
|
| 181 |
+
const int w_stride = nheads * channels;
|
| 182 |
+
const int h_stride = width * w_stride;
|
| 183 |
+
const int h_low_ptr_offset = h_low * h_stride;
|
| 184 |
+
const int h_high_ptr_offset = h_low_ptr_offset + h_stride;
|
| 185 |
+
const int w_low_ptr_offset = w_low * w_stride;
|
| 186 |
+
const int w_high_ptr_offset = w_low_ptr_offset + w_stride;
|
| 187 |
+
const int base_ptr = m * channels + c;
|
| 188 |
+
|
| 189 |
+
const scalar_t w1 = hh * hw, w2 = hh * lw, w3 = lh * hw, w4 = lh * lw;
|
| 190 |
+
const scalar_t top_grad_value = top_grad * attn_weight;
|
| 191 |
+
scalar_t grad_h_weight = 0, grad_w_weight = 0;
|
| 192 |
+
|
| 193 |
+
scalar_t v1 = 0;
|
| 194 |
+
if (h_low >= 0 && w_low >= 0)
|
| 195 |
+
{
|
| 196 |
+
const int ptr1 = h_low_ptr_offset + w_low_ptr_offset + base_ptr;
|
| 197 |
+
v1 = bottom_data[ptr1];
|
| 198 |
+
grad_h_weight -= hw * v1;
|
| 199 |
+
grad_w_weight -= hh * v1;
|
| 200 |
+
atomicAdd(grad_value+ptr1, w1*top_grad_value);
|
| 201 |
+
}
|
| 202 |
+
scalar_t v2 = 0;
|
| 203 |
+
if (h_low >= 0 && w_high <= width - 1)
|
| 204 |
+
{
|
| 205 |
+
const int ptr2 = h_low_ptr_offset + w_high_ptr_offset + base_ptr;
|
| 206 |
+
v2 = bottom_data[ptr2];
|
| 207 |
+
grad_h_weight -= lw * v2;
|
| 208 |
+
grad_w_weight += hh * v2;
|
| 209 |
+
atomicAdd(grad_value+ptr2, w2*top_grad_value);
|
| 210 |
+
}
|
| 211 |
+
scalar_t v3 = 0;
|
| 212 |
+
if (h_high <= height - 1 && w_low >= 0)
|
| 213 |
+
{
|
| 214 |
+
const int ptr3 = h_high_ptr_offset + w_low_ptr_offset + base_ptr;
|
| 215 |
+
v3 = bottom_data[ptr3];
|
| 216 |
+
grad_h_weight += hw * v3;
|
| 217 |
+
grad_w_weight -= lh * v3;
|
| 218 |
+
atomicAdd(grad_value+ptr3, w3*top_grad_value);
|
| 219 |
+
}
|
| 220 |
+
scalar_t v4 = 0;
|
| 221 |
+
if (h_high <= height - 1 && w_high <= width - 1)
|
| 222 |
+
{
|
| 223 |
+
const int ptr4 = h_high_ptr_offset + w_high_ptr_offset + base_ptr;
|
| 224 |
+
v4 = bottom_data[ptr4];
|
| 225 |
+
grad_h_weight += lw * v4;
|
| 226 |
+
grad_w_weight += lh * v4;
|
| 227 |
+
atomicAdd(grad_value+ptr4, w4*top_grad_value);
|
| 228 |
+
}
|
| 229 |
+
|
| 230 |
+
const scalar_t val = (w1 * v1 + w2 * v2 + w3 * v3 + w4 * v4);
|
| 231 |
+
atomicAdd(grad_attn_weight, top_grad * val);
|
| 232 |
+
atomicAdd(grad_sampling_loc, width * grad_w_weight * top_grad_value);
|
| 233 |
+
atomicAdd(grad_sampling_loc + 1, height * grad_h_weight * top_grad_value);
|
| 234 |
+
}
|
| 235 |
+
|
| 236 |
+
|
| 237 |
+
template <typename scalar_t>
|
| 238 |
+
__global__ void ms_deformable_im2col_gpu_kernel(const int n,
|
| 239 |
+
const scalar_t *data_value,
|
| 240 |
+
const int64_t *data_spatial_shapes,
|
| 241 |
+
const int64_t *data_level_start_index,
|
| 242 |
+
const scalar_t *data_sampling_loc,
|
| 243 |
+
const scalar_t *data_attn_weight,
|
| 244 |
+
const int batch_size,
|
| 245 |
+
const int spatial_size,
|
| 246 |
+
const int num_heads,
|
| 247 |
+
const int channels,
|
| 248 |
+
const int num_levels,
|
| 249 |
+
const int num_query,
|
| 250 |
+
const int num_point,
|
| 251 |
+
scalar_t *data_col)
|
| 252 |
+
{
|
| 253 |
+
CUDA_KERNEL_LOOP(index, n)
|
| 254 |
+
{
|
| 255 |
+
int _temp = index;
|
| 256 |
+
const int c_col = _temp % channels;
|
| 257 |
+
_temp /= channels;
|
| 258 |
+
const int sampling_index = _temp;
|
| 259 |
+
const int m_col = _temp % num_heads;
|
| 260 |
+
_temp /= num_heads;
|
| 261 |
+
const int q_col = _temp % num_query;
|
| 262 |
+
_temp /= num_query;
|
| 263 |
+
const int b_col = _temp;
|
| 264 |
+
|
| 265 |
+
scalar_t *data_col_ptr = data_col + index;
|
| 266 |
+
int data_weight_ptr = sampling_index * num_levels * num_point;
|
| 267 |
+
int data_loc_w_ptr = data_weight_ptr << 1;
|
| 268 |
+
const int qid_stride = num_heads * channels;
|
| 269 |
+
const int data_value_ptr_init_offset = b_col * spatial_size * qid_stride;
|
| 270 |
+
scalar_t col = 0;
|
| 271 |
+
|
| 272 |
+
for (int l_col=0; l_col < num_levels; ++l_col)
|
| 273 |
+
{
|
| 274 |
+
const int level_start_id = data_level_start_index[l_col];
|
| 275 |
+
const int spatial_h_ptr = l_col << 1;
|
| 276 |
+
const int spatial_h = data_spatial_shapes[spatial_h_ptr];
|
| 277 |
+
const int spatial_w = data_spatial_shapes[spatial_h_ptr + 1];
|
| 278 |
+
const scalar_t *data_value_ptr = data_value + (data_value_ptr_init_offset + level_start_id * qid_stride);
|
| 279 |
+
for (int p_col=0; p_col < num_point; ++p_col)
|
| 280 |
+
{
|
| 281 |
+
const scalar_t loc_w = data_sampling_loc[data_loc_w_ptr];
|
| 282 |
+
const scalar_t loc_h = data_sampling_loc[data_loc_w_ptr + 1];
|
| 283 |
+
const scalar_t weight = data_attn_weight[data_weight_ptr];
|
| 284 |
+
|
| 285 |
+
const scalar_t h_im = loc_h * spatial_h - 0.5;
|
| 286 |
+
const scalar_t w_im = loc_w * spatial_w - 0.5;
|
| 287 |
+
|
| 288 |
+
if (h_im > -1 && w_im > -1 && h_im < spatial_h && w_im < spatial_w)
|
| 289 |
+
{
|
| 290 |
+
col += ms_deform_attn_im2col_bilinear(data_value_ptr, spatial_h, spatial_w, num_heads, channels, h_im, w_im, m_col, c_col) * weight;
|
| 291 |
+
}
|
| 292 |
+
|
| 293 |
+
data_weight_ptr += 1;
|
| 294 |
+
data_loc_w_ptr += 2;
|
| 295 |
+
}
|
| 296 |
+
}
|
| 297 |
+
*data_col_ptr = col;
|
| 298 |
+
}
|
| 299 |
+
}
|
| 300 |
+
|
| 301 |
+
template <typename scalar_t, unsigned int blockSize>
|
| 302 |
+
__global__ void ms_deformable_col2im_gpu_kernel_shm_blocksize_aware_reduce_v1(const int n,
|
| 303 |
+
const scalar_t *grad_col,
|
| 304 |
+
const scalar_t *data_value,
|
| 305 |
+
const int64_t *data_spatial_shapes,
|
| 306 |
+
const int64_t *data_level_start_index,
|
| 307 |
+
const scalar_t *data_sampling_loc,
|
| 308 |
+
const scalar_t *data_attn_weight,
|
| 309 |
+
const int batch_size,
|
| 310 |
+
const int spatial_size,
|
| 311 |
+
const int num_heads,
|
| 312 |
+
const int channels,
|
| 313 |
+
const int num_levels,
|
| 314 |
+
const int num_query,
|
| 315 |
+
const int num_point,
|
| 316 |
+
scalar_t *grad_value,
|
| 317 |
+
scalar_t *grad_sampling_loc,
|
| 318 |
+
scalar_t *grad_attn_weight)
|
| 319 |
+
{
|
| 320 |
+
CUDA_KERNEL_LOOP(index, n)
|
| 321 |
+
{
|
| 322 |
+
__shared__ scalar_t cache_grad_sampling_loc[blockSize * 2];
|
| 323 |
+
__shared__ scalar_t cache_grad_attn_weight[blockSize];
|
| 324 |
+
unsigned int tid = threadIdx.x;
|
| 325 |
+
int _temp = index;
|
| 326 |
+
const int c_col = _temp % channels;
|
| 327 |
+
_temp /= channels;
|
| 328 |
+
const int sampling_index = _temp;
|
| 329 |
+
const int m_col = _temp % num_heads;
|
| 330 |
+
_temp /= num_heads;
|
| 331 |
+
const int q_col = _temp % num_query;
|
| 332 |
+
_temp /= num_query;
|
| 333 |
+
const int b_col = _temp;
|
| 334 |
+
|
| 335 |
+
const scalar_t top_grad = grad_col[index];
|
| 336 |
+
|
| 337 |
+
int data_weight_ptr = sampling_index * num_levels * num_point;
|
| 338 |
+
int data_loc_w_ptr = data_weight_ptr << 1;
|
| 339 |
+
const int grad_sampling_ptr = data_weight_ptr;
|
| 340 |
+
grad_sampling_loc += grad_sampling_ptr << 1;
|
| 341 |
+
grad_attn_weight += grad_sampling_ptr;
|
| 342 |
+
const int grad_weight_stride = 1;
|
| 343 |
+
const int grad_loc_stride = 2;
|
| 344 |
+
const int qid_stride = num_heads * channels;
|
| 345 |
+
const int data_value_ptr_init_offset = b_col * spatial_size * qid_stride;
|
| 346 |
+
|
| 347 |
+
for (int l_col=0; l_col < num_levels; ++l_col)
|
| 348 |
+
{
|
| 349 |
+
const int level_start_id = data_level_start_index[l_col];
|
| 350 |
+
const int spatial_h_ptr = l_col << 1;
|
| 351 |
+
const int spatial_h = data_spatial_shapes[spatial_h_ptr];
|
| 352 |
+
const int spatial_w = data_spatial_shapes[spatial_h_ptr + 1];
|
| 353 |
+
const int value_ptr_offset = data_value_ptr_init_offset + level_start_id * qid_stride;
|
| 354 |
+
const scalar_t *data_value_ptr = data_value + value_ptr_offset;
|
| 355 |
+
scalar_t *grad_value_ptr = grad_value + value_ptr_offset;
|
| 356 |
+
|
| 357 |
+
for (int p_col=0; p_col < num_point; ++p_col)
|
| 358 |
+
{
|
| 359 |
+
const scalar_t loc_w = data_sampling_loc[data_loc_w_ptr];
|
| 360 |
+
const scalar_t loc_h = data_sampling_loc[data_loc_w_ptr + 1];
|
| 361 |
+
const scalar_t weight = data_attn_weight[data_weight_ptr];
|
| 362 |
+
|
| 363 |
+
const scalar_t h_im = loc_h * spatial_h - 0.5;
|
| 364 |
+
const scalar_t w_im = loc_w * spatial_w - 0.5;
|
| 365 |
+
*(cache_grad_sampling_loc+(threadIdx.x << 1)) = 0;
|
| 366 |
+
*(cache_grad_sampling_loc+((threadIdx.x << 1) + 1)) = 0;
|
| 367 |
+
*(cache_grad_attn_weight+threadIdx.x)=0;
|
| 368 |
+
if (h_im > -1 && w_im > -1 && h_im < spatial_h && w_im < spatial_w)
|
| 369 |
+
{
|
| 370 |
+
ms_deform_attn_col2im_bilinear(
|
| 371 |
+
data_value_ptr, spatial_h, spatial_w, num_heads, channels, h_im, w_im, m_col, c_col,
|
| 372 |
+
top_grad, weight, grad_value_ptr,
|
| 373 |
+
cache_grad_sampling_loc+(threadIdx.x << 1), cache_grad_attn_weight+threadIdx.x);
|
| 374 |
+
}
|
| 375 |
+
|
| 376 |
+
__syncthreads();
|
| 377 |
+
if (tid == 0)
|
| 378 |
+
{
|
| 379 |
+
scalar_t _grad_w=cache_grad_sampling_loc[0], _grad_h=cache_grad_sampling_loc[1], _grad_a=cache_grad_attn_weight[0];
|
| 380 |
+
int sid=2;
|
| 381 |
+
for (unsigned int tid = 1; tid < blockSize; ++tid)
|
| 382 |
+
{
|
| 383 |
+
_grad_w += cache_grad_sampling_loc[sid];
|
| 384 |
+
_grad_h += cache_grad_sampling_loc[sid + 1];
|
| 385 |
+
_grad_a += cache_grad_attn_weight[tid];
|
| 386 |
+
sid += 2;
|
| 387 |
+
}
|
| 388 |
+
|
| 389 |
+
|
| 390 |
+
*grad_sampling_loc = _grad_w;
|
| 391 |
+
*(grad_sampling_loc + 1) = _grad_h;
|
| 392 |
+
*grad_attn_weight = _grad_a;
|
| 393 |
+
}
|
| 394 |
+
__syncthreads();
|
| 395 |
+
|
| 396 |
+
data_weight_ptr += 1;
|
| 397 |
+
data_loc_w_ptr += 2;
|
| 398 |
+
grad_attn_weight += grad_weight_stride;
|
| 399 |
+
grad_sampling_loc += grad_loc_stride;
|
| 400 |
+
}
|
| 401 |
+
}
|
| 402 |
+
}
|
| 403 |
+
}
|
| 404 |
+
|
| 405 |
+
|
| 406 |
+
template <typename scalar_t, unsigned int blockSize>
|
| 407 |
+
__global__ void ms_deformable_col2im_gpu_kernel_shm_blocksize_aware_reduce_v2(const int n,
|
| 408 |
+
const scalar_t *grad_col,
|
| 409 |
+
const scalar_t *data_value,
|
| 410 |
+
const int64_t *data_spatial_shapes,
|
| 411 |
+
const int64_t *data_level_start_index,
|
| 412 |
+
const scalar_t *data_sampling_loc,
|
| 413 |
+
const scalar_t *data_attn_weight,
|
| 414 |
+
const int batch_size,
|
| 415 |
+
const int spatial_size,
|
| 416 |
+
const int num_heads,
|
| 417 |
+
const int channels,
|
| 418 |
+
const int num_levels,
|
| 419 |
+
const int num_query,
|
| 420 |
+
const int num_point,
|
| 421 |
+
scalar_t *grad_value,
|
| 422 |
+
scalar_t *grad_sampling_loc,
|
| 423 |
+
scalar_t *grad_attn_weight)
|
| 424 |
+
{
|
| 425 |
+
CUDA_KERNEL_LOOP(index, n)
|
| 426 |
+
{
|
| 427 |
+
__shared__ scalar_t cache_grad_sampling_loc[blockSize * 2];
|
| 428 |
+
__shared__ scalar_t cache_grad_attn_weight[blockSize];
|
| 429 |
+
unsigned int tid = threadIdx.x;
|
| 430 |
+
int _temp = index;
|
| 431 |
+
const int c_col = _temp % channels;
|
| 432 |
+
_temp /= channels;
|
| 433 |
+
const int sampling_index = _temp;
|
| 434 |
+
const int m_col = _temp % num_heads;
|
| 435 |
+
_temp /= num_heads;
|
| 436 |
+
const int q_col = _temp % num_query;
|
| 437 |
+
_temp /= num_query;
|
| 438 |
+
const int b_col = _temp;
|
| 439 |
+
|
| 440 |
+
const scalar_t top_grad = grad_col[index];
|
| 441 |
+
|
| 442 |
+
int data_weight_ptr = sampling_index * num_levels * num_point;
|
| 443 |
+
int data_loc_w_ptr = data_weight_ptr << 1;
|
| 444 |
+
const int grad_sampling_ptr = data_weight_ptr;
|
| 445 |
+
grad_sampling_loc += grad_sampling_ptr << 1;
|
| 446 |
+
grad_attn_weight += grad_sampling_ptr;
|
| 447 |
+
const int grad_weight_stride = 1;
|
| 448 |
+
const int grad_loc_stride = 2;
|
| 449 |
+
const int qid_stride = num_heads * channels;
|
| 450 |
+
const int data_value_ptr_init_offset = b_col * spatial_size * qid_stride;
|
| 451 |
+
|
| 452 |
+
for (int l_col=0; l_col < num_levels; ++l_col)
|
| 453 |
+
{
|
| 454 |
+
const int level_start_id = data_level_start_index[l_col];
|
| 455 |
+
const int spatial_h_ptr = l_col << 1;
|
| 456 |
+
const int spatial_h = data_spatial_shapes[spatial_h_ptr];
|
| 457 |
+
const int spatial_w = data_spatial_shapes[spatial_h_ptr + 1];
|
| 458 |
+
const int value_ptr_offset = data_value_ptr_init_offset + level_start_id * qid_stride;
|
| 459 |
+
const scalar_t *data_value_ptr = data_value + value_ptr_offset;
|
| 460 |
+
scalar_t *grad_value_ptr = grad_value + value_ptr_offset;
|
| 461 |
+
|
| 462 |
+
for (int p_col=0; p_col < num_point; ++p_col)
|
| 463 |
+
{
|
| 464 |
+
const scalar_t loc_w = data_sampling_loc[data_loc_w_ptr];
|
| 465 |
+
const scalar_t loc_h = data_sampling_loc[data_loc_w_ptr + 1];
|
| 466 |
+
const scalar_t weight = data_attn_weight[data_weight_ptr];
|
| 467 |
+
|
| 468 |
+
const scalar_t h_im = loc_h * spatial_h - 0.5;
|
| 469 |
+
const scalar_t w_im = loc_w * spatial_w - 0.5;
|
| 470 |
+
*(cache_grad_sampling_loc+(threadIdx.x << 1)) = 0;
|
| 471 |
+
*(cache_grad_sampling_loc+((threadIdx.x << 1) + 1)) = 0;
|
| 472 |
+
*(cache_grad_attn_weight+threadIdx.x)=0;
|
| 473 |
+
if (h_im > -1 && w_im > -1 && h_im < spatial_h && w_im < spatial_w)
|
| 474 |
+
{
|
| 475 |
+
ms_deform_attn_col2im_bilinear(
|
| 476 |
+
data_value_ptr, spatial_h, spatial_w, num_heads, channels, h_im, w_im, m_col, c_col,
|
| 477 |
+
top_grad, weight, grad_value_ptr,
|
| 478 |
+
cache_grad_sampling_loc+(threadIdx.x << 1), cache_grad_attn_weight+threadIdx.x);
|
| 479 |
+
}
|
| 480 |
+
|
| 481 |
+
__syncthreads();
|
| 482 |
+
|
| 483 |
+
for (unsigned int s=blockSize/2; s>0; s>>=1)
|
| 484 |
+
{
|
| 485 |
+
if (tid < s) {
|
| 486 |
+
const unsigned int xid1 = tid << 1;
|
| 487 |
+
const unsigned int xid2 = (tid + s) << 1;
|
| 488 |
+
cache_grad_attn_weight[tid] += cache_grad_attn_weight[tid + s];
|
| 489 |
+
cache_grad_sampling_loc[xid1] += cache_grad_sampling_loc[xid2];
|
| 490 |
+
cache_grad_sampling_loc[xid1 + 1] += cache_grad_sampling_loc[xid2 + 1];
|
| 491 |
+
}
|
| 492 |
+
__syncthreads();
|
| 493 |
+
}
|
| 494 |
+
|
| 495 |
+
if (tid == 0)
|
| 496 |
+
{
|
| 497 |
+
*grad_sampling_loc = cache_grad_sampling_loc[0];
|
| 498 |
+
*(grad_sampling_loc + 1) = cache_grad_sampling_loc[1];
|
| 499 |
+
*grad_attn_weight = cache_grad_attn_weight[0];
|
| 500 |
+
}
|
| 501 |
+
__syncthreads();
|
| 502 |
+
|
| 503 |
+
data_weight_ptr += 1;
|
| 504 |
+
data_loc_w_ptr += 2;
|
| 505 |
+
grad_attn_weight += grad_weight_stride;
|
| 506 |
+
grad_sampling_loc += grad_loc_stride;
|
| 507 |
+
}
|
| 508 |
+
}
|
| 509 |
+
}
|
| 510 |
+
}
|
| 511 |
+
|
| 512 |
+
|
| 513 |
+
template <typename scalar_t>
|
| 514 |
+
__global__ void ms_deformable_col2im_gpu_kernel_shm_reduce_v1(const int n,
|
| 515 |
+
const scalar_t *grad_col,
|
| 516 |
+
const scalar_t *data_value,
|
| 517 |
+
const int64_t *data_spatial_shapes,
|
| 518 |
+
const int64_t *data_level_start_index,
|
| 519 |
+
const scalar_t *data_sampling_loc,
|
| 520 |
+
const scalar_t *data_attn_weight,
|
| 521 |
+
const int batch_size,
|
| 522 |
+
const int spatial_size,
|
| 523 |
+
const int num_heads,
|
| 524 |
+
const int channels,
|
| 525 |
+
const int num_levels,
|
| 526 |
+
const int num_query,
|
| 527 |
+
const int num_point,
|
| 528 |
+
scalar_t *grad_value,
|
| 529 |
+
scalar_t *grad_sampling_loc,
|
| 530 |
+
scalar_t *grad_attn_weight)
|
| 531 |
+
{
|
| 532 |
+
CUDA_KERNEL_LOOP(index, n)
|
| 533 |
+
{
|
| 534 |
+
extern __shared__ int _s[];
|
| 535 |
+
scalar_t* cache_grad_sampling_loc = (scalar_t*)_s;
|
| 536 |
+
scalar_t* cache_grad_attn_weight = cache_grad_sampling_loc + 2 * blockDim.x;
|
| 537 |
+
unsigned int tid = threadIdx.x;
|
| 538 |
+
int _temp = index;
|
| 539 |
+
const int c_col = _temp % channels;
|
| 540 |
+
_temp /= channels;
|
| 541 |
+
const int sampling_index = _temp;
|
| 542 |
+
const int m_col = _temp % num_heads;
|
| 543 |
+
_temp /= num_heads;
|
| 544 |
+
const int q_col = _temp % num_query;
|
| 545 |
+
_temp /= num_query;
|
| 546 |
+
const int b_col = _temp;
|
| 547 |
+
|
| 548 |
+
const scalar_t top_grad = grad_col[index];
|
| 549 |
+
|
| 550 |
+
int data_weight_ptr = sampling_index * num_levels * num_point;
|
| 551 |
+
int data_loc_w_ptr = data_weight_ptr << 1;
|
| 552 |
+
const int grad_sampling_ptr = data_weight_ptr;
|
| 553 |
+
grad_sampling_loc += grad_sampling_ptr << 1;
|
| 554 |
+
grad_attn_weight += grad_sampling_ptr;
|
| 555 |
+
const int grad_weight_stride = 1;
|
| 556 |
+
const int grad_loc_stride = 2;
|
| 557 |
+
const int qid_stride = num_heads * channels;
|
| 558 |
+
const int data_value_ptr_init_offset = b_col * spatial_size * qid_stride;
|
| 559 |
+
|
| 560 |
+
for (int l_col=0; l_col < num_levels; ++l_col)
|
| 561 |
+
{
|
| 562 |
+
const int level_start_id = data_level_start_index[l_col];
|
| 563 |
+
const int spatial_h_ptr = l_col << 1;
|
| 564 |
+
const int spatial_h = data_spatial_shapes[spatial_h_ptr];
|
| 565 |
+
const int spatial_w = data_spatial_shapes[spatial_h_ptr + 1];
|
| 566 |
+
const int value_ptr_offset = data_value_ptr_init_offset + level_start_id * qid_stride;
|
| 567 |
+
const scalar_t *data_value_ptr = data_value + value_ptr_offset;
|
| 568 |
+
scalar_t *grad_value_ptr = grad_value + value_ptr_offset;
|
| 569 |
+
|
| 570 |
+
for (int p_col=0; p_col < num_point; ++p_col)
|
| 571 |
+
{
|
| 572 |
+
const scalar_t loc_w = data_sampling_loc[data_loc_w_ptr];
|
| 573 |
+
const scalar_t loc_h = data_sampling_loc[data_loc_w_ptr + 1];
|
| 574 |
+
const scalar_t weight = data_attn_weight[data_weight_ptr];
|
| 575 |
+
|
| 576 |
+
const scalar_t h_im = loc_h * spatial_h - 0.5;
|
| 577 |
+
const scalar_t w_im = loc_w * spatial_w - 0.5;
|
| 578 |
+
*(cache_grad_sampling_loc+(threadIdx.x << 1)) = 0;
|
| 579 |
+
*(cache_grad_sampling_loc+((threadIdx.x << 1) + 1)) = 0;
|
| 580 |
+
*(cache_grad_attn_weight+threadIdx.x)=0;
|
| 581 |
+
if (h_im > -1 && w_im > -1 && h_im < spatial_h && w_im < spatial_w)
|
| 582 |
+
{
|
| 583 |
+
ms_deform_attn_col2im_bilinear(
|
| 584 |
+
data_value_ptr, spatial_h, spatial_w, num_heads, channels, h_im, w_im, m_col, c_col,
|
| 585 |
+
top_grad, weight, grad_value_ptr,
|
| 586 |
+
cache_grad_sampling_loc+(threadIdx.x << 1), cache_grad_attn_weight+threadIdx.x);
|
| 587 |
+
}
|
| 588 |
+
|
| 589 |
+
__syncthreads();
|
| 590 |
+
if (tid == 0)
|
| 591 |
+
{
|
| 592 |
+
scalar_t _grad_w=cache_grad_sampling_loc[0], _grad_h=cache_grad_sampling_loc[1], _grad_a=cache_grad_attn_weight[0];
|
| 593 |
+
int sid=2;
|
| 594 |
+
for (unsigned int tid = 1; tid < blockDim.x; ++tid)
|
| 595 |
+
{
|
| 596 |
+
_grad_w += cache_grad_sampling_loc[sid];
|
| 597 |
+
_grad_h += cache_grad_sampling_loc[sid + 1];
|
| 598 |
+
_grad_a += cache_grad_attn_weight[tid];
|
| 599 |
+
sid += 2;
|
| 600 |
+
}
|
| 601 |
+
|
| 602 |
+
|
| 603 |
+
*grad_sampling_loc = _grad_w;
|
| 604 |
+
*(grad_sampling_loc + 1) = _grad_h;
|
| 605 |
+
*grad_attn_weight = _grad_a;
|
| 606 |
+
}
|
| 607 |
+
__syncthreads();
|
| 608 |
+
|
| 609 |
+
data_weight_ptr += 1;
|
| 610 |
+
data_loc_w_ptr += 2;
|
| 611 |
+
grad_attn_weight += grad_weight_stride;
|
| 612 |
+
grad_sampling_loc += grad_loc_stride;
|
| 613 |
+
}
|
| 614 |
+
}
|
| 615 |
+
}
|
| 616 |
+
}
|
| 617 |
+
|
| 618 |
+
template <typename scalar_t>
|
| 619 |
+
__global__ void ms_deformable_col2im_gpu_kernel_shm_reduce_v2(const int n,
|
| 620 |
+
const scalar_t *grad_col,
|
| 621 |
+
const scalar_t *data_value,
|
| 622 |
+
const int64_t *data_spatial_shapes,
|
| 623 |
+
const int64_t *data_level_start_index,
|
| 624 |
+
const scalar_t *data_sampling_loc,
|
| 625 |
+
const scalar_t *data_attn_weight,
|
| 626 |
+
const int batch_size,
|
| 627 |
+
const int spatial_size,
|
| 628 |
+
const int num_heads,
|
| 629 |
+
const int channels,
|
| 630 |
+
const int num_levels,
|
| 631 |
+
const int num_query,
|
| 632 |
+
const int num_point,
|
| 633 |
+
scalar_t *grad_value,
|
| 634 |
+
scalar_t *grad_sampling_loc,
|
| 635 |
+
scalar_t *grad_attn_weight)
|
| 636 |
+
{
|
| 637 |
+
CUDA_KERNEL_LOOP(index, n)
|
| 638 |
+
{
|
| 639 |
+
extern __shared__ int _s[];
|
| 640 |
+
scalar_t* cache_grad_sampling_loc = (scalar_t*)_s;
|
| 641 |
+
scalar_t* cache_grad_attn_weight = cache_grad_sampling_loc + 2 * blockDim.x;
|
| 642 |
+
unsigned int tid = threadIdx.x;
|
| 643 |
+
int _temp = index;
|
| 644 |
+
const int c_col = _temp % channels;
|
| 645 |
+
_temp /= channels;
|
| 646 |
+
const int sampling_index = _temp;
|
| 647 |
+
const int m_col = _temp % num_heads;
|
| 648 |
+
_temp /= num_heads;
|
| 649 |
+
const int q_col = _temp % num_query;
|
| 650 |
+
_temp /= num_query;
|
| 651 |
+
const int b_col = _temp;
|
| 652 |
+
|
| 653 |
+
const scalar_t top_grad = grad_col[index];
|
| 654 |
+
|
| 655 |
+
int data_weight_ptr = sampling_index * num_levels * num_point;
|
| 656 |
+
int data_loc_w_ptr = data_weight_ptr << 1;
|
| 657 |
+
const int grad_sampling_ptr = data_weight_ptr;
|
| 658 |
+
grad_sampling_loc += grad_sampling_ptr << 1;
|
| 659 |
+
grad_attn_weight += grad_sampling_ptr;
|
| 660 |
+
const int grad_weight_stride = 1;
|
| 661 |
+
const int grad_loc_stride = 2;
|
| 662 |
+
const int qid_stride = num_heads * channels;
|
| 663 |
+
const int data_value_ptr_init_offset = b_col * spatial_size * qid_stride;
|
| 664 |
+
|
| 665 |
+
for (int l_col=0; l_col < num_levels; ++l_col)
|
| 666 |
+
{
|
| 667 |
+
const int level_start_id = data_level_start_index[l_col];
|
| 668 |
+
const int spatial_h_ptr = l_col << 1;
|
| 669 |
+
const int spatial_h = data_spatial_shapes[spatial_h_ptr];
|
| 670 |
+
const int spatial_w = data_spatial_shapes[spatial_h_ptr + 1];
|
| 671 |
+
const int value_ptr_offset = data_value_ptr_init_offset + level_start_id * qid_stride;
|
| 672 |
+
const scalar_t *data_value_ptr = data_value + value_ptr_offset;
|
| 673 |
+
scalar_t *grad_value_ptr = grad_value + value_ptr_offset;
|
| 674 |
+
|
| 675 |
+
for (int p_col=0; p_col < num_point; ++p_col)
|
| 676 |
+
{
|
| 677 |
+
const scalar_t loc_w = data_sampling_loc[data_loc_w_ptr];
|
| 678 |
+
const scalar_t loc_h = data_sampling_loc[data_loc_w_ptr + 1];
|
| 679 |
+
const scalar_t weight = data_attn_weight[data_weight_ptr];
|
| 680 |
+
|
| 681 |
+
const scalar_t h_im = loc_h * spatial_h - 0.5;
|
| 682 |
+
const scalar_t w_im = loc_w * spatial_w - 0.5;
|
| 683 |
+
*(cache_grad_sampling_loc+(threadIdx.x << 1)) = 0;
|
| 684 |
+
*(cache_grad_sampling_loc+((threadIdx.x << 1) + 1)) = 0;
|
| 685 |
+
*(cache_grad_attn_weight+threadIdx.x)=0;
|
| 686 |
+
if (h_im > -1 && w_im > -1 && h_im < spatial_h && w_im < spatial_w)
|
| 687 |
+
{
|
| 688 |
+
ms_deform_attn_col2im_bilinear(
|
| 689 |
+
data_value_ptr, spatial_h, spatial_w, num_heads, channels, h_im, w_im, m_col, c_col,
|
| 690 |
+
top_grad, weight, grad_value_ptr,
|
| 691 |
+
cache_grad_sampling_loc+(threadIdx.x << 1), cache_grad_attn_weight+threadIdx.x);
|
| 692 |
+
}
|
| 693 |
+
|
| 694 |
+
__syncthreads();
|
| 695 |
+
|
| 696 |
+
for (unsigned int s=blockDim.x/2, spre=blockDim.x; s>0; s>>=1, spre>>=1)
|
| 697 |
+
{
|
| 698 |
+
if (tid < s) {
|
| 699 |
+
const unsigned int xid1 = tid << 1;
|
| 700 |
+
const unsigned int xid2 = (tid + s) << 1;
|
| 701 |
+
cache_grad_attn_weight[tid] += cache_grad_attn_weight[tid + s];
|
| 702 |
+
cache_grad_sampling_loc[xid1] += cache_grad_sampling_loc[xid2];
|
| 703 |
+
cache_grad_sampling_loc[xid1 + 1] += cache_grad_sampling_loc[xid2 + 1];
|
| 704 |
+
if (tid + (s << 1) < spre)
|
| 705 |
+
{
|
| 706 |
+
cache_grad_attn_weight[tid] += cache_grad_attn_weight[tid + (s << 1)];
|
| 707 |
+
cache_grad_sampling_loc[xid1] += cache_grad_sampling_loc[xid2 + (s << 1)];
|
| 708 |
+
cache_grad_sampling_loc[xid1 + 1] += cache_grad_sampling_loc[xid2 + 1 + (s << 1)];
|
| 709 |
+
}
|
| 710 |
+
}
|
| 711 |
+
__syncthreads();
|
| 712 |
+
}
|
| 713 |
+
|
| 714 |
+
if (tid == 0)
|
| 715 |
+
{
|
| 716 |
+
*grad_sampling_loc = cache_grad_sampling_loc[0];
|
| 717 |
+
*(grad_sampling_loc + 1) = cache_grad_sampling_loc[1];
|
| 718 |
+
*grad_attn_weight = cache_grad_attn_weight[0];
|
| 719 |
+
}
|
| 720 |
+
__syncthreads();
|
| 721 |
+
|
| 722 |
+
data_weight_ptr += 1;
|
| 723 |
+
data_loc_w_ptr += 2;
|
| 724 |
+
grad_attn_weight += grad_weight_stride;
|
| 725 |
+
grad_sampling_loc += grad_loc_stride;
|
| 726 |
+
}
|
| 727 |
+
}
|
| 728 |
+
}
|
| 729 |
+
}
|
| 730 |
+
|
| 731 |
+
template <typename scalar_t>
|
| 732 |
+
__global__ void ms_deformable_col2im_gpu_kernel_shm_reduce_v2_multi_blocks(const int n,
|
| 733 |
+
const scalar_t *grad_col,
|
| 734 |
+
const scalar_t *data_value,
|
| 735 |
+
const int64_t *data_spatial_shapes,
|
| 736 |
+
const int64_t *data_level_start_index,
|
| 737 |
+
const scalar_t *data_sampling_loc,
|
| 738 |
+
const scalar_t *data_attn_weight,
|
| 739 |
+
const int batch_size,
|
| 740 |
+
const int spatial_size,
|
| 741 |
+
const int num_heads,
|
| 742 |
+
const int channels,
|
| 743 |
+
const int num_levels,
|
| 744 |
+
const int num_query,
|
| 745 |
+
const int num_point,
|
| 746 |
+
scalar_t *grad_value,
|
| 747 |
+
scalar_t *grad_sampling_loc,
|
| 748 |
+
scalar_t *grad_attn_weight)
|
| 749 |
+
{
|
| 750 |
+
CUDA_KERNEL_LOOP(index, n)
|
| 751 |
+
{
|
| 752 |
+
extern __shared__ int _s[];
|
| 753 |
+
scalar_t* cache_grad_sampling_loc = (scalar_t*)_s;
|
| 754 |
+
scalar_t* cache_grad_attn_weight = cache_grad_sampling_loc + 2 * blockDim.x;
|
| 755 |
+
unsigned int tid = threadIdx.x;
|
| 756 |
+
int _temp = index;
|
| 757 |
+
const int c_col = _temp % channels;
|
| 758 |
+
_temp /= channels;
|
| 759 |
+
const int sampling_index = _temp;
|
| 760 |
+
const int m_col = _temp % num_heads;
|
| 761 |
+
_temp /= num_heads;
|
| 762 |
+
const int q_col = _temp % num_query;
|
| 763 |
+
_temp /= num_query;
|
| 764 |
+
const int b_col = _temp;
|
| 765 |
+
|
| 766 |
+
const scalar_t top_grad = grad_col[index];
|
| 767 |
+
|
| 768 |
+
int data_weight_ptr = sampling_index * num_levels * num_point;
|
| 769 |
+
int data_loc_w_ptr = data_weight_ptr << 1;
|
| 770 |
+
const int grad_sampling_ptr = data_weight_ptr;
|
| 771 |
+
grad_sampling_loc += grad_sampling_ptr << 1;
|
| 772 |
+
grad_attn_weight += grad_sampling_ptr;
|
| 773 |
+
const int grad_weight_stride = 1;
|
| 774 |
+
const int grad_loc_stride = 2;
|
| 775 |
+
const int qid_stride = num_heads * channels;
|
| 776 |
+
const int data_value_ptr_init_offset = b_col * spatial_size * qid_stride;
|
| 777 |
+
|
| 778 |
+
for (int l_col=0; l_col < num_levels; ++l_col)
|
| 779 |
+
{
|
| 780 |
+
const int level_start_id = data_level_start_index[l_col];
|
| 781 |
+
const int spatial_h_ptr = l_col << 1;
|
| 782 |
+
const int spatial_h = data_spatial_shapes[spatial_h_ptr];
|
| 783 |
+
const int spatial_w = data_spatial_shapes[spatial_h_ptr + 1];
|
| 784 |
+
const int value_ptr_offset = data_value_ptr_init_offset + level_start_id * qid_stride;
|
| 785 |
+
const scalar_t *data_value_ptr = data_value + value_ptr_offset;
|
| 786 |
+
scalar_t *grad_value_ptr = grad_value + value_ptr_offset;
|
| 787 |
+
|
| 788 |
+
for (int p_col=0; p_col < num_point; ++p_col)
|
| 789 |
+
{
|
| 790 |
+
const scalar_t loc_w = data_sampling_loc[data_loc_w_ptr];
|
| 791 |
+
const scalar_t loc_h = data_sampling_loc[data_loc_w_ptr + 1];
|
| 792 |
+
const scalar_t weight = data_attn_weight[data_weight_ptr];
|
| 793 |
+
|
| 794 |
+
const scalar_t h_im = loc_h * spatial_h - 0.5;
|
| 795 |
+
const scalar_t w_im = loc_w * spatial_w - 0.5;
|
| 796 |
+
*(cache_grad_sampling_loc+(threadIdx.x << 1)) = 0;
|
| 797 |
+
*(cache_grad_sampling_loc+((threadIdx.x << 1) + 1)) = 0;
|
| 798 |
+
*(cache_grad_attn_weight+threadIdx.x)=0;
|
| 799 |
+
if (h_im > -1 && w_im > -1 && h_im < spatial_h && w_im < spatial_w)
|
| 800 |
+
{
|
| 801 |
+
ms_deform_attn_col2im_bilinear(
|
| 802 |
+
data_value_ptr, spatial_h, spatial_w, num_heads, channels, h_im, w_im, m_col, c_col,
|
| 803 |
+
top_grad, weight, grad_value_ptr,
|
| 804 |
+
cache_grad_sampling_loc+(threadIdx.x << 1), cache_grad_attn_weight+threadIdx.x);
|
| 805 |
+
}
|
| 806 |
+
|
| 807 |
+
__syncthreads();
|
| 808 |
+
|
| 809 |
+
for (unsigned int s=blockDim.x/2, spre=blockDim.x; s>0; s>>=1, spre>>=1)
|
| 810 |
+
{
|
| 811 |
+
if (tid < s) {
|
| 812 |
+
const unsigned int xid1 = tid << 1;
|
| 813 |
+
const unsigned int xid2 = (tid + s) << 1;
|
| 814 |
+
cache_grad_attn_weight[tid] += cache_grad_attn_weight[tid + s];
|
| 815 |
+
cache_grad_sampling_loc[xid1] += cache_grad_sampling_loc[xid2];
|
| 816 |
+
cache_grad_sampling_loc[xid1 + 1] += cache_grad_sampling_loc[xid2 + 1];
|
| 817 |
+
if (tid + (s << 1) < spre)
|
| 818 |
+
{
|
| 819 |
+
cache_grad_attn_weight[tid] += cache_grad_attn_weight[tid + (s << 1)];
|
| 820 |
+
cache_grad_sampling_loc[xid1] += cache_grad_sampling_loc[xid2 + (s << 1)];
|
| 821 |
+
cache_grad_sampling_loc[xid1 + 1] += cache_grad_sampling_loc[xid2 + 1 + (s << 1)];
|
| 822 |
+
}
|
| 823 |
+
}
|
| 824 |
+
__syncthreads();
|
| 825 |
+
}
|
| 826 |
+
|
| 827 |
+
if (tid == 0)
|
| 828 |
+
{
|
| 829 |
+
atomicAdd(grad_sampling_loc, cache_grad_sampling_loc[0]);
|
| 830 |
+
atomicAdd(grad_sampling_loc + 1, cache_grad_sampling_loc[1]);
|
| 831 |
+
atomicAdd(grad_attn_weight, cache_grad_attn_weight[0]);
|
| 832 |
+
}
|
| 833 |
+
__syncthreads();
|
| 834 |
+
|
| 835 |
+
data_weight_ptr += 1;
|
| 836 |
+
data_loc_w_ptr += 2;
|
| 837 |
+
grad_attn_weight += grad_weight_stride;
|
| 838 |
+
grad_sampling_loc += grad_loc_stride;
|
| 839 |
+
}
|
| 840 |
+
}
|
| 841 |
+
}
|
| 842 |
+
}
|
| 843 |
+
|
| 844 |
+
|
| 845 |
+
template <typename scalar_t>
|
| 846 |
+
__global__ void ms_deformable_col2im_gpu_kernel_gm(const int n,
|
| 847 |
+
const scalar_t *grad_col,
|
| 848 |
+
const scalar_t *data_value,
|
| 849 |
+
const int64_t *data_spatial_shapes,
|
| 850 |
+
const int64_t *data_level_start_index,
|
| 851 |
+
const scalar_t *data_sampling_loc,
|
| 852 |
+
const scalar_t *data_attn_weight,
|
| 853 |
+
const int batch_size,
|
| 854 |
+
const int spatial_size,
|
| 855 |
+
const int num_heads,
|
| 856 |
+
const int channels,
|
| 857 |
+
const int num_levels,
|
| 858 |
+
const int num_query,
|
| 859 |
+
const int num_point,
|
| 860 |
+
scalar_t *grad_value,
|
| 861 |
+
scalar_t *grad_sampling_loc,
|
| 862 |
+
scalar_t *grad_attn_weight)
|
| 863 |
+
{
|
| 864 |
+
CUDA_KERNEL_LOOP(index, n)
|
| 865 |
+
{
|
| 866 |
+
int _temp = index;
|
| 867 |
+
const int c_col = _temp % channels;
|
| 868 |
+
_temp /= channels;
|
| 869 |
+
const int sampling_index = _temp;
|
| 870 |
+
const int m_col = _temp % num_heads;
|
| 871 |
+
_temp /= num_heads;
|
| 872 |
+
const int q_col = _temp % num_query;
|
| 873 |
+
_temp /= num_query;
|
| 874 |
+
const int b_col = _temp;
|
| 875 |
+
|
| 876 |
+
const scalar_t top_grad = grad_col[index];
|
| 877 |
+
|
| 878 |
+
int data_weight_ptr = sampling_index * num_levels * num_point;
|
| 879 |
+
int data_loc_w_ptr = data_weight_ptr << 1;
|
| 880 |
+
const int grad_sampling_ptr = data_weight_ptr;
|
| 881 |
+
grad_sampling_loc += grad_sampling_ptr << 1;
|
| 882 |
+
grad_attn_weight += grad_sampling_ptr;
|
| 883 |
+
const int grad_weight_stride = 1;
|
| 884 |
+
const int grad_loc_stride = 2;
|
| 885 |
+
const int qid_stride = num_heads * channels;
|
| 886 |
+
const int data_value_ptr_init_offset = b_col * spatial_size * qid_stride;
|
| 887 |
+
|
| 888 |
+
for (int l_col=0; l_col < num_levels; ++l_col)
|
| 889 |
+
{
|
| 890 |
+
const int level_start_id = data_level_start_index[l_col];
|
| 891 |
+
const int spatial_h_ptr = l_col << 1;
|
| 892 |
+
const int spatial_h = data_spatial_shapes[spatial_h_ptr];
|
| 893 |
+
const int spatial_w = data_spatial_shapes[spatial_h_ptr + 1];
|
| 894 |
+
const int value_ptr_offset = data_value_ptr_init_offset + level_start_id * qid_stride;
|
| 895 |
+
const scalar_t *data_value_ptr = data_value + value_ptr_offset;
|
| 896 |
+
scalar_t *grad_value_ptr = grad_value + value_ptr_offset;
|
| 897 |
+
|
| 898 |
+
for (int p_col=0; p_col < num_point; ++p_col)
|
| 899 |
+
{
|
| 900 |
+
const scalar_t loc_w = data_sampling_loc[data_loc_w_ptr];
|
| 901 |
+
const scalar_t loc_h = data_sampling_loc[data_loc_w_ptr + 1];
|
| 902 |
+
const scalar_t weight = data_attn_weight[data_weight_ptr];
|
| 903 |
+
|
| 904 |
+
const scalar_t h_im = loc_h * spatial_h - 0.5;
|
| 905 |
+
const scalar_t w_im = loc_w * spatial_w - 0.5;
|
| 906 |
+
if (h_im > -1 && w_im > -1 && h_im < spatial_h && w_im < spatial_w)
|
| 907 |
+
{
|
| 908 |
+
ms_deform_attn_col2im_bilinear_gm(
|
| 909 |
+
data_value_ptr, spatial_h, spatial_w, num_heads, channels, h_im, w_im, m_col, c_col,
|
| 910 |
+
top_grad, weight, grad_value_ptr,
|
| 911 |
+
grad_sampling_loc, grad_attn_weight);
|
| 912 |
+
}
|
| 913 |
+
data_weight_ptr += 1;
|
| 914 |
+
data_loc_w_ptr += 2;
|
| 915 |
+
grad_attn_weight += grad_weight_stride;
|
| 916 |
+
grad_sampling_loc += grad_loc_stride;
|
| 917 |
+
}
|
| 918 |
+
}
|
| 919 |
+
}
|
| 920 |
+
}
|
| 921 |
+
|
| 922 |
+
|
| 923 |
+
template <typename scalar_t>
|
| 924 |
+
void ms_deformable_im2col_cuda(cudaStream_t stream,
|
| 925 |
+
const scalar_t* data_value,
|
| 926 |
+
const int64_t* data_spatial_shapes,
|
| 927 |
+
const int64_t* data_level_start_index,
|
| 928 |
+
const scalar_t* data_sampling_loc,
|
| 929 |
+
const scalar_t* data_attn_weight,
|
| 930 |
+
const int batch_size,
|
| 931 |
+
const int spatial_size,
|
| 932 |
+
const int num_heads,
|
| 933 |
+
const int channels,
|
| 934 |
+
const int num_levels,
|
| 935 |
+
const int num_query,
|
| 936 |
+
const int num_point,
|
| 937 |
+
scalar_t* data_col)
|
| 938 |
+
{
|
| 939 |
+
const int num_kernels = batch_size * num_query * num_heads * channels;
|
| 940 |
+
const int num_actual_kernels = batch_size * num_query * num_heads * channels;
|
| 941 |
+
const int num_threads = CUDA_NUM_THREADS;
|
| 942 |
+
ms_deformable_im2col_gpu_kernel<scalar_t>
|
| 943 |
+
<<<GET_BLOCKS(num_actual_kernels, num_threads), num_threads,
|
| 944 |
+
0, stream>>>(
|
| 945 |
+
num_kernels, data_value, data_spatial_shapes, data_level_start_index, data_sampling_loc, data_attn_weight,
|
| 946 |
+
batch_size, spatial_size, num_heads, channels, num_levels, num_query, num_point, data_col);
|
| 947 |
+
|
| 948 |
+
cudaError_t err = cudaGetLastError();
|
| 949 |
+
if (err != cudaSuccess)
|
| 950 |
+
{
|
| 951 |
+
printf("error in ms_deformable_im2col_cuda: %s\n", cudaGetErrorString(err));
|
| 952 |
+
}
|
| 953 |
+
|
| 954 |
+
}
|
| 955 |
+
|
| 956 |
+
template <typename scalar_t>
|
| 957 |
+
void ms_deformable_col2im_cuda(cudaStream_t stream,
|
| 958 |
+
const scalar_t* grad_col,
|
| 959 |
+
const scalar_t* data_value,
|
| 960 |
+
const int64_t * data_spatial_shapes,
|
| 961 |
+
const int64_t * data_level_start_index,
|
| 962 |
+
const scalar_t * data_sampling_loc,
|
| 963 |
+
const scalar_t * data_attn_weight,
|
| 964 |
+
const int batch_size,
|
| 965 |
+
const int spatial_size,
|
| 966 |
+
const int num_heads,
|
| 967 |
+
const int channels,
|
| 968 |
+
const int num_levels,
|
| 969 |
+
const int num_query,
|
| 970 |
+
const int num_point,
|
| 971 |
+
scalar_t* grad_value,
|
| 972 |
+
scalar_t* grad_sampling_loc,
|
| 973 |
+
scalar_t* grad_attn_weight)
|
| 974 |
+
{
|
| 975 |
+
const int num_threads = (channels > CUDA_NUM_THREADS)?CUDA_NUM_THREADS:channels;
|
| 976 |
+
const int num_kernels = batch_size * num_query * num_heads * channels;
|
| 977 |
+
const int num_actual_kernels = batch_size * num_query * num_heads * channels;
|
| 978 |
+
if (channels > 1024)
|
| 979 |
+
{
|
| 980 |
+
if ((channels & 1023) == 0)
|
| 981 |
+
{
|
| 982 |
+
ms_deformable_col2im_gpu_kernel_shm_reduce_v2_multi_blocks<scalar_t>
|
| 983 |
+
<<<GET_BLOCKS(num_actual_kernels, num_threads), num_threads,
|
| 984 |
+
num_threads*3*sizeof(scalar_t), stream>>>(
|
| 985 |
+
num_kernels,
|
| 986 |
+
grad_col,
|
| 987 |
+
data_value,
|
| 988 |
+
data_spatial_shapes,
|
| 989 |
+
data_level_start_index,
|
| 990 |
+
data_sampling_loc,
|
| 991 |
+
data_attn_weight,
|
| 992 |
+
batch_size,
|
| 993 |
+
spatial_size,
|
| 994 |
+
num_heads,
|
| 995 |
+
channels,
|
| 996 |
+
num_levels,
|
| 997 |
+
num_query,
|
| 998 |
+
num_point,
|
| 999 |
+
grad_value,
|
| 1000 |
+
grad_sampling_loc,
|
| 1001 |
+
grad_attn_weight);
|
| 1002 |
+
}
|
| 1003 |
+
else
|
| 1004 |
+
{
|
| 1005 |
+
ms_deformable_col2im_gpu_kernel_gm<scalar_t>
|
| 1006 |
+
<<<GET_BLOCKS(num_actual_kernels, num_threads), num_threads,
|
| 1007 |
+
0, stream>>>(
|
| 1008 |
+
num_kernels,
|
| 1009 |
+
grad_col,
|
| 1010 |
+
data_value,
|
| 1011 |
+
data_spatial_shapes,
|
| 1012 |
+
data_level_start_index,
|
| 1013 |
+
data_sampling_loc,
|
| 1014 |
+
data_attn_weight,
|
| 1015 |
+
batch_size,
|
| 1016 |
+
spatial_size,
|
| 1017 |
+
num_heads,
|
| 1018 |
+
channels,
|
| 1019 |
+
num_levels,
|
| 1020 |
+
num_query,
|
| 1021 |
+
num_point,
|
| 1022 |
+
grad_value,
|
| 1023 |
+
grad_sampling_loc,
|
| 1024 |
+
grad_attn_weight);
|
| 1025 |
+
}
|
| 1026 |
+
}
|
| 1027 |
+
else{
|
| 1028 |
+
switch(channels)
|
| 1029 |
+
{
|
| 1030 |
+
case 1:
|
| 1031 |
+
ms_deformable_col2im_gpu_kernel_shm_blocksize_aware_reduce_v1<scalar_t, 1>
|
| 1032 |
+
<<<GET_BLOCKS(num_actual_kernels, num_threads), num_threads,
|
| 1033 |
+
0, stream>>>(
|
| 1034 |
+
num_kernels,
|
| 1035 |
+
grad_col,
|
| 1036 |
+
data_value,
|
| 1037 |
+
data_spatial_shapes,
|
| 1038 |
+
data_level_start_index,
|
| 1039 |
+
data_sampling_loc,
|
| 1040 |
+
data_attn_weight,
|
| 1041 |
+
batch_size,
|
| 1042 |
+
spatial_size,
|
| 1043 |
+
num_heads,
|
| 1044 |
+
channels,
|
| 1045 |
+
num_levels,
|
| 1046 |
+
num_query,
|
| 1047 |
+
num_point,
|
| 1048 |
+
grad_value,
|
| 1049 |
+
grad_sampling_loc,
|
| 1050 |
+
grad_attn_weight);
|
| 1051 |
+
break;
|
| 1052 |
+
case 2:
|
| 1053 |
+
ms_deformable_col2im_gpu_kernel_shm_blocksize_aware_reduce_v1<scalar_t, 2>
|
| 1054 |
+
<<<GET_BLOCKS(num_actual_kernels, num_threads), num_threads,
|
| 1055 |
+
0, stream>>>(
|
| 1056 |
+
num_kernels,
|
| 1057 |
+
grad_col,
|
| 1058 |
+
data_value,
|
| 1059 |
+
data_spatial_shapes,
|
| 1060 |
+
data_level_start_index,
|
| 1061 |
+
data_sampling_loc,
|
| 1062 |
+
data_attn_weight,
|
| 1063 |
+
batch_size,
|
| 1064 |
+
spatial_size,
|
| 1065 |
+
num_heads,
|
| 1066 |
+
channels,
|
| 1067 |
+
num_levels,
|
| 1068 |
+
num_query,
|
| 1069 |
+
num_point,
|
| 1070 |
+
grad_value,
|
| 1071 |
+
grad_sampling_loc,
|
| 1072 |
+
grad_attn_weight);
|
| 1073 |
+
break;
|
| 1074 |
+
case 4:
|
| 1075 |
+
ms_deformable_col2im_gpu_kernel_shm_blocksize_aware_reduce_v1<scalar_t, 4>
|
| 1076 |
+
<<<GET_BLOCKS(num_actual_kernels, num_threads), num_threads,
|
| 1077 |
+
0, stream>>>(
|
| 1078 |
+
num_kernels,
|
| 1079 |
+
grad_col,
|
| 1080 |
+
data_value,
|
| 1081 |
+
data_spatial_shapes,
|
| 1082 |
+
data_level_start_index,
|
| 1083 |
+
data_sampling_loc,
|
| 1084 |
+
data_attn_weight,
|
| 1085 |
+
batch_size,
|
| 1086 |
+
spatial_size,
|
| 1087 |
+
num_heads,
|
| 1088 |
+
channels,
|
| 1089 |
+
num_levels,
|
| 1090 |
+
num_query,
|
| 1091 |
+
num_point,
|
| 1092 |
+
grad_value,
|
| 1093 |
+
grad_sampling_loc,
|
| 1094 |
+
grad_attn_weight);
|
| 1095 |
+
break;
|
| 1096 |
+
case 8:
|
| 1097 |
+
ms_deformable_col2im_gpu_kernel_shm_blocksize_aware_reduce_v1<scalar_t, 8>
|
| 1098 |
+
<<<GET_BLOCKS(num_actual_kernels, num_threads), num_threads,
|
| 1099 |
+
0, stream>>>(
|
| 1100 |
+
num_kernels,
|
| 1101 |
+
grad_col,
|
| 1102 |
+
data_value,
|
| 1103 |
+
data_spatial_shapes,
|
| 1104 |
+
data_level_start_index,
|
| 1105 |
+
data_sampling_loc,
|
| 1106 |
+
data_attn_weight,
|
| 1107 |
+
batch_size,
|
| 1108 |
+
spatial_size,
|
| 1109 |
+
num_heads,
|
| 1110 |
+
channels,
|
| 1111 |
+
num_levels,
|
| 1112 |
+
num_query,
|
| 1113 |
+
num_point,
|
| 1114 |
+
grad_value,
|
| 1115 |
+
grad_sampling_loc,
|
| 1116 |
+
grad_attn_weight);
|
| 1117 |
+
break;
|
| 1118 |
+
case 16:
|
| 1119 |
+
ms_deformable_col2im_gpu_kernel_shm_blocksize_aware_reduce_v1<scalar_t, 16>
|
| 1120 |
+
<<<GET_BLOCKS(num_actual_kernels, num_threads), num_threads,
|
| 1121 |
+
0, stream>>>(
|
| 1122 |
+
num_kernels,
|
| 1123 |
+
grad_col,
|
| 1124 |
+
data_value,
|
| 1125 |
+
data_spatial_shapes,
|
| 1126 |
+
data_level_start_index,
|
| 1127 |
+
data_sampling_loc,
|
| 1128 |
+
data_attn_weight,
|
| 1129 |
+
batch_size,
|
| 1130 |
+
spatial_size,
|
| 1131 |
+
num_heads,
|
| 1132 |
+
channels,
|
| 1133 |
+
num_levels,
|
| 1134 |
+
num_query,
|
| 1135 |
+
num_point,
|
| 1136 |
+
grad_value,
|
| 1137 |
+
grad_sampling_loc,
|
| 1138 |
+
grad_attn_weight);
|
| 1139 |
+
break;
|
| 1140 |
+
case 32:
|
| 1141 |
+
ms_deformable_col2im_gpu_kernel_shm_blocksize_aware_reduce_v1<scalar_t, 32>
|
| 1142 |
+
<<<GET_BLOCKS(num_actual_kernels, num_threads), num_threads,
|
| 1143 |
+
0, stream>>>(
|
| 1144 |
+
num_kernels,
|
| 1145 |
+
grad_col,
|
| 1146 |
+
data_value,
|
| 1147 |
+
data_spatial_shapes,
|
| 1148 |
+
data_level_start_index,
|
| 1149 |
+
data_sampling_loc,
|
| 1150 |
+
data_attn_weight,
|
| 1151 |
+
batch_size,
|
| 1152 |
+
spatial_size,
|
| 1153 |
+
num_heads,
|
| 1154 |
+
channels,
|
| 1155 |
+
num_levels,
|
| 1156 |
+
num_query,
|
| 1157 |
+
num_point,
|
| 1158 |
+
grad_value,
|
| 1159 |
+
grad_sampling_loc,
|
| 1160 |
+
grad_attn_weight);
|
| 1161 |
+
break;
|
| 1162 |
+
case 64:
|
| 1163 |
+
ms_deformable_col2im_gpu_kernel_shm_blocksize_aware_reduce_v2<scalar_t, 64>
|
| 1164 |
+
<<<GET_BLOCKS(num_actual_kernels, num_threads), num_threads,
|
| 1165 |
+
0, stream>>>(
|
| 1166 |
+
num_kernels,
|
| 1167 |
+
grad_col,
|
| 1168 |
+
data_value,
|
| 1169 |
+
data_spatial_shapes,
|
| 1170 |
+
data_level_start_index,
|
| 1171 |
+
data_sampling_loc,
|
| 1172 |
+
data_attn_weight,
|
| 1173 |
+
batch_size,
|
| 1174 |
+
spatial_size,
|
| 1175 |
+
num_heads,
|
| 1176 |
+
channels,
|
| 1177 |
+
num_levels,
|
| 1178 |
+
num_query,
|
| 1179 |
+
num_point,
|
| 1180 |
+
grad_value,
|
| 1181 |
+
grad_sampling_loc,
|
| 1182 |
+
grad_attn_weight);
|
| 1183 |
+
break;
|
| 1184 |
+
case 128:
|
| 1185 |
+
ms_deformable_col2im_gpu_kernel_shm_blocksize_aware_reduce_v2<scalar_t, 128>
|
| 1186 |
+
<<<GET_BLOCKS(num_actual_kernels, num_threads), num_threads,
|
| 1187 |
+
0, stream>>>(
|
| 1188 |
+
num_kernels,
|
| 1189 |
+
grad_col,
|
| 1190 |
+
data_value,
|
| 1191 |
+
data_spatial_shapes,
|
| 1192 |
+
data_level_start_index,
|
| 1193 |
+
data_sampling_loc,
|
| 1194 |
+
data_attn_weight,
|
| 1195 |
+
batch_size,
|
| 1196 |
+
spatial_size,
|
| 1197 |
+
num_heads,
|
| 1198 |
+
channels,
|
| 1199 |
+
num_levels,
|
| 1200 |
+
num_query,
|
| 1201 |
+
num_point,
|
| 1202 |
+
grad_value,
|
| 1203 |
+
grad_sampling_loc,
|
| 1204 |
+
grad_attn_weight);
|
| 1205 |
+
break;
|
| 1206 |
+
case 256:
|
| 1207 |
+
ms_deformable_col2im_gpu_kernel_shm_blocksize_aware_reduce_v2<scalar_t, 256>
|
| 1208 |
+
<<<GET_BLOCKS(num_actual_kernels, num_threads), num_threads,
|
| 1209 |
+
0, stream>>>(
|
| 1210 |
+
num_kernels,
|
| 1211 |
+
grad_col,
|
| 1212 |
+
data_value,
|
| 1213 |
+
data_spatial_shapes,
|
| 1214 |
+
data_level_start_index,
|
| 1215 |
+
data_sampling_loc,
|
| 1216 |
+
data_attn_weight,
|
| 1217 |
+
batch_size,
|
| 1218 |
+
spatial_size,
|
| 1219 |
+
num_heads,
|
| 1220 |
+
channels,
|
| 1221 |
+
num_levels,
|
| 1222 |
+
num_query,
|
| 1223 |
+
num_point,
|
| 1224 |
+
grad_value,
|
| 1225 |
+
grad_sampling_loc,
|
| 1226 |
+
grad_attn_weight);
|
| 1227 |
+
break;
|
| 1228 |
+
case 512:
|
| 1229 |
+
ms_deformable_col2im_gpu_kernel_shm_blocksize_aware_reduce_v2<scalar_t, 512>
|
| 1230 |
+
<<<GET_BLOCKS(num_actual_kernels, num_threads), num_threads,
|
| 1231 |
+
0, stream>>>(
|
| 1232 |
+
num_kernels,
|
| 1233 |
+
grad_col,
|
| 1234 |
+
data_value,
|
| 1235 |
+
data_spatial_shapes,
|
| 1236 |
+
data_level_start_index,
|
| 1237 |
+
data_sampling_loc,
|
| 1238 |
+
data_attn_weight,
|
| 1239 |
+
batch_size,
|
| 1240 |
+
spatial_size,
|
| 1241 |
+
num_heads,
|
| 1242 |
+
channels,
|
| 1243 |
+
num_levels,
|
| 1244 |
+
num_query,
|
| 1245 |
+
num_point,
|
| 1246 |
+
grad_value,
|
| 1247 |
+
grad_sampling_loc,
|
| 1248 |
+
grad_attn_weight);
|
| 1249 |
+
break;
|
| 1250 |
+
case 1024:
|
| 1251 |
+
ms_deformable_col2im_gpu_kernel_shm_blocksize_aware_reduce_v2<scalar_t, 1024>
|
| 1252 |
+
<<<GET_BLOCKS(num_actual_kernels, num_threads), num_threads,
|
| 1253 |
+
0, stream>>>(
|
| 1254 |
+
num_kernels,
|
| 1255 |
+
grad_col,
|
| 1256 |
+
data_value,
|
| 1257 |
+
data_spatial_shapes,
|
| 1258 |
+
data_level_start_index,
|
| 1259 |
+
data_sampling_loc,
|
| 1260 |
+
data_attn_weight,
|
| 1261 |
+
batch_size,
|
| 1262 |
+
spatial_size,
|
| 1263 |
+
num_heads,
|
| 1264 |
+
channels,
|
| 1265 |
+
num_levels,
|
| 1266 |
+
num_query,
|
| 1267 |
+
num_point,
|
| 1268 |
+
grad_value,
|
| 1269 |
+
grad_sampling_loc,
|
| 1270 |
+
grad_attn_weight);
|
| 1271 |
+
break;
|
| 1272 |
+
default:
|
| 1273 |
+
if (channels < 64)
|
| 1274 |
+
{
|
| 1275 |
+
ms_deformable_col2im_gpu_kernel_shm_reduce_v1<scalar_t>
|
| 1276 |
+
<<<GET_BLOCKS(num_actual_kernels, num_threads), num_threads,
|
| 1277 |
+
num_threads*3*sizeof(scalar_t), stream>>>(
|
| 1278 |
+
num_kernels,
|
| 1279 |
+
grad_col,
|
| 1280 |
+
data_value,
|
| 1281 |
+
data_spatial_shapes,
|
| 1282 |
+
data_level_start_index,
|
| 1283 |
+
data_sampling_loc,
|
| 1284 |
+
data_attn_weight,
|
| 1285 |
+
batch_size,
|
| 1286 |
+
spatial_size,
|
| 1287 |
+
num_heads,
|
| 1288 |
+
channels,
|
| 1289 |
+
num_levels,
|
| 1290 |
+
num_query,
|
| 1291 |
+
num_point,
|
| 1292 |
+
grad_value,
|
| 1293 |
+
grad_sampling_loc,
|
| 1294 |
+
grad_attn_weight);
|
| 1295 |
+
}
|
| 1296 |
+
else
|
| 1297 |
+
{
|
| 1298 |
+
ms_deformable_col2im_gpu_kernel_shm_reduce_v2<scalar_t>
|
| 1299 |
+
<<<GET_BLOCKS(num_actual_kernels, num_threads), num_threads,
|
| 1300 |
+
num_threads*3*sizeof(scalar_t), stream>>>(
|
| 1301 |
+
num_kernels,
|
| 1302 |
+
grad_col,
|
| 1303 |
+
data_value,
|
| 1304 |
+
data_spatial_shapes,
|
| 1305 |
+
data_level_start_index,
|
| 1306 |
+
data_sampling_loc,
|
| 1307 |
+
data_attn_weight,
|
| 1308 |
+
batch_size,
|
| 1309 |
+
spatial_size,
|
| 1310 |
+
num_heads,
|
| 1311 |
+
channels,
|
| 1312 |
+
num_levels,
|
| 1313 |
+
num_query,
|
| 1314 |
+
num_point,
|
| 1315 |
+
grad_value,
|
| 1316 |
+
grad_sampling_loc,
|
| 1317 |
+
grad_attn_weight);
|
| 1318 |
+
}
|
| 1319 |
+
}
|
| 1320 |
+
}
|
| 1321 |
+
cudaError_t err = cudaGetLastError();
|
| 1322 |
+
if (err != cudaSuccess)
|
| 1323 |
+
{
|
| 1324 |
+
printf("error in ms_deformable_col2im_cuda: %s\n", cudaGetErrorString(err));
|
| 1325 |
+
}
|
| 1326 |
+
|
| 1327 |
+
}
|
One-to-All-Animation/benchmark/DisCo/annotator/grounded-sam/GroundingDINO/groundingdino/models/GroundingDINO/csrc/cuda_version.cu
ADDED
|
@@ -0,0 +1,7 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
#include <cuda_runtime_api.h>
|
| 2 |
+
|
| 3 |
+
namespace groundingdino {
|
| 4 |
+
int get_cudart_version() {
|
| 5 |
+
return CUDART_VERSION;
|
| 6 |
+
}
|
| 7 |
+
} // namespace groundingdino
|
One-to-All-Animation/benchmark/DisCo/annotator/grounded-sam/GroundingDINO/groundingdino/models/GroundingDINO/csrc/vision.cpp
ADDED
|
@@ -0,0 +1,58 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
// Copyright (c) Facebook, Inc. and its affiliates. All Rights Reserved
|
| 2 |
+
|
| 3 |
+
#include "MsDeformAttn/ms_deform_attn.h"
|
| 4 |
+
|
| 5 |
+
namespace groundingdino {
|
| 6 |
+
|
| 7 |
+
#ifdef WITH_CUDA
|
| 8 |
+
extern int get_cudart_version();
|
| 9 |
+
#endif
|
| 10 |
+
|
| 11 |
+
std::string get_cuda_version() {
|
| 12 |
+
#ifdef WITH_CUDA
|
| 13 |
+
std::ostringstream oss;
|
| 14 |
+
|
| 15 |
+
// copied from
|
| 16 |
+
// https://github.com/pytorch/pytorch/blob/master/aten/src/ATen/cuda/detail/CUDAHooks.cpp#L231
|
| 17 |
+
auto printCudaStyleVersion = [&](int v) {
|
| 18 |
+
oss << (v / 1000) << "." << (v / 10 % 100);
|
| 19 |
+
if (v % 10 != 0) {
|
| 20 |
+
oss << "." << (v % 10);
|
| 21 |
+
}
|
| 22 |
+
};
|
| 23 |
+
printCudaStyleVersion(get_cudart_version());
|
| 24 |
+
return oss.str();
|
| 25 |
+
#else
|
| 26 |
+
return std::string("not available");
|
| 27 |
+
#endif
|
| 28 |
+
}
|
| 29 |
+
|
| 30 |
+
// similar to
|
| 31 |
+
// https://github.com/pytorch/pytorch/blob/master/aten/src/ATen/Version.cpp
|
| 32 |
+
std::string get_compiler_version() {
|
| 33 |
+
std::ostringstream ss;
|
| 34 |
+
#if defined(__GNUC__)
|
| 35 |
+
#ifndef __clang__
|
| 36 |
+
{ ss << "GCC " << __GNUC__ << "." << __GNUC_MINOR__; }
|
| 37 |
+
#endif
|
| 38 |
+
#endif
|
| 39 |
+
|
| 40 |
+
#if defined(__clang_major__)
|
| 41 |
+
{
|
| 42 |
+
ss << "clang " << __clang_major__ << "." << __clang_minor__ << "."
|
| 43 |
+
<< __clang_patchlevel__;
|
| 44 |
+
}
|
| 45 |
+
#endif
|
| 46 |
+
|
| 47 |
+
#if defined(_MSC_VER)
|
| 48 |
+
{ ss << "MSVC " << _MSC_FULL_VER; }
|
| 49 |
+
#endif
|
| 50 |
+
return ss.str();
|
| 51 |
+
}
|
| 52 |
+
|
| 53 |
+
PYBIND11_MODULE(TORCH_EXTENSION_NAME, m) {
|
| 54 |
+
m.def("ms_deform_attn_forward", &ms_deform_attn_forward, "ms_deform_attn_forward");
|
| 55 |
+
m.def("ms_deform_attn_backward", &ms_deform_attn_backward, "ms_deform_attn_backward");
|
| 56 |
+
}
|
| 57 |
+
|
| 58 |
+
} // namespace groundingdino
|
One-to-All-Animation/benchmark/DisCo/annotator/grounded-sam/GroundingDINO/groundingdino/models/GroundingDINO/fuse_modules.py
ADDED
|
@@ -0,0 +1,297 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
# ------------------------------------------------------------------------
|
| 2 |
+
# Grounding DINO
|
| 3 |
+
# url: https://github.com/IDEA-Research/GroundingDINO
|
| 4 |
+
# Copyright (c) 2023 IDEA. All Rights Reserved.
|
| 5 |
+
# Licensed under the Apache License, Version 2.0 [see LICENSE for details]
|
| 6 |
+
# ------------------------------------------------------------------------
|
| 7 |
+
|
| 8 |
+
import torch
|
| 9 |
+
import torch.nn as nn
|
| 10 |
+
import torch.nn.functional as F
|
| 11 |
+
from timm.models.layers import DropPath
|
| 12 |
+
|
| 13 |
+
|
| 14 |
+
class FeatureResizer(nn.Module):
|
| 15 |
+
"""
|
| 16 |
+
This class takes as input a set of embeddings of dimension C1 and outputs a set of
|
| 17 |
+
embedding of dimension C2, after a linear transformation, dropout and normalization (LN).
|
| 18 |
+
"""
|
| 19 |
+
|
| 20 |
+
def __init__(self, input_feat_size, output_feat_size, dropout, do_ln=True):
|
| 21 |
+
super().__init__()
|
| 22 |
+
self.do_ln = do_ln
|
| 23 |
+
# Object feature encoding
|
| 24 |
+
self.fc = nn.Linear(input_feat_size, output_feat_size, bias=True)
|
| 25 |
+
self.layer_norm = nn.LayerNorm(output_feat_size, eps=1e-12)
|
| 26 |
+
self.dropout = nn.Dropout(dropout)
|
| 27 |
+
|
| 28 |
+
def forward(self, encoder_features):
|
| 29 |
+
x = self.fc(encoder_features)
|
| 30 |
+
if self.do_ln:
|
| 31 |
+
x = self.layer_norm(x)
|
| 32 |
+
output = self.dropout(x)
|
| 33 |
+
return output
|
| 34 |
+
|
| 35 |
+
|
| 36 |
+
def l1norm(X, dim, eps=1e-8):
|
| 37 |
+
"""L1-normalize columns of X"""
|
| 38 |
+
norm = torch.abs(X).sum(dim=dim, keepdim=True) + eps
|
| 39 |
+
X = torch.div(X, norm)
|
| 40 |
+
return X
|
| 41 |
+
|
| 42 |
+
|
| 43 |
+
def l2norm(X, dim, eps=1e-8):
|
| 44 |
+
"""L2-normalize columns of X"""
|
| 45 |
+
norm = torch.pow(X, 2).sum(dim=dim, keepdim=True).sqrt() + eps
|
| 46 |
+
X = torch.div(X, norm)
|
| 47 |
+
return X
|
| 48 |
+
|
| 49 |
+
|
| 50 |
+
def func_attention(query, context, smooth=1, raw_feature_norm="softmax", eps=1e-8):
|
| 51 |
+
"""
|
| 52 |
+
query: (n_context, queryL, d)
|
| 53 |
+
context: (n_context, sourceL, d)
|
| 54 |
+
"""
|
| 55 |
+
batch_size_q, queryL = query.size(0), query.size(1)
|
| 56 |
+
batch_size, sourceL = context.size(0), context.size(1)
|
| 57 |
+
|
| 58 |
+
# Get attention
|
| 59 |
+
# --> (batch, d, queryL)
|
| 60 |
+
queryT = torch.transpose(query, 1, 2)
|
| 61 |
+
|
| 62 |
+
# (batch, sourceL, d)(batch, d, queryL)
|
| 63 |
+
# --> (batch, sourceL, queryL)
|
| 64 |
+
attn = torch.bmm(context, queryT)
|
| 65 |
+
if raw_feature_norm == "softmax":
|
| 66 |
+
# --> (batch*sourceL, queryL)
|
| 67 |
+
attn = attn.view(batch_size * sourceL, queryL)
|
| 68 |
+
attn = nn.Softmax()(attn)
|
| 69 |
+
# --> (batch, sourceL, queryL)
|
| 70 |
+
attn = attn.view(batch_size, sourceL, queryL)
|
| 71 |
+
elif raw_feature_norm == "l2norm":
|
| 72 |
+
attn = l2norm(attn, 2)
|
| 73 |
+
elif raw_feature_norm == "clipped_l2norm":
|
| 74 |
+
attn = nn.LeakyReLU(0.1)(attn)
|
| 75 |
+
attn = l2norm(attn, 2)
|
| 76 |
+
else:
|
| 77 |
+
raise ValueError("unknown first norm type:", raw_feature_norm)
|
| 78 |
+
# --> (batch, queryL, sourceL)
|
| 79 |
+
attn = torch.transpose(attn, 1, 2).contiguous()
|
| 80 |
+
# --> (batch*queryL, sourceL)
|
| 81 |
+
attn = attn.view(batch_size * queryL, sourceL)
|
| 82 |
+
attn = nn.Softmax()(attn * smooth)
|
| 83 |
+
# --> (batch, queryL, sourceL)
|
| 84 |
+
attn = attn.view(batch_size, queryL, sourceL)
|
| 85 |
+
# --> (batch, sourceL, queryL)
|
| 86 |
+
attnT = torch.transpose(attn, 1, 2).contiguous()
|
| 87 |
+
|
| 88 |
+
# --> (batch, d, sourceL)
|
| 89 |
+
contextT = torch.transpose(context, 1, 2)
|
| 90 |
+
# (batch x d x sourceL)(batch x sourceL x queryL)
|
| 91 |
+
# --> (batch, d, queryL)
|
| 92 |
+
weightedContext = torch.bmm(contextT, attnT)
|
| 93 |
+
# --> (batch, queryL, d)
|
| 94 |
+
weightedContext = torch.transpose(weightedContext, 1, 2)
|
| 95 |
+
|
| 96 |
+
return weightedContext, attnT
|
| 97 |
+
|
| 98 |
+
|
| 99 |
+
class BiMultiHeadAttention(nn.Module):
|
| 100 |
+
def __init__(self, v_dim, l_dim, embed_dim, num_heads, dropout=0.1, cfg=None):
|
| 101 |
+
super(BiMultiHeadAttention, self).__init__()
|
| 102 |
+
|
| 103 |
+
self.embed_dim = embed_dim
|
| 104 |
+
self.num_heads = num_heads
|
| 105 |
+
self.head_dim = embed_dim // num_heads
|
| 106 |
+
self.v_dim = v_dim
|
| 107 |
+
self.l_dim = l_dim
|
| 108 |
+
|
| 109 |
+
assert (
|
| 110 |
+
self.head_dim * self.num_heads == self.embed_dim
|
| 111 |
+
), f"embed_dim must be divisible by num_heads (got `embed_dim`: {self.embed_dim} and `num_heads`: {self.num_heads})."
|
| 112 |
+
self.scale = self.head_dim ** (-0.5)
|
| 113 |
+
self.dropout = dropout
|
| 114 |
+
|
| 115 |
+
self.v_proj = nn.Linear(self.v_dim, self.embed_dim)
|
| 116 |
+
self.l_proj = nn.Linear(self.l_dim, self.embed_dim)
|
| 117 |
+
self.values_v_proj = nn.Linear(self.v_dim, self.embed_dim)
|
| 118 |
+
self.values_l_proj = nn.Linear(self.l_dim, self.embed_dim)
|
| 119 |
+
|
| 120 |
+
self.out_v_proj = nn.Linear(self.embed_dim, self.v_dim)
|
| 121 |
+
self.out_l_proj = nn.Linear(self.embed_dim, self.l_dim)
|
| 122 |
+
|
| 123 |
+
self.stable_softmax_2d = True
|
| 124 |
+
self.clamp_min_for_underflow = True
|
| 125 |
+
self.clamp_max_for_overflow = True
|
| 126 |
+
|
| 127 |
+
self._reset_parameters()
|
| 128 |
+
|
| 129 |
+
def _shape(self, tensor: torch.Tensor, seq_len: int, bsz: int):
|
| 130 |
+
return tensor.view(bsz, seq_len, self.num_heads, self.head_dim).transpose(1, 2).contiguous()
|
| 131 |
+
|
| 132 |
+
def _reset_parameters(self):
|
| 133 |
+
nn.init.xavier_uniform_(self.v_proj.weight)
|
| 134 |
+
self.v_proj.bias.data.fill_(0)
|
| 135 |
+
nn.init.xavier_uniform_(self.l_proj.weight)
|
| 136 |
+
self.l_proj.bias.data.fill_(0)
|
| 137 |
+
nn.init.xavier_uniform_(self.values_v_proj.weight)
|
| 138 |
+
self.values_v_proj.bias.data.fill_(0)
|
| 139 |
+
nn.init.xavier_uniform_(self.values_l_proj.weight)
|
| 140 |
+
self.values_l_proj.bias.data.fill_(0)
|
| 141 |
+
nn.init.xavier_uniform_(self.out_v_proj.weight)
|
| 142 |
+
self.out_v_proj.bias.data.fill_(0)
|
| 143 |
+
nn.init.xavier_uniform_(self.out_l_proj.weight)
|
| 144 |
+
self.out_l_proj.bias.data.fill_(0)
|
| 145 |
+
|
| 146 |
+
def forward(self, v, l, attention_mask_v=None, attention_mask_l=None):
|
| 147 |
+
"""_summary_
|
| 148 |
+
|
| 149 |
+
Args:
|
| 150 |
+
v (_type_): bs, n_img, dim
|
| 151 |
+
l (_type_): bs, n_text, dim
|
| 152 |
+
attention_mask_v (_type_, optional): _description_. bs, n_img
|
| 153 |
+
attention_mask_l (_type_, optional): _description_. bs, n_text
|
| 154 |
+
|
| 155 |
+
Returns:
|
| 156 |
+
_type_: _description_
|
| 157 |
+
"""
|
| 158 |
+
# if os.environ.get('IPDB_SHILONG_DEBUG', None) == 'INFO':
|
| 159 |
+
# import ipdb; ipdb.set_trace()
|
| 160 |
+
bsz, tgt_len, _ = v.size()
|
| 161 |
+
|
| 162 |
+
query_states = self.v_proj(v) * self.scale
|
| 163 |
+
key_states = self._shape(self.l_proj(l), -1, bsz)
|
| 164 |
+
value_v_states = self._shape(self.values_v_proj(v), -1, bsz)
|
| 165 |
+
value_l_states = self._shape(self.values_l_proj(l), -1, bsz)
|
| 166 |
+
|
| 167 |
+
proj_shape = (bsz * self.num_heads, -1, self.head_dim)
|
| 168 |
+
query_states = self._shape(query_states, tgt_len, bsz).view(*proj_shape)
|
| 169 |
+
key_states = key_states.view(*proj_shape)
|
| 170 |
+
value_v_states = value_v_states.view(*proj_shape)
|
| 171 |
+
value_l_states = value_l_states.view(*proj_shape)
|
| 172 |
+
|
| 173 |
+
src_len = key_states.size(1)
|
| 174 |
+
attn_weights = torch.bmm(query_states, key_states.transpose(1, 2)) # bs*nhead, nimg, ntxt
|
| 175 |
+
|
| 176 |
+
if attn_weights.size() != (bsz * self.num_heads, tgt_len, src_len):
|
| 177 |
+
raise ValueError(
|
| 178 |
+
f"Attention weights should be of size {(bsz * self.num_heads, tgt_len, src_len)}, but is {attn_weights.size()}"
|
| 179 |
+
)
|
| 180 |
+
|
| 181 |
+
if self.stable_softmax_2d:
|
| 182 |
+
attn_weights = attn_weights - attn_weights.max()
|
| 183 |
+
|
| 184 |
+
if self.clamp_min_for_underflow:
|
| 185 |
+
attn_weights = torch.clamp(
|
| 186 |
+
attn_weights, min=-50000
|
| 187 |
+
) # Do not increase -50000, data type half has quite limited range
|
| 188 |
+
if self.clamp_max_for_overflow:
|
| 189 |
+
attn_weights = torch.clamp(
|
| 190 |
+
attn_weights, max=50000
|
| 191 |
+
) # Do not increase 50000, data type half has quite limited range
|
| 192 |
+
|
| 193 |
+
attn_weights_T = attn_weights.transpose(1, 2)
|
| 194 |
+
attn_weights_l = attn_weights_T - torch.max(attn_weights_T, dim=-1, keepdim=True)[0]
|
| 195 |
+
if self.clamp_min_for_underflow:
|
| 196 |
+
attn_weights_l = torch.clamp(
|
| 197 |
+
attn_weights_l, min=-50000
|
| 198 |
+
) # Do not increase -50000, data type half has quite limited range
|
| 199 |
+
if self.clamp_max_for_overflow:
|
| 200 |
+
attn_weights_l = torch.clamp(
|
| 201 |
+
attn_weights_l, max=50000
|
| 202 |
+
) # Do not increase 50000, data type half has quite limited range
|
| 203 |
+
|
| 204 |
+
# mask vison for language
|
| 205 |
+
if attention_mask_v is not None:
|
| 206 |
+
attention_mask_v = (
|
| 207 |
+
attention_mask_v[:, None, None, :].repeat(1, self.num_heads, 1, 1).flatten(0, 1)
|
| 208 |
+
)
|
| 209 |
+
attn_weights_l.masked_fill_(attention_mask_v, float("-inf"))
|
| 210 |
+
|
| 211 |
+
attn_weights_l = attn_weights_l.softmax(dim=-1)
|
| 212 |
+
|
| 213 |
+
# mask language for vision
|
| 214 |
+
if attention_mask_l is not None:
|
| 215 |
+
attention_mask_l = (
|
| 216 |
+
attention_mask_l[:, None, None, :].repeat(1, self.num_heads, 1, 1).flatten(0, 1)
|
| 217 |
+
)
|
| 218 |
+
attn_weights.masked_fill_(attention_mask_l, float("-inf"))
|
| 219 |
+
attn_weights_v = attn_weights.softmax(dim=-1)
|
| 220 |
+
|
| 221 |
+
attn_probs_v = F.dropout(attn_weights_v, p=self.dropout, training=self.training)
|
| 222 |
+
attn_probs_l = F.dropout(attn_weights_l, p=self.dropout, training=self.training)
|
| 223 |
+
|
| 224 |
+
attn_output_v = torch.bmm(attn_probs_v, value_l_states)
|
| 225 |
+
attn_output_l = torch.bmm(attn_probs_l, value_v_states)
|
| 226 |
+
|
| 227 |
+
if attn_output_v.size() != (bsz * self.num_heads, tgt_len, self.head_dim):
|
| 228 |
+
raise ValueError(
|
| 229 |
+
f"`attn_output_v` should be of size {(bsz, self.num_heads, tgt_len, self.head_dim)}, but is {attn_output_v.size()}"
|
| 230 |
+
)
|
| 231 |
+
|
| 232 |
+
if attn_output_l.size() != (bsz * self.num_heads, src_len, self.head_dim):
|
| 233 |
+
raise ValueError(
|
| 234 |
+
f"`attn_output_l` should be of size {(bsz, self.num_heads, src_len, self.head_dim)}, but is {attn_output_l.size()}"
|
| 235 |
+
)
|
| 236 |
+
|
| 237 |
+
attn_output_v = attn_output_v.view(bsz, self.num_heads, tgt_len, self.head_dim)
|
| 238 |
+
attn_output_v = attn_output_v.transpose(1, 2)
|
| 239 |
+
attn_output_v = attn_output_v.reshape(bsz, tgt_len, self.embed_dim)
|
| 240 |
+
|
| 241 |
+
attn_output_l = attn_output_l.view(bsz, self.num_heads, src_len, self.head_dim)
|
| 242 |
+
attn_output_l = attn_output_l.transpose(1, 2)
|
| 243 |
+
attn_output_l = attn_output_l.reshape(bsz, src_len, self.embed_dim)
|
| 244 |
+
|
| 245 |
+
attn_output_v = self.out_v_proj(attn_output_v)
|
| 246 |
+
attn_output_l = self.out_l_proj(attn_output_l)
|
| 247 |
+
|
| 248 |
+
return attn_output_v, attn_output_l
|
| 249 |
+
|
| 250 |
+
|
| 251 |
+
# Bi-Direction MHA (text->image, image->text)
|
| 252 |
+
class BiAttentionBlock(nn.Module):
|
| 253 |
+
def __init__(
|
| 254 |
+
self,
|
| 255 |
+
v_dim,
|
| 256 |
+
l_dim,
|
| 257 |
+
embed_dim,
|
| 258 |
+
num_heads,
|
| 259 |
+
dropout=0.1,
|
| 260 |
+
drop_path=0.0,
|
| 261 |
+
init_values=1e-4,
|
| 262 |
+
cfg=None,
|
| 263 |
+
):
|
| 264 |
+
"""
|
| 265 |
+
Inputs:
|
| 266 |
+
embed_dim - Dimensionality of input and attention feature vectors
|
| 267 |
+
hidden_dim - Dimensionality of hidden layer in feed-forward network
|
| 268 |
+
(usually 2-4x larger than embed_dim)
|
| 269 |
+
num_heads - Number of heads to use in the Multi-Head Attention block
|
| 270 |
+
dropout - Amount of dropout to apply in the feed-forward network
|
| 271 |
+
"""
|
| 272 |
+
super(BiAttentionBlock, self).__init__()
|
| 273 |
+
|
| 274 |
+
# pre layer norm
|
| 275 |
+
self.layer_norm_v = nn.LayerNorm(v_dim)
|
| 276 |
+
self.layer_norm_l = nn.LayerNorm(l_dim)
|
| 277 |
+
self.attn = BiMultiHeadAttention(
|
| 278 |
+
v_dim=v_dim, l_dim=l_dim, embed_dim=embed_dim, num_heads=num_heads, dropout=dropout
|
| 279 |
+
)
|
| 280 |
+
|
| 281 |
+
# add layer scale for training stability
|
| 282 |
+
self.drop_path = DropPath(drop_path) if drop_path > 0.0 else nn.Identity()
|
| 283 |
+
self.gamma_v = nn.Parameter(init_values * torch.ones((v_dim)), requires_grad=True)
|
| 284 |
+
self.gamma_l = nn.Parameter(init_values * torch.ones((l_dim)), requires_grad=True)
|
| 285 |
+
|
| 286 |
+
def forward(self, v, l, attention_mask_v=None, attention_mask_l=None):
|
| 287 |
+
v = self.layer_norm_v(v)
|
| 288 |
+
l = self.layer_norm_l(l)
|
| 289 |
+
delta_v, delta_l = self.attn(
|
| 290 |
+
v, l, attention_mask_v=attention_mask_v, attention_mask_l=attention_mask_l
|
| 291 |
+
)
|
| 292 |
+
# v, l = v + delta_v, l + delta_l
|
| 293 |
+
v = v + self.drop_path(self.gamma_v * delta_v)
|
| 294 |
+
l = l + self.drop_path(self.gamma_l * delta_l)
|
| 295 |
+
return v, l
|
| 296 |
+
|
| 297 |
+
# def forward(self, v:List[torch.Tensor], l, attention_mask_v=None, attention_mask_l=None)
|
One-to-All-Animation/benchmark/DisCo/annotator/grounded-sam/GroundingDINO/groundingdino/models/GroundingDINO/groundingdino.py
ADDED
|
@@ -0,0 +1,395 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
# ------------------------------------------------------------------------
|
| 2 |
+
# Grounding DINO
|
| 3 |
+
# url: https://github.com/IDEA-Research/GroundingDINO
|
| 4 |
+
# Copyright (c) 2023 IDEA. All Rights Reserved.
|
| 5 |
+
# Licensed under the Apache License, Version 2.0 [see LICENSE for details]
|
| 6 |
+
# ------------------------------------------------------------------------
|
| 7 |
+
# Conditional DETR model and criterion classes.
|
| 8 |
+
# Copyright (c) 2021 Microsoft. All Rights Reserved.
|
| 9 |
+
# Licensed under the Apache License, Version 2.0 [see LICENSE for details]
|
| 10 |
+
# ------------------------------------------------------------------------
|
| 11 |
+
# Modified from DETR (https://github.com/facebookresearch/detr)
|
| 12 |
+
# Copyright (c) Facebook, Inc. and its affiliates. All Rights Reserved.
|
| 13 |
+
# ------------------------------------------------------------------------
|
| 14 |
+
# Modified from Deformable DETR (https://github.com/fundamentalvision/Deformable-DETR)
|
| 15 |
+
# Copyright (c) 2020 SenseTime. All Rights Reserved.
|
| 16 |
+
# ------------------------------------------------------------------------
|
| 17 |
+
import copy
|
| 18 |
+
from typing import List
|
| 19 |
+
|
| 20 |
+
import torch
|
| 21 |
+
import torch.nn.functional as F
|
| 22 |
+
from torch import nn
|
| 23 |
+
from torchvision.ops.boxes import nms
|
| 24 |
+
from transformers import AutoTokenizer, BertModel, BertTokenizer, RobertaModel, RobertaTokenizerFast
|
| 25 |
+
|
| 26 |
+
from groundingdino.util import box_ops, get_tokenlizer
|
| 27 |
+
from groundingdino.util.misc import (
|
| 28 |
+
NestedTensor,
|
| 29 |
+
accuracy,
|
| 30 |
+
get_world_size,
|
| 31 |
+
interpolate,
|
| 32 |
+
inverse_sigmoid,
|
| 33 |
+
is_dist_avail_and_initialized,
|
| 34 |
+
nested_tensor_from_tensor_list,
|
| 35 |
+
)
|
| 36 |
+
from groundingdino.util.utils import get_phrases_from_posmap
|
| 37 |
+
from groundingdino.util.visualizer import COCOVisualizer
|
| 38 |
+
from groundingdino.util.vl_utils import create_positive_map_from_span
|
| 39 |
+
|
| 40 |
+
from ..registry import MODULE_BUILD_FUNCS
|
| 41 |
+
from .backbone import build_backbone
|
| 42 |
+
from .bertwarper import (
|
| 43 |
+
BertModelWarper,
|
| 44 |
+
generate_masks_with_special_tokens,
|
| 45 |
+
generate_masks_with_special_tokens_and_transfer_map,
|
| 46 |
+
)
|
| 47 |
+
from .transformer import build_transformer
|
| 48 |
+
from .utils import MLP, ContrastiveEmbed, sigmoid_focal_loss
|
| 49 |
+
|
| 50 |
+
|
| 51 |
+
class GroundingDINO(nn.Module):
|
| 52 |
+
"""This is the Cross-Attention Detector module that performs object detection"""
|
| 53 |
+
|
| 54 |
+
def __init__(
|
| 55 |
+
self,
|
| 56 |
+
backbone,
|
| 57 |
+
transformer,
|
| 58 |
+
num_queries,
|
| 59 |
+
aux_loss=False,
|
| 60 |
+
iter_update=False,
|
| 61 |
+
query_dim=2,
|
| 62 |
+
num_feature_levels=1,
|
| 63 |
+
nheads=8,
|
| 64 |
+
# two stage
|
| 65 |
+
two_stage_type="no", # ['no', 'standard']
|
| 66 |
+
dec_pred_bbox_embed_share=True,
|
| 67 |
+
two_stage_class_embed_share=True,
|
| 68 |
+
two_stage_bbox_embed_share=True,
|
| 69 |
+
num_patterns=0,
|
| 70 |
+
dn_number=100,
|
| 71 |
+
dn_box_noise_scale=0.4,
|
| 72 |
+
dn_label_noise_ratio=0.5,
|
| 73 |
+
dn_labelbook_size=100,
|
| 74 |
+
text_encoder_type="bert-base-uncased",
|
| 75 |
+
sub_sentence_present=True,
|
| 76 |
+
max_text_len=256,
|
| 77 |
+
):
|
| 78 |
+
"""Initializes the model.
|
| 79 |
+
Parameters:
|
| 80 |
+
backbone: torch module of the backbone to be used. See backbone.py
|
| 81 |
+
transformer: torch module of the transformer architecture. See transformer.py
|
| 82 |
+
num_queries: number of object queries, ie detection slot. This is the maximal number of objects
|
| 83 |
+
Conditional DETR can detect in a single image. For COCO, we recommend 100 queries.
|
| 84 |
+
aux_loss: True if auxiliary decoding losses (loss at each decoder layer) are to be used.
|
| 85 |
+
"""
|
| 86 |
+
super().__init__()
|
| 87 |
+
self.num_queries = num_queries
|
| 88 |
+
self.transformer = transformer
|
| 89 |
+
self.hidden_dim = hidden_dim = transformer.d_model
|
| 90 |
+
self.num_feature_levels = num_feature_levels
|
| 91 |
+
self.nheads = nheads
|
| 92 |
+
self.max_text_len = 256
|
| 93 |
+
self.sub_sentence_present = sub_sentence_present
|
| 94 |
+
|
| 95 |
+
# setting query dim
|
| 96 |
+
self.query_dim = query_dim
|
| 97 |
+
assert query_dim == 4
|
| 98 |
+
|
| 99 |
+
# for dn training
|
| 100 |
+
self.num_patterns = num_patterns
|
| 101 |
+
self.dn_number = dn_number
|
| 102 |
+
self.dn_box_noise_scale = dn_box_noise_scale
|
| 103 |
+
self.dn_label_noise_ratio = dn_label_noise_ratio
|
| 104 |
+
self.dn_labelbook_size = dn_labelbook_size
|
| 105 |
+
|
| 106 |
+
# bert
|
| 107 |
+
self.tokenizer = get_tokenlizer.get_tokenlizer(text_encoder_type)
|
| 108 |
+
self.bert = get_tokenlizer.get_pretrained_language_model(text_encoder_type)
|
| 109 |
+
self.bert.pooler.dense.weight.requires_grad_(False)
|
| 110 |
+
self.bert.pooler.dense.bias.requires_grad_(False)
|
| 111 |
+
self.bert = BertModelWarper(bert_model=self.bert)
|
| 112 |
+
|
| 113 |
+
self.feat_map = nn.Linear(self.bert.config.hidden_size, self.hidden_dim, bias=True)
|
| 114 |
+
nn.init.constant_(self.feat_map.bias.data, 0)
|
| 115 |
+
nn.init.xavier_uniform_(self.feat_map.weight.data)
|
| 116 |
+
# freeze
|
| 117 |
+
|
| 118 |
+
# special tokens
|
| 119 |
+
self.specical_tokens = self.tokenizer.convert_tokens_to_ids(["[CLS]", "[SEP]", ".", "?"])
|
| 120 |
+
|
| 121 |
+
# prepare input projection layers
|
| 122 |
+
if num_feature_levels > 1:
|
| 123 |
+
num_backbone_outs = len(backbone.num_channels)
|
| 124 |
+
input_proj_list = []
|
| 125 |
+
for _ in range(num_backbone_outs):
|
| 126 |
+
in_channels = backbone.num_channels[_]
|
| 127 |
+
input_proj_list.append(
|
| 128 |
+
nn.Sequential(
|
| 129 |
+
nn.Conv2d(in_channels, hidden_dim, kernel_size=1),
|
| 130 |
+
nn.GroupNorm(32, hidden_dim),
|
| 131 |
+
)
|
| 132 |
+
)
|
| 133 |
+
for _ in range(num_feature_levels - num_backbone_outs):
|
| 134 |
+
input_proj_list.append(
|
| 135 |
+
nn.Sequential(
|
| 136 |
+
nn.Conv2d(in_channels, hidden_dim, kernel_size=3, stride=2, padding=1),
|
| 137 |
+
nn.GroupNorm(32, hidden_dim),
|
| 138 |
+
)
|
| 139 |
+
)
|
| 140 |
+
in_channels = hidden_dim
|
| 141 |
+
self.input_proj = nn.ModuleList(input_proj_list)
|
| 142 |
+
else:
|
| 143 |
+
assert two_stage_type == "no", "two_stage_type should be no if num_feature_levels=1 !!!"
|
| 144 |
+
self.input_proj = nn.ModuleList(
|
| 145 |
+
[
|
| 146 |
+
nn.Sequential(
|
| 147 |
+
nn.Conv2d(backbone.num_channels[-1], hidden_dim, kernel_size=1),
|
| 148 |
+
nn.GroupNorm(32, hidden_dim),
|
| 149 |
+
)
|
| 150 |
+
]
|
| 151 |
+
)
|
| 152 |
+
|
| 153 |
+
self.backbone = backbone
|
| 154 |
+
self.aux_loss = aux_loss
|
| 155 |
+
self.box_pred_damping = box_pred_damping = None
|
| 156 |
+
|
| 157 |
+
self.iter_update = iter_update
|
| 158 |
+
assert iter_update, "Why not iter_update?"
|
| 159 |
+
|
| 160 |
+
# prepare pred layers
|
| 161 |
+
self.dec_pred_bbox_embed_share = dec_pred_bbox_embed_share
|
| 162 |
+
# prepare class & box embed
|
| 163 |
+
_class_embed = ContrastiveEmbed()
|
| 164 |
+
|
| 165 |
+
_bbox_embed = MLP(hidden_dim, hidden_dim, 4, 3)
|
| 166 |
+
nn.init.constant_(_bbox_embed.layers[-1].weight.data, 0)
|
| 167 |
+
nn.init.constant_(_bbox_embed.layers[-1].bias.data, 0)
|
| 168 |
+
|
| 169 |
+
if dec_pred_bbox_embed_share:
|
| 170 |
+
box_embed_layerlist = [_bbox_embed for i in range(transformer.num_decoder_layers)]
|
| 171 |
+
else:
|
| 172 |
+
box_embed_layerlist = [
|
| 173 |
+
copy.deepcopy(_bbox_embed) for i in range(transformer.num_decoder_layers)
|
| 174 |
+
]
|
| 175 |
+
class_embed_layerlist = [_class_embed for i in range(transformer.num_decoder_layers)]
|
| 176 |
+
self.bbox_embed = nn.ModuleList(box_embed_layerlist)
|
| 177 |
+
self.class_embed = nn.ModuleList(class_embed_layerlist)
|
| 178 |
+
self.transformer.decoder.bbox_embed = self.bbox_embed
|
| 179 |
+
self.transformer.decoder.class_embed = self.class_embed
|
| 180 |
+
|
| 181 |
+
# two stage
|
| 182 |
+
self.two_stage_type = two_stage_type
|
| 183 |
+
assert two_stage_type in ["no", "standard"], "unknown param {} of two_stage_type".format(
|
| 184 |
+
two_stage_type
|
| 185 |
+
)
|
| 186 |
+
if two_stage_type != "no":
|
| 187 |
+
if two_stage_bbox_embed_share:
|
| 188 |
+
assert dec_pred_bbox_embed_share
|
| 189 |
+
self.transformer.enc_out_bbox_embed = _bbox_embed
|
| 190 |
+
else:
|
| 191 |
+
self.transformer.enc_out_bbox_embed = copy.deepcopy(_bbox_embed)
|
| 192 |
+
|
| 193 |
+
if two_stage_class_embed_share:
|
| 194 |
+
assert dec_pred_bbox_embed_share
|
| 195 |
+
self.transformer.enc_out_class_embed = _class_embed
|
| 196 |
+
else:
|
| 197 |
+
self.transformer.enc_out_class_embed = copy.deepcopy(_class_embed)
|
| 198 |
+
|
| 199 |
+
self.refpoint_embed = None
|
| 200 |
+
|
| 201 |
+
self._reset_parameters()
|
| 202 |
+
|
| 203 |
+
def _reset_parameters(self):
|
| 204 |
+
# init input_proj
|
| 205 |
+
for proj in self.input_proj:
|
| 206 |
+
nn.init.xavier_uniform_(proj[0].weight, gain=1)
|
| 207 |
+
nn.init.constant_(proj[0].bias, 0)
|
| 208 |
+
|
| 209 |
+
def init_ref_points(self, use_num_queries):
|
| 210 |
+
self.refpoint_embed = nn.Embedding(use_num_queries, self.query_dim)
|
| 211 |
+
|
| 212 |
+
def forward(self, samples: NestedTensor, targets: List = None, **kw):
|
| 213 |
+
"""The forward expects a NestedTensor, which consists of:
|
| 214 |
+
- samples.tensor: batched images, of shape [batch_size x 3 x H x W]
|
| 215 |
+
- samples.mask: a binary mask of shape [batch_size x H x W], containing 1 on padded pixels
|
| 216 |
+
|
| 217 |
+
It returns a dict with the following elements:
|
| 218 |
+
- "pred_logits": the classification logits (including no-object) for all queries.
|
| 219 |
+
Shape= [batch_size x num_queries x num_classes]
|
| 220 |
+
- "pred_boxes": The normalized boxes coordinates for all queries, represented as
|
| 221 |
+
(center_x, center_y, width, height). These values are normalized in [0, 1],
|
| 222 |
+
relative to the size of each individual image (disregarding possible padding).
|
| 223 |
+
See PostProcess for information on how to retrieve the unnormalized bounding box.
|
| 224 |
+
- "aux_outputs": Optional, only returned when auxilary losses are activated. It is a list of
|
| 225 |
+
dictionnaries containing the two above keys for each decoder layer.
|
| 226 |
+
"""
|
| 227 |
+
if targets is None:
|
| 228 |
+
captions = kw["captions"]
|
| 229 |
+
else:
|
| 230 |
+
captions = [t["caption"] for t in targets]
|
| 231 |
+
len(captions)
|
| 232 |
+
|
| 233 |
+
# encoder texts
|
| 234 |
+
tokenized = self.tokenizer(captions, padding="longest", return_tensors="pt").to(
|
| 235 |
+
samples.device
|
| 236 |
+
)
|
| 237 |
+
(
|
| 238 |
+
text_self_attention_masks,
|
| 239 |
+
position_ids,
|
| 240 |
+
cate_to_token_mask_list,
|
| 241 |
+
) = generate_masks_with_special_tokens_and_transfer_map(
|
| 242 |
+
tokenized, self.specical_tokens, self.tokenizer
|
| 243 |
+
)
|
| 244 |
+
|
| 245 |
+
if text_self_attention_masks.shape[1] > self.max_text_len:
|
| 246 |
+
text_self_attention_masks = text_self_attention_masks[
|
| 247 |
+
:, : self.max_text_len, : self.max_text_len
|
| 248 |
+
]
|
| 249 |
+
position_ids = position_ids[:, : self.max_text_len]
|
| 250 |
+
tokenized["input_ids"] = tokenized["input_ids"][:, : self.max_text_len]
|
| 251 |
+
tokenized["attention_mask"] = tokenized["attention_mask"][:, : self.max_text_len]
|
| 252 |
+
tokenized["token_type_ids"] = tokenized["token_type_ids"][:, : self.max_text_len]
|
| 253 |
+
|
| 254 |
+
# extract text embeddings
|
| 255 |
+
if self.sub_sentence_present:
|
| 256 |
+
tokenized_for_encoder = {k: v for k, v in tokenized.items() if k != "attention_mask"}
|
| 257 |
+
tokenized_for_encoder["attention_mask"] = text_self_attention_masks
|
| 258 |
+
tokenized_for_encoder["position_ids"] = position_ids
|
| 259 |
+
else:
|
| 260 |
+
# import ipdb; ipdb.set_trace()
|
| 261 |
+
tokenized_for_encoder = tokenized
|
| 262 |
+
|
| 263 |
+
bert_output = self.bert(**tokenized_for_encoder) # bs, 195, 768
|
| 264 |
+
|
| 265 |
+
encoded_text = self.feat_map(bert_output["last_hidden_state"]) # bs, 195, d_model
|
| 266 |
+
text_token_mask = tokenized.attention_mask.bool() # bs, 195
|
| 267 |
+
# text_token_mask: True for nomask, False for mask
|
| 268 |
+
# text_self_attention_masks: True for nomask, False for mask
|
| 269 |
+
|
| 270 |
+
if encoded_text.shape[1] > self.max_text_len:
|
| 271 |
+
encoded_text = encoded_text[:, : self.max_text_len, :]
|
| 272 |
+
text_token_mask = text_token_mask[:, : self.max_text_len]
|
| 273 |
+
position_ids = position_ids[:, : self.max_text_len]
|
| 274 |
+
text_self_attention_masks = text_self_attention_masks[
|
| 275 |
+
:, : self.max_text_len, : self.max_text_len
|
| 276 |
+
]
|
| 277 |
+
|
| 278 |
+
text_dict = {
|
| 279 |
+
"encoded_text": encoded_text, # bs, 195, d_model
|
| 280 |
+
"text_token_mask": text_token_mask, # bs, 195
|
| 281 |
+
"position_ids": position_ids, # bs, 195
|
| 282 |
+
"text_self_attention_masks": text_self_attention_masks, # bs, 195,195
|
| 283 |
+
}
|
| 284 |
+
|
| 285 |
+
# import ipdb; ipdb.set_trace()
|
| 286 |
+
|
| 287 |
+
if isinstance(samples, (list, torch.Tensor)):
|
| 288 |
+
samples = nested_tensor_from_tensor_list(samples)
|
| 289 |
+
features, poss = self.backbone(samples)
|
| 290 |
+
|
| 291 |
+
srcs = []
|
| 292 |
+
masks = []
|
| 293 |
+
for l, feat in enumerate(features):
|
| 294 |
+
src, mask = feat.decompose()
|
| 295 |
+
srcs.append(self.input_proj[l](src))
|
| 296 |
+
masks.append(mask)
|
| 297 |
+
assert mask is not None
|
| 298 |
+
if self.num_feature_levels > len(srcs):
|
| 299 |
+
_len_srcs = len(srcs)
|
| 300 |
+
for l in range(_len_srcs, self.num_feature_levels):
|
| 301 |
+
if l == _len_srcs:
|
| 302 |
+
src = self.input_proj[l](features[-1].tensors)
|
| 303 |
+
else:
|
| 304 |
+
src = self.input_proj[l](srcs[-1])
|
| 305 |
+
m = samples.mask
|
| 306 |
+
mask = F.interpolate(m[None].float(), size=src.shape[-2:]).to(torch.bool)[0]
|
| 307 |
+
pos_l = self.backbone[1](NestedTensor(src, mask)).to(src.dtype)
|
| 308 |
+
srcs.append(src)
|
| 309 |
+
masks.append(mask)
|
| 310 |
+
poss.append(pos_l)
|
| 311 |
+
|
| 312 |
+
input_query_bbox = input_query_label = attn_mask = dn_meta = None
|
| 313 |
+
hs, reference, hs_enc, ref_enc, init_box_proposal = self.transformer(
|
| 314 |
+
srcs, masks, input_query_bbox, poss, input_query_label, attn_mask, text_dict
|
| 315 |
+
)
|
| 316 |
+
|
| 317 |
+
# deformable-detr-like anchor update
|
| 318 |
+
outputs_coord_list = []
|
| 319 |
+
for dec_lid, (layer_ref_sig, layer_bbox_embed, layer_hs) in enumerate(
|
| 320 |
+
zip(reference[:-1], self.bbox_embed, hs)
|
| 321 |
+
):
|
| 322 |
+
layer_delta_unsig = layer_bbox_embed(layer_hs)
|
| 323 |
+
layer_outputs_unsig = layer_delta_unsig + inverse_sigmoid(layer_ref_sig)
|
| 324 |
+
layer_outputs_unsig = layer_outputs_unsig.sigmoid()
|
| 325 |
+
outputs_coord_list.append(layer_outputs_unsig)
|
| 326 |
+
outputs_coord_list = torch.stack(outputs_coord_list)
|
| 327 |
+
|
| 328 |
+
# output
|
| 329 |
+
outputs_class = torch.stack(
|
| 330 |
+
[
|
| 331 |
+
layer_cls_embed(layer_hs, text_dict)
|
| 332 |
+
for layer_cls_embed, layer_hs in zip(self.class_embed, hs)
|
| 333 |
+
]
|
| 334 |
+
)
|
| 335 |
+
out = {"pred_logits": outputs_class[-1], "pred_boxes": outputs_coord_list[-1]}
|
| 336 |
+
|
| 337 |
+
# # for intermediate outputs
|
| 338 |
+
# if self.aux_loss:
|
| 339 |
+
# out['aux_outputs'] = self._set_aux_loss(outputs_class, outputs_coord_list)
|
| 340 |
+
|
| 341 |
+
# # for encoder output
|
| 342 |
+
# if hs_enc is not None:
|
| 343 |
+
# # prepare intermediate outputs
|
| 344 |
+
# interm_coord = ref_enc[-1]
|
| 345 |
+
# interm_class = self.transformer.enc_out_class_embed(hs_enc[-1], text_dict)
|
| 346 |
+
# out['interm_outputs'] = {'pred_logits': interm_class, 'pred_boxes': interm_coord}
|
| 347 |
+
# out['interm_outputs_for_matching_pre'] = {'pred_logits': interm_class, 'pred_boxes': init_box_proposal}
|
| 348 |
+
|
| 349 |
+
return out
|
| 350 |
+
|
| 351 |
+
@torch.jit.unused
|
| 352 |
+
def _set_aux_loss(self, outputs_class, outputs_coord):
|
| 353 |
+
# this is a workaround to make torchscript happy, as torchscript
|
| 354 |
+
# doesn't support dictionary with non-homogeneous values, such
|
| 355 |
+
# as a dict having both a Tensor and a list.
|
| 356 |
+
return [
|
| 357 |
+
{"pred_logits": a, "pred_boxes": b}
|
| 358 |
+
for a, b in zip(outputs_class[:-1], outputs_coord[:-1])
|
| 359 |
+
]
|
| 360 |
+
|
| 361 |
+
|
| 362 |
+
@MODULE_BUILD_FUNCS.registe_with_name(module_name="groundingdino")
|
| 363 |
+
def build_groundingdino(args):
|
| 364 |
+
|
| 365 |
+
backbone = build_backbone(args)
|
| 366 |
+
transformer = build_transformer(args)
|
| 367 |
+
|
| 368 |
+
dn_labelbook_size = args.dn_labelbook_size
|
| 369 |
+
dec_pred_bbox_embed_share = args.dec_pred_bbox_embed_share
|
| 370 |
+
sub_sentence_present = args.sub_sentence_present
|
| 371 |
+
|
| 372 |
+
model = GroundingDINO(
|
| 373 |
+
backbone,
|
| 374 |
+
transformer,
|
| 375 |
+
num_queries=args.num_queries,
|
| 376 |
+
aux_loss=True,
|
| 377 |
+
iter_update=True,
|
| 378 |
+
query_dim=4,
|
| 379 |
+
num_feature_levels=args.num_feature_levels,
|
| 380 |
+
nheads=args.nheads,
|
| 381 |
+
dec_pred_bbox_embed_share=dec_pred_bbox_embed_share,
|
| 382 |
+
two_stage_type=args.two_stage_type,
|
| 383 |
+
two_stage_bbox_embed_share=args.two_stage_bbox_embed_share,
|
| 384 |
+
two_stage_class_embed_share=args.two_stage_class_embed_share,
|
| 385 |
+
num_patterns=args.num_patterns,
|
| 386 |
+
dn_number=0,
|
| 387 |
+
dn_box_noise_scale=args.dn_box_noise_scale,
|
| 388 |
+
dn_label_noise_ratio=args.dn_label_noise_ratio,
|
| 389 |
+
dn_labelbook_size=dn_labelbook_size,
|
| 390 |
+
text_encoder_type=args.text_encoder_type,
|
| 391 |
+
sub_sentence_present=sub_sentence_present,
|
| 392 |
+
max_text_len=args.max_text_len,
|
| 393 |
+
)
|
| 394 |
+
|
| 395 |
+
return model
|
One-to-All-Animation/benchmark/DisCo/annotator/grounded-sam/GroundingDINO/groundingdino/models/GroundingDINO/ms_deform_attn.py
ADDED
|
@@ -0,0 +1,413 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
# ------------------------------------------------------------------------
|
| 2 |
+
# Grounding DINO
|
| 3 |
+
# url: https://github.com/IDEA-Research/GroundingDINO
|
| 4 |
+
# Copyright (c) 2023 IDEA. All Rights Reserved.
|
| 5 |
+
# Licensed under the Apache License, Version 2.0 [see LICENSE for details]
|
| 6 |
+
# ------------------------------------------------------------------------
|
| 7 |
+
# Deformable DETR
|
| 8 |
+
# Copyright (c) 2020 SenseTime. All Rights Reserved.
|
| 9 |
+
# Licensed under the Apache License, Version 2.0 [see LICENSE for details]
|
| 10 |
+
# ------------------------------------------------------------------------------------------------
|
| 11 |
+
# Modified from:
|
| 12 |
+
# https://github.com/fundamentalvision/Deformable-DETR/blob/main/models/ops/functions/ms_deform_attn_func.py
|
| 13 |
+
# https://github.com/fundamentalvision/Deformable-DETR/blob/main/models/ops/modules/ms_deform_attn.py
|
| 14 |
+
# https://github.com/open-mmlab/mmcv/blob/master/mmcv/ops/multi_scale_deform_attn.py
|
| 15 |
+
# ------------------------------------------------------------------------------------------------
|
| 16 |
+
|
| 17 |
+
import math
|
| 18 |
+
import warnings
|
| 19 |
+
from typing import Optional
|
| 20 |
+
|
| 21 |
+
import torch
|
| 22 |
+
import torch.nn as nn
|
| 23 |
+
import torch.nn.functional as F
|
| 24 |
+
from torch.autograd import Function
|
| 25 |
+
from torch.autograd.function import once_differentiable
|
| 26 |
+
from torch.nn.init import constant_, xavier_uniform_
|
| 27 |
+
|
| 28 |
+
try:
|
| 29 |
+
from groundingdino import _C
|
| 30 |
+
except:
|
| 31 |
+
warnings.warn("Failed to load custom C++ ops. Running on CPU mode Only!")
|
| 32 |
+
|
| 33 |
+
|
| 34 |
+
# helpers
|
| 35 |
+
def _is_power_of_2(n):
|
| 36 |
+
if (not isinstance(n, int)) or (n < 0):
|
| 37 |
+
raise ValueError("invalid input for _is_power_of_2: {} (type: {})".format(n, type(n)))
|
| 38 |
+
return (n & (n - 1) == 0) and n != 0
|
| 39 |
+
|
| 40 |
+
|
| 41 |
+
class MultiScaleDeformableAttnFunction(Function):
|
| 42 |
+
@staticmethod
|
| 43 |
+
def forward(
|
| 44 |
+
ctx,
|
| 45 |
+
value,
|
| 46 |
+
value_spatial_shapes,
|
| 47 |
+
value_level_start_index,
|
| 48 |
+
sampling_locations,
|
| 49 |
+
attention_weights,
|
| 50 |
+
im2col_step,
|
| 51 |
+
):
|
| 52 |
+
ctx.im2col_step = im2col_step
|
| 53 |
+
output = _C.ms_deform_attn_forward(
|
| 54 |
+
value,
|
| 55 |
+
value_spatial_shapes,
|
| 56 |
+
value_level_start_index,
|
| 57 |
+
sampling_locations,
|
| 58 |
+
attention_weights,
|
| 59 |
+
ctx.im2col_step,
|
| 60 |
+
)
|
| 61 |
+
ctx.save_for_backward(
|
| 62 |
+
value,
|
| 63 |
+
value_spatial_shapes,
|
| 64 |
+
value_level_start_index,
|
| 65 |
+
sampling_locations,
|
| 66 |
+
attention_weights,
|
| 67 |
+
)
|
| 68 |
+
return output
|
| 69 |
+
|
| 70 |
+
@staticmethod
|
| 71 |
+
@once_differentiable
|
| 72 |
+
def backward(ctx, grad_output):
|
| 73 |
+
(
|
| 74 |
+
value,
|
| 75 |
+
value_spatial_shapes,
|
| 76 |
+
value_level_start_index,
|
| 77 |
+
sampling_locations,
|
| 78 |
+
attention_weights,
|
| 79 |
+
) = ctx.saved_tensors
|
| 80 |
+
grad_value, grad_sampling_loc, grad_attn_weight = _C.ms_deform_attn_backward(
|
| 81 |
+
value,
|
| 82 |
+
value_spatial_shapes,
|
| 83 |
+
value_level_start_index,
|
| 84 |
+
sampling_locations,
|
| 85 |
+
attention_weights,
|
| 86 |
+
grad_output,
|
| 87 |
+
ctx.im2col_step,
|
| 88 |
+
)
|
| 89 |
+
|
| 90 |
+
return grad_value, None, None, grad_sampling_loc, grad_attn_weight, None
|
| 91 |
+
|
| 92 |
+
|
| 93 |
+
def multi_scale_deformable_attn_pytorch(
|
| 94 |
+
value: torch.Tensor,
|
| 95 |
+
value_spatial_shapes: torch.Tensor,
|
| 96 |
+
sampling_locations: torch.Tensor,
|
| 97 |
+
attention_weights: torch.Tensor,
|
| 98 |
+
) -> torch.Tensor:
|
| 99 |
+
|
| 100 |
+
bs, _, num_heads, embed_dims = value.shape
|
| 101 |
+
_, num_queries, num_heads, num_levels, num_points, _ = sampling_locations.shape
|
| 102 |
+
value_list = value.split([H_ * W_ for H_, W_ in value_spatial_shapes], dim=1)
|
| 103 |
+
sampling_grids = 2 * sampling_locations - 1
|
| 104 |
+
sampling_value_list = []
|
| 105 |
+
for level, (H_, W_) in enumerate(value_spatial_shapes):
|
| 106 |
+
# bs, H_*W_, num_heads, embed_dims ->
|
| 107 |
+
# bs, H_*W_, num_heads*embed_dims ->
|
| 108 |
+
# bs, num_heads*embed_dims, H_*W_ ->
|
| 109 |
+
# bs*num_heads, embed_dims, H_, W_
|
| 110 |
+
value_l_ = (
|
| 111 |
+
value_list[level].flatten(2).transpose(1, 2).reshape(bs * num_heads, embed_dims, H_, W_)
|
| 112 |
+
)
|
| 113 |
+
# bs, num_queries, num_heads, num_points, 2 ->
|
| 114 |
+
# bs, num_heads, num_queries, num_points, 2 ->
|
| 115 |
+
# bs*num_heads, num_queries, num_points, 2
|
| 116 |
+
sampling_grid_l_ = sampling_grids[:, :, :, level].transpose(1, 2).flatten(0, 1)
|
| 117 |
+
# bs*num_heads, embed_dims, num_queries, num_points
|
| 118 |
+
sampling_value_l_ = F.grid_sample(
|
| 119 |
+
value_l_, sampling_grid_l_, mode="bilinear", padding_mode="zeros", align_corners=False
|
| 120 |
+
)
|
| 121 |
+
sampling_value_list.append(sampling_value_l_)
|
| 122 |
+
# (bs, num_queries, num_heads, num_levels, num_points) ->
|
| 123 |
+
# (bs, num_heads, num_queries, num_levels, num_points) ->
|
| 124 |
+
# (bs, num_heads, 1, num_queries, num_levels*num_points)
|
| 125 |
+
attention_weights = attention_weights.transpose(1, 2).reshape(
|
| 126 |
+
bs * num_heads, 1, num_queries, num_levels * num_points
|
| 127 |
+
)
|
| 128 |
+
output = (
|
| 129 |
+
(torch.stack(sampling_value_list, dim=-2).flatten(-2) * attention_weights)
|
| 130 |
+
.sum(-1)
|
| 131 |
+
.view(bs, num_heads * embed_dims, num_queries)
|
| 132 |
+
)
|
| 133 |
+
return output.transpose(1, 2).contiguous()
|
| 134 |
+
|
| 135 |
+
|
| 136 |
+
class MultiScaleDeformableAttention(nn.Module):
|
| 137 |
+
"""Multi-Scale Deformable Attention Module used in Deformable-DETR
|
| 138 |
+
|
| 139 |
+
`Deformable DETR: Deformable Transformers for End-to-End Object Detection.
|
| 140 |
+
<https://arxiv.org/pdf/2010.04159.pdf>`_.
|
| 141 |
+
|
| 142 |
+
Args:
|
| 143 |
+
embed_dim (int): The embedding dimension of Attention. Default: 256.
|
| 144 |
+
num_heads (int): The number of attention heads. Default: 8.
|
| 145 |
+
num_levels (int): The number of feature map used in Attention. Default: 4.
|
| 146 |
+
num_points (int): The number of sampling points for each query
|
| 147 |
+
in each head. Default: 4.
|
| 148 |
+
img2col_steps (int): The step used in image_to_column. Defualt: 64.
|
| 149 |
+
dropout (float): Dropout layer used in output. Default: 0.1.
|
| 150 |
+
batch_first (bool): if ``True``, then the input and output tensor will be
|
| 151 |
+
provided as `(bs, n, embed_dim)`. Default: False. `(n, bs, embed_dim)`
|
| 152 |
+
"""
|
| 153 |
+
|
| 154 |
+
def __init__(
|
| 155 |
+
self,
|
| 156 |
+
embed_dim: int = 256,
|
| 157 |
+
num_heads: int = 8,
|
| 158 |
+
num_levels: int = 4,
|
| 159 |
+
num_points: int = 4,
|
| 160 |
+
img2col_step: int = 64,
|
| 161 |
+
batch_first: bool = False,
|
| 162 |
+
):
|
| 163 |
+
super().__init__()
|
| 164 |
+
if embed_dim % num_heads != 0:
|
| 165 |
+
raise ValueError(
|
| 166 |
+
"embed_dim must be divisible by num_heads, but got {} and {}".format(
|
| 167 |
+
embed_dim, num_heads
|
| 168 |
+
)
|
| 169 |
+
)
|
| 170 |
+
head_dim = embed_dim // num_heads
|
| 171 |
+
|
| 172 |
+
self.batch_first = batch_first
|
| 173 |
+
|
| 174 |
+
if not _is_power_of_2(head_dim):
|
| 175 |
+
warnings.warn(
|
| 176 |
+
"""
|
| 177 |
+
You'd better set d_model in MSDeformAttn to make sure that
|
| 178 |
+
each dim of the attention head a power of 2, which is more efficient.
|
| 179 |
+
"""
|
| 180 |
+
)
|
| 181 |
+
|
| 182 |
+
self.im2col_step = img2col_step
|
| 183 |
+
self.embed_dim = embed_dim
|
| 184 |
+
self.num_heads = num_heads
|
| 185 |
+
self.num_levels = num_levels
|
| 186 |
+
self.num_points = num_points
|
| 187 |
+
self.sampling_offsets = nn.Linear(embed_dim, num_heads * num_levels * num_points * 2)
|
| 188 |
+
self.attention_weights = nn.Linear(embed_dim, num_heads * num_levels * num_points)
|
| 189 |
+
self.value_proj = nn.Linear(embed_dim, embed_dim)
|
| 190 |
+
self.output_proj = nn.Linear(embed_dim, embed_dim)
|
| 191 |
+
|
| 192 |
+
self.init_weights()
|
| 193 |
+
|
| 194 |
+
def _reset_parameters(self):
|
| 195 |
+
return self.init_weights()
|
| 196 |
+
|
| 197 |
+
def init_weights(self):
|
| 198 |
+
"""
|
| 199 |
+
Default initialization for Parameters of Module.
|
| 200 |
+
"""
|
| 201 |
+
constant_(self.sampling_offsets.weight.data, 0.0)
|
| 202 |
+
thetas = torch.arange(self.num_heads, dtype=torch.float32) * (
|
| 203 |
+
2.0 * math.pi / self.num_heads
|
| 204 |
+
)
|
| 205 |
+
grid_init = torch.stack([thetas.cos(), thetas.sin()], -1)
|
| 206 |
+
grid_init = (
|
| 207 |
+
(grid_init / grid_init.abs().max(-1, keepdim=True)[0])
|
| 208 |
+
.view(self.num_heads, 1, 1, 2)
|
| 209 |
+
.repeat(1, self.num_levels, self.num_points, 1)
|
| 210 |
+
)
|
| 211 |
+
for i in range(self.num_points):
|
| 212 |
+
grid_init[:, :, i, :] *= i + 1
|
| 213 |
+
with torch.no_grad():
|
| 214 |
+
self.sampling_offsets.bias = nn.Parameter(grid_init.view(-1))
|
| 215 |
+
constant_(self.attention_weights.weight.data, 0.0)
|
| 216 |
+
constant_(self.attention_weights.bias.data, 0.0)
|
| 217 |
+
xavier_uniform_(self.value_proj.weight.data)
|
| 218 |
+
constant_(self.value_proj.bias.data, 0.0)
|
| 219 |
+
xavier_uniform_(self.output_proj.weight.data)
|
| 220 |
+
constant_(self.output_proj.bias.data, 0.0)
|
| 221 |
+
|
| 222 |
+
def freeze_sampling_offsets(self):
|
| 223 |
+
print("Freeze sampling offsets")
|
| 224 |
+
self.sampling_offsets.weight.requires_grad = False
|
| 225 |
+
self.sampling_offsets.bias.requires_grad = False
|
| 226 |
+
|
| 227 |
+
def freeze_attention_weights(self):
|
| 228 |
+
print("Freeze attention weights")
|
| 229 |
+
self.attention_weights.weight.requires_grad = False
|
| 230 |
+
self.attention_weights.bias.requires_grad = False
|
| 231 |
+
|
| 232 |
+
def forward(
|
| 233 |
+
self,
|
| 234 |
+
query: torch.Tensor,
|
| 235 |
+
key: Optional[torch.Tensor] = None,
|
| 236 |
+
value: Optional[torch.Tensor] = None,
|
| 237 |
+
query_pos: Optional[torch.Tensor] = None,
|
| 238 |
+
key_padding_mask: Optional[torch.Tensor] = None,
|
| 239 |
+
reference_points: Optional[torch.Tensor] = None,
|
| 240 |
+
spatial_shapes: Optional[torch.Tensor] = None,
|
| 241 |
+
level_start_index: Optional[torch.Tensor] = None,
|
| 242 |
+
**kwargs
|
| 243 |
+
) -> torch.Tensor:
|
| 244 |
+
|
| 245 |
+
"""Forward Function of MultiScaleDeformableAttention
|
| 246 |
+
|
| 247 |
+
Args:
|
| 248 |
+
query (torch.Tensor): Query embeddings with shape
|
| 249 |
+
`(num_query, bs, embed_dim)`
|
| 250 |
+
key (torch.Tensor): Key embeddings with shape
|
| 251 |
+
`(num_key, bs, embed_dim)`
|
| 252 |
+
value (torch.Tensor): Value embeddings with shape
|
| 253 |
+
`(num_key, bs, embed_dim)`
|
| 254 |
+
query_pos (torch.Tensor): The position embedding for `query`. Default: None.
|
| 255 |
+
key_padding_mask (torch.Tensor): ByteTensor for `query`, with shape `(bs, num_key)`,
|
| 256 |
+
indicating which elements within `key` to be ignored in attention.
|
| 257 |
+
reference_points (torch.Tensor): The normalized reference points
|
| 258 |
+
with shape `(bs, num_query, num_levels, 2)`,
|
| 259 |
+
all elements is range in [0, 1], top-left (0, 0),
|
| 260 |
+
bottom-right (1, 1), including padding are.
|
| 261 |
+
or `(N, Length_{query}, num_levels, 4)`, add additional
|
| 262 |
+
two dimensions `(h, w)` to form reference boxes.
|
| 263 |
+
spatial_shapes (torch.Tensor): Spatial shape of features in different levels.
|
| 264 |
+
With shape `(num_levels, 2)`, last dimension represents `(h, w)`.
|
| 265 |
+
level_start_index (torch.Tensor): The start index of each level. A tensor with
|
| 266 |
+
shape `(num_levels, )` which can be represented as
|
| 267 |
+
`[0, h_0 * w_0, h_0 * w_0 + h_1 * w_1, ...]`.
|
| 268 |
+
|
| 269 |
+
Returns:
|
| 270 |
+
torch.Tensor: forward results with shape `(num_query, bs, embed_dim)`
|
| 271 |
+
"""
|
| 272 |
+
|
| 273 |
+
if value is None:
|
| 274 |
+
value = query
|
| 275 |
+
|
| 276 |
+
if query_pos is not None:
|
| 277 |
+
query = query + query_pos
|
| 278 |
+
|
| 279 |
+
if not self.batch_first:
|
| 280 |
+
# change to (bs, num_query ,embed_dims)
|
| 281 |
+
query = query.permute(1, 0, 2)
|
| 282 |
+
value = value.permute(1, 0, 2)
|
| 283 |
+
|
| 284 |
+
bs, num_query, _ = query.shape
|
| 285 |
+
bs, num_value, _ = value.shape
|
| 286 |
+
|
| 287 |
+
assert (spatial_shapes[:, 0] * spatial_shapes[:, 1]).sum() == num_value
|
| 288 |
+
|
| 289 |
+
value = self.value_proj(value)
|
| 290 |
+
if key_padding_mask is not None:
|
| 291 |
+
value = value.masked_fill(key_padding_mask[..., None], float(0))
|
| 292 |
+
value = value.view(bs, num_value, self.num_heads, -1)
|
| 293 |
+
sampling_offsets = self.sampling_offsets(query).view(
|
| 294 |
+
bs, num_query, self.num_heads, self.num_levels, self.num_points, 2
|
| 295 |
+
)
|
| 296 |
+
attention_weights = self.attention_weights(query).view(
|
| 297 |
+
bs, num_query, self.num_heads, self.num_levels * self.num_points
|
| 298 |
+
)
|
| 299 |
+
attention_weights = attention_weights.softmax(-1)
|
| 300 |
+
attention_weights = attention_weights.view(
|
| 301 |
+
bs,
|
| 302 |
+
num_query,
|
| 303 |
+
self.num_heads,
|
| 304 |
+
self.num_levels,
|
| 305 |
+
self.num_points,
|
| 306 |
+
)
|
| 307 |
+
|
| 308 |
+
# bs, num_query, num_heads, num_levels, num_points, 2
|
| 309 |
+
if reference_points.shape[-1] == 2:
|
| 310 |
+
offset_normalizer = torch.stack([spatial_shapes[..., 1], spatial_shapes[..., 0]], -1)
|
| 311 |
+
sampling_locations = (
|
| 312 |
+
reference_points[:, :, None, :, None, :]
|
| 313 |
+
+ sampling_offsets / offset_normalizer[None, None, None, :, None, :]
|
| 314 |
+
)
|
| 315 |
+
elif reference_points.shape[-1] == 4:
|
| 316 |
+
sampling_locations = (
|
| 317 |
+
reference_points[:, :, None, :, None, :2]
|
| 318 |
+
+ sampling_offsets
|
| 319 |
+
/ self.num_points
|
| 320 |
+
* reference_points[:, :, None, :, None, 2:]
|
| 321 |
+
* 0.5
|
| 322 |
+
)
|
| 323 |
+
else:
|
| 324 |
+
raise ValueError(
|
| 325 |
+
"Last dim of reference_points must be 2 or 4, but get {} instead.".format(
|
| 326 |
+
reference_points.shape[-1]
|
| 327 |
+
)
|
| 328 |
+
)
|
| 329 |
+
|
| 330 |
+
if torch.cuda.is_available() and value.is_cuda:
|
| 331 |
+
halffloat = False
|
| 332 |
+
if value.dtype == torch.float16:
|
| 333 |
+
halffloat = True
|
| 334 |
+
value = value.float()
|
| 335 |
+
sampling_locations = sampling_locations.float()
|
| 336 |
+
attention_weights = attention_weights.float()
|
| 337 |
+
|
| 338 |
+
output = MultiScaleDeformableAttnFunction.apply(
|
| 339 |
+
value,
|
| 340 |
+
spatial_shapes,
|
| 341 |
+
level_start_index,
|
| 342 |
+
sampling_locations,
|
| 343 |
+
attention_weights,
|
| 344 |
+
self.im2col_step,
|
| 345 |
+
)
|
| 346 |
+
|
| 347 |
+
if halffloat:
|
| 348 |
+
output = output.half()
|
| 349 |
+
else:
|
| 350 |
+
output = multi_scale_deformable_attn_pytorch(
|
| 351 |
+
value, spatial_shapes, sampling_locations, attention_weights
|
| 352 |
+
)
|
| 353 |
+
|
| 354 |
+
output = self.output_proj(output)
|
| 355 |
+
|
| 356 |
+
if not self.batch_first:
|
| 357 |
+
output = output.permute(1, 0, 2)
|
| 358 |
+
|
| 359 |
+
return output
|
| 360 |
+
|
| 361 |
+
|
| 362 |
+
def create_dummy_class(klass, dependency, message=""):
|
| 363 |
+
"""
|
| 364 |
+
When a dependency of a class is not available, create a dummy class which throws ImportError
|
| 365 |
+
when used.
|
| 366 |
+
|
| 367 |
+
Args:
|
| 368 |
+
klass (str): name of the class.
|
| 369 |
+
dependency (str): name of the dependency.
|
| 370 |
+
message: extra message to print
|
| 371 |
+
Returns:
|
| 372 |
+
class: a class object
|
| 373 |
+
"""
|
| 374 |
+
err = "Cannot import '{}', therefore '{}' is not available.".format(dependency, klass)
|
| 375 |
+
if message:
|
| 376 |
+
err = err + " " + message
|
| 377 |
+
|
| 378 |
+
class _DummyMetaClass(type):
|
| 379 |
+
# throw error on class attribute access
|
| 380 |
+
def __getattr__(_, __): # noqa: B902
|
| 381 |
+
raise ImportError(err)
|
| 382 |
+
|
| 383 |
+
class _Dummy(object, metaclass=_DummyMetaClass):
|
| 384 |
+
# throw error on constructor
|
| 385 |
+
def __init__(self, *args, **kwargs):
|
| 386 |
+
raise ImportError(err)
|
| 387 |
+
|
| 388 |
+
return _Dummy
|
| 389 |
+
|
| 390 |
+
|
| 391 |
+
def create_dummy_func(func, dependency, message=""):
|
| 392 |
+
"""
|
| 393 |
+
When a dependency of a function is not available, create a dummy function which throws
|
| 394 |
+
ImportError when used.
|
| 395 |
+
|
| 396 |
+
Args:
|
| 397 |
+
func (str): name of the function.
|
| 398 |
+
dependency (str or list[str]): name(s) of the dependency.
|
| 399 |
+
message: extra message to print
|
| 400 |
+
Returns:
|
| 401 |
+
function: a function object
|
| 402 |
+
"""
|
| 403 |
+
err = "Cannot import '{}', therefore '{}' is not available.".format(dependency, func)
|
| 404 |
+
if message:
|
| 405 |
+
err = err + " " + message
|
| 406 |
+
|
| 407 |
+
if isinstance(dependency, (list, tuple)):
|
| 408 |
+
dependency = ",".join(dependency)
|
| 409 |
+
|
| 410 |
+
def _dummy(*args, **kwargs):
|
| 411 |
+
raise ImportError(err)
|
| 412 |
+
|
| 413 |
+
return _dummy
|
One-to-All-Animation/benchmark/DisCo/annotator/grounded-sam/GroundingDINO/groundingdino/models/GroundingDINO/transformer.py
ADDED
|
@@ -0,0 +1,959 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
# ------------------------------------------------------------------------
|
| 2 |
+
# Grounding DINO
|
| 3 |
+
# url: https://github.com/IDEA-Research/GroundingDINO
|
| 4 |
+
# Copyright (c) 2023 IDEA. All Rights Reserved.
|
| 5 |
+
# Licensed under the Apache License, Version 2.0 [see LICENSE for details]
|
| 6 |
+
# ------------------------------------------------------------------------
|
| 7 |
+
# DINO
|
| 8 |
+
# Copyright (c) 2022 IDEA. All Rights Reserved.
|
| 9 |
+
# Licensed under the Apache License, Version 2.0 [see LICENSE for details]
|
| 10 |
+
# ------------------------------------------------------------------------
|
| 11 |
+
# Conditional DETR Transformer class.
|
| 12 |
+
# Copyright (c) 2021 Microsoft. All Rights Reserved.
|
| 13 |
+
# Licensed under the Apache License, Version 2.0 [see LICENSE for details]
|
| 14 |
+
# ------------------------------------------------------------------------
|
| 15 |
+
# Modified from DETR (https://github.com/facebookresearch/detr)
|
| 16 |
+
# Copyright (c) Facebook, Inc. and its affiliates. All Rights Reserved.
|
| 17 |
+
# ------------------------------------------------------------------------
|
| 18 |
+
|
| 19 |
+
from typing import Optional
|
| 20 |
+
|
| 21 |
+
import torch
|
| 22 |
+
import torch.utils.checkpoint as checkpoint
|
| 23 |
+
from torch import Tensor, nn
|
| 24 |
+
|
| 25 |
+
from groundingdino.util.misc import inverse_sigmoid
|
| 26 |
+
|
| 27 |
+
from .fuse_modules import BiAttentionBlock
|
| 28 |
+
from .ms_deform_attn import MultiScaleDeformableAttention as MSDeformAttn
|
| 29 |
+
from .transformer_vanilla import TransformerEncoderLayer
|
| 30 |
+
from .utils import (
|
| 31 |
+
MLP,
|
| 32 |
+
_get_activation_fn,
|
| 33 |
+
_get_clones,
|
| 34 |
+
gen_encoder_output_proposals,
|
| 35 |
+
gen_sineembed_for_position,
|
| 36 |
+
get_sine_pos_embed,
|
| 37 |
+
)
|
| 38 |
+
|
| 39 |
+
|
| 40 |
+
class Transformer(nn.Module):
|
| 41 |
+
def __init__(
|
| 42 |
+
self,
|
| 43 |
+
d_model=256,
|
| 44 |
+
nhead=8,
|
| 45 |
+
num_queries=300,
|
| 46 |
+
num_encoder_layers=6,
|
| 47 |
+
num_unicoder_layers=0,
|
| 48 |
+
num_decoder_layers=6,
|
| 49 |
+
dim_feedforward=2048,
|
| 50 |
+
dropout=0.0,
|
| 51 |
+
activation="relu",
|
| 52 |
+
normalize_before=False,
|
| 53 |
+
return_intermediate_dec=False,
|
| 54 |
+
query_dim=4,
|
| 55 |
+
num_patterns=0,
|
| 56 |
+
# for deformable encoder
|
| 57 |
+
num_feature_levels=1,
|
| 58 |
+
enc_n_points=4,
|
| 59 |
+
dec_n_points=4,
|
| 60 |
+
# init query
|
| 61 |
+
learnable_tgt_init=False,
|
| 62 |
+
# two stage
|
| 63 |
+
two_stage_type="no", # ['no', 'standard', 'early', 'combine', 'enceachlayer', 'enclayer1']
|
| 64 |
+
embed_init_tgt=False,
|
| 65 |
+
# for text
|
| 66 |
+
use_text_enhancer=False,
|
| 67 |
+
use_fusion_layer=False,
|
| 68 |
+
use_checkpoint=False,
|
| 69 |
+
use_transformer_ckpt=False,
|
| 70 |
+
use_text_cross_attention=False,
|
| 71 |
+
text_dropout=0.1,
|
| 72 |
+
fusion_dropout=0.1,
|
| 73 |
+
fusion_droppath=0.0,
|
| 74 |
+
):
|
| 75 |
+
super().__init__()
|
| 76 |
+
self.num_feature_levels = num_feature_levels
|
| 77 |
+
self.num_encoder_layers = num_encoder_layers
|
| 78 |
+
self.num_unicoder_layers = num_unicoder_layers
|
| 79 |
+
self.num_decoder_layers = num_decoder_layers
|
| 80 |
+
self.num_queries = num_queries
|
| 81 |
+
assert query_dim == 4
|
| 82 |
+
|
| 83 |
+
# choose encoder layer type
|
| 84 |
+
encoder_layer = DeformableTransformerEncoderLayer(
|
| 85 |
+
d_model, dim_feedforward, dropout, activation, num_feature_levels, nhead, enc_n_points
|
| 86 |
+
)
|
| 87 |
+
|
| 88 |
+
if use_text_enhancer:
|
| 89 |
+
text_enhance_layer = TransformerEncoderLayer(
|
| 90 |
+
d_model=d_model,
|
| 91 |
+
nhead=nhead // 2,
|
| 92 |
+
dim_feedforward=dim_feedforward // 2,
|
| 93 |
+
dropout=text_dropout,
|
| 94 |
+
)
|
| 95 |
+
else:
|
| 96 |
+
text_enhance_layer = None
|
| 97 |
+
|
| 98 |
+
if use_fusion_layer:
|
| 99 |
+
feature_fusion_layer = BiAttentionBlock(
|
| 100 |
+
v_dim=d_model,
|
| 101 |
+
l_dim=d_model,
|
| 102 |
+
embed_dim=dim_feedforward // 2,
|
| 103 |
+
num_heads=nhead // 2,
|
| 104 |
+
dropout=fusion_dropout,
|
| 105 |
+
drop_path=fusion_droppath,
|
| 106 |
+
)
|
| 107 |
+
else:
|
| 108 |
+
feature_fusion_layer = None
|
| 109 |
+
|
| 110 |
+
encoder_norm = nn.LayerNorm(d_model) if normalize_before else None
|
| 111 |
+
assert encoder_norm is None
|
| 112 |
+
self.encoder = TransformerEncoder(
|
| 113 |
+
encoder_layer,
|
| 114 |
+
num_encoder_layers,
|
| 115 |
+
d_model=d_model,
|
| 116 |
+
num_queries=num_queries,
|
| 117 |
+
text_enhance_layer=text_enhance_layer,
|
| 118 |
+
feature_fusion_layer=feature_fusion_layer,
|
| 119 |
+
use_checkpoint=use_checkpoint,
|
| 120 |
+
use_transformer_ckpt=use_transformer_ckpt,
|
| 121 |
+
)
|
| 122 |
+
|
| 123 |
+
# choose decoder layer type
|
| 124 |
+
decoder_layer = DeformableTransformerDecoderLayer(
|
| 125 |
+
d_model,
|
| 126 |
+
dim_feedforward,
|
| 127 |
+
dropout,
|
| 128 |
+
activation,
|
| 129 |
+
num_feature_levels,
|
| 130 |
+
nhead,
|
| 131 |
+
dec_n_points,
|
| 132 |
+
use_text_cross_attention=use_text_cross_attention,
|
| 133 |
+
)
|
| 134 |
+
|
| 135 |
+
decoder_norm = nn.LayerNorm(d_model)
|
| 136 |
+
self.decoder = TransformerDecoder(
|
| 137 |
+
decoder_layer,
|
| 138 |
+
num_decoder_layers,
|
| 139 |
+
decoder_norm,
|
| 140 |
+
return_intermediate=return_intermediate_dec,
|
| 141 |
+
d_model=d_model,
|
| 142 |
+
query_dim=query_dim,
|
| 143 |
+
num_feature_levels=num_feature_levels,
|
| 144 |
+
)
|
| 145 |
+
|
| 146 |
+
self.d_model = d_model
|
| 147 |
+
self.nhead = nhead
|
| 148 |
+
self.dec_layers = num_decoder_layers
|
| 149 |
+
self.num_queries = num_queries # useful for single stage model only
|
| 150 |
+
self.num_patterns = num_patterns
|
| 151 |
+
if not isinstance(num_patterns, int):
|
| 152 |
+
Warning("num_patterns should be int but {}".format(type(num_patterns)))
|
| 153 |
+
self.num_patterns = 0
|
| 154 |
+
|
| 155 |
+
if num_feature_levels > 1:
|
| 156 |
+
if self.num_encoder_layers > 0:
|
| 157 |
+
self.level_embed = nn.Parameter(torch.Tensor(num_feature_levels, d_model))
|
| 158 |
+
else:
|
| 159 |
+
self.level_embed = None
|
| 160 |
+
|
| 161 |
+
self.learnable_tgt_init = learnable_tgt_init
|
| 162 |
+
assert learnable_tgt_init, "why not learnable_tgt_init"
|
| 163 |
+
self.embed_init_tgt = embed_init_tgt
|
| 164 |
+
if (two_stage_type != "no" and embed_init_tgt) or (two_stage_type == "no"):
|
| 165 |
+
self.tgt_embed = nn.Embedding(self.num_queries, d_model)
|
| 166 |
+
nn.init.normal_(self.tgt_embed.weight.data)
|
| 167 |
+
else:
|
| 168 |
+
self.tgt_embed = None
|
| 169 |
+
|
| 170 |
+
# for two stage
|
| 171 |
+
self.two_stage_type = two_stage_type
|
| 172 |
+
assert two_stage_type in ["no", "standard"], "unknown param {} of two_stage_type".format(
|
| 173 |
+
two_stage_type
|
| 174 |
+
)
|
| 175 |
+
if two_stage_type == "standard":
|
| 176 |
+
# anchor selection at the output of encoder
|
| 177 |
+
self.enc_output = nn.Linear(d_model, d_model)
|
| 178 |
+
self.enc_output_norm = nn.LayerNorm(d_model)
|
| 179 |
+
self.two_stage_wh_embedding = None
|
| 180 |
+
|
| 181 |
+
if two_stage_type == "no":
|
| 182 |
+
self.init_ref_points(num_queries) # init self.refpoint_embed
|
| 183 |
+
|
| 184 |
+
self.enc_out_class_embed = None
|
| 185 |
+
self.enc_out_bbox_embed = None
|
| 186 |
+
|
| 187 |
+
self._reset_parameters()
|
| 188 |
+
|
| 189 |
+
def _reset_parameters(self):
|
| 190 |
+
for p in self.parameters():
|
| 191 |
+
if p.dim() > 1:
|
| 192 |
+
nn.init.xavier_uniform_(p)
|
| 193 |
+
for m in self.modules():
|
| 194 |
+
if isinstance(m, MSDeformAttn):
|
| 195 |
+
m._reset_parameters()
|
| 196 |
+
if self.num_feature_levels > 1 and self.level_embed is not None:
|
| 197 |
+
nn.init.normal_(self.level_embed)
|
| 198 |
+
|
| 199 |
+
def get_valid_ratio(self, mask):
|
| 200 |
+
_, H, W = mask.shape
|
| 201 |
+
valid_H = torch.sum(~mask[:, :, 0], 1)
|
| 202 |
+
valid_W = torch.sum(~mask[:, 0, :], 1)
|
| 203 |
+
valid_ratio_h = valid_H.float() / H
|
| 204 |
+
valid_ratio_w = valid_W.float() / W
|
| 205 |
+
valid_ratio = torch.stack([valid_ratio_w, valid_ratio_h], -1)
|
| 206 |
+
return valid_ratio
|
| 207 |
+
|
| 208 |
+
def init_ref_points(self, use_num_queries):
|
| 209 |
+
self.refpoint_embed = nn.Embedding(use_num_queries, 4)
|
| 210 |
+
|
| 211 |
+
def forward(self, srcs, masks, refpoint_embed, pos_embeds, tgt, attn_mask=None, text_dict=None):
|
| 212 |
+
"""
|
| 213 |
+
Input:
|
| 214 |
+
- srcs: List of multi features [bs, ci, hi, wi]
|
| 215 |
+
- masks: List of multi masks [bs, hi, wi]
|
| 216 |
+
- refpoint_embed: [bs, num_dn, 4]. None in infer
|
| 217 |
+
- pos_embeds: List of multi pos embeds [bs, ci, hi, wi]
|
| 218 |
+
- tgt: [bs, num_dn, d_model]. None in infer
|
| 219 |
+
|
| 220 |
+
"""
|
| 221 |
+
# prepare input for encoder
|
| 222 |
+
src_flatten = []
|
| 223 |
+
mask_flatten = []
|
| 224 |
+
lvl_pos_embed_flatten = []
|
| 225 |
+
spatial_shapes = []
|
| 226 |
+
for lvl, (src, mask, pos_embed) in enumerate(zip(srcs, masks, pos_embeds)):
|
| 227 |
+
bs, c, h, w = src.shape
|
| 228 |
+
spatial_shape = (h, w)
|
| 229 |
+
spatial_shapes.append(spatial_shape)
|
| 230 |
+
|
| 231 |
+
src = src.flatten(2).transpose(1, 2) # bs, hw, c
|
| 232 |
+
mask = mask.flatten(1) # bs, hw
|
| 233 |
+
pos_embed = pos_embed.flatten(2).transpose(1, 2) # bs, hw, c
|
| 234 |
+
if self.num_feature_levels > 1 and self.level_embed is not None:
|
| 235 |
+
lvl_pos_embed = pos_embed + self.level_embed[lvl].view(1, 1, -1)
|
| 236 |
+
else:
|
| 237 |
+
lvl_pos_embed = pos_embed
|
| 238 |
+
lvl_pos_embed_flatten.append(lvl_pos_embed)
|
| 239 |
+
src_flatten.append(src)
|
| 240 |
+
mask_flatten.append(mask)
|
| 241 |
+
src_flatten = torch.cat(src_flatten, 1) # bs, \sum{hxw}, c
|
| 242 |
+
mask_flatten = torch.cat(mask_flatten, 1) # bs, \sum{hxw}
|
| 243 |
+
lvl_pos_embed_flatten = torch.cat(lvl_pos_embed_flatten, 1) # bs, \sum{hxw}, c
|
| 244 |
+
spatial_shapes = torch.as_tensor(
|
| 245 |
+
spatial_shapes, dtype=torch.long, device=src_flatten.device
|
| 246 |
+
)
|
| 247 |
+
level_start_index = torch.cat(
|
| 248 |
+
(spatial_shapes.new_zeros((1,)), spatial_shapes.prod(1).cumsum(0)[:-1])
|
| 249 |
+
)
|
| 250 |
+
valid_ratios = torch.stack([self.get_valid_ratio(m) for m in masks], 1)
|
| 251 |
+
|
| 252 |
+
# two stage
|
| 253 |
+
enc_topk_proposals = enc_refpoint_embed = None
|
| 254 |
+
|
| 255 |
+
#########################################################
|
| 256 |
+
# Begin Encoder
|
| 257 |
+
#########################################################
|
| 258 |
+
memory, memory_text = self.encoder(
|
| 259 |
+
src_flatten,
|
| 260 |
+
pos=lvl_pos_embed_flatten,
|
| 261 |
+
level_start_index=level_start_index,
|
| 262 |
+
spatial_shapes=spatial_shapes,
|
| 263 |
+
valid_ratios=valid_ratios,
|
| 264 |
+
key_padding_mask=mask_flatten,
|
| 265 |
+
memory_text=text_dict["encoded_text"],
|
| 266 |
+
text_attention_mask=~text_dict["text_token_mask"],
|
| 267 |
+
# we ~ the mask . False means use the token; True means pad the token
|
| 268 |
+
position_ids=text_dict["position_ids"],
|
| 269 |
+
text_self_attention_masks=text_dict["text_self_attention_masks"],
|
| 270 |
+
)
|
| 271 |
+
#########################################################
|
| 272 |
+
# End Encoder
|
| 273 |
+
# - memory: bs, \sum{hw}, c
|
| 274 |
+
# - mask_flatten: bs, \sum{hw}
|
| 275 |
+
# - lvl_pos_embed_flatten: bs, \sum{hw}, c
|
| 276 |
+
# - enc_intermediate_output: None or (nenc+1, bs, nq, c) or (nenc, bs, nq, c)
|
| 277 |
+
# - enc_intermediate_refpoints: None or (nenc+1, bs, nq, c) or (nenc, bs, nq, c)
|
| 278 |
+
#########################################################
|
| 279 |
+
text_dict["encoded_text"] = memory_text
|
| 280 |
+
# if os.environ.get("SHILONG_AMP_INFNAN_DEBUG") == '1':
|
| 281 |
+
# if memory.isnan().any() | memory.isinf().any():
|
| 282 |
+
# import ipdb; ipdb.set_trace()
|
| 283 |
+
|
| 284 |
+
if self.two_stage_type == "standard":
|
| 285 |
+
output_memory, output_proposals = gen_encoder_output_proposals(
|
| 286 |
+
memory, mask_flatten, spatial_shapes
|
| 287 |
+
)
|
| 288 |
+
output_memory = self.enc_output_norm(self.enc_output(output_memory))
|
| 289 |
+
|
| 290 |
+
if text_dict is not None:
|
| 291 |
+
enc_outputs_class_unselected = self.enc_out_class_embed(output_memory, text_dict)
|
| 292 |
+
else:
|
| 293 |
+
enc_outputs_class_unselected = self.enc_out_class_embed(output_memory)
|
| 294 |
+
|
| 295 |
+
topk_logits = enc_outputs_class_unselected.max(-1)[0]
|
| 296 |
+
enc_outputs_coord_unselected = (
|
| 297 |
+
self.enc_out_bbox_embed(output_memory) + output_proposals
|
| 298 |
+
) # (bs, \sum{hw}, 4) unsigmoid
|
| 299 |
+
topk = self.num_queries
|
| 300 |
+
|
| 301 |
+
topk_proposals = torch.topk(topk_logits, topk, dim=1)[1] # bs, nq
|
| 302 |
+
|
| 303 |
+
# gather boxes
|
| 304 |
+
refpoint_embed_undetach = torch.gather(
|
| 305 |
+
enc_outputs_coord_unselected, 1, topk_proposals.unsqueeze(-1).repeat(1, 1, 4)
|
| 306 |
+
) # unsigmoid
|
| 307 |
+
refpoint_embed_ = refpoint_embed_undetach.detach()
|
| 308 |
+
init_box_proposal = torch.gather(
|
| 309 |
+
output_proposals, 1, topk_proposals.unsqueeze(-1).repeat(1, 1, 4)
|
| 310 |
+
).sigmoid() # sigmoid
|
| 311 |
+
|
| 312 |
+
# gather tgt
|
| 313 |
+
tgt_undetach = torch.gather(
|
| 314 |
+
output_memory, 1, topk_proposals.unsqueeze(-1).repeat(1, 1, self.d_model)
|
| 315 |
+
)
|
| 316 |
+
if self.embed_init_tgt:
|
| 317 |
+
tgt_ = (
|
| 318 |
+
self.tgt_embed.weight[:, None, :].repeat(1, bs, 1).transpose(0, 1)
|
| 319 |
+
) # nq, bs, d_model
|
| 320 |
+
else:
|
| 321 |
+
tgt_ = tgt_undetach.detach()
|
| 322 |
+
|
| 323 |
+
if refpoint_embed is not None:
|
| 324 |
+
refpoint_embed = torch.cat([refpoint_embed, refpoint_embed_], dim=1)
|
| 325 |
+
tgt = torch.cat([tgt, tgt_], dim=1)
|
| 326 |
+
else:
|
| 327 |
+
refpoint_embed, tgt = refpoint_embed_, tgt_
|
| 328 |
+
|
| 329 |
+
elif self.two_stage_type == "no":
|
| 330 |
+
tgt_ = (
|
| 331 |
+
self.tgt_embed.weight[:, None, :].repeat(1, bs, 1).transpose(0, 1)
|
| 332 |
+
) # nq, bs, d_model
|
| 333 |
+
refpoint_embed_ = (
|
| 334 |
+
self.refpoint_embed.weight[:, None, :].repeat(1, bs, 1).transpose(0, 1)
|
| 335 |
+
) # nq, bs, 4
|
| 336 |
+
|
| 337 |
+
if refpoint_embed is not None:
|
| 338 |
+
refpoint_embed = torch.cat([refpoint_embed, refpoint_embed_], dim=1)
|
| 339 |
+
tgt = torch.cat([tgt, tgt_], dim=1)
|
| 340 |
+
else:
|
| 341 |
+
refpoint_embed, tgt = refpoint_embed_, tgt_
|
| 342 |
+
|
| 343 |
+
if self.num_patterns > 0:
|
| 344 |
+
tgt_embed = tgt.repeat(1, self.num_patterns, 1)
|
| 345 |
+
refpoint_embed = refpoint_embed.repeat(1, self.num_patterns, 1)
|
| 346 |
+
tgt_pat = self.patterns.weight[None, :, :].repeat_interleave(
|
| 347 |
+
self.num_queries, 1
|
| 348 |
+
) # 1, n_q*n_pat, d_model
|
| 349 |
+
tgt = tgt_embed + tgt_pat
|
| 350 |
+
|
| 351 |
+
init_box_proposal = refpoint_embed_.sigmoid()
|
| 352 |
+
|
| 353 |
+
else:
|
| 354 |
+
raise NotImplementedError("unknown two_stage_type {}".format(self.two_stage_type))
|
| 355 |
+
#########################################################
|
| 356 |
+
# End preparing tgt
|
| 357 |
+
# - tgt: bs, NQ, d_model
|
| 358 |
+
# - refpoint_embed(unsigmoid): bs, NQ, d_model
|
| 359 |
+
#########################################################
|
| 360 |
+
|
| 361 |
+
#########################################################
|
| 362 |
+
# Begin Decoder
|
| 363 |
+
#########################################################
|
| 364 |
+
hs, references = self.decoder(
|
| 365 |
+
tgt=tgt.transpose(0, 1),
|
| 366 |
+
memory=memory.transpose(0, 1),
|
| 367 |
+
memory_key_padding_mask=mask_flatten,
|
| 368 |
+
pos=lvl_pos_embed_flatten.transpose(0, 1),
|
| 369 |
+
refpoints_unsigmoid=refpoint_embed.transpose(0, 1),
|
| 370 |
+
level_start_index=level_start_index,
|
| 371 |
+
spatial_shapes=spatial_shapes,
|
| 372 |
+
valid_ratios=valid_ratios,
|
| 373 |
+
tgt_mask=attn_mask,
|
| 374 |
+
memory_text=text_dict["encoded_text"],
|
| 375 |
+
text_attention_mask=~text_dict["text_token_mask"],
|
| 376 |
+
# we ~ the mask . False means use the token; True means pad the token
|
| 377 |
+
)
|
| 378 |
+
#########################################################
|
| 379 |
+
# End Decoder
|
| 380 |
+
# hs: n_dec, bs, nq, d_model
|
| 381 |
+
# references: n_dec+1, bs, nq, query_dim
|
| 382 |
+
#########################################################
|
| 383 |
+
|
| 384 |
+
#########################################################
|
| 385 |
+
# Begin postprocess
|
| 386 |
+
#########################################################
|
| 387 |
+
if self.two_stage_type == "standard":
|
| 388 |
+
hs_enc = tgt_undetach.unsqueeze(0)
|
| 389 |
+
ref_enc = refpoint_embed_undetach.sigmoid().unsqueeze(0)
|
| 390 |
+
else:
|
| 391 |
+
hs_enc = ref_enc = None
|
| 392 |
+
#########################################################
|
| 393 |
+
# End postprocess
|
| 394 |
+
# hs_enc: (n_enc+1, bs, nq, d_model) or (1, bs, nq, d_model) or (n_enc, bs, nq, d_model) or None
|
| 395 |
+
# ref_enc: (n_enc+1, bs, nq, query_dim) or (1, bs, nq, query_dim) or (n_enc, bs, nq, d_model) or None
|
| 396 |
+
#########################################################
|
| 397 |
+
|
| 398 |
+
return hs, references, hs_enc, ref_enc, init_box_proposal
|
| 399 |
+
# hs: (n_dec, bs, nq, d_model)
|
| 400 |
+
# references: sigmoid coordinates. (n_dec+1, bs, bq, 4)
|
| 401 |
+
# hs_enc: (n_enc+1, bs, nq, d_model) or (1, bs, nq, d_model) or None
|
| 402 |
+
# ref_enc: sigmoid coordinates. \
|
| 403 |
+
# (n_enc+1, bs, nq, query_dim) or (1, bs, nq, query_dim) or None
|
| 404 |
+
|
| 405 |
+
|
| 406 |
+
class TransformerEncoder(nn.Module):
|
| 407 |
+
def __init__(
|
| 408 |
+
self,
|
| 409 |
+
encoder_layer,
|
| 410 |
+
num_layers,
|
| 411 |
+
d_model=256,
|
| 412 |
+
num_queries=300,
|
| 413 |
+
enc_layer_share=False,
|
| 414 |
+
text_enhance_layer=None,
|
| 415 |
+
feature_fusion_layer=None,
|
| 416 |
+
use_checkpoint=False,
|
| 417 |
+
use_transformer_ckpt=False,
|
| 418 |
+
):
|
| 419 |
+
"""_summary_
|
| 420 |
+
|
| 421 |
+
Args:
|
| 422 |
+
encoder_layer (_type_): _description_
|
| 423 |
+
num_layers (_type_): _description_
|
| 424 |
+
norm (_type_, optional): _description_. Defaults to None.
|
| 425 |
+
d_model (int, optional): _description_. Defaults to 256.
|
| 426 |
+
num_queries (int, optional): _description_. Defaults to 300.
|
| 427 |
+
enc_layer_share (bool, optional): _description_. Defaults to False.
|
| 428 |
+
|
| 429 |
+
"""
|
| 430 |
+
super().__init__()
|
| 431 |
+
# prepare layers
|
| 432 |
+
self.layers = []
|
| 433 |
+
self.text_layers = []
|
| 434 |
+
self.fusion_layers = []
|
| 435 |
+
if num_layers > 0:
|
| 436 |
+
self.layers = _get_clones(encoder_layer, num_layers, layer_share=enc_layer_share)
|
| 437 |
+
|
| 438 |
+
if text_enhance_layer is not None:
|
| 439 |
+
self.text_layers = _get_clones(
|
| 440 |
+
text_enhance_layer, num_layers, layer_share=enc_layer_share
|
| 441 |
+
)
|
| 442 |
+
if feature_fusion_layer is not None:
|
| 443 |
+
self.fusion_layers = _get_clones(
|
| 444 |
+
feature_fusion_layer, num_layers, layer_share=enc_layer_share
|
| 445 |
+
)
|
| 446 |
+
else:
|
| 447 |
+
self.layers = []
|
| 448 |
+
del encoder_layer
|
| 449 |
+
|
| 450 |
+
if text_enhance_layer is not None:
|
| 451 |
+
self.text_layers = []
|
| 452 |
+
del text_enhance_layer
|
| 453 |
+
if feature_fusion_layer is not None:
|
| 454 |
+
self.fusion_layers = []
|
| 455 |
+
del feature_fusion_layer
|
| 456 |
+
|
| 457 |
+
self.query_scale = None
|
| 458 |
+
self.num_queries = num_queries
|
| 459 |
+
self.num_layers = num_layers
|
| 460 |
+
self.d_model = d_model
|
| 461 |
+
|
| 462 |
+
self.use_checkpoint = use_checkpoint
|
| 463 |
+
self.use_transformer_ckpt = use_transformer_ckpt
|
| 464 |
+
|
| 465 |
+
@staticmethod
|
| 466 |
+
def get_reference_points(spatial_shapes, valid_ratios, device):
|
| 467 |
+
reference_points_list = []
|
| 468 |
+
for lvl, (H_, W_) in enumerate(spatial_shapes):
|
| 469 |
+
|
| 470 |
+
ref_y, ref_x = torch.meshgrid(
|
| 471 |
+
torch.linspace(0.5, H_ - 0.5, H_, dtype=torch.float32, device=device),
|
| 472 |
+
torch.linspace(0.5, W_ - 0.5, W_, dtype=torch.float32, device=device),
|
| 473 |
+
)
|
| 474 |
+
ref_y = ref_y.reshape(-1)[None] / (valid_ratios[:, None, lvl, 1] * H_)
|
| 475 |
+
ref_x = ref_x.reshape(-1)[None] / (valid_ratios[:, None, lvl, 0] * W_)
|
| 476 |
+
ref = torch.stack((ref_x, ref_y), -1)
|
| 477 |
+
reference_points_list.append(ref)
|
| 478 |
+
reference_points = torch.cat(reference_points_list, 1)
|
| 479 |
+
reference_points = reference_points[:, :, None] * valid_ratios[:, None]
|
| 480 |
+
return reference_points
|
| 481 |
+
|
| 482 |
+
def forward(
|
| 483 |
+
self,
|
| 484 |
+
# for images
|
| 485 |
+
src: Tensor,
|
| 486 |
+
pos: Tensor,
|
| 487 |
+
spatial_shapes: Tensor,
|
| 488 |
+
level_start_index: Tensor,
|
| 489 |
+
valid_ratios: Tensor,
|
| 490 |
+
key_padding_mask: Tensor,
|
| 491 |
+
# for texts
|
| 492 |
+
memory_text: Tensor = None,
|
| 493 |
+
text_attention_mask: Tensor = None,
|
| 494 |
+
pos_text: Tensor = None,
|
| 495 |
+
text_self_attention_masks: Tensor = None,
|
| 496 |
+
position_ids: Tensor = None,
|
| 497 |
+
):
|
| 498 |
+
"""
|
| 499 |
+
Input:
|
| 500 |
+
- src: [bs, sum(hi*wi), 256]
|
| 501 |
+
- pos: pos embed for src. [bs, sum(hi*wi), 256]
|
| 502 |
+
- spatial_shapes: h,w of each level [num_level, 2]
|
| 503 |
+
- level_start_index: [num_level] start point of level in sum(hi*wi).
|
| 504 |
+
- valid_ratios: [bs, num_level, 2]
|
| 505 |
+
- key_padding_mask: [bs, sum(hi*wi)]
|
| 506 |
+
|
| 507 |
+
- memory_text: bs, n_text, 256
|
| 508 |
+
- text_attention_mask: bs, n_text
|
| 509 |
+
False for no padding; True for padding
|
| 510 |
+
- pos_text: bs, n_text, 256
|
| 511 |
+
|
| 512 |
+
- position_ids: bs, n_text
|
| 513 |
+
Intermedia:
|
| 514 |
+
- reference_points: [bs, sum(hi*wi), num_level, 2]
|
| 515 |
+
Outpus:
|
| 516 |
+
- output: [bs, sum(hi*wi), 256]
|
| 517 |
+
"""
|
| 518 |
+
|
| 519 |
+
output = src
|
| 520 |
+
|
| 521 |
+
# preparation and reshape
|
| 522 |
+
if self.num_layers > 0:
|
| 523 |
+
reference_points = self.get_reference_points(
|
| 524 |
+
spatial_shapes, valid_ratios, device=src.device
|
| 525 |
+
)
|
| 526 |
+
|
| 527 |
+
if self.text_layers:
|
| 528 |
+
# generate pos_text
|
| 529 |
+
bs, n_text, text_dim = memory_text.shape
|
| 530 |
+
if pos_text is None and position_ids is None:
|
| 531 |
+
pos_text = (
|
| 532 |
+
torch.arange(n_text, device=memory_text.device)
|
| 533 |
+
.float()
|
| 534 |
+
.unsqueeze(0)
|
| 535 |
+
.unsqueeze(-1)
|
| 536 |
+
.repeat(bs, 1, 1)
|
| 537 |
+
)
|
| 538 |
+
pos_text = get_sine_pos_embed(pos_text, num_pos_feats=256, exchange_xy=False)
|
| 539 |
+
if position_ids is not None:
|
| 540 |
+
pos_text = get_sine_pos_embed(
|
| 541 |
+
position_ids[..., None], num_pos_feats=256, exchange_xy=False
|
| 542 |
+
)
|
| 543 |
+
|
| 544 |
+
# main process
|
| 545 |
+
for layer_id, layer in enumerate(self.layers):
|
| 546 |
+
# if output.isnan().any() or memory_text.isnan().any():
|
| 547 |
+
# if os.environ.get('IPDB_SHILONG_DEBUG', None) == 'INFO':
|
| 548 |
+
# import ipdb; ipdb.set_trace()
|
| 549 |
+
if self.fusion_layers:
|
| 550 |
+
if self.use_checkpoint:
|
| 551 |
+
output, memory_text = checkpoint.checkpoint(
|
| 552 |
+
self.fusion_layers[layer_id],
|
| 553 |
+
output,
|
| 554 |
+
memory_text,
|
| 555 |
+
key_padding_mask,
|
| 556 |
+
text_attention_mask,
|
| 557 |
+
)
|
| 558 |
+
else:
|
| 559 |
+
output, memory_text = self.fusion_layers[layer_id](
|
| 560 |
+
v=output,
|
| 561 |
+
l=memory_text,
|
| 562 |
+
attention_mask_v=key_padding_mask,
|
| 563 |
+
attention_mask_l=text_attention_mask,
|
| 564 |
+
)
|
| 565 |
+
|
| 566 |
+
if self.text_layers:
|
| 567 |
+
memory_text = self.text_layers[layer_id](
|
| 568 |
+
src=memory_text.transpose(0, 1),
|
| 569 |
+
src_mask=~text_self_attention_masks, # note we use ~ for mask here
|
| 570 |
+
src_key_padding_mask=text_attention_mask,
|
| 571 |
+
pos=(pos_text.transpose(0, 1) if pos_text is not None else None),
|
| 572 |
+
).transpose(0, 1)
|
| 573 |
+
|
| 574 |
+
# main process
|
| 575 |
+
if self.use_transformer_ckpt:
|
| 576 |
+
output = checkpoint.checkpoint(
|
| 577 |
+
layer,
|
| 578 |
+
output,
|
| 579 |
+
pos,
|
| 580 |
+
reference_points,
|
| 581 |
+
spatial_shapes,
|
| 582 |
+
level_start_index,
|
| 583 |
+
key_padding_mask,
|
| 584 |
+
)
|
| 585 |
+
else:
|
| 586 |
+
output = layer(
|
| 587 |
+
src=output,
|
| 588 |
+
pos=pos,
|
| 589 |
+
reference_points=reference_points,
|
| 590 |
+
spatial_shapes=spatial_shapes,
|
| 591 |
+
level_start_index=level_start_index,
|
| 592 |
+
key_padding_mask=key_padding_mask,
|
| 593 |
+
)
|
| 594 |
+
|
| 595 |
+
return output, memory_text
|
| 596 |
+
|
| 597 |
+
|
| 598 |
+
class TransformerDecoder(nn.Module):
|
| 599 |
+
def __init__(
|
| 600 |
+
self,
|
| 601 |
+
decoder_layer,
|
| 602 |
+
num_layers,
|
| 603 |
+
norm=None,
|
| 604 |
+
return_intermediate=False,
|
| 605 |
+
d_model=256,
|
| 606 |
+
query_dim=4,
|
| 607 |
+
num_feature_levels=1,
|
| 608 |
+
):
|
| 609 |
+
super().__init__()
|
| 610 |
+
if num_layers > 0:
|
| 611 |
+
self.layers = _get_clones(decoder_layer, num_layers)
|
| 612 |
+
else:
|
| 613 |
+
self.layers = []
|
| 614 |
+
self.num_layers = num_layers
|
| 615 |
+
self.norm = norm
|
| 616 |
+
self.return_intermediate = return_intermediate
|
| 617 |
+
assert return_intermediate, "support return_intermediate only"
|
| 618 |
+
self.query_dim = query_dim
|
| 619 |
+
assert query_dim in [2, 4], "query_dim should be 2/4 but {}".format(query_dim)
|
| 620 |
+
self.num_feature_levels = num_feature_levels
|
| 621 |
+
|
| 622 |
+
self.ref_point_head = MLP(query_dim // 2 * d_model, d_model, d_model, 2)
|
| 623 |
+
self.query_pos_sine_scale = None
|
| 624 |
+
|
| 625 |
+
self.query_scale = None
|
| 626 |
+
self.bbox_embed = None
|
| 627 |
+
self.class_embed = None
|
| 628 |
+
|
| 629 |
+
self.d_model = d_model
|
| 630 |
+
|
| 631 |
+
self.ref_anchor_head = None
|
| 632 |
+
|
| 633 |
+
def forward(
|
| 634 |
+
self,
|
| 635 |
+
tgt,
|
| 636 |
+
memory,
|
| 637 |
+
tgt_mask: Optional[Tensor] = None,
|
| 638 |
+
memory_mask: Optional[Tensor] = None,
|
| 639 |
+
tgt_key_padding_mask: Optional[Tensor] = None,
|
| 640 |
+
memory_key_padding_mask: Optional[Tensor] = None,
|
| 641 |
+
pos: Optional[Tensor] = None,
|
| 642 |
+
refpoints_unsigmoid: Optional[Tensor] = None, # num_queries, bs, 2
|
| 643 |
+
# for memory
|
| 644 |
+
level_start_index: Optional[Tensor] = None, # num_levels
|
| 645 |
+
spatial_shapes: Optional[Tensor] = None, # bs, num_levels, 2
|
| 646 |
+
valid_ratios: Optional[Tensor] = None,
|
| 647 |
+
# for text
|
| 648 |
+
memory_text: Optional[Tensor] = None,
|
| 649 |
+
text_attention_mask: Optional[Tensor] = None,
|
| 650 |
+
):
|
| 651 |
+
"""
|
| 652 |
+
Input:
|
| 653 |
+
- tgt: nq, bs, d_model
|
| 654 |
+
- memory: hw, bs, d_model
|
| 655 |
+
- pos: hw, bs, d_model
|
| 656 |
+
- refpoints_unsigmoid: nq, bs, 2/4
|
| 657 |
+
- valid_ratios/spatial_shapes: bs, nlevel, 2
|
| 658 |
+
"""
|
| 659 |
+
output = tgt
|
| 660 |
+
|
| 661 |
+
intermediate = []
|
| 662 |
+
reference_points = refpoints_unsigmoid.sigmoid()
|
| 663 |
+
ref_points = [reference_points]
|
| 664 |
+
|
| 665 |
+
for layer_id, layer in enumerate(self.layers):
|
| 666 |
+
|
| 667 |
+
if reference_points.shape[-1] == 4:
|
| 668 |
+
reference_points_input = (
|
| 669 |
+
reference_points[:, :, None]
|
| 670 |
+
* torch.cat([valid_ratios, valid_ratios], -1)[None, :]
|
| 671 |
+
) # nq, bs, nlevel, 4
|
| 672 |
+
else:
|
| 673 |
+
assert reference_points.shape[-1] == 2
|
| 674 |
+
reference_points_input = reference_points[:, :, None] * valid_ratios[None, :]
|
| 675 |
+
query_sine_embed = gen_sineembed_for_position(
|
| 676 |
+
reference_points_input[:, :, 0, :]
|
| 677 |
+
) # nq, bs, 256*2
|
| 678 |
+
|
| 679 |
+
# conditional query
|
| 680 |
+
raw_query_pos = self.ref_point_head(query_sine_embed) # nq, bs, 256
|
| 681 |
+
pos_scale = self.query_scale(output) if self.query_scale is not None else 1
|
| 682 |
+
query_pos = pos_scale * raw_query_pos
|
| 683 |
+
# if os.environ.get("SHILONG_AMP_INFNAN_DEBUG") == '1':
|
| 684 |
+
# if query_pos.isnan().any() | query_pos.isinf().any():
|
| 685 |
+
# import ipdb; ipdb.set_trace()
|
| 686 |
+
|
| 687 |
+
# main process
|
| 688 |
+
output = layer(
|
| 689 |
+
tgt=output,
|
| 690 |
+
tgt_query_pos=query_pos,
|
| 691 |
+
tgt_query_sine_embed=query_sine_embed,
|
| 692 |
+
tgt_key_padding_mask=tgt_key_padding_mask,
|
| 693 |
+
tgt_reference_points=reference_points_input,
|
| 694 |
+
memory_text=memory_text,
|
| 695 |
+
text_attention_mask=text_attention_mask,
|
| 696 |
+
memory=memory,
|
| 697 |
+
memory_key_padding_mask=memory_key_padding_mask,
|
| 698 |
+
memory_level_start_index=level_start_index,
|
| 699 |
+
memory_spatial_shapes=spatial_shapes,
|
| 700 |
+
memory_pos=pos,
|
| 701 |
+
self_attn_mask=tgt_mask,
|
| 702 |
+
cross_attn_mask=memory_mask,
|
| 703 |
+
)
|
| 704 |
+
if output.isnan().any() | output.isinf().any():
|
| 705 |
+
print(f"output layer_id {layer_id} is nan")
|
| 706 |
+
try:
|
| 707 |
+
num_nan = output.isnan().sum().item()
|
| 708 |
+
num_inf = output.isinf().sum().item()
|
| 709 |
+
print(f"num_nan {num_nan}, num_inf {num_inf}")
|
| 710 |
+
except Exception as e:
|
| 711 |
+
print(e)
|
| 712 |
+
# if os.environ.get("SHILONG_AMP_INFNAN_DEBUG") == '1':
|
| 713 |
+
# import ipdb; ipdb.set_trace()
|
| 714 |
+
|
| 715 |
+
# iter update
|
| 716 |
+
if self.bbox_embed is not None:
|
| 717 |
+
# box_holder = self.bbox_embed(output)
|
| 718 |
+
# box_holder[..., :self.query_dim] += inverse_sigmoid(reference_points)
|
| 719 |
+
# new_reference_points = box_holder[..., :self.query_dim].sigmoid()
|
| 720 |
+
|
| 721 |
+
reference_before_sigmoid = inverse_sigmoid(reference_points)
|
| 722 |
+
delta_unsig = self.bbox_embed[layer_id](output)
|
| 723 |
+
outputs_unsig = delta_unsig + reference_before_sigmoid
|
| 724 |
+
new_reference_points = outputs_unsig.sigmoid()
|
| 725 |
+
|
| 726 |
+
reference_points = new_reference_points.detach()
|
| 727 |
+
# if layer_id != self.num_layers - 1:
|
| 728 |
+
ref_points.append(new_reference_points)
|
| 729 |
+
|
| 730 |
+
intermediate.append(self.norm(output))
|
| 731 |
+
|
| 732 |
+
return [
|
| 733 |
+
[itm_out.transpose(0, 1) for itm_out in intermediate],
|
| 734 |
+
[itm_refpoint.transpose(0, 1) for itm_refpoint in ref_points],
|
| 735 |
+
]
|
| 736 |
+
|
| 737 |
+
|
| 738 |
+
class DeformableTransformerEncoderLayer(nn.Module):
|
| 739 |
+
def __init__(
|
| 740 |
+
self,
|
| 741 |
+
d_model=256,
|
| 742 |
+
d_ffn=1024,
|
| 743 |
+
dropout=0.1,
|
| 744 |
+
activation="relu",
|
| 745 |
+
n_levels=4,
|
| 746 |
+
n_heads=8,
|
| 747 |
+
n_points=4,
|
| 748 |
+
):
|
| 749 |
+
super().__init__()
|
| 750 |
+
|
| 751 |
+
# self attention
|
| 752 |
+
self.self_attn = MSDeformAttn(
|
| 753 |
+
embed_dim=d_model,
|
| 754 |
+
num_levels=n_levels,
|
| 755 |
+
num_heads=n_heads,
|
| 756 |
+
num_points=n_points,
|
| 757 |
+
batch_first=True,
|
| 758 |
+
)
|
| 759 |
+
self.dropout1 = nn.Dropout(dropout)
|
| 760 |
+
self.norm1 = nn.LayerNorm(d_model)
|
| 761 |
+
|
| 762 |
+
# ffn
|
| 763 |
+
self.linear1 = nn.Linear(d_model, d_ffn)
|
| 764 |
+
self.activation = _get_activation_fn(activation, d_model=d_ffn)
|
| 765 |
+
self.dropout2 = nn.Dropout(dropout)
|
| 766 |
+
self.linear2 = nn.Linear(d_ffn, d_model)
|
| 767 |
+
self.dropout3 = nn.Dropout(dropout)
|
| 768 |
+
self.norm2 = nn.LayerNorm(d_model)
|
| 769 |
+
|
| 770 |
+
@staticmethod
|
| 771 |
+
def with_pos_embed(tensor, pos):
|
| 772 |
+
return tensor if pos is None else tensor + pos
|
| 773 |
+
|
| 774 |
+
def forward_ffn(self, src):
|
| 775 |
+
src2 = self.linear2(self.dropout2(self.activation(self.linear1(src))))
|
| 776 |
+
src = src + self.dropout3(src2)
|
| 777 |
+
src = self.norm2(src)
|
| 778 |
+
return src
|
| 779 |
+
|
| 780 |
+
def forward(
|
| 781 |
+
self, src, pos, reference_points, spatial_shapes, level_start_index, key_padding_mask=None
|
| 782 |
+
):
|
| 783 |
+
# self attention
|
| 784 |
+
# import ipdb; ipdb.set_trace()
|
| 785 |
+
src2 = self.self_attn(
|
| 786 |
+
query=self.with_pos_embed(src, pos),
|
| 787 |
+
reference_points=reference_points,
|
| 788 |
+
value=src,
|
| 789 |
+
spatial_shapes=spatial_shapes,
|
| 790 |
+
level_start_index=level_start_index,
|
| 791 |
+
key_padding_mask=key_padding_mask,
|
| 792 |
+
)
|
| 793 |
+
src = src + self.dropout1(src2)
|
| 794 |
+
src = self.norm1(src)
|
| 795 |
+
|
| 796 |
+
# ffn
|
| 797 |
+
src = self.forward_ffn(src)
|
| 798 |
+
|
| 799 |
+
return src
|
| 800 |
+
|
| 801 |
+
|
| 802 |
+
class DeformableTransformerDecoderLayer(nn.Module):
|
| 803 |
+
def __init__(
|
| 804 |
+
self,
|
| 805 |
+
d_model=256,
|
| 806 |
+
d_ffn=1024,
|
| 807 |
+
dropout=0.1,
|
| 808 |
+
activation="relu",
|
| 809 |
+
n_levels=4,
|
| 810 |
+
n_heads=8,
|
| 811 |
+
n_points=4,
|
| 812 |
+
use_text_feat_guide=False,
|
| 813 |
+
use_text_cross_attention=False,
|
| 814 |
+
):
|
| 815 |
+
super().__init__()
|
| 816 |
+
|
| 817 |
+
# cross attention
|
| 818 |
+
self.cross_attn = MSDeformAttn(
|
| 819 |
+
embed_dim=d_model,
|
| 820 |
+
num_levels=n_levels,
|
| 821 |
+
num_heads=n_heads,
|
| 822 |
+
num_points=n_points,
|
| 823 |
+
batch_first=True,
|
| 824 |
+
)
|
| 825 |
+
self.dropout1 = nn.Dropout(dropout) if dropout > 0 else nn.Identity()
|
| 826 |
+
self.norm1 = nn.LayerNorm(d_model)
|
| 827 |
+
|
| 828 |
+
# cross attention text
|
| 829 |
+
if use_text_cross_attention:
|
| 830 |
+
self.ca_text = nn.MultiheadAttention(d_model, n_heads, dropout=dropout)
|
| 831 |
+
self.catext_dropout = nn.Dropout(dropout) if dropout > 0 else nn.Identity()
|
| 832 |
+
self.catext_norm = nn.LayerNorm(d_model)
|
| 833 |
+
|
| 834 |
+
# self attention
|
| 835 |
+
self.self_attn = nn.MultiheadAttention(d_model, n_heads, dropout=dropout)
|
| 836 |
+
self.dropout2 = nn.Dropout(dropout) if dropout > 0 else nn.Identity()
|
| 837 |
+
self.norm2 = nn.LayerNorm(d_model)
|
| 838 |
+
|
| 839 |
+
# ffn
|
| 840 |
+
self.linear1 = nn.Linear(d_model, d_ffn)
|
| 841 |
+
self.activation = _get_activation_fn(activation, d_model=d_ffn, batch_dim=1)
|
| 842 |
+
self.dropout3 = nn.Dropout(dropout) if dropout > 0 else nn.Identity()
|
| 843 |
+
self.linear2 = nn.Linear(d_ffn, d_model)
|
| 844 |
+
self.dropout4 = nn.Dropout(dropout) if dropout > 0 else nn.Identity()
|
| 845 |
+
self.norm3 = nn.LayerNorm(d_model)
|
| 846 |
+
|
| 847 |
+
self.key_aware_proj = None
|
| 848 |
+
self.use_text_feat_guide = use_text_feat_guide
|
| 849 |
+
assert not use_text_feat_guide
|
| 850 |
+
self.use_text_cross_attention = use_text_cross_attention
|
| 851 |
+
|
| 852 |
+
def rm_self_attn_modules(self):
|
| 853 |
+
self.self_attn = None
|
| 854 |
+
self.dropout2 = None
|
| 855 |
+
self.norm2 = None
|
| 856 |
+
|
| 857 |
+
@staticmethod
|
| 858 |
+
def with_pos_embed(tensor, pos):
|
| 859 |
+
return tensor if pos is None else tensor + pos
|
| 860 |
+
|
| 861 |
+
def forward_ffn(self, tgt):
|
| 862 |
+
with torch.cuda.amp.autocast(enabled=False):
|
| 863 |
+
tgt2 = self.linear2(self.dropout3(self.activation(self.linear1(tgt))))
|
| 864 |
+
tgt = tgt + self.dropout4(tgt2)
|
| 865 |
+
tgt = self.norm3(tgt)
|
| 866 |
+
return tgt
|
| 867 |
+
|
| 868 |
+
def forward(
|
| 869 |
+
self,
|
| 870 |
+
# for tgt
|
| 871 |
+
tgt: Optional[Tensor], # nq, bs, d_model
|
| 872 |
+
tgt_query_pos: Optional[Tensor] = None, # pos for query. MLP(Sine(pos))
|
| 873 |
+
tgt_query_sine_embed: Optional[Tensor] = None, # pos for query. Sine(pos)
|
| 874 |
+
tgt_key_padding_mask: Optional[Tensor] = None,
|
| 875 |
+
tgt_reference_points: Optional[Tensor] = None, # nq, bs, 4
|
| 876 |
+
memory_text: Optional[Tensor] = None, # bs, num_token, d_model
|
| 877 |
+
text_attention_mask: Optional[Tensor] = None, # bs, num_token
|
| 878 |
+
# for memory
|
| 879 |
+
memory: Optional[Tensor] = None, # hw, bs, d_model
|
| 880 |
+
memory_key_padding_mask: Optional[Tensor] = None,
|
| 881 |
+
memory_level_start_index: Optional[Tensor] = None, # num_levels
|
| 882 |
+
memory_spatial_shapes: Optional[Tensor] = None, # bs, num_levels, 2
|
| 883 |
+
memory_pos: Optional[Tensor] = None, # pos for memory
|
| 884 |
+
# sa
|
| 885 |
+
self_attn_mask: Optional[Tensor] = None, # mask used for self-attention
|
| 886 |
+
cross_attn_mask: Optional[Tensor] = None, # mask used for cross-attention
|
| 887 |
+
):
|
| 888 |
+
"""
|
| 889 |
+
Input:
|
| 890 |
+
- tgt/tgt_query_pos: nq, bs, d_model
|
| 891 |
+
-
|
| 892 |
+
"""
|
| 893 |
+
assert cross_attn_mask is None
|
| 894 |
+
|
| 895 |
+
# self attention
|
| 896 |
+
if self.self_attn is not None:
|
| 897 |
+
# import ipdb; ipdb.set_trace()
|
| 898 |
+
q = k = self.with_pos_embed(tgt, tgt_query_pos)
|
| 899 |
+
tgt2 = self.self_attn(q, k, tgt, attn_mask=self_attn_mask)[0]
|
| 900 |
+
tgt = tgt + self.dropout2(tgt2)
|
| 901 |
+
tgt = self.norm2(tgt)
|
| 902 |
+
|
| 903 |
+
if self.use_text_cross_attention:
|
| 904 |
+
tgt2 = self.ca_text(
|
| 905 |
+
self.with_pos_embed(tgt, tgt_query_pos),
|
| 906 |
+
memory_text.transpose(0, 1),
|
| 907 |
+
memory_text.transpose(0, 1),
|
| 908 |
+
key_padding_mask=text_attention_mask,
|
| 909 |
+
)[0]
|
| 910 |
+
tgt = tgt + self.catext_dropout(tgt2)
|
| 911 |
+
tgt = self.catext_norm(tgt)
|
| 912 |
+
|
| 913 |
+
tgt2 = self.cross_attn(
|
| 914 |
+
query=self.with_pos_embed(tgt, tgt_query_pos).transpose(0, 1),
|
| 915 |
+
reference_points=tgt_reference_points.transpose(0, 1).contiguous(),
|
| 916 |
+
value=memory.transpose(0, 1),
|
| 917 |
+
spatial_shapes=memory_spatial_shapes,
|
| 918 |
+
level_start_index=memory_level_start_index,
|
| 919 |
+
key_padding_mask=memory_key_padding_mask,
|
| 920 |
+
).transpose(0, 1)
|
| 921 |
+
tgt = tgt + self.dropout1(tgt2)
|
| 922 |
+
tgt = self.norm1(tgt)
|
| 923 |
+
|
| 924 |
+
# ffn
|
| 925 |
+
tgt = self.forward_ffn(tgt)
|
| 926 |
+
|
| 927 |
+
return tgt
|
| 928 |
+
|
| 929 |
+
|
| 930 |
+
def build_transformer(args):
|
| 931 |
+
return Transformer(
|
| 932 |
+
d_model=args.hidden_dim,
|
| 933 |
+
dropout=args.dropout,
|
| 934 |
+
nhead=args.nheads,
|
| 935 |
+
num_queries=args.num_queries,
|
| 936 |
+
dim_feedforward=args.dim_feedforward,
|
| 937 |
+
num_encoder_layers=args.enc_layers,
|
| 938 |
+
num_decoder_layers=args.dec_layers,
|
| 939 |
+
normalize_before=args.pre_norm,
|
| 940 |
+
return_intermediate_dec=True,
|
| 941 |
+
query_dim=args.query_dim,
|
| 942 |
+
activation=args.transformer_activation,
|
| 943 |
+
num_patterns=args.num_patterns,
|
| 944 |
+
num_feature_levels=args.num_feature_levels,
|
| 945 |
+
enc_n_points=args.enc_n_points,
|
| 946 |
+
dec_n_points=args.dec_n_points,
|
| 947 |
+
learnable_tgt_init=True,
|
| 948 |
+
# two stage
|
| 949 |
+
two_stage_type=args.two_stage_type, # ['no', 'standard', 'early']
|
| 950 |
+
embed_init_tgt=args.embed_init_tgt,
|
| 951 |
+
use_text_enhancer=args.use_text_enhancer,
|
| 952 |
+
use_fusion_layer=args.use_fusion_layer,
|
| 953 |
+
use_checkpoint=args.use_checkpoint,
|
| 954 |
+
use_transformer_ckpt=args.use_transformer_ckpt,
|
| 955 |
+
use_text_cross_attention=args.use_text_cross_attention,
|
| 956 |
+
text_dropout=args.text_dropout,
|
| 957 |
+
fusion_dropout=args.fusion_dropout,
|
| 958 |
+
fusion_droppath=args.fusion_droppath,
|
| 959 |
+
)
|
One-to-All-Animation/benchmark/DisCo/annotator/grounded-sam/GroundingDINO/groundingdino/models/GroundingDINO/transformer_vanilla.py
ADDED
|
@@ -0,0 +1,123 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
# ------------------------------------------------------------------------
|
| 2 |
+
# Grounding DINO
|
| 3 |
+
# url: https://github.com/IDEA-Research/GroundingDINO
|
| 4 |
+
# Copyright (c) 2023 IDEA. All Rights Reserved.
|
| 5 |
+
# Licensed under the Apache License, Version 2.0 [see LICENSE for details]
|
| 6 |
+
# ------------------------------------------------------------------------
|
| 7 |
+
# Copyright (c) Aishwarya Kamath & Nicolas Carion. Licensed under the Apache License 2.0. All Rights Reserved
|
| 8 |
+
# Copyright (c) Facebook, Inc. and its affiliates. All Rights Reserved
|
| 9 |
+
"""
|
| 10 |
+
DETR Transformer class.
|
| 11 |
+
|
| 12 |
+
Copy-paste from torch.nn.Transformer with modifications:
|
| 13 |
+
* positional encodings are passed in MHattention
|
| 14 |
+
* extra LN at the end of encoder is removed
|
| 15 |
+
* decoder returns a stack of activations from all decoding layers
|
| 16 |
+
"""
|
| 17 |
+
from typing import Optional
|
| 18 |
+
|
| 19 |
+
import torch
|
| 20 |
+
import torch.nn.functional as F
|
| 21 |
+
from torch import Tensor, nn
|
| 22 |
+
|
| 23 |
+
from .utils import (
|
| 24 |
+
MLP,
|
| 25 |
+
_get_activation_fn,
|
| 26 |
+
_get_clones,
|
| 27 |
+
gen_encoder_output_proposals,
|
| 28 |
+
gen_sineembed_for_position,
|
| 29 |
+
sigmoid_focal_loss,
|
| 30 |
+
)
|
| 31 |
+
|
| 32 |
+
|
| 33 |
+
class TextTransformer(nn.Module):
|
| 34 |
+
def __init__(self, num_layers, d_model=256, nheads=8, dim_feedforward=2048, dropout=0.1):
|
| 35 |
+
super().__init__()
|
| 36 |
+
self.num_layers = num_layers
|
| 37 |
+
self.d_model = d_model
|
| 38 |
+
self.nheads = nheads
|
| 39 |
+
self.dim_feedforward = dim_feedforward
|
| 40 |
+
self.norm = None
|
| 41 |
+
|
| 42 |
+
single_encoder_layer = TransformerEncoderLayer(
|
| 43 |
+
d_model=d_model, nhead=nheads, dim_feedforward=dim_feedforward, dropout=dropout
|
| 44 |
+
)
|
| 45 |
+
self.layers = _get_clones(single_encoder_layer, num_layers)
|
| 46 |
+
|
| 47 |
+
def forward(self, memory_text: torch.Tensor, text_attention_mask: torch.Tensor):
|
| 48 |
+
"""
|
| 49 |
+
|
| 50 |
+
Args:
|
| 51 |
+
text_attention_mask: bs, num_token
|
| 52 |
+
memory_text: bs, num_token, d_model
|
| 53 |
+
|
| 54 |
+
Raises:
|
| 55 |
+
RuntimeError: _description_
|
| 56 |
+
|
| 57 |
+
Returns:
|
| 58 |
+
output: bs, num_token, d_model
|
| 59 |
+
"""
|
| 60 |
+
|
| 61 |
+
output = memory_text.transpose(0, 1)
|
| 62 |
+
|
| 63 |
+
for layer in self.layers:
|
| 64 |
+
output = layer(output, src_key_padding_mask=text_attention_mask)
|
| 65 |
+
|
| 66 |
+
if self.norm is not None:
|
| 67 |
+
output = self.norm(output)
|
| 68 |
+
|
| 69 |
+
return output.transpose(0, 1)
|
| 70 |
+
|
| 71 |
+
|
| 72 |
+
class TransformerEncoderLayer(nn.Module):
|
| 73 |
+
def __init__(
|
| 74 |
+
self,
|
| 75 |
+
d_model,
|
| 76 |
+
nhead,
|
| 77 |
+
dim_feedforward=2048,
|
| 78 |
+
dropout=0.1,
|
| 79 |
+
activation="relu",
|
| 80 |
+
normalize_before=False,
|
| 81 |
+
):
|
| 82 |
+
super().__init__()
|
| 83 |
+
self.self_attn = nn.MultiheadAttention(d_model, nhead, dropout=dropout)
|
| 84 |
+
# Implementation of Feedforward model
|
| 85 |
+
self.linear1 = nn.Linear(d_model, dim_feedforward)
|
| 86 |
+
self.dropout = nn.Dropout(dropout)
|
| 87 |
+
self.linear2 = nn.Linear(dim_feedforward, d_model)
|
| 88 |
+
|
| 89 |
+
self.norm1 = nn.LayerNorm(d_model)
|
| 90 |
+
self.norm2 = nn.LayerNorm(d_model)
|
| 91 |
+
self.dropout1 = nn.Dropout(dropout)
|
| 92 |
+
self.dropout2 = nn.Dropout(dropout)
|
| 93 |
+
|
| 94 |
+
self.activation = _get_activation_fn(activation)
|
| 95 |
+
self.normalize_before = normalize_before
|
| 96 |
+
self.nhead = nhead
|
| 97 |
+
|
| 98 |
+
def with_pos_embed(self, tensor, pos: Optional[Tensor]):
|
| 99 |
+
return tensor if pos is None else tensor + pos
|
| 100 |
+
|
| 101 |
+
def forward(
|
| 102 |
+
self,
|
| 103 |
+
src,
|
| 104 |
+
src_mask: Optional[Tensor] = None,
|
| 105 |
+
src_key_padding_mask: Optional[Tensor] = None,
|
| 106 |
+
pos: Optional[Tensor] = None,
|
| 107 |
+
):
|
| 108 |
+
# repeat attn mask
|
| 109 |
+
if src_mask.dim() == 3 and src_mask.shape[0] == src.shape[1]:
|
| 110 |
+
# bs, num_q, num_k
|
| 111 |
+
src_mask = src_mask.repeat(self.nhead, 1, 1)
|
| 112 |
+
|
| 113 |
+
q = k = self.with_pos_embed(src, pos)
|
| 114 |
+
|
| 115 |
+
src2 = self.self_attn(q, k, value=src, attn_mask=src_mask)[0]
|
| 116 |
+
|
| 117 |
+
# src2 = self.self_attn(q, k, value=src, attn_mask=src_mask, key_padding_mask=src_key_padding_mask)[0]
|
| 118 |
+
src = src + self.dropout1(src2)
|
| 119 |
+
src = self.norm1(src)
|
| 120 |
+
src2 = self.linear2(self.dropout(self.activation(self.linear1(src))))
|
| 121 |
+
src = src + self.dropout2(src2)
|
| 122 |
+
src = self.norm2(src)
|
| 123 |
+
return src
|
One-to-All-Animation/benchmark/DisCo/annotator/grounded-sam/GroundingDINO/groundingdino/models/GroundingDINO/utils.py
ADDED
|
@@ -0,0 +1,268 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
# ------------------------------------------------------------------------
|
| 2 |
+
# Grounding DINO
|
| 3 |
+
# url: https://github.com/IDEA-Research/GroundingDINO
|
| 4 |
+
# Copyright (c) 2023 IDEA. All Rights Reserved.
|
| 5 |
+
# Licensed under the Apache License, Version 2.0 [see LICENSE for details]
|
| 6 |
+
# ------------------------------------------------------------------------
|
| 7 |
+
|
| 8 |
+
import copy
|
| 9 |
+
import math
|
| 10 |
+
|
| 11 |
+
import torch
|
| 12 |
+
import torch.nn.functional as F
|
| 13 |
+
from torch import Tensor, nn
|
| 14 |
+
|
| 15 |
+
|
| 16 |
+
def _get_clones(module, N, layer_share=False):
|
| 17 |
+
# import ipdb; ipdb.set_trace()
|
| 18 |
+
if layer_share:
|
| 19 |
+
return nn.ModuleList([module for i in range(N)])
|
| 20 |
+
else:
|
| 21 |
+
return nn.ModuleList([copy.deepcopy(module) for i in range(N)])
|
| 22 |
+
|
| 23 |
+
|
| 24 |
+
def get_sine_pos_embed(
|
| 25 |
+
pos_tensor: torch.Tensor,
|
| 26 |
+
num_pos_feats: int = 128,
|
| 27 |
+
temperature: int = 10000,
|
| 28 |
+
exchange_xy: bool = True,
|
| 29 |
+
):
|
| 30 |
+
"""generate sine position embedding from a position tensor
|
| 31 |
+
Args:
|
| 32 |
+
pos_tensor (torch.Tensor): shape: [..., n].
|
| 33 |
+
num_pos_feats (int): projected shape for each float in the tensor.
|
| 34 |
+
temperature (int): temperature in the sine/cosine function.
|
| 35 |
+
exchange_xy (bool, optional): exchange pos x and pos y. \
|
| 36 |
+
For example, input tensor is [x,y], the results will be [pos(y), pos(x)]. Defaults to True.
|
| 37 |
+
Returns:
|
| 38 |
+
pos_embed (torch.Tensor): shape: [..., n*num_pos_feats].
|
| 39 |
+
"""
|
| 40 |
+
scale = 2 * math.pi
|
| 41 |
+
dim_t = torch.arange(num_pos_feats, dtype=torch.float32, device=pos_tensor.device)
|
| 42 |
+
dim_t = temperature ** (2 * torch.div(dim_t, 2, rounding_mode="floor") / num_pos_feats)
|
| 43 |
+
|
| 44 |
+
def sine_func(x: torch.Tensor):
|
| 45 |
+
sin_x = x * scale / dim_t
|
| 46 |
+
sin_x = torch.stack((sin_x[..., 0::2].sin(), sin_x[..., 1::2].cos()), dim=3).flatten(2)
|
| 47 |
+
return sin_x
|
| 48 |
+
|
| 49 |
+
pos_res = [sine_func(x) for x in pos_tensor.split([1] * pos_tensor.shape[-1], dim=-1)]
|
| 50 |
+
if exchange_xy:
|
| 51 |
+
pos_res[0], pos_res[1] = pos_res[1], pos_res[0]
|
| 52 |
+
pos_res = torch.cat(pos_res, dim=-1)
|
| 53 |
+
return pos_res
|
| 54 |
+
|
| 55 |
+
|
| 56 |
+
def gen_encoder_output_proposals(
|
| 57 |
+
memory: Tensor, memory_padding_mask: Tensor, spatial_shapes: Tensor, learnedwh=None
|
| 58 |
+
):
|
| 59 |
+
"""
|
| 60 |
+
Input:
|
| 61 |
+
- memory: bs, \sum{hw}, d_model
|
| 62 |
+
- memory_padding_mask: bs, \sum{hw}
|
| 63 |
+
- spatial_shapes: nlevel, 2
|
| 64 |
+
- learnedwh: 2
|
| 65 |
+
Output:
|
| 66 |
+
- output_memory: bs, \sum{hw}, d_model
|
| 67 |
+
- output_proposals: bs, \sum{hw}, 4
|
| 68 |
+
"""
|
| 69 |
+
N_, S_, C_ = memory.shape
|
| 70 |
+
proposals = []
|
| 71 |
+
_cur = 0
|
| 72 |
+
for lvl, (H_, W_) in enumerate(spatial_shapes):
|
| 73 |
+
mask_flatten_ = memory_padding_mask[:, _cur : (_cur + H_ * W_)].view(N_, H_, W_, 1)
|
| 74 |
+
valid_H = torch.sum(~mask_flatten_[:, :, 0, 0], 1)
|
| 75 |
+
valid_W = torch.sum(~mask_flatten_[:, 0, :, 0], 1)
|
| 76 |
+
|
| 77 |
+
# import ipdb; ipdb.set_trace()
|
| 78 |
+
|
| 79 |
+
grid_y, grid_x = torch.meshgrid(
|
| 80 |
+
torch.linspace(0, H_ - 1, H_, dtype=torch.float32, device=memory.device),
|
| 81 |
+
torch.linspace(0, W_ - 1, W_, dtype=torch.float32, device=memory.device),
|
| 82 |
+
)
|
| 83 |
+
grid = torch.cat([grid_x.unsqueeze(-1), grid_y.unsqueeze(-1)], -1) # H_, W_, 2
|
| 84 |
+
|
| 85 |
+
scale = torch.cat([valid_W.unsqueeze(-1), valid_H.unsqueeze(-1)], 1).view(N_, 1, 1, 2)
|
| 86 |
+
grid = (grid.unsqueeze(0).expand(N_, -1, -1, -1) + 0.5) / scale
|
| 87 |
+
|
| 88 |
+
if learnedwh is not None:
|
| 89 |
+
# import ipdb; ipdb.set_trace()
|
| 90 |
+
wh = torch.ones_like(grid) * learnedwh.sigmoid() * (2.0**lvl)
|
| 91 |
+
else:
|
| 92 |
+
wh = torch.ones_like(grid) * 0.05 * (2.0**lvl)
|
| 93 |
+
|
| 94 |
+
# scale = torch.cat([W_[None].unsqueeze(-1), H_[None].unsqueeze(-1)], 1).view(1, 1, 1, 2).repeat(N_, 1, 1, 1)
|
| 95 |
+
# grid = (grid.unsqueeze(0).expand(N_, -1, -1, -1) + 0.5) / scale
|
| 96 |
+
# wh = torch.ones_like(grid) / scale
|
| 97 |
+
proposal = torch.cat((grid, wh), -1).view(N_, -1, 4)
|
| 98 |
+
proposals.append(proposal)
|
| 99 |
+
_cur += H_ * W_
|
| 100 |
+
# import ipdb; ipdb.set_trace()
|
| 101 |
+
output_proposals = torch.cat(proposals, 1)
|
| 102 |
+
output_proposals_valid = ((output_proposals > 0.01) & (output_proposals < 0.99)).all(
|
| 103 |
+
-1, keepdim=True
|
| 104 |
+
)
|
| 105 |
+
output_proposals = torch.log(output_proposals / (1 - output_proposals)) # unsigmoid
|
| 106 |
+
output_proposals = output_proposals.masked_fill(memory_padding_mask.unsqueeze(-1), float("inf"))
|
| 107 |
+
output_proposals = output_proposals.masked_fill(~output_proposals_valid, float("inf"))
|
| 108 |
+
|
| 109 |
+
output_memory = memory
|
| 110 |
+
output_memory = output_memory.masked_fill(memory_padding_mask.unsqueeze(-1), float(0))
|
| 111 |
+
output_memory = output_memory.masked_fill(~output_proposals_valid, float(0))
|
| 112 |
+
|
| 113 |
+
# output_memory = output_memory.masked_fill(memory_padding_mask.unsqueeze(-1), float('inf'))
|
| 114 |
+
# output_memory = output_memory.masked_fill(~output_proposals_valid, float('inf'))
|
| 115 |
+
|
| 116 |
+
return output_memory, output_proposals
|
| 117 |
+
|
| 118 |
+
|
| 119 |
+
class RandomBoxPerturber:
|
| 120 |
+
def __init__(
|
| 121 |
+
self, x_noise_scale=0.2, y_noise_scale=0.2, w_noise_scale=0.2, h_noise_scale=0.2
|
| 122 |
+
) -> None:
|
| 123 |
+
self.noise_scale = torch.Tensor(
|
| 124 |
+
[x_noise_scale, y_noise_scale, w_noise_scale, h_noise_scale]
|
| 125 |
+
)
|
| 126 |
+
|
| 127 |
+
def __call__(self, refanchors: Tensor) -> Tensor:
|
| 128 |
+
nq, bs, query_dim = refanchors.shape
|
| 129 |
+
device = refanchors.device
|
| 130 |
+
|
| 131 |
+
noise_raw = torch.rand_like(refanchors)
|
| 132 |
+
noise_scale = self.noise_scale.to(device)[:query_dim]
|
| 133 |
+
|
| 134 |
+
new_refanchors = refanchors * (1 + (noise_raw - 0.5) * noise_scale)
|
| 135 |
+
return new_refanchors.clamp_(0, 1)
|
| 136 |
+
|
| 137 |
+
|
| 138 |
+
def sigmoid_focal_loss(
|
| 139 |
+
inputs, targets, num_boxes, alpha: float = 0.25, gamma: float = 2, no_reduction=False
|
| 140 |
+
):
|
| 141 |
+
"""
|
| 142 |
+
Loss used in RetinaNet for dense detection: https://arxiv.org/abs/1708.02002.
|
| 143 |
+
Args:
|
| 144 |
+
inputs: A float tensor of arbitrary shape.
|
| 145 |
+
The predictions for each example.
|
| 146 |
+
targets: A float tensor with the same shape as inputs. Stores the binary
|
| 147 |
+
classification label for each element in inputs
|
| 148 |
+
(0 for the negative class and 1 for the positive class).
|
| 149 |
+
alpha: (optional) Weighting factor in range (0,1) to balance
|
| 150 |
+
positive vs negative examples. Default = -1 (no weighting).
|
| 151 |
+
gamma: Exponent of the modulating factor (1 - p_t) to
|
| 152 |
+
balance easy vs hard examples.
|
| 153 |
+
Returns:
|
| 154 |
+
Loss tensor
|
| 155 |
+
"""
|
| 156 |
+
prob = inputs.sigmoid()
|
| 157 |
+
ce_loss = F.binary_cross_entropy_with_logits(inputs, targets, reduction="none")
|
| 158 |
+
p_t = prob * targets + (1 - prob) * (1 - targets)
|
| 159 |
+
loss = ce_loss * ((1 - p_t) ** gamma)
|
| 160 |
+
|
| 161 |
+
if alpha >= 0:
|
| 162 |
+
alpha_t = alpha * targets + (1 - alpha) * (1 - targets)
|
| 163 |
+
loss = alpha_t * loss
|
| 164 |
+
|
| 165 |
+
if no_reduction:
|
| 166 |
+
return loss
|
| 167 |
+
|
| 168 |
+
return loss.mean(1).sum() / num_boxes
|
| 169 |
+
|
| 170 |
+
|
| 171 |
+
class MLP(nn.Module):
|
| 172 |
+
"""Very simple multi-layer perceptron (also called FFN)"""
|
| 173 |
+
|
| 174 |
+
def __init__(self, input_dim, hidden_dim, output_dim, num_layers):
|
| 175 |
+
super().__init__()
|
| 176 |
+
self.num_layers = num_layers
|
| 177 |
+
h = [hidden_dim] * (num_layers - 1)
|
| 178 |
+
self.layers = nn.ModuleList(
|
| 179 |
+
nn.Linear(n, k) for n, k in zip([input_dim] + h, h + [output_dim])
|
| 180 |
+
)
|
| 181 |
+
|
| 182 |
+
def forward(self, x):
|
| 183 |
+
for i, layer in enumerate(self.layers):
|
| 184 |
+
x = F.relu(layer(x)) if i < self.num_layers - 1 else layer(x)
|
| 185 |
+
return x
|
| 186 |
+
|
| 187 |
+
|
| 188 |
+
def _get_activation_fn(activation, d_model=256, batch_dim=0):
|
| 189 |
+
"""Return an activation function given a string"""
|
| 190 |
+
if activation == "relu":
|
| 191 |
+
return F.relu
|
| 192 |
+
if activation == "gelu":
|
| 193 |
+
return F.gelu
|
| 194 |
+
if activation == "glu":
|
| 195 |
+
return F.glu
|
| 196 |
+
if activation == "prelu":
|
| 197 |
+
return nn.PReLU()
|
| 198 |
+
if activation == "selu":
|
| 199 |
+
return F.selu
|
| 200 |
+
|
| 201 |
+
raise RuntimeError(f"activation should be relu/gelu, not {activation}.")
|
| 202 |
+
|
| 203 |
+
|
| 204 |
+
def gen_sineembed_for_position(pos_tensor):
|
| 205 |
+
# n_query, bs, _ = pos_tensor.size()
|
| 206 |
+
# sineembed_tensor = torch.zeros(n_query, bs, 256)
|
| 207 |
+
scale = 2 * math.pi
|
| 208 |
+
dim_t = torch.arange(128, dtype=torch.float32, device=pos_tensor.device)
|
| 209 |
+
dim_t = 10000 ** (2 * (torch.div(dim_t, 2, rounding_mode='floor')) / 128)
|
| 210 |
+
x_embed = pos_tensor[:, :, 0] * scale
|
| 211 |
+
y_embed = pos_tensor[:, :, 1] * scale
|
| 212 |
+
pos_x = x_embed[:, :, None] / dim_t
|
| 213 |
+
pos_y = y_embed[:, :, None] / dim_t
|
| 214 |
+
pos_x = torch.stack((pos_x[:, :, 0::2].sin(), pos_x[:, :, 1::2].cos()), dim=3).flatten(2)
|
| 215 |
+
pos_y = torch.stack((pos_y[:, :, 0::2].sin(), pos_y[:, :, 1::2].cos()), dim=3).flatten(2)
|
| 216 |
+
if pos_tensor.size(-1) == 2:
|
| 217 |
+
pos = torch.cat((pos_y, pos_x), dim=2)
|
| 218 |
+
elif pos_tensor.size(-1) == 4:
|
| 219 |
+
w_embed = pos_tensor[:, :, 2] * scale
|
| 220 |
+
pos_w = w_embed[:, :, None] / dim_t
|
| 221 |
+
pos_w = torch.stack((pos_w[:, :, 0::2].sin(), pos_w[:, :, 1::2].cos()), dim=3).flatten(2)
|
| 222 |
+
|
| 223 |
+
h_embed = pos_tensor[:, :, 3] * scale
|
| 224 |
+
pos_h = h_embed[:, :, None] / dim_t
|
| 225 |
+
pos_h = torch.stack((pos_h[:, :, 0::2].sin(), pos_h[:, :, 1::2].cos()), dim=3).flatten(2)
|
| 226 |
+
|
| 227 |
+
pos = torch.cat((pos_y, pos_x, pos_w, pos_h), dim=2)
|
| 228 |
+
else:
|
| 229 |
+
raise ValueError("Unknown pos_tensor shape(-1):{}".format(pos_tensor.size(-1)))
|
| 230 |
+
return pos
|
| 231 |
+
|
| 232 |
+
|
| 233 |
+
class ContrastiveEmbed(nn.Module):
|
| 234 |
+
def __init__(self, max_text_len=256):
|
| 235 |
+
"""
|
| 236 |
+
Args:
|
| 237 |
+
max_text_len: max length of text.
|
| 238 |
+
"""
|
| 239 |
+
super().__init__()
|
| 240 |
+
self.max_text_len = max_text_len
|
| 241 |
+
|
| 242 |
+
def forward(self, x, text_dict):
|
| 243 |
+
"""_summary_
|
| 244 |
+
|
| 245 |
+
Args:
|
| 246 |
+
x (_type_): _description_
|
| 247 |
+
text_dict (_type_): _description_
|
| 248 |
+
{
|
| 249 |
+
'encoded_text': encoded_text, # bs, 195, d_model
|
| 250 |
+
'text_token_mask': text_token_mask, # bs, 195
|
| 251 |
+
# True for used tokens. False for padding tokens
|
| 252 |
+
}
|
| 253 |
+
Returns:
|
| 254 |
+
_type_: _description_
|
| 255 |
+
"""
|
| 256 |
+
assert isinstance(text_dict, dict)
|
| 257 |
+
|
| 258 |
+
y = text_dict["encoded_text"]
|
| 259 |
+
text_token_mask = text_dict["text_token_mask"]
|
| 260 |
+
|
| 261 |
+
res = x @ y.transpose(-1, -2)
|
| 262 |
+
res.masked_fill_(~text_token_mask[:, None, :], float("-inf"))
|
| 263 |
+
|
| 264 |
+
# padding to max_text_len
|
| 265 |
+
new_res = torch.full((*res.shape[:-1], self.max_text_len), float("-inf"), device=res.device)
|
| 266 |
+
new_res[..., : res.shape[-1]] = res
|
| 267 |
+
|
| 268 |
+
return new_res
|
One-to-All-Animation/benchmark/DisCo/annotator/grounded-sam/GroundingDINO/groundingdino/models/__init__.py
ADDED
|
@@ -0,0 +1,18 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
# ------------------------------------------------------------------------
|
| 2 |
+
# Grounding DINO
|
| 3 |
+
# url: https://github.com/IDEA-Research/GroundingDINO
|
| 4 |
+
# Copyright (c) 2023 IDEA. All Rights Reserved.
|
| 5 |
+
# Licensed under the Apache License, Version 2.0 [see LICENSE for details]
|
| 6 |
+
# ------------------------------------------------------------------------
|
| 7 |
+
# Copyright (c) Facebook, Inc. and its affiliates. All Rights Reserved
|
| 8 |
+
from .GroundingDINO import build_groundingdino
|
| 9 |
+
|
| 10 |
+
|
| 11 |
+
def build_model(args):
|
| 12 |
+
# we use register to maintain models from catdet6 on.
|
| 13 |
+
from .registry import MODULE_BUILD_FUNCS
|
| 14 |
+
|
| 15 |
+
assert args.modelname in MODULE_BUILD_FUNCS._module_dict
|
| 16 |
+
build_func = MODULE_BUILD_FUNCS.get(args.modelname)
|
| 17 |
+
model = build_func(args)
|
| 18 |
+
return model
|
One-to-All-Animation/benchmark/DisCo/annotator/grounded-sam/GroundingDINO/groundingdino/models/registry.py
ADDED
|
@@ -0,0 +1,66 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
# ------------------------------------------------------------------------
|
| 2 |
+
# Grounding DINO
|
| 3 |
+
# url: https://github.com/IDEA-Research/GroundingDINO
|
| 4 |
+
# Copyright (c) 2023 IDEA. All Rights Reserved.
|
| 5 |
+
# Licensed under the Apache License, Version 2.0 [see LICENSE for details]
|
| 6 |
+
# ------------------------------------------------------------------------
|
| 7 |
+
# -*- coding: utf-8 -*-
|
| 8 |
+
# @Author: Yihao Chen
|
| 9 |
+
# @Date: 2021-08-16 16:03:17
|
| 10 |
+
# @Last Modified by: Shilong Liu
|
| 11 |
+
# @Last Modified time: 2022-01-23 15:26
|
| 12 |
+
# modified from mmcv
|
| 13 |
+
|
| 14 |
+
import inspect
|
| 15 |
+
from functools import partial
|
| 16 |
+
|
| 17 |
+
|
| 18 |
+
class Registry(object):
|
| 19 |
+
def __init__(self, name):
|
| 20 |
+
self._name = name
|
| 21 |
+
self._module_dict = dict()
|
| 22 |
+
|
| 23 |
+
def __repr__(self):
|
| 24 |
+
format_str = self.__class__.__name__ + "(name={}, items={})".format(
|
| 25 |
+
self._name, list(self._module_dict.keys())
|
| 26 |
+
)
|
| 27 |
+
return format_str
|
| 28 |
+
|
| 29 |
+
def __len__(self):
|
| 30 |
+
return len(self._module_dict)
|
| 31 |
+
|
| 32 |
+
@property
|
| 33 |
+
def name(self):
|
| 34 |
+
return self._name
|
| 35 |
+
|
| 36 |
+
@property
|
| 37 |
+
def module_dict(self):
|
| 38 |
+
return self._module_dict
|
| 39 |
+
|
| 40 |
+
def get(self, key):
|
| 41 |
+
return self._module_dict.get(key, None)
|
| 42 |
+
|
| 43 |
+
def registe_with_name(self, module_name=None, force=False):
|
| 44 |
+
return partial(self.register, module_name=module_name, force=force)
|
| 45 |
+
|
| 46 |
+
def register(self, module_build_function, module_name=None, force=False):
|
| 47 |
+
"""Register a module build function.
|
| 48 |
+
Args:
|
| 49 |
+
module (:obj:`nn.Module`): Module to be registered.
|
| 50 |
+
"""
|
| 51 |
+
if not inspect.isfunction(module_build_function):
|
| 52 |
+
raise TypeError(
|
| 53 |
+
"module_build_function must be a function, but got {}".format(
|
| 54 |
+
type(module_build_function)
|
| 55 |
+
)
|
| 56 |
+
)
|
| 57 |
+
if module_name is None:
|
| 58 |
+
module_name = module_build_function.__name__
|
| 59 |
+
if not force and module_name in self._module_dict:
|
| 60 |
+
raise KeyError("{} is already registered in {}".format(module_name, self.name))
|
| 61 |
+
self._module_dict[module_name] = module_build_function
|
| 62 |
+
|
| 63 |
+
return module_build_function
|
| 64 |
+
|
| 65 |
+
|
| 66 |
+
MODULE_BUILD_FUNCS = Registry("model build functions")
|
One-to-All-Animation/benchmark/DisCo/annotator/grounded-sam/GroundingDINO/groundingdino/util/__init__.py
ADDED
|
@@ -0,0 +1 @@
|
|
|
|
|
|
|
| 1 |
+
# Copyright (c) Facebook, Inc. and its affiliates. All Rights Reserved
|