
Datasets:

pingjiewang commited on
Commit ·
34fa27c
1
Parent(s): f778e48
Update dataset card; add Parquet previews, license and citation
Browse files- CITATION.cff +43 -0
- LICENSE +21 -0
- README.md +196 -19
- previews/axes.parquet +3 -0
- previews/d_axis_1m.parquet +3 -0
- previews/m_axis_1m.parquet +3 -0
- previews/step_axis_1m.parquet +3 -0
- previews/synthetic_mano_uniform_validation_10k.parquet +3 -0
CITATION.cff
ADDED
|
@@ -0,0 +1,43 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
cff-version: 1.2.0
|
| 2 |
+
message: "If you use these loss matrices, please cite the accompanying paper."
|
| 3 |
+
title: "Token Learning Spectrum: Token-Level Loss Trajectories Along Scaling Axes"
|
| 4 |
+
type: dataset
|
| 5 |
+
abstract: "Per-token validation-loss trajectories for one million contextualized tokens along the training-step, data-scale, and model-scale axes of LLM pre-training, plus a synthetic arithmetic example."
|
| 6 |
+
keywords:
|
| 7 |
+
- scaling laws
|
| 8 |
+
- learning-time spectrum
|
| 9 |
+
- token loss
|
| 10 |
+
- learning dynamics
|
| 11 |
+
authors:
|
| 12 |
+
- family-names: Wang
|
| 13 |
+
given-names: Pingjie
|
| 14 |
+
- family-names: Hu
|
| 15 |
+
given-names: Zechen
|
| 16 |
+
- family-names: Yang
|
| 17 |
+
given-names: Peiru
|
| 18 |
+
- family-names: Guo
|
| 19 |
+
given-names: Fu
|
| 20 |
+
- family-names: Zhang
|
| 21 |
+
given-names: Debing
|
| 22 |
+
license: MIT
|
| 23 |
+
url: "https://huggingface.co/datasets/applewpj/token-learning-spectrum-examples"
|
| 24 |
+
repository-code: "https://github.com/applewpj/stepwise-token-learning"
|
| 25 |
+
preferred-citation:
|
| 26 |
+
type: conference-paper
|
| 27 |
+
title: "Smooth Scaling Laws Hide Stepwise Token Learning"
|
| 28 |
+
url: "https://openreview.net/forum?id=THZDVZArRH"
|
| 29 |
+
authors:
|
| 30 |
+
- family-names: Wang
|
| 31 |
+
given-names: Pingjie
|
| 32 |
+
- family-names: Hu
|
| 33 |
+
given-names: Zechen
|
| 34 |
+
- family-names: Yang
|
| 35 |
+
given-names: Peiru
|
| 36 |
+
- family-names: Guo
|
| 37 |
+
given-names: Fu
|
| 38 |
+
- family-names: Zhang
|
| 39 |
+
given-names: Debing
|
| 40 |
+
collection-title: "Advances in Neural Information Processing Systems"
|
| 41 |
+
conference:
|
| 42 |
+
name: "NeurIPS 2026"
|
| 43 |
+
year: 2026
|
LICENSE
ADDED
|
@@ -0,0 +1,21 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
MIT License
|
| 2 |
+
|
| 3 |
+
Copyright (c) 2026 Token Learning Spectrum Authors
|
| 4 |
+
|
| 5 |
+
Permission is hereby granted, free of charge, to any person obtaining a copy
|
| 6 |
+
of this dataset and associated documentation files (the "Dataset"), to deal
|
| 7 |
+
in the Dataset without restriction, including without limitation the rights
|
| 8 |
+
to use, copy, modify, merge, publish, distribute, sublicense, and/or sell
|
| 9 |
+
copies of the Dataset, and to permit persons to whom the Dataset is furnished
|
| 10 |
+
to do so, subject to the following conditions:
|
| 11 |
+
|
| 12 |
+
The above copyright notice and this permission notice shall be included in all
|
| 13 |
+
copies or substantial portions of the Dataset.
|
| 14 |
+
|
| 15 |
+
THE DATASET IS PROVIDED "AS IS", WITHOUT WARRANTY OF ANY KIND, EXPRESS OR
|
| 16 |
+
IMPLIED, INCLUDING BUT NOT LIMITED TO THE WARRANTIES OF MERCHANTABILITY,
|
| 17 |
+
FITNESS FOR A PARTICULAR PURPOSE AND NONINFRINGEMENT. IN NO EVENT SHALL THE
|
| 18 |
+
AUTHORS OR COPYRIGHT HOLDERS BE LIABLE FOR ANY CLAIM, DAMAGES OR OTHER
|
| 19 |
+
LIABILITY, WHETHER IN AN ACTION OF CONTRACT, TORT OR OTHERWISE, ARISING FROM,
|
| 20 |
+
OUT OF OR IN CONNECTION WITH THE DATASET OR THE USE OR OTHER DEALINGS IN THE
|
| 21 |
+
DATASET.
|
README.md
CHANGED
|
@@ -1,37 +1,214 @@
|
|
| 1 |
---
|
| 2 |
license: mit
|
| 3 |
-
pretty_name: Token Learning Spectrum
|
|
|
|
|
|
|
| 4 |
tags:
|
| 5 |
- scaling-laws
|
| 6 |
-
-
|
|
|
|
| 7 |
- token-loss
|
|
|
|
|
|
|
| 8 |
- interpretability
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 9 |
---
|
| 10 |
|
| 11 |
-
|
|
|
|
|
|
|
| 12 |
|
| 13 |
-
|
| 14 |
-
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 15 |
|
| 16 |
-
|
| 17 |
|
| 18 |
-
|
| 19 |
-
|
| 20 |
-
|
| 21 |
-
|
| 22 |
-
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 23 |
```
|
| 24 |
|
| 25 |
-
|
| 26 |
-
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 27 |
|
| 28 |
```bash
|
| 29 |
-
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 30 |
```
|
| 31 |
|
| 32 |
-
|
| 33 |
-
include private model architectures, weights, tokenizers, raw validation text,
|
| 34 |
-
training data composition, experiment registries, or checkpoint paths.
|
| 35 |
|
| 36 |
-
The
|
| 37 |
-
|
|
|
|
|
|
| 1 |
---
|
| 2 |
license: mit
|
| 3 |
+
pretty_name: "Token Learning Spectrum: Token-Level Loss Trajectories Along Scaling Axes"
|
| 4 |
+
task_categories:
|
| 5 |
+
- text-generation
|
| 6 |
tags:
|
| 7 |
- scaling-laws
|
| 8 |
+
- learning-dynamics
|
| 9 |
+
- training-dynamics
|
| 10 |
- token-loss
|
| 11 |
+
- loss-curves
|
| 12 |
+
- language-modeling
|
| 13 |
- interpretability
|
| 14 |
+
- neurips-2026
|
| 15 |
+
size_categories:
|
| 16 |
+
- 1M<n<10M
|
| 17 |
+
configs:
|
| 18 |
+
- config_name: step_axis_1m
|
| 19 |
+
default: true
|
| 20 |
+
data_files:
|
| 21 |
+
- split: preview
|
| 22 |
+
path: previews/step_axis_1m.parquet
|
| 23 |
+
- config_name: d_axis_1m
|
| 24 |
+
data_files:
|
| 25 |
+
- split: preview
|
| 26 |
+
path: previews/d_axis_1m.parquet
|
| 27 |
+
- config_name: m_axis_1m
|
| 28 |
+
data_files:
|
| 29 |
+
- split: preview
|
| 30 |
+
path: previews/m_axis_1m.parquet
|
| 31 |
+
- config_name: synthetic_mano_uniform_validation_10k
|
| 32 |
+
data_files:
|
| 33 |
+
- split: full
|
| 34 |
+
path: previews/synthetic_mano_uniform_validation_10k.parquet
|
| 35 |
+
- config_name: axes
|
| 36 |
+
data_files:
|
| 37 |
+
- split: full
|
| 38 |
+
path: previews/axes.parquet
|
| 39 |
---
|
| 40 |
|
| 41 |
+
<p align="center">
|
| 42 |
+
<a href="https://applewpj.github.io/stepwise-token-learning/"><img src="https://raw.githubusercontent.com/applewpj/stepwise-token-learning/main/assets/readme/banner.png" width="100%" alt="Smooth Scaling Laws Hide Stepwise Token Learning, NeurIPS 2026 Spotlight. Each token's loss falls in one sigmoid-shaped step, and their average is the smooth loss curve."></a>
|
| 43 |
+
</p>
|
| 44 |
|
| 45 |
+
<p align="center">
|
| 46 |
+
<a href="https://applewpj.github.io/stepwise-token-learning/"><img src="https://raw.githubusercontent.com/applewpj/stepwise-token-learning/main/assets/readme/btn-page.svg" alt="Interactive project page"></a>
|
| 47 |
+
<a href="https://openreview.net/forum?id=THZDVZArRH"><img src="https://raw.githubusercontent.com/applewpj/stepwise-token-learning/main/assets/readme/btn-paper.svg" alt="Paper on OpenReview"></a>
|
| 48 |
+
<a href="https://github.com/applewpj/stepwise-token-learning"><img src="https://raw.githubusercontent.com/applewpj/stepwise-token-learning/main/assets/readme/btn-code.svg" alt="Code on GitHub"></a>
|
| 49 |
+
<a href="https://colab.research.google.com/github/applewpj/stepwise-token-learning/blob/main/notebooks/quickstart.ipynb"><img src="https://raw.githubusercontent.com/applewpj/stepwise-token-learning/main/assets/readme/btn-colab.svg" alt="Quickstart in Colab"></a>
|
| 50 |
+
<a href="#citation"><img src="https://raw.githubusercontent.com/applewpj/stepwise-token-learning/main/assets/readme/btn-bibtex.svg" alt="BibTeX"></a>
|
| 51 |
+
</p>
|
| 52 |
|
| 53 |
+
# Token Learning Spectrum: Token-Level Loss Trajectories
|
| 54 |
|
| 55 |
+
Per-token validation-loss trajectories for **one million contextualized tokens**
|
| 56 |
+
along each of three scaling axes of LLM pre-training (training steps *T*, data
|
| 57 |
+
scale *D*, model scale *M*), plus a synthetic arithmetic example. They are the
|
| 58 |
+
inputs to the analysis in
|
| 59 |
+
**[Smooth Scaling Laws Hide Stepwise Token Learning](https://openreview.net/forum?id=THZDVZArRH)**
|
| 60 |
+
(NeurIPS 2026, Spotlight).
|
| 61 |
+
|
| 62 |
+
> **See these trajectories move.** The
|
| 63 |
+
> [interactive project page](https://applewpj.github.io/stepwise-token-learning/)
|
| 64 |
+
> plots tokens from these matrices, shows how they add up to the loss curve,
|
| 65 |
+
> and lets you play with the mechanism. The
|
| 66 |
+
> [code on GitHub](https://github.com/applewpj/stepwise-token-learning)
|
| 67 |
+
> downloads these files and reproduces every figure with one command.
|
| 68 |
+
|
| 69 |
+
## What the Matrices Show
|
| 70 |
+
|
| 71 |
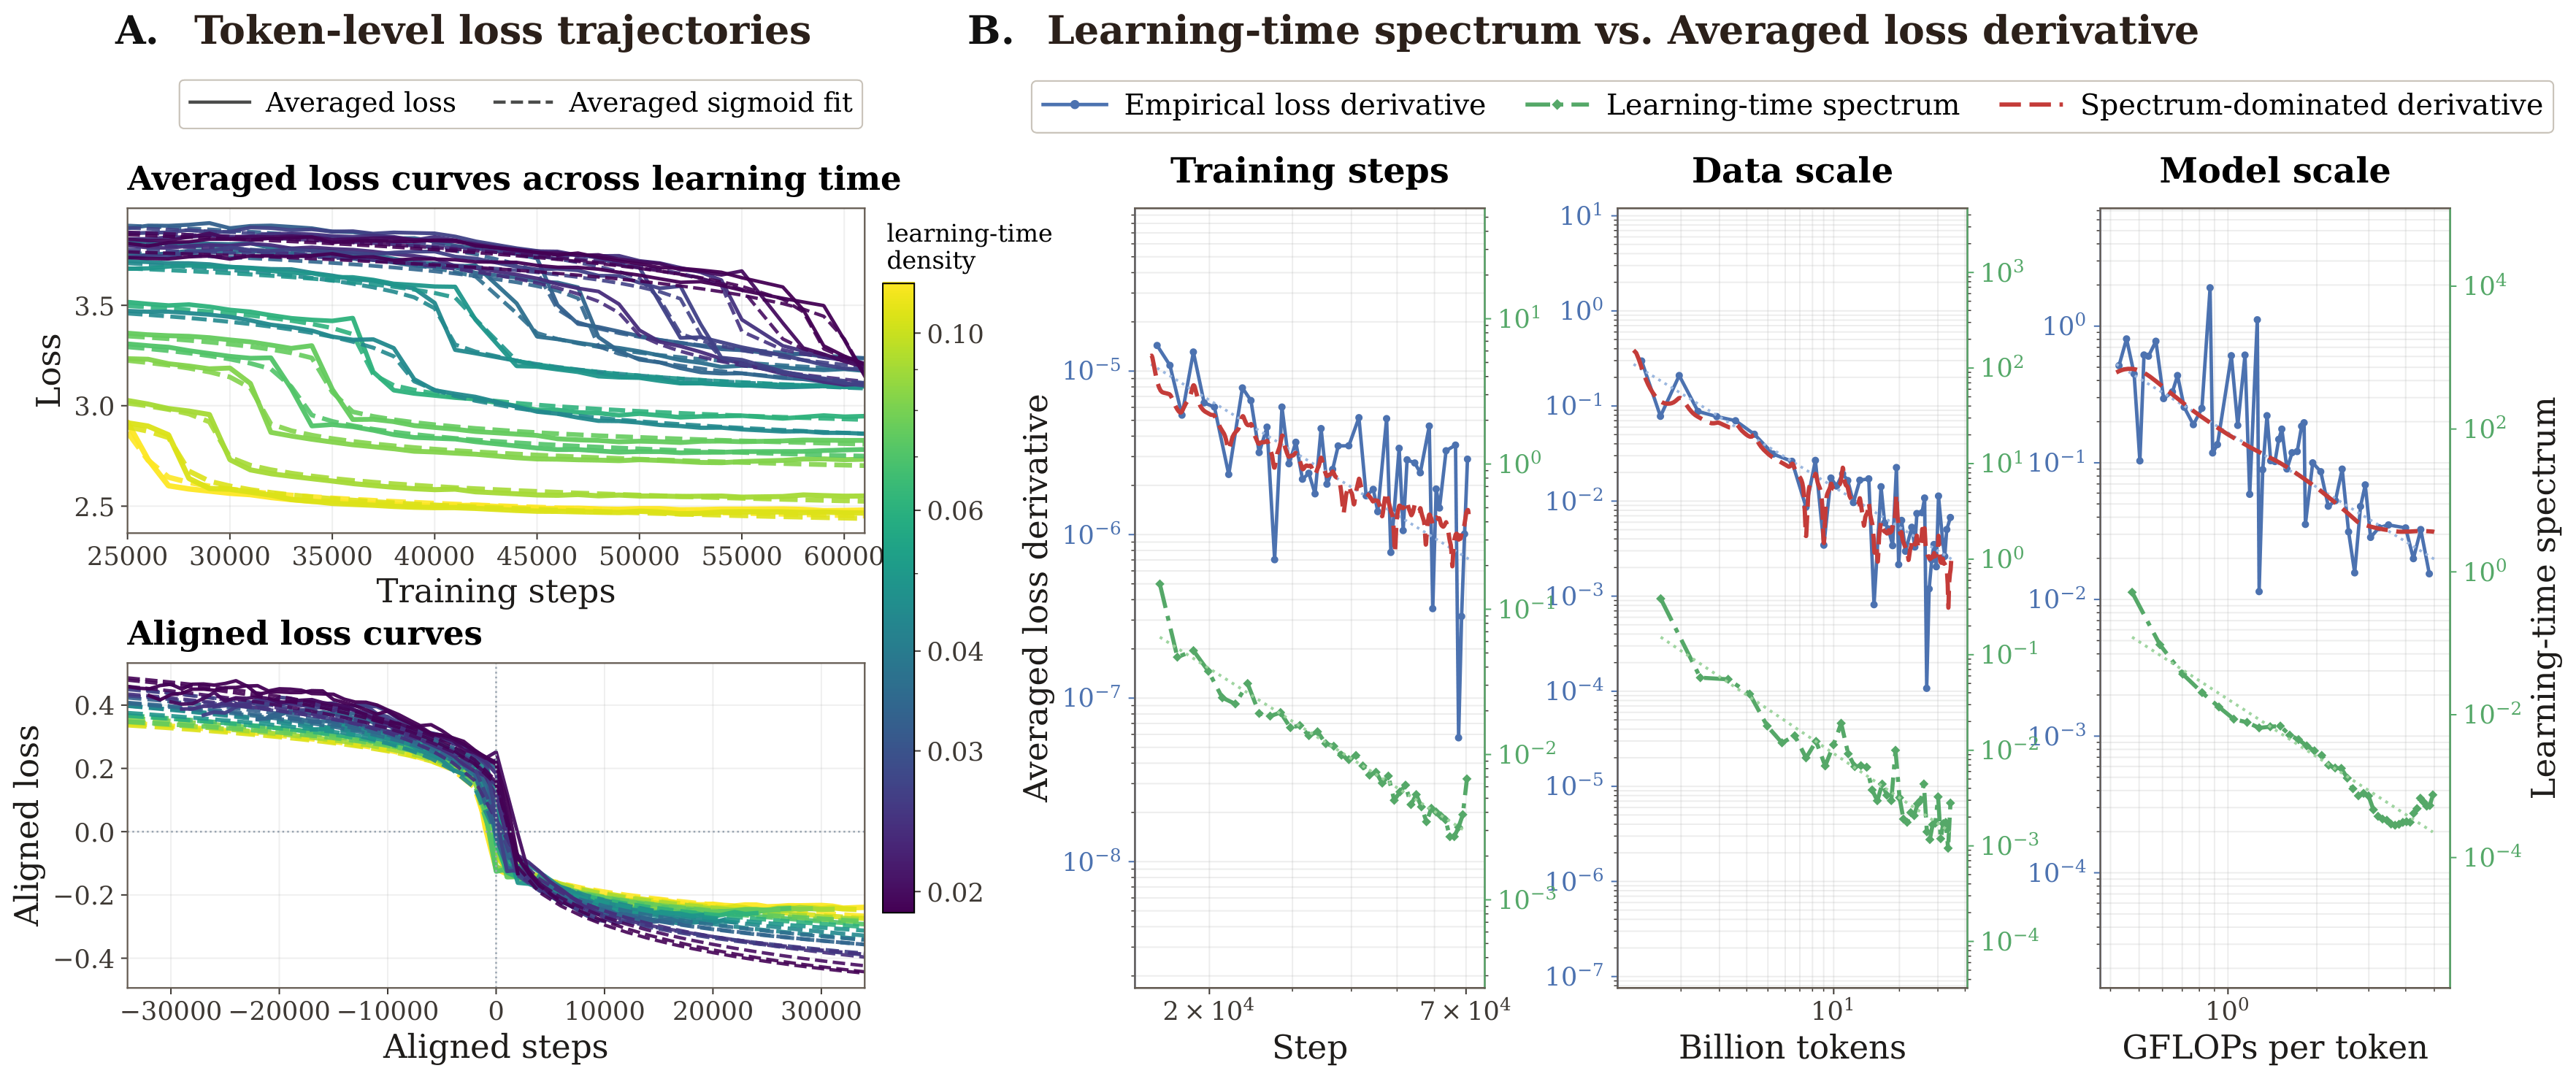
+
Each row is one contextualized token, and each column is a checkpoint or a run
|
| 72 |
+
along the scaling axis *a*. Individual rows drop in localized, sigmoid-like
|
| 73 |
+
steps, which the paper fits with one learning event per token:
|
| 74 |
+
|
| 75 |
+
$$
|
| 76 |
+
\ell_i(a) \approx \ell_i^{\mathrm{post}} + \Delta_i \left[ 1 - \sigma\big( \lambda_i (a - \tau_i) \big) \right]
|
| 77 |
+
$$
|
| 78 |
+
|
| 79 |
+
Here τ is when the token is learned, λ how abruptly, and Δ how much loss it
|
| 80 |
+
sheds. The learning pulses share one shape *g*, so the slope of the averaged
|
| 81 |
+
loss *L* is the distribution of learning times, the learning-time spectrum
|
| 82 |
+
*p*(τ), smoothed by *g*:
|
| 83 |
+
|
| 84 |
+
$$
|
| 85 |
+
-\frac{\mathrm{d}L}{\mathrm{d}a} \approx \int p(\tau) \thinspace g(a - \tau) \thinspace \mathrm{d}\tau
|
| 86 |
+
$$
|
| 87 |
+
|
| 88 |
+
|
| 89 |
+
|
| 90 |
+
## Contents
|
| 91 |
+
|
| 92 |
+
| Asset | Scaling axis | Rows × points | Axis range | NPZ size | Paper | Viewer config |
|
| 93 |
+
| --- | --- | ---: | --- | ---: | --- | --- |
|
| 94 |
+
| [`step_axis_1m`](examples/step_axis_1m/losses.npz) | Training steps *T* | 1,000,000 × 54 | 15,000–71,000 steps | 196.7 MB | Figure 3 | `step_axis_1m` (10K-row preview) |
|
| 95 |
+
| [`d_axis_1m`](examples/d_axis_1m/losses.npz) | Data scale *D* | 1,000,000 × 50 | 1.196–34.662B tokens | 183.0 MB | Figure 4 | `d_axis_1m` (10K-row preview) |
|
| 96 |
+
| [`m_axis_1m`](examples/m_axis_1m/losses.npz) | Model scale *M* | 1,000,000 × 60 | 0.416–4.999 GFLOPs/token | 219.3 MB | Figure 5 | `m_axis_1m` (10K-row preview) |
|
| 97 |
+
| [`synthetic_mano_uniform_validation_10k`](examples/synthetic_mano_uniform_validation_10k/losses.npz) | Training steps | 10,000 × 80 | 5,000–400,000 steps | 1.5 MB | Appendix | `synthetic_mano_uniform_validation_10k` (all rows) |
|
| 98 |
+
|
| 99 |
+
The full matrices are the `losses.npz` files. The Dataset Viewer shows Parquet
|
| 100 |
+
previews: a seeded random sample of 10,000 rows from each T/D/M matrix, the
|
| 101 |
+
complete synthetic matrix, and an `axes` table with the axis values of every
|
| 102 |
+
asset. Byte sizes and SHA256 checksums are listed in
|
| 103 |
+
[`manifest.yaml`](manifest.yaml).
|
| 104 |
+
|
| 105 |
+
## Quick Start
|
| 106 |
+
|
| 107 |
+
Browse a preview with 🤗 Datasets:
|
| 108 |
+
|
| 109 |
+
```python
|
| 110 |
+
from datasets import load_dataset
|
| 111 |
+
|
| 112 |
+
repo = "applewpj/token-learning-spectrum-examples"
|
| 113 |
+
preview = load_dataset(repo, "step_axis_1m", split="preview") # columns: row, loss[54]
|
| 114 |
+
axes = load_dataset(repo, "axes", split="full") # axis values per asset
|
| 115 |
```
|
| 116 |
|
| 117 |
+
Load a full matrix with NumPy:
|
| 118 |
+
|
| 119 |
+
```python
|
| 120 |
+
import numpy as np
|
| 121 |
+
from huggingface_hub import hf_hub_download
|
| 122 |
+
|
| 123 |
+
path = hf_hub_download(
|
| 124 |
+
repo_id="applewpj/token-learning-spectrum-examples",
|
| 125 |
+
repo_type="dataset",
|
| 126 |
+
filename="examples/step_axis_1m/losses.npz",
|
| 127 |
+
)
|
| 128 |
+
with np.load(path, allow_pickle=False) as data:
|
| 129 |
+
steps = data["axis_values"] # (54,) training steps
|
| 130 |
+
losses = data["loss_matrix"] # (1000000, 54) float32, one row per token
|
| 131 |
+
|
| 132 |
+
mean_loss = losses.mean(axis=0) # the aggregate validation-loss curve
|
| 133 |
+
```
|
| 134 |
+
|
| 135 |
+
Reproduce the paper figures from these files with the
|
| 136 |
+
[analysis code](https://github.com/applewpj/stepwise-token-learning). Each
|
| 137 |
+
command downloads the matrix it needs, verifies its checksum, fits it, and
|
| 138 |
+
checks the result against reference numbers:
|
| 139 |
|
| 140 |
```bash
|
| 141 |
+
git clone https://github.com/applewpj/stepwise-token-learning
|
| 142 |
+
cd stepwise-token-learning
|
| 143 |
+
pip install -e .
|
| 144 |
+
tokenlearning reproduce fig3 --quick # Figure 3 from 50,000 tokens, about a minute on CPU
|
| 145 |
+
tokenlearning reproduce all # Figures 3-5 and the appendix at the paper setting
|
| 146 |
+
```
|
| 147 |
+
|
| 148 |
+
The [Colab quickstart](https://colab.research.google.com/github/applewpj/stepwise-token-learning/blob/main/notebooks/quickstart.ipynb)
|
| 149 |
+
runs the same pipeline in the browser.
|
| 150 |
+
|
| 151 |
+
## Data Structure
|
| 152 |
+
|
| 153 |
+
Each `losses.npz` contains:
|
| 154 |
+
|
| 155 |
+
```text
|
| 156 |
+
axis_values: float64 [K] ordered positions along the scaling axis
|
| 157 |
+
loss_matrix: float32 [N, K] loss of token row i at axis point j
|
| 158 |
+
axis_name: string [1] e.g. "training step"
|
| 159 |
+
```
|
| 160 |
+
|
| 161 |
+
Rows are aligned: `loss_matrix[i, j]` is the same contextualized token at every
|
| 162 |
+
axis point `j`, which is what makes token-level trajectories meaningful. The
|
| 163 |
+
synthetic matrix adds per-row metadata: `sample_id`, `token_pos`, `difficulty`,
|
| 164 |
+
`seed`, and `question` (the arithmetic expression).
|
| 165 |
+
|
| 166 |
+
The Parquet previews have one row per token with columns `row` (index into the
|
| 167 |
+
full `loss_matrix`), any per-row metadata, and `loss` (the trajectory as a list
|
| 168 |
+
of `K` floats). The `axes` config has one row per asset with `asset`,
|
| 169 |
+
`axis_name`, `n_points`, `n_tokens`, `preview_rows`, and `axis_values`.
|
| 170 |
+
|
| 171 |
+
## Provenance
|
| 172 |
+
|
| 173 |
+
| Asset | How it was produced |
|
| 174 |
+
| --- | --- |
|
| 175 |
+
| `step_axis_1m` | A 1.5B dense model trained on 300B tokens of a mixed corpus (Chinese, English, mathematics, reasoning, books, papers, code); 54 checkpoints. |
|
| 176 |
+
| `d_axis_1m` | A 290M MoE model; a 50-run sweep over training budgets from 1B to 35B tokens, each run with a complete warmup-constant-decay schedule, used to construct the data-scale frontier. |
|
| 177 |
+
| `m_axis_1m` | A 60-run sweep of model variants from 0.42 to 5.00 GFLOPs/token (≈400M–6B parameters), each trained on 10B tokens and tuned toward a near-optimal model-scale frontier. |
|
| 178 |
+
| `synthetic_mano_uniform_validation_10k` | The public synthetic arithmetic (Mano) pipeline adapted from [PhysicsLM4](https://github.com/facebookresearch/PhysicsLM4); 10,000 validation samples scored at 80 checkpoints. |
|
| 179 |
+
|
| 180 |
+
The T/D/M losses are measured on held-out validation tokens; for the step axis,
|
| 181 |
+
the validation set is sampled from the same distribution as the training
|
| 182 |
+
corpus. The matrices are sanitized analysis artifacts: they keep aligned token
|
| 183 |
+
losses and axis values only, and do not include model architectures, weights,
|
| 184 |
+
tokenizers, validation text, training-data composition, experiment registries,
|
| 185 |
+
or checkpoint paths.
|
| 186 |
+
|
| 187 |
+
## Uses and Limitations
|
| 188 |
+
|
| 189 |
+
Suited for reproducing the paper's analysis, testing alternative learning-time
|
| 190 |
+
estimators or curve-fitting methods, and studying token-level learning dynamics
|
| 191 |
+
along scaling axes.
|
| 192 |
+
|
| 193 |
+
- Rows of the T/D/M matrices cannot be mapped back to token strings or text.
|
| 194 |
+
- These are loss measurements, not a language-model training corpus.
|
| 195 |
+
- Per-token trajectories are noisy; the paper's sigmoid fits describe the
|
| 196 |
+
dominant transition, not every fluctuation.
|
| 197 |
+
|
| 198 |
+
## Citation
|
| 199 |
+
|
| 200 |
+
```bibtex
|
| 201 |
+
@inproceedings{wang2026smooth,
|
| 202 |
+
title = {Smooth Scaling Laws Hide Stepwise Token Learning},
|
| 203 |
+
author = {Wang, Pingjie and Hu, Zechen and Yang, Peiru and Guo, Fu and Zhang, Debing},
|
| 204 |
+
booktitle = {Advances in Neural Information Processing Systems},
|
| 205 |
+
year = {2026},
|
| 206 |
+
url = {https://openreview.net/forum?id=THZDVZArRH}
|
| 207 |
+
}
|
| 208 |
```
|
| 209 |
|
| 210 |
+
## License and Contact
|
|
|
|
|
|
|
| 211 |
|
| 212 |
+
The matrices are released under the [MIT License](LICENSE). Questions and
|
| 213 |
+
issues are welcome on the
|
| 214 |
+
[GitHub issue tracker](https://github.com/applewpj/stepwise-token-learning/issues).
|
previews/axes.parquet
ADDED
|
@@ -0,0 +1,3 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
version https://git-lfs.github.com/spec/v1
|
| 2 |
+
oid sha256:b7c9a73e05614c9953e3f81e74d5f9cc622a848556c8d7782d648a47e2be9806
|
| 3 |
+
size 3889
|
previews/d_axis_1m.parquet
ADDED
|
@@ -0,0 +1,3 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
version https://git-lfs.github.com/spec/v1
|
| 2 |
+
oid sha256:a2656c214f62b9ef192fea5ea48420029386e99a0c45e3d219b193d6dbe93ba2
|
| 3 |
+
size 2479293
|
previews/m_axis_1m.parquet
ADDED
|
@@ -0,0 +1,3 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
version https://git-lfs.github.com/spec/v1
|
| 2 |
+
oid sha256:0d3ebd69d6f9e9c0d3c745d8ed6358c476455da666060c1764dbc73f7626f038
|
| 3 |
+
size 2841411
|
previews/step_axis_1m.parquet
ADDED
|
@@ -0,0 +1,3 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
version https://git-lfs.github.com/spec/v1
|
| 2 |
+
oid sha256:b3e015fc6b08b5d838e2a3a275adeb55f61ee0292540188153668c7fa384f0ee
|
| 3 |
+
size 2613898
|
previews/synthetic_mano_uniform_validation_10k.parquet
ADDED
|
@@ -0,0 +1,3 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
version https://git-lfs.github.com/spec/v1
|
| 2 |
+
oid sha256:83bbb17226ff9e73640d15646b1a93863f427b01befd27264991d84d2ccf63a8
|
| 3 |
+
size 1274351
|