
datasetId stringlengths 2 117 | card stringlengths 19 1.01M |
|---|---|
davanstrien/autotrain-data-french-medical-ner | Invalid username or password. |
contemmcm/20_newsgroups | ---
task_categories:
- text-classification
dataset_info:
features:
- name: from
dtype: string
- name: subject
dtype: string
- name: organization
dtype: string
- name: text
dtype: string
- name: label
dtype:
class_label:
names:
... |
mitermix/chess-selfplay | ---
license: apache-2.0
---
|
misza222/owczpodh-dog-results | ---
dataset_info:
features:
- name: images
dtype: image
- name: prompts
dtype: string
splits:
- name: train
num_bytes: 3813312.0
num_examples: 8
download_size: 3814513
dataset_size: 3813312.0
---
# Dataset Card for "owczpodh-dog-results"
[More Information needed](https://github.com/huggin... |
universeTBD/arxiv-astro-abstracts-all | ---
license: mit
dataset_info:
features:
- name: arxiv_id
dtype: string
- name: text
dtype: string
splits:
- name: train
num_bytes: 321324568.42730767
num_examples: 264252
- name: valid
num_bytes: 35703540.4771302
num_examples: 29362
- name: test
num_bytes: 39670060.09556214
... |
AIGym/custom-generated2 | ---
dataset_info:
features:
- name: text
dtype: string
splits:
- name: train
num_bytes: 56106
num_examples: 429
download_size: 30436
dataset_size: 56106
configs:
- config_name: default
data_files:
- split: train
path: data/train-*
---
|
ai2lumos/lumos_unified_ground_iterative | ---
license: apache-2.0
task_categories:
- text-generation
- question-answering
language:
- en
tags:
- language-agent
- maths
- reasoning
- question-answering
- web-agent
- grounding
size_categories:
- 10K<n<100K
---
# 🪄 Agent Lumos: Unified and Modular Training for Open-Source Language Agents
<p align="center">
🌐... |
Elhassnaoui-2001/hf_dataset | ---
license: apache-2.0
---
|
lunarlist/edited_common_voice | ---
dataset_info:
features:
- name: audio_filepath
dtype: audio
- name: text
dtype: string
- name: duration
dtype: float64
splits:
- name: train
num_bytes: 6731304269.504
num_examples: 36296
- name: test
num_bytes: 340059709.94
num_examples: 1911
download_size: 6985650459
d... |
gabrielmbmb/wikipedia_genstruct_dpo | ---
dataset_info:
features:
- name: title
dtype: string
- name: content
dtype: string
- name: messages
sequence: 'null'
- name: generation_model
sequence: string
- name: generation_prompt
sequence: string
- name: raw_generation_responses
sequence: string
- name: conversation
... |
PokerMon/PokemonHorizons | ---
license: unknown
---
If you found this from a search engine or randomly stumbled upon this "dataset", go to https://huggingface.co/PokerMon/PokemonHorizons, as this is not the intended location of what you're looking for.
The link above leads to all Pokemon Horizons episodes, whether it is subbed or not.
This dat... |
natural_questions | ---
annotations_creators:
- no-annotation
language_creators:
- crowdsourced
language:
- en
license:
- cc-by-sa-3.0
multilinguality:
- monolingual
size_categories:
- 100K<n<1M
source_datasets:
- original
task_categories:
- question-answering
task_ids:
- open-domain-qa
paperswithcode_id: natural-questions
pretty_name: Na... |
LoLZeS666/test | ---
license: apache-2.0
---
|
yutakobayashi/diet-members-voice-embeddings | ---
license: apache-2.0
language:
- ja
pretty_name: a
---
# diet-members-voice-embeddings
日本の国会議員の声を [speechbrain/spkrec-ecapa-voxceleb](https://huggingface.co/speechbrain/spkrec-ecapa-voxceleb)で embedding したデータセットです。話者分離などのタスクで使用できます。
国会中継や演説等の分析など、ご自由にお使いください。
## 使用例
以下はトランスクリプトと音声ファイルを元に、話者分析を行う例です。
```bash
... |
Samir001/Resume_Summary | ---
license: other
---
Description: The resumes are taken from here: https://www.kaggle.com/datasets/gauravduttakiit/resume-dataset
The resumes related to data science job positions are filtered and then summarised.
|
joey234/mmlu-college_chemistry-neg-answer | ---
dataset_info:
features:
- name: question
dtype: string
- name: choices
sequence: string
- name: answer
dtype:
class_label:
names:
'0': A
'1': B
'2': C
'3': D
- name: neg_answer
dtype: string
splits:
- name: test
num_bytes: 27423... |
Isamu136/wikiart_indexed | ---
dataset_info:
features:
- name: image
dtype: image
- name: artist
dtype:
class_label:
names:
'0': Unknown Artist
'1': boris-kustodiev
'2': camille-pissarro
'3': childe-hassam
'4': claude-monet
'5': edgar-degas
'6': eug... |
hezarai/parsynth-ocr-200k | ---
task_categories:
- image-to-image
language:
- fa
tags:
- hezar
pretty_name: ParsynthOCR-200K
size_categories:
- 100K<n<1M
---
ParsynthOCR is a synthetic dataset for Persian OCR. This version is a preview of the original 4 million samples dataset (ParsynthOCR-4M).
# Usage
## 🤗 Datasets
```python
from datasets impo... |
joey234/affixal_negation_nonce | ---
dataset_info:
features:
- name: word
dtype: string
- name: affix
dtype: string
- name: label
dtype: int64
splits:
- name: train
num_bytes: 25284.0
num_examples: 880
download_size: 9528
dataset_size: 25284.0
configs:
- config_name: default
data_files:
- split: train
path: ... |
DBQ/Mr.Porter.Product.prices.Germany | ---
annotations_creators:
- other
language_creators:
- other
language:
- en
license:
- unknown
multilinguality:
- monolingual
source_datasets:
- original
task_categories:
- text-classification
- image-classification
- feature-extraction
- image-segmentation
- image-to-image
- image-to-text
- object-detection
- summariz... |
Henriquee/CarEvaluationDataset | ---
license: mit
---
|
mikhail-panzo/fleurs-fil | ---
dataset_info:
features:
- name: speaker_embeddings
sequence: float32
- name: input_ids
sequence: int32
- name: labels
sequence:
sequence: float32
splits:
- name: train
num_bytes: 675276860
num_examples: 2619
download_size: 670723068
dataset_size: 675276860
configs:
- config... |
xuanzz/VideoCaptions | ---
license: mit
---
|
Danitg95/feedback | ---
license: other
---
|
haor/pixiv_month_top50 | ---
license: openrail
---
18-22/10 pixiv Monthly ranking top 50
768 x *
total:38532
with txt |
Tristan/sample_test | ---
dataset_info:
features:
- name: image
dtype: image
- name: id
dtype: int64
- name: Attributes_LAION_ViT_H_14_2B_descriptors_text_davinci_003_full
sequence: string
splits:
- name: test
num_bytes: 177091.0
num_examples: 10
download_size: 154991
dataset_size: 177091.0
---
# Dataset ... |
joey234/mmlu-high_school_us_history-original-neg-prepend | ---
dataset_info:
features:
- name: question
dtype: string
- name: choices
sequence: string
- name: answer
dtype:
class_label:
names:
'0': A
'1': B
'2': C
'3': D
- name: neg_prompt
dtype: string
splits:
- name: test
num_bytes: 51139... |
anindyamondal/Omnicount-191 | ---
language:
- en
tags:
- counting
- object-counting
---
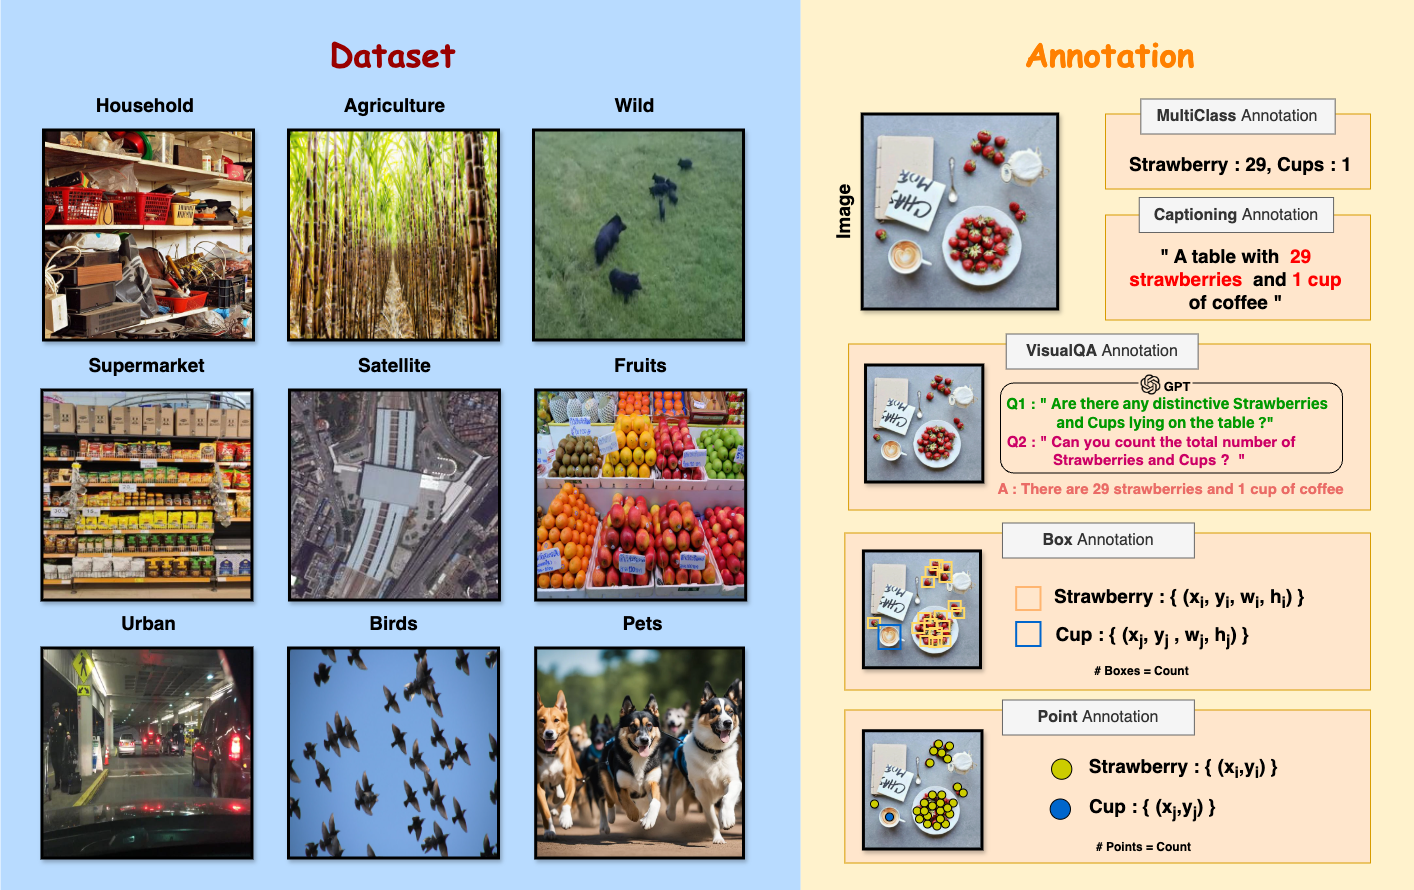
# Dataset Card for Dataset Name
OmniCount-191 is a first-of-its-kind dataset with multi-label object counts, including points, bounding boxes, and VQA... |
open-llm-leaderboard/details_Undi95__ReMM-v2-L2-13B | ---
pretty_name: Evaluation run of Undi95/ReMM-v2-L2-13B
dataset_summary: "Dataset automatically created during the evaluation run of model\
\ [Undi95/ReMM-v2-L2-13B](https://huggingface.co/Undi95/ReMM-v2-L2-13B) on the [Open\
\ LLM Leaderboard](https://huggingface.co/spaces/HuggingFaceH4/open_llm_leaderboard).\n\
... |
one-sec-cv12/chunk_89 | ---
dataset_info:
features:
- name: audio
dtype:
audio:
sampling_rate: 16000
splits:
- name: train
num_bytes: 24703929792.5
num_examples: 257204
download_size: 22700301276
dataset_size: 24703929792.5
---
# Dataset Card for "chunk_89"
[More Information needed](https://github.com/hu... |
Estwld/atomic2020-instruct-drop_duplicates | ---
dataset_info:
features:
- name: knowledge_type
dtype: string
- name: task_type
dtype: string
- name: input
dtype: string
- name: output
dtype: string
splits:
- name: train
num_bytes: 755049360
num_examples: 2016508
- name: validation
num_bytes: 70762021
num_examples: ... |
vegeta/legaltokenized256 | ---
dataset_info:
features:
- name: input_ids
sequence: int32
- name: attention_mask
sequence: int8
splits:
- name: train
num_bytes: 27564311544
num_examples: 21400863
- name: validation
num_bytes: 3008263104
num_examples: 2335608
download_size: 7092165713
dataset_size: 305725746... |
Admin0805/Chat | ---
license: mit
---
|
shubh0493/TaxAI | ---
license: mit
---
|
roa7n/knots_AF_no_fragments | ---
dataset_info:
features:
- name: ID
dtype: string
- name: latestVersion
dtype: int64
- name: globalMetricValue
dtype: float64
- name: uniprotStart
dtype: int64
- name: uniprotEnd
dtype: int64
- name: uniprotSequence
dtype: string
- name: Length
dtype: float64
- name: Dom... |
pranav301102/customer-service-for-llm | ---
license: apache-2.0
---
|
shaaz10/rbiscrape_v1.0_120823 | ---
license: unknown
---
|
CyberHarem/tohsaka_rin_fatestaynightufotable_fatestaynightufotable | ---
license: mit
task_categories:
- text-to-image
tags:
- art
- not-for-all-audiences
size_categories:
- n<1K
---
# Dataset of Tohsaka Rin (Fate Stay Night [UFOTABLE])
This is the dataset of Tohsaka Rin (Fate Stay Night [UFOTABLE]), containing 722 images and their tags.
The core tags of this character are `long_hair... |
masakhane/afriqa_wiki_en_fr_100 | ---
language:
- en
- fr
multilinguality:
- multilingual
task_categories:
- text-retrieval
license: apache-2.0
viewer: true
pretty_name: Wikipedia 100 word Passages
---
|
open-llm-leaderboard/details_rinna__bilingual-gpt-neox-4b-instruction-sft | ---
pretty_name: Evaluation run of rinna/bilingual-gpt-neox-4b-instruction-sft
dataset_summary: "Dataset automatically created during the evaluation run of model\
\ [rinna/bilingual-gpt-neox-4b-instruction-sft](https://huggingface.co/rinna/bilingual-gpt-neox-4b-instruction-sft)\
\ on the [Open LLM Leaderboard](http... |
netcat420/MHENN3b | ---
license: mit
---
|
osanseviero/yannic_test2 | ---
task_categories:
- automatic-speech-recognition
dataset_info:
features:
- name: CHANNEL_NAME
dtype: string
- name: URL
dtype: string
- name: TITLE
dtype: string
- name: DESCRIPTION
dtype: string
- name: TRANSCRIPTION
dtype: string
- name: SEGMENTS
dtype: string
splits:
- na... |
CyberHarem/lysithea_von_cordelia_fireemblem | ---
license: mit
task_categories:
- text-to-image
tags:
- art
- not-for-all-audiences
size_categories:
- n<1K
---
# Dataset of lysithea_von_cordelia (Fire Emblem)
This is the dataset of lysithea_von_cordelia (Fire Emblem), containing 500 images and their tags.
The core tags of this character are `long_hair, white_ha... |
CyberHarem/fuyutsuki_kantaicollection | ---
license: mit
task_categories:
- text-to-image
tags:
- art
- not-for-all-audiences
size_categories:
- n<1K
---
# Dataset of fuyutsuki/冬月/후유츠키 (Kantai Collection)
This is the dataset of fuyutsuki/冬月/후유츠키 (Kantai Collection), containing 315 images and their tags.
The core tags of this character are `long_hair, one_... |
Skepsun/cvalues_rlhf | ---
license: apache-2.0
language:
- zh
---
Converted from: https://modelscope.cn/datasets/damo/CValues-Comparison/summary. We obtained harmless set by selecting `pos_type="拒绝为主"` and `neg_type="风险回复"`. We obtained helpful set by selecting `pos_type="拒绝&正向建议"` and `neg_type="拒绝为主"`. |
FanChen0116/bus_few4_05x | ---
dataset_info:
features:
- name: id
dtype: int64
- name: tokens
sequence: string
- name: labels
sequence:
class_label:
names:
'0': O
'1': I-from_location
'2': B-from_location
'3': B-leaving_date
'4': I-leaving_date
'5': I-t... |
tyzhu/squad_rare_v4_train_10_eval_10 | ---
dataset_info:
features:
- name: id
dtype: string
- name: title
dtype: string
- name: context
dtype: string
- name: question
dtype: string
- name: answers
sequence:
- name: text
dtype: string
- name: answer_start
dtype: int32
- name: context_id
dtype: string
... |
tyzhu/squad_qa_title_v5_full_recite_full_passage_first_permute_rerun | ---
configs:
- config_name: default
data_files:
- split: train
path: data/train-*
- split: validation
path: data/validation-*
dataset_info:
features:
- name: id
dtype: string
- name: title
dtype: string
- name: context
dtype: string
- name: question
dtype: string
- name: answer... |
GEODE/GeoEDdA | ---
license: cc-by-nc-4.0
task_categories:
- token-classification
language:
- fr
tags:
- spacy
pretty_name: GeoEDdA
---
# GeoEDdA: A Gold Standard Dataset for Geo-semantic Annotation of Diderot & d’Alembert’s Encyclopédie
## Dataset Description
<!-- Provide a longer summary of what this model is. -->
- **Authors:*... |
bigscience-data/roots_indic-mr_mkb | ---
language: mr
license: cc-by-sa-4.0
extra_gated_prompt: 'By accessing this dataset, you agree to abide by the BigScience
Ethical Charter. The charter can be found at:
https://hf.co/spaces/bigscience/ethical-charter'
extra_gated_fields:
I have read and agree to abide by the BigScience Ethical Charter: checkbox... |
CyberHarem/haze_arknights | ---
license: mit
task_categories:
- text-to-image
tags:
- art
- not-for-all-audiences
size_categories:
- n<1K
---
# Dataset of haze/ヘイズ/夜烟 (Arknights)
This is the dataset of haze/ヘイズ/夜烟 (Arknights), containing 88 images and their tags.
The core tags of this character are `animal_ears, hat, black_headwear, witch_hat,... |
jagoldz/gahd | ---
license: cc-by-4.0
task_categories:
- text-classification
language:
- de
tags:
- hate-speech-detection
- hate-speech
pretty_name: GAHD
size_categories:
- 10K<n<100K
---
# Dataset Card for GAHD
## Dataset Description
GAHD is a **G**erman **A**dversarial **H**ate speech **D**ataset containing 10,996 examples. We co... |
LambdaTests/VQAv2Validation_ViT_H_14_A_T_C_Q_benchmarks_partition_global_19_1000 | ---
dataset_info:
features:
- name: id
dtype: int64
- name: response
dtype: string
splits:
- name: train
num_bytes: 888
num_examples: 32
download_size: 1999
dataset_size: 888
---
# Dataset Card for "VQAv2Validation_ViT_H_14_A_T_C_Q_benchmarks_partition_global_19_1000"
[More Information ne... |
indentcorp-data/food_gpt4labeled_one_by_one | ---
dataset_info:
features:
- name: instruction
dtype: string
- name: output
dtype: string
splits:
- name: train
num_bytes: 215629584
num_examples: 150348
- name: validation
num_bytes: 6384501
num_examples: 4353
download_size: 33711938
dataset_size: 222014085
configs:
- config_na... |
karimasbar/data2 | ---
license: mit
---
|
lmms-lab/CMMMU | ---
dataset_info:
features:
- name: id
dtype: string
- name: type
dtype: string
- name: source_type
dtype: string
- name: source
dtype: string
- name: question
dtype: string
- name: option1
dtype: string
- name: option2
dtype: string
- name: option3
dtype: string
- na... |
9wimu9/sinhala_33m_sorted_by_size | ---
dataset_info:
features:
- name: text
dtype: string
splits:
- name: train
num_bytes: 8136854907
num_examples: 33947380
download_size: 3787995288
dataset_size: 8136854907
---
# Dataset Card for "sinhala_33m_sorted_by_size"
[More Information needed](https://github.com/huggingface/datasets/blob... |
MaryDatascientist/test | ---
dataset_info:
features:
- name: tokens
sequence: string
- name: ner_tags
sequence: int64
- name: lang
dtype: string
splits:
- name: train
num_bytes: 1260
num_examples: 4
- name: validation
num_bytes: 1010
num_examples: 4
- name: test
num_bytes: 1654
num_examples: ... |
HyperbeeAI/teknium_openhermes_rewriting | ---
dataset_info:
features:
- name: instruction
dtype: string
- name: old_answer
dtype: string
- name: improved_answer
dtype: string
splits:
- name: train
num_bytes: 656650329
num_examples: 242831
download_size: 313784909
dataset_size: 656650329
configs:
- config_name: default
data... |
devozs/israeli_soccer_news | ---
dataset_info:
features:
- name: article_title
dtype: string
- name: article_body
dtype: string
- name: article_body_length
dtype: int64
splits:
- name: train
num_bytes: 8956722.687408645
num_examples: 4310
- name: validation
num_bytes: 995422.3125913552
num_examples: 479
... |
davidberenstein1957/ultra_feedback_dutch_cleaned_helm_instruct_geitje_ultra_vs_gpt4_turbo_example | ---
dataset_info:
features:
- name: GEITje-7B-ultra
dtype: string
- name: TowerInstruct-13B-v0.1
dtype: string
- name: TowerInstruct-7B-v0.2
dtype: string
- name: geitje-7b-chat
dtype: string
- name: gpt-4-turbo
dtype: string
- name: llama-2-13b-chat-dutch
dtype: string
- name: p... |
liuyanchen1015/VALUE_mrpc_uninflect | ---
dataset_info:
features:
- name: sentence1
dtype: string
- name: sentence2
dtype: string
- name: label
dtype: int64
- name: idx
dtype: int64
- name: value_score
dtype: int64
splits:
- name: test
num_bytes: 156118
num_examples: 566
- name: train
num_bytes: 346454
... |
adamjweintraut/lyrlen | ---
dataset_info:
features:
- name: title
dtype: string
- name: id
dtype: int64
- name: genre
dtype: string
- name: lyric_chunk_n
dtype: int64
- name: sylls
dtype: int64
- name: orig
dtype: string
- name: target
dtype: string
splits:
- name: train
num_bytes: 15546161
... |
prhegde/preference-data-math-stack-exchange | ---
license: apache-2.0
---
The preference dataset is derived from the [stack exchange dataset](https://huggingface.co/datasets/HuggingFaceH4/stack-exchange-preferences) which contains questions and answers from the Stack Overflow Data Dump. This contains questions and answers for various topics. For this work, we use... |
yixin/metacloak_vggface2_protected_11 | ---
dataset_info:
features:
- name: image
dtype: image
- name: instance_name
dtype: string
- name: class_name
dtype: string
splits:
- name: vggface2_protected_11
num_bytes: 92062568.0
num_examples: 192
download_size: 92067725
dataset_size: 92062568.0
---
# Dataset Card for "metacloak... |
SDbiaseval/embeddings | ---
license: apache-2.0
---
|
denyslaz/evaluation_dataset | ---
dataset_info:
features:
- name: query_id
dtype: string
- name: query
dtype: string
- name: doc_id
dtype: string
- name: doc
dtype: string
- name: mode
dtype: string
splits:
- name: validation
num_bytes: 2936816
num_examples: 820
- name: train
num_bytes: 74566
nu... |
iamjadhav/controlnet_inpaint_test | ---
license: apache-2.0
---
|
liuyanchen1015/MULTI_VALUE_mrpc_yall | ---
dataset_info:
features:
- name: sentence1
dtype: string
- name: sentence2
dtype: string
- name: label
dtype: int64
- name: idx
dtype: int64
- name: value_score
dtype: int64
splits:
- name: test
num_bytes: 2343
num_examples: 9
- name: train
num_bytes: 9600
num_ex... |
BeIR/quora-qrels | ---
annotations_creators: []
language_creators: []
language:
- en
license:
- cc-by-sa-4.0
multilinguality:
- monolingual
paperswithcode_id: beir
pretty_name: BEIR Benchmark
size_categories:
msmarco:
- 1M<n<10M
trec-covid:
- 100k<n<1M
nfcorpus:
- 1K<n<10K
nq:
- 1M<n<10M
hotpotqa:
- 1M<n<10M
fiqa:
... |
Hashif/judgement-summarisation-llama-2 | ---
dataset_info:
features:
- name: text
dtype: string
splits:
- name: train
num_bytes: 96106569.43206446
num_examples: 3239
- name: test
num_bytes: 10681804.567935538
num_examples: 360
download_size: 51200571
dataset_size: 106788374.0
configs:
- config_name: default
data_files:
- ... |
alex2awesome/city-council-gpt3-silver-standard-summaries | ---
dataset_info:
features:
- name: text
dtype: string
- name: summary
dtype: string
splits:
- name: train
num_bytes: 21349237
num_examples: 3250
download_size: 9490470
dataset_size: 21349237
---
# Dataset Card for "city-council-gpt3-silver-standard-summaries"
[More Information needed](ht... |
open-llm-leaderboard/details_seungduk__KoSOLAR-10.7B-v0.1 | ---
pretty_name: Evaluation run of seungduk/KoSOLAR-10.7B-v0.1
dataset_summary: "Dataset automatically created during the evaluation run of model\
\ [seungduk/KoSOLAR-10.7B-v0.1](https://huggingface.co/seungduk/KoSOLAR-10.7B-v0.1)\
\ on the [Open LLM Leaderboard](https://huggingface.co/spaces/HuggingFaceH4/open_llm... |
Jaya1995/Maintenance | ---
dataset_info:
features:
- name: sentence
dtype: string
splits:
- name: train
num_bytes: 6677
num_examples: 100
download_size: 4106
dataset_size: 6677
configs:
- config_name: default
data_files:
- split: train
path: data/train-*
---
# Dataset Card for "Maintenance"
[More Information ... |
PrincipledPreTraining/DiscoEval | ---
license: bsd
task_categories:
- text-classification
language:
- en
tags:
- Discourse
- Discourse Evaluation
- NLP
pretty_name: DiscoEval
size_categories:
- 100K<n<1M
---
# DiscoEval Benchmark Datasets
## Table of Contents
- [Dataset Description](#dataset-description)
- [Dataset Summary](#dataset-summary)
- [D... |
ibranze/araproje_arc_tr_f3 | ---
dataset_info:
features:
- name: id
dtype: string
- name: question
dtype: string
- name: choices
sequence:
- name: text
dtype: string
- name: label
dtype: string
- name: answerKey
dtype: string
splits:
- name: validation
num_bytes: 86423.0
num_examples: 250
... |
SrushtiR/Srushti | ---
dataset_info:
features:
- name: image
dtype: image
- name: label
dtype:
class_label:
names:
'0': Fire
'1': Normal
'2': Smoke
splits:
- name: train
num_bytes: 160965820.64
num_examples: 6060
- name: validation
num_bytes: 85813019.0
num_e... |
CyberHarem/wakui_rumi_idolmastercinderellagirls | ---
license: mit
task_categories:
- text-to-image
tags:
- art
- not-for-all-audiences
size_categories:
- n<1K
---
# Dataset of wakui_rumi/和久井留美 (THE iDOLM@STER: Cinderella Girls)
This is the dataset of wakui_rumi/和久井留美 (THE iDOLM@STER: Cinderella Girls), containing 46 images and their tags.
The core tags of this cha... |
CyberHarem/kobayakawa_sae_idolmastercinderellagirls | ---
license: mit
task_categories:
- text-to-image
tags:
- art
- not-for-all-audiences
size_categories:
- n<1K
---
# Dataset of kobayakawa_sae/小早川紗枝 (THE iDOLM@STER: Cinderella Girls)
This is the dataset of kobayakawa_sae/小早川紗枝 (THE iDOLM@STER: Cinderella Girls), containing 500 images and their tags.
The core tags of... |
open-llm-leaderboard/details_G-reen__EXPERIMENT-SFT-m7b2-3-merged | ---
pretty_name: Evaluation run of G-reen/EXPERIMENT-SFT-m7b2-3-merged
dataset_summary: "Dataset automatically created during the evaluation run of model\
\ [G-reen/EXPERIMENT-SFT-m7b2-3-merged](https://huggingface.co/G-reen/EXPERIMENT-SFT-m7b2-3-merged)\
\ on the [Open LLM Leaderboard](https://huggingface.co/space... |
AlanYky/subjective-flipped | ---
dataset_info:
features:
- name: inputs
dtype: string
- name: target
dtype: string
splits:
- name: train
num_bytes: 743714
num_examples: 500
download_size: 317923
dataset_size: 743714
configs:
- config_name: default
data_files:
- split: train
path: data/train-*
---
|
mask-distilled-onesec-cv12-each-chunk-uniq/chunk_166 | ---
dataset_info:
features:
- name: logits
sequence: float32
- name: mfcc
sequence:
sequence: float64
splits:
- name: train
num_bytes: 1164112672.0
num_examples: 228616
download_size: 1190208422
dataset_size: 1164112672.0
---
# Dataset Card for "chunk_166"
[More Information needed](... |
nateraw/fuego-20230206-040851-d8a7d1 | ---
tags:
- fuego
fuego:
id: 20230206-040851-d8a7d1
status: done
script: run_glue.py
requirements_file: requirements.txt
space_id: nateraw/fuego-20230206-040851-d8a7d1
space_hardware: t4-small
github_repo_id: huggingface/transformers
github_repo_branch: main
github_repo_sha: 59d5edef34ae0fa56065a2e863... |
Rewcifer/trainset2_2000_cutoff_llama | ---
dataset_info:
features:
- name: text
dtype: string
splits:
- name: train
num_bytes: 249703784.98341143
num_examples: 50000
download_size: 45154240
dataset_size: 249703784.98341143
configs:
- config_name: default
data_files:
- split: train
path: data/train-*
---
# Dataset Card for "tr... |
Verdant/CONTROLNET | ---
license: openrail
---
|
Domino-ai/amazon_polarity_10_pct | ---
configs:
- config_name: default
data_files:
- split: train
path: data/train-*
- split: test
path: data/test-*
dataset_info:
features:
- name: label
dtype:
class_label:
names:
'0': negative
'1': positive
- name: title
dtype: string
- name: content
d... |
CyberHarem/frenda_seivelun_toarumajutsunoindex | ---
license: mit
task_categories:
- text-to-image
tags:
- art
- not-for-all-audiences
size_categories:
- n<1K
---
# Dataset of frenda_seivelun (To Aru Majutsu no Index)
This is the dataset of frenda_seivelun (To Aru Majutsu no Index), containing 137 images and their tags.
Images are crawled from many sites (e.g. dan... |
Chefelipe/LUANPEREIRA | ---
license: openrail
---
|
kuaiyubilly/mathmodels | ---
license: mit
---
|
divi7007/divi7007 | ---
dataset_info:
features:
- name: input_ids
sequence: int32
- name: attention_mask
sequence: int8
splits:
- name: train
num_bytes: 1966464
num_examples: 48
download_size: 0
dataset_size: 1966464
---
# Dataset Card for "divi7007"
[More Information needed](https://github.com/huggingface/d... |
matemato/pokemon_bulbapedia_desc_only | ---
dataset_info:
features:
- name: image
dtype: image
- name: text
dtype: string
splits:
- name: train
num_bytes: 100674542.0
num_examples: 721
download_size: 83888862
dataset_size: 100674542.0
---
# Dataset Card for "pokemon_bulbapedia_desc_only"
[More Information needed](https://github... |
argilla/dolly-curate-falcon7b-instruct-generations | ---
language: en
dataset_info:
features:
- name: prompt
dtype: string
- name: response-1
dtype: string
- name: response-2
dtype: string
- name: category
dtype: string
- name: original_response
dtype: string
- name: external_id
dtype: int64
splits:
- name: train
num_bytes: 1... |
open-llm-leaderboard/details_aisquared__dlite-v1-124m | ---
pretty_name: Evaluation run of aisquared/dlite-v1-124m
dataset_summary: "Dataset automatically created during the evaluation run of model\
\ [aisquared/dlite-v1-124m](https://huggingface.co/aisquared/dlite-v1-124m) on the\
\ [Open LLM Leaderboard](https://huggingface.co/spaces/HuggingFaceH4/open_llm_leaderboard... |
Ohwang/Nuclear_tweets_12k | ---
dataset_info:
config_name: Nuclear tweets(12k)
features:
- name: tweets
dtype: string
- name: Label
dtype: string
splits:
- name: train
num_bytes: 2991435
num_examples: 12091
download_size: 0
dataset_size: 2991435
configs:
- config_name: Nuclear tweets(12k)
data_files:
- split: t... |
azevedopedroc/livias | ---
license: openrail
---
|
ittailup/csic | ---
dataset_info:
features:
- name: text
dtype: string
splits:
- name: train
num_bytes: 929188919
num_examples: 30929
download_size: 529968371
dataset_size: 929188919
---
# Dataset Card for "csic"
[More Information needed](https://github.com/huggingface/datasets/blob/main/CONTRIBUTING.md#how-to... |
yusuf802/new-image-dataset | ---
configs:
- config_name: default
data_files:
- split: train
path: data/train-*
- split: test
path: data/test-*
dataset_info:
features:
- name: image
dtype: image
- name: label
dtype:
class_label:
names:
'0': Apple_Black_rot
'1': Apple_Cedar_apple_rust
... |
eDsny/lucasjales | ---
license: openrail
---
|
unography/shopify-stock-images-2048 | ---
dataset_info:
features:
- name: image
dtype: image
splits:
- name: train
num_bytes: 3133241115.93101
num_examples: 10799
download_size: 3203022329
dataset_size: 3133241115.93101
configs:
- config_name: default
data_files:
- split: train
path: data/train-*
---
|
pnrr/data-turkish-class | ---
pretty_name: Turkish_data
annotations_creators:
- expert-generated
language_creators:
- expert-generated
language:
- tr
license:
- other
multilinguality:
- monolingual
size_categories:
- 10K<n<100K
source_datasets:
- original
task_categories:
- text-classification
task_ids:
- sentiment-classification
paperswithcode... |
Subsets and Splits
No community queries yet
The top public SQL queries from the community will appear here once available.