
url stringlengths 61 61 | repository_url stringclasses 1
value | labels_url stringlengths 75 75 | comments_url stringlengths 70 70 | events_url stringlengths 68 68 | html_url stringlengths 49 51 | id int64 1.1B 5.46B | node_id stringlengths 18 25 | number int64 3.55k 8.62k | title stringlengths 1 290 | user dict | labels listlengths 0 4 | state stringclasses 2
values | locked bool 1
class | assignees listlengths 0 4 | milestone dict | comments int64 0 49 | created_at timestamp[ms]date 2022-01-10 10:32:04 2026-09-14 22:10:44 | updated_at timestamp[ms]date 2022-01-11 14:16:47 2026-09-15 02:20:24 | closed_at timestamp[ms]date 2022-01-11 14:16:47 2026-09-14 22:11:06 ⌀ | assignee dict | author_association stringclasses 4
values | issue_field_values listlengths 0 0 | type null | active_lock_reason null | draft bool 2
classes | pull_request dict | body stringlengths 1 58.6k ⌀ | closed_by dict | reactions dict | timeline_url stringlengths 70 70 | performed_via_github_app null | state_reason stringclasses 4
values | sub_issues_summary dict | issue_dependencies_summary dict | pinned_comment null | is_pull_request bool 2
classes |
|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|
https://api.github.com/repos/huggingface/datasets/issues/7469 | https://api.github.com/repos/huggingface/datasets | https://api.github.com/repos/huggingface/datasets/issues/7469/labels{/name} | https://api.github.com/repos/huggingface/datasets/issues/7469/comments | https://api.github.com/repos/huggingface/datasets/issues/7469/events | https://github.com/huggingface/datasets/issues/7469 | 2,936,606,080 | I_kwDODunzps6vCQ2A | 7,469 | Custom split name with the web interface | {
"login": "vince62s",
"id": 15141326,
"node_id": "MDQ6VXNlcjE1MTQxMzI2",
"avatar_url": "https://avatars.githubusercontent.com/u/15141326?v=4",
"gravatar_id": "",
"url": "https://api.github.com/users/vince62s",
"html_url": "https://github.com/vince62s",
"followers_url": "https://api.github.com/users/vin... | [] | closed | false | [] | null | 0 | 2025-03-20T20:45:59 | 2025-03-21T07:20:37 | 2025-03-21T07:20:37 | null | NONE | [] | null | null | null | null | ### Describe the bug
According the doc here: https://huggingface.co/docs/hub/datasets-file-names-and-splits#custom-split-name
it should infer the split name from the subdir of data or the beg of the name of the files in data.
When doing this manually through web upload it does not work. it uses "train" as a unique spl... | {
"login": "vince62s",
"id": 15141326,
"node_id": "MDQ6VXNlcjE1MTQxMzI2",
"avatar_url": "https://avatars.githubusercontent.com/u/15141326?v=4",
"gravatar_id": "",
"url": "https://api.github.com/users/vince62s",
"html_url": "https://github.com/vince62s",
"followers_url": "https://api.github.com/users/vin... | {
"url": "https://api.github.com/repos/huggingface/datasets/issues/7469/reactions",
"total_count": 0,
"+1": 0,
"-1": 0,
"laugh": 0,
"hooray": 0,
"confused": 0,
"heart": 0,
"rocket": 0,
"eyes": 0
} | https://api.github.com/repos/huggingface/datasets/issues/7469/timeline | null | completed | {
"total": 0,
"completed": 0,
"percent_completed": 0
} | {
"blocked_by": 0,
"total_blocked_by": 0,
"blocking": 0,
"total_blocking": 0
} | null | false |
https://api.github.com/repos/huggingface/datasets/issues/7468 | https://api.github.com/repos/huggingface/datasets | https://api.github.com/repos/huggingface/datasets/issues/7468/labels{/name} | https://api.github.com/repos/huggingface/datasets/issues/7468/comments | https://api.github.com/repos/huggingface/datasets/issues/7468/events | https://github.com/huggingface/datasets/issues/7468 | 2,934,094,103 | I_kwDODunzps6u4rkX | 7,468 | function `load_dataset` can't solve folder path with regex characters like "[]" | {
"login": "Hpeox",
"id": 89294013,
"node_id": "MDQ6VXNlcjg5Mjk0MDEz",
"avatar_url": "https://avatars.githubusercontent.com/u/89294013?v=4",
"gravatar_id": "",
"url": "https://api.github.com/users/Hpeox",
"html_url": "https://github.com/Hpeox",
"followers_url": "https://api.github.com/users/Hpeox/follow... | [] | open | false | [] | null | 1 | 2025-03-20T05:21:59 | 2025-03-25T10:18:12 | null | null | NONE | [] | null | null | null | null | ### Describe the bug
When using the `load_dataset` function with a folder path containing regex special characters (such as "[]"), the issue occurs due to how the path is handled in the `resolve_pattern` function. This function passes the unprocessed path directly to `AbstractFileSystem.glob`, which supports regular e... | null | {
"url": "https://api.github.com/repos/huggingface/datasets/issues/7468/reactions",
"total_count": 0,
"+1": 0,
"-1": 0,
"laugh": 0,
"hooray": 0,
"confused": 0,
"heart": 0,
"rocket": 0,
"eyes": 0
} | https://api.github.com/repos/huggingface/datasets/issues/7468/timeline | null | null | {
"total": 0,
"completed": 0,
"percent_completed": 0
} | {
"blocked_by": 0,
"total_blocked_by": 0,
"blocking": 0,
"total_blocking": 0
} | null | false |
https://api.github.com/repos/huggingface/datasets/issues/7467 | https://api.github.com/repos/huggingface/datasets | https://api.github.com/repos/huggingface/datasets/issues/7467/labels{/name} | https://api.github.com/repos/huggingface/datasets/issues/7467/comments | https://api.github.com/repos/huggingface/datasets/issues/7467/events | https://github.com/huggingface/datasets/issues/7467 | 2,930,067,107 | I_kwDODunzps6upUaj | 7,467 | load_dataset with streaming hangs on parquet datasets | {
"login": "The0nix",
"id": 10550252,
"node_id": "MDQ6VXNlcjEwNTUwMjUy",
"avatar_url": "https://avatars.githubusercontent.com/u/10550252?v=4",
"gravatar_id": "",
"url": "https://api.github.com/users/The0nix",
"html_url": "https://github.com/The0nix",
"followers_url": "https://api.github.com/users/The0ni... | [] | closed | false | [] | null | 2 | 2025-03-18T23:33:54 | 2026-05-06T16:07:14 | 2026-05-06T16:06:09 | null | NONE | [] | null | null | null | null | ### Describe the bug
When I try to load a dataset with parquet files (e.g. "bigcode/the-stack") the dataset loads, but python interpreter can't exit and hangs
### Steps to reproduce the bug
```python3
import datasets
print('Start')
dataset = datasets.load_dataset("bigcode/the-stack", data_dir="data/yaml", streaming... | {
"login": "lhoestq",
"id": 42851186,
"node_id": "MDQ6VXNlcjQyODUxMTg2",
"avatar_url": "https://avatars.githubusercontent.com/u/42851186?v=4",
"gravatar_id": "",
"url": "https://api.github.com/users/lhoestq",
"html_url": "https://github.com/lhoestq",
"followers_url": "https://api.github.com/users/lhoest... | {
"url": "https://api.github.com/repos/huggingface/datasets/issues/7467/reactions",
"total_count": 1,
"+1": 1,
"-1": 0,
"laugh": 0,
"hooray": 0,
"confused": 0,
"heart": 0,
"rocket": 0,
"eyes": 0
} | https://api.github.com/repos/huggingface/datasets/issues/7467/timeline | null | completed | {
"total": 0,
"completed": 0,
"percent_completed": 0
} | {
"blocked_by": 0,
"total_blocked_by": 0,
"blocking": 0,
"total_blocking": 0
} | null | false |
https://api.github.com/repos/huggingface/datasets/issues/7466 | https://api.github.com/repos/huggingface/datasets | https://api.github.com/repos/huggingface/datasets/issues/7466/labels{/name} | https://api.github.com/repos/huggingface/datasets/issues/7466/comments | https://api.github.com/repos/huggingface/datasets/issues/7466/events | https://github.com/huggingface/datasets/pull/7466 | 2,928,661,327 | PR_kwDODunzps6PHQyp | 7,466 | Fix local pdf loading | {
"login": "lhoestq",
"id": 42851186,
"node_id": "MDQ6VXNlcjQyODUxMTg2",
"avatar_url": "https://avatars.githubusercontent.com/u/42851186?v=4",
"gravatar_id": "",
"url": "https://api.github.com/users/lhoestq",
"html_url": "https://github.com/lhoestq",
"followers_url": "https://api.github.com/users/lhoest... | [] | closed | false | [] | null | 1 | 2025-03-18T14:09:06 | 2025-03-18T14:11:52 | 2025-03-18T14:09:21 | null | MEMBER | [] | null | null | false | {
"url": "https://api.github.com/repos/huggingface/datasets/pulls/7466",
"html_url": "https://github.com/huggingface/datasets/pull/7466",
"diff_url": "https://github.com/huggingface/datasets/pull/7466.diff",
"patch_url": "https://github.com/huggingface/datasets/pull/7466.patch",
"merged_at": "2025-03-18T14:09... | fir this error when accessing a local pdf
```
File ~/.pyenv/versions/3.12.2/envs/hf-datasets/lib/python3.12/site-packages/pdfminer/psparser.py:220, in PSBaseParser.seek(self, pos)
218 """Seeks the parser to the given position."""
219 log.debug("seek: %r", pos)
--> 220 self.fp.seek(pos)
221 # reset t... | {
"login": "lhoestq",
"id": 42851186,
"node_id": "MDQ6VXNlcjQyODUxMTg2",
"avatar_url": "https://avatars.githubusercontent.com/u/42851186?v=4",
"gravatar_id": "",
"url": "https://api.github.com/users/lhoestq",
"html_url": "https://github.com/lhoestq",
"followers_url": "https://api.github.com/users/lhoest... | {
"url": "https://api.github.com/repos/huggingface/datasets/issues/7466/reactions",
"total_count": 0,
"+1": 0,
"-1": 0,
"laugh": 0,
"hooray": 0,
"confused": 0,
"heart": 0,
"rocket": 0,
"eyes": 0
} | https://api.github.com/repos/huggingface/datasets/issues/7466/timeline | null | null | null | null | null | true |
https://api.github.com/repos/huggingface/datasets/issues/7464 | https://api.github.com/repos/huggingface/datasets | https://api.github.com/repos/huggingface/datasets/issues/7464/labels{/name} | https://api.github.com/repos/huggingface/datasets/issues/7464/comments | https://api.github.com/repos/huggingface/datasets/issues/7464/events | https://github.com/huggingface/datasets/pull/7464 | 2,926,478,838 | PR_kwDODunzps6PABJa | 7,464 | Minor fix for metadata files in extension counter | {
"login": "lhoestq",
"id": 42851186,
"node_id": "MDQ6VXNlcjQyODUxMTg2",
"avatar_url": "https://avatars.githubusercontent.com/u/42851186?v=4",
"gravatar_id": "",
"url": "https://api.github.com/users/lhoestq",
"html_url": "https://github.com/lhoestq",
"followers_url": "https://api.github.com/users/lhoest... | [] | closed | false | [] | null | 1 | 2025-03-17T21:57:11 | 2025-03-18T15:21:43 | 2025-03-18T15:21:41 | null | MEMBER | [] | null | null | false | {
"url": "https://api.github.com/repos/huggingface/datasets/pulls/7464",
"html_url": "https://github.com/huggingface/datasets/pull/7464",
"diff_url": "https://github.com/huggingface/datasets/pull/7464.diff",
"patch_url": "https://github.com/huggingface/datasets/pull/7464.patch",
"merged_at": "2025-03-18T15:21... | null | {
"login": "lhoestq",
"id": 42851186,
"node_id": "MDQ6VXNlcjQyODUxMTg2",
"avatar_url": "https://avatars.githubusercontent.com/u/42851186?v=4",
"gravatar_id": "",
"url": "https://api.github.com/users/lhoestq",
"html_url": "https://github.com/lhoestq",
"followers_url": "https://api.github.com/users/lhoest... | {
"url": "https://api.github.com/repos/huggingface/datasets/issues/7464/reactions",
"total_count": 0,
"+1": 0,
"-1": 0,
"laugh": 0,
"hooray": 0,
"confused": 0,
"heart": 0,
"rocket": 0,
"eyes": 0
} | https://api.github.com/repos/huggingface/datasets/issues/7464/timeline | null | null | null | null | null | true |
https://api.github.com/repos/huggingface/datasets/issues/7463 | https://api.github.com/repos/huggingface/datasets | https://api.github.com/repos/huggingface/datasets/issues/7463/labels{/name} | https://api.github.com/repos/huggingface/datasets/issues/7463/comments | https://api.github.com/repos/huggingface/datasets/issues/7463/events | https://github.com/huggingface/datasets/pull/7463 | 2,925,924,452 | PR_kwDODunzps6O-I6K | 7,463 | Adds EXR format to store depth images in float32 | {
"login": "ducha-aiki",
"id": 4803565,
"node_id": "MDQ6VXNlcjQ4MDM1NjU=",
"avatar_url": "https://avatars.githubusercontent.com/u/4803565?v=4",
"gravatar_id": "",
"url": "https://api.github.com/users/ducha-aiki",
"html_url": "https://github.com/ducha-aiki",
"followers_url": "https://api.github.com/users... | [] | open | false | [] | null | 3 | 2025-03-17T17:42:40 | 2025-11-13T13:09:01 | null | null | NONE | [] | null | null | false | {
"url": "https://api.github.com/repos/huggingface/datasets/pulls/7463",
"html_url": "https://github.com/huggingface/datasets/pull/7463",
"diff_url": "https://github.com/huggingface/datasets/pull/7463.diff",
"patch_url": "https://github.com/huggingface/datasets/pull/7463.patch",
"merged_at": null
} | This PR adds the EXR feature to store depth images (or can be normals, etc) in float32.
It relies on [openexr_numpy](https://github.com/martinResearch/openexr_numpy/tree/main) to manipulate EXR images.
| null | {
"url": "https://api.github.com/repos/huggingface/datasets/issues/7463/reactions",
"total_count": 0,
"+1": 0,
"-1": 0,
"laugh": 0,
"hooray": 0,
"confused": 0,
"heart": 0,
"rocket": 0,
"eyes": 0
} | https://api.github.com/repos/huggingface/datasets/issues/7463/timeline | null | null | null | null | null | true |
https://api.github.com/repos/huggingface/datasets/issues/7462 | https://api.github.com/repos/huggingface/datasets | https://api.github.com/repos/huggingface/datasets/issues/7462/labels{/name} | https://api.github.com/repos/huggingface/datasets/issues/7462/comments | https://api.github.com/repos/huggingface/datasets/issues/7462/events | https://github.com/huggingface/datasets/pull/7462 | 2,925,612,945 | PR_kwDODunzps6O9EA1 | 7,462 | set dev version | {
"login": "lhoestq",
"id": 42851186,
"node_id": "MDQ6VXNlcjQyODUxMTg2",
"avatar_url": "https://avatars.githubusercontent.com/u/42851186?v=4",
"gravatar_id": "",
"url": "https://api.github.com/users/lhoestq",
"html_url": "https://github.com/lhoestq",
"followers_url": "https://api.github.com/users/lhoest... | [] | closed | false | [] | null | 1 | 2025-03-17T16:00:53 | 2025-03-17T16:03:31 | 2025-03-17T16:01:08 | null | MEMBER | [] | null | null | false | {
"url": "https://api.github.com/repos/huggingface/datasets/pulls/7462",
"html_url": "https://github.com/huggingface/datasets/pull/7462",
"diff_url": "https://github.com/huggingface/datasets/pull/7462.diff",
"patch_url": "https://github.com/huggingface/datasets/pull/7462.patch",
"merged_at": "2025-03-17T16:01... | null | {
"login": "lhoestq",
"id": 42851186,
"node_id": "MDQ6VXNlcjQyODUxMTg2",
"avatar_url": "https://avatars.githubusercontent.com/u/42851186?v=4",
"gravatar_id": "",
"url": "https://api.github.com/users/lhoestq",
"html_url": "https://github.com/lhoestq",
"followers_url": "https://api.github.com/users/lhoest... | {
"url": "https://api.github.com/repos/huggingface/datasets/issues/7462/reactions",
"total_count": 0,
"+1": 0,
"-1": 0,
"laugh": 0,
"hooray": 0,
"confused": 0,
"heart": 0,
"rocket": 0,
"eyes": 0
} | https://api.github.com/repos/huggingface/datasets/issues/7462/timeline | null | null | null | null | null | true |
https://api.github.com/repos/huggingface/datasets/issues/7461 | https://api.github.com/repos/huggingface/datasets | https://api.github.com/repos/huggingface/datasets/issues/7461/labels{/name} | https://api.github.com/repos/huggingface/datasets/issues/7461/comments | https://api.github.com/repos/huggingface/datasets/issues/7461/events | https://github.com/huggingface/datasets/issues/7461 | 2,925,608,123 | I_kwDODunzps6uYTy7 | 7,461 | List of images behave differently on IterableDataset and Dataset | {
"login": "FredrikNoren",
"id": 1288009,
"node_id": "MDQ6VXNlcjEyODgwMDk=",
"avatar_url": "https://avatars.githubusercontent.com/u/1288009?v=4",
"gravatar_id": "",
"url": "https://api.github.com/users/FredrikNoren",
"html_url": "https://github.com/FredrikNoren",
"followers_url": "https://api.github.com... | [] | closed | false | [] | null | 2 | 2025-03-17T15:59:23 | 2025-03-18T08:57:17 | 2025-03-18T08:57:16 | null | NONE | [] | null | null | null | null | ### Describe the bug
This code:
```python
def train_iterable_gen():
images = np.array(load_image("https://cdn.britannica.com/61/93061-050-99147DCE/Statue-of-Liberty-Island-New-York-Bay.jpg").resize((128, 128)))
yield {
"images": np.expand_dims(images, axis=0),
"messages": [
... | {
"login": "FredrikNoren",
"id": 1288009,
"node_id": "MDQ6VXNlcjEyODgwMDk=",
"avatar_url": "https://avatars.githubusercontent.com/u/1288009?v=4",
"gravatar_id": "",
"url": "https://api.github.com/users/FredrikNoren",
"html_url": "https://github.com/FredrikNoren",
"followers_url": "https://api.github.com... | {
"url": "https://api.github.com/repos/huggingface/datasets/issues/7461/reactions",
"total_count": 0,
"+1": 0,
"-1": 0,
"laugh": 0,
"hooray": 0,
"confused": 0,
"heart": 0,
"rocket": 0,
"eyes": 0
} | https://api.github.com/repos/huggingface/datasets/issues/7461/timeline | null | completed | {
"total": 0,
"completed": 0,
"percent_completed": 0
} | {
"blocked_by": 0,
"total_blocked_by": 0,
"blocking": 0,
"total_blocking": 0
} | null | false |
https://api.github.com/repos/huggingface/datasets/issues/7460 | https://api.github.com/repos/huggingface/datasets | https://api.github.com/repos/huggingface/datasets/issues/7460/labels{/name} | https://api.github.com/repos/huggingface/datasets/issues/7460/comments | https://api.github.com/repos/huggingface/datasets/issues/7460/events | https://github.com/huggingface/datasets/pull/7460 | 2,925,605,865 | PR_kwDODunzps6O9Ccc | 7,460 | release: 3.4.1 | {
"login": "lhoestq",
"id": 42851186,
"node_id": "MDQ6VXNlcjQyODUxMTg2",
"avatar_url": "https://avatars.githubusercontent.com/u/42851186?v=4",
"gravatar_id": "",
"url": "https://api.github.com/users/lhoestq",
"html_url": "https://github.com/lhoestq",
"followers_url": "https://api.github.com/users/lhoest... | [] | closed | false | [] | null | 1 | 2025-03-17T15:58:31 | 2025-03-17T16:01:14 | 2025-03-17T15:59:19 | null | MEMBER | [] | null | null | false | {
"url": "https://api.github.com/repos/huggingface/datasets/pulls/7460",
"html_url": "https://github.com/huggingface/datasets/pull/7460",
"diff_url": "https://github.com/huggingface/datasets/pull/7460.diff",
"patch_url": "https://github.com/huggingface/datasets/pull/7460.patch",
"merged_at": "2025-03-17T15:59... | null | {
"login": "lhoestq",
"id": 42851186,
"node_id": "MDQ6VXNlcjQyODUxMTg2",
"avatar_url": "https://avatars.githubusercontent.com/u/42851186?v=4",
"gravatar_id": "",
"url": "https://api.github.com/users/lhoestq",
"html_url": "https://github.com/lhoestq",
"followers_url": "https://api.github.com/users/lhoest... | {
"url": "https://api.github.com/repos/huggingface/datasets/issues/7460/reactions",
"total_count": 0,
"+1": 0,
"-1": 0,
"laugh": 0,
"hooray": 0,
"confused": 0,
"heart": 0,
"rocket": 0,
"eyes": 0
} | https://api.github.com/repos/huggingface/datasets/issues/7460/timeline | null | null | null | null | null | true |
https://api.github.com/repos/huggingface/datasets/issues/7459 | https://api.github.com/repos/huggingface/datasets | https://api.github.com/repos/huggingface/datasets/issues/7459/labels{/name} | https://api.github.com/repos/huggingface/datasets/issues/7459/comments | https://api.github.com/repos/huggingface/datasets/issues/7459/events | https://github.com/huggingface/datasets/pull/7459 | 2,925,491,766 | PR_kwDODunzps6O8pWp | 7,459 | Fix data_files filtering | {
"login": "lhoestq",
"id": 42851186,
"node_id": "MDQ6VXNlcjQyODUxMTg2",
"avatar_url": "https://avatars.githubusercontent.com/u/42851186?v=4",
"gravatar_id": "",
"url": "https://api.github.com/users/lhoestq",
"html_url": "https://github.com/lhoestq",
"followers_url": "https://api.github.com/users/lhoest... | [] | closed | false | [] | null | 1 | 2025-03-17T15:20:21 | 2025-03-17T15:25:56 | 2025-03-17T15:25:54 | null | MEMBER | [] | null | null | false | {
"url": "https://api.github.com/repos/huggingface/datasets/pulls/7459",
"html_url": "https://github.com/huggingface/datasets/pull/7459",
"diff_url": "https://github.com/huggingface/datasets/pull/7459.diff",
"patch_url": "https://github.com/huggingface/datasets/pull/7459.patch",
"merged_at": "2025-03-17T15:25... | close https://github.com/huggingface/datasets/issues/7458 | {
"login": "lhoestq",
"id": 42851186,
"node_id": "MDQ6VXNlcjQyODUxMTg2",
"avatar_url": "https://avatars.githubusercontent.com/u/42851186?v=4",
"gravatar_id": "",
"url": "https://api.github.com/users/lhoestq",
"html_url": "https://github.com/lhoestq",
"followers_url": "https://api.github.com/users/lhoest... | {
"url": "https://api.github.com/repos/huggingface/datasets/issues/7459/reactions",
"total_count": 1,
"+1": 1,
"-1": 0,
"laugh": 0,
"hooray": 0,
"confused": 0,
"heart": 0,
"rocket": 0,
"eyes": 0
} | https://api.github.com/repos/huggingface/datasets/issues/7459/timeline | null | null | null | null | null | true |
https://api.github.com/repos/huggingface/datasets/issues/7458 | https://api.github.com/repos/huggingface/datasets | https://api.github.com/repos/huggingface/datasets/issues/7458/labels{/name} | https://api.github.com/repos/huggingface/datasets/issues/7458/comments | https://api.github.com/repos/huggingface/datasets/issues/7458/events | https://github.com/huggingface/datasets/issues/7458 | 2,925,403,528 | I_kwDODunzps6uXh2I | 7,458 | Loading the `laion/filtered-wit` dataset in streaming mode fails on v3.4.0 | {
"login": "nikita-savelyevv",
"id": 23343961,
"node_id": "MDQ6VXNlcjIzMzQzOTYx",
"avatar_url": "https://avatars.githubusercontent.com/u/23343961?v=4",
"gravatar_id": "",
"url": "https://api.github.com/users/nikita-savelyevv",
"html_url": "https://github.com/nikita-savelyevv",
"followers_url": "https://... | [] | closed | false | [
{
"login": "lhoestq",
"id": 42851186,
"node_id": "MDQ6VXNlcjQyODUxMTg2",
"avatar_url": "https://avatars.githubusercontent.com/u/42851186?v=4",
"gravatar_id": "",
"url": "https://api.github.com/users/lhoestq",
"html_url": "https://github.com/lhoestq",
"followers_url": "https://api.git... | null | 1 | 2025-03-17T14:54:02 | 2025-03-17T16:02:04 | 2025-03-17T15:25:55 | {
"login": "lhoestq",
"id": 42851186,
"node_id": "MDQ6VXNlcjQyODUxMTg2",
"avatar_url": "https://avatars.githubusercontent.com/u/42851186?v=4",
"gravatar_id": "",
"url": "https://api.github.com/users/lhoestq",
"html_url": "https://github.com/lhoestq",
"followers_url": "https://api.github.com/users/lhoest... | NONE | [] | null | null | null | null | ### Describe the bug
Loading https://huggingface.co/datasets/laion/filtered-wit in streaming mode fails after update to `datasets==3.4.0`. The dataset loads fine on v3.3.2.
### Steps to reproduce the bug
Steps to reproduce:
```
pip install datastes==3.4.0
python -c "from datasets import load_dataset; load_dataset('l... | {
"login": "lhoestq",
"id": 42851186,
"node_id": "MDQ6VXNlcjQyODUxMTg2",
"avatar_url": "https://avatars.githubusercontent.com/u/42851186?v=4",
"gravatar_id": "",
"url": "https://api.github.com/users/lhoestq",
"html_url": "https://github.com/lhoestq",
"followers_url": "https://api.github.com/users/lhoest... | {
"url": "https://api.github.com/repos/huggingface/datasets/issues/7458/reactions",
"total_count": 0,
"+1": 0,
"-1": 0,
"laugh": 0,
"hooray": 0,
"confused": 0,
"heart": 0,
"rocket": 0,
"eyes": 0
} | https://api.github.com/repos/huggingface/datasets/issues/7458/timeline | null | completed | {
"total": 0,
"completed": 0,
"percent_completed": 0
} | {
"blocked_by": 0,
"total_blocked_by": 0,
"blocking": 0,
"total_blocking": 0
} | null | false |
https://api.github.com/repos/huggingface/datasets/issues/7457 | https://api.github.com/repos/huggingface/datasets | https://api.github.com/repos/huggingface/datasets/issues/7457/labels{/name} | https://api.github.com/repos/huggingface/datasets/issues/7457/comments | https://api.github.com/repos/huggingface/datasets/issues/7457/events | https://github.com/huggingface/datasets/issues/7457 | 2,924,886,467 | I_kwDODunzps6uVjnD | 7,457 | Document the HF_DATASETS_CACHE env variable | {
"login": "LSerranoPEReN",
"id": 92166725,
"node_id": "U_kgDOBX5aRQ",
"avatar_url": "https://avatars.githubusercontent.com/u/92166725?v=4",
"gravatar_id": "",
"url": "https://api.github.com/users/LSerranoPEReN",
"html_url": "https://github.com/LSerranoPEReN",
"followers_url": "https://api.github.com/us... | [
{
"id": 1935892871,
"node_id": "MDU6TGFiZWwxOTM1ODkyODcx",
"url": "https://api.github.com/repos/huggingface/datasets/labels/enhancement",
"name": "enhancement",
"color": "a2eeef",
"default": true,
"description": "New feature or request",
"archived_at": null,
"archived_by": null
... | closed | false | [
{
"login": "Harry-Yang0518",
"id": 129883215,
"node_id": "U_kgDOB73cTw",
"avatar_url": "https://avatars.githubusercontent.com/u/129883215?v=4",
"gravatar_id": "",
"url": "https://api.github.com/users/Harry-Yang0518",
"html_url": "https://github.com/Harry-Yang0518",
"followers_url": "... | null | 4 | 2025-03-17T12:24:50 | 2025-05-06T15:54:39 | 2025-05-06T15:54:39 | {
"login": "Harry-Yang0518",
"id": 129883215,
"node_id": "U_kgDOB73cTw",
"avatar_url": "https://avatars.githubusercontent.com/u/129883215?v=4",
"gravatar_id": "",
"url": "https://api.github.com/users/Harry-Yang0518",
"html_url": "https://github.com/Harry-Yang0518",
"followers_url": "https://api.github.c... | NONE | [] | null | null | null | null | ### Feature request
Hello,
I have a use case where my team is sharing models and dataset in shared directory to avoid duplication.
I noticed that the [cache documentation for datasets](https://huggingface.co/docs/datasets/main/en/cache) only mention the `HF_HOME` environment variable but never the `HF_DATASETS_CACHE`... | {
"login": "lhoestq",
"id": 42851186,
"node_id": "MDQ6VXNlcjQyODUxMTg2",
"avatar_url": "https://avatars.githubusercontent.com/u/42851186?v=4",
"gravatar_id": "",
"url": "https://api.github.com/users/lhoestq",
"html_url": "https://github.com/lhoestq",
"followers_url": "https://api.github.com/users/lhoest... | {
"url": "https://api.github.com/repos/huggingface/datasets/issues/7457/reactions",
"total_count": 0,
"+1": 0,
"-1": 0,
"laugh": 0,
"hooray": 0,
"confused": 0,
"heart": 0,
"rocket": 0,
"eyes": 0
} | https://api.github.com/repos/huggingface/datasets/issues/7457/timeline | null | completed | {
"total": 0,
"completed": 0,
"percent_completed": 0
} | {
"blocked_by": 0,
"total_blocked_by": 0,
"blocking": 0,
"total_blocking": 0
} | null | false |
https://api.github.com/repos/huggingface/datasets/issues/7456 | https://api.github.com/repos/huggingface/datasets | https://api.github.com/repos/huggingface/datasets/issues/7456/labels{/name} | https://api.github.com/repos/huggingface/datasets/issues/7456/comments | https://api.github.com/repos/huggingface/datasets/issues/7456/events | https://github.com/huggingface/datasets/issues/7456 | 2,922,676,278 | I_kwDODunzps6uNIA2 | 7,456 | .add_faiss_index and .add_elasticsearch_index returns ImportError at Google Colab | {
"login": "MapleBloom",
"id": 109490785,
"node_id": "U_kgDOBoayYQ",
"avatar_url": "https://avatars.githubusercontent.com/u/109490785?v=4",
"gravatar_id": "",
"url": "https://api.github.com/users/MapleBloom",
"html_url": "https://github.com/MapleBloom",
"followers_url": "https://api.github.com/users/Map... | [] | open | false | [] | null | 6 | 2025-03-16T00:51:49 | 2025-03-17T15:57:19 | null | null | NONE | [] | null | null | null | null | ### Describe the bug
At Google Colab
```!pip install faiss-cpu``` works
```import faiss``` no error
but
```embeddings_dataset.add_faiss_index(column='embeddings')```
returns
```
[/usr/local/lib/python3.11/dist-packages/datasets/search.py](https://localhost:8080/#) in init(self, device, string_factory, metric_type, cus... | null | {
"url": "https://api.github.com/repos/huggingface/datasets/issues/7456/reactions",
"total_count": 0,
"+1": 0,
"-1": 0,
"laugh": 0,
"hooray": 0,
"confused": 0,
"heart": 0,
"rocket": 0,
"eyes": 0
} | https://api.github.com/repos/huggingface/datasets/issues/7456/timeline | null | null | {
"total": 0,
"completed": 0,
"percent_completed": 0
} | {
"blocked_by": 0,
"total_blocked_by": 0,
"blocking": 0,
"total_blocking": 0
} | null | false |
https://api.github.com/repos/huggingface/datasets/issues/7455 | https://api.github.com/repos/huggingface/datasets | https://api.github.com/repos/huggingface/datasets/issues/7455/labels{/name} | https://api.github.com/repos/huggingface/datasets/issues/7455/comments | https://api.github.com/repos/huggingface/datasets/issues/7455/events | https://github.com/huggingface/datasets/issues/7455 | 2,921,933,250 | I_kwDODunzps6uKSnC | 7,455 | Problems with local dataset after upgrade from 3.3.2 to 3.4.0 | {
"login": "andjoer",
"id": 60151338,
"node_id": "MDQ6VXNlcjYwMTUxMzM4",
"avatar_url": "https://avatars.githubusercontent.com/u/60151338?v=4",
"gravatar_id": "",
"url": "https://api.github.com/users/andjoer",
"html_url": "https://github.com/andjoer",
"followers_url": "https://api.github.com/users/andjoe... | [] | open | false | [] | null | 1 | 2025-03-15T09:22:50 | 2025-03-17T16:20:43 | null | null | NONE | [] | null | null | null | null | ### Describe the bug
I was not able to open a local saved dataset anymore that was created using an older datasets version after the upgrade yesterday from datasets 3.3.2 to 3.4.0
The traceback is
```
Traceback (most recent call last):
File "/usr/local/lib/python3.10/dist-packages/datasets/packaged_modules/arrow/... | null | {
"url": "https://api.github.com/repos/huggingface/datasets/issues/7455/reactions",
"total_count": 0,
"+1": 0,
"-1": 0,
"laugh": 0,
"hooray": 0,
"confused": 0,
"heart": 0,
"rocket": 0,
"eyes": 0
} | https://api.github.com/repos/huggingface/datasets/issues/7455/timeline | null | null | {
"total": 0,
"completed": 0,
"percent_completed": 0
} | {
"blocked_by": 0,
"total_blocked_by": 0,
"blocking": 0,
"total_blocking": 0
} | null | false |
https://api.github.com/repos/huggingface/datasets/issues/7454 | https://api.github.com/repos/huggingface/datasets | https://api.github.com/repos/huggingface/datasets/issues/7454/labels{/name} | https://api.github.com/repos/huggingface/datasets/issues/7454/comments | https://api.github.com/repos/huggingface/datasets/issues/7454/events | https://github.com/huggingface/datasets/pull/7454 | 2,920,760,793 | PR_kwDODunzps6Os6bx | 7,454 | set dev version | {
"login": "lhoestq",
"id": 42851186,
"node_id": "MDQ6VXNlcjQyODUxMTg2",
"avatar_url": "https://avatars.githubusercontent.com/u/42851186?v=4",
"gravatar_id": "",
"url": "https://api.github.com/users/lhoestq",
"html_url": "https://github.com/lhoestq",
"followers_url": "https://api.github.com/users/lhoest... | [] | closed | false | [] | null | 1 | 2025-03-14T16:48:19 | 2025-03-14T16:50:31 | 2025-03-14T16:48:28 | null | MEMBER | [] | null | null | false | {
"url": "https://api.github.com/repos/huggingface/datasets/pulls/7454",
"html_url": "https://github.com/huggingface/datasets/pull/7454",
"diff_url": "https://github.com/huggingface/datasets/pull/7454.diff",
"patch_url": "https://github.com/huggingface/datasets/pull/7454.patch",
"merged_at": "2025-03-14T16:48... | null | {
"login": "lhoestq",
"id": 42851186,
"node_id": "MDQ6VXNlcjQyODUxMTg2",
"avatar_url": "https://avatars.githubusercontent.com/u/42851186?v=4",
"gravatar_id": "",
"url": "https://api.github.com/users/lhoestq",
"html_url": "https://github.com/lhoestq",
"followers_url": "https://api.github.com/users/lhoest... | {
"url": "https://api.github.com/repos/huggingface/datasets/issues/7454/reactions",
"total_count": 0,
"+1": 0,
"-1": 0,
"laugh": 0,
"hooray": 0,
"confused": 0,
"heart": 0,
"rocket": 0,
"eyes": 0
} | https://api.github.com/repos/huggingface/datasets/issues/7454/timeline | null | null | null | null | null | true |
https://api.github.com/repos/huggingface/datasets/issues/7453 | https://api.github.com/repos/huggingface/datasets | https://api.github.com/repos/huggingface/datasets/issues/7453/labels{/name} | https://api.github.com/repos/huggingface/datasets/issues/7453/comments | https://api.github.com/repos/huggingface/datasets/issues/7453/events | https://github.com/huggingface/datasets/pull/7453 | 2,920,719,503 | PR_kwDODunzps6OsxR1 | 7,453 | release: 3.4.0 | {
"login": "lhoestq",
"id": 42851186,
"node_id": "MDQ6VXNlcjQyODUxMTg2",
"avatar_url": "https://avatars.githubusercontent.com/u/42851186?v=4",
"gravatar_id": "",
"url": "https://api.github.com/users/lhoestq",
"html_url": "https://github.com/lhoestq",
"followers_url": "https://api.github.com/users/lhoest... | [] | closed | false | [] | null | 1 | 2025-03-14T16:30:45 | 2025-03-14T16:38:10 | 2025-03-14T16:38:08 | null | MEMBER | [] | null | null | false | {
"url": "https://api.github.com/repos/huggingface/datasets/pulls/7453",
"html_url": "https://github.com/huggingface/datasets/pull/7453",
"diff_url": "https://github.com/huggingface/datasets/pull/7453.diff",
"patch_url": "https://github.com/huggingface/datasets/pull/7453.patch",
"merged_at": "2025-03-14T16:38... | null | {
"login": "lhoestq",
"id": 42851186,
"node_id": "MDQ6VXNlcjQyODUxMTg2",
"avatar_url": "https://avatars.githubusercontent.com/u/42851186?v=4",
"gravatar_id": "",
"url": "https://api.github.com/users/lhoestq",
"html_url": "https://github.com/lhoestq",
"followers_url": "https://api.github.com/users/lhoest... | {
"url": "https://api.github.com/repos/huggingface/datasets/issues/7453/reactions",
"total_count": 0,
"+1": 0,
"-1": 0,
"laugh": 0,
"hooray": 0,
"confused": 0,
"heart": 0,
"rocket": 0,
"eyes": 0
} | https://api.github.com/repos/huggingface/datasets/issues/7453/timeline | null | null | null | null | null | true |
https://api.github.com/repos/huggingface/datasets/issues/7452 | https://api.github.com/repos/huggingface/datasets | https://api.github.com/repos/huggingface/datasets/issues/7452/labels{/name} | https://api.github.com/repos/huggingface/datasets/issues/7452/comments | https://api.github.com/repos/huggingface/datasets/issues/7452/events | https://github.com/huggingface/datasets/pull/7452 | 2,920,354,783 | PR_kwDODunzps6Orhw4 | 7,452 | minor docs changes | {
"login": "lhoestq",
"id": 42851186,
"node_id": "MDQ6VXNlcjQyODUxMTg2",
"avatar_url": "https://avatars.githubusercontent.com/u/42851186?v=4",
"gravatar_id": "",
"url": "https://api.github.com/users/lhoestq",
"html_url": "https://github.com/lhoestq",
"followers_url": "https://api.github.com/users/lhoest... | [] | closed | false | [] | null | 1 | 2025-03-14T14:14:04 | 2025-03-14T14:16:38 | 2025-03-14T14:14:20 | null | MEMBER | [] | null | null | false | {
"url": "https://api.github.com/repos/huggingface/datasets/pulls/7452",
"html_url": "https://github.com/huggingface/datasets/pull/7452",
"diff_url": "https://github.com/huggingface/datasets/pull/7452.diff",
"patch_url": "https://github.com/huggingface/datasets/pull/7452.patch",
"merged_at": "2025-03-14T14:14... | before the release | {
"login": "lhoestq",
"id": 42851186,
"node_id": "MDQ6VXNlcjQyODUxMTg2",
"avatar_url": "https://avatars.githubusercontent.com/u/42851186?v=4",
"gravatar_id": "",
"url": "https://api.github.com/users/lhoestq",
"html_url": "https://github.com/lhoestq",
"followers_url": "https://api.github.com/users/lhoest... | {
"url": "https://api.github.com/repos/huggingface/datasets/issues/7452/reactions",
"total_count": 0,
"+1": 0,
"-1": 0,
"laugh": 0,
"hooray": 0,
"confused": 0,
"heart": 0,
"rocket": 0,
"eyes": 0
} | https://api.github.com/repos/huggingface/datasets/issues/7452/timeline | null | null | null | null | null | true |
https://api.github.com/repos/huggingface/datasets/issues/7451 | https://api.github.com/repos/huggingface/datasets | https://api.github.com/repos/huggingface/datasets/issues/7451/labels{/name} | https://api.github.com/repos/huggingface/datasets/issues/7451/comments | https://api.github.com/repos/huggingface/datasets/issues/7451/events | https://github.com/huggingface/datasets/pull/7451 | 2,919,835,663 | PR_kwDODunzps6OpwDz | 7,451 | Fix resuming after `ds.set_epoch(new_epoch)` | {
"login": "lhoestq",
"id": 42851186,
"node_id": "MDQ6VXNlcjQyODUxMTg2",
"avatar_url": "https://avatars.githubusercontent.com/u/42851186?v=4",
"gravatar_id": "",
"url": "https://api.github.com/users/lhoestq",
"html_url": "https://github.com/lhoestq",
"followers_url": "https://api.github.com/users/lhoest... | [] | closed | false | [] | null | 1 | 2025-03-14T10:31:25 | 2025-03-14T10:50:11 | 2025-03-14T10:50:09 | null | MEMBER | [] | null | null | false | {
"url": "https://api.github.com/repos/huggingface/datasets/pulls/7451",
"html_url": "https://github.com/huggingface/datasets/pull/7451",
"diff_url": "https://github.com/huggingface/datasets/pull/7451.diff",
"patch_url": "https://github.com/huggingface/datasets/pull/7451.patch",
"merged_at": "2025-03-14T10:50... | close https://github.com/huggingface/datasets/issues/7447 | {
"login": "lhoestq",
"id": 42851186,
"node_id": "MDQ6VXNlcjQyODUxMTg2",
"avatar_url": "https://avatars.githubusercontent.com/u/42851186?v=4",
"gravatar_id": "",
"url": "https://api.github.com/users/lhoestq",
"html_url": "https://github.com/lhoestq",
"followers_url": "https://api.github.com/users/lhoest... | {
"url": "https://api.github.com/repos/huggingface/datasets/issues/7451/reactions",
"total_count": 0,
"+1": 0,
"-1": 0,
"laugh": 0,
"hooray": 0,
"confused": 0,
"heart": 0,
"rocket": 0,
"eyes": 0
} | https://api.github.com/repos/huggingface/datasets/issues/7451/timeline | null | null | null | null | null | true |
https://api.github.com/repos/huggingface/datasets/issues/7450 | https://api.github.com/repos/huggingface/datasets | https://api.github.com/repos/huggingface/datasets/issues/7450/labels{/name} | https://api.github.com/repos/huggingface/datasets/issues/7450/comments | https://api.github.com/repos/huggingface/datasets/issues/7450/events | https://github.com/huggingface/datasets/pull/7450 | 2,916,681,414 | PR_kwDODunzps6OfMKs | 7,450 | Add IterableDataset.decode with multithreading | {
"login": "lhoestq",
"id": 42851186,
"node_id": "MDQ6VXNlcjQyODUxMTg2",
"avatar_url": "https://avatars.githubusercontent.com/u/42851186?v=4",
"gravatar_id": "",
"url": "https://api.github.com/users/lhoestq",
"html_url": "https://github.com/lhoestq",
"followers_url": "https://api.github.com/users/lhoest... | [] | closed | false | [] | null | 1 | 2025-03-13T10:41:35 | 2025-03-14T10:35:37 | 2025-03-14T10:35:35 | null | MEMBER | [] | null | null | false | {
"url": "https://api.github.com/repos/huggingface/datasets/pulls/7450",
"html_url": "https://github.com/huggingface/datasets/pull/7450",
"diff_url": "https://github.com/huggingface/datasets/pull/7450.diff",
"patch_url": "https://github.com/huggingface/datasets/pull/7450.patch",
"merged_at": "2025-03-14T10:35... | Useful for dataset streaming for multimodal datasets, and especially for lerobot.
It speeds up streaming up to 20 times.
When decoding is enabled (default), media types are decoded:
* audio -> dict of "array" and "sampling_rate" and "path"
* image -> PIL.Image
* video -> torchvision.io.VideoReader
You can e... | {
"login": "lhoestq",
"id": 42851186,
"node_id": "MDQ6VXNlcjQyODUxMTg2",
"avatar_url": "https://avatars.githubusercontent.com/u/42851186?v=4",
"gravatar_id": "",
"url": "https://api.github.com/users/lhoestq",
"html_url": "https://github.com/lhoestq",
"followers_url": "https://api.github.com/users/lhoest... | {
"url": "https://api.github.com/repos/huggingface/datasets/issues/7450/reactions",
"total_count": 0,
"+1": 0,
"-1": 0,
"laugh": 0,
"hooray": 0,
"confused": 0,
"heart": 0,
"rocket": 0,
"eyes": 0
} | https://api.github.com/repos/huggingface/datasets/issues/7450/timeline | null | null | null | null | null | true |
https://api.github.com/repos/huggingface/datasets/issues/7449 | https://api.github.com/repos/huggingface/datasets | https://api.github.com/repos/huggingface/datasets/issues/7449/labels{/name} | https://api.github.com/repos/huggingface/datasets/issues/7449/comments | https://api.github.com/repos/huggingface/datasets/issues/7449/events | https://github.com/huggingface/datasets/issues/7449 | 2,916,235,092 | I_kwDODunzps6t0jdU | 7,449 | Cannot load data with different schemas from different parquet files | {
"login": "li-plus",
"id": 39846316,
"node_id": "MDQ6VXNlcjM5ODQ2MzE2",
"avatar_url": "https://avatars.githubusercontent.com/u/39846316?v=4",
"gravatar_id": "",
"url": "https://api.github.com/users/li-plus",
"html_url": "https://github.com/li-plus",
"followers_url": "https://api.github.com/users/li-plu... | [] | closed | false | [] | null | 2 | 2025-03-13T08:14:49 | 2025-03-17T07:27:48 | 2025-03-17T07:27:46 | null | NONE | [] | null | null | null | null | ### Describe the bug
Cannot load samples with optional fields from different files. The schema cannot be correctly derived.
### Steps to reproduce the bug
When I place two samples with an optional field `some_extra_field` within a single parquet file, it can be loaded via `load_dataset`.
```python
import pandas as ... | {
"login": "li-plus",
"id": 39846316,
"node_id": "MDQ6VXNlcjM5ODQ2MzE2",
"avatar_url": "https://avatars.githubusercontent.com/u/39846316?v=4",
"gravatar_id": "",
"url": "https://api.github.com/users/li-plus",
"html_url": "https://github.com/li-plus",
"followers_url": "https://api.github.com/users/li-plu... | {
"url": "https://api.github.com/repos/huggingface/datasets/issues/7449/reactions",
"total_count": 0,
"+1": 0,
"-1": 0,
"laugh": 0,
"hooray": 0,
"confused": 0,
"heart": 0,
"rocket": 0,
"eyes": 0
} | https://api.github.com/repos/huggingface/datasets/issues/7449/timeline | null | completed | {
"total": 0,
"completed": 0,
"percent_completed": 0
} | {
"blocked_by": 0,
"total_blocked_by": 0,
"blocking": 0,
"total_blocking": 0
} | null | false |
https://api.github.com/repos/huggingface/datasets/issues/7448 | https://api.github.com/repos/huggingface/datasets | https://api.github.com/repos/huggingface/datasets/issues/7448/labels{/name} | https://api.github.com/repos/huggingface/datasets/issues/7448/comments | https://api.github.com/repos/huggingface/datasets/issues/7448/events | https://github.com/huggingface/datasets/issues/7448 | 2,916,025,762 | I_kwDODunzps6tzwWi | 7,448 | `datasets.disable_caching` doesn't work | {
"login": "UCC-team",
"id": 35629974,
"node_id": "MDQ6VXNlcjM1NjI5OTc0",
"avatar_url": "https://avatars.githubusercontent.com/u/35629974?v=4",
"gravatar_id": "",
"url": "https://api.github.com/users/UCC-team",
"html_url": "https://github.com/UCC-team",
"followers_url": "https://api.github.com/users/UCC... | [] | open | false | [] | null | 3 | 2025-03-13T06:40:12 | 2026-05-10T12:02:44 | null | null | NONE | [] | null | null | null | null | When I use `Dataset.from_generator(my_gen)` to load my dataset, it simply skips my changes to the generator function.
I tried `datasets.disable_caching`, but it doesn't work! | null | {
"url": "https://api.github.com/repos/huggingface/datasets/issues/7448/reactions",
"total_count": 1,
"+1": 1,
"-1": 0,
"laugh": 0,
"hooray": 0,
"confused": 0,
"heart": 0,
"rocket": 0,
"eyes": 0
} | https://api.github.com/repos/huggingface/datasets/issues/7448/timeline | null | null | {
"total": 0,
"completed": 0,
"percent_completed": 0
} | {
"blocked_by": 0,
"total_blocked_by": 0,
"blocking": 0,
"total_blocking": 0
} | null | false |
https://api.github.com/repos/huggingface/datasets/issues/7447 | https://api.github.com/repos/huggingface/datasets | https://api.github.com/repos/huggingface/datasets/issues/7447/labels{/name} | https://api.github.com/repos/huggingface/datasets/issues/7447/comments | https://api.github.com/repos/huggingface/datasets/issues/7447/events | https://github.com/huggingface/datasets/issues/7447 | 2,915,233,248 | I_kwDODunzps6twu3g | 7,447 | Epochs shortened after resuming mid-epoch with Iterable dataset+StatefulDataloader(persistent_workers=True) | {
"login": "dhruvdcoder",
"id": 4356534,
"node_id": "MDQ6VXNlcjQzNTY1MzQ=",
"avatar_url": "https://avatars.githubusercontent.com/u/4356534?v=4",
"gravatar_id": "",
"url": "https://api.github.com/users/dhruvdcoder",
"html_url": "https://github.com/dhruvdcoder",
"followers_url": "https://api.github.com/us... | [] | closed | false | [] | null | 6 | 2025-03-12T21:41:05 | 2025-07-09T23:04:57 | 2025-03-14T10:50:10 | null | NONE | [] | null | null | null | null | ### Describe the bug
When `torchdata.stateful_dataloader.StatefulDataloader(persistent_workers=True)` the epochs after resuming only iterate through the examples that were left in the epoch when the training was interrupted. For example, in the script below training is interrupted on step 124 (epoch 1) when 3 batches ... | {
"login": "lhoestq",
"id": 42851186,
"node_id": "MDQ6VXNlcjQyODUxMTg2",
"avatar_url": "https://avatars.githubusercontent.com/u/42851186?v=4",
"gravatar_id": "",
"url": "https://api.github.com/users/lhoestq",
"html_url": "https://github.com/lhoestq",
"followers_url": "https://api.github.com/users/lhoest... | {
"url": "https://api.github.com/repos/huggingface/datasets/issues/7447/reactions",
"total_count": 0,
"+1": 0,
"-1": 0,
"laugh": 0,
"hooray": 0,
"confused": 0,
"heart": 0,
"rocket": 0,
"eyes": 0
} | https://api.github.com/repos/huggingface/datasets/issues/7447/timeline | null | completed | {
"total": 0,
"completed": 0,
"percent_completed": 0
} | {
"blocked_by": 0,
"total_blocked_by": 0,
"blocking": 0,
"total_blocking": 0
} | null | false |
https://api.github.com/repos/huggingface/datasets/issues/7446 | https://api.github.com/repos/huggingface/datasets | https://api.github.com/repos/huggingface/datasets/issues/7446/labels{/name} | https://api.github.com/repos/huggingface/datasets/issues/7446/comments | https://api.github.com/repos/huggingface/datasets/issues/7446/events | https://github.com/huggingface/datasets/issues/7446 | 2,913,050,552 | I_kwDODunzps6toZ-4 | 7,446 | pyarrow.lib.ArrowTypeError: Expected dict key of type str or bytes, got 'int' | {
"login": "rangehow",
"id": 88258534,
"node_id": "MDQ6VXNlcjg4MjU4NTM0",
"avatar_url": "https://avatars.githubusercontent.com/u/88258534?v=4",
"gravatar_id": "",
"url": "https://api.github.com/users/rangehow",
"html_url": "https://github.com/rangehow",
"followers_url": "https://api.github.com/users/ran... | [] | closed | false | [] | null | 2 | 2025-03-12T07:48:37 | 2025-07-04T05:14:45 | 2025-07-04T05:14:45 | null | NONE | [] | null | null | null | null | ### Describe the bug
A dict with its keys are all str but get following error
```python
test_data=[{'input_ids':[1,2,3],'labels':[[Counter({2:1})]]}]
dataset = datasets.Dataset.from_list(test_data)
```
```bash
pyarrow.lib.ArrowTypeError: Expected dict key of type str or bytes, got 'int'
```
### Steps to reproduce the... | {
"login": "rangehow",
"id": 88258534,
"node_id": "MDQ6VXNlcjg4MjU4NTM0",
"avatar_url": "https://avatars.githubusercontent.com/u/88258534?v=4",
"gravatar_id": "",
"url": "https://api.github.com/users/rangehow",
"html_url": "https://github.com/rangehow",
"followers_url": "https://api.github.com/users/ran... | {
"url": "https://api.github.com/repos/huggingface/datasets/issues/7446/reactions",
"total_count": 0,
"+1": 0,
"-1": 0,
"laugh": 0,
"hooray": 0,
"confused": 0,
"heart": 0,
"rocket": 0,
"eyes": 0
} | https://api.github.com/repos/huggingface/datasets/issues/7446/timeline | null | completed | {
"total": 0,
"completed": 0,
"percent_completed": 0
} | {
"blocked_by": 0,
"total_blocked_by": 0,
"blocking": 0,
"total_blocking": 0
} | null | false |
https://api.github.com/repos/huggingface/datasets/issues/7445 | https://api.github.com/repos/huggingface/datasets | https://api.github.com/repos/huggingface/datasets/issues/7445/labels{/name} | https://api.github.com/repos/huggingface/datasets/issues/7445/comments | https://api.github.com/repos/huggingface/datasets/issues/7445/events | https://github.com/huggingface/datasets/pull/7445 | 2,911,507,923 | PR_kwDODunzps6ONygU | 7,445 | Fix small bugs with async map | {
"login": "lhoestq",
"id": 42851186,
"node_id": "MDQ6VXNlcjQyODUxMTg2",
"avatar_url": "https://avatars.githubusercontent.com/u/42851186?v=4",
"gravatar_id": "",
"url": "https://api.github.com/users/lhoestq",
"html_url": "https://github.com/lhoestq",
"followers_url": "https://api.github.com/users/lhoest... | [] | closed | false | [] | null | 1 | 2025-03-11T18:30:57 | 2025-03-13T10:38:03 | 2025-03-13T10:37:58 | null | MEMBER | [] | null | null | false | {
"url": "https://api.github.com/repos/huggingface/datasets/pulls/7445",
"html_url": "https://github.com/huggingface/datasets/pull/7445",
"diff_url": "https://github.com/huggingface/datasets/pull/7445.diff",
"patch_url": "https://github.com/huggingface/datasets/pull/7445.patch",
"merged_at": "2025-03-13T10:37... | helpful for the next PR to enable parallel image/audio/video decoding and make multimodal datasets go brr (e.g. for lerobot)
- fix with_indices
- fix resuming with save_state_dict() / load_state_dict() - omg that wasn't easy
- remove unnecessary decoding in map() to enable parallelism in FormattedExampleIterable l... | {
"login": "lhoestq",
"id": 42851186,
"node_id": "MDQ6VXNlcjQyODUxMTg2",
"avatar_url": "https://avatars.githubusercontent.com/u/42851186?v=4",
"gravatar_id": "",
"url": "https://api.github.com/users/lhoestq",
"html_url": "https://github.com/lhoestq",
"followers_url": "https://api.github.com/users/lhoest... | {
"url": "https://api.github.com/repos/huggingface/datasets/issues/7445/reactions",
"total_count": 0,
"+1": 0,
"-1": 0,
"laugh": 0,
"hooray": 0,
"confused": 0,
"heart": 0,
"rocket": 0,
"eyes": 0
} | https://api.github.com/repos/huggingface/datasets/issues/7445/timeline | null | null | null | null | null | true |
https://api.github.com/repos/huggingface/datasets/issues/7444 | https://api.github.com/repos/huggingface/datasets | https://api.github.com/repos/huggingface/datasets/issues/7444/labels{/name} | https://api.github.com/repos/huggingface/datasets/issues/7444/comments | https://api.github.com/repos/huggingface/datasets/issues/7444/events | https://github.com/huggingface/datasets/issues/7444 | 2,911,202,445 | I_kwDODunzps6thWyN | 7,444 | Excessive warnings when resuming an IterableDataset+buffered shuffle+DDP. | {
"login": "dhruvdcoder",
"id": 4356534,
"node_id": "MDQ6VXNlcjQzNTY1MzQ=",
"avatar_url": "https://avatars.githubusercontent.com/u/4356534?v=4",
"gravatar_id": "",
"url": "https://api.github.com/users/dhruvdcoder",
"html_url": "https://github.com/dhruvdcoder",
"followers_url": "https://api.github.com/us... | [] | open | false | [] | null | 2 | 2025-03-11T16:34:39 | 2025-11-22T06:45:25 | null | null | NONE | [] | null | null | null | null | ### Describe the bug
I have a large dataset that I shared into 1024 shards and save on the disk during pre-processing. During training, I load the dataset using load_from_disk() and convert it into an iterable dataset, shuffle it and split the shards to different DDP nodes using the recommended method.
However, when ... | null | {
"url": "https://api.github.com/repos/huggingface/datasets/issues/7444/reactions",
"total_count": 2,
"+1": 2,
"-1": 0,
"laugh": 0,
"hooray": 0,
"confused": 0,
"heart": 0,
"rocket": 0,
"eyes": 0
} | https://api.github.com/repos/huggingface/datasets/issues/7444/timeline | null | null | {
"total": 0,
"completed": 0,
"percent_completed": 0
} | {
"blocked_by": 0,
"total_blocked_by": 0,
"blocking": 0,
"total_blocking": 0
} | null | false |
https://api.github.com/repos/huggingface/datasets/issues/7443 | https://api.github.com/repos/huggingface/datasets | https://api.github.com/repos/huggingface/datasets/issues/7443/labels{/name} | https://api.github.com/repos/huggingface/datasets/issues/7443/comments | https://api.github.com/repos/huggingface/datasets/issues/7443/events | https://github.com/huggingface/datasets/issues/7443 | 2,908,585,656 | I_kwDODunzps6tXX64 | 7,443 | index error when num_shards > len(dataset) | {
"login": "eminorhan",
"id": 17934496,
"node_id": "MDQ6VXNlcjE3OTM0NDk2",
"avatar_url": "https://avatars.githubusercontent.com/u/17934496?v=4",
"gravatar_id": "",
"url": "https://api.github.com/users/eminorhan",
"html_url": "https://github.com/eminorhan",
"followers_url": "https://api.github.com/users/... | [] | open | false | [] | null | 1 | 2025-03-10T22:40:59 | 2025-03-10T23:43:08 | null | null | NONE | [] | null | null | null | null | In `ds.push_to_hub()` and `ds.save_to_disk()`, `num_shards` must be smaller than or equal to the number of rows in the dataset, but currently this is not checked anywhere inside these functions. Attempting to invoke these functions with `num_shards > len(dataset)` should raise an informative `ValueError`.
I frequently... | null | {
"url": "https://api.github.com/repos/huggingface/datasets/issues/7443/reactions",
"total_count": 1,
"+1": 1,
"-1": 0,
"laugh": 0,
"hooray": 0,
"confused": 0,
"heart": 0,
"rocket": 0,
"eyes": 0
} | https://api.github.com/repos/huggingface/datasets/issues/7443/timeline | null | null | {
"total": 0,
"completed": 0,
"percent_completed": 0
} | {
"blocked_by": 0,
"total_blocked_by": 0,
"blocking": 0,
"total_blocking": 0
} | null | false |
https://api.github.com/repos/huggingface/datasets/issues/7442 | https://api.github.com/repos/huggingface/datasets | https://api.github.com/repos/huggingface/datasets/issues/7442/labels{/name} | https://api.github.com/repos/huggingface/datasets/issues/7442/comments | https://api.github.com/repos/huggingface/datasets/issues/7442/events | https://github.com/huggingface/datasets/issues/7442 | 2,905,543,017 | I_kwDODunzps6tLxFp | 7,442 | Flexible Loader | {
"login": "dipta007",
"id": 13894030,
"node_id": "MDQ6VXNlcjEzODk0MDMw",
"avatar_url": "https://avatars.githubusercontent.com/u/13894030?v=4",
"gravatar_id": "",
"url": "https://api.github.com/users/dipta007",
"html_url": "https://github.com/dipta007",
"followers_url": "https://api.github.com/users/dip... | [
{
"id": 1935892871,
"node_id": "MDU6TGFiZWwxOTM1ODkyODcx",
"url": "https://api.github.com/repos/huggingface/datasets/labels/enhancement",
"name": "enhancement",
"color": "a2eeef",
"default": true,
"description": "New feature or request",
"archived_at": null,
"archived_by": null
... | closed | false | [] | null | 3 | 2025-03-09T16:55:03 | 2026-02-21T19:58:58 | 2026-02-21T19:58:58 | null | NONE | [] | null | null | null | null | ### Feature request
Can we have a utility function that will use `load_from_disk` when given the local path and `load_dataset` if given an HF dataset?
It can be something as simple as this one:
```
def load_hf_dataset(path_or_name):
if os.path.exists(path_or_name):
return load_from_disk(path_or_name)
... | {
"login": "dipta007",
"id": 13894030,
"node_id": "MDQ6VXNlcjEzODk0MDMw",
"avatar_url": "https://avatars.githubusercontent.com/u/13894030?v=4",
"gravatar_id": "",
"url": "https://api.github.com/users/dipta007",
"html_url": "https://github.com/dipta007",
"followers_url": "https://api.github.com/users/dip... | {
"url": "https://api.github.com/repos/huggingface/datasets/issues/7442/reactions",
"total_count": 0,
"+1": 0,
"-1": 0,
"laugh": 0,
"hooray": 0,
"confused": 0,
"heart": 0,
"rocket": 0,
"eyes": 0
} | https://api.github.com/repos/huggingface/datasets/issues/7442/timeline | null | completed | {
"total": 0,
"completed": 0,
"percent_completed": 0
} | {
"blocked_by": 0,
"total_blocked_by": 0,
"blocking": 0,
"total_blocking": 0
} | null | false |
https://api.github.com/repos/huggingface/datasets/issues/7441 | https://api.github.com/repos/huggingface/datasets | https://api.github.com/repos/huggingface/datasets/issues/7441/labels{/name} | https://api.github.com/repos/huggingface/datasets/issues/7441/comments | https://api.github.com/repos/huggingface/datasets/issues/7441/events | https://github.com/huggingface/datasets/issues/7441 | 2,904,702,329 | I_kwDODunzps6tIj15 | 7,441 | `drop_last_batch` does not drop the last batch using IterableDataset + interleave_datasets + multi_worker | {
"login": "memray",
"id": 4197249,
"node_id": "MDQ6VXNlcjQxOTcyNDk=",
"avatar_url": "https://avatars.githubusercontent.com/u/4197249?v=4",
"gravatar_id": "",
"url": "https://api.github.com/users/memray",
"html_url": "https://github.com/memray",
"followers_url": "https://api.github.com/users/memray/foll... | [] | open | false | [] | null | 3 | 2025-03-08T10:28:44 | 2025-10-09T10:14:24 | null | null | NONE | [] | null | null | null | null | ### Describe the bug
See the script below
`drop_last_batch=True` is defined using map() for each dataset.
The last batch for each dataset is expected to be dropped, id 21-25.
The code behaves as expected when num_workers=0 or 1.
When using num_workers>1, 'a-11', 'b-11', 'a-12', 'b-12' are gone and instead 21 and 22 a... | null | {
"url": "https://api.github.com/repos/huggingface/datasets/issues/7441/reactions",
"total_count": 0,
"+1": 0,
"-1": 0,
"laugh": 0,
"hooray": 0,
"confused": 0,
"heart": 0,
"rocket": 0,
"eyes": 0
} | https://api.github.com/repos/huggingface/datasets/issues/7441/timeline | null | null | {
"total": 0,
"completed": 0,
"percent_completed": 0
} | {
"blocked_by": 0,
"total_blocked_by": 0,
"blocking": 0,
"total_blocking": 0
} | null | false |
https://api.github.com/repos/huggingface/datasets/issues/7440 | https://api.github.com/repos/huggingface/datasets | https://api.github.com/repos/huggingface/datasets/issues/7440/labels{/name} | https://api.github.com/repos/huggingface/datasets/issues/7440/comments | https://api.github.com/repos/huggingface/datasets/issues/7440/events | https://github.com/huggingface/datasets/issues/7440 | 2,903,740,662 | I_kwDODunzps6tE5D2 | 7,440 | IterableDataset raises FileNotFoundError instead of retrying | {
"login": "bauwenst",
"id": 145220868,
"node_id": "U_kgDOCKflBA",
"avatar_url": "https://avatars.githubusercontent.com/u/145220868?v=4",
"gravatar_id": "",
"url": "https://api.github.com/users/bauwenst",
"html_url": "https://github.com/bauwenst",
"followers_url": "https://api.github.com/users/bauwenst/... | [] | open | false | [] | null | 11 | 2025-03-07T19:14:18 | 2026-04-24T11:15:36 | null | null | NONE | [] | null | null | null | null | ### Describe the bug
In https://github.com/huggingface/datasets/issues/6843 it was noted that the streaming feature of `datasets` is highly susceptible to outages and doesn't back off for long (or even *at all*).
I was training a model while streaming SlimPajama and training crashed with a `FileNotFoundError`. I can ... | null | {
"url": "https://api.github.com/repos/huggingface/datasets/issues/7440/reactions",
"total_count": 2,
"+1": 1,
"-1": 0,
"laugh": 0,
"hooray": 0,
"confused": 0,
"heart": 0,
"rocket": 0,
"eyes": 1
} | https://api.github.com/repos/huggingface/datasets/issues/7440/timeline | null | null | {
"total": 0,
"completed": 0,
"percent_completed": 0
} | {
"blocked_by": 0,
"total_blocked_by": 0,
"blocking": 0,
"total_blocking": 0
} | null | false |
https://api.github.com/repos/huggingface/datasets/issues/7439 | https://api.github.com/repos/huggingface/datasets | https://api.github.com/repos/huggingface/datasets/issues/7439/labels{/name} | https://api.github.com/repos/huggingface/datasets/issues/7439/comments | https://api.github.com/repos/huggingface/datasets/issues/7439/events | https://github.com/huggingface/datasets/pull/7439 | 2,900,143,289 | PR_kwDODunzps6NoCdD | 7,439 | Fix multi gpu process example | {
"login": "SwayStar123",
"id": 46050679,
"node_id": "MDQ6VXNlcjQ2MDUwNjc5",
"avatar_url": "https://avatars.githubusercontent.com/u/46050679?v=4",
"gravatar_id": "",
"url": "https://api.github.com/users/SwayStar123",
"html_url": "https://github.com/SwayStar123",
"followers_url": "https://api.github.com/... | [] | closed | false | [] | null | 1 | 2025-03-06T11:29:19 | 2025-03-06T17:07:28 | 2025-03-06T17:06:38 | null | NONE | [] | null | null | false | {
"url": "https://api.github.com/repos/huggingface/datasets/pulls/7439",
"html_url": "https://github.com/huggingface/datasets/pull/7439",
"diff_url": "https://github.com/huggingface/datasets/pull/7439.diff",
"patch_url": "https://github.com/huggingface/datasets/pull/7439.patch",
"merged_at": null
} | to is not an inplace function.
But i am not sure about this code anyway, i think this is modifying the global variable `model` everytime the function is called? Which is on every batch? So it is juggling the same model on every gpu right? Isnt that very inefficient? | {
"login": "SwayStar123",
"id": 46050679,
"node_id": "MDQ6VXNlcjQ2MDUwNjc5",
"avatar_url": "https://avatars.githubusercontent.com/u/46050679?v=4",
"gravatar_id": "",
"url": "https://api.github.com/users/SwayStar123",
"html_url": "https://github.com/SwayStar123",
"followers_url": "https://api.github.com/... | {
"url": "https://api.github.com/repos/huggingface/datasets/issues/7439/reactions",
"total_count": 0,
"+1": 0,
"-1": 0,
"laugh": 0,
"hooray": 0,
"confused": 0,
"heart": 0,
"rocket": 0,
"eyes": 0
} | https://api.github.com/repos/huggingface/datasets/issues/7439/timeline | null | null | null | null | null | true |
https://api.github.com/repos/huggingface/datasets/issues/7438 | https://api.github.com/repos/huggingface/datasets | https://api.github.com/repos/huggingface/datasets/issues/7438/labels{/name} | https://api.github.com/repos/huggingface/datasets/issues/7438/comments | https://api.github.com/repos/huggingface/datasets/issues/7438/events | https://github.com/huggingface/datasets/pull/7438 | 2,899,209,484 | PR_kwDODunzps6Nk37h | 7,438 | Allow dataset row indexing with np.int types (#7423) | {
"login": "DavidRConnell",
"id": 35470740,
"node_id": "MDQ6VXNlcjM1NDcwNzQw",
"avatar_url": "https://avatars.githubusercontent.com/u/35470740?v=4",
"gravatar_id": "",
"url": "https://api.github.com/users/DavidRConnell",
"html_url": "https://github.com/DavidRConnell",
"followers_url": "https://api.githu... | [] | closed | false | [] | null | 4 | 2025-03-06T03:10:43 | 2025-07-23T17:56:22 | 2025-07-23T16:44:42 | null | CONTRIBUTOR | [] | null | null | false | {
"url": "https://api.github.com/repos/huggingface/datasets/pulls/7438",
"html_url": "https://github.com/huggingface/datasets/pull/7438",
"diff_url": "https://github.com/huggingface/datasets/pull/7438.diff",
"patch_url": "https://github.com/huggingface/datasets/pull/7438.patch",
"merged_at": "2025-07-23T16:44... | @lhoestq
Proposed fix for #7423. Added a couple simple tests as requested. I had some test failures related to Java and pyspark even when installing with dev but these don't seem to be related to the changes here and fail for me even on clean main.
The typeerror raised when using the wrong type is: "Wrong key type... | {
"login": "lhoestq",
"id": 42851186,
"node_id": "MDQ6VXNlcjQyODUxMTg2",
"avatar_url": "https://avatars.githubusercontent.com/u/42851186?v=4",
"gravatar_id": "",
"url": "https://api.github.com/users/lhoestq",
"html_url": "https://github.com/lhoestq",
"followers_url": "https://api.github.com/users/lhoest... | {
"url": "https://api.github.com/repos/huggingface/datasets/issues/7438/reactions",
"total_count": 0,
"+1": 0,
"-1": 0,
"laugh": 0,
"hooray": 0,
"confused": 0,
"heart": 0,
"rocket": 0,
"eyes": 0
} | https://api.github.com/repos/huggingface/datasets/issues/7438/timeline | null | null | null | null | null | true |
https://api.github.com/repos/huggingface/datasets/issues/7437 | https://api.github.com/repos/huggingface/datasets | https://api.github.com/repos/huggingface/datasets/issues/7437/labels{/name} | https://api.github.com/repos/huggingface/datasets/issues/7437/comments | https://api.github.com/repos/huggingface/datasets/issues/7437/events | https://github.com/huggingface/datasets/pull/7437 | 2,899,104,679 | PR_kwDODunzps6Nkhla | 7,437 | Use pyupgrade --py39-plus for remaining files | {
"login": "cyyever",
"id": 17618148,
"node_id": "MDQ6VXNlcjE3NjE4MTQ4",
"avatar_url": "https://avatars.githubusercontent.com/u/17618148?v=4",
"gravatar_id": "",
"url": "https://api.github.com/users/cyyever",
"html_url": "https://github.com/cyyever",
"followers_url": "https://api.github.com/users/cyyeve... | [] | open | false | [] | null | 1 | 2025-03-06T02:12:25 | 2025-07-30T08:34:34 | null | null | CONTRIBUTOR | [] | null | null | false | {
"url": "https://api.github.com/repos/huggingface/datasets/pulls/7437",
"html_url": "https://github.com/huggingface/datasets/pull/7437",
"diff_url": "https://github.com/huggingface/datasets/pull/7437.diff",
"patch_url": "https://github.com/huggingface/datasets/pull/7437.patch",
"merged_at": null
} | This work follows #7428. And "requires-python" is set in pyproject.toml | null | {
"url": "https://api.github.com/repos/huggingface/datasets/issues/7437/reactions",
"total_count": 0,
"+1": 0,
"-1": 0,
"laugh": 0,
"hooray": 0,
"confused": 0,
"heart": 0,
"rocket": 0,
"eyes": 0
} | https://api.github.com/repos/huggingface/datasets/issues/7437/timeline | null | null | null | null | null | true |
https://api.github.com/repos/huggingface/datasets/issues/7436 | https://api.github.com/repos/huggingface/datasets | https://api.github.com/repos/huggingface/datasets/issues/7436/labels{/name} | https://api.github.com/repos/huggingface/datasets/issues/7436/comments | https://api.github.com/repos/huggingface/datasets/issues/7436/events | https://github.com/huggingface/datasets/pull/7436 | 2,898,385,725 | PR_kwDODunzps6NiArv | 7,436 | chore: fix typos | {
"login": "afuetterer",
"id": 35225576,
"node_id": "MDQ6VXNlcjM1MjI1NTc2",
"avatar_url": "https://avatars.githubusercontent.com/u/35225576?v=4",
"gravatar_id": "",
"url": "https://api.github.com/users/afuetterer",
"html_url": "https://github.com/afuetterer",
"followers_url": "https://api.github.com/use... | [] | closed | false | [] | null | 0 | 2025-03-05T20:17:54 | 2025-04-28T14:00:09 | 2025-04-28T13:51:26 | null | CONTRIBUTOR | [] | null | null | false | {
"url": "https://api.github.com/repos/huggingface/datasets/pulls/7436",
"html_url": "https://github.com/huggingface/datasets/pull/7436",
"diff_url": "https://github.com/huggingface/datasets/pull/7436.diff",
"patch_url": "https://github.com/huggingface/datasets/pull/7436.patch",
"merged_at": "2025-04-28T13:51... | null | {
"login": "lhoestq",
"id": 42851186,
"node_id": "MDQ6VXNlcjQyODUxMTg2",
"avatar_url": "https://avatars.githubusercontent.com/u/42851186?v=4",
"gravatar_id": "",
"url": "https://api.github.com/users/lhoestq",
"html_url": "https://github.com/lhoestq",
"followers_url": "https://api.github.com/users/lhoest... | {
"url": "https://api.github.com/repos/huggingface/datasets/issues/7436/reactions",
"total_count": 0,
"+1": 0,
"-1": 0,
"laugh": 0,
"hooray": 0,
"confused": 0,
"heart": 0,
"rocket": 0,
"eyes": 0
} | https://api.github.com/repos/huggingface/datasets/issues/7436/timeline | null | null | null | null | null | true |
https://api.github.com/repos/huggingface/datasets/issues/7435 | https://api.github.com/repos/huggingface/datasets | https://api.github.com/repos/huggingface/datasets/issues/7435/labels{/name} | https://api.github.com/repos/huggingface/datasets/issues/7435/comments | https://api.github.com/repos/huggingface/datasets/issues/7435/events | https://github.com/huggingface/datasets/pull/7435 | 2,895,536,956 | PR_kwDODunzps6NYUnr | 7,435 | Refactor `string_to_dict` to return `None` if there is no match instead of raising `ValueError` | {
"login": "ringohoffman",
"id": 27844407,
"node_id": "MDQ6VXNlcjI3ODQ0NDA3",
"avatar_url": "https://avatars.githubusercontent.com/u/27844407?v=4",
"gravatar_id": "",
"url": "https://api.github.com/users/ringohoffman",
"html_url": "https://github.com/ringohoffman",
"followers_url": "https://api.github.c... | [] | closed | false | [] | null | 8 | 2025-03-04T22:01:20 | 2025-03-12T16:52:00 | 2025-03-12T16:52:00 | null | NONE | [] | null | null | false | {
"url": "https://api.github.com/repos/huggingface/datasets/pulls/7435",
"html_url": "https://github.com/huggingface/datasets/pull/7435",
"diff_url": "https://github.com/huggingface/datasets/pull/7435.diff",
"patch_url": "https://github.com/huggingface/datasets/pull/7435.patch",
"merged_at": "2025-03-12T16:51... | Making this change, as encouraged here:
* https://github.com/huggingface/datasets/pull/7434#discussion_r1979933054
instead of having the pattern of using `try`-`except` to handle when there is no match, we can instead check if the return value is `None`; we can also assert that the return value should not be `Non... | {
"login": "lhoestq",
"id": 42851186,
"node_id": "MDQ6VXNlcjQyODUxMTg2",
"avatar_url": "https://avatars.githubusercontent.com/u/42851186?v=4",
"gravatar_id": "",
"url": "https://api.github.com/users/lhoestq",
"html_url": "https://github.com/lhoestq",
"followers_url": "https://api.github.com/users/lhoest... | {
"url": "https://api.github.com/repos/huggingface/datasets/issues/7435/reactions",
"total_count": 0,
"+1": 0,
"-1": 0,
"laugh": 0,
"hooray": 0,
"confused": 0,
"heart": 0,
"rocket": 0,
"eyes": 0
} | https://api.github.com/repos/huggingface/datasets/issues/7435/timeline | null | null | null | null | null | true |
https://api.github.com/repos/huggingface/datasets/issues/7434 | https://api.github.com/repos/huggingface/datasets | https://api.github.com/repos/huggingface/datasets/issues/7434/labels{/name} | https://api.github.com/repos/huggingface/datasets/issues/7434/comments | https://api.github.com/repos/huggingface/datasets/issues/7434/events | https://github.com/huggingface/datasets/pull/7434 | 2,893,075,908 | PR_kwDODunzps6NP-vn | 7,434 | Refactor `Dataset.map` to reuse cache files mapped with different `num_proc` | {
"login": "ringohoffman",
"id": 27844407,
"node_id": "MDQ6VXNlcjI3ODQ0NDA3",
"avatar_url": "https://avatars.githubusercontent.com/u/27844407?v=4",
"gravatar_id": "",
"url": "https://api.github.com/users/ringohoffman",
"html_url": "https://github.com/ringohoffman",
"followers_url": "https://api.github.c... | [] | closed | false | [] | null | 10 | 2025-03-04T06:12:37 | 2025-05-14T10:45:10 | 2025-05-12T15:14:08 | null | NONE | [] | null | null | false | {
"url": "https://api.github.com/repos/huggingface/datasets/pulls/7434",
"html_url": "https://github.com/huggingface/datasets/pull/7434",
"diff_url": "https://github.com/huggingface/datasets/pull/7434.diff",
"patch_url": "https://github.com/huggingface/datasets/pull/7434.patch",
"merged_at": "2025-05-12T15:14... | Fixes #7433
This refactor unifies `num_proc is None or num_proc == 1` and `num_proc > 1`; instead of handling them completely separately where one uses a list of kwargs and shards and the other just uses a single set of kwargs and `self`, by wrapping the `num_proc == 1` case in a list and making the difference just ... | {
"login": "lhoestq",
"id": 42851186,
"node_id": "MDQ6VXNlcjQyODUxMTg2",
"avatar_url": "https://avatars.githubusercontent.com/u/42851186?v=4",
"gravatar_id": "",
"url": "https://api.github.com/users/lhoestq",
"html_url": "https://github.com/lhoestq",
"followers_url": "https://api.github.com/users/lhoest... | {
"url": "https://api.github.com/repos/huggingface/datasets/issues/7434/reactions",
"total_count": 0,
"+1": 0,
"-1": 0,
"laugh": 0,
"hooray": 0,
"confused": 0,
"heart": 0,
"rocket": 0,
"eyes": 0
} | https://api.github.com/repos/huggingface/datasets/issues/7434/timeline | null | null | null | null | null | true |
https://api.github.com/repos/huggingface/datasets/issues/7433 | https://api.github.com/repos/huggingface/datasets | https://api.github.com/repos/huggingface/datasets/issues/7433/labels{/name} | https://api.github.com/repos/huggingface/datasets/issues/7433/comments | https://api.github.com/repos/huggingface/datasets/issues/7433/events | https://github.com/huggingface/datasets/issues/7433 | 2,890,240,400 | I_kwDODunzps6sRZGQ | 7,433 | `Dataset.map` ignores existing caches and remaps when ran with different `num_proc` | {
"login": "ringohoffman",
"id": 27844407,
"node_id": "MDQ6VXNlcjI3ODQ0NDA3",
"avatar_url": "https://avatars.githubusercontent.com/u/27844407?v=4",
"gravatar_id": "",
"url": "https://api.github.com/users/ringohoffman",
"html_url": "https://github.com/ringohoffman",
"followers_url": "https://api.github.c... | [] | closed | false | [] | null | 2 | 2025-03-03T05:51:26 | 2025-05-12T15:14:09 | 2025-05-12T15:14:09 | null | NONE | [] | null | null | null | null | ### Describe the bug
If you `map` a dataset and save it to a specific `cache_file_name` with a specific `num_proc`, and then call map again with that same existing `cache_file_name` but a different `num_proc`, the dataset will be re-mapped.
### Steps to reproduce the bug
1. Download a dataset
```python
import datase... | {
"login": "lhoestq",
"id": 42851186,
"node_id": "MDQ6VXNlcjQyODUxMTg2",
"avatar_url": "https://avatars.githubusercontent.com/u/42851186?v=4",
"gravatar_id": "",
"url": "https://api.github.com/users/lhoestq",
"html_url": "https://github.com/lhoestq",
"followers_url": "https://api.github.com/users/lhoest... | {
"url": "https://api.github.com/repos/huggingface/datasets/issues/7433/reactions",
"total_count": 0,
"+1": 0,
"-1": 0,
"laugh": 0,
"hooray": 0,
"confused": 0,
"heart": 0,
"rocket": 0,
"eyes": 0
} | https://api.github.com/repos/huggingface/datasets/issues/7433/timeline | null | completed | {
"total": 0,
"completed": 0,
"percent_completed": 0
} | {
"blocked_by": 0,
"total_blocked_by": 0,
"blocking": 0,
"total_blocking": 0
} | null | false |
https://api.github.com/repos/huggingface/datasets/issues/7432 | https://api.github.com/repos/huggingface/datasets | https://api.github.com/repos/huggingface/datasets/issues/7432/labels{/name} | https://api.github.com/repos/huggingface/datasets/issues/7432/comments | https://api.github.com/repos/huggingface/datasets/issues/7432/events | https://github.com/huggingface/datasets/pull/7432 | 2,887,717,289 | PR_kwDODunzps6M-DI0 | 7,432 | Fix type annotation | {
"login": "NeilGirdhar",
"id": 730137,
"node_id": "MDQ6VXNlcjczMDEzNw==",
"avatar_url": "https://avatars.githubusercontent.com/u/730137?v=4",
"gravatar_id": "",
"url": "https://api.github.com/users/NeilGirdhar",
"html_url": "https://github.com/NeilGirdhar",
"followers_url": "https://api.github.com/user... | [] | closed | false | [] | null | 1 | 2025-02-28T17:28:20 | 2025-03-04T15:53:03 | 2025-03-04T15:53:03 | null | CONTRIBUTOR | [] | null | null | false | {
"url": "https://api.github.com/repos/huggingface/datasets/pulls/7432",
"html_url": "https://github.com/huggingface/datasets/pull/7432",
"diff_url": "https://github.com/huggingface/datasets/pull/7432.diff",
"patch_url": "https://github.com/huggingface/datasets/pull/7432.patch",
"merged_at": null
} | null | {
"login": "lhoestq",
"id": 42851186,
"node_id": "MDQ6VXNlcjQyODUxMTg2",
"avatar_url": "https://avatars.githubusercontent.com/u/42851186?v=4",
"gravatar_id": "",
"url": "https://api.github.com/users/lhoestq",
"html_url": "https://github.com/lhoestq",
"followers_url": "https://api.github.com/users/lhoest... | {
"url": "https://api.github.com/repos/huggingface/datasets/issues/7432/reactions",
"total_count": 0,
"+1": 0,
"-1": 0,
"laugh": 0,
"hooray": 0,
"confused": 0,
"heart": 0,
"rocket": 0,
"eyes": 0
} | https://api.github.com/repos/huggingface/datasets/issues/7432/timeline | null | null | null | null | null | true |
https://api.github.com/repos/huggingface/datasets/issues/7431 | https://api.github.com/repos/huggingface/datasets | https://api.github.com/repos/huggingface/datasets/issues/7431/labels{/name} | https://api.github.com/repos/huggingface/datasets/issues/7431/comments | https://api.github.com/repos/huggingface/datasets/issues/7431/events | https://github.com/huggingface/datasets/issues/7431 | 2,887,244,074 | I_kwDODunzps6sF9kq | 7,431 | Issues with large Datasets | {
"login": "nikitabelooussovbtis",
"id": 106806889,
"node_id": "U_kgDOBl2-aQ",
"avatar_url": "https://avatars.githubusercontent.com/u/106806889?v=4",
"gravatar_id": "",
"url": "https://api.github.com/users/nikitabelooussovbtis",
"html_url": "https://github.com/nikitabelooussovbtis",
"followers_url": "ht... | [] | open | false | [] | null | 4 | 2025-02-28T14:05:22 | 2025-03-04T15:02:26 | null | null | NONE | [] | null | null | null | null | ### Describe the bug
If the coco annotation file is too large the dataset will not be able to load it, not entirely sure were the issue is but I am guessing it is due to the code trying to load it all as one line into a dataframe. This was for object detections.
My current work around is the following code but would ... | null | {
"url": "https://api.github.com/repos/huggingface/datasets/issues/7431/reactions",
"total_count": 0,
"+1": 0,
"-1": 0,
"laugh": 0,
"hooray": 0,
"confused": 0,
"heart": 0,
"rocket": 0,
"eyes": 0
} | https://api.github.com/repos/huggingface/datasets/issues/7431/timeline | null | null | {
"total": 0,
"completed": 0,
"percent_completed": 0
} | {
"blocked_by": 0,
"total_blocked_by": 0,
"blocking": 0,
"total_blocking": 0
} | null | false |
https://api.github.com/repos/huggingface/datasets/issues/7430 | https://api.github.com/repos/huggingface/datasets | https://api.github.com/repos/huggingface/datasets/issues/7430/labels{/name} | https://api.github.com/repos/huggingface/datasets/issues/7430/comments | https://api.github.com/repos/huggingface/datasets/issues/7430/events | https://github.com/huggingface/datasets/issues/7430 | 2,886,922,573 | I_kwDODunzps6sEvFN | 7,430 | Error in code "Time to slice and dice" from course "NLP Course" | {
"login": "Yurkmez",
"id": 122965300,
"node_id": "U_kgDOB1RNNA",
"avatar_url": "https://avatars.githubusercontent.com/u/122965300?v=4",
"gravatar_id": "",
"url": "https://api.github.com/users/Yurkmez",
"html_url": "https://github.com/Yurkmez",
"followers_url": "https://api.github.com/users/Yurkmez/foll... | [] | closed | false | [] | null | 2 | 2025-02-28T11:36:10 | 2025-03-05T11:32:47 | 2025-03-03T17:52:15 | null | NONE | [] | null | null | null | null | ### Describe the bug
When we execute code
```
frequencies = (
train_df["condition"]
.value_counts()
.to_frame()
.reset_index()
.rename(columns={"index": "condition", "condition": "frequency"})
)
frequencies.head()
```
answer should be like this
condition | frequency
birth control | 27655
dep... | {
"login": "lhoestq",
"id": 42851186,
"node_id": "MDQ6VXNlcjQyODUxMTg2",
"avatar_url": "https://avatars.githubusercontent.com/u/42851186?v=4",
"gravatar_id": "",
"url": "https://api.github.com/users/lhoestq",
"html_url": "https://github.com/lhoestq",
"followers_url": "https://api.github.com/users/lhoest... | {
"url": "https://api.github.com/repos/huggingface/datasets/issues/7430/reactions",
"total_count": 0,
"+1": 0,
"-1": 0,
"laugh": 0,
"hooray": 0,
"confused": 0,
"heart": 0,
"rocket": 0,
"eyes": 0
} | https://api.github.com/repos/huggingface/datasets/issues/7430/timeline | null | completed | {
"total": 0,
"completed": 0,
"percent_completed": 0
} | {
"blocked_by": 0,
"total_blocked_by": 0,
"blocking": 0,
"total_blocking": 0
} | null | false |
https://api.github.com/repos/huggingface/datasets/issues/7429 | https://api.github.com/repos/huggingface/datasets | https://api.github.com/repos/huggingface/datasets/issues/7429/labels{/name} | https://api.github.com/repos/huggingface/datasets/issues/7429/comments | https://api.github.com/repos/huggingface/datasets/issues/7429/events | https://github.com/huggingface/datasets/pull/7429 | 2,886,806,513 | PR_kwDODunzps6M67Jd | 7,429 | Improved type annotation | {
"login": "saiden89",
"id": 45285915,
"node_id": "MDQ6VXNlcjQ1Mjg1OTE1",
"avatar_url": "https://avatars.githubusercontent.com/u/45285915?v=4",
"gravatar_id": "",
"url": "https://api.github.com/users/saiden89",
"html_url": "https://github.com/saiden89",
"followers_url": "https://api.github.com/users/sai... | [] | open | false | [] | null | 3 | 2025-02-28T10:39:10 | 2025-05-15T12:27:17 | null | null | NONE | [] | null | null | false | {
"url": "https://api.github.com/repos/huggingface/datasets/pulls/7429",
"html_url": "https://github.com/huggingface/datasets/pull/7429",
"diff_url": "https://github.com/huggingface/datasets/pull/7429.diff",
"patch_url": "https://github.com/huggingface/datasets/pull/7429.patch",
"merged_at": null
} | I've refined several type annotations throughout the codebase to align with current best practices and enhance overall clarity. Given the complexity of the code, there may still be areas that need further attention. I welcome any feedback or suggestions to make these improvements even better.
- Fixes #7202 | null | {
"url": "https://api.github.com/repos/huggingface/datasets/issues/7429/reactions",
"total_count": 2,
"+1": 0,
"-1": 0,
"laugh": 0,
"hooray": 0,
"confused": 0,
"heart": 2,
"rocket": 0,
"eyes": 0
} | https://api.github.com/repos/huggingface/datasets/issues/7429/timeline | null | null | null | null | null | true |
https://api.github.com/repos/huggingface/datasets/issues/7428 | https://api.github.com/repos/huggingface/datasets | https://api.github.com/repos/huggingface/datasets/issues/7428/labels{/name} | https://api.github.com/repos/huggingface/datasets/issues/7428/comments | https://api.github.com/repos/huggingface/datasets/issues/7428/events | https://github.com/huggingface/datasets/pull/7428 | 2,886,111,651 | PR_kwDODunzps6M4kW8 | 7,428 | Use pyupgrade --py39-plus | {
"login": "cyyever",
"id": 17618148,
"node_id": "MDQ6VXNlcjE3NjE4MTQ4",
"avatar_url": "https://avatars.githubusercontent.com/u/17618148?v=4",
"gravatar_id": "",
"url": "https://api.github.com/users/cyyever",
"html_url": "https://github.com/cyyever",
"followers_url": "https://api.github.com/users/cyyeve... | [] | closed | false | [] | null | 3 | 2025-02-28T03:39:44 | 2025-03-22T00:51:20 | 2025-03-05T15:04:16 | null | CONTRIBUTOR | [] | null | null | false | {
"url": "https://api.github.com/repos/huggingface/datasets/pulls/7428",
"html_url": "https://github.com/huggingface/datasets/pull/7428",
"diff_url": "https://github.com/huggingface/datasets/pull/7428.diff",
"patch_url": "https://github.com/huggingface/datasets/pull/7428.patch",
"merged_at": "2025-03-05T15:04... | null | {
"login": "lhoestq",
"id": 42851186,
"node_id": "MDQ6VXNlcjQyODUxMTg2",
"avatar_url": "https://avatars.githubusercontent.com/u/42851186?v=4",
"gravatar_id": "",
"url": "https://api.github.com/users/lhoestq",
"html_url": "https://github.com/lhoestq",
"followers_url": "https://api.github.com/users/lhoest... | {
"url": "https://api.github.com/repos/huggingface/datasets/issues/7428/reactions",
"total_count": 0,
"+1": 0,
"-1": 0,
"laugh": 0,
"hooray": 0,
"confused": 0,
"heart": 0,
"rocket": 0,
"eyes": 0
} | https://api.github.com/repos/huggingface/datasets/issues/7428/timeline | null | null | null | null | null | true |
https://api.github.com/repos/huggingface/datasets/issues/7427 | https://api.github.com/repos/huggingface/datasets | https://api.github.com/repos/huggingface/datasets/issues/7427/labels{/name} | https://api.github.com/repos/huggingface/datasets/issues/7427/comments | https://api.github.com/repos/huggingface/datasets/issues/7427/events | https://github.com/huggingface/datasets/issues/7427 | 2,886,032,571 | I_kwDODunzps6sBVy7 | 7,427 | Error splitting the input into NAL units. | {
"login": "MengHao666",
"id": 47114466,
"node_id": "MDQ6VXNlcjQ3MTE0NDY2",
"avatar_url": "https://avatars.githubusercontent.com/u/47114466?v=4",
"gravatar_id": "",
"url": "https://api.github.com/users/MengHao666",
"html_url": "https://github.com/MengHao666",
"followers_url": "https://api.github.com/use... | [] | open | false | [] | null | 2 | 2025-02-28T02:30:15 | 2025-03-04T01:40:28 | null | null | NONE | [] | null | null | null | null | ### Describe the bug
I am trying to finetune qwen2.5-vl on 16 * 80G GPUS, and I use `LLaMA-Factory` and set `preprocessing_num_workers=16`. However, I met the following error and the program seem to got crush. It seems that the error come from `datasets` library
The error logging is like following:
```text
Convertin... | null | {
"url": "https://api.github.com/repos/huggingface/datasets/issues/7427/reactions",
"total_count": 0,
"+1": 0,
"-1": 0,
"laugh": 0,
"hooray": 0,
"confused": 0,
"heart": 0,
"rocket": 0,
"eyes": 0
} | https://api.github.com/repos/huggingface/datasets/issues/7427/timeline | null | null | {
"total": 0,
"completed": 0,
"percent_completed": 0
} | {
"blocked_by": 0,
"total_blocked_by": 0,
"blocking": 0,
"total_blocking": 0
} | null | false |
https://api.github.com/repos/huggingface/datasets/issues/7426 | https://api.github.com/repos/huggingface/datasets | https://api.github.com/repos/huggingface/datasets/issues/7426/labels{/name} | https://api.github.com/repos/huggingface/datasets/issues/7426/comments | https://api.github.com/repos/huggingface/datasets/issues/7426/events | https://github.com/huggingface/datasets/pull/7426 | 2,883,754,507 | PR_kwDODunzps6Mwe6B | 7,426 | fix: None default with bool type on load creates typing error | {
"login": "stephantul",
"id": 8882233,
"node_id": "MDQ6VXNlcjg4ODIyMzM=",
"avatar_url": "https://avatars.githubusercontent.com/u/8882233?v=4",
"gravatar_id": "",
"url": "https://api.github.com/users/stephantul",
"html_url": "https://github.com/stephantul",
"followers_url": "https://api.github.com/users... | [] | closed | false | [] | null | 0 | 2025-02-27T08:11:36 | 2025-03-04T15:53:40 | 2025-03-04T15:53:40 | null | CONTRIBUTOR | [] | null | null | false | {
"url": "https://api.github.com/repos/huggingface/datasets/pulls/7426",
"html_url": "https://github.com/huggingface/datasets/pull/7426",
"diff_url": "https://github.com/huggingface/datasets/pull/7426.diff",
"patch_url": "https://github.com/huggingface/datasets/pull/7426.patch",
"merged_at": "2025-03-04T15:53... | Hello!
Pyright flags any use of `load_dataset` as an error, because the default for `trust_remote_code` is `None`, but the function is typed as `bool`, not `Optional[bool]`. I changed the type and docstrings to reflect this, but no other code was touched.
| {
"login": "lhoestq",
"id": 42851186,
"node_id": "MDQ6VXNlcjQyODUxMTg2",
"avatar_url": "https://avatars.githubusercontent.com/u/42851186?v=4",
"gravatar_id": "",
"url": "https://api.github.com/users/lhoestq",
"html_url": "https://github.com/lhoestq",
"followers_url": "https://api.github.com/users/lhoest... | {
"url": "https://api.github.com/repos/huggingface/datasets/issues/7426/reactions",
"total_count": 0,
"+1": 0,
"-1": 0,
"laugh": 0,
"hooray": 0,
"confused": 0,
"heart": 0,
"rocket": 0,
"eyes": 0
} | https://api.github.com/repos/huggingface/datasets/issues/7426/timeline | null | null | null | null | null | true |
https://api.github.com/repos/huggingface/datasets/issues/7425 | https://api.github.com/repos/huggingface/datasets | https://api.github.com/repos/huggingface/datasets/issues/7425/labels{/name} | https://api.github.com/repos/huggingface/datasets/issues/7425/comments | https://api.github.com/repos/huggingface/datasets/issues/7425/events | https://github.com/huggingface/datasets/issues/7425 | 2,883,684,686 | I_kwDODunzps6r4YlO | 7,425 | load_dataset("livecodebench/code_generation_lite", version_tag="release_v2") TypeError: 'NoneType' object is not callable | {
"login": "dshwei",
"id": 42167236,
"node_id": "MDQ6VXNlcjQyMTY3MjM2",
"avatar_url": "https://avatars.githubusercontent.com/u/42167236?v=4",
"gravatar_id": "",
"url": "https://api.github.com/users/dshwei",
"html_url": "https://github.com/dshwei",
"followers_url": "https://api.github.com/users/dshwei/fo... | [] | open | false | [] | null | 10 | 2025-02-27T07:36:02 | 2025-03-27T05:05:33 | null | null | NONE | [] | null | null | null | null | ### Describe the bug
from datasets import load_dataset
lcb_codegen = load_dataset("livecodebench/code_generation_lite", version_tag="release_v2")
or
configs = get_dataset_config_names("livecodebench/code_generation_lite", trust_remote_code=True)
both error:
Traceback (most recent call last):
File "", line 1, in
File... | null | {
"url": "https://api.github.com/repos/huggingface/datasets/issues/7425/reactions",
"total_count": 1,
"+1": 0,
"-1": 0,
"laugh": 0,
"hooray": 0,
"confused": 0,
"heart": 0,
"rocket": 0,
"eyes": 1
} | https://api.github.com/repos/huggingface/datasets/issues/7425/timeline | null | null | {
"total": 0,
"completed": 0,
"percent_completed": 0
} | {
"blocked_by": 0,
"total_blocked_by": 0,
"blocking": 0,
"total_blocking": 0
} | null | false |
https://api.github.com/repos/huggingface/datasets/issues/7424 | https://api.github.com/repos/huggingface/datasets | https://api.github.com/repos/huggingface/datasets/issues/7424/labels{/name} | https://api.github.com/repos/huggingface/datasets/issues/7424/comments | https://api.github.com/repos/huggingface/datasets/issues/7424/events | https://github.com/huggingface/datasets/pull/7424 | 2,882,663,621 | PR_kwDODunzps6Ms1Qx | 7,424 | Faster folder based builder + parquet support + allow repeated media + use torchvideo | {
"login": "lhoestq",
"id": 42851186,
"node_id": "MDQ6VXNlcjQyODUxMTg2",
"avatar_url": "https://avatars.githubusercontent.com/u/42851186?v=4",
"gravatar_id": "",
"url": "https://api.github.com/users/lhoestq",
"html_url": "https://github.com/lhoestq",
"followers_url": "https://api.github.com/users/lhoest... | [] | closed | false | [] | null | 1 | 2025-02-26T19:55:18 | 2025-03-05T18:51:00 | 2025-03-05T17:41:23 | null | MEMBER | [] | null | null | false | {
"url": "https://api.github.com/repos/huggingface/datasets/pulls/7424",
"html_url": "https://github.com/huggingface/datasets/pull/7424",
"diff_url": "https://github.com/huggingface/datasets/pull/7424.diff",
"patch_url": "https://github.com/huggingface/datasets/pull/7424.patch",
"merged_at": "2025-03-05T17:41... | This will be useful for LeRobotDataset (robotics datasets for [lerobot](https://github.com/huggingface/lerobot) based on videos)
Impacted builders:
- ImageFolder
- AudioFolder
- VideoFolder
Improvements:
- faster to stream (got a 5x speed up on an image dataset)
- improved RAM usage
- support for metadata.p... | {
"login": "lhoestq",
"id": 42851186,
"node_id": "MDQ6VXNlcjQyODUxMTg2",
"avatar_url": "https://avatars.githubusercontent.com/u/42851186?v=4",
"gravatar_id": "",
"url": "https://api.github.com/users/lhoestq",
"html_url": "https://github.com/lhoestq",
"followers_url": "https://api.github.com/users/lhoest... | {
"url": "https://api.github.com/repos/huggingface/datasets/issues/7424/reactions",
"total_count": 2,
"+1": 0,
"-1": 0,
"laugh": 0,
"hooray": 0,
"confused": 0,
"heart": 0,
"rocket": 2,
"eyes": 0
} | https://api.github.com/repos/huggingface/datasets/issues/7424/timeline | null | null | null | null | null | true |
https://api.github.com/repos/huggingface/datasets/issues/7423 | https://api.github.com/repos/huggingface/datasets | https://api.github.com/repos/huggingface/datasets/issues/7423/labels{/name} | https://api.github.com/repos/huggingface/datasets/issues/7423/comments | https://api.github.com/repos/huggingface/datasets/issues/7423/events | https://github.com/huggingface/datasets/issues/7423 | 2,879,271,409 | I_kwDODunzps6rnjHx | 7,423 | Row indexing a dataset with numpy integers | {
"login": "DavidRConnell",
"id": 35470740,
"node_id": "MDQ6VXNlcjM1NDcwNzQw",
"avatar_url": "https://avatars.githubusercontent.com/u/35470740?v=4",
"gravatar_id": "",
"url": "https://api.github.com/users/DavidRConnell",
"html_url": "https://github.com/DavidRConnell",
"followers_url": "https://api.githu... | [
{
"id": 1935892871,
"node_id": "MDU6TGFiZWwxOTM1ODkyODcx",
"url": "https://api.github.com/repos/huggingface/datasets/labels/enhancement",
"name": "enhancement",
"color": "a2eeef",
"default": true,
"description": "New feature or request",
"archived_at": null,
"archived_by": null
... | closed | false | [] | null | 1 | 2025-02-25T18:44:45 | 2025-07-28T02:23:17 | 2025-07-28T02:23:17 | null | CONTRIBUTOR | [] | null | null | null | null | ### Feature request
Allow indexing datasets with a scalar numpy integer type.
### Motivation
Indexing a dataset with a scalar numpy.int* object raises a TypeError. This is due to the test in `datasets/formatting/formatting.py:key_to_query_type`
``` python
def key_to_query_type(key: Union[int, slice, range, str, Ite... | {
"login": "DavidRConnell",
"id": 35470740,
"node_id": "MDQ6VXNlcjM1NDcwNzQw",
"avatar_url": "https://avatars.githubusercontent.com/u/35470740?v=4",
"gravatar_id": "",
"url": "https://api.github.com/users/DavidRConnell",
"html_url": "https://github.com/DavidRConnell",
"followers_url": "https://api.githu... | {
"url": "https://api.github.com/repos/huggingface/datasets/issues/7423/reactions",
"total_count": 0,
"+1": 0,
"-1": 0,
"laugh": 0,
"hooray": 0,
"confused": 0,
"heart": 0,
"rocket": 0,
"eyes": 0
} | https://api.github.com/repos/huggingface/datasets/issues/7423/timeline | null | completed | {
"total": 0,
"completed": 0,
"percent_completed": 0
} | {
"blocked_by": 0,
"total_blocked_by": 0,
"blocking": 0,
"total_blocking": 0
} | null | false |
https://api.github.com/repos/huggingface/datasets/issues/7421 | https://api.github.com/repos/huggingface/datasets | https://api.github.com/repos/huggingface/datasets/issues/7421/labels{/name} | https://api.github.com/repos/huggingface/datasets/issues/7421/comments | https://api.github.com/repos/huggingface/datasets/issues/7421/events | https://github.com/huggingface/datasets/issues/7421 | 2,878,369,052 | I_kwDODunzps6rkG0c | 7,421 | DVC integration broken | {
"login": "maxstrobel",
"id": 34747372,
"node_id": "MDQ6VXNlcjM0NzQ3Mzcy",
"avatar_url": "https://avatars.githubusercontent.com/u/34747372?v=4",
"gravatar_id": "",
"url": "https://api.github.com/users/maxstrobel",
"html_url": "https://github.com/maxstrobel",
"followers_url": "https://api.github.com/use... | [] | open | false | [] | null | 1 | 2025-02-25T13:14:31 | 2025-03-03T17:42:02 | null | null | NONE | [] | null | null | null | null | ### Describe the bug
The DVC integration seems to be broken.
Followed this guide: https://dvc.org/doc/user-guide/integrations/huggingface
### Steps to reproduce the bug
#### Script to reproduce
~~~python
from datasets import load_dataset
dataset = load_dataset(
"csv",
data_files="dvc://workshop/satellite-d... | null | {
"url": "https://api.github.com/repos/huggingface/datasets/issues/7421/reactions",
"total_count": 0,
"+1": 0,
"-1": 0,
"laugh": 0,
"hooray": 0,
"confused": 0,
"heart": 0,
"rocket": 0,
"eyes": 0
} | https://api.github.com/repos/huggingface/datasets/issues/7421/timeline | null | null | {
"total": 0,
"completed": 0,
"percent_completed": 0
} | {
"blocked_by": 0,
"total_blocked_by": 0,
"blocking": 0,
"total_blocking": 0
} | null | false |
https://api.github.com/repos/huggingface/datasets/issues/7420 | https://api.github.com/repos/huggingface/datasets | https://api.github.com/repos/huggingface/datasets/issues/7420/labels{/name} | https://api.github.com/repos/huggingface/datasets/issues/7420/comments | https://api.github.com/repos/huggingface/datasets/issues/7420/events | https://github.com/huggingface/datasets/issues/7420 | 2,876,281,928 | I_kwDODunzps6rcJRI | 7,420 | better correspondence between cached and saved datasets created using from_generator | {
"login": "vttrifonov",
"id": 12157034,
"node_id": "MDQ6VXNlcjEyMTU3MDM0",
"avatar_url": "https://avatars.githubusercontent.com/u/12157034?v=4",
"gravatar_id": "",
"url": "https://api.github.com/users/vttrifonov",
"html_url": "https://github.com/vttrifonov",
"followers_url": "https://api.github.com/use... | [
{
"id": 1935892871,
"node_id": "MDU6TGFiZWwxOTM1ODkyODcx",
"url": "https://api.github.com/repos/huggingface/datasets/labels/enhancement",
"name": "enhancement",
"color": "a2eeef",
"default": true,
"description": "New feature or request",
"archived_at": null,
"archived_by": null
... | open | false | [] | null | 3 | 2025-02-24T22:14:37 | 2026-01-05T15:16:35 | null | null | CONTRIBUTOR | [] | null | null | null | null | ### Feature request
At the moment `.from_generator` can only create a dataset that lives in the cache. The cached dataset cannot be loaded with `load_from_disk` because the cache folder is missing `state.json`. So the only way to convert this cached dataset to a regular is to use `save_to_disk` which needs to create a... | null | {
"url": "https://api.github.com/repos/huggingface/datasets/issues/7420/reactions",
"total_count": 0,
"+1": 0,
"-1": 0,
"laugh": 0,
"hooray": 0,
"confused": 0,
"heart": 0,
"rocket": 0,
"eyes": 0
} | https://api.github.com/repos/huggingface/datasets/issues/7420/timeline | null | null | {
"total": 0,
"completed": 0,
"percent_completed": 0
} | {
"blocked_by": 0,
"total_blocked_by": 0,
"blocking": 0,
"total_blocking": 0
} | null | false |
https://api.github.com/repos/huggingface/datasets/issues/7419 | https://api.github.com/repos/huggingface/datasets | https://api.github.com/repos/huggingface/datasets/issues/7419/labels{/name} | https://api.github.com/repos/huggingface/datasets/issues/7419/comments | https://api.github.com/repos/huggingface/datasets/issues/7419/events | https://github.com/huggingface/datasets/issues/7419 | 2,875,635,320 | I_kwDODunzps6rZrZ4 | 7,419 | Import order crashes script execution | {
"login": "DamienMatias",
"id": 23298479,
"node_id": "MDQ6VXNlcjIzMjk4NDc5",
"avatar_url": "https://avatars.githubusercontent.com/u/23298479?v=4",
"gravatar_id": "",
"url": "https://api.github.com/users/DamienMatias",
"html_url": "https://github.com/DamienMatias",
"followers_url": "https://api.github.c... | [] | open | false | [] | null | 0 | 2025-02-24T17:03:43 | 2025-02-24T17:03:43 | null | null | NONE | [] | null | null | null | null | ### Describe the bug
Hello,
I'm trying to convert an HF dataset into a TFRecord so I'm importing `tensorflow` and `datasets` to do so.
Depending in what order I'm importing those librairies, my code hangs forever and is unkillable (CTRL+C doesn't work, I need to kill my shell entirely).
Thank you for your help
🙏
... | null | {
"url": "https://api.github.com/repos/huggingface/datasets/issues/7419/reactions",
"total_count": 0,
"+1": 0,
"-1": 0,
"laugh": 0,
"hooray": 0,
"confused": 0,
"heart": 0,
"rocket": 0,
"eyes": 0
} | https://api.github.com/repos/huggingface/datasets/issues/7419/timeline | null | null | {
"total": 0,
"completed": 0,
"percent_completed": 0
} | {
"blocked_by": 0,
"total_blocked_by": 0,
"blocking": 0,
"total_blocking": 0
} | null | false |
https://api.github.com/repos/huggingface/datasets/issues/7418 | https://api.github.com/repos/huggingface/datasets | https://api.github.com/repos/huggingface/datasets/issues/7418/labels{/name} | https://api.github.com/repos/huggingface/datasets/issues/7418/comments | https://api.github.com/repos/huggingface/datasets/issues/7418/events | https://github.com/huggingface/datasets/issues/7418 | 2,868,701,471 | I_kwDODunzps6q_Okf | 7,418 | pyarrow.lib.arrowinvalid: cannot mix list and non-list, non-null values with map function | {
"login": "alexxchen",
"id": 15705569,
"node_id": "MDQ6VXNlcjE1NzA1NTY5",
"avatar_url": "https://avatars.githubusercontent.com/u/15705569?v=4",
"gravatar_id": "",
"url": "https://api.github.com/users/alexxchen",
"html_url": "https://github.com/alexxchen",
"followers_url": "https://api.github.com/users/... | [] | closed | false | [] | null | 7 | 2025-02-21T10:58:06 | 2026-03-09T15:58:00 | 2026-03-09T15:58:00 | null | NONE | [] | null | null | null | null | ### Describe the bug
Encounter pyarrow.lib.arrowinvalid error with map function in some example when loading the dataset
### Steps to reproduce the bug
```
from datasets import load_dataset
from PIL import Image, PngImagePlugin
dataset = load_dataset("leonardPKU/GEOQA_R1V_Train_8K")
system_prompt="You are a helpful... | {
"login": "lhoestq",
"id": 42851186,
"node_id": "MDQ6VXNlcjQyODUxMTg2",
"avatar_url": "https://avatars.githubusercontent.com/u/42851186?v=4",
"gravatar_id": "",
"url": "https://api.github.com/users/lhoestq",
"html_url": "https://github.com/lhoestq",
"followers_url": "https://api.github.com/users/lhoest... | {
"url": "https://api.github.com/repos/huggingface/datasets/issues/7418/reactions",
"total_count": 0,
"+1": 0,
"-1": 0,
"laugh": 0,
"hooray": 0,
"confused": 0,
"heart": 0,
"rocket": 0,
"eyes": 0
} | https://api.github.com/repos/huggingface/datasets/issues/7418/timeline | null | completed | {
"total": 0,
"completed": 0,
"percent_completed": 0
} | {
"blocked_by": 0,
"total_blocked_by": 0,
"blocking": 0,
"total_blocking": 0
} | null | false |
https://api.github.com/repos/huggingface/datasets/issues/7417 | https://api.github.com/repos/huggingface/datasets | https://api.github.com/repos/huggingface/datasets/issues/7417/labels{/name} | https://api.github.com/repos/huggingface/datasets/issues/7417/comments | https://api.github.com/repos/huggingface/datasets/issues/7417/events | https://github.com/huggingface/datasets/pull/7417 | 2,866,868,922 | PR_kwDODunzps6L78k3 | 7,417 | set dev version | {
"login": "lhoestq",
"id": 42851186,
"node_id": "MDQ6VXNlcjQyODUxMTg2",
"avatar_url": "https://avatars.githubusercontent.com/u/42851186?v=4",
"gravatar_id": "",
"url": "https://api.github.com/users/lhoestq",
"html_url": "https://github.com/lhoestq",
"followers_url": "https://api.github.com/users/lhoest... | [] | closed | false | [] | null | 1 | 2025-02-20T17:45:29 | 2025-02-20T17:47:50 | 2025-02-20T17:45:36 | null | MEMBER | [] | null | null | false | {
"url": "https://api.github.com/repos/huggingface/datasets/pulls/7417",
"html_url": "https://github.com/huggingface/datasets/pull/7417",
"diff_url": "https://github.com/huggingface/datasets/pull/7417.diff",
"patch_url": "https://github.com/huggingface/datasets/pull/7417.patch",
"merged_at": "2025-02-20T17:45... | null | {
"login": "lhoestq",
"id": 42851186,
"node_id": "MDQ6VXNlcjQyODUxMTg2",
"avatar_url": "https://avatars.githubusercontent.com/u/42851186?v=4",
"gravatar_id": "",
"url": "https://api.github.com/users/lhoestq",
"html_url": "https://github.com/lhoestq",
"followers_url": "https://api.github.com/users/lhoest... | {
"url": "https://api.github.com/repos/huggingface/datasets/issues/7417/reactions",
"total_count": 0,
"+1": 0,
"-1": 0,
"laugh": 0,
"hooray": 0,
"confused": 0,
"heart": 0,
"rocket": 0,
"eyes": 0
} | https://api.github.com/repos/huggingface/datasets/issues/7417/timeline | null | null | null | null | null | true |
https://api.github.com/repos/huggingface/datasets/issues/7416 | https://api.github.com/repos/huggingface/datasets | https://api.github.com/repos/huggingface/datasets/issues/7416/labels{/name} | https://api.github.com/repos/huggingface/datasets/issues/7416/comments | https://api.github.com/repos/huggingface/datasets/issues/7416/events | https://github.com/huggingface/datasets/pull/7416 | 2,866,862,143 | PR_kwDODunzps6L77G2 | 7,416 | Release: 3.3.2 | {
"login": "lhoestq",
"id": 42851186,
"node_id": "MDQ6VXNlcjQyODUxMTg2",
"avatar_url": "https://avatars.githubusercontent.com/u/42851186?v=4",
"gravatar_id": "",
"url": "https://api.github.com/users/lhoestq",
"html_url": "https://github.com/lhoestq",
"followers_url": "https://api.github.com/users/lhoest... | [] | closed | false | [] | null | 1 | 2025-02-20T17:42:11 | 2025-02-20T17:44:35 | 2025-02-20T17:43:28 | null | MEMBER | [] | null | null | false | {
"url": "https://api.github.com/repos/huggingface/datasets/pulls/7416",
"html_url": "https://github.com/huggingface/datasets/pull/7416",
"diff_url": "https://github.com/huggingface/datasets/pull/7416.diff",
"patch_url": "https://github.com/huggingface/datasets/pull/7416.patch",
"merged_at": "2025-02-20T17:43... | null | {
"login": "lhoestq",
"id": 42851186,
"node_id": "MDQ6VXNlcjQyODUxMTg2",
"avatar_url": "https://avatars.githubusercontent.com/u/42851186?v=4",
"gravatar_id": "",
"url": "https://api.github.com/users/lhoestq",
"html_url": "https://github.com/lhoestq",
"followers_url": "https://api.github.com/users/lhoest... | {
"url": "https://api.github.com/repos/huggingface/datasets/issues/7416/reactions",
"total_count": 0,
"+1": 0,
"-1": 0,
"laugh": 0,
"hooray": 0,
"confused": 0,
"heart": 0,
"rocket": 0,
"eyes": 0
} | https://api.github.com/repos/huggingface/datasets/issues/7416/timeline | null | null | null | null | null | true |
https://api.github.com/repos/huggingface/datasets/issues/7415 | https://api.github.com/repos/huggingface/datasets | https://api.github.com/repos/huggingface/datasets/issues/7415/labels{/name} | https://api.github.com/repos/huggingface/datasets/issues/7415/comments | https://api.github.com/repos/huggingface/datasets/issues/7415/events | https://github.com/huggingface/datasets/issues/7415 | 2,865,774,546 | I_kwDODunzps6q0D_S | 7,415 | Shard Dataset at specific indices | {
"login": "nikonikolov",
"id": 11044035,
"node_id": "MDQ6VXNlcjExMDQ0MDM1",
"avatar_url": "https://avatars.githubusercontent.com/u/11044035?v=4",
"gravatar_id": "",
"url": "https://api.github.com/users/nikonikolov",
"html_url": "https://github.com/nikonikolov",
"followers_url": "https://api.github.com/... | [] | open | false | [] | null | 3 | 2025-02-20T10:43:10 | 2025-02-24T11:06:45 | null | null | NONE | [] | null | null | null | null | I have a dataset of sequences, where each example in the sequence is a separate row in the dataset (similar to LeRobotDataset). When running `Dataset.save_to_disk` how can I provide indices where it's possible to shard the dataset such that no episode spans more than 1 shard. Consequently, when I run `Dataset.load_from... | null | {
"url": "https://api.github.com/repos/huggingface/datasets/issues/7415/reactions",
"total_count": 0,
"+1": 0,
"-1": 0,
"laugh": 0,
"hooray": 0,
"confused": 0,
"heart": 0,
"rocket": 0,
"eyes": 0
} | https://api.github.com/repos/huggingface/datasets/issues/7415/timeline | null | null | {
"total": 0,
"completed": 0,
"percent_completed": 0
} | {
"blocked_by": 0,
"total_blocked_by": 0,
"blocking": 0,
"total_blocking": 0
} | null | false |
https://api.github.com/repos/huggingface/datasets/issues/7414 | https://api.github.com/repos/huggingface/datasets | https://api.github.com/repos/huggingface/datasets/issues/7414/labels{/name} | https://api.github.com/repos/huggingface/datasets/issues/7414/comments | https://api.github.com/repos/huggingface/datasets/issues/7414/events | https://github.com/huggingface/datasets/pull/7414 | 2,863,798,756 | PR_kwDODunzps6LxjsH | 7,414 | Gracefully cancel async tasks | {
"login": "lhoestq",
"id": 42851186,
"node_id": "MDQ6VXNlcjQyODUxMTg2",
"avatar_url": "https://avatars.githubusercontent.com/u/42851186?v=4",
"gravatar_id": "",
"url": "https://api.github.com/users/lhoestq",
"html_url": "https://github.com/lhoestq",
"followers_url": "https://api.github.com/users/lhoest... | [] | closed | false | [] | null | 1 | 2025-02-19T16:10:58 | 2025-02-20T14:12:26 | 2025-02-20T14:12:23 | null | MEMBER | [] | null | null | false | {
"url": "https://api.github.com/repos/huggingface/datasets/pulls/7414",
"html_url": "https://github.com/huggingface/datasets/pull/7414",
"diff_url": "https://github.com/huggingface/datasets/pull/7414.diff",
"patch_url": "https://github.com/huggingface/datasets/pull/7414.patch",
"merged_at": "2025-02-20T14:12... | null | {
"login": "lhoestq",
"id": 42851186,
"node_id": "MDQ6VXNlcjQyODUxMTg2",
"avatar_url": "https://avatars.githubusercontent.com/u/42851186?v=4",
"gravatar_id": "",
"url": "https://api.github.com/users/lhoestq",
"html_url": "https://github.com/lhoestq",
"followers_url": "https://api.github.com/users/lhoest... | {
"url": "https://api.github.com/repos/huggingface/datasets/issues/7414/reactions",
"total_count": 0,
"+1": 0,
"-1": 0,
"laugh": 0,
"hooray": 0,
"confused": 0,
"heart": 0,
"rocket": 0,
"eyes": 0
} | https://api.github.com/repos/huggingface/datasets/issues/7414/timeline | null | null | null | null | null | true |
https://api.github.com/repos/huggingface/datasets/issues/7413 | https://api.github.com/repos/huggingface/datasets | https://api.github.com/repos/huggingface/datasets/issues/7413/labels{/name} | https://api.github.com/repos/huggingface/datasets/issues/7413/comments | https://api.github.com/repos/huggingface/datasets/issues/7413/events | https://github.com/huggingface/datasets/issues/7413 | 2,860,947,582 | I_kwDODunzps6qhph- | 7,413 | Documentation on multiple media files of the same type with WebDataset | {
"login": "DCNemesis",
"id": 3616964,
"node_id": "MDQ6VXNlcjM2MTY5NjQ=",
"avatar_url": "https://avatars.githubusercontent.com/u/3616964?v=4",
"gravatar_id": "",
"url": "https://api.github.com/users/DCNemesis",
"html_url": "https://github.com/DCNemesis",
"followers_url": "https://api.github.com/users/DC... | [] | open | false | [] | null | 1 | 2025-02-18T16:13:20 | 2025-02-20T14:17:54 | null | null | NONE | [] | null | null | null | null | The [current documentation](https://huggingface.co/docs/datasets/en/video_dataset) on a creating a video dataset includes only examples with one media file and one json. It would be useful to have examples where multiple files of the same type are included. For example, in a sign language dataset, you may have a base v... | null | {
"url": "https://api.github.com/repos/huggingface/datasets/issues/7413/reactions",
"total_count": 0,
"+1": 0,
"-1": 0,
"laugh": 0,
"hooray": 0,
"confused": 0,
"heart": 0,
"rocket": 0,
"eyes": 0
} | https://api.github.com/repos/huggingface/datasets/issues/7413/timeline | null | null | {
"total": 0,
"completed": 0,
"percent_completed": 0
} | {
"blocked_by": 0,
"total_blocked_by": 0,
"blocking": 0,
"total_blocking": 0
} | null | false |
https://api.github.com/repos/huggingface/datasets/issues/7412 | https://api.github.com/repos/huggingface/datasets | https://api.github.com/repos/huggingface/datasets/issues/7412/labels{/name} | https://api.github.com/repos/huggingface/datasets/issues/7412/comments | https://api.github.com/repos/huggingface/datasets/issues/7412/events | https://github.com/huggingface/datasets/issues/7412 | 2,859,433,710 | I_kwDODunzps6qb37u | 7,412 | Index Error Invalid Ket is out of bounds for size 0 for code-search-net/code_search_net dataset | {
"login": "harshakhmk",
"id": 56113657,
"node_id": "MDQ6VXNlcjU2MTEzNjU3",
"avatar_url": "https://avatars.githubusercontent.com/u/56113657?v=4",
"gravatar_id": "",
"url": "https://api.github.com/users/harshakhmk",
"html_url": "https://github.com/harshakhmk",
"followers_url": "https://api.github.com/use... | [] | open | false | [] | null | 0 | 2025-02-18T05:58:33 | 2025-02-18T06:42:07 | null | null | NONE | [] | null | null | null | null | ### Describe the bug
I am trying to do model pruning on sentence-transformers/all-mini-L6-v2 for the code-search-net/code_search_net dataset using INCTrainer class
However I am getting below error
```
raise IndexError(f"Invalid Key: {key is our of bounds for size {size}")
IndexError: Invalid key: 1840208 is out of b... | null | {
"url": "https://api.github.com/repos/huggingface/datasets/issues/7412/reactions",
"total_count": 0,
"+1": 0,
"-1": 0,
"laugh": 0,
"hooray": 0,
"confused": 0,
"heart": 0,
"rocket": 0,
"eyes": 0
} | https://api.github.com/repos/huggingface/datasets/issues/7412/timeline | null | null | {
"total": 0,
"completed": 0,
"percent_completed": 0
} | {
"blocked_by": 0,
"total_blocked_by": 0,
"blocking": 0,
"total_blocking": 0
} | null | false |
https://api.github.com/repos/huggingface/datasets/issues/7411 | https://api.github.com/repos/huggingface/datasets | https://api.github.com/repos/huggingface/datasets/issues/7411/labels{/name} | https://api.github.com/repos/huggingface/datasets/issues/7411/comments | https://api.github.com/repos/huggingface/datasets/issues/7411/events | https://github.com/huggingface/datasets/pull/7411 | 2,858,993,390 | PR_kwDODunzps6LhV0Z | 7,411 | Attempt to fix multiprocessing hang by closing and joining the pool before termination | {
"login": "dakinggg",
"id": 43149077,
"node_id": "MDQ6VXNlcjQzMTQ5MDc3",
"avatar_url": "https://avatars.githubusercontent.com/u/43149077?v=4",
"gravatar_id": "",
"url": "https://api.github.com/users/dakinggg",
"html_url": "https://github.com/dakinggg",
"followers_url": "https://api.github.com/users/dak... | [] | closed | false | [] | null | 3 | 2025-02-17T23:58:03 | 2025-02-19T21:11:24 | 2025-02-19T13:40:32 | null | CONTRIBUTOR | [] | null | null | false | {
"url": "https://api.github.com/repos/huggingface/datasets/pulls/7411",
"html_url": "https://github.com/huggingface/datasets/pull/7411",
"diff_url": "https://github.com/huggingface/datasets/pull/7411.diff",
"patch_url": "https://github.com/huggingface/datasets/pull/7411.patch",
"merged_at": "2025-02-19T13:40... | https://github.com/huggingface/datasets/issues/6393 has plagued me on and off for a very long time. I have had various workarounds (one time combining two filter calls into one filter call removed the issue, another time making rank 0 go first resolved a cache race condition, one time i think upgrading the version of s... | {
"login": "lhoestq",
"id": 42851186,
"node_id": "MDQ6VXNlcjQyODUxMTg2",
"avatar_url": "https://avatars.githubusercontent.com/u/42851186?v=4",
"gravatar_id": "",
"url": "https://api.github.com/users/lhoestq",
"html_url": "https://github.com/lhoestq",
"followers_url": "https://api.github.com/users/lhoest... | {
"url": "https://api.github.com/repos/huggingface/datasets/issues/7411/reactions",
"total_count": 0,
"+1": 0,
"-1": 0,
"laugh": 0,
"hooray": 0,
"confused": 0,
"heart": 0,
"rocket": 0,
"eyes": 0
} | https://api.github.com/repos/huggingface/datasets/issues/7411/timeline | null | null | null | null | null | true |
https://api.github.com/repos/huggingface/datasets/issues/7410 | https://api.github.com/repos/huggingface/datasets | https://api.github.com/repos/huggingface/datasets/issues/7410/labels{/name} | https://api.github.com/repos/huggingface/datasets/issues/7410/comments | https://api.github.com/repos/huggingface/datasets/issues/7410/events | https://github.com/huggingface/datasets/pull/7410 | 2,858,085,707 | PR_kwDODunzps6LeQBF | 7,410 | Set dev version | {
"login": "lhoestq",
"id": 42851186,
"node_id": "MDQ6VXNlcjQyODUxMTg2",
"avatar_url": "https://avatars.githubusercontent.com/u/42851186?v=4",
"gravatar_id": "",
"url": "https://api.github.com/users/lhoestq",
"html_url": "https://github.com/lhoestq",
"followers_url": "https://api.github.com/users/lhoest... | [] | closed | false | [] | null | 1 | 2025-02-17T14:54:39 | 2025-02-17T14:56:58 | 2025-02-17T14:54:56 | null | MEMBER | [] | null | null | false | {
"url": "https://api.github.com/repos/huggingface/datasets/pulls/7410",
"html_url": "https://github.com/huggingface/datasets/pull/7410",
"diff_url": "https://github.com/huggingface/datasets/pull/7410.diff",
"patch_url": "https://github.com/huggingface/datasets/pull/7410.patch",
"merged_at": "2025-02-17T14:54... | null | {
"login": "lhoestq",
"id": 42851186,
"node_id": "MDQ6VXNlcjQyODUxMTg2",
"avatar_url": "https://avatars.githubusercontent.com/u/42851186?v=4",
"gravatar_id": "",
"url": "https://api.github.com/users/lhoestq",
"html_url": "https://github.com/lhoestq",
"followers_url": "https://api.github.com/users/lhoest... | {
"url": "https://api.github.com/repos/huggingface/datasets/issues/7410/reactions",
"total_count": 0,
"+1": 0,
"-1": 0,
"laugh": 0,
"hooray": 0,
"confused": 0,
"heart": 0,
"rocket": 0,
"eyes": 0
} | https://api.github.com/repos/huggingface/datasets/issues/7410/timeline | null | null | null | null | null | true |
https://api.github.com/repos/huggingface/datasets/issues/7409 | https://api.github.com/repos/huggingface/datasets | https://api.github.com/repos/huggingface/datasets/issues/7409/labels{/name} | https://api.github.com/repos/huggingface/datasets/issues/7409/comments | https://api.github.com/repos/huggingface/datasets/issues/7409/events | https://github.com/huggingface/datasets/pull/7409 | 2,858,079,508 | PR_kwDODunzps6LeOpY | 7,409 | Release: 3.3.1 | {
"login": "lhoestq",
"id": 42851186,
"node_id": "MDQ6VXNlcjQyODUxMTg2",
"avatar_url": "https://avatars.githubusercontent.com/u/42851186?v=4",
"gravatar_id": "",
"url": "https://api.github.com/users/lhoestq",
"html_url": "https://github.com/lhoestq",
"followers_url": "https://api.github.com/users/lhoest... | [] | closed | false | [] | null | 1 | 2025-02-17T14:52:12 | 2025-02-17T14:54:32 | 2025-02-17T14:53:13 | null | MEMBER | [] | null | null | false | {
"url": "https://api.github.com/repos/huggingface/datasets/pulls/7409",
"html_url": "https://github.com/huggingface/datasets/pull/7409",
"diff_url": "https://github.com/huggingface/datasets/pull/7409.diff",
"patch_url": "https://github.com/huggingface/datasets/pull/7409.patch",
"merged_at": "2025-02-17T14:53... | null | {
"login": "lhoestq",
"id": 42851186,
"node_id": "MDQ6VXNlcjQyODUxMTg2",
"avatar_url": "https://avatars.githubusercontent.com/u/42851186?v=4",
"gravatar_id": "",
"url": "https://api.github.com/users/lhoestq",
"html_url": "https://github.com/lhoestq",
"followers_url": "https://api.github.com/users/lhoest... | {
"url": "https://api.github.com/repos/huggingface/datasets/issues/7409/reactions",
"total_count": 0,
"+1": 0,
"-1": 0,
"laugh": 0,
"hooray": 0,
"confused": 0,
"heart": 0,
"rocket": 0,
"eyes": 0
} | https://api.github.com/repos/huggingface/datasets/issues/7409/timeline | null | null | null | null | null | true |
https://api.github.com/repos/huggingface/datasets/issues/7408 | https://api.github.com/repos/huggingface/datasets | https://api.github.com/repos/huggingface/datasets/issues/7408/labels{/name} | https://api.github.com/repos/huggingface/datasets/issues/7408/comments | https://api.github.com/repos/huggingface/datasets/issues/7408/events | https://github.com/huggingface/datasets/pull/7408 | 2,858,012,313 | PR_kwDODunzps6Ld_-m | 7,408 | Fix filter speed regression | {
"login": "lhoestq",
"id": 42851186,
"node_id": "MDQ6VXNlcjQyODUxMTg2",
"avatar_url": "https://avatars.githubusercontent.com/u/42851186?v=4",
"gravatar_id": "",
"url": "https://api.github.com/users/lhoestq",
"html_url": "https://github.com/lhoestq",
"followers_url": "https://api.github.com/users/lhoest... | [] | closed | false | [] | null | 1 | 2025-02-17T14:25:32 | 2025-02-17T14:28:48 | 2025-02-17T14:28:46 | null | MEMBER | [] | null | null | false | {
"url": "https://api.github.com/repos/huggingface/datasets/pulls/7408",
"html_url": "https://github.com/huggingface/datasets/pull/7408",
"diff_url": "https://github.com/huggingface/datasets/pull/7408.diff",
"patch_url": "https://github.com/huggingface/datasets/pull/7408.patch",
"merged_at": "2025-02-17T14:28... | close https://github.com/huggingface/datasets/issues/7404 | {
"login": "lhoestq",
"id": 42851186,
"node_id": "MDQ6VXNlcjQyODUxMTg2",
"avatar_url": "https://avatars.githubusercontent.com/u/42851186?v=4",
"gravatar_id": "",
"url": "https://api.github.com/users/lhoestq",
"html_url": "https://github.com/lhoestq",
"followers_url": "https://api.github.com/users/lhoest... | {
"url": "https://api.github.com/repos/huggingface/datasets/issues/7408/reactions",
"total_count": 0,
"+1": 0,
"-1": 0,
"laugh": 0,
"hooray": 0,
"confused": 0,
"heart": 0,
"rocket": 0,
"eyes": 0
} | https://api.github.com/repos/huggingface/datasets/issues/7408/timeline | null | null | null | null | null | true |
https://api.github.com/repos/huggingface/datasets/issues/7407 | https://api.github.com/repos/huggingface/datasets | https://api.github.com/repos/huggingface/datasets/issues/7407/labels{/name} | https://api.github.com/repos/huggingface/datasets/issues/7407/comments | https://api.github.com/repos/huggingface/datasets/issues/7407/events | https://github.com/huggingface/datasets/pull/7407 | 2,856,517,442 | PR_kwDODunzps6LY7y5 | 7,407 | Update use_with_pandas.mdx: to_pandas() correction in last section | {
"login": "ibarrien",
"id": 7552335,
"node_id": "MDQ6VXNlcjc1NTIzMzU=",
"avatar_url": "https://avatars.githubusercontent.com/u/7552335?v=4",
"gravatar_id": "",
"url": "https://api.github.com/users/ibarrien",
"html_url": "https://github.com/ibarrien",
"followers_url": "https://api.github.com/users/ibarr... | [] | closed | false | [] | null | 0 | 2025-02-17T01:53:31 | 2025-02-20T17:28:04 | 2025-02-20T17:28:04 | null | CONTRIBUTOR | [] | null | null | false | {
"url": "https://api.github.com/repos/huggingface/datasets/pulls/7407",
"html_url": "https://github.com/huggingface/datasets/pull/7407",
"diff_url": "https://github.com/huggingface/datasets/pull/7407.diff",
"patch_url": "https://github.com/huggingface/datasets/pull/7407.patch",
"merged_at": "2025-02-20T17:28... | last section ``to_pandas()" | {
"login": "lhoestq",
"id": 42851186,
"node_id": "MDQ6VXNlcjQyODUxMTg2",
"avatar_url": "https://avatars.githubusercontent.com/u/42851186?v=4",
"gravatar_id": "",
"url": "https://api.github.com/users/lhoestq",
"html_url": "https://github.com/lhoestq",
"followers_url": "https://api.github.com/users/lhoest... | {
"url": "https://api.github.com/repos/huggingface/datasets/issues/7407/reactions",
"total_count": 0,
"+1": 0,
"-1": 0,
"laugh": 0,
"hooray": 0,
"confused": 0,
"heart": 0,
"rocket": 0,
"eyes": 0
} | https://api.github.com/repos/huggingface/datasets/issues/7407/timeline | null | null | null | null | null | true |
https://api.github.com/repos/huggingface/datasets/issues/7406 | https://api.github.com/repos/huggingface/datasets | https://api.github.com/repos/huggingface/datasets/issues/7406/labels{/name} | https://api.github.com/repos/huggingface/datasets/issues/7406/comments | https://api.github.com/repos/huggingface/datasets/issues/7406/events | https://github.com/huggingface/datasets/issues/7406 | 2,856,441,206 | I_kwDODunzps6qQdV2 | 7,406 | Adding Core Maintainer List to CONTRIBUTING.md | {
"login": "jp1924",
"id": 93233241,
"node_id": "U_kgDOBY6gWQ",
"avatar_url": "https://avatars.githubusercontent.com/u/93233241?v=4",
"gravatar_id": "",
"url": "https://api.github.com/users/jp1924",
"html_url": "https://github.com/jp1924",
"followers_url": "https://api.github.com/users/jp1924/followers"... | [
{
"id": 1935892871,
"node_id": "MDU6TGFiZWwxOTM1ODkyODcx",
"url": "https://api.github.com/repos/huggingface/datasets/labels/enhancement",
"name": "enhancement",
"color": "a2eeef",
"default": true,
"description": "New feature or request",
"archived_at": null,
"archived_by": null
... | closed | false | [] | null | 3 | 2025-02-17T00:32:40 | 2025-03-24T10:57:54 | 2025-03-24T10:57:54 | null | CONTRIBUTOR | [] | null | null | null | null | ### Feature request
I propose adding a core maintainer list to the `CONTRIBUTING.md` file.
### Motivation
The Transformers and Liger-Kernel projects maintain lists of core maintainers for each module.
However, the Datasets project doesn't have such a list.
### Your contribution
I have nothing to add here. | {
"login": "jp1924",
"id": 93233241,
"node_id": "U_kgDOBY6gWQ",
"avatar_url": "https://avatars.githubusercontent.com/u/93233241?v=4",
"gravatar_id": "",
"url": "https://api.github.com/users/jp1924",
"html_url": "https://github.com/jp1924",
"followers_url": "https://api.github.com/users/jp1924/followers"... | {
"url": "https://api.github.com/repos/huggingface/datasets/issues/7406/reactions",
"total_count": 0,
"+1": 0,
"-1": 0,
"laugh": 0,
"hooray": 0,
"confused": 0,
"heart": 0,
"rocket": 0,
"eyes": 0
} | https://api.github.com/repos/huggingface/datasets/issues/7406/timeline | null | completed | {
"total": 0,
"completed": 0,
"percent_completed": 0
} | {
"blocked_by": 0,
"total_blocked_by": 0,
"blocking": 0,
"total_blocking": 0
} | null | false |
https://api.github.com/repos/huggingface/datasets/issues/7405 | https://api.github.com/repos/huggingface/datasets | https://api.github.com/repos/huggingface/datasets/issues/7405/labels{/name} | https://api.github.com/repos/huggingface/datasets/issues/7405/comments | https://api.github.com/repos/huggingface/datasets/issues/7405/events | https://github.com/huggingface/datasets/issues/7405 | 2,856,372,814 | I_kwDODunzps6qQMpO | 7,405 | Lazy loading of environment variables | {
"login": "nikvaessen",
"id": 7225987,
"node_id": "MDQ6VXNlcjcyMjU5ODc=",
"avatar_url": "https://avatars.githubusercontent.com/u/7225987?v=4",
"gravatar_id": "",
"url": "https://api.github.com/users/nikvaessen",
"html_url": "https://github.com/nikvaessen",
"followers_url": "https://api.github.com/users... | [] | open | false | [] | null | 1 | 2025-02-16T22:31:41 | 2025-02-17T15:17:18 | null | null | NONE | [] | null | null | null | null | ### Describe the bug
Loading a `.env` file after an `import datasets` call does not correctly use the environment variables.
This is due the fact that environment variables are read at import time:
https://github.com/huggingface/datasets/blob/de062f0552a810c52077543c1169c38c1f0c53fc/src/datasets/config.py#L155C1-L15... | null | {
"url": "https://api.github.com/repos/huggingface/datasets/issues/7405/reactions",
"total_count": 0,
"+1": 0,
"-1": 0,
"laugh": 0,
"hooray": 0,
"confused": 0,
"heart": 0,
"rocket": 0,
"eyes": 0
} | https://api.github.com/repos/huggingface/datasets/issues/7405/timeline | null | null | {
"total": 0,
"completed": 0,
"percent_completed": 0
} | {
"blocked_by": 0,
"total_blocked_by": 0,
"blocking": 0,
"total_blocking": 0
} | null | false |
https://api.github.com/repos/huggingface/datasets/issues/7404 | https://api.github.com/repos/huggingface/datasets | https://api.github.com/repos/huggingface/datasets/issues/7404/labels{/name} | https://api.github.com/repos/huggingface/datasets/issues/7404/comments | https://api.github.com/repos/huggingface/datasets/issues/7404/events | https://github.com/huggingface/datasets/issues/7404 | 2,856,366,207 | I_kwDODunzps6qQLB_ | 7,404 | Performance regression in `dataset.filter` | {
"login": "ttim",
"id": 82200,
"node_id": "MDQ6VXNlcjgyMjAw",
"avatar_url": "https://avatars.githubusercontent.com/u/82200?v=4",
"gravatar_id": "",
"url": "https://api.github.com/users/ttim",
"html_url": "https://github.com/ttim",
"followers_url": "https://api.github.com/users/ttim/followers",
"follo... | [] | closed | false | [
{
"login": "lhoestq",
"id": 42851186,
"node_id": "MDQ6VXNlcjQyODUxMTg2",
"avatar_url": "https://avatars.githubusercontent.com/u/42851186?v=4",
"gravatar_id": "",
"url": "https://api.github.com/users/lhoestq",
"html_url": "https://github.com/lhoestq",
"followers_url": "https://api.git... | null | 3 | 2025-02-16T22:19:14 | 2025-02-17T17:46:06 | 2025-02-17T14:28:48 | {
"login": "lhoestq",
"id": 42851186,
"node_id": "MDQ6VXNlcjQyODUxMTg2",
"avatar_url": "https://avatars.githubusercontent.com/u/42851186?v=4",
"gravatar_id": "",
"url": "https://api.github.com/users/lhoestq",
"html_url": "https://github.com/lhoestq",
"followers_url": "https://api.github.com/users/lhoest... | NONE | [] | null | null | null | null | ### Describe the bug
We're filtering dataset of ~1M (small-ish) records. At some point in the code we do `dataset.filter`, before (including 3.2.0) it was taking couple of seconds, and now it takes 4 hours.
We use 16 threads/workers, and stack trace at them look as follows:
```
Traceback (most recent call last):
Fi... | {
"login": "lhoestq",
"id": 42851186,
"node_id": "MDQ6VXNlcjQyODUxMTg2",
"avatar_url": "https://avatars.githubusercontent.com/u/42851186?v=4",
"gravatar_id": "",
"url": "https://api.github.com/users/lhoestq",
"html_url": "https://github.com/lhoestq",
"followers_url": "https://api.github.com/users/lhoest... | {
"url": "https://api.github.com/repos/huggingface/datasets/issues/7404/reactions",
"total_count": 0,
"+1": 0,
"-1": 0,
"laugh": 0,
"hooray": 0,
"confused": 0,
"heart": 0,
"rocket": 0,
"eyes": 0
} | https://api.github.com/repos/huggingface/datasets/issues/7404/timeline | null | completed | {
"total": 0,
"completed": 0,
"percent_completed": 0
} | {
"blocked_by": 0,
"total_blocked_by": 0,
"blocking": 0,
"total_blocking": 0
} | null | false |
https://api.github.com/repos/huggingface/datasets/issues/7402 | https://api.github.com/repos/huggingface/datasets | https://api.github.com/repos/huggingface/datasets/issues/7402/labels{/name} | https://api.github.com/repos/huggingface/datasets/issues/7402/comments | https://api.github.com/repos/huggingface/datasets/issues/7402/events | https://github.com/huggingface/datasets/pull/7402 | 2,855,880,858 | PR_kwDODunzps6LW8G3 | 7,402 | Fix a typo in arrow_dataset.py | {
"login": "jingedawang",
"id": 7996256,
"node_id": "MDQ6VXNlcjc5OTYyNTY=",
"avatar_url": "https://avatars.githubusercontent.com/u/7996256?v=4",
"gravatar_id": "",
"url": "https://api.github.com/users/jingedawang",
"html_url": "https://github.com/jingedawang",
"followers_url": "https://api.github.com/us... | [] | closed | false | [] | null | 0 | 2025-02-16T04:52:02 | 2025-02-20T17:29:28 | 2025-02-20T17:29:28 | null | CONTRIBUTOR | [] | null | null | false | {
"url": "https://api.github.com/repos/huggingface/datasets/pulls/7402",
"html_url": "https://github.com/huggingface/datasets/pull/7402",
"diff_url": "https://github.com/huggingface/datasets/pull/7402.diff",
"patch_url": "https://github.com/huggingface/datasets/pull/7402.patch",
"merged_at": "2025-02-20T17:29... | "in the feature" should be "in the future" | {
"login": "lhoestq",
"id": 42851186,
"node_id": "MDQ6VXNlcjQyODUxMTg2",
"avatar_url": "https://avatars.githubusercontent.com/u/42851186?v=4",
"gravatar_id": "",
"url": "https://api.github.com/users/lhoestq",
"html_url": "https://github.com/lhoestq",
"followers_url": "https://api.github.com/users/lhoest... | {
"url": "https://api.github.com/repos/huggingface/datasets/issues/7402/reactions",
"total_count": 0,
"+1": 0,
"-1": 0,
"laugh": 0,
"hooray": 0,
"confused": 0,
"heart": 0,
"rocket": 0,
"eyes": 0
} | https://api.github.com/repos/huggingface/datasets/issues/7402/timeline | null | null | null | null | null | true |
https://api.github.com/repos/huggingface/datasets/issues/7401 | https://api.github.com/repos/huggingface/datasets | https://api.github.com/repos/huggingface/datasets/issues/7401/labels{/name} | https://api.github.com/repos/huggingface/datasets/issues/7401/comments | https://api.github.com/repos/huggingface/datasets/issues/7401/events | https://github.com/huggingface/datasets/pull/7401 | 2,853,260,869 | PR_kwDODunzps6LOMSo | 7,401 | set dev version | {
"login": "lhoestq",
"id": 42851186,
"node_id": "MDQ6VXNlcjQyODUxMTg2",
"avatar_url": "https://avatars.githubusercontent.com/u/42851186?v=4",
"gravatar_id": "",
"url": "https://api.github.com/users/lhoestq",
"html_url": "https://github.com/lhoestq",
"followers_url": "https://api.github.com/users/lhoest... | [] | closed | false | [] | null | 1 | 2025-02-14T10:17:03 | 2025-02-14T10:19:20 | 2025-02-14T10:17:13 | null | MEMBER | [] | null | null | false | {
"url": "https://api.github.com/repos/huggingface/datasets/pulls/7401",
"html_url": "https://github.com/huggingface/datasets/pull/7401",
"diff_url": "https://github.com/huggingface/datasets/pull/7401.diff",
"patch_url": "https://github.com/huggingface/datasets/pull/7401.patch",
"merged_at": "2025-02-14T10:17... | null | {
"login": "lhoestq",
"id": 42851186,
"node_id": "MDQ6VXNlcjQyODUxMTg2",
"avatar_url": "https://avatars.githubusercontent.com/u/42851186?v=4",
"gravatar_id": "",
"url": "https://api.github.com/users/lhoestq",
"html_url": "https://github.com/lhoestq",
"followers_url": "https://api.github.com/users/lhoest... | {
"url": "https://api.github.com/repos/huggingface/datasets/issues/7401/reactions",
"total_count": 0,
"+1": 0,
"-1": 0,
"laugh": 0,
"hooray": 0,
"confused": 0,
"heart": 0,
"rocket": 0,
"eyes": 0
} | https://api.github.com/repos/huggingface/datasets/issues/7401/timeline | null | null | null | null | null | true |
https://api.github.com/repos/huggingface/datasets/issues/7399 | https://api.github.com/repos/huggingface/datasets | https://api.github.com/repos/huggingface/datasets/issues/7399/labels{/name} | https://api.github.com/repos/huggingface/datasets/issues/7399/comments | https://api.github.com/repos/huggingface/datasets/issues/7399/events | https://github.com/huggingface/datasets/issues/7399 | 2,853,098,442 | I_kwDODunzps6qDtPK | 7,399 | Synchronize parameters for various datasets | {
"login": "grofte",
"id": 7976840,
"node_id": "MDQ6VXNlcjc5NzY4NDA=",
"avatar_url": "https://avatars.githubusercontent.com/u/7976840?v=4",
"gravatar_id": "",
"url": "https://api.github.com/users/grofte",
"html_url": "https://github.com/grofte",
"followers_url": "https://api.github.com/users/grofte/foll... | [] | open | false | [] | null | 2 | 2025-02-14T09:15:11 | 2025-02-19T11:50:29 | null | null | NONE | [] | null | null | null | null | ### Describe the bug
[IterableDatasetDict](https://huggingface.co/docs/datasets/v3.2.0/en/package_reference/main_classes#datasets.IterableDatasetDict.map) map function is missing the `desc` parameter. You can see the equivalent map function for [Dataset here](https://huggingface.co/docs/datasets/v3.2.0/en/package_refe... | null | {
"url": "https://api.github.com/repos/huggingface/datasets/issues/7399/reactions",
"total_count": 0,
"+1": 0,
"-1": 0,
"laugh": 0,
"hooray": 0,
"confused": 0,
"heart": 0,
"rocket": 0,
"eyes": 0
} | https://api.github.com/repos/huggingface/datasets/issues/7399/timeline | null | null | {
"total": 0,
"completed": 0,
"percent_completed": 0
} | {
"blocked_by": 0,
"total_blocked_by": 0,
"blocking": 0,
"total_blocking": 0
} | null | false |
https://api.github.com/repos/huggingface/datasets/issues/7398 | https://api.github.com/repos/huggingface/datasets | https://api.github.com/repos/huggingface/datasets/issues/7398/labels{/name} | https://api.github.com/repos/huggingface/datasets/issues/7398/comments | https://api.github.com/repos/huggingface/datasets/issues/7398/events | https://github.com/huggingface/datasets/pull/7398 | 2,853,097,869 | PR_kwDODunzps6LNoDk | 7,398 | Release: 3.3.0 | {
"login": "lhoestq",
"id": 42851186,
"node_id": "MDQ6VXNlcjQyODUxMTg2",
"avatar_url": "https://avatars.githubusercontent.com/u/42851186?v=4",
"gravatar_id": "",
"url": "https://api.github.com/users/lhoestq",
"html_url": "https://github.com/lhoestq",
"followers_url": "https://api.github.com/users/lhoest... | [] | closed | false | [] | null | 1 | 2025-02-14T09:15:03 | 2025-02-14T09:57:39 | 2025-02-14T09:57:37 | null | MEMBER | [] | null | null | false | {
"url": "https://api.github.com/repos/huggingface/datasets/pulls/7398",
"html_url": "https://github.com/huggingface/datasets/pull/7398",
"diff_url": "https://github.com/huggingface/datasets/pull/7398.diff",
"patch_url": "https://github.com/huggingface/datasets/pull/7398.patch",
"merged_at": "2025-02-14T09:57... | null | {
"login": "lhoestq",
"id": 42851186,
"node_id": "MDQ6VXNlcjQyODUxMTg2",
"avatar_url": "https://avatars.githubusercontent.com/u/42851186?v=4",
"gravatar_id": "",
"url": "https://api.github.com/users/lhoestq",
"html_url": "https://github.com/lhoestq",
"followers_url": "https://api.github.com/users/lhoest... | {
"url": "https://api.github.com/repos/huggingface/datasets/issues/7398/reactions",
"total_count": 0,
"+1": 0,
"-1": 0,
"laugh": 0,
"hooray": 0,
"confused": 0,
"heart": 0,
"rocket": 0,
"eyes": 0
} | https://api.github.com/repos/huggingface/datasets/issues/7398/timeline | null | null | null | null | null | true |
https://api.github.com/repos/huggingface/datasets/issues/7397 | https://api.github.com/repos/huggingface/datasets | https://api.github.com/repos/huggingface/datasets/issues/7397/labels{/name} | https://api.github.com/repos/huggingface/datasets/issues/7397/comments | https://api.github.com/repos/huggingface/datasets/issues/7397/events | https://github.com/huggingface/datasets/pull/7397 | 2,852,829,763 | PR_kwDODunzps6LMuQD | 7,397 | Kannada dataset(Conversations, Wikipedia etc) | {
"login": "Likhith2612",
"id": 146451281,
"node_id": "U_kgDOCLqrUQ",
"avatar_url": "https://avatars.githubusercontent.com/u/146451281?v=4",
"gravatar_id": "",
"url": "https://api.github.com/users/Likhith2612",
"html_url": "https://github.com/Likhith2612",
"followers_url": "https://api.github.com/users/... | [] | closed | false | [] | null | 1 | 2025-02-14T06:53:03 | 2025-02-20T17:28:54 | 2025-02-20T17:28:53 | null | NONE | [] | null | null | false | {
"url": "https://api.github.com/repos/huggingface/datasets/pulls/7397",
"html_url": "https://github.com/huggingface/datasets/pull/7397",
"diff_url": "https://github.com/huggingface/datasets/pull/7397.diff",
"patch_url": "https://github.com/huggingface/datasets/pull/7397.patch",
"merged_at": null
} | null | {
"login": "lhoestq",
"id": 42851186,
"node_id": "MDQ6VXNlcjQyODUxMTg2",
"avatar_url": "https://avatars.githubusercontent.com/u/42851186?v=4",
"gravatar_id": "",
"url": "https://api.github.com/users/lhoestq",
"html_url": "https://github.com/lhoestq",
"followers_url": "https://api.github.com/users/lhoest... | {
"url": "https://api.github.com/repos/huggingface/datasets/issues/7397/reactions",
"total_count": 0,
"+1": 0,
"-1": 0,
"laugh": 0,
"hooray": 0,
"confused": 0,
"heart": 0,
"rocket": 0,
"eyes": 0
} | https://api.github.com/repos/huggingface/datasets/issues/7397/timeline | null | null | null | null | null | true |
https://api.github.com/repos/huggingface/datasets/issues/7400 | https://api.github.com/repos/huggingface/datasets | https://api.github.com/repos/huggingface/datasets/issues/7400/labels{/name} | https://api.github.com/repos/huggingface/datasets/issues/7400/comments | https://api.github.com/repos/huggingface/datasets/issues/7400/events | https://github.com/huggingface/datasets/issues/7400 | 2,853,201,277 | I_kwDODunzps6qEGV9 | 7,400 | 504 Gateway Timeout when uploading large dataset to Hugging Face Hub | {
"login": "hotchpotch",
"id": 3500,
"node_id": "MDQ6VXNlcjM1MDA=",
"avatar_url": "https://avatars.githubusercontent.com/u/3500?v=4",
"gravatar_id": "",
"url": "https://api.github.com/users/hotchpotch",
"html_url": "https://github.com/hotchpotch",
"followers_url": "https://api.github.com/users/hotchpotc... | [] | open | false | [] | null | 4 | 2025-02-14T02:18:35 | 2025-02-14T23:48:36 | null | null | NONE | [] | null | null | null | null | ### Description
I encountered consistent 504 Gateway Timeout errors while attempting to upload a large dataset (approximately 500GB) to the Hugging Face Hub. The upload fails during the process with a Gateway Timeout error.
I will continue trying to upload. While it might succeed in future attempts, I wanted to report... | null | {
"url": "https://api.github.com/repos/huggingface/datasets/issues/7400/reactions",
"total_count": 0,
"+1": 0,
"-1": 0,
"laugh": 0,
"hooray": 0,
"confused": 0,
"heart": 0,
"rocket": 0,
"eyes": 0
} | https://api.github.com/repos/huggingface/datasets/issues/7400/timeline | null | null | {
"total": 0,
"completed": 0,
"percent_completed": 0
} | {
"blocked_by": 0,
"total_blocked_by": 0,
"blocking": 0,
"total_blocking": 0
} | null | false |
https://api.github.com/repos/huggingface/datasets/issues/7396 | https://api.github.com/repos/huggingface/datasets | https://api.github.com/repos/huggingface/datasets/issues/7396/labels{/name} | https://api.github.com/repos/huggingface/datasets/issues/7396/comments | https://api.github.com/repos/huggingface/datasets/issues/7396/events | https://github.com/huggingface/datasets/pull/7396 | 2,851,716,755 | PR_kwDODunzps6LJBmT | 7,396 | Update README.md | {
"login": "lhoestq",
"id": 42851186,
"node_id": "MDQ6VXNlcjQyODUxMTg2",
"avatar_url": "https://avatars.githubusercontent.com/u/42851186?v=4",
"gravatar_id": "",
"url": "https://api.github.com/users/lhoestq",
"html_url": "https://github.com/lhoestq",
"followers_url": "https://api.github.com/users/lhoest... | [] | closed | false | [] | null | 1 | 2025-02-13T17:44:36 | 2025-02-13T17:46:57 | 2025-02-13T17:44:51 | null | MEMBER | [] | null | null | false | {
"url": "https://api.github.com/repos/huggingface/datasets/pulls/7396",
"html_url": "https://github.com/huggingface/datasets/pull/7396",
"diff_url": "https://github.com/huggingface/datasets/pull/7396.diff",
"patch_url": "https://github.com/huggingface/datasets/pull/7396.patch",
"merged_at": "2025-02-13T17:44... | null | {
"login": "lhoestq",
"id": 42851186,
"node_id": "MDQ6VXNlcjQyODUxMTg2",
"avatar_url": "https://avatars.githubusercontent.com/u/42851186?v=4",
"gravatar_id": "",
"url": "https://api.github.com/users/lhoestq",
"html_url": "https://github.com/lhoestq",
"followers_url": "https://api.github.com/users/lhoest... | {
"url": "https://api.github.com/repos/huggingface/datasets/issues/7396/reactions",
"total_count": 0,
"+1": 0,
"-1": 0,
"laugh": 0,
"hooray": 0,
"confused": 0,
"heart": 0,
"rocket": 0,
"eyes": 0
} | https://api.github.com/repos/huggingface/datasets/issues/7396/timeline | null | null | null | null | null | true |
https://api.github.com/repos/huggingface/datasets/issues/7395 | https://api.github.com/repos/huggingface/datasets | https://api.github.com/repos/huggingface/datasets/issues/7395/labels{/name} | https://api.github.com/repos/huggingface/datasets/issues/7395/comments | https://api.github.com/repos/huggingface/datasets/issues/7395/events | https://github.com/huggingface/datasets/pull/7395 | 2,851,575,160 | PR_kwDODunzps6LIivQ | 7,395 | Update docs | {
"login": "lhoestq",
"id": 42851186,
"node_id": "MDQ6VXNlcjQyODUxMTg2",
"avatar_url": "https://avatars.githubusercontent.com/u/42851186?v=4",
"gravatar_id": "",
"url": "https://api.github.com/users/lhoestq",
"html_url": "https://github.com/lhoestq",
"followers_url": "https://api.github.com/users/lhoest... | [] | closed | false | [] | null | 1 | 2025-02-13T16:43:15 | 2025-02-13T17:20:32 | 2025-02-13T17:20:30 | null | MEMBER | [] | null | null | false | {
"url": "https://api.github.com/repos/huggingface/datasets/pulls/7395",
"html_url": "https://github.com/huggingface/datasets/pull/7395",
"diff_url": "https://github.com/huggingface/datasets/pull/7395.diff",
"patch_url": "https://github.com/huggingface/datasets/pull/7395.patch",
"merged_at": "2025-02-13T17:20... | - update min python version
- replace canonical dataset names with new names
- avoid examples with trust_remote_code | {
"login": "lhoestq",
"id": 42851186,
"node_id": "MDQ6VXNlcjQyODUxMTg2",
"avatar_url": "https://avatars.githubusercontent.com/u/42851186?v=4",
"gravatar_id": "",
"url": "https://api.github.com/users/lhoestq",
"html_url": "https://github.com/lhoestq",
"followers_url": "https://api.github.com/users/lhoest... | {
"url": "https://api.github.com/repos/huggingface/datasets/issues/7395/reactions",
"total_count": 0,
"+1": 0,
"-1": 0,
"laugh": 0,
"hooray": 0,
"confused": 0,
"heart": 0,
"rocket": 0,
"eyes": 0
} | https://api.github.com/repos/huggingface/datasets/issues/7395/timeline | null | null | null | null | null | true |
https://api.github.com/repos/huggingface/datasets/issues/7394 | https://api.github.com/repos/huggingface/datasets | https://api.github.com/repos/huggingface/datasets/issues/7394/labels{/name} | https://api.github.com/repos/huggingface/datasets/issues/7394/comments | https://api.github.com/repos/huggingface/datasets/issues/7394/events | https://github.com/huggingface/datasets/issues/7394 | 2,847,172,115 | I_kwDODunzps6ptGYT | 7,394 | Using load_dataset with data_files and split arguments yields an error | {
"login": "devon-research",
"id": 61103399,
"node_id": "MDQ6VXNlcjYxMTAzMzk5",
"avatar_url": "https://avatars.githubusercontent.com/u/61103399?v=4",
"gravatar_id": "",
"url": "https://api.github.com/users/devon-research",
"html_url": "https://github.com/devon-research",
"followers_url": "https://api.gi... | [] | open | false | [] | null | 1 | 2025-02-12T04:50:11 | 2025-11-21T14:05:23 | null | null | NONE | [] | null | null | null | null | ### Describe the bug
It seems the list of valid splits recorded by the package becomes incorrectly overwritten when using the `data_files` argument.
If I run
```python
from datasets import load_dataset
load_dataset("allenai/super", split="all_examples", data_files="tasks/expert.jsonl")
```
then I get the error
```
Va... | null | {
"url": "https://api.github.com/repos/huggingface/datasets/issues/7394/reactions",
"total_count": 0,
"+1": 0,
"-1": 0,
"laugh": 0,
"hooray": 0,
"confused": 0,
"heart": 0,
"rocket": 0,
"eyes": 0
} | https://api.github.com/repos/huggingface/datasets/issues/7394/timeline | null | null | {
"total": 0,
"completed": 0,
"percent_completed": 0
} | {
"blocked_by": 0,
"total_blocked_by": 0,
"blocking": 0,
"total_blocking": 0
} | null | false |
https://api.github.com/repos/huggingface/datasets/issues/7393 | https://api.github.com/repos/huggingface/datasets | https://api.github.com/repos/huggingface/datasets/issues/7393/labels{/name} | https://api.github.com/repos/huggingface/datasets/issues/7393/comments | https://api.github.com/repos/huggingface/datasets/issues/7393/events | https://github.com/huggingface/datasets/pull/7393 | 2,846,446,674 | PR_kwDODunzps6K3DiZ | 7,393 | Optimized sequence encoding for scalars | {
"login": "lukasgd",
"id": 38319063,
"node_id": "MDQ6VXNlcjM4MzE5MDYz",
"avatar_url": "https://avatars.githubusercontent.com/u/38319063?v=4",
"gravatar_id": "",
"url": "https://api.github.com/users/lukasgd",
"html_url": "https://github.com/lukasgd",
"followers_url": "https://api.github.com/users/lukasg... | [] | closed | false | [] | null | 1 | 2025-02-11T20:30:44 | 2025-02-13T17:11:33 | 2025-02-13T17:11:32 | null | CONTRIBUTOR | [] | null | null | false | {
"url": "https://api.github.com/repos/huggingface/datasets/pulls/7393",
"html_url": "https://github.com/huggingface/datasets/pull/7393",
"diff_url": "https://github.com/huggingface/datasets/pull/7393.diff",
"patch_url": "https://github.com/huggingface/datasets/pull/7393.patch",
"merged_at": "2025-02-13T17:11... | The change in https://github.com/huggingface/datasets/pull/3197 introduced redundant list-comprehensions when `obj` is a long sequence of scalars. This becomes a noticeable overhead when loading data from an `IterableDataset` in the function `_apply_feature_types_on_example` and can be eliminated by adding a check for ... | {
"login": "lhoestq",
"id": 42851186,
"node_id": "MDQ6VXNlcjQyODUxMTg2",
"avatar_url": "https://avatars.githubusercontent.com/u/42851186?v=4",
"gravatar_id": "",
"url": "https://api.github.com/users/lhoestq",
"html_url": "https://github.com/lhoestq",
"followers_url": "https://api.github.com/users/lhoest... | {
"url": "https://api.github.com/repos/huggingface/datasets/issues/7393/reactions",
"total_count": 0,
"+1": 0,
"-1": 0,
"laugh": 0,
"hooray": 0,
"confused": 0,
"heart": 0,
"rocket": 0,
"eyes": 0
} | https://api.github.com/repos/huggingface/datasets/issues/7393/timeline | null | null | null | null | null | true |
https://api.github.com/repos/huggingface/datasets/issues/7392 | https://api.github.com/repos/huggingface/datasets | https://api.github.com/repos/huggingface/datasets/issues/7392/labels{/name} | https://api.github.com/repos/huggingface/datasets/issues/7392/comments | https://api.github.com/repos/huggingface/datasets/issues/7392/events | https://github.com/huggingface/datasets/issues/7392 | 2,846,095,043 | I_kwDODunzps6po_bD | 7,392 | push_to_hub payload too large error when using large ClassLabel feature | {
"login": "DavidRConnell",
"id": 35470740,
"node_id": "MDQ6VXNlcjM1NDcwNzQw",
"avatar_url": "https://avatars.githubusercontent.com/u/35470740?v=4",
"gravatar_id": "",
"url": "https://api.github.com/users/DavidRConnell",
"html_url": "https://github.com/DavidRConnell",
"followers_url": "https://api.githu... | [] | open | false | [] | null | 1 | 2025-02-11T17:51:34 | 2025-02-11T18:01:31 | null | null | CONTRIBUTOR | [] | null | null | null | null | ### Describe the bug
When using `datasets.DatasetDict.push_to_hub` an `HfHubHTTPError: 413 Client Error: Payload Too Large for url` is raised if the dataset contains a large `ClassLabel` feature. Even if the total size of the dataset is small.
### Steps to reproduce the bug
``` python
import random
import sys
impor... | null | {
"url": "https://api.github.com/repos/huggingface/datasets/issues/7392/reactions",
"total_count": 0,
"+1": 0,
"-1": 0,
"laugh": 0,
"hooray": 0,
"confused": 0,
"heart": 0,
"rocket": 0,
"eyes": 0
} | https://api.github.com/repos/huggingface/datasets/issues/7392/timeline | null | null | {
"total": 0,
"completed": 0,
"percent_completed": 0
} | {
"blocked_by": 0,
"total_blocked_by": 0,
"blocking": 0,
"total_blocking": 0
} | null | false |
https://api.github.com/repos/huggingface/datasets/issues/7391 | https://api.github.com/repos/huggingface/datasets | https://api.github.com/repos/huggingface/datasets/issues/7391/labels{/name} | https://api.github.com/repos/huggingface/datasets/issues/7391/comments | https://api.github.com/repos/huggingface/datasets/issues/7391/events | https://github.com/huggingface/datasets/issues/7391 | 2,845,184,764 | I_kwDODunzps6plhL8 | 7,391 | AttributeError: module 'pyarrow.lib' has no attribute 'ListViewType' | {
"login": "LinXin04",
"id": 25193686,
"node_id": "MDQ6VXNlcjI1MTkzNjg2",
"avatar_url": "https://avatars.githubusercontent.com/u/25193686?v=4",
"gravatar_id": "",
"url": "https://api.github.com/users/LinXin04",
"html_url": "https://github.com/LinXin04",
"followers_url": "https://api.github.com/users/Lin... | [] | open | false | [] | null | 0 | 2025-02-11T12:02:26 | 2025-02-11T12:02:26 | null | null | NONE | [] | null | null | null | null | pyarrow 尝试了若干个版本都不可以 | null | {
"url": "https://api.github.com/repos/huggingface/datasets/issues/7391/reactions",
"total_count": 0,
"+1": 0,
"-1": 0,
"laugh": 0,
"hooray": 0,
"confused": 0,
"heart": 0,
"rocket": 0,
"eyes": 0
} | https://api.github.com/repos/huggingface/datasets/issues/7391/timeline | null | null | {
"total": 0,
"completed": 0,
"percent_completed": 0
} | {
"blocked_by": 0,
"total_blocked_by": 0,
"blocking": 0,
"total_blocking": 0
} | null | false |
https://api.github.com/repos/huggingface/datasets/issues/7390 | https://api.github.com/repos/huggingface/datasets | https://api.github.com/repos/huggingface/datasets/issues/7390/labels{/name} | https://api.github.com/repos/huggingface/datasets/issues/7390/comments | https://api.github.com/repos/huggingface/datasets/issues/7390/events | https://github.com/huggingface/datasets/issues/7390 | 2,843,813,365 | I_kwDODunzps6pgSX1 | 7,390 | Re-add py.typed | {
"login": "NeilGirdhar",
"id": 730137,
"node_id": "MDQ6VXNlcjczMDEzNw==",
"avatar_url": "https://avatars.githubusercontent.com/u/730137?v=4",
"gravatar_id": "",
"url": "https://api.github.com/users/NeilGirdhar",
"html_url": "https://github.com/NeilGirdhar",
"followers_url": "https://api.github.com/user... | [
{
"id": 1935892871,
"node_id": "MDU6TGFiZWwxOTM1ODkyODcx",
"url": "https://api.github.com/repos/huggingface/datasets/labels/enhancement",
"name": "enhancement",
"color": "a2eeef",
"default": true,
"description": "New feature or request",
"archived_at": null,
"archived_by": null
... | open | false | [] | null | 1 | 2025-02-10T22:12:52 | 2025-08-10T00:51:17 | null | null | CONTRIBUTOR | [] | null | null | null | null | ### Feature request
The motivation for removing py.typed no longer seems to apply. Would a solution like [this one](https://github.com/huggingface/huggingface_hub/pull/2752) work here?
### Motivation
MyPy support is broken. As more type checkers come out, such as RedKnot, these may also be broken. It would be goo... | null | {
"url": "https://api.github.com/repos/huggingface/datasets/issues/7390/reactions",
"total_count": 13,
"+1": 13,
"-1": 0,
"laugh": 0,
"hooray": 0,
"confused": 0,
"heart": 0,
"rocket": 0,
"eyes": 0
} | https://api.github.com/repos/huggingface/datasets/issues/7390/timeline | null | null | {
"total": 0,
"completed": 0,
"percent_completed": 0
} | {
"blocked_by": 0,
"total_blocked_by": 0,
"blocking": 0,
"total_blocking": 0
} | null | false |
https://api.github.com/repos/huggingface/datasets/issues/7389 | https://api.github.com/repos/huggingface/datasets | https://api.github.com/repos/huggingface/datasets/issues/7389/labels{/name} | https://api.github.com/repos/huggingface/datasets/issues/7389/comments | https://api.github.com/repos/huggingface/datasets/issues/7389/events | https://github.com/huggingface/datasets/issues/7389 | 2,843,592,606 | I_kwDODunzps6pfcee | 7,389 | Getting statistics about filtered examples | {
"login": "jonathanasdf",
"id": 511073,
"node_id": "MDQ6VXNlcjUxMTA3Mw==",
"avatar_url": "https://avatars.githubusercontent.com/u/511073?v=4",
"gravatar_id": "",
"url": "https://api.github.com/users/jonathanasdf",
"html_url": "https://github.com/jonathanasdf",
"followers_url": "https://api.github.com/u... | [] | closed | false | [] | null | 2 | 2025-02-10T20:48:29 | 2025-02-11T20:44:15 | 2025-02-11T20:44:13 | null | NONE | [] | null | null | null | null | @lhoestq wondering if the team has thought about this and if there are any recommendations?
Currently when processing datasets some examples are bound to get filtered out, whether it's due to bad format, or length is too long, or any other custom filters that might be getting applied. Let's just focus on the filter by... | {
"login": "jonathanasdf",
"id": 511073,
"node_id": "MDQ6VXNlcjUxMTA3Mw==",
"avatar_url": "https://avatars.githubusercontent.com/u/511073?v=4",
"gravatar_id": "",
"url": "https://api.github.com/users/jonathanasdf",
"html_url": "https://github.com/jonathanasdf",
"followers_url": "https://api.github.com/u... | {
"url": "https://api.github.com/repos/huggingface/datasets/issues/7389/reactions",
"total_count": 0,
"+1": 0,
"-1": 0,
"laugh": 0,
"hooray": 0,
"confused": 0,
"heart": 0,
"rocket": 0,
"eyes": 0
} | https://api.github.com/repos/huggingface/datasets/issues/7389/timeline | null | completed | {
"total": 0,
"completed": 0,
"percent_completed": 0
} | {
"blocked_by": 0,
"total_blocked_by": 0,
"blocking": 0,
"total_blocking": 0
} | null | false |
https://api.github.com/repos/huggingface/datasets/issues/7388 | https://api.github.com/repos/huggingface/datasets | https://api.github.com/repos/huggingface/datasets/issues/7388/labels{/name} | https://api.github.com/repos/huggingface/datasets/issues/7388/comments | https://api.github.com/repos/huggingface/datasets/issues/7388/events | https://github.com/huggingface/datasets/issues/7388 | 2,843,188,499 | I_kwDODunzps6pd50T | 7,388 | OSError: [Errno 22] Invalid argument forbidden character | {
"login": "langflogit",
"id": 124634542,
"node_id": "U_kgDOB23Frg",
"avatar_url": "https://avatars.githubusercontent.com/u/124634542?v=4",
"gravatar_id": "",
"url": "https://api.github.com/users/langflogit",
"html_url": "https://github.com/langflogit",
"followers_url": "https://api.github.com/users/lan... | [] | closed | false | [] | null | 2 | 2025-02-10T17:46:31 | 2025-02-11T13:42:32 | 2025-02-11T13:42:30 | null | NONE | [] | null | null | null | null | ### Describe the bug
I'm on Windows and i'm trying to load a datasets but i'm having title error because files in the repository are named with charactere like < >which can't be in a name file. Could it be possible to load this datasets but removing those charactere ?
### Steps to reproduce the bug
load_dataset("CAT... | {
"login": "langflogit",
"id": 124634542,
"node_id": "U_kgDOB23Frg",
"avatar_url": "https://avatars.githubusercontent.com/u/124634542?v=4",
"gravatar_id": "",
"url": "https://api.github.com/users/langflogit",
"html_url": "https://github.com/langflogit",
"followers_url": "https://api.github.com/users/lan... | {
"url": "https://api.github.com/repos/huggingface/datasets/issues/7388/reactions",
"total_count": 0,
"+1": 0,
"-1": 0,
"laugh": 0,
"hooray": 0,
"confused": 0,
"heart": 0,
"rocket": 0,
"eyes": 0
} | https://api.github.com/repos/huggingface/datasets/issues/7388/timeline | null | completed | {
"total": 0,
"completed": 0,
"percent_completed": 0
} | {
"blocked_by": 0,
"total_blocked_by": 0,
"blocking": 0,
"total_blocking": 0
} | null | false |
https://api.github.com/repos/huggingface/datasets/issues/7387 | https://api.github.com/repos/huggingface/datasets | https://api.github.com/repos/huggingface/datasets/issues/7387/labels{/name} | https://api.github.com/repos/huggingface/datasets/issues/7387/comments | https://api.github.com/repos/huggingface/datasets/issues/7387/events | https://github.com/huggingface/datasets/issues/7387 | 2,841,228,048 | I_kwDODunzps6pWbMQ | 7,387 | Dynamic adjusting dataloader sampling weight | {
"login": "whc688",
"id": 72799643,
"node_id": "MDQ6VXNlcjcyNzk5NjQz",
"avatar_url": "https://avatars.githubusercontent.com/u/72799643?v=4",
"gravatar_id": "",
"url": "https://api.github.com/users/whc688",
"html_url": "https://github.com/whc688",
"followers_url": "https://api.github.com/users/whc688/fo... | [] | open | false | [] | null | 3 | 2025-02-10T03:18:47 | 2025-03-07T14:06:54 | null | null | NONE | [] | null | null | null | null | Hi,
Thanks for your wonderful work! I'm wondering is there a way to dynamically adjust the sampling weight of each data in the dataset during training? Looking forward to your reply, thanks again. | null | {
"url": "https://api.github.com/repos/huggingface/datasets/issues/7387/reactions",
"total_count": 0,
"+1": 0,
"-1": 0,
"laugh": 0,
"hooray": 0,
"confused": 0,
"heart": 0,
"rocket": 0,
"eyes": 0
} | https://api.github.com/repos/huggingface/datasets/issues/7387/timeline | null | null | {
"total": 0,
"completed": 0,
"percent_completed": 0
} | {
"blocked_by": 0,
"total_blocked_by": 0,
"blocking": 0,
"total_blocking": 0
} | null | false |
https://api.github.com/repos/huggingface/datasets/issues/7386 | https://api.github.com/repos/huggingface/datasets | https://api.github.com/repos/huggingface/datasets/issues/7386/labels{/name} | https://api.github.com/repos/huggingface/datasets/issues/7386/comments | https://api.github.com/repos/huggingface/datasets/issues/7386/events | https://github.com/huggingface/datasets/issues/7386 | 2,840,032,524 | I_kwDODunzps6pR3UM | 7,386 | Add bookfolder Dataset Builder for Digital Book Formats | {
"login": "shikanime",
"id": 22115108,
"node_id": "MDQ6VXNlcjIyMTE1MTA4",
"avatar_url": "https://avatars.githubusercontent.com/u/22115108?v=4",
"gravatar_id": "",
"url": "https://api.github.com/users/shikanime",
"html_url": "https://github.com/shikanime",
"followers_url": "https://api.github.com/users/... | [
{
"id": 1935892871,
"node_id": "MDU6TGFiZWwxOTM1ODkyODcx",
"url": "https://api.github.com/repos/huggingface/datasets/labels/enhancement",
"name": "enhancement",
"color": "a2eeef",
"default": true,
"description": "New feature or request",
"archived_at": null,
"archived_by": null
... | closed | false | [] | null | 1 | 2025-02-08T14:27:55 | 2025-02-08T14:30:10 | 2025-02-08T14:30:09 | null | NONE | [] | null | null | null | null | ### Feature request
This feature proposes adding a new dataset builder called bookfolder to the datasets library. This builder would allow users to easily load datasets consisting of various digital book formats, including: AZW, AZW3, CB7, CBR, CBT, CBZ, EPUB, MOBI, and PDF.
### Motivation
Currently, loading dataset... | {
"login": "shikanime",
"id": 22115108,
"node_id": "MDQ6VXNlcjIyMTE1MTA4",
"avatar_url": "https://avatars.githubusercontent.com/u/22115108?v=4",
"gravatar_id": "",
"url": "https://api.github.com/users/shikanime",
"html_url": "https://github.com/shikanime",
"followers_url": "https://api.github.com/users/... | {
"url": "https://api.github.com/repos/huggingface/datasets/issues/7386/reactions",
"total_count": 0,
"+1": 0,
"-1": 0,
"laugh": 0,
"hooray": 0,
"confused": 0,
"heart": 0,
"rocket": 0,
"eyes": 0
} | https://api.github.com/repos/huggingface/datasets/issues/7386/timeline | null | completed | {
"total": 0,
"completed": 0,
"percent_completed": 0
} | {
"blocked_by": 0,
"total_blocked_by": 0,
"blocking": 0,
"total_blocking": 0
} | null | false |
https://api.github.com/repos/huggingface/datasets/issues/7385 | https://api.github.com/repos/huggingface/datasets | https://api.github.com/repos/huggingface/datasets/issues/7385/labels{/name} | https://api.github.com/repos/huggingface/datasets/issues/7385/comments | https://api.github.com/repos/huggingface/datasets/issues/7385/events | https://github.com/huggingface/datasets/pull/7385 | 2,830,664,522 | PR_kwDODunzps6KBO6i | 7,385 | Make IterableDataset (optionally) resumable | {
"login": "yzhangcs",
"id": 18402347,
"node_id": "MDQ6VXNlcjE4NDAyMzQ3",
"avatar_url": "https://avatars.githubusercontent.com/u/18402347?v=4",
"gravatar_id": "",
"url": "https://api.github.com/users/yzhangcs",
"html_url": "https://github.com/yzhangcs",
"followers_url": "https://api.github.com/users/yzh... | [] | open | false | [] | null | 2 | 2025-02-04T15:55:33 | 2025-03-03T17:31:40 | null | null | CONTRIBUTOR | [] | null | null | false | {
"url": "https://api.github.com/repos/huggingface/datasets/pulls/7385",
"html_url": "https://github.com/huggingface/datasets/pull/7385",
"diff_url": "https://github.com/huggingface/datasets/pull/7385.diff",
"patch_url": "https://github.com/huggingface/datasets/pull/7385.patch",
"merged_at": null
} | ### What does this PR do?
This PR introduces a new `stateful` option to the `dataset.shuffle` method, which defaults to `False`.
When enabled, this option allows for resumable shuffling of `IterableDataset` instances, albeit with some additional memory overhead.
Key points:
* All tests have passed
* Docstrings ... | null | {
"url": "https://api.github.com/repos/huggingface/datasets/issues/7385/reactions",
"total_count": 0,
"+1": 0,
"-1": 0,
"laugh": 0,
"hooray": 0,
"confused": 0,
"heart": 0,
"rocket": 0,
"eyes": 0
} | https://api.github.com/repos/huggingface/datasets/issues/7385/timeline | null | null | null | null | null | true |
https://api.github.com/repos/huggingface/datasets/issues/7384 | https://api.github.com/repos/huggingface/datasets | https://api.github.com/repos/huggingface/datasets/issues/7384/labels{/name} | https://api.github.com/repos/huggingface/datasets/issues/7384/comments | https://api.github.com/repos/huggingface/datasets/issues/7384/events | https://github.com/huggingface/datasets/pull/7384 | 2,828,208,828 | PR_kwDODunzps6J4wVi | 7,384 | Support async functions in map() | {
"login": "lhoestq",
"id": 42851186,
"node_id": "MDQ6VXNlcjQyODUxMTg2",
"avatar_url": "https://avatars.githubusercontent.com/u/42851186?v=4",
"gravatar_id": "",
"url": "https://api.github.com/users/lhoestq",
"html_url": "https://github.com/lhoestq",
"followers_url": "https://api.github.com/users/lhoest... | [] | closed | false | [] | null | 2 | 2025-02-03T18:18:40 | 2025-02-13T14:01:13 | 2025-02-13T14:00:06 | null | MEMBER | [] | null | null | false | {
"url": "https://api.github.com/repos/huggingface/datasets/pulls/7384",
"html_url": "https://github.com/huggingface/datasets/pull/7384",
"diff_url": "https://github.com/huggingface/datasets/pull/7384.diff",
"patch_url": "https://github.com/huggingface/datasets/pull/7384.patch",
"merged_at": "2025-02-13T14:00... | e.g. to download images or call an inference API like HF or vLLM
```python
import asyncio
import random
from datasets import Dataset
async def f(x):
await asyncio.sleep(random.random())
ds = Dataset.from_dict({"data": range(100)})
ds.map(f)
# Map: 100%|█████████████████████████████| 100/100 [00:0... | {
"login": "lhoestq",
"id": 42851186,
"node_id": "MDQ6VXNlcjQyODUxMTg2",
"avatar_url": "https://avatars.githubusercontent.com/u/42851186?v=4",
"gravatar_id": "",
"url": "https://api.github.com/users/lhoestq",
"html_url": "https://github.com/lhoestq",
"followers_url": "https://api.github.com/users/lhoest... | {
"url": "https://api.github.com/repos/huggingface/datasets/issues/7384/reactions",
"total_count": 3,
"+1": 0,
"-1": 0,
"laugh": 0,
"hooray": 0,
"confused": 0,
"heart": 3,
"rocket": 0,
"eyes": 0
} | https://api.github.com/repos/huggingface/datasets/issues/7384/timeline | null | null | null | null | null | true |
https://api.github.com/repos/huggingface/datasets/issues/7382 | https://api.github.com/repos/huggingface/datasets | https://api.github.com/repos/huggingface/datasets/issues/7382/labels{/name} | https://api.github.com/repos/huggingface/datasets/issues/7382/comments | https://api.github.com/repos/huggingface/datasets/issues/7382/events | https://github.com/huggingface/datasets/pull/7382 | 2,823,480,924 | PR_kwDODunzps6Jo69f | 7,382 | Add Pandas, PyArrow and Polars docs | {
"login": "lhoestq",
"id": 42851186,
"node_id": "MDQ6VXNlcjQyODUxMTg2",
"avatar_url": "https://avatars.githubusercontent.com/u/42851186?v=4",
"gravatar_id": "",
"url": "https://api.github.com/users/lhoestq",
"html_url": "https://github.com/lhoestq",
"followers_url": "https://api.github.com/users/lhoest... | [] | closed | false | [] | null | 1 | 2025-01-31T13:22:59 | 2025-01-31T16:30:59 | 2025-01-31T16:30:57 | null | MEMBER | [] | null | null | false | {
"url": "https://api.github.com/repos/huggingface/datasets/pulls/7382",
"html_url": "https://github.com/huggingface/datasets/pull/7382",
"diff_url": "https://github.com/huggingface/datasets/pull/7382.diff",
"patch_url": "https://github.com/huggingface/datasets/pull/7382.patch",
"merged_at": "2025-01-31T16:30... | (also added the missing numpy docs and fixed a small bug in pyarrow formatting) | {
"login": "lhoestq",
"id": 42851186,
"node_id": "MDQ6VXNlcjQyODUxMTg2",
"avatar_url": "https://avatars.githubusercontent.com/u/42851186?v=4",
"gravatar_id": "",
"url": "https://api.github.com/users/lhoestq",
"html_url": "https://github.com/lhoestq",
"followers_url": "https://api.github.com/users/lhoest... | {
"url": "https://api.github.com/repos/huggingface/datasets/issues/7382/reactions",
"total_count": 0,
"+1": 0,
"-1": 0,
"laugh": 0,
"hooray": 0,
"confused": 0,
"heart": 0,
"rocket": 0,
"eyes": 0
} | https://api.github.com/repos/huggingface/datasets/issues/7382/timeline | null | null | null | null | null | true |
https://api.github.com/repos/huggingface/datasets/issues/7381 | https://api.github.com/repos/huggingface/datasets | https://api.github.com/repos/huggingface/datasets/issues/7381/labels{/name} | https://api.github.com/repos/huggingface/datasets/issues/7381/comments | https://api.github.com/repos/huggingface/datasets/issues/7381/events | https://github.com/huggingface/datasets/issues/7381 | 2,815,649,092 | I_kwDODunzps6n02VE | 7,381 | Iterating over values of a column in the IterableDataset | {
"login": "TopCoder2K",
"id": 47208659,
"node_id": "MDQ6VXNlcjQ3MjA4NjU5",
"avatar_url": "https://avatars.githubusercontent.com/u/47208659?v=4",
"gravatar_id": "",
"url": "https://api.github.com/users/TopCoder2K",
"html_url": "https://github.com/TopCoder2K",
"followers_url": "https://api.github.com/use... | [
{
"id": 1935892871,
"node_id": "MDU6TGFiZWwxOTM1ODkyODcx",
"url": "https://api.github.com/repos/huggingface/datasets/labels/enhancement",
"name": "enhancement",
"color": "a2eeef",
"default": true,
"description": "New feature or request",
"archived_at": null,
"archived_by": null
... | closed | false | [
{
"login": "TopCoder2K",
"id": 47208659,
"node_id": "MDQ6VXNlcjQ3MjA4NjU5",
"avatar_url": "https://avatars.githubusercontent.com/u/47208659?v=4",
"gravatar_id": "",
"url": "https://api.github.com/users/TopCoder2K",
"html_url": "https://github.com/TopCoder2K",
"followers_url": "https:... | null | 11 | 2025-01-28T13:17:36 | 2025-05-22T18:00:04 | 2025-05-22T18:00:04 | {
"login": "TopCoder2K",
"id": 47208659,
"node_id": "MDQ6VXNlcjQ3MjA4NjU5",
"avatar_url": "https://avatars.githubusercontent.com/u/47208659?v=4",
"gravatar_id": "",
"url": "https://api.github.com/users/TopCoder2K",
"html_url": "https://github.com/TopCoder2K",
"followers_url": "https://api.github.com/use... | CONTRIBUTOR | [] | null | null | null | null | ### Feature request
I would like to be able to iterate (and re-iterate if needed) over a column of an `IterableDataset` instance. The following example shows the supposed API:
```python
def gen():
yield {"text": "Good", "label": 0}
yield {"text": "Bad", "label": 1}
ds = IterableDataset.from_generator(gen)
tex... | {
"login": "TopCoder2K",
"id": 47208659,
"node_id": "MDQ6VXNlcjQ3MjA4NjU5",
"avatar_url": "https://avatars.githubusercontent.com/u/47208659?v=4",
"gravatar_id": "",
"url": "https://api.github.com/users/TopCoder2K",
"html_url": "https://github.com/TopCoder2K",
"followers_url": "https://api.github.com/use... | {
"url": "https://api.github.com/repos/huggingface/datasets/issues/7381/reactions",
"total_count": 1,
"+1": 1,
"-1": 0,
"laugh": 0,
"hooray": 0,
"confused": 0,
"heart": 0,
"rocket": 0,
"eyes": 0
} | https://api.github.com/repos/huggingface/datasets/issues/7381/timeline | null | completed | {
"total": 0,
"completed": 0,
"percent_completed": 0
} | {
"blocked_by": 0,
"total_blocked_by": 0,
"blocking": 0,
"total_blocking": 0
} | null | false |
https://api.github.com/repos/huggingface/datasets/issues/7380 | https://api.github.com/repos/huggingface/datasets | https://api.github.com/repos/huggingface/datasets/issues/7380/labels{/name} | https://api.github.com/repos/huggingface/datasets/issues/7380/comments | https://api.github.com/repos/huggingface/datasets/issues/7380/events | https://github.com/huggingface/datasets/pull/7380 | 2,811,566,116 | PR_kwDODunzps6JAkj5 | 7,380 | fix: dill default for version bigger 0.3.8 | {
"login": "sam-hey",
"id": 40773225,
"node_id": "MDQ6VXNlcjQwNzczMjI1",
"avatar_url": "https://avatars.githubusercontent.com/u/40773225?v=4",
"gravatar_id": "",
"url": "https://api.github.com/users/sam-hey",
"html_url": "https://github.com/sam-hey",
"followers_url": "https://api.github.com/users/sam-he... | [] | closed | false | [] | null | 1 | 2025-01-26T13:37:16 | 2025-03-13T20:40:19 | 2025-03-13T20:40:19 | null | NONE | [] | null | null | false | {
"url": "https://api.github.com/repos/huggingface/datasets/pulls/7380",
"html_url": "https://github.com/huggingface/datasets/pull/7380",
"diff_url": "https://github.com/huggingface/datasets/pull/7380.diff",
"patch_url": "https://github.com/huggingface/datasets/pull/7380.patch",
"merged_at": null
} | Fixes def log for dill version >= 0.3.9
https://pypi.org/project/dill/
This project uses dill with the release of version 0.3.9 the datasets lib. | {
"login": "sam-hey",
"id": 40773225,
"node_id": "MDQ6VXNlcjQwNzczMjI1",
"avatar_url": "https://avatars.githubusercontent.com/u/40773225?v=4",
"gravatar_id": "",
"url": "https://api.github.com/users/sam-hey",
"html_url": "https://github.com/sam-hey",
"followers_url": "https://api.github.com/users/sam-he... | {
"url": "https://api.github.com/repos/huggingface/datasets/issues/7380/reactions",
"total_count": 0,
"+1": 0,
"-1": 0,
"laugh": 0,
"hooray": 0,
"confused": 0,
"heart": 0,
"rocket": 0,
"eyes": 0
} | https://api.github.com/repos/huggingface/datasets/issues/7380/timeline | null | null | null | null | null | true |
https://api.github.com/repos/huggingface/datasets/issues/7378 | https://api.github.com/repos/huggingface/datasets | https://api.github.com/repos/huggingface/datasets/issues/7378/labels{/name} | https://api.github.com/repos/huggingface/datasets/issues/7378/comments | https://api.github.com/repos/huggingface/datasets/issues/7378/events | https://github.com/huggingface/datasets/issues/7378 | 2,802,957,388 | I_kwDODunzps6nEbxM | 7,378 | Allow pushing config version to hub | {
"login": "momeara",
"id": 129072,
"node_id": "MDQ6VXNlcjEyOTA3Mg==",
"avatar_url": "https://avatars.githubusercontent.com/u/129072?v=4",
"gravatar_id": "",
"url": "https://api.github.com/users/momeara",
"html_url": "https://github.com/momeara",
"followers_url": "https://api.github.com/users/momeara/fo... | [
{
"id": 1935892871,
"node_id": "MDU6TGFiZWwxOTM1ODkyODcx",
"url": "https://api.github.com/repos/huggingface/datasets/labels/enhancement",
"name": "enhancement",
"color": "a2eeef",
"default": true,
"description": "New feature or request",
"archived_at": null,
"archived_by": null
... | open | false | [] | null | 1 | 2025-01-21T22:35:07 | 2025-01-30T13:56:56 | null | null | NONE | [] | null | null | null | null | ### Feature request
Currently, when datasets are created, they can be versioned by passing the `version` argument to `load_dataset(...)`. For example creating `outcomes.csv` on the command line
```
echo "id,value\n1,0\n2,0\n3,1\n4,1\n" > outcomes.csv
```
and creating it
```
import datasets
dataset = datasets.load_dat... | null | {
"url": "https://api.github.com/repos/huggingface/datasets/issues/7378/reactions",
"total_count": 0,
"+1": 0,
"-1": 0,
"laugh": 0,
"hooray": 0,
"confused": 0,
"heart": 0,
"rocket": 0,
"eyes": 0
} | https://api.github.com/repos/huggingface/datasets/issues/7378/timeline | null | null | {
"total": 0,
"completed": 0,
"percent_completed": 0
} | {
"blocked_by": 0,
"total_blocked_by": 0,
"blocking": 0,
"total_blocking": 0
} | null | false |
https://api.github.com/repos/huggingface/datasets/issues/7377 | https://api.github.com/repos/huggingface/datasets | https://api.github.com/repos/huggingface/datasets/issues/7377/labels{/name} | https://api.github.com/repos/huggingface/datasets/issues/7377/comments | https://api.github.com/repos/huggingface/datasets/issues/7377/events | https://github.com/huggingface/datasets/issues/7377 | 2,802,723,285 | I_kwDODunzps6nDinV | 7,377 | Support for sparse arrays with the Arrow Sparse Tensor format? | {
"login": "JulesGM",
"id": 3231217,
"node_id": "MDQ6VXNlcjMyMzEyMTc=",
"avatar_url": "https://avatars.githubusercontent.com/u/3231217?v=4",
"gravatar_id": "",
"url": "https://api.github.com/users/JulesGM",
"html_url": "https://github.com/JulesGM",
"followers_url": "https://api.github.com/users/JulesGM/... | [
{
"id": 1935892871,
"node_id": "MDU6TGFiZWwxOTM1ODkyODcx",
"url": "https://api.github.com/repos/huggingface/datasets/labels/enhancement",
"name": "enhancement",
"color": "a2eeef",
"default": true,
"description": "New feature or request",
"archived_at": null,
"archived_by": null
... | open | false | [] | null | 3 | 2025-01-21T20:14:35 | 2026-02-03T23:05:02 | null | null | NONE | [] | null | null | null | null | ### Feature request
AI in biology is becoming a big thing. One thing that would be a huge benefit to the field that Huggingface Datasets doesn't currently have is native support for **sparse arrays**.
Arrow has support for sparse tensors.
https://arrow.apache.org/docs/format/Other.html#sparse-tensor
It would be ... | null | {
"url": "https://api.github.com/repos/huggingface/datasets/issues/7377/reactions",
"total_count": 4,
"+1": 2,
"-1": 0,
"laugh": 0,
"hooray": 0,
"confused": 0,
"heart": 0,
"rocket": 0,
"eyes": 2
} | https://api.github.com/repos/huggingface/datasets/issues/7377/timeline | null | null | {
"total": 0,
"completed": 0,
"percent_completed": 0
} | {
"blocked_by": 0,
"total_blocked_by": 0,
"blocking": 0,
"total_blocking": 0
} | null | false |
https://api.github.com/repos/huggingface/datasets/issues/7376 | https://api.github.com/repos/huggingface/datasets | https://api.github.com/repos/huggingface/datasets/issues/7376/labels{/name} | https://api.github.com/repos/huggingface/datasets/issues/7376/comments | https://api.github.com/repos/huggingface/datasets/issues/7376/events | https://github.com/huggingface/datasets/pull/7376 | 2,802,621,104 | PR_kwDODunzps6IiO9j | 7,376 | [docs] uv install | {
"login": "stevhliu",
"id": 59462357,
"node_id": "MDQ6VXNlcjU5NDYyMzU3",
"avatar_url": "https://avatars.githubusercontent.com/u/59462357?v=4",
"gravatar_id": "",
"url": "https://api.github.com/users/stevhliu",
"html_url": "https://github.com/stevhliu",
"followers_url": "https://api.github.com/users/ste... | [] | closed | false | [] | null | 0 | 2025-01-21T19:15:48 | 2025-03-14T20:16:35 | 2025-03-14T20:16:35 | null | MEMBER | [] | null | null | false | {
"url": "https://api.github.com/repos/huggingface/datasets/pulls/7376",
"html_url": "https://github.com/huggingface/datasets/pull/7376",
"diff_url": "https://github.com/huggingface/datasets/pull/7376.diff",
"patch_url": "https://github.com/huggingface/datasets/pull/7376.patch",
"merged_at": null
} | Proposes adding uv to installation docs (see Slack thread [here](https://huggingface.slack.com/archives/C01N44FJDHT/p1737377177709279) for more context) if you're interested! | {
"login": "stevhliu",
"id": 59462357,
"node_id": "MDQ6VXNlcjU5NDYyMzU3",
"avatar_url": "https://avatars.githubusercontent.com/u/59462357?v=4",
"gravatar_id": "",
"url": "https://api.github.com/users/stevhliu",
"html_url": "https://github.com/stevhliu",
"followers_url": "https://api.github.com/users/ste... | {
"url": "https://api.github.com/repos/huggingface/datasets/issues/7376/reactions",
"total_count": 0,
"+1": 0,
"-1": 0,
"laugh": 0,
"hooray": 0,
"confused": 0,
"heart": 0,
"rocket": 0,
"eyes": 0
} | https://api.github.com/repos/huggingface/datasets/issues/7376/timeline | null | null | null | null | null | true |
https://api.github.com/repos/huggingface/datasets/issues/7375 | https://api.github.com/repos/huggingface/datasets | https://api.github.com/repos/huggingface/datasets/issues/7375/labels{/name} | https://api.github.com/repos/huggingface/datasets/issues/7375/comments | https://api.github.com/repos/huggingface/datasets/issues/7375/events | https://github.com/huggingface/datasets/issues/7375 | 2,800,609,218 | I_kwDODunzps6m7efC | 7,375 | vllm批量推理报错 | {
"login": "YuShengzuishuai",
"id": 51228154,
"node_id": "MDQ6VXNlcjUxMjI4MTU0",
"avatar_url": "https://avatars.githubusercontent.com/u/51228154?v=4",
"gravatar_id": "",
"url": "https://api.github.com/users/YuShengzuishuai",
"html_url": "https://github.com/YuShengzuishuai",
"followers_url": "https://api... | [] | open | false | [] | null | 1 | 2025-01-21T03:22:23 | 2025-01-30T14:02:40 | null | null | NONE | [] | null | null | null | null | ### Describe the bug

### Steps to reproduce the bug
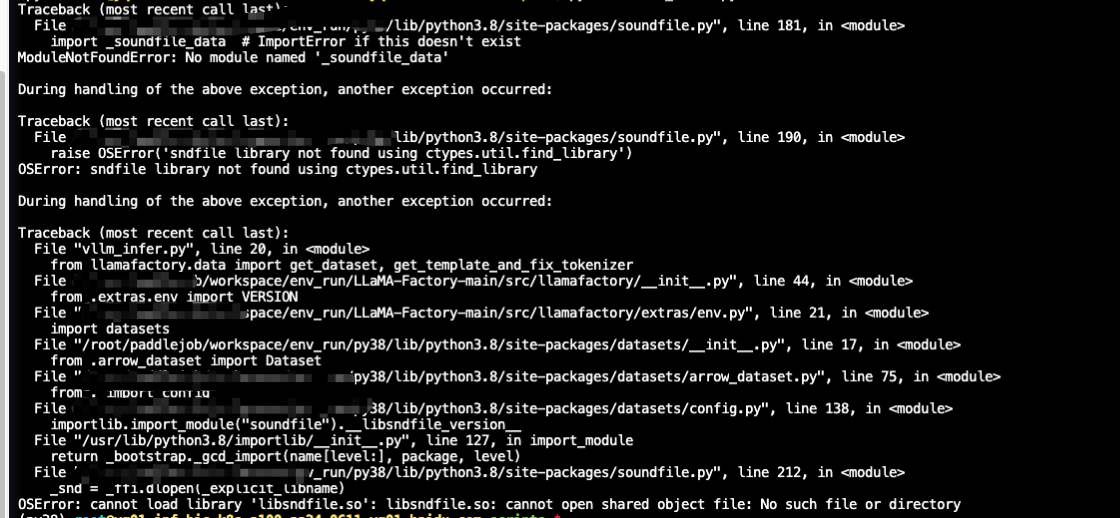
### Expected behavior
 | {
"login": "lhoestq",
"id": 42851186,
"node_id": "MDQ6VXNlcjQyODUxMTg2",
"avatar_url": "https://avatars.githubusercontent.com/u/42851186?v=4",
"gravatar_id": "",
"url": "https://api.github.com/users/lhoestq",
"html_url": "https://github.com/lhoestq",
"followers_url": "https://api.github.com/users/lhoest... | {
"url": "https://api.github.com/repos/huggingface/datasets/issues/7374/reactions",
"total_count": 0,
"+1": 0,
"-1": 0,
"laugh": 0,
"hooray": 0,
"confused": 0,
"heart": 0,
"rocket": 0,
"eyes": 0
} | https://api.github.com/repos/huggingface/datasets/issues/7374/timeline | null | null | null | null | null | true |
https://api.github.com/repos/huggingface/datasets/issues/7373 | https://api.github.com/repos/huggingface/datasets | https://api.github.com/repos/huggingface/datasets/issues/7373/labels{/name} | https://api.github.com/repos/huggingface/datasets/issues/7373/comments | https://api.github.com/repos/huggingface/datasets/issues/7373/events | https://github.com/huggingface/datasets/issues/7373 | 2,793,237,139 | I_kwDODunzps6mfWqT | 7,373 | Excessive RAM Usage After Dataset Concatenation concatenate_datasets | {
"login": "sam-hey",
"id": 40773225,
"node_id": "MDQ6VXNlcjQwNzczMjI1",
"avatar_url": "https://avatars.githubusercontent.com/u/40773225?v=4",
"gravatar_id": "",
"url": "https://api.github.com/users/sam-hey",
"html_url": "https://github.com/sam-hey",
"followers_url": "https://api.github.com/users/sam-he... | [] | open | false | [] | null | 3 | 2025-01-16T16:33:10 | 2025-03-27T17:40:59 | null | null | NONE | [] | null | null | null | null | ### Describe the bug
When loading a dataset from disk, concatenating it, and starting the training process, the RAM usage progressively increases until the kernel terminates the process due to excessive memory consumption.
https://github.com/huggingface/datasets/issues/2276
### Steps to reproduce the bug
```python
... | null | {
"url": "https://api.github.com/repos/huggingface/datasets/issues/7373/reactions",
"total_count": 0,
"+1": 0,
"-1": 0,
"laugh": 0,
"hooray": 0,
"confused": 0,
"heart": 0,
"rocket": 0,
"eyes": 0
} | https://api.github.com/repos/huggingface/datasets/issues/7373/timeline | null | null | {
"total": 0,
"completed": 0,
"percent_completed": 0
} | {
"blocked_by": 0,
"total_blocked_by": 0,
"blocking": 0,
"total_blocking": 0
} | null | false |
https://api.github.com/repos/huggingface/datasets/issues/7372 | https://api.github.com/repos/huggingface/datasets | https://api.github.com/repos/huggingface/datasets/issues/7372/labels{/name} | https://api.github.com/repos/huggingface/datasets/issues/7372/comments | https://api.github.com/repos/huggingface/datasets/issues/7372/events | https://github.com/huggingface/datasets/issues/7372 | 2,791,760,968 | I_kwDODunzps6mZuRI | 7,372 | Inconsistent Behavior Between `load_dataset` and `load_from_disk` When Loading Sharded Datasets | {
"login": "gaohongkui",
"id": 38203359,
"node_id": "MDQ6VXNlcjM4MjAzMzU5",
"avatar_url": "https://avatars.githubusercontent.com/u/38203359?v=4",
"gravatar_id": "",
"url": "https://api.github.com/users/gaohongkui",
"html_url": "https://github.com/gaohongkui",
"followers_url": "https://api.github.com/use... | [] | open | false | [] | null | 0 | 2025-01-16T05:47:20 | 2025-01-16T05:47:20 | null | null | NONE | [] | null | null | null | null | ### Description
I encountered an inconsistency in behavior between `load_dataset` and `load_from_disk` when loading sharded datasets. Here is a minimal example to reproduce the issue:
#### Code 1: Using `load_dataset`
```python
from datasets import Dataset, load_dataset
# First save with max_shard_size=10
Dataset.fr... | null | {
"url": "https://api.github.com/repos/huggingface/datasets/issues/7372/reactions",
"total_count": 0,
"+1": 0,
"-1": 0,
"laugh": 0,
"hooray": 0,
"confused": 0,
"heart": 0,
"rocket": 0,
"eyes": 0
} | https://api.github.com/repos/huggingface/datasets/issues/7372/timeline | null | null | {
"total": 0,
"completed": 0,
"percent_completed": 0
} | {
"blocked_by": 0,
"total_blocked_by": 0,
"blocking": 0,
"total_blocking": 0
} | null | false |
https://api.github.com/repos/huggingface/datasets/issues/7371 | https://api.github.com/repos/huggingface/datasets | https://api.github.com/repos/huggingface/datasets/issues/7371/labels{/name} | https://api.github.com/repos/huggingface/datasets/issues/7371/comments | https://api.github.com/repos/huggingface/datasets/issues/7371/events | https://github.com/huggingface/datasets/issues/7371 | 2,790,549,889 | I_kwDODunzps6mVGmB | 7,371 | 500 Server error with pushing a dataset | {
"login": "martinmatak",
"id": 7677814,
"node_id": "MDQ6VXNlcjc2Nzc4MTQ=",
"avatar_url": "https://avatars.githubusercontent.com/u/7677814?v=4",
"gravatar_id": "",
"url": "https://api.github.com/users/martinmatak",
"html_url": "https://github.com/martinmatak",
"followers_url": "https://api.github.com/us... | [] | open | false | [] | null | 1 | 2025-01-15T18:23:02 | 2025-01-15T20:06:05 | null | null | NONE | [] | null | null | null | null | ### Describe the bug
Suddenly, I started getting this error message saying it was an internal error.
`Error creating/pushing dataset: 500 Server Error: Internal Server Error for url: https://huggingface.co/api/datasets/ll4ma-lab/grasp-dataset/commit/main (Request ID: Root=1-6787f0b7-66d5bd45413e481c4c2fb22d;670d04ff-... | null | {
"url": "https://api.github.com/repos/huggingface/datasets/issues/7371/reactions",
"total_count": 0,
"+1": 0,
"-1": 0,
"laugh": 0,
"hooray": 0,
"confused": 0,
"heart": 0,
"rocket": 0,
"eyes": 0
} | https://api.github.com/repos/huggingface/datasets/issues/7371/timeline | null | null | {
"total": 0,
"completed": 0,
"percent_completed": 0
} | {
"blocked_by": 0,
"total_blocked_by": 0,
"blocking": 0,
"total_blocking": 0
} | null | false |
https://api.github.com/repos/huggingface/datasets/issues/7370 | https://api.github.com/repos/huggingface/datasets | https://api.github.com/repos/huggingface/datasets/issues/7370/labels{/name} | https://api.github.com/repos/huggingface/datasets/issues/7370/comments | https://api.github.com/repos/huggingface/datasets/issues/7370/events | https://github.com/huggingface/datasets/pull/7370 | 2,787,972,786 | PR_kwDODunzps6HwAu7 | 7,370 | Support faster processing using pandas or polars functions in `IterableDataset.map()` | {
"login": "lhoestq",
"id": 42851186,
"node_id": "MDQ6VXNlcjQyODUxMTg2",
"avatar_url": "https://avatars.githubusercontent.com/u/42851186?v=4",
"gravatar_id": "",
"url": "https://api.github.com/users/lhoestq",
"html_url": "https://github.com/lhoestq",
"followers_url": "https://api.github.com/users/lhoest... | [] | closed | false | [] | null | 2 | 2025-01-14T18:14:13 | 2025-01-31T11:08:15 | 2025-01-30T13:30:57 | null | MEMBER | [] | null | null | false | {
"url": "https://api.github.com/repos/huggingface/datasets/pulls/7370",
"html_url": "https://github.com/huggingface/datasets/pull/7370",
"diff_url": "https://github.com/huggingface/datasets/pull/7370.diff",
"patch_url": "https://github.com/huggingface/datasets/pull/7370.patch",
"merged_at": "2025-01-30T13:30... | Following the polars integration :)
Allow super fast processing using pandas or polars functions in `IterableDataset.map()` by adding support to pandas and polars formatting in `IterableDataset`
```python
import polars as pl
from datasets import Dataset
ds = Dataset.from_dict({"i": range(10)}).to_iterable_da... | {
"login": "lhoestq",
"id": 42851186,
"node_id": "MDQ6VXNlcjQyODUxMTg2",
"avatar_url": "https://avatars.githubusercontent.com/u/42851186?v=4",
"gravatar_id": "",
"url": "https://api.github.com/users/lhoestq",
"html_url": "https://github.com/lhoestq",
"followers_url": "https://api.github.com/users/lhoest... | {
"url": "https://api.github.com/repos/huggingface/datasets/issues/7370/reactions",
"total_count": 0,
"+1": 0,
"-1": 0,
"laugh": 0,
"hooray": 0,
"confused": 0,
"heart": 0,
"rocket": 0,
"eyes": 0
} | https://api.github.com/repos/huggingface/datasets/issues/7370/timeline | null | null | null | null | null | true |
https://api.github.com/repos/huggingface/datasets/issues/7369 | https://api.github.com/repos/huggingface/datasets | https://api.github.com/repos/huggingface/datasets/issues/7369/labels{/name} | https://api.github.com/repos/huggingface/datasets/issues/7369/comments | https://api.github.com/repos/huggingface/datasets/issues/7369/events | https://github.com/huggingface/datasets/issues/7369 | 2,787,193,238 | I_kwDODunzps6mITGW | 7,369 | Importing dataset gives unhelpful error message when filenames in metadata.csv are not found in the directory | {
"login": "svencornetsdegroot",
"id": 38278139,
"node_id": "MDQ6VXNlcjM4Mjc4MTM5",
"avatar_url": "https://avatars.githubusercontent.com/u/38278139?v=4",
"gravatar_id": "",
"url": "https://api.github.com/users/svencornetsdegroot",
"html_url": "https://github.com/svencornetsdegroot",
"followers_url": "ht... | [] | open | false | [] | null | 1 | 2025-01-14T13:53:21 | 2025-01-14T15:05:51 | null | null | NONE | [] | null | null | null | null | ### Describe the bug
While importing an audiofolder dataset, where the names of the audiofiles don't correspond to the filenames in the metadata.csv, we get an unclear error message that is not helpful for the debugging, i.e.
```
ValueError: Instruction "train" corresponds to no data!
```
### Steps to reproduce the ... | null | {
"url": "https://api.github.com/repos/huggingface/datasets/issues/7369/reactions",
"total_count": 1,
"+1": 1,
"-1": 0,
"laugh": 0,
"hooray": 0,
"confused": 0,
"heart": 0,
"rocket": 0,
"eyes": 0
} | https://api.github.com/repos/huggingface/datasets/issues/7369/timeline | null | null | {
"total": 0,
"completed": 0,
"percent_completed": 0
} | {
"blocked_by": 0,
"total_blocked_by": 0,
"blocking": 0,
"total_blocking": 0
} | null | false |
https://api.github.com/repos/huggingface/datasets/issues/7368 | https://api.github.com/repos/huggingface/datasets | https://api.github.com/repos/huggingface/datasets/issues/7368/labels{/name} | https://api.github.com/repos/huggingface/datasets/issues/7368/comments | https://api.github.com/repos/huggingface/datasets/issues/7368/events | https://github.com/huggingface/datasets/pull/7368 | 2,784,272,477 | PR_kwDODunzps6HjE97 | 7,368 | Add with_split to DatasetDict.map | {
"login": "jp1924",
"id": 93233241,
"node_id": "U_kgDOBY6gWQ",
"avatar_url": "https://avatars.githubusercontent.com/u/93233241?v=4",
"gravatar_id": "",
"url": "https://api.github.com/users/jp1924",
"html_url": "https://github.com/jp1924",
"followers_url": "https://api.github.com/users/jp1924/followers"... | [] | closed | false | [] | null | 9 | 2025-01-13T15:09:56 | 2025-03-08T05:45:02 | 2025-03-07T14:09:52 | null | CONTRIBUTOR | [] | null | null | false | {
"url": "https://api.github.com/repos/huggingface/datasets/pulls/7368",
"html_url": "https://github.com/huggingface/datasets/pull/7368",
"diff_url": "https://github.com/huggingface/datasets/pull/7368.diff",
"patch_url": "https://github.com/huggingface/datasets/pull/7368.patch",
"merged_at": "2025-03-07T14:09... | #7356 | {
"login": "lhoestq",
"id": 42851186,
"node_id": "MDQ6VXNlcjQyODUxMTg2",
"avatar_url": "https://avatars.githubusercontent.com/u/42851186?v=4",
"gravatar_id": "",
"url": "https://api.github.com/users/lhoestq",
"html_url": "https://github.com/lhoestq",
"followers_url": "https://api.github.com/users/lhoest... | {
"url": "https://api.github.com/repos/huggingface/datasets/issues/7368/reactions",
"total_count": 0,
"+1": 0,
"-1": 0,
"laugh": 0,
"hooray": 0,
"confused": 0,
"heart": 0,
"rocket": 0,
"eyes": 0
} | https://api.github.com/repos/huggingface/datasets/issues/7368/timeline | null | null | null | null | null | true |
https://api.github.com/repos/huggingface/datasets/issues/7366 | https://api.github.com/repos/huggingface/datasets | https://api.github.com/repos/huggingface/datasets/issues/7366/labels{/name} | https://api.github.com/repos/huggingface/datasets/issues/7366/comments | https://api.github.com/repos/huggingface/datasets/issues/7366/events | https://github.com/huggingface/datasets/issues/7366 | 2,781,522,894 | I_kwDODunzps6lyqvO | 7,366 | Dataset.from_dict() can't handle large dict | {
"login": "CSU-OSS",
"id": 164967134,
"node_id": "U_kgDOCdUy3g",
"avatar_url": "https://avatars.githubusercontent.com/u/164967134?v=4",
"gravatar_id": "",
"url": "https://api.github.com/users/CSU-OSS",
"html_url": "https://github.com/CSU-OSS",
"followers_url": "https://api.github.com/users/CSU-OSS/foll... | [] | open | false | [] | null | 0 | 2025-01-11T02:05:21 | 2025-01-11T02:05:21 | null | null | NONE | [] | null | null | null | null | ### Describe the bug
I have 26,000,000 3-tuples. When I use Dataset.from_dict() to load, neither. py nor Jupiter notebook can run successfully. This is my code:
```
# len(example_data) is 26,000,000, 'diff' is a text
diff1_list = [example_data[i].texts[0] for i in range(len(example_data))]
diff2_list =... | null | {
"url": "https://api.github.com/repos/huggingface/datasets/issues/7366/reactions",
"total_count": 1,
"+1": 1,
"-1": 0,
"laugh": 0,
"hooray": 0,
"confused": 0,
"heart": 0,
"rocket": 0,
"eyes": 0
} | https://api.github.com/repos/huggingface/datasets/issues/7366/timeline | null | null | {
"total": 0,
"completed": 0,
"percent_completed": 0
} | {
"blocked_by": 0,
"total_blocked_by": 0,
"blocking": 0,
"total_blocking": 0
} | null | false |
https://api.github.com/repos/huggingface/datasets/issues/7365 | https://api.github.com/repos/huggingface/datasets | https://api.github.com/repos/huggingface/datasets/issues/7365/labels{/name} | https://api.github.com/repos/huggingface/datasets/issues/7365/comments | https://api.github.com/repos/huggingface/datasets/issues/7365/events | https://github.com/huggingface/datasets/issues/7365 | 2,780,216,199 | I_kwDODunzps6ltruH | 7,365 | A parameter is specified but not used in datasets.arrow_dataset.Dataset.from_pandas() | {
"login": "NourOM02",
"id": 69003192,
"node_id": "MDQ6VXNlcjY5MDAzMTky",
"avatar_url": "https://avatars.githubusercontent.com/u/69003192?v=4",
"gravatar_id": "",
"url": "https://api.github.com/users/NourOM02",
"html_url": "https://github.com/NourOM02",
"followers_url": "https://api.github.com/users/Nou... | [] | open | false | [] | null | 0 | 2025-01-10T13:39:33 | 2025-01-10T13:39:33 | null | null | NONE | [] | null | null | null | null | ### Describe the bug
I am interested in creating train, test and eval splits from a pandas Dataframe, therefore I was looking at the possibilities I can follow. I noticed the split parameter and was hopeful to use it in order to generate the 3 at once, however, while trying to understand the code, i noticed that it ha... | null | {
"url": "https://api.github.com/repos/huggingface/datasets/issues/7365/reactions",
"total_count": 0,
"+1": 0,
"-1": 0,
"laugh": 0,
"hooray": 0,
"confused": 0,
"heart": 0,
"rocket": 0,
"eyes": 0
} | https://api.github.com/repos/huggingface/datasets/issues/7365/timeline | null | null | {
"total": 0,
"completed": 0,
"percent_completed": 0
} | {
"blocked_by": 0,
"total_blocked_by": 0,
"blocking": 0,
"total_blocking": 0
} | null | false |
https://api.github.com/repos/huggingface/datasets/issues/7364 | https://api.github.com/repos/huggingface/datasets | https://api.github.com/repos/huggingface/datasets/issues/7364/labels{/name} | https://api.github.com/repos/huggingface/datasets/issues/7364/comments | https://api.github.com/repos/huggingface/datasets/issues/7364/events | https://github.com/huggingface/datasets/issues/7364 | 2,776,929,268 | I_kwDODunzps6lhJP0 | 7,364 | API endpoints for gated dataset access requests | {
"login": "jerome-white",
"id": 6140840,
"node_id": "MDQ6VXNlcjYxNDA4NDA=",
"avatar_url": "https://avatars.githubusercontent.com/u/6140840?v=4",
"gravatar_id": "",
"url": "https://api.github.com/users/jerome-white",
"html_url": "https://github.com/jerome-white",
"followers_url": "https://api.github.com... | [
{
"id": 1935892871,
"node_id": "MDU6TGFiZWwxOTM1ODkyODcx",
"url": "https://api.github.com/repos/huggingface/datasets/labels/enhancement",
"name": "enhancement",
"color": "a2eeef",
"default": true,
"description": "New feature or request",
"archived_at": null,
"archived_by": null
... | closed | false | [] | null | 3 | 2025-01-09T06:21:20 | 2025-01-09T11:17:40 | 2025-01-09T11:17:20 | null | NONE | [] | null | null | null | null | ### Feature request
I would like a programatic way of requesting access to gated datasets. The current solution to gain access forces me to visit a website and physically click an "agreement" button (as per the [documentation](https://huggingface.co/docs/hub/en/datasets-gated#access-gated-datasets-as-a-user)).
An i... | {
"login": "jerome-white",
"id": 6140840,
"node_id": "MDQ6VXNlcjYxNDA4NDA=",
"avatar_url": "https://avatars.githubusercontent.com/u/6140840?v=4",
"gravatar_id": "",
"url": "https://api.github.com/users/jerome-white",
"html_url": "https://github.com/jerome-white",
"followers_url": "https://api.github.com... | {
"url": "https://api.github.com/repos/huggingface/datasets/issues/7364/reactions",
"total_count": 0,
"+1": 0,
"-1": 0,
"laugh": 0,
"hooray": 0,
"confused": 0,
"heart": 0,
"rocket": 0,
"eyes": 0
} | https://api.github.com/repos/huggingface/datasets/issues/7364/timeline | null | not_planned | {
"total": 0,
"completed": 0,
"percent_completed": 0
} | {
"blocked_by": 0,
"total_blocked_by": 0,
"blocking": 0,
"total_blocking": 0
} | null | false |
Subsets and Splits
No community queries yet
The top public SQL queries from the community will appear here once available.