
url stringlengths 61 61 | repository_url stringclasses 1
value | labels_url stringlengths 75 75 | comments_url stringlengths 70 70 | events_url stringlengths 68 68 | html_url stringlengths 49 51 | id int64 1.1B 5.46B | node_id stringlengths 18 25 | number int64 3.55k 8.62k | title stringlengths 1 290 | user dict | labels listlengths 0 4 | state stringclasses 2
values | locked bool 1
class | assignees listlengths 0 4 | milestone dict | comments int64 0 49 | created_at timestamp[ms]date 2022-01-10 10:32:04 2026-09-14 22:10:44 | updated_at timestamp[ms]date 2022-01-11 14:16:47 2026-09-15 02:20:24 | closed_at timestamp[ms]date 2022-01-11 14:16:47 2026-09-14 22:11:06 ⌀ | assignee dict | author_association stringclasses 4
values | issue_field_values listlengths 0 0 | type null | active_lock_reason null | draft bool 2
classes | pull_request dict | body stringlengths 1 58.6k ⌀ | closed_by dict | reactions dict | timeline_url stringlengths 70 70 | performed_via_github_app null | state_reason stringclasses 4
values | sub_issues_summary dict | issue_dependencies_summary dict | pinned_comment null | is_pull_request bool 2
classes |
|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|
https://api.github.com/repos/huggingface/datasets/issues/5389 | https://api.github.com/repos/huggingface/datasets | https://api.github.com/repos/huggingface/datasets/issues/5389/labels{/name} | https://api.github.com/repos/huggingface/datasets/issues/5389/comments | https://api.github.com/repos/huggingface/datasets/issues/5389/events | https://github.com/huggingface/datasets/pull/5389 | 1,509,348,626 | PR_kwDODunzps5GHsOo | 5,389 | Fix link in `load_dataset` docstring | {
"login": "mariosasko",
"id": 47462742,
"node_id": "MDQ6VXNlcjQ3NDYyNzQy",
"avatar_url": "https://avatars.githubusercontent.com/u/47462742?v=4",
"gravatar_id": "",
"url": "https://api.github.com/users/mariosasko",
"html_url": "https://github.com/mariosasko",
"followers_url": "https://api.github.com/use... | [] | closed | false | [] | null | 6 | 2022-12-23T13:26:31 | 2023-01-25T19:00:43 | 2023-01-24T16:33:38 | null | COLLABORATOR | [] | null | null | false | {
"url": "https://api.github.com/repos/huggingface/datasets/pulls/5389",
"html_url": "https://github.com/huggingface/datasets/pull/5389",
"diff_url": "https://github.com/huggingface/datasets/pull/5389.diff",
"patch_url": "https://github.com/huggingface/datasets/pull/5389.patch",
"merged_at": "2023-01-24T16:33... | Fix https://github.com/huggingface/datasets/issues/5387, fix https://github.com/huggingface/datasets/issues/4566 | {
"login": "mariosasko",
"id": 47462742,
"node_id": "MDQ6VXNlcjQ3NDYyNzQy",
"avatar_url": "https://avatars.githubusercontent.com/u/47462742?v=4",
"gravatar_id": "",
"url": "https://api.github.com/users/mariosasko",
"html_url": "https://github.com/mariosasko",
"followers_url": "https://api.github.com/use... | {
"url": "https://api.github.com/repos/huggingface/datasets/issues/5389/reactions",
"total_count": 0,
"+1": 0,
"-1": 0,
"laugh": 0,
"hooray": 0,
"confused": 0,
"heart": 0,
"rocket": 0,
"eyes": 0
} | https://api.github.com/repos/huggingface/datasets/issues/5389/timeline | null | null | null | null | null | true |
https://api.github.com/repos/huggingface/datasets/issues/5388 | https://api.github.com/repos/huggingface/datasets | https://api.github.com/repos/huggingface/datasets/issues/5388/labels{/name} | https://api.github.com/repos/huggingface/datasets/issues/5388/comments | https://api.github.com/repos/huggingface/datasets/issues/5388/events | https://github.com/huggingface/datasets/issues/5388 | 1,509,042,348 | I_kwDODunzps5Z8iis | 5,388 | Getting Value Error while loading a dataset.. | {
"login": "valmetisrinivas",
"id": 51160232,
"node_id": "MDQ6VXNlcjUxMTYwMjMy",
"avatar_url": "https://avatars.githubusercontent.com/u/51160232?v=4",
"gravatar_id": "",
"url": "https://api.github.com/users/valmetisrinivas",
"html_url": "https://github.com/valmetisrinivas",
"followers_url": "https://api... | [] | closed | false | [] | null | 4 | 2022-12-23T08:16:43 | 2022-12-29T08:36:33 | 2022-12-27T17:59:09 | null | NONE | [] | null | null | null | null | ### Describe the bug
I am trying to load a dataset using Hugging Face Datasets load_dataset method. I am getting the value error as show below. Can someone help with this? I am using Windows laptop and Google Colab notebook.
```
WARNING:datasets.builder:Using custom data configuration default-a1d9e8eaedd958cd
---... | {
"login": "albertvillanova",
"id": 8515462,
"node_id": "MDQ6VXNlcjg1MTU0NjI=",
"avatar_url": "https://avatars.githubusercontent.com/u/8515462?v=4",
"gravatar_id": "",
"url": "https://api.github.com/users/albertvillanova",
"html_url": "https://github.com/albertvillanova",
"followers_url": "https://api.g... | {
"url": "https://api.github.com/repos/huggingface/datasets/issues/5388/reactions",
"total_count": 0,
"+1": 0,
"-1": 0,
"laugh": 0,
"hooray": 0,
"confused": 0,
"heart": 0,
"rocket": 0,
"eyes": 0
} | https://api.github.com/repos/huggingface/datasets/issues/5388/timeline | null | completed | {
"total": 0,
"completed": 0,
"percent_completed": 0
} | {
"blocked_by": 0,
"total_blocked_by": 0,
"blocking": 0,
"total_blocking": 0
} | null | false |
https://api.github.com/repos/huggingface/datasets/issues/5387 | https://api.github.com/repos/huggingface/datasets | https://api.github.com/repos/huggingface/datasets/issues/5387/labels{/name} | https://api.github.com/repos/huggingface/datasets/issues/5387/comments | https://api.github.com/repos/huggingface/datasets/issues/5387/events | https://github.com/huggingface/datasets/issues/5387 | 1,508,740,177 | I_kwDODunzps5Z7YxR | 5,387 | Missing documentation page : improve-performance | {
"login": "astariul",
"id": 43774355,
"node_id": "MDQ6VXNlcjQzNzc0MzU1",
"avatar_url": "https://avatars.githubusercontent.com/u/43774355?v=4",
"gravatar_id": "",
"url": "https://api.github.com/users/astariul",
"html_url": "https://github.com/astariul",
"followers_url": "https://api.github.com/users/ast... | [] | closed | false | [] | null | 1 | 2022-12-23T01:12:57 | 2023-01-24T16:33:40 | 2023-01-24T16:33:40 | null | NONE | [] | null | null | null | null | ### Describe the bug
Trying to access https://huggingface.co/docs/datasets/v2.8.0/en/package_reference/cache#improve-performance, the page is missing.
The link is in here : https://huggingface.co/docs/datasets/v2.8.0/en/package_reference/loading_methods#datasets.load_dataset.keep_in_memory
### Steps to reproduce t... | {
"login": "mariosasko",
"id": 47462742,
"node_id": "MDQ6VXNlcjQ3NDYyNzQy",
"avatar_url": "https://avatars.githubusercontent.com/u/47462742?v=4",
"gravatar_id": "",
"url": "https://api.github.com/users/mariosasko",
"html_url": "https://github.com/mariosasko",
"followers_url": "https://api.github.com/use... | {
"url": "https://api.github.com/repos/huggingface/datasets/issues/5387/reactions",
"total_count": 0,
"+1": 0,
"-1": 0,
"laugh": 0,
"hooray": 0,
"confused": 0,
"heart": 0,
"rocket": 0,
"eyes": 0
} | https://api.github.com/repos/huggingface/datasets/issues/5387/timeline | null | completed | {
"total": 0,
"completed": 0,
"percent_completed": 0
} | {
"blocked_by": 0,
"total_blocked_by": 0,
"blocking": 0,
"total_blocking": 0
} | null | false |
https://api.github.com/repos/huggingface/datasets/issues/5386 | https://api.github.com/repos/huggingface/datasets | https://api.github.com/repos/huggingface/datasets/issues/5386/labels{/name} | https://api.github.com/repos/huggingface/datasets/issues/5386/comments | https://api.github.com/repos/huggingface/datasets/issues/5386/events | https://github.com/huggingface/datasets/issues/5386 | 1,508,592,918 | I_kwDODunzps5Z600W | 5,386 | `max_shard_size` in `datasets.push_to_hub()` breaks with large files | {
"login": "salieri",
"id": 1086393,
"node_id": "MDQ6VXNlcjEwODYzOTM=",
"avatar_url": "https://avatars.githubusercontent.com/u/1086393?v=4",
"gravatar_id": "",
"url": "https://api.github.com/users/salieri",
"html_url": "https://github.com/salieri",
"followers_url": "https://api.github.com/users/salieri/... | [] | closed | false | [] | null | 2 | 2022-12-22T21:50:58 | 2022-12-26T23:45:51 | 2022-12-26T23:45:51 | null | NONE | [] | null | null | null | null | ### Describe the bug
`max_shard_size` parameter for `datasets.push_to_hub()` works unreliably with large files, generating shard files that are way past the specified limit.
In my private dataset, which contains unprocessed images of all sizes (up to `~100MB` per file), I've encountered cases where `max_shard_siz... | {
"login": "salieri",
"id": 1086393,
"node_id": "MDQ6VXNlcjEwODYzOTM=",
"avatar_url": "https://avatars.githubusercontent.com/u/1086393?v=4",
"gravatar_id": "",
"url": "https://api.github.com/users/salieri",
"html_url": "https://github.com/salieri",
"followers_url": "https://api.github.com/users/salieri/... | {
"url": "https://api.github.com/repos/huggingface/datasets/issues/5386/reactions",
"total_count": 0,
"+1": 0,
"-1": 0,
"laugh": 0,
"hooray": 0,
"confused": 0,
"heart": 0,
"rocket": 0,
"eyes": 0
} | https://api.github.com/repos/huggingface/datasets/issues/5386/timeline | null | completed | {
"total": 0,
"completed": 0,
"percent_completed": 0
} | {
"blocked_by": 0,
"total_blocked_by": 0,
"blocking": 0,
"total_blocking": 0
} | null | false |
https://api.github.com/repos/huggingface/datasets/issues/5385 | https://api.github.com/repos/huggingface/datasets | https://api.github.com/repos/huggingface/datasets/issues/5385/labels{/name} | https://api.github.com/repos/huggingface/datasets/issues/5385/comments | https://api.github.com/repos/huggingface/datasets/issues/5385/events | https://github.com/huggingface/datasets/issues/5385 | 1,508,535,532 | I_kwDODunzps5Z6mzs | 5,385 | Is `fs=` deprecated in `load_from_disk()` as well? | {
"login": "dconathan",
"id": 15098095,
"node_id": "MDQ6VXNlcjE1MDk4MDk1",
"avatar_url": "https://avatars.githubusercontent.com/u/15098095?v=4",
"gravatar_id": "",
"url": "https://api.github.com/users/dconathan",
"html_url": "https://github.com/dconathan",
"followers_url": "https://api.github.com/users/... | [] | closed | false | [] | null | 3 | 2022-12-22T21:00:45 | 2023-01-23T10:50:05 | 2023-01-23T10:50:04 | null | CONTRIBUTOR | [] | null | null | null | null | ### Describe the bug
The `fs=` argument was deprecated from `Dataset.save_to_disk` and `Dataset.load_from_disk` in favor of automagically figuring it out via fsspec:
https://github.com/huggingface/datasets/blob/9a7272cd4222383a5b932b0083a4cc173fda44e8/src/datasets/arrow_dataset.py#L1339-L1340
Is there a reason the... | {
"login": "albertvillanova",
"id": 8515462,
"node_id": "MDQ6VXNlcjg1MTU0NjI=",
"avatar_url": "https://avatars.githubusercontent.com/u/8515462?v=4",
"gravatar_id": "",
"url": "https://api.github.com/users/albertvillanova",
"html_url": "https://github.com/albertvillanova",
"followers_url": "https://api.g... | {
"url": "https://api.github.com/repos/huggingface/datasets/issues/5385/reactions",
"total_count": 0,
"+1": 0,
"-1": 0,
"laugh": 0,
"hooray": 0,
"confused": 0,
"heart": 0,
"rocket": 0,
"eyes": 0
} | https://api.github.com/repos/huggingface/datasets/issues/5385/timeline | null | completed | {
"total": 0,
"completed": 0,
"percent_completed": 0
} | {
"blocked_by": 0,
"total_blocked_by": 0,
"blocking": 0,
"total_blocking": 0
} | null | false |
https://api.github.com/repos/huggingface/datasets/issues/5384 | https://api.github.com/repos/huggingface/datasets | https://api.github.com/repos/huggingface/datasets/issues/5384/labels{/name} | https://api.github.com/repos/huggingface/datasets/issues/5384/comments | https://api.github.com/repos/huggingface/datasets/issues/5384/events | https://github.com/huggingface/datasets/pull/5384 | 1,508,152,598 | PR_kwDODunzps5GDmR6 | 5,384 | Handle 0-dim tensors in `cast_to_python_objects` | {
"login": "mariosasko",
"id": 47462742,
"node_id": "MDQ6VXNlcjQ3NDYyNzQy",
"avatar_url": "https://avatars.githubusercontent.com/u/47462742?v=4",
"gravatar_id": "",
"url": "https://api.github.com/users/mariosasko",
"html_url": "https://github.com/mariosasko",
"followers_url": "https://api.github.com/use... | [] | closed | false | [] | null | 2 | 2022-12-22T16:15:30 | 2023-01-13T16:10:15 | 2023-01-13T16:00:52 | null | COLLABORATOR | [] | null | null | false | {
"url": "https://api.github.com/repos/huggingface/datasets/pulls/5384",
"html_url": "https://github.com/huggingface/datasets/pull/5384",
"diff_url": "https://github.com/huggingface/datasets/pull/5384.diff",
"patch_url": "https://github.com/huggingface/datasets/pull/5384.patch",
"merged_at": "2023-01-13T16:00... | Fix #5229 | {
"login": "mariosasko",
"id": 47462742,
"node_id": "MDQ6VXNlcjQ3NDYyNzQy",
"avatar_url": "https://avatars.githubusercontent.com/u/47462742?v=4",
"gravatar_id": "",
"url": "https://api.github.com/users/mariosasko",
"html_url": "https://github.com/mariosasko",
"followers_url": "https://api.github.com/use... | {
"url": "https://api.github.com/repos/huggingface/datasets/issues/5384/reactions",
"total_count": 0,
"+1": 0,
"-1": 0,
"laugh": 0,
"hooray": 0,
"confused": 0,
"heart": 0,
"rocket": 0,
"eyes": 0
} | https://api.github.com/repos/huggingface/datasets/issues/5384/timeline | null | null | null | null | null | true |
https://api.github.com/repos/huggingface/datasets/issues/5383 | https://api.github.com/repos/huggingface/datasets | https://api.github.com/repos/huggingface/datasets/issues/5383/labels{/name} | https://api.github.com/repos/huggingface/datasets/issues/5383/comments | https://api.github.com/repos/huggingface/datasets/issues/5383/events | https://github.com/huggingface/datasets/issues/5383 | 1,507,293,968 | I_kwDODunzps5Z13sQ | 5,383 | IterableDataset missing column_names, differs from Dataset interface | {
"login": "iceboundflame",
"id": 933687,
"node_id": "MDQ6VXNlcjkzMzY4Nw==",
"avatar_url": "https://avatars.githubusercontent.com/u/933687?v=4",
"gravatar_id": "",
"url": "https://api.github.com/users/iceboundflame",
"html_url": "https://github.com/iceboundflame",
"followers_url": "https://api.github.co... | [
{
"id": 1935892871,
"node_id": "MDU6TGFiZWwxOTM1ODkyODcx",
"url": "https://api.github.com/repos/huggingface/datasets/labels/enhancement",
"name": "enhancement",
"color": "a2eeef",
"default": true,
"description": "New feature or request",
"archived_at": null,
"archived_by": null
... | closed | false | [
{
"login": "patrickloeber",
"id": 50772274,
"node_id": "MDQ6VXNlcjUwNzcyMjc0",
"avatar_url": "https://avatars.githubusercontent.com/u/50772274?v=4",
"gravatar_id": "",
"url": "https://api.github.com/users/patrickloeber",
"html_url": "https://github.com/patrickloeber",
"followers_url"... | null | 6 | 2022-12-22T05:27:02 | 2023-03-13T19:03:33 | 2023-03-13T19:03:33 | {
"login": "patrickloeber",
"id": 50772274,
"node_id": "MDQ6VXNlcjUwNzcyMjc0",
"avatar_url": "https://avatars.githubusercontent.com/u/50772274?v=4",
"gravatar_id": "",
"url": "https://api.github.com/users/patrickloeber",
"html_url": "https://github.com/patrickloeber",
"followers_url": "https://api.githu... | NONE | [] | null | null | null | null | ### Describe the bug
The documentation on [Stream](https://huggingface.co/docs/datasets/v1.18.2/stream.html) seems to imply that IterableDataset behaves just like a Dataset. However, examples like
```
dataset.map(augment_data, batched=True, remove_columns=dataset.column_names, ...)
```
will not work because `.colu... | {
"login": "mariosasko",
"id": 47462742,
"node_id": "MDQ6VXNlcjQ3NDYyNzQy",
"avatar_url": "https://avatars.githubusercontent.com/u/47462742?v=4",
"gravatar_id": "",
"url": "https://api.github.com/users/mariosasko",
"html_url": "https://github.com/mariosasko",
"followers_url": "https://api.github.com/use... | {
"url": "https://api.github.com/repos/huggingface/datasets/issues/5383/reactions",
"total_count": 0,
"+1": 0,
"-1": 0,
"laugh": 0,
"hooray": 0,
"confused": 0,
"heart": 0,
"rocket": 0,
"eyes": 0
} | https://api.github.com/repos/huggingface/datasets/issues/5383/timeline | null | completed | {
"total": 0,
"completed": 0,
"percent_completed": 0
} | {
"blocked_by": 0,
"total_blocked_by": 0,
"blocking": 0,
"total_blocking": 0
} | null | false |
https://api.github.com/repos/huggingface/datasets/issues/5382 | https://api.github.com/repos/huggingface/datasets | https://api.github.com/repos/huggingface/datasets/issues/5382/labels{/name} | https://api.github.com/repos/huggingface/datasets/issues/5382/comments | https://api.github.com/repos/huggingface/datasets/issues/5382/events | https://github.com/huggingface/datasets/pull/5382 | 1,504,788,691 | PR_kwDODunzps5F4Q0V | 5,382 | Raise from disconnect error in xopen | {
"login": "lhoestq",
"id": 42851186,
"node_id": "MDQ6VXNlcjQyODUxMTg2",
"avatar_url": "https://avatars.githubusercontent.com/u/42851186?v=4",
"gravatar_id": "",
"url": "https://api.github.com/users/lhoestq",
"html_url": "https://github.com/lhoestq",
"followers_url": "https://api.github.com/users/lhoest... | [] | closed | false | [] | null | 3 | 2022-12-20T15:52:44 | 2023-01-26T09:51:13 | 2023-01-26T09:42:45 | null | MEMBER | [] | null | null | false | {
"url": "https://api.github.com/repos/huggingface/datasets/pulls/5382",
"html_url": "https://github.com/huggingface/datasets/pull/5382",
"diff_url": "https://github.com/huggingface/datasets/pull/5382.diff",
"patch_url": "https://github.com/huggingface/datasets/pull/5382.patch",
"merged_at": "2023-01-26T09:42... | this way we can know the cause of the disconnect
related to https://github.com/huggingface/datasets/issues/5374 | {
"login": "lhoestq",
"id": 42851186,
"node_id": "MDQ6VXNlcjQyODUxMTg2",
"avatar_url": "https://avatars.githubusercontent.com/u/42851186?v=4",
"gravatar_id": "",
"url": "https://api.github.com/users/lhoestq",
"html_url": "https://github.com/lhoestq",
"followers_url": "https://api.github.com/users/lhoest... | {
"url": "https://api.github.com/repos/huggingface/datasets/issues/5382/reactions",
"total_count": 0,
"+1": 0,
"-1": 0,
"laugh": 0,
"hooray": 0,
"confused": 0,
"heart": 0,
"rocket": 0,
"eyes": 0
} | https://api.github.com/repos/huggingface/datasets/issues/5382/timeline | null | null | null | null | null | true |
https://api.github.com/repos/huggingface/datasets/issues/5381 | https://api.github.com/repos/huggingface/datasets | https://api.github.com/repos/huggingface/datasets/issues/5381/labels{/name} | https://api.github.com/repos/huggingface/datasets/issues/5381/comments | https://api.github.com/repos/huggingface/datasets/issues/5381/events | https://github.com/huggingface/datasets/issues/5381 | 1,504,498,387 | I_kwDODunzps5ZrNLT | 5,381 | Wrong URL for the_pile dataset | {
"login": "LeoGrin",
"id": 45738728,
"node_id": "MDQ6VXNlcjQ1NzM4NzI4",
"avatar_url": "https://avatars.githubusercontent.com/u/45738728?v=4",
"gravatar_id": "",
"url": "https://api.github.com/users/LeoGrin",
"html_url": "https://github.com/LeoGrin",
"followers_url": "https://api.github.com/users/LeoGri... | [] | closed | false | [] | null | 1 | 2022-12-20T12:40:14 | 2023-02-15T16:24:57 | 2023-02-15T16:24:57 | null | NONE | [] | null | null | null | null | ### Describe the bug
When trying to load `the_pile` dataset from the library, I get a `FileNotFound` error.
### Steps to reproduce the bug
Steps to reproduce:
Run:
```
from datasets import load_dataset
dataset = load_dataset("the_pile")
```
I get the output:
"name": "FileNotFoundError",
"message... | {
"login": "mariosasko",
"id": 47462742,
"node_id": "MDQ6VXNlcjQ3NDYyNzQy",
"avatar_url": "https://avatars.githubusercontent.com/u/47462742?v=4",
"gravatar_id": "",
"url": "https://api.github.com/users/mariosasko",
"html_url": "https://github.com/mariosasko",
"followers_url": "https://api.github.com/use... | {
"url": "https://api.github.com/repos/huggingface/datasets/issues/5381/reactions",
"total_count": 0,
"+1": 0,
"-1": 0,
"laugh": 0,
"hooray": 0,
"confused": 0,
"heart": 0,
"rocket": 0,
"eyes": 0
} | https://api.github.com/repos/huggingface/datasets/issues/5381/timeline | null | completed | {
"total": 0,
"completed": 0,
"percent_completed": 0
} | {
"blocked_by": 0,
"total_blocked_by": 0,
"blocking": 0,
"total_blocking": 0
} | null | false |
https://api.github.com/repos/huggingface/datasets/issues/5380 | https://api.github.com/repos/huggingface/datasets | https://api.github.com/repos/huggingface/datasets/issues/5380/labels{/name} | https://api.github.com/repos/huggingface/datasets/issues/5380/comments | https://api.github.com/repos/huggingface/datasets/issues/5380/events | https://github.com/huggingface/datasets/issues/5380 | 1,504,404,043 | I_kwDODunzps5Zq2JL | 5,380 | Improve dataset `.skip()` speed in streaming mode | {
"login": "versae",
"id": 173537,
"node_id": "MDQ6VXNlcjE3MzUzNw==",
"avatar_url": "https://avatars.githubusercontent.com/u/173537?v=4",
"gravatar_id": "",
"url": "https://api.github.com/users/versae",
"html_url": "https://github.com/versae",
"followers_url": "https://api.github.com/users/versae/follow... | [
{
"id": 1935892871,
"node_id": "MDU6TGFiZWwxOTM1ODkyODcx",
"url": "https://api.github.com/repos/huggingface/datasets/labels/enhancement",
"name": "enhancement",
"color": "a2eeef",
"default": true,
"description": "New feature or request",
"archived_at": null,
"archived_by": null
... | open | false | [] | null | 11 | 2022-12-20T11:25:23 | 2025-11-10T20:05:37 | null | null | CONTRIBUTOR | [] | null | null | null | null | ### Feature request
Add extra information to the `dataset_infos.json` file to include the number of samples/examples in each shard, for example in a new field `num_examples` alongside `num_bytes`. The `.skip()` function could use this information to ignore the download of a shard when in streaming mode, which AFAICT... | null | {
"url": "https://api.github.com/repos/huggingface/datasets/issues/5380/reactions",
"total_count": 8,
"+1": 8,
"-1": 0,
"laugh": 0,
"hooray": 0,
"confused": 0,
"heart": 0,
"rocket": 0,
"eyes": 0
} | https://api.github.com/repos/huggingface/datasets/issues/5380/timeline | null | null | {
"total": 0,
"completed": 0,
"percent_completed": 0
} | {
"blocked_by": 0,
"total_blocked_by": 0,
"blocking": 0,
"total_blocking": 0
} | null | false |
https://api.github.com/repos/huggingface/datasets/issues/5379 | https://api.github.com/repos/huggingface/datasets | https://api.github.com/repos/huggingface/datasets/issues/5379/labels{/name} | https://api.github.com/repos/huggingface/datasets/issues/5379/comments | https://api.github.com/repos/huggingface/datasets/issues/5379/events | https://github.com/huggingface/datasets/pull/5379 | 1,504,010,639 | PR_kwDODunzps5F1r2k | 5,379 | feat: depth estimation dataset guide. | {
"login": "sayakpaul",
"id": 22957388,
"node_id": "MDQ6VXNlcjIyOTU3Mzg4",
"avatar_url": "https://avatars.githubusercontent.com/u/22957388?v=4",
"gravatar_id": "",
"url": "https://api.github.com/users/sayakpaul",
"html_url": "https://github.com/sayakpaul",
"followers_url": "https://api.github.com/users/... | [] | closed | false | [
{
"login": "sayakpaul",
"id": 22957388,
"node_id": "MDQ6VXNlcjIyOTU3Mzg4",
"avatar_url": "https://avatars.githubusercontent.com/u/22957388?v=4",
"gravatar_id": "",
"url": "https://api.github.com/users/sayakpaul",
"html_url": "https://github.com/sayakpaul",
"followers_url": "https://a... | null | 8 | 2022-12-20T05:32:11 | 2023-01-13T12:30:31 | 2023-01-13T12:23:34 | {
"login": "sayakpaul",
"id": 22957388,
"node_id": "MDQ6VXNlcjIyOTU3Mzg4",
"avatar_url": "https://avatars.githubusercontent.com/u/22957388?v=4",
"gravatar_id": "",
"url": "https://api.github.com/users/sayakpaul",
"html_url": "https://github.com/sayakpaul",
"followers_url": "https://api.github.com/users/... | MEMBER | [] | null | null | false | {
"url": "https://api.github.com/repos/huggingface/datasets/pulls/5379",
"html_url": "https://github.com/huggingface/datasets/pull/5379",
"diff_url": "https://github.com/huggingface/datasets/pull/5379.diff",
"patch_url": "https://github.com/huggingface/datasets/pull/5379.patch",
"merged_at": "2023-01-13T12:23... | This PR adds a guide for prepping datasets for depth estimation.
PR to add documentation images is up here: https://huggingface.co/datasets/huggingface/documentation-images/discussions/22 | {
"login": "sayakpaul",
"id": 22957388,
"node_id": "MDQ6VXNlcjIyOTU3Mzg4",
"avatar_url": "https://avatars.githubusercontent.com/u/22957388?v=4",
"gravatar_id": "",
"url": "https://api.github.com/users/sayakpaul",
"html_url": "https://github.com/sayakpaul",
"followers_url": "https://api.github.com/users/... | {
"url": "https://api.github.com/repos/huggingface/datasets/issues/5379/reactions",
"total_count": 1,
"+1": 0,
"-1": 0,
"laugh": 0,
"hooray": 1,
"confused": 0,
"heart": 0,
"rocket": 0,
"eyes": 0
} | https://api.github.com/repos/huggingface/datasets/issues/5379/timeline | null | null | null | null | null | true |
https://api.github.com/repos/huggingface/datasets/issues/5378 | https://api.github.com/repos/huggingface/datasets | https://api.github.com/repos/huggingface/datasets/issues/5378/labels{/name} | https://api.github.com/repos/huggingface/datasets/issues/5378/comments | https://api.github.com/repos/huggingface/datasets/issues/5378/events | https://github.com/huggingface/datasets/issues/5378 | 1,503,887,508 | I_kwDODunzps5Zo4CU | 5,378 | The dataset "the_pile", subset "enron_emails" , load_dataset() failure | {
"login": "shaoyuta",
"id": 52023469,
"node_id": "MDQ6VXNlcjUyMDIzNDY5",
"avatar_url": "https://avatars.githubusercontent.com/u/52023469?v=4",
"gravatar_id": "",
"url": "https://api.github.com/users/shaoyuta",
"html_url": "https://github.com/shaoyuta",
"followers_url": "https://api.github.com/users/sha... | [] | closed | false | [] | null | 1 | 2022-12-20T02:19:13 | 2022-12-20T07:52:54 | 2022-12-20T07:52:54 | null | NONE | [] | null | null | null | null | ### Describe the bug
When run
"datasets.load_dataset("the_pile","enron_emails")" failure

### Steps to reproduce the bug
Run below code in python cli:
>>> import datasets
>>> datasets.load_dataset(... | {
"login": "albertvillanova",
"id": 8515462,
"node_id": "MDQ6VXNlcjg1MTU0NjI=",
"avatar_url": "https://avatars.githubusercontent.com/u/8515462?v=4",
"gravatar_id": "",
"url": "https://api.github.com/users/albertvillanova",
"html_url": "https://github.com/albertvillanova",
"followers_url": "https://api.g... | {
"url": "https://api.github.com/repos/huggingface/datasets/issues/5378/reactions",
"total_count": 0,
"+1": 0,
"-1": 0,
"laugh": 0,
"hooray": 0,
"confused": 0,
"heart": 0,
"rocket": 0,
"eyes": 0
} | https://api.github.com/repos/huggingface/datasets/issues/5378/timeline | null | completed | {
"total": 0,
"completed": 0,
"percent_completed": 0
} | {
"blocked_by": 0,
"total_blocked_by": 0,
"blocking": 0,
"total_blocking": 0
} | null | false |
https://api.github.com/repos/huggingface/datasets/issues/5377 | https://api.github.com/repos/huggingface/datasets | https://api.github.com/repos/huggingface/datasets/issues/5377/labels{/name} | https://api.github.com/repos/huggingface/datasets/issues/5377/comments | https://api.github.com/repos/huggingface/datasets/issues/5377/events | https://github.com/huggingface/datasets/pull/5377 | 1,503,477,833 | PR_kwDODunzps5Fz5lw | 5,377 | Add a parallel implementation of to_tf_dataset() | {
"login": "Rocketknight1",
"id": 12866554,
"node_id": "MDQ6VXNlcjEyODY2NTU0",
"avatar_url": "https://avatars.githubusercontent.com/u/12866554?v=4",
"gravatar_id": "",
"url": "https://api.github.com/users/Rocketknight1",
"html_url": "https://github.com/Rocketknight1",
"followers_url": "https://api.githu... | [] | closed | false | [] | null | 32 | 2022-12-19T19:40:27 | 2023-01-25T16:28:44 | 2023-01-25T16:21:40 | null | MEMBER | [] | null | null | false | {
"url": "https://api.github.com/repos/huggingface/datasets/pulls/5377",
"html_url": "https://github.com/huggingface/datasets/pull/5377",
"diff_url": "https://github.com/huggingface/datasets/pull/5377.diff",
"patch_url": "https://github.com/huggingface/datasets/pull/5377.patch",
"merged_at": "2023-01-25T16:21... | Hey all! Here's a first draft of the PR to add a multiprocessing implementation for `to_tf_dataset()`. It worked in some quick testing for me, but obviously I need to do some much more rigorous testing/benchmarking, and add some proper library tests.
The core idea is that we do everything using `multiprocessing` and... | {
"login": "Rocketknight1",
"id": 12866554,
"node_id": "MDQ6VXNlcjEyODY2NTU0",
"avatar_url": "https://avatars.githubusercontent.com/u/12866554?v=4",
"gravatar_id": "",
"url": "https://api.github.com/users/Rocketknight1",
"html_url": "https://github.com/Rocketknight1",
"followers_url": "https://api.githu... | {
"url": "https://api.github.com/repos/huggingface/datasets/issues/5377/reactions",
"total_count": 0,
"+1": 0,
"-1": 0,
"laugh": 0,
"hooray": 0,
"confused": 0,
"heart": 0,
"rocket": 0,
"eyes": 0
} | https://api.github.com/repos/huggingface/datasets/issues/5377/timeline | null | null | null | null | null | true |
https://api.github.com/repos/huggingface/datasets/issues/5376 | https://api.github.com/repos/huggingface/datasets | https://api.github.com/repos/huggingface/datasets/issues/5376/labels{/name} | https://api.github.com/repos/huggingface/datasets/issues/5376/comments | https://api.github.com/repos/huggingface/datasets/issues/5376/events | https://github.com/huggingface/datasets/pull/5376 | 1,502,730,559 | PR_kwDODunzps5FxWkM | 5,376 | set dev version | {
"login": "lhoestq",
"id": 42851186,
"node_id": "MDQ6VXNlcjQyODUxMTg2",
"avatar_url": "https://avatars.githubusercontent.com/u/42851186?v=4",
"gravatar_id": "",
"url": "https://api.github.com/users/lhoestq",
"html_url": "https://github.com/lhoestq",
"followers_url": "https://api.github.com/users/lhoest... | [] | closed | false | [] | null | 1 | 2022-12-19T10:56:56 | 2022-12-19T11:01:55 | 2022-12-19T10:57:16 | null | MEMBER | [] | null | null | false | {
"url": "https://api.github.com/repos/huggingface/datasets/pulls/5376",
"html_url": "https://github.com/huggingface/datasets/pull/5376",
"diff_url": "https://github.com/huggingface/datasets/pull/5376.diff",
"patch_url": "https://github.com/huggingface/datasets/pull/5376.patch",
"merged_at": "2022-12-19T10:57... | null | {
"login": "lhoestq",
"id": 42851186,
"node_id": "MDQ6VXNlcjQyODUxMTg2",
"avatar_url": "https://avatars.githubusercontent.com/u/42851186?v=4",
"gravatar_id": "",
"url": "https://api.github.com/users/lhoestq",
"html_url": "https://github.com/lhoestq",
"followers_url": "https://api.github.com/users/lhoest... | {
"url": "https://api.github.com/repos/huggingface/datasets/issues/5376/reactions",
"total_count": 0,
"+1": 0,
"-1": 0,
"laugh": 0,
"hooray": 0,
"confused": 0,
"heart": 0,
"rocket": 0,
"eyes": 0
} | https://api.github.com/repos/huggingface/datasets/issues/5376/timeline | null | null | null | null | null | true |
https://api.github.com/repos/huggingface/datasets/issues/5375 | https://api.github.com/repos/huggingface/datasets | https://api.github.com/repos/huggingface/datasets/issues/5375/labels{/name} | https://api.github.com/repos/huggingface/datasets/issues/5375/comments | https://api.github.com/repos/huggingface/datasets/issues/5375/events | https://github.com/huggingface/datasets/pull/5375 | 1,502,720,404 | PR_kwDODunzps5FxUbG | 5,375 | Release: 2.8.0 | {
"login": "lhoestq",
"id": 42851186,
"node_id": "MDQ6VXNlcjQyODUxMTg2",
"avatar_url": "https://avatars.githubusercontent.com/u/42851186?v=4",
"gravatar_id": "",
"url": "https://api.github.com/users/lhoestq",
"html_url": "https://github.com/lhoestq",
"followers_url": "https://api.github.com/users/lhoest... | [] | closed | false | [] | null | 1 | 2022-12-19T10:48:26 | 2022-12-19T10:55:43 | 2022-12-19T10:53:15 | null | MEMBER | [] | null | null | false | {
"url": "https://api.github.com/repos/huggingface/datasets/pulls/5375",
"html_url": "https://github.com/huggingface/datasets/pull/5375",
"diff_url": "https://github.com/huggingface/datasets/pull/5375.diff",
"patch_url": "https://github.com/huggingface/datasets/pull/5375.patch",
"merged_at": "2022-12-19T10:53... | null | {
"login": "lhoestq",
"id": 42851186,
"node_id": "MDQ6VXNlcjQyODUxMTg2",
"avatar_url": "https://avatars.githubusercontent.com/u/42851186?v=4",
"gravatar_id": "",
"url": "https://api.github.com/users/lhoestq",
"html_url": "https://github.com/lhoestq",
"followers_url": "https://api.github.com/users/lhoest... | {
"url": "https://api.github.com/repos/huggingface/datasets/issues/5375/reactions",
"total_count": 0,
"+1": 0,
"-1": 0,
"laugh": 0,
"hooray": 0,
"confused": 0,
"heart": 0,
"rocket": 0,
"eyes": 0
} | https://api.github.com/repos/huggingface/datasets/issues/5375/timeline | null | null | null | null | null | true |
https://api.github.com/repos/huggingface/datasets/issues/5374 | https://api.github.com/repos/huggingface/datasets | https://api.github.com/repos/huggingface/datasets/issues/5374/labels{/name} | https://api.github.com/repos/huggingface/datasets/issues/5374/comments | https://api.github.com/repos/huggingface/datasets/issues/5374/events | https://github.com/huggingface/datasets/issues/5374 | 1,501,872,945 | I_kwDODunzps5ZhMMx | 5,374 | Using too many threads results in: Got disconnected from remote data host. Retrying in 5sec | {
"login": "Muennighoff",
"id": 62820084,
"node_id": "MDQ6VXNlcjYyODIwMDg0",
"avatar_url": "https://avatars.githubusercontent.com/u/62820084?v=4",
"gravatar_id": "",
"url": "https://api.github.com/users/Muennighoff",
"html_url": "https://github.com/Muennighoff",
"followers_url": "https://api.github.com/... | [] | closed | false | [] | null | 7 | 2022-12-18T11:38:58 | 2023-07-24T15:23:07 | 2023-07-24T15:23:07 | null | CONTRIBUTOR | [] | null | null | null | null | ### Describe the bug
`streaming_download_manager` seems to disconnect if too many runs access the same underlying dataset 🧐
The code works fine for me if I have ~100 runs in parallel, but disconnects once scaling to 200.
Possibly related:
- https://github.com/huggingface/datasets/pull/3100
- https://github.com/... | {
"login": "mariosasko",
"id": 47462742,
"node_id": "MDQ6VXNlcjQ3NDYyNzQy",
"avatar_url": "https://avatars.githubusercontent.com/u/47462742?v=4",
"gravatar_id": "",
"url": "https://api.github.com/users/mariosasko",
"html_url": "https://github.com/mariosasko",
"followers_url": "https://api.github.com/use... | {
"url": "https://api.github.com/repos/huggingface/datasets/issues/5374/reactions",
"total_count": 0,
"+1": 0,
"-1": 0,
"laugh": 0,
"hooray": 0,
"confused": 0,
"heart": 0,
"rocket": 0,
"eyes": 0
} | https://api.github.com/repos/huggingface/datasets/issues/5374/timeline | null | completed | {
"total": 0,
"completed": 0,
"percent_completed": 0
} | {
"blocked_by": 0,
"total_blocked_by": 0,
"blocking": 0,
"total_blocking": 0
} | null | false |
https://api.github.com/repos/huggingface/datasets/issues/5373 | https://api.github.com/repos/huggingface/datasets | https://api.github.com/repos/huggingface/datasets/issues/5373/labels{/name} | https://api.github.com/repos/huggingface/datasets/issues/5373/comments | https://api.github.com/repos/huggingface/datasets/issues/5373/events | https://github.com/huggingface/datasets/pull/5373 | 1,501,484,197 | PR_kwDODunzps5FtRU4 | 5,373 | Simplify skipping | {
"login": "Muennighoff",
"id": 62820084,
"node_id": "MDQ6VXNlcjYyODIwMDg0",
"avatar_url": "https://avatars.githubusercontent.com/u/62820084?v=4",
"gravatar_id": "",
"url": "https://api.github.com/users/Muennighoff",
"html_url": "https://github.com/Muennighoff",
"followers_url": "https://api.github.com/... | [] | closed | false | [] | null | 1 | 2022-12-17T17:23:52 | 2022-12-18T21:43:31 | 2022-12-18T21:40:21 | null | CONTRIBUTOR | [] | null | null | false | {
"url": "https://api.github.com/repos/huggingface/datasets/pulls/5373",
"html_url": "https://github.com/huggingface/datasets/pull/5373",
"diff_url": "https://github.com/huggingface/datasets/pull/5373.diff",
"patch_url": "https://github.com/huggingface/datasets/pull/5373.patch",
"merged_at": "2022-12-18T21:40... | Was hoping to find a way to speed up the skipping as I'm running into bottlenecks skipping 100M examples on C4 (it takes 12 hours to skip), but didn't find anything better than this small change :(
Maybe there's a way to directly skip whole shards to speed it up? 🧐 | {
"login": "Muennighoff",
"id": 62820084,
"node_id": "MDQ6VXNlcjYyODIwMDg0",
"avatar_url": "https://avatars.githubusercontent.com/u/62820084?v=4",
"gravatar_id": "",
"url": "https://api.github.com/users/Muennighoff",
"html_url": "https://github.com/Muennighoff",
"followers_url": "https://api.github.com/... | {
"url": "https://api.github.com/repos/huggingface/datasets/issues/5373/reactions",
"total_count": 0,
"+1": 0,
"-1": 0,
"laugh": 0,
"hooray": 0,
"confused": 0,
"heart": 0,
"rocket": 0,
"eyes": 0
} | https://api.github.com/repos/huggingface/datasets/issues/5373/timeline | null | null | null | null | null | true |
https://api.github.com/repos/huggingface/datasets/issues/5372 | https://api.github.com/repos/huggingface/datasets | https://api.github.com/repos/huggingface/datasets/issues/5372/labels{/name} | https://api.github.com/repos/huggingface/datasets/issues/5372/comments | https://api.github.com/repos/huggingface/datasets/issues/5372/events | https://github.com/huggingface/datasets/pull/5372 | 1,501,377,802 | PR_kwDODunzps5Fs9w5 | 5,372 | Fix streaming pandas.read_excel | {
"login": "albertvillanova",
"id": 8515462,
"node_id": "MDQ6VXNlcjg1MTU0NjI=",
"avatar_url": "https://avatars.githubusercontent.com/u/8515462?v=4",
"gravatar_id": "",
"url": "https://api.github.com/users/albertvillanova",
"html_url": "https://github.com/albertvillanova",
"followers_url": "https://api.g... | [] | closed | false | [] | null | 2 | 2022-12-17T12:58:52 | 2023-01-06T11:50:58 | 2023-01-06T11:43:37 | null | MEMBER | [] | null | null | false | {
"url": "https://api.github.com/repos/huggingface/datasets/pulls/5372",
"html_url": "https://github.com/huggingface/datasets/pull/5372",
"diff_url": "https://github.com/huggingface/datasets/pull/5372.diff",
"patch_url": "https://github.com/huggingface/datasets/pull/5372.patch",
"merged_at": "2023-01-06T11:43... | This PR fixes `xpandas_read_excel`:
- Support passing a path string, besides a file-like object
- Support passing `use_auth_token`
- First assumes the host server supports HTTP range requests; only if a ValueError is thrown (Cannot seek streaming HTTP file), then it preserves previous behavior (see [#3355](https://g... | {
"login": "albertvillanova",
"id": 8515462,
"node_id": "MDQ6VXNlcjg1MTU0NjI=",
"avatar_url": "https://avatars.githubusercontent.com/u/8515462?v=4",
"gravatar_id": "",
"url": "https://api.github.com/users/albertvillanova",
"html_url": "https://github.com/albertvillanova",
"followers_url": "https://api.g... | {
"url": "https://api.github.com/repos/huggingface/datasets/issues/5372/reactions",
"total_count": 0,
"+1": 0,
"-1": 0,
"laugh": 0,
"hooray": 0,
"confused": 0,
"heart": 0,
"rocket": 0,
"eyes": 0
} | https://api.github.com/repos/huggingface/datasets/issues/5372/timeline | null | null | null | null | null | true |
https://api.github.com/repos/huggingface/datasets/issues/5371 | https://api.github.com/repos/huggingface/datasets | https://api.github.com/repos/huggingface/datasets/issues/5371/labels{/name} | https://api.github.com/repos/huggingface/datasets/issues/5371/comments | https://api.github.com/repos/huggingface/datasets/issues/5371/events | https://github.com/huggingface/datasets/issues/5371 | 1,501,369,036 | I_kwDODunzps5ZfRLM | 5,371 | Add a robustness benchmark dataset for vision | {
"login": "sayakpaul",
"id": 22957388,
"node_id": "MDQ6VXNlcjIyOTU3Mzg4",
"avatar_url": "https://avatars.githubusercontent.com/u/22957388?v=4",
"gravatar_id": "",
"url": "https://api.github.com/users/sayakpaul",
"html_url": "https://github.com/sayakpaul",
"followers_url": "https://api.github.com/users/... | [
{
"id": 2067376369,
"node_id": "MDU6TGFiZWwyMDY3Mzc2MzY5",
"url": "https://api.github.com/repos/huggingface/datasets/labels/dataset%20request",
"name": "dataset request",
"color": "e99695",
"default": false,
"description": "Requesting to add a new dataset",
"archived_at": null,
"... | open | false | [
{
"login": "sayakpaul",
"id": 22957388,
"node_id": "MDQ6VXNlcjIyOTU3Mzg4",
"avatar_url": "https://avatars.githubusercontent.com/u/22957388?v=4",
"gravatar_id": "",
"url": "https://api.github.com/users/sayakpaul",
"html_url": "https://github.com/sayakpaul",
"followers_url": "https://a... | null | 1 | 2022-12-17T12:35:13 | 2022-12-20T06:21:41 | null | {
"login": "sayakpaul",
"id": 22957388,
"node_id": "MDQ6VXNlcjIyOTU3Mzg4",
"avatar_url": "https://avatars.githubusercontent.com/u/22957388?v=4",
"gravatar_id": "",
"url": "https://api.github.com/users/sayakpaul",
"html_url": "https://github.com/sayakpaul",
"followers_url": "https://api.github.com/users/... | MEMBER | [] | null | null | null | null | ### Name
ImageNet-C
### Paper
Benchmarking Neural Network Robustness to Common Corruptions and Perturbations
### Data
https://github.com/hendrycks/robustness
### Motivation
It's a known fact that vision models are brittle when they meet with slightly corrupted and perturbed data. This is also corre... | null | {
"url": "https://api.github.com/repos/huggingface/datasets/issues/5371/reactions",
"total_count": 2,
"+1": 0,
"-1": 0,
"laugh": 0,
"hooray": 0,
"confused": 0,
"heart": 0,
"rocket": 2,
"eyes": 0
} | https://api.github.com/repos/huggingface/datasets/issues/5371/timeline | null | null | {
"total": 0,
"completed": 0,
"percent_completed": 0
} | {
"blocked_by": 0,
"total_blocked_by": 0,
"blocking": 0,
"total_blocking": 0
} | null | false |
https://api.github.com/repos/huggingface/datasets/issues/5369 | https://api.github.com/repos/huggingface/datasets | https://api.github.com/repos/huggingface/datasets/issues/5369/labels{/name} | https://api.github.com/repos/huggingface/datasets/issues/5369/comments | https://api.github.com/repos/huggingface/datasets/issues/5369/events | https://github.com/huggingface/datasets/pull/5369 | 1,500,622,276 | PR_kwDODunzps5Fqaj- | 5,369 | Distributed support | {
"login": "lhoestq",
"id": 42851186,
"node_id": "MDQ6VXNlcjQyODUxMTg2",
"avatar_url": "https://avatars.githubusercontent.com/u/42851186?v=4",
"gravatar_id": "",
"url": "https://api.github.com/users/lhoestq",
"html_url": "https://github.com/lhoestq",
"followers_url": "https://api.github.com/users/lhoest... | [] | closed | false | [] | null | 11 | 2022-12-16T17:43:47 | 2023-07-25T12:00:31 | 2023-01-16T13:33:32 | null | MEMBER | [] | null | null | false | {
"url": "https://api.github.com/repos/huggingface/datasets/pulls/5369",
"html_url": "https://github.com/huggingface/datasets/pull/5369",
"diff_url": "https://github.com/huggingface/datasets/pull/5369.diff",
"patch_url": "https://github.com/huggingface/datasets/pull/5369.patch",
"merged_at": "2023-01-16T13:33... | To split your dataset across your training nodes, you can use the new [`datasets.distributed.split_dataset_by_node`]:
```python
import os
from datasets.distributed import split_dataset_by_node
ds = split_dataset_by_node(ds, rank=int(os.environ["RANK"]), world_size=int(os.environ["WORLD_SIZE"]))
```
This wor... | {
"login": "lhoestq",
"id": 42851186,
"node_id": "MDQ6VXNlcjQyODUxMTg2",
"avatar_url": "https://avatars.githubusercontent.com/u/42851186?v=4",
"gravatar_id": "",
"url": "https://api.github.com/users/lhoestq",
"html_url": "https://github.com/lhoestq",
"followers_url": "https://api.github.com/users/lhoest... | {
"url": "https://api.github.com/repos/huggingface/datasets/issues/5369/reactions",
"total_count": 0,
"+1": 0,
"-1": 0,
"laugh": 0,
"hooray": 0,
"confused": 0,
"heart": 0,
"rocket": 0,
"eyes": 0
} | https://api.github.com/repos/huggingface/datasets/issues/5369/timeline | null | null | null | null | null | true |
https://api.github.com/repos/huggingface/datasets/issues/5368 | https://api.github.com/repos/huggingface/datasets | https://api.github.com/repos/huggingface/datasets/issues/5368/labels{/name} | https://api.github.com/repos/huggingface/datasets/issues/5368/comments | https://api.github.com/repos/huggingface/datasets/issues/5368/events | https://github.com/huggingface/datasets/pull/5368 | 1,500,322,973 | PR_kwDODunzps5FpZyx | 5,368 | Align remove columns behavior and input dict mutation in `map` with previous behavior | {
"login": "mariosasko",
"id": 47462742,
"node_id": "MDQ6VXNlcjQ3NDYyNzQy",
"avatar_url": "https://avatars.githubusercontent.com/u/47462742?v=4",
"gravatar_id": "",
"url": "https://api.github.com/users/mariosasko",
"html_url": "https://github.com/mariosasko",
"followers_url": "https://api.github.com/use... | [] | closed | false | [] | null | 1 | 2022-12-16T14:28:47 | 2022-12-16T16:28:08 | 2022-12-16T16:25:12 | null | COLLABORATOR | [] | null | null | false | {
"url": "https://api.github.com/repos/huggingface/datasets/pulls/5368",
"html_url": "https://github.com/huggingface/datasets/pull/5368",
"diff_url": "https://github.com/huggingface/datasets/pull/5368.diff",
"patch_url": "https://github.com/huggingface/datasets/pull/5368.patch",
"merged_at": "2022-12-16T16:25... | Align the `remove_columns` behavior and input dict mutation in `map` with the behavior before https://github.com/huggingface/datasets/pull/5252. | {
"login": "mariosasko",
"id": 47462742,
"node_id": "MDQ6VXNlcjQ3NDYyNzQy",
"avatar_url": "https://avatars.githubusercontent.com/u/47462742?v=4",
"gravatar_id": "",
"url": "https://api.github.com/users/mariosasko",
"html_url": "https://github.com/mariosasko",
"followers_url": "https://api.github.com/use... | {
"url": "https://api.github.com/repos/huggingface/datasets/issues/5368/reactions",
"total_count": 0,
"+1": 0,
"-1": 0,
"laugh": 0,
"hooray": 0,
"confused": 0,
"heart": 0,
"rocket": 0,
"eyes": 0
} | https://api.github.com/repos/huggingface/datasets/issues/5368/timeline | null | null | null | null | null | true |
https://api.github.com/repos/huggingface/datasets/issues/5367 | https://api.github.com/repos/huggingface/datasets | https://api.github.com/repos/huggingface/datasets/issues/5367/labels{/name} | https://api.github.com/repos/huggingface/datasets/issues/5367/comments | https://api.github.com/repos/huggingface/datasets/issues/5367/events | https://github.com/huggingface/datasets/pull/5367 | 1,499,174,749 | PR_kwDODunzps5FlevK | 5,367 | Fix remove columns from lazy dict | {
"login": "lhoestq",
"id": 42851186,
"node_id": "MDQ6VXNlcjQyODUxMTg2",
"avatar_url": "https://avatars.githubusercontent.com/u/42851186?v=4",
"gravatar_id": "",
"url": "https://api.github.com/users/lhoestq",
"html_url": "https://github.com/lhoestq",
"followers_url": "https://api.github.com/users/lhoest... | [] | closed | false | [] | null | 1 | 2022-12-15T22:04:12 | 2022-12-15T22:27:53 | 2022-12-15T22:24:50 | null | MEMBER | [] | null | null | false | {
"url": "https://api.github.com/repos/huggingface/datasets/pulls/5367",
"html_url": "https://github.com/huggingface/datasets/pull/5367",
"diff_url": "https://github.com/huggingface/datasets/pull/5367.diff",
"patch_url": "https://github.com/huggingface/datasets/pull/5367.patch",
"merged_at": "2022-12-15T22:24... | This was introduced in https://github.com/huggingface/datasets/pull/5252 and causing the transformers CI to break: https://app.circleci.com/pipelines/github/huggingface/transformers/53886/workflows/522faf2e-a053-454c-94f8-a617fde33393/jobs/648597
Basically this code should return a dataset with only one column:
`... | {
"login": "lhoestq",
"id": 42851186,
"node_id": "MDQ6VXNlcjQyODUxMTg2",
"avatar_url": "https://avatars.githubusercontent.com/u/42851186?v=4",
"gravatar_id": "",
"url": "https://api.github.com/users/lhoestq",
"html_url": "https://github.com/lhoestq",
"followers_url": "https://api.github.com/users/lhoest... | {
"url": "https://api.github.com/repos/huggingface/datasets/issues/5367/reactions",
"total_count": 0,
"+1": 0,
"-1": 0,
"laugh": 0,
"hooray": 0,
"confused": 0,
"heart": 0,
"rocket": 0,
"eyes": 0
} | https://api.github.com/repos/huggingface/datasets/issues/5367/timeline | null | null | null | null | null | true |
https://api.github.com/repos/huggingface/datasets/issues/5366 | https://api.github.com/repos/huggingface/datasets | https://api.github.com/repos/huggingface/datasets/issues/5366/labels{/name} | https://api.github.com/repos/huggingface/datasets/issues/5366/comments | https://api.github.com/repos/huggingface/datasets/issues/5366/events | https://github.com/huggingface/datasets/pull/5366 | 1,498,530,851 | PR_kwDODunzps5FjSFl | 5,366 | ExamplesIterable fixes | {
"login": "lhoestq",
"id": 42851186,
"node_id": "MDQ6VXNlcjQyODUxMTg2",
"avatar_url": "https://avatars.githubusercontent.com/u/42851186?v=4",
"gravatar_id": "",
"url": "https://api.github.com/users/lhoestq",
"html_url": "https://github.com/lhoestq",
"followers_url": "https://api.github.com/users/lhoest... | [] | closed | false | [] | null | 1 | 2022-12-15T14:23:05 | 2022-12-15T14:44:47 | 2022-12-15T14:41:45 | null | MEMBER | [] | null | null | false | {
"url": "https://api.github.com/repos/huggingface/datasets/pulls/5366",
"html_url": "https://github.com/huggingface/datasets/pull/5366",
"diff_url": "https://github.com/huggingface/datasets/pull/5366.diff",
"patch_url": "https://github.com/huggingface/datasets/pull/5366.patch",
"merged_at": "2022-12-15T14:41... | fix typing and ExamplesIterable.shard_data_sources | {
"login": "lhoestq",
"id": 42851186,
"node_id": "MDQ6VXNlcjQyODUxMTg2",
"avatar_url": "https://avatars.githubusercontent.com/u/42851186?v=4",
"gravatar_id": "",
"url": "https://api.github.com/users/lhoestq",
"html_url": "https://github.com/lhoestq",
"followers_url": "https://api.github.com/users/lhoest... | {
"url": "https://api.github.com/repos/huggingface/datasets/issues/5366/reactions",
"total_count": 0,
"+1": 0,
"-1": 0,
"laugh": 0,
"hooray": 0,
"confused": 0,
"heart": 0,
"rocket": 0,
"eyes": 0
} | https://api.github.com/repos/huggingface/datasets/issues/5366/timeline | null | null | null | null | null | true |
https://api.github.com/repos/huggingface/datasets/issues/5365 | https://api.github.com/repos/huggingface/datasets | https://api.github.com/repos/huggingface/datasets/issues/5365/labels{/name} | https://api.github.com/repos/huggingface/datasets/issues/5365/comments | https://api.github.com/repos/huggingface/datasets/issues/5365/events | https://github.com/huggingface/datasets/pull/5365 | 1,498,422,466 | PR_kwDODunzps5Fi6ZD | 5,365 | fix: image array should support other formats than uint8 | {
"login": "vigsterkr",
"id": 30353,
"node_id": "MDQ6VXNlcjMwMzUz",
"avatar_url": "https://avatars.githubusercontent.com/u/30353?v=4",
"gravatar_id": "",
"url": "https://api.github.com/users/vigsterkr",
"html_url": "https://github.com/vigsterkr",
"followers_url": "https://api.github.com/users/vigsterkr/... | [] | closed | false | [] | null | 4 | 2022-12-15T13:17:50 | 2023-01-26T18:46:45 | 2023-01-26T18:39:36 | null | CONTRIBUTOR | [] | null | null | false | {
"url": "https://api.github.com/repos/huggingface/datasets/pulls/5365",
"html_url": "https://github.com/huggingface/datasets/pull/5365",
"diff_url": "https://github.com/huggingface/datasets/pull/5365.diff",
"patch_url": "https://github.com/huggingface/datasets/pull/5365.patch",
"merged_at": "2023-01-26T18:39... | Currently images that are provided as ndarrays, but not in `uint8` format are going to loose data. Namely, for example in a depth image where the data is in float32 format, the type-casting to uint8 will basically make the whole image blank.
`PIL.Image.fromarray` [does support mode `F`](https://pillow.readthedocs.io/e... | {
"login": "lhoestq",
"id": 42851186,
"node_id": "MDQ6VXNlcjQyODUxMTg2",
"avatar_url": "https://avatars.githubusercontent.com/u/42851186?v=4",
"gravatar_id": "",
"url": "https://api.github.com/users/lhoestq",
"html_url": "https://github.com/lhoestq",
"followers_url": "https://api.github.com/users/lhoest... | {
"url": "https://api.github.com/repos/huggingface/datasets/issues/5365/reactions",
"total_count": 0,
"+1": 0,
"-1": 0,
"laugh": 0,
"hooray": 0,
"confused": 0,
"heart": 0,
"rocket": 0,
"eyes": 0
} | https://api.github.com/repos/huggingface/datasets/issues/5365/timeline | null | null | null | null | null | true |
https://api.github.com/repos/huggingface/datasets/issues/5364 | https://api.github.com/repos/huggingface/datasets | https://api.github.com/repos/huggingface/datasets/issues/5364/labels{/name} | https://api.github.com/repos/huggingface/datasets/issues/5364/comments | https://api.github.com/repos/huggingface/datasets/issues/5364/events | https://github.com/huggingface/datasets/pull/5364 | 1,498,360,628 | PR_kwDODunzps5Fiss1 | 5,364 | Support for writing arrow files directly with BeamWriter | {
"login": "mariosasko",
"id": 47462742,
"node_id": "MDQ6VXNlcjQ3NDYyNzQy",
"avatar_url": "https://avatars.githubusercontent.com/u/47462742?v=4",
"gravatar_id": "",
"url": "https://api.github.com/users/mariosasko",
"html_url": "https://github.com/mariosasko",
"followers_url": "https://api.github.com/use... | [] | closed | false | [] | null | 6 | 2022-12-15T12:38:05 | 2024-01-11T14:52:33 | 2024-01-11T14:45:15 | null | COLLABORATOR | [] | null | null | true | {
"url": "https://api.github.com/repos/huggingface/datasets/pulls/5364",
"html_url": "https://github.com/huggingface/datasets/pull/5364",
"diff_url": "https://github.com/huggingface/datasets/pull/5364.diff",
"patch_url": "https://github.com/huggingface/datasets/pull/5364.patch",
"merged_at": null
} | Make it possible to write Arrow files directly with `BeamWriter` rather than converting from Parquet to Arrow, which is sub-optimal, especially for big datasets for which Beam is primarily used. | {
"login": "lhoestq",
"id": 42851186,
"node_id": "MDQ6VXNlcjQyODUxMTg2",
"avatar_url": "https://avatars.githubusercontent.com/u/42851186?v=4",
"gravatar_id": "",
"url": "https://api.github.com/users/lhoestq",
"html_url": "https://github.com/lhoestq",
"followers_url": "https://api.github.com/users/lhoest... | {
"url": "https://api.github.com/repos/huggingface/datasets/issues/5364/reactions",
"total_count": 0,
"+1": 0,
"-1": 0,
"laugh": 0,
"hooray": 0,
"confused": 0,
"heart": 0,
"rocket": 0,
"eyes": 0
} | https://api.github.com/repos/huggingface/datasets/issues/5364/timeline | null | null | null | null | null | true |
https://api.github.com/repos/huggingface/datasets/issues/5363 | https://api.github.com/repos/huggingface/datasets | https://api.github.com/repos/huggingface/datasets/issues/5363/labels{/name} | https://api.github.com/repos/huggingface/datasets/issues/5363/comments | https://api.github.com/repos/huggingface/datasets/issues/5363/events | https://github.com/huggingface/datasets/issues/5363 | 1,498,171,317 | I_kwDODunzps5ZTEe1 | 5,363 | Dataset.from_generator() crashes on simple example | {
"login": "villmow",
"id": 2743060,
"node_id": "MDQ6VXNlcjI3NDMwNjA=",
"avatar_url": "https://avatars.githubusercontent.com/u/2743060?v=4",
"gravatar_id": "",
"url": "https://api.github.com/users/villmow",
"html_url": "https://github.com/villmow",
"followers_url": "https://api.github.com/users/villmow/... | [] | closed | false | [] | null | 0 | 2022-12-15T10:21:28 | 2022-12-15T11:51:33 | 2022-12-15T11:51:33 | null | NONE | [] | null | null | null | null | null | {
"login": "villmow",
"id": 2743060,
"node_id": "MDQ6VXNlcjI3NDMwNjA=",
"avatar_url": "https://avatars.githubusercontent.com/u/2743060?v=4",
"gravatar_id": "",
"url": "https://api.github.com/users/villmow",
"html_url": "https://github.com/villmow",
"followers_url": "https://api.github.com/users/villmow/... | {
"url": "https://api.github.com/repos/huggingface/datasets/issues/5363/reactions",
"total_count": 0,
"+1": 0,
"-1": 0,
"laugh": 0,
"hooray": 0,
"confused": 0,
"heart": 0,
"rocket": 0,
"eyes": 0
} | https://api.github.com/repos/huggingface/datasets/issues/5363/timeline | null | completed | {
"total": 0,
"completed": 0,
"percent_completed": 0
} | {
"blocked_by": 0,
"total_blocked_by": 0,
"blocking": 0,
"total_blocking": 0
} | null | false |
https://api.github.com/repos/huggingface/datasets/issues/5362 | https://api.github.com/repos/huggingface/datasets | https://api.github.com/repos/huggingface/datasets/issues/5362/labels{/name} | https://api.github.com/repos/huggingface/datasets/issues/5362/comments | https://api.github.com/repos/huggingface/datasets/issues/5362/events | https://github.com/huggingface/datasets/issues/5362 | 1,497,643,744 | I_kwDODunzps5ZRDrg | 5,362 | Run 'GPT-J' failure due to download dataset fail (' ConnectionError: Couldn't reach http://eaidata.bmk.sh/data/enron_emails.jsonl.zst ' ) | {
"login": "shaoyuta",
"id": 52023469,
"node_id": "MDQ6VXNlcjUyMDIzNDY5",
"avatar_url": "https://avatars.githubusercontent.com/u/52023469?v=4",
"gravatar_id": "",
"url": "https://api.github.com/users/shaoyuta",
"html_url": "https://github.com/shaoyuta",
"followers_url": "https://api.github.com/users/sha... | [] | closed | false | [
{
"login": "albertvillanova",
"id": 8515462,
"node_id": "MDQ6VXNlcjg1MTU0NjI=",
"avatar_url": "https://avatars.githubusercontent.com/u/8515462?v=4",
"gravatar_id": "",
"url": "https://api.github.com/users/albertvillanova",
"html_url": "https://github.com/albertvillanova",
"followers_... | null | 2 | 2022-12-15T01:23:03 | 2022-12-15T07:45:54 | 2022-12-15T07:45:53 | {
"login": "albertvillanova",
"id": 8515462,
"node_id": "MDQ6VXNlcjg1MTU0NjI=",
"avatar_url": "https://avatars.githubusercontent.com/u/8515462?v=4",
"gravatar_id": "",
"url": "https://api.github.com/users/albertvillanova",
"html_url": "https://github.com/albertvillanova",
"followers_url": "https://api.g... | NONE | [] | null | null | null | null | ### Describe the bug
Run model "GPT-J" with dataset "the_pile" fail.
The fail out is as below:
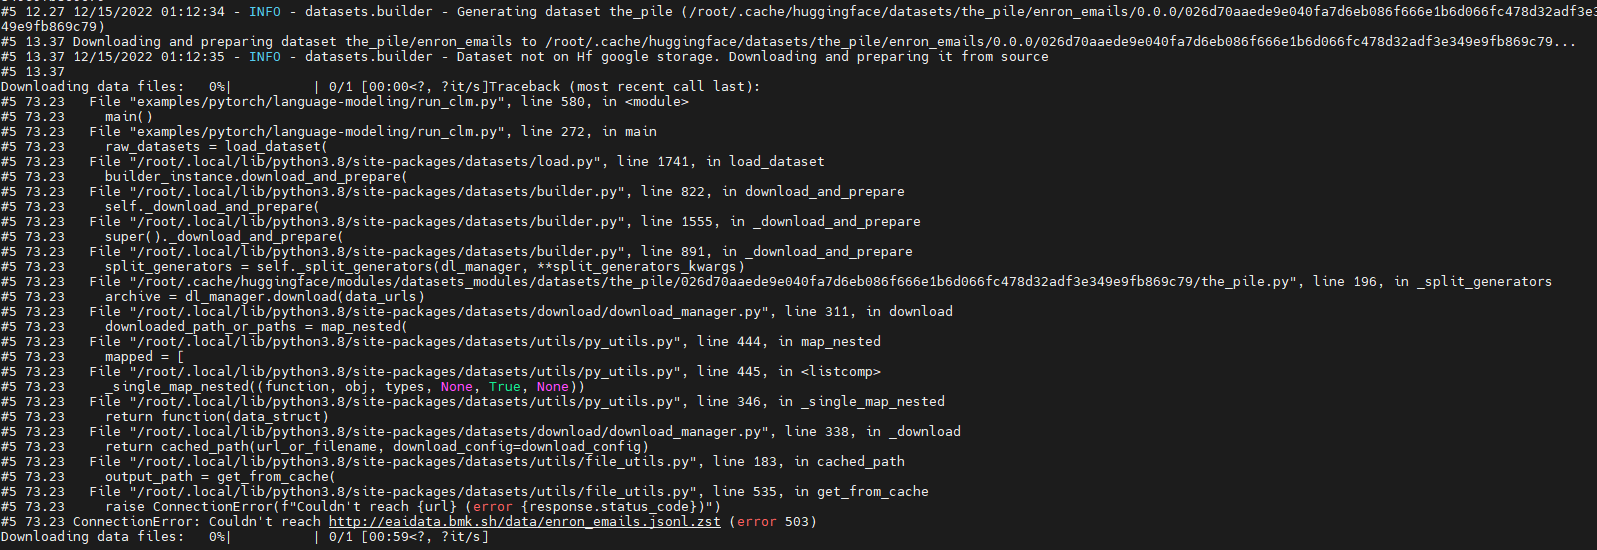
Looks like which is due to "http://eaidata.bmk.sh/data/enron_emails.jsonl.zst" unreachable .
### Steps to ... | {
"login": "albertvillanova",
"id": 8515462,
"node_id": "MDQ6VXNlcjg1MTU0NjI=",
"avatar_url": "https://avatars.githubusercontent.com/u/8515462?v=4",
"gravatar_id": "",
"url": "https://api.github.com/users/albertvillanova",
"html_url": "https://github.com/albertvillanova",
"followers_url": "https://api.g... | {
"url": "https://api.github.com/repos/huggingface/datasets/issues/5362/reactions",
"total_count": 0,
"+1": 0,
"-1": 0,
"laugh": 0,
"hooray": 0,
"confused": 0,
"heart": 0,
"rocket": 0,
"eyes": 0
} | https://api.github.com/repos/huggingface/datasets/issues/5362/timeline | null | completed | {
"total": 0,
"completed": 0,
"percent_completed": 0
} | {
"blocked_by": 0,
"total_blocked_by": 0,
"blocking": 0,
"total_blocking": 0
} | null | false |
https://api.github.com/repos/huggingface/datasets/issues/5361 | https://api.github.com/repos/huggingface/datasets | https://api.github.com/repos/huggingface/datasets/issues/5361/labels{/name} | https://api.github.com/repos/huggingface/datasets/issues/5361/comments | https://api.github.com/repos/huggingface/datasets/issues/5361/events | https://github.com/huggingface/datasets/issues/5361 | 1,497,153,889 | I_kwDODunzps5ZPMFh | 5,361 | How concatenate `Audio` elements using batch mapping | {
"login": "bayartsogt-ya",
"id": 43239645,
"node_id": "MDQ6VXNlcjQzMjM5NjQ1",
"avatar_url": "https://avatars.githubusercontent.com/u/43239645?v=4",
"gravatar_id": "",
"url": "https://api.github.com/users/bayartsogt-ya",
"html_url": "https://github.com/bayartsogt-ya",
"followers_url": "https://api.githu... | [] | closed | false | [] | null | 3 | 2022-12-14T18:13:55 | 2023-07-21T14:30:51 | 2023-07-21T14:30:51 | null | NONE | [] | null | null | null | null | ### Describe the bug
I am trying to do concatenate audios in a dataset e.g. `google/fleurs`.
```python
print(dataset)
# Dataset({
# features: ['path', 'audio'],
# num_rows: 24
# })
def mapper_function(batch):
# to merge every 3 audio
# np.concatnate(audios[i: i+3]) for i in range(i, len(batc... | {
"login": "mariosasko",
"id": 47462742,
"node_id": "MDQ6VXNlcjQ3NDYyNzQy",
"avatar_url": "https://avatars.githubusercontent.com/u/47462742?v=4",
"gravatar_id": "",
"url": "https://api.github.com/users/mariosasko",
"html_url": "https://github.com/mariosasko",
"followers_url": "https://api.github.com/use... | {
"url": "https://api.github.com/repos/huggingface/datasets/issues/5361/reactions",
"total_count": 0,
"+1": 0,
"-1": 0,
"laugh": 0,
"hooray": 0,
"confused": 0,
"heart": 0,
"rocket": 0,
"eyes": 0
} | https://api.github.com/repos/huggingface/datasets/issues/5361/timeline | null | completed | {
"total": 0,
"completed": 0,
"percent_completed": 0
} | {
"blocked_by": 0,
"total_blocked_by": 0,
"blocking": 0,
"total_blocking": 0
} | null | false |
https://api.github.com/repos/huggingface/datasets/issues/5360 | https://api.github.com/repos/huggingface/datasets | https://api.github.com/repos/huggingface/datasets/issues/5360/labels{/name} | https://api.github.com/repos/huggingface/datasets/issues/5360/comments | https://api.github.com/repos/huggingface/datasets/issues/5360/events | https://github.com/huggingface/datasets/issues/5360 | 1,496,947,177 | I_kwDODunzps5ZOZnp | 5,360 | IterableDataset returns duplicated data using PyTorch DDP | {
"login": "lhoestq",
"id": 42851186,
"node_id": "MDQ6VXNlcjQyODUxMTg2",
"avatar_url": "https://avatars.githubusercontent.com/u/42851186?v=4",
"gravatar_id": "",
"url": "https://api.github.com/users/lhoestq",
"html_url": "https://github.com/lhoestq",
"followers_url": "https://api.github.com/users/lhoest... | [] | closed | false | [
{
"login": "lhoestq",
"id": 42851186,
"node_id": "MDQ6VXNlcjQyODUxMTg2",
"avatar_url": "https://avatars.githubusercontent.com/u/42851186?v=4",
"gravatar_id": "",
"url": "https://api.github.com/users/lhoestq",
"html_url": "https://github.com/lhoestq",
"followers_url": "https://api.git... | null | 11 | 2022-12-14T16:06:19 | 2023-06-15T09:51:13 | 2023-01-16T13:33:33 | {
"login": "lhoestq",
"id": 42851186,
"node_id": "MDQ6VXNlcjQyODUxMTg2",
"avatar_url": "https://avatars.githubusercontent.com/u/42851186?v=4",
"gravatar_id": "",
"url": "https://api.github.com/users/lhoestq",
"html_url": "https://github.com/lhoestq",
"followers_url": "https://api.github.com/users/lhoest... | MEMBER | [] | null | null | null | null | As mentioned in https://github.com/huggingface/datasets/issues/3423, when using PyTorch DDP the dataset ends up with duplicated data. We already check for the PyTorch `worker_info` for single node, but we should also check for `torch.distributed.get_world_size()` and `torch.distributed.get_rank()` | {
"login": "lhoestq",
"id": 42851186,
"node_id": "MDQ6VXNlcjQyODUxMTg2",
"avatar_url": "https://avatars.githubusercontent.com/u/42851186?v=4",
"gravatar_id": "",
"url": "https://api.github.com/users/lhoestq",
"html_url": "https://github.com/lhoestq",
"followers_url": "https://api.github.com/users/lhoest... | {
"url": "https://api.github.com/repos/huggingface/datasets/issues/5360/reactions",
"total_count": 0,
"+1": 0,
"-1": 0,
"laugh": 0,
"hooray": 0,
"confused": 0,
"heart": 0,
"rocket": 0,
"eyes": 0
} | https://api.github.com/repos/huggingface/datasets/issues/5360/timeline | null | completed | {
"total": 0,
"completed": 0,
"percent_completed": 0
} | {
"blocked_by": 0,
"total_blocked_by": 0,
"blocking": 0,
"total_blocking": 0
} | null | false |
https://api.github.com/repos/huggingface/datasets/issues/5359 | https://api.github.com/repos/huggingface/datasets | https://api.github.com/repos/huggingface/datasets/issues/5359/labels{/name} | https://api.github.com/repos/huggingface/datasets/issues/5359/comments | https://api.github.com/repos/huggingface/datasets/issues/5359/events | https://github.com/huggingface/datasets/pull/5359 | 1,495,297,857 | PR_kwDODunzps5FYHWm | 5,359 | Raise error if ClassLabel names is not python list | {
"login": "freddyheppell",
"id": 1475568,
"node_id": "MDQ6VXNlcjE0NzU1Njg=",
"avatar_url": "https://avatars.githubusercontent.com/u/1475568?v=4",
"gravatar_id": "",
"url": "https://api.github.com/users/freddyheppell",
"html_url": "https://github.com/freddyheppell",
"followers_url": "https://api.github.... | [] | closed | false | [] | null | 3 | 2022-12-13T23:04:06 | 2022-12-22T16:35:49 | 2022-12-22T16:32:49 | null | CONTRIBUTOR | [] | null | null | false | {
"url": "https://api.github.com/repos/huggingface/datasets/pulls/5359",
"html_url": "https://github.com/huggingface/datasets/pull/5359",
"diff_url": "https://github.com/huggingface/datasets/pull/5359.diff",
"patch_url": "https://github.com/huggingface/datasets/pull/5359.patch",
"merged_at": "2022-12-22T16:32... | Checks type of names provided to ClassLabel to avoid easy and hard to debug errors (closes #5332 - see for discussion) | {
"login": "mariosasko",
"id": 47462742,
"node_id": "MDQ6VXNlcjQ3NDYyNzQy",
"avatar_url": "https://avatars.githubusercontent.com/u/47462742?v=4",
"gravatar_id": "",
"url": "https://api.github.com/users/mariosasko",
"html_url": "https://github.com/mariosasko",
"followers_url": "https://api.github.com/use... | {
"url": "https://api.github.com/repos/huggingface/datasets/issues/5359/reactions",
"total_count": 0,
"+1": 0,
"-1": 0,
"laugh": 0,
"hooray": 0,
"confused": 0,
"heart": 0,
"rocket": 0,
"eyes": 0
} | https://api.github.com/repos/huggingface/datasets/issues/5359/timeline | null | null | null | null | null | true |
https://api.github.com/repos/huggingface/datasets/issues/5358 | https://api.github.com/repos/huggingface/datasets | https://api.github.com/repos/huggingface/datasets/issues/5358/labels{/name} | https://api.github.com/repos/huggingface/datasets/issues/5358/comments | https://api.github.com/repos/huggingface/datasets/issues/5358/events | https://github.com/huggingface/datasets/pull/5358 | 1,495,270,822 | PR_kwDODunzps5FYBcq | 5,358 | Fix `fs.open` resource leaks | {
"login": "tkukurin",
"id": 297847,
"node_id": "MDQ6VXNlcjI5Nzg0Nw==",
"avatar_url": "https://avatars.githubusercontent.com/u/297847?v=4",
"gravatar_id": "",
"url": "https://api.github.com/users/tkukurin",
"html_url": "https://github.com/tkukurin",
"followers_url": "https://api.github.com/users/tkukuri... | [] | closed | false | [] | null | 3 | 2022-12-13T22:35:51 | 2023-01-05T16:46:31 | 2023-01-05T15:59:51 | null | CONTRIBUTOR | [] | null | null | false | {
"url": "https://api.github.com/repos/huggingface/datasets/pulls/5358",
"html_url": "https://github.com/huggingface/datasets/pull/5358",
"diff_url": "https://github.com/huggingface/datasets/pull/5358.diff",
"patch_url": "https://github.com/huggingface/datasets/pull/5358.patch",
"merged_at": "2023-01-05T15:59... | Invoking `{load,save}_from_dict` results in resource leak warnings, this should fix.
Introduces no significant logic changes. | {
"login": "lhoestq",
"id": 42851186,
"node_id": "MDQ6VXNlcjQyODUxMTg2",
"avatar_url": "https://avatars.githubusercontent.com/u/42851186?v=4",
"gravatar_id": "",
"url": "https://api.github.com/users/lhoestq",
"html_url": "https://github.com/lhoestq",
"followers_url": "https://api.github.com/users/lhoest... | {
"url": "https://api.github.com/repos/huggingface/datasets/issues/5358/reactions",
"total_count": 0,
"+1": 0,
"-1": 0,
"laugh": 0,
"hooray": 0,
"confused": 0,
"heart": 0,
"rocket": 0,
"eyes": 0
} | https://api.github.com/repos/huggingface/datasets/issues/5358/timeline | null | null | null | null | null | true |
https://api.github.com/repos/huggingface/datasets/issues/5357 | https://api.github.com/repos/huggingface/datasets | https://api.github.com/repos/huggingface/datasets/issues/5357/labels{/name} | https://api.github.com/repos/huggingface/datasets/issues/5357/comments | https://api.github.com/repos/huggingface/datasets/issues/5357/events | https://github.com/huggingface/datasets/pull/5357 | 1,495,029,602 | PR_kwDODunzps5FXNyR | 5,357 | Support torch dataloader without torch formatting | {
"login": "lhoestq",
"id": 42851186,
"node_id": "MDQ6VXNlcjQyODUxMTg2",
"avatar_url": "https://avatars.githubusercontent.com/u/42851186?v=4",
"gravatar_id": "",
"url": "https://api.github.com/users/lhoestq",
"html_url": "https://github.com/lhoestq",
"followers_url": "https://api.github.com/users/lhoest... | [] | closed | false | [] | null | 7 | 2022-12-13T19:39:24 | 2023-01-04T12:45:40 | 2022-12-15T19:15:54 | null | MEMBER | [] | null | null | false | {
"url": "https://api.github.com/repos/huggingface/datasets/pulls/5357",
"html_url": "https://github.com/huggingface/datasets/pull/5357",
"diff_url": "https://github.com/huggingface/datasets/pull/5357.diff",
"patch_url": "https://github.com/huggingface/datasets/pull/5357.patch",
"merged_at": "2022-12-15T19:15... | In https://github.com/huggingface/datasets/pull/5084 we make the torch formatting consistent with the map-style datasets formatting: a torch formatted iterable dataset will yield torch tensors.
The previous behavior of the torch formatting for iterable dataset was simply to make the iterable dataset inherit from `to... | {
"login": "lhoestq",
"id": 42851186,
"node_id": "MDQ6VXNlcjQyODUxMTg2",
"avatar_url": "https://avatars.githubusercontent.com/u/42851186?v=4",
"gravatar_id": "",
"url": "https://api.github.com/users/lhoestq",
"html_url": "https://github.com/lhoestq",
"followers_url": "https://api.github.com/users/lhoest... | {
"url": "https://api.github.com/repos/huggingface/datasets/issues/5357/reactions",
"total_count": 0,
"+1": 0,
"-1": 0,
"laugh": 0,
"hooray": 0,
"confused": 0,
"heart": 0,
"rocket": 0,
"eyes": 0
} | https://api.github.com/repos/huggingface/datasets/issues/5357/timeline | null | null | null | null | null | true |
https://api.github.com/repos/huggingface/datasets/issues/5356 | https://api.github.com/repos/huggingface/datasets | https://api.github.com/repos/huggingface/datasets/issues/5356/labels{/name} | https://api.github.com/repos/huggingface/datasets/issues/5356/comments | https://api.github.com/repos/huggingface/datasets/issues/5356/events | https://github.com/huggingface/datasets/pull/5356 | 1,494,961,609 | PR_kwDODunzps5FW-c9 | 5,356 | Clean filesystem and logging docstrings | {
"login": "stevhliu",
"id": 59462357,
"node_id": "MDQ6VXNlcjU5NDYyMzU3",
"avatar_url": "https://avatars.githubusercontent.com/u/59462357?v=4",
"gravatar_id": "",
"url": "https://api.github.com/users/stevhliu",
"html_url": "https://github.com/stevhliu",
"followers_url": "https://api.github.com/users/ste... | [] | closed | false | [] | null | 1 | 2022-12-13T18:54:09 | 2022-12-14T17:25:58 | 2022-12-14T17:22:16 | null | MEMBER | [] | null | null | false | {
"url": "https://api.github.com/repos/huggingface/datasets/pulls/5356",
"html_url": "https://github.com/huggingface/datasets/pull/5356",
"diff_url": "https://github.com/huggingface/datasets/pull/5356.diff",
"patch_url": "https://github.com/huggingface/datasets/pull/5356.patch",
"merged_at": "2022-12-14T17:22... | This PR cleans the `Filesystems` and `Logging` docstrings. | {
"login": "stevhliu",
"id": 59462357,
"node_id": "MDQ6VXNlcjU5NDYyMzU3",
"avatar_url": "https://avatars.githubusercontent.com/u/59462357?v=4",
"gravatar_id": "",
"url": "https://api.github.com/users/stevhliu",
"html_url": "https://github.com/stevhliu",
"followers_url": "https://api.github.com/users/ste... | {
"url": "https://api.github.com/repos/huggingface/datasets/issues/5356/reactions",
"total_count": 0,
"+1": 0,
"-1": 0,
"laugh": 0,
"hooray": 0,
"confused": 0,
"heart": 0,
"rocket": 0,
"eyes": 0
} | https://api.github.com/repos/huggingface/datasets/issues/5356/timeline | null | null | null | null | null | true |
https://api.github.com/repos/huggingface/datasets/issues/5355 | https://api.github.com/repos/huggingface/datasets | https://api.github.com/repos/huggingface/datasets/issues/5355/labels{/name} | https://api.github.com/repos/huggingface/datasets/issues/5355/comments | https://api.github.com/repos/huggingface/datasets/issues/5355/events | https://github.com/huggingface/datasets/pull/5355 | 1,493,076,860 | PR_kwDODunzps5FQcYG | 5,355 | Clean up Table class docstrings | {
"login": "stevhliu",
"id": 59462357,
"node_id": "MDQ6VXNlcjU5NDYyMzU3",
"avatar_url": "https://avatars.githubusercontent.com/u/59462357?v=4",
"gravatar_id": "",
"url": "https://api.github.com/users/stevhliu",
"html_url": "https://github.com/stevhliu",
"followers_url": "https://api.github.com/users/ste... | [] | closed | false | [] | null | 1 | 2022-12-13T00:29:47 | 2022-12-13T18:17:56 | 2022-12-13T18:14:42 | null | MEMBER | [] | null | null | false | {
"url": "https://api.github.com/repos/huggingface/datasets/pulls/5355",
"html_url": "https://github.com/huggingface/datasets/pull/5355",
"diff_url": "https://github.com/huggingface/datasets/pull/5355.diff",
"patch_url": "https://github.com/huggingface/datasets/pull/5355.patch",
"merged_at": "2022-12-13T18:14... | This PR cleans up the `Table` class docstrings :) | {
"login": "stevhliu",
"id": 59462357,
"node_id": "MDQ6VXNlcjU5NDYyMzU3",
"avatar_url": "https://avatars.githubusercontent.com/u/59462357?v=4",
"gravatar_id": "",
"url": "https://api.github.com/users/stevhliu",
"html_url": "https://github.com/stevhliu",
"followers_url": "https://api.github.com/users/ste... | {
"url": "https://api.github.com/repos/huggingface/datasets/issues/5355/reactions",
"total_count": 0,
"+1": 0,
"-1": 0,
"laugh": 0,
"hooray": 0,
"confused": 0,
"heart": 0,
"rocket": 0,
"eyes": 0
} | https://api.github.com/repos/huggingface/datasets/issues/5355/timeline | null | null | null | null | null | true |
https://api.github.com/repos/huggingface/datasets/issues/5354 | https://api.github.com/repos/huggingface/datasets | https://api.github.com/repos/huggingface/datasets/issues/5354/labels{/name} | https://api.github.com/repos/huggingface/datasets/issues/5354/comments | https://api.github.com/repos/huggingface/datasets/issues/5354/events | https://github.com/huggingface/datasets/issues/5354 | 1,492,174,125 | I_kwDODunzps5Y8MUt | 5,354 | Consider using "Sequence" instead of "List" | {
"login": "tranhd95",
"id": 15568078,
"node_id": "MDQ6VXNlcjE1NTY4MDc4",
"avatar_url": "https://avatars.githubusercontent.com/u/15568078?v=4",
"gravatar_id": "",
"url": "https://api.github.com/users/tranhd95",
"html_url": "https://github.com/tranhd95",
"followers_url": "https://api.github.com/users/tra... | [
{
"id": 1935892871,
"node_id": "MDU6TGFiZWwxOTM1ODkyODcx",
"url": "https://api.github.com/repos/huggingface/datasets/labels/enhancement",
"name": "enhancement",
"color": "a2eeef",
"default": true,
"description": "New feature or request",
"archived_at": null,
"archived_by": null
... | open | false | [
{
"login": "avinashsai",
"id": 22453634,
"node_id": "MDQ6VXNlcjIyNDUzNjM0",
"avatar_url": "https://avatars.githubusercontent.com/u/22453634?v=4",
"gravatar_id": "",
"url": "https://api.github.com/users/avinashsai",
"html_url": "https://github.com/avinashsai",
"followers_url": "https:... | null | 19 | 2022-12-12T15:39:45 | 2026-09-02T03:48:02 | null | {
"login": "avinashsai",
"id": 22453634,
"node_id": "MDQ6VXNlcjIyNDUzNjM0",
"avatar_url": "https://avatars.githubusercontent.com/u/22453634?v=4",
"gravatar_id": "",
"url": "https://api.github.com/users/avinashsai",
"html_url": "https://github.com/avinashsai",
"followers_url": "https://api.github.com/use... | NONE | [] | null | null | null | null | ### Feature request
Hi, please consider using `Sequence` type annotation instead of `List` in function arguments such as in [`Dataset.from_parquet()`](https://github.com/huggingface/datasets/blob/main/src/datasets/arrow_dataset.py#L1088). It leads to type checking errors, see below.
**How to reproduce**
```py
... | null | {
"url": "https://api.github.com/repos/huggingface/datasets/issues/5354/reactions",
"total_count": 0,
"+1": 0,
"-1": 0,
"laugh": 0,
"hooray": 0,
"confused": 0,
"heart": 0,
"rocket": 0,
"eyes": 0
} | https://api.github.com/repos/huggingface/datasets/issues/5354/timeline | null | null | {
"total": 0,
"completed": 0,
"percent_completed": 0
} | {
"blocked_by": 0,
"total_blocked_by": 0,
"blocking": 0,
"total_blocking": 0
} | null | false |
https://api.github.com/repos/huggingface/datasets/issues/5353 | https://api.github.com/repos/huggingface/datasets | https://api.github.com/repos/huggingface/datasets/issues/5353/labels{/name} | https://api.github.com/repos/huggingface/datasets/issues/5353/comments | https://api.github.com/repos/huggingface/datasets/issues/5353/events | https://github.com/huggingface/datasets/issues/5353 | 1,491,880,500 | I_kwDODunzps5Y7Eo0 | 5,353 | Support remote file systems for `Audio` | {
"login": "OllieBroadhurst",
"id": 46894149,
"node_id": "MDQ6VXNlcjQ2ODk0MTQ5",
"avatar_url": "https://avatars.githubusercontent.com/u/46894149?v=4",
"gravatar_id": "",
"url": "https://api.github.com/users/OllieBroadhurst",
"html_url": "https://github.com/OllieBroadhurst",
"followers_url": "https://api... | [
{
"id": 1935892871,
"node_id": "MDU6TGFiZWwxOTM1ODkyODcx",
"url": "https://api.github.com/repos/huggingface/datasets/labels/enhancement",
"name": "enhancement",
"color": "a2eeef",
"default": true,
"description": "New feature or request",
"archived_at": null,
"archived_by": null
... | closed | false | [] | null | 1 | 2022-12-12T13:22:13 | 2022-12-12T13:37:14 | 2022-12-12T13:37:14 | null | NONE | [] | null | null | null | null | ### Feature request
Hi there!
It would be super cool if `Audio()`, and potentially other features, could read files from a remote file system.
### Motivation
Large amounts of data is often stored in buckets. `load_from_disk` is able to retrieve data from cloud storage but to my knowledge actually copies the datas... | {
"login": "OllieBroadhurst",
"id": 46894149,
"node_id": "MDQ6VXNlcjQ2ODk0MTQ5",
"avatar_url": "https://avatars.githubusercontent.com/u/46894149?v=4",
"gravatar_id": "",
"url": "https://api.github.com/users/OllieBroadhurst",
"html_url": "https://github.com/OllieBroadhurst",
"followers_url": "https://api... | {
"url": "https://api.github.com/repos/huggingface/datasets/issues/5353/reactions",
"total_count": 0,
"+1": 0,
"-1": 0,
"laugh": 0,
"hooray": 0,
"confused": 0,
"heart": 0,
"rocket": 0,
"eyes": 0
} | https://api.github.com/repos/huggingface/datasets/issues/5353/timeline | null | completed | {
"total": 0,
"completed": 0,
"percent_completed": 0
} | {
"blocked_by": 0,
"total_blocked_by": 0,
"blocking": 0,
"total_blocking": 0
} | null | false |
https://api.github.com/repos/huggingface/datasets/issues/5352 | https://api.github.com/repos/huggingface/datasets | https://api.github.com/repos/huggingface/datasets/issues/5352/labels{/name} | https://api.github.com/repos/huggingface/datasets/issues/5352/comments | https://api.github.com/repos/huggingface/datasets/issues/5352/events | https://github.com/huggingface/datasets/issues/5352 | 1,490,796,414 | I_kwDODunzps5Y279- | 5,352 | __init__() got an unexpected keyword argument 'input_size' | {
"login": "J-shel",
"id": 82662111,
"node_id": "MDQ6VXNlcjgyNjYyMTEx",
"avatar_url": "https://avatars.githubusercontent.com/u/82662111?v=4",
"gravatar_id": "",
"url": "https://api.github.com/users/J-shel",
"html_url": "https://github.com/J-shel",
"followers_url": "https://api.github.com/users/J-shel/fo... | [] | open | false | [] | null | 2 | 2022-12-12T02:52:03 | 2022-12-19T01:38:48 | null | null | NONE | [] | null | null | null | null | ### Describe the bug
I try to define a custom configuration with a input_size attribute following the instructions by "Specifying several dataset configurations" in https://huggingface.co/docs/datasets/v1.2.1/add_dataset.html
But when I load the dataset, I got an error "__init__() got an unexpected keyword argument... | null | {
"url": "https://api.github.com/repos/huggingface/datasets/issues/5352/reactions",
"total_count": 0,
"+1": 0,
"-1": 0,
"laugh": 0,
"hooray": 0,
"confused": 0,
"heart": 0,
"rocket": 0,
"eyes": 0
} | https://api.github.com/repos/huggingface/datasets/issues/5352/timeline | null | null | {
"total": 0,
"completed": 0,
"percent_completed": 0
} | {
"blocked_by": 0,
"total_blocked_by": 0,
"blocking": 0,
"total_blocking": 0
} | null | false |
https://api.github.com/repos/huggingface/datasets/issues/5351 | https://api.github.com/repos/huggingface/datasets | https://api.github.com/repos/huggingface/datasets/issues/5351/labels{/name} | https://api.github.com/repos/huggingface/datasets/issues/5351/comments | https://api.github.com/repos/huggingface/datasets/issues/5351/events | https://github.com/huggingface/datasets/issues/5351 | 1,490,659,504 | I_kwDODunzps5Y2aiw | 5,351 | Do we need to implement `_prepare_split`? | {
"login": "jmwoloso",
"id": 7530947,
"node_id": "MDQ6VXNlcjc1MzA5NDc=",
"avatar_url": "https://avatars.githubusercontent.com/u/7530947?v=4",
"gravatar_id": "",
"url": "https://api.github.com/users/jmwoloso",
"html_url": "https://github.com/jmwoloso",
"followers_url": "https://api.github.com/users/jmwol... | [] | closed | false | [] | null | 11 | 2022-12-12T01:38:54 | 2022-12-20T18:20:57 | 2022-12-12T16:48:56 | null | NONE | [] | null | null | null | null | ### Describe the bug
I'm not sure this is a bug or if it's just missing in the documentation, or i'm not doing something correctly, but I'm subclassing `DatasetBuilder` and getting the following error because on the `DatasetBuilder` class the `_prepare_split` method is abstract (as are the others we are required to im... | {
"login": "jmwoloso",
"id": 7530947,
"node_id": "MDQ6VXNlcjc1MzA5NDc=",
"avatar_url": "https://avatars.githubusercontent.com/u/7530947?v=4",
"gravatar_id": "",
"url": "https://api.github.com/users/jmwoloso",
"html_url": "https://github.com/jmwoloso",
"followers_url": "https://api.github.com/users/jmwol... | {
"url": "https://api.github.com/repos/huggingface/datasets/issues/5351/reactions",
"total_count": 0,
"+1": 0,
"-1": 0,
"laugh": 0,
"hooray": 0,
"confused": 0,
"heart": 0,
"rocket": 0,
"eyes": 0
} | https://api.github.com/repos/huggingface/datasets/issues/5351/timeline | null | completed | {
"total": 0,
"completed": 0,
"percent_completed": 0
} | {
"blocked_by": 0,
"total_blocked_by": 0,
"blocking": 0,
"total_blocking": 0
} | null | false |
https://api.github.com/repos/huggingface/datasets/issues/5350 | https://api.github.com/repos/huggingface/datasets | https://api.github.com/repos/huggingface/datasets/issues/5350/labels{/name} | https://api.github.com/repos/huggingface/datasets/issues/5350/comments | https://api.github.com/repos/huggingface/datasets/issues/5350/events | https://github.com/huggingface/datasets/pull/5350 | 1,487,559,904 | PR_kwDODunzps5E8y2E | 5,350 | Clean up Loading methods docstrings | {
"login": "stevhliu",
"id": 59462357,
"node_id": "MDQ6VXNlcjU5NDYyMzU3",
"avatar_url": "https://avatars.githubusercontent.com/u/59462357?v=4",
"gravatar_id": "",
"url": "https://api.github.com/users/stevhliu",
"html_url": "https://github.com/stevhliu",
"followers_url": "https://api.github.com/users/ste... | [] | closed | false | [] | null | 1 | 2022-12-09T22:25:30 | 2022-12-12T17:27:20 | 2022-12-12T17:24:01 | null | MEMBER | [] | null | null | false | {
"url": "https://api.github.com/repos/huggingface/datasets/pulls/5350",
"html_url": "https://github.com/huggingface/datasets/pull/5350",
"diff_url": "https://github.com/huggingface/datasets/pull/5350.diff",
"patch_url": "https://github.com/huggingface/datasets/pull/5350.patch",
"merged_at": "2022-12-12T17:24... | Clean up for the docstrings in Loading methods! | {
"login": "stevhliu",
"id": 59462357,
"node_id": "MDQ6VXNlcjU5NDYyMzU3",
"avatar_url": "https://avatars.githubusercontent.com/u/59462357?v=4",
"gravatar_id": "",
"url": "https://api.github.com/users/stevhliu",
"html_url": "https://github.com/stevhliu",
"followers_url": "https://api.github.com/users/ste... | {
"url": "https://api.github.com/repos/huggingface/datasets/issues/5350/reactions",
"total_count": 0,
"+1": 0,
"-1": 0,
"laugh": 0,
"hooray": 0,
"confused": 0,
"heart": 0,
"rocket": 0,
"eyes": 0
} | https://api.github.com/repos/huggingface/datasets/issues/5350/timeline | null | null | null | null | null | true |
https://api.github.com/repos/huggingface/datasets/issues/5349 | https://api.github.com/repos/huggingface/datasets | https://api.github.com/repos/huggingface/datasets/issues/5349/labels{/name} | https://api.github.com/repos/huggingface/datasets/issues/5349/comments | https://api.github.com/repos/huggingface/datasets/issues/5349/events | https://github.com/huggingface/datasets/pull/5349 | 1,487,396,780 | PR_kwDODunzps5E8N6G | 5,349 | Clean up remaining Main Classes docstrings | {
"login": "stevhliu",
"id": 59462357,
"node_id": "MDQ6VXNlcjU5NDYyMzU3",
"avatar_url": "https://avatars.githubusercontent.com/u/59462357?v=4",
"gravatar_id": "",
"url": "https://api.github.com/users/stevhliu",
"html_url": "https://github.com/stevhliu",
"followers_url": "https://api.github.com/users/ste... | [] | closed | false | [] | null | 1 | 2022-12-09T20:17:15 | 2022-12-12T17:27:17 | 2022-12-12T17:24:13 | null | MEMBER | [] | null | null | false | {
"url": "https://api.github.com/repos/huggingface/datasets/pulls/5349",
"html_url": "https://github.com/huggingface/datasets/pull/5349",
"diff_url": "https://github.com/huggingface/datasets/pull/5349.diff",
"patch_url": "https://github.com/huggingface/datasets/pull/5349.patch",
"merged_at": "2022-12-12T17:24... | This PR cleans up the remaining docstrings in Main Classes (`IterableDataset`, `IterableDatasetDict`, and `Features`). | {
"login": "stevhliu",
"id": 59462357,
"node_id": "MDQ6VXNlcjU5NDYyMzU3",
"avatar_url": "https://avatars.githubusercontent.com/u/59462357?v=4",
"gravatar_id": "",
"url": "https://api.github.com/users/stevhliu",
"html_url": "https://github.com/stevhliu",
"followers_url": "https://api.github.com/users/ste... | {
"url": "https://api.github.com/repos/huggingface/datasets/issues/5349/reactions",
"total_count": 0,
"+1": 0,
"-1": 0,
"laugh": 0,
"hooray": 0,
"confused": 0,
"heart": 0,
"rocket": 0,
"eyes": 0
} | https://api.github.com/repos/huggingface/datasets/issues/5349/timeline | null | null | null | null | null | true |
https://api.github.com/repos/huggingface/datasets/issues/5348 | https://api.github.com/repos/huggingface/datasets | https://api.github.com/repos/huggingface/datasets/issues/5348/labels{/name} | https://api.github.com/repos/huggingface/datasets/issues/5348/comments | https://api.github.com/repos/huggingface/datasets/issues/5348/events | https://github.com/huggingface/datasets/issues/5348 | 1,486,975,626 | I_kwDODunzps5YoXKK | 5,348 | The data downloaded in the download folder of the cache does not respect `umask` | {
"login": "SaulLu",
"id": 55560583,
"node_id": "MDQ6VXNlcjU1NTYwNTgz",
"avatar_url": "https://avatars.githubusercontent.com/u/55560583?v=4",
"gravatar_id": "",
"url": "https://api.github.com/users/SaulLu",
"html_url": "https://github.com/SaulLu",
"followers_url": "https://api.github.com/users/SaulLu/fo... | [] | open | false | [] | null | 1 | 2022-12-09T15:46:27 | 2022-12-09T17:21:26 | null | null | CONTRIBUTOR | [] | null | null | null | null | ### Describe the bug
For a project on a cluster we are several users to share the same cache for the datasets library. And we have a problem with the permissions on the data downloaded in the cache.
Indeed, it seems that the data is downloaded by giving read and write permissions only to the user launching the com... | null | {
"url": "https://api.github.com/repos/huggingface/datasets/issues/5348/reactions",
"total_count": 1,
"+1": 0,
"-1": 0,
"laugh": 0,
"hooray": 0,
"confused": 0,
"heart": 1,
"rocket": 0,
"eyes": 0
} | https://api.github.com/repos/huggingface/datasets/issues/5348/timeline | null | null | {
"total": 0,
"completed": 0,
"percent_completed": 0
} | {
"blocked_by": 0,
"total_blocked_by": 0,
"blocking": 0,
"total_blocking": 0
} | null | false |
https://api.github.com/repos/huggingface/datasets/issues/5347 | https://api.github.com/repos/huggingface/datasets | https://api.github.com/repos/huggingface/datasets/issues/5347/labels{/name} | https://api.github.com/repos/huggingface/datasets/issues/5347/comments | https://api.github.com/repos/huggingface/datasets/issues/5347/events | https://github.com/huggingface/datasets/pull/5347 | 1,486,920,261 | PR_kwDODunzps5E6jb1 | 5,347 | Force soundfile to return float32 instead of the default float64 | {
"login": "qmeeus",
"id": 25608944,
"node_id": "MDQ6VXNlcjI1NjA4OTQ0",
"avatar_url": "https://avatars.githubusercontent.com/u/25608944?v=4",
"gravatar_id": "",
"url": "https://api.github.com/users/qmeeus",
"html_url": "https://github.com/qmeeus",
"followers_url": "https://api.github.com/users/qmeeus/fo... | [] | open | false | [] | null | 8 | 2022-12-09T15:10:24 | 2023-01-17T16:12:49 | null | null | NONE | [] | null | null | false | {
"url": "https://api.github.com/repos/huggingface/datasets/pulls/5347",
"html_url": "https://github.com/huggingface/datasets/pull/5347",
"diff_url": "https://github.com/huggingface/datasets/pull/5347.diff",
"patch_url": "https://github.com/huggingface/datasets/pull/5347.patch",
"merged_at": null
} | (Fixes issue #5345) | null | {
"url": "https://api.github.com/repos/huggingface/datasets/issues/5347/reactions",
"total_count": 1,
"+1": 1,
"-1": 0,
"laugh": 0,
"hooray": 0,
"confused": 0,
"heart": 0,
"rocket": 0,
"eyes": 0
} | https://api.github.com/repos/huggingface/datasets/issues/5347/timeline | null | null | null | null | null | true |
https://api.github.com/repos/huggingface/datasets/issues/5346 | https://api.github.com/repos/huggingface/datasets | https://api.github.com/repos/huggingface/datasets/issues/5346/labels{/name} | https://api.github.com/repos/huggingface/datasets/issues/5346/comments | https://api.github.com/repos/huggingface/datasets/issues/5346/events | https://github.com/huggingface/datasets/issues/5346 | 1,486,884,983 | I_kwDODunzps5YoBB3 | 5,346 | [Quick poll] Give your opinion on the future of the Hugging Face Open Source ecosystem! | {
"login": "LysandreJik",
"id": 30755778,
"node_id": "MDQ6VXNlcjMwNzU1Nzc4",
"avatar_url": "https://avatars.githubusercontent.com/u/30755778?v=4",
"gravatar_id": "",
"url": "https://api.github.com/users/LysandreJik",
"html_url": "https://github.com/LysandreJik",
"followers_url": "https://api.github.com/... | [] | closed | false | [] | null | 3 | 2022-12-09T14:48:02 | 2023-06-02T20:24:44 | 2023-01-25T19:35:40 | null | MEMBER | [] | null | null | null | null | Thanks to all of you, Datasets is just about to pass 15k stars!
Since the last survey, a lot has happened: the [diffusers](https://github.com/huggingface/diffusers), [evaluate](https://github.com/huggingface/evaluate) and [skops](https://github.com/skops-dev/skops) libraries were born. `timm` joined the Hugging Face... | {
"login": "LysandreJik",
"id": 30755778,
"node_id": "MDQ6VXNlcjMwNzU1Nzc4",
"avatar_url": "https://avatars.githubusercontent.com/u/30755778?v=4",
"gravatar_id": "",
"url": "https://api.github.com/users/LysandreJik",
"html_url": "https://github.com/LysandreJik",
"followers_url": "https://api.github.com/... | {
"url": "https://api.github.com/repos/huggingface/datasets/issues/5346/reactions",
"total_count": 3,
"+1": 0,
"-1": 0,
"laugh": 0,
"hooray": 0,
"confused": 0,
"heart": 0,
"rocket": 3,
"eyes": 0
} | https://api.github.com/repos/huggingface/datasets/issues/5346/timeline | null | completed | {
"total": 0,
"completed": 0,
"percent_completed": 0
} | {
"blocked_by": 0,
"total_blocked_by": 0,
"blocking": 0,
"total_blocking": 0
} | null | false |
https://api.github.com/repos/huggingface/datasets/issues/5345 | https://api.github.com/repos/huggingface/datasets | https://api.github.com/repos/huggingface/datasets/issues/5345/labels{/name} | https://api.github.com/repos/huggingface/datasets/issues/5345/comments | https://api.github.com/repos/huggingface/datasets/issues/5345/events | https://github.com/huggingface/datasets/issues/5345 | 1,486,555,384 | I_kwDODunzps5Ymwj4 | 5,345 | Wrong dtype for array in audio features | {
"login": "qmeeus",
"id": 25608944,
"node_id": "MDQ6VXNlcjI1NjA4OTQ0",
"avatar_url": "https://avatars.githubusercontent.com/u/25608944?v=4",
"gravatar_id": "",
"url": "https://api.github.com/users/qmeeus",
"html_url": "https://github.com/qmeeus",
"followers_url": "https://api.github.com/users/qmeeus/fo... | [] | open | false | [] | null | 3 | 2022-12-09T11:05:11 | 2023-02-10T14:39:28 | null | null | NONE | [] | null | null | null | null | ### Describe the bug
When concatenating/interleaving different datasets, I stumble into an error because the features can't be aligned. After some investigation, I understood that the audio arrays had different dtypes, namely `float32` and `float64`. Consequently, the datasets cannot be merged.
### Steps to repro... | null | {
"url": "https://api.github.com/repos/huggingface/datasets/issues/5345/reactions",
"total_count": 0,
"+1": 0,
"-1": 0,
"laugh": 0,
"hooray": 0,
"confused": 0,
"heart": 0,
"rocket": 0,
"eyes": 0
} | https://api.github.com/repos/huggingface/datasets/issues/5345/timeline | null | null | {
"total": 0,
"completed": 0,
"percent_completed": 0
} | {
"blocked_by": 0,
"total_blocked_by": 0,
"blocking": 0,
"total_blocking": 0
} | null | false |
https://api.github.com/repos/huggingface/datasets/issues/5344 | https://api.github.com/repos/huggingface/datasets | https://api.github.com/repos/huggingface/datasets/issues/5344/labels{/name} | https://api.github.com/repos/huggingface/datasets/issues/5344/comments | https://api.github.com/repos/huggingface/datasets/issues/5344/events | https://github.com/huggingface/datasets/pull/5344 | 1,485,628,319 | PR_kwDODunzps5E2BPN | 5,344 | Clean up Dataset and DatasetDict | {
"login": "stevhliu",
"id": 59462357,
"node_id": "MDQ6VXNlcjU5NDYyMzU3",
"avatar_url": "https://avatars.githubusercontent.com/u/59462357?v=4",
"gravatar_id": "",
"url": "https://api.github.com/users/stevhliu",
"html_url": "https://github.com/stevhliu",
"followers_url": "https://api.github.com/users/ste... | [] | closed | false | [] | null | 1 | 2022-12-09T00:02:08 | 2022-12-13T00:56:07 | 2022-12-13T00:53:02 | null | MEMBER | [] | null | null | false | {
"url": "https://api.github.com/repos/huggingface/datasets/pulls/5344",
"html_url": "https://github.com/huggingface/datasets/pull/5344",
"diff_url": "https://github.com/huggingface/datasets/pull/5344.diff",
"patch_url": "https://github.com/huggingface/datasets/pull/5344.patch",
"merged_at": "2022-12-13T00:53... | This PR cleans up the docstrings for the other half of the methods in `Dataset` and finishes `DatasetDict`. | {
"login": "stevhliu",
"id": 59462357,
"node_id": "MDQ6VXNlcjU5NDYyMzU3",
"avatar_url": "https://avatars.githubusercontent.com/u/59462357?v=4",
"gravatar_id": "",
"url": "https://api.github.com/users/stevhliu",
"html_url": "https://github.com/stevhliu",
"followers_url": "https://api.github.com/users/ste... | {
"url": "https://api.github.com/repos/huggingface/datasets/issues/5344/reactions",
"total_count": 1,
"+1": 0,
"-1": 0,
"laugh": 0,
"hooray": 0,
"confused": 0,
"heart": 1,
"rocket": 0,
"eyes": 0
} | https://api.github.com/repos/huggingface/datasets/issues/5344/timeline | null | null | null | null | null | true |
https://api.github.com/repos/huggingface/datasets/issues/5343 | https://api.github.com/repos/huggingface/datasets | https://api.github.com/repos/huggingface/datasets/issues/5343/labels{/name} | https://api.github.com/repos/huggingface/datasets/issues/5343/comments | https://api.github.com/repos/huggingface/datasets/issues/5343/events | https://github.com/huggingface/datasets/issues/5343 | 1,485,297,823 | I_kwDODunzps5Yh9if | 5,343 | T5 for Q&A produces truncated sentence | {
"login": "junyongyou",
"id": 13484072,
"node_id": "MDQ6VXNlcjEzNDg0MDcy",
"avatar_url": "https://avatars.githubusercontent.com/u/13484072?v=4",
"gravatar_id": "",
"url": "https://api.github.com/users/junyongyou",
"html_url": "https://github.com/junyongyou",
"followers_url": "https://api.github.com/use... | [] | closed | false | [] | null | 0 | 2022-12-08T19:48:46 | 2022-12-08T19:57:17 | 2022-12-08T19:57:17 | null | NONE | [] | null | null | null | null | Dear all, I am fine-tuning T5 for Q&A task using the MedQuAD ([GitHub - abachaa/MedQuAD: Medical Question Answering Dataset of 47,457 QA pairs created from 12 NIH websites](https://github.com/abachaa/MedQuAD)) dataset. In the dataset, there are many long answers with thousands of words. I have used pytorch_lightning to... | {
"login": "junyongyou",
"id": 13484072,
"node_id": "MDQ6VXNlcjEzNDg0MDcy",
"avatar_url": "https://avatars.githubusercontent.com/u/13484072?v=4",
"gravatar_id": "",
"url": "https://api.github.com/users/junyongyou",
"html_url": "https://github.com/junyongyou",
"followers_url": "https://api.github.com/use... | {
"url": "https://api.github.com/repos/huggingface/datasets/issues/5343/reactions",
"total_count": 0,
"+1": 0,
"-1": 0,
"laugh": 0,
"hooray": 0,
"confused": 0,
"heart": 0,
"rocket": 0,
"eyes": 0
} | https://api.github.com/repos/huggingface/datasets/issues/5343/timeline | null | completed | {
"total": 0,
"completed": 0,
"percent_completed": 0
} | {
"blocked_by": 0,
"total_blocked_by": 0,
"blocking": 0,
"total_blocking": 0
} | null | false |
https://api.github.com/repos/huggingface/datasets/issues/5342 | https://api.github.com/repos/huggingface/datasets | https://api.github.com/repos/huggingface/datasets/issues/5342/labels{/name} | https://api.github.com/repos/huggingface/datasets/issues/5342/comments | https://api.github.com/repos/huggingface/datasets/issues/5342/events | https://github.com/huggingface/datasets/issues/5342 | 1,485,244,178 | I_kwDODunzps5YhwcS | 5,342 | Emotion dataset cannot be downloaded | {
"login": "cbarond",
"id": 78887193,
"node_id": "MDQ6VXNlcjc4ODg3MTkz",
"avatar_url": "https://avatars.githubusercontent.com/u/78887193?v=4",
"gravatar_id": "",
"url": "https://api.github.com/users/cbarond",
"html_url": "https://github.com/cbarond",
"followers_url": "https://api.github.com/users/cbaron... | [
{
"id": 1935892865,
"node_id": "MDU6TGFiZWwxOTM1ODkyODY1",
"url": "https://api.github.com/repos/huggingface/datasets/labels/duplicate",
"name": "duplicate",
"color": "cfd3d7",
"default": true,
"description": "This issue or pull request already exists",
"archived_at": null,
"archi... | closed | false | [] | null | 7 | 2022-12-08T19:07:09 | 2023-02-23T19:13:19 | 2022-12-09T10:46:11 | null | NONE | [] | null | null | null | null | ### Describe the bug
The emotion dataset gives a FileNotFoundError. The full error is: `FileNotFoundError: Couldn't find file at https://www.dropbox.com/s/1pzkadrvffbqw6o/train.txt?dl=1`.
It was working yesterday (December 7, 2022), but stopped working today (December 8, 2022).
### Steps to reproduce the bug
... | {
"login": "albertvillanova",
"id": 8515462,
"node_id": "MDQ6VXNlcjg1MTU0NjI=",
"avatar_url": "https://avatars.githubusercontent.com/u/8515462?v=4",
"gravatar_id": "",
"url": "https://api.github.com/users/albertvillanova",
"html_url": "https://github.com/albertvillanova",
"followers_url": "https://api.g... | {
"url": "https://api.github.com/repos/huggingface/datasets/issues/5342/reactions",
"total_count": 0,
"+1": 0,
"-1": 0,
"laugh": 0,
"hooray": 0,
"confused": 0,
"heart": 0,
"rocket": 0,
"eyes": 0
} | https://api.github.com/repos/huggingface/datasets/issues/5342/timeline | null | completed | {
"total": 0,
"completed": 0,
"percent_completed": 0
} | {
"blocked_by": 0,
"total_blocked_by": 0,
"blocking": 0,
"total_blocking": 0
} | null | false |
https://api.github.com/repos/huggingface/datasets/issues/5341 | https://api.github.com/repos/huggingface/datasets | https://api.github.com/repos/huggingface/datasets/issues/5341/labels{/name} | https://api.github.com/repos/huggingface/datasets/issues/5341/comments | https://api.github.com/repos/huggingface/datasets/issues/5341/events | https://github.com/huggingface/datasets/pull/5341 | 1,484,376,644 | PR_kwDODunzps5Exohx | 5,341 | Remove tasks.json | {
"login": "lhoestq",
"id": 42851186,
"node_id": "MDQ6VXNlcjQyODUxMTg2",
"avatar_url": "https://avatars.githubusercontent.com/u/42851186?v=4",
"gravatar_id": "",
"url": "https://api.github.com/users/lhoestq",
"html_url": "https://github.com/lhoestq",
"followers_url": "https://api.github.com/users/lhoest... | [] | closed | false | [] | null | 1 | 2022-12-08T11:04:35 | 2022-12-09T12:26:21 | 2022-12-09T12:23:20 | null | MEMBER | [] | null | null | false | {
"url": "https://api.github.com/repos/huggingface/datasets/pulls/5341",
"html_url": "https://github.com/huggingface/datasets/pull/5341",
"diff_url": "https://github.com/huggingface/datasets/pull/5341.diff",
"patch_url": "https://github.com/huggingface/datasets/pull/5341.patch",
"merged_at": "2022-12-09T12:23... | After discussions in https://github.com/huggingface/datasets/pull/5335 we should remove this file that is not used anymore. We should update https://github.com/huggingface/hub-docs/blob/main/js/src/lib/interfaces/Types.ts instead. | {
"login": "lhoestq",
"id": 42851186,
"node_id": "MDQ6VXNlcjQyODUxMTg2",
"avatar_url": "https://avatars.githubusercontent.com/u/42851186?v=4",
"gravatar_id": "",
"url": "https://api.github.com/users/lhoestq",
"html_url": "https://github.com/lhoestq",
"followers_url": "https://api.github.com/users/lhoest... | {
"url": "https://api.github.com/repos/huggingface/datasets/issues/5341/reactions",
"total_count": 0,
"+1": 0,
"-1": 0,
"laugh": 0,
"hooray": 0,
"confused": 0,
"heart": 0,
"rocket": 0,
"eyes": 0
} | https://api.github.com/repos/huggingface/datasets/issues/5341/timeline | null | null | null | null | null | true |
https://api.github.com/repos/huggingface/datasets/issues/5340 | https://api.github.com/repos/huggingface/datasets | https://api.github.com/repos/huggingface/datasets/issues/5340/labels{/name} | https://api.github.com/repos/huggingface/datasets/issues/5340/comments | https://api.github.com/repos/huggingface/datasets/issues/5340/events | https://github.com/huggingface/datasets/pull/5340 | 1,483,182,158 | PR_kwDODunzps5EtWo3 | 5,340 | Clean up DatasetInfo and Dataset docstrings | {
"login": "stevhliu",
"id": 59462357,
"node_id": "MDQ6VXNlcjU5NDYyMzU3",
"avatar_url": "https://avatars.githubusercontent.com/u/59462357?v=4",
"gravatar_id": "",
"url": "https://api.github.com/users/stevhliu",
"html_url": "https://github.com/stevhliu",
"followers_url": "https://api.github.com/users/ste... | [] | closed | false | [] | null | 1 | 2022-12-08T00:17:53 | 2022-12-08T19:33:14 | 2022-12-08T19:30:10 | null | MEMBER | [] | null | null | false | {
"url": "https://api.github.com/repos/huggingface/datasets/pulls/5340",
"html_url": "https://github.com/huggingface/datasets/pull/5340",
"diff_url": "https://github.com/huggingface/datasets/pull/5340.diff",
"patch_url": "https://github.com/huggingface/datasets/pull/5340.patch",
"merged_at": "2022-12-08T19:30... | This PR cleans up the docstrings for `DatasetInfo` and about half of the methods in `Dataset`. | {
"login": "stevhliu",
"id": 59462357,
"node_id": "MDQ6VXNlcjU5NDYyMzU3",
"avatar_url": "https://avatars.githubusercontent.com/u/59462357?v=4",
"gravatar_id": "",
"url": "https://api.github.com/users/stevhliu",
"html_url": "https://github.com/stevhliu",
"followers_url": "https://api.github.com/users/ste... | {
"url": "https://api.github.com/repos/huggingface/datasets/issues/5340/reactions",
"total_count": 1,
"+1": 0,
"-1": 0,
"laugh": 0,
"hooray": 0,
"confused": 0,
"heart": 1,
"rocket": 0,
"eyes": 0
} | https://api.github.com/repos/huggingface/datasets/issues/5340/timeline | null | null | null | null | null | true |
https://api.github.com/repos/huggingface/datasets/issues/5339 | https://api.github.com/repos/huggingface/datasets | https://api.github.com/repos/huggingface/datasets/issues/5339/labels{/name} | https://api.github.com/repos/huggingface/datasets/issues/5339/comments | https://api.github.com/repos/huggingface/datasets/issues/5339/events | https://github.com/huggingface/datasets/pull/5339 | 1,482,817,424 | PR_kwDODunzps5EsC8N | 5,339 | Add Video feature, videofolder, and video-classification task | {
"login": "nateraw",
"id": 32437151,
"node_id": "MDQ6VXNlcjMyNDM3MTUx",
"avatar_url": "https://avatars.githubusercontent.com/u/32437151?v=4",
"gravatar_id": "",
"url": "https://api.github.com/users/nateraw",
"html_url": "https://github.com/nateraw",
"followers_url": "https://api.github.com/users/natera... | [] | closed | false | [] | null | 4 | 2022-12-07T20:48:34 | 2024-01-11T06:30:24 | 2023-10-11T09:13:11 | null | CONTRIBUTOR | [] | null | null | true | {
"url": "https://api.github.com/repos/huggingface/datasets/pulls/5339",
"html_url": "https://github.com/huggingface/datasets/pull/5339",
"diff_url": "https://github.com/huggingface/datasets/pull/5339.diff",
"patch_url": "https://github.com/huggingface/datasets/pull/5339.patch",
"merged_at": null
} | This PR does the following:
- Adds `Video` feature (Resolves #5225 )
- Adds `video-classification` task
- Adds `videofolder` packaged module for easy loading of local video classification datasets
TODO:
- [ ] add tests
- [ ] add docs | {
"login": "albertvillanova",
"id": 8515462,
"node_id": "MDQ6VXNlcjg1MTU0NjI=",
"avatar_url": "https://avatars.githubusercontent.com/u/8515462?v=4",
"gravatar_id": "",
"url": "https://api.github.com/users/albertvillanova",
"html_url": "https://github.com/albertvillanova",
"followers_url": "https://api.g... | {
"url": "https://api.github.com/repos/huggingface/datasets/issues/5339/reactions",
"total_count": 1,
"+1": 0,
"-1": 0,
"laugh": 0,
"hooray": 0,
"confused": 0,
"heart": 1,
"rocket": 0,
"eyes": 0
} | https://api.github.com/repos/huggingface/datasets/issues/5339/timeline | null | null | null | null | null | true |
https://api.github.com/repos/huggingface/datasets/issues/5338 | https://api.github.com/repos/huggingface/datasets | https://api.github.com/repos/huggingface/datasets/issues/5338/labels{/name} | https://api.github.com/repos/huggingface/datasets/issues/5338/comments | https://api.github.com/repos/huggingface/datasets/issues/5338/events | https://github.com/huggingface/datasets/issues/5338 | 1,482,646,151 | I_kwDODunzps5YX2KH | 5,338 | `map()` stops every 1000 steps | {
"login": "bayartsogt-ya",
"id": 43239645,
"node_id": "MDQ6VXNlcjQzMjM5NjQ1",
"avatar_url": "https://avatars.githubusercontent.com/u/43239645?v=4",
"gravatar_id": "",
"url": "https://api.github.com/users/bayartsogt-ya",
"html_url": "https://github.com/bayartsogt-ya",
"followers_url": "https://api.githu... | [] | closed | false | [] | null | 3 | 2022-12-07T19:09:40 | 2025-02-14T18:10:07 | 2022-12-10T00:39:28 | null | NONE | [] | null | null | null | null | ### Describe the bug
I am passing the following `prepare_dataset` function to `Dataset.map` (code is inspired from [here](https://github.com/huggingface/community-events/blob/main/whisper-fine-tuning-event/run_speech_recognition_seq2seq_streaming.py#L454))
```python3
def prepare_dataset(batch):
# load and res... | {
"login": "bayartsogt-ya",
"id": 43239645,
"node_id": "MDQ6VXNlcjQzMjM5NjQ1",
"avatar_url": "https://avatars.githubusercontent.com/u/43239645?v=4",
"gravatar_id": "",
"url": "https://api.github.com/users/bayartsogt-ya",
"html_url": "https://github.com/bayartsogt-ya",
"followers_url": "https://api.githu... | {
"url": "https://api.github.com/repos/huggingface/datasets/issues/5338/reactions",
"total_count": 2,
"+1": 2,
"-1": 0,
"laugh": 0,
"hooray": 0,
"confused": 0,
"heart": 0,
"rocket": 0,
"eyes": 0
} | https://api.github.com/repos/huggingface/datasets/issues/5338/timeline | null | completed | {
"total": 0,
"completed": 0,
"percent_completed": 0
} | {
"blocked_by": 0,
"total_blocked_by": 0,
"blocking": 0,
"total_blocking": 0
} | null | false |
https://api.github.com/repos/huggingface/datasets/issues/5337 | https://api.github.com/repos/huggingface/datasets | https://api.github.com/repos/huggingface/datasets/issues/5337/labels{/name} | https://api.github.com/repos/huggingface/datasets/issues/5337/comments | https://api.github.com/repos/huggingface/datasets/issues/5337/events | https://github.com/huggingface/datasets/issues/5337 | 1,481,692,156 | I_kwDODunzps5YUNP8 | 5,337 | Support webdataset format | {
"login": "lhoestq",
"id": 42851186,
"node_id": "MDQ6VXNlcjQyODUxMTg2",
"avatar_url": "https://avatars.githubusercontent.com/u/42851186?v=4",
"gravatar_id": "",
"url": "https://api.github.com/users/lhoestq",
"html_url": "https://github.com/lhoestq",
"followers_url": "https://api.github.com/users/lhoest... | [] | closed | false | [
{
"login": "lhoestq",
"id": 42851186,
"node_id": "MDQ6VXNlcjQyODUxMTg2",
"avatar_url": "https://avatars.githubusercontent.com/u/42851186?v=4",
"gravatar_id": "",
"url": "https://api.github.com/users/lhoestq",
"html_url": "https://github.com/lhoestq",
"followers_url": "https://api.git... | null | 5 | 2022-12-07T11:32:25 | 2024-03-06T14:39:29 | 2024-03-06T14:39:28 | {
"login": "lhoestq",
"id": 42851186,
"node_id": "MDQ6VXNlcjQyODUxMTg2",
"avatar_url": "https://avatars.githubusercontent.com/u/42851186?v=4",
"gravatar_id": "",
"url": "https://api.github.com/users/lhoestq",
"html_url": "https://github.com/lhoestq",
"followers_url": "https://api.github.com/users/lhoest... | MEMBER | [] | null | null | null | null | Webdataset is an efficient format for iterable datasets. It would be nice to support it in `datasets`, as discussed in https://github.com/rom1504/img2dataset/issues/234.
In particular it would be awesome to be able to load one using `load_dataset` in streaming mode (either from a local directory, or from a dataset o... | {
"login": "lhoestq",
"id": 42851186,
"node_id": "MDQ6VXNlcjQyODUxMTg2",
"avatar_url": "https://avatars.githubusercontent.com/u/42851186?v=4",
"gravatar_id": "",
"url": "https://api.github.com/users/lhoestq",
"html_url": "https://github.com/lhoestq",
"followers_url": "https://api.github.com/users/lhoest... | {
"url": "https://api.github.com/repos/huggingface/datasets/issues/5337/reactions",
"total_count": 4,
"+1": 4,
"-1": 0,
"laugh": 0,
"hooray": 0,
"confused": 0,
"heart": 0,
"rocket": 0,
"eyes": 0
} | https://api.github.com/repos/huggingface/datasets/issues/5337/timeline | null | completed | {
"total": 0,
"completed": 0,
"percent_completed": 0
} | {
"blocked_by": 0,
"total_blocked_by": 0,
"blocking": 0,
"total_blocking": 0
} | null | false |
https://api.github.com/repos/huggingface/datasets/issues/5336 | https://api.github.com/repos/huggingface/datasets | https://api.github.com/repos/huggingface/datasets/issues/5336/labels{/name} | https://api.github.com/repos/huggingface/datasets/issues/5336/comments | https://api.github.com/repos/huggingface/datasets/issues/5336/events | https://github.com/huggingface/datasets/pull/5336 | 1,479,649,900 | PR_kwDODunzps5Egzed | 5,336 | Set `IterableDataset.map` param `batch_size` typing as optional | {
"login": "alvarobartt",
"id": 36760800,
"node_id": "MDQ6VXNlcjM2NzYwODAw",
"avatar_url": "https://avatars.githubusercontent.com/u/36760800?v=4",
"gravatar_id": "",
"url": "https://api.github.com/users/alvarobartt",
"html_url": "https://github.com/alvarobartt",
"followers_url": "https://api.github.com/... | [] | closed | false | [] | null | 3 | 2022-12-06T17:08:10 | 2022-12-07T14:14:56 | 2022-12-07T14:06:27 | null | MEMBER | [] | null | null | false | {
"url": "https://api.github.com/repos/huggingface/datasets/pulls/5336",
"html_url": "https://github.com/huggingface/datasets/pull/5336",
"diff_url": "https://github.com/huggingface/datasets/pull/5336.diff",
"patch_url": "https://github.com/huggingface/datasets/pull/5336.patch",
"merged_at": "2022-12-07T14:06... | This PR solves #5325
~Indeed we're using the typing for optional values as `Union[type, None]` as it's similar to how Python 3.10 handles optional values as `type | None`, instead of using `Optional[type]`.~
~Do we want to start using `Union[type, None]` for type-hinting optional values or just keep on using `Op... | {
"login": "lhoestq",
"id": 42851186,
"node_id": "MDQ6VXNlcjQyODUxMTg2",
"avatar_url": "https://avatars.githubusercontent.com/u/42851186?v=4",
"gravatar_id": "",
"url": "https://api.github.com/users/lhoestq",
"html_url": "https://github.com/lhoestq",
"followers_url": "https://api.github.com/users/lhoest... | {
"url": "https://api.github.com/repos/huggingface/datasets/issues/5336/reactions",
"total_count": 0,
"+1": 0,
"-1": 0,
"laugh": 0,
"hooray": 0,
"confused": 0,
"heart": 0,
"rocket": 0,
"eyes": 0
} | https://api.github.com/repos/huggingface/datasets/issues/5336/timeline | null | null | null | null | null | true |
https://api.github.com/repos/huggingface/datasets/issues/5335 | https://api.github.com/repos/huggingface/datasets | https://api.github.com/repos/huggingface/datasets/issues/5335/labels{/name} | https://api.github.com/repos/huggingface/datasets/issues/5335/comments | https://api.github.com/repos/huggingface/datasets/issues/5335/events | https://github.com/huggingface/datasets/pull/5335 | 1,478,890,788 | PR_kwDODunzps5EeHdA | 5,335 | Update tasks.json | {
"login": "sayakpaul",
"id": 22957388,
"node_id": "MDQ6VXNlcjIyOTU3Mzg4",
"avatar_url": "https://avatars.githubusercontent.com/u/22957388?v=4",
"gravatar_id": "",
"url": "https://api.github.com/users/sayakpaul",
"html_url": "https://github.com/sayakpaul",
"followers_url": "https://api.github.com/users/... | [] | closed | false | [] | null | 11 | 2022-12-06T11:37:57 | 2023-09-24T10:06:42 | 2022-12-07T12:46:03 | null | MEMBER | [] | null | null | false | {
"url": "https://api.github.com/repos/huggingface/datasets/pulls/5335",
"html_url": "https://github.com/huggingface/datasets/pull/5335",
"diff_url": "https://github.com/huggingface/datasets/pull/5335.diff",
"patch_url": "https://github.com/huggingface/datasets/pull/5335.patch",
"merged_at": null
} | Context:
* https://github.com/huggingface/datasets/issues/5255#issuecomment-1339107195
Cc: @osanseviero | {
"login": "sayakpaul",
"id": 22957388,
"node_id": "MDQ6VXNlcjIyOTU3Mzg4",
"avatar_url": "https://avatars.githubusercontent.com/u/22957388?v=4",
"gravatar_id": "",
"url": "https://api.github.com/users/sayakpaul",
"html_url": "https://github.com/sayakpaul",
"followers_url": "https://api.github.com/users/... | {
"url": "https://api.github.com/repos/huggingface/datasets/issues/5335/reactions",
"total_count": 0,
"+1": 0,
"-1": 0,
"laugh": 0,
"hooray": 0,
"confused": 0,
"heart": 0,
"rocket": 0,
"eyes": 0
} | https://api.github.com/repos/huggingface/datasets/issues/5335/timeline | null | null | null | null | null | true |
https://api.github.com/repos/huggingface/datasets/issues/5334 | https://api.github.com/repos/huggingface/datasets | https://api.github.com/repos/huggingface/datasets/issues/5334/labels{/name} | https://api.github.com/repos/huggingface/datasets/issues/5334/comments | https://api.github.com/repos/huggingface/datasets/issues/5334/events | https://github.com/huggingface/datasets/pull/5334 | 1,477,421,927 | PR_kwDODunzps5EY9zN | 5,334 | Clean up docstrings | {
"login": "stevhliu",
"id": 59462357,
"node_id": "MDQ6VXNlcjU5NDYyMzU3",
"avatar_url": "https://avatars.githubusercontent.com/u/59462357?v=4",
"gravatar_id": "",
"url": "https://api.github.com/users/stevhliu",
"html_url": "https://github.com/stevhliu",
"followers_url": "https://api.github.com/users/ste... | [
{
"id": 1935892861,
"node_id": "MDU6TGFiZWwxOTM1ODkyODYx",
"url": "https://api.github.com/repos/huggingface/datasets/labels/documentation",
"name": "documentation",
"color": "0075ca",
"default": true,
"description": "Improvements or additions to documentation",
"archived_at": null,
... | closed | false | [] | null | 3 | 2022-12-05T20:56:08 | 2022-12-09T01:44:25 | 2022-12-09T01:41:44 | null | MEMBER | [] | null | null | false | {
"url": "https://api.github.com/repos/huggingface/datasets/pulls/5334",
"html_url": "https://github.com/huggingface/datasets/pull/5334",
"diff_url": "https://github.com/huggingface/datasets/pull/5334.diff",
"patch_url": "https://github.com/huggingface/datasets/pull/5334.patch",
"merged_at": "2022-12-09T01:41... | As raised by @polinaeterna in #5324, some of the docstrings are a bit of a mess because it has both Markdown and Sphinx syntax. This PR fixes the docstring for `DatasetBuilder`.
I'll start working on cleaning up the rest of the docstrings and removing the old Sphinx syntax (let me know if you prefer one big PR with... | {
"login": "stevhliu",
"id": 59462357,
"node_id": "MDQ6VXNlcjU5NDYyMzU3",
"avatar_url": "https://avatars.githubusercontent.com/u/59462357?v=4",
"gravatar_id": "",
"url": "https://api.github.com/users/stevhliu",
"html_url": "https://github.com/stevhliu",
"followers_url": "https://api.github.com/users/ste... | {
"url": "https://api.github.com/repos/huggingface/datasets/issues/5334/reactions",
"total_count": 1,
"+1": 0,
"-1": 0,
"laugh": 0,
"hooray": 0,
"confused": 0,
"heart": 1,
"rocket": 0,
"eyes": 0
} | https://api.github.com/repos/huggingface/datasets/issues/5334/timeline | null | null | null | null | null | true |
https://api.github.com/repos/huggingface/datasets/issues/5333 | https://api.github.com/repos/huggingface/datasets | https://api.github.com/repos/huggingface/datasets/issues/5333/labels{/name} | https://api.github.com/repos/huggingface/datasets/issues/5333/comments | https://api.github.com/repos/huggingface/datasets/issues/5333/events | https://github.com/huggingface/datasets/pull/5333 | 1,476,890,156 | PR_kwDODunzps5EXGQ2 | 5,333 | fix: 🐛 pass the token to get the list of config names | {
"login": "severo",
"id": 1676121,
"node_id": "MDQ6VXNlcjE2NzYxMjE=",
"avatar_url": "https://avatars.githubusercontent.com/u/1676121?v=4",
"gravatar_id": "",
"url": "https://api.github.com/users/severo",
"html_url": "https://github.com/severo",
"followers_url": "https://api.github.com/users/severo/foll... | [] | closed | false | [] | null | 1 | 2022-12-05T16:06:09 | 2022-12-06T08:25:17 | 2022-12-06T08:22:49 | null | CONTRIBUTOR | [] | null | null | false | {
"url": "https://api.github.com/repos/huggingface/datasets/pulls/5333",
"html_url": "https://github.com/huggingface/datasets/pull/5333",
"diff_url": "https://github.com/huggingface/datasets/pull/5333.diff",
"patch_url": "https://github.com/huggingface/datasets/pull/5333.patch",
"merged_at": "2022-12-06T08:22... | Otherwise, get_dataset_infos doesn't work on gated or private datasets, even with the correct token. | {
"login": "severo",
"id": 1676121,
"node_id": "MDQ6VXNlcjE2NzYxMjE=",
"avatar_url": "https://avatars.githubusercontent.com/u/1676121?v=4",
"gravatar_id": "",
"url": "https://api.github.com/users/severo",
"html_url": "https://github.com/severo",
"followers_url": "https://api.github.com/users/severo/foll... | {
"url": "https://api.github.com/repos/huggingface/datasets/issues/5333/reactions",
"total_count": 1,
"+1": 0,
"-1": 0,
"laugh": 0,
"hooray": 0,
"confused": 0,
"heart": 1,
"rocket": 0,
"eyes": 0
} | https://api.github.com/repos/huggingface/datasets/issues/5333/timeline | null | null | null | null | null | true |
https://api.github.com/repos/huggingface/datasets/issues/5332 | https://api.github.com/repos/huggingface/datasets | https://api.github.com/repos/huggingface/datasets/issues/5332/labels{/name} | https://api.github.com/repos/huggingface/datasets/issues/5332/comments | https://api.github.com/repos/huggingface/datasets/issues/5332/events | https://github.com/huggingface/datasets/issues/5332 | 1,476,513,072 | I_kwDODunzps5YAc0w | 5,332 | Passing numpy array to ClassLabel names causes ValueError | {
"login": "freddyheppell",
"id": 1475568,
"node_id": "MDQ6VXNlcjE0NzU1Njg=",
"avatar_url": "https://avatars.githubusercontent.com/u/1475568?v=4",
"gravatar_id": "",
"url": "https://api.github.com/users/freddyheppell",
"html_url": "https://github.com/freddyheppell",
"followers_url": "https://api.github.... | [] | closed | false | [] | null | 5 | 2022-12-05T12:59:03 | 2022-12-22T16:32:50 | 2022-12-22T16:32:50 | null | CONTRIBUTOR | [] | null | null | null | null | ### Describe the bug
If a numpy array is passed to the names argument of ClassLabel, creating a dataset with those features causes an error.
### Steps to reproduce the bug
https://colab.research.google.com/drive/1cV_es1PWZiEuus17n-2C-w0KEoEZ68IX
TLDR:
If I define my classes as:
```
my_classes = np.array(['on... | {
"login": "mariosasko",
"id": 47462742,
"node_id": "MDQ6VXNlcjQ3NDYyNzQy",
"avatar_url": "https://avatars.githubusercontent.com/u/47462742?v=4",
"gravatar_id": "",
"url": "https://api.github.com/users/mariosasko",
"html_url": "https://github.com/mariosasko",
"followers_url": "https://api.github.com/use... | {
"url": "https://api.github.com/repos/huggingface/datasets/issues/5332/reactions",
"total_count": 0,
"+1": 0,
"-1": 0,
"laugh": 0,
"hooray": 0,
"confused": 0,
"heart": 0,
"rocket": 0,
"eyes": 0
} | https://api.github.com/repos/huggingface/datasets/issues/5332/timeline | null | completed | {
"total": 0,
"completed": 0,
"percent_completed": 0
} | {
"blocked_by": 0,
"total_blocked_by": 0,
"blocking": 0,
"total_blocking": 0
} | null | false |
https://api.github.com/repos/huggingface/datasets/issues/5331 | https://api.github.com/repos/huggingface/datasets | https://api.github.com/repos/huggingface/datasets/issues/5331/labels{/name} | https://api.github.com/repos/huggingface/datasets/issues/5331/comments | https://api.github.com/repos/huggingface/datasets/issues/5331/events | https://github.com/huggingface/datasets/pull/5331 | 1,473,146,738 | PR_kwDODunzps5EKDpr | 5,331 | Support for multiple configs in packaged modules via metadata yaml info | {
"login": "polinaeterna",
"id": 16348744,
"node_id": "MDQ6VXNlcjE2MzQ4NzQ0",
"avatar_url": "https://avatars.githubusercontent.com/u/16348744?v=4",
"gravatar_id": "",
"url": "https://api.github.com/users/polinaeterna",
"html_url": "https://github.com/polinaeterna",
"followers_url": "https://api.github.c... | [] | closed | false | [] | null | 22 | 2022-12-02T16:43:44 | 2023-07-24T15:49:54 | 2023-07-13T13:27:56 | null | CONTRIBUTOR | [] | null | null | false | {
"url": "https://api.github.com/repos/huggingface/datasets/pulls/5331",
"html_url": "https://github.com/huggingface/datasets/pull/5331",
"diff_url": "https://github.com/huggingface/datasets/pull/5331.diff",
"patch_url": "https://github.com/huggingface/datasets/pull/5331.patch",
"merged_at": "2023-07-13T13:27... | will solve https://github.com/huggingface/datasets/issues/5209 and https://github.com/huggingface/datasets/issues/5151 and many other...
Config parameters for packaged builders are parsed from `“builder_config”` field in README.md file (separate firs-level field, not part of “dataset_info”), example:
```yaml
---
... | {
"login": "polinaeterna",
"id": 16348744,
"node_id": "MDQ6VXNlcjE2MzQ4NzQ0",
"avatar_url": "https://avatars.githubusercontent.com/u/16348744?v=4",
"gravatar_id": "",
"url": "https://api.github.com/users/polinaeterna",
"html_url": "https://github.com/polinaeterna",
"followers_url": "https://api.github.c... | {
"url": "https://api.github.com/repos/huggingface/datasets/issues/5331/reactions",
"total_count": 0,
"+1": 0,
"-1": 0,
"laugh": 0,
"hooray": 0,
"confused": 0,
"heart": 0,
"rocket": 0,
"eyes": 0
} | https://api.github.com/repos/huggingface/datasets/issues/5331/timeline | null | null | null | null | null | true |
https://api.github.com/repos/huggingface/datasets/issues/5329 | https://api.github.com/repos/huggingface/datasets | https://api.github.com/repos/huggingface/datasets/issues/5329/labels{/name} | https://api.github.com/repos/huggingface/datasets/issues/5329/comments | https://api.github.com/repos/huggingface/datasets/issues/5329/events | https://github.com/huggingface/datasets/pull/5329 | 1,471,999,125 | PR_kwDODunzps5EGK3y | 5,329 | Clarify imagefolder is for small datasets | {
"login": "stevhliu",
"id": 59462357,
"node_id": "MDQ6VXNlcjU5NDYyMzU3",
"avatar_url": "https://avatars.githubusercontent.com/u/59462357?v=4",
"gravatar_id": "",
"url": "https://api.github.com/users/stevhliu",
"html_url": "https://github.com/stevhliu",
"followers_url": "https://api.github.com/users/ste... | [] | closed | false | [] | null | 4 | 2022-12-01T21:47:29 | 2022-12-06T17:20:04 | 2022-12-06T17:16:53 | null | MEMBER | [] | null | null | false | {
"url": "https://api.github.com/repos/huggingface/datasets/pulls/5329",
"html_url": "https://github.com/huggingface/datasets/pull/5329",
"diff_url": "https://github.com/huggingface/datasets/pull/5329.diff",
"patch_url": "https://github.com/huggingface/datasets/pull/5329.patch",
"merged_at": "2022-12-06T17:16... | Based on feedback from [here](https://github.com/huggingface/datasets/issues/5317#issuecomment-1334108824), this PR adds a note to the `imagefolder` loading and creating docs that `imagefolder` is designed for small scale image datasets. | {
"login": "stevhliu",
"id": 59462357,
"node_id": "MDQ6VXNlcjU5NDYyMzU3",
"avatar_url": "https://avatars.githubusercontent.com/u/59462357?v=4",
"gravatar_id": "",
"url": "https://api.github.com/users/stevhliu",
"html_url": "https://github.com/stevhliu",
"followers_url": "https://api.github.com/users/ste... | {
"url": "https://api.github.com/repos/huggingface/datasets/issues/5329/reactions",
"total_count": 1,
"+1": 0,
"-1": 0,
"laugh": 0,
"hooray": 0,
"confused": 0,
"heart": 1,
"rocket": 0,
"eyes": 0
} | https://api.github.com/repos/huggingface/datasets/issues/5329/timeline | null | null | null | null | null | true |
https://api.github.com/repos/huggingface/datasets/issues/5328 | https://api.github.com/repos/huggingface/datasets | https://api.github.com/repos/huggingface/datasets/issues/5328/labels{/name} | https://api.github.com/repos/huggingface/datasets/issues/5328/comments | https://api.github.com/repos/huggingface/datasets/issues/5328/events | https://github.com/huggingface/datasets/pull/5328 | 1,471,661,437 | PR_kwDODunzps5EFAyT | 5,328 | Fix docs building for main | {
"login": "albertvillanova",
"id": 8515462,
"node_id": "MDQ6VXNlcjg1MTU0NjI=",
"avatar_url": "https://avatars.githubusercontent.com/u/8515462?v=4",
"gravatar_id": "",
"url": "https://api.github.com/users/albertvillanova",
"html_url": "https://github.com/albertvillanova",
"followers_url": "https://api.g... | [] | closed | false | [] | null | 3 | 2022-12-01T17:07:45 | 2022-12-02T16:29:00 | 2022-12-02T16:26:00 | null | MEMBER | [] | null | null | false | {
"url": "https://api.github.com/repos/huggingface/datasets/pulls/5328",
"html_url": "https://github.com/huggingface/datasets/pull/5328",
"diff_url": "https://github.com/huggingface/datasets/pull/5328.diff",
"patch_url": "https://github.com/huggingface/datasets/pull/5328.patch",
"merged_at": "2022-12-02T16:26... | This PR reverts the triggering event for building documentation introduced by:
- #5250
Fix #5326. | {
"login": "albertvillanova",
"id": 8515462,
"node_id": "MDQ6VXNlcjg1MTU0NjI=",
"avatar_url": "https://avatars.githubusercontent.com/u/8515462?v=4",
"gravatar_id": "",
"url": "https://api.github.com/users/albertvillanova",
"html_url": "https://github.com/albertvillanova",
"followers_url": "https://api.g... | {
"url": "https://api.github.com/repos/huggingface/datasets/issues/5328/reactions",
"total_count": 0,
"+1": 0,
"-1": 0,
"laugh": 0,
"hooray": 0,
"confused": 0,
"heart": 0,
"rocket": 0,
"eyes": 0
} | https://api.github.com/repos/huggingface/datasets/issues/5328/timeline | null | null | null | null | null | true |
https://api.github.com/repos/huggingface/datasets/issues/5327 | https://api.github.com/repos/huggingface/datasets | https://api.github.com/repos/huggingface/datasets/issues/5327/labels{/name} | https://api.github.com/repos/huggingface/datasets/issues/5327/comments | https://api.github.com/repos/huggingface/datasets/issues/5327/events | https://github.com/huggingface/datasets/pull/5327 | 1,471,657,247 | PR_kwDODunzps5EE_3Q | 5,327 | Avoid unwanted behaviour when splits from script and metadata are not matching because of outdated metadata | {
"login": "polinaeterna",
"id": 16348744,
"node_id": "MDQ6VXNlcjE2MzQ4NzQ0",
"avatar_url": "https://avatars.githubusercontent.com/u/16348744?v=4",
"gravatar_id": "",
"url": "https://api.github.com/users/polinaeterna",
"html_url": "https://github.com/polinaeterna",
"followers_url": "https://api.github.c... | [] | open | false | [
{
"login": "polinaeterna",
"id": 16348744,
"node_id": "MDQ6VXNlcjE2MzQ4NzQ0",
"avatar_url": "https://avatars.githubusercontent.com/u/16348744?v=4",
"gravatar_id": "",
"url": "https://api.github.com/users/polinaeterna",
"html_url": "https://github.com/polinaeterna",
"followers_url": "... | null | 1 | 2022-12-01T17:05:23 | 2023-01-23T12:48:29 | null | {
"login": "polinaeterna",
"id": 16348744,
"node_id": "MDQ6VXNlcjE2MzQ4NzQ0",
"avatar_url": "https://avatars.githubusercontent.com/u/16348744?v=4",
"gravatar_id": "",
"url": "https://api.github.com/users/polinaeterna",
"html_url": "https://github.com/polinaeterna",
"followers_url": "https://api.github.c... | CONTRIBUTOR | [] | null | null | true | {
"url": "https://api.github.com/repos/huggingface/datasets/pulls/5327",
"html_url": "https://github.com/huggingface/datasets/pull/5327",
"diff_url": "https://github.com/huggingface/datasets/pull/5327.diff",
"patch_url": "https://github.com/huggingface/datasets/pull/5327.patch",
"merged_at": null
} | will fix #5315 | null | {
"url": "https://api.github.com/repos/huggingface/datasets/issues/5327/reactions",
"total_count": 0,
"+1": 0,
"-1": 0,
"laugh": 0,
"hooray": 0,
"confused": 0,
"heart": 0,
"rocket": 0,
"eyes": 0
} | https://api.github.com/repos/huggingface/datasets/issues/5327/timeline | null | null | null | null | null | true |
https://api.github.com/repos/huggingface/datasets/issues/5326 | https://api.github.com/repos/huggingface/datasets | https://api.github.com/repos/huggingface/datasets/issues/5326/labels{/name} | https://api.github.com/repos/huggingface/datasets/issues/5326/comments | https://api.github.com/repos/huggingface/datasets/issues/5326/events | https://github.com/huggingface/datasets/issues/5326 | 1,471,634,168 | I_kwDODunzps5Xt1r4 | 5,326 | No documentation for main branch is built | {
"login": "albertvillanova",
"id": 8515462,
"node_id": "MDQ6VXNlcjg1MTU0NjI=",
"avatar_url": "https://avatars.githubusercontent.com/u/8515462?v=4",
"gravatar_id": "",
"url": "https://api.github.com/users/albertvillanova",
"html_url": "https://github.com/albertvillanova",
"followers_url": "https://api.g... | [
{
"id": 1935892857,
"node_id": "MDU6TGFiZWwxOTM1ODkyODU3",
"url": "https://api.github.com/repos/huggingface/datasets/labels/bug",
"name": "bug",
"color": "d73a4a",
"default": true,
"description": "Something isn't working",
"archived_at": null,
"archived_by": null
}
] | closed | false | [
{
"login": "albertvillanova",
"id": 8515462,
"node_id": "MDQ6VXNlcjg1MTU0NjI=",
"avatar_url": "https://avatars.githubusercontent.com/u/8515462?v=4",
"gravatar_id": "",
"url": "https://api.github.com/users/albertvillanova",
"html_url": "https://github.com/albertvillanova",
"followers_... | null | 0 | 2022-12-01T16:50:58 | 2022-12-02T16:26:01 | 2022-12-02T16:26:01 | {
"login": "albertvillanova",
"id": 8515462,
"node_id": "MDQ6VXNlcjg1MTU0NjI=",
"avatar_url": "https://avatars.githubusercontent.com/u/8515462?v=4",
"gravatar_id": "",
"url": "https://api.github.com/users/albertvillanova",
"html_url": "https://github.com/albertvillanova",
"followers_url": "https://api.g... | MEMBER | [] | null | null | null | null | Since:
- #5250
- Commit: 703b84311f4ead83c7f79639f2dfa739295f0be6
the docs for main branch are no longer built.
The change introduced only triggers the docs building for releases. | {
"login": "albertvillanova",
"id": 8515462,
"node_id": "MDQ6VXNlcjg1MTU0NjI=",
"avatar_url": "https://avatars.githubusercontent.com/u/8515462?v=4",
"gravatar_id": "",
"url": "https://api.github.com/users/albertvillanova",
"html_url": "https://github.com/albertvillanova",
"followers_url": "https://api.g... | {
"url": "https://api.github.com/repos/huggingface/datasets/issues/5326/reactions",
"total_count": 0,
"+1": 0,
"-1": 0,
"laugh": 0,
"hooray": 0,
"confused": 0,
"heart": 0,
"rocket": 0,
"eyes": 0
} | https://api.github.com/repos/huggingface/datasets/issues/5326/timeline | null | completed | {
"total": 0,
"completed": 0,
"percent_completed": 0
} | {
"blocked_by": 0,
"total_blocked_by": 0,
"blocking": 0,
"total_blocking": 0
} | null | false |
https://api.github.com/repos/huggingface/datasets/issues/5325 | https://api.github.com/repos/huggingface/datasets | https://api.github.com/repos/huggingface/datasets/issues/5325/labels{/name} | https://api.github.com/repos/huggingface/datasets/issues/5325/comments | https://api.github.com/repos/huggingface/datasets/issues/5325/events | https://github.com/huggingface/datasets/issues/5325 | 1,471,536,822 | I_kwDODunzps5Xtd62 | 5,325 | map(...batch_size=None) for IterableDataset | {
"login": "frankier",
"id": 299380,
"node_id": "MDQ6VXNlcjI5OTM4MA==",
"avatar_url": "https://avatars.githubusercontent.com/u/299380?v=4",
"gravatar_id": "",
"url": "https://api.github.com/users/frankier",
"html_url": "https://github.com/frankier",
"followers_url": "https://api.github.com/users/frankie... | [
{
"id": 1935892871,
"node_id": "MDU6TGFiZWwxOTM1ODkyODcx",
"url": "https://api.github.com/repos/huggingface/datasets/labels/enhancement",
"name": "enhancement",
"color": "a2eeef",
"default": true,
"description": "New feature or request",
"archived_at": null,
"archived_by": null
... | closed | false | [
{
"login": "alvarobartt",
"id": 36760800,
"node_id": "MDQ6VXNlcjM2NzYwODAw",
"avatar_url": "https://avatars.githubusercontent.com/u/36760800?v=4",
"gravatar_id": "",
"url": "https://api.github.com/users/alvarobartt",
"html_url": "https://github.com/alvarobartt",
"followers_url": "htt... | null | 5 | 2022-12-01T15:43:42 | 2022-12-07T15:54:43 | 2022-12-07T15:54:42 | {
"login": "alvarobartt",
"id": 36760800,
"node_id": "MDQ6VXNlcjM2NzYwODAw",
"avatar_url": "https://avatars.githubusercontent.com/u/36760800?v=4",
"gravatar_id": "",
"url": "https://api.github.com/users/alvarobartt",
"html_url": "https://github.com/alvarobartt",
"followers_url": "https://api.github.com/... | CONTRIBUTOR | [] | null | null | null | null | ### Feature request
Dataset.map(...) allows batch_size to be None. It would be nice if IterableDataset did too.
### Motivation
Although it may seem a bit of a spurious request given that `IterableDataset` is meant for larger than memory datasets, but there are a couple of reasons why this might be nice.
One is th... | {
"login": "lhoestq",
"id": 42851186,
"node_id": "MDQ6VXNlcjQyODUxMTg2",
"avatar_url": "https://avatars.githubusercontent.com/u/42851186?v=4",
"gravatar_id": "",
"url": "https://api.github.com/users/lhoestq",
"html_url": "https://github.com/lhoestq",
"followers_url": "https://api.github.com/users/lhoest... | {
"url": "https://api.github.com/repos/huggingface/datasets/issues/5325/reactions",
"total_count": 0,
"+1": 0,
"-1": 0,
"laugh": 0,
"hooray": 0,
"confused": 0,
"heart": 0,
"rocket": 0,
"eyes": 0
} | https://api.github.com/repos/huggingface/datasets/issues/5325/timeline | null | completed | {
"total": 0,
"completed": 0,
"percent_completed": 0
} | {
"blocked_by": 0,
"total_blocked_by": 0,
"blocking": 0,
"total_blocking": 0
} | null | false |
https://api.github.com/repos/huggingface/datasets/issues/5324 | https://api.github.com/repos/huggingface/datasets | https://api.github.com/repos/huggingface/datasets/issues/5324/labels{/name} | https://api.github.com/repos/huggingface/datasets/issues/5324/comments | https://api.github.com/repos/huggingface/datasets/issues/5324/events | https://github.com/huggingface/datasets/issues/5324 | 1,471,524,512 | I_kwDODunzps5Xta6g | 5,324 | Fix docstrings and types in documentation that appears on the website | {
"login": "polinaeterna",
"id": 16348744,
"node_id": "MDQ6VXNlcjE2MzQ4NzQ0",
"avatar_url": "https://avatars.githubusercontent.com/u/16348744?v=4",
"gravatar_id": "",
"url": "https://api.github.com/users/polinaeterna",
"html_url": "https://github.com/polinaeterna",
"followers_url": "https://api.github.c... | [
{
"id": 1935892861,
"node_id": "MDU6TGFiZWwxOTM1ODkyODYx",
"url": "https://api.github.com/repos/huggingface/datasets/labels/documentation",
"name": "documentation",
"color": "0075ca",
"default": true,
"description": "Improvements or additions to documentation",
"archived_at": null,
... | open | false | [] | null | 5 | 2022-12-01T15:34:53 | 2026-09-01T12:09:58 | null | null | CONTRIBUTOR | [] | null | null | null | null | While I was working on https://github.com/huggingface/datasets/pull/5313 I've noticed that we have a mess in how we annotate types and format args and return values in the code. And some of it is displayed in the [Reference section](https://huggingface.co/docs/datasets/package_reference/builder_classes) of the document... | null | {
"url": "https://api.github.com/repos/huggingface/datasets/issues/5324/reactions",
"total_count": 0,
"+1": 0,
"-1": 0,
"laugh": 0,
"hooray": 0,
"confused": 0,
"heart": 0,
"rocket": 0,
"eyes": 0
} | https://api.github.com/repos/huggingface/datasets/issues/5324/timeline | null | null | {
"total": 0,
"completed": 0,
"percent_completed": 0
} | {
"blocked_by": 0,
"total_blocked_by": 0,
"blocking": 0,
"total_blocking": 0
} | null | false |
https://api.github.com/repos/huggingface/datasets/issues/5323 | https://api.github.com/repos/huggingface/datasets | https://api.github.com/repos/huggingface/datasets/issues/5323/labels{/name} | https://api.github.com/repos/huggingface/datasets/issues/5323/comments | https://api.github.com/repos/huggingface/datasets/issues/5323/events | https://github.com/huggingface/datasets/issues/5323 | 1,471,518,803 | I_kwDODunzps5XtZhT | 5,323 | Duplicated Keys in Taskmaster-2 Dataset | {
"login": "liaeh",
"id": 52380283,
"node_id": "MDQ6VXNlcjUyMzgwMjgz",
"avatar_url": "https://avatars.githubusercontent.com/u/52380283?v=4",
"gravatar_id": "",
"url": "https://api.github.com/users/liaeh",
"html_url": "https://github.com/liaeh",
"followers_url": "https://api.github.com/users/liaeh/follow... | [] | closed | false | [
{
"login": "albertvillanova",
"id": 8515462,
"node_id": "MDQ6VXNlcjg1MTU0NjI=",
"avatar_url": "https://avatars.githubusercontent.com/u/8515462?v=4",
"gravatar_id": "",
"url": "https://api.github.com/users/albertvillanova",
"html_url": "https://github.com/albertvillanova",
"followers_... | null | 2 | 2022-12-01T15:31:06 | 2022-12-01T16:26:06 | 2022-12-01T16:26:06 | {
"login": "albertvillanova",
"id": 8515462,
"node_id": "MDQ6VXNlcjg1MTU0NjI=",
"avatar_url": "https://avatars.githubusercontent.com/u/8515462?v=4",
"gravatar_id": "",
"url": "https://api.github.com/users/albertvillanova",
"html_url": "https://github.com/albertvillanova",
"followers_url": "https://api.g... | NONE | [] | null | null | null | null | ### Describe the bug
Loading certain splits () of the taskmaster-2 dataset fails because of a DuplicatedKeysError. This occurs for the following domains: `'hotels', 'movies', 'music', 'sports'`. The domains `'flights', 'food-ordering', 'restaurant-search'` load fine.
Output:
### Steps to reproduce the bug
```
... | {
"login": "albertvillanova",
"id": 8515462,
"node_id": "MDQ6VXNlcjg1MTU0NjI=",
"avatar_url": "https://avatars.githubusercontent.com/u/8515462?v=4",
"gravatar_id": "",
"url": "https://api.github.com/users/albertvillanova",
"html_url": "https://github.com/albertvillanova",
"followers_url": "https://api.g... | {
"url": "https://api.github.com/repos/huggingface/datasets/issues/5323/reactions",
"total_count": 0,
"+1": 0,
"-1": 0,
"laugh": 0,
"hooray": 0,
"confused": 0,
"heart": 0,
"rocket": 0,
"eyes": 0
} | https://api.github.com/repos/huggingface/datasets/issues/5323/timeline | null | completed | {
"total": 0,
"completed": 0,
"percent_completed": 0
} | {
"blocked_by": 0,
"total_blocked_by": 0,
"blocking": 0,
"total_blocking": 0
} | null | false |
https://api.github.com/repos/huggingface/datasets/issues/5322 | https://api.github.com/repos/huggingface/datasets | https://api.github.com/repos/huggingface/datasets/issues/5322/labels{/name} | https://api.github.com/repos/huggingface/datasets/issues/5322/comments | https://api.github.com/repos/huggingface/datasets/issues/5322/events | https://github.com/huggingface/datasets/pull/5322 | 1,471,502,162 | PR_kwDODunzps5EEeQP | 5,322 | Raise error for `.tar` archives in the same way as for `.tar.gz` and `.tgz` in `_get_extraction_protocol` | {
"login": "polinaeterna",
"id": 16348744,
"node_id": "MDQ6VXNlcjE2MzQ4NzQ0",
"avatar_url": "https://avatars.githubusercontent.com/u/16348744?v=4",
"gravatar_id": "",
"url": "https://api.github.com/users/polinaeterna",
"html_url": "https://github.com/polinaeterna",
"followers_url": "https://api.github.c... | [] | closed | false | [] | null | 1 | 2022-12-01T15:19:28 | 2022-12-14T16:37:16 | 2022-12-14T16:33:30 | null | CONTRIBUTOR | [] | null | null | false | {
"url": "https://api.github.com/repos/huggingface/datasets/pulls/5322",
"html_url": "https://github.com/huggingface/datasets/pull/5322",
"diff_url": "https://github.com/huggingface/datasets/pull/5322.diff",
"patch_url": "https://github.com/huggingface/datasets/pull/5322.patch",
"merged_at": "2022-12-14T16:33... | Currently `download_and_extract` doesn't throw an error when it is used with files with `.tar` extension in streaming mode because `_get_extraction_protocol` doesn't do it (like it does for `tar.gz` and `tgz`). `_get_extraction_protocol` returns formatted url as if we support tar protocol but we don't.
That means tha... | {
"login": "polinaeterna",
"id": 16348744,
"node_id": "MDQ6VXNlcjE2MzQ4NzQ0",
"avatar_url": "https://avatars.githubusercontent.com/u/16348744?v=4",
"gravatar_id": "",
"url": "https://api.github.com/users/polinaeterna",
"html_url": "https://github.com/polinaeterna",
"followers_url": "https://api.github.c... | {
"url": "https://api.github.com/repos/huggingface/datasets/issues/5322/reactions",
"total_count": 0,
"+1": 0,
"-1": 0,
"laugh": 0,
"hooray": 0,
"confused": 0,
"heart": 0,
"rocket": 0,
"eyes": 0
} | https://api.github.com/repos/huggingface/datasets/issues/5322/timeline | null | null | null | null | null | true |
https://api.github.com/repos/huggingface/datasets/issues/5321 | https://api.github.com/repos/huggingface/datasets | https://api.github.com/repos/huggingface/datasets/issues/5321/labels{/name} | https://api.github.com/repos/huggingface/datasets/issues/5321/comments | https://api.github.com/repos/huggingface/datasets/issues/5321/events | https://github.com/huggingface/datasets/pull/5321 | 1,471,430,667 | PR_kwDODunzps5EEOhE | 5,321 | Fix loading from HF GCP cache | {
"login": "lhoestq",
"id": 42851186,
"node_id": "MDQ6VXNlcjQyODUxMTg2",
"avatar_url": "https://avatars.githubusercontent.com/u/42851186?v=4",
"gravatar_id": "",
"url": "https://api.github.com/users/lhoestq",
"html_url": "https://github.com/lhoestq",
"followers_url": "https://api.github.com/users/lhoest... | [] | closed | false | [] | null | 2 | 2022-12-01T14:39:06 | 2022-12-01T16:10:09 | 2022-12-01T16:07:02 | null | MEMBER | [] | null | null | false | {
"url": "https://api.github.com/repos/huggingface/datasets/pulls/5321",
"html_url": "https://github.com/huggingface/datasets/pull/5321",
"diff_url": "https://github.com/huggingface/datasets/pull/5321.diff",
"patch_url": "https://github.com/huggingface/datasets/pull/5321.patch",
"merged_at": "2022-12-01T16:07... | As reported in https://discuss.huggingface.co/t/error-loading-wikipedia-dataset/26599/4 it's not possible to download a cached version of Wikipedia from the HF GCP cache
I fixed it and added an integration test (runs in 10sec) | {
"login": "lhoestq",
"id": 42851186,
"node_id": "MDQ6VXNlcjQyODUxMTg2",
"avatar_url": "https://avatars.githubusercontent.com/u/42851186?v=4",
"gravatar_id": "",
"url": "https://api.github.com/users/lhoestq",
"html_url": "https://github.com/lhoestq",
"followers_url": "https://api.github.com/users/lhoest... | {
"url": "https://api.github.com/repos/huggingface/datasets/issues/5321/reactions",
"total_count": 0,
"+1": 0,
"-1": 0,
"laugh": 0,
"hooray": 0,
"confused": 0,
"heart": 0,
"rocket": 0,
"eyes": 0
} | https://api.github.com/repos/huggingface/datasets/issues/5321/timeline | null | null | null | null | null | true |
https://api.github.com/repos/huggingface/datasets/issues/5320 | https://api.github.com/repos/huggingface/datasets | https://api.github.com/repos/huggingface/datasets/issues/5320/labels{/name} | https://api.github.com/repos/huggingface/datasets/issues/5320/comments | https://api.github.com/repos/huggingface/datasets/issues/5320/events | https://github.com/huggingface/datasets/pull/5320 | 1,471,360,910 | PR_kwDODunzps5ED_UQ | 5,320 | [Extract] Place the lock file next to the destination directory | {
"login": "lhoestq",
"id": 42851186,
"node_id": "MDQ6VXNlcjQyODUxMTg2",
"avatar_url": "https://avatars.githubusercontent.com/u/42851186?v=4",
"gravatar_id": "",
"url": "https://api.github.com/users/lhoestq",
"html_url": "https://github.com/lhoestq",
"followers_url": "https://api.github.com/users/lhoest... | [] | closed | false | [] | null | 1 | 2022-12-01T13:55:49 | 2022-12-01T15:36:44 | 2022-12-01T15:33:58 | null | MEMBER | [] | null | null | false | {
"url": "https://api.github.com/repos/huggingface/datasets/pulls/5320",
"html_url": "https://github.com/huggingface/datasets/pull/5320",
"diff_url": "https://github.com/huggingface/datasets/pull/5320.diff",
"patch_url": "https://github.com/huggingface/datasets/pull/5320.patch",
"merged_at": "2022-12-01T15:33... | Previously it was placed next to the archive to extract, but the archive can be in a read-only directory as noticed in https://github.com/huggingface/datasets/issues/5295
Therefore I moved the lock location to be next to the destination directory, which is required to have write permissions | {
"login": "lhoestq",
"id": 42851186,
"node_id": "MDQ6VXNlcjQyODUxMTg2",
"avatar_url": "https://avatars.githubusercontent.com/u/42851186?v=4",
"gravatar_id": "",
"url": "https://api.github.com/users/lhoestq",
"html_url": "https://github.com/lhoestq",
"followers_url": "https://api.github.com/users/lhoest... | {
"url": "https://api.github.com/repos/huggingface/datasets/issues/5320/reactions",
"total_count": 0,
"+1": 0,
"-1": 0,
"laugh": 0,
"hooray": 0,
"confused": 0,
"heart": 0,
"rocket": 0,
"eyes": 0
} | https://api.github.com/repos/huggingface/datasets/issues/5320/timeline | null | null | null | null | null | true |
https://api.github.com/repos/huggingface/datasets/issues/5319 | https://api.github.com/repos/huggingface/datasets | https://api.github.com/repos/huggingface/datasets/issues/5319/labels{/name} | https://api.github.com/repos/huggingface/datasets/issues/5319/comments | https://api.github.com/repos/huggingface/datasets/issues/5319/events | https://github.com/huggingface/datasets/pull/5319 | 1,470,945,515 | PR_kwDODunzps5ECkfc | 5,319 | Fix Text sample_by paragraph | {
"login": "albertvillanova",
"id": 8515462,
"node_id": "MDQ6VXNlcjg1MTU0NjI=",
"avatar_url": "https://avatars.githubusercontent.com/u/8515462?v=4",
"gravatar_id": "",
"url": "https://api.github.com/users/albertvillanova",
"html_url": "https://github.com/albertvillanova",
"followers_url": "https://api.g... | [] | closed | false | [] | null | 1 | 2022-12-01T09:08:09 | 2022-12-01T15:21:44 | 2022-12-01T15:19:00 | null | MEMBER | [] | null | null | false | {
"url": "https://api.github.com/repos/huggingface/datasets/pulls/5319",
"html_url": "https://github.com/huggingface/datasets/pull/5319",
"diff_url": "https://github.com/huggingface/datasets/pull/5319.diff",
"patch_url": "https://github.com/huggingface/datasets/pull/5319.patch",
"merged_at": "2022-12-01T15:19... | Fix #5316. | {
"login": "albertvillanova",
"id": 8515462,
"node_id": "MDQ6VXNlcjg1MTU0NjI=",
"avatar_url": "https://avatars.githubusercontent.com/u/8515462?v=4",
"gravatar_id": "",
"url": "https://api.github.com/users/albertvillanova",
"html_url": "https://github.com/albertvillanova",
"followers_url": "https://api.g... | {
"url": "https://api.github.com/repos/huggingface/datasets/issues/5319/reactions",
"total_count": 0,
"+1": 0,
"-1": 0,
"laugh": 0,
"hooray": 0,
"confused": 0,
"heart": 0,
"rocket": 0,
"eyes": 0
} | https://api.github.com/repos/huggingface/datasets/issues/5319/timeline | null | null | null | null | null | true |
https://api.github.com/repos/huggingface/datasets/issues/5318 | https://api.github.com/repos/huggingface/datasets | https://api.github.com/repos/huggingface/datasets/issues/5318/labels{/name} | https://api.github.com/repos/huggingface/datasets/issues/5318/comments | https://api.github.com/repos/huggingface/datasets/issues/5318/events | https://github.com/huggingface/datasets/pull/5318 | 1,470,749,750 | PR_kwDODunzps5EB6RM | 5,318 | Origin/fix missing features error | {
"login": "eunseojo",
"id": 12104720,
"node_id": "MDQ6VXNlcjEyMTA0NzIw",
"avatar_url": "https://avatars.githubusercontent.com/u/12104720?v=4",
"gravatar_id": "",
"url": "https://api.github.com/users/eunseojo",
"html_url": "https://github.com/eunseojo",
"followers_url": "https://api.github.com/users/eun... | [] | closed | false | [] | null | 5 | 2022-12-01T06:18:39 | 2022-12-12T19:06:42 | 2022-12-04T05:49:39 | null | CONTRIBUTOR | [] | null | null | false | {
"url": "https://api.github.com/repos/huggingface/datasets/pulls/5318",
"html_url": "https://github.com/huggingface/datasets/pull/5318",
"diff_url": "https://github.com/huggingface/datasets/pull/5318.diff",
"patch_url": "https://github.com/huggingface/datasets/pull/5318.patch",
"merged_at": "2022-12-04T05:49... | This fixes the problem of when the dataset_load function reads a function with "features" provided but some read batches don't have columns that later show up. For instance, the provided "features" requires columns A,B,C but only columns B,C show. This fixes this by adding the column A with nulls. | {
"login": "eunseojo",
"id": 12104720,
"node_id": "MDQ6VXNlcjEyMTA0NzIw",
"avatar_url": "https://avatars.githubusercontent.com/u/12104720?v=4",
"gravatar_id": "",
"url": "https://api.github.com/users/eunseojo",
"html_url": "https://github.com/eunseojo",
"followers_url": "https://api.github.com/users/eun... | {
"url": "https://api.github.com/repos/huggingface/datasets/issues/5318/reactions",
"total_count": 0,
"+1": 0,
"-1": 0,
"laugh": 0,
"hooray": 0,
"confused": 0,
"heart": 0,
"rocket": 0,
"eyes": 0
} | https://api.github.com/repos/huggingface/datasets/issues/5318/timeline | null | null | null | null | null | true |
https://api.github.com/repos/huggingface/datasets/issues/5317 | https://api.github.com/repos/huggingface/datasets | https://api.github.com/repos/huggingface/datasets/issues/5317/labels{/name} | https://api.github.com/repos/huggingface/datasets/issues/5317/comments | https://api.github.com/repos/huggingface/datasets/issues/5317/events | https://github.com/huggingface/datasets/issues/5317 | 1,470,390,164 | I_kwDODunzps5XpF-U | 5,317 | `ImageFolder` performs poorly with large datasets | {
"login": "salieri",
"id": 1086393,
"node_id": "MDQ6VXNlcjEwODYzOTM=",
"avatar_url": "https://avatars.githubusercontent.com/u/1086393?v=4",
"gravatar_id": "",
"url": "https://api.github.com/users/salieri",
"html_url": "https://github.com/salieri",
"followers_url": "https://api.github.com/users/salieri/... | [] | open | false | [] | null | 3 | 2022-12-01T00:04:21 | 2022-12-01T21:49:26 | null | null | NONE | [] | null | null | null | null | ### Describe the bug
While testing image dataset creation, I'm seeing significant performance bottlenecks with imagefolders when scanning a directory structure with large number of images.
## Setup
* Nested directories (5 levels deep)
* 3M+ images
* 1 `metadata.jsonl` file
## Performance Degradation Point... | null | {
"url": "https://api.github.com/repos/huggingface/datasets/issues/5317/reactions",
"total_count": 0,
"+1": 0,
"-1": 0,
"laugh": 0,
"hooray": 0,
"confused": 0,
"heart": 0,
"rocket": 0,
"eyes": 0
} | https://api.github.com/repos/huggingface/datasets/issues/5317/timeline | null | null | {
"total": 0,
"completed": 0,
"percent_completed": 0
} | {
"blocked_by": 0,
"total_blocked_by": 0,
"blocking": 0,
"total_blocking": 0
} | null | false |
https://api.github.com/repos/huggingface/datasets/issues/5316 | https://api.github.com/repos/huggingface/datasets | https://api.github.com/repos/huggingface/datasets/issues/5316/labels{/name} | https://api.github.com/repos/huggingface/datasets/issues/5316/comments | https://api.github.com/repos/huggingface/datasets/issues/5316/events | https://github.com/huggingface/datasets/issues/5316 | 1,470,115,681 | I_kwDODunzps5XoC9h | 5,316 | Bug in sample_by="paragraph" | {
"login": "adampauls",
"id": 1243668,
"node_id": "MDQ6VXNlcjEyNDM2Njg=",
"avatar_url": "https://avatars.githubusercontent.com/u/1243668?v=4",
"gravatar_id": "",
"url": "https://api.github.com/users/adampauls",
"html_url": "https://github.com/adampauls",
"followers_url": "https://api.github.com/users/ad... | [] | closed | false | [
{
"login": "albertvillanova",
"id": 8515462,
"node_id": "MDQ6VXNlcjg1MTU0NjI=",
"avatar_url": "https://avatars.githubusercontent.com/u/8515462?v=4",
"gravatar_id": "",
"url": "https://api.github.com/users/albertvillanova",
"html_url": "https://github.com/albertvillanova",
"followers_... | null | 1 | 2022-11-30T19:24:13 | 2022-12-01T15:19:02 | 2022-12-01T15:19:02 | {
"login": "albertvillanova",
"id": 8515462,
"node_id": "MDQ6VXNlcjg1MTU0NjI=",
"avatar_url": "https://avatars.githubusercontent.com/u/8515462?v=4",
"gravatar_id": "",
"url": "https://api.github.com/users/albertvillanova",
"html_url": "https://github.com/albertvillanova",
"followers_url": "https://api.g... | NONE | [] | null | null | null | null | ### Describe the bug
I think [this line](https://github.com/huggingface/datasets/blob/main/src/datasets/packaged_modules/text/text.py#L96) is wrong and should be `batch = f.read(self.config.chunksize)`. Otherwise it will never terminate because even when `f` is finished reading, `batch` will still be truthy from the l... | {
"login": "albertvillanova",
"id": 8515462,
"node_id": "MDQ6VXNlcjg1MTU0NjI=",
"avatar_url": "https://avatars.githubusercontent.com/u/8515462?v=4",
"gravatar_id": "",
"url": "https://api.github.com/users/albertvillanova",
"html_url": "https://github.com/albertvillanova",
"followers_url": "https://api.g... | {
"url": "https://api.github.com/repos/huggingface/datasets/issues/5316/reactions",
"total_count": 0,
"+1": 0,
"-1": 0,
"laugh": 0,
"hooray": 0,
"confused": 0,
"heart": 0,
"rocket": 0,
"eyes": 0
} | https://api.github.com/repos/huggingface/datasets/issues/5316/timeline | null | completed | {
"total": 0,
"completed": 0,
"percent_completed": 0
} | {
"blocked_by": 0,
"total_blocked_by": 0,
"blocking": 0,
"total_blocking": 0
} | null | false |
https://api.github.com/repos/huggingface/datasets/issues/5315 | https://api.github.com/repos/huggingface/datasets | https://api.github.com/repos/huggingface/datasets/issues/5315/labels{/name} | https://api.github.com/repos/huggingface/datasets/issues/5315/comments | https://api.github.com/repos/huggingface/datasets/issues/5315/events | https://github.com/huggingface/datasets/issues/5315 | 1,470,026,797 | I_kwDODunzps5XntQt | 5,315 | Adding new splits to a dataset script with existing old splits info in metadata's `dataset_info` fails | {
"login": "polinaeterna",
"id": 16348744,
"node_id": "MDQ6VXNlcjE2MzQ4NzQ0",
"avatar_url": "https://avatars.githubusercontent.com/u/16348744?v=4",
"gravatar_id": "",
"url": "https://api.github.com/users/polinaeterna",
"html_url": "https://github.com/polinaeterna",
"followers_url": "https://api.github.c... | [
{
"id": 1935892857,
"node_id": "MDU6TGFiZWwxOTM1ODkyODU3",
"url": "https://api.github.com/repos/huggingface/datasets/labels/bug",
"name": "bug",
"color": "d73a4a",
"default": true,
"description": "Something isn't working",
"archived_at": null,
"archived_by": null
}
] | open | false | [
{
"login": "polinaeterna",
"id": 16348744,
"node_id": "MDQ6VXNlcjE2MzQ4NzQ0",
"avatar_url": "https://avatars.githubusercontent.com/u/16348744?v=4",
"gravatar_id": "",
"url": "https://api.github.com/users/polinaeterna",
"html_url": "https://github.com/polinaeterna",
"followers_url": "... | null | 3 | 2022-11-30T18:02:15 | 2022-12-02T07:02:53 | null | {
"login": "polinaeterna",
"id": 16348744,
"node_id": "MDQ6VXNlcjE2MzQ4NzQ0",
"avatar_url": "https://avatars.githubusercontent.com/u/16348744?v=4",
"gravatar_id": "",
"url": "https://api.github.com/users/polinaeterna",
"html_url": "https://github.com/polinaeterna",
"followers_url": "https://api.github.c... | CONTRIBUTOR | [] | null | null | null | null | ### Describe the bug
If you first create a custom dataset with a specific set of splits, generate metadata with `datasets-cli test ... --save_info`, then change your script to include more splits, it fails.
That's what happened in https://huggingface.co/datasets/mrdbourke/food_vision_199_classes/discussions/2#6385f... | null | {
"url": "https://api.github.com/repos/huggingface/datasets/issues/5315/reactions",
"total_count": 0,
"+1": 0,
"-1": 0,
"laugh": 0,
"hooray": 0,
"confused": 0,
"heart": 0,
"rocket": 0,
"eyes": 0
} | https://api.github.com/repos/huggingface/datasets/issues/5315/timeline | null | null | {
"total": 0,
"completed": 0,
"percent_completed": 0
} | {
"blocked_by": 0,
"total_blocked_by": 0,
"blocking": 0,
"total_blocking": 0
} | null | false |
https://api.github.com/repos/huggingface/datasets/issues/5314 | https://api.github.com/repos/huggingface/datasets | https://api.github.com/repos/huggingface/datasets/issues/5314/labels{/name} | https://api.github.com/repos/huggingface/datasets/issues/5314/comments | https://api.github.com/repos/huggingface/datasets/issues/5314/events | https://github.com/huggingface/datasets/issues/5314 | 1,469,685,118 | I_kwDODunzps5XmZ1- | 5,314 | Datasets: classification_report() got an unexpected keyword argument 'suffix' | {
"login": "JonathanAlis",
"id": 42126634,
"node_id": "MDQ6VXNlcjQyMTI2NjM0",
"avatar_url": "https://avatars.githubusercontent.com/u/42126634?v=4",
"gravatar_id": "",
"url": "https://api.github.com/users/JonathanAlis",
"html_url": "https://github.com/JonathanAlis",
"followers_url": "https://api.github.c... | [] | closed | false | [] | null | 2 | 2022-11-30T14:01:03 | 2023-07-21T14:40:31 | 2023-07-21T14:40:31 | null | NONE | [] | null | null | null | null | https://github.com/huggingface/datasets/blob/main/metrics/seqeval/seqeval.py
> import datasets
predictions = [['O', 'O', 'B-MISC', 'I-MISC', 'I-MISC', 'I-MISC', 'O'], ['B-PER', 'I-PER', 'O']]
references = [['O', 'O', 'O', 'B-MISC', 'I-MISC', 'I-MISC', 'O'], ['B-PER', 'I-PER', 'O']]
seqeval = datasets.load_metri... | {
"login": "mariosasko",
"id": 47462742,
"node_id": "MDQ6VXNlcjQ3NDYyNzQy",
"avatar_url": "https://avatars.githubusercontent.com/u/47462742?v=4",
"gravatar_id": "",
"url": "https://api.github.com/users/mariosasko",
"html_url": "https://github.com/mariosasko",
"followers_url": "https://api.github.com/use... | {
"url": "https://api.github.com/repos/huggingface/datasets/issues/5314/reactions",
"total_count": 0,
"+1": 0,
"-1": 0,
"laugh": 0,
"hooray": 0,
"confused": 0,
"heart": 0,
"rocket": 0,
"eyes": 0
} | https://api.github.com/repos/huggingface/datasets/issues/5314/timeline | null | completed | {
"total": 0,
"completed": 0,
"percent_completed": 0
} | {
"blocked_by": 0,
"total_blocked_by": 0,
"blocking": 0,
"total_blocking": 0
} | null | false |
https://api.github.com/repos/huggingface/datasets/issues/5313 | https://api.github.com/repos/huggingface/datasets | https://api.github.com/repos/huggingface/datasets/issues/5313/labels{/name} | https://api.github.com/repos/huggingface/datasets/issues/5313/comments | https://api.github.com/repos/huggingface/datasets/issues/5313/events | https://github.com/huggingface/datasets/pull/5313 | 1,468,484,136 | PR_kwDODunzps5D6Qfb | 5,313 | Fix description of streaming in the docs | {
"login": "polinaeterna",
"id": 16348744,
"node_id": "MDQ6VXNlcjE2MzQ4NzQ0",
"avatar_url": "https://avatars.githubusercontent.com/u/16348744?v=4",
"gravatar_id": "",
"url": "https://api.github.com/users/polinaeterna",
"html_url": "https://github.com/polinaeterna",
"followers_url": "https://api.github.c... | [] | closed | false | [] | null | 1 | 2022-11-29T18:00:28 | 2022-12-01T14:55:30 | 2022-12-01T14:00:34 | null | CONTRIBUTOR | [] | null | null | false | {
"url": "https://api.github.com/repos/huggingface/datasets/pulls/5313",
"html_url": "https://github.com/huggingface/datasets/pull/5313",
"diff_url": "https://github.com/huggingface/datasets/pull/5313.diff",
"patch_url": "https://github.com/huggingface/datasets/pull/5313.patch",
"merged_at": "2022-12-01T14:00... | We say that "the data is being downloaded progressively" which is not true, it's just streamed, so I fixed it. Probably I missed some other places where it is written?
Also changed docstrings for `StreamingDownloadManager`'s `download` and `extract` to reflect the same, as these docstrings are displayed in the docu... | {
"login": "polinaeterna",
"id": 16348744,
"node_id": "MDQ6VXNlcjE2MzQ4NzQ0",
"avatar_url": "https://avatars.githubusercontent.com/u/16348744?v=4",
"gravatar_id": "",
"url": "https://api.github.com/users/polinaeterna",
"html_url": "https://github.com/polinaeterna",
"followers_url": "https://api.github.c... | {
"url": "https://api.github.com/repos/huggingface/datasets/issues/5313/reactions",
"total_count": 0,
"+1": 0,
"-1": 0,
"laugh": 0,
"hooray": 0,
"confused": 0,
"heart": 0,
"rocket": 0,
"eyes": 0
} | https://api.github.com/repos/huggingface/datasets/issues/5313/timeline | null | null | null | null | null | true |
https://api.github.com/repos/huggingface/datasets/issues/5312 | https://api.github.com/repos/huggingface/datasets | https://api.github.com/repos/huggingface/datasets/issues/5312/labels{/name} | https://api.github.com/repos/huggingface/datasets/issues/5312/comments | https://api.github.com/repos/huggingface/datasets/issues/5312/events | https://github.com/huggingface/datasets/pull/5312 | 1,468,352,562 | PR_kwDODunzps5D5zxI | 5,312 | Add DatasetDict.to_pandas | {
"login": "lhoestq",
"id": 42851186,
"node_id": "MDQ6VXNlcjQyODUxMTg2",
"avatar_url": "https://avatars.githubusercontent.com/u/42851186?v=4",
"gravatar_id": "",
"url": "https://api.github.com/users/lhoestq",
"html_url": "https://github.com/lhoestq",
"followers_url": "https://api.github.com/users/lhoest... | [] | closed | false | [] | null | 12 | 2022-11-29T16:30:02 | 2023-09-24T10:06:19 | 2023-01-25T17:33:42 | null | MEMBER | [] | null | null | false | {
"url": "https://api.github.com/repos/huggingface/datasets/pulls/5312",
"html_url": "https://github.com/huggingface/datasets/pull/5312",
"diff_url": "https://github.com/huggingface/datasets/pull/5312.diff",
"patch_url": "https://github.com/huggingface/datasets/pull/5312.patch",
"merged_at": null
} | From discussions in https://github.com/huggingface/datasets/issues/5189, for tabular data it doesn't really make sense to have to do
```python
df = load_dataset(...)["train"].to_pandas()
```
because many datasets are not split.
In this PR I added `to_pandas` to `DatasetDict` which returns the DataFrame:
If th... | {
"login": "lhoestq",
"id": 42851186,
"node_id": "MDQ6VXNlcjQyODUxMTg2",
"avatar_url": "https://avatars.githubusercontent.com/u/42851186?v=4",
"gravatar_id": "",
"url": "https://api.github.com/users/lhoestq",
"html_url": "https://github.com/lhoestq",
"followers_url": "https://api.github.com/users/lhoest... | {
"url": "https://api.github.com/repos/huggingface/datasets/issues/5312/reactions",
"total_count": 1,
"+1": 1,
"-1": 0,
"laugh": 0,
"hooray": 0,
"confused": 0,
"heart": 0,
"rocket": 0,
"eyes": 0
} | https://api.github.com/repos/huggingface/datasets/issues/5312/timeline | null | null | null | null | null | true |
https://api.github.com/repos/huggingface/datasets/issues/5311 | https://api.github.com/repos/huggingface/datasets | https://api.github.com/repos/huggingface/datasets/issues/5311/labels{/name} | https://api.github.com/repos/huggingface/datasets/issues/5311/comments | https://api.github.com/repos/huggingface/datasets/issues/5311/events | https://github.com/huggingface/datasets/pull/5311 | 1,467,875,153 | PR_kwDODunzps5D4Mm3 | 5,311 | Add `features` param to `IterableDataset.map` | {
"login": "alvarobartt",
"id": 36760800,
"node_id": "MDQ6VXNlcjM2NzYwODAw",
"avatar_url": "https://avatars.githubusercontent.com/u/36760800?v=4",
"gravatar_id": "",
"url": "https://api.github.com/users/alvarobartt",
"html_url": "https://github.com/alvarobartt",
"followers_url": "https://api.github.com/... | [] | closed | false | [] | null | 1 | 2022-11-29T11:08:34 | 2022-12-06T15:45:02 | 2022-12-06T15:42:04 | null | MEMBER | [] | null | null | false | {
"url": "https://api.github.com/repos/huggingface/datasets/pulls/5311",
"html_url": "https://github.com/huggingface/datasets/pull/5311",
"diff_url": "https://github.com/huggingface/datasets/pull/5311.diff",
"patch_url": "https://github.com/huggingface/datasets/pull/5311.patch",
"merged_at": "2022-12-06T15:42... | ## Description
As suggested by @lhoestq in #3888, we should be adding the param `features` to `IterableDataset.map` so that the features can be preserved (not turned into `None` as that's the default behavior) whenever the user passes those as param, so as to be consistent with `Dataset.map`, as it provides the `fea... | {
"login": "lhoestq",
"id": 42851186,
"node_id": "MDQ6VXNlcjQyODUxMTg2",
"avatar_url": "https://avatars.githubusercontent.com/u/42851186?v=4",
"gravatar_id": "",
"url": "https://api.github.com/users/lhoestq",
"html_url": "https://github.com/lhoestq",
"followers_url": "https://api.github.com/users/lhoest... | {
"url": "https://api.github.com/repos/huggingface/datasets/issues/5311/reactions",
"total_count": 0,
"+1": 0,
"-1": 0,
"laugh": 0,
"hooray": 0,
"confused": 0,
"heart": 0,
"rocket": 0,
"eyes": 0
} | https://api.github.com/repos/huggingface/datasets/issues/5311/timeline | null | null | null | null | null | true |
https://api.github.com/repos/huggingface/datasets/issues/5310 | https://api.github.com/repos/huggingface/datasets | https://api.github.com/repos/huggingface/datasets/issues/5310/labels{/name} | https://api.github.com/repos/huggingface/datasets/issues/5310/comments | https://api.github.com/repos/huggingface/datasets/issues/5310/events | https://github.com/huggingface/datasets/pull/5310 | 1,467,719,635 | PR_kwDODunzps5D3rGw | 5,310 | Support xPath for Windows pathnames | {
"login": "albertvillanova",
"id": 8515462,
"node_id": "MDQ6VXNlcjg1MTU0NjI=",
"avatar_url": "https://avatars.githubusercontent.com/u/8515462?v=4",
"gravatar_id": "",
"url": "https://api.github.com/users/albertvillanova",
"html_url": "https://github.com/albertvillanova",
"followers_url": "https://api.g... | [] | closed | false | [] | null | 1 | 2022-11-29T09:20:47 | 2022-11-30T12:00:09 | 2022-11-30T11:57:16 | null | MEMBER | [] | null | null | false | {
"url": "https://api.github.com/repos/huggingface/datasets/pulls/5310",
"html_url": "https://github.com/huggingface/datasets/pull/5310",
"diff_url": "https://github.com/huggingface/datasets/pull/5310.diff",
"patch_url": "https://github.com/huggingface/datasets/pull/5310.patch",
"merged_at": "2022-11-30T11:57... | This PR implements a string representation of `xPath`, which is valid for local paths (also windows) and remote URLs.
Additionally, some `os.path` methods are fixed for remote URLs on Windows machines.
Now, on Windows machines:
```python
In [2]: str(xPath("C:\\dir\\file.txt"))
Out[2]: 'C:\\dir\\file.txt'
In [... | {
"login": "albertvillanova",
"id": 8515462,
"node_id": "MDQ6VXNlcjg1MTU0NjI=",
"avatar_url": "https://avatars.githubusercontent.com/u/8515462?v=4",
"gravatar_id": "",
"url": "https://api.github.com/users/albertvillanova",
"html_url": "https://github.com/albertvillanova",
"followers_url": "https://api.g... | {
"url": "https://api.github.com/repos/huggingface/datasets/issues/5310/reactions",
"total_count": 0,
"+1": 0,
"-1": 0,
"laugh": 0,
"hooray": 0,
"confused": 0,
"heart": 0,
"rocket": 0,
"eyes": 0
} | https://api.github.com/repos/huggingface/datasets/issues/5310/timeline | null | null | null | null | null | true |
https://api.github.com/repos/huggingface/datasets/issues/5309 | https://api.github.com/repos/huggingface/datasets | https://api.github.com/repos/huggingface/datasets/issues/5309/labels{/name} | https://api.github.com/repos/huggingface/datasets/issues/5309/comments | https://api.github.com/repos/huggingface/datasets/issues/5309/events | https://github.com/huggingface/datasets/pull/5309 | 1,466,758,987 | PR_kwDODunzps5D0g1y | 5,309 | Close stream in `ArrowWriter.finalize` before inference error | {
"login": "mariosasko",
"id": 47462742,
"node_id": "MDQ6VXNlcjQ3NDYyNzQy",
"avatar_url": "https://avatars.githubusercontent.com/u/47462742?v=4",
"gravatar_id": "",
"url": "https://api.github.com/users/mariosasko",
"html_url": "https://github.com/mariosasko",
"followers_url": "https://api.github.com/use... | [] | closed | false | [] | null | 1 | 2022-11-28T16:59:39 | 2022-12-07T12:55:20 | 2022-12-07T12:52:15 | null | COLLABORATOR | [] | null | null | false | {
"url": "https://api.github.com/repos/huggingface/datasets/pulls/5309",
"html_url": "https://github.com/huggingface/datasets/pull/5309",
"diff_url": "https://github.com/huggingface/datasets/pull/5309.diff",
"patch_url": "https://github.com/huggingface/datasets/pull/5309.patch",
"merged_at": "2022-12-07T12:52... | Ensure the file stream is closed in `ArrowWriter.finalize` before raising the `SchemaInferenceError` to avoid the `PermissionError` on Windows in `incomplete_dir`'s `shutil.rmtree`. | {
"login": "mariosasko",
"id": 47462742,
"node_id": "MDQ6VXNlcjQ3NDYyNzQy",
"avatar_url": "https://avatars.githubusercontent.com/u/47462742?v=4",
"gravatar_id": "",
"url": "https://api.github.com/users/mariosasko",
"html_url": "https://github.com/mariosasko",
"followers_url": "https://api.github.com/use... | {
"url": "https://api.github.com/repos/huggingface/datasets/issues/5309/reactions",
"total_count": 0,
"+1": 0,
"-1": 0,
"laugh": 0,
"hooray": 0,
"confused": 0,
"heart": 0,
"rocket": 0,
"eyes": 0
} | https://api.github.com/repos/huggingface/datasets/issues/5309/timeline | null | null | null | null | null | true |
https://api.github.com/repos/huggingface/datasets/issues/5308 | https://api.github.com/repos/huggingface/datasets | https://api.github.com/repos/huggingface/datasets/issues/5308/labels{/name} | https://api.github.com/repos/huggingface/datasets/issues/5308/comments | https://api.github.com/repos/huggingface/datasets/issues/5308/events | https://github.com/huggingface/datasets/pull/5308 | 1,466,552,281 | PR_kwDODunzps5Dz0Tv | 5,308 | Support `topdown` parameter in `xwalk` | {
"login": "mariosasko",
"id": 47462742,
"node_id": "MDQ6VXNlcjQ3NDYyNzQy",
"avatar_url": "https://avatars.githubusercontent.com/u/47462742?v=4",
"gravatar_id": "",
"url": "https://api.github.com/users/mariosasko",
"html_url": "https://github.com/mariosasko",
"followers_url": "https://api.github.com/use... | [] | closed | false | [] | null | 2 | 2022-11-28T14:42:41 | 2022-12-09T12:58:55 | 2022-12-09T12:55:59 | null | COLLABORATOR | [] | null | null | false | {
"url": "https://api.github.com/repos/huggingface/datasets/pulls/5308",
"html_url": "https://github.com/huggingface/datasets/pull/5308",
"diff_url": "https://github.com/huggingface/datasets/pull/5308.diff",
"patch_url": "https://github.com/huggingface/datasets/pull/5308.patch",
"merged_at": "2022-12-09T12:55... | Add support for the `topdown` parameter in `xwalk` when `fsspec>=2022.11.0` is installed. | {
"login": "mariosasko",
"id": 47462742,
"node_id": "MDQ6VXNlcjQ3NDYyNzQy",
"avatar_url": "https://avatars.githubusercontent.com/u/47462742?v=4",
"gravatar_id": "",
"url": "https://api.github.com/users/mariosasko",
"html_url": "https://github.com/mariosasko",
"followers_url": "https://api.github.com/use... | {
"url": "https://api.github.com/repos/huggingface/datasets/issues/5308/reactions",
"total_count": 0,
"+1": 0,
"-1": 0,
"laugh": 0,
"hooray": 0,
"confused": 0,
"heart": 0,
"rocket": 0,
"eyes": 0
} | https://api.github.com/repos/huggingface/datasets/issues/5308/timeline | null | null | null | null | null | true |
https://api.github.com/repos/huggingface/datasets/issues/5307 | https://api.github.com/repos/huggingface/datasets | https://api.github.com/repos/huggingface/datasets/issues/5307/labels{/name} | https://api.github.com/repos/huggingface/datasets/issues/5307/comments | https://api.github.com/repos/huggingface/datasets/issues/5307/events | https://github.com/huggingface/datasets/pull/5307 | 1,466,477,427 | PR_kwDODunzps5Dzj8r | 5,307 | Use correct dataset type in `from_generator` docs | {
"login": "mariosasko",
"id": 47462742,
"node_id": "MDQ6VXNlcjQ3NDYyNzQy",
"avatar_url": "https://avatars.githubusercontent.com/u/47462742?v=4",
"gravatar_id": "",
"url": "https://api.github.com/users/mariosasko",
"html_url": "https://github.com/mariosasko",
"followers_url": "https://api.github.com/use... | [] | closed | false | [] | null | 1 | 2022-11-28T13:59:10 | 2022-11-28T15:30:37 | 2022-11-28T15:27:26 | null | COLLABORATOR | [] | null | null | false | {
"url": "https://api.github.com/repos/huggingface/datasets/pulls/5307",
"html_url": "https://github.com/huggingface/datasets/pull/5307",
"diff_url": "https://github.com/huggingface/datasets/pull/5307.diff",
"patch_url": "https://github.com/huggingface/datasets/pull/5307.patch",
"merged_at": "2022-11-28T15:27... | Use the correct dataset type in the `from_generator` docs (example with sharding). | {
"login": "mariosasko",
"id": 47462742,
"node_id": "MDQ6VXNlcjQ3NDYyNzQy",
"avatar_url": "https://avatars.githubusercontent.com/u/47462742?v=4",
"gravatar_id": "",
"url": "https://api.github.com/users/mariosasko",
"html_url": "https://github.com/mariosasko",
"followers_url": "https://api.github.com/use... | {
"url": "https://api.github.com/repos/huggingface/datasets/issues/5307/reactions",
"total_count": 0,
"+1": 0,
"-1": 0,
"laugh": 0,
"hooray": 0,
"confused": 0,
"heart": 0,
"rocket": 0,
"eyes": 0
} | https://api.github.com/repos/huggingface/datasets/issues/5307/timeline | null | null | null | null | null | true |
https://api.github.com/repos/huggingface/datasets/issues/5306 | https://api.github.com/repos/huggingface/datasets | https://api.github.com/repos/huggingface/datasets/issues/5306/labels{/name} | https://api.github.com/repos/huggingface/datasets/issues/5306/comments | https://api.github.com/repos/huggingface/datasets/issues/5306/events | https://github.com/huggingface/datasets/issues/5306 | 1,465,968,639 | I_kwDODunzps5XYOf_ | 5,306 | Can't use custom feature description when loading a dataset | {
"login": "clefourrier",
"id": 22726840,
"node_id": "MDQ6VXNlcjIyNzI2ODQw",
"avatar_url": "https://avatars.githubusercontent.com/u/22726840?v=4",
"gravatar_id": "",
"url": "https://api.github.com/users/clefourrier",
"html_url": "https://github.com/clefourrier",
"followers_url": "https://api.github.com/... | [] | closed | false | [] | null | 1 | 2022-11-28T07:55:44 | 2022-11-28T08:11:45 | 2022-11-28T08:11:44 | null | MEMBER | [] | null | null | null | null | ### Describe the bug
I have created a feature dictionary to describe my datasets' column types, to use when loading the dataset, following [the doc](https://huggingface.co/docs/datasets/main/en/about_dataset_features). It crashes at dataset load.
### Steps to reproduce the bug
```python
# Creating features
task_... | {
"login": "clefourrier",
"id": 22726840,
"node_id": "MDQ6VXNlcjIyNzI2ODQw",
"avatar_url": "https://avatars.githubusercontent.com/u/22726840?v=4",
"gravatar_id": "",
"url": "https://api.github.com/users/clefourrier",
"html_url": "https://github.com/clefourrier",
"followers_url": "https://api.github.com/... | {
"url": "https://api.github.com/repos/huggingface/datasets/issues/5306/reactions",
"total_count": 0,
"+1": 0,
"-1": 0,
"laugh": 0,
"hooray": 0,
"confused": 0,
"heart": 0,
"rocket": 0,
"eyes": 0
} | https://api.github.com/repos/huggingface/datasets/issues/5306/timeline | null | completed | {
"total": 0,
"completed": 0,
"percent_completed": 0
} | {
"blocked_by": 0,
"total_blocked_by": 0,
"blocking": 0,
"total_blocking": 0
} | null | false |
https://api.github.com/repos/huggingface/datasets/issues/5305 | https://api.github.com/repos/huggingface/datasets | https://api.github.com/repos/huggingface/datasets/issues/5305/labels{/name} | https://api.github.com/repos/huggingface/datasets/issues/5305/comments | https://api.github.com/repos/huggingface/datasets/issues/5305/events | https://github.com/huggingface/datasets/issues/5305 | 1,465,627,826 | I_kwDODunzps5XW7Sy | 5,305 | Dataset joelito/mc4_legal does not work with multiple files | {
"login": "JoelNiklaus",
"id": 3775944,
"node_id": "MDQ6VXNlcjM3NzU5NDQ=",
"avatar_url": "https://avatars.githubusercontent.com/u/3775944?v=4",
"gravatar_id": "",
"url": "https://api.github.com/users/JoelNiklaus",
"html_url": "https://github.com/JoelNiklaus",
"followers_url": "https://api.github.com/us... | [] | closed | false | [
{
"login": "albertvillanova",
"id": 8515462,
"node_id": "MDQ6VXNlcjg1MTU0NjI=",
"avatar_url": "https://avatars.githubusercontent.com/u/8515462?v=4",
"gravatar_id": "",
"url": "https://api.github.com/users/albertvillanova",
"html_url": "https://github.com/albertvillanova",
"followers_... | null | 2 | 2022-11-28T00:16:16 | 2022-11-28T07:22:42 | 2022-11-28T07:22:42 | {
"login": "albertvillanova",
"id": 8515462,
"node_id": "MDQ6VXNlcjg1MTU0NjI=",
"avatar_url": "https://avatars.githubusercontent.com/u/8515462?v=4",
"gravatar_id": "",
"url": "https://api.github.com/users/albertvillanova",
"html_url": "https://github.com/albertvillanova",
"followers_url": "https://api.g... | CONTRIBUTOR | [] | null | null | null | null | ### Describe the bug
The dataset https://huggingface.co/datasets/joelito/mc4_legal works for languages like bg with a single data file, but not for languages with multiple files like de. It shows zero rows for the de dataset.
joelniklaus@Joels-MacBook-Pro ~/N/P/C/L/p/m/mc4_legal (main) [1]> python test_mc4_legal.... | {
"login": "albertvillanova",
"id": 8515462,
"node_id": "MDQ6VXNlcjg1MTU0NjI=",
"avatar_url": "https://avatars.githubusercontent.com/u/8515462?v=4",
"gravatar_id": "",
"url": "https://api.github.com/users/albertvillanova",
"html_url": "https://github.com/albertvillanova",
"followers_url": "https://api.g... | {
"url": "https://api.github.com/repos/huggingface/datasets/issues/5305/reactions",
"total_count": 0,
"+1": 0,
"-1": 0,
"laugh": 0,
"hooray": 0,
"confused": 0,
"heart": 0,
"rocket": 0,
"eyes": 0
} | https://api.github.com/repos/huggingface/datasets/issues/5305/timeline | null | completed | {
"total": 0,
"completed": 0,
"percent_completed": 0
} | {
"blocked_by": 0,
"total_blocked_by": 0,
"blocking": 0,
"total_blocking": 0
} | null | false |
https://api.github.com/repos/huggingface/datasets/issues/5304 | https://api.github.com/repos/huggingface/datasets | https://api.github.com/repos/huggingface/datasets/issues/5304/labels{/name} | https://api.github.com/repos/huggingface/datasets/issues/5304/comments | https://api.github.com/repos/huggingface/datasets/issues/5304/events | https://github.com/huggingface/datasets/issues/5304 | 1,465,110,367 | I_kwDODunzps5XU89f | 5,304 | timit_asr doesn't load the test split. | {
"login": "seyong92",
"id": 17842800,
"node_id": "MDQ6VXNlcjE3ODQyODAw",
"avatar_url": "https://avatars.githubusercontent.com/u/17842800?v=4",
"gravatar_id": "",
"url": "https://api.github.com/users/seyong92",
"html_url": "https://github.com/seyong92",
"followers_url": "https://api.github.com/users/sey... | [] | closed | false | [] | null | 1 | 2022-11-26T10:18:22 | 2023-02-10T16:33:21 | 2023-02-10T16:33:21 | null | NONE | [] | null | null | null | null | ### Describe the bug
When I use the function ```timit = load_dataset('timit_asr', data_dir=data_dir)```, it only loads train split, not test split.
I tried to change the directory and filename to lower case to upper case for the test split, but it does not work at all.
```python
DatasetDict({
train: Datase... | {
"login": "mariosasko",
"id": 47462742,
"node_id": "MDQ6VXNlcjQ3NDYyNzQy",
"avatar_url": "https://avatars.githubusercontent.com/u/47462742?v=4",
"gravatar_id": "",
"url": "https://api.github.com/users/mariosasko",
"html_url": "https://github.com/mariosasko",
"followers_url": "https://api.github.com/use... | {
"url": "https://api.github.com/repos/huggingface/datasets/issues/5304/reactions",
"total_count": 0,
"+1": 0,
"-1": 0,
"laugh": 0,
"hooray": 0,
"confused": 0,
"heart": 0,
"rocket": 0,
"eyes": 0
} | https://api.github.com/repos/huggingface/datasets/issues/5304/timeline | null | completed | {
"total": 0,
"completed": 0,
"percent_completed": 0
} | {
"blocked_by": 0,
"total_blocked_by": 0,
"blocking": 0,
"total_blocking": 0
} | null | false |
https://api.github.com/repos/huggingface/datasets/issues/5303 | https://api.github.com/repos/huggingface/datasets | https://api.github.com/repos/huggingface/datasets/issues/5303/labels{/name} | https://api.github.com/repos/huggingface/datasets/issues/5303/comments | https://api.github.com/repos/huggingface/datasets/issues/5303/events | https://github.com/huggingface/datasets/pull/5303 | 1,464,837,251 | PR_kwDODunzps5DuVTa | 5,303 | Skip dataset verifications by default | {
"login": "mariosasko",
"id": 47462742,
"node_id": "MDQ6VXNlcjQ3NDYyNzQy",
"avatar_url": "https://avatars.githubusercontent.com/u/47462742?v=4",
"gravatar_id": "",
"url": "https://api.github.com/users/mariosasko",
"html_url": "https://github.com/mariosasko",
"followers_url": "https://api.github.com/use... | [] | closed | false | [] | null | 17 | 2022-11-25T18:39:09 | 2023-02-13T16:50:42 | 2023-02-13T16:43:47 | null | COLLABORATOR | [] | null | null | false | {
"url": "https://api.github.com/repos/huggingface/datasets/pulls/5303",
"html_url": "https://github.com/huggingface/datasets/pull/5303",
"diff_url": "https://github.com/huggingface/datasets/pull/5303.diff",
"patch_url": "https://github.com/huggingface/datasets/pull/5303.patch",
"merged_at": "2023-02-13T16:43... | Skip the dataset verifications (split and checksum verifications, duplicate keys check) by default unless a dataset is being tested (`datasets-cli test/run_beam`). The main goal is to avoid running the checksum check in the default case due to how expensive it can be for large datasets.
PS: Maybe we should deprecate... | {
"login": "mariosasko",
"id": 47462742,
"node_id": "MDQ6VXNlcjQ3NDYyNzQy",
"avatar_url": "https://avatars.githubusercontent.com/u/47462742?v=4",
"gravatar_id": "",
"url": "https://api.github.com/users/mariosasko",
"html_url": "https://github.com/mariosasko",
"followers_url": "https://api.github.com/use... | {
"url": "https://api.github.com/repos/huggingface/datasets/issues/5303/reactions",
"total_count": 3,
"+1": 3,
"-1": 0,
"laugh": 0,
"hooray": 0,
"confused": 0,
"heart": 0,
"rocket": 0,
"eyes": 0
} | https://api.github.com/repos/huggingface/datasets/issues/5303/timeline | null | null | null | null | null | true |
https://api.github.com/repos/huggingface/datasets/issues/5302 | https://api.github.com/repos/huggingface/datasets | https://api.github.com/repos/huggingface/datasets/issues/5302/labels{/name} | https://api.github.com/repos/huggingface/datasets/issues/5302/comments | https://api.github.com/repos/huggingface/datasets/issues/5302/events | https://github.com/huggingface/datasets/pull/5302 | 1,464,778,901 | PR_kwDODunzps5DuJJp | 5,302 | Improve `use_auth_token` docstring and deprecate `use_auth_token` in `download_and_prepare` | {
"login": "mariosasko",
"id": 47462742,
"node_id": "MDQ6VXNlcjQ3NDYyNzQy",
"avatar_url": "https://avatars.githubusercontent.com/u/47462742?v=4",
"gravatar_id": "",
"url": "https://api.github.com/users/mariosasko",
"html_url": "https://github.com/mariosasko",
"followers_url": "https://api.github.com/use... | [] | closed | false | [] | null | 1 | 2022-11-25T17:09:21 | 2022-12-09T14:20:15 | 2022-12-09T14:17:20 | null | COLLABORATOR | [] | null | null | false | {
"url": "https://api.github.com/repos/huggingface/datasets/pulls/5302",
"html_url": "https://github.com/huggingface/datasets/pull/5302",
"diff_url": "https://github.com/huggingface/datasets/pull/5302.diff",
"patch_url": "https://github.com/huggingface/datasets/pull/5302.patch",
"merged_at": "2022-12-09T14:17... | Clarify in the docstrings what happens when `use_auth_token` is `None` and deprecate the `use_auth_token` param in `download_and_prepare`. | {
"login": "mariosasko",
"id": 47462742,
"node_id": "MDQ6VXNlcjQ3NDYyNzQy",
"avatar_url": "https://avatars.githubusercontent.com/u/47462742?v=4",
"gravatar_id": "",
"url": "https://api.github.com/users/mariosasko",
"html_url": "https://github.com/mariosasko",
"followers_url": "https://api.github.com/use... | {
"url": "https://api.github.com/repos/huggingface/datasets/issues/5302/reactions",
"total_count": 0,
"+1": 0,
"-1": 0,
"laugh": 0,
"hooray": 0,
"confused": 0,
"heart": 0,
"rocket": 0,
"eyes": 0
} | https://api.github.com/repos/huggingface/datasets/issues/5302/timeline | null | null | null | null | null | true |
https://api.github.com/repos/huggingface/datasets/issues/5301 | https://api.github.com/repos/huggingface/datasets | https://api.github.com/repos/huggingface/datasets/issues/5301/labels{/name} | https://api.github.com/repos/huggingface/datasets/issues/5301/comments | https://api.github.com/repos/huggingface/datasets/issues/5301/events | https://github.com/huggingface/datasets/pull/5301 | 1,464,749,156 | PR_kwDODunzps5DuCzR | 5,301 | Return a split Dataset in load_dataset | {
"login": "lhoestq",
"id": 42851186,
"node_id": "MDQ6VXNlcjQyODUxMTg2",
"avatar_url": "https://avatars.githubusercontent.com/u/42851186?v=4",
"gravatar_id": "",
"url": "https://api.github.com/users/lhoestq",
"html_url": "https://github.com/lhoestq",
"followers_url": "https://api.github.com/users/lhoest... | [] | closed | false | [] | null | 2 | 2022-11-25T16:35:54 | 2023-09-24T10:06:15 | 2023-02-21T13:13:13 | null | MEMBER | [] | null | null | true | {
"url": "https://api.github.com/repos/huggingface/datasets/pulls/5301",
"html_url": "https://github.com/huggingface/datasets/pull/5301",
"diff_url": "https://github.com/huggingface/datasets/pull/5301.diff",
"patch_url": "https://github.com/huggingface/datasets/pull/5301.patch",
"merged_at": null
} | ...instead of a DatasetDict.
```python
# now supported
ds = load_dataset("squad")
ds[0]
for example in ds:
pass
# still works
ds["train"]
ds["validation"]
# new
ds.splits # Dict[str, Dataset] | None
# soon to be supported (not in this PR)
ds = load_dataset("dataset_with_no_splits")
ds[0]
f... | {
"login": "lhoestq",
"id": 42851186,
"node_id": "MDQ6VXNlcjQyODUxMTg2",
"avatar_url": "https://avatars.githubusercontent.com/u/42851186?v=4",
"gravatar_id": "",
"url": "https://api.github.com/users/lhoestq",
"html_url": "https://github.com/lhoestq",
"followers_url": "https://api.github.com/users/lhoest... | {
"url": "https://api.github.com/repos/huggingface/datasets/issues/5301/reactions",
"total_count": 1,
"+1": 0,
"-1": 0,
"laugh": 0,
"hooray": 0,
"confused": 0,
"heart": 1,
"rocket": 0,
"eyes": 0
} | https://api.github.com/repos/huggingface/datasets/issues/5301/timeline | null | null | null | null | null | true |
https://api.github.com/repos/huggingface/datasets/issues/5300 | https://api.github.com/repos/huggingface/datasets | https://api.github.com/repos/huggingface/datasets/issues/5300/labels{/name} | https://api.github.com/repos/huggingface/datasets/issues/5300/comments | https://api.github.com/repos/huggingface/datasets/issues/5300/events | https://github.com/huggingface/datasets/pull/5300 | 1,464,697,136 | PR_kwDODunzps5Dt3uK | 5,300 | Use same `num_proc` for dataset download and generation | {
"login": "mariosasko",
"id": 47462742,
"node_id": "MDQ6VXNlcjQ3NDYyNzQy",
"avatar_url": "https://avatars.githubusercontent.com/u/47462742?v=4",
"gravatar_id": "",
"url": "https://api.github.com/users/mariosasko",
"html_url": "https://github.com/mariosasko",
"followers_url": "https://api.github.com/use... | [] | closed | false | [] | null | 2 | 2022-11-25T15:37:42 | 2022-12-07T12:55:39 | 2022-12-07T12:52:51 | null | COLLABORATOR | [] | null | null | false | {
"url": "https://api.github.com/repos/huggingface/datasets/pulls/5300",
"html_url": "https://github.com/huggingface/datasets/pull/5300",
"diff_url": "https://github.com/huggingface/datasets/pull/5300.diff",
"patch_url": "https://github.com/huggingface/datasets/pull/5300.patch",
"merged_at": "2022-12-07T12:52... | Use the same `num_proc` value for data download and generation. Additionally, do not set `num_proc` to 16 in `DownloadManager` by default (`num_proc` now has to be specified explicitly). | {
"login": "mariosasko",
"id": 47462742,
"node_id": "MDQ6VXNlcjQ3NDYyNzQy",
"avatar_url": "https://avatars.githubusercontent.com/u/47462742?v=4",
"gravatar_id": "",
"url": "https://api.github.com/users/mariosasko",
"html_url": "https://github.com/mariosasko",
"followers_url": "https://api.github.com/use... | {
"url": "https://api.github.com/repos/huggingface/datasets/issues/5300/reactions",
"total_count": 1,
"+1": 1,
"-1": 0,
"laugh": 0,
"hooray": 0,
"confused": 0,
"heart": 0,
"rocket": 0,
"eyes": 0
} | https://api.github.com/repos/huggingface/datasets/issues/5300/timeline | null | null | null | null | null | true |
https://api.github.com/repos/huggingface/datasets/issues/5299 | https://api.github.com/repos/huggingface/datasets | https://api.github.com/repos/huggingface/datasets/issues/5299/labels{/name} | https://api.github.com/repos/huggingface/datasets/issues/5299/comments | https://api.github.com/repos/huggingface/datasets/issues/5299/events | https://github.com/huggingface/datasets/pull/5299 | 1,464,695,091 | PR_kwDODunzps5Dt3Sk | 5,299 | Fix xopen for Windows pathnames | {
"login": "albertvillanova",
"id": 8515462,
"node_id": "MDQ6VXNlcjg1MTU0NjI=",
"avatar_url": "https://avatars.githubusercontent.com/u/8515462?v=4",
"gravatar_id": "",
"url": "https://api.github.com/users/albertvillanova",
"html_url": "https://github.com/albertvillanova",
"followers_url": "https://api.g... | [] | closed | false | [] | null | 1 | 2022-11-25T15:35:28 | 2022-11-29T08:23:58 | 2022-11-29T08:21:24 | null | MEMBER | [] | null | null | false | {
"url": "https://api.github.com/repos/huggingface/datasets/pulls/5299",
"html_url": "https://github.com/huggingface/datasets/pull/5299",
"diff_url": "https://github.com/huggingface/datasets/pull/5299.diff",
"patch_url": "https://github.com/huggingface/datasets/pull/5299.patch",
"merged_at": "2022-11-29T08:21... | This PR fixes a bug in `xopen` function for Windows pathnames.
Fix #5298. | {
"login": "albertvillanova",
"id": 8515462,
"node_id": "MDQ6VXNlcjg1MTU0NjI=",
"avatar_url": "https://avatars.githubusercontent.com/u/8515462?v=4",
"gravatar_id": "",
"url": "https://api.github.com/users/albertvillanova",
"html_url": "https://github.com/albertvillanova",
"followers_url": "https://api.g... | {
"url": "https://api.github.com/repos/huggingface/datasets/issues/5299/reactions",
"total_count": 0,
"+1": 0,
"-1": 0,
"laugh": 0,
"hooray": 0,
"confused": 0,
"heart": 0,
"rocket": 0,
"eyes": 0
} | https://api.github.com/repos/huggingface/datasets/issues/5299/timeline | null | null | null | null | null | true |
https://api.github.com/repos/huggingface/datasets/issues/5298 | https://api.github.com/repos/huggingface/datasets | https://api.github.com/repos/huggingface/datasets/issues/5298/labels{/name} | https://api.github.com/repos/huggingface/datasets/issues/5298/comments | https://api.github.com/repos/huggingface/datasets/issues/5298/events | https://github.com/huggingface/datasets/issues/5298 | 1,464,681,871 | I_kwDODunzps5XTUWP | 5,298 | Bug in xopen with Windows pathnames | {
"login": "albertvillanova",
"id": 8515462,
"node_id": "MDQ6VXNlcjg1MTU0NjI=",
"avatar_url": "https://avatars.githubusercontent.com/u/8515462?v=4",
"gravatar_id": "",
"url": "https://api.github.com/users/albertvillanova",
"html_url": "https://github.com/albertvillanova",
"followers_url": "https://api.g... | [
{
"id": 1935892857,
"node_id": "MDU6TGFiZWwxOTM1ODkyODU3",
"url": "https://api.github.com/repos/huggingface/datasets/labels/bug",
"name": "bug",
"color": "d73a4a",
"default": true,
"description": "Something isn't working",
"archived_at": null,
"archived_by": null
}
] | closed | false | [
{
"login": "albertvillanova",
"id": 8515462,
"node_id": "MDQ6VXNlcjg1MTU0NjI=",
"avatar_url": "https://avatars.githubusercontent.com/u/8515462?v=4",
"gravatar_id": "",
"url": "https://api.github.com/users/albertvillanova",
"html_url": "https://github.com/albertvillanova",
"followers_... | null | 0 | 2022-11-25T15:21:32 | 2022-11-29T08:21:25 | 2022-11-29T08:21:25 | {
"login": "albertvillanova",
"id": 8515462,
"node_id": "MDQ6VXNlcjg1MTU0NjI=",
"avatar_url": "https://avatars.githubusercontent.com/u/8515462?v=4",
"gravatar_id": "",
"url": "https://api.github.com/users/albertvillanova",
"html_url": "https://github.com/albertvillanova",
"followers_url": "https://api.g... | MEMBER | [] | null | null | null | null | Currently, `xopen` function has a bug with local Windows pathnames:
From its implementation:
```python
def xopen(file: str, mode="r", *args, **kwargs):
file = _as_posix(PurePath(file))
main_hop, *rest_hops = file.split("::")
if is_local_path(main_hop):
return open(file, mode, *args, **kwarg... | {
"login": "albertvillanova",
"id": 8515462,
"node_id": "MDQ6VXNlcjg1MTU0NjI=",
"avatar_url": "https://avatars.githubusercontent.com/u/8515462?v=4",
"gravatar_id": "",
"url": "https://api.github.com/users/albertvillanova",
"html_url": "https://github.com/albertvillanova",
"followers_url": "https://api.g... | {
"url": "https://api.github.com/repos/huggingface/datasets/issues/5298/reactions",
"total_count": 0,
"+1": 0,
"-1": 0,
"laugh": 0,
"hooray": 0,
"confused": 0,
"heart": 0,
"rocket": 0,
"eyes": 0
} | https://api.github.com/repos/huggingface/datasets/issues/5298/timeline | null | completed | {
"total": 0,
"completed": 0,
"percent_completed": 0
} | {
"blocked_by": 0,
"total_blocked_by": 0,
"blocking": 0,
"total_blocking": 0
} | null | false |
https://api.github.com/repos/huggingface/datasets/issues/5297 | https://api.github.com/repos/huggingface/datasets | https://api.github.com/repos/huggingface/datasets/issues/5297/labels{/name} | https://api.github.com/repos/huggingface/datasets/issues/5297/comments | https://api.github.com/repos/huggingface/datasets/issues/5297/events | https://github.com/huggingface/datasets/pull/5297 | 1,464,554,491 | PR_kwDODunzps5DtZjg | 5,297 | Fix xjoin for Windows pathnames | {
"login": "albertvillanova",
"id": 8515462,
"node_id": "MDQ6VXNlcjg1MTU0NjI=",
"avatar_url": "https://avatars.githubusercontent.com/u/8515462?v=4",
"gravatar_id": "",
"url": "https://api.github.com/users/albertvillanova",
"html_url": "https://github.com/albertvillanova",
"followers_url": "https://api.g... | [] | closed | false | [] | null | 1 | 2022-11-25T13:30:17 | 2022-11-29T08:07:39 | 2022-11-29T08:05:12 | null | MEMBER | [] | null | null | false | {
"url": "https://api.github.com/repos/huggingface/datasets/pulls/5297",
"html_url": "https://github.com/huggingface/datasets/pull/5297",
"diff_url": "https://github.com/huggingface/datasets/pull/5297.diff",
"patch_url": "https://github.com/huggingface/datasets/pull/5297.patch",
"merged_at": "2022-11-29T08:05... | This PR fixes a bug in `xjoin` function with Windows pathnames.
Fix #5296. | {
"login": "albertvillanova",
"id": 8515462,
"node_id": "MDQ6VXNlcjg1MTU0NjI=",
"avatar_url": "https://avatars.githubusercontent.com/u/8515462?v=4",
"gravatar_id": "",
"url": "https://api.github.com/users/albertvillanova",
"html_url": "https://github.com/albertvillanova",
"followers_url": "https://api.g... | {
"url": "https://api.github.com/repos/huggingface/datasets/issues/5297/reactions",
"total_count": 0,
"+1": 0,
"-1": 0,
"laugh": 0,
"hooray": 0,
"confused": 0,
"heart": 0,
"rocket": 0,
"eyes": 0
} | https://api.github.com/repos/huggingface/datasets/issues/5297/timeline | null | null | null | null | null | true |
https://api.github.com/repos/huggingface/datasets/issues/5296 | https://api.github.com/repos/huggingface/datasets | https://api.github.com/repos/huggingface/datasets/issues/5296/labels{/name} | https://api.github.com/repos/huggingface/datasets/issues/5296/comments | https://api.github.com/repos/huggingface/datasets/issues/5296/events | https://github.com/huggingface/datasets/issues/5296 | 1,464,553,580 | I_kwDODunzps5XS1Bs | 5,296 | Bug in xjoin with Windows pathnames | {
"login": "albertvillanova",
"id": 8515462,
"node_id": "MDQ6VXNlcjg1MTU0NjI=",
"avatar_url": "https://avatars.githubusercontent.com/u/8515462?v=4",
"gravatar_id": "",
"url": "https://api.github.com/users/albertvillanova",
"html_url": "https://github.com/albertvillanova",
"followers_url": "https://api.g... | [
{
"id": 1935892857,
"node_id": "MDU6TGFiZWwxOTM1ODkyODU3",
"url": "https://api.github.com/repos/huggingface/datasets/labels/bug",
"name": "bug",
"color": "d73a4a",
"default": true,
"description": "Something isn't working",
"archived_at": null,
"archived_by": null
}
] | closed | false | [
{
"login": "albertvillanova",
"id": 8515462,
"node_id": "MDQ6VXNlcjg1MTU0NjI=",
"avatar_url": "https://avatars.githubusercontent.com/u/8515462?v=4",
"gravatar_id": "",
"url": "https://api.github.com/users/albertvillanova",
"html_url": "https://github.com/albertvillanova",
"followers_... | null | 0 | 2022-11-25T13:29:33 | 2022-11-29T08:05:13 | 2022-11-29T08:05:13 | {
"login": "albertvillanova",
"id": 8515462,
"node_id": "MDQ6VXNlcjg1MTU0NjI=",
"avatar_url": "https://avatars.githubusercontent.com/u/8515462?v=4",
"gravatar_id": "",
"url": "https://api.github.com/users/albertvillanova",
"html_url": "https://github.com/albertvillanova",
"followers_url": "https://api.g... | MEMBER | [] | null | null | null | null | Currently, `xjoin` function has a bug with local Windows pathnames: instead of returning the OS-dependent join pathname, it always returns it in POSIX format.
```python
from datasets.download.streaming_download_manager import xjoin
path = xjoin("C:\\Users\\USERNAME", "filename.txt")
```
Join path should be:
... | {
"login": "albertvillanova",
"id": 8515462,
"node_id": "MDQ6VXNlcjg1MTU0NjI=",
"avatar_url": "https://avatars.githubusercontent.com/u/8515462?v=4",
"gravatar_id": "",
"url": "https://api.github.com/users/albertvillanova",
"html_url": "https://github.com/albertvillanova",
"followers_url": "https://api.g... | {
"url": "https://api.github.com/repos/huggingface/datasets/issues/5296/reactions",
"total_count": 0,
"+1": 0,
"-1": 0,
"laugh": 0,
"hooray": 0,
"confused": 0,
"heart": 0,
"rocket": 0,
"eyes": 0
} | https://api.github.com/repos/huggingface/datasets/issues/5296/timeline | null | completed | {
"total": 0,
"completed": 0,
"percent_completed": 0
} | {
"blocked_by": 0,
"total_blocked_by": 0,
"blocking": 0,
"total_blocking": 0
} | null | false |
https://api.github.com/repos/huggingface/datasets/issues/5295 | https://api.github.com/repos/huggingface/datasets | https://api.github.com/repos/huggingface/datasets/issues/5295/labels{/name} | https://api.github.com/repos/huggingface/datasets/issues/5295/comments | https://api.github.com/repos/huggingface/datasets/issues/5295/events | https://github.com/huggingface/datasets/issues/5295 | 1,464,006,743 | I_kwDODunzps5XQvhX | 5,295 | Extractions failed when .zip file located on read-only path (e.g., SageMaker FastFile mode) | {
"login": "verdimrc",
"id": 2340781,
"node_id": "MDQ6VXNlcjIzNDA3ODE=",
"avatar_url": "https://avatars.githubusercontent.com/u/2340781?v=4",
"gravatar_id": "",
"url": "https://api.github.com/users/verdimrc",
"html_url": "https://github.com/verdimrc",
"followers_url": "https://api.github.com/users/verdi... | [] | closed | false | [
{
"login": "lhoestq",
"id": 42851186,
"node_id": "MDQ6VXNlcjQyODUxMTg2",
"avatar_url": "https://avatars.githubusercontent.com/u/42851186?v=4",
"gravatar_id": "",
"url": "https://api.github.com/users/lhoestq",
"html_url": "https://github.com/lhoestq",
"followers_url": "https://api.git... | null | 2 | 2022-11-25T03:59:43 | 2023-07-21T14:39:09 | 2023-07-21T14:39:09 | {
"login": "lhoestq",
"id": 42851186,
"node_id": "MDQ6VXNlcjQyODUxMTg2",
"avatar_url": "https://avatars.githubusercontent.com/u/42851186?v=4",
"gravatar_id": "",
"url": "https://api.github.com/users/lhoestq",
"html_url": "https://github.com/lhoestq",
"followers_url": "https://api.github.com/users/lhoest... | NONE | [] | null | null | null | null | ### Describe the bug
Hi,
`load_dataset()` does not work .zip files located on a read-only directory. Looks like it's because Dataset creates a lock file in the [same directory](https://github.com/huggingface/datasets/blob/df4bdd365f2abb695f113cbf8856a925bc70901b/src/datasets/utils/extract.py) as the .zip file.
... | {
"login": "mariosasko",
"id": 47462742,
"node_id": "MDQ6VXNlcjQ3NDYyNzQy",
"avatar_url": "https://avatars.githubusercontent.com/u/47462742?v=4",
"gravatar_id": "",
"url": "https://api.github.com/users/mariosasko",
"html_url": "https://github.com/mariosasko",
"followers_url": "https://api.github.com/use... | {
"url": "https://api.github.com/repos/huggingface/datasets/issues/5295/reactions",
"total_count": 0,
"+1": 0,
"-1": 0,
"laugh": 0,
"hooray": 0,
"confused": 0,
"heart": 0,
"rocket": 0,
"eyes": 0
} | https://api.github.com/repos/huggingface/datasets/issues/5295/timeline | null | completed | {
"total": 0,
"completed": 0,
"percent_completed": 0
} | {
"blocked_by": 0,
"total_blocked_by": 0,
"blocking": 0,
"total_blocking": 0
} | null | false |
https://api.github.com/repos/huggingface/datasets/issues/5294 | https://api.github.com/repos/huggingface/datasets | https://api.github.com/repos/huggingface/datasets/issues/5294/labels{/name} | https://api.github.com/repos/huggingface/datasets/issues/5294/comments | https://api.github.com/repos/huggingface/datasets/issues/5294/events | https://github.com/huggingface/datasets/pull/5294 | 1,463,679,582 | PR_kwDODunzps5DqgLW | 5,294 | Support streaming datasets with pathlib.Path.with_suffix | {
"login": "albertvillanova",
"id": 8515462,
"node_id": "MDQ6VXNlcjg1MTU0NjI=",
"avatar_url": "https://avatars.githubusercontent.com/u/8515462?v=4",
"gravatar_id": "",
"url": "https://api.github.com/users/albertvillanova",
"html_url": "https://github.com/albertvillanova",
"followers_url": "https://api.g... | [] | closed | false | [] | null | 1 | 2022-11-24T18:04:38 | 2022-11-29T07:09:08 | 2022-11-29T07:06:32 | null | MEMBER | [] | null | null | false | {
"url": "https://api.github.com/repos/huggingface/datasets/pulls/5294",
"html_url": "https://github.com/huggingface/datasets/pull/5294",
"diff_url": "https://github.com/huggingface/datasets/pull/5294.diff",
"patch_url": "https://github.com/huggingface/datasets/pull/5294.patch",
"merged_at": "2022-11-29T07:06... | This PR extends the support in streaming mode for datasets that use `pathlib.Path.with_suffix`.
Fix #5293. | {
"login": "albertvillanova",
"id": 8515462,
"node_id": "MDQ6VXNlcjg1MTU0NjI=",
"avatar_url": "https://avatars.githubusercontent.com/u/8515462?v=4",
"gravatar_id": "",
"url": "https://api.github.com/users/albertvillanova",
"html_url": "https://github.com/albertvillanova",
"followers_url": "https://api.g... | {
"url": "https://api.github.com/repos/huggingface/datasets/issues/5294/reactions",
"total_count": 0,
"+1": 0,
"-1": 0,
"laugh": 0,
"hooray": 0,
"confused": 0,
"heart": 0,
"rocket": 0,
"eyes": 0
} | https://api.github.com/repos/huggingface/datasets/issues/5294/timeline | null | null | null | null | null | true |
https://api.github.com/repos/huggingface/datasets/issues/5293 | https://api.github.com/repos/huggingface/datasets | https://api.github.com/repos/huggingface/datasets/issues/5293/labels{/name} | https://api.github.com/repos/huggingface/datasets/issues/5293/comments | https://api.github.com/repos/huggingface/datasets/issues/5293/events | https://github.com/huggingface/datasets/issues/5293 | 1,463,669,201 | I_kwDODunzps5XPdHR | 5,293 | Support streaming datasets with pathlib.Path.with_suffix | {
"login": "albertvillanova",
"id": 8515462,
"node_id": "MDQ6VXNlcjg1MTU0NjI=",
"avatar_url": "https://avatars.githubusercontent.com/u/8515462?v=4",
"gravatar_id": "",
"url": "https://api.github.com/users/albertvillanova",
"html_url": "https://github.com/albertvillanova",
"followers_url": "https://api.g... | [
{
"id": 1935892871,
"node_id": "MDU6TGFiZWwxOTM1ODkyODcx",
"url": "https://api.github.com/repos/huggingface/datasets/labels/enhancement",
"name": "enhancement",
"color": "a2eeef",
"default": true,
"description": "New feature or request",
"archived_at": null,
"archived_by": null
... | closed | false | [
{
"login": "albertvillanova",
"id": 8515462,
"node_id": "MDQ6VXNlcjg1MTU0NjI=",
"avatar_url": "https://avatars.githubusercontent.com/u/8515462?v=4",
"gravatar_id": "",
"url": "https://api.github.com/users/albertvillanova",
"html_url": "https://github.com/albertvillanova",
"followers_... | null | 0 | 2022-11-24T17:52:08 | 2022-11-29T07:06:33 | 2022-11-29T07:06:33 | {
"login": "albertvillanova",
"id": 8515462,
"node_id": "MDQ6VXNlcjg1MTU0NjI=",
"avatar_url": "https://avatars.githubusercontent.com/u/8515462?v=4",
"gravatar_id": "",
"url": "https://api.github.com/users/albertvillanova",
"html_url": "https://github.com/albertvillanova",
"followers_url": "https://api.g... | MEMBER | [] | null | null | null | null | Extend support for streaming datasets that use `pathlib.Path.with_suffix`.
This feature will be useful e.g. for datasets containing text files and annotated files with the same name but different extension. | {
"login": "albertvillanova",
"id": 8515462,
"node_id": "MDQ6VXNlcjg1MTU0NjI=",
"avatar_url": "https://avatars.githubusercontent.com/u/8515462?v=4",
"gravatar_id": "",
"url": "https://api.github.com/users/albertvillanova",
"html_url": "https://github.com/albertvillanova",
"followers_url": "https://api.g... | {
"url": "https://api.github.com/repos/huggingface/datasets/issues/5293/reactions",
"total_count": 0,
"+1": 0,
"-1": 0,
"laugh": 0,
"hooray": 0,
"confused": 0,
"heart": 0,
"rocket": 0,
"eyes": 0
} | https://api.github.com/repos/huggingface/datasets/issues/5293/timeline | null | completed | {
"total": 0,
"completed": 0,
"percent_completed": 0
} | {
"blocked_by": 0,
"total_blocked_by": 0,
"blocking": 0,
"total_blocking": 0
} | null | false |
https://api.github.com/repos/huggingface/datasets/issues/5292 | https://api.github.com/repos/huggingface/datasets | https://api.github.com/repos/huggingface/datasets/issues/5292/labels{/name} | https://api.github.com/repos/huggingface/datasets/issues/5292/comments | https://api.github.com/repos/huggingface/datasets/issues/5292/events | https://github.com/huggingface/datasets/issues/5292 | 1,463,053,832 | I_kwDODunzps5XNG4I | 5,292 | Missing documentation build for versions 2.7.1 and 2.6.2 | {
"login": "albertvillanova",
"id": 8515462,
"node_id": "MDQ6VXNlcjg1MTU0NjI=",
"avatar_url": "https://avatars.githubusercontent.com/u/8515462?v=4",
"gravatar_id": "",
"url": "https://api.github.com/users/albertvillanova",
"html_url": "https://github.com/albertvillanova",
"followers_url": "https://api.g... | [
{
"id": 4296013012,
"node_id": "LA_kwDODunzps8AAAABAA_01A",
"url": "https://api.github.com/repos/huggingface/datasets/labels/maintenance",
"name": "maintenance",
"color": "d4c5f9",
"default": false,
"description": "Maintenance tasks",
"archived_at": null,
"archived_by": null
}
... | closed | false | [
{
"login": "albertvillanova",
"id": 8515462,
"node_id": "MDQ6VXNlcjg1MTU0NjI=",
"avatar_url": "https://avatars.githubusercontent.com/u/8515462?v=4",
"gravatar_id": "",
"url": "https://api.github.com/users/albertvillanova",
"html_url": "https://github.com/albertvillanova",
"followers_... | null | 1 | 2022-11-24T09:42:10 | 2022-11-24T10:10:02 | 2022-11-24T10:10:02 | {
"login": "albertvillanova",
"id": 8515462,
"node_id": "MDQ6VXNlcjg1MTU0NjI=",
"avatar_url": "https://avatars.githubusercontent.com/u/8515462?v=4",
"gravatar_id": "",
"url": "https://api.github.com/users/albertvillanova",
"html_url": "https://github.com/albertvillanova",
"followers_url": "https://api.g... | MEMBER | [] | null | null | null | null | After the patch releases [2.7.1](https://github.com/huggingface/datasets/releases/tag/2.7.1) and [2.6.2](https://github.com/huggingface/datasets/releases/tag/2.6.2), the online docs were not properly built (the build_documentation workflow was not triggered).
There was a fix by:
- #5291
However, both documentati... | {
"login": "albertvillanova",
"id": 8515462,
"node_id": "MDQ6VXNlcjg1MTU0NjI=",
"avatar_url": "https://avatars.githubusercontent.com/u/8515462?v=4",
"gravatar_id": "",
"url": "https://api.github.com/users/albertvillanova",
"html_url": "https://github.com/albertvillanova",
"followers_url": "https://api.g... | {
"url": "https://api.github.com/repos/huggingface/datasets/issues/5292/reactions",
"total_count": 0,
"+1": 0,
"-1": 0,
"laugh": 0,
"hooray": 0,
"confused": 0,
"heart": 0,
"rocket": 0,
"eyes": 0
} | https://api.github.com/repos/huggingface/datasets/issues/5292/timeline | null | completed | {
"total": 0,
"completed": 0,
"percent_completed": 0
} | {
"blocked_by": 0,
"total_blocked_by": 0,
"blocking": 0,
"total_blocking": 0
} | null | false |
https://api.github.com/repos/huggingface/datasets/issues/5291 | https://api.github.com/repos/huggingface/datasets | https://api.github.com/repos/huggingface/datasets/issues/5291/labels{/name} | https://api.github.com/repos/huggingface/datasets/issues/5291/comments | https://api.github.com/repos/huggingface/datasets/issues/5291/events | https://github.com/huggingface/datasets/pull/5291 | 1,462,983,472 | PR_kwDODunzps5DoKNC | 5,291 | [build doc] for v2.7.1 & v2.6.2 | {
"login": "mishig25",
"id": 11827707,
"node_id": "MDQ6VXNlcjExODI3NzA3",
"avatar_url": "https://avatars.githubusercontent.com/u/11827707?v=4",
"gravatar_id": "",
"url": "https://api.github.com/users/mishig25",
"html_url": "https://github.com/mishig25",
"followers_url": "https://api.github.com/users/mis... | [] | closed | false | [] | null | 2 | 2022-11-24T08:54:47 | 2022-11-24T09:14:10 | 2022-11-24T09:11:15 | null | NONE | [] | null | null | false | {
"url": "https://api.github.com/repos/huggingface/datasets/pulls/5291",
"html_url": "https://github.com/huggingface/datasets/pull/5291",
"diff_url": "https://github.com/huggingface/datasets/pull/5291.diff",
"patch_url": "https://github.com/huggingface/datasets/pull/5291.patch",
"merged_at": null
} | Do NOT merge. Using this PR to build docs for [v2.7.1](https://github.com/huggingface/datasets/pull/5291/commits/f4914af20700f611b9331a9e3ba34743bbeff934) & [v2.6.2](https://github.com/huggingface/datasets/pull/5291/commits/025f85300a0874eeb90a20393c62f25ac0accaa0) | {
"login": "mishig25",
"id": 11827707,
"node_id": "MDQ6VXNlcjExODI3NzA3",
"avatar_url": "https://avatars.githubusercontent.com/u/11827707?v=4",
"gravatar_id": "",
"url": "https://api.github.com/users/mishig25",
"html_url": "https://github.com/mishig25",
"followers_url": "https://api.github.com/users/mis... | {
"url": "https://api.github.com/repos/huggingface/datasets/issues/5291/reactions",
"total_count": 0,
"+1": 0,
"-1": 0,
"laugh": 0,
"hooray": 0,
"confused": 0,
"heart": 0,
"rocket": 0,
"eyes": 0
} | https://api.github.com/repos/huggingface/datasets/issues/5291/timeline | null | null | null | null | null | true |
https://api.github.com/repos/huggingface/datasets/issues/5290 | https://api.github.com/repos/huggingface/datasets | https://api.github.com/repos/huggingface/datasets/issues/5290/labels{/name} | https://api.github.com/repos/huggingface/datasets/issues/5290/comments | https://api.github.com/repos/huggingface/datasets/issues/5290/events | https://github.com/huggingface/datasets/pull/5290 | 1,462,716,766 | PR_kwDODunzps5DnQsS | 5,290 | fix error where reading breaks when batch missing an assigned column feature | {
"login": "eunseojo",
"id": 12104720,
"node_id": "MDQ6VXNlcjEyMTA0NzIw",
"avatar_url": "https://avatars.githubusercontent.com/u/12104720?v=4",
"gravatar_id": "",
"url": "https://api.github.com/users/eunseojo",
"html_url": "https://github.com/eunseojo",
"followers_url": "https://api.github.com/users/eun... | [] | open | false | [] | null | 1 | 2022-11-24T03:53:46 | 2022-11-25T03:21:54 | null | null | CONTRIBUTOR | [] | null | null | false | {
"url": "https://api.github.com/repos/huggingface/datasets/pulls/5290",
"html_url": "https://github.com/huggingface/datasets/pull/5290",
"diff_url": "https://github.com/huggingface/datasets/pull/5290.diff",
"patch_url": "https://github.com/huggingface/datasets/pull/5290.patch",
"merged_at": null
} | null | null | {
"url": "https://api.github.com/repos/huggingface/datasets/issues/5290/reactions",
"total_count": 0,
"+1": 0,
"-1": 0,
"laugh": 0,
"hooray": 0,
"confused": 0,
"heart": 0,
"rocket": 0,
"eyes": 0
} | https://api.github.com/repos/huggingface/datasets/issues/5290/timeline | null | null | null | null | null | true |
https://api.github.com/repos/huggingface/datasets/issues/5289 | https://api.github.com/repos/huggingface/datasets | https://api.github.com/repos/huggingface/datasets/issues/5289/labels{/name} | https://api.github.com/repos/huggingface/datasets/issues/5289/comments | https://api.github.com/repos/huggingface/datasets/issues/5289/events | https://github.com/huggingface/datasets/pull/5289 | 1,462,543,139 | PR_kwDODunzps5Dmrk9 | 5,289 | Added support for JXL images. | {
"login": "alexjc",
"id": 445208,
"node_id": "MDQ6VXNlcjQ0NTIwOA==",
"avatar_url": "https://avatars.githubusercontent.com/u/445208?v=4",
"gravatar_id": "",
"url": "https://api.github.com/users/alexjc",
"html_url": "https://github.com/alexjc",
"followers_url": "https://api.github.com/users/alexjc/follow... | [] | open | false | [] | null | 12 | 2022-11-23T23:16:33 | 2026-08-30T11:59:18 | null | null | NONE | [] | null | null | false | {
"url": "https://api.github.com/repos/huggingface/datasets/pulls/5289",
"html_url": "https://github.com/huggingface/datasets/pull/5289",
"diff_url": "https://github.com/huggingface/datasets/pull/5289.diff",
"patch_url": "https://github.com/huggingface/datasets/pull/5289.patch",
"merged_at": null
} | JPEG-XL is the most advanced of the next-generation of image codecs, supporting both lossless and lossy files — with better compression and quality than PNG and JPG respectively. It has reduced the disk sizes and bandwidth required for many of the datasets I use.
Pillow does not yet support JXL, but there's a plugi... | null | {
"url": "https://api.github.com/repos/huggingface/datasets/issues/5289/reactions",
"total_count": 1,
"+1": 1,
"-1": 0,
"laugh": 0,
"hooray": 0,
"confused": 0,
"heart": 0,
"rocket": 0,
"eyes": 0
} | https://api.github.com/repos/huggingface/datasets/issues/5289/timeline | null | null | null | null | null | true |
https://api.github.com/repos/huggingface/datasets/issues/5288 | https://api.github.com/repos/huggingface/datasets | https://api.github.com/repos/huggingface/datasets/issues/5288/labels{/name} | https://api.github.com/repos/huggingface/datasets/issues/5288/comments | https://api.github.com/repos/huggingface/datasets/issues/5288/events | https://github.com/huggingface/datasets/issues/5288 | 1,462,134,067 | I_kwDODunzps5XJmUz | 5,288 | Lossy json serialization - deserialization of dataset info | {
"login": "anuragprat1k",
"id": 57542204,
"node_id": "MDQ6VXNlcjU3NTQyMjA0",
"avatar_url": "https://avatars.githubusercontent.com/u/57542204?v=4",
"gravatar_id": "",
"url": "https://api.github.com/users/anuragprat1k",
"html_url": "https://github.com/anuragprat1k",
"followers_url": "https://api.github.c... | [] | open | false | [] | null | 1 | 2022-11-23T17:20:15 | 2022-11-25T12:53:51 | null | null | NONE | [] | null | null | null | null | ### Describe the bug
Saving a dataset to disk as json (using `to_json`) and then loading it again (using `load_dataset`) results in features whose labels are not type-cast correctly. In the code snippet below, `features.label` should have a label of type `ClassLabel` but has type `Value` instead.
### Steps to re... | null | {
"url": "https://api.github.com/repos/huggingface/datasets/issues/5288/reactions",
"total_count": 0,
"+1": 0,
"-1": 0,
"laugh": 0,
"hooray": 0,
"confused": 0,
"heart": 0,
"rocket": 0,
"eyes": 0
} | https://api.github.com/repos/huggingface/datasets/issues/5288/timeline | null | null | {
"total": 0,
"completed": 0,
"percent_completed": 0
} | {
"blocked_by": 0,
"total_blocked_by": 0,
"blocking": 0,
"total_blocking": 0
} | null | false |
Subsets and Splits
No community queries yet
The top public SQL queries from the community will appear here once available.