
Datasets:
File size: 4,517 Bytes
bad0758 eb337ef 29b71f5 a3848c5 bad0758 6ca1075 bad0758 31d10e8 a3848c5 bad0758 a3848c5 bad0758 5afdc84 c40f9ee 5afdc84 | 1 2 3 4 5 6 7 8 9 10 11 12 13 14 15 16 17 18 19 20 21 22 23 24 25 26 27 28 29 30 31 32 33 34 35 36 37 38 39 40 41 42 43 44 45 46 47 48 49 50 51 52 53 54 55 56 57 58 59 60 61 62 63 64 65 66 67 68 69 70 71 72 73 74 75 76 77 78 79 80 81 82 83 84 85 86 87 88 89 90 91 92 93 94 95 96 97 98 99 100 101 102 103 104 105 106 107 108 109 110 111 112 113 114 115 116 117 118 119 120 121 122 123 | ---
license: cc-by-4.0
task_categories:
- text-classification
language:
- en
- multilingual
tags:
- research-intent
- golden-dataset
- openaire
pretty_name: Research Intent — Collaborative Golden Dataset
---
# Research Intent — Collaborative Golden Dataset
[](https://github.com/ethicalabs-ai/Echo-DSRN/)
[](https://opensource.org/licenses/Apache-2.0)
[](https://www.python.org/downloads/)
[](https://openaire-2026.ethicalabs.ai/)
[](https://innovation.openaire.eu/component/content/article/openaire-ai-hackathon.html)
[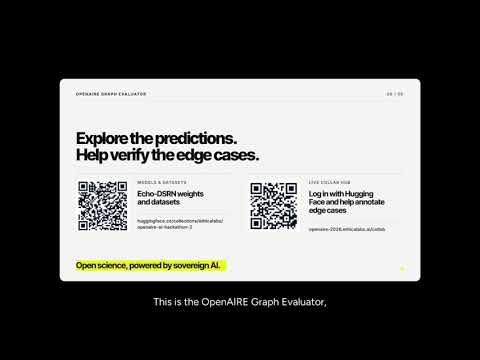](https://www.youtube.com/watch?v=9LHmmzLK3zs)
[**▶️ Watch the Video**](https://www.youtube.com/watch?v=9LHmmzLK3zs)
A curated, consensus-labelled dataset for research paper intent classification,
built from the LLM-as-Judge annotations of the Echo-DSRN collaborative platform
(OpenAIRE AI Hackathon 2026).
## OpenAIRE AI Hackathon 2026 🇪🇺
This dataset is part of **ethicalabs.ai**'s entry in the [OpenAIRE AI Hackathon 2026](https://innovation.openaire.eu/component/content/article/openaire-ai-hackathon.html), co-organised by OpenAIRE and Alien Intelligence — a 12-week open science build challenge.
**[🔴 Live Demo → openaire-2026.ethicalabs.ai](https://openaire-2026.ethicalabs.ai/)**
The live application classifies research papers in real time using this model, with publication metadata streamed from the [OpenAIRE Graph API](https://graph.openaire.eu) under **CC BY 4.0**.
---
## Labels
- **Methodology** — introduces a new algorithm, model architecture, or method
- **Dataset** — primarily contributes a new dataset, benchmark, or annotation scheme
- **Review** — survey, systematic review, or position paper
- **Applied** — applies existing methods to a domain problem
- **Theoretical** — mathematical or formal analysis
- **Unclassifiable** — garbled, non-English, or non-academic content
## Golden labelling
The golden label per paper is the **majority-vote consensus** across all
LLM judge models (plus human curator annotations where available). Papers
flagged as low-quality by **more than one** judge are labelled
**Unclassifiable** instead of being discarded — turning a quality filter into
a detection signal for non-academic content.
## Splits
The dataset ships with stratified `train` / `val` / `test` splits
(80/10/10). Stratification preserves the label distribution across splits,
with explicit safeguarding so the rare **Dataset** class (≈2% of records)
appears in every split.
## Data structure
Consensus label per paper — no ChatML messages and no judge rationale, so
consumers build their own training format from `title` + `description` +
`label`.
```json
{
"doi": "10.48550/arXiv.2106.01345",
"title": "...",
"description": "abstract text",
"label": "Dataset",
"flag_count": 0,
"model_votes": {
"Gemma-4-E4B-it-GGUF": "Dataset",
"Qwen3.5-4B-GGUF": "Methodology"
}
}
```
- `label` — the golden consensus label
- `flag_count` — number of judges that flagged quality issues
- `model_votes` — per-model predictions used for the consensus
> For ChatML conversation format with inline reasoning, see the companion
> dataset `ethicalabs/Research-Intent-Judge`.
## Files
- `golden_train.jsonl` — 7,999 records
- `golden_val.jsonl` — 1,001 records
- `golden_test.jsonl` — 1,001 records
- `golden_stats.json` — label distribution, split sizes, flag counts
## Provenance
Built from `ethicalabs/Research-Intent-Judge` via
`scripts/export_golden_dataset.py` in the
[OpenAIRE-AI-Research-Evaluator](https://github.com/ethicalabs-ai/OpenAIRE-AI-Research-Evaluator)
repository. Paper metadata originates from arXiv and the OpenAIRE Graph
(CC BY 4.0).
## License
CC-BY 4.0.
## Citation
If you reuse this work, please cite:
```bibtex
@software{echo_dsrn_research_intent_clf,
author = {Massimo Roberto Scamarcia},
title = {OpenAIRE Graph Evaluator: Research paper classifier and LLM-as-Judge pipeline},
year = {2026},
url = {https://huggingface.co/collections/ethicalabs/openaire-ai-hackathon-2026}
}
```
|