
repo_name stringlengths 9 75 | topic stringclasses 30
values | issue_number int64 1 203k | title stringlengths 1 976 | body stringlengths 0 254k | state stringclasses 2
values | created_at stringlengths 20 20 | updated_at stringlengths 20 20 | url stringlengths 38 105 | labels listlengths 0 9 | user_login stringlengths 1 39 | comments_count int64 0 452 |
|---|---|---|---|---|---|---|---|---|---|---|---|
fastapi-users/fastapi-users | fastapi | 1,221 | issue with 11.0 and safari | i changed your examples -> sqlalchemy to use cookie instead of jwt auth. users.py code likes following. two issues i found
1. i installed 11.0 using pip, the login always failed with 204. after i roll back to 10.4.2 the login works.
2. when i use safari Version 16.3 (18614.4.6.1.6) on mac ventura 13.2.1, after logi... | closed | 2023-05-29T05:51:54Z | 2023-05-29T07:04:46Z | https://github.com/fastapi-users/fastapi-users/issues/1221 | [] | wesleysanjose | 0 |
ultralytics/ultralytics | python | 19,671 | OOM (RAM not gpu) using DDP trainning | ### Search before asking
- [x] I have searched the Ultralytics YOLO [issues](https://github.com/ultralytics/ultralytics/issues) and found no similar bug report.
### Ultralytics YOLO Component
_No response_
### Bug
Hi,
sorry to bother again, But I'm facing a OOM problem in multi-gpu training. See this:
![Ima... | open | 2025-03-13T02:35:10Z | 2025-03-14T10:04:52Z | https://github.com/ultralytics/ultralytics/issues/19671 | [
"bug",
"devops"
] | wcyjerry | 7 |
feder-cr/Jobs_Applier_AI_Agent_AIHawk | automation | 891 | Does it really have to create a new resume every time apply? | ### Feature summary
_No response_
### Feature description
Does it really have to create a new resume every time apply? I don't think it is necessary. How can I turn that feature off? Thanks.
### Motivation
_No response_
### Alternatives considered
_No response_
### Additional context
_No response_ | closed | 2024-11-20T08:33:55Z | 2024-11-20T11:06:52Z | https://github.com/feder-cr/Jobs_Applier_AI_Agent_AIHawk/issues/891 | [
"enhancement"
] | mrtknrt | 0 |
iperov/DeepFaceLab | machine-learning | 5,212 | data_src faceset extract.bat not working | I have a bug that is blocking me to do the [ data_src faceset extract.bat ] process.
here is the error code : F tensorflow/core/common_runtime/gpu/gpu_util.cc:291] GPU->CPU Memcpy failed
but the [ data_dst faceset extract.bat ] works !
I have a RTX 2060 and a i5 9600kf (no intergrated graphics)
Thanks
and sor... | closed | 2020-12-23T17:16:04Z | 2021-02-28T17:11:19Z | https://github.com/iperov/DeepFaceLab/issues/5212 | [] | CherifBouabdallah | 2 |
CorentinJ/Real-Time-Voice-Cloning | python | 330 | Not detecting Librispeech dataset | I tried to preprocess synthesizer_audio. I have both train-clean-100 and 360 datasets loaded.
but i keep getting this result
`LibriSpeech: 100%|██████████████████| 1172/1172 [00:00<00:00, 3402.16speakers/s]
The dataset consists of 0 utterances, 0 mel frames, 0 audio timesteps (0.00 hours).
` | closed | 2020-04-24T11:20:46Z | 2020-07-04T17:46:32Z | https://github.com/CorentinJ/Real-Time-Voice-Cloning/issues/330 | [] | LostKin | 4 |
google-research/bert | nlp | 942 | Pre-Training BERT from scratch using Tokenized input file and custom vocabulary file for Khmer language | Hi!
I would like to know if it's possible for me to use tokenized/segmented documents as my input file to the `create_pretraining_data.py`. The main reason for this is because the segmentation/tokenization for the Khmer language is different than that of English.
```
Original:
វាមានមកជាមួយនូវ
Segmented:... | open | 2019-11-27T07:10:25Z | 2019-11-28T01:49:23Z | https://github.com/google-research/bert/issues/942 | [] | nikmuhammadnaim | 1 |
sherlock-project/sherlock | python | 2,299 | False positive for: Reddit (via AWS Lambda) | ### Additional info
Getting false positives for reddit on every search. Not sure what's going on, the error message
`Sorry, nobody on Reddit goes by that name.` appears to be correct
### Code of Conduct
- [X] I agree to follow this project's Code of Conduct | closed | 2024-09-21T20:39:29Z | 2024-09-21T21:28:47Z | https://github.com/sherlock-project/sherlock/issues/2299 | [
"false positive"
] | ReganBell | 0 |
aleju/imgaug | machine-learning | 223 | Make Rot90 direction clear | First off thanks so much for this tool! I think it's really helpful for preparing datasets.
I just wanted to mention something I found while working with the Rot90 augmenter. I was rotating my images with PIL and found that the direction of rotation was opposite. PIL rotates images counterclockwise (ROTATE_90 means ... | closed | 2018-12-29T08:01:32Z | 2019-01-06T14:34:54Z | https://github.com/aleju/imgaug/issues/223 | [
"TODO"
] | ck244 | 4 |
hzwer/ECCV2022-RIFE | computer-vision | 370 | 8FPS视频插帧后视频时长变短 | 作者你好,当我输入帧率为8的视频进行插帧处理后,视频时长会变短,例如输入8FPS时长2s的视频,插帧后变为16FPS时长1s的视频;输入8FPS时长3s的视频,插帧后变为16FPS时长2s的视频,请问这是因为什么原因呢 | closed | 2024-07-28T08:05:20Z | 2024-07-28T09:32:11Z | https://github.com/hzwer/ECCV2022-RIFE/issues/370 | [] | DX8906 | 0 |
CorentinJ/Real-Time-Voice-Cloning | pytorch | 560 | Error message keeps saying I need to download the pretrained models even though i already have? | 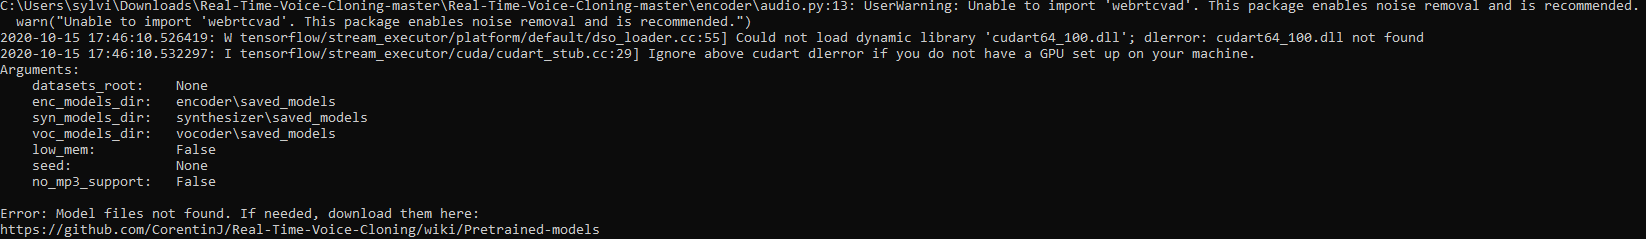
| closed | 2020-10-16T00:58:35Z | 2020-10-16T05:24:14Z | https://github.com/CorentinJ/Real-Time-Voice-Cloning/issues/560 | [] | icandancelikecool | 1 |
unit8co/darts | data-science | 2,440 | [Question] should old versions of pandas be taken into account in PR | When I make a pull request, new versions of Pandas are used for tests:
```
tests (macos-13, 3.9, all)
tests (ubuntu-latest, 3.9, all)
```
But when the merge happens, I see that they have old versions:
`tests (ubuntu-latest, 3.8, core) `
that show failures, like [here.](https://github.com/unit8co/darts/comm... | closed | 2024-07-02T12:23:53Z | 2024-07-03T10:55:38Z | https://github.com/unit8co/darts/issues/2440 | [] | quant12345 | 2 |
cvat-ai/cvat | pytorch | 9,139 | Error:”Cannot update the task “When I have created a task and want to assign the job to a user | who can help me!!!!! T T | closed | 2025-02-24T01:51:27Z | 2025-02-24T08:11:26Z | https://github.com/cvat-ai/cvat/issues/9139 | [] | kawamiovo | 1 |
Miksus/rocketry | automation | 230 | Exception Log | **Is your feature request related to a problem? Please describe.**
I want to access the class name separately from it's tracebrack when an exception occurs in logging.
**Describe the solution you'd like**
Pass Exception instance into `task_run` variable to access from `log_failure` method; for example Line **636**... | open | 2024-01-28T06:11:22Z | 2024-01-28T06:11:22Z | https://github.com/Miksus/rocketry/issues/230 | [
"enhancement"
] | SepehrBazyar | 0 |
lexiforest/curl_cffi | web-scraping | 333 | [BUG]不会自动进行url编码 | **Describe the bug**
curl_cffi在使用requests.get()时都不会将url中的特殊字符编码,Session().get()也一样,但requests库会自动进行编码。
**To Reproduce**
```
from curl_cffi.requests import get
from requests import get as request_get
proxy = {"http": "http://127.0.0.1:10809", "https": "http://127.0.0.1:10809"}
url = 'https://yande.re/post.json... | closed | 2024-06-30T12:35:30Z | 2024-08-03T06:25:41Z | https://github.com/lexiforest/curl_cffi/issues/333 | [
"bug"
] | ANewPassword | 2 |
strawberry-graphql/strawberry | fastapi | 3,198 | Integration of SQLAlchemy with Strawberry | Hello,
I have been working with Strawberry GraphQL for a while and I am enjoying the experience and the simplicity it brings to working with GraphQL in Python. I have a query regarding the integration of ORM tools, specifically SQLAlchemy, with Strawberry.
As many projects rely on SQLAlchemy for their database op... | closed | 2023-11-03T16:41:01Z | 2025-03-20T15:56:27Z | https://github.com/strawberry-graphql/strawberry/issues/3198 | [] | DeanNeaht | 2 |
HumanSignal/labelImg | deep-learning | 416 | How could I select the bounding hide by another bounding boxes | If there are many bounding boxes in the image, it is hard to edit the size of the bounding boxes unless I move the other bounding boxes away or delete them. Is it possible to tell the app I want to change the size of specific bounding box? Thanks | open | 2018-12-29T07:18:44Z | 2018-12-29T07:18:44Z | https://github.com/HumanSignal/labelImg/issues/416 | [] | stereomatchingkiss | 0 |
tensorpack/tensorpack | tensorflow | 904 | AttributeError: 'TrainLoop' object has no attribute 'starting_epoch' | The problem occurred when L318 below is executed if `stats is not None` (e.g. when you restore training from a log dir). The full error message is attached in the end.
https://github.com/tensorpack/tensorpack/blob/36b05bb71a498da3ea430c3a109cf9a9dddecbd8/tensorpack/callbacks/monitor.py#L309-L318
It can be seen `sel... | closed | 2018-09-21T10:04:49Z | 2018-09-21T20:14:52Z | https://github.com/tensorpack/tensorpack/issues/904 | [
"bug"
] | thuzhf | 1 |
jofpin/trape | flask | 68 | ip stay onlineafter reboot | the ip status stays online when the victim reboot his router and change his ip | open | 2018-11-25T21:20:18Z | 2018-11-25T21:20:18Z | https://github.com/jofpin/trape/issues/68 | [] | revdamage | 0 |
ClimbsRocks/auto_ml | scikit-learn | 198 | categorical ensemble: eventually, get weighted average of feature_importances_ | right now we don't have any great way of saying what's broadly important if we're training up 50k categories. sure, we'll print the analytics results for each of those categories, but that's not going to help us figure out what matters across all of it without a lot of manual looking.
but we should be able to get a... | open | 2017-04-05T21:43:12Z | 2017-04-05T21:43:12Z | https://github.com/ClimbsRocks/auto_ml/issues/198 | [] | ClimbsRocks | 0 |
aiortc/aiortc | asyncio | 706 | Buffer control for video delay / quality performance | Hi,
I have an application that uses aiortc to convert a RTSP video to webRTC and it works fine but i experience some delay in the video.
I know that for example in VLC i can see the video and change the "Caching" in order to avoid the buffering and reduce the delay.
I have checked some old issues to control ... | closed | 2022-04-25T10:30:36Z | 2022-04-25T11:18:17Z | https://github.com/aiortc/aiortc/issues/706 | [] | vcb1 | 0 |
Buuntu/fastapi-react | fastapi | 86 | [Feature Request] Add Storybook support | Any thoughts on adding [Storybook](https://storybook.js.org/) support as part of a development workflow? | closed | 2020-07-15T13:33:48Z | 2020-07-24T22:00:55Z | https://github.com/Buuntu/fastapi-react/issues/86 | [] | inactivist | 3 |
drivendataorg/erdantic | pydantic | 62 | Failed build on main branch (tests #209) | Workflow failed: [tests #209](https://github.com/drivendataorg/erdantic/actions/runs/2642826843)
| closed | 2022-07-10T00:13:25Z | 2025-03-19T20:17:43Z | https://github.com/drivendataorg/erdantic/issues/62 | [
"bug"
] | github-actions[bot] | 1 |
benbusby/whoogle-search | flask | 761 | "Open Links in New Tab" setting no longer working | It appears the "Open Links in New Tab" setting has stopped working recently. I use the Docker image at benbusby/whoogle-search:latest . In the benbusby/whoogle-search:0.7.2 image (built 21 days ago) this setting functions normally. | closed | 2022-05-17T22:51:35Z | 2022-05-25T17:37:34Z | https://github.com/benbusby/whoogle-search/issues/761 | [] | ras07 | 2 |
aminalaee/sqladmin | fastapi | 726 | Not able to edit fields in sql admin when using s3 filetype | ### Checklist
- [X] The bug is reproducible against the latest release or `master`.
- [X] There are no similar issues or pull requests to fix it yet.
### Describe the bug
Hey,
I raised the earlier in fastapi-storages as well.
So i am not able to edit other fields when i saved a entry in my table with column being ... | closed | 2024-03-11T10:27:59Z | 2024-10-03T15:10:53Z | https://github.com/aminalaee/sqladmin/issues/726 | [] | Shauryadhaka | 4 |
python-restx/flask-restx | flask | 123 | Improve configuration docs | In response to a recent issue, I've started a dedicated documentation page for the configuration options supported by Flask-RESTX https://github.com/python-restx/flask-restx/commit/990bd355e17d6c7111e745df8763da80265cd50d . Most of these are documented *somewhere*, however it would be beneficial for users if these were... | closed | 2020-04-21T19:00:19Z | 2020-05-08T09:06:17Z | https://github.com/python-restx/flask-restx/issues/123 | [
"documentation"
] | SteadBytes | 9 |
Miksus/rocketry | pydantic | 203 | ENH - Downtime recovery (persistance, crash recovery, process restart) | **Is your feature request related to a problem? Please describe.**
We use schedulers in production systems. During the patching operations (or any other downtime of the server), the schedulers are shutted down. Consider the following scenario:
- 08:03: the task "X" runs according to the schedule `daily between 08:0... | open | 2023-06-07T06:11:23Z | 2023-06-07T06:14:18Z | https://github.com/Miksus/rocketry/issues/203 | [
"enhancement"
] | Leikt | 0 |
ydataai/ydata-profiling | pandas | 1,313 | index -9223372036854775808 is out of bounds for axis 0 with size 2 | ### Current Behaviour
IndexError Traceback (most recent call last)
<ipython-input-34-c0d0834d8e2d> in <module>
----> 1 profile_report.get_description()
~/anaconda3/envs/py3.7/lib/python3.7/site-packages/typeguard/__init__.py in wrapper(*args, **kwargs)
1031 memo = _CallM... | open | 2023-04-18T02:46:42Z | 2023-05-08T17:00:33Z | https://github.com/ydataai/ydata-profiling/issues/1313 | [
"question/discussion ❓"
] | zhoujianch | 1 |
sammchardy/python-binance | api | 1,430 | python 3.7,python-binance latest, simple example report this error in china | (<class 'requests.exceptions.ProxyError'>, ProxyError(MaxRetryError("HTTPSConnectionPool(host='api.binance.com', port=443): Max retries exceeded with url: /api/v3/ping (Caused by ProxyError('Unable to connect to proxy', FileNotFoundError(2, 'No such file or directory')))")), <traceback object at 0x000001FC7BA6A188>)
... | closed | 2024-10-13T06:28:12Z | 2024-10-23T22:11:21Z | https://github.com/sammchardy/python-binance/issues/1430 | [
"question"
] | mingmingshiliyu | 2 |
deezer/spleeter | tensorflow | 748 | 2.9.2 Unable to find python.exe | when i select the python path, it said: "Unable to find python.exe".
my python path: D:\Python_3_9_12
my email: frankienul@163.com | closed | 2022-04-13T06:13:51Z | 2022-04-13T09:57:55Z | https://github.com/deezer/spleeter/issues/748 | [
"bug",
"invalid"
] | Frankienul | 1 |
vitalik/django-ninja | django | 798 | How to use OneToMany and ManyToMany for data query and insertion | ```Python
class Group(models.Model):
id = models.UUIDField(primary_key=True, default=uuid.uuid4, editable=False)
name = models.TextField(null=True, blank=True, )
created_at = models.DateTimeField(auto_now_add=True)
updated_at = models.DateTimeField(auto_now=True)
class user(models.Model):
i... | open | 2023-07-19T18:01:48Z | 2023-07-20T07:13:38Z | https://github.com/vitalik/django-ninja/issues/798 | [] | MaxwellEdisons | 4 |
plotly/dash | plotly | 2,552 | provide control item that allows selecting and ordering options | Like sortable lists in Ag Grid:
https://github.com/plotly/dash/assets/101562106/e35dcbbc-e6d3-436e-9bac-67edbabb2e4f
**Code for video app:**
app.py
```
import dash_ag_grid as dag
from dash import dcc, html, Input, Output, State, Dash, ctx, callback
import pandas as pd
import dash
app = Dash(__name__)
... | open | 2023-05-31T11:39:09Z | 2024-08-13T19:33:43Z | https://github.com/plotly/dash/issues/2552 | [
"feature",
"P3"
] | celia-lm | 0 |
ymcui/Chinese-LLaMA-Alpaca-2 | nlp | 522 | “基座模型”和“指令模型”该怎么使用? | ### 提交前必须检查以下项目
- [X] 请确保使用的是仓库最新代码(git pull),一些问题已被解决和修复。
- [X] 我已阅读[项目文档](https://github.com/ymcui/Chinese-LLaMA-Alpaca-2/wiki)和[FAQ章节](https://github.com/ymcui/Chinese-LLaMA-Alpaca-2/wiki/常见问题)并且已在Issue中对问题进行了搜索,没有找到相似问题和解决方案。
- [X] 第三方插件问题:例如[llama.cpp](https://github.com/ggerganov/llama.cpp)、[LangChain](https://g... | closed | 2024-02-06T06:04:26Z | 2024-02-06T06:13:36Z | https://github.com/ymcui/Chinese-LLaMA-Alpaca-2/issues/522 | [] | kgdxpr | 1 |
apify/crawlee-python | web-scraping | 145 | Resolve incorrect handling of configuration overrides in pydantic | https://github.com/pydantic/pydantic-settings/issues/180 - we probably want to make the sources in [`_settings_build_values`](https://github.com/pydantic/pydantic-settings/blob/8c5a45e43cca4e88a6d65fcb280529499fc6200a/pydantic_settings/main.py#L146) convert the keys to field names from aliases in case `populate_by_name... | open | 2024-05-09T13:15:05Z | 2024-05-09T13:15:05Z | https://github.com/apify/crawlee-python/issues/145 | [
"t-tooling"
] | janbuchar | 0 |
microsoft/MMdnn | tensorflow | 831 | tensorflow to caffe, reshape layer | Platform (like ubuntu 16.04/win10):
ubuntu 16.04
Python version:
3.5.5
Source framework with version (like Tensorflow 1.4.1 with GPU):
tensorflow
Destination framework with version (like CNTK 2.3 with GPU):
caffe
Pre-trained model path (webpath or webdisk path):
Running scripts:
Hello
I have a questi... | open | 2020-05-07T02:02:23Z | 2020-05-13T01:32:48Z | https://github.com/microsoft/MMdnn/issues/831 | [] | hnuhchen | 6 |
horovod/horovod | tensorflow | 3,664 | Tensorflow horovod distributed training on a100 mig error | **Environment:**
1. Framework: (TensorFlow)
2. Framework version: 1.15.4
3. Horovod version: 0.20.2
4. MPI version: 4.0.5
5. CUDA version:11.1
6. NCCL version:
7. Python version: 3.6
8. Spark / PySpark version:
9. Ray version:
10. OS and version:
11. GCC version:
12. CMake version:
**Bug report:**
Horov... | open | 2022-08-23T07:18:53Z | 2022-08-23T07:37:48Z | https://github.com/horovod/horovod/issues/3664 | [
"bug"
] | wukong1992 | 0 |
miguelgrinberg/microblog | flask | 150 | Secure the API with a security key | closed | 2019-02-08T08:33:48Z | 2019-02-08T08:34:12Z | https://github.com/miguelgrinberg/microblog/issues/150 | [] | endritbytyci | 0 | |
thp/urlwatch | automation | 688 | Help request for Amazon price tracker with urlwatch | Hi, I'm trying to build a simple price tracker for Amazon products, for example this one:

Note that as the language changes, so does Amazon's HTML, but I don't think the principle changes.
My current conf... | closed | 2022-01-04T21:59:05Z | 2022-05-08T08:18:22Z | https://github.com/thp/urlwatch/issues/688 | [] | Jorman | 6 |
nl8590687/ASRT_SpeechRecognition | tensorflow | 125 | 运行ASRT_v0.5.0版本 testClient.py 识别 ST-CMDS-20170001_1-OS 数据集中音频,出问题 | 运行 testClient 识别 ST-CMDS-20170001_1-OS 数据集中 的 20170001P00002A0076.wav 时候,程序卡住了,各位有遇到这样的情况吗? | closed | 2019-06-26T12:06:45Z | 2020-09-02T02:51:43Z | https://github.com/nl8590687/ASRT_SpeechRecognition/issues/125 | [] | baiyuting | 7 |
wkentaro/labelme | computer-vision | 985 | [Feature] Export Polygons for Visualization of the Labeling process as image | **Is your feature request related to a problem? Please describe.**
In order to better verifty the label quality and the process of how the labels were created, it would be nice to see the background image with the polygons drawn in.
**Describe the solution you'd like**
Export functionality to png
**Describe alt... | closed | 2022-02-10T10:11:29Z | 2022-06-25T04:30:13Z | https://github.com/wkentaro/labelme/issues/985 | [] | andife | 2 |
scanapi/scanapi | rest-api | 266 | Allow a delay between successive API calls | ### Enable the possibility to `sleep` between API calls.
The API I am accessing for test purposes builds up a list of quotes returning a status of `PROGRESSING` until all quotes are retrieved at which point the status is `COMPLETED`. In other words, this API has to be polled. I am able to work around this with a... | closed | 2020-09-02T18:26:06Z | 2020-10-06T14:06:57Z | https://github.com/scanapi/scanapi/issues/266 | [
"Feature",
"Hacktoberfest"
] | malminhas | 3 |
ets-labs/python-dependency-injector | flask | 126 | Providers dictionary is empty for declarative catalog instance | ``` python
"""Declarative catalog simple example."""
from dependency_injector import catalogs
from dependency_injector import providers
# Defining declarative catalog:
class Catalog(catalogs.DeclarativeCatalog):
"""Providers catalog."""
factory1 = providers.Factory(object)
factory2 = providers.Factory(... | closed | 2016-05-16T07:20:07Z | 2016-05-16T15:12:58Z | https://github.com/ets-labs/python-dependency-injector/issues/126 | [
"bug"
] | rmk135 | 1 |
zihangdai/xlnet | tensorflow | 264 | get_sequence_output is not contextualized | Hi,
I finally managed to use `get_sequence_output` to get word embeddings after dealing with random embeddings due to dropout, random seed, etc.
However, `get_sequence_output()` doesn't seem to be contextualized. If you have a string that says 'Bank river.' and get the embeddings for `Bank`, and try another one w... | open | 2020-04-27T08:50:24Z | 2020-08-01T16:02:21Z | https://github.com/zihangdai/xlnet/issues/264 | [] | maziyarpanahi | 1 |
mwaskom/seaborn | pandas | 2,916 | facetgrid: when hue value doesn't appear in all graphs the legend appears to be misannotated | **Problem:**
The same color is assigned to two different values in the legend.
**The code to reproduce:**
```
import numpy as np
import pandas as pd
import seaborn as sns
import matplotlib.pyplot as plt
sna = pd.DataFrame(
{
'x' : np.tile(range(10), 5),
'y' : list(range(10)) + ... | closed | 2022-07-21T01:23:54Z | 2022-07-22T21:09:08Z | https://github.com/mwaskom/seaborn/issues/2916 | [] | bengroves | 4 |
cle-b/httpdbg | rest-api | 130 | Allow to set default option for wrap text | When reviewing in the web UI I need to constantly check the wrap text per request to easily see the data. Would be cool if it wrapped by default, or have that option exposed in config & stored in a cookie for subsequenet runs. | closed | 2024-01-09T15:53:45Z | 2024-01-15T02:11:09Z | https://github.com/cle-b/httpdbg/issues/130 | [] | benm5678 | 3 |
jmcnamara/XlsxWriter | pandas | 650 | worksheet.fh is None during write_rich_string | Python 3.7.4
```
$ pip show xlsxwriter
Name: XlsxWriter
Version: 1.1.8
Summary: A Python module for creating Excel XLSX files.
Home-page: https://github.com/jmcnamara/XlsxWriter
Author: John McNamara
Author-email: jmcnamara@cpan.org
License: BSD
```
Minimum reproducible example:
```python
#!/usr/bin/... | closed | 2019-08-16T20:52:08Z | 2019-08-17T17:12:56Z | https://github.com/jmcnamara/XlsxWriter/issues/650 | [
"bug"
] | reinderien | 4 |
WZMIAOMIAO/deep-learning-for-image-processing | deep-learning | 690 | 图像分割,CEloss做二分类与BCEloss做二分类 | **Describe the current behavior**
我在使用网络做分割任务时,CEloss的结果比BCEloss结果更好,请问这个是有什么讲究吗?因为我映像中二分类任务一般使用BCEloss,那么我用CEloss处理二分类任务是不是很奇怪?
| open | 2022-11-16T01:27:35Z | 2022-12-03T06:09:43Z | https://github.com/WZMIAOMIAO/deep-learning-for-image-processing/issues/690 | [] | Buling-Knight | 2 |
akfamily/akshare | data-science | 5,588 | stock_board_cons_ths,请求概念和个股的关系 | 接口名称:stock_board_cons_ths
浏览器直接访问url,访问正常。
请问相应的js逆向还没有适配成功吗? | closed | 2025-02-13T11:32:09Z | 2025-02-15T14:42:55Z | https://github.com/akfamily/akshare/issues/5588 | [] | wdl5i | 1 |
zappa/Zappa | django | 829 | [Migrated] Allow file exclusion using pathspec | Originally from: https://github.com/Miserlou/Zappa/issues/2070 by [suriya](https://github.com/suriya)
## Description
This commit introduces `.gitignore` style patterns to customize what files can be excluded from a project's package.
## GitHub Issues
https://github.com/Miserlou/Zappa/issues/1359
| closed | 2021-02-20T12:52:11Z | 2024-04-13T19:10:11Z | https://github.com/zappa/Zappa/issues/829 | [
"no-activity",
"auto-closed"
] | jneves | 3 |
flairNLP/flair | nlp | 3,186 | FileNotFoundError: [Errno 2] No such file or directory: 'chunk' | ### Question
Hi! I can download and use all models as ever, but chunk. The files get downloaded, I can also find them in my .flair folder. But every time I want to load them into Classifier, the error message above appears. Other models like NER are working flawlessly.
I am using a Mac, if I can provide further i... | closed | 2023-04-05T08:51:16Z | 2023-04-05T11:52:19Z | https://github.com/flairNLP/flair/issues/3186 | [
"question"
] | michaelgoeggelmann | 3 |
openapi-generators/openapi-python-client | rest-api | 468 | Test Python 3.10 | closed | 2021-08-15T16:54:24Z | 2021-10-17T00:11:34Z | https://github.com/openapi-generators/openapi-python-client/issues/468 | [
"✨ enhancement"
] | dbanty | 0 | |
mitmproxy/pdoc | api | 691 | Including markdown is buggy and local images do not work | #### Problem Description
If you include a markdown and try to link a local image it does not work
A clear and concise description of what the bug is.
#### Steps to reproduce the behavior:
1. Create `doc/img.png`
1. Create a `doc/include.md` with an image link ``
2. `.. include ../doc/includ... | closed | 2024-05-15T21:26:13Z | 2024-05-16T01:14:44Z | https://github.com/mitmproxy/pdoc/issues/691 | [
"bug"
] | meghprkh | 4 |
Zeyi-Lin/HivisionIDPhotos | fastapi | 145 | docke部署在vps上如何更新? | docke部署在vps上如何更新? 之前部署的,看到今天更新啦 | closed | 2024-09-18T00:38:25Z | 2024-09-19T06:01:26Z | https://github.com/Zeyi-Lin/HivisionIDPhotos/issues/145 | [] | muskmust | 2 |
ahmedfgad/GeneticAlgorithmPython | numpy | 257 | The on_generation callback is not called at the end of generation 0 | The `on_generation` callback is called at the of the generation starting with generation 1, but it is not called at the end of generation 0
```
import pygad
import numpy
function_inputs = [4,-2,3.5,5,-11,-4.7]
desired_output = 44
def fitness_func(ga_instance, solution, solution_idx):
output = numpy.sum... | closed | 2023-12-16T18:21:40Z | 2024-01-28T00:29:20Z | https://github.com/ahmedfgad/GeneticAlgorithmPython/issues/257 | [
"question"
] | sunderved | 2 |
MagicStack/asyncpg | asyncio | 1,035 | new version release? | It's been a while since the last release and there've been a few bug fixes and smaller features since then. Would it be possible to release a new version? This'd greatly help me as I've been running a version with a commit applied on top of it for a while now. | closed | 2023-05-17T07:38:29Z | 2023-07-07T01:26:54Z | https://github.com/MagicStack/asyncpg/issues/1035 | [] | fvannee | 6 |
alteryx/featuretools | data-science | 1,792 | Increase the usage of augmented assignment statements | :eyes: Some source code analysis tools can help to find opportunities for improving software components.
:thought_balloon: I propose to [increase the usage of augmented assignment statements](https://docs.python.org/3/reference/simple_stmts.html#augmented-assignment-statements "Augmented assignment statements") accord... | open | 2021-11-21T15:04:25Z | 2021-11-21T15:04:25Z | https://github.com/alteryx/featuretools/issues/1792 | [] | elfring | 0 |
darrenburns/posting | rest-api | 221 | Remove left and right padding | Hi there, I just tried out posting and started to configure it a little bit. What I would be missing is a way to remove the padding/inset from the left and right. I configured my terminal to already add plenty of spacing - so that would be a nice option.
Thanks for your work! :) | open | 2025-03-11T15:46:25Z | 2025-03-11T20:36:26Z | https://github.com/darrenburns/posting/issues/221 | [] | niklasravnsborg | 1 |
postmanlabs/httpbin | api | 309 | http2bin dead? | The `HTTP/2` flavour seems down. | closed | 2016-11-07T08:30:31Z | 2018-04-26T17:51:11Z | https://github.com/postmanlabs/httpbin/issues/309 | [] | jeroen | 9 |
browser-use/browser-use | python | 187 | Support for Amazon Bedrock Client: Fix ValidationException with message role | ## Overview
When using Amazon Bedrock's Claude 3 model through `ChatBedrock`, the agent fails with a ValidationException indicating that the first message must use the "user" role.
## Current Behavior
The agent fails with the following error:
```An error occurred (ValidationException) when calling the InvokeModel... | open | 2025-01-08T06:39:32Z | 2025-01-15T21:56:57Z | https://github.com/browser-use/browser-use/issues/187 | [] | daisuke-awaji | 2 |
docarray/docarray | pydantic | 1,330 | IOMixin for DocVec (to/from) | We want to support IO functionality in `DocVec` such as from/to json, csv, bytes, etc. For example, to/from json is needed to make it FastAPI-compatible.
However, we can not use the existing IOMixin here as the logic behind DocVec is different from DocList and we'd have to overwrite some functions.
Solution:
Create ... | closed | 2023-04-03T08:42:16Z | 2023-06-28T07:18:38Z | https://github.com/docarray/docarray/issues/1330 | [] | jupyterjazz | 4 |
OpenInterpreter/open-interpreter | python | 966 | Cannot run OpenInterpreter using the command line | ### Describe the bug
I cannot run OpenInterpreter using the command line. When I try to run the command `interpreter` in PowerShell or CMD, I get an error that says:
```
interpreter : El término 'interpreter' no se reconoce como nombre de un cmdlet, función, archivo de script o programa
ejecutable. Compruebe si esc... | closed | 2024-01-25T14:51:48Z | 2024-03-19T21:04:58Z | https://github.com/OpenInterpreter/open-interpreter/issues/966 | [
"Bug"
] | vidalnuneza | 2 |
fastapi/sqlmodel | fastapi | 148 | Adding a value to a Field greater than the max_length results in null values | ### First Check
- [X] I added a very descriptive title to this issue.
- [X] I used the GitHub search to find a similar issue and didn't find it.
- [X] I searched the SQLModel documentation, with the integrated search.
- [x] I already searched in Google "How to X in SQLModel" and didn't find any information.
- [X] I al... | closed | 2021-10-28T16:05:40Z | 2021-10-28T16:09:45Z | https://github.com/fastapi/sqlmodel/issues/148 | [
"question"
] | mudassirkhan19 | 1 |
thtrieu/darkflow | tensorflow | 372 | AssertionError: Over-read bin/yolo2-voc.weights | I tried to run the yolo-voc.cfg with the weights file downloaded from https://pjreddie.com/darknet/yolo/ but it shows the following error:
ubuntu@ubuntu-S2600CW:~/Desktop/virtualroiflow/darkflow$ ./flow --model cfg/yolo2-voc.cfg --load bin/yolo2-voc.weights --train --dataset "VOCdevkit/VOC2007/JPEGImages/" --annotat... | open | 2017-08-10T11:55:01Z | 2021-05-30T08:51:55Z | https://github.com/thtrieu/darkflow/issues/372 | [] | tankienleong | 12 |
horovod/horovod | deep-learning | 4,028 | Tensorflow Saved model not portable with latest tf.keras.optimizers | **Environment:**
1. Framework: (TensorFlow, Keras, PyTorch, MXNet) Tensorflow
2. Framework version: 2.11
3. Horovod version: 0.28.1
4. MPI version: N/A
5. CUDA version: 11.2 (tested in CPU version)
6. NCCL version: 11.2
7. Python version: 3.10
8. Spark / PySpark version: N/A
9. Ray version: N/A
10. OS and ver... | open | 2024-03-11T04:52:40Z | 2024-03-15T03:44:31Z | https://github.com/horovod/horovod/issues/4028 | [
"bug"
] | supercharleszhu | 0 |
home-assistant/core | python | 140,809 | Linkplay sound mode does not apply to WiiM (Pro at least) | ### The problem
The LinkPlay media player allows to select a few pre-defined sound-modes which do not work on WiiM devices, at least not to my WiiM Pro.
WiiM uses a api-command EQLoad which allows to set one of the following predefined-EQ
["Flat", "Acoustic", "Bass Booster", "Bass Reducer", "Classical", "Dance", "Deep... | closed | 2025-03-17T17:01:05Z | 2025-03-23T15:22:57Z | https://github.com/home-assistant/core/issues/140809 | [
"integration: linkplay"
] | vingerha | 10 |
davidteather/TikTok-Api | api | 835 | [BUG] - Liked Videos Documentation/Code Snippet Incorrect | Your documentation page and code snippet in Examples for getting a user's likes are incorrect.
I believe this is the correct way:
```
user = api.user(username="my_likes_are_open")
for video in user.liked():
# do something
```
| closed | 2022-02-19T01:30:32Z | 2023-08-08T15:16:04Z | https://github.com/davidteather/TikTok-Api/issues/835 | [
"bug"
] | ryanjmarcus | 0 |
xonsh/xonsh | data-science | 5,058 | $MULTILINE_PROMPT doesn't filter out OSC commands | I'm adding "terminal integration" to xonsh and as such need to add various prompt commands to prompt for the terminal to recognize when input/output starts/ends etc. [doc](https://github.com/wez/wezterm/blob/main/docs/shell-integration.md)
It's working fine in other prompt variables, but then in `$MULTILINE_PROMPT` ... | closed | 2023-02-15T14:24:56Z | 2023-02-21T09:11:40Z | https://github.com/xonsh/xonsh/issues/5058 | [
"prompt"
] | eugenesvk | 2 |
paperless-ngx/paperless-ngx | machine-learning | 9,041 | Automatic tagging fails without error | ### Description
All files upload, OCR and archive automatically. Document type is automatically set by Paperless-NGX. Tags are not being set automatically, even if text is recognized and there should be matching tags. 10+ documents tested, same results.
### Steps to reproduce
Make a tag matching rule in the WebUI se... | closed | 2025-02-08T09:55:33Z | 2025-03-11T03:12:35Z | https://github.com/paperless-ngx/paperless-ngx/issues/9041 | [
"not a bug"
] | Aviatorpaal | 3 |
microsoft/qlib | machine-learning | 1,561 | can qlib solve the compatibility problem with python3.10 | ## 🐛 Bug Description
<!-- A clear and concise description of what the bug is. -->
## To Reproduce
Steps to reproduce the behavior:
1.
1.
1.
## Expected Behavior
<!-- A clear and concise description of what you expected to happen. -->
## Screenshot
<!-- A screenshot of the error message or a... | open | 2023-06-20T02:46:51Z | 2023-06-20T02:46:51Z | https://github.com/microsoft/qlib/issues/1561 | [
"bug"
] | kenny996 | 0 |
hootnot/oanda-api-v20 | rest-api | 102 | Issue with market orders | Hi I'm a python beginner trying to issue some oanda orders with python. I'm stuck and would like some further illustration:
```python
from exampleauth import exampleAuth
+
r = orders.OrderCreate(accountID, data=mktOrder.data)
```
1) my question is: what should i do with the first part? What should I replace ... | closed | 2017-10-08T19:42:09Z | 2018-01-13T08:43:35Z | https://github.com/hootnot/oanda-api-v20/issues/102 | [
"question"
] | fx007 | 3 |
python-restx/flask-restx | flask | 303 | Header X-Fields breaks on Schemathesis tests | Field masks should not be implicitly provided, but only explicitly set by the user
### **Code**
```
from flask import Flask
from flask_restx import Api, Resource, fields
from werkzeug.middleware.proxy_fix import ProxyFix
app = Flask(__name__)
app.wsgi_app = ProxyFix(app.wsgi_app)
api = Api(
app,
... | open | 2021-04-29T15:59:03Z | 2023-01-13T20:14:20Z | https://github.com/python-restx/flask-restx/issues/303 | [
"bug"
] | GvandeSteeg | 2 |
aminalaee/sqladmin | asyncio | 741 | Ajax query passes incorrect urn when admin mounted on sub fastapi app | ### Checklist
- [X] The bug is reproducible against the latest release or `master`.
- [X] There are no similar issues or pull requests to fix it yet.
### Describe the bug
Ajax request from browser doesn't consider urn which setted up by sub fastapi app.
### Steps to reproduce the bug
1) Link admin to su... | open | 2024-04-09T03:53:37Z | 2024-05-13T11:46:18Z | https://github.com/aminalaee/sqladmin/issues/741 | [] | infanasotku | 3 |
yunjey/pytorch-tutorial | deep-learning | 212 | BN should be used after ReLU | <https://github.com/yunjey/pytorch-tutorial/blob/master/tutorials/02-intermediate/convolutional_neural_network/main.py#L41-L42>
```python
nn.ReLU(),
nn.BatchNorm2d(...),
```
BN should be used after ReLU. Features might be truncated by non-linearity like ReLU, so BN is used to normalize the distribution of feat... | closed | 2020-07-06T09:12:26Z | 2020-07-24T06:55:41Z | https://github.com/yunjey/pytorch-tutorial/issues/212 | [] | yunlingz | 0 |
exaloop/codon | numpy | 86 | Can I use codon with Cffi? | I didn't find any discussion group. | closed | 2022-12-12T01:02:49Z | 2022-12-18T04:20:39Z | https://github.com/exaloop/codon/issues/86 | [
"question"
] | nile649 | 2 |
AUTOMATIC1111/stable-diffusion-webui | pytorch | 16,205 | [Bug]: Calling webui-user.bat hangs because python commands are not called with 'call' statement | ### Checklist
- [X] The issue exists after disabling all extensions
- [X] The issue exists on a clean installation of webui
- [X] The issue is caused by an extension, but I believe it is caused by a bug in the webui
- [X] The issue exists in the current version of the webui
- [X] The issue has not been reported before... | closed | 2024-07-13T13:29:30Z | 2024-10-29T14:55:14Z | https://github.com/AUTOMATIC1111/stable-diffusion-webui/issues/16205 | [
"bug-report"
] | stevenengland | 2 |
google-research/bert | tensorflow | 559 | problem multiclass text classification | Hi,
I am trying to classify text in 34 mutually exclusive classes using BERT. After preparing train, dev and test TSV files, and I try to execute the command for training and testing
`!python bert/run_classifier.py \
--task_name=cola \
--do_train=true \
--do_eval=true \
--data_dir=./Bert_Input_Folder \
--voc... | open | 2019-04-07T02:13:04Z | 2020-09-13T14:47:59Z | https://github.com/google-research/bert/issues/559 | [] | 86mm86 | 14 |
15r10nk/inline-snapshot | pytest | 201 | Docs: Comparison of snapshot libraries | It would be great to have a section in the docs about the differences (advantages, differences) of `inline-snapshot` in comparison to other libraries.

*[star-history.com](https://star-history.com/#syrusakbary/snapshottest&syrupy-... | open | 2025-02-21T19:03:16Z | 2025-02-21T20:42:13Z | https://github.com/15r10nk/inline-snapshot/issues/201 | [] | fkromer | 2 |
Evil0ctal/Douyin_TikTok_Download_API | fastapi | 535 | [BUG] 获取的A_Bogus在获取直播讲解数据时无效 | ***发生错误的平台?***
抖音
***发生错误的端点?***
Douyin-Web-API
***提交的输入值?***
https://compass.jinritemai.com/compass_api/author/live/live_room_detail/flow/trend_analysis_point?live_room_id=7455646931982043923&trend_gap=minute&msToken=s2NOPES1pvj4x4sKzqRuG7ldukD5A-zZ3v6SZ8lToTmDyC2OSma4wlyt4BY4RqLAHMgTC_p-BK72tIVXtBJ4WPcEtux5O... | closed | 2025-01-10T15:26:15Z | 2025-02-15T09:15:47Z | https://github.com/Evil0ctal/Douyin_TikTok_Download_API/issues/535 | [
"BUG"
] | slaners | 2 |
keras-team/keras | deep-learning | 20,648 | tf.keras.models.Sequential | hi dear.
i have problem:
model = tf.keras.models.Sequential([
mobile_net,
### ann layer
tf.keras.layers.Dense(1, activation='sigmoid') #[0, 1] or [1, 0]
])
in new versions of tensorflow and keras it has problme :
ValueError: Only instances of keras.Layer can be added to a Sequential model. Received: <tens... | closed | 2024-12-15T20:25:59Z | 2024-12-18T06:55:16Z | https://github.com/keras-team/keras/issues/20648 | [
"type:support"
] | moeinnm-99 | 9 |
lukas-blecher/LaTeX-OCR | pytorch | 172 | mac segmentation when setting up | When executing latexocr or pix2tex I get the following error:
```
18195 segmentation fault pix2tex
18182 segmentation fault latexocr
```
torch 1.12.1
python 3.7.13/3.9.12 | closed | 2022-08-31T05:58:58Z | 2022-09-01T07:19:43Z | https://github.com/lukas-blecher/LaTeX-OCR/issues/172 | [
"duplicate"
] | yingjiahao14 | 1 |
piskvorky/gensim | machine-learning | 2,726 | C extension not loaded, training will be slow. Install a C compiler and reinstall gensim for fast training. | Im trying to run naive-bayes.py from the following file(https://github.com/rockash/Fake-news-Detection) but i get the error mentioned in the title, i have tried uninstalling gensim and reinstalling it again using both pip and conda but nothing seems to work.i also have mingw installed and have added /bin to path as the... | closed | 2020-01-15T01:41:06Z | 2020-01-27T09:02:30Z | https://github.com/piskvorky/gensim/issues/2726 | [
"need info"
] | gmnabeel | 6 |
ccxt/ccxt | api | 24,823 | fetchOrderWs() not supported for Binance despite being documented | ### Operating System
Ubuntu
### Programming Languages
Python
### CCXT Version
4.4.40
### Description
The `fetchOrderWs()` method is documented and reportedly supported by `ccxt` for Binance. However, when attempting to call the method, it raises an error: `binance fetchOrderWs() is not supported yet`.
### Code
... | open | 2025-01-10T08:58:12Z | 2025-01-10T08:58:12Z | https://github.com/ccxt/ccxt/issues/24823 | [] | m4rvxpn | 0 |
pydata/xarray | pandas | 9,826 | Run duck array tests in separate CI jobs | ### What is your issue?
As a follow up to #9798 we should consider running a two CI jobs with `pint`, `sparse`, `jax` installed (one with latest version, one with minimum supported version), and remove them from the other jobs.
cc @slevang | open | 2024-11-26T00:32:49Z | 2024-11-26T17:24:45Z | https://github.com/pydata/xarray/issues/9826 | [
"topic-testing",
"topic-arrays",
"CI",
"array API standard"
] | dcherian | 2 |
ultralytics/ultralytics | machine-learning | 19,824 | WeightsUnpickler error | Hello;
I am working on a project and using the Yolov8.yaml file to train the module from scratch, everything okay however I have faced this problem, and I am stuck here I have used this repo before, and there were no problems or errors, but when I want to return to the project, I have faced this issue.
and this is the... | open | 2025-03-22T13:36:31Z | 2025-03-23T00:22:18Z | https://github.com/ultralytics/ultralytics/issues/19824 | [
"detect"
] | Salmankm93 | 2 |
pytorch/vision | machine-learning | 8,748 | Setting `flickr8k` from `illinois.edu` to `root` argument of `Flickr8k()` doesn't load any images, returning the length `0` | ### 🐛 Describe the bug
Setting [flickr8k](https://github.com/goodwillyoga/Flickr8k_dataset?tab=readme-ov-file) from [illinois.edu](https://illinois.edu/fb/sec/1713398) to `root` argument of [Flickr8k()](https://pytorch.org/vision/stable/generated/torchvision.datasets.Flickr8k.html) doesn't load any images, returnin... | open | 2024-11-25T14:15:39Z | 2024-11-27T17:29:26Z | https://github.com/pytorch/vision/issues/8748 | [] | hyperkai | 1 |
microsoft/JARVIS | deep-learning | 42 | Consider using huggingface_hub library for Inference | [In `awesome_chat.py`](https://github.com/microsoft/JARVIS/blob/main/server/awesome_chat.py#L348), you implement the inference method `huggingface_model_inference` (that uses the Hugging Face Hub under the hood) using `requests` and custom code. One thing you can do to deduplicate some code is to use `huggingface_hub` ... | closed | 2023-04-05T11:58:05Z | 2023-04-05T18:26:10Z | https://github.com/microsoft/JARVIS/issues/42 | [
"enhancement"
] | Wauplin | 8 |
3b1b/manim | python | 1,205 | python3 -m pip install -r requirements.txt not working | This is on Mac OS Catalina.
Typing python3 -m pip install -r requirements.txt in the correct directory brings
``Collecting argparse==1.4.0
Using cached argparse-1.4.0-py2.py3-none-any.whl (23 kB)
Collecting colour==0.1.5
Using cached colour-0.1.5-py2.py3-none-any.whl (23 kB)
Collecting numpy==1.15.0
Using ... | closed | 2020-08-18T01:42:49Z | 2020-08-18T13:08:12Z | https://github.com/3b1b/manim/issues/1205 | [] | ghost | 2 |
qubvel-org/segmentation_models.pytorch | computer-vision | 774 | SMP models are ten times more precise, than a three-class multiclass segmentation | I have a tough segmentation task. My objects are small (10x10 pixels - 20x20 pixels), there are issues with class imbalance (98% of pixels in my photoset is background) there are other elements that look like the class, There is no clear border and the quality of photos are poor. Think of black/white dots on the skin... | closed | 2023-06-01T19:28:21Z | 2023-08-09T01:52:36Z | https://github.com/qubvel-org/segmentation_models.pytorch/issues/774 | [
"Stale"
] | SixtyTrees | 2 |
autogluon/autogluon | computer-vision | 4,315 | Getting ZeroDivisionError while fitting the Timeseries | **Getting ZeroDivisionError while fitting the Timeseries**
**Expected behavior**
Should Run Successfully
**To Reproduce**
1. Download the [dataset](https://drive.google.com/file/d/123t6L2vbaL-uuch2jfzY6tiAlJgLskUW/view?usp=sharing)
2. create new column df["id_col"] = "default"
3. Set DataValue as target
4. Se... | open | 2024-07-09T06:32:31Z | 2024-08-01T13:39:24Z | https://github.com/autogluon/autogluon/issues/4315 | [
"bug: unconfirmed",
"Needs Triage"
] | AhangarAamir | 7 |
huggingface/pytorch-image-models | pytorch | 2,149 | [BUG] list_pretrained returns more models than list_models | A minor bug that I just wanted to flag. `list_models()` returns fewer models than `list_models(pretrained=True)`.
**To Reproduce**
Steps to reproduce the behavior:
1. `len(timm.list_models()) == 1032`
2. `len(timm.list_models(pretrained=True)) == 1329`
**Expected behavior**
Pretrained models should be a subs... | closed | 2024-04-15T21:56:07Z | 2024-04-15T22:26:24Z | https://github.com/huggingface/pytorch-image-models/issues/2149 | [
"bug"
] | tanyav2 | 1 |
modelscope/data-juicer | data-visualization | 531 | [Bug]: 开启checkpoint,当配置的一个pipline执行到最后一个算子时,np>left samples,在开启checkpoint会报错。 | ### Before Reporting 报告之前
- [X] I have pulled the latest code of main branch to run again and the bug still existed. 我已经拉取了主分支上最新的代码,重新运行之后,问题仍不能解决。
- [X] I have read the [README](https://github.com/alibaba/data-juicer/blob/main/README.md) carefully and no error occurred during the installation process. (Otherwise, w... | closed | 2025-01-06T13:36:50Z | 2025-01-14T05:53:07Z | https://github.com/modelscope/data-juicer/issues/531 | [
"bug",
"dj:core"
] | HunterLG | 2 |
dynaconf/dynaconf | fastapi | 555 | [DOCS] Build docs only when a tag is released | Currently every time a new commit goes to master branch the webhook tells netlify to build the docs.
The problem is that docs goes out of sync with latest release version.
There are 3 ways of resolving this problem:
## 1 settings `ignore_builds` to something that will exclude untagged master
https://docs.ne... | closed | 2021-03-15T16:11:35Z | 2021-10-08T12:32:01Z | https://github.com/dynaconf/dynaconf/issues/555 | [
"enhancement",
"hacktoberfest",
"Docs"
] | rochacbruno | 1 |
zappa/Zappa | flask | 800 | [Migrated] InvalidSignatureException | Originally from: https://github.com/Miserlou/Zappa/issues/1953 by [neerajb1](https://github.com/neerajb1)
<!--- Provide a general summary of the issue in the Title above -->
Getting InvalidSignatureException Issue
<!--- Provide a more detailed introduction to the issue itself, and why you consider it to be a bug -... | closed | 2021-02-20T12:42:38Z | 2022-08-18T02:02:57Z | https://github.com/zappa/Zappa/issues/800 | [] | jneves | 1 |
lazyprogrammer/machine_learning_examples | data-science | 62 | warning with saving the model | it apperas that the accuracy of the model is so good but after saving the model and load it, it gives a non reasonable results ..
the model is not saved correctly
| closed | 2020-04-28T21:15:06Z | 2025-02-19T23:11:25Z | https://github.com/lazyprogrammer/machine_learning_examples/issues/62 | [] | HoudaKilani | 1 |
rthalley/dnspython | asyncio | 209 | zone.origin.to_text() returns a different type depending on python version. | Using dnspython 1.14
```
import dns.zone
zone_text = (
'$ORIGIN %(name)s\n%(name)s 3600 IN SOA %(ns)s '
'email.email.com. 1421777854 3600 600 86400 3600\n%(name)s '
'3600 IN NS %(ns)s\n') % {'name': 'example.com.', 'ns': 'ns1.designate.com'}
zone = dns.zone.from_text(zone_text, check_origin=False)
print(... | closed | 2016-09-27T20:16:22Z | 2016-09-28T07:32:21Z | https://github.com/rthalley/dnspython/issues/209 | [
"Bug",
"Fixed"
] | grahamhayes | 12 |
miguelgrinberg/flasky | flask | 118 | how can i updata my detabase using a Paas not Foreman | in Foreman i can use `foreman run python manage.py deploy`
But in many PaaS, I can't run shell Script.
What I could is only git my code.
So, what code should be added?
| closed | 2016-03-03T12:55:58Z | 2016-06-01T16:23:27Z | https://github.com/miguelgrinberg/flasky/issues/118 | [
"question"
] | Abirdcfly | 1 |
modin-project/modin | pandas | 7,355 | BUG: Cpu count would be set incorrectly on a cluster. | cpu count on a cluster would be by default set to the number of cpus on head node(node where modin initialization is performed), This should be set to the total number of cpus in the cluster. This issue is similar to https://github.com/modin-project/modin/issues/2798 | closed | 2024-08-01T14:53:02Z | 2024-08-01T16:33:13Z | https://github.com/modin-project/modin/issues/7355 | [] | arunjose696 | 0 |
redis/redis-om-python | pydantic | 455 | Can't install using Python 3.11 | pip basically does not found the latest versions when using python 3.11... (it only reaches until 0.0.27)
```
python3.10 -m pip index versions redis-om
WARNING: pip index is currently an experimental command. It may be removed/changed in a future release without prior warning.
redis-om (0.1.1)
Available versions... | closed | 2023-01-04T10:00:35Z | 2023-01-08T11:08:39Z | https://github.com/redis/redis-om-python/issues/455 | [] | bonastreyair | 3 |
OpenGeoscience/geonotebook | jupyter | 77 | Set up read the docs | @danlamanna lets coordinate on content/headings | closed | 2017-01-23T17:52:51Z | 2017-05-03T19:25:55Z | https://github.com/OpenGeoscience/geonotebook/issues/77 | [] | kotfic | 2 |
pytorch/pytorch | deep-learning | 149,457 | Error when tracing torch.func.functional_call | ### 🐛 Describe the bug
I'm trying to add support for scanning over mulitple layers, and have verified it works with _fake_scan, so now I'm trying to replace that call with real `scan`. However I am running into an error in torch.compile when it's trying to trace the call to torch.func.functional_call with in my scan ... | open | 2025-03-18T22:14:50Z | 2025-03-19T20:56:05Z | https://github.com/pytorch/pytorch/issues/149457 | [
"triaged",
"oncall: pt2",
"module: dynamo"
] | angelayi | 0 |
pyeve/eve | flask | 1,067 | Problem implementing get for S3 custom MediaStorage class | Using eve 0.7.4, I'm trying to implement a `MediaStorage` class to store and retrieve data from AWS S3. I am following documentation information and checked a similar question on [SO](https://stackoverflow.com/questions/21823649/how-to-upload-image-through-python-eve-to-some-external-storage-server-e-g-s3/21824645#218... | closed | 2017-09-25T16:33:45Z | 2017-10-19T17:30:49Z | https://github.com/pyeve/eve/issues/1067 | [] | gwainer | 5 |
Subsets and Splits
No community queries yet
The top public SQL queries from the community will appear here once available.