
repo_name stringlengths 9 75 | topic stringclasses 30
values | issue_number int64 1 203k | title stringlengths 1 976 | body stringlengths 0 254k | state stringclasses 2
values | created_at stringlengths 20 20 | updated_at stringlengths 20 20 | url stringlengths 38 105 | labels listlengths 0 9 | user_login stringlengths 1 39 | comments_count int64 0 452 |
|---|---|---|---|---|---|---|---|---|---|---|---|
allenai/allennlp | nlp | 5,177 | I want load my model by own scripts how i do | in your tutorial, you say:
see our chapter on writing your own scripts for pointers on how to save and load models if you aren't using configuration files.
but https://guide.allennlp.org/writing-your-own-script#3 is None , can you give me some suggest | closed | 2021-05-05T08:50:20Z | 2021-05-19T16:15:24Z | https://github.com/allenai/allennlp/issues/5177 | [
"question",
"stale"
] | dugudongfangshuo | 2 |
davidsandberg/facenet | computer-vision | 1,007 | Transferring Models to C++ using OpenCV | Hi @davidsandberg and thanks for sharing your great work.
I want to use the models in C++ using OpenCV.
This is what I have already tried and the corresponding errors:
1- Input layer not found:
First, I tried to use readNetFromTensorflow("model.pb") with no config file. I tried to use your .pb file but it has th... | open | 2019-04-17T06:39:13Z | 2019-12-08T16:37:21Z | https://github.com/davidsandberg/facenet/issues/1007 | [] | Rasoul20sh | 4 |
graphql-python/graphene | graphql | 1,113 | DataLoader doesn't work | I've tried to implement the DataLoader in my schema. I've attempted a very simple implementation before I go more complex. It's very very similar to the documentation. Unfortunately, it goes through and creates all the Promises, but it doesn't batch them all together. It just runs them sequentially. | closed | 2019-12-19T00:24:42Z | 2019-12-30T19:46:53Z | https://github.com/graphql-python/graphene/issues/1113 | [] | pollaro | 3 |
huggingface/transformers | python | 36,714 | Gemma3 minimal fine tuning example? | I've been trying to fine tune gemma3 but I can't seem to figure out exactly how to do it. Here's what I have now:
```python
import tempfile
from typing import Any, cast
from transformers import AutoProcessor, Gemma3ForConditionalGeneration
from transformers import TrainingArguments, Trainer
from common import HF_TOKEN... | closed | 2025-03-14T09:54:00Z | 2025-03-18T09:47:45Z | https://github.com/huggingface/transformers/issues/36714 | [] | FredrikNoren | 4 |
RomelTorres/alpha_vantage | pandas | 127 | Momentum | Hi,
I'm developing a trading system and I'm trying your API.
I got some trouble to understand MOM (Momentum indicator) parameter. Your documentation says:
> Number of data points used to calculate each MOM value. Positive integers are accepted (e.g., time_period=60, time_period=200)
The question is:
**time... | closed | 2019-04-26T20:07:32Z | 2019-09-12T01:55:43Z | https://github.com/RomelTorres/alpha_vantage/issues/127 | [
"question"
] | kairosart | 1 |
ansible/ansible | python | 84,499 | Ability to hide 'included' lines when using include_role or include_tasks with default callback plugin | ### Summary
I just upgraded, and notice that latest now prints "included: host1, host2, hostX" for all included roles.
I use this playbook to be able to auto tag roles.
```yaml
tasks:
- include_role:
name: "{{ role_item }}"
apply:
tags: "{{ role_item | split('/') | last }}"
... | open | 2024-12-30T11:47:50Z | 2025-01-14T16:58:46Z | https://github.com/ansible/ansible/issues/84499 | [
"waiting_on_contributor",
"feature"
] | eoli3n | 4 |
InstaPy/InstaPy | automation | 6,015 | Selenium Errors |
Script will not start. I am working on Mac OS Big Sur M1 and using Python 3.7.2
When starting script after creating the workspace I get the following Selenium errors
Workspace in use: "/Users/using/user/user/user"
Traceback (most recent call last):
File "/Users/rosie/Desktop/InstaPy-master/GF_Test.py", lin... | closed | 2021-01-09T19:50:20Z | 2021-07-21T05:18:51Z | https://github.com/InstaPy/InstaPy/issues/6015 | [
"wontfix"
] | digitizesuccess | 3 |
graphdeco-inria/gaussian-splatting | computer-vision | 1,117 | RuntimeError: CUDA error: invalid configuration argument | 
| open | 2024-12-20T03:13:58Z | 2024-12-20T03:13:58Z | https://github.com/graphdeco-inria/gaussian-splatting/issues/1117 | [] | chenqi13814529300 | 0 |
CorentinJ/Real-Time-Voice-Cloning | deep-learning | 909 | *SOLVED* QBasicTimer::start error | Hello All,
*SOLVED*
did not have venv setup correctly /activated.
Debian Bullseye
Went through the installation steps. when launching the demo_toolbox.py the Gui comes up with all buttons greyed out and in the terminal the following keeps repeating.
QBasicTimer::start: QBasicTimer can only be used with threa... | closed | 2021-11-26T18:44:04Z | 2021-12-28T12:33:21Z | https://github.com/CorentinJ/Real-Time-Voice-Cloning/issues/909 | [] | brcisna | 0 |
plotly/dash-table | dash | 222 | Allow HyperLinks in cells via either dash_html_components.A, plain HTML string, or a markdown string | Right now, the cells can only be plain text. It will be great to support either HTML String or dash_html_components.A | closed | 2018-11-05T23:01:56Z | 2020-09-16T10:38:26Z | https://github.com/plotly/dash-table/issues/222 | [
"dash-type-enhancement"
] | zshao | 42 |
fastapi/sqlmodel | sqlalchemy | 545 | Many to many relationship between a table and itself | ### First Check
- [X] I added a very descriptive title to this issue.
- [X] I used the GitHub search to find a similar issue and didn't find it.
- [X] I searched the SQLModel documentation, with the integrated search.
- [X] I already searched in Google "How to X in SQLModel" and didn't find any information.
- [X... | open | 2023-01-31T10:24:33Z | 2024-01-31T15:42:50Z | https://github.com/fastapi/sqlmodel/issues/545 | [
"feature"
] | joaopfg | 6 |
plotly/dash | jupyter | 2,586 | Dash & XLwings. Attempting to pre-load Excel before Dash callback to save load time. | Windows 10 Enterprise for local. Windows Server 2022 Standard for the server
3.10 Python, Microsoft 365 Apps for enterprise, 0.28.7 xlwings
I have a web interface project that is using a connection between XLwings and Dash. The Excel file is large and takes about 15 seconds to load, while the calc only takes 5 se... | closed | 2023-07-06T18:02:17Z | 2023-07-12T23:17:15Z | https://github.com/plotly/dash/issues/2586 | [] | karnrage | 1 |
tensorpack/tensorpack | tensorflow | 1,450 | Faster RCNN ValueError: Trying to load an array of shape (81,) into variable 'cascade_rcnn_stage1/outputs/class/b' whose shape is (3,). | Faster RCNN
ValueError: Trying to load an array of shape (81,) into variable 'cascade_rcnn_stage1/outputs/class/b' whose shape is (3,).
When I run my model, the program reports an error. May I ask where is the reason and if the application is done? | closed | 2020-06-03T03:40:11Z | 2020-06-03T03:50:24Z | https://github.com/tensorpack/tensorpack/issues/1450 | [] | fei161 | 2 |
wagtail/wagtail | django | 11,975 | Configure pre-commit hooks to automatically fix formatting and linting issues on commit | ### Is your proposal related to a problem?
Before committing changes, the black formatter has to be run to make sure the code follows the formatting guidelines. Formatting issues can cause a PR to fail checks, requiring another commit to be made to fix the issue.
### Describe the solution you'd like
[pre-commit]... | closed | 2024-05-23T08:09:18Z | 2024-05-23T08:15:36Z | https://github.com/wagtail/wagtail/issues/11975 | [
"type:Enhancement"
] | NXPY123 | 1 |
plotly/dash | jupyter | 2,444 | change behavior of grouping in go.Scatter x axes | When plotting a go.Scatter with many values in the x axis, the points suddenly get grouped, so for the same visible point, multiple values are represented.
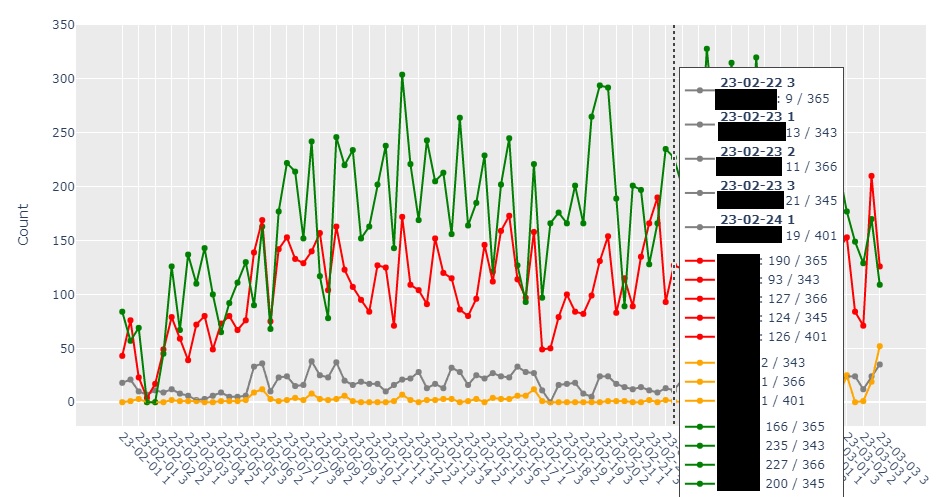
How can I represent all datapoints s... | open | 2023-03-06T07:42:21Z | 2024-08-13T19:28:32Z | https://github.com/plotly/dash/issues/2444 | [
"feature",
"P3"
] | asicoderOfficial | 5 |
waditu/tushare | pandas | 1,476 | #新需求 恳请米哥加入财务指标的ttm数据 | ID :18781065195
恳请米哥加入财务指标的ttm数据 | open | 2020-12-21T07:06:50Z | 2021-01-06T10:53:06Z | https://github.com/waditu/tushare/issues/1476 | [] | Kebing007 | 2 |
pydata/bottleneck | numpy | 111 | bn.move_median seg fault | The following causes a seg fault:
```
In [1]: a = np.array([1, 2, np.inf, 3, 4, 5])
In [2]: bn.move_median(a, window=3)
Segmentation fault
```
If the location of np.inf or the window size is changed then the function does not seg fault.
move_median.c uses C's INFINITY to mark missing values in the heaps. I assume th... | closed | 2016-04-29T19:55:28Z | 2016-05-24T23:39:14Z | https://github.com/pydata/bottleneck/issues/111 | [] | kwgoodman | 14 |
alteryx/featuretools | data-science | 1,930 | Remove pinned minimum responses version when moto can handle responses 0.19.0 | Currently there is an [error in moto](https://github.com/spulec/moto/issues/4913) with the latest version of responses (0.19.0). This caused our minimum dependency tests to break, so we've pinned `responses<0.19.0` in the `minimum_rest_requirements.txt`.
Once there is a moto version that can handle responses 0.19.0... | closed | 2022-03-07T18:03:34Z | 2022-03-09T18:07:49Z | https://github.com/alteryx/featuretools/issues/1930 | [] | tamargrey | 0 |
electricitymaps/electricitymaps-contrib | data-visualization | 7,764 | [Data Issue]: Canary Islands no data since 23.01.2025 | ### When did this happen?
no data en canary Islands since
2025-01.23 ca 10:00
Example: El Hierro

### What zones are affected?
El Hierro, Gomera, La Palma, Tenerriffe, Gran Canaria, Fuerteventura/Lancarote
### What is the... | closed | 2025-01-24T14:41:43Z | 2025-02-03T10:11:19Z | https://github.com/electricitymaps/electricitymaps-contrib/issues/7764 | [
"help wanted",
"good first issue",
"data"
] | strassburger | 5 |
quantmind/pulsar | asyncio | 110 | Error during chunked https | My app spits out one of these per chunk
```
2014-05-06 10:02:27 ERROR base_events.py:691 - default_exception_handler Exception in callback <bound method _SelectorSslTransport._read_ready of <asyncio.selector_events._SelectorSslTransport object at 0x25c95d0>>()
handle: Handle(<bound method _SelectorSslTransport._read_... | closed | 2014-05-06T18:10:04Z | 2014-05-30T08:58:48Z | https://github.com/quantmind/pulsar/issues/110 | [
"http",
"bug"
] | impliers | 7 |
thtrieu/darkflow | tensorflow | 1,069 | Load trained weights to my tensorflow YOLO tiny network | Hello,
I am trying to convert tiny yolo v2 weights to tensorflow compatible weights and then load into my own yolo model and fine tune for my data. Is it possible to load this model checkpoints into my network if I make config network file and my yolo network same?
Thanks | open | 2019-08-08T03:03:39Z | 2019-08-08T03:03:39Z | https://github.com/thtrieu/darkflow/issues/1069 | [] | Ajaz-Ahmad | 0 |
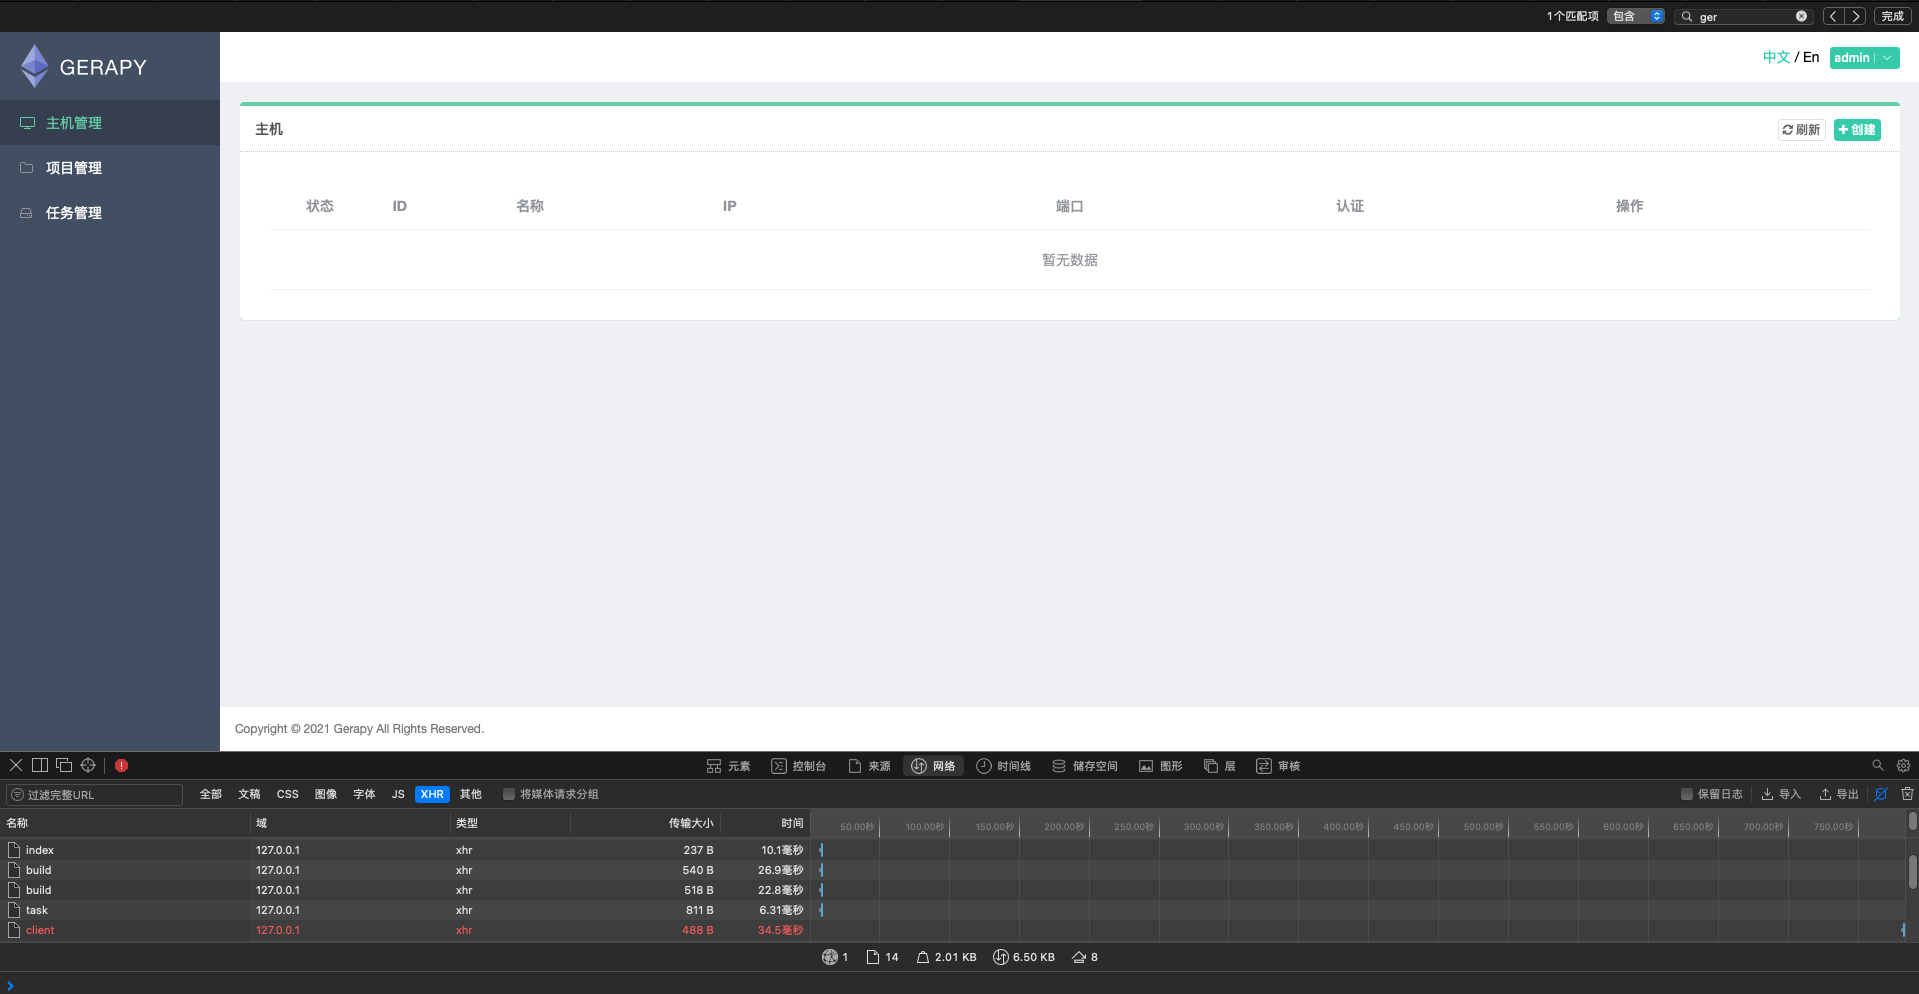
Gerapy/Gerapy | django | 207 | 如api/index/status/、api/client/,末尾“/”结尾的接口都报401 | # 如```api/index/status/``` ```api/client/```末尾“/”结尾的接口都报401.
**Screenshots**
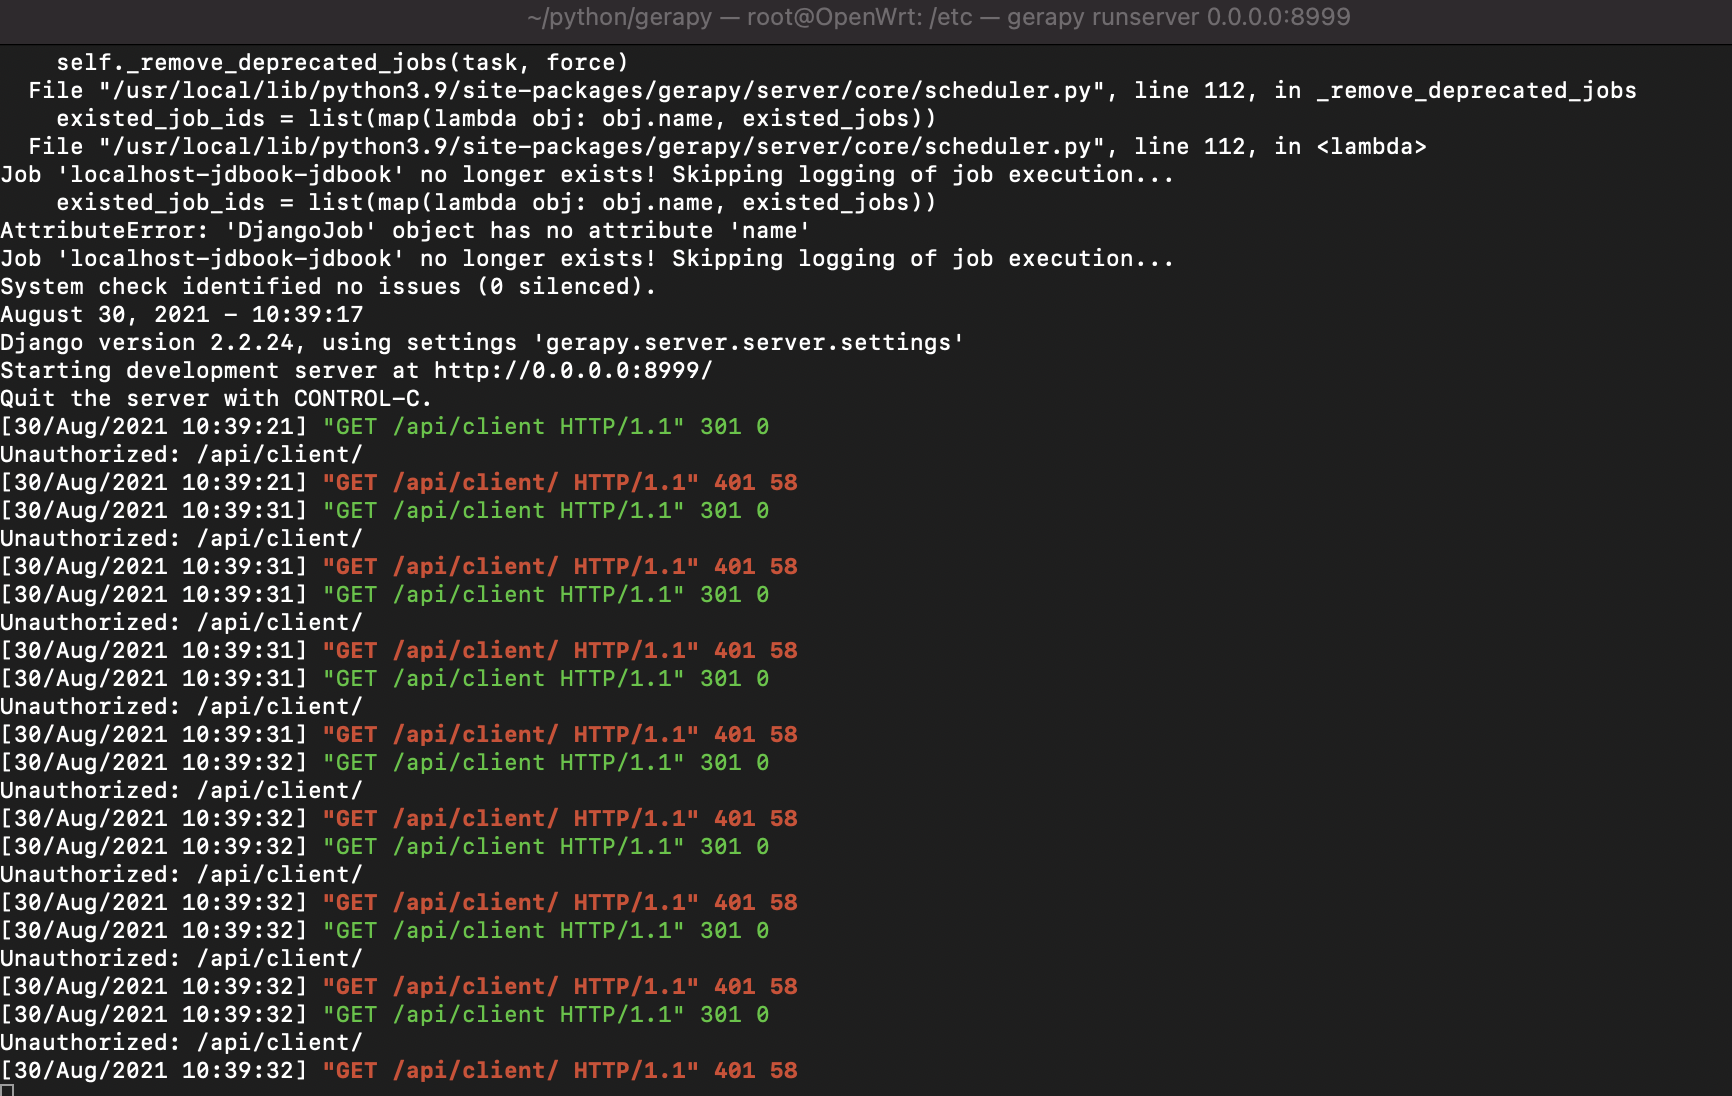
# 我的运行环境
*... | closed | 2021-08-30T02:45:10Z | 2021-12-26T07:41:29Z | https://github.com/Gerapy/Gerapy/issues/207 | [
"bug"
] | jiangslee | 1 |
developmentseed/lonboard | data-visualization | 378 | Bug: Allow non-served HTML export for polygon layer | Currently fails because web worker was not able to load
<img width="1574" alt="image" src="https://github.com/developmentseed/lonboard/assets/15164633/c3e6d07f-4c8c-4ad1-846e-0e119af4df92">
| closed | 2024-02-23T21:12:44Z | 2024-02-26T18:02:55Z | https://github.com/developmentseed/lonboard/issues/378 | [] | kylebarron | 0 |
koxudaxi/datamodel-code-generator | fastapi | 1,435 | Wrong parent class for pydantic V2 root models | **Describe the bug**
Generator uses `pydantic.BaseModel` as parent class for root model instead of `pydantic.RootModel`
Example schema (`custom_id.yaml`):
```yaml
openapi: 3.0.0
components:
schemas:
CustomId:
description: My custom ID
type: string
format: uuid
```
Used commandline:... | closed | 2023-07-19T14:47:01Z | 2023-08-08T16:01:59Z | https://github.com/koxudaxi/datamodel-code-generator/issues/1435 | [] | andreyLetenkovWefox | 9 |
adamerose/PandasGUI | pandas | 210 | PandasGUI in Ubuntu | Any idea on how to solve this issue?
Thanks
PandasGUI INFO — pandasgui.gui — Opening PandasGUI
libGL error: MESA-LOADER: failed to open radeonsi: /usr/lib/dri/radeonsi_dri.so: cannot open shared object file: No such file or directory (search paths /usr/lib/x86_64-linux-gnu/dri:\$${ORIGIN}/dri:/usr/lib/dri, suffix ... | open | 2022-08-30T01:49:32Z | 2022-08-30T01:49:32Z | https://github.com/adamerose/PandasGUI/issues/210 | [] | mfdphd | 0 |
microsoft/qlib | deep-learning | 1,771 | DDG-DA NaN loss | ## 🐛 Bug Description
<!-- A clear and concise description of what the bug is. -->
## To Reproduce
Steps to reproduce the behavior:
1. download the repo with git clone https://github.com/microsoft/qlib.git
2. install qlib with cd qlib and pip install .
3. cd examples/benchmark_dynamic/DDG-DA/
4. run DDG... | closed | 2024-03-27T18:08:22Z | 2024-05-01T03:24:15Z | https://github.com/microsoft/qlib/issues/1771 | [
"bug"
] | l0ngc | 3 |
PaddlePaddle/PaddleHub | nlp | 1,612 | paddlehub同类语义范例中,加载ernie模型后,调用方法报错 | 请帮看看如下问题
paddlehub 2.1.0
paddlenlp 2.0.7
paddlepaddle-gpu 2.1.2.post101
python3.7
https://aistudio.baidu.com/bdvgpu/user/621532/2342769/notebooks/2342769.ipynb
module = hub.Module(name="ernie")
**#AttributeError: 'Ernie' object has no attribute... | open | 2021-09-07T03:49:50Z | 2021-09-08T07:48:21Z | https://github.com/PaddlePaddle/PaddleHub/issues/1612 | [
"nlp"
] | conquer66666 | 6 |
prkumar/uplink | rest-api | 225 | Support *args **kwargs to built in converters (e.g. pydantic by_alias) | **Is your feature request related to a problem? Please describe.**
Pydantic is supported out of the box but I can't use it to serialize when using field aliases.
Pydantic has support for this but I don't see a way to pass this information in Uplink.
Say I have a pydantic model like the following. The API uses came... | open | 2021-06-08T17:41:30Z | 2022-10-03T17:39:00Z | https://github.com/prkumar/uplink/issues/225 | [] | jkornblum | 4 |
axnsan12/drf-yasg | rest-api | 422 | AttributeError: module 'ruamel.yaml' has no attribute 'SafeDumper' | Hello! After docker image build, trying to run containers via docker-compose up, and facing error:
Traceback (most recent call last):
django_1 | File "manage.py", line 21, in <module>
django_1 | main()
django_1 | File "manage.py", line 17, in main
django_1 | execute_from_command_line(sys.... | closed | 2019-07-26T10:52:12Z | 2019-09-29T15:41:58Z | https://github.com/axnsan12/drf-yasg/issues/422 | [] | Almaz97 | 2 |
jupyter/nbgrader | jupyter | 1,404 | manually grader raises error | <!--
Thanks for helping to improve nbgrader!
If you are submitting a bug report or looking for support, please use the below
template so we can efficiently solve the problem.
If you are requesting a new feature, feel free to remove irrelevant pieces of
the issue template.
-->
### Operating system: Ubunt... | closed | 2020-12-29T15:25:00Z | 2021-03-26T07:49:10Z | https://github.com/jupyter/nbgrader/issues/1404 | [
"duplicate"
] | donatog | 4 |
fastapi/sqlmodel | sqlalchemy | 535 | [M2M] Query dependent incl. `link_model` fields | ### First Check
- [X] I added a very descriptive title to this issue.
- [X] I used the GitHub search to find a similar issue and didn't find it.
- [X] I searched the SQLModel documentation, with the integrated search.
- [X] I already searched in Google "How to X in SQLModel" and didn't find any information.
- [X... | open | 2023-01-23T14:41:34Z | 2024-04-02T20:51:44Z | https://github.com/fastapi/sqlmodel/issues/535 | [
"question"
] | Pk13055 | 3 |
viewflow/viewflow | django | 242 | NSubprocess View Error |
there is no subprocess property
`
for subprocess in activation.subprocesses
should be replaced with
for subprocess in activation.subprocesses()
`
| closed | 2019-05-16T21:51:34Z | 2019-05-27T09:49:10Z | https://github.com/viewflow/viewflow/issues/242 | [] | ivan-fedorov-probegin | 1 |
httpie/http-prompt | rest-api | 76 | malformed URL not handled (unexpected ":") | When one replaces in an URL a dot by a colon, an exception is not caught:
```
C:\>http-prompt https://google:com
Version: 0.5.0
Traceback (most recent call last):
File "c:\users\yop\appdata\local\programs\python\python35-32\lib\runpy.py", line 184, in _run_module_as_main
"__main__", mod_spec)
File "c:\users\y... | closed | 2016-09-08T16:58:50Z | 2016-09-20T13:45:29Z | https://github.com/httpie/http-prompt/issues/76 | [
"bug"
] | wsw70 | 1 |
django-import-export/django-import-export | django | 1,954 | Export breaks if Field description contains space | **Describe the bug**
```python
class BookResource(ModelResource):
name = Field(attribute="author__name", column_name="Author Name")
class Meta:
fields = ("Author Name", )
model = Book
```

| closed | 2024-09-20T08:02:06Z | 2024-09-21T14:06:27Z | https://github.com/django-import-export/django-import-export/issues/1954 | [
"bug"
] | matthewhegarty | 1 |
roboflow/supervision | deep-learning | 1,554 | Allow TIFF (and more) image formats in `load_yolo_annotations` | ### Search before asking
- [X] I have searched the Supervision [issues](https://github.com/roboflow/supervision/issues) and found no similar feature requests.
### Description
* Currently, `load_yolo_annotations` only allows `png,` `jpg`, and `jpeg` file formats. `load_yolo_annotations` is internally called b... | closed | 2024-09-28T15:04:57Z | 2025-01-19T13:02:38Z | https://github.com/roboflow/supervision/issues/1554 | [
"enhancement",
"hacktoberfest"
] | patel-zeel | 11 |
art049/odmantic | pydantic | 357 | Using the union operator in model breaks | # Bug
Using the union operator `|` within a model's Field type, breaks in pydantic with `TypeError: type 'types.UnionType' is not subscriptable`
### Current Behavior
Add a model with the union operator:
```python
class Media(Model):
value: str | None = None
```
The code currently fails with:
```
... | open | 2023-06-01T13:19:42Z | 2024-01-05T07:05:17Z | https://github.com/art049/odmantic/issues/357 | [
"bug"
] | iamKunal | 1 |
flasgger/flasgger | api | 1 | Load UI parameters from /spec | Load dynamically options like Expand etc..
| closed | 2015-07-29T21:54:47Z | 2017-03-24T20:07:07Z | https://github.com/flasgger/flasgger/issues/1 | [] | rochacbruno | 0 |
tqdm/tqdm | pandas | 1,542 | PackageNotFoundError | Traceback (most recent call last):
File "main.py", line 4, in <module>
File "PyInstaller\loader\pyimod02_importers.py", line 419, in exec_module
File "whisperx\__init__.py", line 1, in <module>
File "PyInstaller\loader\pyimod02_importers.py", line 419, in exec_module
File "whisperx\transcribe.py", line 9... | open | 2023-12-26T09:54:06Z | 2023-12-26T09:54:06Z | https://github.com/tqdm/tqdm/issues/1542 | [] | WhozKunal | 0 |
davidsandberg/facenet | tensorflow | 438 | Why using SVM to train in the facenet/src/classifier.py training process | 你好,git 上的davidsandberg/facenet 是对facenet 完全的实现么
他的acenet/src/classifier.py train model.fit(emb_array, labels) (#96)中 训练 是直接使用SVM ,这与和 facenet貌似没什么关系
Hello, the training of acenet/src/classifier.py "model.fit (emb_array, labels) (#96)" used SVM, which seemed to have nothing to do with facenet。
| closed | 2017-08-24T03:01:39Z | 2019-03-27T00:56:25Z | https://github.com/davidsandberg/facenet/issues/438 | [] | yuanzhenjie | 6 |
hack4impact/flask-base | sqlalchemy | 199 | Heroku bundling issues | Hi, I am having a similar issue with #110, it seems like script ordering problems. This is after pushing to a heroku app. However as localhost everything renders correctly and does not throw the same errors.
Has anybody run into script bundling issues this when deploying to Heroku?
```
Uncaught SyntaxError: Unexpe... | closed | 2020-01-13T16:50:35Z | 2020-06-21T09:10:51Z | https://github.com/hack4impact/flask-base/issues/199 | [] | MapZombie | 2 |
microsoft/MMdnn | tensorflow | 131 | Save weights&bias in other format other than .npy. | Hi, I want to transform tensorflow model files into MMdnn IR and parsing them in C++, but the weights&bias data are saved in .npy format, which is not really meant to be read from outside NumPy. So can we save weights&bias data in other format during transformation, such as HDF? | closed | 2018-03-27T03:28:16Z | 2018-03-29T11:20:09Z | https://github.com/microsoft/MMdnn/issues/131 | [] | Mookel | 0 |
microsoft/unilm | nlp | 1,579 | unimim is still unavailable after one year | A year later, unimim still has not released the source code. A year ago, I spent a long time trying to replicate and analyze this paper, but was unable to do so. Are there any plans to make the source code of this paper available?
To be honest, I am a bit disappointed. | open | 2024-06-20T12:47:15Z | 2024-09-26T15:36:59Z | https://github.com/microsoft/unilm/issues/1579 | [] | jsrdcht | 3 |
litestar-org/litestar | asyncio | 3,011 | Docs: Document SSE | ### Summary
The SSE documentation is currently lacking:
- Docs for `ServerSentEventMessage`
- Sending messages a dicts | closed | 2024-01-21T18:49:38Z | 2025-03-20T15:54:20Z | https://github.com/litestar-org/litestar/issues/3011 | [
"Documentation :books:",
"Help Wanted :sos:",
"area/docs"
] | provinzkraut | 3 |
keras-team/keras | pytorch | 20,219 | mul got incompatible shapes for broadcasting | I'm trying to run this code in jax backend, and I've got a static inference shape result successfully. However, when I try to execute dynamically, I get this error message, which really confused me a lot.
Here is the code and what I got as results.
version:
python 3.10
keras 3.5.0
jax 0.4.31
```python
impo... | closed | 2024-09-06T08:52:04Z | 2024-10-17T02:02:20Z | https://github.com/keras-team/keras/issues/20219 | [
"stat:awaiting response from contributor",
"stale",
"type:Bug"
] | Isa-Fay | 7 |
CorentinJ/Real-Time-Voice-Cloning | deep-learning | 382 | Synthesizer training: loss exploded, has anybody seen this? | Here is the error:
in line 220 of Real-Time-Voice-Cloning-master/synthesizer/train.py", line 220
Loss exploded to nan at step 32
Exiting due to exception: Loss exploded
(believe loss=nan is causing this, but how loss ended up with NAN?)
Complete info:
(voice) goodman@goodman-dl-box:~/development/Real-Tim... | closed | 2020-06-26T23:14:33Z | 2020-07-24T06:31:30Z | https://github.com/CorentinJ/Real-Time-Voice-Cloning/issues/382 | [] | goodmangu | 2 |
ufoym/deepo | tensorflow | 119 | Is there any images support ubuntu16.04? | I find that the images pulled are from ubuntu18.04. So how can i get the earlier images? hope for your help. | closed | 2019-09-02T02:53:17Z | 2019-09-11T07:34:51Z | https://github.com/ufoym/deepo/issues/119 | [] | wyjforwjy | 2 |
python-security/pyt | flask | 45 | Blackbox functions return tainted value (false positives) | So, there are 2 commented out tests that I added during my interprocedural PR [here](https://github.com/python-security/pyt/blob/master/tests/vulnerabilities_across_files_test.py#L49) and [here](https://github.com/python-security/pyt/blob/master/tests/vulnerabilities_across_files_test.py#L67).
I was going to fix th... | closed | 2017-05-18T00:02:05Z | 2017-11-12T03:29:50Z | https://github.com/python-security/pyt/issues/45 | [] | KevinHock | 5 |
ultralytics/yolov5 | machine-learning | 12,753 | Did anyone calculate the number of calculations happen in YOLO model? | ### Search before asking
- [X] I have searched the YOLOv5 [issues](https://github.com/ultralytics/yolov5/issues) and [discussions](https://github.com/ultralytics/yolov5/discussions) and found no similar questions.
### Question
I know, how to calculate `computation cost` for a convolutional layer.
The computation... | closed | 2024-02-22T04:45:08Z | 2024-05-23T23:55:59Z | https://github.com/ultralytics/yolov5/issues/12753 | [
"question",
"Stale"
] | aravindchakravarti | 6 |
aleju/imgaug | deep-learning | 163 | Augmenting boxes - including empty lists of boxes | My problem is potentially with the design and not one specific bug.
I have multiple images to augment, and some of them have no objects in them, while others have bounding boxes. However, there is no way to signalize empty set of bounding boxes for particular image.
I can not pass None to the list of the boxes:
`A... | open | 2018-08-07T08:13:22Z | 2018-08-07T17:12:53Z | https://github.com/aleju/imgaug/issues/163 | [] | ikamensh | 1 |
littlecodersh/ItChat | api | 384 | 使用mac terminal 生成的二维码手机识别不出 | 尝试过 itchat.auto_login(enableCmdQR=2) 。 显示在terminal里面的二维码识别不出。
建议在README 让 关于Mac用户的设置改成
`itchat.auto_login(enableCmdQR= -2)`
希望可以采纳。谢谢
=====分割线======
刚刚又试了一下 有时能识别enableCmdQR=2, 有时能识别 enableCmdQR=-2。 | closed | 2017-05-30T03:10:09Z | 2017-06-09T02:54:21Z | https://github.com/littlecodersh/ItChat/issues/384 | [
"question"
] | YunyuZhang | 1 |
huggingface/diffusers | deep-learning | 10,677 | Support for training with Grayscale images? | I am trying to train an unconditional diffusion model on grayscale images using your [pipeline](https://huggingface.co/docs/diffusers/training/unconditional_training). When running training with the default parameters I discovered inferred images that contained colour (specifically green). Where it learnt such colours ... | open | 2025-01-28T22:25:19Z | 2025-02-28T15:02:57Z | https://github.com/huggingface/diffusers/issues/10677 | [
"stale"
] | DavidGill159 | 1 |
vitalik/django-ninja | django | 1,227 | [BUG] Primary keys are always marked as nullable | **Describe the bug**
As a result of #1181, all primary keys are now marked as nullable in ModelSchema, regardless of whether the field is set to nullable or not. I'm not sure why this was done, but I would expect it to defer to the field's own nullable setting instead if for some reason you have a nullable primary key... | open | 2024-07-11T14:38:51Z | 2024-08-02T18:22:47Z | https://github.com/vitalik/django-ninja/issues/1227 | [] | pmdevita | 3 |
dropbox/PyHive | sqlalchemy | 138 | For Presto, fetchall needs to be called even on non-result-returning queries | This is because execution is asynchronous in Presto. Failing to call fetchall results in ABANDONED_QUERY.
See also #123 | open | 2017-07-08T05:15:23Z | 2017-07-08T05:15:31Z | https://github.com/dropbox/PyHive/issues/138 | [
"bug"
] | jingw | 0 |
Evil0ctal/Douyin_TikTok_Download_API | web-scraping | 452 | [BUG] 一个星期前使用Web app过并且成功下载了200+视频,但是这个星期突然不行了,按照视频教程更换了Cookie,仍然不行 | ***发生错误的平台?***
如:抖音
***发生错误的端点?***
如:Web APP
***提交的输入值?***
如:短视频链接
***是否有再次尝试?***
如:是,发生错误后X时间后错误依旧存在。
***你有查看本项目的自述文件或接口文档吗?***
如:有,并且很确定该问题是程序导致的。
这是我的Cookie,已经按照了视频教程重复过多次,并且在一个星期前已经成功下载了200+视频,但是不知道为什么最近这几天突然出现视频教程中的情况突然不能解析了,有可能是我的Cookie除了问题吗?
ttwid=1%7C-0dflMMeBDApYTLvDCHU5M9zmhMbAw... | closed | 2024-07-17T08:47:35Z | 2024-07-27T21:53:09Z | https://github.com/Evil0ctal/Douyin_TikTok_Download_API/issues/452 | [
"BUG"
] | Losoy1 | 6 |
flairNLP/flair | pytorch | 3,489 | [Bug]: TextRegressor breaks due to unrelated labels | ### Describe the bug
`TextRegressor._labels_to_tensor` iterates over every label on the sentence; not just the regression label specified by `self.label_name`. This leads to unexpected behavior.
For example, TextRegressor cannot be used as part of a multitask model. `_labels_to_tensor` will attempt to convert th... | closed | 2024-07-03T23:34:03Z | 2024-07-04T14:58:26Z | https://github.com/flairNLP/flair/issues/3489 | [
"bug"
] | sheldon-roberts | 0 |
quantmind/pulsar | asyncio | 153 | `Connection` object can not pickle | `Connection` object can not pickle
| closed | 2015-07-08T05:43:07Z | 2015-07-09T19:23:16Z | https://github.com/quantmind/pulsar/issues/153 | [
"won't fix"
] | nmg1986 | 3 |
marimo-team/marimo | data-visualization | 4,190 | Docker module does not work | ### Describe the bug
When I attempt to use the `DockerClient` class to connect to a docker enginer I get a `DockerException`.
```
Traceback (most recent call last):
File "/lib/python3.12/site-packages/urllib3/contrib/emscripten/connection.py", line 116, in request
self._response = send_streaming_request(request... | closed | 2025-03-21T14:51:35Z | 2025-03-21T20:36:02Z | https://github.com/marimo-team/marimo/issues/4190 | [
"bug",
"upstream"
] | dchassin | 13 |
tfranzel/drf-spectacular | rest-api | 645 | Spectacular Swagger-UI view (doesn't render in browser) | I am attempting to get the swagger-ui to render using SpectacularSwaggerView.as_view(), but when I access the URL in the browser it just downloads the spec and doesn't render the Swagger-UI,
I am defining my schema routes as follows,
re_path(r"^(?P<version>(v2))/schema/$", SpectacularAPIView.as_view(), name='... | closed | 2022-01-28T16:26:12Z | 2024-02-12T16:54:24Z | https://github.com/tfranzel/drf-spectacular/issues/645 | [] | jd-dev-pneu | 13 |
tensorlayer/TensorLayer | tensorflow | 337 | deformable conv2d missing function | https://github.com/tensorlayer/tensorlayer/pull/234 | closed | 2018-02-19T15:28:11Z | 2018-02-19T15:46:57Z | https://github.com/tensorlayer/TensorLayer/issues/337 | [] | zsdonghao | 2 |
ShishirPatil/gorilla | api | 581 | [BFCL] Issue with temporal models/function calling | New models like Llama 3.1 have the "Cutting Knowledge Date" and the current date built into the system prompt. With these, some of the test cases need to be updated.
Example: #183, `simple` has this parameter:
```
"year": {
"type": "integer",
"description": "The year in which the lawsuit ... | closed | 2024-08-14T01:31:10Z | 2024-09-09T07:37:54Z | https://github.com/ShishirPatil/gorilla/issues/581 | [
"enhancement",
"BFCL-General"
] | aw632 | 1 |
onnx/onnxmltools | scikit-learn | 380 | Conveting from h2o to onnx failing | Upon calling `onnxmltools.convert_h20()`
> Getting **AttributionError : module 'onnxmltools.convert.common.utils' has no attribute 'h2o_installed'**
so upon checking file onnxmltools/onnxmltools/convert/common/**utils.py**
I found single line
`from onnxconverter_common.utils import *
`
which is basica... | closed | 2020-04-01T11:01:10Z | 2020-04-01T19:32:00Z | https://github.com/onnx/onnxmltools/issues/380 | [] | divatemangesh | 1 |
tensorflow/tensor2tensor | machine-learning | 1,378 | About the '_rev' in translation problem when using two vocabularies | ### Description
Hi, guys. I have an error when using the 'translate_enzh_wmt32k_rev' problem for decoding.
It was fine during training with the reverse problem name but interrupted when decoding.
...
### Environment information
```
OS: Ubuntu 16.04
$ pip freeze | grep tensor
tensorflow-gpu == 1.12.0
tens... | open | 2019-01-17T07:33:59Z | 2019-02-21T10:46:40Z | https://github.com/tensorflow/tensor2tensor/issues/1378 | [] | Changl14 | 2 |
Kanaries/pygwalker | matplotlib | 59 | UnicodeDecodeError: 'gbk' codec can't decode byte 0x94 in position 357182: illegal multibyte sequence | CODE:
import pandas as pd
import pygwalker as pyg
df = pd.read_csv(r'E:\VSCODE\QSPR_loss_cal\2.csv')
gwalker = pyg.walk(df)
ERROR:
UnicodeDecodeError Traceback (most recent call last)
Cell In[13], line 5
2 import pygwalker as pyg
4 df = pd.read_csv(r'E:\VSCODE\QSPR_loss_c... | closed | 2023-03-04T12:28:11Z | 2023-03-04T12:57:29Z | https://github.com/Kanaries/pygwalker/issues/59 | [] | midas628 | 3 |
sqlalchemy/alembic | sqlalchemy | 1,391 | Computed statements containing newlines cause warnings on autogenerate | **Describe the bug**
When using ORM code that contains multi-line computed statements, they always generate warnings when being fed into Alembic. Like this:
```py
class MyModel(Base):
...
whatever: Mapped[int] = mapped_column(Computed("""1
+ 2""")) # just a simple multi-line expression for demo ... | closed | 2024-01-09T18:21:51Z | 2024-01-15T15:09:51Z | https://github.com/sqlalchemy/alembic/issues/1391 | [
"autogenerate - detection",
"use case"
] | GeorchW | 2 |
graphistry/pygraphistry | jupyter | 610 | [FEA] store node, edge file_id and dataset_id | **Is your feature request related to a problem? Please describe.**
In python flows like `g.plot()`, it would be quite handy to be able to get the `node_file_id`, `edge_file_id`, and `dataset_id`
This came up in some recent testing work. with the new remote endpoints, presumably, this will become even more natura... | open | 2024-11-01T04:21:02Z | 2024-11-01T04:22:12Z | https://github.com/graphistry/pygraphistry/issues/610 | [
"enhancement",
"help wanted"
] | lmeyerov | 0 |
pallets/flask | flask | 5,131 | After switching to latest flask, app timeouts on some requests | When I wanted to upgrade from 2.2.x to 2.3.x I encountered problem with timeouts on some requests, without any error log about it.
Any ideas please ? What can cause it?
- Python version: 3.10
- Flask version: 2.3.2
- gunicorn: 20.1.0
- gevent: 22.10.2
- nginx: 1.18.0 | closed | 2023-05-17T14:30:07Z | 2023-05-17T14:38:36Z | https://github.com/pallets/flask/issues/5131 | [] | pipozzz | 0 |
gunthercox/ChatterBot | machine-learning | 2,311 | Is this project being maintained? | Is this project being maintained?
Is it still available...? | closed | 2023-05-13T10:53:56Z | 2025-03-01T21:11:47Z | https://github.com/gunthercox/ChatterBot/issues/2311 | [] | creeper-0910 | 26 |
shibing624/text2vec | nlp | 145 | text2vec中,关于token与汉字字符换算 | 模型中max_seq_length指的应该是模型能处理的最大token数,我想问下,这个模型中的token跟汉字字符是一个大概什么样比例的换算关系,我在一个博客上看到在text2vec上是1token约等于1.5个汉字,请问这个结论对吗? | open | 2023-12-26T01:33:44Z | 2023-12-26T10:40:51Z | https://github.com/shibing624/text2vec/issues/145 | [
"question"
] | cutelitchi | 1 |
ultralytics/ultralytics | computer-vision | 18,926 | i have geting problem while processing result (converted custom trained yolov8n model to openvino) | ### Search before asking
- [x] I have searched the Ultralytics YOLO [issues](https://github.com/ultralytics/ultralytics/issues) and [discussions](https://github.com/orgs/ultralytics/discussions) and found no similar questions.
### Question
i am geting probelem in processing returned result from openvino result
imp... | open | 2025-01-28T08:12:48Z | 2025-01-29T12:58:49Z | https://github.com/ultralytics/ultralytics/issues/18926 | [
"question",
"detect",
"exports"
] | Vinaygoudasp7 | 16 |
cchen156/Learning-to-See-in-the-Dark | tensorflow | 101 | Library versions | Hello. Which version of numpy and scipy did you use? | open | 2020-01-15T07:44:11Z | 2020-01-15T07:44:11Z | https://github.com/cchen156/Learning-to-See-in-the-Dark/issues/101 | [] | amandaliviani | 0 |
sktime/sktime | data-science | 7,594 | [ENH] design question: what should clusterers with `capability:out_of_sample = False` do when `predict` sees new data? | Issue for design discussion: what should clusterers with `capability:out_of_sample = False` do when `predict` sees new data?
The general issue is, clusterers have a taggable property called `capability:out_of_sample` - if this is `False`, the `X` in `predict` must be the same as in `fit`. This property does not occu... | open | 2025-01-02T13:25:33Z | 2025-01-03T00:40:17Z | https://github.com/sktime/sktime/issues/7594 | [
"API design",
"module:clustering",
"enhancement"
] | fkiraly | 2 |
coqui-ai/TTS | python | 2,652 | IndexError in train.py demo | ### Describe the bug
I tried the train.py demo in Python 3.10 Ubuntu but I get this error:
```
line 59, in <module>
train_samples, eval_samples = load_tts_samples(
IndexError: list index out of range
```
### To Reproduce
Run any training demo (example: recipes/ljspeech/vits-tts/train_vits.py
### Expected b... | closed | 2023-06-05T06:41:48Z | 2023-06-29T19:23:01Z | https://github.com/coqui-ai/TTS/issues/2652 | [
"bug"
] | guighub | 4 |
noirbizarre/flask-restplus | api | 330 | Download link in SwaggerUI corrupts the file (changes the encoding) | Hi,
There is an issue (basically swagger messes up the encoding of the file) when adding binary data into Response, that seems to be originated in Swagger (https://github.com/swagger-api/swagger-ui/issues/2132).
It seems that the issue is solved in version 2.2.10 ? Do you have any plans of upgrading swagger or pat... | open | 2017-09-28T13:49:37Z | 2018-02-08T18:50:41Z | https://github.com/noirbizarre/flask-restplus/issues/330 | [] | naeioan | 3 |
DistrictDataLabs/yellowbrick | scikit-learn | 698 | RTD webhook needs to be updated | Hello!
Your project, Yellowbrick, is currently using GitHub Services to trigger builds on Read the Docs.
Effective January 31, 2019, GitHub will no longer process requests using the Services feature, and so Read the Docs will not receive notifications on updates to your repository.To continue building your Read ... | closed | 2019-01-28T16:35:22Z | 2019-01-28T16:45:47Z | https://github.com/DistrictDataLabs/yellowbrick/issues/698 | [
"type: task"
] | bbengfort | 2 |
databricks/koalas | pandas | 1,362 | Job aborted due to stage failure when running in AWS EMR | I set up an EMR 6.0.0 Cluster on AWS. I then added an EMR notebook, and installed Koalas in it. When I try to run the [Getting Started](https://koalas.readthedocs.io/en/latest/getting_started/10min.html), at point 3, I get:
```
An error occurred while calling o166.collectToPython.
: org.apache.spark.SparkException... | closed | 2020-03-23T13:31:28Z | 2020-08-17T06:49:26Z | https://github.com/databricks/koalas/issues/1362 | [
"not a koalas issue"
] | rabejens | 4 |
nerfstudio-project/nerfstudio | computer-vision | 3,324 | Metashape data processing doesn't use adjusted camera calibration parameters | In an exported Metashape cameras XML file there are (at least sometimes) two sets of camera calibration parameters: the initial and adjusted parameters. I assume the adjusted calibration parameters are better, but Nerfstudio uses the initial ones.
Here's an extract from the cameras XML:
```xml
<?xml version="1.0" ... | open | 2024-07-22T15:14:25Z | 2024-07-22T15:14:25Z | https://github.com/nerfstudio-project/nerfstudio/issues/3324 | [] | Akkete | 0 |
seleniumbase/SeleniumBase | pytest | 2,759 | When using ThreadPoolExecutor, a minor problem occurs. | Now, I'm using like below.
``` python
def setup_driver() -> Driver:
driver = Driver(browser="chrome", headless=True, no_sandbox=True)
return driver
```
``` python
# def crawling(driver): driver = setup_driver() driver.get(url) ...
with ThreadPoolExecutor(max_workers=4) as executor:
results[A... | closed | 2024-05-07T06:30:09Z | 2024-05-07T13:18:00Z | https://github.com/seleniumbase/SeleniumBase/issues/2759 | [
"invalid usage"
] | hwk06023 | 1 |
oegedijk/explainerdashboard | plotly | 160 | using explainerdashboard with H2OAutoMLClassifier | Hi!
Thanks for making the explainerdashboard, it seems to be a great tool for data scientists!
I have a question: Is it possible to run ClassifierExplainer on H2O models, such as H2OAutoMLClassifier? It seems to be a sklearn wrapper for the H2OAutoML module.
(https://github.com/h2oai/h2o-tutorials/blob/master/tuto... | closed | 2021-11-25T10:22:50Z | 2021-12-23T19:15:43Z | https://github.com/oegedijk/explainerdashboard/issues/160 | [] | luchpa | 4 |
yzhao062/pyod | data-science | 501 | can not save deepsvdd models | when i try to save trained deepsvdd model with code "dump", I got this error "TypeError: can't pickle _thread.RLock objects", please tell me how to solve it. | open | 2023-05-22T11:34:11Z | 2023-05-22T11:34:11Z | https://github.com/yzhao062/pyod/issues/501 | [] | zhouyongxiu | 0 |
scikit-hep/awkward | numpy | 2,555 | `ak.num` should raise an `AxisError` when counting string characters | ### Version of Awkward Array
main
### Description and code to reproduce
I'm of the view that it's so easy to change types in Awkward, we should be stricter about the difference between e.g. a string and a list of characters. As such, `ak.num` should validate `purelist_depth` to ensure that the operation is valid. | open | 2023-07-01T20:55:20Z | 2023-07-01T20:55:20Z | https://github.com/scikit-hep/awkward/issues/2555 | [
"bug"
] | agoose77 | 0 |
holoviz/panel | plotly | 7,391 | Support VTK + Trame | [Trame](https://www.kitware.com/trame/) integration with Panel has been an ask for a while (see https://github.com/holoviz/panel/issues/4761), especially as the vtk.js serializer used within Panel is not as up-to-date as the one in Trame. It's possible to do this within an `iframe` via:
https://github.com/pyvista/pa... | open | 2024-10-12T18:03:04Z | 2024-10-12T20:19:27Z | https://github.com/holoviz/panel/issues/7391 | [] | akaszynski | 2 |
globaleaks/globaleaks-whistleblowing-software | sqlalchemy | 3,011 | GDPR Compliance: make it possible for users to download their data | Make it possible for admins and recipients to ask to download their own data on a GlobaLeaks platform ([Art.17](https://gdpr-info.eu/art-17-gdpr/)). Check how other platforms make it for examples. Important to understand what constitutes users data in the context of a whistleblowing system. | open | 2021-05-22T11:57:12Z | 2021-05-23T16:38:21Z | https://github.com/globaleaks/globaleaks-whistleblowing-software/issues/3011 | [
"T: Feature",
"F: GDPR"
] | cyberflaneuse | 0 |
fastapi/sqlmodel | sqlalchemy | 152 | SQLModel creates an index for every field in SQLite | ### First Check
- [X] I added a very descriptive title to this issue.
- [X] I used the GitHub search to find a similar issue and didn't find it.
- [X] I searched the SQLModel documentation, with the integrated search.
- [X] I already searched in Google "How to X in SQLModel" and didn't find any information.
- [X] I al... | closed | 2021-11-06T10:03:43Z | 2021-12-29T03:34:42Z | https://github.com/fastapi/sqlmodel/issues/152 | [
"question"
] | rabinadk1 | 2 |
dunossauro/fastapi-do-zero | sqlalchemy | 147 | A construção do docker do fastzero_app falha no código-fonte das Aulas 10 a 12 | @dunossauro
Olá.
Gostaria de relatar um problema encontrado relacionado ao título mencionado. Vou enviar um pull request em breve.
# Conteúdo
Ao clonar o repositório principal mais recente e executar `docker build -t "fast_zero"` . usando o código-fonte da Aula 10 a 12, ocorreu o seguinte erro:
```bash
❯ docke... | closed | 2024-05-21T04:33:15Z | 2024-05-24T01:19:31Z | https://github.com/dunossauro/fastapi-do-zero/issues/147 | [] | K-dash | 5 |
geex-arts/django-jet | django | 159 | Replacing my logo (image) with 'Django Administration' | Hi,
What is the best practice for replacing my company's logo file with the 'Django Administration' title?
Thx! | open | 2016-12-20T15:00:21Z | 2020-01-28T09:52:35Z | https://github.com/geex-arts/django-jet/issues/159 | [] | ghost | 16 |
graphql-python/graphene-sqlalchemy | graphql | 39 | Fragments doesn't seem to work | Graphene does not seem to resolve the other object Type using fragments in the query.
Here is my schema:
```python
class User(db.Model):
__tablename__ = 'tbl_users'
id = Column(String(40), primary_key=True)
username = Column(String(64), index=True, unique=True)
email = Column(String(64), ... | closed | 2017-04-03T06:07:49Z | 2023-02-26T00:53:17Z | https://github.com/graphql-python/graphene-sqlalchemy/issues/39 | [] | richmondwang | 1 |
deepspeedai/DeepSpeed | machine-learning | 5,704 | on Activation Checkpointing | I want to use [Activation Checkpointing](https://www.deepspeed.ai/docs/config-json/) in my project, as the activation values cost much GPU memory,I need to significantly reduce GPU memory usage.
When I set the config json like this, The memory remains the same. It doesn't work!
```
"activation_checkpointing": {
... | closed | 2024-06-28T11:51:45Z | 2024-08-03T11:10:21Z | https://github.com/deepspeedai/DeepSpeed/issues/5704 | [
"bug",
"training"
] | ChaunceyWang | 7 |
ultralytics/yolov5 | pytorch | 13,529 | drone resolutions for input yolov5 | ### Search before asking
- [x] I have searched the YOLOv5 [issues](https://github.com/ultralytics/yolov5/issues) and [discussions](https://github.com/ultralytics/yolov5/discussions) and found no similar questions.
### Question
halo
I am using a drone and trying to detect rice fields using yolov5. after successfull... | open | 2025-03-10T09:03:52Z | 2025-03-15T22:39:39Z | https://github.com/ultralytics/yolov5/issues/13529 | [
"question",
"detect"
] | pepsodent72 | 9 |
jina-ai/serve | fastapi | 6,127 | `StableLM` example from the homepage doesn't work properly. | I was going through the small example on the [homepage of the docs](https://docs.jina.ai/), and it gives me a weird error:
```console
WARNI… gateway@6246 Getting endpoints failed: failed to connect to all [12/09/23 07:58:35]
addresses. Waiting for another trial ... | closed | 2023-12-09T08:21:00Z | 2023-12-11T12:20:43Z | https://github.com/jina-ai/serve/issues/6127 | [] | codetalker7 | 14 |
tqdm/tqdm | pandas | 1,524 | CLI: Does not work with bash `continue` | - [ ] I have marked all applicable categories:
+ [x] documentation request (i.e. "X is missing from the documentation." If instead I want to ask "how to use X?" I understand [StackOverflow#tqdm] is more appropriate)
+ [ ] new feature request
- [ ] I have visited the [source website], and in particular
rea... | open | 2023-10-19T09:12:01Z | 2023-10-19T09:12:16Z | https://github.com/tqdm/tqdm/issues/1524 | [] | LecrisUT | 0 |
modin-project/modin | pandas | 7,426 | Modin with Ray or Dask behaviour when cgroups linux thresholds are set | Hi,
Want to understand, does modin either with Ray or Dask respects cgroups threshold with workload pools of using only specific percentage of CPU or Memory, Or it still tries to utilize total system CPU or memory by default when disk spillover is enabled. | open | 2025-01-23T14:00:23Z | 2025-01-23T14:00:23Z | https://github.com/modin-project/modin/issues/7426 | [
"question ❓",
"Triage 🩹"
] | visheshgitrepo | 0 |
autogluon/autogluon | data-science | 3,989 | Support Pandas 2.2 | Currently the pandas version is limited to <2.2. Please support pandas 2.2.x as well.
| closed | 2024-03-18T22:32:07Z | 2024-04-11T21:45:07Z | https://github.com/autogluon/autogluon/issues/3989 | [
"enhancement",
"dependency"
] | fbreuer | 1 |
CorentinJ/Real-Time-Voice-Cloning | deep-learning | 759 | ModuleNotFoundError: No module named 'matplotlib' | I've installed all the required files and programs to execute it, but I can't seem to make it run
Here is my error:
`C:\Users\Owner>python` Documents\Real-Time-Voice-Cloning-master\demo_toolbox.py
Traceback (most recent call last):
File "C:\Users\Owner\Documents\Real-Time-Voice-Cloning-master\demo_toolbox.py", ... | closed | 2021-05-16T00:19:24Z | 2021-06-04T00:19:21Z | https://github.com/CorentinJ/Real-Time-Voice-Cloning/issues/759 | [] | HiloTakenaka | 3 |
deeppavlov/DeepPavlov | nlp | 902 | Training multi_squad_noans model? | When i run "python -m deeppavlov train deeppavlov/configs/squad/multi_squad_nouns.json" it is getting stuck and running through ages at line "Loading saved tokens vocab from */vocab_embedder.pckl" and finally server getting killed. Im even using GPU's. Have you faced such issue while training multi_squad_noans model. C... | closed | 2019-06-25T18:09:50Z | 2020-05-21T10:05:19Z | https://github.com/deeppavlov/DeepPavlov/issues/902 | [] | jayachandra2128 | 1 |
anapaulagomes/pytest-picked | pytest | 6 | Improve infos on README | Things to accomplish here:
- [ ] Remove "TODO" session
- [ ] Add gif with the demonstration of how to use it
- [ ] Add some examples with `git status` output
- [ ] Add badge for pypi
- [ ] Replace _ picked_ for _pytest-picked_ on LICENSE session | closed | 2018-05-27T16:05:27Z | 2018-06-27T07:49:30Z | https://github.com/anapaulagomes/pytest-picked/issues/6 | [
"enhancement"
] | anapaulagomes | 0 |
jupyter-book/jupyter-book | jupyter | 1,346 | Alternate citation styles not working | ## Describe the bug
I am trying to reproduce the alternate citation styles in the [docs](https://jupyterbook.org/content/citations.html?highlight=citations) but it seems all of them default to the numbered style.
See the rendered HTML:
<img width="710" alt="Screen Shot 2021-06-01 at 5 04 31 PM" src="https://use... | closed | 2021-06-02T00:14:01Z | 2021-06-23T17:08:45Z | https://github.com/jupyter-book/jupyter-book/issues/1346 | [
"bug"
] | firasm | 3 |
pydantic/pydantic-settings | pydantic | 421 | Add SOPS settings source for secrets | [SOPS](https://github.com/getsops/sops) is a simple and portable way of handling secrets. It would be nice if there was an integrated way of handling sops files similar to `AzureKeyVaultSettingsSource`. | closed | 2024-09-25T09:34:31Z | 2024-10-09T14:31:25Z | https://github.com/pydantic/pydantic-settings/issues/421 | [
"unconfirmed"
] | pavelzw | 2 |
xinntao/Real-ESRGAN | pytorch | 665 | Even faster inference with torch 2 | Not sure if this has been mentioned before.
I observe about 1.5-2x speed up using torch 2 (no tiling, no face enhancement, fp16), and a slight VRAM reduction on my NVIDIA A4000.
| Setup | Time per frame |
|-|-|
| No compile, channel_first | 1x |
| Torch 2, compile only ... | open | 2023-07-20T15:43:45Z | 2024-06-04T08:50:55Z | https://github.com/xinntao/Real-ESRGAN/issues/665 | [] | wacky6 | 4 |
ShishirPatil/gorilla | api | 424 | Java/Javascript split questions | 1. can we show the detailed scores for Java/Javascript splits on the leaderboard (instead of the averaged Simple function)? One observation I have from running the benchmark myself is that Prompt model seems to have more advantages over FC endpoints.
2. for Java types (Array/ArrayList/Hashmap), from the parsing code ... | open | 2024-05-11T05:00:24Z | 2024-07-01T11:51:44Z | https://github.com/ShishirPatil/gorilla/issues/424 | [] | vandyxiaowei | 2 |
amidaware/tacticalrmm | django | 1,936 | Duplicate Hostname in Email subject and body in Check/Task Failed messages | **Server Info (please complete the following information):**
- RMM Version (as shown in top left of web UI): 0.19.2
**Installation Method:**
- [x] Docker
**Agent Info (please complete the following information):**
- Agent version (as shown in the 'Summary' tab of the agent from web UI): 2.7.0
**Describe ... | open | 2024-07-26T08:59:02Z | 2024-07-26T08:59:02Z | https://github.com/amidaware/tacticalrmm/issues/1936 | [] | nescafe2002 | 0 |
Subsets and Splits
No community queries yet
The top public SQL queries from the community will appear here once available.