
repo_name stringlengths 9 75 | topic stringclasses 30
values | issue_number int64 1 203k | title stringlengths 1 976 | body stringlengths 0 254k | state stringclasses 2
values | created_at stringlengths 20 20 | updated_at stringlengths 20 20 | url stringlengths 38 105 | labels listlengths 0 9 | user_login stringlengths 1 39 | comments_count int64 0 452 |
|---|---|---|---|---|---|---|---|---|---|---|---|
strawberry-graphql/strawberry | django | 3,539 | feat: Excluding a field from a type by making it private | ## Describe the Bug/Feature
How to exclude a field from a type?
```py
@strawberry.type(name="File")
class FileType(DjangoFileType):
path: strawberry.Private[str]
```
**Current**: The `path` field still shows up in the schema.
**Expected**: No more `path` field exposed. | open | 2024-06-14T21:09:11Z | 2025-03-20T15:56:45Z | https://github.com/strawberry-graphql/strawberry/issues/3539 | [] | Eraldo | 4 |
junyanz/pytorch-CycleGAN-and-pix2pix | computer-vision | 1,114 | --input_nc 3 --output_nc 1 --lambda_identity 0 | i use` python train.py --dataroot ./datasets/data --name sar_cyclegan --model cycle_gan --input_nc 3 --output_nc 1 --lambda_identity 0` train the model
and `python test.py --dataroot ./datasets/data --name sar_cyclegan --model cycle_gan --output_nc 1` to test
but i get the image is 3 channel,i don't konw why | closed | 2020-08-03T15:54:26Z | 2020-09-04T07:15:17Z | https://github.com/junyanz/pytorch-CycleGAN-and-pix2pix/issues/1114 | [] | lucyLLLL | 1 |
stanford-oval/storm | nlp | 93 | Establish Clear Contribution Guidelines | As an open source project, there is a currently lack clear guidelines for contributors. This absence of documentation makes it challenging for new contributors to understand how to effectively participate in the project. Specifically, there's uncertainty around how to structure pull requests for code reviews and other ... | open | 2024-07-19T20:17:12Z | 2024-07-22T14:19:59Z | https://github.com/stanford-oval/storm/issues/93 | [] | rmcc3 | 1 |
onnx/onnxmltools | scikit-learn | 625 | Add source distribution to PyPI releases | Hi! I'm a maintainer of the [`onnxmltools` Conda feedstock](https://github.com/conda-forge/onnxmltools-feedstock).
You didn't ship a source distribution for your [1.11.1](https://pypi.org/project/onnxmltools/1.11.1/#files) and [1.11.2](https://pypi.org/project/onnxmltools/1.11.2/#files) releases on PyPI.
We rely ... | closed | 2023-05-19T06:56:30Z | 2023-05-31T13:43:34Z | https://github.com/onnx/onnxmltools/issues/625 | [] | janjagusch | 5 |
marcomusy/vedo | numpy | 515 | Continuous probing of a volume? | Looking at the probeLine2.py example, I can see that integer values are being obtained from probing the volume object, but how do you get an interpolated value? What I ultimately want to do is to take a mesh and construct a signed distance volume object. Then, given a set of points, probe the volume object to get an i... | closed | 2021-11-05T17:04:01Z | 2021-11-05T18:46:48Z | https://github.com/marcomusy/vedo/issues/515 | [] | DanKrsi | 2 |
google/seq2seq | tensorflow | 284 | InvalidArgumentError while training, when using a different dataset. | I used generate_vocab.py to create vocab.sources.txt and vocab.targets.txt files. Then when I run train I get the following error -
The vocab size for vocab.sources.txt is 135.
I use the example_configs/nmt_small.yml model.
This is the error I get: -
InvalidArgumentError (see above for traceback): Assign require... | open | 2017-07-25T21:08:31Z | 2017-07-27T00:25:54Z | https://github.com/google/seq2seq/issues/284 | [] | VatsalThrow | 2 |
slackapi/bolt-python | fastapi | 717 | Error in : dialogs_app.py | When i run this bolt python app and try to submit - the UI Screen just stuck without closing and it shows error - "We had some trouble connecting . Try Again"
i did a print and the UI accept and print the value in terminal but the dialog never close/submit.
| closed | 2022-09-13T01:34:15Z | 2022-09-13T06:49:17Z | https://github.com/slackapi/bolt-python/issues/717 | [
"question"
] | jambeshmpt | 9 |
gee-community/geemap | jupyter | 254 | Add WhiteboxTools GUI for JupyterLab and Jupyter Notebook | Currently, [WhiteboxTools](https://github.com/jblindsay/whitebox-tools) contains 447 tools for advanced geospatial analysis. The Tkinter-based WhiteboxTools GUI can only be invoked using a command prompt or Python code editor. It would be great to add GUI support for JupyterLab and Jupyter Notebook, which can greatly e... | closed | 2021-01-08T01:01:35Z | 2021-10-26T08:29:50Z | https://github.com/gee-community/geemap/issues/254 | [
"Feature Request"
] | giswqs | 3 |
deepinsight/insightface | pytorch | 2,531 | https://insightface.ai/demos is broken | Is there any plan to maintain the website? | open | 2024-02-23T03:27:39Z | 2024-02-23T03:27:39Z | https://github.com/deepinsight/insightface/issues/2531 | [] | sigpro | 0 |
plotly/dash | data-visualization | 2,629 | [BUG] Integrated JupyterDash fails to display running app. | **Describe your context**
```
dash 2.12.1
dash-bootstrap-components 1.4.2
dash-core-components 2.0.0
dash-html-components 2.0.0
dash-table 5.0.0
jupyter-dash 0.4.2
```
JupyterLab 3.6.1
**Describe the bug**
Using the JupyterDash integrated into th... | closed | 2023-08-22T10:37:41Z | 2023-11-22T17:16:15Z | https://github.com/plotly/dash/issues/2629 | [] | mmwinther | 10 |
alteryx/featuretools | data-science | 2,350 | Remove click and its associated functions | - We can reduce our package size by removing click, which isn't really that used in Featuretools | closed | 2022-10-31T21:02:23Z | 2022-11-03T20:30:20Z | https://github.com/alteryx/featuretools/issues/2350 | [] | gsheni | 0 |
unit8co/darts | data-science | 1,928 | [BUG] Unable to save TFTModel | **Describe the bug**
Dear darts-Team, I try to save a TFTModel with .save() and retrieve the following error message:
```python
In [1]: self.model.save(self.run.info.artifact_uri.replace("file://", "") + "/model.pt")
---------------------------------------------------------------------------
AttributeError ... | closed | 2023-08-01T07:57:08Z | 2024-01-21T15:33:32Z | https://github.com/unit8co/darts/issues/1928 | [
"bug",
"triage"
] | meteoDaniel | 10 |
tableau/server-client-python | rest-api | 1,211 | Failed to download image for view in workbook that has missing embedded credentials in another view. | **Describe the bug**
When attempting to download the image for a view in a workbook, the client returns an error if the workbook has missing embedded credentials in another view (even if the image for that view is not being downloaded)
**Versions**
Details of your environment, including:
- Tableau Server version... | closed | 2023-03-23T21:37:48Z | 2023-08-03T23:31:18Z | https://github.com/tableau/server-client-python/issues/1211 | [
"help wanted",
"wontfix"
] | mauropasi | 3 |
pywinauto/pywinauto | automation | 896 | Finding element by XPath in pywinauto | ## Actual Behavior
Finding element by XPath is convenient feature and it is not supported in current pywinauto version.
For now, finding elements needs much works in complex business desktop application.
Furthermore, I have to reference proper parent wrapper object to speed up when finding matched element by sever... | open | 2020-02-26T09:40:20Z | 2022-05-12T16:28:31Z | https://github.com/pywinauto/pywinauto/issues/896 | [
"enhancement"
] | rockdevmufasa | 2 |
nerfstudio-project/nerfstudio | computer-vision | 3,379 | Exported nerfacto point cloud has huge skybox surrounding it | Not sure if this is a bug, but has something changed with nerfacto point cloud export recently? The point clouds now have this enormous skybox surrounding it which is about 10 million points in this example. Same with world frame and remove outliers enabled and disabled.
https://www.youtube.com/watch?v=wP69fZ_taUE
... | open | 2024-08-23T13:15:50Z | 2024-08-24T21:43:42Z | https://github.com/nerfstudio-project/nerfstudio/issues/3379 | [] | gradeeterna | 6 |
tatsu-lab/stanford_alpaca | deep-learning | 27 | could be open source the model ? | hi ,dear
the model could be open source ?
| closed | 2023-03-15T04:35:51Z | 2023-03-15T13:42:15Z | https://github.com/tatsu-lab/stanford_alpaca/issues/27 | [] | ucas010 | 4 |
Skyvern-AI/skyvern | automation | 1,941 | API returns 404 | I followed the instructions in the readme.md, and installed it on my macbook pro with docker compose.
but the api returns 404, and the error message is {"detail":"Organization not found"}, please help.
Thanks in advance.
<img width="1294" alt="Image" src="https://github.com/user-attachments/assets/1a7dcb67-3aad-48c0-... | closed | 2025-03-16T05:46:46Z | 2025-03-19T05:23:04Z | https://github.com/Skyvern-AI/skyvern/issues/1941 | [] | treblam | 3 |
SciTools/cartopy | matplotlib | 2,419 | How exactly to use StadiaMaps instead of Stamen? | I'm getting **HTTP Error 404: Not Found** with my below test script (Note-my actual API-key from StadiaMaps is replaced with X below):
```
import matplotlib.pyplot as plt
import cartopy.crs as ccrs
from cartopy.io.img_tiles import Stamen
import cartopy.io.img_tiles as cimgt
class Stamen(cimgt.Stamen):
def ... | closed | 2024-07-25T07:58:25Z | 2024-07-30T06:39:37Z | https://github.com/SciTools/cartopy/issues/2419 | [] | Anto007 | 6 |
pyppeteer/pyppeteer | automation | 70 | SSLCertVerificationError | https://github.com/miyakogi/pyppeteer/issues/219
| closed | 2020-03-23T02:24:47Z | 2020-03-23T05:33:25Z | https://github.com/pyppeteer/pyppeteer/issues/70 | [
"bug"
] | leadscloud | 6 |
unionai-oss/pandera | pandas | 1,864 | DataFrame validation on initiation failed to raise error | **Describe the bug**
Dataframe validation on initiation fail to raise schema error for data that is of the wrong type or wrong value range. This does not happen in version 0.20.4
- [ x] I have checked that this issue has not already been reported.
- [ x] I have confirmed this bug exists on the latest version of pa... | closed | 2024-11-22T19:45:17Z | 2024-11-22T19:46:35Z | https://github.com/unionai-oss/pandera/issues/1864 | [
"bug"
] | Zionett | 1 |
Evil0ctal/Douyin_TikTok_Download_API | web-scraping | 27 | 连续下载需求 | 有一个app叫4k video downloader,它有个智能模式下载tiktok: 只要点击一个灯泡按钮,就会自动读出剪贴板里的地址,然后在UI里显示一条Log区域,先显示URL,解析完成,log区域就变成了nickname / video title / [download status]。多次数点击灯泡会显示多条log,一条条URL依次下载。
这个app最近有错误,无法正确解析URL了。所以今天我在github上发现了你的项目,试用了下觉得非常好。但是同时我也希望能有4k downloader这种流畅的下载体验。
我尝试修改你的项目,我目前只能把clear_file和tar file注释掉,下载路径设置到 ~/D... | open | 2022-05-17T15:28:47Z | 2023-02-13T15:10:02Z | https://github.com/Evil0ctal/Douyin_TikTok_Download_API/issues/27 | [
"enhancement"
] | Tairraos | 7 |
gevent/gevent | asyncio | 1,474 | Why doesn't gevent provide functions to replace requests etc' in case one wants to avoid monkey patching? | Essentially this question: https://stackoverflow.com/questions/58633378/why-doesnt-gevent-come-with-its-own-arsenal-of-functions-instead-of-monkey-pat?noredirect=1#comment103641315_58633378
| closed | 2019-11-02T12:07:29Z | 2019-11-03T06:39:50Z | https://github.com/gevent/gevent/issues/1474 | [] | uriva | 2 |
DistrictDataLabs/yellowbrick | matplotlib | 1,310 | InterclusterDistance AttributeError: 'NoneType' object has no attribute '_get_renderer' | Hi!
I've tried to install the InterclusterDistance and execute the example provided in the tutorials (code below) but
I am getting the following error AttributeError: 'NoneType' object has no attribute '_get_renderer' (report also below). I'm using jupyter lab and a virtual environment.
Could you be so kind as t... | open | 2023-09-20T11:00:28Z | 2023-10-24T17:40:05Z | https://github.com/DistrictDataLabs/yellowbrick/issues/1310 | [] | faiafederico | 2 |
CorentinJ/Real-Time-Voice-Cloning | pytorch | 1,076 | demo_toolbox.py running error | When I run demo_toolbox.py I get this errors
How can I fix this errors?
=====================================================
(VoiceCloning) A:\Real-Time-Voice-Cloning-master>python demo_toolbox.py
Traceback (most recent call last):
File "demo_toolbox.py", line 5, in <module>
from toolbox import Toolbox... | open | 2022-05-30T01:39:17Z | 2022-05-30T11:13:47Z | https://github.com/CorentinJ/Real-Time-Voice-Cloning/issues/1076 | [] | arteeeem1337 | 3 |
NullArray/AutoSploit | automation | 530 | Unhandled Exception (28bb33634) | Autosploit version: `3.0`
OS information: `Linux-4.18.0-kali2-amd64-x86_64-with-Kali-kali-rolling-kali-rolling`
Running context: `autosploit.py`
Error meesage: `[Errno 17] File exists: '/root/Desktop/webapp_exploit/AutoSploit/autosploit_out/2019-03-03_20h48m10s/'`
Error traceback:
```
Traceback (most recent call):
Fil... | closed | 2019-03-03T15:19:10Z | 2019-03-06T01:26:26Z | https://github.com/NullArray/AutoSploit/issues/530 | [] | AutosploitReporter | 0 |
yeongpin/cursor-free-vip | automation | 212 | [Bug]: Linux Path Not Found | ### Commit before submitting
- [x] I understand that Issues are used to provide feedback and solve problems, not to complain in the comments section, and will provide more information to help solve the problem.
- [x] I have checked the top Issue and searched for existing [open issues](https://github.com/yeongpin/curso... | closed | 2025-03-12T13:41:43Z | 2025-03-13T03:49:42Z | https://github.com/yeongpin/cursor-free-vip/issues/212 | [
"bug"
] | onurcanbaysal | 1 |
huggingface/datasets | machine-learning | 7,467 | load_dataset with streaming hangs on parquet datasets | ### Describe the bug
When I try to load a dataset with parquet files (e.g. "bigcode/the-stack") the dataset loads, but python interpreter can't exit and hangs
### Steps to reproduce the bug
```python3
import datasets
print('Start')
dataset = datasets.load_dataset("bigcode/the-stack", data_dir="data/yaml", streaming... | open | 2025-03-18T23:33:54Z | 2025-03-18T23:33:54Z | https://github.com/huggingface/datasets/issues/7467 | [] | The0nix | 0 |
iperov/DeepFaceLab | deep-learning | 5,667 | HELP! Merge96 won't work | I'm running on the RTX3000 series. I keep getting this long error and I have no idea what to do. This is on a completely new PC. My previous one didn't have any issues.
3070 TI
16 GB
--------------------------------------------------------------------------------------------------------------------------------... | open | 2023-05-04T01:51:13Z | 2023-06-08T23:18:16Z | https://github.com/iperov/DeepFaceLab/issues/5667 | [] | 0zymandia55 | 1 |
matterport/Mask_RCNN | tensorflow | 2,461 | Predict an extra input | I would like to create a flood level estimator that predicts the level each instance is submerged in. I have annotated the levels along with the other required annotations required in json file. The model predicts the classes and masks accurately but I'm stuck in where to modify to help it train and learn the level par... | open | 2021-01-13T17:12:39Z | 2021-01-13T17:13:12Z | https://github.com/matterport/Mask_RCNN/issues/2461 | [] | aarthy2000 | 0 |
autogluon/autogluon | scikit-learn | 3,909 | Documentation Update Request: Issues with Specifying Hyperparameters and Tuning Them Example | ### Describe the issue linked to the documentation
## Description:
I encountered multiple issues while following the example code provided in the [Specifying Hyperparameters and Tuning Them section](https://auto.gluon.ai/scoredebugweight/tutorials/tabular_prediction/tabular-indepth.html#specifying-hyperparameters-and... | closed | 2024-02-08T07:04:58Z | 2024-02-08T08:26:26Z | https://github.com/autogluon/autogluon/issues/3909 | [
"API & Doc",
"Needs Triage"
] | Chaozhuang22 | 0 |
shibing624/text2vec | nlp | 7 | wordembedding.embed计算的是每个单字的embedding而不是按照切好的词计算的 | a = "你好吗"
计算的是“你”,“好”,“吗”((3, 1, 200) 的平均值)而不是“你好”,“吗”的平均值
问题可能是wordembedding.embed中出现的
for sentence in sentence_list:
emb = [] | closed | 2020-02-20T09:16:16Z | 2020-05-14T03:47:27Z | https://github.com/shibing624/text2vec/issues/7 | [
"question",
"wontfix"
] | etrigger | 2 |
flasgger/flasgger | api | 608 | Data validation with swag_from doesn't work with OpenAPI 3 | A similar problem to #357 still exists if you want to validate with swag_from, as it expects a definition as parameter and doesn't work with components/schemas (OpenAPI 3)
The issue was found on flasgger 0.9.7.1 | open | 2024-01-25T12:01:02Z | 2024-01-25T12:01:02Z | https://github.com/flasgger/flasgger/issues/608 | [] | bsarkadi | 0 |
modelscope/data-juicer | data-visualization | 163 | Selector算子的意义是什么 | ### Before Asking 在提问之前
- [X] I have read the [README](https://github.com/alibaba/data-juicer/blob/main/README.md) carefully. 我已经仔细阅读了 [README](https://github.com/alibaba/data-juicer/blob/main/README_ZH.md) 上的操作指引。
- [X] I have pulled the latest code of main branch to run again and the problem still existed. 我已经拉取了主分... | closed | 2023-12-30T08:51:19Z | 2024-01-04T01:45:48Z | https://github.com/modelscope/data-juicer/issues/163 | [
"question"
] | echo-valor | 1 |
mars-project/mars | pandas | 2,805 | Use versioneer to manage release versions | [versioneer](https://github.com/python-versioneer/python-versioneer) is a tool for version management given VCS. It is a widely-used tool and can create version strings given tags and git changes. When applied, we do not need to bump versions in source code any more. | closed | 2022-03-10T08:44:05Z | 2022-03-10T22:41:40Z | https://github.com/mars-project/mars/issues/2805 | [
"mod: deploy",
"type: feature"
] | wjsi | 0 |
huggingface/datasets | numpy | 6,679 | Node.js 16 GitHub Actions are deprecated | `Node.js` 16 GitHub Actions are deprecated. See: https://github.blog/changelog/2023-09-22-github-actions-transitioning-from-node-16-to-node-20/
We should update them to Node 20.
See warnings in our CI, e.g.: https://github.com/huggingface/datasets/actions/runs/7957295009?pr=6678
> Node.js 16 actions are deprecat... | closed | 2024-02-19T09:47:37Z | 2024-02-28T06:56:35Z | https://github.com/huggingface/datasets/issues/6679 | [
"maintenance"
] | albertvillanova | 0 |
JaidedAI/EasyOCR | pytorch | 574 | always download model itself. | I am new to EasyOCR.
As the example in Readme.MD, using pip install easyocr, and runing the example.
I download the model from model hub, and put into ~/.EasyOCR/model,
```
$ ls -1 ~/.EasyOCR/model/
english_g2.zip
temp.zip
zh_sim_g2.zip
```
but, each time I run the code, it always show the downloading.
My ne... | closed | 2021-10-24T06:11:18Z | 2022-08-07T05:00:31Z | https://github.com/JaidedAI/EasyOCR/issues/574 | [] | q1208c | 7 |
healthchecks/healthchecks | django | 891 | Unable to configure ntfy access token | With commit [bbb06ff](https://github.com/healthchecks/healthchecks/commit/bbb06ff358226ba2c3a5f2b4e526eb2ab8ca3ce2), the ability to use an access token with healthchecks appears to have been added. However, when using the "latest" docker image [sha256-9b7323e548076857ac465f3d4dd2e9acc45da5ce387dc83a64e14285204df759](ht... | closed | 2023-09-10T19:56:49Z | 2023-09-11T07:07:36Z | https://github.com/healthchecks/healthchecks/issues/891 | [] | miversen33 | 1 |
neuml/txtai | nlp | 1 | Unable to install txtai, below is the error. I have installed c++ build tools | File "c:\users\gaussfer\anaconda3\lib\distutils\command\build_ext.py", line 340, in run
self.build_extensions()
File "C:\Users\Gaussfer\AppData\Local\Temp\pip-install-1drqoyp0\faiss-gpu\setup.py", line 50, in build_extensions
self._remove_flag('-Wstrict-prototypes')
File "C:\Users\Ga... | closed | 2020-08-12T15:22:30Z | 2021-05-13T14:58:41Z | https://github.com/neuml/txtai/issues/1 | [] | chintanckg | 5 |
deepspeedai/DeepSpeed | deep-learning | 5,573 | [BUG] Does deepspeed work with torch amp autocast? | During training, fp16 is set to true.
But for some submodules, i want to using fp32.
with torch.cuda.amp.autocast(enabled=False):
x = self.model(x.float())
#
An error occur, show half vs float type not matching | open | 2024-05-28T07:16:08Z | 2024-08-03T17:08:52Z | https://github.com/deepspeedai/DeepSpeed/issues/5573 | [
"bug",
"training"
] | lqniunjunlper | 1 |
huggingface/datasets | pandas | 6,562 | datasets.DownloadMode.FORCE_REDOWNLOAD use cache to download dataset features with load_dataset function | ### Describe the bug
I have updated my dataset by adding a new feature, and push it to the hub. When I want to download it on my machine which contain the old version by using `datasets.load_dataset("your_dataset_name", download_mode=datasets.DownloadMode.FORCE_REDOWNLOAD)` I get an error (paste bellow).
Seems that... | open | 2024-01-05T19:10:25Z | 2024-01-05T19:10:25Z | https://github.com/huggingface/datasets/issues/6562 | [] | LsTam91 | 0 |
streamlit/streamlit | deep-learning | 10,353 | Makes @st.cache_resource compatible with Cython | ### Checklist
- [x] I have searched the [existing issues](https://github.com/streamlit/streamlit/issues) for similar feature requests.
- [x] I added a descriptive title and summary to this issue.
### Summary
For a user program that uses `@st.cache_resource`, currently it is not possible to use Cython to compile the ... | closed | 2025-02-06T11:09:52Z | 2025-02-07T11:49:35Z | https://github.com/streamlit/streamlit/issues/10353 | [
"type:enhancement",
"feature:cache"
] | tutu-sol | 1 |
fastapi-users/fastapi-users | asyncio | 122 | How to use Oauth2 authentication in a Fastapi app ? | Just some thoughts as I try to understand how to use the Oauth2 implementation inside a fastapi app.
The official tutorial is here: https://fastapi.tiangolo.com/tutorial/security/oauth2-jwt/ and it is what I want to achieve.
As I already use this nice fastapi-users plugin I assume I can use it to simplify the in... | closed | 2020-03-07T11:35:03Z | 2020-03-09T09:12:23Z | https://github.com/fastapi-users/fastapi-users/issues/122 | [
"question"
] | MariusMez | 2 |
dunossauro/fastapi-do-zero | sqlalchemy | 283 | Revisar slides | Algumas alterações foram feitas na 2.2.1. Revisar todos os slides
- [ ] 00
- [ ] 01
- [ ] 02
- [ ] 03
- [ ] 04
- [ ] 05
- [ ] 06
- [ ] 07
- [ ] 08 - Precisam ser criados após #302
- [ ] 09
- [ ] 10
- [ ] 11
- [ ] 12
- [ ] 13 | open | 2025-01-23T20:33:42Z | 2025-03-11T19:30:52Z | https://github.com/dunossauro/fastapi-do-zero/issues/283 | [] | dunossauro | 0 |
jmcarpenter2/swifter | pandas | 146 | swifter install is stuck | Hey guys, using Python 3.9 here on my local (MacOS). Tried a simple pip install swifter in my venv, and have not been able to pass through this:
`INFO: pip is looking at multiple versions of ipykernel to determine which version is compatible with other requirements. This could take a while.
Collecting ipykernel>=4.... | closed | 2020-12-30T22:06:23Z | 2021-06-25T19:09:52Z | https://github.com/jmcarpenter2/swifter/issues/146 | [
"installation issue"
] | amankagarwal | 11 |
python-restx/flask-restx | flask | 441 | How to reuse the nested Resource methods in the encompassing Resource methods ? | I have a resource called `Profile` which nests a list of `Port` resources like so:
```json
{
"profile": "abcd"
"ports": [
{
"port": "5687"
"state": "state"
"protocol": "protocol"
"direction": "direction"
... | open | 2022-06-01T11:10:20Z | 2022-06-14T19:35:45Z | https://github.com/python-restx/flask-restx/issues/441 | [
"question"
] | realnitinworks | 3 |
pandas-dev/pandas | data-science | 61,071 | BUG: Potentially incorrect result of `df.rolling(window=...).mean()` | ### Pandas version checks
- [x] I have checked that this issue has not already been reported.
- [x] I have confirmed this bug exists on the [latest version](https://pandas.pydata.org/docs/whatsnew/index.html) of pandas.
- [ ] I have confirmed this bug exists on the [main branch](https://pandas.pydata.org/docs/dev/ge... | closed | 2025-03-06T20:12:51Z | 2025-03-07T09:23:59Z | https://github.com/pandas-dev/pandas/issues/61071 | [
"Bug",
"Window",
"Closing Candidate"
] | lazyniv | 2 |
dsdanielpark/Bard-API | api | 19 | How to continue an conversation? | Can you show me what I need to save so that Bard can remember the previous conversation without starting a new one after each question?
I'm trying to write it on PHP
I used Chrome Dev Tools to monitor and found SNlM0e and conversation_id unchanged, I tried saving it again but the result is not as expected | closed | 2023-05-18T14:26:09Z | 2023-05-22T06:58:17Z | https://github.com/dsdanielpark/Bard-API/issues/19 | [] | CatAnonymous | 7 |
Ehco1996/django-sspanel | django | 237 | dev 分支有 bug,last_use_time migrate 时报错 | ```
File "/usr/src/app/apps/sspanel/migrations/0017_auto_20190704_0243.py", line 9, in <module>
class Migration(migrations.Migration):
File "/usr/src/app/apps/sspanel/migrations/0017_auto_20190704_0243.py", line 48, in Migration
field=models.DateTimeField(db_index=True, default=DateTime(1996, 2, 2, 0, 0... | closed | 2019-07-04T02:53:42Z | 2019-07-08T12:21:07Z | https://github.com/Ehco1996/django-sspanel/issues/237 | [] | ghost | 1 |
qubvel-org/segmentation_models.pytorch | computer-vision | 350 | Multiclass segmentation, visualizing results | I have implemented a multiclass segmentation network, but I am confused to why the visualization of my predicted mask shows the wrong colors. As shown in the picture, the green class gets predicted to be yellow. But as the structure is correct, I don't think that it is actually predicting incorrectly, but that it is sh... | closed | 2021-02-19T14:13:14Z | 2021-03-23T09:00:34Z | https://github.com/qubvel-org/segmentation_models.pytorch/issues/350 | [] | Hampusli | 0 |
junyanz/pytorch-CycleGAN-and-pix2pix | pytorch | 820 | pix2pix single datasetmode error | Hi, thank you for this great project.
While I try to test pix2pix model with single dataset I struggle to solve the key error, but I couldn't.
Please help me how to solve this problem. I have no idea.
:
* https://github.com/onnx/onnx/pull/6164
* https://github.com/onnx/onnx/pull/6222
### Notes
I... | closed | 2024-07-19T19:22:24Z | 2024-07-30T15:32:49Z | https://github.com/onnx/onnx/issues/6239 | [
"question"
] | cjvolzka | 12 |
microsoft/Bringing-Old-Photos-Back-to-Life | pytorch | 200 | How to test: How should I test my own training data | closed | 2021-09-25T03:25:09Z | 2021-12-15T08:05:54Z | https://github.com/microsoft/Bringing-Old-Photos-Back-to-Life/issues/200 | [] | YuanLi95 | 0 | |
jina-ai/clip-as-service | pytorch | 612 | bert_base 运行出现报错 ValueError: Attempted to map inputs that were not found in graph_def: [segment_ids:0] | Process BertWorker-3:
Traceback (most recent call last):
File "/home/anaconda3/lib/python3.6/multiprocessing/process.py", line 258, in _bootstrap
self.run()
File "/home/anaconda3/lib/python3.6/site-packages/bert_base-0.0.9-py3.6.egg/bert_base/server/__init__.py", line 492, in run
self._run()
File "/... | open | 2020-12-08T02:04:24Z | 2020-12-08T02:04:24Z | https://github.com/jina-ai/clip-as-service/issues/612 | [] | SevenMpp | 0 |
google-research/bert | nlp | 800 | Performance metrics of the classifier | I used run_classifier.py to perform a sentence classification task, which is similar to Cola.
My question is how to get the recall score, precision score and f1 score, since the eval file only shows the result of accuracy.
Thanks! | open | 2019-08-12T15:54:02Z | 2021-02-09T11:06:31Z | https://github.com/google-research/bert/issues/800 | [] | chenty58 | 7 |
OWASP/Nettacker | automation | 184 | bug to http_fuzzer | my poc named "elasticsearch_unauthorized_access_poc" use model "http_fuzzer",
here is my poc results:
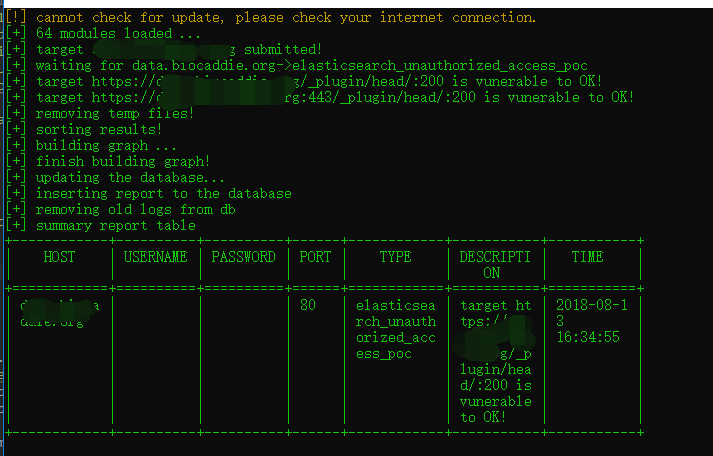
two ports match,but only show one raw !
_________________
**OS**: `windows`
**OS Version... | closed | 2018-08-13T08:51:39Z | 2021-02-02T20:57:55Z | https://github.com/OWASP/Nettacker/issues/184 | [
"possible bug"
] | aliluyala | 3 |
pydata/xarray | numpy | 10,130 | interp on chunked dimension can fail (oom) | ### What is your issue?
Hi,
I am using `interp` with `linear` method along a _sorted_ chunked dimension.
From the Dask dashboard I see workers failing and restarting, till it fails, with messages along the lines of:
```
distributed.nanny.memory - WARNING - Worker tcp://127.0.0.1:45829 (pid=65947) exceeded 95% memory ... | open | 2025-03-14T23:14:47Z | 2025-03-24T17:13:39Z | https://github.com/pydata/xarray/issues/10130 | [
"upstream issue"
] | abiasiol | 3 |
sqlalchemy/sqlalchemy | sqlalchemy | 10,811 | SQLAlchemy crashing python, when executing query | ### Describe the bug
My python-interpreter is crashing when executing/commiting any simple query .
```
(se-mono) (base) pratyush@Pratyushs-MacBook-Pro se-mono % python
Python 3.11.4 (main, Jan 1 2024, 13:32:34) [Clang 14.0.3 (clang-1403.0.22.14.1)] on darwin
Type "help", "copyright", "credits" or "license" for... | closed | 2024-01-01T17:39:18Z | 2024-01-23T14:01:33Z | https://github.com/sqlalchemy/sqlalchemy/issues/10811 | [] | s-pratyush | 1 |
joerick/pyinstrument | django | 152 | distutils has been deprecated in Python 3.10 | https://github.com/joerick/pyinstrument/blob/ccf0ec48732a693c65af0293523090be47927057/setup.py#L1
Since setuptools is used and this looks like an unused import I guess this can be safely removed.
Ref : https://www.python.org/dev/peps/pep-0632/#migration-advice | closed | 2021-10-02T06:57:11Z | 2021-10-26T07:52:43Z | https://github.com/joerick/pyinstrument/issues/152 | [] | tirkarthi | 0 |
mitmproxy/pdoc | api | 376 | Hang when processing example in docstring | #### Problem Description
pdoc hangs when processing certain examples in docstrings. This took me *ages* to pin down :)
#### Steps to reproduce the behavior:
Add this content to some file, foo.py:
```python
def foo():
"""Foo the foo.
Examples:
>>> class Foo(object):
... pass
... | closed | 2022-04-09T00:23:06Z | 2022-04-09T17:02:16Z | https://github.com/mitmproxy/pdoc/issues/376 | [
"bug"
] | Andrew-Sheridan | 4 |
biolab/orange3 | numpy | 6,893 | Add menu option to clean up copied-widget sequence numbers | <!--
Thanks for taking the time to submit a feature request!
For the best chance at our team considering your request, please answer the following questions to the best of your ability.
-->
**What's your use case?**
I'd like to have a quick way for removing all numberings added to widgets when they've been copy... | closed | 2024-09-18T15:50:26Z | 2024-09-28T12:20:54Z | https://github.com/biolab/orange3/issues/6893 | [] | wvdvegte | 2 |
ResidentMario/missingno | data-visualization | 167 | Between 8 and 10 million rows the plot breaks down for me. | It shows NaN where there are none and NaNs that do exist dont show up anymore.
Obviously one could take a sample but the behaviour is unexpected and I thought something was wrong with my data. | closed | 2023-06-19T11:32:18Z | 2023-07-05T08:04:35Z | https://github.com/ResidentMario/missingno/issues/167 | [] | aronnoordhoek | 2 |
encode/apistar | api | 362 | Docs on initializing components? | From the README:
> More typically you'll want to include settings into the build method of custom components, so that you can control their initialization, based on the application settings.
There's no longer a `build()` method, so this section needs an update. | closed | 2017-11-20T21:00:40Z | 2018-03-12T15:52:18Z | https://github.com/encode/apistar/issues/362 | [] | pikeas | 1 |
biolab/orange3 | scikit-learn | 5,982 | Feature Constructor: Handle missing values for StringVariables | <!--
Thanks for taking the time to report a bug!
If you're raising an issue about an add-on (i.e., installed via Options > Add-ons), raise an issue in the relevant add-on's issue tracker instead. See: https://github.com/biolab?q=orange3
To fix the bug, we need to be able to reproduce it. Please answer the following... | closed | 2022-05-20T12:08:00Z | 2022-09-09T12:17:48Z | https://github.com/biolab/orange3/issues/5982 | [
"bug",
"snack"
] | VesnaT | 0 |
huggingface/transformers | pytorch | 36,390 | A potential bug in modeling_llava_onevision.py | ### System Info
The `special_image_mask` in [this line](https://github.com/huggingface/transformers/blob/main/src/transformers/models/llava_onevision/modeling_llava_onevision.py#L743) seems to be a typo, it should be `special_video_mask`?
Thank you!
### Who can help?
_No response_
### Information
- [ ] The offici... | closed | 2025-02-25T07:24:44Z | 2025-02-25T08:34:52Z | https://github.com/huggingface/transformers/issues/36390 | [
"bug"
] | yinsong1986 | 0 |
pmaji/crypto-whale-watching-app | dash | 57 | No hover text on Plotly lines | As suggested here https://github.com/pmaji/crypto-whale-watching-app/pull/31#issuecomment-367026912 it'd be great to have a hover text on Plotly lines ("ladder whales") as with the bubbles instead of annotations, but Plotly does not support that. A workaround might be https://stackoverflow.com/questions/46037897/line-h... | closed | 2018-02-20T22:26:35Z | 2018-02-22T08:06:54Z | https://github.com/pmaji/crypto-whale-watching-app/issues/57 | [] | mifunetoshiro | 4 |
DistrictDataLabs/yellowbrick | scikit-learn | 328 | Fix typos in the documentation. | This task will create one or more PRs into the main code branch to fix these.
There are a few places in the documentation that could use a little polish - they are missing imports or there is a simple typo.
Group:
@Kautumn06
@ndanielsen (technical support) | closed | 2018-03-10T20:38:22Z | 2018-07-23T16:09:25Z | https://github.com/DistrictDataLabs/yellowbrick/issues/328 | [
"type: documentation"
] | ndanielsen | 4 |
streamlit/streamlit | data-visualization | 9,939 | Thankyou!! | ### Message
_No response_ | closed | 2024-11-28T00:06:33Z | 2024-11-28T19:58:08Z | https://github.com/streamlit/streamlit/issues/9939 | [
"type:kudos"
] | Sammy92dec | 1 |
CorentinJ/Real-Time-Voice-Cloning | pytorch | 1,022 | Encoder long training time | Any idea on what is the median of the encoder training time?
I've also noticed that the length of the loader in the encoder train is 156250000 and it is the same even if I change the dataset, is that normal? and if it is what does it represent? and wouldn't it take like forever to finish? | open | 2022-02-22T20:50:15Z | 2022-02-22T20:58:47Z | https://github.com/CorentinJ/Real-Time-Voice-Cloning/issues/1022 | [] | allonios2 | 0 |
plotly/dash | jupyter | 3,110 | proc permission error when executing an app bundled with pyinstaller | I am attempting to bundle a flask/dash app using pyinstaller and execute it from CLI. The installer is able to bundle correctly, but when i try to executable the file, i get the following error:
```
* Serving Flask app 'rakaia.entrypoint'
* Debug mode: on
Exception in thread Thread-2:
Traceback (most recent call la... | closed | 2024-12-17T20:29:47Z | 2024-12-18T01:46:14Z | https://github.com/plotly/dash/issues/3110 | [] | matt-sd-watson | 1 |
onnx/onnx | scikit-learn | 5,974 | onnx.checker.check_model() does not report mismatch input/output shapes | # Bug Report
### Is the issue related to model conversion?
<!-- If the ONNX checker reports issues with this model then this is most probably related to the converter used to convert the original framework model to ONNX. Please create this bug in the appropriate converter's GitHub repo (pytorch, tensorflow-onnx, sk... | open | 2024-02-28T18:37:58Z | 2024-03-15T20:05:20Z | https://github.com/onnx/onnx/issues/5974 | [
"bug",
"module: checker",
"contributions welcome"
] | fs-eire | 1 |
PaddlePaddle/ERNIE | nlp | 256 | save_inference_model_path生成模型不一致问题 | 问题描述:使用ernie做完一个文本多分类模型训练。现在发现每次**重新**调用predict_classifier时,利用ckpt成代用save_inference_model持久化模型对同样的输入预测出来的结果概率值不相同。但是如果不调用save_inference_model,而是使用之前的生成持久化模型,则对同样的输入预测是相同的。
测试环境:cpu和gpu都测试,使用ernie2.0的代码,版本一致
| closed | 2019-08-03T02:36:58Z | 2019-08-06T02:34:43Z | https://github.com/PaddlePaddle/ERNIE/issues/256 | [] | qibaoyuan | 3 |
gee-community/geemap | jupyter | 1,194 | Addition of add_legend to plotlymap module | ### Description
Hello, I would like to make a feature request. The addition of add_legend to plotlymap module. I have read the different features in the module but the addition of a legend isn't one of them. I'm currently developing a dashboard with Dash in Python and I use plotlymap from geemap to visualize some ma... | closed | 2022-08-10T02:09:13Z | 2023-06-23T00:57:40Z | https://github.com/gee-community/geemap/issues/1194 | [
"Feature Request",
"help wanted"
] | alexacanche | 1 |
google-research/bert | tensorflow | 813 | why the result model.ckpt is such bigger than the pretrained bert model | After I run `run_classifier.py`,I see the fine tuning result model(1.2GB) is such bigger than the pretrained BERT model(390MB).
The model which is saved by fine tuning :

The defalt pretrained bert model:
... | open | 2019-08-20T08:10:33Z | 2019-08-28T02:22:20Z | https://github.com/google-research/bert/issues/813 | [] | MrRace | 5 |
cvat-ai/cvat | computer-vision | 8,960 | Increase maximum label name length | ### Actions before raising this issue
- [x] I searched the existing issues and did not find anything similar.
- [x] I read/searched [the docs](https://docs.cvat.ai/docs/)
### Is your feature request related to a problem? Please describe.
Hi everyone,
I cannot succeed in importing COCO-v1 .zip dataset when label name... | open | 2025-01-17T12:11:40Z | 2025-01-17T12:11:40Z | https://github.com/cvat-ai/cvat/issues/8960 | [
"enhancement"
] | wastecollector | 0 |
sammchardy/python-binance | api | 835 | How to run the new async DepthCacheManager in the background? | I realize that this is not a problem with your library, but a problem in my understanding of python's async/await features, but I'm hoping you could help me out here. I am trying to run the DepthCacheManager in the background so that I can access the order book at any time inside my code. Prior to the async stuff I jus... | open | 2021-05-08T16:34:32Z | 2021-05-11T19:58:39Z | https://github.com/sammchardy/python-binance/issues/835 | [] | mfurlend | 3 |
benbusby/whoogle-search | flask | 770 | [BUG] Whoogle Docker not working - PermissionError: [Errno 13] Permission denied .... | **Describe the bug**
Whoogle stopped working, I get the following error
> Internal Server Error
>
> The server encountered an internal error and was unable to complete your request. Either the server is overloaded or there is an error in the application
>
I have read https://github.com/benbusby/whoogle-sea... | closed | 2022-05-28T20:08:36Z | 2022-06-05T09:39:35Z | https://github.com/benbusby/whoogle-search/issues/770 | [
"bug"
] | aindriu80 | 3 |
xzkostyan/clickhouse-sqlalchemy | sqlalchemy | 107 | sqlalchemy query clickhouse missing rows | **Describe the bug**
Expect to query 3 rows of data, but get a row
**Expected behavior**
Get what i want
**To Reproduce**
via py code
```py
from sqlalchemy import create_engine
from clickhouse_sqlalchemy import make_session
uri = "clickhouse://default:xxx@ip"
sql = "select * from system.numbers limi... | closed | 2020-10-26T01:44:49Z | 2020-11-17T16:06:49Z | https://github.com/xzkostyan/clickhouse-sqlalchemy/issues/107 | [] | vgxl | 1 |
deepset-ai/haystack | nlp | 8,542 | bug: Runtime meta parameter is ignored in AnswerBuilder | **Describe the bug**
When using an `AnswerBuilder` after a `ChatGenerator` I am also passing meta information to the `AnswerBuilder`. However, when I do this noticed that the meta information I pass is ignored.
Here is an example piece of code
```python
from haystack import Pipeline
from haystack.dataclasses im... | closed | 2024-11-13T12:57:36Z | 2024-11-20T19:07:06Z | https://github.com/deepset-ai/haystack/issues/8542 | [
"type:bug",
"P1"
] | sjrl | 1 |
ExpDev07/coronavirus-tracker-api | rest-api | 155 | JHU recovery data won't be updated | Hello!
I'm using your API to fetch data for a discord bot, and as I was looking through the code, I noticed that the source for JHU data isn't going to be updated anymore per a recent update.
(https://github.com/CSSEGISandData/COVID-19/tree/master/csse_covid_19_data/csse_covid_19_time_series)
You may want to updat... | closed | 2020-03-24T03:36:06Z | 2020-03-24T05:01:13Z | https://github.com/ExpDev07/coronavirus-tracker-api/issues/155 | [
"bug"
] | tctree333 | 13 |
fugue-project/fugue | pandas | 227 | [BUG] Native Python example in "Introduction" page not working even after changing schema to "*, col3:str" | Hello, I just happen to run the native Python code example from the "Introductions" [page](https://fugue-tutorials.readthedocs.io/en/latest/tutorials/beginner/introduction.html):
```
from typing import List, Dict, Any
f_data = data.copy()
# schema: *. col3:str
def concat_and_reverse(df: List[Dict[str,Any]]) ->... | closed | 2021-06-19T18:52:46Z | 2021-06-19T20:05:07Z | https://github.com/fugue-project/fugue/issues/227 | [] | pybokeh | 2 |
deepset-ai/haystack | machine-learning | 8,119 | docs: clean up docstrings of OpenAITextEmbedder | closed | 2024-07-30T09:12:30Z | 2024-07-31T07:53:26Z | https://github.com/deepset-ai/haystack/issues/8119 | [] | dfokina | 0 | |
jumpserver/jumpserver | django | 14,128 | [Bug] SSH连接Linux资产 SSH向导生成的密码连接提示密码错误/使用SSH CLIENT连接提示密码错误 | ### Product Version
v4.1.0
### Product Edition
- [X] Community Edition
- [ ] Enterprise Edition
- [ ] Enterprise Trial Edition
### Installation Method
- [ ] Online Installation (One-click command installation)
- [ ] Offline Package Installation
- [ ] All-in-One
- [ ] 1Panel
- [X] Kubernetes
- [ ] Source Code
### ... | closed | 2024-09-12T06:50:33Z | 2024-09-12T08:07:52Z | https://github.com/jumpserver/jumpserver/issues/14128 | [
"🐛 Bug"
] | wulabing | 0 |
taverntesting/tavern | pytest | 461 | YML common stage fragments | I want to reuse a stage yml in multiple files . I am getting an error if I want to add a key in include common.yml and reuse in multiple files.
Basically I want request and response code in a common.yml file reuse in multiple files. | closed | 2019-10-10T08:09:45Z | 2019-11-19T17:58:39Z | https://github.com/taverntesting/tavern/issues/461 | [] | anishmac99 | 3 |
marimo-team/marimo | data-visualization | 4,141 | SSO implementation | ### Description
Couldn't find anything about SSO (OAuth2/OIDC) implementation. Do we need it? Is it worth it?
### Suggested solution
Add SSO auth
### Alternative
_No response_
### Additional context
_No response_ | open | 2025-03-18T09:35:38Z | 2025-03-18T12:37:57Z | https://github.com/marimo-team/marimo/issues/4141 | [
"enhancement"
] | fuad00 | 2 |
Lightning-AI/pytorch-lightning | pytorch | 20,644 | Computation graph not being built | ### Bug description
The computation graph is not being created when precision == 'bf16-mixed' and nn.module is used earlier in a 'no_grad()'.
The following example script elicits the following error on 'out2.backward()'.
I encountered this bug when trying to create an inner optimisation loop for one of my modules.
... | open | 2025-03-14T13:50:06Z | 2025-03-14T13:51:40Z | https://github.com/Lightning-AI/pytorch-lightning/issues/20644 | [
"bug",
"needs triage",
"ver: 2.5.x"
] | joeagriffith | 0 |
ultrafunkamsterdam/undetected-chromedriver | automation | 1,870 | [NoDriver] Element.send_keys() works unexpectedly | Hello. I faced an issue using NoDriver.
When I try to find an element via `.find('Username', best_match=True) it succeed just 25-50% times on same page. 'Username' is a text of label for the input field, but the input field itself has `#email` CSS selector.
Even after I started using `.select('#email')` it is no... | open | 2024-05-07T02:21:43Z | 2024-08-28T11:18:54Z | https://github.com/ultrafunkamsterdam/undetected-chromedriver/issues/1870 | [] | RobertAzovski | 7 |
joke2k/django-environ | django | 493 | v0.11.0/ v0.11.1 breaks on Mac OSX | The following error occurs after updating to v0.11.0 (and v0.11.1) on Mac OSX.
Python version: 3.11.3
Django: 4.2.4
Stacktrace:
Traceback (most recent call last):
File "<removed>/lib/python3.11/site-packages/environ/environ.py", line 419, in _get_value
value = self.ENVIRON[var_name]
~~~~~~~... | closed | 2023-09-01T12:12:55Z | 2023-09-03T15:24:03Z | https://github.com/joke2k/django-environ/issues/493 | [
"duplicate"
] | brent-cybrid | 1 |
Avaiga/taipy | data-visualization | 2,394 | specify an anchor for positionned dialogs | open | 2025-01-13T10:22:37Z | 2025-01-13T10:22:37Z | https://github.com/Avaiga/taipy/issues/2394 | [
"📈 Improvement",
"🖰 GUI",
"🟨 Priority: Medium"
] | FredLL-Avaiga | 0 | |
modelscope/modelscope | nlp | 973 | 请问下为何 qwen/Qwen-14B-Chat 模型在离开modelscope加载环境外,会出现退化现象? | Model related: @wenmengzhou @tastelikefeet
Pipeline related: @Firmament-cyou @wenmengzhou
请问一下modelscope大佬,我在使用 qwen/Qwen-14B-Chat 的时候,两种不同的方式,产生了完全不同的结果。
方法一:正常的modelscope调用方式,采用[官网-快速使用](https://modelscope.cn/models/qwen/qwen-14b-chat)的方式加载模型。
对话结果正常:
代码为:
```
model_id = "qwen/Qwen-14B-Chat"
model_d... | closed | 2024-09-03T09:24:56Z | 2024-09-14T10:50:05Z | https://github.com/modelscope/modelscope/issues/973 | [] | tigflanker | 2 |
yunjey/pytorch-tutorial | pytorch | 77 | Need to update the readme, for new users | Please update the readme or the cd, because the test files, **main.py** and **main-gpu.py** is in different directory, _cd pytorch-tutorial/tutorials/01-basics/feedforward_neural_network_. | closed | 2017-11-06T04:01:07Z | 2018-05-10T08:58:05Z | https://github.com/yunjey/pytorch-tutorial/issues/77 | [] | farahanams | 0 |
plotly/dash | data-science | 2,877 | [Feature Request] Add `outputs` and `outputs_list` to `window.dash_clientside.callback_context` | For dash's client-side callbacks, adding `outputs` and `outputs_list` for `window.dash_clientside.callback_context` will improve operational freedom in many scenarios. Currently, only the following information can be obtained in the client-side callbacks:
`
Error is raised
`RuntimeError: ONNX export failed: Couldn't export Python operator SwishImplementation`
Maybe we need an option to use relu instead of swish which can be exported to onnx | closed | 2019-12-16T12:32:32Z | 2019-12-16T13:36:42Z | https://github.com/qubvel-org/segmentation_models.pytorch/issues/122 | [] | Vozf | 2 |
s3rius/FastAPI-template | asyncio | 121 | pypi.org/simple No matching distribution found for fastapi_template | <img width="885" alt="image" src="https://user-images.githubusercontent.com/103866132/185525223-4cd1fb4a-c852-4101-abc7-f499b68eb9fc.png">
| closed | 2022-08-19T01:52:21Z | 2022-08-29T22:23:49Z | https://github.com/s3rius/FastAPI-template/issues/121 | [] | web5gogogo | 2 |
OpenGeoscience/geonotebook | jupyter | 55 | Convert circleci deployment to use ansible geonotebook role. | ref: https://github.com/OpenGeoscience/geonotebook/issues/52
This may require minor changes to the ansible role to ensure we don't try to checkout to the directory which has already been populated by circle | closed | 2016-11-28T15:20:39Z | 2017-05-03T19:26:37Z | https://github.com/OpenGeoscience/geonotebook/issues/55 | [] | kotfic | 0 |
django-import-export/django-import-export | django | 1,208 | Foreign Key to mapping table | Hello,
I've a `Resource` table that connects through foreign key to a `SkillCodePair` table, which itself is a table that relates three other tables through ForeignKey relationships. Is there a way to add an export/import that will create something that will span the relationships? i.e.
category | skill ... | closed | 2020-11-09T10:00:00Z | 2021-11-24T09:52:38Z | https://github.com/django-import-export/django-import-export/issues/1208 | [
"question"
] | JonesKenzie | 1 |
pydantic/FastUI | pydantic | 99 | Backport PEP 585 + PEP 604 to Python 3.8 and 3.9 | Hey FastUI project maintainers, could you please share your opinion on https://github.com/python/typing_extensions/issues/315 ?
I think introducing it in `typing_extensions` would make working with built-in generics slightly more convenient and easier to document for the new Python programmers that would be interested... | closed | 2023-12-15T01:03:23Z | 2023-12-23T11:12:57Z | https://github.com/pydantic/FastUI/issues/99 | [] | bswck | 2 |
graphql-python/graphene | graphql | 1,034 | Accessing other class variables in resolve methods? | Hi, I have a use case where I need to access other class variable in the resolve method. For example,
```
class Test(graphene.ObjectType):
one = graphene.List(lambda: graphene.String())
two = graphene.List(lambda: graphene.Int())
def resolve_one(self, info):
return ["1", "2", "3"]
def resolve_t... | closed | 2019-07-15T20:41:12Z | 2019-07-17T19:22:27Z | https://github.com/graphql-python/graphene/issues/1034 | [] | vangalamaheshh | 3 |
hyperspy/hyperspy | data-visualization | 3,326 | Improve Opportunistic Cacheing | In relation to #3325 we need to think about how we handle multiple chunks at one time.
#### Describe the functionality you would like to see.
Something to consider is how we currently handle caching chunks. In this case we would have to have multiple chunks in memory at the same time. I think this is a good th... | open | 2024-03-02T16:08:36Z | 2024-03-09T18:06:51Z | https://github.com/hyperspy/hyperspy/issues/3326 | [] | CSSFrancis | 1 |
Subsets and Splits
No community queries yet
The top public SQL queries from the community will appear here once available.