
repo_name stringlengths 9 75 | topic stringclasses 30
values | issue_number int64 1 203k | title stringlengths 1 976 | body stringlengths 0 254k | state stringclasses 2
values | created_at stringlengths 20 20 | updated_at stringlengths 20 20 | url stringlengths 38 105 | labels listlengths 0 9 | user_login stringlengths 1 39 | comments_count int64 0 452 |
|---|---|---|---|---|---|---|---|---|---|---|---|
tox-dev/tox | automation | 2,483 | `tox` + `poetry`: unable to find installation candidates for existing package `lalsuite==7.6` | Hello, I am posting this issue here as opposed to the `poetry` issue tracker since the problem only seems to occur when using tox in conjunction with poetry, but if further investigation were to show that tox is not at the root of the problem I'd be happy to move it.
I have a minimal example of a poetry-managed pro... | closed | 2022-08-23T10:14:45Z | 2022-08-23T19:36:00Z | https://github.com/tox-dev/tox/issues/2483 | [
"bug:normal"
] | jacopok | 4 |
QuivrHQ/quivr | api | 3,544 | Implement first version of parsing evaluation | For a list of potential datasets for parsing see [CORE-335](https://linear.app/getquivr/issue/CORE-335/parsing-evaluation-datasets).
For details on OmniDocBench see [CORE-332](https://linear.app/getquivr/issue/CORE-332/parsing-save-omnidocbench-dataset-to-experiment-tracker) or [Notion](https://www.notion.so/getquivr... | open | 2025-01-02T15:40:03Z | 2025-01-31T09:51:37Z | https://github.com/QuivrHQ/quivr/issues/3544 | [] | chloedia | 1 |
huggingface/transformers | machine-learning | 36,320 | Support for Multi-Modality Models (DeepSeek Janus-Pro-7B) | ### Feature request
I’m requesting support for multi_modality models in transformers, specifically for models like DeepSeek Janus-Pro-7B.
Currently, when attempting to load this model using AutoModel.from_pretrained(), I received the following error:
KeyError: 'multi_modality'
During handling of the above exception,... | closed | 2025-02-21T06:49:16Z | 2025-02-21T08:33:57Z | https://github.com/huggingface/transformers/issues/36320 | [
"Feature request"
] | smiling621 | 3 |
gevent/gevent | asyncio | 1,273 | Occupy 100% cpu | * gevent version: 1.3.5
* Python version: cpython 3.6.5 (official package with ubuntu 18.04)
* Operating System: Ubuntu 18.04 Linux 4.15.0-1019-aws x86_64
### Description:
Recently I setup a webservice with gunicorn + gevent (flask).
After running for several hours, process cpu usage bump to 100%, but sti... | closed | 2018-08-21T11:21:33Z | 2018-08-21T13:04:27Z | https://github.com/gevent/gevent/issues/1273 | [
"Type: Question"
] | monsterxx03 | 2 |
python-restx/flask-restx | api | 564 | Value of different types (e.g., str, list) | It seems swagger cannot properly handle the JSON payload and I've been wondering if it's my implementation or there's something wrong. I have attached a MWE to demonstrate part of the issue I have been facing and it is mainly associated with the fact that a value of a key could be of different types, e.g. `str` or `lis... | open | 2023-09-23T16:43:57Z | 2023-09-25T15:13:39Z | https://github.com/python-restx/flask-restx/issues/564 | [
"question"
] | thanasissdr | 2 |
holoviz/panel | matplotlib | 6,911 | Document how to use .from_param to create a widget from a reactive parameter | I can't figure out how to create a widget from a reactive parameter.
More specifically
```python
import panel as pn
pn.extension()
zoom = pn.rx(2)
slider = pn.widgets.IntSlider.from_param(zoom, start=1, end=10)
```
I get
```bash
AttributeError: 'rx' object has no attribute 'name'
Traceback (m... | open | 2024-06-10T19:32:03Z | 2024-07-16T14:37:47Z | https://github.com/holoviz/panel/issues/6911 | [
"type: docs",
"need input from Philipp"
] | MarcSkovMadsen | 5 |
wagtail/wagtail | django | 12,985 | Overzealous text wrapping in listing tables | ### Issue Summary
Listing table styling results in broken-looking wrapping of some elements. For example, on a site with `wagtail-localize` installed:

Expected output: words wrapping normally unless the viewport isn't wide enou... | open | 2025-03-21T17:20:04Z | 2025-03-21T17:20:04Z | https://github.com/wagtail/wagtail/issues/12985 | [
"type:Bug",
"status:Unconfirmed"
] | alxbridge | 0 |
timkpaine/lantern | plotly | 189 | Replace cufflinks.datagen with local datagen | closed | 2019-07-30T18:37:39Z | 2019-08-15T01:07:41Z | https://github.com/timkpaine/lantern/issues/189 | [
"ready",
"feature",
"plotly/cufflinks"
] | timkpaine | 0 | |
Kanaries/pygwalker | pandas | 628 | Hide table render | Is there a way to not render the table? I tried some parameter to pass in `gw_mode` but then I can hide the view and not the table.
| open | 2024-09-25T12:27:22Z | 2024-09-26T02:14:36Z | https://github.com/Kanaries/pygwalker/issues/628 | [
"enhancement"
] | RodrigoSKohl | 2 |
sinaptik-ai/pandas-ai | pandas | 1,037 | Google Colab requirements issues (Blinker, iPython) | ### System Info
Standard Google Colab instance (tested on Free and Pro versions)
### 🐛 Describe the bug
Several issues were found when installing the latest version in Google Colab:
1: **Blinker**: is 1.7 version really needed, or 1.4+ is enough?
```
Attempting uninstall: blinker
Found existing installati... | closed | 2024-03-15T09:16:18Z | 2024-03-16T10:10:42Z | https://github.com/sinaptik-ai/pandas-ai/issues/1037 | [] | DmitriiCM | 4 |
alteryx/featuretools | data-science | 2,411 | NumberOfWordsInQuotes freezes on twitter dataset | NumberOfWordsInQuotes completely freezes up on this dataset
[twitter_training.csv](https://github.com/alteryx/featuretools/files/10252617/twitter_training.csv)
```python
import featuretools as ft
from featuretools.primitives import NumberOfWordsInQuotes
df = pd.read_csv("./twitter_training.csv")
es = ft.Entity... | closed | 2022-12-17T19:27:46Z | 2023-01-18T16:55:29Z | https://github.com/alteryx/featuretools/issues/2411 | [
"bug"
] | ozzieD | 0 |
ultralytics/ultralytics | pytorch | 18,788 | yolo-cls | > it seems that the imgsz parameter is not working. I set imgsz to 256 here, but still infer based on the size of 224.My code is as follows:
> ```
>
> from ultralytics import YOLO
> model=YOLO('./runs/classify/train/weights/best.pt')
> result=model("./daisy/5547758_eea9edfd54_n.jpg",imgsz=(256,256), save=False,devic... | closed | 2025-01-21T02:45:29Z | 2025-03-10T06:13:41Z | https://github.com/ultralytics/ultralytics/issues/18788 | [
"bug",
"classify"
] | litao-zhx | 4 |
automagica/automagica | automation | 109 | Can I somehow select a specific element from dropdown list on the browser Chrome | **I have the following HTML code:**
<select data-toggle="tooltip" data-placement="top" title="" data-placeholder="Rol" id="cmbRol" class=" form-control parsley-validated selection" data-original-title="Rol" style="display: none;">
<option value="A... | closed | 2020-02-17T21:06:16Z | 2020-02-21T19:39:08Z | https://github.com/automagica/automagica/issues/109 | [] | digobo | 4 |
PaddlePaddle/PaddleHub | nlp | 1,350 | 无法上传module | 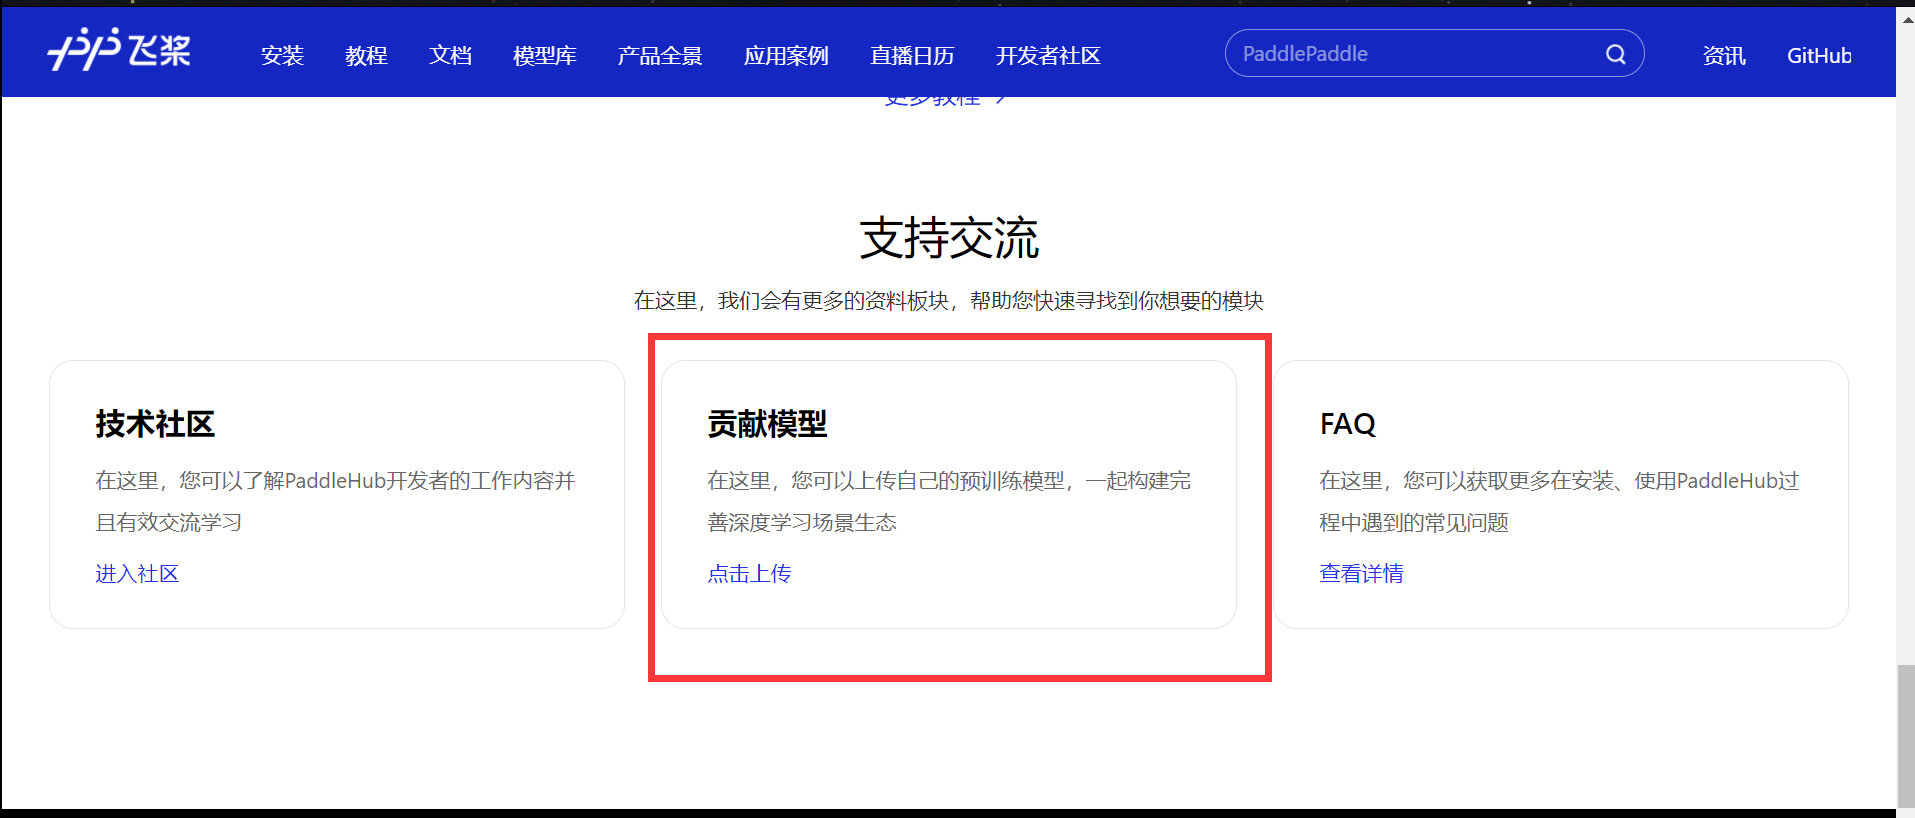
点击上传后跳转至登陆界面,输入账户密码后转404
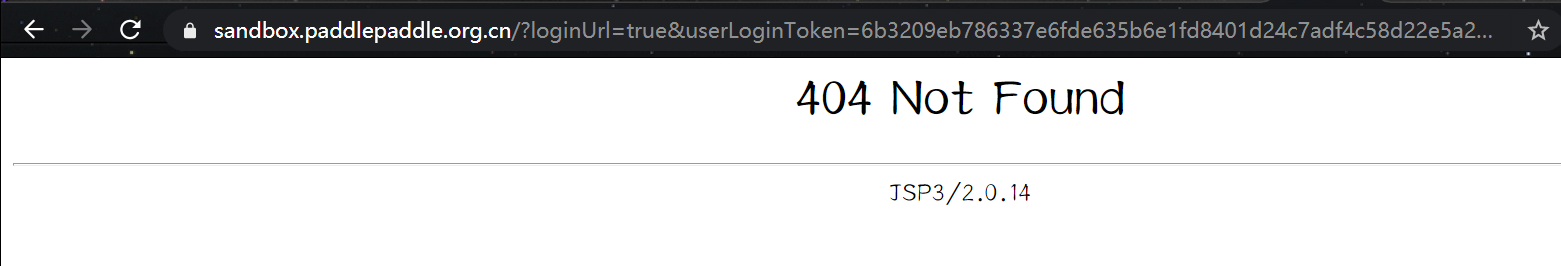
| open | 2021-04-02T14:56:50Z | 2021-04-06T06:05:56Z | https://github.com/PaddlePaddle/PaddleHub/issues/1350 | [] | thomas-yanxin | 2 |
pytest-dev/pytest-django | pytest | 405 | --pdb breaks django TestCase db flush/rollback | Added a failing test case in this branch:
https://github.com/asfaltboy/pytest-django/blob/feature/pdb-failure/tests/test_unittest.py#L249
| closed | 2016-10-24T15:13:43Z | 2016-10-24T16:11:36Z | https://github.com/pytest-dev/pytest-django/issues/405 | [] | asfaltboy | 2 |
sloria/TextBlob | nlp | 209 | How can I use TextBlob with Spanish input for sentiment analysis? | I recently ran a sentiment analysis and polarity test on a sample of tweets with the keyword "elecciones." My results indicate that most have a subjectivity and polarity of 0 even when this is clearly not the case. I'm wondering if textblob is missing something because I didn't configure it properly to handle Spanish i... | open | 2018-05-22T14:53:40Z | 2020-04-12T03:56:40Z | https://github.com/sloria/TextBlob/issues/209 | [] | MathildaEliza | 2 |
allenai/allennlp | pytorch | 5,614 | FSDP Accelerator auto_wrap ? | Currently looking at the discussion here https://github.com/allenai/allennlp/discussions/5433 and the code https://github.com/allenai/allennlp/blob/1caf0dafa3bc8d0bb309a46e2ccb12f714923260/allennlp/nn/parallel/fairscale_fsdp_accelerator.py#L126-L127
It seems like you have to manually wrap each individual unit of par... | closed | 2022-04-05T00:53:37Z | 2022-08-01T16:10:10Z | https://github.com/allenai/allennlp/issues/5614 | [
"Feature request",
"stale"
] | vikigenius | 11 |
aws/aws-sdk-pandas | pandas | 2,744 | Mock awswrangler.dynamodb inside ray remote function | I'm trying to test an util which fetches items from dynamodb using `awswrangler.dynamodb.read_items` as a dataframe
```
@ray.remote(num_returns=2)
def check_data(table_name: str):
ddb_df = awswrangler.dynamodb.read_items(
table_name=table_name,
key_condition_expression=(Key("PK").eq("abcd") & ... | closed | 2024-03-25T10:34:57Z | 2024-04-08T13:16:40Z | https://github.com/aws/aws-sdk-pandas/issues/2744 | [
"question"
] | abhi211199 | 1 |
explosion/spaCy | nlp | 13,084 | Tokenizer not splitting by infix in some cases | ## How to reproduce the behaviour
I would like the tokenizer to split by nearly any punctuation symbol, and I am having issues in some weird cases.
I initialize the tokenizer this way:
```
prefix_re = compile_prefix_regex(nlp.Defaults.prefixes).search
suffix_re = compile_suffix_regex(nlp.Defa... | closed | 2023-10-25T06:42:25Z | 2023-10-25T08:18:42Z | https://github.com/explosion/spaCy/issues/13084 | [
"feat / tokenizer"
] | borjafdezgauna | 2 |
pyeve/eve | flask | 894 | How to get return value of callback functions which are registered to Eve app ? | Hi,
according to this http://python-eve.org/snippets/hooks_blueprints.html, I noticed that function `set_username_as_none` has a return value.
``` python
def set_username_as_none(username):
resource = request.endpoint.split('|')[0]
return current_app.data.driver.db[resource].update(
{"user" : username... | closed | 2016-08-11T06:02:23Z | 2018-05-18T18:19:49Z | https://github.com/pyeve/eve/issues/894 | [
"stale"
] | liuyangc3 | 1 |
tensorlayer/TensorLayer | tensorflow | 370 | Do we have a slack channel? | Hello,
The [gitter chat room](https://gitter.im/tensorlayer/Lobby#?utm_source=badge&utm_medium=badge&utm_campaign=pr-badge) has two expired slack invitation links. Do we still use Slack, if not what is the preferred communication channel for discussing usage and development (e.g. roadmap, feature proposals)? Thanks!... | closed | 2018-03-02T06:19:41Z | 2018-03-02T16:35:24Z | https://github.com/tensorlayer/TensorLayer/issues/370 | [] | hanm | 2 |
QuivrHQ/quivr | api | 2,694 | [Bug]: blank response with ollama backend | ### What happened?
When I tried to use Quivr with Ollam qwen:72b model, the chat is already empty. There is no error showing in the log or web page. I checked the superbase chat history table the assistant text is empty:
<img width="1476" alt="image" src="https://github.com/QuivrHQ/quivr/assets/10804665/0ec5d9d6-3dc6... | closed | 2024-06-20T08:45:17Z | 2024-09-27T12:09:15Z | https://github.com/QuivrHQ/quivr/issues/2694 | [
"bug",
"Stale",
"area: backend"
] | travisgu | 6 |
huggingface/transformers | pytorch | 36,533 | Warning related to torch.tensor() usage in transformers.models.encodec.modeling_encodec.py (Version 4.47.0) | ### System Info
When using the transformers library (version 4.47.0), I am encountering a warning regarding the use of torch.tensor() in the modeling_encodec.py file. The warning suggests that it is recommended to use sourceTensor.clone().detach() instead of torch.tensor() to avoid potential issues. This issue appears... | closed | 2025-03-04T10:59:07Z | 2025-03-11T13:41:14Z | https://github.com/huggingface/transformers/issues/36533 | [
"bug"
] | GiorgiaAuroraAdorni | 1 |
sktime/pytorch-forecasting | pandas | 1,274 | What is the expected format of dataloaders generated from TimeSeriesDataset? | - PyTorch-Forecasting version: 0.10.3
- PyTorch version: 1.13.1
- Python version: 3.9.16
- Operating System: Google Collab Linux kernel
### Expected behavior
I have 5 targets. When I load from the test set dataloader, this is what I get:
```
# this returns a list of len 2, where each element is a list of l... | open | 2023-03-09T18:27:10Z | 2023-03-09T18:39:39Z | https://github.com/sktime/pytorch-forecasting/issues/1274 | [] | dempseyryan | 0 |
KaiyangZhou/deep-person-reid | computer-vision | 501 | How to get the activation map of all the layers? | Currently, I see that the activation map is only returned at the output layer. But the function visactmap() is implemented to handle printing multiple activation maps. | closed | 2022-04-14T01:31:54Z | 2022-04-15T19:04:10Z | https://github.com/KaiyangZhou/deep-person-reid/issues/501 | [] | bhosalems | 1 |
iperov/DeepFaceLive | machine-learning | 153 | where download window build exe? | how can i download the windows build exe in the description of the readme? | closed | 2023-05-09T13:34:41Z | 2023-05-09T13:48:32Z | https://github.com/iperov/DeepFaceLive/issues/153 | [] | 159znznzzn | 1 |
Miserlou/Zappa | flask | 2,208 | Failed to find libmysqlclient.so.18 when using slim_handler | <!--- Provide a general summary of the issue in the Title above -->
This issue has been posted [here](https://github.com/Miserlou/Zappa/issues/1834) and [here](https://github.com/Miserlou/Zappa/issues/776) but so far no fix.
When trying to use Postgres (psycopg2 and psyopg2-binary) it seems Zappa still tries to imp... | open | 2021-02-05T06:54:20Z | 2021-02-05T06:56:42Z | https://github.com/Miserlou/Zappa/issues/2208 | [] | philmade | 0 |
xlwings/xlwings | automation | 1,990 | MacOS M1 + Wps office Application could not handle this command. | #### OS (e.g. Windows 10 or macOS Sierra)
macOS Monterey 12.5 M1
#### Versions of xlwings, Excel and Python (e.g. 0.11.8, Office 365, Python 3.7)
xlwings:0.27.12 Excel:wpsoffice ,python 3.8.13
#### Describe your issue (incl. Traceback!)
Run the following code:
```python
# Your traceback here
if __name__ == "__... | closed | 2022-08-13T04:29:41Z | 2022-08-13T08:40:42Z | https://github.com/xlwings/xlwings/issues/1990 | [] | ZhaoyangJia | 1 |
davidsandberg/facenet | computer-vision | 800 | when I have 20K people, how can I recognize them , the KNN maybe is not a good way, | who can help me to solve this ,I have no idea to recognize lager amount of people? | open | 2018-06-25T08:51:29Z | 2020-04-10T02:02:23Z | https://github.com/davidsandberg/facenet/issues/800 | [] | rain2008204 | 5 |
flairNLP/flair | pytorch | 3,306 | [Bug]: ColumnCorpus class is not properly loading conll format file | ### Describe the bug
Eg file:
```
Test O
Load O
Data O
To O
Corpus O
Hi O
John NAME
```
Checking the "Johh" token in the 6th sentence the label is wrong, shows as "ME" instead of "NAME". Also, when checking the dictionary returned by `corpus.make_tag_dictionary` neither "ME" or "NAME" show up. Wh... | closed | 2023-08-30T13:36:28Z | 2023-08-31T13:01:14Z | https://github.com/flairNLP/flair/issues/3306 | [
"bug"
] | pjdrm-unbabel | 2 |
pytest-dev/pytest-django | pytest | 587 | Need to clear caches in `django.db.connections` during `django_db_modify_db_settings`? | [ConnectionHandler](https://github.com/django/django/blob/84dcd1624784c2239f96a97b3151145a85dfbbe3/django/db/utils.py#L135) (`django.db.connections` is an instance of this) caches, so I ended up with with problems due to using connection from the old config† after changing settings from a `django_db_modify_db_settings`... | open | 2018-03-12T18:28:26Z | 2018-04-14T13:44:33Z | https://github.com/pytest-dev/pytest-django/issues/587 | [
"bug"
] | Code0x58 | 2 |
netbox-community/netbox | django | 18,538 | ISOLATED_DEPLOYMENT not respected after login | ### Deployment Type
Self-hosted
### NetBox Version
NetBox Community v4.2.2
### Python Version
3.10
### Steps to Reproduce
We deployed NetBox with Helm Chart 5.0.22 on Kubernetes without ISOLATED_DEPLOYMENT and then updated deployment with ISOLATED_DEPLOYMENT . We posted this issue [# 518](https://github.com/net... | open | 2025-01-30T10:51:06Z | 2025-01-30T18:45:00Z | https://github.com/netbox-community/netbox/issues/18538 | [
"type: bug",
"status: needs owner",
"severity: low"
] | salcinad | 1 |
microsoft/nni | deep-learning | 4,991 | EmptyLayerError() or UnBalancedGroupError() during pruning depthwise separable convolution | **Describe the issue**:
Errors when pruning depthwise separable convolution
when 'total_sparsity' has different value , it may encounter error as follows:
1. EmptyLayerError
```
raise EmptyLayerError()
nni.compression.pytorch.speedup.error_code.EmptyLayerError: Pruning a Layer to empty is not legal
```
... | open | 2022-07-08T06:02:36Z | 2022-11-18T05:00:18Z | https://github.com/microsoft/nni/issues/4991 | [
"v3.0"
] | HiddenMarkovModel | 15 |
plotly/dash | data-science | 2,460 | [BUG] pytest_runtest_makereport "did not yield" | **Describe your context**
Dash is a transitive dependency and v2.9.0 is being pulled in and failing our GitHub CI.
**Describe the bug**
Our GitHub CI tests are failing with the below stacktrace. The issue started this morning with the release of dash v2.9.0. I believe I've tracked it to this line: https://github... | closed | 2023-03-16T17:24:17Z | 2023-03-17T14:21:04Z | https://github.com/plotly/dash/issues/2460 | [] | aaronatclockwork | 5 |
iperov/DeepFaceLab | machine-learning | 775 | PC crashed, DeepFake error when using autosave | Hi,
I ran Deepfake for two days and just now my pc froze and crashed. I wanted to continue the process with autosave but it shows an error message. I believe that it can be fixable but I don't have the knowledge to do that. Can someone please help?
:
File "/home/admin/ray-pack/tmp/job/99000080/pyenv/lib/python3.7/site-packages/mars/services/scheduling/supervisor/autoscale.py... | open | 2022-02-24T09:16:16Z | 2022-03-04T04:10:40Z | https://github.com/mars-project/mars/issues/2747 | [
"type: bug",
"mod: storage"
] | chaokunyang | 0 |
freqtrade/freqtrade | python | 10,722 | How to understand the legend within plot by draw with plot-dataframe | <!--
Have you searched for similar issues before posting it?
Did you have a VERY good look at the [documentation](https://www.freqtrade.io/en/latest/) and are sure that the question is not explained there
Please do not use the question template to report bugs or to request new features.
-->
## Describe your e... | closed | 2024-09-29T11:34:12Z | 2024-09-29T14:17:11Z | https://github.com/freqtrade/freqtrade/issues/10722 | [
"Question"
] | winsonet | 4 |
AirtestProject/Airtest | automation | 559 | AirtestIDE连接夜神模拟器,执行脚本偶现socket connection broken | **描述问题bug**
AirtestIDE连接夜神模拟器,执行脚本偶现socket connection broken
**AirtestIDE控制台黑窗口相关报错信息**:
[01:46:22][DEBUG]<airtest.core.android.adb> C:\D\file\AirtestIDE_2019-01-15_py3_win64\AirtestIDE\AirtestIDE_2019-01-15_py3_win64\airtest\core\android\static\adb\windows\adb.exe -P 5037 -s 127.0.0.1:62001 shell getprop ro.pro... | open | 2019-10-14T05:59:35Z | 2021-10-10T02:39:23Z | https://github.com/AirtestProject/Airtest/issues/559 | [
"bug",
"module/yosemite"
] | lidong342714677 | 7 |
skypilot-org/skypilot | data-science | 4,412 | [Core] Autostop/autodown fails on AWS | <!-- Describe the bug report / feature request here -->
Getting the following logs for autostopping a cluster on AWS, in `~/.sky/skylet.log`
```
AutostopEvent error: module 'urllib3.util' has no attribute 'PROTOCOL_TLS'
Traceback (most recent call last):
File "/home/ubuntu/skypilot-runtime/lib/python3.10/sit... | closed | 2024-11-25T22:29:01Z | 2024-12-19T09:31:33Z | https://github.com/skypilot-org/skypilot/issues/4412 | [
"triage"
] | Michaelvll | 1 |
pydantic/pydantic-ai | pydantic | 1,023 | System Prompt for Human In The Loop Use Cases | ### Initial Checks
- [x] I confirm that I'm using the latest version of Pydantic AI
### Description
Hi everybody,
This is not necessarily a bug, but I am having trouble figuring something out: We allow users to chat with agents. A user enters a message, the agent processes it, and a response is sent back to the use... | open | 2025-03-01T08:44:59Z | 2025-03-11T13:08:53Z | https://github.com/pydantic/pydantic-ai/issues/1023 | [
"need confirmation"
] | jkuehn | 3 |
plotly/dash-table | plotly | 472 | Rendering dash-table with dcc.tabs / multi-tab layout | I am attempting to render data-table with multi-tab layout. My dash application follows multi-page/tab layout outlined here - [dash-tabs](https://dash.plot.ly/dash-core-components/tabs).
```
- app.py
- index.py
- apps
|-- __init__.py
|-- temp1.py
```
In one of tab.py file, I am writing my code for th... | closed | 2019-06-18T17:13:05Z | 2019-06-20T23:36:57Z | https://github.com/plotly/dash-table/issues/472 | [] | kevalshah90 | 6 |
huggingface/pytorch-image-models | pytorch | 2,060 | [FEATURE] Feature only support for Twins-PVT and Mvitv2 | Both are pyramid networks and can be used for multi-scale feature extraction, but to my knowledge do not support it like similar architectures such as PVT or Swin. | closed | 2023-12-18T09:55:23Z | 2024-04-11T15:38:22Z | https://github.com/huggingface/pytorch-image-models/issues/2060 | [
"enhancement"
] | L-Reichardt | 1 |
OFA-Sys/Chinese-CLIP | computer-vision | 345 | 使用下列代码,如何加载自己训练的 'ViT-L-14'模型指定路径的.pt文件。(比如加载Epoch为2的./data/model/epoch2.pt模型) | import torch
from PIL import Image
import cn_clip.clip as clip
from cn_clip.clip import load_from_name, available_models
print("Available models:", available_models())
# Available models: ['ViT-B-16', 'ViT-L-14', 'ViT-L-14-336', 'ViT-H-14', 'RN50']
device = "cuda" if torch.cuda.is_available() else "cpu"
m... | open | 2024-08-14T03:07:00Z | 2025-01-03T03:52:09Z | https://github.com/OFA-Sys/Chinese-CLIP/issues/345 | [] | laitianan | 8 |
proplot-dev/proplot | data-visualization | 281 | Issue with one level contour plot with a specified color | ### Description
This error happens only when line color is provided for a contour plot with one level. Proplot does not show the contour in this case.
### Steps to reproduce
```python
import xarray as xr
import numpy as np
import proplot as pplt
da = xr.DataArray(
np.array(
[[ 0, 1, 2],
... | closed | 2021-09-14T18:35:58Z | 2021-09-14T21:14:18Z | https://github.com/proplot-dev/proplot/issues/281 | [
"bug"
] | kinyatoride | 1 |
long2ice/fastapi-cache | fastapi | 119 | [Feature Request] Add a minimum logging | There was a difficult time recently when I tried and couldn't figure out why everything seemed to work, but the cache wouldn't write. It turned out that it was because there was no connection to redis. But it was impossible to understand it from the logs. It would be nice if at least on startup it would say that the co... | open | 2023-03-17T15:19:10Z | 2023-05-14T21:43:11Z | https://github.com/long2ice/fastapi-cache/issues/119 | [
"documentation"
] | Krishnacore | 2 |
roboflow/supervision | computer-vision | 1,676 | Add way to "filter out" low confidence keypoints | ### Search before asking
- [X] I have searched the Supervision [issues](https://github.com/roboflow/supervision/issues) and found no similar feature requests.
### Description
In pose estimation, low confidence keypoints should be set to 0.
It would be great to include this in `supervision` instead of asking the us... | open | 2024-11-19T15:20:59Z | 2025-02-15T14:49:44Z | https://github.com/roboflow/supervision/issues/1676 | [
"enhancement"
] | Dref360 | 1 |
miguelgrinberg/Flask-SocketIO | flask | 1,502 | Emitting, not broadcasting, to a single client in an external process | Is this possible to emit to a single client in an external process? I assume that SocketIO needs to run on Redis. How do I communicate which client that the external process should emit to? | closed | 2021-03-22T16:41:28Z | 2021-03-23T00:37:50Z | https://github.com/miguelgrinberg/Flask-SocketIO/issues/1502 | [
"question"
] | tsoernes | 3 |
seleniumbase/SeleniumBase | pytest | 3,360 | Is there any way to interfere with global variables from Class BaseCase? | Like title , My code :
```
good_count = 0
bad_count = 0
class MyTestClass(BaseCase):
def test_swag_labs(self):
global good_count, bad_count
try:
#something here
while True:
if True:
good_count += 1
... | closed | 2024-12-22T12:55:42Z | 2024-12-22T15:38:39Z | https://github.com/seleniumbase/SeleniumBase/issues/3360 | [
"question",
"external"
] | zxczxcdev | 5 |
wandb/wandb | data-science | 8,782 | [Bug-App]: Storage can't release | ### Describe the bug
<!--- Describe your issue here --->


I want to ask why these folders are empty ( i delete it) , but I can still see t... | closed | 2024-11-06T17:32:13Z | 2024-11-14T07:10:22Z | https://github.com/wandb/wandb/issues/8782 | [
"ty:bug",
"a:app"
] | sanbuphy | 2 |
pallets-eco/flask-sqlalchemy | flask | 661 | execute db migrate error at flask-sqlalchemy 'dialects\mysql\base.py' | Hi:
I'm creating a flask project and I using the flask-migrate to managing the mysql based on flask-sqlalchey.
but when I execute the command 'python manager.py db migrate -m "inital migration"', I got errors like:
File "D:\ProgramData\Anaconda3\envs\books\lib\site-packages\sqlalchemy\engine\reflection.py"... | closed | 2018-12-27T07:59:12Z | 2020-12-05T20:37:29Z | https://github.com/pallets-eco/flask-sqlalchemy/issues/661 | [] | Applex007 | 1 |
Sanster/IOPaint | pytorch | 561 | [Feature Request] Automatic download after object removal (inpainting) | **Is your feature request related to a problem? Please describe.**
To ease the workflow it is very useful, if the new image with removed object is automatically downloaded after inapinting has finished.
**Describe the solution you'd like**
At least user should be able to activate this feature in settings. Per defa... | closed | 2024-08-23T12:54:20Z | 2024-12-09T02:08:54Z | https://github.com/Sanster/IOPaint/issues/561 | [
"stale"
] | manuelkamp | 2 |
plotly/dash | data-visualization | 2,535 | [Feature Request] Improve documentation on clientside callbacks | It took me so long to be able to try to figure out how to run javascript in dash. The documentation was not really verbose and helpful. I hope we can update this. Cheers.
| closed | 2023-05-19T16:32:39Z | 2024-07-24T17:11:31Z | https://github.com/plotly/dash/issues/2535 | [] | Vasallius | 1 |
home-assistant/core | python | 141,032 | Reporting based off debugger | ### The problem
Honestly I'm assuming really not an issue because I've installed HA OS on an old windows surface, which is using wifi. Plenty of issues but I feel like its too be expected. Nonetheless, this one asked to be reported so here we are:
"Something is blocking Home Assistant from wrapping up the start up ph... | closed | 2025-03-21T01:32:59Z | 2025-03-21T20:50:28Z | https://github.com/home-assistant/core/issues/141032 | [
"custom integration"
] | exhale96 | 1 |
ultrafunkamsterdam/undetected-chromedriver | automation | 953 | Code example doesn't log anything | I tried code in README.md but it doesn't log anything. Just open browser and go target page only.
```
import undetected_chromedriver as uc
from pprint import pformat
driver = uc.Chrome(enable_cdp_events=True)
def mylousyprintfunction(eventdata):
print(eventdata)
# print(pformat(eventdata))
#... | closed | 2022-12-16T03:26:16Z | 2022-12-30T07:06:52Z | https://github.com/ultrafunkamsterdam/undetected-chromedriver/issues/953 | [] | TranNgocKhoa | 0 |
holoviz/panel | plotly | 6,902 | test_multi_select_double_click error | @hoxbro - I see this UI test error:
```
(base) panel $ pixi run test-ui
✨ Pixi task (_install-ui in test-ui): playwright install chromium
✨ Pixi task (test-ui in test-ui): pytest panel/tests/ui --ui --browser chromium -n logical --dist loadgroup --reruns 3 --reruns-delay 10
====================================... | closed | 2024-06-07T16:27:29Z | 2024-06-15T15:12:13Z | https://github.com/holoviz/panel/issues/6902 | [] | cdeil | 2 |
ydataai/ydata-profiling | jupyter | 1,087 | Incorporate Categorical Variables in Interactions | ### Missing functionality
I often encounter product data, which are grouped and categorised in different ways. Having found the library recently and wanting to use it, I would like to quickly see how these categories interact with each other.
I think this would be useful for datasets which can be grouped in differe... | open | 2022-10-01T14:39:13Z | 2022-10-03T08:40:49Z | https://github.com/ydataai/ydata-profiling/issues/1087 | [
"feature request 💬"
] | LyndonFan | 2 |
tqdm/tqdm | jupyter | 691 | MPI compatibility | - [x] I have visited the [source website], and in particular read the [known issues]
- [x] I have searched through the [issue tracker] for duplicates
- [x] I have mentioned version numbers, operating system and environment, where applicable:
```python
import tqdm, sys
print(tqdm.__version__, sys.version, sys... | closed | 2019-03-04T14:11:13Z | 2020-10-08T14:06:40Z | https://github.com/tqdm/tqdm/issues/691 | [
"p0-bug-critical ☢",
"to-fix ⌛",
"synchronisation ⇶"
] | biochem-fan | 6 |
huggingface/pytorch-image-models | pytorch | 2,255 | [FEATURE] Training scripts for reproducing result of MobileNet V4 on IN1K. | Thanks for adding mobilenet v4 to this great project. Timm is always the best place for sota image models.
I would like to ask if the training script of mnv4 can be released, because the training strategy is often difficult to synchronize.
I would like to compare mnv4 with my own models under timm training settings,... | closed | 2024-08-08T09:38:17Z | 2024-08-08T14:59:47Z | https://github.com/huggingface/pytorch-image-models/issues/2255 | [
"enhancement"
] | go2sea | 0 |
django-import-export/django-import-export | django | 1,051 | Setting fields to be excluded in during validation | During validation, `full_clean()` is [called](https://github.com/django-import-export/django-import-export/blob/master/import_export/resources.py#L299). Excluded fields are set to those which have already generated errors.
This means that the user has no control over which fields on the model are excluded from vali... | closed | 2019-12-16T15:31:32Z | 2024-02-29T08:51:00Z | https://github.com/django-import-export/django-import-export/issues/1051 | [] | matthewhegarty | 2 |
DistrictDataLabs/yellowbrick | matplotlib | 1,235 | Add Dropping Curve Documentation | Now that we've merged in our new Dropping Curve with https://github.com/DistrictDataLabs/yellowbrick/pull/1206, which does not include any documentation, we'd like to follow up by adding docs with a description of the use cases.
@charlesincharge has already added comments and an article in his original issue https:/... | closed | 2022-04-16T15:13:48Z | 2022-05-21T18:17:03Z | https://github.com/DistrictDataLabs/yellowbrick/issues/1235 | [
"type: documentation"
] | lwgray | 6 |
hack4impact/flask-base | flask | 122 | RQ multiple workers with variable lifetimes. | I want to setup plenty of tasks to be delegated to workers on a queue -or possibly multiple queues. Each of these workers will need to have longer than the default 180 seconds.
I tried looking around online to see how to set this up with flask without much luck so I was wondering if there if someone here could expl... | closed | 2017-02-28T18:58:20Z | 2017-03-01T16:51:31Z | https://github.com/hack4impact/flask-base/issues/122 | [] | Mattpwinchester | 7 |
KevinMusgrave/pytorch-metric-learning | computer-vision | 682 | Normalised embeddings when using a combination of miners and losses. | hi, first of all thank you for making this repo and maintaining it, you have been a great help.
i am training a feature extractor to cluster similar objects based on visual similarity, and i am using a combination of triplet loss with euclidean distance and cosine similarity, here is the relevant code below:
```
... | closed | 2024-01-10T09:38:06Z | 2024-01-10T11:42:38Z | https://github.com/KevinMusgrave/pytorch-metric-learning/issues/682 | [] | riririririi | 2 |
tensorly/tensorly | numpy | 554 | OOM issue | #### Describe the bug
weights, factors = initialize_cp(
File "/home/wzm289/miniconda3/envs/lucas_mttl/lib/python3.9/site-packages/tensorly/decomposition/_cp.py", line 76, in initialize_cp
U, S, _ = svd_interface(
File "/home/wzm289/miniconda3/envs/lucas_mttl/lib/python3.9/site-packages/tensorly/tenalg/svd.... | closed | 2024-04-30T08:21:27Z | 2024-05-01T06:56:07Z | https://github.com/tensorly/tensorly/issues/554 | [] | shuishen112 | 6 |
litestar-org/litestar | asyncio | 3,904 | Enhancement: Add machine-readable error codes in HttpException | !!! Please ignore, found similar solution in documentation !!!
### Summary
~~At this moment exceptions in Litestar only offer a human-readable `detail` field, which does not have its machine-readable counterpart - the status code is too broad. Not providing machine-readable errors is often considered a bad prac... | closed | 2024-12-18T04:46:22Z | 2025-03-20T15:55:03Z | https://github.com/litestar-org/litestar/issues/3904 | [
"Enhancement"
] | Tapeline | 0 |
flasgger/flasgger | api | 299 | Flasgger Multiple Pages | Hi, I'm using Flask-restful integration with many blueprints and using yml to write the specs.
May I know if we can create multiple pages, probably a configuration that groups tags together in a page name that will be called after /apidocs/ e.g. /apidocs/pagename1 or /apidocs/pagename2
Thanks | closed | 2019-04-29T08:17:50Z | 2019-05-01T10:14:39Z | https://github.com/flasgger/flasgger/issues/299 | [] | IreneMaryanne | 1 |
MilesCranmer/PySR | scikit-learn | 514 | [Feature]: Composite regressors | ### Feature Request
A common pattern in applications of symbolic regression is that there exists some "bottleneck latent" parameters that can describe the data in fewer dimensions than that of the input features. For example, some data can have an underlying universal "shape", in the simplest case a univariate funct... | closed | 2024-01-03T15:10:39Z | 2024-12-01T00:12:57Z | https://github.com/MilesCranmer/PySR/issues/514 | [
"enhancement"
] | eelregit | 1 |
facebookresearch/fairseq | pytorch | 4,858 | `fairseq-generate` `RuntimeError: Mask Type should be defined` | ## ❓ Questions and Help
#### What is your question?
Upon trying to generate translations from a fairseq transformer model, I get the following error:
```
fairseq-generate fairseq-bin --path checkpoints/transformer/checkpoint_last.pt --beam 4 > gen.out
```
```
File "/home/marco/anaconda3/envs/fairseq_test/l... | closed | 2022-11-11T07:00:36Z | 2022-11-22T06:24:17Z | https://github.com/facebookresearch/fairseq/issues/4858 | [
"question",
"needs triage"
] | mcognetta | 2 |
xorbitsai/xorbits | numpy | 424 | BUG: groupby .agg('size') concat issue after execute map | Note that the issue tracker is NOT the place for general support. For
discussions about development, questions about usage, or any general questions,
contact us on https://discuss.xorbits.io/.
We did not meet this issue in our regular CI, because the CI environment is either a pure CPU environment or only the GPU... | closed | 2023-05-05T07:26:04Z | 2023-05-08T03:11:00Z | https://github.com/xorbitsai/xorbits/issues/424 | [
"bug",
"gpu"
] | ChengjieLi28 | 0 |
giotto-ai/giotto-tda | scikit-learn | 624 | Working with large datasets. | Hi.
I have a datasets of one 1 million samples and each sample has 50000 features. My machine is Intel i9 with 64GB DDR4 RAM.
Will the giotto-tda Mapper scale up to this dataset on the specified machine?
In general, what are the scalability issues that I should expect while using giotto-tda Mapper?
| closed | 2022-03-19T21:24:41Z | 2022-03-20T06:57:17Z | https://github.com/giotto-ai/giotto-tda/issues/624 | [
"enhancement"
] | OmarRafique | 0 |
ultralytics/ultralytics | deep-learning | 18,844 | WandB not logging the default metrics properly (axis scales) | ### Search before asking
- [x] I have searched the Ultralytics YOLO [issues](https://github.com/ultralytics/ultralytics/issues) and [discussions](https://github.com/orgs/ultralytics/discussions) and found no similar questions.
### Question
Hello guys,
I wonder why the standard metrics are not logged related to the... | closed | 2025-01-23T11:30:57Z | 2025-02-26T19:18:21Z | https://github.com/ultralytics/ultralytics/issues/18844 | [
"question",
"dependencies",
"detect"
] | Petros626 | 11 |
onnx/onnx | machine-learning | 6,182 | Shape inference check fails with external data. | # Bug Report
### Is the issue related to model conversion?
Related to it.
### Describe the bug
Consider the following code snippet (I am using `torch` for ease of model definition. This will reproduce with pure `onnx` as well):
```
import torch
import onnx
class Linear(torch.nn.Module):
def __ini... | closed | 2024-06-14T15:09:13Z | 2024-07-18T20:05:17Z | https://github.com/onnx/onnx/issues/6182 | [
"bug"
] | stswidwinski | 4 |
globaleaks/globaleaks-whistleblowing-software | sqlalchemy | 4,408 | Texts Customization issue - defined word not avaliable for alteration in english language version | Hi!
Currently using v 5.0.52 and I'm missing the word "whistleblowing policy" in the "Add custom Text" drop down. We have a client, who wnats to use a different term.
When altering the German version of the term, the word is stated as original text - but is not visible in the drop down there either
 mapping ? | Hello,
I am building my first api, from a quite complex model (45+ domain objects) - and I would to know if marshmallow could fit my need as I have not found the answer elsewhere.
I use SQL Alchemy with an imperative mapping style: domain objects are defined in domain/model.py while tables are defined in adapters... | open | 2021-10-08T09:22:36Z | 2025-01-12T05:01:27Z | https://github.com/marshmallow-code/marshmallow-sqlalchemy/issues/411 | [
"question"
] | evoludigit | 1 |
mljar/mercury | data-visualization | 15 | Invalid X-Frame-Options header was found when loading .../output_1.html : ALLOWALL is not a valid directive | error message when loading iframe | closed | 2022-01-20T08:05:13Z | 2023-02-13T14:48:50Z | https://github.com/mljar/mercury/issues/15 | [
"bug"
] | pplonski | 0 |
CorentinJ/Real-Time-Voice-Cloning | pytorch | 1,107 | Is there any benefit to doing the training myself? | I see in the Wiki that there is a guide on how to train the models myself. For this, I would need around 500GB of data. For what I'm trying to do this might be impractical. What is the benefit of doing the training myself? All I want to do is use the program to generate speech for 3 voices of my choosing via code (i.e.... | open | 2022-09-06T01:22:25Z | 2023-03-23T13:04:26Z | https://github.com/CorentinJ/Real-Time-Voice-Cloning/issues/1107 | [] | CodingRox82 | 2 |
JaidedAI/EasyOCR | machine-learning | 1,015 | Training a Sentence Text Recognition | Hi Everyone,
I wanted to discuss the issue of recognizing a varying number of words.
The current state of the models is that Detection cuts out every single word then the recognition model gives a prediction on the word level.
I wanted to explore the ability to Train a Text Recognizer that can recognize a sentence... | open | 2023-05-10T18:17:16Z | 2023-05-10T18:17:16Z | https://github.com/JaidedAI/EasyOCR/issues/1015 | [] | bely66 | 0 |
voila-dashboards/voila | jupyter | 661 | Preventing timeout issues by sending heartbeat messages while long running cell is running. | closed | 2020-07-24T15:13:36Z | 2020-08-18T12:20:18Z | https://github.com/voila-dashboards/voila/issues/661 | [] | SylvainCorlay | 1 | |
mwaskom/seaborn | data-visualization | 3,505 | AttributeError: 'numpy.bool_' object has no attribute 'startswith' | Getting the following error while running the code, when specifying hue as a boolean type, as follows. In the below code block
`alone` is a `bool` type
### **Code**
```
import seaborn as sns
df = sns.load_dataset('titanic')
df.info()
sns.set(style="whitegrid", color_codes=True)
sns.countplot(x="sex", hue... | closed | 2023-09-28T04:35:34Z | 2023-09-29T01:09:25Z | https://github.com/mwaskom/seaborn/issues/3505 | [] | sarath-mec | 5 |
netbox-community/netbox | django | 17,635 | Report raises AbortTransaction() when commit=False and log_failure() has been used | ### Deployment Type
Self-hosted
### NetBox Version
v4.1.2
### Python Version
3.11
### Steps to Reproduce
Create a script that logs a failure. Run the script with commit=False
```
from extras.scripts import Script
class LogFailure(Script):
description = "Log one failure"
def test_error_... | closed | 2024-09-27T17:35:54Z | 2025-01-17T03:02:35Z | https://github.com/netbox-community/netbox/issues/17635 | [
"type: bug",
"status: accepted",
"severity: low"
] | craized | 0 |
statsmodels/statsmodels | data-science | 9,229 | DOC: Some function links in 'Regression diagnostics' are broken | <img width="541" alt="image" src="https://github.com/statsmodels/statsmodels/assets/77875500/0604c1ba-cd4c-4808-8032-26bf731b585d">
[Regression diagnostics - statsmodels 0.15.0 (+270)](https://www.statsmodels.org/devel/examples/notebooks/generated/regression_diagnostics.html#Regression-diagnostics)
[Regression di... | open | 2024-04-23T11:20:07Z | 2024-04-24T14:04:28Z | https://github.com/statsmodels/statsmodels/issues/9229 | [] | luke396 | 3 |
iterative/dvc | machine-learning | 10,306 | pull: "Fetching" step takes forever | # pull: "Fetching" takes forever
## Description
Since the update to the version 3.45, ``dvc pull`` started to spend a massive amount of time for "Fetching".
Can't tell precisely what is the reason, but at least the computation of the md5 of a large file is done repetitively within different ``dvc pull`` executions... | closed | 2024-02-16T16:01:25Z | 2024-04-26T15:36:46Z | https://github.com/iterative/dvc/issues/10306 | [
"bug",
"performance",
"regression"
] | zhf231298 | 5 |
xonsh/xonsh | data-science | 5,124 | `.xsh` parser doesn't allow `**kwargs,`? | Not sure if i'm losing it on reporting this one, but if i remove the `,` at the end of line it seem to work.
I definitely know it's valid syntax in 3.10+ python:
```python
def _load_xontrib_(
xsh: XonshSession,
**kwargs,
) -> dict:
```
putting that in a `.xsh` in a `xontrib/` folder i was trying t... | open | 2023-04-23T00:26:30Z | 2023-05-31T04:25:59Z | https://github.com/xonsh/xonsh/issues/5124 | [
"parser"
] | goodboy | 1 |
ShishirPatil/gorilla | api | 130 | [Apibench] Wrong number of APIs for TF and HF | Hi! Thank you so much for the code and data. I think it is a very expiring and looking forward work.
I'm opening this issue because I have a concern/doubt about the real number of APIs for the TF and HF datasets.
In the paper, you give the following statistics:
- TorchHub: 95
- TensorFlow Hub: 626
- HuggingFac... | closed | 2023-10-11T10:37:29Z | 2023-11-14T21:53:23Z | https://github.com/ShishirPatil/gorilla/issues/130 | [
"apibench-data"
] | EscVM | 4 |
predict-idlab/plotly-resampler | data-visualization | 63 | Different behavior with hf_x with type `int64` vs `float64` | Hello !
This is a really neat project ! Great job !
I have experienced a weird behavior. I work in a `jupyter notebook` inside `vscode`. The data has a shape of `(6261089,)`.
This snippet work perfectly fine.
```python
fig = FigureResampler(go.Figure())
fig.add_trace(go.Scattergl(name='Trace', showlegend=True... | closed | 2022-05-18T18:18:43Z | 2022-05-19T10:47:19Z | https://github.com/predict-idlab/plotly-resampler/issues/63 | [
"bug"
] | PandaGab | 3 |
koaning/scikit-lego | scikit-learn | 248 | [BUG] 13 tests are failing in the master branch | In order to help us fix a potential bug we need:
- [ ] a clear and concise description of what the bug is.
- [ ] code that helps us reproduce this
- [ ] **optional** a unit test that helps us catch the bug in the future
| closed | 2020-01-03T12:25:12Z | 2020-01-03T20:28:51Z | https://github.com/koaning/scikit-lego/issues/248 | [
"bug"
] | greatsharma | 4 |
koxudaxi/datamodel-code-generator | pydantic | 1,827 | Use default keyword argument in generated optional fields | **Is your feature request related to a problem? Please describe.**
The generator produces code that is not compatible with PEP 681's `dataclass_transform` interface. For more details see
https://github.com/microsoft/pyright/issues/7166
**Describe the solution you'd like**
I would like the generator to use the `... | closed | 2024-01-30T21:53:00Z | 2024-03-18T21:19:08Z | https://github.com/koxudaxi/datamodel-code-generator/issues/1827 | [
"enhancement"
] | mjperrone | 6 |
mwaskom/seaborn | data-science | 3,476 | Monitor seaborn's security posture with the OpenSSF Scorecard | Hey, I'm Pedro and I'm back (see #3319, #3344, and #3436) with another security suggestion:
I suggest that you adopt the [OpenSSF Scorecard Action](https://github.com/ossf/scorecard-action). Scorecard is a tool that scans your repository and gives actionable suggestions of how the project can improve its supply-chai... | open | 2023-09-15T22:16:54Z | 2023-09-15T22:18:16Z | https://github.com/mwaskom/seaborn/issues/3476 | [] | pnacht | 0 |
biolab/orange3 | data-visualization | 6,240 | BUG: Zoom-In keyboard shortcut not working | It seems that the zoom-in shortcut Ctrl-+ is not working. Menu item for zoom-in works. No errors or crashes.
Env: Orange 3.33 + Windows10 Pro 64bit | closed | 2022-12-07T02:47:21Z | 2023-01-25T20:23:20Z | https://github.com/biolab/orange3/issues/6240 | [
"wish",
"snack"
] | dsanalytics | 7 |
HIT-SCIR/ltp | nlp | 281 | 某些情况,分词无视了 "." | ## 问题*类型*
分词功能问题
## 出错*场景*
“分词系统感觉自己特别的笨.”
运行这句话得出的结果将 “”笨 .“” 作为一个名词处理
## 如何复现这一错误
分词和标签标注功能运行上述例句
## 期望结果
笨和 . 分开 | closed | 2018-01-09T13:07:38Z | 2018-12-24T04:46:58Z | https://github.com/HIT-SCIR/ltp/issues/281 | [] | InhabaTewi | 3 |
pyg-team/pytorch_geometric | pytorch | 9,538 | Code fail with torch_sparse/storage.py Error | ### 🐛 Describe the bug
I am trying to run my code that uses torch-spase. But it keeps failing with the following error:
`
RuntimeError:
attribute lookup is not defined on python value of type 'type':
File "/srv/lustre01/project/pt_cloud-muhqxqc6fxo/users/abdelouahed.benmhame/AAAI2024/ICLR2025/lib/python3.8/sit... | open | 2024-07-24T08:50:03Z | 2024-07-24T11:33:18Z | https://github.com/pyg-team/pytorch_geometric/issues/9538 | [
"bug"
] | benmhamed-a | 5 |
quokkaproject/quokka | flask | 340 | No handlers could be found for logger "root" | I'm running the Quokka CMS throught Docker containers, like instructed
https://github.com/quokkaproject/docker-gunicorn-supervisor
When I run:
`docker-compose run --rm quokka python manage.py populate`
This problem occurrs in manage.py (https://github.com/rochacbruno/quokka/blob/9a30d629a6e4877f952342eac7472e0bc91e... | closed | 2016-03-24T01:35:16Z | 2019-02-28T06:50:28Z | https://github.com/quokkaproject/quokka/issues/340 | [] | erichideki | 12 |
mwaskom/seaborn | pandas | 3,029 | univariate histograms fail due to data indexing | **Issue**
Seaborn fails to generate histograms on data frames with certain indexes (duplicated).
This is wrong because the histogram is a function of a 1-D column and most not depend on frame indexes (and btw, nonunique indexes are legitimate and appear in data science tasks).
**Reproduce**
Under `seaborn==... | closed | 2022-09-16T08:17:51Z | 2022-09-17T09:06:45Z | https://github.com/mwaskom/seaborn/issues/3029 | [] | maciejskorski | 5 |
3b1b/manim | python | 1,904 | Unsupported element type | ### Describe the error
<!-- A clear and concise description of what you want to make. -->
The arrows can't be displayed correctly. There is only a tip on top.
### Code and Error
**Code**:
<!-- The code you run -->
manimgl vex.py
**Error**:
<!-- The error traceback you get when run your code -->
... | open | 2022-11-17T12:50:21Z | 2024-06-28T03:27:22Z | https://github.com/3b1b/manim/issues/1904 | [] | xeonliu | 13 |
lgienapp/aquarel | data-visualization | 19 | Add unit tests | Each `set_` method should have an associated unit test that checks if the underlying `matplotlib.rcparams` are updated successfully and correctly. | closed | 2022-08-31T12:34:19Z | 2022-09-28T11:09:57Z | https://github.com/lgienapp/aquarel/issues/19 | [
"enhancement"
] | lgienapp | 0 |
KaiyangZhou/deep-person-reid | computer-vision | 551 | the junk pids in jumarket1501.py are inconsistent | In the market1501 file, [0, -1] is defined as junk pids, but only the picture with id -1 is discarded in the process_dir method. Why was it handled this way? | open | 2023-07-18T06:18:09Z | 2023-07-30T11:06:22Z | https://github.com/KaiyangZhou/deep-person-reid/issues/551 | [] | wsysuan | 1 |
lepture/authlib | flask | 329 | Allow setting `oauth_body_hash` | **Is your feature request related to a problem? Please describe.**
When using OAuth 1 for the [LTI 1.1 protocol](http://www.imsglobal.org/specs/ltiv1p1/implementation-guide) setting the `oauth_body_hash` parameter is required for some implementations. Currently `authlib.oauth1.rfc5849.client_auth.ClientAuth` doesn't... | closed | 2021-03-10T12:10:58Z | 2021-06-19T06:43:05Z | https://github.com/lepture/authlib/issues/329 | [
"feature request"
] | libre-man | 2 |
Subsets and Splits
No community queries yet
The top public SQL queries from the community will appear here once available.