
repo_name stringlengths 9 75 | topic stringclasses 30
values | issue_number int64 1 203k | title stringlengths 1 976 | body stringlengths 0 254k | state stringclasses 2
values | created_at stringlengths 20 20 | updated_at stringlengths 20 20 | url stringlengths 38 105 | labels listlengths 0 9 | user_login stringlengths 1 39 | comments_count int64 0 452 |
|---|---|---|---|---|---|---|---|---|---|---|---|
FactoryBoy/factory_boy | sqlalchemy | 705 | Fix simple typo: charactes -> characters | # Issue Type
[x] Bug (Typo)
# Steps to Replicate
1. Examine docs/fuzzy.rst.
2. Search for `charactes`.
# Expected Behaviour
1. Should read `characters`.
| closed | 2020-02-26T07:18:08Z | 2020-02-26T10:37:20Z | https://github.com/FactoryBoy/factory_boy/issues/705 | [] | timgates42 | 1 |
scikit-optimize/scikit-optimize | scikit-learn | 1,090 | Best practice for saving model in database? | Q1:
I'm looking for a best practice for saving the skopt optimizer model in the database.
There is indeed a way to save the model to a file by `dump(res, 'result.pkl')` and `res_loaded = load('result.pkl')`. I can try to save the file in database or save the content of result.pkl in database.
I wonder if it is t... | open | 2021-11-11T02:13:39Z | 2021-11-11T02:13:39Z | https://github.com/scikit-optimize/scikit-optimize/issues/1090 | [] | oleotiger | 0 |
serengil/deepface | deep-learning | 1,371 | Can image alignment be performed before performing face detection | ### Before You Report a Bug, Please Confirm You Have Done The Following...
- [X] I have updated to the latest version of the packages.
- [X] I have searched for both [existing issues](https://github.com/serengil/deepface/issues) and [closed issues](https://github.com/serengil/deepface/issues?q=is%3Aissue+is%3Aclosed) ... | closed | 2024-10-18T07:56:21Z | 2024-10-18T08:06:44Z | https://github.com/serengil/deepface/issues/1371 | [
"bug"
] | TheHonestBob | 1 |
qwj/python-proxy | asyncio | 71 | Alive Command not working with ssh | Hello,
im in a local network and sometimes i'm switching to an open wifi. Both cant reach each other.
Im using pproxy version: 2.3.2 : `pproxy -l redir://:3126 -a 3 -r ssh://myip/` to reach the internet in my local network. In the open wifi i have direct internet access. Thats why i need the "alive" command to be w... | closed | 2020-02-04T16:01:54Z | 2020-02-04T16:05:46Z | https://github.com/qwj/python-proxy/issues/71 | [] | ghost | 0 |
albumentations-team/albumentations | machine-learning | 2,424 | [Feature request] Add apply_to_images to RandomGravel | open | 2025-03-11T01:13:59Z | 2025-03-11T01:14:05Z | https://github.com/albumentations-team/albumentations/issues/2424 | [
"enhancement",
"good first issue"
] | ternaus | 0 | |
mirumee/ariadne | api | 1,051 | Support passing Python `Enum` directly to `make_executable_schema` | `make_executable_schema` could have two lines of magic that would repack `Enum`s to `ariadne.EnumType(enum.__name__, enum).bind_to_schema(schema)` | closed | 2023-03-17T17:02:54Z | 2023-03-20T12:27:06Z | https://github.com/mirumee/ariadne/issues/1051 | [
"enhancement",
"docs"
] | rafalp | 0 |
mouredev/Hello-Python | fastapi | 540 | 网络上赌博遇到赢了钱平台不给出款这么办 | 被黑了不能出款找我们大力出黑团队多年经验,如果你被黑了请联系我们帮忙把损失降到最低/微x:<>《微信zdn200手机号18469854912》前期出款不收任何费用,团队我们都是先出款/后收费。不成功收费、
当网赢了不能提款的问题怎么办呢?
首先我们应该保持冷静,如果提现被拒绝不重复点了,切不能跟平台客服称代理人有任何争执,一旦激怒对方,极有可能造成账号冻结之类的情况,这样问题就很难处理了,此时对方的理由或者我们要表示相信,并尽快处理,在稳定住对方后希望。
第一时间联系专业出黑团队,通过藏分锁卡等手段分批出款,这样问题我们就顺利解决了,如果您目前遇到网赢钱无法提款的,请及时联系专业出黑团队为您处理↓↓↓↓↓
.recommendations is returning a None value
Thanks beforehand for helping out. | closed | 2023-03-12T13:28:54Z | 2023-12-12T21:07:07Z | https://github.com/ranaroussi/yfinance/issues/1449 | [] | pabgone | 4 |
neuml/txtai | nlp | 185 | Add function parameter to embeddings reindex | Add a new function parameter to the embeddings.reindex method. This will allow preparing data for indexing. This is useful if the encoder is changed or some other processing needs to happen on the data.
Note that if the function changes the data, only the ANN index is affected, not the database. | closed | 2021-12-23T12:11:10Z | 2021-12-23T12:13:18Z | https://github.com/neuml/txtai/issues/185 | [] | davidmezzetti | 0 |
tensorpack/tensorpack | tensorflow | 1,429 | ImageNet DataFlow iteration does not end | If you're asking about an unexpected problem which you do not know the root cause,
use this template. __PLEASE DO NOT DELETE THIS TEMPLATE, FILL IT__:
If you already know the root cause to your problem,
feel free to delete everything in this template.
### 1. What you did:
I am trying to create ImageNet dataf... | closed | 2020-04-24T22:59:42Z | 2020-04-24T23:26:32Z | https://github.com/tensorpack/tensorpack/issues/1429 | [] | bhiziroglu | 3 |
MODSetter/SurfSense | fastapi | 2 | Support for local (self-hosted) LLMs | Hi,
The project is very interesting and I love the idea of being able to ask questions about your data.
For more privacy focused people, is it possible to add support for local LLMs? Maybe Ollama support?
Thank you and keep you the great work you're doing! 👏 | closed | 2024-08-23T12:31:28Z | 2024-09-20T06:13:57Z | https://github.com/MODSetter/SurfSense/issues/2 | [] | danielnbalasoiu | 5 |
keras-team/keras | deep-learning | 20,019 | Unexpected saving/loading `.h5` weights behavior on Keras 3+. | Hello there,
Here's a strange problem. Loading the model from `.h5` weights file after saving:
```python
# load the model
try:
print(f"\nStart loading model {savepath}", flush=True)
model_loaded = load_model(savepath)
print(f"Done loading model {savepath}", flush=True)
model_loaded.summary()... | closed | 2024-07-20T06:41:25Z | 2024-08-20T01:54:30Z | https://github.com/keras-team/keras/issues/20019 | [
"stat:awaiting response from contributor",
"stale",
"type:Bug"
] | abhaskumarsinha | 6 |
huggingface/transformers | machine-learning | 36,317 | DS3 zero3_save_16bit_model is not compatible with resume_from_checkpoint | ### System Info
- `transformers` version: 4.48.3
- Platform: Linux-5.4.0-148-generic-x86_64-with-glibc2.35
- Python version: 3.11.10
- Huggingface_hub version: 0.28.1
- Safetensors version: 0.5.2
- Accelerate version: 1.3.0
- Accelerate config: not found
- PyTorch version (GPU?): 2.5.1+cu124 (True)
- Tensorflow ver... | open | 2025-02-21T05:56:30Z | 2025-03-23T08:03:25Z | https://github.com/huggingface/transformers/issues/36317 | [
"bug"
] | starmpcc | 1 |
blacklanternsecurity/bbot | automation | 1,912 | Is custom output module supported? | **Description**
Is custom output module supported? I tested it and it seems not to work.
Adding the output module to module_dirs is ineffective.
Although I can directly modify _asset_inventory.py_, it doesn't feel very elegant | closed | 2024-11-02T12:17:09Z | 2024-11-19T02:03:07Z | https://github.com/blacklanternsecurity/bbot/issues/1912 | [
"enhancement"
] | syunaht | 5 |
vipstone/faceai | tensorflow | 39 | 文字识别效果没有你 demo的好,用的是相同的素材 | 
| closed | 2019-08-04T03:19:01Z | 2019-08-04T03:29:43Z | https://github.com/vipstone/faceai/issues/39 | [] | shuxinhuang | 1 |
proplot-dev/proplot | data-visualization | 235 | Matshow/imshow changes layout in matplotlib >= 3.3 | ### Description
I set up a subplots layout the way I need it for my figure and the subplots look good. But as soon as I start filling the axes with image-data using `matshow` or `imshow`, the layout is completely changed. It appears, the axes change their aspect ratio to one, resulting in large margins in the final ... | closed | 2020-11-14T23:25:42Z | 2021-07-04T17:44:13Z | https://github.com/proplot-dev/proplot/issues/235 | [
"bug"
] | matthias-k | 7 |
mwaskom/seaborn | pandas | 3,585 | so.Est() + tick label formatter => 'PseudoAxis' object has no attribute '_view_interval' | Hi, thanks for cool library, I especially enjoy using objects interface.
While using it I encountered a small issue when trying to customise tick labels using matplotlib formatter in combination with `so.Est()`. If I replace it with `so.Agg()` the issue disappears. I guess this has something to do with the fact that... | open | 2023-12-05T22:25:21Z | 2024-05-12T19:09:32Z | https://github.com/mwaskom/seaborn/issues/3585 | [
"bug",
"objects-scale"
] | stas-sl | 8 |
gradio-app/gradio | data-visualization | 10,453 | Concurrency is not working properly, regardless of concurrency_limit | ### Describe the bug
We are encountering an issue where Gradio's concurrency handling is not working as expected. Despite setting both `max_size` and `default_concurrency_limit`, the app does not scale beyond 2 concurrent sessions.
### Steps to Reproduce:
1. Launch the Gradio app with 4 instances.
2. Send a chat mess... | closed | 2025-01-28T18:38:24Z | 2025-01-31T21:30:01Z | https://github.com/gradio-app/gradio/issues/10453 | [
"bug"
] | GeorgSchenzel | 6 |
dpgaspar/Flask-AppBuilder | rest-api | 2,258 | Appbuilder under reverse proxy with subdomain | ### Environment
Flask-Appbuilder version:
latest
### Describe the expected results
By setting `APPLICATION_ROOT` variable, the builder should expose all resources under the given root subpath. This is particularly convenient when running the app under reverse proxy. For instance if you need to run the app und... | open | 2024-07-10T20:08:59Z | 2024-07-10T20:55:22Z | https://github.com/dpgaspar/Flask-AppBuilder/issues/2258 | [] | francescognn | 1 |
chainer/chainer | numpy | 8,244 | LARS learning rate when norm is less than threshold | When LARS is used, it is expected that LR given to the optimizer is already multiplied by eta.
https://github.com/chainer/chainer/blob/30fcfa67e6e21ff6682bcbda0fdd1543a203cae6/chainer/optimizer_hooks/gradient_lars.py#L101
Therefore, in the code above, if the norm of weight (p_norm) is less than the threshold, the a... | closed | 2019-10-04T07:51:40Z | 2020-02-05T21:22:14Z | https://github.com/chainer/chainer/issues/8244 | [
"stale",
"issue-checked"
] | shmurai | 4 |
pydantic/pydantic | pydantic | 10,471 | json schema breaks with `Secret` type that uses default | ### Initial Checks
- [X] I confirm that I'm using Pydantic V2
### Description
When using the `Secret` support and the default value is set using the `Secret` type itself, pydantic raises a `TypeError`:
```
TypeError: Can't get secret type from Secret. Please use Secret[<type>], or subclass from Secret[<type>] inst... | closed | 2024-09-23T18:04:46Z | 2024-09-25T13:20:04Z | https://github.com/pydantic/pydantic/issues/10471 | [
"question"
] | rbiseck3 | 2 |
hyperspy/hyperspy | data-visualization | 3,448 | Issue between `plot_style` keyword and `widget`plotting backend | #### Describe the bug
The `plot_style` keyword of the method `plot` doesn't work anymore with the `matplotlib` `widget` backend, while it works with the `ipympl` one.
#### To Reproduce
MWE
```python
%matplotlib widget
import hyperspy.api as hs
data = np.random.random((100, 100))
s = hs.signals.Signal1D(da... | closed | 2024-10-09T12:38:57Z | 2024-11-07T20:39:41Z | https://github.com/hyperspy/hyperspy/issues/3448 | [
"type: bug",
"release: next patch"
] | amcar-dtu | 7 |
prisma-labs/python-graphql-client | graphql | 12 | How can I use string.format to inject values into the query? | Since the string starts with {}, this will be interpreted as a key in python's `String.format` function. What is the best way to programatically include values into the query? | closed | 2019-01-31T13:31:35Z | 2019-02-28T20:56:56Z | https://github.com/prisma-labs/python-graphql-client/issues/12 | [] | otmezger | 2 |
inducer/pudb | pytest | 70 | pudb.post_mortem takes a tuple when it should take a traceback | The [interface for PDB](http://docs.python.org/2/library/pdb.html#pdb.post_mortem) takes a traceback object for `post_mortem`, not the entire `sys.exc_info`. The tuple here breaks integration with some external tools that expect a thing like PDB.
Will work up a patch assuming this isn't intended?
| closed | 2013-03-28T05:51:04Z | 2013-05-24T00:43:45Z | https://github.com/inducer/pudb/issues/70 | [] | Julian | 4 |
globaleaks/globaleaks-whistleblowing-software | sqlalchemy | 3,236 | "Request support" feature's functionality | We've got a problem with the "request support" feature.
I added a new admin user to one site of our multitenant platform in order to them to receive support requests sent on that site. They have activated the account and have e-mails enabled.
Result is, requests come to other, older admins of that site but not t... | closed | 2022-06-14T07:40:22Z | 2023-02-02T15:43:38Z | https://github.com/globaleaks/globaleaks-whistleblowing-software/issues/3236 | [] | evariitta | 6 |
recommenders-team/recommenders | data-science | 1,379 | [ASK] the negtive sample is not very well in NCF | ### Description
hi,dear
Have tried the [NCF](https://github.com/microsoft/recommenders/blob/main/examples/00_quick_start/ncf_movielens.ipynb) with the ml-20m dataset, but killed by memory,then I find the codes down, **when I only sample 100 negtive items**, the process is also very slow, so how to deal with it ?
``... | closed | 2021-04-21T01:26:38Z | 2021-12-17T09:31:44Z | https://github.com/recommenders-team/recommenders/issues/1379 | [
"help wanted"
] | ucasiggcas | 1 |
seleniumbase/SeleniumBase | web-scraping | 2,337 | webdriver classes conflict on enable `uc` and `wire` | I need to use `wire` mode and `uc` too, but...
**✅ It works**
```python
>>> driver = Driver(wire=True)
>>> driver.requests
[]
```
**❌ It causes a webdriver class conflict**
```python
>>> driver = Driver(wire=True, uc=True)
>>> driver.requests
AttributeError: 'Chrome' object has no attribute 'requests'
`... | closed | 2023-12-04T14:46:01Z | 2024-10-13T17:43:02Z | https://github.com/seleniumbase/SeleniumBase/issues/2337 | [
"duplicate",
"UC Mode / CDP Mode"
] | d3cryptofc | 7 |
keras-team/keras | data-science | 20,285 | Possible typo in the "Transfer learning & fine-tuning" guide | I'm not sure if this is issue. For now it is an observation.
Reading the guide about [Transfer learning & fine-tuning](https://github.com/keras-team/keras/blob/master/guides/transfer_learning.py) I had some trouble to understand the following statement: https://github.com/keras-team/keras/blob/38db71acb207fb1dda380a... | closed | 2024-09-24T23:02:56Z | 2024-09-30T04:21:12Z | https://github.com/keras-team/keras/issues/20285 | [
"type:support"
] | miticollo | 6 |
clovaai/donut | nlp | 200 | Neither of the DocVQA Task1 (Document VQA) demos work | Neither the hugging face nor google colab notebook can run docVQA | open | 2023-05-30T16:48:50Z | 2023-07-03T09:19:53Z | https://github.com/clovaai/donut/issues/200 | [] | David-McSharry | 2 |
strawberry-graphql/strawberry | graphql | 2,884 | Issues with `strawberry.field` resolver argument type | Despite `_RESOLVER_TYPE` containing `Awaitable[T]` mypy complains about passing callables to `strawberry.field`:
```py
from typing import Callable, Awaitable
import strawberry
resolver: Callable[..., Awaitable[int]]
"""
e.g.
async def resolver() -> int:
...
"""
owo = strawberry.field(resolver)
```
... | open | 2023-06-23T12:54:16Z | 2025-03-20T15:56:15Z | https://github.com/strawberry-graphql/strawberry/issues/2884 | [
"bug"
] | ThirVondukr | 0 |
lepture/authlib | django | 58 | No way to generate tokens containing user data | In some use cases it's nice to be able to generate tokens that are not stored in a database but just contain signed data.
However, the `AuthorizationServer` has this code in `init_app`:
self.generate_token = self.create_bearer_token_generator(app)
The function it calls only takes a string from the config w... | closed | 2018-05-25T10:13:55Z | 2018-06-16T08:09:42Z | https://github.com/lepture/authlib/issues/58 | [
"feature request"
] | ThiefMaster | 4 |
yinkaisheng/Python-UIAutomation-for-Windows | automation | 212 | control position is in correct in Win11 | Cannot get the correct position of the control.
This is the error log,
Can not move cursor. ButtonControl's BoundingRectangle is (0,0,0,0)[0x0]. SearchProperties: {regexName: '.*Log Out', ControlType: ButtonControl}
This is what got from uiautomation.py
ControlType: ButtonControl ClassName: AutomationId:... | open | 2022-06-21T02:38:49Z | 2022-06-21T02:38:49Z | https://github.com/yinkaisheng/Python-UIAutomation-for-Windows/issues/212 | [] | hzh-hzh | 0 |
jmcarpenter2/swifter | pandas | 221 | npartitions ignored | Hello. I'm using swifter 1.4.0 from pip with Python 3.11.2. Swifter works fine for my use cases except that the configuration variables are ignored. In particular, I want to set a much larger number of partitions than the default (`20*cpu_count()`), but all attempts to do so have failed: swifter just sticks to its defa... | open | 2023-08-30T15:52:20Z | 2023-12-01T15:04:34Z | https://github.com/jmcarpenter2/swifter/issues/221 | [] | alexbaretta | 2 |
koxudaxi/datamodel-code-generator | fastapi | 1,797 | Default value when using ref | Hello!
I have spec which uses `ref`. I would like to have default value for referenced field to be generated automatically. The only default value I managed to get is `None`.
My spec is like this:
```yaml
...
components:
schemas:
ParameterSet:
type: object
properties:
parame... | open | 2024-01-06T05:07:16Z | 2024-02-14T06:26:49Z | https://github.com/koxudaxi/datamodel-code-generator/issues/1797 | [] | aldoshkind | 2 |
nl8590687/ASRT_SpeechRecognition | tensorflow | 283 | 有pretrained数据可以共享嘛 | 请问作者或者哪位朋友有没有pretrained好的model可以分享一下,我这台小电脑有点训练不过来...感恩感恩 | closed | 2022-05-23T14:56:53Z | 2022-11-07T23:56:53Z | https://github.com/nl8590687/ASRT_SpeechRecognition/issues/283 | [] | kqz8866 | 0 |
ultralytics/ultralytics | machine-learning | 19,748 | Overfitting issue for detection task with small dataset | ### Search before asking
- [x] I have searched the Ultralytics YOLO [issues](https://github.com/ultralytics/ultralytics/issues) and [discussions](https://github.com/orgs/ultralytics/discussions) and found no similar questions.
### Question
Hi, I am trying to use Yolov8 to train a detection task on [bone fracture de... | open | 2025-03-17T18:59:46Z | 2025-03-20T21:06:42Z | https://github.com/ultralytics/ultralytics/issues/19748 | [
"question",
"detect"
] | deJQK | 12 |
Esri/arcgis-python-api | jupyter | 2,087 | Upgrade from arcgis==1.8.5.post3 to arcgis==2.3.1 caused recursion error upon login? | **Describe the bug**
So I am upgrading all our packages in our project, including Python from 3.8 to 3.11. `arcgis` was upgraded, but is the one package causing us issues now, as we cannot login anymore withour username/password. We know the credentials are correct, as the 3.8 version of the code is currently deployed... | closed | 2024-09-27T17:08:20Z | 2024-10-02T22:41:09Z | https://github.com/Esri/arcgis-python-api/issues/2087 | [
"bug"
] | xaviernogueira | 7 |
albumentations-team/albumentations | machine-learning | 1,775 | Optional version update check on library import | ## Feature description
Add an environment variable to disable the automatic library version check on import
### Motivation and context
Following [update check MR](https://github.com/albumentations-team/albumentations/pull/1725)
Working in an offline environment, on library import the library works well and do... | closed | 2024-06-05T04:57:22Z | 2024-06-06T23:58:46Z | https://github.com/albumentations-team/albumentations/issues/1775 | [
"enhancement"
] | lerignoux | 1 |
mwaskom/seaborn | data-visualization | 3,823 | Feature request: Diverging stacked bar | Hi, I'm currently analysing likerts data and it's common practice to analyse the response using diverging stacked bar.
Seeing there are no implementation for it in the library I wanted to propose that as an enhancement.
Expected problems: handling a even and odd number of bins makes handling the center data different... | open | 2025-01-29T21:28:57Z | 2025-01-30T19:34:33Z | https://github.com/mwaskom/seaborn/issues/3823 | [] | Ownezx | 9 |
twopirllc/pandas-ta | pandas | 208 | Issue with SMA | 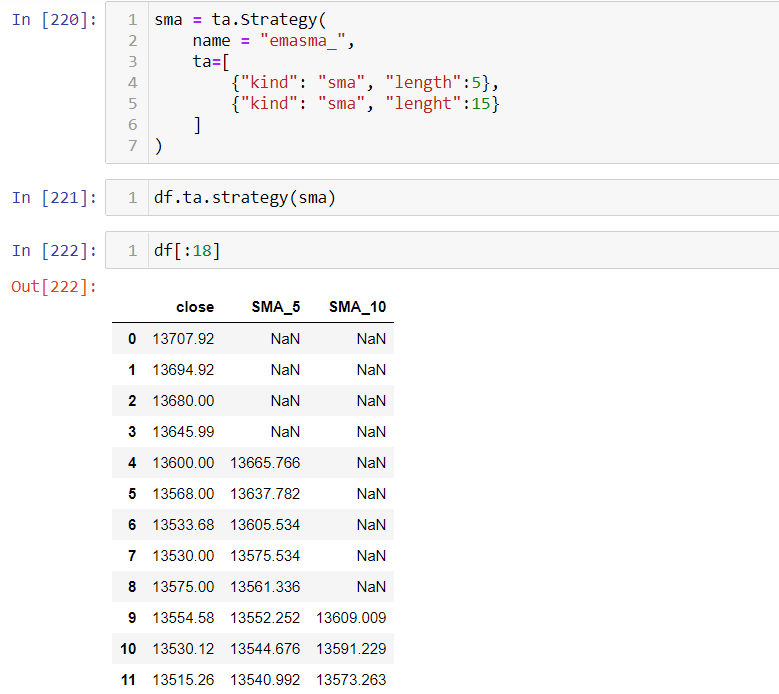
While I am trying to do a SMA crossover with SMA 5 and 15, it's giving me SMA 10 no matter what | closed | 2021-02-02T18:41:58Z | 2023-10-19T19:52:01Z | https://github.com/twopirllc/pandas-ta/issues/208 | [
"info"
] | chaudhary-v | 5 |
python-visualization/folium | data-visualization | 1,329 | Draw plugin export button does not work in Microsoft Edge | **Describe the bug**
Draw plugin export button does not work in Microsoft Edge. When you mouse over the export button, Edge shows you the correct`data:` URL, but nothing happens when you click. No hints populating in the Developer Tools console or debugger.
**To Reproduce**
As far as I can tell, this bug happens i... | closed | 2020-05-12T23:23:57Z | 2020-05-23T08:16:01Z | https://github.com/python-visualization/folium/issues/1329 | [] | and-viceversa | 1 |
mars-project/mars | pandas | 2,893 | [PROPOSAL] The Execution API | # The Execution API
## Background
Mars provides some interfaces for third party backends, but it is difficult to implement them and can not take the advantages of third party engine. For example, the Ray backend has to implement the Mars actor pool for Ray, the channel for Ray, the storage backend for Ray. Howeve... | open | 2022-04-01T08:18:22Z | 2022-05-23T06:19:45Z | https://github.com/mars-project/mars/issues/2893 | [
"proposal"
] | fyrestone | 0 |
dask/dask | scikit-learn | 11,515 | ⚠️ Upstream CI failed ⚠️ | [Workflow Run URL](https://github.com/dask/dask/actions/runs/11808903001)
<details><summary>Python 3.12 Test Summary</summary>
```
dask/array/tests/test_array_core.py::test_zarr_pass_store: TypeError: LocalStore.__init__() got an unexpected keyword argument 'mode'
dask/tests/test_order.py::test_array_store_final_order... | closed | 2024-11-13T01:58:24Z | 2024-11-13T16:12:30Z | https://github.com/dask/dask/issues/11515 | [
"upstream"
] | github-actions[bot] | 0 |
stanford-oval/storm | nlp | 68 | Good Repository | closed | 2024-07-13T02:34:47Z | 2024-07-13T10:27:51Z | https://github.com/stanford-oval/storm/issues/68 | [] | MAFLIXD | 0 | |
vitalik/django-ninja | pydantic | 704 | Hinting ModelSchema about custom fields | I use prefixed UUIDv7 as ID fields in my database. The field looks like this:
```py
from django.db.models import UUIDField
from uuid6 import uuid7
from uuid import UUID
from base58 import b58encode, b58decode
class PrefixedIdentityField(UUIDField):
def __init__(self, prefix: str, *args, **kwargs):
... | open | 2023-03-16T20:59:04Z | 2023-03-17T12:41:13Z | https://github.com/vitalik/django-ninja/issues/704 | [] | jleclanche | 1 |
python-visualization/folium | data-visualization | 1,233 | Unable to remove markers or polylines added to the Map | I am currently using Folium (0.10.0) to create a Map for a given data. In my specific use case, I would like to add markers and then delete the specific markers as the data gets updated. This also should work with respective polylines that are plotted between these markers.
I have been looking for the appropriate wa... | closed | 2019-11-25T13:13:23Z | 2022-05-23T14:16:27Z | https://github.com/python-visualization/folium/issues/1233 | [] | prashanthgpkr | 2 |
aiogram/aiogram | asyncio | 1,472 | Get user from `chat_boost` with source `ChatBoostSourcePremium` | ### aiogram version
3.x
### Problem
Currently, user from chat boost always `None` in `UserContextMiddleware`: https://github.com/aiogram/aiogram/blob/dev-3.x/aiogram/dispatcher/middlewares/user_context.py#L117-L118, but `chat_boost` with source `ChatBoostSourcePremium` always has user that boosted the chat: https://... | closed | 2024-04-28T08:05:27Z | 2024-08-13T23:12:40Z | https://github.com/aiogram/aiogram/issues/1472 | [
"enhancement"
] | Desiders | 2 |
davidteather/TikTok-Api | api | 1,127 | Videos generated in the last 24 hours for a specific word | Is it possible with this project to search for a word in tiktok and get the videos generated in the last 24 hours for that word?
For example search for the word fortnite and show me the urls/videos that were generated in the last 24 hours with that word?
If it is possible, how would be the command to do it (I alr... | open | 2024-03-12T00:28:05Z | 2024-03-12T00:28:05Z | https://github.com/davidteather/TikTok-Api/issues/1127 | [
"bug"
] | Root-FTW | 0 |
miguelgrinberg/flasky | flask | 461 | I'm a newbie, why can't I run it? | Hi, so let it run?
8.1 code
Use export FLASK_APP=__init__.py
`venv) [zhyz@zhyz-pc app]$ export FLASK_APP=__init__.py
(venv) [zhyz@zhyz-pc app]$ flask shell
Traceback (most recent call last):
File "/home/zhyz/flasky/venv/bin/flask", line 8, in <module>
sys.exit(main())
File "/home/zhyz/flasky/venv/lib/py... | closed | 2020-03-04T09:45:05Z | 2020-03-05T02:44:16Z | https://github.com/miguelgrinberg/flasky/issues/461 | [
"question"
] | zhihuiyuze | 4 |
statsmodels/statsmodels | data-science | 9,035 | ENH: diagnostic plots with errors in variables, instrumental variables, measurement error | problem that I was not aware of as generic issue
In diagnostic plots like residual plots, CPR, ..., we want to have no (or known) pattern of the graph if the null model holds. This requires that there is no correlation between the variables on x and y axis under the null. Deviations can be interpreted as violation o... | open | 2023-10-20T16:56:34Z | 2023-10-23T15:08:29Z | https://github.com/statsmodels/statsmodels/issues/9035 | [
"type-enh",
"comp-regression",
"comp-graphics",
"topic-diagnostic"
] | josef-pkt | 0 |
scikit-image/scikit-image | computer-vision | 7,654 | Can template matching be achieved? | ### Description:
Need to find the corresponding product:


Need to find all identical products:
 finds error in ``numpy/f2py/tests/util.py`` | See https://github.com/numpy/numpy/actions/runs/12226281360/job/34101383557. I think it is due to an indentation error:
```
except subprocess.CalledProcessError:
pytest.skip("meson not present, skipping compiler dependent test", allow_module_level=True)
return runmeson.returncode == 0
... | closed | 2024-12-09T02:51:34Z | 2024-12-09T09:46:14Z | https://github.com/numpy/numpy/issues/27941 | [] | charris | 2 |
aiortc/aiortc | asyncio | 522 | aiortc create Janus meeting room fail | I use the aiortc example to connect the janus public website and set the room to 1235
Aiortc failed to create the janus room.
python3.6 janus.py https://janus.conf.meetecho.com/janus --play-from 190309153658147087.mp4 --room 1235
Traceback (most recent call last):
File "janus.py", line 249, in <module>
ru... | closed | 2021-04-08T07:00:15Z | 2021-04-08T10:15:41Z | https://github.com/aiortc/aiortc/issues/522 | [] | zhiweny1122 | 2 |
horovod/horovod | tensorflow | 3,623 | KerasEstimator breaks for length of feature_cols > 1 | I was running the Keras Estimator with one feature column on an LSTM model with input shape (,50,1) passed to the feature_cols parameter, and it worked fine. The problem came when I passed it two feature columns instead for an LSTM model with input shape (,50,2).
```
model = Sequential()
model.add(LSTM(... | open | 2022-07-28T07:20:39Z | 2022-08-17T23:46:38Z | https://github.com/horovod/horovod/issues/3623 | [
"bug"
] | adamelk | 2 |
nolar/kopf | asyncio | 370 | Force-kill the operator from inside if stuck at exiting | > <a href="https://github.com/nolar"><img align="left" height="50" src="https://avatars0.githubusercontent.com/u/544296?v=4"></a> An issue by [nolar](https://github.com/nolar) at _2020-05-26 13:48:17+00:00_
> Original URL: https://github.com/zalando-incubator/kopf/issues/370
>
## Problem
<!-- What pro... | closed | 2020-08-18T20:04:53Z | 2020-09-10T23:00:43Z | https://github.com/nolar/kopf/issues/370 | [
"enhancement",
"archive"
] | kopf-archiver[bot] | 0 |
adbar/trafilatura | web-scraping | 207 | Remove headers | Thank you for such an incredibly useful package!
I'm building a corpus of documents which I'm using to automatically generate questions. For a given document, I'd like to solely extract non-header text (i.e only the paragraph text). Is this supported by the `trafilatura.extract()` method? That method returns only a ... | closed | 2022-05-11T15:31:30Z | 2022-08-16T15:59:01Z | https://github.com/adbar/trafilatura/issues/207 | [
"question"
] | nehasrikn | 4 |
freqtrade/freqtrade | python | 11,344 | Best way to handle multiple strategies for one pair or one strategy for multiple pairs. | Dont know if I missed it in the doc or the existing discussions.
multiple strategies for one pair:
Currently I m using multiple dockers/bots, I wonder if it is achievable using one bot.
one strategy for multiple pairs:
This one I have less clue as of now. Say If I buy btc is there a way to trigger sale of eth? | closed | 2025-02-07T09:51:32Z | 2025-02-11T05:37:55Z | https://github.com/freqtrade/freqtrade/issues/11344 | [
"Question",
"Strategy assistance"
] | zihaom | 8 |
cupy/cupy | numpy | 8,698 | working with string arrays with CuPy | ### Description
The following code runs as expected:
```py
import numpy as np
string_array = ["apple", "banana", "cherry"]
numpy_arr=np.array(string_array)
```
However, when I swap NumPy for CuPy like this:
```py
string_array = ["apple", "banana", "cherry"]
# Convert to a CuPy array
cupy_array = cp.array(string_arra... | open | 2024-10-26T08:56:13Z | 2024-10-27T09:49:54Z | https://github.com/cupy/cupy/issues/8698 | [
"issue-checked"
] | uribracha2611 | 2 |
Esri/arcgis-python-api | jupyter | 1,459 | using pivot with SHAPE as index or in columns results in an Error with version 2.1.0 | **Describe the bug**
For some data wrangling I'm using pivot on a panda's data frame that is spatially enabled using the Shape column as an index. In version 2.0.1 that ships with ArcGIS Pro 3.0 this works fine. On version 2.1.0 that ships with ArcGIS Pro 3.1 beta I'm getting an error.
It also fails if the SHAPE co... | closed | 2023-02-08T00:14:08Z | 2023-04-21T17:04:52Z | https://github.com/Esri/arcgis-python-api/issues/1459 | [
"bug"
] | BoudewijnBoogaard | 2 |
pytest-dev/pytest-django | pytest | 472 | Database fixtures are run when they shouldn't be for SimpleTestCase unit tests | pytest-django uses a function internally for checking if a test is a Django test case class, named `is_django_unittest`. This class is used to determine if database setup is needed or not. This is implemented with an `issubclass` check for `SimpleTestCase`. However, the Django documentation states the following:
> S... | open | 2017-03-27T16:56:53Z | 2022-09-22T16:48:25Z | https://github.com/pytest-dev/pytest-django/issues/472 | [] | w0rp | 8 |
indico/indico | flask | 6,632 | Allow downloading survey charts | Surveys allow one to download the raw CSV data but there is currently no way to download the charts in PDF or some other format.
This makes sharing the results in e.g. presentations difficult. It might be worth to investigate if we could add support for PDF export using weasyprint. | open | 2024-11-27T15:13:41Z | 2024-11-27T15:13:42Z | https://github.com/indico/indico/issues/6632 | [
"enhancement"
] | tomasr8 | 0 |
CorentinJ/Real-Time-Voice-Cloning | python | 600 | Nvidia 3080 | So I just got the 3080 and now the project hangs when I load an audio file. Has anyone else upgraded to a new 30 series? | closed | 2020-11-19T19:58:08Z | 2020-12-05T08:29:17Z | https://github.com/CorentinJ/Real-Time-Voice-Cloning/issues/600 | [] | shyt47 | 12 |
xzkostyan/clickhouse-sqlalchemy | sqlalchemy | 39 | Query execution raises exception when using raw connection | Hi,
We're having some issues with the driver under a use case which is using a raw connection.
How to reproduce:
```python
from sqlalchemy import create_engine, Column, MetaData, literal
from datetime import date, timedelta
from clickhouse_sqlalchemy import make_session, get_declarative_base, types, engines
... | closed | 2018-11-29T21:59:31Z | 2019-01-26T12:51:55Z | https://github.com/xzkostyan/clickhouse-sqlalchemy/issues/39 | [] | AchilleAsh | 1 |
JoeanAmier/TikTokDownloader | api | 196 | 有大佬能告诉一下怎么采集视频评论,点赞量等吗 | 现在运行main.exe可以做到采集视频以及原声还有封面,但是功能中的采集评论,点赞量,收藏量等数据我不知道怎么实现,有无大佬帮忙解答 | open | 2024-04-13T07:07:26Z | 2024-04-15T07:32:45Z | https://github.com/JoeanAmier/TikTokDownloader/issues/196 | [] | Robin-Teng | 6 |
iterative/dvc | machine-learning | 9,968 | fetch: initial fetch of a cloud upload-url takes *forever* | # Bug Report
`fetch: initial fetch of a cloud upload-url takes *forever*`
## Description
I'm importing several large s3 buckets (`dvc import-url --version-aware s3://bucket/path`) which are about 100k files totalling around 50GB.
When I pull a new repo, I expected the initial `dvc fetch` to be slow, but it's *r... | closed | 2023-09-22T16:36:57Z | 2024-08-21T13:55:31Z | https://github.com/iterative/dvc/issues/9968 | [
"p2-medium",
"performance"
] | d1sounds | 8 |
babysor/MockingBird | pytorch | 189 | toolbox运行时报错:Model files not found. Please download the models | 使用的是Windows11 系统
预先训练好的模型已经按照要求放在了 synthesizer/saved_models 下
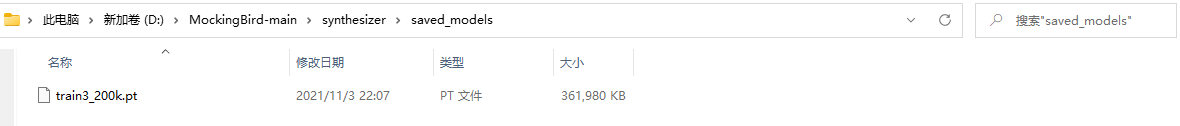
已经检查过第三方库和FFmpeg的安装状态,使用power shell运行时会报错
 BERT with 4 GPU V100 (each 16GB) with this training configuration:
_Data is only 200million words_
--train_batch_size=8
--max_seq_length=512
--max_predictions_per_seq=75
--num_train_steps=7000000
--num_warmup_steps=70000
--learning_rate=1e-4
--vocab_size=70K
_Tensorflow 1.15_
 and [discussions](https://github.com/orgs/ultralytics/discussions) and found no similar questions.
### Question
Greetings, i have a use case where the network must take an image with 9 cha... | closed | 2025-02-16T22:34:22Z | 2025-02-17T10:51:56Z | https://github.com/ultralytics/ultralytics/issues/19269 | [
"question",
"detect"
] | Spyridonidis98 | 5 |
aiortc/aioquic | asyncio | 522 | examples/http3_client.py: How to manually control the data transmission rate. | I would like to send data at specific time interval, and I am trying to change line 233 of examples/http3_client.py to this:
`for i in range(len(data_list)):
self._http.send_data(
stream_id=stream_id, data=data_list[i], end_stream=False
)
self.transmit()
time.sleep(0.05)`
But it didn't work as expected. In... | closed | 2024-06-26T09:30:53Z | 2024-06-30T07:39:35Z | https://github.com/aiortc/aioquic/issues/522 | [] | Anvilian | 1 |
amisadmin/fastapi-amis-admin | fastapi | 177 | ModelAdmin 表单里面所有默认文本输入框均无法输入空值 | https://github.com/amisadmin/fastapi-amis-admin/blame/dfaf22887babf6f6efd50eb513d93a47e7025622/fastapi_amis_admin/admin/parser.py#L289
这行给 input-text 都加了个 clearValueOnEmpty 参数,会忽略掉对应字段。但是实际上提交的时候数据还在。所以导致了当输入空值的时候,会把原来的值填进去,导致修改失败。
| open | 2024-07-19T07:29:20Z | 2024-07-19T07:29:20Z | https://github.com/amisadmin/fastapi-amis-admin/issues/177 | [] | oubeichen | 0 |
explosion/spaCy | deep-learning | 12,788 | A | <!-- Describe the problem or suggestion here. If you've found a mistake and you know the answer, feel free to submit a pull request straight away: https://github.com/explosion/spaCy/pulls -->
## Which page or section is this issue related to?
<!-- Please include the URL and/or source. --> | closed | 2023-07-04T15:02:21Z | 2023-08-04T00:02:20Z | https://github.com/explosion/spaCy/issues/12788 | [
"invalid"
] | 4158794031 | 1 |
django-cms/django-cms | django | 7,240 | Some tests misusing assertTrue for comparisons | `assertTrue` is not for comparing arguments, should use `assertEqual` for that.
The developer's intent of the test was to compare argument 1 with argument 2, which is not happening. Really what is happening is the test is passing because first argument is truthy. The correct method to use is assertEqual. [more details... | closed | 2022-02-15T16:34:35Z | 2022-07-28T04:48:05Z | https://github.com/django-cms/django-cms/issues/7240 | [
"stale"
] | code-review-doctor | 2 |
kizniche/Mycodo | automation | 476 | Feat req: kPa output float | ## Mycodo Issue Report:
- Specific Mycodo Version: 6.1.1
#### Problem Description
Pressure reading in kPa is output as int, rounding out the decimal values in live and graph displays
### Additional Notes
This is just a feature request as using Pa instead works fine | closed | 2018-05-19T23:54:45Z | 2018-06-20T03:17:49Z | https://github.com/kizniche/Mycodo/issues/476 | [] | mrplow | 21 |
comfyanonymous/ComfyUI | pytorch | 6,294 | Jus throw an error | ### Expected Behavior
Workflow to works
### Actual Behavior
An error
### Steps to Reproduce
Just load CR_Simple_Banner_demo1.json
### Debug Logs
```powershell
got prompt
!!! Exception during processing !!! CR_TextList.make_list() missing 1 required positional argument: 'loops'
Traceback (most recent call last)... | closed | 2024-12-31T16:55:15Z | 2024-12-31T17:56:39Z | https://github.com/comfyanonymous/ComfyUI/issues/6294 | [
"Custom Nodes Bug"
] | dule1970 | 3 |
numba/numba | numpy | 9,333 | Regression in parallel code between 0.55 and 0.56 | Hi,
I wish to report some regression of code which was running until numba 0.55.2 (and earlier) and stopped working with numba 0.56.0 (and any later version I tried). It simply seg-faults after a couple of seconds. The code is using parallel loops, without those parallel loops it works as expected.
Here is the c... | open | 2023-12-05T12:40:26Z | 2023-12-05T20:33:17Z | https://github.com/numba/numba/issues/9333 | [
"ParallelAccelerator",
"bug - segfault"
] | kif | 3 |
abhiTronix/vidgear | dash | 174 | still got ModuleNotFoundError | File "D:\workspace\ripcio.prj\testarea\vidgear.py", line 6, in <module>
from vidgear.gears import CamGear
ModuleNotFoundError: No module named 'vidgear.gears'; 'vidgear' is not a package
I've tried everything........ | closed | 2020-12-08T09:32:33Z | 2020-12-09T04:51:31Z | https://github.com/abhiTronix/vidgear/issues/174 | [
"DUPLICATE :recycle:",
"INVALID :stop_sign:"
] | kamarisoim | 3 |
scanapi/scanapi | rest-api | 205 | Render json content with indentation | Current, when we render the json content of a response, it is missing indentation:

It would be better if we could render it like this:
```json
{
"count": 964,
"next": "https://pokeapi.co/api... | closed | 2020-06-30T12:55:17Z | 2020-08-01T23:43:10Z | https://github.com/scanapi/scanapi/issues/205 | [
"Feature",
"Reporter"
] | camilamaia | 0 |
dynaconf/dynaconf | django | 1,165 | Environment variable for array | I have this kind of YAML config:
```
default:
SETTINGS:
- NAME: test1
VALUE: value1
- NAME: test2
VALUe: value2
```
I'm wondering how I can override the settings "test1", "value1", etc. via environment variables?
Or if it is possible to add a new setting with environment vari... | open | 2024-07-22T08:12:57Z | 2024-07-22T12:41:29Z | https://github.com/dynaconf/dynaconf/issues/1165 | [
"question"
] | molntamas | 3 |
Significant-Gravitas/AutoGPT | python | 9,606 | 测试Issue - 请忽略 | 这是一个测试Issue,用于测试GitHub MCP功能。请忽略此Issue。 | closed | 2025-03-09T09:28:58Z | 2025-03-11T04:02:58Z | https://github.com/Significant-Gravitas/AutoGPT/issues/9606 | [] | Ai-trainee | 1 |
jupyter/nbviewer | jupyter | 458 | SVG images no longer work in nbviewer | The notebook
http://nbviewer.ipython.org/github/libdynd/libdynd/blob/master/docs/intro-01/HowDyNDViewsMemory.ipynb
includes lots of inline svg images, and used to work fine. Now just the text of the links are displaying in place of the images.
| closed | 2015-05-15T07:02:46Z | 2015-06-18T19:04:29Z | https://github.com/jupyter/nbviewer/issues/458 | [
"tag:Upstream"
] | mwiebe | 3 |
QingdaoU/OnlineJudge | django | 207 | OJ backend is always using port 80 | I edited the config .yml file to make oj-backend to use port 8081 and confirmed via `sudo docker-compose config`.

After that I restarted docker-compose using `sudo docker-compose restart` and checked usi... | closed | 2018-12-25T06:20:04Z | 2018-12-26T07:21:32Z | https://github.com/QingdaoU/OnlineJudge/issues/207 | [] | McDic | 8 |
s3rius/FastAPI-template | fastapi | 92 | Add Docker-Swarm support | Hi there !
Since we are using docker-compose and there is also a Kubernetes config, I was wondering If it would be a good idea to add a Docker Swarm configuration. That's something I would be interested in and I would like to propose something if that's accepted !
| open | 2022-06-22T13:22:48Z | 2022-07-10T23:14:07Z | https://github.com/s3rius/FastAPI-template/issues/92 | [] | sorasful | 6 |
pydantic/FastUI | fastapi | 83 | Accidentally created issue | Sorry, opened in error from GitHub mobile! | closed | 2023-12-08T11:56:12Z | 2023-12-08T14:36:15Z | https://github.com/pydantic/FastUI/issues/83 | [] | tombola | 0 |
omnilib/aiomultiprocess | asyncio | 175 | allow child jobs to schedule into the pool | should be able to pickle a PoolInfo object that allows you to submit more jobs into the pool | open | 2022-12-15T19:25:35Z | 2024-04-26T19:14:47Z | https://github.com/omnilib/aiomultiprocess/issues/175 | [
"enhancement"
] | earonesty | 1 |
christabor/flask_jsondash | plotly | 109 | Make refreshInterval date format easier to use | Currently miliseconds are pretty cumbersome, especially for longer timeframes, like days.
The most user friendly experience would probably be something like natural language parsing, e.g.:
`2d`, `2days`, `1hour`, `30mins`, or similar. How best to achieve this (third-party, internal, etc), and the edge-cases, are ... | closed | 2017-05-11T21:04:23Z | 2017-05-11T23:24:16Z | https://github.com/christabor/flask_jsondash/issues/109 | [
"enhancement"
] | christabor | 0 |
arogozhnikov/einops | tensorflow | 20 | Why differently shaped tensors can't be concatenated with rearrange? | Currently, concatenation as in the example is done by calling `stack_on_zeroth_dimension()` first then rearranging the tensor into the appropriate shape. However, most `backend.stack()` requires that all except the stacked dimension to be the same, so simple concatenation of a dimension with different lengths is not po... | open | 2018-11-20T02:43:54Z | 2024-09-17T04:35:08Z | https://github.com/arogozhnikov/einops/issues/20 | [
"question"
] | Mithrillion | 4 |
PokeAPI/pokeapi | api | 600 | Direct-link to 'Paras' results in 'not found' | Direct link to pokemon 'Paras' isn't working.
https://pokeapi.co/api/v2/pokemon/paras
Results in a "Not Found" error.
He's reachable by ID, but not name. | closed | 2021-03-22T10:39:54Z | 2021-03-22T13:16:11Z | https://github.com/PokeAPI/pokeapi/issues/600 | [
"cloudflare"
] | Lunnen | 1 |
huggingface/datasets | deep-learning | 7,359 | There are multiple 'mteb/arguana' configurations in the cache: default, corpus, queries with HF_HUB_OFFLINE=1 | ### Describe the bug
Hey folks,
I am trying to run this code -
```python
from datasets import load_dataset, get_dataset_config_names
ds = load_dataset("mteb/arguana")
```
with HF_HUB_OFFLINE=1
But I get the following error -
```python
Using the latest cached version of the dataset since mteb/arguana... | open | 2025-01-06T17:42:49Z | 2025-01-06T17:43:31Z | https://github.com/huggingface/datasets/issues/7359 | [] | Bhavya6187 | 1 |
schemathesis/schemathesis | pytest | 1,994 | [FEATURE] graphql not required handling | Currently when fields in graphql schemas are not required, schemathesis can send `null` to them.
According to the graphql specs this is valid and it is useful to find bugs.
But sometimes it would be easier to not send null values
Is there a way to turn the null value sending behavior off? It would be nice to hav... | closed | 2024-01-25T12:08:38Z | 2024-08-06T19:23:32Z | https://github.com/schemathesis/schemathesis/issues/1994 | [
"Priority: Medium",
"Type: Feature",
"Specification: GraphQL",
"Difficulty: Intermediate"
] | devkral | 2 |
recommenders-team/recommenders | deep-learning | 1,641 | Could you please with a Json script to monitor Azure AD group changes, i.e. if someone is added or removed from an AD group then an email should be sent to a specific email | if someone is added or removed from an AD group then an email should be sent to a specific email
| closed | 2022-02-12T11:52:27Z | 2023-08-31T21:55:38Z | https://github.com/recommenders-team/recommenders/issues/1641 | [
"help wanted"
] | Thubagale | 0 |
Subsets and Splits
No community queries yet
The top public SQL queries from the community will appear here once available.