
repo_name stringlengths 9 75 | topic stringclasses 30
values | issue_number int64 1 203k | title stringlengths 1 976 | body stringlengths 0 254k | state stringclasses 2
values | created_at stringlengths 20 20 | updated_at stringlengths 20 20 | url stringlengths 38 105 | labels listlengths 0 9 | user_login stringlengths 1 39 | comments_count int64 0 452 |
|---|---|---|---|---|---|---|---|---|---|---|---|
streamlit/streamlit | machine-learning | 10,143 | Static file sharing with local image html tag | ### Checklist
- [X] I have searched the [existing issues](https://github.com/streamlit/streamlit/issues) for similar issues.
- [X] I added a very descriptive title to this issue.
- [X] I have provided sufficient information below to help reproduce this issue.
### Summary
After enabling static sharing to true i... | closed | 2025-01-09T03:49:57Z | 2025-01-09T04:24:26Z | https://github.com/streamlit/streamlit/issues/10143 | [
"type:bug",
"status:needs-triage"
] | Walter909 | 3 |
zappa/Zappa | flask | 1,214 | Runtime.HandlerNotFound: Handler 'lambda_handler' missing on module 'handler' | ## Context
when i deploy my django(3.2.6) service with Zappa, if i deploy zappa in local that can work very clearly but when i using github action, it doesn't work and send me log like (Runtime.HandlerNotFound: Handler 'lambda_handler' missing on module 'handler')
I can't catch, "what is wrong did i".
please hel... | closed | 2023-01-20T05:24:33Z | 2023-01-25T00:28:22Z | https://github.com/zappa/Zappa/issues/1214 | [] | hyeokju98 | 0 |
Lightning-AI/pytorch-lightning | data-science | 19,953 | Make TensorBoardLogger default version creation ascii sortable | ### Description & Motivation
Make it so it by default when opening Tensorboard in the default log directory runs are stored in ascending or descending order.
### Pitch
The current TensorBoardLogger default version stamping does not provide a graceful view when sorting experiment runs from TensorBoard.
I th... | open | 2024-06-06T18:27:21Z | 2024-06-06T20:11:20Z | https://github.com/Lightning-AI/pytorch-lightning/issues/19953 | [
"feature",
"needs triage"
] | jdenhof | 0 |
modelscope/modelscope | nlp | 1,257 | 今天网页打不开了。 | 魔塔今天很卡很卡,阿里云挂了吗? | closed | 2025-03-11T08:41:21Z | 2025-03-17T01:42:42Z | https://github.com/modelscope/modelscope/issues/1257 | [] | lk137095576 | 2 |
comfyanonymous/ComfyUI | pytorch | 6,288 | Execute update_comfyui.bat:_pygit2.GitError: failed to send request: 操作超时 | ### Expected Behavior
How to solve it, it can always be updated
### Actual Behavior
Execute update_comfyui.bat, unable to update, there are agents, can always pull, the error appears in the past two days
### Steps to Reproduce
Execute update_comfyui.bat, unable to update, there are agents, can always pull, the err... | open | 2024-12-31T08:11:23Z | 2025-01-02T23:53:36Z | https://github.com/comfyanonymous/ComfyUI/issues/6288 | [
"Potential Bug"
] | IAFFeng | 6 |
pallets-eco/flask-sqlalchemy | flask | 750 | exception no route to host takes upto 30 secs | We are connected to patroni (HA PostgresSQL).
When testing HA, when I delete the master database pod, patroni setups up the route to the backup master. This takes about 300ms.
When this happens,
The exception takes between 10=30s for the exception: "could not connect to server: No route to host"
2019-0... | closed | 2019-06-11T04:21:14Z | 2020-12-05T20:21:49Z | https://github.com/pallets-eco/flask-sqlalchemy/issues/750 | [] | gil0109 | 1 |
deepspeedai/DeepSpeed | machine-learning | 5,698 | [REQUEST]win10 install fail build_win.bat | when I run build_win.bat, I get a deepspeed whl file finnally. The matter seems to have been resolved. However, when I ran the program, the following issue occurred
File "D:\anaconda3\envs\llm\lib\site-packages\sat\__init__.py", line 6, in <module>
from .training.deepspeed_training import training_main
Fil... | closed | 2024-06-26T09:00:23Z | 2024-08-14T21:24:42Z | https://github.com/deepspeedai/DeepSpeed/issues/5698 | [] | shark-xiake | 4 |
bmoscon/cryptofeed | asyncio | 443 | Small bug and suggested fix in demo_binance_delivery.py | **Describe the bug**
A clear and concise description of what the bug is.
Line 20: max depth can't be 3, should be e.g. 5
| closed | 2021-03-17T14:22:07Z | 2021-04-02T07:07:30Z | https://github.com/bmoscon/cryptofeed/issues/443 | [
"bug"
] | idclevxx | 5 |
deeppavlov/DeepPavlov | tensorflow | 1,028 | Multi-hot additional features in NER | I am trying to use additional features in NER (ner_rus model), but I have problems with modifiyng your code for this task. Could you help me with some advice? In my case each token has from 1 to 11 different features from one list, so it would be nice represent this by multi-hot vector, however, as I know, deeppavlov d... | closed | 2019-10-03T13:44:06Z | 2020-05-20T05:02:22Z | https://github.com/deeppavlov/DeepPavlov/issues/1028 | [] | BloodSource | 1 |
tflearn/tflearn | data-science | 496 | About classification by AlexNet | I trained and saved a model (the default parameters are used in "alexnet.py") by adding [model.save('models/model.tflearn')] at the end of "alexnet.py", then I used the following codes to classify the training data set but the correct rate is very low (about 13%). I wonder what is the problem about my process ? Does a... | open | 2016-12-05T06:02:13Z | 2017-03-02T10:40:26Z | https://github.com/tflearn/tflearn/issues/496 | [] | joei1981 | 3 |
keras-team/keras | deep-learning | 20,236 | "replication_pad1d" not implemented for 'Half' | This error report was obtained when I executed codes with function `keras.layers.MaxPooling1D` dynamically, but statically with shape output.
The version info is keras 3.5.0 with PyTorch 2.4.0
```
import os
import re
import torch
import numpy as np
os.environ['KERAS_BACKEND']='torch'
import keras
layer = k... | closed | 2024-09-09T05:41:53Z | 2024-09-18T23:22:54Z | https://github.com/keras-team/keras/issues/20236 | [
"type:Bug"
] | MilkFiish | 2 |
mirumee/ariadne | api | 560 | FileNotFoundError: [Errno 2] No such file or directory: | The default implementation is to treat the graphql path as an absolute path, how about using a relative path relative to the module's path that calls `load_schema_from_path` | closed | 2021-04-26T14:48:32Z | 2021-05-20T12:43:36Z | https://github.com/mirumee/ariadne/issues/560 | [] | zqbake | 2 |
chaoss/augur | data-visualization | 2,627 | Change Requests Accepted metric API | The canonical definition is here: https://chaoss.community/?p=3589 | open | 2023-11-30T18:05:04Z | 2023-11-30T18:20:24Z | https://github.com/chaoss/augur/issues/2627 | [
"API",
"first-timers-only"
] | sgoggins | 0 |
TheAlgorithms/Python | python | 12,350 | saasas | ### What would you like to share?
assaas
### Additional information
_No response_ | closed | 2024-11-05T10:32:26Z | 2024-11-05T10:32:38Z | https://github.com/TheAlgorithms/Python/issues/12350 | [
"awaiting triage"
] | ruslansenatorov | 0 |
deepspeedai/DeepSpeed | pytorch | 6,729 | GPU mem doesn't release after delete tensors in optimizer.bit16groups | I'm developing a peft algorithm, basically it does the following:
Say the training process has 30 steps in total,
1. For global step 0\~9: train `lmhead` + `layer_0`
2. For global step 10\~19: train `lmhead` + `layer_1`
3. For global step 20\~29: train `lmhead` + `layer_0`
The key point is that, after the switch, the... | closed | 2024-11-08T11:42:49Z | 2024-12-06T21:59:52Z | https://github.com/deepspeedai/DeepSpeed/issues/6729 | [] | wheresmyhair | 2 |
indico/indico | flask | 6,395 | Cannot move session to another day | **Is your feature request related to a problem? Please describe.**
In https://indico.cern.ch/event/1381446/ I had a session scheduled on Wednesday and wanted to move the whole session to Friday. Strangely I could edit the start and end **times** of the session but not the day.
:
pass
```
After running `python3 tqdm_test.py 2> tqdm_test.txt` on bash, ... | closed | 2019-12-13T02:42:45Z | 2020-03-31T18:56:13Z | https://github.com/tqdm/tqdm/issues/865 | [
"duplicate 🗐",
"question/docs ‽"
] | c-j-lh | 1 |
tensorpack/tensorpack | tensorflow | 1,438 | ValueError: not enough values to unpack (expected 2, got 1) | Hi. I want to run:
```
./predict.py --evaluate /home/n/Documents/cars_mask_rcnn/tests/models_ex1/stats.json --load /home/n/Documents/cars_mask_rcnn/tests/models_ex1/model-5000.data-00000-of-00001 --config SAME-AS-TRAINING
```
However Im getting:
```
/home/n/.conda/envs/cars/lib/python3.6/site-packages/tens... | closed | 2020-05-11T09:41:54Z | 2020-05-11T09:55:10Z | https://github.com/tensorpack/tensorpack/issues/1438 | [] | Adblu | 1 |
ray-project/ray | deep-learning | 51,601 | [Cluster] Ray job submit/logs sporadically stops following logs | ### What happened + What you expected to happen
The commands `ray job submit` and `ray job logs -f` are supposed to keep printing the output of the job until it terminates.
Lately though, I find these commands sporadically stop following logs and exit.
Interestingly, before exiting, they print the job status, same a... | open | 2025-03-21T19:20:55Z | 2025-03-21T22:51:27Z | https://github.com/ray-project/ray/issues/51601 | [
"bug",
"triage",
"core"
] | jleben | 0 |
Zeyi-Lin/HivisionIDPhotos | fastapi | 196 | add_background接口传入input_image_base64显示missing input_image接口调用不成功 | 换背景颜色接口传入input_image文件可以调用成功,传入图片input_image_base64则调用不成功
接口返回结果:
{
"detail": [
{
"type": "missing",
"loc": [
"body",
"input_image"
],
"msg": "Field required",
"input": null
}
]
} | closed | 2024-10-23T15:14:21Z | 2024-11-21T10:47:57Z | https://github.com/Zeyi-Lin/HivisionIDPhotos/issues/196 | [] | leyan-lian | 5 |
flairNLP/flair | nlp | 3,192 | Zero (0) F-1 Score for Sequene Tagger with transformer embedding with BIO tags | ### Question
Hi, I have data in BIO format (not BIOES). I am training a sequence tagger model with transformer embedding but consistently get 0 f1-score for every epoch for XLM-ROBERTA-LARGE, but for other models (BERT-BASE-UNCASED) I'm getting a non-zero F-1 score. Could you please help me understand the reason? I ca... | closed | 2023-04-14T01:14:22Z | 2025-03-11T05:16:53Z | https://github.com/flairNLP/flair/issues/3192 | [
"question",
"Awaiting Response"
] | iambankaratharva | 2 |
ivy-llc/ivy | numpy | 28,248 | Fix Ivy Failing Test: paddle - elementwise.not_equal | closed | 2024-02-11T20:17:46Z | 2024-02-25T10:16:01Z | https://github.com/ivy-llc/ivy/issues/28248 | [
"Sub Task"
] | ksheroz | 0 | |
fugue-project/fugue | pandas | 166 | [BUG] SparkExecutionEngine take can't presort on columns with names that have more than 1 character | **Minimal Code To Reproduce**
```python
from fugue import FugueWorkflow
from fugue_spark import SparkExecutionEngine
import pandas as pd
test = pd.DataFrame({"mode": [1,1,2,2,3,3,4,4.0], "err": ["a","b","c","d","a","b","c","d"], "test": [1,1,2,2,3,3,4,4.0]})
with FugueWorkflow(SparkExecutionEngine) as dag:
... | closed | 2021-01-30T19:54:13Z | 2021-01-30T23:02:38Z | https://github.com/fugue-project/fugue/issues/166 | [
"bug",
"spark",
"high priority"
] | kvnkho | 0 |
litestar-org/polyfactory | pydantic | 559 | Bug: Validation Error in Pydantic model with optional list | ### Description
Even the simplest model with an optional list appears to not work. Instead of generating a valid coverage including `None` and a random string, a validation error is raised. Worth noting that it seems to be making a list of list of str, rather than a list of string.
### URL to code causing the iss... | closed | 2024-06-26T14:24:03Z | 2025-03-20T15:53:17Z | https://github.com/litestar-org/polyfactory/issues/559 | [
"bug"
] | RLC92 | 1 |
adbar/trafilatura | web-scraping | 586 | Extracting content from an URl is getting none | import requests
from main_content_extractor import MainContentExtractor
url = "https://testing.nbnhchurch.org/"
response = requests.get(url)
response.encoding = 'utf-8'
content = response.text
extracted_html = MainContentExtractor.extract(content)
extracted_markdown = MainContentExtractor.extract(content, outp... | open | 2024-05-05T12:01:12Z | 2024-05-06T15:45:11Z | https://github.com/adbar/trafilatura/issues/586 | [
"question"
] | Fabiha15 | 1 |
pallets-eco/flask-sqlalchemy | sqlalchemy | 498 | Problems with lazy initialization and configuration parameter warnings | It is common in most Flask extensions to be able to initialize them either directly like `foo = Foo(app)` or lazily like `foo = Foo()` and later `foo.init_app(app)`. The second way is particularly useful if one has different sets of configurations which are loaded dynamically while, at the same time, the object of some... | closed | 2017-05-11T14:21:18Z | 2020-12-05T20:55:50Z | https://github.com/pallets-eco/flask-sqlalchemy/issues/498 | [] | MichiK | 1 |
pallets-eco/flask-sqlalchemy | sqlalchemy | 772 | What is the future for separate MetaData when using multiple database bindings? | There was some planning/discussion about the subject some time ago. What's the status? Will it become possible to use same table names across different bindings?
| closed | 2019-08-21T13:37:19Z | 2020-12-05T20:21:44Z | https://github.com/pallets-eco/flask-sqlalchemy/issues/772 | [] | 4lph4-Ph4un | 3 |
jupyter/nbgrader | jupyter | 1,744 | Confusion over selenium versions | As per the current `main` , I'm not able to run tests:
`AttributeError: 'WebDriver' object has no attribute 'find_elements_by_css_selector'` errors all over the place
If I revert selenium to 4.2, tests pass.
| closed | 2023-03-03T11:25:47Z | 2023-03-03T14:04:37Z | https://github.com/jupyter/nbgrader/issues/1744 | [] | perllaghu | 2 |
inventree/InvenTree | django | 8,289 | [FR] Add "Request for Quote" (RFQ) Feature to Inventree | ### Please verify that this feature request has NOT been suggested before.
- [x] I checked and didn't find a similar feature request
### Problem statement
We build systems that include fabricated custom components (machined aluminum, bent sheet metal, etc.) that we design but 3rd party fabricators manufacture. Thes... | open | 2024-10-15T05:35:24Z | 2025-03-20T14:46:21Z | https://github.com/inventree/InvenTree/issues/8289 | [
"enhancement"
] | jrobelia | 5 |
twopirllc/pandas-ta | pandas | 530 | Some Indicators using future data? | I do a test as following,and possible found more some functions may use future data. pls help to check.
```python
def f1(d1):
df = d1.sort_values(by=["time"], ascending=True)
df["datetime"] = df.fdate + " " + df.time
df.set_index(pd.DatetimeIndex(df["datetime"]), inplace=True)
df.ta.strategy("A... | closed | 2022-05-07T23:52:40Z | 2022-05-23T10:10:19Z | https://github.com/twopirllc/pandas-ta/issues/530 | [
"wontfix",
"info",
"AI / ML"
] | ruifeng96150 | 4 |
hpcaitech/ColossalAI | deep-learning | 5,972 | [fp8] support hybrid parallel plugin | closed | 2024-08-07T05:56:44Z | 2024-08-13T01:44:51Z | https://github.com/hpcaitech/ColossalAI/issues/5972 | [] | wangbluo | 0 | |
roboflow/supervision | machine-learning | 1,120 | the result.mp4 cannot be played on the browser | ### Search before asking
- [X] I have searched the Supervision [issues](https://github.com/roboflow/supervision/issues) and found no similar feature requests.
### Question
i dont know why the result.mp4 is much large than the original, and it cannot be played on the browser, the code is as following
```
import ... | closed | 2024-04-17T00:42:45Z | 2024-05-08T14:47:13Z | https://github.com/roboflow/supervision/issues/1120 | [
"question"
] | wilsonlv | 4 |
gevent/gevent | asyncio | 1,626 | Misleading link in README | * gevent version: master branch
* Python version: n/a
* Operating System: n/a
### Description:
The README links to "bug tracker" that isn't a bug tracker
### What I've run:
https://github.com/gevent/gevent
Notice link to "bug tracker" that takes you to https://github.com/gevent/gevent/wiki/Projects
... | closed | 2020-05-26T05:40:43Z | 2020-05-26T11:04:32Z | https://github.com/gevent/gevent/issues/1626 | [] | Rosuav | 2 |
matplotlib/matplotlib | data-science | 29,739 | Error finding "ninja" when setting up development environment | Following the instructions in https://matplotlib.org/devdocs/devel/development_setup.html#create-local-environment (but using `uv` to manage the virtual environment), I end up with the following error:
```
% uv pip install --verbose --no-build-isolation --editable ".[dev]"
DEBUG uv 0.6.5 (Homebrew 2025-03-06)
DEBUG Se... | open | 2025-03-12T12:24:35Z | 2025-03-12T12:24:35Z | https://github.com/matplotlib/matplotlib/issues/29739 | [] | dstansby | 0 |
HIT-SCIR/ltp | nlp | 331 | how pyltp close log in python program | I want to close pyltp log, but I didn't find the function, anyone how to close log, please tell me. | closed | 2019-01-27T09:59:17Z | 2020-06-17T02:43:39Z | https://github.com/HIT-SCIR/ltp/issues/331 | [] | xiongma | 1 |
ivy-llc/ivy | numpy | 28,634 | Fix Frontend Failing Test: torch - activations.tensorflow.keras.activations.get | To-do List: https://github.com/unifyai/ivy/issues/27498 | closed | 2024-03-18T17:28:51Z | 2024-03-25T13:23:13Z | https://github.com/ivy-llc/ivy/issues/28634 | [
"Sub Task"
] | ZJay07 | 0 |
chezou/tabula-py | pandas | 197 | Error to Import tabula |
I faced the following problem when I try to import tabula after install its package.
The output message shows something get wrong with the Pandas package, but its installation is working well!
>>> import tabula
Traceback (most recent call last):
File "<stdin>", line 1, in <module>
File "D:\Python\lib\site... | closed | 2019-12-16T18:30:06Z | 2019-12-16T18:30:28Z | https://github.com/chezou/tabula-py/issues/197 | [] | macedojleo | 1 |
pydata/xarray | pandas | 9,342 | API for filtering / subsetting | ### What is your issue?
(Copied from https://github.com/xarray-contrib/datatree/issues/79 - see there for more discussion)
---
So far we've only really implemented dictionary-like `get/setitem` syntax, but we should add a variety of other ways to select nodes from a tree too. Here are some suggestions:
```pyt... | open | 2024-08-13T16:12:42Z | 2024-08-13T16:12:42Z | https://github.com/pydata/xarray/issues/9342 | [
"enhancement",
"topic-DataTree"
] | TomNicholas | 0 |
dask/dask | numpy | 10,991 | Combined save and calculation is using excessive memory | Not clear if this is truly a "bug", but it seems highly undesirable + I can't work out how to avoid it
# Describe the issue:
We are trying to save large data arrays to file, and *at the same time* check the data for any occurrences of a given value
All while, hopefully, loading and processing each data chunk only ... | open | 2024-03-11T10:39:33Z | 2024-03-28T11:26:09Z | https://github.com/dask/dask/issues/10991 | [
"needs triage"
] | pp-mo | 3 |
Yorko/mlcourse.ai | data-science | 596 | links are broken on mlcourse.ai | example: https://festline.github.io/notebooks/blob/master/jupyter_english/topic02_visual_data_analysis/topic2_visual_data_analysis.ipynb?flush_cache=true | closed | 2019-05-30T02:15:44Z | 2019-06-27T14:54:06Z | https://github.com/Yorko/mlcourse.ai/issues/596 | [] | nickcorona | 4 |
MaartenGr/BERTopic | nlp | 1,567 | How to get consistent topics and consistent visualizations | I ran my exact same code in two different Google Collab notebooks.
In my first iteration, after running `topic_model.get_topics()` I had 6 topics, and topic 0 looked like:
0: [('as', 0.08563909021495479),
('at', 0.06317604494537135),
('going', 0.060597216092035056),
('getting', 0.060597216092035056),
(... | open | 2023-10-08T00:13:11Z | 2023-10-10T13:16:00Z | https://github.com/MaartenGr/BERTopic/issues/1567 | [] | fgar13 | 1 |
graphdeco-inria/gaussian-splatting | computer-vision | 637 | ValueError: need at least one array to concatenate | i'm using nerf synthetic data. Getting the following error when trying for less number of input images during training like 3 or 4 images , and transforms.json being generated from dense colmap output. I could successsfully run the code for other scenes, it's just blundering with the "leaves" scene. May be bcoz of num... | open | 2024-01-28T02:34:22Z | 2024-02-09T22:09:30Z | https://github.com/graphdeco-inria/gaussian-splatting/issues/637 | [] | Gurutva | 1 |
rio-labs/rio | data-visualization | 186 | [Feature Request] Add `tabs` component | ### Description
I suggest adding a Tabs component to the `rio-ui` Python UI library. Tabs are a useful feature that helps users by organizing content into different sections that they can easily switch between. This makes the layout easier to use and looks more professional. Adding this feature will make `rio-ui` me... | open | 2024-12-03T11:17:32Z | 2024-12-03T13:56:24Z | https://github.com/rio-labs/rio/issues/186 | [
"new component"
] | gunungpw | 1 |
AutoGPTQ/AutoGPTQ | nlp | 327 | 用quant_with_alpaca.py量化微调过的llama2-13b报错AttributeError: 'QuantLinear' object has no attribute 'q4' | python3.8
torch2.0
| open | 2023-09-07T09:32:42Z | 2024-03-04T09:07:38Z | https://github.com/AutoGPTQ/AutoGPTQ/issues/327 | [
"chinese"
] | yzw-yzw | 4 |
streamlit/streamlit | data-science | 10,750 | Support expandable blocks in markdown | ### Checklist
- [x] I have searched the [existing issues](https://github.com/streamlit/streamlit/issues) for similar feature requests.
- [x] I added a descriptive title and summary to this issue.
### Summary
Support expandable content blocks in markdown similar to how its supported in Notion and Github, e.g.:
<deta... | open | 2025-03-12T16:49:06Z | 2025-03-12T17:01:12Z | https://github.com/streamlit/streamlit/issues/10750 | [
"type:enhancement",
"feature:markdown"
] | lukasmasuch | 1 |
django-import-export/django-import-export | django | 2,030 | Remove `FIXME` in `widgets.py` | A [rogue FIXME](https://github.com/django-import-export/django-import-export/blob/e3ce2e3bce1405dfcd12ec4183af2c9b0b235e1b/import_export/widgets.py#L185) persists from #1939.
Need to check that None values are exported correctly to xlsx.
| open | 2025-01-31T21:32:46Z | 2025-01-31T21:32:51Z | https://github.com/django-import-export/django-import-export/issues/2030 | [
"chore"
] | matthewhegarty | 0 |
yunjey/pytorch-tutorial | deep-learning | 198 | Tensorboard image broken: scipy.misc.toimage deprecated | With the latest version of scipy.misc, scipy.misc.toimage is no longer available. To load and save an image as png we now have to use PIL, breaking tensorboard image summary.
Here is how I fixed the bug:
1./ At the end of main.py, log a uint8 image
logger.image_summary(tag, (images * 255).astype(np.uint8), st... | open | 2019-12-04T22:30:22Z | 2021-12-10T02:25:58Z | https://github.com/yunjey/pytorch-tutorial/issues/198 | [] | ghost | 1 |
pytest-dev/pytest-cov | pytest | 574 | Is it possible pytest-cov tie to fixed version of `coverage`? | Looks like we're always pulling latest version of `coverage`.
Recently it's upgraded to 7.0.0 and break old code (I'm using omit rule e.g. `something**` in coveragerc)
I could solve it by adding `coverage` lib with fixed version to my project.
But is it possible to tied to major version number? to avoid breaking... | open | 2022-12-19T12:38:32Z | 2022-12-19T12:42:03Z | https://github.com/pytest-dev/pytest-cov/issues/574 | [] | akivamu | 1 |
ultralytics/ultralytics | deep-learning | 19,647 | Why does accuracy drop to 0.0 during training? | ### Search before asking
- [x] I have searched the Ultralytics YOLO [issues](https://github.com/ultralytics/ultralytics/issues) and [discussions](https://github.com/orgs/ultralytics/discussions) and found no similar questions.
### Question
With my dataset I have this training history:
:
File "test.py", line 91, in <module>
test_instance.run()
File "/usr/local/lib/python2.7/dist-packages/grab-0.4.13-py2.7.egg/grab/spider/base.py", line 941, in run
for result in self.transport.iterate_results():
File "/usr/local/lib/python2.7/dist-packages/grab-0.4.13-py2... | closed | 2014-09-16T10:42:27Z | 2014-09-19T08:11:18Z | https://github.com/lorien/grab/issues/65 | [] | craw1er | 1 |
jowilf/starlette-admin | sqlalchemy | 388 | Enhancement: Update `exclude_fields_from_list`, `exclude_fields_from_detail`, `exclude_fields_from_create`, `exclude_fields_from_edit` conditionally on runtime. | I wan't to disable/enable - show/hide fields conditionally.
Let's say the current user has permission to visit `Company` view but if the current user doesn't have `SUPERUSER` role, they shouldn't see the company contact info in the list view.
Another scenario could be like this:
I have two tables, articles and... | closed | 2023-11-08T06:55:41Z | 2023-11-09T00:58:09Z | https://github.com/jowilf/starlette-admin/issues/388 | [
"enhancement"
] | hasansezertasan | 1 |
Miserlou/Zappa | flask | 1,881 | Local Test -OK, Clean Deploy - Error Post Deployment (Failed to find library, OpenBLAS WARNIN) | <!--- Provide a general summary of the issue in the Title above -->
Post Zappa init. Local Test is fine. No Error in Deploy BUT fails post deployment , Error is as below :
OpenBLAS WARNING - could not determine the L2 cache size on this system
## Context
<!--- Provide a more detailed introduction to the issue itse... | open | 2019-06-05T13:41:14Z | 2020-05-11T11:27:41Z | https://github.com/Miserlou/Zappa/issues/1881 | [] | bbjishnu | 1 |
mitmproxy/mitmproxy | python | 6,947 | Make Rust default but optional dependency | #### Problem Description
`mitmproxy` does not run without Rust components.
Rust is broken on some non-mainstream platforms.
On mainstream platforms it is still a very heavy dependency to build.
#### Proposal
Could we make Rust stuff optional? Enabled by default, but so that it can be disabled manually.
```
... | closed | 2024-06-23T15:47:12Z | 2024-06-23T16:12:22Z | https://github.com/mitmproxy/mitmproxy/issues/6947 | [
"kind/feature"
] | barracuda156 | 3 |
RayVentura/ShortGPT | automation | 146 | 🐛 [Bug]: no method availablbe for opening '/content/ShortGPT/videos' | ### What happened?
when running 'automate the creation of shorts' I get the following error message,
Error File "/content/ShortGPT/gui/ui_tab_short_automation.py", line 114, in create_short
for step_num, step_info in shortEngine.makeContent():
File "/content/ShortGPT/shortGPT/engine/abstract_content_engine.... | open | 2024-10-31T20:04:05Z | 2025-01-16T19:11:10Z | https://github.com/RayVentura/ShortGPT/issues/146 | [
"bug"
] | mavi-unyereno | 1 |
chezou/tabula-py | pandas | 376 | Security vulnerability in tabula-1.0.5-jar-with-dependencies.jar | ### Summary
There is at least one vulnerable package in tabula-1.0.5-jar-with-dependencies.jar
https://github.com/advisories/GHSA-4jrv-ppp4-jm57
### Did you read the FAQ?
- [X] I have read the FAQ
### Did you search GitHub Discussions?
- [X] I have searched the discussions
### (Optional) PDF URL
_... | closed | 2024-02-20T14:25:25Z | 2024-02-21T21:36:34Z | https://github.com/chezou/tabula-py/issues/376 | [
"tabula-java limitation"
] | gsonOutdated | 4 |
charlesq34/pointnet | tensorflow | 153 | batch_inference.py Bug | run batch_inference.py will have this error "unsupported operand type(s) for +: 'range' and 'list'"
I fix it follow this
```
def sample_data(data, num_sample):
""" data is in N x ...
we want to keep num_samplexC of them.
if N > num_sample, we will randomly keep num_sample of them.
... | open | 2018-11-21T01:32:13Z | 2018-11-21T01:32:13Z | https://github.com/charlesq34/pointnet/issues/153 | [] | ldepn | 0 |
statsmodels/statsmodels | data-science | 9,323 | BUG: UECM.from_ardl residuals | #### Describe the bug
When using statsmodels.tsa.ardl.UECM.from_ardl, the residuals method of the resulting UECM subtracts the fitted values of the UECM (i.e., in differences) from the endogenous value of the ARDL (i.e., in levels). This flows through into the methods for testing residuals (serial correlation, etc.)... | closed | 2024-07-30T14:13:26Z | 2024-10-16T08:01:19Z | https://github.com/statsmodels/statsmodels/issues/9323 | [
"comp-tsa",
"type-bug",
"type-bug-wrong"
] | defra-ma | 4 |
SYSTRAN/faster-whisper | deep-learning | 480 | When it runs in a thread, it can run normally. But when the thread exits, it cannot exit normally, causing an exception. | When it runs in a thread, it can run normally. But when the thread exits, it cannot exit normally, causing an exception. | open | 2023-09-19T10:11:30Z | 2023-09-20T01:04:57Z | https://github.com/SYSTRAN/faster-whisper/issues/480 | [] | HerbertLi2020 | 3 |
graphql-python/graphql-core | graphql | 183 | Use type guards | As an example I specifically need them in `type/definition.py` to correctly narrow down the types in a codegen tool. In the meantime I've reimplemented these functions:
```python
def is_required_type(t: Any) -> TypeGuard[GraphQLNonNull]:
return isinstance(t, GraphQLNonNull)
def is_list_type(t: Any) -> Typ... | closed | 2022-11-01T09:27:36Z | 2022-11-03T21:49:25Z | https://github.com/graphql-python/graphql-core/issues/183 | [
"enhancement"
] | helderco | 3 |
pytest-dev/pytest-html | pytest | 596 | Chinese do not display properly in the report(4.0.0rc0、3.2.0) | nodeid show Chinese code normal,but report to html is confused


| open | 2023-03-15T03:36:58Z | 2023-04-03T20:46:33Z | https://github.com/pytest-dev/pytest-html/issues/596 | [] | Abilish | 7 |
3b1b/manim | python | 1,162 | Binomial distribution toy animation | Hi! I would like to animate a "galton board" (see the image below), but I didn't find any tutorial or implementation of gravity.
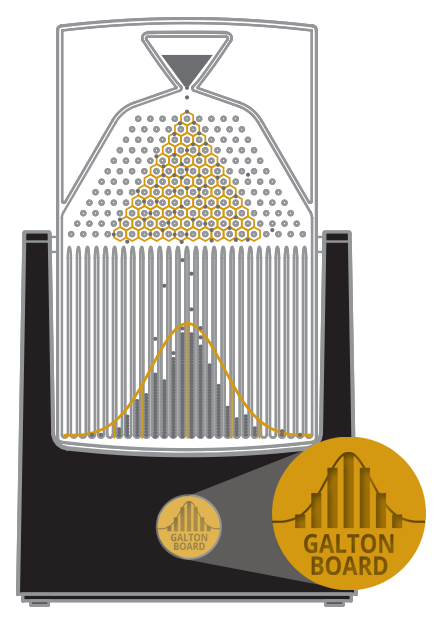
Thanks in advance.
| closed | 2020-07-09T18:44:36Z | 2020-07-10T04:34:44Z | https://github.com/3b1b/manim/issues/1162 | [] | pedroslrey | 2 |
gunthercox/ChatterBot | machine-learning | 2,083 | error in installing chatterbot | i couldnt install chatterbot . i am get error .
coding :
C:\Users\Admin\env>pip install chatterbot
Collecting chatterbot
Using cached ChatterBot-1.0.5-py2.py3-none-any.whl (67 kB)
Collecting nltk<4.0,>=3.2
Using cached nltk-3.5.zip (1.4 MB)
Collecting sqlalchemy<1.3,>=1.2
Using cached SQLAlchemy-1.2.19... | closed | 2020-12-16T11:50:54Z | 2025-02-17T19:23:20Z | https://github.com/gunthercox/ChatterBot/issues/2083 | [] | cat0405 | 1 |
biolab/orange3 | scikit-learn | 6,414 | Edit Domain resets when reopening orange | ### Discussed in https://github.com/biolab/orange3/discussions/6412
<div type='discussions-op-text'>
<sup>Originally posted by **zikook** April 14, 2023</sup>
Hi,
When I close and reopen Orange, changes I've made in Edit Domain, for example naming a variable, sometimes disappear.
This happens when I use the wi... | closed | 2023-04-14T22:04:07Z | 2023-11-30T14:01:56Z | https://github.com/biolab/orange3/issues/6414 | [] | janezd | 6 |
JaidedAI/EasyOCR | machine-learning | 949 | AttributeError: 'Reader' object has no attribute 'readText' | AttributeError: 'Reader' object has no attribute 'readText' | closed | 2023-02-10T13:18:57Z | 2023-02-10T13:23:24Z | https://github.com/JaidedAI/EasyOCR/issues/949 | [] | Shoichii | 0 |
pytorch/pytorch | machine-learning | 149,061 | Best way to disable "fx graph cache hit for key"? | I have a possibly niche use case:
* I might rerun the same run a few times
* So I will run into "fx graph cache hit for key"
* I want to see precompilation and autotuning in the logs
* So I want to bypass fx graph cache
* Want to avoid having to C++ compile the kernel again (codecache does that), since C++ compile... | open | 2025-03-12T17:39:14Z | 2025-03-13T15:18:15Z | https://github.com/pytorch/pytorch/issues/149061 | [
"triaged",
"module: fx.passes",
"module: inductor"
] | henrylhtsang | 0 |
yt-dlp/yt-dlp | python | 12,580 | Chaturbate Failed to download m3u8 information | ### Checklist
- [x] I'm reporting that yt-dlp is broken on a **supported** site
- [x] I've verified that I have **updated yt-dlp to nightly or master** ([update instructions](https://github.com/yt-dlp/yt-dlp#update-channels))
- [x] I've checked that all provided URLs are playable in a browser with the same IP and same... | open | 2025-03-12T00:15:53Z | 2025-03-18T22:39:41Z | https://github.com/yt-dlp/yt-dlp/issues/12580 | [
"external issue",
"NSFW"
] | mikeymatrix70 | 14 |
minivision-ai/photo2cartoon | computer-vision | 35 | 头像分割模型的训练数据集 | 请问能否提供头像分割模型的训练数据集? | closed | 2020-07-18T06:24:31Z | 2020-07-20T12:02:45Z | https://github.com/minivision-ai/photo2cartoon/issues/35 | [] | WANGRuoxi233 | 2 |
Guovin/iptv-api | api | 317 | 你这个rtp地址如何转成m3u的呢,或者说这个直播源怎么用 | 你这个rtp地址如何转成m3u的呢,或者说这个直播源怎么用 | closed | 2024-09-11T06:03:25Z | 2024-09-12T01:56:15Z | https://github.com/Guovin/iptv-api/issues/317 | [
"help wanted",
"question"
] | seitaone | 1 |
autogluon/autogluon | computer-vision | 4,812 | [BUG] Time Series train data,i excluded_model_types have 'ChronosZeroShot[bolt_base]', 'ChronosFineTuned[bolt_small]',but train still there | **Bug Report Checklist**
<!-- Please ensure at least one of the following to help the developers troubleshoot the problem: -->
- [x] I provided code that demonstrates a minimal reproducible example. <!-- Ideal, especially via source install -->
- [ ] I confirmed bug exists on the latest mainline of AutoGluon via sour... | closed | 2025-01-20T10:06:49Z | 2025-01-20T10:48:35Z | https://github.com/autogluon/autogluon/issues/4812 | [
"bug: unconfirmed",
"Needs Triage"
] | aspeden | 1 |
keras-team/keras | machine-learning | 20,276 | GRU + Large `recurrent_dropout` Bug | **Keras version:** 3.5.0
**Backend:** TensorFlow 2.17.0
I encountered a strange bug when working with the GRU layer. If you create a simple model with a GRU layer and set `recurrent_dropout=0.5`, very strange behavior occurs:
0. **With sequence length 20**: Everything works as expected.
1. **With sequence len... | closed | 2024-09-21T22:16:22Z | 2024-12-18T17:30:08Z | https://github.com/keras-team/keras/issues/20276 | [
"type:Bug"
] | nokados | 6 |
activeloopai/deeplake | tensorflow | 2,977 | [BUG] Deeplake dataset row access fails under multiprocessing | ### Severity
P0 - Critical breaking issue or missing functionality
### Current Behavior
Accessing deeplake dataset rows under a multiprocessing library such as concurrent futures results in an error.
Consider the following script which creates a dummy deeplake dataset and tries to access it with multiprocessing
... | closed | 2024-10-25T22:03:10Z | 2024-11-08T03:45:47Z | https://github.com/activeloopai/deeplake/issues/2977 | [
"bug"
] | abhayv | 3 |
pyg-team/pytorch_geometric | deep-learning | 9,570 | LLM + GNN Example Missing | ### 🚀 The feature, motivation and pitch
Hello, in your example documentation there exists a directory `llm` with a README containing a title of `Examples for Co-training LLMs and GNNs`, however, the remainder of the document is empty.
Is the example missing? Or was it never meant to be merged in #9350 ?
Thank... | closed | 2024-08-05T15:37:15Z | 2025-01-21T17:06:31Z | https://github.com/pyg-team/pytorch_geometric/issues/9570 | [
"feature"
] | LaneMatthewJ | 1 |
microsoft/qlib | deep-learning | 1,099 | Segmentation Fault when qrun with lightgbm workflow config | ## 🐛 Bug Description
(quant) ➜ examples git:(main) ✗ qrun benchmarks/LightGBM/workflow_config_lightgbm_Alpha158.yaml
[98703:MainThread](2022-05-15 11:46:07,937) INFO - qlib.Initialization - [config.py:402] - default_conf: client.
[98703:MainThread](2022-05-15 11:46:07,938) INFO - qlib.Initialization - [__ini... | closed | 2022-05-15T03:56:41Z | 2025-02-27T17:22:05Z | https://github.com/microsoft/qlib/issues/1099 | [
"bug"
] | ethanygao | 8 |
PaddlePaddle/ERNIE | nlp | 94 | 显卡内存不足导致的?但错误日志不明显,辛苦确认下。 | 同样的脚本,小样本语料都基本是ok的。
大样本就会跪。
batch size是 64
猜测是显存不足,但是错误日志看着很不明显,辛苦确认下。
I0413 02:31:41.502923 6739 TrainerInternal.cpp:165] Batch=48599 samples=3110336 AvgCost=0.726715 CurrentCost=6.82351 Eval: error=0.0763677 CurrentEval: error=0.46875
*** Aborted at 1555093901 (unix time) try "date -d @1555093901" if you ... | closed | 2019-04-13T08:55:24Z | 2020-05-28T13:52:41Z | https://github.com/PaddlePaddle/ERNIE/issues/94 | [
"wontfix"
] | onfireisme | 5 |
junyanz/pytorch-CycleGAN-and-pix2pix | pytorch | 735 | optimal parameters for synthetic depth image to real depth image | Hi,
I am planning to train a cycleGAN model to translate synthetic depth images to real depth images from my depth-camera. I do not have any idea how to choose the optimal parameters. My synthetic and real images have size 480x640. I am planning to resize them to 512x512 -> load_size=512 and I will use crop_size=512. ... | open | 2019-08-19T14:16:42Z | 2019-09-03T19:13:02Z | https://github.com/junyanz/pytorch-CycleGAN-and-pix2pix/issues/735 | [] | frk1993 | 3 |
ibis-project/ibis | pandas | 10,609 | feat: Add Feldera backend | ### Which new backend would you like to see in Ibis?
[Feldera](https://www.feldera.com) is a new streaming database with an incremental compute engine. It would be awesome to have an Ibis backend similar to RisingWave
### Code of Conduct
- [X] I agree to follow this project's Code of Conduct | open | 2024-12-22T23:51:12Z | 2024-12-23T14:38:01Z | https://github.com/ibis-project/ibis/issues/10609 | [
"feature",
"new backend"
] | rupurt | 2 |
plotly/dash | jupyter | 2,484 | [Feature Request] Dash Pages - custom page_container in dash.register_page | **Is your feature request related to a problem? Please describe.**
I think it would be convenient to be able to redirect some pages to custom `page_container`. There might be case when we don't want to display our page in standard way in `page_container`, but for example as a whole new page.
**Describe the solution... | closed | 2023-03-30T13:13:50Z | 2024-07-24T18:30:07Z | https://github.com/plotly/dash/issues/2484 | [] | m-ganko | 1 |
Textualize/rich | python | 2,882 | [BUG] Wrong encoding in Windows CMD or Powershell redirection | **Describe the bug**
**Problem**: `Rich` uses the wrong `stdout.encoding` in Windows when the underlining `stdout` is a [`FileIO`][fio] (this is the default mode for [CMD/PowerShell redirection][rd] such as `pip > out.txt`). In most cases, the program crashes with `UnicodeEncodeError` or prints out Mojibake.
[rd]... | open | 2023-03-19T14:56:18Z | 2023-09-04T22:31:25Z | https://github.com/Textualize/rich/issues/2882 | [
"Needs triage"
] | gdlmx | 1 |
sqlalchemy/sqlalchemy | sqlalchemy | 11,822 | add "The server failed to resume the transaction. to disconnect exceptions | ### Discussed in https://github.com/sqlalchemy/sqlalchemy/discussions/11809
<div type='discussions-op-text'>
<sup>Originally posted by **manmayaray** August 30, 2024</sup>
### Describe the use case
File "src/pymssql/_pymssql.pyx", line 479, in pymssql._pymssql.Cursor.execute
pymssql._pymssql.OperationalError... | closed | 2024-09-02T15:19:57Z | 2024-09-02T23:43:04Z | https://github.com/sqlalchemy/sqlalchemy/issues/11822 | [
"bug",
"SQL Server",
"near-term release"
] | zzzeek | 2 |
CorentinJ/Real-Time-Voice-Cloning | tensorflow | 482 | Model files not found. | While trying to install the Real-Time-Voice-Cloning repo,
I am unable to run the toolbox, because I always get the following error:
_Error: Model files not found. If needed, download them here:_
I tried this command python `demo_toolbox.py`
and this one with the path to the modules `python demo_toolbox.py -d C:\Use... | closed | 2020-08-11T12:42:51Z | 2020-08-11T17:51:36Z | https://github.com/CorentinJ/Real-Time-Voice-Cloning/issues/482 | [] | c0ball | 7 |
Nekmo/amazon-dash | dash | 81 | Update to support Home Assistant's new authentication system | Put an `x` into all the boxes [ ] relevant to your *issue* (like this: `[x]`)
### What is the purpose of your *issue*?
- [ ] Bug report (encountered problems with amazon-dash)
- [x] Feature request (request for a new functionality)
- [ ] Question
- [ ] Other
#### Description
With the release of version 0.7... | closed | 2018-08-30T03:23:49Z | 2018-09-25T02:17:48Z | https://github.com/Nekmo/amazon-dash/issues/81 | [
"enhancement"
] | bachya | 2 |
satwikkansal/wtfpython | python | 250 | Giving interviewers crazy ideas |
This repository unleashes potentially deadly information and ideas to interviewers.
Thus, it can become the potential cause of several interview candidates pulling their hair out, possibly reaching a state of madness
#### Some background:
 does not handle index arrays of booleans correctly for data dictionary in Detections object. | ### Search before asking
- [X] I have searched the Supervision [issues](https://github.com/roboflow/supervision/issues) and found no similar bug report.
### Bug
When I tried to use boolean array indexing to get specific detections from a Detections object, the data field sometimes returns the wrong values (e... | closed | 2024-03-28T03:29:54Z | 2024-03-28T12:43:07Z | https://github.com/roboflow/supervision/issues/1061 | [
"bug",
"api:detection"
] | rolson24 | 3 |
microsoft/nni | deep-learning | 5,149 | Remove trials from experiment | <!-- Please only use this template for submitting enhancement requests -->
**What would you like to be added**:
Remove trials from experiment, either in the web page or in the command line.
**Why is this needed**:
Sometime one trial may get strange result due to numerical issue, which is difficult to anticipa... | open | 2022-09-30T11:55:03Z | 2022-10-08T09:35:44Z | https://github.com/microsoft/nni/issues/5149 | [
"new feature",
"WebUI",
"need more info"
] | DDDOH | 4 |
skypilot-org/skypilot | data-science | 4,856 | [API server] Warning when shutdown foreground server by ctrl-c | ```
multiprocessing/resource_tracker.py:224: UserWarning: resource_tracker: There appear to be 5 leaked semaphore objects to clean up at shutdown
warnings.warn('resource_tracker: There appear to be %d '
```
Still hitting it somehow, https://github.com/skypilot-org/skypilot/pull/4852#issuecomment-2690338719 | closed | 2025-02-28T16:48:11Z | 2025-03-19T00:47:35Z | https://github.com/skypilot-org/skypilot/issues/4856 | [] | aylei | 0 |
deepfakes/faceswap | deep-learning | 1,335 | Can I run faceswap.py directly without installation? | 1. I got nothing from the following try:
```console
➜ faceswap git:(master) ✗ python faceswap.py extract -i ./data -o ./output
Setting Faceswap backend to NVIDIA
<module 'lib.cli.args' from '....../faceswap/lib/cli/args.py'>
usage: faceswap.py [-h] {extract,train,convert,gui} ...
positional arguments:
... | closed | 2023-08-01T21:37:35Z | 2023-08-03T10:10:07Z | https://github.com/deepfakes/faceswap/issues/1335 | [] | jiapei100 | 2 |
aminalaee/sqladmin | sqlalchemy | 847 | Parameter `identity` can't be used | ### Checklist
- [X] The bug is reproducible against the latest release or `master`.
- [X] There are no similar issues or pull requests to fix it yet.
### Describe the bug
Parameter `identity` can't be used because `ModelViewMeta` redefines this parameter [here](https://github.com/aminalaee/sqladmin/blob/main/sqladmi... | open | 2024-10-28T13:39:56Z | 2024-10-28T13:39:56Z | https://github.com/aminalaee/sqladmin/issues/847 | [] | sheldygg | 0 |
InstaPy/InstaPy | automation | 6,265 | Unable to save account progress HELP??!! | **Hi, im having problems for 2 days straight. i can't seem to have my insta bot running i got this:**
Workspace in use: "C:/Users/ahsan/OneDrive/Bureaublad/instapy/assets/InstaPy"
OOOOOOOOOOOOOOOOOOOOOOOOOOOOOOOOOOOOOOOOOOOOOOOOOOOOOO
INFO [2021-07-09 13:20:47] [zravsalie] Session started!
ooooooooooooooooooooo... | open | 2021-07-09T11:32:23Z | 2021-07-21T13:37:57Z | https://github.com/InstaPy/InstaPy/issues/6265 | [] | superindo | 1 |
ndleah/python-mini-project | data-visualization | 232 | Typo in Firebase_Authentication_Using_Flask | # Description
In the sign up template there is a small typo: 'atleast' should read 'at least'. This typo is also in the screenshot.
## Type of issue
- [x] Documentation
## Solution
- I will create a pull request to change the text, and create a new screenshot.
## Checklist:
- [x] I have read the proj... | closed | 2024-03-02T19:42:18Z | 2024-06-02T05:14:26Z | https://github.com/ndleah/python-mini-project/issues/232 | [] | coderwessel | 0 |
tpvasconcelos/ridgeplot | plotly | 215 | Different colors or colormaps for different data series | Hi, thank you for this package.
I was wandering if it was possible to have the colors (or colormaps) represent categorical data. For example, in the minimum and maximum temperature example in the documentation, have all data regarding minimum temperature in blue and data regarding maximum temperatures in red.
I made ... | closed | 2024-10-10T12:08:39Z | 2024-11-18T15:51:34Z | https://github.com/tpvasconcelos/ridgeplot/issues/215 | [
"enhancement",
"COLOR"
] | lorenzoamir | 11 |
fastapi/sqlmodel | pydantic | 94 | Async, upsert get_or_create, helpers | ### First Check
- [X] I added a very descriptive title to this issue.
- [X] I used the GitHub search to find a similar issue and didn't find it.
- [X] I searched the SQLModel documentation, with the integrated search.
- [X] I already searched in Google "How to X in SQLModel" and didn't find any information.
- [X] I al... | open | 2021-09-14T06:34:54Z | 2022-01-12T02:53:12Z | https://github.com/fastapi/sqlmodel/issues/94 | [
"question"
] | tuxpowered | 2 |
polarsource/polar | fastapi | 4,295 | Checkout: Background in checkout page is cut off | ### Description
<!-- A brief description with a link to the page on the site where you found the issue. -->
The checkout page background seems to be cut off, the background only goes as far as the screen height.
### Current Behavior
<!-- A brief description of the current behavior of the issue. -->
The backgr... | closed | 2024-10-24T12:14:41Z | 2024-10-29T13:45:39Z | https://github.com/polarsource/polar/issues/4295 | [
"bug"
] | reynaldichernando | 1 |
dmlc/gluon-cv | computer-vision | 853 | TypeError: zip argument #2 must support iteration | I trained the fastrcnn on my custom datasets, which only has one class 'ship', and I got this error after the first epoch finished.
>Traceback (most recent call last):
File "train_faster_rcnn.py", line 500, in <module>
train(net, train_data, val_data, eval_metric, ctx, args)
File "train_faster_rcnn.py",... | closed | 2019-07-08T02:19:43Z | 2021-05-24T06:45:29Z | https://github.com/dmlc/gluon-cv/issues/853 | [
"Stale"
] | Keanu-L | 1 |
openapi-generators/openapi-python-client | rest-api | 952 | Missing references in API generation process | **Describe the bug**
While trying to generate the OpenAPI client, I come across a bug that not only modifies several files unnecessarily but also displays a warning message about endpoint generating, which root cause is unclear to me:
```
Warning(s) encountered while generating. Client was generated, but some ... | open | 2024-02-01T23:13:06Z | 2024-09-17T00:01:11Z | https://github.com/openapi-generators/openapi-python-client/issues/952 | [] | kwaksaewon | 2 |
DistrictDataLabs/yellowbrick | matplotlib | 616 | Extend color selection on ResidualsPlot() to histogram | When running ResidualsPlot() visualizer, the `test_color` and `train_color` do not propagate down to the histogram. It would be nice if the histogram on the right reflected the color choices as well.
```visualizer = ResidualsPlot(regr_ols, test_color='#615d6c', train_color='#6F8AB7')
visualizer.fit(X_train, y_train... | closed | 2018-09-19T04:47:39Z | 2018-09-19T20:09:36Z | https://github.com/DistrictDataLabs/yellowbrick/issues/616 | [] | black-tea | 1 |
exaloop/codon | numpy | 150 | Cannot detect attributes added via __init__ | I've tried to run Codon on this source code:
```python
class MyClass:
def __init__(self, value):
self.value
MyClass(1)
```
```bash
codon build --release --cost-kind=latency --exe ./1.py
```
But got an error:
```
1.py:3:9-19: error: 'MyClass' object has no attribute 'value'
╰─ 1.py:5:1-11:... | closed | 2023-01-03T18:18:38Z | 2023-01-04T01:56:20Z | https://github.com/exaloop/codon/issues/150 | [] | dolfinus | 1 |
explosion/spaCy | data-science | 13,127 | Spacy defines Noun as a root for a sentence | Please I have a questio about spacy dep:
Lets take two example sentences: "A **company** doing social media", "a company that do social media"
company is the root in both. Why? and how spacy was trained to get such result?
Are there functions to update Spacy for this specific structure?
So that I annotate the s... | closed | 2023-11-15T09:23:08Z | 2023-12-16T00:02:25Z | https://github.com/explosion/spaCy/issues/13127 | [] | Ali-MH-Mansour | 1 |
marshmallow-code/apispec | rest-api | 108 | How to specify attributes (such as dump_only,...) on Nested fields? | Say you have a dump_only Nested field in your model.
The model reads:
```python
class Parent(Schema):
child = Nested(Child, dump_ony=True)
```
Assuming you added Child to the definitions, the spec then looks like
```
"Parent": {
"properties": {
"child": {
"$ref": "#/... | closed | 2017-02-16T17:53:19Z | 2017-03-05T14:10:34Z | https://github.com/marshmallow-code/apispec/issues/108 | [] | lafrech | 2 |
STVIR/pysot | computer-vision | 113 | Question about pre-trained backbone | Imagenet-based pre-trained backbones expect input images normalized in the same way:
1. The images have to be loaded in to a range of [0, 1]
2. then normalized using mean = [0.485, 0.456, 0.406] and std = [0.229, 0.224, 0.225]
My questions:
1. Do we need to follow the same rule for object tracking ?
2. For Sia... | closed | 2019-07-17T11:32:52Z | 2019-10-27T17:32:34Z | https://github.com/STVIR/pysot/issues/113 | [] | chris-mh-wu | 6 |
waditu/tushare | pandas | 1,118 | 龙虎榜数据缺失 | 根据调取方法pro.query('top_list', trade_date =date)中,我发现有时候会出现数据缺失的现象。
例如:
`pro.query('top_list', trade_date = ‘20190809’)`
时,我们可以看到,只有两条华阳国际的记录,分别是:
` trade_date ... reason`
`12 20190809 ... 连续三个交易日内,涨幅偏离值累计达到20%的证券`
`13 20190809 ... ... | open | 2019-08-13T03:53:10Z | 2019-08-14T02:36:45Z | https://github.com/waditu/tushare/issues/1118 | [] | thegreenflamingo | 1 |
Subsets and Splits
No community queries yet
The top public SQL queries from the community will appear here once available.