
repo_name stringlengths 9 75 | topic stringclasses 30
values | issue_number int64 1 203k | title stringlengths 1 976 | body stringlengths 0 254k | state stringclasses 2
values | created_at stringlengths 20 20 | updated_at stringlengths 20 20 | url stringlengths 38 105 | labels listlengths 0 9 | user_login stringlengths 1 39 | comments_count int64 0 452 |
|---|---|---|---|---|---|---|---|---|---|---|---|
aleju/imgaug | deep-learning | 654 | Unzoom without padding | Hello,
Is it possible to unzoom without padding?
```
img_trans_train = iaa.Sequential([
iaa.Affine(scale=(0.32, 1)),
iaa.CropToFixedSize(width=1920, height=1280),
])
```
My original images are 6000x4000. If a scale of 0.32 is applied, the images become 1920x1280 so CropToFixedSize sho... | closed | 2020-04-19T16:54:35Z | 2020-04-19T17:16:41Z | https://github.com/aleju/imgaug/issues/654 | [] | Neabfi | 1 |
geopandas/geopandas | pandas | 2,945 | BUG: | - [x] I have checked that this issue has not already been reported.
- [x] I have confirmed this bug exists on the latest version of geopandas.
- [ ] (optional) I have confirmed this bug exists on the main branch of geopandas.
---
I tried running the example from [this](https://geopandas.org/en/v0.13.2/galle... | closed | 2023-06-28T14:43:56Z | 2023-07-05T01:50:09Z | https://github.com/geopandas/geopandas/issues/2945 | [
"bug",
"needs triage"
] | pushkarnimkar | 2 |
pytest-dev/pytest-html | pytest | 135 | Adding log to HTML report when show details | Hello there, I use these kind of test with pytest and the html pluging:
```
import logging
log = logging.getLogger(__name__)
def test_random(app_config):
log.info("Random test")
pass
```
Is there a way to get the output of log.info in the report? Even when the test is passed? I only get output when ... | closed | 2017-10-29T16:21:44Z | 2022-03-17T16:35:15Z | https://github.com/pytest-dev/pytest-html/issues/135 | [] | nicoarg | 6 |
saulpw/visidata | pandas | 1,446 | Enable setting HTTP User-Agent header | I'm trying to explore this API, but it has aggressive 'security' controls which block the default requests user agent.
This doesn't make much sense for an API, but I can work around it in requests by using the Firefox User-Agent. However, I'd really like to do this in visidata so I can hit the endpoint directly, rathe... | closed | 2022-07-29T04:59:13Z | 2022-07-31T11:38:03Z | https://github.com/saulpw/visidata/issues/1446 | [
"wishlist",
"wish granted"
] | daviewales | 6 |
seleniumbase/SeleniumBase | web-scraping | 2,396 | How to connect seleniumbase.Driver to "debugger_address" | Someone can help me connect seleneniumbase.Driver to a existing driver with "debugger_address" and "chromedriver" was patched. I tried some code below
Example 1:
```
from seleniumbase.undetected import Chrome, ChromeOptions
remote_debugging_address = "127.0.0.1:5555"
options = ChromeOptions()
options.debugger_a... | closed | 2023-12-29T05:58:08Z | 2023-12-29T17:56:51Z | https://github.com/seleniumbase/SeleniumBase/issues/2396 | [
"duplicate",
"question",
"UC Mode / CDP Mode"
] | henzycuong1 | 1 |
tartiflette/tartiflette | graphql | 263 | Variable definition aren't properly validated on non-nullable list items | When defining a variable definition as follow `$myVar: [String!]`, Tartiflette engine returns an error when we don't provide a value for this variable even if its not a mandatory one. This seems to be due to the `TartifletteVisitor` which enter in the `_on_non_null_type_in` method and marks the whole variable definitio... | closed | 2019-07-16T09:54:45Z | 2019-07-17T12:00:15Z | https://github.com/tartiflette/tartiflette/issues/263 | [
"bug"
] | Maximilien-R | 1 |
d2l-ai/d2l-en | machine-learning | 1,676 | Fomula 2.4.11 does not make sense | 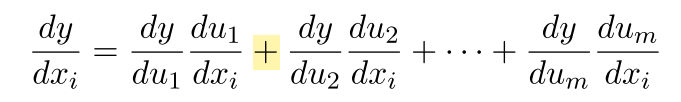
This formula is in the ["calculus" section](https://github.com/d2l-ai/d2l-en/blob/83ecc03a240f1e30dc36dd53083b1d5914391bcc/chapter_preliminaries/calculus.md) -> "Chain Rule". If we remove those $du_i$, it ... | closed | 2021-03-16T15:57:58Z | 2021-03-20T04:43:57Z | https://github.com/d2l-ai/d2l-en/issues/1676 | [] | Banyc | 2 |
scikit-optimize/scikit-optimize | scikit-learn | 897 | AttributeError: 'NoneType' object has no attribute 'log10' | Hello,
I used to use
```
scikit-optimize 0.5.2
```
and it worked fine.
Today, I tried my same experiment but using
```
scikit-optimize 0.7.4
```
and I am having the following error:
```
File "/home/karahbit/ve-radical.hpo/lib/python3.6/site-packages/skopt/space/space.py", line 234, in __init__
se... | closed | 2020-03-27T05:07:32Z | 2020-03-29T21:29:45Z | https://github.com/scikit-optimize/scikit-optimize/issues/897 | [] | karahbit | 2 |
fa0311/TwitterInternalAPIDocument | graphql | 24 | Not working github action | closed | 2022-10-19T23:32:59Z | 2022-10-20T02:24:18Z | https://github.com/fa0311/TwitterInternalAPIDocument/issues/24 | [
"bug"
] | fa0311 | 1 | |
smarie/python-pytest-cases | pytest | 157 | Can't get cartesian product of cases depending on fixture | In the same way that this
```python
import sys
import pytest_cases
@pytest_cases.parametrize("x", [1, 2, 3])
def case_x(x):
return x
@pytest_cases.parametrize("y", [1, 2, 3])
def case_y(y):
return y
@pytest_cases.parametrize_with_cases("x", cases=case_x)
@pytest_cases.parametrize_with_cas... | closed | 2020-12-03T23:11:09Z | 2020-12-04T10:15:15Z | https://github.com/smarie/python-pytest-cases/issues/157 | [] | plammens | 2 |
python-gitlab/python-gitlab | api | 2,229 | retrieving commit stats from a ProjectMergeRequest | ## Description of the problem, including code/CLI snippet
**feature request**
There isn't a way to get the statistics associated with the commits of a given ProjectMergeRequest object
```
# project is of type Project
mrs = project.mergerequests.list(all=True)
for mr in mrs:
comms = mr.commits(all=True)
... | closed | 2022-08-09T22:39:29Z | 2023-08-14T01:10:25Z | https://github.com/python-gitlab/python-gitlab/issues/2229 | [
"support"
] | roth-mh | 2 |
arnaudmiribel/streamlit-extras | streamlit | 41 | Add https://github.com/arnaudmiribel/streamlit-faker | (It requires streamlit-extras, not sure if that's gonna raise troubles) | closed | 2022-10-05T20:52:35Z | 2022-11-10T23:19:07Z | https://github.com/arnaudmiribel/streamlit-extras/issues/41 | [
"enhancement"
] | arnaudmiribel | 0 |
thomaxxl/safrs | rest-api | 85 | Run in example demo_relationship.py creating users or books in flask_admin returns Integrity Errors | Integrity error. (sqlite3.IntegrityError) NOT NULL constraint failed: Users.id [SQL: INSERT INTO "Users" (name, email) VALUES (?, ?)] [parameters: ('user4711', 'u4711@mail.com')] (Background on this error at: http://sqlalche.me/e/13/gkpj)
Primary Key is missing in the Insert Syntax.
class User(SAFRSBase, db.Mode... | closed | 2020-12-21T20:27:44Z | 2021-02-03T15:56:05Z | https://github.com/thomaxxl/safrs/issues/85 | [] | agoe | 17 |
zappa/Zappa | django | 608 | [Migrated] Lambda/Zappa Request Concurrency and Speed | Originally from: https://github.com/Miserlou/Zappa/issues/1559 by [sibblegp](https://github.com/sibblegp)
<!--- Provide a general summary of the issue in the Title above -->
## Context
<!--- Provide a more detailed introduction to the issue itself, and why you consider it to be a bug -->
<!--- Also, please make sur... | closed | 2021-02-20T12:26:33Z | 2022-07-16T06:54:20Z | https://github.com/zappa/Zappa/issues/608 | [] | jneves | 1 |
widgetti/solara | flask | 207 | Less dependencies | Not even recovered from the pydantic nightmare, I think we should see if we can trim down our dependencies. The risk of a package breaking in the future, not providing a backward and/or forward compatibility or not removing the changing the minimal Python version required has bitten us too many times in the Python ecos... | open | 2023-07-11T15:09:20Z | 2023-07-21T07:23:24Z | https://github.com/widgetti/solara/issues/207 | [] | maartenbreddels | 9 |
huggingface/pytorch-image-models | pytorch | 1,566 | keyerror from model.state_dict() | I try to use convnext_base_384_in22ft1k to train my model, so load the weight of 'https://dl.fbaipublicfiles.com/convnext/convnext_base_22k_1k_384.pth', but it show me, keyerror: stem.0.weight.
it looks like convnext_base_384_in22ft1k doesnot have stem.0.weight, but 'https://dl.fbaipublicfiles.com/convnext/convnext_b... | closed | 2022-11-25T02:47:47Z | 2023-04-22T19:36:16Z | https://github.com/huggingface/pytorch-image-models/issues/1566 | [
"bug"
] | Chaoran-F | 8 |
deepset-ai/haystack | nlp | 8,192 | YAML deserialization error in `OutputAdapter` when using `List` | **Describe the bug**
YAML deserialization fails for `OutputAdapter` when using `List` in the `output_type` parameter. Here's an example:
```python
from haystack import Pipeline
pipeline_yaml = """
components:
output_adapter:
type: haystack.components.converters.output_adapter.OutputAdapter
init_pa... | closed | 2024-08-10T10:35:52Z | 2024-08-13T12:38:24Z | https://github.com/deepset-ai/haystack/issues/8192 | [
"type:bug",
"P1"
] | oryx1729 | 4 |
albumentations-team/albumentations | deep-learning | 2,394 | [New feature] Add apply_to_images to CLAHE | open | 2025-03-11T00:59:04Z | 2025-03-11T00:59:11Z | https://github.com/albumentations-team/albumentations/issues/2394 | [
"enhancement",
"good first issue"
] | ternaus | 0 | |
joke2k/django-environ | django | 255 | AttributeError: 'PosixPath' object has no attribute 'read' | I am getting the following error
```
File "<frozen importlib._bootstrap>", line 665, in _load_unlocked
File "<frozen importlib._bootstrap_external>", line 678, in exec_module
File "<frozen importlib._bootstrap>", line 219, in _call_with_frames_removed
File "/usr/src/app/path/settings.py", line 30, in <mod... | closed | 2020-05-05T16:12:50Z | 2020-05-05T17:24:30Z | https://github.com/joke2k/django-environ/issues/255 | [] | pupattan | 1 |
ultralytics/ultralytics | computer-vision | 19,097 | How does segmentation task work | ### Search before asking
- [x] I have searched the Ultralytics YOLO [issues](https://github.com/ultralytics/ultralytics/issues) and [discussions](https://github.com/orgs/ultralytics/discussions) and found no similar questions.
### Question
Hi team!
I have tried my best to figure out how yolo-seg works but i failed... | open | 2025-02-06T09:15:44Z | 2025-02-07T03:31:03Z | https://github.com/ultralytics/ultralytics/issues/19097 | [
"question",
"segment"
] | JasonSloan | 4 |
noirbizarre/flask-restplus | api | 70 | "Can't read swagger JSON" with url_prefix='/' in a blueprint | Hi,
I have a current flask-restful server that we want to upgrade and add blueprints so that we can root different versions with "v2", "v3", etc.To be backward compatible, we would like do the following:
```
FLASK_APP = flask.Flask(__name__)
blueprint = flask.Blueprint('v1', __name__, url_prefix='/')
API = restplus.A... | closed | 2015-09-17T02:21:15Z | 2015-10-14T21:00:14Z | https://github.com/noirbizarre/flask-restplus/issues/70 | [] | ebourgeois | 5 |
seleniumbase/SeleniumBase | web-scraping | 2,382 | How to restart the browser with pytest? | 1. I have millons of urls and need to crawl the data from the website.
2. The anti-crawling technologies restrict that one broswer can only crawl ten pages, then you must close the browser and restart it again.
3. I find that pytest is designed for web testing, not crawling website, it's hard to restart the browser.
... | closed | 2023-12-22T02:41:36Z | 2023-12-23T05:53:37Z | https://github.com/seleniumbase/SeleniumBase/issues/2382 | [
"question",
"UC Mode / CDP Mode"
] | mIgLLL | 1 |
flasgger/flasgger | rest-api | 479 | Body not required when at least one parameter of the given schema is required | Hello,
# Describe bug
I use Flasgger with Marshmallow. If a schema is used for the body of a POST request, the body is not described as required.
# How to reproduce bug
For example, my application has one endpoint to create an user: "/v1/pcc/{pcc_uid}/user" with a body parameter which is a UserSchema. One param... | open | 2021-05-10T14:49:36Z | 2021-05-10T14:49:36Z | https://github.com/flasgger/flasgger/issues/479 | [] | ced42 | 0 |
microsoft/nni | pytorch | 5,456 | 'Trainer' object has no attribute 'optimizer_frequencies' | **Describe the issue**: when running the experiment via experiment.run(config), this error throws :
AttributeError Traceback (most recent call last)
[<ipython-input-32-1486538249e8>](https://localhost:8080/#) in <module>
6 config = RetiariiExeConfig(execution_engine='oneshot')
... | open | 2023-03-16T16:55:02Z | 2023-05-29T02:15:29Z | https://github.com/microsoft/nni/issues/5456 | [] | yasmineLalabouali | 2 |
iperov/DeepFaceLab | machine-learning | 5,428 | Quick96 - cant update preview | I have created deepfakes before and there were no problems with them. But now when i start to train quick96 it goes to ~1093 iterations i can't update the preview. Well, i can update it, but i need to wait about 20 minutes. I dont really know why this can happen. I have pretty bad gpu, but i didnt got any problems befo... | open | 2021-11-15T08:59:03Z | 2023-06-08T22:47:35Z | https://github.com/iperov/DeepFaceLab/issues/5428 | [] | kolyapichkur | 1 |
onnx/onnx | tensorflow | 6,348 | Unexpected floatBuffer output with onnxModel that substract 2 input floatBuffer | # Ask a Question
### Question
I have a simple onnxmodel that have as input 2 float x, y and give as output x-y. I tried to implement in java a wrapper that load the model and then display the output buffer. So for example I have filled the input Buffers x with 3.0 and y with 1.0, so that i expect to get a buffer ... | closed | 2024-09-05T19:27:37Z | 2024-09-19T13:59:14Z | https://github.com/onnx/onnx/issues/6348 | [
"question"
] | HasnaBoumiza | 1 |
flairNLP/flair | pytorch | 3,163 | [Question]: Best way to run a Flair NER model in parallel across different points in an application | ### Question
Hello Flair team,
I am currently using a Named Entity Recognition (NER) model built with Flair in various points of my application. I would like to know the most efficient way to run this model in parallel. Is it necessary to load the model into memory at each point in the application where it is used?... | closed | 2023-03-27T15:11:58Z | 2023-09-17T05:59:12Z | https://github.com/flairNLP/flair/issues/3163 | [
"question",
"wontfix"
] | rafgonlop1 | 2 |
numba/numba | numpy | 9,512 | Add support for more random functions. | Why is there no support for functions like `random.choice()` or `random.sample()`? In my usecase most of the time they are faster than `numpy.random.choice` for `size=1`. | open | 2024-03-26T14:31:02Z | 2024-03-28T14:53:31Z | https://github.com/numba/numba/issues/9512 | [
"feature_request"
] | alex180500 | 1 |
sqlalchemy/sqlalchemy | sqlalchemy | 10,030 | support Enum objects that have no elements...somehow....this is technically a regression even though ive never seen an enum like this | ### Describe the bug
It looks like Enums that map to Callable objects and overwrite `__call__` will not map automatically with their proper name anymore.
I suppose it's possible that this a different error that was previously shadowed by the faulty behavior. But in the production database the enum type exists with ... | closed | 2023-06-28T13:28:29Z | 2023-06-28T20:22:26Z | https://github.com/sqlalchemy/sqlalchemy/issues/10030 | [
"bug",
"awaiting info",
"regression",
"near-term release",
"orm - annotated declarative"
] | Daverball | 9 |
polakowo/vectorbt | data-visualization | 526 | Cannot seem to make my strategy go either 1 asset long or 1 asset short | I am trying to set up my strategy in such a way that (based on my indicator) it either goes long 1 asset or short 1 asset (i.e., it reverses its position) based on my indicator, since I am trading futures. Therefore, I do not want to sell short (i.e. add cash), but fully reverse my position.
I have already tried to... | closed | 2022-11-14T16:43:08Z | 2024-03-16T10:39:31Z | https://github.com/polakowo/vectorbt/issues/526 | [] | StanMorseld | 1 |
paperless-ngx/paperless-ngx | django | 8,251 | [BUG] OCR fails on lage resolution PDFs | ### Description
In the past I scanned a lot of documents via Switfscan (you can take pictures and it will create a PDF and also do OCR on top).
Now I want to switch to Paperless-NGX but all my old self scanned documents fail. I guess because these files are big (~500kb/file) and saved with high resolution images.
... | closed | 2024-11-10T20:28:47Z | 2024-12-11T03:17:17Z | https://github.com/paperless-ngx/paperless-ngx/issues/8251 | [
"not a bug"
] | Schluggi | 2 |
JaidedAI/EasyOCR | machine-learning | 349 | Chinese dataset | Would you like to provide the dataset for Chinese training?
My e-mail is : huangwenlu@bupt.edu.cn.
Thank you very much. | closed | 2021-01-12T11:10:04Z | 2022-03-02T09:24:28Z | https://github.com/JaidedAI/EasyOCR/issues/349 | [] | hwlll | 0 |
reloadware/reloadium | flask | 207 | asyncio ? | asyncio not supported | open | 2024-12-08T14:41:20Z | 2024-12-08T14:41:20Z | https://github.com/reloadware/reloadium/issues/207 | [] | MaxmaxmaximusFree | 0 |
dmlc/gluon-nlp | numpy | 792 | SplitSampler to have configurable sampling ability | ## Description
I'm currently trying to integrate Horovod with Gluon. I came across SplitSampler that virtually partitions the data and randomly samples from a particular partition. I would like to use this partitioning mechanism with other samplers such as bucket sampler, etc. Would it be possible to configure the cho... | closed | 2019-06-24T17:50:56Z | 2019-10-13T04:35:54Z | https://github.com/dmlc/gluon-nlp/issues/792 | [
"enhancement"
] | chandana1332 | 6 |
tfranzel/drf-spectacular | rest-api | 989 | GIS source lookup with hops and geo_field not working | **Describe the bug**
`GeometryField` in `restframework_gis.serializers.GeoFeatureModelSerializer` with source lookup fails with KeyError in `drf_spectacular/contrib/rest_framework_gis.py", line 125, in map_geo_field`.
Same issue as https://github.com/tfranzel/drf-spectacular/issues/813 , but serializer `GeoFeatureMod... | open | 2023-05-23T14:58:06Z | 2025-01-22T17:48:40Z | https://github.com/tfranzel/drf-spectacular/issues/989 | [
"enhancement"
] | masb3 | 5 |
CorentinJ/Real-Time-Voice-Cloning | tensorflow | 470 | Issue - python: can't open file 'demo_toolbox.py': [Errno 2] No such file or directory | Hello, I'm new to programming and I know basically nothing. I have been trying to install the software by following the steps in the site. Everything went well until that part:

When I open the command prom... | closed | 2020-08-06T05:34:04Z | 2020-08-07T07:39:28Z | https://github.com/CorentinJ/Real-Time-Voice-Cloning/issues/470 | [] | ghost | 1 |
google-research/bert | tensorflow | 746 | Bert pre-training loss convergence | i am trying to pretrain BERT on my own dataset. Even though the code shows that saving and restoring from checkpoints is occuring, my loss value tends to stagnate at around 7. I am not seeing any convergence at all. What can I do? | open | 2019-07-03T15:21:04Z | 2020-11-22T14:43:26Z | https://github.com/google-research/bert/issues/746 | [] | abhi060698 | 6 |
arogozhnikov/einops | tensorflow | 321 | [Feature suggestion] Optionally return the inferred dimensions | # Description
Einops calculates automatically some of the inferred dimension. For example, in ViT, Einops is great for decomposing a tensor into stacked patches like this:
```python
x = torch.ones([1, 1, 256, 256])
patches = rearrange(x, 'b c (nx px) (ny py) -> b (c nx ny) px py', px=32, py=32)
```
This decomp... | open | 2024-05-14T07:34:47Z | 2024-09-14T18:03:49Z | https://github.com/arogozhnikov/einops/issues/321 | [
"feature suggestion"
] | ml-w | 3 |
tfranzel/drf-spectacular | rest-api | 721 | How do I specify a required request-body and not allow sending empty values for any of the fields in it? | I have the following code that ensures SwaggerUI shows a request-body with 3 fields. However, SwaggerUI allows me to make a request with all those fields left as blank. How can I make the full request-body required and whereby a value must be provided for all 3 fields?
I tried adding the key-value pair of `"required... | closed | 2022-04-28T13:49:40Z | 2022-04-29T16:28:05Z | https://github.com/tfranzel/drf-spectacular/issues/721 | [] | bluelight773 | 1 |
Teemu/pytest-sugar | pytest | 24 | pytest-sugar 0.3.0 on PyPI missing README.rst | ```
marca@marca-mac2.local ⮀ ~ ⮀ clean ⮀
❯ pip install pytest_sugar
Downloading/unpacking pytest-sugar
Using download cache from /Users/marca/.pip/download-cache/http%3A%2F%2Flocalhost%3A3141%2Froot%2Fpypi%2F%2Bf%2Fe1fe15005822e871d29a23effb159251%2Fpytest-sugar-0.3.0.tar.gz
Running setup.py egg_info for package p... | closed | 2014-02-05T22:58:04Z | 2014-02-06T16:45:54Z | https://github.com/Teemu/pytest-sugar/issues/24 | [] | msabramo | 0 |
ludwig-ai/ludwig | computer-vision | 3,884 | Ludwig: Fine-Tune Mistral-7b missing LudwigModel import and/or definition | **Describe the bug**
Ludwig: Fine-Tune Mistral-7b missing LudwigModel import and/or definition.
**To Reproduce**
Steps to reproduce the behavior:
1. Go to 'https://colab.research.google.com/drive/1i_8A1n__b7ljRWHzIsAdhO7u7r49vUm4#scrollTo=k-dtCIj73498'
1. Run Cells in cola
1. Scroll down to 'qlora_fine_tuning... | closed | 2024-01-16T18:18:11Z | 2024-01-16T21:02:17Z | https://github.com/ludwig-ai/ludwig/issues/3884 | [] | noahgift | 8 |
tqdm/tqdm | jupyter | 1,650 | `format_interval` displays wrong output for negative intervals | - [x] I have marked all applicable categories:
+ [ ] exception-raising bug
+ [x] visual output bug
- [x] I have visited the [source website], and in particular
read the [known issues]
- [x] I have searched through the [issue tracker] for duplicates
- [x] I have mentioned version numbers, operating system and
... | open | 2025-02-02T15:30:38Z | 2025-02-02T15:35:20Z | https://github.com/tqdm/tqdm/issues/1650 | [] | DavidBuchanan314 | 1 |
quantumlib/Cirq | api | 6,817 | Quantum Engine streaming is broken | See discussion about backend in b/343530665
| closed | 2024-12-06T00:07:32Z | 2025-01-08T21:01:58Z | https://github.com/quantumlib/Cirq/issues/6817 | [
"kind/bug-report",
"area/google/engine"
] | senecameeks | 0 |
ccxt/ccxt | api | 25,104 | duplicate sell order when place order for coinbase via createMarketSellOrder | ### Operating System
_No response_
### Programming Languages
_No response_
### CCXT Version
"ccxt": "^4.4.38"
### Description
the market sell order was created via
const order = await this.exchange.createMarketSellOrder(
unifiedSymbol,
formattedAmount
);
I am sure i... | closed | 2025-01-30T17:45:02Z | 2025-03-18T04:18:04Z | https://github.com/ccxt/ccxt/issues/25104 | [
"question"
] | adamchenwei | 2 |
collerek/ormar | fastapi | 1,004 | `__hash__` TypeError in v0.12.1 | **Describe the bug**
After upgrading from v0.12.0 to v0.12.1 my test suite fails with a lot of these errors:
```python
self = Service({'id': None, 'created_at': None, 'updated_at': None, 'more sensitive fields')
name = 'sensitive', value = UUID('53cadcf0-cdce-4101-8218-22c96d3edd39')
def __setattr__(self... | closed | 2023-02-01T21:28:42Z | 2023-02-03T16:10:24Z | https://github.com/collerek/ormar/issues/1004 | [
"bug"
] | sondrelg | 6 |
huggingface/datasets | deep-learning | 6,645 | Support fsspec 2024.2 | Support fsspec 2024.2.
First, we should address:
- #6644 | closed | 2024-02-07T12:45:29Z | 2024-02-29T15:12:19Z | https://github.com/huggingface/datasets/issues/6645 | [
"enhancement"
] | albertvillanova | 1 |
bonzanini/Book-SocialMediaMiningPython | data-visualization | 13 | micro_geo2kml.py errors when run | Hi,
while executing the python file micro_geo2kml.py I found many errors
first for loop in the line 39, can't accept the argument.
in the line 40 for the same reson

| closed | 2019-01-09T22:22:53Z | 2019-01-10T15:11:41Z | https://github.com/bonzanini/Book-SocialMediaMiningPython/issues/13 | [] | petersamoaa | 1 |
open-mmlab/mmdetection | pytorch | 11,951 | Multi-gpu training get stacked at | val_dataloader = dict(
batch_size=1,
dataset=dict(
ann_file='val/annotations_val.json',
backend_args=None,
data_prefix=dict(img='val/images/'),
data_root='/Dados/kailash_data/long_range/split_data/',
metainfo=dict(classes=('person', ), palette=[
(
... | open | 2024-09-08T08:30:52Z | 2024-09-26T13:54:08Z | https://github.com/open-mmlab/mmdetection/issues/11951 | [] | kailash-delvify | 1 |
python-restx/flask-restx | api | 21 | Improvement: Optional compression for responses | This is a nice value add; potentially could be done with a decorator so it could be configured per resource response method, or alternatively, as a blanket option. | closed | 2020-01-27T09:17:19Z | 2020-02-11T02:02:24Z | https://github.com/python-restx/flask-restx/issues/21 | [] | callamd | 2 |
lepture/authlib | django | 79 | Flask OAuth2 Authorization server lazy initialization broken in 0.8 | Flask OAuth2 authorization server is broken in 0.8 when using lazy init.
`authenticate_client`/`ClientAuthorization` is only instanciated once [here](https://github.com/lepture/authlib/blob/v0.8/authlib/specs/rfc6749/authorization_server.py#L20) but with lazy `init_app`, `query_client` is not yet provided and so equ... | closed | 2018-08-02T18:09:15Z | 2018-08-12T04:50:10Z | https://github.com/lepture/authlib/issues/79 | [] | noirbizarre | 2 |
databricks/spark-sklearn | scikit-learn | 107 | Need for an example | More than an issue, I need an example regarding this statement in the main `README`:
> convert Spark's Dataframes seamlessly into numpy ndarray or sparse matrices
How can I do this with `spark-sklearn`? Can you provide an example?
Many thanks in advance. | closed | 2019-02-16T06:45:28Z | 2019-02-16T15:36:30Z | https://github.com/databricks/spark-sklearn/issues/107 | [] | frbattid | 1 |
FlareSolverr/FlareSolverr | api | 300 | Outbound Proxy Support | Looked in the issues here and reddit and did not see anything similar.
Does flaresolverr support outbound proxy support? Any docker ENV to send all outbound traffic through a web proxy?
Thanks! | closed | 2022-02-07T13:36:17Z | 2022-04-16T19:16:20Z | https://github.com/FlareSolverr/FlareSolverr/issues/300 | [] | dadcoachengineer | 2 |
jupyter/nbviewer | jupyter | 945 | 404 : Not Found Remote HTTP 404: not found among 68 files | Hello, im trying to render my notebooks from https://github.com/Tvix22/thepythonlab/tree/master/Lab11%20BuyAndHold
and this is the url i try.
https://nbviewer.jupyter.org/github/Tvix22/thepythonlab/tree/master/Lab11%20BuyAndHold/
and when i try to run one notebook, recive a 404 error, but the notebook are ok in my ... | open | 2020-07-18T16:46:32Z | 2020-08-08T17:09:34Z | https://github.com/jupyter/nbviewer/issues/945 | [] | Tvix22 | 3 |
junyanz/pytorch-CycleGAN-and-pix2pix | computer-vision | 867 | Hi, I tried to convert into coreml. | I've converted into onnx, then mlmodel.
But the result's input/ output was MLMultiarray.
How can I change Just input/output as image using my original pretrained model? | open | 2019-12-05T12:00:40Z | 2020-09-29T23:50:51Z | https://github.com/junyanz/pytorch-CycleGAN-and-pix2pix/issues/867 | [] | HeoJinLareine | 1 |
aimhubio/aim | tensorflow | 3,043 | No module named 'aim._sdk.run_status_watcher' | ## 🐛 Bug
I am trying to instantiate the watcher but getting this error
```
pip install -U aim
pip install -U websockets
aim-watcher --repo . start
Traceback (most recent call last):
File "/home/ash022/mambaforge/envs/catboost/bin/aim-watcher", line 5, in <module>
from aimcore.cli.watcher_cli import c... | open | 2023-10-11T11:51:01Z | 2023-10-11T11:51:01Z | https://github.com/aimhubio/aim/issues/3043 | [
"type / bug",
"help wanted"
] | animesh | 0 |
FujiwaraChoki/MoneyPrinterV2 | automation | 8 | Improper Text wrapping in Shorts | The Shorts have improper text wrapping:

| closed | 2024-02-18T15:44:46Z | 2024-02-18T16:46:52Z | https://github.com/FujiwaraChoki/MoneyPrinterV2/issues/8 | [] | supperfreddo | 1 |
iperov/DeepFaceLab | deep-learning | 589 | DFL 2.0 Latest Release Multi-GPU 1/28/2019 | Hello - Multi gpu is not working correctly, **it is working but it's not up to our satisfaction**, We understand this is a new release and their will be issues. I am just letting you know what we are seeing while testing the latest release.
My PC specs:
AMD RYZEN 3900x 12 core
64gb 3400mhz Patriot ram
1 tb WD ... | closed | 2020-01-28T19:49:09Z | 2020-01-30T20:51:10Z | https://github.com/iperov/DeepFaceLab/issues/589 | [] | ajgoyt | 1 |
jmcnamara/XlsxWriter | pandas | 467 | Feature Request: Support custom table styles | Currently, the user can only specify a built-in style name when creating a worksheet table via the `style` option when calling `add_table()` and xlsxwriter always writes an empty tag to the `tableStyles` element. The `Workbook` class will need a new method for `add_table_style()` and the `Styles` class `_write_table_st... | closed | 2017-09-18T17:38:33Z | 2019-11-10T13:45:27Z | https://github.com/jmcnamara/XlsxWriter/issues/467 | [
"feature request",
"medium term"
] | gblacksf | 6 |
ufoym/deepo | jupyter | 109 | Please consider supportting JupyterLab | Thank you, your image is awesome and super useful, and the jupyterlab is very useful too! | closed | 2019-05-13T02:18:53Z | 2019-05-13T21:11:57Z | https://github.com/ufoym/deepo/issues/109 | [] | Bingmang | 2 |
huggingface/datasets | tensorflow | 6,702 | Push samples to dataset on hub without having the dataset locally | ### Feature request
Say I have the following code:
```
from datasets import Dataset
import pandas as pd
new_data = {
"column_1": ["value1", "value2"],
"column_2": ["value3", "value4"],
}
df_new = pd.DataFrame(new_data)
dataset_new = Dataset.from_pandas(df_new)
# add these samples to a remote datase... | closed | 2024-02-29T19:17:12Z | 2024-03-08T21:08:38Z | https://github.com/huggingface/datasets/issues/6702 | [
"enhancement"
] | jbdel | 2 |
koxudaxi/datamodel-code-generator | fastapi | 1,820 | Consider replacing `datamodel-code-generator/datamodel_code_generator/reference.py` with the referencing library | Context: I've spent the last week writing a code generation script that converts JSON schemas into Python dataclasses and C++ classes; and today I stumbled into your wonderful project!
My schemas are all file-based, an in my parser I uses the [python-jsonschema/referencing](https://github.com/python-jsonschema/refer... | open | 2024-01-25T18:04:29Z | 2024-01-30T17:57:24Z | https://github.com/koxudaxi/datamodel-code-generator/issues/1820 | [] | leonardopsantos | 2 |
mars-project/mars | numpy | 2,565 | Use sample method to estimate DataFrame memory cost | If there is object fields in a DataFrame, calculating exact memory cost can be expensive. Hence sampling methods can be used to get rough estimation about the size. | closed | 2021-10-28T16:01:43Z | 2021-11-12T07:00:22Z | https://github.com/mars-project/mars/issues/2565 | [
"type: enhancement",
"mod: dataframe"
] | wjsi | 0 |
vitalik/django-ninja | rest-api | 457 | LimitOffsetPagination pagination does not work with statuses | Hello, I have strange issue
When I use @paginate(LimitOffsetPagination) I can't return status code because it breaks schemas


# Background
Here our aim is to make mercury accessible within LAN. Currently it can only be accessed on the same computer it is hosted on at Localhost (127.0.0.1:8000). To achieve this please follow along. ... | open | 2022-02-10T23:43:13Z | 2024-05-20T14:09:23Z | https://github.com/mljar/mercury/issues/40 | [] | shivendra2015iiit | 9 |
widgetti/solara | jupyter | 151 | Mermaid improvements | Currently, mermaid is not bundled in solara-assets, which gives 404 errors on airgapped or firewalled environments.
Also, we should try to match what nbconvert is doing so experiences with nbconvert, voila and solara are similar: https://github.com/jupyter/nbconvert/pull/1957 | open | 2023-06-13T10:16:48Z | 2023-06-13T10:16:58Z | https://github.com/widgetti/solara/issues/151 | [
"enhancement",
"good first issue"
] | maartenbreddels | 0 |
wkentaro/labelme | deep-learning | 1,241 | Labelme opens tiff format file with error | ### Provide environment information
Python 3.7.13
labelme 5.1.1
labelme2coco 0.2.1
### What OS are you using?
macOS 13.2.1
### Describe the Bug
When opening tiff format images with Labelme, the software flashes back with the following error message:
OSError: cannot write mode I;16B as PNG
... | open | 2023-03-01T13:35:35Z | 2023-03-01T13:35:35Z | https://github.com/wkentaro/labelme/issues/1241 | [
"issue::bug"
] | zhunv | 0 |
scikit-hep/awkward | numpy | 3,321 | ak.where unexpectedly fails on typetracers of option types | ### Version of Awkward Array
2.7.1
### Description and code to reproduce
The following code:
```python3
import json
import awkward as ak
fromdict = {'class': 'RecordArray', 'fields': ['muon', 'jet'], 'contents': [{'class': 'ListOffsetArray', 'offsets': 'i64', 'content': {'class': 'RecordArray', 'fields': ['p... | closed | 2024-12-02T17:57:27Z | 2024-12-02T19:02:09Z | https://github.com/scikit-hep/awkward/issues/3321 | [
"bug (unverified)"
] | lgray | 1 |
dagster-io/dagster | data-science | 27,855 | why dagster automatically convert job config of timestamp string into datetime | ### What's the issue?
why dagster automatically convert job config of timestamp string into datetime?
I config a job with string of datetime, because dagster does not support datetime as config field.
but either start the job from UI or from graph api, the job runs with error:
Error 1: Invalid scalar at path root:end... | open | 2025-02-14T04:57:14Z | 2025-02-14T05:01:09Z | https://github.com/dagster-io/dagster/issues/27855 | [
"type: bug"
] | mathews | 1 |
OthersideAI/self-operating-computer | automation | 222 | [FEATURE] Can I change the base_url of model api? | Can I change the base_url of model api? | open | 2025-01-02T11:49:48Z | 2025-01-02T11:49:48Z | https://github.com/OthersideAI/self-operating-computer/issues/222 | [
"enhancement"
] | ikebo | 0 |
errbotio/errbot | automation | 784 | Slack Messaging to Channels | I was trying to send messages to channels in Slack, but I couldn't get it to work, so I took a look at the backend code in text.py, and I found a bug.
```
def build_identifier(self, text_representation):
if text_representation.startswith('#'):
return self.query_room(test_representation[1:])
... | closed | 2016-06-09T14:12:53Z | 2016-06-09T18:37:17Z | https://github.com/errbotio/errbot/issues/784 | [] | jlu368 | 3 |
ageitgey/face_recognition | machine-learning | 1,403 | Encoding is not prepared for certain images | * face_recognition version: 1.3.0
* Python version: 3.7
* Operating System: ubuntu
### Description
I am using this piece of code for generating encoding of the images for training the model.
image = PIL.Image.open(services.utils.get_image_from_url(image_url))
image = ImageOps.exif_transpose(... | open | 2022-01-11T12:15:26Z | 2022-01-24T13:22:29Z | https://github.com/ageitgey/face_recognition/issues/1403 | [] | nidhiSingh89 | 2 |
Anjok07/ultimatevocalremovergui | pytorch | 936 | 不明白是啥原因?帮忙看看,谢谢 | Last Error Received:
Process: VR 架构
如果此错误仍然存在,请与开发人员联系并提供错误详细信息。
Raw Error Details:
MemoryError: "Unable to allocate 6.93 GiB for an array with shape (3781, 2, 769, 320) and data type float32"
Traceback Error: "
File "UVR.py", line 4716, in process_start
File "separate.py", line 675, in seperate
F... | open | 2023-10-30T22:44:19Z | 2023-11-05T23:45:27Z | https://github.com/Anjok07/ultimatevocalremovergui/issues/936 | [] | jwdg001 | 2 |
waditu/tushare | pandas | 1,023 | About Proxy | 请问是否可以添加代理参数设置?当前,我自己设置urllib.request.ProxyHandler,但不能作用于TuShare,谢谢。 | closed | 2019-04-28T05:22:42Z | 2019-05-05T14:50:18Z | https://github.com/waditu/tushare/issues/1023 | [] | ericwu021 | 1 |
Gerapy/Gerapy | django | 73 | 如果调度出现繁忙,调度任务可能会被忽略 | 以下是后台日志:

以下我找到的参考解决方案:
https://stackoverflow.com/questions/30235604/next-run-time-missed-by-some-seconds-in-job-scheduling-in-apscheuler
| open | 2018-07-23T09:42:26Z | 2018-07-24T06:25:29Z | https://github.com/Gerapy/Gerapy/issues/73 | [] | kevinwu199 | 3 |
pytest-dev/pytest-django | pytest | 507 | Database errors BEFORE running tests | When running pytest, I get "no DB access error" caused by modules evaluated during import.
The suggestion is to mark tests with pytest.mark.django_db or use db fixture
But I cant do this, as error occurs BEFORE any test is actually run!
I also get DB errors in other modules that are imported at this time, but th... | closed | 2017-08-24T14:55:39Z | 2020-10-16T20:05:25Z | https://github.com/pytest-dev/pytest-django/issues/507 | [] | KayaLukenIncapptic | 1 |
3b1b/manim | python | 2,296 | I don't understand why I can't do gradient fill on a square in manimgl-1.7.1 version | ### Describe the error
I want to implement gradient filling inside the square in manimgl, but using set_color_by_gradient cannot achieve the effect I want.
### Code
```
from manimlib import*
sin=np.sin
cos=np.cos
My_color=[BLUE_E,WHITE]
class MainScene(Scene):
def construct(self) -> None:
tex=Te... | open | 2025-01-07T15:03:40Z | 2025-02-04T06:59:18Z | https://github.com/3b1b/manim/issues/2296 | [] | gd247217 | 1 |
public-apis/public-apis | api | 3,458 | Axolotl not working | Axolotl api is no longer working :

| closed | 2023-03-09T21:24:33Z | 2023-08-14T00:35:58Z | https://github.com/public-apis/public-apis/issues/3458 | [
"enhancement"
] | icepick4 | 2 |
autogluon/autogluon | computer-vision | 3,920 | Conda does not install `ray` by default | `mamba install -c conda-forge autogluon` does not install `ray` due to the fact that we are pinning its dependency `grpcio` to a lower version in conda https://github.com/conda-forge/autogluon.core-feedstock/blob/f08041aeeeff124bc3dd0742d91a0af691e468c5/recipe/meta.yaml#L44-L46
We should add that back once the [upstre... | closed | 2024-02-14T19:30:19Z | 2024-04-04T23:17:14Z | https://github.com/autogluon/autogluon/issues/3920 | [
"install",
"dependency"
] | suzhoum | 3 |
httpie/cli | api | 1,600 | add arm64 binary to the build workflow | ## Checklist
- [ x ] I've searched for similar feature requests.
---
## Enhancement request
i use termux on the go when i dont have access to my laptop, but unfortunately the arm64 binary doesn't included in GitHub build workflow I would appreciate anyone can add it to Linux build work flow
Note:
I already ... | open | 2024-09-10T15:45:29Z | 2024-09-10T15:45:29Z | https://github.com/httpie/cli/issues/1600 | [
"enhancement",
"new"
] | melsiir | 0 |
PaddlePaddle/PaddleHub | nlp | 1,822 | paddlehub使用hub convert 把inference 模型转换程paddleHub的预训练模型,那有官方的把paddleHub的预训练模型转换回infernce 模型的命令吗? | 使用命令hub convert可一键转换Inference Model转换成PaddleHub的预训练模型,那能反过来把PaddleHub的预训练模型转换成Inference Model么? | closed | 2022-03-30T06:14:38Z | 2022-03-31T02:22:26Z | https://github.com/PaddlePaddle/PaddleHub/issues/1822 | [] | smallhaozigithub | 1 |
keras-team/autokeras | tensorflow | 1,202 | ModuleNotFoundError: No module named 'kerastuner' -- Autokeras==1.0.3 | ### Bug Description
<!---
When I make import autokeras it is requested "kerastuner" but kerastuner do not have install require for this version-->
### Bug Reproduction
Code for reproducing the bug:
>>> import autokeras
Traceback (most recent call last):
File "<stdin>", line 1, in <module>
File "/home/l... | closed | 2020-06-23T21:32:03Z | 2023-07-25T09:05:22Z | https://github.com/keras-team/autokeras/issues/1202 | [
"algorithm"
] | leandroimail | 8 |
jumpserver/jumpserver | django | 14,952 | [Question] RemoteApp machine deployment problem | ### Product Version
4.6.0
### Product Edition
- [x] Community Edition
- [ ] Enterprise Edition
- [ ] Enterprise Trial Edition
### Installation Method
- [ ] Online Installation (One-click command installation)
- [x] Offline Package Installation
- [ ] All-in-One
- [ ] 1Panel
- [ ] Kubernetes
- [ ] Source Code
### E... | open | 2025-02-28T08:23:50Z | 2025-03-24T02:33:16Z | https://github.com/jumpserver/jumpserver/issues/14952 | [
"⏳ Pending feedback",
"🤔 Question"
] | obgranat | 19 |
jmcnamara/XlsxWriter | pandas | 159 | Second Y axis "data bar" can't match the X axis key well | Hi, John or any helper
i am the new comer for the xlsxwriter, which is fantastic for the chart drawing! but some question also come up
1. can i change the bar vertical size, i want to control the thick or thin
2. if i add another axis (set_y2_axis), the position of the 2nd axis bar can't point to the X axis key accura... | closed | 2014-09-30T14:54:49Z | 2014-10-09T13:14:03Z | https://github.com/jmcnamara/XlsxWriter/issues/159 | [
"question"
] | peter-zyj | 4 |
ivy-llc/ivy | numpy | 28,272 | Fix Frontend Failing Test: tensorflow - pointwise_ops.torch.real | To-do List: https://github.com/unifyai/ivy/issues/27499 | closed | 2024-02-13T04:51:09Z | 2024-03-11T12:22:02Z | https://github.com/ivy-llc/ivy/issues/28272 | [
"Sub Task"
] | Sai-Suraj-27 | 0 |
CPJKU/madmom | numpy | 480 | CRFChordRecognitionProcessor VS DeepChromaChordRecognitionProcessor | Hello guys,
I've been playing with `DeepChromaChordRecognitionProcessor` and `CRFChordRecognitionProcessor` and there is a major performance difference between them.
This code will run in 1.2 seconds (for a 4min song)
```
chord_processor = DeepChromaProcessor()
chord_decoder = DeepChromaChordRecognitionProcess... | closed | 2021-08-30T14:09:19Z | 2021-09-07T22:01:59Z | https://github.com/CPJKU/madmom/issues/480 | [] | geraldoramos | 1 |
Textualize/rich | python | 3,423 | [BUG] text justify "fully" egde-case with more than 1 space continuosly | - [x] I've checked [docs](https://rich.readthedocs.io/en/latest/introduction.html) and [closed issues](https://github.com/Textualize/rich/issues?q=is%3Aissue+is%3Aclosed) for possible solutions.
- [x] I can't find my issue in the [FAQ](https://github.com/Textualize/rich/blob/master/FAQ.md).
**Describe the bug**
... | closed | 2024-07-11T20:29:50Z | 2024-07-11T21:40:22Z | https://github.com/Textualize/rich/issues/3423 | [
"Needs triage"
] | oppZ | 2 |
ultralytics/ultralytics | python | 18,875 | The optimizer and loss functions used for fine-tuning YOLO11n-pose and YOLOv8n-pose | ### Search before asking
- [x] I have searched the Ultralytics YOLO [issues](https://github.com/ultralytics/ultralytics/issues) and [discussions](https://github.com/orgs/ultralytics/discussions) and found no similar questions.
### Question
Hello,
I am a university student from Japan conducting research on pose esti... | open | 2025-01-25T03:43:47Z | 2025-01-25T04:50:38Z | https://github.com/ultralytics/ultralytics/issues/18875 | [
"question",
"pose"
] | bgcomYSTO | 3 |
hack4impact/flask-base | flask | 17 | Allowed to log in even before confirming email | Steps to reproduce:
1. Make an account
2. Don't confirm email
3. Log in with account
Expected
4. See message that asks to reconfirm email and you are blocked from doing other user things
Actual
4. See message that asks to reconfirm email and you _can_ do other user things
| closed | 2015-10-24T17:15:33Z | 2016-04-18T04:35:15Z | https://github.com/hack4impact/flask-base/issues/17 | [
"bug",
"high priority"
] | sandlerben | 8 |
open-mmlab/mmdetection | pytorch | 11,247 | When training with rtmdet_ins_tiny, the bbox correlation accuracy is normal, but the segm correlation accuracy is all zero | ### log:
12/04 16:06:52 - mmengine - INFO - Evaluating bbox...
Loading and preparing results...
DONE (t=0.01s)
creating index...
index created!
Running per image evaluation...
Evaluate annotation type *bbox*
DONE (t=0.91s).
Accumulating evaluation results...
DONE (t=0.10s).
Average Precision (AP) @[ IoU=0.... | open | 2023-12-04T08:25:28Z | 2024-10-16T10:13:02Z | https://github.com/open-mmlab/mmdetection/issues/11247 | [] | 20171758 | 4 |
plotly/dash | dash | 2,454 | [BUG] No dialog box for dcc.Download component in Edge browser | # Software
```
dash 2.7.0
```
### Browser
* OS: Windows 10
* Browser: Edge
* Version: 110.0.1587.69 (Official Build) (64-bit)
# Issue
### Describe the bug
In the Microsoft Edge browser, after clicking the download button, it is directly saved to the default folder for downloads. The window... | closed | 2023-03-13T16:17:27Z | 2023-03-14T15:15:09Z | https://github.com/plotly/dash/issues/2454 | [] | Pomurnik | 2 |
vitalik/django-ninja | django | 590 | Cannot send more than one http request to the same endpoint |
I see that this issue was raised here [/issues/203](https://github.com/vitalik/django-ninja/issues/203) but I'm not sure why it was closed. I am having the issue still and I have tried the hacks suggested and nothing is working. I suspect it may be because the endpoint is SSL enforced but I'm not sure. I need both a ... | closed | 2022-10-15T06:59:01Z | 2023-11-24T13:08:02Z | https://github.com/vitalik/django-ninja/issues/590 | [] | charissalaw | 1 |
ageitgey/face_recognition | python | 1,412 | Can't run Face Recognition on Apple Silicon M1 | * face_recognition version: 1.3.0
* Python version: 3.8.10
* Operating System: macOS 12.1
### Description
Can't run Face Recognition on Apple Silicon based Mac
### What I Did
After installing face recognition using pip3 and running `face_recognition` I get the following error message
```
Traceback (mo... | open | 2022-02-18T23:40:24Z | 2023-02-09T07:02:31Z | https://github.com/ageitgey/face_recognition/issues/1412 | [] | MemoryAccessRegister | 9 |
pytorch/pytorch | deep-learning | 149,290 | as_subclass doesn't work under TorchDispatchMode | ### 🐛 Describe the bug
We have a torch.Tensor subclass which shares autograd history with a passed in `data` torch.Tensor using the `as_subclass` method. This works well except in the case where we use `TorchDispatchMode`:
```
import torch
from torch.utils._python_dispatch import TorchDispatchMode
class Foo(TorchDi... | open | 2025-03-17T03:39:42Z | 2025-03-17T15:33:27Z | https://github.com/pytorch/pytorch/issues/149290 | [
"triaged",
"module: __torch_dispatch__"
] | pritamdamania87 | 0 |
aiogram/aiogram | asyncio | 1,378 | updated telgram url chanel fragment | ### Checklist
- [X] I am sure the error is coming from aiogram code
- [X] I have searched in the issue tracker for similar bug reports, including closed ones
### Operating system
how to change fragment telegram channel username with python ?
### Python version
how to change fragment telegram channel username with ... | closed | 2023-11-27T12:56:43Z | 2023-11-28T00:22:21Z | https://github.com/aiogram/aiogram/issues/1378 | [
"upstream"
] | pyaidev | 3 |
deepspeedai/DeepSpeed | pytorch | 7,137 | [REQUEST]Does DeepSpeed support multi-node inference? | I am wondering if DeepSpeed supports multi-node inference. If so, could you please point me to the relevant documentation or examples? I have checked the official documentation and only found these two related to multi-node but these seems to be multi-node training instead of inference.
1. [https://www.deepspeed.ai/ge... | open | 2025-03-14T08:24:47Z | 2025-03-14T20:11:37Z | https://github.com/deepspeedai/DeepSpeed/issues/7137 | [
"enhancement"
] | zyyyyy5 | 1 |
pydata/pandas-datareader | pandas | 82 | utils should be _utils | There are not public functions in `utils` so the entire module should probably be marked as private.
| closed | 2015-08-27T02:56:03Z | 2015-09-26T18:23:06Z | https://github.com/pydata/pandas-datareader/issues/82 | [] | bashtage | 1 |
huggingface/pytorch-image-models | pytorch | 1,831 | [BUG] ModelEma doesn't update. |
I am creating my our custom code for Deep learning model where a built my network from scratch using existing state-of-the-art tools. Every thing works just fine except that ModelEma doesn't update during training/validation of the network.
After successfully call the model I used:
` model_ema = ModelEma(
... | closed | 2023-05-29T11:04:37Z | 2023-05-29T16:56:54Z | https://github.com/huggingface/pytorch-image-models/issues/1831 | [
"bug"
] | opencomvis | 1 |
piccolo-orm/piccolo | fastapi | 669 | Is there a way to order with aggregated column? | Hi,
I want to order with aggregated column e.g 'revenue_agg', is there a way to do it?
Facility.select(
Facility.code, Facility.name, Sum(Facility.revenue).as_alias("revenue_agg")).where(
Facility.practice.name == practice_name.title().strip(),
Facility.year == year,
... | closed | 2022-11-09T17:22:32Z | 2022-11-22T21:09:36Z | https://github.com/piccolo-orm/piccolo/issues/669 | [] | devsarvesh92 | 3 |
LibreTranslate/LibreTranslate | api | 704 | Enhancement: Include remaining requests and end of period in headers | It is very common for rate limited APIs to include information about the remaining limits, so that requests can be prevented properly. Currently you need to guess if you are within the limit, leading to additional api-calls that fail with 429 or worse 403.
I would suggest adding the following common headers to the r... | open | 2024-10-24T06:46:17Z | 2024-10-24T06:46:29Z | https://github.com/LibreTranslate/LibreTranslate/issues/704 | [
"enhancement"
] | Idrinth | 0 |
jmcnamara/XlsxWriter | pandas | 760 | Feature request: Dataclass integration | To start with a disclaimer, this is my first ever time trying out your library so my feature request may sound a little bit odd. Or it may have been already implemented in a way that I missed on the documentation. Let me know if that is the case. (Also I barely know what excel files are). But I think the integration of... | closed | 2020-11-14T11:50:10Z | 2020-11-19T07:54:16Z | https://github.com/jmcnamara/XlsxWriter/issues/760 | [
"wont_fix",
"feature request"
] | isik-kaplan | 1 |
Subsets and Splits
No community queries yet
The top public SQL queries from the community will appear here once available.