
repo_name stringlengths 9 75 | topic stringclasses 30
values | issue_number int64 1 203k | title stringlengths 1 976 | body stringlengths 0 254k | state stringclasses 2
values | created_at stringlengths 20 20 | updated_at stringlengths 20 20 | url stringlengths 38 105 | labels listlengths 0 9 | user_login stringlengths 1 39 | comments_count int64 0 452 |
|---|---|---|---|---|---|---|---|---|---|---|---|
InstaPy/InstaPy | automation | 6,811 | Followers | @froz_n_heart | open | 2024-06-03T07:09:10Z | 2024-06-03T07:09:10Z | https://github.com/InstaPy/InstaPy/issues/6811 | [] | Frozenheart3780 | 0 |
yzhao062/pyod | data-science | 463 | ValueError: Input contains NaN, infinity or a value too large for dtype('float64'). | when i use LSCP for od: all features used is well run.
but when i choose some features in all (for example 2 features chosen),
it will report error: ValueError: Input contains NaN, infinity or a value too large for dtype('float64'). | closed | 2022-12-13T12:28:14Z | 2022-12-15T08:03:47Z | https://github.com/yzhao062/pyod/issues/463 | [] | Jason-kid | 2 |
benbusby/whoogle-search | flask | 909 | whoogle.env problem | Whoogle.env not working on every setting. I use replit.
- My whoogle.env
`HOOGLE_CONFIG_NEAR=Edirne
#WHOOGLE_CONFIG_COUNTRY=TR
WHOOGLE_CONFIG_LANGUAGE=lang_tr
WHOOGLE_CONFIG_SEARCH_LANGUAGE=lang_en
WHOOGLE_CONFIG_DISABLE=1
WHOOGLE_CONFIG_URL=https://www.indexia.gq
WHOOGLE_CONFIG_STYLE=":root :ro... | closed | 2022-12-15T19:41:08Z | 2023-01-05T00:45:09Z | https://github.com/benbusby/whoogle-search/issues/909 | [] | hxvy0 | 4 |
Esri/arcgis-python-api | jupyter | 1,841 | create_view method does not work on hosted feature layers if layer ids are not in sequential order. | **Describe the bug**
create_view method does not work on hosted feature layers whose layer ids are **not** in sequential order. (ie unique layer ids has been enabled and layers were moved, EVEN IF YOU REALIZE YOU DID THIS AND TURN OFF ASSIGN UNIQUE IDS (pardon all caps)).
**To Reproduce**
Steps to reproduce the beha... | closed | 2024-06-09T21:28:51Z | 2024-06-20T12:23:48Z | https://github.com/Esri/arcgis-python-api/issues/1841 | [
"bug"
] | ramcgreg | 3 |
aio-libs/aiomysql | asyncio | 385 | Syntactic sugar for aiomysql | I successfully use your library in several projects.
I propose a solution to simplify the work with the library.
```python
import asyncio
from CshLib.conn import MySQL
class MySQLModules(MySQL):
user = 'stat'
password = 'bh0020'
db = 'modules'
async def test():
async with MySQLModule... | open | 2019-02-12T17:43:31Z | 2022-01-13T02:44:43Z | https://github.com/aio-libs/aiomysql/issues/385 | [
"enhancement"
] | atitoff | 1 |
praw-dev/praw | api | 2,000 | Title-only submissions | ### Describe the Bug
In [this](https://github.com/praw-dev/praw/blob/master/praw/models/reddit/subreddit.py#L3443C1-L3445C33) section of `/praw/models/reddit/subreddit.py`, the following code appears:
```Python
if (bool(selftext) or selftext == "") == bool(url):
msg = "Either 'selftext' or 'url' must be p... | closed | 2023-12-04T19:59:23Z | 2023-12-04T22:29:39Z | https://github.com/praw-dev/praw/issues/2000 | [] | ghost | 2 |
ultralytics/yolov5 | deep-learning | 13,437 | Setting Custom Anchors in YOLOv5 for Mismatched Bounding Box Sizes | ### Search before asking
- [X] I have searched the YOLOv5 [issues](https://github.com/ultralytics/yolov5/issues) and [discussions](https://github.com/ultralytics/yolov5/discussions) and found no similar questions.
### Question
Hi,
I'm facing a challenge with my object detection model. My training data is quite l... | closed | 2024-11-28T02:10:29Z | 2024-12-03T07:05:24Z | https://github.com/ultralytics/yolov5/issues/13437 | [
"question",
"detect"
] | shinzokuro | 2 |
databricks/koalas | pandas | 1,663 | java.lang.IllegalArgumentException when using toPandas | Hi! I bootstrapped an EMR 5.30.1 cluster using koalas with conda. I'm getting in a dead-end here with the following error whenever trying to convert a koalas dataframe to a pandas dataframe after computing some operations. Here's the full traceback:
```
/usr/lib/spark/python/pyspark/sql/dataframe.py:2148: UserWarni... | closed | 2020-07-19T23:42:34Z | 2020-07-21T01:43:59Z | https://github.com/databricks/koalas/issues/1663 | [] | ghost | 4 |
benbusby/whoogle-search | flask | 810 | whoogle with gluetun | Where I have to put the network_mode: "container:gluetun" line in the docker-compose file to make it work with gluetun?
Do I have to edit something else apart from the docker-compose file?
```
# cant use mem_limit in a 3.x docker-compose file in non swarm mode
# see https://github.com/docker/compose/issues/4513
... | closed | 2022-07-07T09:37:19Z | 2022-07-13T16:10:11Z | https://github.com/benbusby/whoogle-search/issues/810 | [
"question"
] | yed01 | 2 |
kensho-technologies/graphql-compiler | graphql | 163 | Improve error message when a meta-field is queried but not built-in or present in the schema | open | 2019-01-22T21:35:18Z | 2019-01-22T22:39:11Z | https://github.com/kensho-technologies/graphql-compiler/issues/163 | [
"enhancement",
"user friendliness",
"good first issue"
] | jmeulemans | 2 | |
dmlc/gluon-nlp | numpy | 1,169 | more frequent releases | For GluonNLP 0.9, it was mainly blocked by mxnet 1.6 release. Many bug fixes and useful APIs are not shipped to users because of that. Now that MXNet 1.6 release is official, I suggest gluonnlp make more frequent releases such that fixes, features and improvements are shipped faster. Maybe once per month? | open | 2020-02-24T07:04:18Z | 2020-06-12T18:47:29Z | https://github.com/dmlc/gluon-nlp/issues/1169 | [
"discussion"
] | eric-haibin-lin | 1 |
geopandas/geopandas | pandas | 2,589 | BUG: Clipping with empty shape produces cryptic error | - [x] I have checked that this issue has not already been reported.
- [x] I have confirmed this bug exists on the latest version of geopandas.
---
**Note**: Please read [this guide](https://matthewrocklin.com/blog/work/2018/02/28/minimal-bug-reports) detailing how to provide the necessary information for us to... | closed | 2022-10-11T00:14:36Z | 2022-10-22T13:54:27Z | https://github.com/geopandas/geopandas/issues/2589 | [
"enhancement"
] | fbunt | 7 |
deepfakes/faceswap | machine-learning | 956 | Failed to convert image: ... Reason: '>=' not supported between instances of 'NoneType' and 'float' | **Describe the bug**
When doing a convert on a video clip I used to build the model, I'm getting errors on frames that have a face to swap:
12/17/2019 21:04:57 ERROR Failed to convert image: 'hk trim_000117.png'. Reason: '>=' not supported between instances of 'NoneType' and 'float'
12/17/2019 21:04:57 ERROR F... | closed | 2019-12-18T02:50:30Z | 2020-09-26T23:59:51Z | https://github.com/deepfakes/faceswap/issues/956 | [] | jpchow26 | 10 |
plotly/dash-core-components | dash | 45 | Feature request: Add a button component | Hi,
Could you please add a regular GUI button component to dash-core-components?
Is there any workaround that is available for the meanwhile?
Thanks for the great work in this project.
| closed | 2017-08-02T08:00:30Z | 2017-08-21T18:55:39Z | https://github.com/plotly/dash-core-components/issues/45 | [] | yuvval | 2 |
microsoft/JARVIS | pytorch | 144 | Web server fails to start: The symbol "video_urls" was declared a constant here: script | I am getting below errors when trying to start the web server. The only thing that comes to my mind is that JARVIS repo is on a separate NVME partition but it is mounted in my home directory
`(jarvis) tomasz@JARVISGPT:~/repos/JARVIS/web$ sudo npm run dev
> vue3-ts-vite-router-tailwindcss@0.0.0 dev
> vite
... | closed | 2023-04-13T23:14:34Z | 2023-04-14T14:13:16Z | https://github.com/microsoft/JARVIS/issues/144 | [] | newDevPL | 1 |
tqdm/tqdm | pandas | 743 | notebook with unknown total | Cannot use notebook with unknown `total` for v4.32.0
migrated from #742 | closed | 2019-05-13T22:01:09Z | 2019-05-13T22:43:59Z | https://github.com/tqdm/tqdm/issues/743 | [
"p0-bug-critical ☢",
"submodule-notebook 📓"
] | casperdcl | 3 |
Evil0ctal/Douyin_TikTok_Download_API | web-scraping | 537 | 设置robots.txt失败 | 我不想搜索引擎爬取收录该站点,于是尝试修改/app/app/main.py。在其中设置了get('robot.txt')的路由,访问将返回robots.txt。但是无论我将robots.txt放置在/app/还是/app/app/中,都无法正确得到结果。提示错误 404 not found。 | closed | 2025-01-15T12:02:54Z | 2025-01-16T09:54:44Z | https://github.com/Evil0ctal/Douyin_TikTok_Download_API/issues/537 | [
"enhancement"
] | hadwinfu | 2 |
nerfstudio-project/nerfstudio | computer-vision | 3,559 | poster super blurry on Mac M1 | Pro Mac M1 generated super blurry reconstruction of poster.
used this training command: ns-train nerfacto --data data/nerfstudio/poster --machine.device-type mps
nothing that looks like a chair.
Had to install torch 2.4.1 and most recent torchvision instead of 2.0.1 to get it to install.
![Image 1-2-25 at 7... | open | 2025-01-02T13:13:09Z | 2025-01-02T13:22:14Z | https://github.com/nerfstudio-project/nerfstudio/issues/3559 | [] | robogo-pj | 1 |
CorentinJ/Real-Time-Voice-Cloning | python | 654 | Stuck on Successfully opened dynamic library cudnn64_7.dll | I did all the installations and when I record myself and press on Synthetize only I get stuck on this line in the CLI:
`2021-02-10 00:45:37.068088: I tensorflow/stream_executor/platform/default/dso_loader.cc:44] Successfully opened dynamic library cudnn64_7.dll`
The GUI stop responding and it says:
`Loading the ... | closed | 2021-02-10T06:00:26Z | 2021-02-14T16:05:49Z | https://github.com/CorentinJ/Real-Time-Voice-Cloning/issues/654 | [] | jtpaquet | 3 |
wandb/wandb | tensorflow | 9,435 | [Bug-App]: The sweep search parameter in offline mode causes most of the results to repeat and loops these results. | ### Describe the bug
<!--- Describe your issue here --->
wandb The sweep search parameter in offline mode, after a period of time (about 1 hour) the later searches will repeat the results of the previous K runs and loop through the results of these K searches until the sweep_num=end search ends.
even I update the rec... | closed | 2025-02-07T03:08:09Z | 2025-02-13T22:04:28Z | https://github.com/wandb/wandb/issues/9435 | [
"ty:bug",
"a:app"
] | Tokenmw | 3 |
roboflow/supervision | tensorflow | 1,339 | draw wrong OrientedBoxAnnotator with InferenceSlicer | ### Search before asking
- [X] I have searched the Supervision [issues](https://github.com/roboflow/supervision/issues) and found no similar bug report.
### Bug
I'm using official yolov8m_obb.pt and if I write code like below
```python
def callback(image_slice: np.ndarray) -> sv.Detections:
result = model(... | closed | 2024-07-10T05:52:36Z | 2024-07-18T13:46:39Z | https://github.com/roboflow/supervision/issues/1339 | [
"bug"
] | DawnMagnet | 7 |
nteract/papermill | jupyter | 716 | Papermill execute_notebook() seems to break for nbclient < 0.7.0 | ## 🐛 Bug
Relevant package versions:
```bash
papermill=2.3.4
nbclient=0.6.0
python=3.9.0
```
When trying to batch execute notebooks with `pm.execute_notebook()`, in environments with `nbclient < 0.7.0` I get the following error:
```bash
Traceback (most recent call last):
File "/glade/u/home/eromashk... | closed | 2023-03-10T19:44:36Z | 2023-11-29T18:13:17Z | https://github.com/nteract/papermill/issues/716 | [
"bug",
"help wanted"
] | rmshkv | 1 |
koxudaxi/datamodel-code-generator | pydantic | 1,943 | When using snake-case-fields and msgspec, field ordering does not always work correctly | **Describe the bug**
A clear and concise description of what the bug is.
**To Reproduce**
Example schema: https://raw.githubusercontent.com/kubernetes/kubernetes/release-1.28/api/openapi-spec/v3/api__v1_openapi.json
Used commandline:
```
$ datamodel-codegen --url 'https://raw.githubusercontent.com/kubernete... | closed | 2024-05-01T20:28:51Z | 2024-06-02T16:22:04Z | https://github.com/koxudaxi/datamodel-code-generator/issues/1943 | [] | ianbuss | 0 |
statsmodels/statsmodels | data-science | 8,713 | Results of n-way MANOVA with interactions differ significantly from results from R's stats::manova | (I'm not sure if this is a bug or a feature request - sorry for false alarm if this was expected!)
I get different results when performing n-way MANOVA with interactions when using this implementation and R.
Let's use data from the file I attached as an example.
[metals.csv](https://github.com/statsmodels/stats... | open | 2023-03-03T13:52:28Z | 2023-04-05T15:40:27Z | https://github.com/statsmodels/statsmodels/issues/8713 | [
"type-bug",
"FAQ",
"comp-multivariate"
] | mikrzol | 13 |
mage-ai/mage-ai | data-science | 4,978 | A Block Runs page within the UI | **Is your feature request related to a problem? Please describe.**
It's difficult to monitor which pipelines and blocks are actively running when a high number of pipelines/blocks are running or queued.
**Describe the solution you'd like**
A page in the UI similar to `Pipeline Runs` but for Blocks. Please include ... | open | 2024-04-23T19:02:22Z | 2024-04-26T22:27:15Z | https://github.com/mage-ai/mage-ai/issues/4978 | [
"feature"
] | jdvermeire | 0 |
pandas-dev/pandas | pandas | 60,575 | DOC: fix docstring validation errors for pandas.core and pandas.errors | > follow up on issues #59698, #59458 and #58063 pandas has a script for validating docstrings:
>
> https://github.com/pandas-dev/pandas/blob/b0192c70610a9db593968374ea60d189daaaccc7/ci/code_checks.sh#L86-L100
>
> Currently, some methods fail docstring validation check. The task here is:
>
> * take 2-4 methods... | closed | 2024-12-15T13:58:58Z | 2024-12-15T14:07:24Z | https://github.com/pandas-dev/pandas/issues/60575 | [] | sunlight798 | 0 |
ultralytics/ultralytics | pytorch | 18,973 | Tensorrt cannot speed up inference time well | ### Search before asking
- [x] I have searched the Ultralytics YOLO [issues](https://github.com/ultralytics/ultralytics/issues) and [discussions](https://github.com/orgs/ultralytics/discussions) and found no similar questions.
### Question
I have tried to use tensorrt to speed up the inference speed, but it has no ... | open | 2025-02-03T03:20:32Z | 2025-02-10T09:03:23Z | https://github.com/ultralytics/ultralytics/issues/18973 | [
"question",
"detect",
"exports"
] | darouwan | 9 |
PrefectHQ/prefect | data-science | 17,317 | subprocess.CalledProcessError: Command '['git', 'clone', <repo>, '--depth', '1', '/home/pipelines']' returned non-zero exit status 128. | ### Bug summary
after upgrade to 3.2.8 prefect start getting error for cloning git in worker
subprocess.CalledProcessError: Command '['git', 'clone', 'https://git.mygit', '--depth', '1', '/home/pipelines']' returned non-zero exit status 128.
File "/home/prefect/.virtualenvs/prefect/lib/python3.12/site-packages/prefe... | closed | 2025-02-28T05:52:49Z | 2025-03-04T22:46:59Z | https://github.com/PrefectHQ/prefect/issues/17317 | [
"bug"
] | ramelito | 4 |
vimalloc/flask-jwt-extended | flask | 33 | (Question) CSRF Token | Why does not include CSRF Token in claims of JWT (cookie mode) instead of create another dedicated new cookie ?
On front end we can read the payload and forge the http request with CSRF header
Edit: forget my question, the cookie is httponly ... | closed | 2017-03-24T14:13:32Z | 2017-04-10T18:45:45Z | https://github.com/vimalloc/flask-jwt-extended/issues/33 | [] | johaven | 7 |
sergree/matchering | numpy | 2 | Exapmles of the algorithm | Hello, @sergree.
Do you have some examples of your algorithms available for evaluation? I wanna know if this tool is useful for our use in automated rehearsal A/V recording mastering. | closed | 2019-11-10T10:27:44Z | 2019-12-30T21:46:22Z | https://github.com/sergree/matchering/issues/2 | [
"question"
] | romansavrulin | 1 |
miguelgrinberg/Flask-SocketIO | flask | 1,561 | Get currently connected clients list | Sir is there any way to get currently connected users lists of sid? And get users list of sid from a room? | closed | 2021-05-28T13:35:48Z | 2021-06-27T19:35:02Z | https://github.com/miguelgrinberg/Flask-SocketIO/issues/1561 | [
"question"
] | The-Gk | 11 |
flasgger/flasgger | flask | 523 | Accessing flasgger_static endpoints behind a reverse proxy? | Let's assume I have a Flask app exposing an endpoint `/login` and I expose this app behind a reverse proxy (traefik) using the prefix `my_app` (the proxy has to strip the prefix, however when I use the "try it out" function in swagger ui, it send the request to `/my_app/login` and my app doesn't know this route).
Wi... | open | 2022-03-29T17:31:43Z | 2024-02-19T06:15:40Z | https://github.com/flasgger/flasgger/issues/523 | [] | mautini | 1 |
serengil/deepface | machine-learning | 1,256 | [iOS SDK]: <a short description of my proposal> | ### Description
Hi, Can you please create iOS SDK of your SDK so that I can use it on iOS too?
### Additional Info
_No response_ | closed | 2024-06-11T12:42:06Z | 2024-06-11T13:41:48Z | https://github.com/serengil/deepface/issues/1256 | [
"enhancement"
] | pkr5637 | 1 |
PokeAPI/pokeapi | api | 511 | error "500" on endpoint 'pokemon/10150' only | 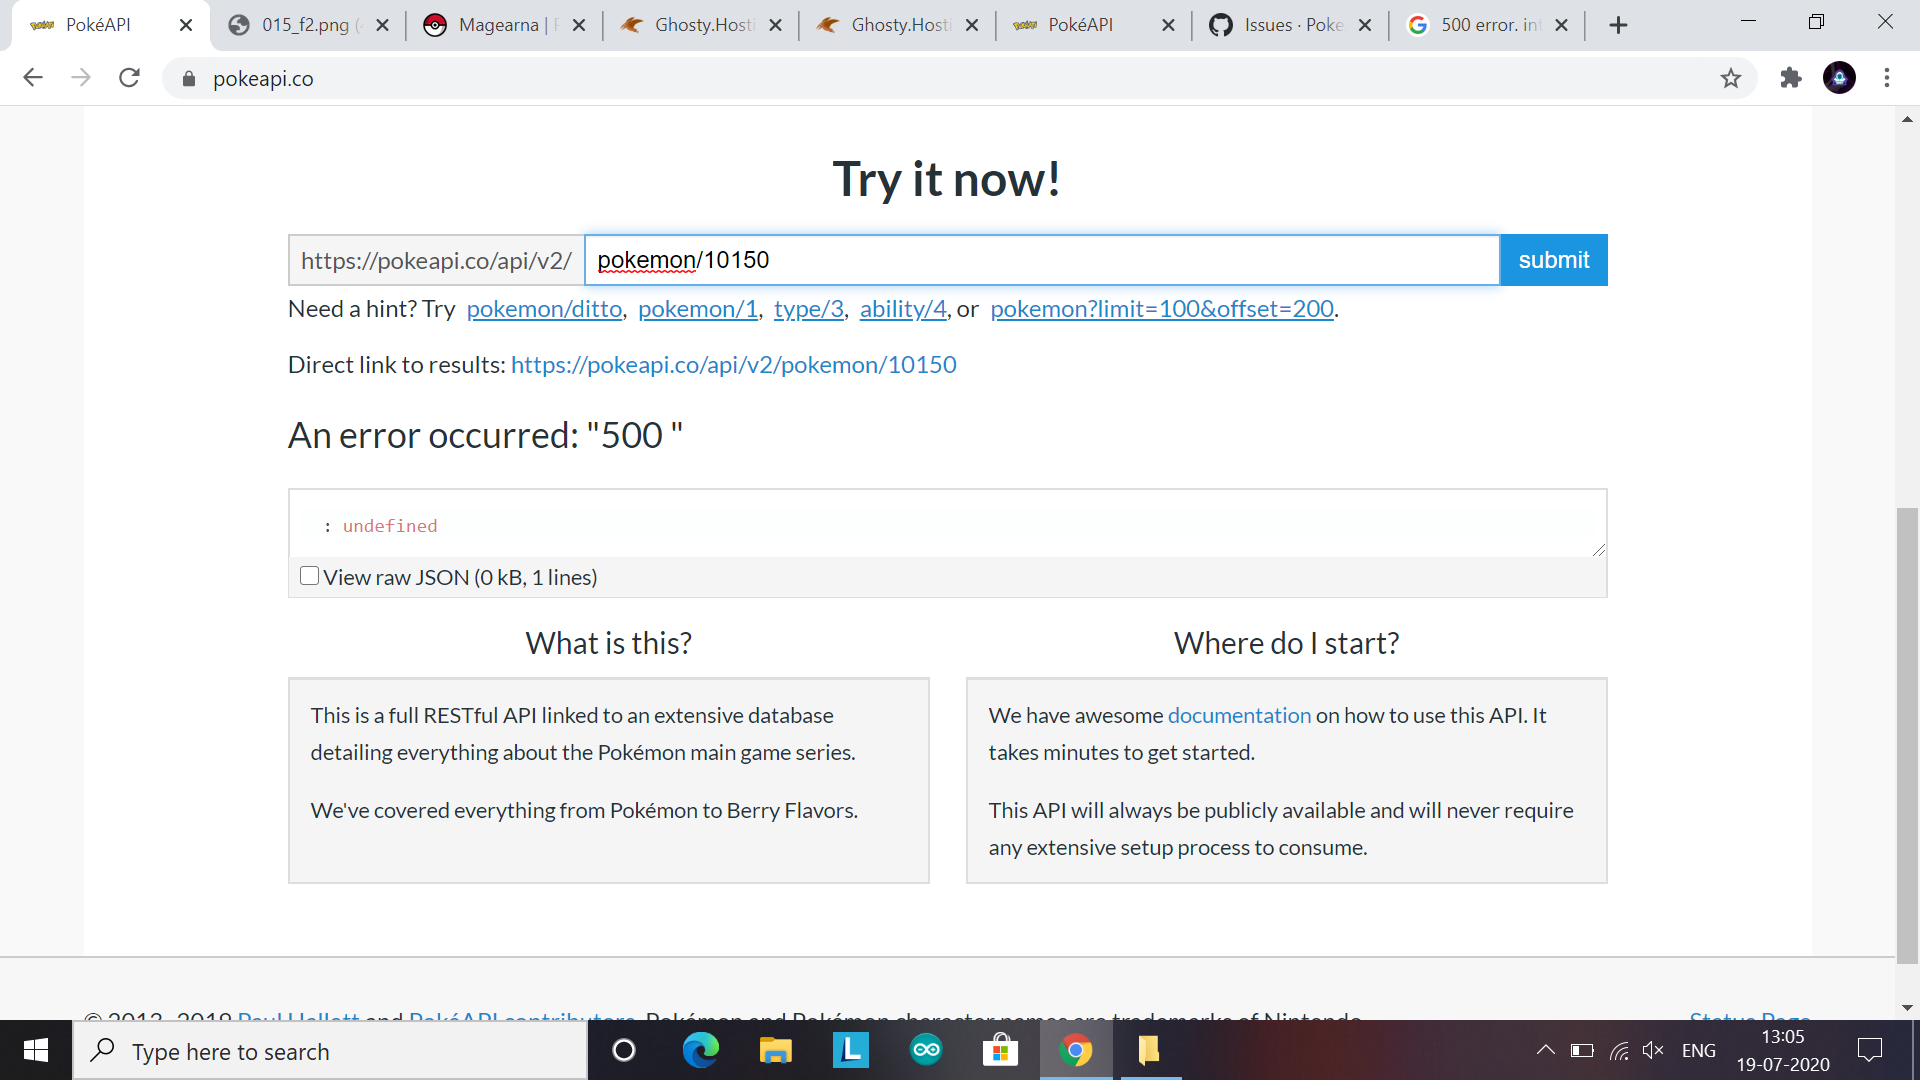
| closed | 2020-07-19T07:36:09Z | 2020-07-19T11:03:41Z | https://github.com/PokeAPI/pokeapi/issues/511 | [] | FirezTheGreat | 5 |
pandas-dev/pandas | data-science | 60,727 | DOC: Add comparison with SPSS | ### Pandas version checks
- [x] I have checked that the issue still exists on the latest versions of the docs on `main` [here](https://pandas.pydata.org/docs/dev/)
### Location of the documentation
https://pandas.pydata.org/docs/getting_started/comparison/index.html
### Documentation problem
I teach pandas, and h... | closed | 2025-01-17T18:18:52Z | 2025-01-22T18:41:46Z | https://github.com/pandas-dev/pandas/issues/60727 | [
"Docs",
"good first issue"
] | afeld | 1 |
OFA-Sys/Chinese-CLIP | nlp | 210 | 为什么转onnx时会生成extra_file部分,能不能不要这部分,将所有的信息都放到onnx模型中 | closed | 2023-09-19T08:54:14Z | 2024-11-30T10:54:04Z | https://github.com/OFA-Sys/Chinese-CLIP/issues/210 | [] | noseding | 1 | |
davidteather/TikTok-Api | api | 927 | [FEATURE_REQUEST] - Get TikTok ads | Hi, so I go straight to the point. I reveresed tiktok about a month ago, I can get any data I want, I can do any actions I want. BUT I can't crawl tiktok ads... I tried everything, I redo all the requests, generated a new `device_id`, etc. none of the worked. I don't what am I missing
So can you support tiktok ads in ... | closed | 2022-08-04T05:56:48Z | 2023-08-08T22:09:00Z | https://github.com/davidteather/TikTok-Api/issues/927 | [
"feature_request"
] | master0yoda | 1 |
pyg-team/pytorch_geometric | pytorch | 8,891 | Getting error passing torch_geometric.data.Data() object in SparseTensor format to torch_geometric.nn.conv.RGCNConv for training | ### 🐛 Describe the bug
I am trying to run `RGCNConv` on my `torch_geometric.data.Data()` object using `SparseTensor` method for `edge_index`. The [docs](https://pytorch-geometric.readthedocs.io/en/latest/generated/torch_geometric.nn.conv.RGCNConv.html#torch_geometric.nn.conv.RGCNConv.forward) say that when using `Spa... | closed | 2024-02-09T17:54:28Z | 2024-02-12T20:19:22Z | https://github.com/pyg-team/pytorch_geometric/issues/8891 | [
"bug"
] | Rajat1206 | 2 |
ranaroussi/yfinance | pandas | 2,272 | Screening by industries | Hi!
Is it possible to add a feature for screening by industries?
Currently, I do it like this:
```
from yfinance.const import EQUITY_SCREENER_EQ_MAP, EQUITY_SCREENER_FIELDS
from yfinance import EquityQuery
sector = "Basic Materials"
industry = "Chemicals"
EQUITY_SCREENER_FIELDS.get("eq_fields").update(["... | open | 2025-02-17T13:06:29Z | 2025-02-20T12:22:44Z | https://github.com/ranaroussi/yfinance/issues/2272 | [] | ggeeoorrgg | 8 |
wkentaro/labelme | deep-learning | 1,330 | Switching from rectangular annotation to multi point annotation, the program will automatically exit | ### Provide environment information
Switching from rectangular annotation to multi point annotation, the program will automatically exit
### What OS are you using?
win
### Describe the Bug
Ctrl+R
Click on the image
At this point, a dot will appear in the image
Then press the shortcut keys ctrl+N
Click ... | open | 2023-09-25T07:00:57Z | 2023-09-25T07:00:57Z | https://github.com/wkentaro/labelme/issues/1330 | [
"issue::bug"
] | monkeycc | 0 |
plotly/dash | flask | 2,984 | [QUESTION] Does Dash have an official logo | Does Dash have a purely official logo image that doesn't include the word `plotly`. | closed | 2024-09-05T09:17:24Z | 2024-09-26T16:19:08Z | https://github.com/plotly/dash/issues/2984 | [
"feature",
"P2"
] | CNFeffery | 5 |
adbar/trafilatura | web-scraping | 302 | Method of Sourcing Elements | Hi!
Would it be possible to source where the text is coming from? I'd like to be able to know which css selector a given text snippet comes from. | closed | 2023-02-13T20:02:37Z | 2023-02-20T16:39:37Z | https://github.com/adbar/trafilatura/issues/302 | [
"feedback"
] | jackHedaya | 3 |
iperov/DeepFaceLab | machine-learning | 5,591 | Lazy GUI |
Tippper | closed | 2022-12-08T00:11:55Z | 2022-12-08T00:13:21Z | https://github.com/iperov/DeepFaceLab/issues/5591 | [] | robtoll | 0 |
man-group/arctic | pandas | 712 | Pandas deprecation issue in chunkstore | /Users/bryantmoscon/arctic/arctic/serialization/numpy_arrays.py:112: FutureWarning: A future version of pandas will default to `skipna=True`. To silence this warning, pass `skipna=True|False` explicitly.
arr, mask = self._convert_types(df[c].values) | closed | 2019-02-07T23:18:13Z | 2019-02-08T13:19:59Z | https://github.com/man-group/arctic/issues/712 | [
"deprecation"
] | bmoscon | 1 |
streamlit/streamlit | machine-learning | 9,929 | Sync `st.data_editor` to a database | ### Checklist
- [X] I have searched the [existing issues](https://github.com/streamlit/streamlit/issues) for similar feature requests.
- [X] I added a descriptive title and summary to this issue.
### Summary
I use st.data_editor to connect the data to the table in my database, num_rows="dynamic", and after deleting ... | open | 2024-11-26T07:53:43Z | 2024-11-27T02:24:05Z | https://github.com/streamlit/streamlit/issues/9929 | [
"type:enhancement",
"feature:st.data_editor",
"feature:connections"
] | dtiosd | 3 |
sloria/TextBlob | nlp | 342 | Is there a simple way to list all latin language codes ? | I am writing a script that needs to use one font or another depending on the language detected.
What I want to do is simple : If not Latin, use the NOTO font. Can I do this quick via some method ?
Alternatively, can I list all latin languages defined in TextBlob so I can say if not in list of lang codes, use NOT... | open | 2020-08-11T13:53:51Z | 2021-01-10T19:43:15Z | https://github.com/sloria/TextBlob/issues/342 | [] | journeytosilius | 1 |
CorentinJ/Real-Time-Voice-Cloning | deep-learning | 1,143 | Segmentation fault while using toolbox ! | Dear Friends, I am facing segmentation fault
`
Segmentation fault (core dumped)`
while using
`$ python demo_toolbox.py`
There is nothing which happens other than this fault, no window popup or any other error. I tried several python versions and also torch versions. Same result.
I am using Centos 7. Earlier ... | closed | 2022-12-02T15:46:47Z | 2022-12-19T11:30:12Z | https://github.com/CorentinJ/Real-Time-Voice-Cloning/issues/1143 | [] | Tortoise17 | 0 |
jmcnamara/XlsxWriter | pandas | 929 | Feature Request: Pivot Table support |
## Feature requests
Add `Feature request:` to the title.
Is there a way to include pivot table create based on the data that has been written?
Creating a table on one tab that I would like to create 2 different pivot tables. Column headings and row headings etc are known.
| closed | 2022-12-13T06:42:59Z | 2022-12-13T12:09:59Z | https://github.com/jmcnamara/XlsxWriter/issues/929 | [] | birchtj | 1 |
jacobgil/pytorch-grad-cam | computer-vision | 7 | Two questions? | Thanks for sharing this amazing code. I have two questions, the one is that how to retrain or fine-tune VGG network with my own data, such as faces with different attributes? The other is that how to use the label information? | closed | 2018-03-22T16:33:12Z | 2018-11-25T19:24:28Z | https://github.com/jacobgil/pytorch-grad-cam/issues/7 | [] | happsky | 0 |
neuml/txtai | nlp | 354 | Feature: Improve performance of Translation with different underlying library | I see that txtai uses Helsinki OPUS MT models for translation, but it is rather slow for me. I suspect this has at least something to do with Python.
As with using Tika server rather than Python-based text extraction packages, I wonder if there's a way to make use of the OPUS models with the Marian Server in order ... | closed | 2022-10-10T05:37:23Z | 2023-03-11T03:27:03Z | https://github.com/neuml/txtai/issues/354 | [] | nickchomey | 9 |
redis/redis-om-python | pydantic | 525 | [Enhancement] Support Pydantic v2 | 
Pydantic v2 comes with several performance and safety benefits due to being compiled in Rust with python bindings.
I'd love to see the models: HashModel, JsonModel, EmbeddedJsonModel all use the new and improved... | closed | 2023-06-19T00:22:45Z | 2024-05-02T14:34:19Z | https://github.com/redis/redis-om-python/issues/525 | [] | XChikuX | 3 |
nschloe/tikzplotlib | matplotlib | 355 | wrong aspect ratio and tick labels | Hi!
The save command ignores the plot properties as defined in Python, so figure size and also ticks.
Here you find the Python code:
```
import numpy as np
import matplotlib.pyplot as plt
import tikzplotlib
fig, axs = plt.subplots(2,1,sharex=True, figsize=(5,3))
for ax in axs:
ax.plot(np.random.ran... | open | 2019-12-13T14:11:51Z | 2020-06-12T18:29:43Z | https://github.com/nschloe/tikzplotlib/issues/355 | [] | IsabellLehmann | 3 |
graphql-python/graphene-django | django | 806 | Add to convert_form_field single dispatch | Is it possible to add more resolvers to the `convert_form_field` single dispatch function?
I want to add a custom resolver to automatically be used to convert GraphQL IDs to database compatible integer IDs:
```python
@convert_form_field.register(ModelChoiceField)
def convert_form_field_to_id(field):
return... | closed | 2019-10-22T09:55:06Z | 2022-12-07T05:52:25Z | https://github.com/graphql-python/graphene-django/issues/806 | [
"wontfix"
] | AceFire6 | 3 |
apache/airflow | data-science | 47,646 | Fix Connections Test Endpoint Should Allow None in the Request Body | ### Description
The test endpoint doesn't need `Connection Type` since the connection should already exist in the database.
### Are you willing to submit a PR?
- [x] Yes I am willing to submit a PR!
### Code of Conduct
- [x] I agree to follow this project's [Code of Conduct](https://github.com/apache/airflow/blob/... | closed | 2025-03-11T21:25:04Z | 2025-03-16T13:49:07Z | https://github.com/apache/airflow/issues/47646 | [
"area:API",
"type:bug-fix",
"priority:medium",
"affected_version:3.0.0beta"
] | bugraoz93 | 1 |
MagicStack/asyncpg | asyncio | 1,107 | Asyncpg.pool creates more connections than its max_size | <!--
Thank you for reporting an issue/feature request.
If this is a feature request, please disregard this template. If this is
a bug report, please answer to the questions below.
It will be much easier for us to fix the issue if a test case that reproduces
the problem is provided, with clear instructions on ... | open | 2023-11-19T12:17:32Z | 2023-11-21T20:13:30Z | https://github.com/MagicStack/asyncpg/issues/1107 | [] | no-to-mediocrity | 0 |
Anjok07/ultimatevocalremovergui | pytorch | 1,676 | Not enough GPU video memory even with AMD RX 7700 XT | I tried to use my AMD RX 7700 XT, which has 12 GB of VRAM, for GPU conversion when using the "MB-Roformer-Inst-V2" MDX-Net model. However, it never works and always pops up an error after a couple of seconds, as shown below. Can anyone figure out why my GPU is showing the low video memory error? Any help is appreciated... | open | 2024-12-21T22:09:24Z | 2024-12-29T21:49:12Z | https://github.com/Anjok07/ultimatevocalremovergui/issues/1676 | [] | Isocheims | 5 |
TencentARC/GFPGAN | pytorch | 122 | .version is not found | I'm getting error as ".version is not found in /gfpgan/__init__.py". How to proceed further ? | open | 2021-12-16T12:50:56Z | 2022-01-18T12:55:59Z | https://github.com/TencentARC/GFPGAN/issues/122 | [] | aravindh-c | 1 |
hzwer/ECCV2022-RIFE | computer-vision | 222 | cannot run on Google Colab | i executed the cell but after a few seconds, there was an error with ```^C``` at the end.
(i wanted to convert a 30fps video to 60fps, the input video resolution is 2304x4096, the length is 19s) | open | 2021-12-18T16:38:06Z | 2021-12-22T02:10:18Z | https://github.com/hzwer/ECCV2022-RIFE/issues/222 | [] | mikebilly | 6 |
graphdeco-inria/gaussian-splatting | computer-vision | 990 | How to merge multiple Gaussian models | Excuse me。How to merge multiple Gaussian models。 | open | 2024-09-18T11:57:37Z | 2024-11-22T07:57:30Z | https://github.com/graphdeco-inria/gaussian-splatting/issues/990 | [] | haggleSS | 5 |
OpenVisualCloud/CDN-Transcode-Sample | dash | 100 | [Enhancement][Q1'20] Avoid using unnecessary sudo in sample scripts and deployment/Kubernetes/start.sh | closed | 2019-11-26T01:55:43Z | 2020-01-17T01:21:00Z | https://github.com/OpenVisualCloud/CDN-Transcode-Sample/issues/100 | [
"enhancement"
] | wenquan-mao | 1 | |
mitmproxy/mitmproxy | python | 7,138 | Warn if `tls_version_client_min` is not supported by the current OpenSSL build | From https://github.com/mitmproxy/mitmproxy/discussions/7082: When the user configures tls_version_(client|server)_min, we should find a way to check if that is actually supported and warn if it's not. | closed | 2024-08-30T10:29:22Z | 2024-08-31T07:02:13Z | https://github.com/mitmproxy/mitmproxy/issues/7138 | [
"kind/feature",
"help wanted",
"area/addons"
] | mhils | 0 |
TencentARC/GFPGAN | pytorch | 592 | No module named 'basicsr' | Trying to use this with stable diffusion webui, got this error:
```
*** Error loading script: convert_gfpganv_to_clean.py
Traceback (most recent call last):
File "C:\Users\stable-diffusion-webui\modules\scripts.py", line 515, in load_scripts
script_module = script_loading.load_module(scriptfile.p... | open | 2024-11-26T10:37:19Z | 2024-11-28T12:17:16Z | https://github.com/TencentARC/GFPGAN/issues/592 | [] | lanly-dev | 0 |
Significant-Gravitas/AutoGPT | python | 9,530 | Add SDM Block Cost | The SDM block needs to have block costs | closed | 2025-02-26T21:59:07Z | 2025-02-26T22:25:29Z | https://github.com/Significant-Gravitas/AutoGPT/issues/9530 | [] | Swiftyos | 0 |
graphistry/pygraphistry | jupyter | 492 | land pygraphistry token fix | closed | 2023-06-30T14:37:01Z | 2023-09-07T21:09:32Z | https://github.com/graphistry/pygraphistry/issues/492 | [
"bug",
"p2",
"infra",
"security"
] | lmeyerov | 0 | |
autokey/autokey | automation | 846 | Handle invalid regex for Trigger on (user input) | ### AutoKey is a Xorg application and will not function in a Wayland session. Do you use Xorg (X11) or Wayland?
Xorg
### Has this issue already been reported?
- [X] I have searched through the existing issues.
### Is this a question rather than an issue?
- [X] This is not a question.
### What type of issue is thi... | open | 2023-04-24T20:38:52Z | 2023-05-06T14:21:14Z | https://github.com/autokey/autokey/issues/846 | [
"bug",
"user interface",
"autokey triggers"
] | josephj11 | 13 |
deepspeedai/DeepSpeed | machine-learning | 7,028 | [BUG] `import deepspeed` crashes on `deepspeed==0.16.3` with `triton==3.2.0` on CPU machine | **Describe the bug**
A clear and concise description of what the bug is.
- [deepspeed uses the @triton.autotuner decorator](https://github.com/deepspeedai/DeepSpeed/blob/22d7fdc0f444571131d77ab13be858b5118770ef/deepspeed/ops/transformer/inference/triton/triton_matmul_kernel.py#L51), which leads to the autotuner bei... | open | 2025-02-13T02:42:03Z | 2025-02-14T02:04:16Z | https://github.com/deepspeedai/DeepSpeed/issues/7028 | [
"bug",
"training"
] | hongpeng-guo | 3 |
encode/httpx | asyncio | 2,126 | `raise_for_status` now raises an exception for 1xx and 3xx responses | Hi!
I've just noticed that `response.raise_for_status()` now raises an exception for 1xx and 3xx requests. I don't think it was the case before (namely with version 0.18) and the documentation doesn't seem to have been updated here: https://www.python-httpx.org/exceptions/
> The HTTPStatusError class is raised by... | closed | 2022-03-14T16:42:42Z | 2022-04-01T15:06:24Z | https://github.com/encode/httpx/issues/2126 | [
"good first issue",
"docs"
] | remi-dupre | 2 |
jupyterhub/repo2docker | jupyter | 1,225 | Python 3.11 and beyond | <!-- Thank you for contributing. These HTML commments will not render in the issue, but you can delete them once you've read them if you prefer! -->
### Proposed change
Support Python 3.11, and perhaps automatically support future Python releases?
Python 3.11.0 was released in [October 2022](https://peps.pytho... | closed | 2022-12-27T02:25:20Z | 2024-05-29T13:27:34Z | https://github.com/jupyterhub/repo2docker/issues/1225 | [
"needs: discussion"
] | mjpieters | 3 |
python-restx/flask-restx | api | 236 | IntEnum cannot be used as response code anymore | In flask-restplus it was possible to use IntEnum as response code. It's useful as python contains http status code listed as IntEnum.
Since [this modification](https://github.com/python-restx/flask-restx/commit/10b8a65974fe9e59e1fc230cccb37710f0d0d2ee) it's not possible anymore as the str representation is not the ... | open | 2020-10-09T18:44:20Z | 2020-10-09T18:44:20Z | https://github.com/python-restx/flask-restx/issues/236 | [
"bug"
] | Colin-b | 0 |
scikit-multilearn/scikit-multilearn | scikit-learn | 246 | setup.py TypeError: an integer is required (got type str) | I wanted to install the latest version of this package with the fixes to mlknn and brknn but when I run setup.py, I get the error:
File "setup.py", line 16, in <module>
with io.open('README.md', 'r', 'utf-8') as f:
TypeError: an integer is required (got type str) | closed | 2022-10-03T01:07:53Z | 2023-03-03T18:39:17Z | https://github.com/scikit-multilearn/scikit-multilearn/issues/246 | [] | Caaarlogan | 1 |
aws/aws-sdk-pandas | pandas | 2,802 | Support IAM Trusted Identity Propagation with Redshift | **Is your feature request related to a problem? Please describe.**
IAM Trusted Identity Propagation is the recommended approach to pass user identity down to the data access so it can be used to apply permissions on the data access based on the user permissions instead of the IAM role used by the Python runtime.
**... | open | 2024-05-03T17:39:36Z | 2024-10-08T00:20:25Z | https://github.com/aws/aws-sdk-pandas/issues/2802 | [
"feature",
"needs-triage"
] | vgkowski | 0 |
ageitgey/face_recognition | machine-learning | 1,395 | Running an efficient query against MySQL | * face_recognition version: latest
* Python version: 3.8
* Operating System: ubuntu
### Description
Im trying to run the query bellow in MySQL to get the most relevant pictures. I put `limit 50`
The first X results accurate - same person, but I don't understand how to remove the other not relevant results
`... | open | 2021-12-15T12:39:51Z | 2021-12-15T12:39:51Z | https://github.com/ageitgey/face_recognition/issues/1395 | [] | avifatal | 0 |
pandas-dev/pandas | pandas | 60,274 | API: to_excel with merge_cells=False treats index and columns differently | ```python
df = pd.DataFrame({"a": [1, 1], "b": [2, 3], "c": 4, "d": 5}).set_index(["a", "b"])
df.columns = pd.MultiIndex.from_tuples([("x", "y"), ("x", "z")])
df.to_excel("test.xlsx", merge_cells=False)
```

In the above ... | closed | 2024-11-10T15:43:32Z | 2024-11-13T21:02:29Z | https://github.com/pandas-dev/pandas/issues/60274 | [
"Bug",
"IO Excel",
"MultiIndex"
] | rhshadrach | 3 |
ned2/slapdash | plotly | 5 | CSS assets do not seem to load when running in PyCharm | I notice the `bootstrap.min.css` and `custom.css` files in the `slapdash/assets` folder, along with FontAwesome. However, these assets do not seem to load when running the app:

When I n... | closed | 2018-10-29T10:05:57Z | 2019-03-05T11:51:58Z | https://github.com/ned2/slapdash/issues/5 | [] | brylie | 17 |
thtrieu/darkflow | tensorflow | 414 | Training YOLOv2 correct number of filters | Hello @thtrieu
As it is stated on the guide, if I want to use the tiny-yolo-voc.cfg I need to set up the formula according to the classes as:
num * (classes + 5), being num = 5 and classes are 3 so 5 * (3 + 5) = 40
But I am working in the YOLOv2 model (yolo.cfg). Can you help me out with the formula of the n... | open | 2017-10-06T10:16:57Z | 2024-05-16T16:56:06Z | https://github.com/thtrieu/darkflow/issues/414 | [] | AndresPMD | 18 |
litestar-org/litestar | asyncio | 3,396 | Enhancement: SQLAdmin Support | ### Summary
SQLAdmin has a fork for litestar, but it isn't properly supported and there are no issues or discussions around its limitations. Is there support for making this better integrated in the litestar community?
### Basic Example
When using both litestar sqlalchemy plugin and the sqladmin fork https://github.... | closed | 2024-04-16T16:34:28Z | 2025-03-20T15:54:36Z | https://github.com/litestar-org/litestar/issues/3396 | [
"Enhancement"
] | colebaileygit | 5 |
piskvorky/gensim | machine-learning | 3,066 | Warnings of deprecated functions | <!--
**IMPORTANT**:
- Use the [Gensim mailing list](https://groups.google.com/forum/#!forum/gensim) to ask general or usage questions. Github issues are only for bug reports.
- Check [Recipes&FAQ](https://github.com/RaRe-Technologies/gensim/wiki/Recipes-&-FAQ) first for common answers.
Github bug reports that d... | closed | 2021-03-09T14:55:50Z | 2021-03-22T09:35:49Z | https://github.com/piskvorky/gensim/issues/3066 | [] | FredHappyface | 0 |
snooppr/snoop | web-scraping | 39 | Ошибка | На termux вот такое:
Traceback (most recent call last):
File "/data/data/com.termux/files/usr/lib/python3.8/multiprocessing/synchronize.py", line 28, in <module>
from _multiprocessing import SemLock, sem_unlink
ImportError: cannot import name 'SemLock' from '_multiprocessing' (/data/data/com.termux/files/usr/... | closed | 2020-10-07T23:09:30Z | 2020-10-08T20:41:31Z | https://github.com/snooppr/snoop/issues/39 | [
"bug"
] | Drauggy | 6 |
roboflow/supervision | deep-learning | 1,715 | `move_masks` only supports movement in positive direction | If you compare the code of `move_masks`, `move_detections` and `move_oriented_boxes`, you'll find that only mask code restricts offset direction:
```python
if offset[0] < 0 or offset[1] < 0:
raise ValueError(f"Offset values must be non-negative integers. Got: {offset}")
```
It should be possible to... | closed | 2024-12-06T09:17:48Z | 2024-12-16T14:08:27Z | https://github.com/roboflow/supervision/issues/1715 | [
"bug",
"help wanted"
] | LinasKo | 3 |
deezer/spleeter | tensorflow | 366 | [Discussion] Command line works but not api? Spleeter-GPU | This boggles my mind, has anyone had similar experience? | closed | 2020-05-08T22:28:57Z | 2020-05-11T15:15:48Z | https://github.com/deezer/spleeter/issues/366 | [
"question"
] | aidv | 2 |
biolab/orange3 | data-visualization | 6,646 | Add GESD to outliers | Please add support for Generalized ESD, a robust and powerful unsupervised algorithm for identification of outliers. This algorithm is easy to understand but seemingly underused because few tools make it readily available. | closed | 2023-11-20T15:49:56Z | 2023-12-12T23:15:25Z | https://github.com/biolab/orange3/issues/6646 | [] | belg4mit | 2 |
piskvorky/gensim | machine-learning | 2,860 | AttributeError: 'FastText' object has no attribute 'intersect_word2vec_format' | #### Problem description
I would like to fine-tune a fasttext embeddings model trained on wiki data on new in domain data,
I was using this code;
#### Steps/code/corpus to reproduce
model = KeyedVectors.load_word2vec_format(args.pretrained_model,binary=False)
model_Fasttext_cbow = FastText(size=args.vector_size... | open | 2020-06-17T14:51:08Z | 2020-06-18T23:05:19Z | https://github.com/piskvorky/gensim/issues/2860 | [] | saharghannay | 1 |
deezer/spleeter | deep-learning | 815 | [Bug] looping over files will cause a race condition | - [x] I didn't find a similar issue already open.
- [x] I read the documentation (README AND Wiki)
- [x] I have installed FFMpeg
- [x] My problem is related to Spleeter only, not a derivative product (such as Webapplication, or GUI provided by others)
## Description
when looping over audio files, do separation a... | open | 2022-12-30T15:32:51Z | 2023-03-10T14:34:18Z | https://github.com/deezer/spleeter/issues/815 | [
"bug",
"invalid"
] | binbinxue | 2 |
hpcaitech/ColossalAI | deep-learning | 5,527 | Grok-1: ValueError: 'localhost.localdomain' does not appear to be an IPv4 or IPv6 address | Follow the guide from <https://github.com/hpcaitech/ColossalAI/tree/main/examples/language/grok-1>
and got this error.
(/SSD_DATA/chenhy/anaconda_envs/xai) [chenhy@centos7gpu grok-1]$ ./run_inference_fast.sh /HDD_DATA/chenhy/xai/grok-1/
[2024-03-28 09:35:31,685] torch.distributed.run: [WARNING] master_addr is ... | closed | 2024-03-28T01:32:48Z | 2024-03-28T05:35:53Z | https://github.com/hpcaitech/ColossalAI/issues/5527 | [
"example"
] | nijisakai | 2 |
Yorko/mlcourse.ai | pandas | 754 | AttributeError: 'NoneType' object has no attribute 'split' using anaconda | needed to upgrade threadpoolctl to 3.2
pip install threadpoolctl --upgrade
to fix the error [AttributeError: 'NoneType' object has no attribute 'split'](https://stackoverflow.com/questions/71352354/sklearn-kmeans-is-not-working-as-i-only-get-nonetype-object-has-no-attribute) in [topic 3](https://mlcourse.ai/book/top... | closed | 2023-09-10T15:37:17Z | 2024-08-19T16:13:22Z | https://github.com/Yorko/mlcourse.ai/issues/754 | [] | Selithrarion | 6 |
seleniumbase/SeleniumBase | web-scraping | 2,954 | set_wire_proxy does not worked | Hi. I tried to dynamicly set proxy for chrome webdriver with wire, but it does not worked
My code:
```
driver = Driver(
headless2=True,
no_sandbox=True,
disable_gpu=True,
wire=True,
#ad_block=True,
#block_images=True,
... | closed | 2024-07-24T00:15:25Z | 2024-07-24T03:35:36Z | https://github.com/seleniumbase/SeleniumBase/issues/2954 | [
"invalid usage"
] | Mracobes9 | 1 |
junyanz/pytorch-CycleGAN-and-pix2pix | deep-learning | 769 | Load input to RAM | Hello i am training a CycleGan with a huge number of images(70 000) for each collection, A and B. All images are panoramas 256*512 and i was wondering if it possible to load all images to RAM and not loading for each epoch all the images again.I have enough RAM capacity as all images are around 10GB. Is it possible fr... | closed | 2019-09-16T12:23:46Z | 2019-09-17T15:32:20Z | https://github.com/junyanz/pytorch-CycleGAN-and-pix2pix/issues/769 | [] | KyriakosZantis | 4 |
microsoft/unilm | nlp | 860 | EdgeLM : ONNX runtime | Regarding this paper : EdgeFormer: A Parameter-Efficient Transformer for On-Device Seq2seq Generation.
Great work!
could you pls share how to infer a model using ONNX runtime? | open | 2022-09-08T07:25:38Z | 2022-09-09T06:44:01Z | https://github.com/microsoft/unilm/issues/860 | [] | santha96 | 2 |
numba/numba | numpy | 9,801 | np.dot should upcast types | <!--
Thanks for opening an issue! To help the Numba team handle your information
efficiently, please first ensure that there is no other issue present that
already describes the issue you have
(search at https://github.com/numba/numba/issues?&q=is%3Aissue).
-->
## Reporting a bug
<!--
Before submittin... | open | 2024-11-20T21:20:11Z | 2024-11-26T15:09:41Z | https://github.com/numba/numba/issues/9801 | [
"feature_request",
"numpy"
] | rlangefe | 10 |
KaiyangZhou/deep-person-reid | computer-vision | 39 | Testing of a trained model | @luzai @KaiyangZhou Hi just wanted to know how to test the trained model for a video ? since the trained model is having an extension of "pth.tar" is there any other method which we can use to test this model
pls share the comand Thank you | closed | 2018-07-20T08:22:00Z | 2018-09-03T18:12:46Z | https://github.com/KaiyangZhou/deep-person-reid/issues/39 | [] | abhigoku10 | 0 |
iterative/dvc | data-science | 10,681 | auto push on a repository basis | I run a lot of my ML workloads in short lived containers in a dedicated ML cluster. The typical workflow is like this:
1. Prepare experiment locally, run a single, smaller epoch for testing
2. `git push && dvc push` to repository
3. Start container, `git pull && dvc pull` in the container
4. Run either `dvc repro` or `... | open | 2025-02-03T10:34:09Z | 2025-02-16T20:13:31Z | https://github.com/iterative/dvc/issues/10681 | [
"triage",
"feature",
"A: data-sync"
] | igordertigor | 2 |
sunscrapers/djoser | rest-api | 49 | No issue. | Deleted. Please delete.
| closed | 2015-05-30T19:16:40Z | 2015-05-31T08:47:56Z | https://github.com/sunscrapers/djoser/issues/49 | [] | ghost | 1 |
arogozhnikov/einops | tensorflow | 12 | logsumexp reduction support | It would be nice to have it, but there are problems with backends
- numpy.logaddexp.reduce is available (scipy.special.logsumexp is better, but I can't use it)
- tf.reduce_logsumexp is available
- **problem** cupy doesn'h have an implementation
- chainer has "chainer.functions.logsumexp", but we can't use if for cu... | closed | 2018-11-03T02:08:12Z | 2023-03-16T05:16:11Z | https://github.com/arogozhnikov/einops/issues/12 | [
"enhancement"
] | arogozhnikov | 1 |
automl/auto-sklearn | scikit-learn | 1,587 | [Question] Is it possible to change the hyperparameter space of an algorithm? | # Short Question Description
Is it possible to change the hyper-parameter space of an algorithm (such as
PCA), so that it is restricted or enlargedd in respect to the default ones?
I know that we can override the `get_hyperparameter_search_space` method, but
I think it would be easier if there would be an accessi... | open | 2022-09-20T12:00:51Z | 2022-09-21T13:28:15Z | https://github.com/automl/auto-sklearn/issues/1587 | [
"enhancement"
] | 00sapo | 2 |
plotly/dash | data-visualization | 2,910 | DatePickerRange popup calendar additional date avaliable even with min/max date specified | Thank you so much for helping improve the quality of Dash!
We do our best to catch bugs during the release process, but we rely on your help to find the ones that slip through.
**Describe your context**
Please provide us your environment, so we can easily reproduce the issue.
- replace the result of `pip l... | open | 2024-07-02T21:59:16Z | 2024-08-13T19:53:56Z | https://github.com/plotly/dash/issues/2910 | [
"bug",
"sev-3",
"P3"
] | ForsakenRei | 0 |
flasgger/flasgger | flask | 119 | Upgrade version of swagger-ui | UI v3 was added just before swagger-ui version 3 was released, now the current version is 3.0.16 | closed | 2017-06-22T11:45:48Z | 2018-08-01T07:15:00Z | https://github.com/flasgger/flasgger/issues/119 | [] | mrfuxi | 3 |
onnx/onnx | scikit-learn | 6,187 | onnx.checker crashes on LayerNormalization | # Bug Report
### Describe the bug
```
#!/usr/bin/env python
import onnx
import onnx.parser
modeltxt = """
<
ir_version: 10,
opset_import: ["" : 17]
>
graph (float in0, float[2,7,8,1,3] in1, float[3,7] in2) => () {
out0, out1, out2 = LayerNormalization <epsilon: float = -841.058, stash_type: int... | closed | 2024-06-17T12:07:09Z | 2024-07-08T15:14:58Z | https://github.com/onnx/onnx/issues/6187 | [
"bug"
] | mgehre-amd | 0 |
google-research/bert | nlp | 638 | module 'tokenization' has no attribute 'FullTokenizer' | I'm importing tokenization, have installed via pip, and cannot instantiate the tokenizer. I'm using the following code below and continue to get an error message of "module 'tokenization' has no attribute 'FullTokenizer'".
Anyone have a sense as to why?
`tokenizer = tokenization.FullTokenizer(vocab_file=vocab_fil... | closed | 2019-05-11T23:52:43Z | 2023-06-10T01:46:51Z | https://github.com/google-research/bert/issues/638 | [] | 1337-Pete | 9 |
biosustain/potion | sqlalchemy | 135 | v0.15.0 tag does not match master branch v0.15.0 | Hello, I encountered a build error while packaging potion for [conda-forge](https://conda-forge.org/). The v0.15.0 tag commit hash does not match the master branch commit hash for the v0.15.0 release.
The commit hash for the master branch v0.15.0 release is: 8a42ccb21422d405cdb9a62319754e43477d2bc1
The commit has... | closed | 2018-07-08T16:34:14Z | 2018-07-20T11:29:43Z | https://github.com/biosustain/potion/issues/135 | [] | corburn | 1 |
google-research/bert | nlp | 780 | whole word mask is not support in chinese | it seems pre-train corpus using whole word mask is not support in chinese yet.
even passing --do_whole_word_mask=True using create_pretraining_data.py, nothing happens.
is there someone know how to do that? | open | 2019-07-21T02:32:16Z | 2019-07-23T04:21:54Z | https://github.com/google-research/bert/issues/780 | [] | brightmart | 3 |
Subsets and Splits
No community queries yet
The top public SQL queries from the community will appear here once available.