
repo_name stringlengths 9 75 | topic stringclasses 30
values | issue_number int64 1 203k | title stringlengths 1 976 | body stringlengths 0 254k | state stringclasses 2
values | created_at stringlengths 20 20 | updated_at stringlengths 20 20 | url stringlengths 38 105 | labels listlengths 0 9 | user_login stringlengths 1 39 | comments_count int64 0 452 |
|---|---|---|---|---|---|---|---|---|---|---|---|
zihangdai/xlnet | tensorflow | 242 | Xlnet Training Error | Hi, I want to train xlnet model for Turkish language. So I create an input file that appropriate to the specified rules. I run the sentencepiece code and then the data_utils code succesfully.
When I run the code with below parameters for training, I got the following error:
**Input**
```
!python train_gpu.py \
... | closed | 2019-10-21T21:21:05Z | 2019-11-28T10:24:01Z | https://github.com/zihangdai/xlnet/issues/242 | [] | yusufani | 5 |
kymatio/kymatio | numpy | 663 | Flaky TF FFT unit test | So I keep getting intermittent test failures on GH Actions with the 2D FFT unit test:
```
=================================== FAILURES ===================================
____________________ TestFFT.test_fft[TensorFlowBackend2D] _____________________
self = <test_tensorflow_backend_2d.TestFFT object at 0x7f09371... | closed | 2021-02-11T22:16:40Z | 2022-06-23T22:09:01Z | https://github.com/kymatio/kymatio/issues/663 | [] | janden | 0 |
babysor/MockingBird | pytorch | 406 | 求助, No module named 'vocoder.wavernn' | Mac M1,所有依赖包安装完成后运行demo,提示报错,大家有没有思路;
Traceback (most recent call last):
File "/Users/***/work/demo/MockingBird/demo_toolbox.py", line 2, in <module>
from toolbox import Toolbox
File "/Users/***/work/demo/MockingBird/toolbox/__init__.py", line 5, in <module>
from vocoder.wavernn import inference as r... | closed | 2022-02-27T00:46:46Z | 2022-02-27T13:22:25Z | https://github.com/babysor/MockingBird/issues/406 | [] | hxqbeyond | 4 |
pyjanitor-devs/pyjanitor | pandas | 1,210 | [ENH] deconcatenate_columns | Make `deconcatenate_columns` have more features - separate by position/regex etc
Inspiration is from the new [features](https://hadley.quarto.pub/upcoming-features-in-the-tidyverse/#tidyr-1.3.0) coming to `tidyr` - I feel it'd make extraction easier for the end user. | closed | 2022-11-27T03:55:20Z | 2025-03-22T23:23:35Z | https://github.com/pyjanitor-devs/pyjanitor/issues/1210 | [] | samukweku | 1 |
fastapi-admin/fastapi-admin | fastapi | 66 | Incorrect dependency versions | Please pin the dependency versions, in particular the quickstart instructions are only compatible with `aioredis<2.0` | closed | 2021-08-07T02:34:37Z | 2021-09-03T08:14:30Z | https://github.com/fastapi-admin/fastapi-admin/issues/66 | [] | lovetoburnswhen | 0 |
tflearn/tflearn | data-science | 749 | how to train a many to many sequence labeling using LSTM? | I'm working on a sequence labeling task, and I want to use LSTM to do this task.
My input and output looks like below:
I got 3 samples and each of them has different length.
X = [ [123, 2, 3], [4, 5 ,22, 10, 2], [1, 5] ]
y = [ [0, 0, 2], [0, 1, 0, 0,2 ], [0, 1] ]
It's like the fifth architecture(from left) in... | open | 2017-05-12T00:56:42Z | 2019-03-22T20:13:28Z | https://github.com/tflearn/tflearn/issues/749 | [] | chrisplyn | 2 |
koxudaxi/datamodel-code-generator | fastapi | 2,337 | RecursionError in generated code with nested properties | **Describe the bug**
Generated python code with nested properties causes `pydantic v2` to be stuck in infinite loop.
**To Reproduce**
Example schema:
```json
{
"title": "Test",
"type": "object",
"properties": {
"TestObject": {
"title": "TestObject",
"type": "object",
"properties": {
... | closed | 2025-03-06T11:45:40Z | 2025-03-22T08:38:49Z | https://github.com/koxudaxi/datamodel-code-generator/issues/2337 | [
"bug",
"help wanted"
] | kampelmuehler | 3 |
keras-team/keras | pytorch | 20,538 | Bugs using keras.src.utils.split_dataset on tf.data.Dataset loaded using tf.data.experimental.make_csv_dataset on versions v3.4.0+ | Bug description:
We've noticed two bugs that appear when using split_dataset on tf datasets loaded using tf.data.experimental.make_csv_dataset for keras versions 3.4.0 onward. One of two things happens on attempting to call split_dataset on a dataset loaded using make_csv_dataset, either the split_dataset call hangs... | closed | 2024-11-22T22:37:19Z | 2024-11-30T11:19:56Z | https://github.com/keras-team/keras/issues/20538 | [
"type:Bug"
] | sfenu-3 | 7 |
pydantic/FastUI | fastapi | 333 | Initial value on form doesn't work with datetime | When I have a form with datetime with initial value, it doesn't respect the initial value
```
class SomeForm(BaseModel):
start_date: datetime
c.ModalForm(model=SomeForm, initial=SomeForm(start_date=datetime.now(UTC))
```
.). After a further digging, there are some concerns:
+ the parameters, confidence_threshold and... | open | 2017-09-12T09:44:47Z | 2020-08-04T08:12:01Z | https://github.com/amdegroot/ssd.pytorch/issues/62 | [] | hli2020 | 13 |
AUTOMATIC1111/stable-diffusion-webui | deep-learning | 16,809 | [Bug]: random crash with "press any key to continue" | ### Checklist
- [x] The issue exists after disabling all extensions
- [ ] The issue exists on a clean installation of webui
- [ ] The issue is caused by an extension, but I believe it is caused by a bug in the webui
- [x] The issue exists in the current version of the webui
- [ ] The issue has not been reported before... | open | 2025-01-25T00:26:22Z | 2025-02-14T08:48:22Z | https://github.com/AUTOMATIC1111/stable-diffusion-webui/issues/16809 | [
"bug-report"
] | cain666-4u | 4 |
dpgaspar/Flask-AppBuilder | flask | 2,023 | could 'AUTH_ROLES_SYNC_AT_LOGIN' be enable in phases depending on set of users or specific role | If you'd like to report a bug in Flask-Appbuilder, fill out the template below. Provide
any extra information that may be useful
Responsible disclosure:
We want to keep Flask-AppBuilder safe for everyone. If you've discovered a security vulnerability
please report to danielvazgaspar@gmail.com.
### Environment
... | open | 2023-04-26T07:32:53Z | 2023-04-26T07:32:53Z | https://github.com/dpgaspar/Flask-AppBuilder/issues/2023 | [] | naveenbussari | 0 |
datadvance/DjangoChannelsGraphqlWs | graphql | 74 | How can I get query_string inside customAuthMiddleware? | Hi! Help me please understand how to get `query_string` inside Custom Auth middleware? I try to pass query_string like this:
`http://0.0.0.0/graphql/?token=some_token_here` but I can't get it :)
middleware:
```py
class TokenAuthMiddleware(BaseMiddleware):
def __init__(self, inner):
self.inner = inn... | closed | 2021-06-29T12:15:55Z | 2021-06-29T20:39:43Z | https://github.com/datadvance/DjangoChannelsGraphqlWs/issues/74 | [] | MIRAMAXED | 0 |
chatanywhere/GPT_API_free | api | 206 | 接口报401 | 
已正确配置key,但一直报401 | closed | 2024-04-02T02:35:10Z | 2024-04-06T10:32:39Z | https://github.com/chatanywhere/GPT_API_free/issues/206 | [] | lingjieiot | 1 |
widgetti/solara | flask | 1,012 | Potential issue: Race condition in page disconnection handling: "cannot disconnect a page that is in state: DISCONNECTED" | ### Description
I'm encountering an error in my Solara application related to page connection state management. The application throws an assertion error when attempting to disconnect a page that is already in a DISCONNECTED state. This appears to be a race condition in the page connection management system.
### Step... | open | 2025-03-02T22:14:50Z | 2025-03-02T22:16:09Z | https://github.com/widgetti/solara/issues/1012 | [] | JovanVeljanoski | 0 |
litestar-org/polyfactory | pydantic | 230 | Generation not following the constraints when validator is specified | ### Description
The generator is not following the constraints when a custom validator is specified.
### URL to code causing the issue
_No response_
### MCVE
```python
from pydantic import validator
from polyfactory.factories.pydantic_factory import ModelFactory
class Product(BaseModel):
price:... | closed | 2023-06-10T08:59:28Z | 2025-03-20T15:53:03Z | https://github.com/litestar-org/polyfactory/issues/230 | [
"bug"
] | HarshTrivedi | 10 |
napari/napari | numpy | 6,978 | Deprecated `edge_color` cannot be passed to `ViewerModel.add_points` | ### 🐛 Bug Report
I tried to pass `edge_color` through `ViewerModel.add_points`. I expected to get a deprecation warning, but instead I got an exception:
```
TypeError: add_points() got an unexpected keyword argument 'edge_color'
```
Note that I can pass `edge_color` to the `Points.__init__`.
I assume sim... | closed | 2024-06-11T22:00:30Z | 2024-06-13T00:38:38Z | https://github.com/napari/napari/issues/6978 | [
"bug"
] | andy-sweet | 9 |
d2l-ai/d2l-en | computer-vision | 2,489 | installing d2l package on google colab | I've tried to run the codes on google colab.
So I tried `pip install d2l==1.0.0-beta0`, but didn't work.
So I used `pip install d2l==1.0.0-alpha0`, and tried to run the following code.
```python
d2l.set_figsize()
img = d2l.plt.imread('../img/catdog.jpg')
d2l.plt.imshow(img);
```
But it says `FileNotFoundError: ... | closed | 2023-05-15T05:50:24Z | 2023-07-10T13:26:54Z | https://github.com/d2l-ai/d2l-en/issues/2489 | [
"bug"
] | minjae35 | 1 |
voxel51/fiftyone | computer-vision | 5,498 | [BUG] Could not convert string to float in Augmentation with Albumentations | ### Describe the problem
So, I was trying to augment my dataset using Albumentations by following [this tutorial](https://docs.voxel51.com/tutorials/data_augmentation.html). Here, I used the "quickstart" dataset. But, when I applied the augmentation, there's an error message: "could not convert string to float: 'id'" ... | open | 2025-02-19T03:45:06Z | 2025-02-19T03:53:10Z | https://github.com/voxel51/fiftyone/issues/5498 | [
"bug"
] | riset-testing-khs | 0 |
joouha/euporie | jupyter | 4 | [Q] Any ideas on how hard it is to display images in TUI emacs via the Kitty protocol? | I have been wondering about this for some time, but I had not seen anyone who knows enough elisp and Kitty to ask. | closed | 2021-05-09T14:23:09Z | 2021-05-09T18:33:31Z | https://github.com/joouha/euporie/issues/4 | [] | NightMachinery | 2 |
jazzband/django-oauth-toolkit | django | 759 | Client for 3rd party providers | Does django-oauth-toolkit work with external providers like Okta and Ping Identity, or does it assume that you are using your own authorization/resource servers? | open | 2019-11-03T22:12:40Z | 2019-11-03T22:12:40Z | https://github.com/jazzband/django-oauth-toolkit/issues/759 | [] | andrewtmendoza | 0 |
amidaware/tacticalrmm | django | 2,173 | Maintenance Mode Schedules | Ability to schedule maintenance periods, we have several Azure VMs that turn off when not in use that we do not need alerts for "over due" agent on.
| closed | 2025-03-20T09:48:30Z | 2025-03-20T17:18:55Z | https://github.com/amidaware/tacticalrmm/issues/2173 | [] | safetynetit | 1 |
deepset-ai/haystack | machine-learning | 8,353 | feat: Add `StringJoiner` as a convenience component | **Is your feature request related to a problem? Please describe.**
As @ju-gu and I have been building pipelines with many branches that branch into many different Prompt Builders we ran into a need for a component like `StringJoiner` which would concatenate strings into a list of strings. In our specific use case our ... | closed | 2024-09-11T13:19:31Z | 2024-10-30T15:03:43Z | https://github.com/deepset-ai/haystack/issues/8353 | [
"P1"
] | sjrl | 7 |
cvat-ai/cvat | pytorch | 8,420 | error in debugging of REST server | ### Actions before raising this issue
- [X] I searched the existing issues and did not find anything similar.
- [X] I read/searched [the docs](https://docs.cvat.ai/docs/)
### Steps to Reproduce
Hello,
I am trying to prepare developement environment according to https://docs.cvat.ai/docs/contributing/devel... | closed | 2024-09-09T22:59:10Z | 2024-09-10T07:09:23Z | https://github.com/cvat-ai/cvat/issues/8420 | [
"bug"
] | tsune10696 | 1 |
scikit-multilearn/scikit-multilearn | scikit-learn | 89 | Error while performing Binary Relevance or Label Powerset | I am trying to perform a simple classification using Binary Relevance or Label Powerset. I consistently encounter the error despite also trying to convert it into a sparse matrix. How do I overcome this?
Here is my code:
```
import pandas as pd
import numpy as np
from scipy import sparse
from sklearn.naive_ba... | closed | 2017-12-11T16:56:01Z | 2017-12-13T13:01:30Z | https://github.com/scikit-multilearn/scikit-multilearn/issues/89 | [] | ansin218 | 7 |
jupyterlab/jupyter-ai | jupyter | 655 | Empty "Section Navigation" in user docs | <!-- Welcome! Thank you for contributing. These HTML comments will not render in the issue.
Before creating a new issue:
* Search for relevant issues
* Follow the issue reporting guidelines:
https://jupyterlab.readthedocs.io/en/latest/getting_started/issue.html
-->
## Description
The left panel of the ... | closed | 2024-02-26T23:35:36Z | 2024-11-27T18:50:44Z | https://github.com/jupyterlab/jupyter-ai/issues/655 | [
"bug",
"documentation"
] | JasonWeill | 1 |
robinhood/faust | asyncio | 624 | Dynamically adding, removing agents, channels, tasks ... | This is not an issue so I am not using the template. I was wondering if there is a way to add and remove tasks, agents,
and channels (at the minimum) dynamically? I read about mode.Service but can quite comprehend how and if at all this serves my use case? In summary, I am looking for something like
``` python
d... | open | 2020-08-02T22:43:33Z | 2021-06-07T09:51:23Z | https://github.com/robinhood/faust/issues/624 | [] | CowBoy4mH3LL | 3 |
BeanieODM/beanie | asyncio | 203 | How can I use like?? | i want do it
```
select * from mysql where name like '%str%' and age like '%str%'
```
but i cant do it ,can you help me ??
```
class Department(Document):
department_id: int = Field(title='部门id')
name: str = Indexed(str, index_type=TEXT, title='部门名称') # Field(default=None, title='部门名称')
```
``... | closed | 2022-02-14T10:50:42Z | 2022-02-14T11:43:10Z | https://github.com/BeanieODM/beanie/issues/203 | [] | douyahu | 1 |
chaoss/augur | data-visualization | 2,856 | Improve Contributor Resolution Logging | Conform Contributor Resolution to #2848
| closed | 2024-07-01T23:40:13Z | 2024-10-01T22:50:44Z | https://github.com/chaoss/augur/issues/2856 | [
"feature-request"
] | sgoggins | 0 |
Kanaries/pygwalker | pandas | 86 | Support for statistical annotations | Often when biologists draw a plot to compare data, statistical analysis along with the statistical annotation of the p-value comparison on the graph is a crucial step. Can this feature be implemented? If so, and if there is help needed, I would be more than happy to help out with this feature.
Here is an example:
)
- [x] I've checked that all provided URLs are playable in a browser with the same IP and same... | closed | 2025-03-19T11:51:29Z | 2025-03-19T11:54:27Z | https://github.com/yt-dlp/yt-dlp/issues/12666 | [
"site-bug",
"triage"
] | EmmaKnijn | 1 |
opengeos/leafmap | jupyter | 904 | add_raster does not work on Jupyter of visual studio code using remote development | <!-- Please search existing issues to avoid creating duplicates. -->
### Environment Information
- Leafmap version: 0.38.1
- Python version: 3.12.6 | packaged by conda-forge | (main, Sep 22 2024, 14:16:49) [GCC 13.3.0]
- Operating System: Ubuntu 22.04
### Description
From my local computer I have connecte... | closed | 2024-09-26T10:45:17Z | 2024-10-20T05:35:49Z | https://github.com/opengeos/leafmap/issues/904 | [
"bug"
] | karantai | 7 |
zappa/Zappa | flask | 444 | [Migrated] Improve support for Django with custom uwsgi function | Originally from: https://github.com/Miserlou/Zappa/issues/1164 by [bxm156](https://github.com/bxm156)
## Context
I use django, but prefer to use my own uwsgi function so that I can wrap certain middlewares for monitoring. Zappa is great because I just use ```app_function```, instead of ```django_settings```, and viol... | closed | 2021-02-20T08:34:55Z | 2022-07-16T07:33:52Z | https://github.com/zappa/Zappa/issues/444 | [] | jneves | 1 |
aimhubio/aim | tensorflow | 2,558 | silent ignore of list metrics | ## 🐛 Bug
If Run.track receives a list input, it is silently ignored
### To reproduce
>>> import aim
>>> run = aim.Run()
>>> x = []
>>> run.track(x, name="temp")
UI doesn't show any metrics in the corresponding run
### Expected behavior
I believe at least a warning, but personally a error should be... | open | 2023-03-02T05:45:49Z | 2023-03-02T19:22:37Z | https://github.com/aimhubio/aim/issues/2558 | [
"type / bug",
"help wanted"
] | lakshya-4gp | 2 |
chmp/ipytest | pytest | 118 | Add proper documentation how to handle external test files | Expand the current section on state in notebooks to explain how this applies to external test files and how to address this using `ipytest`. See #117 | closed | 2024-08-01T14:50:26Z | 2024-08-05T13:10:35Z | https://github.com/chmp/ipytest/issues/118 | [] | chmp | 0 |
skforecast/skforecast | scikit-learn | 153 | ForecasterAutoreg: include lags of exog in skforecast.model_selection.grid_search_forecaster ? | The docs say: "ForecasterAutoreg and ForecasterAutoregCustom allow to include exogenous variables as predictors as long as their future values are known, since they must be included during the predict process." [source](https://joaquinamatrodrigo.github.io/skforecast/0.1/guides/autoregresive-forecaster-exogenous.html)
... | closed | 2022-05-04T09:18:09Z | 2023-04-05T10:11:51Z | https://github.com/skforecast/skforecast/issues/153 | [
"question"
] | zora-no | 6 |
explosion/spaCy | machine-learning | 13,300 | Training spacy model stucking in 99% | ## Description
So i am training a NER model using transformers and my gpu, the problem happens in the training when the bar that keeps tracks of the progress reachs 99%, it takes 5 minutes to reach 99% and then take many more to go from 99 to 100 maybe even an hour,this is the way that was supposed to work?
## How ... | closed | 2024-02-02T12:00:45Z | 2024-02-06T10:01:45Z | https://github.com/explosion/spaCy/issues/13300 | [
"training"
] | Rafa7046 | 1 |
anselal/antminer-monitor | dash | 92 | Builtins.keyerror "pools" | 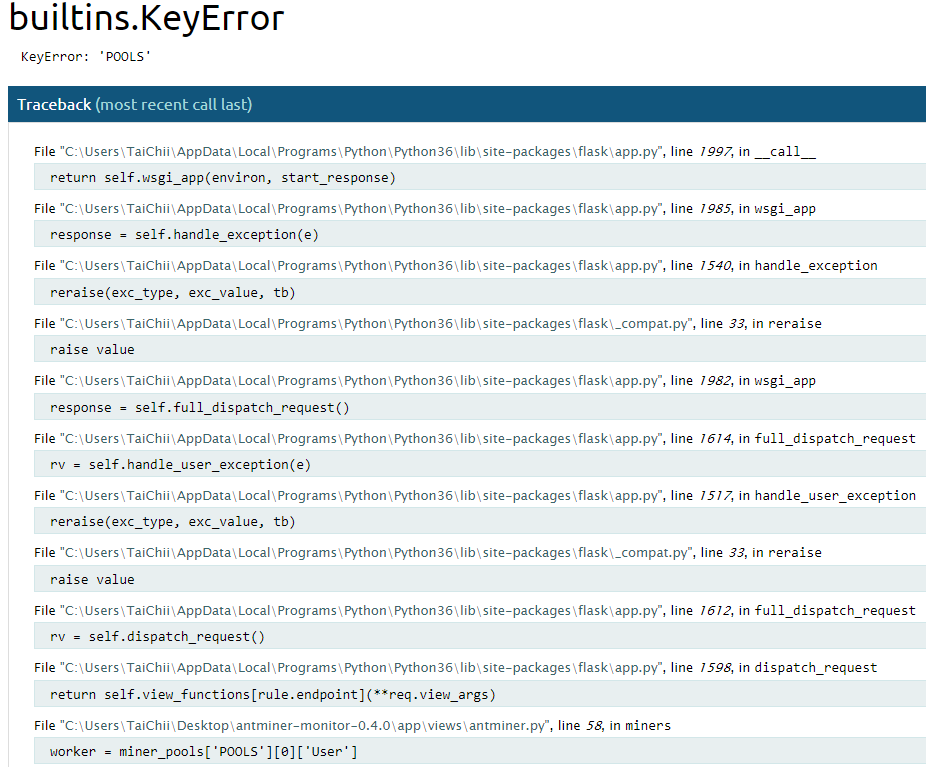
| closed | 2018-04-23T19:10:34Z | 2018-05-03T05:28:08Z | https://github.com/anselal/antminer-monitor/issues/92 | [
":dancing_men: duplicate"
] | alaaelmahdy | 1 |
litestar-org/litestar | pydantic | 3,304 | Enhancement(Infra): Docs preview link in first message | ### Summary
Instead of searching through a sea of commits, comments, and bots posting in the pull request thread preferably we would just edit the message in place with a link and a new section.
### Basic Example
See: https://github.com/python/devguide/pull/1300
### Drawbacks and Impact
_No response_
### Unresol... | open | 2024-04-02T04:30:04Z | 2025-03-20T15:54:32Z | https://github.com/litestar-org/litestar/issues/3304 | [
"Documentation :books:",
"Enhancement",
"Help Wanted :sos:",
"Good First Issue",
"Infrastructure",
"CI"
] | JacobCoffee | 2 |
pydata/xarray | pandas | 9,281 | Splitting out lazy indexing layer and backends layer as zarr-python features | ### What is your issue?
### **tl;dr: Could we factor out all of xarray's lazy indexing + backends as fully-featured virtual lazy zarr arrays?**
When you do `xr.open_dataset`, a few main things happen:
1) the data on disk is examined and a lazy representation built (which knows the data's `shape` and `dtype`)
2)... | open | 2024-07-26T03:11:01Z | 2024-08-07T20:29:06Z | https://github.com/pydata/xarray/issues/9281 | [
"topic-backends",
"topic-internals",
"topic-indexing",
"enhancement",
"topic-zarr",
"topic-arrays",
"topic-lazy array",
"topic-chunked-arrays"
] | TomNicholas | 3 |
clovaai/donut | computer-vision | 63 | inference speed is very slow on cpu for docvqa task and CUDA out of memory | it is taking almost 300 sec for single question on CPU
on gpu i am getting cuda out of memory
below are the configuration
NVIDIA GeForce RTX 2080 Ti
memory 11264 MiB | closed | 2022-09-29T13:05:16Z | 2022-11-16T13:40:39Z | https://github.com/clovaai/donut/issues/63 | [] | roburst2 | 1 |
Sanster/IOPaint | pytorch | 91 | prompt input box missing? | works on localhost but there is no prompt input box with lama model. do you need sd checkpoint? | closed | 2022-10-21T01:50:17Z | 2022-11-07T14:14:37Z | https://github.com/Sanster/IOPaint/issues/91 | [] | eformx | 1 |
STVIR/pysot | computer-vision | 111 | 我是个初学者,想请教下为什么SiamRPN论文中的section3.1中第一个模拟实验(shift等于0)时存在很大的center bias?shfit是什么?能解释下对一张图像shift意味着什么吗? | 我是个初学者,想请教下为什么section3.1中第一个模拟实验(shift等于0)时存在很大的center bias?shfit是什么?能解释下对一张图像shift意味着什么吗? | closed | 2019-07-16T12:39:48Z | 2019-12-18T15:49:55Z | https://github.com/STVIR/pysot/issues/111 | [
"good first issue"
] | FanOfJames | 2 |
Gerapy/Gerapy | django | 246 | docker germey/gerapy 镜像 cron 任务无法按时运行 | **Describe the bug**
A clear and concise description of what the bug is.
**To Reproduce**
Steps to reproduce the behavior:
1. Go to '...'
2. Click on '....'
3. Scroll down to '....'
4. See error
**Traceback**
Run time of job "execute (trigger: cron[hour='15', minute='59', second='0'], next run at: 2022-0... | closed | 2022-06-08T01:58:48Z | 2024-05-06T05:27:24Z | https://github.com/Gerapy/Gerapy/issues/246 | [
"bug"
] | InfernalAzazel | 0 |
koaning/scikit-lego | scikit-learn | 467 | [BUG] ZeroInflatedRegressor is not included in pip/conda package? | Hello, I would like to use ZeroInflatedRegressor, but after I installed scikit-lego from both pip and conda, there is import error like below.
`ImportError: cannot import name 'ZeroInflatedRegressor' from 'sklego.meta' `
It seems that the package does not include the `ZeroInflatedRegressor`.
Could I install the ... | closed | 2021-05-07T02:34:29Z | 2021-05-14T02:12:27Z | https://github.com/koaning/scikit-lego/issues/467 | [
"bug"
] | jeongwhanchoi | 1 |
pywinauto/pywinauto | automation | 540 | .click_input() coordination bug using rectangle().top or bottom | Using `.click_input()` with a `.rectangle()`'s top or bottom erroneously uses a higher value.
This only happens with `click_input`. I've noted (after reading the docs) that `click_input()` is similar to `mouse.click()` while the simple `click()` is doing some `WM_*` messages. Unfortunately there are elements I can't... | open | 2018-08-10T14:01:00Z | 2022-05-12T16:23:39Z | https://github.com/pywinauto/pywinauto/issues/540 | [
"bug"
] | meshuggahtas | 4 |
huggingface/text-generation-inference | nlp | 2,643 | How do you download a subfile? | ### System Info
Specifically: bartowski/NemoMix-Unleashed-12B-GGUF/NemoMix-Unleashed-12B-Q4_K_M.gguf
I tried:
```
command: --model-id bartowski/NemoMix-Unleashed-12B-GGUF/NemoMix-Unleashed-12B-Q4_K_M.gguf
```
but it failed.
### Information
- [X] Docker
- [ ] The CLI directly
### Tasks
- [ ] An officially supp... | open | 2024-10-14T02:05:06Z | 2024-10-16T18:44:28Z | https://github.com/huggingface/text-generation-inference/issues/2643 | [] | PeterTucker | 1 |
microsoft/unilm | nlp | 1,283 | Confused about lm_head in Beit2 model pretrain | **Describe**
Model I am using (beit2/model_pretrain):

On the line 130, the size of **x** shoule be (batch_size, patch_nums, embed_dim).
Turn to line 137, the size after **lm_head** should be (batch_size, masked_... | open | 2023-09-07T02:19:46Z | 2023-09-11T01:47:31Z | https://github.com/microsoft/unilm/issues/1283 | [] | ZhouZhichengSteven | 1 |
electricitymaps/electricitymaps-contrib | data-visualization | 7,581 | Detailed data for powerImportBreakdown and powerExportBreakdown | The /power-breakdown/latest?zone=XX endpoint returns these sub-objects as a part of the response:
```
...
"powerImportBreakdown": {
"FR": 3050,
"GR": 205
},
"powerExportBreakdown": {
"FR": 0,
"GR": 0
},
...
```
Could it be feasible to have a breakd... | open | 2024-12-19T08:08:48Z | 2025-03-06T08:25:00Z | https://github.com/electricitymaps/electricitymaps-contrib/issues/7581 | [] | fcalderan | 3 |
miguelgrinberg/Flask-Migrate | flask | 54 | new alembic version is 0.7.5.post1 breaks | With the new alembic version Flask-Migrate can't figure out what version alembic has.
```
$ ./manage.py
Traceback (most recent call last):
File "./manage.py", line 8, in <module>
from endor import MANAGER
File "/home/ffwi/endor/endor/__init__.py", line 16, in <module>
from flask.ext.migrate import Migrate... | closed | 2015-03-20T17:42:46Z | 2015-03-20T17:44:09Z | https://github.com/miguelgrinberg/Flask-Migrate/issues/54 | [] | XenGi | 1 |
serengil/deepface | deep-learning | 606 | Installation Issues | Failed to install via pip3.
Log:
`Collecting deepface
Downloading deepface-0.0.75-py3-none-any.whl (65 kB)
━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━ 65.0/65.0 kB 1.3 MB/s eta 0:00:00
Collecting numpy>=1.14.0
Downloading numpy-1.23.5-cp311-cp311-macosx_10_9_x86_64.whl (18.1 MB)
━━━━━━━━━━━━━━━━━━... | closed | 2022-11-21T12:41:30Z | 2023-01-20T16:09:48Z | https://github.com/serengil/deepface/issues/606 | [] | ashermyers | 5 |
flasgger/flasgger | flask | 616 | OpenAPI client generator docs link? | Hey there! I'm one of the maintainers of [openapi-ts](https://github.com/hey-api/openapi-ts), a package for turning the generated OpenAPI specs into TypeScript clients. Would you be open to including a section in README on generating clients from OpenAPI specs? FastAPI has a [similar section](https://fastapi.tiangolo.c... | open | 2024-04-03T11:15:37Z | 2024-06-02T23:21:47Z | https://github.com/flasgger/flasgger/issues/616 | [] | mrlubos | 3 |
roboflow/supervision | deep-learning | 679 | May I know where I can download tracking_result.mp4? | ### Search before asking
- [X] I have searched the Supervision [issues](https://github.com/roboflow/supervision/issues) and found no similar bug report.
### Bug
examples/tracking$ python script.py \
--source_weights_path yolov8s.pt \
--source_video_path input.mp4 \
--target_video_path tracking_result.mp4
Traceb... | closed | 2023-12-17T15:35:31Z | 2023-12-17T15:42:27Z | https://github.com/roboflow/supervision/issues/679 | [
"bug"
] | AK51 | 0 |
tflearn/tflearn | data-science | 217 | Freezing as TensorFlow graph | Hi,
I'm just wondering if it's possible to freeze a graph as a TensorFlow model, using
TensorFlow's FreezeGraph functionality, for instance:
```
def save_graph(sess,output_path,checkpoint,checkpoint_state_name,input_graph_name,output_graph_name):
checkpoint_prefix = os.path.join(output_path,checkpoint)
sav... | closed | 2016-07-21T15:59:05Z | 2017-09-24T11:33:41Z | https://github.com/tflearn/tflearn/issues/217 | [] | chrisruk | 7 |
pytorch/vision | computer-vision | 8,252 | Reading frames from VideoReader freezes eventually | ### 🐛 Describe the bug
The problem only occurs under some specific conditions:
1. The video backend is 'video_reader'
2. The VideoReader object is initialized with raw bytes rather than a path string
3. This byte buffer is loaded from an avi video file
Example code:
```
from torchvision.io import VideoReader
... | open | 2024-02-05T01:05:18Z | 2024-02-05T11:03:29Z | https://github.com/pytorch/vision/issues/8252 | [] | treasan | 1 |
pyro-ppl/numpyro | numpy | 2,000 | Running mcmc within jit might cause tracer leak | ### Bug Description
A part of https://github.com/pyro-ppl/numpyro/issues/1981
During MCMC run, we cache some functions so that later run might be faster. However, this might cause some leaks.
### Steps to Reproduce
```
JAX_CHECK_TRACER_LEAKS=1 pytest -vs test/infer/test_mcmc.py::test_chain_inside_jit
JAX_CHECK_TRACER... | open | 2025-03-07T00:43:21Z | 2025-03-07T00:43:21Z | https://github.com/pyro-ppl/numpyro/issues/2000 | [
"bug"
] | fehiepsi | 0 |
httpie/cli | rest-api | 611 | Set non-zero return code on error | This would be very convenient way to fail fast scripts that run with `-e`
This would be like `curl --fail` only without swallowing the output.
It looks that now the return code is always 0.
```
$ http -v PUT invalid://httpbin.org/put API-Key:foo hello=world
http: error: InvalidSchema: No connection adapter... | closed | 2017-09-20T13:02:43Z | 2017-09-20T13:28:00Z | https://github.com/httpie/cli/issues/611 | [] | jakub-bochenski | 2 |
Avaiga/taipy | automation | 1,619 | [🐛 BUG] Creating a new scenario in the scenario selector with *on_creation* should select it | **Problem**: When I create a new scenario with the *on_creation* callback, I start editing its properties. Since the new scenario was not selected when I created it, I edited the properties of a previously selected scenario.
**Expected behavior:**
Creating a new scenario through the scenario selector and with *on_... | closed | 2024-07-31T09:52:50Z | 2024-08-08T16:28:20Z | https://github.com/Avaiga/taipy/issues/1619 | [
"📈 Improvement",
"🖰 GUI",
"🟩 Priority: Low"
] | FlorianJacta | 0 |
microsoft/nni | data-science | 5,670 | NNI install in development mode on macOS M1 | I install nni from soruce code in development mode on apple M1 by following instructions from https://nni.readthedocs.io/en/stable/notes/build_from_source.html
After install, I can import nni successfully.
However, when I try some simple NAS tutorial in here https://nni.readthedocs.io/en/stable/tutorials/hello_n... | open | 2023-08-24T19:57:07Z | 2023-10-25T14:08:56Z | https://github.com/microsoft/nni/issues/5670 | [] | XiaochunLiu | 1 |
influxdata/influxdb-client-python | jupyter | 347 | query_data_frame with many columns throws Pandas PerformanceWarning | <!--
Thank you for reporting a bug.
* Please add a :+1: or comment on a similar existing bug report instead of opening a new one.
* https://github.com/influxdata/influxdb-client-python/issues?utf8=%E2%9C%93&q=is%3Aissue+is%3Aopen+is%3Aclosed+sort%3Aupdated-desc+label%3Abug+
* Please check whether the bug c... | closed | 2021-10-17T23:35:09Z | 2021-10-20T12:29:36Z | https://github.com/influxdata/influxdb-client-python/issues/347 | [
"enhancement"
] | sjamesc | 1 |
graphql-python/graphene-django | graphql | 1,036 | Cannot make django abstract class to work | Hello !
I'm trying to have a unique interface for two concrete classes that are similar and inherit from a common abstract class.
My django model classes:
```python
class Metadata(models.Model):
name = models.CharField(max_length=255)
sequence = models.PositiveSmallIntegerField()
is_choices = Fals... | closed | 2020-09-11T11:06:52Z | 2020-09-19T09:38:32Z | https://github.com/graphql-python/graphene-django/issues/1036 | [
"🐛bug"
] | remje | 3 |
Yorko/mlcourse.ai | seaborn | 640 | Mistake in assignment 8 | There is no true formula for updating weights using gradient descent:
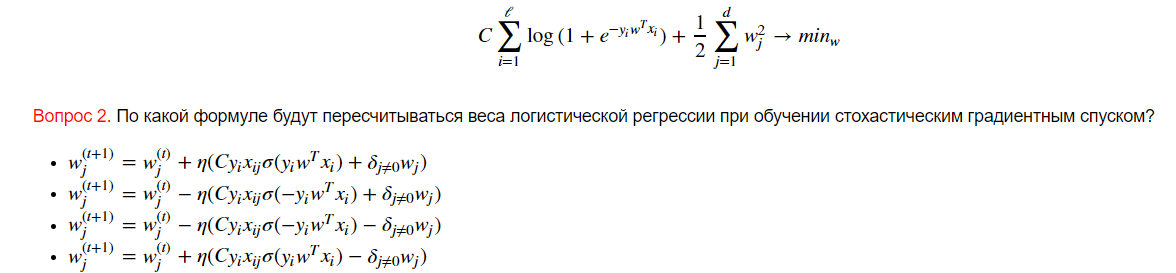
Right formula is:
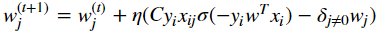
... | closed | 2019-10-30T22:11:54Z | 2019-11-04T14:09:57Z | https://github.com/Yorko/mlcourse.ai/issues/640 | [
"enhancement"
] | Ecclesiast | 1 |
recommenders-team/recommenders | machine-learning | 1,915 | [ASK] Multinomial VAE not working | ### Description
<!--- Describe your general ask in detail -->
I am running Multinomial VAE on movielens 1m dataset as given in the [example notebook](https://github.com/microsoft/recommenders/blob/main/examples/02_model_collaborative_filtering/multi_vae_deep_dive.ipynb) but getting an error when fitting the model. Th... | open | 2023-04-07T04:52:05Z | 2023-08-30T16:35:12Z | https://github.com/recommenders-team/recommenders/issues/1915 | [
"help wanted"
] | kone807 | 4 |
ageitgey/face_recognition | python | 1,071 | Training from multiple photos per identity | I would like to ask, is it necessary and OK to train for multiple photos per identity. For example, I have 5 distinct person and each one has 10 photos.
How do i pass multiple photos for training?
``
source_image = face_recognition.load_image_file(f)
all_face_encodings[individual_name] = face_recognition.face... | open | 2020-02-26T11:04:54Z | 2020-03-05T12:33:40Z | https://github.com/ageitgey/face_recognition/issues/1071 | [] | tetrahydra | 1 |
keras-team/keras | machine-learning | 20,191 | ops.image.affine_transform() does not work as a layer in GPU | Hi,
I notice ops.image.affine_transform() does not work as part of a model in GPU
TF version: 2.16.1
keras version: 3.5.0
Some observations from some testing
1. model.predict_step() works, but model.predict() does not
2. it works if using CPU only
3. other similar functions such as ops.image.resize(), ops.... | open | 2024-08-30T22:55:19Z | 2024-09-18T14:24:19Z | https://github.com/keras-team/keras/issues/20191 | [
"stat:awaiting keras-eng",
"type:Bug"
] | kwchan7 | 5 |
nolar/kopf | asyncio | 981 | Adjust log level of `TemporaryError`possible? | ### Keywords
temporaryerror, retry, handler
### Problem
Thanks for this great framework! :+1:
I am using `TemporaryError` throughout my operator quite a lot. I have a few long-running tasks which I don't want to eagerly watch, so I raise `TemporaryError` if certain conditions aren't met (yet). Basically, just li... | open | 2022-11-21T15:54:24Z | 2022-11-21T15:54:24Z | https://github.com/nolar/kopf/issues/981 | [
"question"
] | Schille | 0 |
jupyter-incubator/sparkmagic | jupyter | 566 | Sparkmagic session dies if cell runs longer than `livy.server.session.timeout` | Hello - I'm using sparkmagic to execute long-running spark jobs, and running into an issue where the sparkmagic livy session dies if the submitted spark job runs longer than the configured livy.server.session.timeout. The error manifests as the usual:
```
An error was encountered:
Invalid status code '404' from http... | closed | 2019-09-04T17:24:18Z | 2019-09-27T16:20:15Z | https://github.com/jupyter-incubator/sparkmagic/issues/566 | [
"kind:bug"
] | jpugliesi | 6 |
ading2210/poe-api | graphql | 135 | How deploy this project on Vercel | What role does this piece of code play in poe.py? Will there be any errors if I delete this code? Because I want to deploy this project on Vercel, but this code needs to write files locally, which leads to its incorrect execution on Vercel.
` if self.device_id is None:
self.device_id = self.get_device_... | open | 2023-06-30T06:44:08Z | 2023-07-01T14:48:44Z | https://github.com/ading2210/poe-api/issues/135 | [
"bug"
] | win4r | 1 |
vllm-project/vllm | pytorch | 14,398 | [Installation]: | ### Your current environment
```text
error: could not create 'build\bdist.win-amd64\wheel\.\vllm\model_executor\layers\quantization\utils\configs\N=1536,K=1536,device_name=AMD_Instinct_MI300X,dtype=fp8_w8a8,block_shape=[128,128].json': No such file or directory
[end of output]
note: This error originate... | open | 2025-03-07T02:22:22Z | 2025-03-20T03:35:43Z | https://github.com/vllm-project/vllm/issues/14398 | [
"installation"
] | catn1pdeal3r | 5 |
pyro-ppl/numpyro | numpy | 1,559 | Support checking for Multinomial is unnecessarily multidimensional | A multidimensional array is constructed when checking the support for a multinomial with total count broadcasted across multidimensional probs or logits.
```python
mixing_dist = dist.CategoricalProbs(
probs=np.array([0.4, 0.1, 0.1, 0.1, 0.1])
)
component_dist = dist.MultinomialProbs(
total_count=jnp.array... | closed | 2023-03-20T20:07:47Z | 2023-03-27T21:13:14Z | https://github.com/pyro-ppl/numpyro/issues/1559 | [
"question"
] | aravikumar0 | 2 |
dpgaspar/Flask-AppBuilder | rest-api | 2,055 | Charts in FAB where the model returns a series | I'm trying to work out how to correctly structure my model so that I can graph out a simply line (or bar) graph. The data model for the table is roughly like this:
```
class Birds(Model):
id = Column(String(100), primary_key=True, nullable=False) # this is the id of the observation, 1 per day
created = C... | open | 2023-06-09T16:49:12Z | 2023-06-09T16:49:23Z | https://github.com/dpgaspar/Flask-AppBuilder/issues/2055 | [] | aodj | 0 |
iMerica/dj-rest-auth | rest-api | 322 | ModuleNotFoundError: No module named 'dj_rest_authcore' => dj-rest-auth | I have followed the documentation(https://dj-rest-auth.readthedocs.io/en/latest/installation.html).
Installed the package using `pip install dj-rest-auth`
Added dj_rest_auth app to INSTALLED_APPS in your django settings.py:
Added `path('dj-rest-auth/', include('dj_rest_auth.urls'))` in urls.py
When I am doi... | closed | 2021-10-22T04:56:28Z | 2021-10-24T14:25:00Z | https://github.com/iMerica/dj-rest-auth/issues/322 | [] | shakthifuture | 1 |
google-research/bert | nlp | 367 | Fine-tune with TriviaQA | For fine-tune with TriviaQA on question answering task mentioned in README, TriviaQA set from wiki or TriviaQA set from web or both should be used? | open | 2019-01-15T15:03:27Z | 2019-01-15T15:04:16Z | https://github.com/google-research/bert/issues/367 | [] | bcbcbcbcbcl | 0 |
waditu/tushare | pandas | 798 | 获取财务指标数据的接口pro.fina_indicator,文档说ts_code不是必须的,但是如果接口不传递ts_code会报缺少该参数的错误。 | 文档中给出的不传递ts_code的例子也不能通过运行。 | closed | 2018-11-03T08:11:18Z | 2018-11-05T03:23:46Z | https://github.com/waditu/tushare/issues/798 | [] | jianmo-lc | 1 |
gradio-app/gradio | deep-learning | 10,771 | API recorder very broken on chats | ### Describe the bug
The API recorder doesn't work on ChatInterface. Instead of returning the chat API, it returns other APIs, but it doesn't seem to know how to call any of them.
### Have you searched existing issues? 🔎
- [x] I have searched and found no existing issues
### Reproduction
```python
import gradi... | closed | 2025-03-10T14:10:49Z | 2025-03-10T15:57:36Z | https://github.com/gradio-app/gradio/issues/10771 | [
"bug"
] | edmcman | 1 |
gee-community/geemap | jupyter | 618 | Get current device location | This feature allows users to get the current device location (i.e., lat-lon) and zoom the map to the current location, similar to what Google Maps provides. https://github.com/giswqs/geemap-heroku/issues/1#issuecomment-898390398
| closed | 2021-08-13T11:52:28Z | 2021-08-13T12:13:15Z | https://github.com/gee-community/geemap/issues/618 | [
"Feature Request"
] | giswqs | 1 |
AutoViML/AutoViz | scikit-learn | 35 | The title part at the top of the output image is cut off | When using `vervose=2` to output an `svg` or `png` file, there is an issue where the top title part is cut off.
There seems to be a problem with the `height` value setting, please check. | closed | 2021-01-14T12:20:43Z | 2023-04-17T11:36:18Z | https://github.com/AutoViML/AutoViz/issues/35 | [] | beobest2 | 3 |
mljar/mljar-supervised | scikit-learn | 754 | user warning in test: tests/tests_automl/test_targets.py::AutoMLTargetsTest::test_regression_missing_target | ```
============================= test session starts ==============================
platform linux -- Python 3.12.3, pytest-8.3.2, pluggy-1.5.0 -- /home/adas/mljar/mljar-supervised/venv/bin/python3
cachedir: .pytest_cache
rootdir: /home/adas/mljar/mljar-supervised
configfile: pytest.ini
plugins: cov-5.0.0
colle... | closed | 2024-08-23T09:32:18Z | 2024-09-02T08:12:20Z | https://github.com/mljar/mljar-supervised/issues/754 | [] | a-szulc | 0 |
man-group/arctic | pandas | 332 | unable to install arctic on windows machine. |
#### Arctic Version
1.41
```
# Arctic version here
```
#### Arctic Store
```
# VersionStore, TickStore, or ChunkStore
```
#### Platform and version
Windows 7 Professional, 64 bit
#### Description of problem and/or code sample that reproduces the issue
Hi Team, running into some issues with the... | closed | 2017-03-06T14:22:01Z | 2017-03-06T14:28:36Z | https://github.com/man-group/arctic/issues/332 | [] | kwtneo | 3 |
microsoft/unilm | nlp | 1,466 | Broken link, Can't download the checkpoints associated with the Text Detection task for DiT | **Describe the bug**
Model I am using (UniLM, MiniLM, LayoutLM ...): DiT
The problem arises when using:
* [ ] the official example scripts:
Can't download the checkpoints associated with the Text Detection task.
A clear and concise description of what the bug is.
When trying to download checkpoints and ... | closed | 2024-02-20T09:59:58Z | 2024-04-18T16:14:35Z | https://github.com/microsoft/unilm/issues/1466 | [] | rm-asif-amin | 2 |
cleanlab/cleanlab | data-science | 957 | fix tutorials based on dev dependencies, update pinned versions of dependences in CI | CI dependencies should all be pinned to recent versions here:
https://github.com/cleanlab/cleanlab/blob/master/docs/requirements.txt
And tutorials' code updated to ensure these latest package versions work | closed | 2024-01-16T17:30:48Z | 2024-02-07T21:56:09Z | https://github.com/cleanlab/cleanlab/issues/957 | [
"next release",
"needs triage"
] | jwmueller | 1 |
lux-org/lux | jupyter | 480 | AttributeError: 'LuxDataFrame' object has no attribute '_type_override' | I am trying to specify an intent (df.intent = ['PERS_WGT_NUM']). I have been successful with other datasets. However, with my current dataset I am getting the following error:
AttributeError: 'LuxDataFrame' object has no attribute '_type_override'
Any help would be appreciated. Thank you. | open | 2022-06-02T16:59:54Z | 2022-06-02T16:59:54Z | https://github.com/lux-org/lux/issues/480 | [] | MaryDonovanMartello | 0 |
jmcnamara/XlsxWriter | pandas | 149 | Format set_align | Hi,
reading the doc I had the feeling that the good practice for creating Format object is by calling the add_format method with a dictionary, is that correct?
But with this method I don't know how to specify alignment center and vcenter:
``` python
format = ws.add_format({'align':'center', 'align':'vcenter'})
# but t... | closed | 2014-08-13T14:56:21Z | 2014-08-13T15:40:15Z | https://github.com/jmcnamara/XlsxWriter/issues/149 | [
"question"
] | m3tr0 | 2 |
django-import-export/django-import-export | django | 1,964 | Tablib 3.7.0 support? | tablib 3.7.0 has been released a few days ago. Shall we update our dependency to use it? | closed | 2024-10-11T17:53:05Z | 2024-10-11T18:28:19Z | https://github.com/django-import-export/django-import-export/issues/1964 | [
"question"
] | jameslao | 2 |
sczhou/CodeFormer | pytorch | 27 | I can't improve the photo | 


### Steps to Reproduce
I am getting an error:
"Could not restore project backup.
KeyError: "There is no item named 'project.json' in the archive... | closed | 2024-10-04T10:35:46Z | 2024-10-07T13:06:53Z | https://github.com/cvat-ai/cvat/issues/8508 | [
"bug"
] | pavelorlovyeah | 2 |
miguelgrinberg/flasky | flask | 332 | ImportError: No module named dotenv(when I run in python3.6 and python2.7) | Traceback (most recent call last):
File "/usr/local/bin/flask", line 11, in <module>
sys.exit(main())
File "/usr/local/lib/python2.7/site-packages/flask/cli.py", line 478, in main
cli.main(args=args, prog_name=name)
File "/usr/local/lib/python2.7/site-packages/flask/cli.py", line 345, in main
re... | closed | 2018-01-15T18:22:15Z | 2022-02-16T07:53:38Z | https://github.com/miguelgrinberg/flasky/issues/332 | [
"question"
] | Alexcn | 12 |
httpie/cli | python | 677 | HTTPie fails inside of AWS EC2 User Data init script | ## Issue Overview
When I run the following httpie command interactively, it works fine:
```
http --download --output /tmp/pwsh.deb https://github.com/PowerShell/PowerShell/releases/download/v6.0.2/powershell_6.0.2-1.ubuntu.16.04_amd64.deb
```
However, when I run the same command in an Amazon Web Services (AW... | closed | 2018-05-04T17:14:43Z | 2020-05-23T18:46:37Z | https://github.com/httpie/cli/issues/677 | [] | pcgeek86 | 3 |
Subsets and Splits
No community queries yet
The top public SQL queries from the community will appear here once available.