
repo_name stringlengths 9 75 | topic stringclasses 30
values | issue_number int64 1 203k | title stringlengths 1 976 | body stringlengths 0 254k | state stringclasses 2
values | created_at stringlengths 20 20 | updated_at stringlengths 20 20 | url stringlengths 38 105 | labels listlengths 0 9 | user_login stringlengths 1 39 | comments_count int64 0 452 |
|---|---|---|---|---|---|---|---|---|---|---|---|
PaddlePaddle/ERNIE | nlp | 181 | 使用run_sequence_labeling报错 | I0628 17:59:50.612715 1562 build_strategy.cc:285] SeqOnlyAllReduceOps:0, num_trainers:1
Traceback (most recent call last):
File "run_sequence_labeling.py", line 283, in <module>
main(args)
File "run_sequence_labeling.py", line 203, in main
dev_count)
File "/home/wangzs/ERNIE/finetune/sequence_label... | closed | 2019-06-28T10:07:28Z | 2019-06-28T10:07:51Z | https://github.com/PaddlePaddle/ERNIE/issues/181 | [] | wzs951015 | 0 |
dynaconf/dynaconf | flask | 1,234 | feat: Add debug info CLI command | Right now the output of inspect is
```json
{
"header": {
"env_filter": "None",
"key_filter": "KEY",
"new_first": "True",
"history_limit": "None",
"include_internal": "False"
},
"current": 1,
"history": [
{
"loader": "settings_loader",
"identifier": "/src/test_app/defaults",
... | closed | 2025-02-04T11:37:07Z | 2025-02-14T16:33:15Z | https://github.com/dynaconf/dynaconf/issues/1234 | [
"Not a Bug",
"RFC"
] | rochacbruno | 0 |
glumpy/glumpy | numpy | 266 | Trackball default angles | I believe there is a mistake at
https://github.com/glumpy/glumpy/blob/77ee22a1e7691aea4856c075edbd77c94727b891/glumpy/transforms/trackball.py#L91
I think it should be
``
self._trackball = _trackball.Trackball(theta,phi)
``
this code prints 45 45
``
points['transform'] = Trackball(Position("position"), theta... | open | 2020-10-26T15:43:36Z | 2020-11-02T15:44:33Z | https://github.com/glumpy/glumpy/issues/266 | [] | HukamiEstia | 1 |
amdegroot/ssd.pytorch | computer-vision | 427 | only 1 class label | how should i define the class index if i have only a single class: {plane (VOC format)}
Currently, I have define VOC_CLASSES = [('plane')] {line 20} and self.class_to_ind = dict(plane=0) {line45} in voc0712.py like this. Is it correct? I can run with this code but my AP is always 0 ,so i'm not sure is this the proble... | open | 2019-11-01T05:11:12Z | 2020-07-22T14:52:59Z | https://github.com/amdegroot/ssd.pytorch/issues/427 | [] | teepakorn123 | 3 |
tortoise/tortoise-orm | asyncio | 854 | How to handle changes in models? | Does tortoise automatically add a column whenever an already generated model (database table) has been updated? Or do I have to write code to make the change myself and or state the change in my library documentation. Thanks! | closed | 2021-08-05T01:56:27Z | 2021-08-11T23:43:46Z | https://github.com/tortoise/tortoise-orm/issues/854 | [] | na-stewart | 7 |
BeanieODM/beanie | asyncio | 204 | alias failed in projection | ```
class TokenView(BaseModel):
token: str
class UserModel(Document):
uid: PydanticObjectId = Field(alias="user")
token: str = Field(alias="key")
>>> t = await UserModel.find_one(UserModel.token == token).project(TokenView)
pydantic.error_wrappers.ValidationError: 1 validation errors for ... | closed | 2022-02-14T11:03:30Z | 2022-03-10T06:30:52Z | https://github.com/BeanieODM/beanie/issues/204 | [] | lsaint | 2 |
miguelgrinberg/Flask-SocketIO | flask | 1,088 | access to the socket object | I would love to get access to the whole socket object like you do with nodejs socket.io it makes life a lot easier. Like getting the socket object as a parameter like in nodejs. If its in json it be all the better that would be great. Please consider this in the project. Thank you | closed | 2019-10-27T19:53:51Z | 2020-01-19T18:44:23Z | https://github.com/miguelgrinberg/Flask-SocketIO/issues/1088 | [
"question"
] | nh916 | 3 |
Farama-Foundation/Gymnasium | api | 409 | [Question] Segmentation fault (core dumped) | ### Question

When I run : env = gym.make("FrozenLake-v1") and reset the env,
report error: Segmentation fault (core dumped), actually all the envs have the same question.
my environment: ubuntu16.04 & pyt... | closed | 2023-03-28T11:21:23Z | 2023-07-14T15:08:43Z | https://github.com/Farama-Foundation/Gymnasium/issues/409 | [
"question"
] | TongYan1999 | 5 |
seleniumbase/SeleniumBase | pytest | 3,356 | does SeleniumBase provide a method similar to getTargets()? |
does SeleniumBase provide a method similar to getTargets()?
https://www.selenium.dev/selenium/docs/api/java/org/openqa/selenium/devtools/idealized/target/Target.html#getTargets() | closed | 2024-12-20T15:47:00Z | 2024-12-20T17:37:19Z | https://github.com/seleniumbase/SeleniumBase/issues/3356 | [
"question",
"UC Mode / CDP Mode"
] | quyunet | 1 |
streamlit/streamlit | data-visualization | 10,645 | Row hover effect in `st.dataframe` is barely visible | ### Checklist
- [x] I have searched the [existing issues](https://github.com/streamlit/streamlit/issues) for similar issues.
- [x] I added a very descriptive title to this issue.
- [x] I have provided sufficient information below to help reproduce this issue.
### Summary
The row hover effect introduced in #10104 is ... | open | 2025-03-05T08:25:01Z | 2025-03-05T13:26:36Z | https://github.com/streamlit/streamlit/issues/10645 | [
"type:enhancement",
"feature:st.dataframe"
] | VERBOSE-01 | 6 |
huggingface/datasets | pandas | 6,689 | .load_dataset() method defaults to zstandard | ### Describe the bug
Regardless of what method I use, datasets defaults to zstandard for unpacking my datasets.
This is poor behavior, because not only is zstandard not a dependency in the huggingface package (and therefore, your dataset loading will be interrupted while it asks you to install the package), but it ... | closed | 2024-02-22T17:39:27Z | 2024-03-07T14:54:16Z | https://github.com/huggingface/datasets/issues/6689 | [] | ElleLeonne | 4 |
tflearn/tflearn | data-science | 1,144 | how to update from version1 to version2 in tensorflow | I have NN model in tesorflow1.14 but i want to update as per tensorflow2 but how can i do i am facing problem. I read tensorflow website but not useful or get idea for my code.
# Build neural network
net = tflearn.input_data(shape=[None, len(train_x[0])])
net = tflearn.fully_connected(net, 8)
net = tflea... | open | 2020-01-10T06:48:08Z | 2020-01-10T06:48:08Z | https://github.com/tflearn/tflearn/issues/1144 | [] | messi313 | 0 |
liangliangyy/DjangoBlog | django | 433 | Error | <!--
如果你不认真勾选下面的内容,我可能会直接关闭你的 Issue。
提问之前,建议先阅读 https://github.com/ruby-china/How-To-Ask-Questions-The-Smart-Way
-->
**我确定我已经查看了** (标注`[ ]`为`[x]`)
- [ ] [DjangoBlog的readme](https://github.com/liangliangyy/DjangoBlog/blob/master/README.md)
- [ ] [配置说明](https://github.com/liangliangyy/DjangoBlog/blob/master/bin... | closed | 2020-11-17T04:57:29Z | 2020-11-20T16:40:04Z | https://github.com/liangliangyy/DjangoBlog/issues/433 | [] | ghost | 0 |
ageitgey/face_recognition | python | 1,241 | print | How i can print percentage of compare of two faces? | closed | 2020-11-08T20:05:19Z | 2020-11-11T10:21:57Z | https://github.com/ageitgey/face_recognition/issues/1241 | [] | sk3lk0 | 1 |
Zeyi-Lin/HivisionIDPhotos | machine-learning | 50 | 大佬加油,美颜换装好了,我就把我证件照小程序后台接口对接这个 | open | 2024-09-05T02:45:03Z | 2024-09-05T03:31:32Z | https://github.com/Zeyi-Lin/HivisionIDPhotos/issues/50 | [] | mark420524 | 1 | |
Netflix/metaflow | data-science | 1,738 | Add option to batch decorator to increase ephemeralStorage on Fargate | It would be good to have an option to vary the ephemeral storage that a batch job needs on Fargate, since the default (20GB) is relatively low for our needs, and there is no other option on Fargate to increase storage (tmpfs is not an option). Further conversation about this is available on the [ask-metaflow chat](http... | open | 2024-02-16T10:06:23Z | 2024-02-16T10:06:23Z | https://github.com/Netflix/metaflow/issues/1738 | [] | stev-0 | 0 |
Lightning-AI/pytorch-lightning | data-science | 20,558 | Error: torch.cuda.OutOfMemoryError: CUDA out of memory. Tried to allocate more than 1EB memory | ### Bug description
I’m using pytorch lighting DDP training with batch size = 16, 8 (gpu per node) * 2 (2 nodes) = 16 total gpus. However, I got the following
error, which happens in ModelCheckpoint callback. There seems to be an error during synchronization between nodes when saving the model checkpoint. And I decrea... | open | 2025-01-22T11:49:59Z | 2025-01-22T11:50:16Z | https://github.com/Lightning-AI/pytorch-lightning/issues/20558 | [
"bug",
"needs triage",
"ver: 2.3.x"
] | Neronjust2017 | 0 |
unit8co/darts | data-science | 2,384 | [BUG] TSMixer TimeBatchNorm2d using BatchNorm instead of LayerNorm | **Describe the bug**
TSMixer implementation overall uses `LayerNorm` and doesn't give a `BatchNorm` option. In the paper it was shortly mentioned that the `LayerNorm` gave better results on smaller batches. However, the `TimeBatchNorm2d` implementation bases `BatchNorm2d` which in my tests has been unstable agreeing ... | closed | 2024-05-17T00:24:41Z | 2024-08-28T07:07:22Z | https://github.com/unit8co/darts/issues/2384 | [
"improvement"
] | tRosenflanz | 7 |
amidaware/tacticalrmm | django | 1,922 | [Feature request] duplicate webhook | **Is your feature request related to a problem? Please describe.**
impossible to easily duplicate a webhook without doing a few copy and paste and this is a bit of a paradox as every hook currently need to be duplicated for FAIL and OK
**Describe the solution you'd like**

| open | 2024-02-26T15:56:09Z | 2024-02-26T15:56:09Z | https://github.com/OpenBB-finance/OpenBB/issues/6126 | [] | jenil1122 | 0 |
serengil/deepface | deep-learning | 1,400 | Suggestion to improve face alignment performance in extract_faces() | ### Description
First of all, I want to say thank you for creating and maintaining **DeepFace**. It’s a very useful and convenient framework.
While using the `extract_faces()` function, I noticed that when `alignment=True`, the _confidence_ of the detection results and overall performance are negatively impacted, e... | closed | 2024-12-17T17:48:00Z | 2024-12-18T17:12:13Z | https://github.com/serengil/deepface/issues/1400 | [
"enhancement"
] | huulockt | 4 |
BoltzmannEntropy/xtts2-ui | streamlit | 28 | AssertionError: Torch not compiled with CUDA enabled | I did everything in the README.
(I am using CPU only)
When running python app.py I get: AssertionError: Torch not compiled with CUDA enabled
| open | 2024-06-06T09:20:46Z | 2024-08-21T10:22:27Z | https://github.com/BoltzmannEntropy/xtts2-ui/issues/28 | [] | 0wwafa | 2 |
Gozargah/Marzban | api | 1,472 | Crucial bug [Dev version] | Latest dev version broke my ws+tls configs , client apps doesn't recognize host and path even if the field is not empty in panel (doesn't matter in host settings or core settings )
After it happened in my main server , I tested it with a fresh new server and same issue happened again .
Downgrading to latest version f... | closed | 2024-12-02T01:57:50Z | 2024-12-02T15:44:30Z | https://github.com/Gozargah/Marzban/issues/1472 | [] | NotaNerd021 | 7 |
jazzband/django-oauth-toolkit | django | 589 | Release new version to PyPI to address bad default value for RefreshToken `revoked` | The version on pypi (1.1.0) contains a critical bug that invalidates all refresh tokens when running a migration, and is NOT noted in the changelog. This was corrected in a follow-up pull request, but was not released yet.
https://github.com/jazzband/django-oauth-toolkit/commit/83ec4ac1e774641670d4641483e622f9b60b50... | closed | 2018-05-08T02:38:55Z | 2018-05-08T11:33:44Z | https://github.com/jazzband/django-oauth-toolkit/issues/589 | [] | wli | 2 |
LibrePhotos/librephotos | django | 855 | Failure reading exif tags: Multiple tag issues returned, invalid use case | # 🛑 Before you create an issue make sure that:
- Your issue is **strictly related to LibrePhotos** itself. Questions about setting up a reverse proxy belong in what ever reverse proxy you are using.
- You have read the [documentation](https://docs.librephotos.com) thoroughly.
- You have searched for a similar issu... | closed | 2023-05-15T09:23:03Z | 2023-05-15T11:40:51Z | https://github.com/LibrePhotos/librephotos/issues/855 | [
"bug"
] | ChrisFab16 | 1 |
cvat-ai/cvat | pytorch | 8,525 | The server down? |

| closed | 2024-10-10T07:04:50Z | 2024-10-10T07:30:46Z | https://github.com/cvat-ai/cvat/issues/8525 | [] | SeanChia76 | 1 |
Lightning-AI/pytorch-lightning | pytorch | 19,952 | Class name displayed incorrectly | ### 📚 Documentation
### 📚 The doc issue
Hello everyone,
I found what initially looked like a typo in the docs. But it seems like a problem with displaying the text, because it show up correctly when copy-pasting the text. The problem showed up in the two browsers (Edge and Firefox) that I tested.
,when i run it with reload mode, i found it load model twice and cause OOM error.
after testing, i found when run the code with `gradio xxx.py` reload mode, the code outside main will run twice, i have a demo from office ... | closed | 2024-10-29T07:46:47Z | 2024-11-04T21:50:53Z | https://github.com/gradio-app/gradio/issues/9865 | [
"bug"
] | phoenixor | 3 |
15r10nk/inline-snapshot | pytest | 132 | time-machine test dependency is problematic for PyPy3 | I'm sorry to be bothering you but the `time-machine` test dependency that is present right now makes it impossible to run over 200 tests on PyPy3. `time-machine` relies on patching internals of CPython's `_datetime` implementation, and as such is not installable on PyPy3 at all.
Could you please consider using e.g. ... | closed | 2024-11-07T17:36:17Z | 2024-11-11T12:22:10Z | https://github.com/15r10nk/inline-snapshot/issues/132 | [] | mgorny | 6 |
indico/indico | sqlalchemy | 6,673 | Visualization issue with event title in event management area | **Describe the bug**
Event title in the event management area is not displayed properly. The text overlaps and is somehow cropped. On the screenshot you can see that the conference title is long and doesn't fit on one line. The second line of the title is displayed too close to the first line and they overlap, see arr... | open | 2024-12-14T09:51:15Z | 2024-12-19T04:33:12Z | https://github.com/indico/indico/issues/6673 | [
"bug"
] | markpolyak | 5 |
assafelovic/gpt-researcher | automation | 469 | Error 422 without details | I'm trying to implement a Tavily search tool in my LangGraph graph, but it gives me an 422 error. So I tried a very basic stand alone version, but I still get this error. Unfortunately I don't get any specific information and looking at the API docs I have the feeling nothing is wrong with the input data. Btw I also ge... | closed | 2024-05-06T04:38:47Z | 2024-05-07T14:13:30Z | https://github.com/assafelovic/gpt-researcher/issues/469 | [] | guidorietbroek | 1 |
CorentinJ/Real-Time-Voice-Cloning | deep-learning | 715 | No Visualizations appear at visdom while training | I started the server then i started training in another process but no visualizations appear while training as in the training instructions
| closed | 2021-03-29T09:32:16Z | 2021-04-01T01:08:58Z | https://github.com/CorentinJ/Real-Time-Voice-Cloning/issues/715 | [] | mennatallah644 | 1 |
fedspendingtransparency/usaspending-api | pytest | 3,768 | IMLS sub-agency appears twice | This looks like a data bug somewhere - the agency IMLS has 2 sub-agency with identical name and abbreviations. Curiously the award/transaction numbers differ however, so it seems like it does have 2 records somewhere.
```
curl -s 'https://api.usaspending.gov/api/v2/agency/474/sub_agency/' | jq
{
"toptier_code":... | open | 2023-03-29T04:30:42Z | 2023-03-29T04:30:59Z | https://github.com/fedspendingtransparency/usaspending-api/issues/3768 | [] | grugnog | 0 |
JoeanAmier/TikTokDownloader | api | 263 | ValueError:unknown url type: '/' [12340]Failed toexecutescript’'main' due to unhandled exception! | TikTokDownloader 5.4 downloaded for a while and then just crashed.
Traceback (most recent call 1ast):
File"main.py",line 1l,in<module>
File "asyncio\runners.py",1ine 194, in run
File "asyncio\runners. py”, line 118, in run
File"asyncio\base_events.py", 1ine 687, in run_until_complete
File "main.py”, line 7, in ... | open | 2024-07-26T17:27:53Z | 2024-07-27T01:35:18Z | https://github.com/JoeanAmier/TikTokDownloader/issues/263 | [] | LaneElenex1 | 1 |
mlfoundations/open_clip | computer-vision | 237 | Training open_clip with custom text and image encoder | I understand you can specify `--model` while training open clip if you want to use a different image or text encoder.
But I want to use custom image AND text encoder simultaneously to train the open clip model. How do I specify both?
FYI - I have the weights of those model. Might also explore picking up something... | open | 2022-11-19T16:08:03Z | 2023-01-07T21:37:50Z | https://github.com/mlfoundations/open_clip/issues/237 | [
"new feature",
"important"
] | nahidalam | 6 |
simple-login/app | flask | 1,978 | Hotel | Hotel app | open | 2023-12-22T00:35:23Z | 2024-01-10T18:29:19Z | https://github.com/simple-login/app/issues/1978 | [] | Preet0330 | 1 |
joeyespo/grip | flask | 101 | Password/Token message written to STDOUT | `v3.2.0`
I'm using a pipeline like
``` bash
grip --export README.md - | wkhtmltopdf - README.pdf
```
to build a PDF. I have set my access token in `~/.grip/settings.py` but the info message appears in the output. My workaround:
``` bash
grip --export README.md - | grep -v "Using personal access token" \
| wkh... | closed | 2015-03-07T15:46:41Z | 2015-03-21T04:08:09Z | https://github.com/joeyespo/grip/issues/101 | [
"bug",
"contributor-friendly"
] | fergusg | 0 |
ResidentMario/missingno | pandas | 95 | vmin/vmax argument of heatmap() does not seem to have an effect + throws error | Hi,
according to the source code, the color scale of heatmap() is automatically adjusted to range from -1 to 1 by vmin/vmax. However, this does not seem to work. My data set features correlations only down to -0.1, but they are marked in deep red.
Setting the parameters explicitly throws an error:
```
heatmap... | closed | 2019-08-02T07:46:38Z | 2019-08-04T16:30:16Z | https://github.com/ResidentMario/missingno/issues/95 | [] | moritzkoerber | 3 |
ydataai/ydata-profiling | data-science | 1,142 | Feature Request: change variables in the interaction field with arrow keys | ### Missing functionality
Currently, to change the variable,
one has to use the mouse.
But a convenient way to change the variable would be with the arrow keys.
### Proposed feature
Change variable with arrow keys in the interaction view
### Alternatives considered
_No response_
### Additional context
_No resp... | open | 2022-11-10T14:49:36Z | 2023-09-19T02:40:03Z | https://github.com/ydataai/ydata-profiling/issues/1142 | [
"feature request 💬",
"getting started ☝"
] | m-a-r-o-u | 4 |
xlwings/xlwings | automation | 2,413 | SharePoint: SHAREPOINT_WIN issue with xlwings versions after 0.30.13 | #### System: Windows 10
#### Software versions: xlwings-0.30.14 / xlwings-0.30.15, Office 365 (version 2312), Python 3.12.2
#### Describe your issue (incl. Traceback!)
Using xlwings-0.30.13 works fine. Version xlwings-0.30.14 and xlwings 0.30.15 will yield the following error message while running xw.Book(self... | closed | 2024-03-11T11:17:49Z | 2024-03-18T07:17:18Z | https://github.com/xlwings/xlwings/issues/2413 | [
"bug"
] | timo-stein | 16 |
man-group/arctic | pandas | 734 | UTC timezone failed on write, where my old data were all utc | #### Arctic Version
```
# 1.7.4.0
```
#### Arctic Store
```
# VersionStore,
```
#### Platform and version
Debian 9
#### Description of problem and/or code sample that reproduces the issue
lib.write("test", ddf)
Traceback (most recent call last):
File "<input>", line 1, in <module>
File "... | closed | 2019-03-07T23:12:42Z | 2019-03-25T09:55:15Z | https://github.com/man-group/arctic/issues/734 | [] | rick-sanchez-c137 | 2 |
FactoryBoy/factory_boy | django | 260 | Random Photo Colors and Sizes | I see that I can create a photo with a certain color and size [like this](https://factoryboy.readthedocs.org/en/latest/orms.html?highlight=django#factory.django.ImageField):
``` python
class MyFactory(factory.django.DjangoModelFactory):
class Meta:
model = models.MyModel
the_image = factory.django.Ima... | open | 2016-01-05T00:25:23Z | 2019-04-11T07:41:00Z | https://github.com/FactoryBoy/factory_boy/issues/260 | [
"Feature"
] | saulshanabrook | 16 |
seleniumbase/SeleniumBase | pytest | 3,313 | iframe error using sb.activate_cdp_mode() | Hello,I am using the sb.activate_cdp_mode() method to bypass automation detection when solving a custom captcha. However, when I activate this mode, the sb.switch_to.frame(iframe) method stops working, I get an error: Element {iframe} was not present after 10 seconds!
If I use the sb.get(url) method, then switching to... | closed | 2024-12-04T19:56:27Z | 2024-12-05T18:21:17Z | https://github.com/seleniumbase/SeleniumBase/issues/3313 | [
"question",
"UC Mode / CDP Mode"
] | FrostUNK | 3 |
Gozargah/Marzban | api | 1,579 | Bug title | [Error] peer(bmXO…fgyo) - Failed to send handshake initiation: write udp [::]:39051->[2606:4700:d0::a29f:c001]:2408: sendto: network is unreachable
i have this error on Node server and fixed for couple hours after i restart the docker | closed | 2025-01-06T20:43:19Z | 2025-01-11T17:04:50Z | https://github.com/Gozargah/Marzban/issues/1579 | [] | DrCure6 | 0 |
fastapi-users/fastapi-users | fastapi | 878 | Allow update single field with `PATCH` `users/me` | ## Describe the bug
Currently, when I try to update a user field on `users/me` using `PATCH`, I'm getting a validation error because the `email` field is mandatory. Accordingly, with the `PATCH` method spec, we should be able to update a single field without providing all other fields. But, even if I provide the fiel... | closed | 2022-01-17T17:50:10Z | 2022-01-17T18:00:38Z | https://github.com/fastapi-users/fastapi-users/issues/878 | [
"bug"
] | fullonic | 1 |
SYSTRAN/faster-whisper | deep-learning | 944 | IMPORTANT: 1.0.3 VAD v5 is much worse than 1.0.2 or 1.0.1 VAD v4 for some certain audio data. WHY? | [All falls down.zip](https://github.com/user-attachments/files/16440204/All.falls.down.zip)
For testing some audio files that only contain human voice dialogue, the v5 VAD seems to be better than v4.
But for the music lyrics transcription I tested, 1.0.3 VAD v5 is much worse than 1.0.2 or 1.0.1 VAD v4, v5 and rel... | open | 2024-07-31T11:01:39Z | 2024-08-06T08:56:49Z | https://github.com/SYSTRAN/faster-whisper/issues/944 | [] | ckgithub2019 | 8 |
ageitgey/face_recognition | machine-learning | 973 | Error with rtsp camera | * face_recognition version:1.2.3
* Python version: 3.6
* Operating System: Windows 10
I am trying to get a streaming from an RTSP camera, get it in the first few minutes, but then the system closes.
### What I Did
Debugging the code I get the error: cv2.error: OpenCV (4.1.1) C: \ projects \ opencv-python... | open | 2019-11-08T12:19:59Z | 2019-11-11T11:43:51Z | https://github.com/ageitgey/face_recognition/issues/973 | [] | camilaferreiranas | 4 |
xonsh/xonsh | data-science | 4,688 | Directory completion wrong when completing on user home abbreviation (~) | This is similar to https://github.com/xonsh/xonsh/issues/1964, which was closed a long time ago (2017).
Tab completion of `code ~/D` leads to `code ~/D/home/pierre/D`, which is wrong.
Note that it works well with commands like `ls` or `cd`.
Also, if I set `$BASH_COMPLETIONS = []`, it works well with other prog... | closed | 2022-03-03T08:44:14Z | 2022-03-29T12:59:26Z | https://github.com/xonsh/xonsh/issues/4688 | [
"completion"
] | paugier | 2 |
mirumee/ariadne | graphql | 418 | Make snake_casing more consistent | Hi! Pretty neat project!
I have a "complaint" about snake_casing **consistency** throughout the whole framework.
The `convert_camel_case_to_snake`, `convert_kwargs_to_snake_case` `snake_case_fallback_resolvers` are really helpful, but the picture is not complete, because there is no tool in the framework to conve... | closed | 2020-08-29T17:23:08Z | 2021-03-20T23:27:00Z | https://github.com/mirumee/ariadne/issues/418 | [
"bug",
"roadmap"
] | kissgyorgy | 8 |
marcomusy/vedo | numpy | 73 | K3d freezes Jupyter notebook after showing a mesh | I am using vtkplotter with Trimesh in Jupyter notebook, but the k3d display takes about 5 seconds to load every time I run the cell with the ``show`` command. So I want to disable the k3d display and just use the default separate window. Right now I do this by uninstalling k3d from my Python environment. Is there a bet... | open | 2019-11-04T18:17:44Z | 2019-11-27T14:14:02Z | https://github.com/marcomusy/vedo/issues/73 | [
"bug",
"testing-phase",
"jupyter"
] | panangam | 16 |
streamlit/streamlit | data-science | 10,389 | First Day of the week is still Sunday | ### Checklist
- [x] I have searched the [existing issues](https://github.com/streamlit/streamlit/issues) for similar issues.
- [x] I added a very descriptive title to this issue.
- [x] I have provided sufficient information below to help reproduce this issue.
### Summary
As @jrieke said in the [issue](https://github... | closed | 2025-02-13T09:05:01Z | 2025-02-14T08:29:35Z | https://github.com/streamlit/streamlit/issues/10389 | [
"upstream"
] | sglbl | 2 |
taverntesting/tavern | pytest | 18 | BadSchemaError | Okay so I've been trying to find information on this problem however it seems that your package is fairly new so I can't find much online. Anyways, my problem is that I am trying to test my server however I keep ending up with badschemaerrors whenever I try to test my yaml file with pytest. Here is my yaml file:
`... | closed | 2018-01-19T23:00:09Z | 2018-01-25T16:42:14Z | https://github.com/taverntesting/tavern/issues/18 | [] | zicameau | 6 |
charlesq34/pointnet | tensorflow | 106 | About the visualization of segmentation | Hello Charles,
I had trouble with visualizing the results. After training, I ran batch_inference.py and got the figure Area_4_pred below (the testing area is Area_4).

Howerver, my raw data of Ar... | open | 2018-05-19T06:48:05Z | 2019-07-29T01:42:47Z | https://github.com/charlesq34/pointnet/issues/106 | [] | bingo830422 | 4 |
sqlalchemy/alembic | sqlalchemy | 1,025 | Drop python 3.6 | I think we need to remove support for python 3.6, since the current main uses `from __future__ import annotation` that raises `SyntaxError: future feature annotations is not defined` on py 3.6
@zzzeek this probably requires 1.8? | closed | 2022-05-02T18:12:50Z | 2022-05-07T14:48:36Z | https://github.com/sqlalchemy/alembic/issues/1025 | [
"pep 484"
] | CaselIT | 2 |
tensorflow/tensor2tensor | machine-learning | 1,832 | Model Apply and Application for Image Classification? | Dear experts,
I want to use Tensor2Tensor for image classification tasks. After model training, I got its CKPT and MATA files. Since I don’t know the specific structure of the model, I don't know how to apply these files to practice, classification for my own images for example. Are there any experts who encounter t... | open | 2020-07-11T02:56:58Z | 2020-07-11T02:56:58Z | https://github.com/tensorflow/tensor2tensor/issues/1832 | [] | KXCY-AI | 0 |
ultralytics/yolov5 | deep-learning | 12,841 | How to convert segment json data labeled by labelme to yolo format? | ### Search before asking
- [X] I have searched the YOLOv5 [issues](https://github.com/ultralytics/yolov5/issues) and [discussions](https://github.com/ultralytics/yolov5/discussions) and found no similar questions.
### Question
How to convert segment json data labeled by labelme to yolo format?
Can you share some d... | closed | 2024-03-23T02:26:10Z | 2024-05-05T00:23:01Z | https://github.com/ultralytics/yolov5/issues/12841 | [
"question",
"Stale"
] | fewshotstudy | 4 |
Significant-Gravitas/AutoGPT | python | 8,848 | Add Hubspot blocks | Start wtih Company contact and engagement | closed | 2024-12-01T14:43:43Z | 2025-01-31T01:57:58Z | https://github.com/Significant-Gravitas/AutoGPT/issues/8848 | [
"Stale"
] | aarushik93 | 2 |
huggingface/datasets | numpy | 6,782 | Image cast_storage very slow for arrays (e.g. numpy, tensors) | Update: see comments below
### Describe the bug
Operations that save an image from a path are very slow.
I believe the reason for this is that the image data (`numpy`) is converted into `pyarrow` format but then back to python using `.pylist()` before being converted to a numpy array again.
`pylist` is alread... | open | 2024-04-05T13:46:54Z | 2024-04-10T14:36:13Z | https://github.com/huggingface/datasets/issues/6782 | [] | Modexus | 3 |
MaxHalford/prince | scikit-learn | 1 | DOC: MCA argument. Contingency table or raw observations? | In https://github.com/MaxHalford/Prince/blob/a854849c9e1ee2b331bb0fd4f0f939b1c01b0f01/prince/mca.py#L13 it says that `MCA` takes a dataframe that's a contingency table. From the examples (like `mca-ogm.py`) it looks like `MCA` takes the actual N obs x K variables DataFrame, not the summarized contingency table. Or I co... | closed | 2016-11-21T14:13:32Z | 2016-11-21T15:14:12Z | https://github.com/MaxHalford/prince/issues/1 | [] | TomAugspurger | 1 |
christabor/flask_jsondash | plotly | 128 | ValueError: urls must start with a leading slash | I know somewhere I made a mistake but downloading and running it plainly gave me this error. I can understand somewhere in the routing the error is but I can find it, Can you help?
`
Traceback (most recent call last):
File "app.py", line 17, in <module>
app.register_blueprint(charts)
File "C:\Users\c_th... | open | 2017-06-21T10:01:44Z | 2023-03-25T23:34:25Z | https://github.com/christabor/flask_jsondash/issues/128 | [] | Thuruv | 25 |
aminalaee/sqladmin | fastapi | 840 | Add an ability to add forms into actions | ### Checklist
- [X] There are no similar issues or pull requests for this yet.
### Is your feature related to a problem? Please describe.
I want to be able to ask the admin panel user for a string when they chose to use an actions. in my specific case, it will be used to let the admin send the message to the user se... | closed | 2024-10-19T12:57:18Z | 2024-10-24T09:11:49Z | https://github.com/aminalaee/sqladmin/issues/840 | [] | badger-py | 1 |
cvat-ai/cvat | pytorch | 8,595 | No shortcut for 'done' | ### Actions before raising this issue
- [X] I searched the existing issues and did not find anything similar.
- [X] I read/searched [the docs](https://docs.cvat.ai/docs/)
### Is your feature request related to a problem? Please describe.
As I want to find a shortcut for 'done' in poly line, there shows press 'undefi... | closed | 2024-10-25T08:41:22Z | 2024-10-25T10:11:35Z | https://github.com/cvat-ai/cvat/issues/8595 | [
"enhancement"
] | lordhjx | 1 |
jupyter/nbgrader | jupyter | 1,241 | Configuration Options (how to?) | Operating system: Windows 10
nbgrader version: 0.6.0
Jupyter notebook version: conda 4.7.12
### Expected behavior
Ideally nbgrader would be consistent in the directories it looks into and where to look depending on the assignment/course.
### Actual behavior
When i first created an assignment on the homepage... | open | 2019-10-08T20:13:00Z | 2019-11-02T09:57:19Z | https://github.com/jupyter/nbgrader/issues/1241 | [
"question"
] | timothhw | 3 |
Sanster/IOPaint | pytorch | 536 | malware found inside - cond_stage_model_decode.pt - Real or FP? | June 1st using another custom node with a Lama Remover I selected the model LDM, it starts to download dependency and has a use if IOPaint and the LDM Decode model:
`LDM_DECODE_MODEL_URL = os.environ.get(
"LDM_DECODE_MODEL_URL",
"https://github.com/Sanster/models/releases/download/add_ldm/cond_stage_mode... | closed | 2024-06-04T16:51:32Z | 2024-12-12T02:06:31Z | https://github.com/Sanster/IOPaint/issues/536 | [
"stale"
] | creeduk | 4 |
marshmallow-code/flask-smorest | rest-api | 606 | How to show docs with nginx url prefix set? | I have project which uses flask-smorest and when I run it locally it shows docs on url `/docs/swagger`. But on my production server I have in nginx setup to append `api/` prefix on each url and then docs are not showing because flask-smorest expects openapi.json on `docs/openapi.json` but mine nginx append `api/` and o... | open | 2024-02-15T15:43:04Z | 2024-04-18T19:21:40Z | https://github.com/marshmallow-code/flask-smorest/issues/606 | [
"question"
] | almosthuman56 | 1 |
JoeanAmier/XHS-Downloader | api | 71 | 新版本无法使用监听粘贴板功能 | 
使用监听粘贴板功能,一复制就报错退出无法使用。
还有提个意见,能否以作品id命名文件夹和文件名称而不是标题。 | open | 2024-03-31T07:57:09Z | 2024-04-05T03:09:28Z | https://github.com/JoeanAmier/XHS-Downloader/issues/71 | [
"功能异常(bug)",
"确认问题(confirm)",
"处理完成(complete)"
] | SakuraXiaoWen | 3 |
python-gino/gino | sqlalchemy | 670 | Load balancer with Gino's create_engine | Hello,
* GINO version: 1.0.0
* Gino-Starlette version: 0.1.1
* FastAPI version: 0.54.1
* Python version: 3.8.1
* asyncpg version: 0.20.1
* PostgreSQL version: PostgreSQL 12.1
### Description
I want to use two different engines, depending on the Request method. If the request method is Get, it will use th... | closed | 2020-05-12T10:03:44Z | 2020-06-11T12:07:20Z | https://github.com/python-gino/gino/issues/670 | [
"question"
] | ThanVij29 | 3 |
cvat-ai/cvat | pytorch | 9,057 | (Self Hosted) Annotation Download Fails Over HTTPS (but over http it works fine) | **Story**
When attempting to download a dataset in my CVAT deployment, a new tab briefly opens and closes without downloading anything. The issue seems to be related to mixed content, where CVAT is running over HTTPS, but dataset download URLs are served over HTTP. Modern browsers block such downloads for security reas... | closed | 2025-02-05T12:44:04Z | 2025-02-06T07:23:43Z | https://github.com/cvat-ai/cvat/issues/9057 | [
"need info"
] | osman-goni-cse | 5 |
plotly/dash | data-science | 2,764 | Dangerous link detected error after upgrading to Dash 2.15.0 | ```
dash 2.15.0
dash-bootstrap-components 1.5.0
dash-core-components 2.0.0
dash-extensions 1.0.12
dash-html-components 2.0.0
dash-iconify 0.1.2
dash-mantine-components 0.12.1
dash-table 5.0.0
```
After upgrading to Dash 2.15.0, I have ap... | closed | 2024-02-18T13:47:23Z | 2024-04-22T15:43:09Z | https://github.com/plotly/dash/issues/2764 | [
"bug",
"sev-1"
] | emilhe | 11 |
jpadilla/django-rest-framework-jwt | django | 407 | User settings isn't working at all | Hello i'm using last version with Django 1.11 and `JWT_EXPIRATION_DELTA` not working. I believe it's cause by this line https://github.com/GetBlimp/django-rest-framework-jwt/blob/3b1b15a488e58722be59f6fe5a449e3e34d42b81/rest_framework_jwt/settings.py#L7 | closed | 2017-12-15T14:14:16Z | 2017-12-15T14:38:45Z | https://github.com/jpadilla/django-rest-framework-jwt/issues/407 | [] | ArtemBernatskyy | 2 |
plotly/dash | jupyter | 3,177 | [BUG] Long callbacks create processes | Thank you so much for helping improve the quality of Dash!
We do our best to catch bugs during the release process, but we rely on your help to find the ones that slip through.
**Describe your context**
Please provide us your environment, so we can easily reproduce the issue.
- replace the result of `pip list | gr... | open | 2025-02-21T11:19:24Z | 2025-02-21T14:37:37Z | https://github.com/plotly/dash/issues/3177 | [
"documentation",
"bug",
"P3"
] | Mark531 | 0 |
donnemartin/system-design-primer | python | 847 | Drd | open | 2024-03-31T15:31:22Z | 2024-06-23T17:39:54Z | https://github.com/donnemartin/system-design-primer/issues/847 | [
"needs-review"
] | Yasakelma | 1 | |
InstaPy/InstaPy | automation | 6,126 | run multiple accounts .. idee ? | hi guys, i have no idea if it's Out .. an idea how to run 2 accounts?
@elulcao I need your help ;)
| closed | 2021-03-21T11:28:08Z | 2021-07-21T05:18:40Z | https://github.com/InstaPy/InstaPy/issues/6126 | [
"wontfix"
] | Polkyanik | 2 |
onnx/onnxmltools | scikit-learn | 620 | Kernel crashing while executing convert_catboost | My python kernel dies in VS Code whenever I run convert_catboost,
this is not happening for convert_sklearn, convert_xgboost, convert_lightgbm, also not for tf2onnx.utils.save_onnx_model,
only happening for
```
from onnxmltools.convert.common.data_types import FloatTensorType
from onnxmltools.convert import conve... | closed | 2023-04-17T06:10:19Z | 2023-12-07T23:06:29Z | https://github.com/onnx/onnxmltools/issues/620 | [] | hanzigs | 12 |
explosion/spaCy | deep-learning | 13,658 | Spacy installation on python 3.13 fails | <!-- NOTE: For questions or install related issues, please open a Discussion instead. -->
## How to reproduce the behaviour
<!-- Include a code example or the steps that led to the problem. Please try to be as specific as possible. -->
`pip3.13 install spacy`
C:\Users\talta\AppData\Local\Programs\Python\Python3... | open | 2024-10-12T07:42:28Z | 2025-03-24T13:11:56Z | https://github.com/explosion/spaCy/issues/13658 | [] | RubTalha | 35 |
ipyflow/ipyflow | jupyter | 164 | Jupyterlite support | IPyflow for JuypterLite
- Jupyterlite docs > Howto > Create a custom kernel:
https://jupyterlite.readthedocs.io/en/stable/howto/extensions/kernel.html
- https://github.com/jupyterlite/xeus
- https://jupyterlite-xeus.readthedocs.io/en/latest/
| open | 2024-07-11T21:42:40Z | 2024-09-27T16:04:45Z | https://github.com/ipyflow/ipyflow/issues/164 | [] | westurner | 3 |
falconry/falcon | api | 1,880 | Test: Add Django 3.x with WSGI and ASGI modes to the benchmarks | open | 2021-03-09T17:11:15Z | 2022-01-07T20:23:23Z | https://github.com/falconry/falcon/issues/1880 | [
"perf"
] | kgriffs | 0 | |
ultralytics/yolov5 | pytorch | 12,878 | Expected performance on an Jetson Orin AGX | ### Search before asking
- [X] I have searched the YOLOv5 [issues](https://github.com/ultralytics/yolov5/issues) and [discussions](https://github.com/ultralytics/yolov5/discussions) and found no similar questions.
### Question
We have been using your YoloV5 model for a number of years, it provides impressive detect... | closed | 2024-04-03T09:19:18Z | 2024-05-07T15:43:57Z | https://github.com/ultralytics/yolov5/issues/12878 | [
"question",
"Stale"
] | AWilco | 4 |
deepspeedai/DeepSpeed | pytorch | 6,835 | [REQUEST] domino integration to nanotron | Hello Deepspeed team! I’m excited about the recent introduction of Domino and its impressive TP optimization. It would be fantastic if we could integrate Domino into the [Nanotron library](https://github.com/huggingface/nanotron) to enhance its tensor parallelism capabilities. Thank you
cc @GuanhuaWang | open | 2024-12-07T17:32:33Z | 2025-02-10T15:58:42Z | https://github.com/deepspeedai/DeepSpeed/issues/6835 | [
"enhancement"
] | NouamaneTazi | 4 |
koaning/scikit-lego | scikit-learn | 165 | [DOCS] fairness docs: explain what z is |
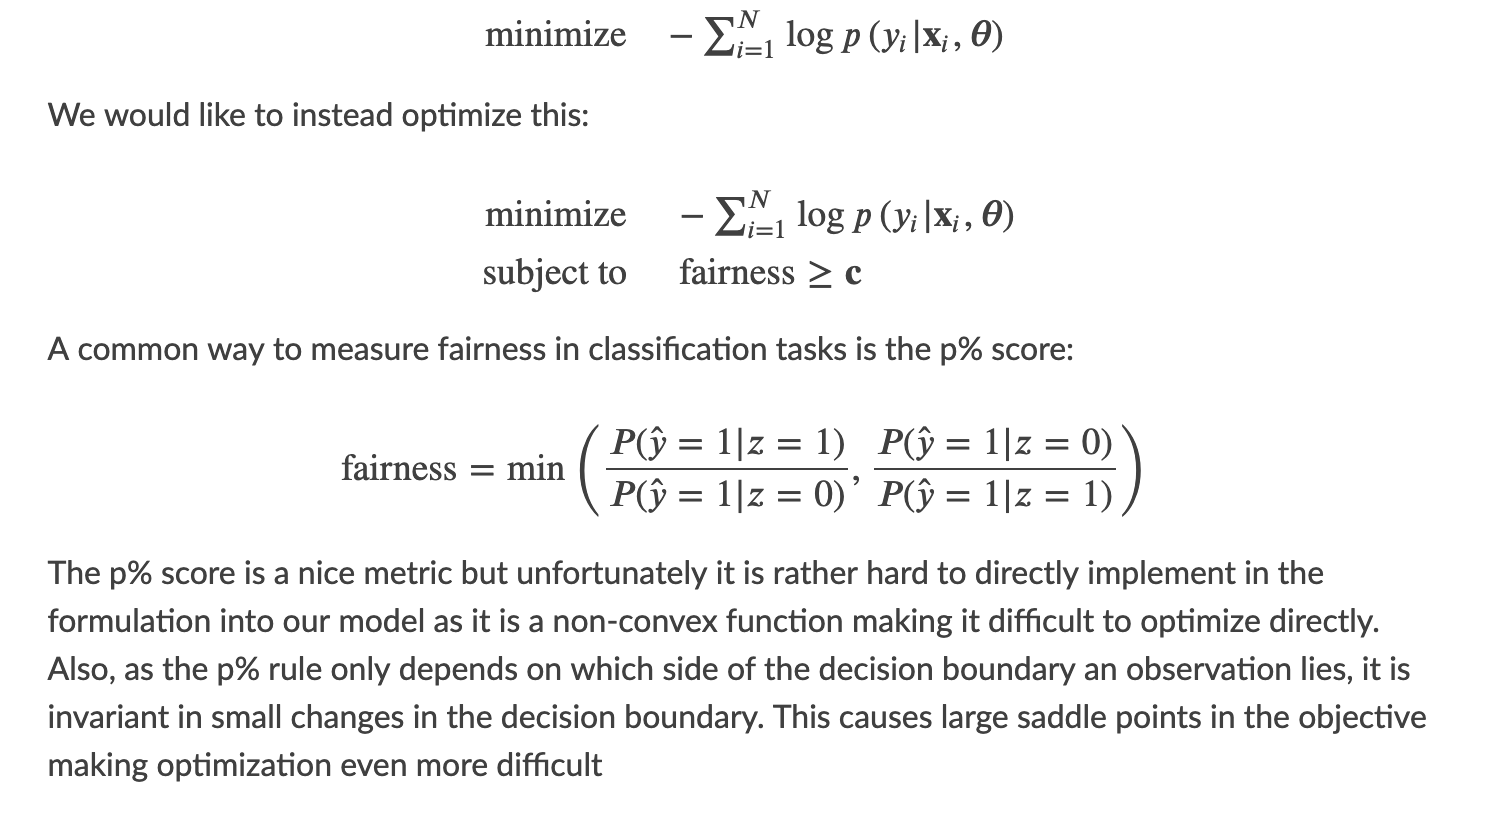
The docs currently do not explain what `z` means in the formula. | closed | 2019-07-16T10:22:23Z | 2019-10-22T12:05:29Z | https://github.com/koaning/scikit-lego/issues/165 | [
"documentation"
] | koaning | 1 |
healthchecks/healthchecks | django | 1,046 | ilert integration | Hi!
It would be great to get ilert integrated. They are an alternative to opsgenie and pagerduty, made and hosted in Germany.
- https://www.ilert.com/
- API Description: https://api.ilert.com/api-docs/ | open | 2024-08-10T10:55:48Z | 2024-10-22T12:55:22Z | https://github.com/healthchecks/healthchecks/issues/1046 | [
"new integration"
] | cinemast | 2 |
Anjok07/ultimatevocalremovergui | pytorch | 641 | SSL Error | I try to download the VR models from the Download Center but it always stops and the only thing it says is "SSL Error". | open | 2023-07-03T01:10:25Z | 2023-07-03T01:10:25Z | https://github.com/Anjok07/ultimatevocalremovergui/issues/641 | [] | kenichi512 | 0 |
ijl/orjson | numpy | 101 | dumps twice will cause an error | I use xxhash will and dumps it twice will let value from `b30d56b4` become `'\x08\x00\x00\x00\x00\x00\x00\x00'`.
error sample code below
``` python
import pytest
import orjson
import xxhash
def test_will_failed():
content = dict(a=xxhash.xxh32_hexdigest("12345"))
orjson.dumps(content)
res = orj... | closed | 2020-06-11T08:48:25Z | 2020-06-18T12:49:57Z | https://github.com/ijl/orjson/issues/101 | [] | Yvictor | 2 |
statsmodels/statsmodels | data-science | 8,993 | Improving the _regularized_grad method | Hi, everyone!
I would like to improve the method code: **_regularized_grad** which is in [class SlicedInverseReg.](https://github.com/statsmodels/statsmodels/blob/main/statsmodels/regression/dimred.py)
With the help of my improvement, the method became twice as fast.
I copied the old and new codes into separate ... | closed | 2023-09-05T15:11:34Z | 2024-04-08T13:05:29Z | https://github.com/statsmodels/statsmodels/issues/8993 | [] | quant12345 | 0 |
huggingface/transformers | machine-learning | 36,119 | Adapting Whisper to the new loss_function attribute | @ArthurZucker @muellerzr Following up on #35838, #34191, #34198, #34283
I would like to help bring in Whisper into this. I see it was not included in the last #35875 round of fixes related to the loss function bug fix (grad acc.) nor the new global "loss_function" attr. Being an encodec model derived from Bart code in... | open | 2025-02-10T16:37:08Z | 2025-02-19T14:12:18Z | https://github.com/huggingface/transformers/issues/36119 | [
"Good Second Issue",
"Feature request"
] | yoadsn | 3 |
pytorch/pytorch | machine-learning | 149,227 | Unexpected behaviour in using torch.nn.utils.rnn.pack_padded_sequence API | ### 🐛 Describe the bug
The test cases test_pack_padded_sequence_empty and test_pack_padded_sequence_zero_length expect a valid PackedSequence output for an empty tensor or a sequence with a zero length. This contradicts the underlying behaviour in the current implementation.
```python
from torch.nn.utils.rnn import... | open | 2025-03-14T21:05:31Z | 2025-03-17T15:25:26Z | https://github.com/pytorch/pytorch/issues/149227 | [
"module: rnn",
"triaged"
] | sjh0849 | 0 |
babysor/MockingBird | deep-learning | 788 | 数据集和模型的关系 | 数据集和模型是什么关系?分别有什么作用吗?生成的模型和导入的音频是否有关?数据集是不是由音频做成的? | open | 2022-11-22T12:30:40Z | 2022-11-22T12:30:40Z | https://github.com/babysor/MockingBird/issues/788 | [] | wu-shanglin | 0 |
pbugnion/gmaps | jupyter | 175 | Exporting html file of map using ipywidgets, and later trying to view map in browser | I am using the ipywidget's embed_minimal_html command to output the resulting html file of the google map image from jupyter notebook, which it definitely outputs. However, I don't understand why I am not able to see the map (using this html file) properly in a web browser afterwards. I get a blank page, and it seems t... | closed | 2017-08-25T15:17:47Z | 2017-08-31T23:03:29Z | https://github.com/pbugnion/gmaps/issues/175 | [] | akanevs | 2 |
ultralytics/yolov5 | pytorch | 12,718 | Same model returns different predictions on different devices | ### Search before asking
- [X] I have searched the YOLOv5 [issues](https://github.com/ultralytics/yolov5/issues) and [discussions](https://github.com/ultralytics/yolov5/discussions) and found no similar questions.
### Question
**Description**
I have trained one model and tested it on three different devices:
**... | closed | 2024-02-07T16:33:49Z | 2024-03-19T00:20:29Z | https://github.com/ultralytics/yolov5/issues/12718 | [
"question",
"Stale"
] | pizzatakeaway | 2 |
aminalaee/sqladmin | asyncio | 861 | navigation menu | ### Checklist
- [X] The bug is reproducible against the latest release or `master`.
- [X] There are no similar issues or pull requests to fix it yet.
### Describe the bug
When clicking on a navigation menu, all menus are expanded. I want to keep the other menu groups in their original folded or opened state
### Ste... | open | 2024-12-10T08:56:22Z | 2024-12-10T08:56:22Z | https://github.com/aminalaee/sqladmin/issues/861 | [] | maxiaojunwolf | 0 |
roboflow/supervision | deep-learning | 825 | AttributeError: 'Results' object has no attribute 'obb' | ### Search before asking
- [X] I have searched the Supervision [issues](https://github.com/roboflow/supervision/issues) and found no similar bug report.
### Bug
i was testing the example provided in the documentation, but i get this error when i run the code, you can see **it prints the detection results** but stil... | closed | 2024-01-31T15:25:23Z | 2024-01-31T16:12:48Z | https://github.com/roboflow/supervision/issues/825 | [
"bug",
"question"
] | AliMostafaRadwan | 6 |
kubeflow/katib | scikit-learn | 1,856 | [Feature] Add Helm supports | /kind feature
Can we add Helm supports just like what KServe did?
See https://github.com/kserve/kserve/pull/1878
- It will help the users to customize the installation more easier. Such as
1. The live/ready probes
2. The MySQL version
3. Others
---
<!-- Don't delete this message to encourage use... | closed | 2022-04-27T09:07:00Z | 2022-05-17T12:13:54Z | https://github.com/kubeflow/katib/issues/1856 | [
"kind/feature"
] | haoxins | 5 |
aiortc/aiortc | asyncio | 939 | Can already encoded audio/video be sent (without having to encode it)? | Sorry for asking here (docs say it's not that bad if purely related to aiortc). This could be a feature request as well.
Imagine I have an already VP8 encoded video in a file. Is it possible to create a `MediaPlayer` with it so later, when passing its `MediaStreamTrack` to `pc.addTrack()`, the media encoding is bypa... | closed | 2023-09-21T15:53:06Z | 2023-10-05T07:30:48Z | https://github.com/aiortc/aiortc/issues/939 | [] | ibc | 4 |
dropbox/PyHive | sqlalchemy | 198 | Using async=True with sqlalchemy | I must be missing something really simple here ... but I cannot figure out how to asynchronously fetch the data from pyhive using sqlalchemy.
Is there any snippet for that ? | open | 2018-03-27T15:52:15Z | 2018-03-27T15:52:15Z | https://github.com/dropbox/PyHive/issues/198 | [] | AbdealiLoKo | 0 |
plotly/plotly.py | plotly | 4,753 | provide parameter to set lat/long ranges of current view with tile maps | Hello Plotly Team!
I have a feature request for the tile-maps.
As a worked on Figure Friday week 35 with the people map dataset, I noticed that it is currently quite hard to set the lat/lon ranges to have a nice view of the map, specially if we want a responsive app or if the data changes.
Currently, if I didn't... | open | 2024-09-08T17:06:31Z | 2024-09-09T17:41:29Z | https://github.com/plotly/plotly.py/issues/4753 | [
"feature",
"P3"
] | sdidier-dev | 0 |
paperless-ngx/paperless-ngx | django | 7,939 | [BUG] Closing a document opened from Dashboard returns to Documents | ### Description
When opening a file from the dashboard and then closing it, you are returned to the Documents section not the Dashboard. I've stumbled across this multiple times when editing files from the _INBOX_-Section on my Dashboard.
### Steps to reproduce
1. Open file from Dashboard
2. Close file via **x** in... | closed | 2024-10-16T14:01:48Z | 2024-11-16T03:12:03Z | https://github.com/paperless-ngx/paperless-ngx/issues/7939 | [
"not a bug"
] | luc-ass | 5 |
Significant-Gravitas/AutoGPT | python | 9,425 | Upgrade block search functionality | Currently search only checks block name and it must contain search phrase exactly; for example searching for "AI Sum" won't include "AI Text Summarizer" but it should.
Search should be more forgiving, ideas:
1. Use string similarity algorithm instead of checking exactly (e.g. The Levenshtein Distance algorithm)
2. Di... | open | 2025-02-05T10:34:14Z | 2025-02-15T13:54:59Z | https://github.com/Significant-Gravitas/AutoGPT/issues/9425 | [
"good first issue",
"platform/frontend"
] | linear[bot] | 2 |
Subsets and Splits
No community queries yet
The top public SQL queries from the community will appear here once available.