
pinned_comment string | closed_at string | timeline_url string | sub_issues_summary string | comments string | repository_url string | active_lock_reason string | closed_by string | state_reason string | state string | html_url string | assignee string | performed_via_github_app string | comments_url string | body string | draft string | url string | issue_field_values string | number string | title string | id string | labels string | issue_dependencies_summary string | locked string | reactions string | pull_request string | type string | events_url string | created_at string | labels_url string | assignees string | author_association string | updated_at string | user string | milestone string | node_id string | is_pull_request bool |
|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|
value:2020-06-08T08:45:03Z | value:https://api.github.com/repos/huggingface/datasets/issues/242/timeline | json:{"total": 0, "completed": 0, "percent_completed": 0} | value:2 | value:https://api.github.com/repos/huggingface/datasets | json:{"login": "lhoestq", "id": 42851186, "node_id": "MDQ6VXNlcjQyODUxMTg2", "avatar_url": "https://avatars.githubusercontent.com/u/42851186?v=4", "gravatar_id": "", "url": "https://api.github.com/users/lhoestq", "html_url": "https://github.com/lhoestq", "followers_url": "https://api.github.com/users/lhoestq/followers"... | value:completed | value:closed | value:https://github.com/huggingface/datasets/issues/242 | value:https://api.github.com/repos/huggingface/datasets/issues/242/comments | value:When I run
```python
dataset = nlp.load_dataset('glue', 'mnli')
```
I get an encoding error (could it be because I'm using Windows?) :
```python
# Lots of error log lines later...
~\Miniconda3\envs\nlp\lib\site-packages\tqdm\std.py in __iter__(self)
1128 try:
-> 1129 for obj in ite... | value:https://api.github.com/repos/huggingface/datasets/issues/242 | json:[] | value:242 | value:UnicodeDecodeError when downloading GLUE-MNLI | value:631733683 | json:[] | json:{"blocked_by": 0, "total_blocked_by": 0, "blocking": 0, "total_blocking": 0} | value:False | json:{"url": "https://api.github.com/repos/huggingface/datasets/issues/242/reactions", "total_count": 0, "+1": 0, "-1": 0, "laugh": 0, "hooray": 0, "confused": 0, "heart": 0, "rocket": 0, "eyes": 0} | value:https://api.github.com/repos/huggingface/datasets/issues/242/events | value:2020-06-05T16:30:01Z | value:https://api.github.com/repos/huggingface/datasets/issues/242/labels{/name} | json:[] | value:CONTRIBUTOR | value:2020-06-09T16:06:47Z | json:{"login": "patpizio", "id": 15801338, "node_id": "MDQ6VXNlcjE1ODAxMzM4", "avatar_url": "https://avatars.githubusercontent.com/u/15801338?v=4", "gravatar_id": "", "url": "https://api.github.com/users/patpizio", "html_url": "https://github.com/patpizio", "followers_url": "https://api.github.com/users/patpizio/follow... | value:MDU6SXNzdWU2MzE3MzM2ODM= | true | ||||||||
value:2020-06-08T08:35:31Z | value:https://api.github.com/repos/huggingface/datasets/issues/241/timeline | value:2 | value:https://api.github.com/repos/huggingface/datasets | json:{"login": "lhoestq", "id": 42851186, "node_id": "MDQ6VXNlcjQyODUxMTg2", "avatar_url": "https://avatars.githubusercontent.com/u/42851186?v=4", "gravatar_id": "", "url": "https://api.github.com/users/lhoestq", "html_url": "https://github.com/lhoestq", "followers_url": "https://api.github.com/users/lhoestq/followers"... | value:closed | value:https://github.com/huggingface/datasets/pull/241 | value:https://api.github.com/repos/huggingface/datasets/issues/241/comments | value:If the cache dir of a dataset is empty, the dataset fails to load and throws a FileNotFounfError. We could end up with empty cache dir because there was a line in the code that created the cache dir without using a temp dir. Using a temp dir is useful as it gets renamed to the real cache dir only if the full proc... | value:False | value:https://api.github.com/repos/huggingface/datasets/issues/241 | json:[] | value:241 | value:Fix empty cache dir | value:631703079 | json:[] | value:False | json:{"url": "https://api.github.com/repos/huggingface/datasets/issues/241/reactions", "total_count": 0, "+1": 0, "-1": 0, "laugh": 0, "hooray": 0, "confused": 0, "heart": 0, "rocket": 0, "eyes": 0} | json:{"url": "https://api.github.com/repos/huggingface/datasets/pulls/241", "html_url": "https://github.com/huggingface/datasets/pull/241", "diff_url": "https://github.com/huggingface/datasets/pull/241.diff", "patch_url": "https://github.com/huggingface/datasets/pull/241.patch", "merged_at": "2020-06-08T08:35:31Z"} | value:https://api.github.com/repos/huggingface/datasets/issues/241/events | value:2020-06-05T15:45:22Z | value:https://api.github.com/repos/huggingface/datasets/issues/241/labels{/name} | json:[] | value:MEMBER | value:2020-06-08T08:35:33Z | json:{"login": "lhoestq", "id": 42851186, "node_id": "MDQ6VXNlcjQyODUxMTg2", "avatar_url": "https://avatars.githubusercontent.com/u/42851186?v=4", "gravatar_id": "", "url": "https://api.github.com/users/lhoestq", "html_url": "https://github.com/lhoestq", "followers_url": "https://api.github.com/users/lhoestq/followers"... | value:MDExOlB1bGxSZXF1ZXN0NDI4NTQwMDM0 | true | |||||||||
value:2020-06-08T09:18:14Z | value:https://api.github.com/repos/huggingface/datasets/issues/240/timeline | json:{"total": 0, "completed": 0, "percent_completed": 0} | value:4 | value:https://api.github.com/repos/huggingface/datasets | json:{"login": "patrickvonplaten", "id": 23423619, "node_id": "MDQ6VXNlcjIzNDIzNjE5", "avatar_url": "https://avatars.githubusercontent.com/u/23423619?v=4", "gravatar_id": "", "url": "https://api.github.com/users/patrickvonplaten", "html_url": "https://github.com/patrickvonplaten", "followers_url": "https://api.github.c... | value:completed | value:closed | value:https://github.com/huggingface/datasets/issues/240 | value:https://api.github.com/repos/huggingface/datasets/issues/240/comments | value:When calling:
```python
import nlp
dataset = nlp.load_dataset("trivia_qa", split="validation[:1%]")
```
the resulting dataset is not deterministic over different google colabs.
After talking to @thomwolf, I suspect the reason to be the use of `glob.glob` in line:
https://github.com/huggingface/nlp/bl... | value:https://api.github.com/repos/huggingface/datasets/issues/240 | json:[] | value:240 | value:Deterministic dataset loading | value:631434677 | json:[] | json:{"blocked_by": 0, "total_blocked_by": 0, "blocking": 0, "total_blocking": 0} | value:False | json:{"url": "https://api.github.com/repos/huggingface/datasets/issues/240/reactions", "total_count": 0, "+1": 0, "-1": 0, "laugh": 0, "hooray": 0, "confused": 0, "heart": 0, "rocket": 0, "eyes": 0} | value:https://api.github.com/repos/huggingface/datasets/issues/240/events | value:2020-06-05T09:03:26Z | value:https://api.github.com/repos/huggingface/datasets/issues/240/labels{/name} | json:[] | value:CONTRIBUTOR | value:2020-06-08T09:18:14Z | json:{"login": "patrickvonplaten", "id": 23423619, "node_id": "MDQ6VXNlcjIzNDIzNjE5", "avatar_url": "https://avatars.githubusercontent.com/u/23423619?v=4", "gravatar_id": "", "url": "https://api.github.com/users/patrickvonplaten", "html_url": "https://github.com/patrickvonplaten", "followers_url": "https://api.github.c... | value:MDU6SXNzdWU2MzE0MzQ2Nzc= | true | ||||||||
value:2020-06-07T13:01:04Z | value:https://api.github.com/repos/huggingface/datasets/issues/239/timeline | json:{"total": 0, "completed": 0, "percent_completed": 0} | value:5 | value:https://api.github.com/repos/huggingface/datasets | json:{"login": "richarddwang", "id": 17963619, "node_id": "MDQ6VXNlcjE3OTYzNjE5", "avatar_url": "https://avatars.githubusercontent.com/u/17963619?v=4", "gravatar_id": "", "url": "https://api.github.com/users/richarddwang", "html_url": "https://github.com/richarddwang", "followers_url": "https://api.github.com/users/ric... | value:completed | value:closed | value:https://github.com/huggingface/datasets/issues/239 | json:{"login": "lhoestq", "id": 42851186, "node_id": "MDQ6VXNlcjQyODUxMTg2", "avatar_url": "https://avatars.githubusercontent.com/u/42851186?v=4", "gravatar_id": "", "url": "https://api.github.com/users/lhoestq", "html_url": "https://github.com/lhoestq", "followers_url": "https://api.github.com/users/lhoestq/followers"... | value:https://api.github.com/repos/huggingface/datasets/issues/239/comments | value:Hi, I am trying to create Toronto Book Corpus. #131
I ran
`~/nlp % python nlp-cli test datasets/bookcorpus --save_infos --all_configs`
but this doesn't create `dataset_info.json` and try to use it
```
INFO:nlp.load:Checking datasets/bookcorpus/bookcorpus.py for additional imports.
INFO:filelock:Lock 1397... | value:https://api.github.com/repos/huggingface/datasets/issues/239 | json:[] | value:239 | value:[Creating new dataset] Not found dataset_info.json | value:631340440 | json:[] | json:{"blocked_by": 0, "total_blocked_by": 0, "blocking": 0, "total_blocking": 0} | value:False | json:{"url": "https://api.github.com/repos/huggingface/datasets/issues/239/reactions", "total_count": 0, "+1": 0, "-1": 0, "laugh": 0, "hooray": 0, "confused": 0, "heart": 0, "rocket": 0, "eyes": 0} | value:https://api.github.com/repos/huggingface/datasets/issues/239/events | value:2020-06-05T06:15:04Z | value:https://api.github.com/repos/huggingface/datasets/issues/239/labels{/name} | json:[{"login": "lhoestq", "id": 42851186, "node_id": "MDQ6VXNlcjQyODUxMTg2", "avatar_url": "https://avatars.githubusercontent.com/u/42851186?v=4", "gravatar_id": "", "url": "https://api.github.com/users/lhoestq", "html_url": "https://github.com/lhoestq", "followers_url": "https://api.github.com/users/lhoestq/followers... | value:CONTRIBUTOR | value:2020-06-07T13:01:04Z | json:{"login": "richarddwang", "id": 17963619, "node_id": "MDQ6VXNlcjE3OTYzNjE5", "avatar_url": "https://avatars.githubusercontent.com/u/17963619?v=4", "gravatar_id": "", "url": "https://api.github.com/users/richarddwang", "html_url": "https://github.com/richarddwang", "followers_url": "https://api.github.com/users/ric... | value:MDU6SXNzdWU2MzEzNDA0NDA= | true | |||||||
value:2020-06-29T17:10:19Z | value:https://api.github.com/repos/huggingface/datasets/issues/238/timeline | json:{"total": 0, "completed": 0, "percent_completed": 0} | value:1 | value:https://api.github.com/repos/huggingface/datasets | json:{"login": "lhoestq", "id": 42851186, "node_id": "MDQ6VXNlcjQyODUxMTg2", "avatar_url": "https://avatars.githubusercontent.com/u/42851186?v=4", "gravatar_id": "", "url": "https://api.github.com/users/lhoestq", "html_url": "https://github.com/lhoestq", "followers_url": "https://api.github.com/users/lhoestq/followers"... | value:completed | value:closed | value:https://github.com/huggingface/datasets/issues/238 | value:https://api.github.com/repos/huggingface/datasets/issues/238/comments | value:When running BERT-Score, I'm meeting this warning :
> Warning: Empty candidate sentence; Setting recall to be 0.
Code :
```
import nlp
metric = nlp.load_metric("bertscore")
scores = metric.compute(["swag", "swags"], ["swags", "totally something different"], lang="en", device=0)
```
---
**What a... | value:https://api.github.com/repos/huggingface/datasets/issues/238 | json:[] | value:238 | value:[Metric] Bertscore : Warning : Empty candidate sentence; Setting recall to be 0. | value:631260143 | json:[{"id": 2067393914, "node_id": "MDU6TGFiZWwyMDY3MzkzOTE0", "url": "https://api.github.com/repos/huggingface/datasets/labels/metric%20bug", "name": "metric bug", "color": "25b21e", "default": false, "description": "A bug in a metric script", "archived_at": null, "archived_by": null}] | json:{"blocked_by": 0, "total_blocked_by": 0, "blocking": 0, "total_blocking": 0} | value:False | json:{"url": "https://api.github.com/repos/huggingface/datasets/issues/238/reactions", "total_count": 1, "+1": 1, "-1": 0, "laugh": 0, "hooray": 0, "confused": 0, "heart": 0, "rocket": 0, "eyes": 0} | value:https://api.github.com/repos/huggingface/datasets/issues/238/events | value:2020-06-05T02:14:47Z | value:https://api.github.com/repos/huggingface/datasets/issues/238/labels{/name} | json:[] | value:NONE | value:2020-06-29T17:10:19Z | json:{"login": "astariul", "id": 43774355, "node_id": "MDQ6VXNlcjQzNzc0MzU1", "avatar_url": "https://avatars.githubusercontent.com/u/43774355?v=4", "gravatar_id": "", "url": "https://api.github.com/users/astariul", "html_url": "https://github.com/astariul", "followers_url": "https://api.github.com/users/astariul/follow... | value:MDU6SXNzdWU2MzEyNjAxNDM= | true | ||||||||
value:2020-06-06T10:51:34Z | value:https://api.github.com/repos/huggingface/datasets/issues/237/timeline | json:{"total": 0, "completed": 0, "percent_completed": 0} | value:3 | value:https://api.github.com/repos/huggingface/datasets | json:{"login": "patpizio", "id": 15801338, "node_id": "MDQ6VXNlcjE1ODAxMzM4", "avatar_url": "https://avatars.githubusercontent.com/u/15801338?v=4", "gravatar_id": "", "url": "https://api.github.com/users/patpizio", "html_url": "https://github.com/patpizio", "followers_url": "https://api.github.com/users/patpizio/follow... | value:completed | value:closed | value:https://github.com/huggingface/datasets/issues/237 | value:https://api.github.com/repos/huggingface/datasets/issues/237/comments | value:When I try to download MultiNLI with
```python
dataset = load_dataset('multi_nli')
```
I get this long error:
```python
---------------------------------------------------------------------------
OSError Traceback (most recent call last)
<ipython-input-13-3b11f6be4cb9>... | value:https://api.github.com/repos/huggingface/datasets/issues/237 | json:[] | value:237 | value:Can't download MultiNLI | value:631199940 | json:[] | json:{"blocked_by": 0, "total_blocked_by": 0, "blocking": 0, "total_blocking": 0} | value:False | json:{"url": "https://api.github.com/repos/huggingface/datasets/issues/237/reactions", "total_count": 0, "+1": 0, "-1": 0, "laugh": 0, "hooray": 0, "confused": 0, "heart": 0, "rocket": 0, "eyes": 0} | value:https://api.github.com/repos/huggingface/datasets/issues/237/events | value:2020-06-04T23:05:21Z | value:https://api.github.com/repos/huggingface/datasets/issues/237/labels{/name} | json:[] | value:CONTRIBUTOR | value:2020-06-06T10:51:34Z | json:{"login": "patpizio", "id": 15801338, "node_id": "MDQ6VXNlcjE1ODAxMzM4", "avatar_url": "https://avatars.githubusercontent.com/u/15801338?v=4", "gravatar_id": "", "url": "https://api.github.com/users/patpizio", "html_url": "https://github.com/patpizio", "followers_url": "https://api.github.com/users/patpizio/follow... | value:MDU6SXNzdWU2MzExOTk5NDA= | true | ||||||||
value:2020-06-11T07:45:21Z | value:https://api.github.com/repos/huggingface/datasets/issues/236/timeline | value:9 | value:https://api.github.com/repos/huggingface/datasets | json:{"login": "lhoestq", "id": 42851186, "node_id": "MDQ6VXNlcjQyODUxMTg2", "avatar_url": "https://avatars.githubusercontent.com/u/42851186?v=4", "gravatar_id": "", "url": "https://api.github.com/users/lhoestq", "html_url": "https://github.com/lhoestq", "followers_url": "https://api.github.com/users/lhoestq/followers"... | value:closed | value:https://github.com/huggingface/datasets/pull/236 | value:https://api.github.com/repos/huggingface/datasets/issues/236/comments | value:Hello,
Thanks for the amazing library that you put together. I'm Alessandro Suglia, the first author of CompGuessWhat?!, a recently released dataset for grounded language learning accepted to ACL 2020 ([https://compguesswhat.github.io](https://compguesswhat.github.io)).
This pull-request adds the CompGuessW... | value:False | value:https://api.github.com/repos/huggingface/datasets/issues/236 | json:[] | value:236 | value:CompGuessWhat?! dataset | value:631099875 | json:[] | value:False | json:{"url": "https://api.github.com/repos/huggingface/datasets/issues/236/reactions", "total_count": 0, "+1": 0, "-1": 0, "laugh": 0, "hooray": 0, "confused": 0, "heart": 0, "rocket": 0, "eyes": 0} | json:{"url": "https://api.github.com/repos/huggingface/datasets/pulls/236", "html_url": "https://github.com/huggingface/datasets/pull/236", "diff_url": "https://github.com/huggingface/datasets/pull/236.diff", "patch_url": "https://github.com/huggingface/datasets/pull/236.patch", "merged_at": "2020-06-11T07:45:21Z"} | value:https://api.github.com/repos/huggingface/datasets/issues/236/events | value:2020-06-04T19:45:50Z | value:https://api.github.com/repos/huggingface/datasets/issues/236/labels{/name} | json:[] | value:CONTRIBUTOR | value:2020-06-11T09:43:42Z | json:{"login": "aleSuglia", "id": 1479733, "node_id": "MDQ6VXNlcjE0Nzk3MzM=", "avatar_url": "https://avatars.githubusercontent.com/u/1479733?v=4", "gravatar_id": "", "url": "https://api.github.com/users/aleSuglia", "html_url": "https://github.com/aleSuglia", "followers_url": "https://api.github.com/users/aleSuglia/foll... | value:MDExOlB1bGxSZXF1ZXN0NDI4MDUwNzI4 | true | |||||||||
value:2020-06-12T15:38:55Z | value:https://api.github.com/repos/huggingface/datasets/issues/235/timeline | value:6 | value:https://api.github.com/repos/huggingface/datasets | json:{"login": "lhoestq", "id": 42851186, "node_id": "MDQ6VXNlcjQyODUxMTg2", "avatar_url": "https://avatars.githubusercontent.com/u/42851186?v=4", "gravatar_id": "", "url": "https://api.github.com/users/lhoestq", "html_url": "https://github.com/lhoestq", "followers_url": "https://api.github.com/users/lhoestq/followers"... | value:closed | value:https://github.com/huggingface/datasets/pull/235 | value:https://api.github.com/repos/huggingface/datasets/issues/235/comments | value:## Adding an *experimental datasets* folder
After using the 🤗nlp library for some time, I find that while it makes it super easy to create new memory-mapped datasets with lots of cool utilities, a lot of what I want to do doesn't work well with the current `MockDownloader` based testing paradigm, making it ha... | value:False | value:https://api.github.com/repos/huggingface/datasets/issues/235 | json:[] | value:235 | value:Add experimental datasets | value:630952297 | json:[] | value:False | json:{"url": "https://api.github.com/repos/huggingface/datasets/issues/235/reactions", "total_count": 0, "+1": 0, "-1": 0, "laugh": 0, "hooray": 0, "confused": 0, "heart": 0, "rocket": 0, "eyes": 0} | json:{"url": "https://api.github.com/repos/huggingface/datasets/pulls/235", "html_url": "https://github.com/huggingface/datasets/pull/235", "diff_url": "https://github.com/huggingface/datasets/pull/235.diff", "patch_url": "https://github.com/huggingface/datasets/pull/235.patch", "merged_at": "2020-06-12T15:38:55Z"} | value:https://api.github.com/repos/huggingface/datasets/issues/235/events | value:2020-06-04T15:54:56Z | value:https://api.github.com/repos/huggingface/datasets/issues/235/labels{/name} | json:[] | value:MEMBER | value:2020-06-12T15:38:55Z | json:{"login": "yjernite", "id": 10469459, "node_id": "MDQ6VXNlcjEwNDY5NDU5", "avatar_url": "https://avatars.githubusercontent.com/u/10469459?v=4", "gravatar_id": "", "url": "https://api.github.com/users/yjernite", "html_url": "https://github.com/yjernite", "followers_url": "https://api.github.com/users/yjernite/follow... | value:MDExOlB1bGxSZXF1ZXN0NDI3OTM1MjQ0 | true | |||||||||
value:2020-07-06T09:33:26Z | value:https://api.github.com/repos/huggingface/datasets/issues/234/timeline | json:{"total": 0, "completed": 0, "percent_completed": 0} | value:4 | value:https://api.github.com/repos/huggingface/datasets | json:{"login": "Nouman97", "id": 42269506, "node_id": "MDQ6VXNlcjQyMjY5NTA2", "avatar_url": "https://avatars.githubusercontent.com/u/42269506?v=4", "gravatar_id": "", "url": "https://api.github.com/users/Nouman97", "html_url": "https://github.com/Nouman97", "followers_url": "https://api.github.com/users/Nouman97/follow... | value:completed | value:closed | value:https://github.com/huggingface/datasets/issues/234 | value:https://api.github.com/repos/huggingface/datasets/issues/234/comments | value:Hello,
Does anyone know how we can call our custom dataset using the nlp.load command? Let's say that I have a dataset based on the same format as that of squad-v1.1, how am I supposed to load it using huggingface nlp.
Thank you! | value:https://api.github.com/repos/huggingface/datasets/issues/234 | json:[] | value:234 | value:Huggingface NLP, Uploading custom dataset | value:630534427 | json:[] | json:{"blocked_by": 0, "total_blocked_by": 0, "blocking": 0, "total_blocking": 0} | value:False | json:{"url": "https://api.github.com/repos/huggingface/datasets/issues/234/reactions", "total_count": 0, "+1": 0, "-1": 0, "laugh": 0, "hooray": 0, "confused": 0, "heart": 0, "rocket": 0, "eyes": 0} | value:https://api.github.com/repos/huggingface/datasets/issues/234/events | value:2020-06-04T05:59:06Z | value:https://api.github.com/repos/huggingface/datasets/issues/234/labels{/name} | json:[] | value:NONE | value:2020-07-06T09:33:26Z | json:{"login": "Nouman97", "id": 42269506, "node_id": "MDQ6VXNlcjQyMjY5NTA2", "avatar_url": "https://avatars.githubusercontent.com/u/42269506?v=4", "gravatar_id": "", "url": "https://api.github.com/users/Nouman97", "html_url": "https://github.com/Nouman97", "followers_url": "https://api.github.com/users/Nouman97/follow... | value:MDU6SXNzdWU2MzA1MzQ0Mjc= | true | ||||||||
value:2020-06-08T09:16:59Z | value:https://api.github.com/repos/huggingface/datasets/issues/233/timeline | json:{"total": 0, "completed": 0, "percent_completed": 0} | value:5 | value:https://api.github.com/repos/huggingface/datasets | json:{"login": "lhoestq", "id": 42851186, "node_id": "MDQ6VXNlcjQyODUxMTg2", "avatar_url": "https://avatars.githubusercontent.com/u/42851186?v=4", "gravatar_id": "", "url": "https://api.github.com/users/lhoestq", "html_url": "https://github.com/lhoestq", "followers_url": "https://api.github.com/users/lhoestq/followers"... | value:completed | value:closed | value:https://github.com/huggingface/datasets/issues/233 | value:https://api.github.com/repos/huggingface/datasets/issues/233/comments | value:i run following code to download c4 English corpus.
```
dataset = nlp.load_dataset('c4', 'en', beam_runner='DirectRunner'
, data_dir='/mypath')
```
and i met failure as follows
```
Downloading and preparing dataset c4/en (download: Unknown size, generated: Unknown size, total: Unknown size) to /home/... | value:https://api.github.com/repos/huggingface/datasets/issues/233 | json:[] | value:233 | value:Fail to download c4 english corpus | value:630432132 | json:[] | json:{"blocked_by": 0, "total_blocked_by": 0, "blocking": 0, "total_blocking": 0} | value:False | json:{"url": "https://api.github.com/repos/huggingface/datasets/issues/233/reactions", "total_count": 3, "+1": 3, "-1": 0, "laugh": 0, "hooray": 0, "confused": 0, "heart": 0, "rocket": 0, "eyes": 0} | value:https://api.github.com/repos/huggingface/datasets/issues/233/events | value:2020-06-04T01:06:38Z | value:https://api.github.com/repos/huggingface/datasets/issues/233/labels{/name} | json:[] | value:NONE | value:2021-01-08T07:17:32Z | json:{"login": "donggyukimc", "id": 16605764, "node_id": "MDQ6VXNlcjE2NjA1NzY0", "avatar_url": "https://avatars.githubusercontent.com/u/16605764?v=4", "gravatar_id": "", "url": "https://api.github.com/users/donggyukimc", "html_url": "https://github.com/donggyukimc", "followers_url": "https://api.github.com/users/donggy... | value:MDU6SXNzdWU2MzA0MzIxMzI= | true | ||||||||
value:2020-06-08T09:02:57Z | value:https://api.github.com/repos/huggingface/datasets/issues/232/timeline | value:1 | value:https://api.github.com/repos/huggingface/datasets | json:{"login": "lhoestq", "id": 42851186, "node_id": "MDQ6VXNlcjQyODUxMTg2", "avatar_url": "https://avatars.githubusercontent.com/u/42851186?v=4", "gravatar_id": "", "url": "https://api.github.com/users/lhoestq", "html_url": "https://github.com/lhoestq", "followers_url": "https://api.github.com/users/lhoestq/followers"... | value:closed | value:https://github.com/huggingface/datasets/pull/232 | value:https://api.github.com/repos/huggingface/datasets/issues/232/comments | value:With this PR users will be able to upload their own datasets and metrics.
As mentioned in #181, I had to use the new endpoints and revert the use of dataclasses (just in case we have changes in the API in the future).
We now distinguish commands for datasets and commands for metrics:
```bash
nlp-cli uploa... | value:False | value:https://api.github.com/repos/huggingface/datasets/issues/232 | json:[] | value:232 | value:Nlp cli fix endpoints | value:630029568 | json:[] | value:False | json:{"url": "https://api.github.com/repos/huggingface/datasets/issues/232/reactions", "total_count": 1, "+1": 1, "-1": 0, "laugh": 0, "hooray": 0, "confused": 0, "heart": 0, "rocket": 0, "eyes": 0} | json:{"url": "https://api.github.com/repos/huggingface/datasets/pulls/232", "html_url": "https://github.com/huggingface/datasets/pull/232", "diff_url": "https://github.com/huggingface/datasets/pull/232.diff", "patch_url": "https://github.com/huggingface/datasets/pull/232.patch", "merged_at": "2020-06-08T09:02:57Z"} | value:https://api.github.com/repos/huggingface/datasets/issues/232/events | value:2020-06-03T14:10:39Z | value:https://api.github.com/repos/huggingface/datasets/issues/232/labels{/name} | json:[] | value:MEMBER | value:2020-06-08T09:02:58Z | json:{"login": "lhoestq", "id": 42851186, "node_id": "MDQ6VXNlcjQyODUxMTg2", "avatar_url": "https://avatars.githubusercontent.com/u/42851186?v=4", "gravatar_id": "", "url": "https://api.github.com/users/lhoestq", "html_url": "https://github.com/lhoestq", "followers_url": "https://api.github.com/users/lhoestq/followers"... | value:MDExOlB1bGxSZXF1ZXN0NDI3MjI5NDcy | true | |||||||||
value:2020-06-03T14:25:55Z | value:https://api.github.com/repos/huggingface/datasets/issues/231/timeline | value:0 | value:https://api.github.com/repos/huggingface/datasets | json:{"login": "lhoestq", "id": 42851186, "node_id": "MDQ6VXNlcjQyODUxMTg2", "avatar_url": "https://avatars.githubusercontent.com/u/42851186?v=4", "gravatar_id": "", "url": "https://api.github.com/users/lhoestq", "html_url": "https://github.com/lhoestq", "followers_url": "https://api.github.com/users/lhoestq/followers"... | value:closed | value:https://github.com/huggingface/datasets/pull/231 | value:https://api.github.com/repos/huggingface/datasets/issues/231/comments | value:One method from the DownloadManager was missing and some users couldn't run the tests because of that.
@yjernite | value:False | value:https://api.github.com/repos/huggingface/datasets/issues/231 | json:[] | value:231 | value:Add .download to MockDownloadManager | value:629988694 | json:[] | value:False | json:{"url": "https://api.github.com/repos/huggingface/datasets/issues/231/reactions", "total_count": 1, "+1": 1, "-1": 0, "laugh": 0, "hooray": 0, "confused": 0, "heart": 0, "rocket": 0, "eyes": 0} | json:{"url": "https://api.github.com/repos/huggingface/datasets/pulls/231", "html_url": "https://github.com/huggingface/datasets/pull/231", "diff_url": "https://github.com/huggingface/datasets/pull/231.diff", "patch_url": "https://github.com/huggingface/datasets/pull/231.patch", "merged_at": "2020-06-03T14:25:54Z"} | value:https://api.github.com/repos/huggingface/datasets/issues/231/events | value:2020-06-03T13:20:00Z | value:https://api.github.com/repos/huggingface/datasets/issues/231/labels{/name} | json:[] | value:MEMBER | value:2020-06-03T14:25:56Z | json:{"login": "lhoestq", "id": 42851186, "node_id": "MDQ6VXNlcjQyODUxMTg2", "avatar_url": "https://avatars.githubusercontent.com/u/42851186?v=4", "gravatar_id": "", "url": "https://api.github.com/users/lhoestq", "html_url": "https://github.com/lhoestq", "followers_url": "https://api.github.com/users/lhoestq/followers"... | value:MDExOlB1bGxSZXF1ZXN0NDI3MTk3MTcz | true | |||||||||
value:2020-06-03T14:34:07Z | value:https://api.github.com/repos/huggingface/datasets/issues/230/timeline | value:0 | value:https://api.github.com/repos/huggingface/datasets | json:{"login": "lhoestq", "id": 42851186, "node_id": "MDQ6VXNlcjQyODUxMTg2", "avatar_url": "https://avatars.githubusercontent.com/u/42851186?v=4", "gravatar_id": "", "url": "https://api.github.com/users/lhoestq", "html_url": "https://github.com/lhoestq", "followers_url": "https://api.github.com/users/lhoestq/followers"... | value:closed | value:https://github.com/huggingface/datasets/pull/230 | value:https://api.github.com/repos/huggingface/datasets/issues/230/comments | value:As pointed out in #227, we shouldn't force users to install apache beam if the processed dataset can be downloaded. I moved the imports of some datasets to avoid this problem | value:False | value:https://api.github.com/repos/huggingface/datasets/issues/230 | json:[] | value:230 | value:Don't force to install apache beam for wikipedia dataset | value:629983684 | json:[] | value:False | json:{"url": "https://api.github.com/repos/huggingface/datasets/issues/230/reactions", "total_count": 0, "+1": 0, "-1": 0, "laugh": 0, "hooray": 0, "confused": 0, "heart": 0, "rocket": 0, "eyes": 0} | json:{"url": "https://api.github.com/repos/huggingface/datasets/pulls/230", "html_url": "https://github.com/huggingface/datasets/pull/230", "diff_url": "https://github.com/huggingface/datasets/pull/230.diff", "patch_url": "https://github.com/huggingface/datasets/pull/230.patch", "merged_at": "2020-06-03T14:34:07Z"} | value:https://api.github.com/repos/huggingface/datasets/issues/230/events | value:2020-06-03T13:13:07Z | value:https://api.github.com/repos/huggingface/datasets/issues/230/labels{/name} | json:[] | value:MEMBER | value:2020-06-03T14:34:09Z | json:{"login": "lhoestq", "id": 42851186, "node_id": "MDQ6VXNlcjQyODUxMTg2", "avatar_url": "https://avatars.githubusercontent.com/u/42851186?v=4", "gravatar_id": "", "url": "https://api.github.com/users/lhoestq", "html_url": "https://github.com/lhoestq", "followers_url": "https://api.github.com/users/lhoestq/followers"... | value:MDExOlB1bGxSZXF1ZXN0NDI3MTkzMTQ0 | true | |||||||||
value:2020-06-03T12:48:33Z | value:https://api.github.com/repos/huggingface/datasets/issues/229/timeline | value:1 | value:https://api.github.com/repos/huggingface/datasets | json:{"login": "lhoestq", "id": 42851186, "node_id": "MDQ6VXNlcjQyODUxMTg2", "avatar_url": "https://avatars.githubusercontent.com/u/42851186?v=4", "gravatar_id": "", "url": "https://api.github.com/users/lhoestq", "html_url": "https://github.com/lhoestq", "followers_url": "https://api.github.com/users/lhoestq/followers"... | value:closed | value:https://github.com/huggingface/datasets/pull/229 | value:https://api.github.com/repos/huggingface/datasets/issues/229/comments | value:As the file required for the viewing in the live nlp viewer is named as dataset_info.json | value:False | value:https://api.github.com/repos/huggingface/datasets/issues/229 | json:[] | value:229 | value:Rename dataset_infos.json to dataset_info.json | value:629956490 | json:[] | value:False | json:{"url": "https://api.github.com/repos/huggingface/datasets/issues/229/reactions", "total_count": 0, "+1": 0, "-1": 0, "laugh": 0, "hooray": 0, "confused": 0, "heart": 0, "rocket": 0, "eyes": 0} | json:{"url": "https://api.github.com/repos/huggingface/datasets/pulls/229", "html_url": "https://github.com/huggingface/datasets/pull/229", "diff_url": "https://github.com/huggingface/datasets/pull/229.diff", "patch_url": "https://github.com/huggingface/datasets/pull/229.patch", "merged_at": null} | value:https://api.github.com/repos/huggingface/datasets/issues/229/events | value:2020-06-03T12:31:44Z | value:https://api.github.com/repos/huggingface/datasets/issues/229/labels{/name} | json:[] | value:NONE | value:2020-06-03T12:52:54Z | json:{"login": "aswin-giridhar", "id": 11817160, "node_id": "MDQ6VXNlcjExODE3MTYw", "avatar_url": "https://avatars.githubusercontent.com/u/11817160?v=4", "gravatar_id": "", "url": "https://api.github.com/users/aswin-giridhar", "html_url": "https://github.com/aswin-giridhar", "followers_url": "https://api.github.com/use... | value:MDExOlB1bGxSZXF1ZXN0NDI3MTcxMzc5 | true | |||||||||
value:2020-07-17T17:44:22Z | value:https://api.github.com/repos/huggingface/datasets/issues/228/timeline | json:{"total": 0, "completed": 0, "percent_completed": 0} | value:4 | value:https://api.github.com/repos/huggingface/datasets | json:{"login": "lhoestq", "id": 42851186, "node_id": "MDQ6VXNlcjQyODUxMTg2", "avatar_url": "https://avatars.githubusercontent.com/u/42851186?v=4", "gravatar_id": "", "url": "https://api.github.com/users/lhoestq", "html_url": "https://github.com/lhoestq", "followers_url": "https://api.github.com/users/lhoestq/followers"... | value:completed | value:closed | value:https://github.com/huggingface/datasets/issues/228 | json:{"login": "srush", "id": 35882, "node_id": "MDQ6VXNlcjM1ODgy", "avatar_url": "https://avatars.githubusercontent.com/u/35882?v=4", "gravatar_id": "", "url": "https://api.github.com/users/srush", "html_url": "https://github.com/srush", "followers_url": "https://api.github.com/users/srush/followers", "following_url":... | value:https://api.github.com/repos/huggingface/datasets/issues/228/comments | value:When I try to access the XNLI dataset, I get the following error. The option of plain_text get selected automatically and then I get the following error.
```
FileNotFoundError: [Errno 2] No such file or directory: '/home/sasha/.cache/huggingface/datasets/xnli/plain_text/1.0.0/dataset_info.json'
Traceback:
F... | value:https://api.github.com/repos/huggingface/datasets/issues/228 | json:[] | value:228 | value:Not able to access the XNLI dataset | value:629952402 | json:[{"id": 2107841032, "node_id": "MDU6TGFiZWwyMTA3ODQxMDMy", "url": "https://api.github.com/repos/huggingface/datasets/labels/nlp-viewer", "name": "nlp-viewer", "color": "94203D", "default": false, "description": "", "archived_at": null, "archived_by": null}] | json:{"blocked_by": 0, "total_blocked_by": 0, "blocking": 0, "total_blocking": 0} | value:False | json:{"url": "https://api.github.com/repos/huggingface/datasets/issues/228/reactions", "total_count": 1, "+1": 1, "-1": 0, "laugh": 0, "hooray": 0, "confused": 0, "heart": 0, "rocket": 0, "eyes": 0} | value:https://api.github.com/repos/huggingface/datasets/issues/228/events | value:2020-06-03T12:25:14Z | value:https://api.github.com/repos/huggingface/datasets/issues/228/labels{/name} | json:[{"login": "srush", "id": 35882, "node_id": "MDQ6VXNlcjM1ODgy", "avatar_url": "https://avatars.githubusercontent.com/u/35882?v=4", "gravatar_id": "", "url": "https://api.github.com/users/srush", "html_url": "https://github.com/srush", "followers_url": "https://api.github.com/users/srush/followers", "following_url"... | value:NONE | value:2020-07-17T17:44:22Z | json:{"login": "aswin-giridhar", "id": 11817160, "node_id": "MDQ6VXNlcjExODE3MTYw", "avatar_url": "https://avatars.githubusercontent.com/u/11817160?v=4", "gravatar_id": "", "url": "https://api.github.com/users/aswin-giridhar", "html_url": "https://github.com/aswin-giridhar", "followers_url": "https://api.github.com/use... | value:MDU6SXNzdWU2Mjk5NTI0MDI= | true | |||||||
value:2020-06-03T15:25:41Z | value:https://api.github.com/repos/huggingface/datasets/issues/227/timeline | json:{"total": 0, "completed": 0, "percent_completed": 0} | value:3 | value:https://api.github.com/repos/huggingface/datasets | json:{"login": "lhoestq", "id": 42851186, "node_id": "MDQ6VXNlcjQyODUxMTg2", "avatar_url": "https://avatars.githubusercontent.com/u/42851186?v=4", "gravatar_id": "", "url": "https://api.github.com/users/lhoestq", "html_url": "https://github.com/lhoestq", "followers_url": "https://api.github.com/users/lhoestq/followers"... | value:completed | value:closed | value:https://github.com/huggingface/datasets/issues/227 | json:{"login": "lhoestq", "id": 42851186, "node_id": "MDQ6VXNlcjQyODUxMTg2", "avatar_url": "https://avatars.githubusercontent.com/u/42851186?v=4", "gravatar_id": "", "url": "https://api.github.com/users/lhoestq", "html_url": "https://github.com/lhoestq", "followers_url": "https://api.github.com/users/lhoestq/followers"... | value:https://api.github.com/repos/huggingface/datasets/issues/227/comments | value:Hi, first thanks to @lhoestq 's revolutionary work, I successfully downloaded processed wikipedia according to the doc. 😍😍😍
But at the first try, it tell me to install `apache_beam` and `mwparserfromhell`, which I thought wouldn't be used according to #204 , it was kind of confusing me at that time.
Mayb... | value:https://api.github.com/repos/huggingface/datasets/issues/227 | json:[] | value:227 | value:Should we still have to force to install apache_beam to download wikipedia ? | value:629845704 | json:[] | json:{"blocked_by": 0, "total_blocked_by": 0, "blocking": 0, "total_blocking": 0} | value:False | json:{"url": "https://api.github.com/repos/huggingface/datasets/issues/227/reactions", "total_count": 0, "+1": 0, "-1": 0, "laugh": 0, "hooray": 0, "confused": 0, "heart": 0, "rocket": 0, "eyes": 0} | value:https://api.github.com/repos/huggingface/datasets/issues/227/events | value:2020-06-03T09:33:20Z | value:https://api.github.com/repos/huggingface/datasets/issues/227/labels{/name} | json:[{"login": "lhoestq", "id": 42851186, "node_id": "MDQ6VXNlcjQyODUxMTg2", "avatar_url": "https://avatars.githubusercontent.com/u/42851186?v=4", "gravatar_id": "", "url": "https://api.github.com/users/lhoestq", "html_url": "https://github.com/lhoestq", "followers_url": "https://api.github.com/users/lhoestq/followers... | value:CONTRIBUTOR | value:2020-06-03T15:25:41Z | json:{"login": "richarddwang", "id": 17963619, "node_id": "MDQ6VXNlcjE3OTYzNjE5", "avatar_url": "https://avatars.githubusercontent.com/u/17963619?v=4", "gravatar_id": "", "url": "https://api.github.com/users/richarddwang", "html_url": "https://github.com/richarddwang", "followers_url": "https://api.github.com/users/ric... | value:MDU6SXNzdWU2Mjk4NDU3MDQ= | true | |||||||
value:2020-06-03T14:37:22Z | value:https://api.github.com/repos/huggingface/datasets/issues/226/timeline | value:1 | value:https://api.github.com/repos/huggingface/datasets | json:{"login": "mariamabarham", "id": 38249783, "node_id": "MDQ6VXNlcjM4MjQ5Nzgz", "avatar_url": "https://avatars.githubusercontent.com/u/38249783?v=4", "gravatar_id": "", "url": "https://api.github.com/users/mariamabarham", "html_url": "https://github.com/mariamabarham", "followers_url": "https://api.github.com/users/... | value:closed | value:https://github.com/huggingface/datasets/pull/226 | value:https://api.github.com/repos/huggingface/datasets/issues/226/comments | value:This PR add the BlendedSkillTalk dataset, which is used to fine tune the blenderbot. | value:False | value:https://api.github.com/repos/huggingface/datasets/issues/226 | json:[] | value:226 | value:add BlendedSkillTalk dataset | value:628344520 | json:[] | value:False | json:{"url": "https://api.github.com/repos/huggingface/datasets/issues/226/reactions", "total_count": 0, "+1": 0, "-1": 0, "laugh": 0, "hooray": 0, "confused": 0, "heart": 0, "rocket": 0, "eyes": 0} | json:{"url": "https://api.github.com/repos/huggingface/datasets/pulls/226", "html_url": "https://github.com/huggingface/datasets/pull/226", "diff_url": "https://github.com/huggingface/datasets/pull/226.diff", "patch_url": "https://github.com/huggingface/datasets/pull/226.patch", "merged_at": "2020-06-03T14:37:22Z"} | value:https://api.github.com/repos/huggingface/datasets/issues/226/events | value:2020-06-01T10:54:45Z | value:https://api.github.com/repos/huggingface/datasets/issues/226/labels{/name} | json:[] | value:CONTRIBUTOR | value:2020-06-03T14:37:23Z | json:{"login": "mariamabarham", "id": 38249783, "node_id": "MDQ6VXNlcjM4MjQ5Nzgz", "avatar_url": "https://avatars.githubusercontent.com/u/38249783?v=4", "gravatar_id": "", "url": "https://api.github.com/users/mariamabarham", "html_url": "https://github.com/mariamabarham", "followers_url": "https://api.github.com/users/... | value:MDExOlB1bGxSZXF1ZXN0NDI1OTA0MjEz | true | |||||||||
value:2020-06-03T15:27:18Z | value:https://api.github.com/repos/huggingface/datasets/issues/225/timeline | json:{"total": 0, "completed": 0, "percent_completed": 0} | value:3 | value:https://api.github.com/repos/huggingface/datasets | json:{"login": "yjernite", "id": 10469459, "node_id": "MDQ6VXNlcjEwNDY5NDU5", "avatar_url": "https://avatars.githubusercontent.com/u/10469459?v=4", "gravatar_id": "", "url": "https://api.github.com/users/yjernite", "html_url": "https://github.com/yjernite", "followers_url": "https://api.github.com/users/yjernite/follow... | value:completed | value:closed | value:https://github.com/huggingface/datasets/issues/225 | json:{"login": "yjernite", "id": 10469459, "node_id": "MDQ6VXNlcjEwNDY5NDU5", "avatar_url": "https://avatars.githubusercontent.com/u/10469459?v=4", "gravatar_id": "", "url": "https://api.github.com/users/yjernite", "html_url": "https://github.com/yjernite", "followers_url": "https://api.github.com/users/yjernite/follow... | value:https://api.github.com/repos/huggingface/datasets/issues/225/comments | value:It seems that the ROUGE score of `nlp` is lower than the one of `files2rouge`.
Here is a self-contained notebook to reproduce both scores : https://colab.research.google.com/drive/14EyAXValB6UzKY9x4rs_T3pyL7alpw_F?usp=sharing
---
`nlp` : (Only mid F-scores)
>rouge1 0.33508031962733364
rouge2 0.145743... | value:https://api.github.com/repos/huggingface/datasets/issues/225 | json:[] | value:225 | value:[ROUGE] Different scores with `files2rouge` | value:628083366 | json:[{"id": 2067400959, "node_id": "MDU6TGFiZWwyMDY3NDAwOTU5", "url": "https://api.github.com/repos/huggingface/datasets/labels/Metric%20discussion", "name": "Metric discussion", "color": "d722e8", "default": false, "description": "Discussions on the metrics", "archived_at": null, "archived_by": null}] | json:{"blocked_by": 0, "total_blocked_by": 0, "blocking": 0, "total_blocking": 0} | value:False | json:{"url": "https://api.github.com/repos/huggingface/datasets/issues/225/reactions", "total_count": 0, "+1": 0, "-1": 0, "laugh": 0, "hooray": 0, "confused": 0, "heart": 0, "rocket": 0, "eyes": 0} | value:https://api.github.com/repos/huggingface/datasets/issues/225/events | value:2020-06-01T00:50:36Z | value:https://api.github.com/repos/huggingface/datasets/issues/225/labels{/name} | json:[{"login": "yjernite", "id": 10469459, "node_id": "MDQ6VXNlcjEwNDY5NDU5", "avatar_url": "https://avatars.githubusercontent.com/u/10469459?v=4", "gravatar_id": "", "url": "https://api.github.com/users/yjernite", "html_url": "https://github.com/yjernite", "followers_url": "https://api.github.com/users/yjernite/follo... | value:NONE | value:2020-06-03T15:27:18Z | json:{"login": "astariul", "id": 43774355, "node_id": "MDQ6VXNlcjQzNzc0MzU1", "avatar_url": "https://avatars.githubusercontent.com/u/43774355?v=4", "gravatar_id": "", "url": "https://api.github.com/users/astariul", "html_url": "https://github.com/astariul", "followers_url": "https://api.github.com/users/astariul/follow... | value:MDU6SXNzdWU2MjgwODMzNjY= | true | |||||||
value:2021-01-04T09:53:32Z | value:https://api.github.com/repos/huggingface/datasets/issues/224/timeline | json:{"total": 0, "completed": 0, "percent_completed": 0} | value:6 | value:https://api.github.com/repos/huggingface/datasets | json:{"login": "yjernite", "id": 10469459, "node_id": "MDQ6VXNlcjEwNDY5NDU5", "avatar_url": "https://avatars.githubusercontent.com/u/10469459?v=4", "gravatar_id": "", "url": "https://api.github.com/users/yjernite", "html_url": "https://github.com/yjernite", "followers_url": "https://api.github.com/users/yjernite/follow... | value:completed | value:closed | value:https://github.com/huggingface/datasets/issues/224 | json:{"login": "yjernite", "id": 10469459, "node_id": "MDQ6VXNlcjEwNDY5NDU5", "avatar_url": "https://avatars.githubusercontent.com/u/10469459?v=4", "gravatar_id": "", "url": "https://api.github.com/users/yjernite", "html_url": "https://github.com/yjernite", "followers_url": "https://api.github.com/users/yjernite/follow... | value:https://api.github.com/repos/huggingface/datasets/issues/224/comments | value:Hi, I am interested in porting google research's new BLEURT learned metric to PyTorch (because I wish to do something experimental with language generation and backpropping through BLEURT). I noticed that you guys don't have it yet so I am partly just asking if you plan to add it (@thomwolf said you want to do so... | value:https://api.github.com/repos/huggingface/datasets/issues/224 | json:[] | value:224 | value:[Feature Request/Help] BLEURT model -> PyTorch | value:627791693 | json:[{"id": 1935892871, "node_id": "MDU6TGFiZWwxOTM1ODkyODcx", "url": "https://api.github.com/repos/huggingface/datasets/labels/enhancement", "name": "enhancement", "color": "a2eeef", "default": true, "description": "New feature or request", "archived_at": null, "archived_by": null}] | json:{"blocked_by": 0, "total_blocked_by": 0, "blocking": 0, "total_blocking": 0} | value:False | json:{"url": "https://api.github.com/repos/huggingface/datasets/issues/224/reactions", "total_count": 1, "+1": 1, "-1": 0, "laugh": 0, "hooray": 0, "confused": 0, "heart": 0, "rocket": 0, "eyes": 0} | value:https://api.github.com/repos/huggingface/datasets/issues/224/events | value:2020-05-30T18:30:40Z | value:https://api.github.com/repos/huggingface/datasets/issues/224/labels{/name} | json:[{"login": "yjernite", "id": 10469459, "node_id": "MDQ6VXNlcjEwNDY5NDU5", "avatar_url": "https://avatars.githubusercontent.com/u/10469459?v=4", "gravatar_id": "", "url": "https://api.github.com/users/yjernite", "html_url": "https://github.com/yjernite", "followers_url": "https://api.github.com/users/yjernite/follo... | value:NONE | value:2023-08-26T17:38:48Z | json:{"login": "adamwlev", "id": 6889910, "node_id": "MDQ6VXNlcjY4ODk5MTA=", "avatar_url": "https://avatars.githubusercontent.com/u/6889910?v=4", "gravatar_id": "", "url": "https://api.github.com/users/adamwlev", "html_url": "https://github.com/adamwlev", "followers_url": "https://api.github.com/users/adamwlev/follower... | value:MDU6SXNzdWU2Mjc3OTE2OTM= | true | |||||||
value:2020-12-03T13:39:33Z | value:https://api.github.com/repos/huggingface/datasets/issues/223/timeline | json:{"total": 0, "completed": 0, "percent_completed": 0} | value:3 | value:https://api.github.com/repos/huggingface/datasets | json:{"login": "yjernite", "id": 10469459, "node_id": "MDQ6VXNlcjEwNDY5NDU5", "avatar_url": "https://avatars.githubusercontent.com/u/10469459?v=4", "gravatar_id": "", "url": "https://api.github.com/users/yjernite", "html_url": "https://github.com/yjernite", "followers_url": "https://api.github.com/users/yjernite/follow... | value:completed | value:closed | value:https://github.com/huggingface/datasets/issues/223 | value:https://api.github.com/repos/huggingface/datasets/issues/223/comments | value:Hi,
I think it would be interesting to add the FLUE dataset for francophones or anyone wishing to work on French.
In other requests, I read that you are already working on some datasets, and I was wondering if FLUE was planned.
If it is not the case, I can provide each of the cleaned FLUE datasets (in th... | value:https://api.github.com/repos/huggingface/datasets/issues/223 | json:[] | value:223 | value:[Feature request] Add FLUE dataset | value:627683386 | json:[{"id": 2067376369, "node_id": "MDU6TGFiZWwyMDY3Mzc2MzY5", "url": "https://api.github.com/repos/huggingface/datasets/labels/dataset%20request", "name": "dataset request", "color": "e99695", "default": false, "description": "Requesting to add a new dataset", "archived_at": null, "archived_by": null}] | json:{"blocked_by": 0, "total_blocked_by": 0, "blocking": 0, "total_blocking": 0} | value:False | json:{"url": "https://api.github.com/repos/huggingface/datasets/issues/223/reactions", "total_count": 0, "+1": 0, "-1": 0, "laugh": 0, "hooray": 0, "confused": 0, "heart": 0, "rocket": 0, "eyes": 0} | value:https://api.github.com/repos/huggingface/datasets/issues/223/events | value:2020-05-30T08:52:15Z | value:https://api.github.com/repos/huggingface/datasets/issues/223/labels{/name} | json:[] | value:NONE | value:2020-12-03T13:39:33Z | json:{"login": "lbourdois", "id": 58078086, "node_id": "MDQ6VXNlcjU4MDc4MDg2", "avatar_url": "https://avatars.githubusercontent.com/u/58078086?v=4", "gravatar_id": "", "url": "https://api.github.com/users/lbourdois", "html_url": "https://github.com/lbourdois", "followers_url": "https://api.github.com/users/lbourdois/fo... | value:MDU6SXNzdWU2Mjc2ODMzODY= | true | ||||||||
value:2020-06-04T00:21:05Z | value:https://api.github.com/repos/huggingface/datasets/issues/222/timeline | json:{"total": 0, "completed": 0, "percent_completed": 0} | value:6 | value:https://api.github.com/repos/huggingface/datasets | json:{"login": "carlos-aguayo", "id": 338917, "node_id": "MDQ6VXNlcjMzODkxNw==", "avatar_url": "https://avatars.githubusercontent.com/u/338917?v=4", "gravatar_id": "", "url": "https://api.github.com/users/carlos-aguayo", "html_url": "https://github.com/carlos-aguayo", "followers_url": "https://api.github.com/users/carl... | value:completed | value:closed | value:https://github.com/huggingface/datasets/issues/222 | value:https://api.github.com/repos/huggingface/datasets/issues/222/comments | value:When I run the notebook in Colab
https://colab.research.google.com/github/huggingface/nlp/blob/master/notebooks/Overview.ipynb
breaks when running this cell:
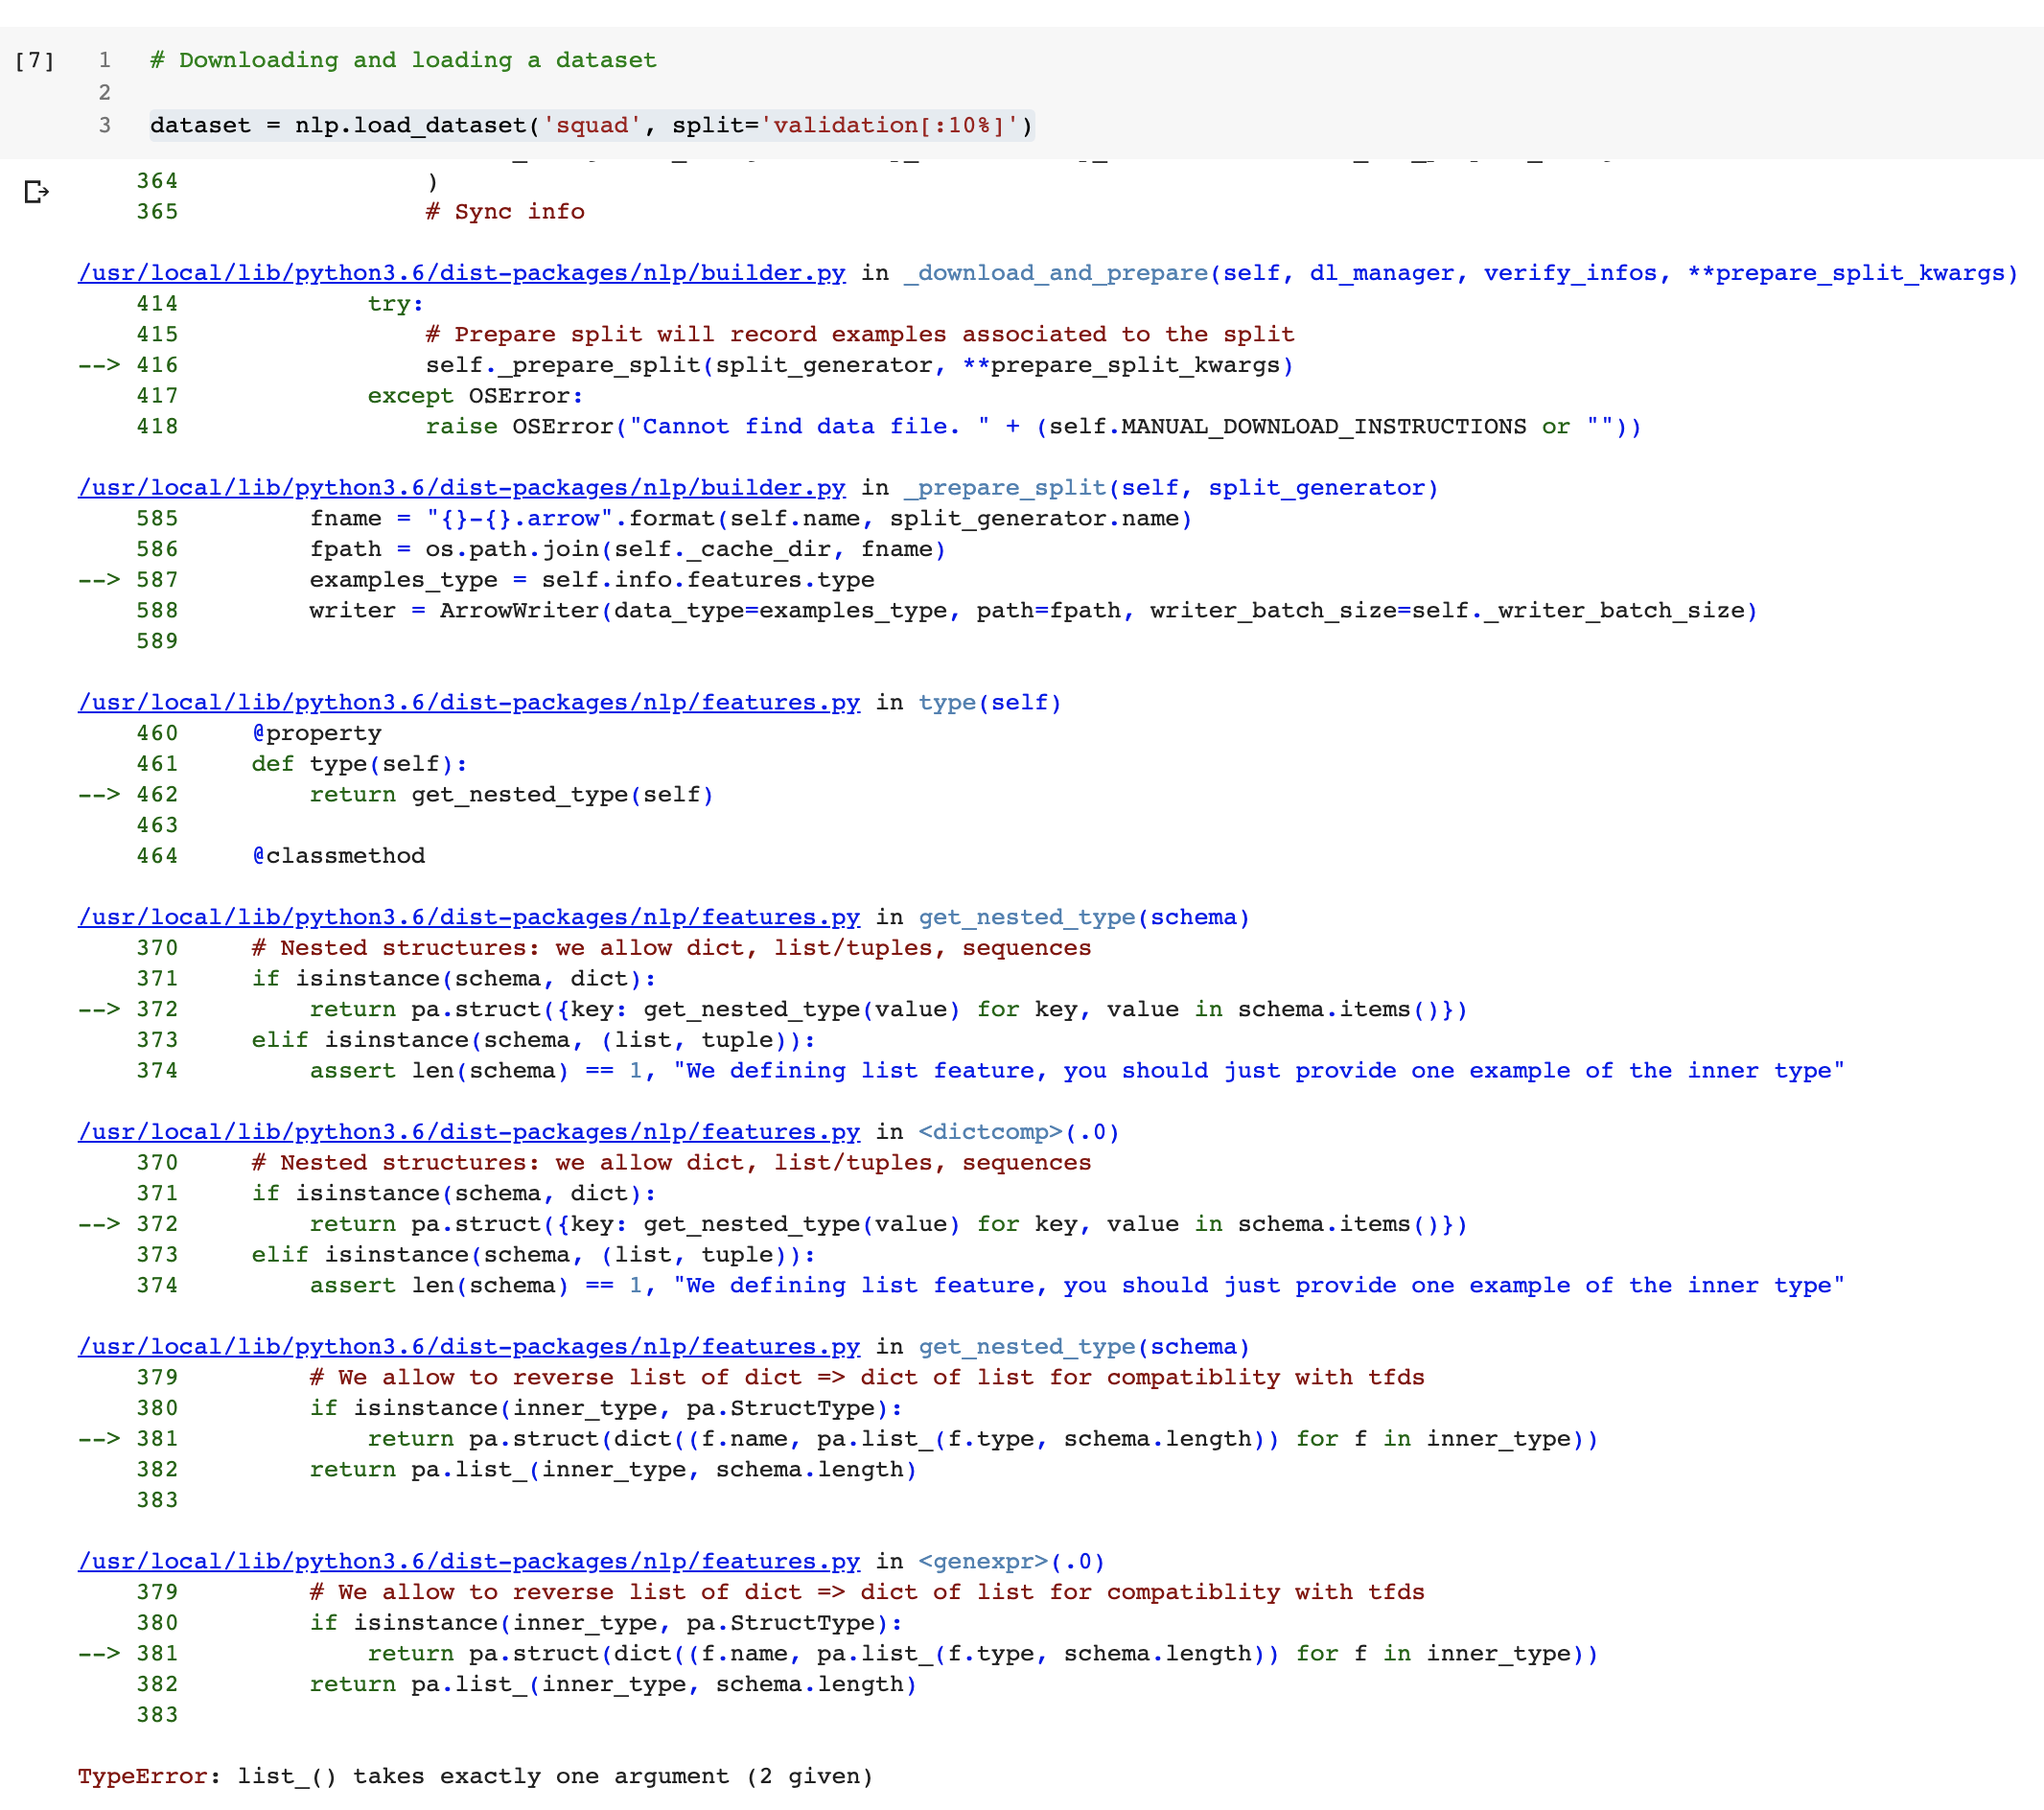
| value:https://api.github.com/repos/huggingface/datasets/issues/222 | json:[] | value:222 | value:Colab Notebook breaks when downloading the squad dataset | value:627586690 | json:[] | json:{"blocked_by": 0, "total_blocked_by": 0, "blocking": 0, "total_blocking": 0} | value:False | json:{"url": "https://api.github.com/repos/huggingface/datasets/issues/222/reactions", "total_count": 0, "+1": 0, "-1": 0, "laugh": 0, "hooray": 0, "confused": 0, "heart": 0, "rocket": 0, "eyes": 0} | value:https://api.github.com/repos/huggingface/datasets/issues/222/events | value:2020-05-29T22:55:59Z | value:https://api.github.com/repos/huggingface/datasets/issues/222/labels{/name} | json:[] | value:NONE | value:2020-06-04T00:21:05Z | json:{"login": "carlos-aguayo", "id": 338917, "node_id": "MDQ6VXNlcjMzODkxNw==", "avatar_url": "https://avatars.githubusercontent.com/u/338917?v=4", "gravatar_id": "", "url": "https://api.github.com/users/carlos-aguayo", "html_url": "https://github.com/carlos-aguayo", "followers_url": "https://api.github.com/users/carl... | value:MDU6SXNzdWU2Mjc1ODY2OTA= | true | ||||||||
value:2020-05-29T15:02:23Z | value:https://api.github.com/repos/huggingface/datasets/issues/221/timeline | value:1 | value:https://api.github.com/repos/huggingface/datasets | json:{"login": "lhoestq", "id": 42851186, "node_id": "MDQ6VXNlcjQyODUxMTg2", "avatar_url": "https://avatars.githubusercontent.com/u/42851186?v=4", "gravatar_id": "", "url": "https://api.github.com/users/lhoestq", "html_url": "https://github.com/lhoestq", "followers_url": "https://api.github.com/users/lhoestq/followers"... | value:closed | value:https://github.com/huggingface/datasets/pull/221 | value:https://api.github.com/repos/huggingface/datasets/issues/221/comments | value:When I run the command `RUN_SLOW=1 pytest tests/test_dataset_common.py::LocalDatasetTest::test_load_real_dataset_arcd` while working on #220. I get the error ` unexpected keyword argument "'download_and_prepare_kwargs'"` at the level of `load_dataset`. Indeed, this [function](https://github.com/huggingface/nlp/b... | value:False | value:https://api.github.com/repos/huggingface/datasets/issues/221 | json:[] | value:221 | value:Fix tests/test_dataset_common.py | value:627300648 | json:[] | value:False | json:{"url": "https://api.github.com/repos/huggingface/datasets/issues/221/reactions", "total_count": 0, "+1": 0, "-1": 0, "laugh": 0, "hooray": 0, "confused": 0, "heart": 0, "rocket": 0, "eyes": 0} | json:{"url": "https://api.github.com/repos/huggingface/datasets/pulls/221", "html_url": "https://github.com/huggingface/datasets/pull/221", "diff_url": "https://github.com/huggingface/datasets/pull/221.diff", "patch_url": "https://github.com/huggingface/datasets/pull/221.patch", "merged_at": "2020-05-29T15:02:23Z"} | value:https://api.github.com/repos/huggingface/datasets/issues/221/events | value:2020-05-29T14:12:15Z | value:https://api.github.com/repos/huggingface/datasets/issues/221/labels{/name} | json:[] | value:CONTRIBUTOR | value:2020-06-01T12:20:42Z | json:{"login": "tayciryahmed", "id": 13635495, "node_id": "MDQ6VXNlcjEzNjM1NDk1", "avatar_url": "https://avatars.githubusercontent.com/u/13635495?v=4", "gravatar_id": "", "url": "https://api.github.com/users/tayciryahmed", "html_url": "https://github.com/tayciryahmed", "followers_url": "https://api.github.com/users/tay... | value:MDExOlB1bGxSZXF1ZXN0NDI1MTI5OTc0 | true | |||||||||
value:2020-05-29T14:57:21Z | value:https://api.github.com/repos/huggingface/datasets/issues/220/timeline | value:2 | value:https://api.github.com/repos/huggingface/datasets | json:{"login": "lhoestq", "id": 42851186, "node_id": "MDQ6VXNlcjQyODUxMTg2", "avatar_url": "https://avatars.githubusercontent.com/u/42851186?v=4", "gravatar_id": "", "url": "https://api.github.com/users/lhoestq", "html_url": "https://github.com/lhoestq", "followers_url": "https://api.github.com/users/lhoestq/followers"... | value:closed | value:https://github.com/huggingface/datasets/pull/220 | value:https://api.github.com/repos/huggingface/datasets/issues/220/comments | value:Added Arabic Reading Comprehension Dataset (ARCD): https://arxiv.org/abs/1906.05394 | value:False | value:https://api.github.com/repos/huggingface/datasets/issues/220 | json:[] | value:220 | value:dataset_arcd | value:627280683 | json:[] | value:False | json:{"url": "https://api.github.com/repos/huggingface/datasets/issues/220/reactions", "total_count": 1, "+1": 0, "-1": 0, "laugh": 0, "hooray": 1, "confused": 0, "heart": 0, "rocket": 0, "eyes": 0} | json:{"url": "https://api.github.com/repos/huggingface/datasets/pulls/220", "html_url": "https://github.com/huggingface/datasets/pull/220", "diff_url": "https://github.com/huggingface/datasets/pull/220.diff", "patch_url": "https://github.com/huggingface/datasets/pull/220.patch", "merged_at": "2020-05-29T14:57:21Z"} | value:https://api.github.com/repos/huggingface/datasets/issues/220/events | value:2020-05-29T13:46:50Z | value:https://api.github.com/repos/huggingface/datasets/issues/220/labels{/name} | json:[] | value:CONTRIBUTOR | value:2020-05-29T14:58:40Z | json:{"login": "tayciryahmed", "id": 13635495, "node_id": "MDQ6VXNlcjEzNjM1NDk1", "avatar_url": "https://avatars.githubusercontent.com/u/13635495?v=4", "gravatar_id": "", "url": "https://api.github.com/users/tayciryahmed", "html_url": "https://github.com/tayciryahmed", "followers_url": "https://api.github.com/users/tay... | value:MDExOlB1bGxSZXF1ZXN0NDI1MTEzMzEy | true | |||||||||
value:2020-05-29T13:30:12Z | value:https://api.github.com/repos/huggingface/datasets/issues/219/timeline | value:0 | value:https://api.github.com/repos/huggingface/datasets | json:{"login": "lhoestq", "id": 42851186, "node_id": "MDQ6VXNlcjQyODUxMTg2", "avatar_url": "https://avatars.githubusercontent.com/u/42851186?v=4", "gravatar_id": "", "url": "https://api.github.com/users/lhoestq", "html_url": "https://github.com/lhoestq", "followers_url": "https://api.github.com/users/lhoestq/followers"... | value:closed | value:https://github.com/huggingface/datasets/pull/219 | value:https://api.github.com/repos/huggingface/datasets/issues/219/comments | value:This should fix your env because you had `mwparserfromhell ` as a first party for `isort` @patrickvonplaten | value:False | value:https://api.github.com/repos/huggingface/datasets/issues/219 | json:[] | value:219 | value:force mwparserfromhell as third party | value:627235893 | json:[] | value:False | json:{"url": "https://api.github.com/repos/huggingface/datasets/issues/219/reactions", "total_count": 0, "+1": 0, "-1": 0, "laugh": 0, "hooray": 0, "confused": 0, "heart": 0, "rocket": 0, "eyes": 0} | json:{"url": "https://api.github.com/repos/huggingface/datasets/pulls/219", "html_url": "https://github.com/huggingface/datasets/pull/219", "diff_url": "https://github.com/huggingface/datasets/pull/219.diff", "patch_url": "https://github.com/huggingface/datasets/pull/219.patch", "merged_at": "2020-05-29T13:30:12Z"} | value:https://api.github.com/repos/huggingface/datasets/issues/219/events | value:2020-05-29T12:33:17Z | value:https://api.github.com/repos/huggingface/datasets/issues/219/labels{/name} | json:[] | value:MEMBER | value:2020-05-29T13:30:13Z | json:{"login": "lhoestq", "id": 42851186, "node_id": "MDQ6VXNlcjQyODUxMTg2", "avatar_url": "https://avatars.githubusercontent.com/u/42851186?v=4", "gravatar_id": "", "url": "https://api.github.com/users/lhoestq", "html_url": "https://github.com/lhoestq", "followers_url": "https://api.github.com/users/lhoestq/followers"... | value:MDExOlB1bGxSZXF1ZXN0NDI1MDc2NjQx | true | |||||||||
value:2020-05-29T12:31:00Z | value:https://api.github.com/repos/huggingface/datasets/issues/218/timeline | value:0 | value:https://api.github.com/repos/huggingface/datasets | json:{"login": "lhoestq", "id": 42851186, "node_id": "MDQ6VXNlcjQyODUxMTg2", "avatar_url": "https://avatars.githubusercontent.com/u/42851186?v=4", "gravatar_id": "", "url": "https://api.github.com/users/lhoestq", "html_url": "https://github.com/lhoestq", "followers_url": "https://api.github.com/users/lhoestq/followers"... | value:closed | value:https://github.com/huggingface/datasets/pull/218 | value:https://api.github.com/repos/huggingface/datasets/issues/218/comments | value:Scripts are ready !
However they are not processed nor directly available from gcp yet. | value:False | value:https://api.github.com/repos/huggingface/datasets/issues/218 | json:[] | value:218 | value:Add Natual Questions and C4 scripts | value:627173407 | json:[] | value:False | json:{"url": "https://api.github.com/repos/huggingface/datasets/issues/218/reactions", "total_count": 0, "+1": 0, "-1": 0, "laugh": 0, "hooray": 0, "confused": 0, "heart": 0, "rocket": 0, "eyes": 0} | json:{"url": "https://api.github.com/repos/huggingface/datasets/pulls/218", "html_url": "https://github.com/huggingface/datasets/pull/218", "diff_url": "https://github.com/huggingface/datasets/pull/218.diff", "patch_url": "https://github.com/huggingface/datasets/pull/218.patch", "merged_at": "2020-05-29T12:31:00Z"} | value:https://api.github.com/repos/huggingface/datasets/issues/218/events | value:2020-05-29T10:40:30Z | value:https://api.github.com/repos/huggingface/datasets/issues/218/labels{/name} | json:[] | value:MEMBER | value:2020-05-29T12:31:01Z | json:{"login": "lhoestq", "id": 42851186, "node_id": "MDQ6VXNlcjQyODUxMTg2", "avatar_url": "https://avatars.githubusercontent.com/u/42851186?v=4", "gravatar_id": "", "url": "https://api.github.com/users/lhoestq", "html_url": "https://github.com/lhoestq", "followers_url": "https://api.github.com/users/lhoestq/followers"... | value:MDExOlB1bGxSZXF1ZXN0NDI1MDI2NzEz | true | |||||||||
value:2026-10-01T13:01:22Z | value:https://api.github.com/repos/huggingface/datasets/issues/217/timeline | json:{"total": 0, "completed": 0, "percent_completed": 0} | value:30 | value:https://api.github.com/repos/huggingface/datasets | json:{"login": "lhoestq", "id": 42851186, "node_id": "MDQ6VXNlcjQyODUxMTg2", "avatar_url": "https://avatars.githubusercontent.com/u/42851186?v=4", "gravatar_id": "", "url": "https://api.github.com/users/lhoestq", "html_url": "https://github.com/lhoestq", "followers_url": "https://api.github.com/users/lhoestq/followers"... | value:completed | value:closed | value:https://github.com/huggingface/datasets/issues/217 | value:https://api.github.com/repos/huggingface/datasets/issues/217/comments | value:It seems like many of the best performing models on the GLUE benchmark make some use of multitask learning (simultaneous training on multiple tasks).
The [T5 paper](https://arxiv.org/pdf/1910.10683.pdf) highlights multiple ways of mixing the tasks together during finetuning:
- **Examples-proportional mixing**... | value:https://api.github.com/repos/huggingface/datasets/issues/217 | json:[] | value:217 | value:Multi-task dataset mixing | value:627128403 | json:[{"id": 1935892871, "node_id": "MDU6TGFiZWwxOTM1ODkyODcx", "url": "https://api.github.com/repos/huggingface/datasets/labels/enhancement", "name": "enhancement", "color": "a2eeef", "default": true, "description": "New feature or request", "archived_at": null, "archived_by": null}, {"id": 2067400324, "node_id": "MDU... | json:{"blocked_by": 0, "total_blocked_by": 0, "blocking": 0, "total_blocking": 0} | value:False | json:{"url": "https://api.github.com/repos/huggingface/datasets/issues/217/reactions", "total_count": 12, "+1": 12, "-1": 0, "laugh": 0, "hooray": 0, "confused": 0, "heart": 0, "rocket": 0, "eyes": 0} | value:https://api.github.com/repos/huggingface/datasets/issues/217/events | value:2020-05-29T09:22:26Z | value:https://api.github.com/repos/huggingface/datasets/issues/217/labels{/name} | json:[] | value:CONTRIBUTOR | value:2026-10-01T13:01:22Z | json:{"login": "ghomasHudson", "id": 13795113, "node_id": "MDQ6VXNlcjEzNzk1MTEz", "avatar_url": "https://avatars.githubusercontent.com/u/13795113?v=4", "gravatar_id": "", "url": "https://api.github.com/users/ghomasHudson", "html_url": "https://github.com/ghomasHudson", "followers_url": "https://api.github.com/users/gho... | value:MDU6SXNzdWU2MjcxMjg0MDM= | true | ||||||||
value:2020-06-01T00:04:35Z | value:https://api.github.com/repos/huggingface/datasets/issues/216/timeline | json:{"total": 0, "completed": 0, "percent_completed": 0} | value:3 | value:https://api.github.com/repos/huggingface/datasets | json:{"login": "astariul", "id": 43774355, "node_id": "MDQ6VXNlcjQzNzc0MzU1", "avatar_url": "https://avatars.githubusercontent.com/u/43774355?v=4", "gravatar_id": "", "url": "https://api.github.com/users/astariul", "html_url": "https://github.com/astariul", "followers_url": "https://api.github.com/users/astariul/follow... | value:completed | value:closed | value:https://github.com/huggingface/datasets/issues/216 | value:https://api.github.com/repos/huggingface/datasets/issues/216/comments | value:I'm trying to use ROUGE metric, but I don't know how to get the ROUGE-2 metric.
---
I compute scores with :
```python
import nlp
rouge = nlp.load_metric('rouge')
with open("pred.txt") as p, open("ref.txt") as g:
for lp, lg in zip(p, g):
rouge.add([lp], [lg])
score = rouge.compute()
`... | value:https://api.github.com/repos/huggingface/datasets/issues/216 | json:[] | value:216 | value:❓ How to get ROUGE-2 with the ROUGE metric ? | value:626896890 | json:[] | json:{"blocked_by": 0, "total_blocked_by": 0, "blocking": 0, "total_blocking": 0} | value:False | json:{"url": "https://api.github.com/repos/huggingface/datasets/issues/216/reactions", "total_count": 0, "+1": 0, "-1": 0, "laugh": 0, "hooray": 0, "confused": 0, "heart": 0, "rocket": 0, "eyes": 0} | value:https://api.github.com/repos/huggingface/datasets/issues/216/events | value:2020-05-28T23:47:32Z | value:https://api.github.com/repos/huggingface/datasets/issues/216/labels{/name} | json:[] | value:NONE | value:2020-06-01T00:04:35Z | json:{"login": "astariul", "id": 43774355, "node_id": "MDQ6VXNlcjQzNzc0MzU1", "avatar_url": "https://avatars.githubusercontent.com/u/43774355?v=4", "gravatar_id": "", "url": "https://api.github.com/users/astariul", "html_url": "https://github.com/astariul", "followers_url": "https://api.github.com/users/astariul/follow... | value:MDU6SXNzdWU2MjY4OTY4OTA= | true | ||||||||
value:2022-02-10T13:05:45Z | value:https://api.github.com/repos/huggingface/datasets/issues/215/timeline | json:{"total": 0, "completed": 0, "percent_completed": 0} | value:12 | value:https://api.github.com/repos/huggingface/datasets | json:{"login": "albertvillanova", "id": 8515462, "node_id": "MDQ6VXNlcjg1MTU0NjI=", "avatar_url": "https://avatars.githubusercontent.com/u/8515462?v=4", "gravatar_id": "", "url": "https://api.github.com/users/albertvillanova", "html_url": "https://github.com/albertvillanova", "followers_url": "https://api.github.com/us... | value:completed | value:closed | value:https://github.com/huggingface/datasets/issues/215 | value:https://api.github.com/repos/huggingface/datasets/issues/215/comments | value:Getting this error when i run `nlp.load_dataset('blog_authorship_corpus')`.
```
raise NonMatchingSplitsSizesError(str(bad_splits))
nlp.utils.info_utils.NonMatchingSplitsSizesError: [{'expected': SplitInfo(name='train',
num_bytes=610252351, num_examples=532812, dataset_name='blog_authorship_corpus'),
're... | value:https://api.github.com/repos/huggingface/datasets/issues/215 | json:[] | value:215 | value:NonMatchingSplitsSizesError when loading blog_authorship_corpus | value:626867879 | json:[{"id": 2067388877, "node_id": "MDU6TGFiZWwyMDY3Mzg4ODc3", "url": "https://api.github.com/repos/huggingface/datasets/labels/dataset%20bug", "name": "dataset bug", "color": "2edb81", "default": false, "description": "A bug in a dataset script provided in the library", "archived_at": null, "archived_by": null}] | json:{"blocked_by": 0, "total_blocked_by": 0, "blocking": 0, "total_blocking": 0} | value:False | json:{"url": "https://api.github.com/repos/huggingface/datasets/issues/215/reactions", "total_count": 0, "+1": 0, "-1": 0, "laugh": 0, "hooray": 0, "confused": 0, "heart": 0, "rocket": 0, "eyes": 0} | value:https://api.github.com/repos/huggingface/datasets/issues/215/events | value:2020-05-28T22:55:19Z | value:https://api.github.com/repos/huggingface/datasets/issues/215/labels{/name} | json:[] | value:NONE | value:2025-01-04T00:03:12Z | json:{"login": "cedricconol", "id": 52105365, "node_id": "MDQ6VXNlcjUyMTA1MzY1", "avatar_url": "https://avatars.githubusercontent.com/u/52105365?v=4", "gravatar_id": "", "url": "https://api.github.com/users/cedricconol", "html_url": "https://github.com/cedricconol", "followers_url": "https://api.github.com/users/cedric... | value:MDU6SXNzdWU2MjY4Njc4Nzk= | true | ||||||||
value:2020-05-29T11:32:20Z | value:https://api.github.com/repos/huggingface/datasets/issues/214/timeline | value:13 | value:https://api.github.com/repos/huggingface/datasets | json:{"login": "patrickvonplaten", "id": 23423619, "node_id": "MDQ6VXNlcjIzNDIzNjE5", "avatar_url": "https://avatars.githubusercontent.com/u/23423619?v=4", "gravatar_id": "", "url": "https://api.github.com/users/patrickvonplaten", "html_url": "https://github.com/patrickvonplaten", "followers_url": "https://api.github.c... | value:closed | value:https://github.com/huggingface/datasets/pull/214 | value:https://api.github.com/repos/huggingface/datasets/issues/214/comments | value:The `.map()` function is super useful, but can IMO a bit tedious when filtering certain examples.
I think, filtering out examples is also a very common operation people would like to perform on datasets.
This PR is a proposal to add a `.filter()` function in the same spirit than the `.map()` function.
Here... | value:False | value:https://api.github.com/repos/huggingface/datasets/issues/214 | json:[] | value:214 | value:[arrow_dataset.py] add new filter function | value:626641549 | json:[] | value:False | json:{"url": "https://api.github.com/repos/huggingface/datasets/issues/214/reactions", "total_count": 0, "+1": 0, "-1": 0, "laugh": 0, "hooray": 0, "confused": 0, "heart": 0, "rocket": 0, "eyes": 0} | json:{"url": "https://api.github.com/repos/huggingface/datasets/pulls/214", "html_url": "https://github.com/huggingface/datasets/pull/214", "diff_url": "https://github.com/huggingface/datasets/pull/214.diff", "patch_url": "https://github.com/huggingface/datasets/pull/214.patch", "merged_at": "2020-05-29T11:32:20Z"} | value:https://api.github.com/repos/huggingface/datasets/issues/214/events | value:2020-05-28T16:21:40Z | value:https://api.github.com/repos/huggingface/datasets/issues/214/labels{/name} | json:[] | value:CONTRIBUTOR | value:2020-05-29T11:43:29Z | json:{"login": "patrickvonplaten", "id": 23423619, "node_id": "MDQ6VXNlcjIzNDIzNjE5", "avatar_url": "https://avatars.githubusercontent.com/u/23423619?v=4", "gravatar_id": "", "url": "https://api.github.com/users/patrickvonplaten", "html_url": "https://github.com/patrickvonplaten", "followers_url": "https://api.github.c... | value:MDExOlB1bGxSZXF1ZXN0NDI0NTk1NjIx | true | |||||||||
value:2020-05-29T09:51:16Z | value:https://api.github.com/repos/huggingface/datasets/issues/213/timeline | value:0 | value:https://api.github.com/repos/huggingface/datasets | json:{"login": "lhoestq", "id": 42851186, "node_id": "MDQ6VXNlcjQyODUxMTg2", "avatar_url": "https://avatars.githubusercontent.com/u/42851186?v=4", "gravatar_id": "", "url": "https://api.github.com/users/lhoestq", "html_url": "https://github.com/lhoestq", "followers_url": "https://api.github.com/users/lhoestq/followers"... | value:closed | value:https://github.com/huggingface/datasets/pull/213 | value:https://api.github.com/repos/huggingface/datasets/issues/213/comments | value:WDYT @yjernite ?
For example:
```python
dataset = nlp.load_dataset('wikipedia', '20200501.aa')
```
Raises:
```
MissingBeamOptions: Trying to generate a dataset using Apache Beam, yet no Beam Runner or PipelineOptions() has been provided in `load_dataset` or in the builder arguments. For big datasets it has... | value:False | value:https://api.github.com/repos/huggingface/datasets/issues/213 | json:[] | value:213 | value:better message if missing beam options | value:626587995 | json:[] | value:False | json:{"url": "https://api.github.com/repos/huggingface/datasets/issues/213/reactions", "total_count": 0, "+1": 0, "-1": 0, "laugh": 0, "hooray": 0, "confused": 0, "heart": 0, "rocket": 0, "eyes": 0} | json:{"url": "https://api.github.com/repos/huggingface/datasets/pulls/213", "html_url": "https://github.com/huggingface/datasets/pull/213", "diff_url": "https://github.com/huggingface/datasets/pull/213.diff", "patch_url": "https://github.com/huggingface/datasets/pull/213.patch", "merged_at": "2020-05-29T09:51:16Z"} | value:https://api.github.com/repos/huggingface/datasets/issues/213/events | value:2020-05-28T15:06:57Z | value:https://api.github.com/repos/huggingface/datasets/issues/213/labels{/name} | json:[] | value:MEMBER | value:2020-05-29T09:51:17Z | json:{"login": "lhoestq", "id": 42851186, "node_id": "MDQ6VXNlcjQyODUxMTg2", "avatar_url": "https://avatars.githubusercontent.com/u/42851186?v=4", "gravatar_id": "", "url": "https://api.github.com/users/lhoestq", "html_url": "https://github.com/lhoestq", "followers_url": "https://api.github.com/users/lhoestq/followers"... | value:MDExOlB1bGxSZXF1ZXN0NDI0NTUxODE3 | true | |||||||||
value:2020-05-29T10:41:04Z | value:https://api.github.com/repos/huggingface/datasets/issues/212/timeline | value:0 | value:https://api.github.com/repos/huggingface/datasets | json:{"login": "lhoestq", "id": 42851186, "node_id": "MDQ6VXNlcjQyODUxMTg2", "avatar_url": "https://avatars.githubusercontent.com/u/42851186?v=4", "gravatar_id": "", "url": "https://api.github.com/users/lhoestq", "html_url": "https://github.com/lhoestq", "followers_url": "https://api.github.com/users/lhoestq/followers"... | value:closed | value:https://github.com/huggingface/datasets/pull/212 | value:https://api.github.com/repos/huggingface/datasets/issues/212/comments | value:This should fix #116
Previously the `.add` method of metrics expected a batch of examples.
Now `.add` expects one prediction/reference and `.add_batch` expects a batch.
I think it is more coherent with the way the ArrowWriter works. | value:False | value:https://api.github.com/repos/huggingface/datasets/issues/212 | json:[] | value:212 | value:have 'add' and 'add_batch' for metrics | value:626580198 | json:[] | value:False | json:{"url": "https://api.github.com/repos/huggingface/datasets/issues/212/reactions", "total_count": 0, "+1": 0, "-1": 0, "laugh": 0, "hooray": 0, "confused": 0, "heart": 0, "rocket": 0, "eyes": 0} | json:{"url": "https://api.github.com/repos/huggingface/datasets/pulls/212", "html_url": "https://github.com/huggingface/datasets/pull/212", "diff_url": "https://github.com/huggingface/datasets/pull/212.diff", "patch_url": "https://github.com/huggingface/datasets/pull/212.patch", "merged_at": "2020-05-29T10:41:04Z"} | value:https://api.github.com/repos/huggingface/datasets/issues/212/events | value:2020-05-28T14:56:47Z | value:https://api.github.com/repos/huggingface/datasets/issues/212/labels{/name} | json:[] | value:MEMBER | value:2020-05-29T10:41:05Z | json:{"login": "lhoestq", "id": 42851186, "node_id": "MDQ6VXNlcjQyODUxMTg2", "avatar_url": "https://avatars.githubusercontent.com/u/42851186?v=4", "gravatar_id": "", "url": "https://api.github.com/users/lhoestq", "html_url": "https://github.com/lhoestq", "followers_url": "https://api.github.com/users/lhoestq/followers"... | value:MDExOlB1bGxSZXF1ZXN0NDI0NTQ1NjAy | true | |||||||||
value:2020-07-23T10:15:16Z | value:https://api.github.com/repos/huggingface/datasets/issues/211/timeline | json:{"total": 0, "completed": 0, "percent_completed": 0} | value:7 | value:https://api.github.com/repos/huggingface/datasets | json:{"login": "lhoestq", "id": 42851186, "node_id": "MDQ6VXNlcjQyODUxMTg2", "avatar_url": "https://avatars.githubusercontent.com/u/42851186?v=4", "gravatar_id": "", "url": "https://api.github.com/users/lhoestq", "html_url": "https://github.com/lhoestq", "followers_url": "https://api.github.com/users/lhoestq/followers"... | value:completed | value:closed | value:https://github.com/huggingface/datasets/issues/211 | json:{"login": "thomwolf", "id": 7353373, "node_id": "MDQ6VXNlcjczNTMzNzM=", "avatar_url": "https://avatars.githubusercontent.com/u/7353373?v=4", "gravatar_id": "", "url": "https://api.github.com/users/thomwolf", "html_url": "https://github.com/thomwolf", "followers_url": "https://api.github.com/users/thomwolf/follower... | value:https://api.github.com/repos/huggingface/datasets/issues/211/comments | value:Running the following code
```
import nlp
ds = nlp.load_dataset("trivia_qa", "rc", split="validation[:1%]") # this might take 2.3 min to download but it's cached afterwards...
ds.map(lambda x: x, load_from_cache_file=False)
```
triggers a `ArrowInvalid: Could not convert TagMe with type str: convertin... | value:https://api.github.com/repos/huggingface/datasets/issues/211 | json:[] | value:211 | value:[Arrow writer, Trivia_qa] Could not convert TagMe with type str: converting to null type | value:626565994 | json:[{"id": 1935892871, "node_id": "MDU6TGFiZWwxOTM1ODkyODcx", "url": "https://api.github.com/repos/huggingface/datasets/labels/enhancement", "name": "enhancement", "color": "a2eeef", "default": true, "description": "New feature or request", "archived_at": null, "archived_by": null}] | json:{"blocked_by": 0, "total_blocked_by": 0, "blocking": 0, "total_blocking": 0} | value:False | json:{"url": "https://api.github.com/repos/huggingface/datasets/issues/211/reactions", "total_count": 0, "+1": 0, "-1": 0, "laugh": 0, "hooray": 0, "confused": 0, "heart": 0, "rocket": 0, "eyes": 0} | value:https://api.github.com/repos/huggingface/datasets/issues/211/events | value:2020-05-28T14:38:14Z | value:https://api.github.com/repos/huggingface/datasets/issues/211/labels{/name} | json:[{"login": "thomwolf", "id": 7353373, "node_id": "MDQ6VXNlcjczNTMzNzM=", "avatar_url": "https://avatars.githubusercontent.com/u/7353373?v=4", "gravatar_id": "", "url": "https://api.github.com/users/thomwolf", "html_url": "https://github.com/thomwolf", "followers_url": "https://api.github.com/users/thomwolf/followe... | value:CONTRIBUTOR | value:2020-07-23T10:15:16Z | json:{"login": "patrickvonplaten", "id": 23423619, "node_id": "MDQ6VXNlcjIzNDIzNjE5", "avatar_url": "https://avatars.githubusercontent.com/u/23423619?v=4", "gravatar_id": "", "url": "https://api.github.com/users/patrickvonplaten", "html_url": "https://github.com/patrickvonplaten", "followers_url": "https://api.github.c... | value:MDU6SXNzdWU2MjY1NjU5OTQ= | true | |||||||
value:2020-05-28T13:22:10Z | value:https://api.github.com/repos/huggingface/datasets/issues/210/timeline | value:0 | value:https://api.github.com/repos/huggingface/datasets | json:{"login": "lhoestq", "id": 42851186, "node_id": "MDQ6VXNlcjQyODUxMTg2", "avatar_url": "https://avatars.githubusercontent.com/u/42851186?v=4", "gravatar_id": "", "url": "https://api.github.com/users/lhoestq", "html_url": "https://github.com/lhoestq", "followers_url": "https://api.github.com/users/lhoestq/followers"... | value:closed | value:https://github.com/huggingface/datasets/pull/210 | value:https://api.github.com/repos/huggingface/datasets/issues/210/comments | value:The text was wrong as noticed in #202 | value:False | value:https://api.github.com/repos/huggingface/datasets/issues/210 | json:[] | value:210 | value:fix xnli metric kwargs description | value:626504243 | json:[] | value:False | json:{"url": "https://api.github.com/repos/huggingface/datasets/issues/210/reactions", "total_count": 0, "+1": 0, "-1": 0, "laugh": 0, "hooray": 0, "confused": 0, "heart": 0, "rocket": 0, "eyes": 0} | json:{"url": "https://api.github.com/repos/huggingface/datasets/pulls/210", "html_url": "https://github.com/huggingface/datasets/pull/210", "diff_url": "https://github.com/huggingface/datasets/pull/210.diff", "patch_url": "https://github.com/huggingface/datasets/pull/210.patch", "merged_at": "2020-05-28T13:22:10Z"} | value:https://api.github.com/repos/huggingface/datasets/issues/210/events | value:2020-05-28T13:21:44Z | value:https://api.github.com/repos/huggingface/datasets/issues/210/labels{/name} | json:[] | value:MEMBER | value:2020-05-28T13:22:11Z | json:{"login": "lhoestq", "id": 42851186, "node_id": "MDQ6VXNlcjQyODUxMTg2", "avatar_url": "https://avatars.githubusercontent.com/u/42851186?v=4", "gravatar_id": "", "url": "https://api.github.com/users/lhoestq", "html_url": "https://github.com/lhoestq", "followers_url": "https://api.github.com/users/lhoestq/followers"... | value:MDExOlB1bGxSZXF1ZXN0NDI0NDgyNDgz | true | |||||||||
value:2020-05-28T15:15:04Z | value:https://api.github.com/repos/huggingface/datasets/issues/209/timeline | value:3 | value:https://api.github.com/repos/huggingface/datasets | json:{"login": "lhoestq", "id": 42851186, "node_id": "MDQ6VXNlcjQyODUxMTg2", "avatar_url": "https://avatars.githubusercontent.com/u/42851186?v=4", "gravatar_id": "", "url": "https://api.github.com/users/lhoestq", "html_url": "https://github.com/lhoestq", "followers_url": "https://api.github.com/users/lhoestq/followers"... | value:closed | value:https://github.com/huggingface/datasets/pull/209 | value:https://api.github.com/repos/huggingface/datasets/issues/209/comments | value:I tried to use the ``nlp`` library to load personnal datasets. I mainly copy-paste the code for ``multi-news`` dataset because my files are stored on Google Drive.
One of my dataset is small (< 25Mo) so it can be verified by Drive without asking the authorization to the user. This makes the download starts di... | value:False | value:https://api.github.com/repos/huggingface/datasets/issues/209 | json:[] | value:209 | value:Add a Google Drive exception for small files | value:626405849 | json:[] | value:False | json:{"url": "https://api.github.com/repos/huggingface/datasets/issues/209/reactions", "total_count": 0, "+1": 0, "-1": 0, "laugh": 0, "hooray": 0, "confused": 0, "heart": 0, "rocket": 0, "eyes": 0} | json:{"url": "https://api.github.com/repos/huggingface/datasets/pulls/209", "html_url": "https://github.com/huggingface/datasets/pull/209", "diff_url": "https://github.com/huggingface/datasets/pull/209.diff", "patch_url": "https://github.com/huggingface/datasets/pull/209.patch", "merged_at": "2020-05-28T15:15:04Z"} | value:https://api.github.com/repos/huggingface/datasets/issues/209/events | value:2020-05-28T10:40:17Z | value:https://api.github.com/repos/huggingface/datasets/issues/209/labels{/name} | json:[] | value:CONTRIBUTOR | value:2020-05-28T15:15:04Z | json:{"login": "airKlizz", "id": 25703835, "node_id": "MDQ6VXNlcjI1NzAzODM1", "avatar_url": "https://avatars.githubusercontent.com/u/25703835?v=4", "gravatar_id": "", "url": "https://api.github.com/users/airKlizz", "html_url": "https://github.com/airKlizz", "followers_url": "https://api.github.com/users/airKlizz/follow... | value:MDExOlB1bGxSZXF1ZXN0NDI0NDAwOTc4 | true | |||||||||
value:2020-05-28T12:48:00Z | value:https://api.github.com/repos/huggingface/datasets/issues/208/timeline | value:0 | value:https://api.github.com/repos/huggingface/datasets | json:{"login": "patrickvonplaten", "id": 23423619, "node_id": "MDQ6VXNlcjIzNDIzNjE5", "avatar_url": "https://avatars.githubusercontent.com/u/23423619?v=4", "gravatar_id": "", "url": "https://api.github.com/users/patrickvonplaten", "html_url": "https://github.com/patrickvonplaten", "followers_url": "https://api.github.c... | value:closed | value:https://github.com/huggingface/datasets/pull/208 | value:https://api.github.com/repos/huggingface/datasets/issues/208/comments | value:Thanks @yjernite for letting me know. in the dummy data command the config name shuold be passed to the dataset builder and not the config itself.
Also, @lhoestq fixed small import bug introduced by beam command I think. | value:False | value:https://api.github.com/repos/huggingface/datasets/issues/208 | json:[] | value:208 | value:[Dummy data] insert config name instead of config | value:626398519 | json:[] | value:False | json:{"url": "https://api.github.com/repos/huggingface/datasets/issues/208/reactions", "total_count": 0, "+1": 0, "-1": 0, "laugh": 0, "hooray": 0, "confused": 0, "heart": 0, "rocket": 0, "eyes": 0} | json:{"url": "https://api.github.com/repos/huggingface/datasets/pulls/208", "html_url": "https://github.com/huggingface/datasets/pull/208", "diff_url": "https://github.com/huggingface/datasets/pull/208.diff", "patch_url": "https://github.com/huggingface/datasets/pull/208.patch", "merged_at": "2020-05-28T12:48:00Z"} | value:https://api.github.com/repos/huggingface/datasets/issues/208/events | value:2020-05-28T10:28:19Z | value:https://api.github.com/repos/huggingface/datasets/issues/208/labels{/name} | json:[] | value:CONTRIBUTOR | value:2020-05-28T12:48:01Z | json:{"login": "patrickvonplaten", "id": 23423619, "node_id": "MDQ6VXNlcjIzNDIzNjE5", "avatar_url": "https://avatars.githubusercontent.com/u/23423619?v=4", "gravatar_id": "", "url": "https://api.github.com/users/patrickvonplaten", "html_url": "https://github.com/patrickvonplaten", "followers_url": "https://api.github.c... | value:MDExOlB1bGxSZXF1ZXN0NDI0Mzk0ODIx | true | |||||||||
value:2022-02-10T13:17:45Z | value:https://api.github.com/repos/huggingface/datasets/issues/207/timeline | json:{"total": 0, "completed": 0, "percent_completed": 0} | value:3 | value:https://api.github.com/repos/huggingface/datasets | json:{"login": "albertvillanova", "id": 8515462, "node_id": "MDQ6VXNlcjg1MTU0NjI=", "avatar_url": "https://avatars.githubusercontent.com/u/8515462?v=4", "gravatar_id": "", "url": "https://api.github.com/users/albertvillanova", "html_url": "https://github.com/albertvillanova", "followers_url": "https://api.github.com/us... | value:completed | value:closed | value:https://github.com/huggingface/datasets/issues/207 | value:https://api.github.com/repos/huggingface/datasets/issues/207/comments | value:While the new [NLP viewer](https://huggingface.co/nlp/viewer/) is a great tool, I think it would be best to outright remove the option of looking at the test sets. At the very least, a warning should be displayed to users before showing the test set. Newcomers to the field might not be aware of best practices, an... | value:https://api.github.com/repos/huggingface/datasets/issues/207 | json:[] | value:207 | value:Remove test set from NLP viewer | value:625932200 | json:[{"id": 2107841032, "node_id": "MDU6TGFiZWwyMTA3ODQxMDMy", "url": "https://api.github.com/repos/huggingface/datasets/labels/nlp-viewer", "name": "nlp-viewer", "color": "94203D", "default": false, "description": "", "archived_at": null, "archived_by": null}] | json:{"blocked_by": 0, "total_blocked_by": 0, "blocking": 0, "total_blocking": 0} | value:False | json:{"url": "https://api.github.com/repos/huggingface/datasets/issues/207/reactions", "total_count": 3, "+1": 3, "-1": 0, "laugh": 0, "hooray": 0, "confused": 0, "heart": 0, "rocket": 0, "eyes": 0} | value:https://api.github.com/repos/huggingface/datasets/issues/207/events | value:2020-05-27T18:32:07Z | value:https://api.github.com/repos/huggingface/datasets/issues/207/labels{/name} | json:[] | value:NONE | value:2022-02-10T13:17:45Z | json:{"login": "chrisdonahue", "id": 748399, "node_id": "MDQ6VXNlcjc0ODM5OQ==", "avatar_url": "https://avatars.githubusercontent.com/u/748399?v=4", "gravatar_id": "", "url": "https://api.github.com/users/chrisdonahue", "html_url": "https://github.com/chrisdonahue", "followers_url": "https://api.github.com/users/chrisdo... | value:MDU6SXNzdWU2MjU5MzIyMDA= | true | ||||||||
value:2020-06-10T09:11:14Z | value:https://api.github.com/repos/huggingface/datasets/issues/206/timeline | json:{"total": 0, "completed": 0, "percent_completed": 0} | value:2 | value:https://api.github.com/repos/huggingface/datasets | json:{"login": "airKlizz", "id": 25703835, "node_id": "MDQ6VXNlcjI1NzAzODM1", "avatar_url": "https://avatars.githubusercontent.com/u/25703835?v=4", "gravatar_id": "", "url": "https://api.github.com/users/airKlizz", "html_url": "https://github.com/airKlizz", "followers_url": "https://api.github.com/users/airKlizz/follow... | value:completed | value:closed | value:https://github.com/huggingface/datasets/issues/206 | value:https://api.github.com/repos/huggingface/datasets/issues/206/comments | value:Hi,
I am using ``nlp`` to load personal datasets. I created summarization datasets in multi-languages based on wikinews. I have one dataset for english and one for german (french is getting to be ready as well). I want to keep these datasets independent because they need different pre-processing (add different... | value:https://api.github.com/repos/huggingface/datasets/issues/206 | json:[] | value:206 | value:[Question] Combine 2 datasets which have the same columns | value:625842989 | json:[] | json:{"blocked_by": 0, "total_blocked_by": 0, "blocking": 0, "total_blocking": 0} | value:False | json:{"url": "https://api.github.com/repos/huggingface/datasets/issues/206/reactions", "total_count": 0, "+1": 0, "-1": 0, "laugh": 0, "hooray": 0, "confused": 0, "heart": 0, "rocket": 0, "eyes": 0} | value:https://api.github.com/repos/huggingface/datasets/issues/206/events | value:2020-05-27T16:25:52Z | value:https://api.github.com/repos/huggingface/datasets/issues/206/labels{/name} | json:[] | value:CONTRIBUTOR | value:2020-06-10T09:11:14Z | json:{"login": "airKlizz", "id": 25703835, "node_id": "MDQ6VXNlcjI1NzAzODM1", "avatar_url": "https://avatars.githubusercontent.com/u/25703835?v=4", "gravatar_id": "", "url": "https://api.github.com/users/airKlizz", "html_url": "https://github.com/airKlizz", "followers_url": "https://api.github.com/users/airKlizz/follow... | value:MDU6SXNzdWU2MjU4NDI5ODk= | true | ||||||||
value:2020-05-27T16:39:56Z | value:https://api.github.com/repos/huggingface/datasets/issues/205/timeline | value:0 | value:https://api.github.com/repos/huggingface/datasets | json:{"login": "lhoestq", "id": 42851186, "node_id": "MDQ6VXNlcjQyODUxMTg2", "avatar_url": "https://avatars.githubusercontent.com/u/42851186?v=4", "gravatar_id": "", "url": "https://api.github.com/users/lhoestq", "html_url": "https://github.com/lhoestq", "followers_url": "https://api.github.com/users/lhoestq/followers"... | value:closed | value:https://github.com/huggingface/datasets/pull/205 | value:https://api.github.com/repos/huggingface/datasets/issues/205/comments | value:I tried to play around with `tf.data.Dataset.from_generator` and I found out that the `__iter__` that we have for `nlp.arrow_dataset.Dataset` ignores the format that has been set (torch or tensorflow).
With these changes I should be able to come up with a `tf.data.Dataset` that uses lazy loading, as asked in #19... | value:False | value:https://api.github.com/repos/huggingface/datasets/issues/205 | json:[] | value:205 | value:Better arrow dataset iter | value:625839335 | json:[] | value:False | json:{"url": "https://api.github.com/repos/huggingface/datasets/issues/205/reactions", "total_count": 0, "+1": 0, "-1": 0, "laugh": 0, "hooray": 0, "confused": 0, "heart": 0, "rocket": 0, "eyes": 0} | json:{"url": "https://api.github.com/repos/huggingface/datasets/pulls/205", "html_url": "https://github.com/huggingface/datasets/pull/205", "diff_url": "https://github.com/huggingface/datasets/pull/205.diff", "patch_url": "https://github.com/huggingface/datasets/pull/205.patch", "merged_at": "2020-05-27T16:39:56Z"} | value:https://api.github.com/repos/huggingface/datasets/issues/205/events | value:2020-05-27T16:20:21Z | value:https://api.github.com/repos/huggingface/datasets/issues/205/labels{/name} | json:[] | value:MEMBER | value:2020-05-27T16:39:58Z | json:{"login": "lhoestq", "id": 42851186, "node_id": "MDQ6VXNlcjQyODUxMTg2", "avatar_url": "https://avatars.githubusercontent.com/u/42851186?v=4", "gravatar_id": "", "url": "https://api.github.com/users/lhoestq", "html_url": "https://github.com/lhoestq", "followers_url": "https://api.github.com/users/lhoestq/followers"... | value:MDExOlB1bGxSZXF1ZXN0NDIzOTY2ODE1 | true | |||||||||
value:2020-05-28T08:10:34Z | value:https://api.github.com/repos/huggingface/datasets/issues/204/timeline | value:0 | value:https://api.github.com/repos/huggingface/datasets | json:{"login": "lhoestq", "id": 42851186, "node_id": "MDQ6VXNlcjQyODUxMTg2", "avatar_url": "https://avatars.githubusercontent.com/u/42851186?v=4", "gravatar_id": "", "url": "https://api.github.com/users/lhoestq", "html_url": "https://github.com/lhoestq", "followers_url": "https://api.github.com/users/lhoestq/followers"... | value:closed | value:https://github.com/huggingface/datasets/pull/204 | value:https://api.github.com/repos/huggingface/datasets/issues/204/comments | value:# Add Dataflow support + Wikipedia + Wiki40b
## Support datasets processing with Apache Beam
Some datasets are too big to be processed on a single machine, for example: wikipedia, wiki40b, etc. Apache Beam allows to process datasets on many execution engines like Dataflow, Spark, Flink, etc.
To process s... | value:False | value:https://api.github.com/repos/huggingface/datasets/issues/204 | json:[] | value:204 | value:Add Dataflow support + Wikipedia + Wiki40b | value:625655849 | json:[] | value:False | json:{"url": "https://api.github.com/repos/huggingface/datasets/issues/204/reactions", "total_count": 0, "+1": 0, "-1": 0, "laugh": 0, "hooray": 0, "confused": 0, "heart": 0, "rocket": 0, "eyes": 0} | json:{"url": "https://api.github.com/repos/huggingface/datasets/pulls/204", "html_url": "https://github.com/huggingface/datasets/pull/204", "diff_url": "https://github.com/huggingface/datasets/pull/204.diff", "patch_url": "https://github.com/huggingface/datasets/pull/204.patch", "merged_at": "2020-05-28T08:10:34Z"} | value:https://api.github.com/repos/huggingface/datasets/issues/204/events | value:2020-05-27T12:32:49Z | value:https://api.github.com/repos/huggingface/datasets/issues/204/labels{/name} | json:[] | value:MEMBER | value:2020-05-28T08:10:35Z | json:{"login": "lhoestq", "id": 42851186, "node_id": "MDQ6VXNlcjQyODUxMTg2", "avatar_url": "https://avatars.githubusercontent.com/u/42851186?v=4", "gravatar_id": "", "url": "https://api.github.com/users/lhoestq", "html_url": "https://github.com/lhoestq", "followers_url": "https://api.github.com/users/lhoestq/followers"... | value:MDExOlB1bGxSZXF1ZXN0NDIzODE5MTQw | true | |||||||||
value:2020-05-27T16:40:38Z | value:https://api.github.com/repos/huggingface/datasets/issues/203/timeline | value:0 | value:https://api.github.com/repos/huggingface/datasets | json:{"login": "lhoestq", "id": 42851186, "node_id": "MDQ6VXNlcjQyODUxMTg2", "avatar_url": "https://avatars.githubusercontent.com/u/42851186?v=4", "gravatar_id": "", "url": "https://api.github.com/users/lhoestq", "html_url": "https://github.com/lhoestq", "followers_url": "https://api.github.com/users/lhoestq/followers"... | value:closed | value:https://github.com/huggingface/datasets/pull/203 | value:https://api.github.com/repos/huggingface/datasets/issues/203/comments | value:Some datasets like glue (see #130) and scientific_papers (see #197) have many configs.
For example for glue there are cola, sst2, mrpc etc.
Currently if a user does `load_dataset('glue')`, then Cola is loaded by default and it can be confusing. Instead, we should raise an error to let the user know that he ha... | value:False | value:https://api.github.com/repos/huggingface/datasets/issues/203 | json:[] | value:203 | value:Raise an error if no config name for datasets like glue | value:625515488 | json:[] | value:False | json:{"url": "https://api.github.com/repos/huggingface/datasets/issues/203/reactions", "total_count": 0, "+1": 0, "-1": 0, "laugh": 0, "hooray": 0, "confused": 0, "heart": 0, "rocket": 0, "eyes": 0} | json:{"url": "https://api.github.com/repos/huggingface/datasets/pulls/203", "html_url": "https://github.com/huggingface/datasets/pull/203", "diff_url": "https://github.com/huggingface/datasets/pull/203.diff", "patch_url": "https://github.com/huggingface/datasets/pull/203.patch", "merged_at": "2020-05-27T16:40:38Z"} | value:https://api.github.com/repos/huggingface/datasets/issues/203/events | value:2020-05-27T09:03:58Z | value:https://api.github.com/repos/huggingface/datasets/issues/203/labels{/name} | json:[] | value:MEMBER | value:2020-05-27T16:40:39Z | json:{"login": "lhoestq", "id": 42851186, "node_id": "MDQ6VXNlcjQyODUxMTg2", "avatar_url": "https://avatars.githubusercontent.com/u/42851186?v=4", "gravatar_id": "", "url": "https://api.github.com/users/lhoestq", "html_url": "https://github.com/lhoestq", "followers_url": "https://api.github.com/users/lhoestq/followers"... | value:MDExOlB1bGxSZXF1ZXN0NDIzNzEyMTQ3 | true | |||||||||
value:2020-05-28T13:22:36Z | value:https://api.github.com/repos/huggingface/datasets/issues/202/timeline | json:{"total": 0, "completed": 0, "percent_completed": 0} | value:1 | value:https://api.github.com/repos/huggingface/datasets | json:{"login": "lhoestq", "id": 42851186, "node_id": "MDQ6VXNlcjQyODUxMTg2", "avatar_url": "https://avatars.githubusercontent.com/u/42851186?v=4", "gravatar_id": "", "url": "https://api.github.com/users/lhoestq", "html_url": "https://github.com/lhoestq", "followers_url": "https://api.github.com/users/lhoestq/followers"... | value:completed | value:closed | value:https://github.com/huggingface/datasets/issues/202 | value:https://api.github.com/repos/huggingface/datasets/issues/202/comments | value:Hi!
The [`_KWARGS_DESCRIPTION`](https://github.com/huggingface/nlp/blob/7d0fa58641f3f462fb2861dcdd6ce7f0da3f6a56/metrics/xnli/xnli.py#L45) for the XNLI metric uses `Args` and `Returns` text from [BLEU](https://github.com/huggingface/nlp/blob/7d0fa58641f3f462fb2861dcdd6ce7f0da3f6a56/metrics/bleu/bleu.py#L58) me... | value:https://api.github.com/repos/huggingface/datasets/issues/202 | json:[] | value:202 | value:Mistaken `_KWARGS_DESCRIPTION` for XNLI metric | value:625493983 | json:[] | json:{"blocked_by": 0, "total_blocked_by": 0, "blocking": 0, "total_blocking": 0} | value:False | json:{"url": "https://api.github.com/repos/huggingface/datasets/issues/202/reactions", "total_count": 0, "+1": 0, "-1": 0, "laugh": 0, "hooray": 0, "confused": 0, "heart": 0, "rocket": 0, "eyes": 0} | value:https://api.github.com/repos/huggingface/datasets/issues/202/events | value:2020-05-27T08:34:42Z | value:https://api.github.com/repos/huggingface/datasets/issues/202/labels{/name} | json:[] | value:NONE | value:2020-05-28T13:22:36Z | json:{"login": "phiyodr", "id": 33572125, "node_id": "MDQ6VXNlcjMzNTcyMTI1", "avatar_url": "https://avatars.githubusercontent.com/u/33572125?v=4", "gravatar_id": "", "url": "https://api.github.com/users/phiyodr", "html_url": "https://github.com/phiyodr", "followers_url": "https://api.github.com/users/phiyodr/followers"... | value:MDU6SXNzdWU2MjU0OTM5ODM= | true | ||||||||
value:2020-05-26T23:00:56Z | value:https://api.github.com/repos/huggingface/datasets/issues/201/timeline | value:2 | value:https://api.github.com/repos/huggingface/datasets | json:{"login": "thomwolf", "id": 7353373, "node_id": "MDQ6VXNlcjczNTMzNzM=", "avatar_url": "https://avatars.githubusercontent.com/u/7353373?v=4", "gravatar_id": "", "url": "https://api.github.com/users/thomwolf", "html_url": "https://github.com/thomwolf", "followers_url": "https://api.github.com/users/thomwolf/follower... | value:closed | value:https://github.com/huggingface/datasets/pull/201 | value:https://api.github.com/repos/huggingface/datasets/issues/201/comments | value: | value:False | value:https://api.github.com/repos/huggingface/datasets/issues/201 | json:[] | value:201 | value:Fix typo in README | value:625235430 | json:[] | value:False | json:{"url": "https://api.github.com/repos/huggingface/datasets/issues/201/reactions", "total_count": 0, "+1": 0, "-1": 0, "laugh": 0, "hooray": 0, "confused": 0, "heart": 0, "rocket": 0, "eyes": 0} | json:{"url": "https://api.github.com/repos/huggingface/datasets/pulls/201", "html_url": "https://github.com/huggingface/datasets/pull/201", "diff_url": "https://github.com/huggingface/datasets/pull/201.diff", "patch_url": "https://github.com/huggingface/datasets/pull/201.patch", "merged_at": "2020-05-26T23:00:56Z"} | value:https://api.github.com/repos/huggingface/datasets/issues/201/events | value:2020-05-26T22:18:21Z | value:https://api.github.com/repos/huggingface/datasets/issues/201/labels{/name} | json:[] | value:MEMBER | value:2020-05-26T23:40:31Z | json:{"login": "LysandreJik", "id": 30755778, "node_id": "MDQ6VXNlcjMwNzU1Nzc4", "avatar_url": "https://avatars.githubusercontent.com/u/30755778?v=4", "gravatar_id": "", "url": "https://api.github.com/users/LysandreJik", "html_url": "https://github.com/LysandreJik", "followers_url": "https://api.github.com/users/Lysand... | value:MDExOlB1bGxSZXF1ZXN0NDIzNDkzNTMw | true | |||||||||
value:2020-05-27T09:07:53Z | value:https://api.github.com/repos/huggingface/datasets/issues/200/timeline | value:1 | value:https://api.github.com/repos/huggingface/datasets | json:{"login": "lhoestq", "id": 42851186, "node_id": "MDQ6VXNlcjQyODUxMTg2", "avatar_url": "https://avatars.githubusercontent.com/u/42851186?v=4", "gravatar_id": "", "url": "https://api.github.com/users/lhoestq", "html_url": "https://github.com/lhoestq", "followers_url": "https://api.github.com/users/lhoestq/followers"... | value:closed | value:https://github.com/huggingface/datasets/pull/200 | value:https://api.github.com/repos/huggingface/datasets/issues/200/comments | value:Right now if the schema was not specified when instantiating `ArrowWriter`, then it could be set with the first `write_table` for example (it calls `self._build_writer()` to do so).
I noticed that it was not done if the first example is added via `.write`, so I added it for coherence. | value:False | value:https://api.github.com/repos/huggingface/datasets/issues/200 | json:[] | value:200 | value:[ArrowWriter] Set schema at first write example | value:625226638 | json:[] | value:False | json:{"url": "https://api.github.com/repos/huggingface/datasets/issues/200/reactions", "total_count": 0, "+1": 0, "-1": 0, "laugh": 0, "hooray": 0, "confused": 0, "heart": 0, "rocket": 0, "eyes": 0} | json:{"url": "https://api.github.com/repos/huggingface/datasets/pulls/200", "html_url": "https://github.com/huggingface/datasets/pull/200", "diff_url": "https://github.com/huggingface/datasets/pull/200.diff", "patch_url": "https://github.com/huggingface/datasets/pull/200.patch", "merged_at": "2020-05-27T09:07:53Z"} | value:https://api.github.com/repos/huggingface/datasets/issues/200/events | value:2020-05-26T21:59:48Z | value:https://api.github.com/repos/huggingface/datasets/issues/200/labels{/name} | json:[] | value:MEMBER | value:2020-05-27T09:07:54Z | json:{"login": "lhoestq", "id": 42851186, "node_id": "MDQ6VXNlcjQyODUxMTg2", "avatar_url": "https://avatars.githubusercontent.com/u/42851186?v=4", "gravatar_id": "", "url": "https://api.github.com/users/lhoestq", "html_url": "https://github.com/lhoestq", "followers_url": "https://api.github.com/users/lhoestq/followers"... | value:MDExOlB1bGxSZXF1ZXN0NDIzNDg2NTM0 | true | |||||||||
value:2020-05-26T21:50:24Z | value:https://api.github.com/repos/huggingface/datasets/issues/199/timeline | value:2 | value:https://api.github.com/repos/huggingface/datasets | json:{"login": "lhoestq", "id": 42851186, "node_id": "MDQ6VXNlcjQyODUxMTg2", "avatar_url": "https://avatars.githubusercontent.com/u/42851186?v=4", "gravatar_id": "", "url": "https://api.github.com/users/lhoestq", "html_url": "https://github.com/lhoestq", "followers_url": "https://api.github.com/users/lhoestq/followers"... | value:closed | value:https://github.com/huggingface/datasets/pull/199 | value:https://api.github.com/repos/huggingface/datasets/issues/199/comments | value:Hi,
this PR just removes the `dataset_info.json` file and adds a newly generated `dataset_infos.json` file. | value:False | value:https://api.github.com/repos/huggingface/datasets/issues/199 | json:[] | value:199 | value:Fix GermEval 2014 dataset infos | value:625217440 | json:[] | value:False | json:{"url": "https://api.github.com/repos/huggingface/datasets/issues/199/reactions", "total_count": 0, "+1": 0, "-1": 0, "laugh": 0, "hooray": 0, "confused": 0, "heart": 0, "rocket": 0, "eyes": 0} | json:{"url": "https://api.github.com/repos/huggingface/datasets/pulls/199", "html_url": "https://github.com/huggingface/datasets/pull/199", "diff_url": "https://github.com/huggingface/datasets/pull/199.diff", "patch_url": "https://github.com/huggingface/datasets/pull/199.patch", "merged_at": "2020-05-26T21:50:24Z"} | value:https://api.github.com/repos/huggingface/datasets/issues/199/events | value:2020-05-26T21:41:44Z | value:https://api.github.com/repos/huggingface/datasets/issues/199/labels{/name} | json:[] | value:CONTRIBUTOR | value:2020-05-26T21:50:24Z | json:{"login": "stefan-it", "id": 20651387, "node_id": "MDQ6VXNlcjIwNjUxMzg3", "avatar_url": "https://avatars.githubusercontent.com/u/20651387?v=4", "gravatar_id": "", "url": "https://api.github.com/users/stefan-it", "html_url": "https://github.com/stefan-it", "followers_url": "https://api.github.com/users/stefan-it/fo... | value:MDExOlB1bGxSZXF1ZXN0NDIzNDc4ODIx | true | |||||||||
value:2020-05-26T22:43:49Z | value:https://api.github.com/repos/huggingface/datasets/issues/198/timeline | json:{"total": 0, "completed": 0, "percent_completed": 0} | value:2 | value:https://api.github.com/repos/huggingface/datasets | json:{"login": "srush", "id": 35882, "node_id": "MDQ6VXNlcjM1ODgy", "avatar_url": "https://avatars.githubusercontent.com/u/35882?v=4", "gravatar_id": "", "url": "https://api.github.com/users/srush", "html_url": "https://github.com/srush", "followers_url": "https://api.github.com/users/srush/followers", "following_url":... | value:completed | value:closed | value:https://github.com/huggingface/datasets/issues/198 | value:https://api.github.com/repos/huggingface/datasets/issues/198/comments | value:The offset input box warns of numbers larger than a limit (like 2000) but then the errors start at a smaller value than that limit (like 1955).
> ValueError: Index (2000) outside of table length (2000).
> Traceback:
> File "/home/sasha/.local/lib/python3.7/site-packages/streamlit/ScriptRunner.py", line 322, ... | value:https://api.github.com/repos/huggingface/datasets/issues/198 | json:[] | value:198 | value:Index outside of table length | value:625200627 | json:[] | json:{"blocked_by": 0, "total_blocked_by": 0, "blocking": 0, "total_blocking": 0} | value:False | json:{"url": "https://api.github.com/repos/huggingface/datasets/issues/198/reactions", "total_count": 0, "+1": 0, "-1": 0, "laugh": 0, "hooray": 0, "confused": 0, "heart": 0, "rocket": 0, "eyes": 0} | value:https://api.github.com/repos/huggingface/datasets/issues/198/events | value:2020-05-26T21:09:40Z | value:https://api.github.com/repos/huggingface/datasets/issues/198/labels{/name} | json:[] | value:NONE | value:2020-05-26T22:43:49Z | json:{"login": "casajarm", "id": 305717, "node_id": "MDQ6VXNlcjMwNTcxNw==", "avatar_url": "https://avatars.githubusercontent.com/u/305717?v=4", "gravatar_id": "", "url": "https://api.github.com/users/casajarm", "html_url": "https://github.com/casajarm", "followers_url": "https://api.github.com/users/casajarm/followers"... | value:MDU6SXNzdWU2MjUyMDA2Mjc= | true | ||||||||
value:2020-05-28T08:19:28Z | value:https://api.github.com/repos/huggingface/datasets/issues/197/timeline | json:{"total": 0, "completed": 0, "percent_completed": 0} | value:3 | value:https://api.github.com/repos/huggingface/datasets | json:{"login": "lhoestq", "id": 42851186, "node_id": "MDQ6VXNlcjQyODUxMTg2", "avatar_url": "https://avatars.githubusercontent.com/u/42851186?v=4", "gravatar_id": "", "url": "https://api.github.com/users/lhoestq", "html_url": "https://github.com/lhoestq", "followers_url": "https://api.github.com/users/lhoestq/followers"... | value:completed | value:closed | value:https://github.com/huggingface/datasets/issues/197 | value:https://api.github.com/repos/huggingface/datasets/issues/197/comments | value:Hi!
I have been playing around with this module, and I am a bit confused about the `scientific_papers` dataset. I thought that it would download two separate datasets, arxiv and pubmed. But when I run the following:
```
dataset = nlp.load_dataset('scientific_papers', data_dir='.', cache_dir='.')
Downloadi... | value:https://api.github.com/repos/huggingface/datasets/issues/197 | json:[] | value:197 | value:Scientific Papers only downloading Pubmed | value:624966904 | json:[] | json:{"blocked_by": 0, "total_blocked_by": 0, "blocking": 0, "total_blocking": 0} | value:False | json:{"url": "https://api.github.com/repos/huggingface/datasets/issues/197/reactions", "total_count": 0, "+1": 0, "-1": 0, "laugh": 0, "hooray": 0, "confused": 0, "heart": 0, "rocket": 0, "eyes": 0} | value:https://api.github.com/repos/huggingface/datasets/issues/197/events | value:2020-05-26T15:18:47Z | value:https://api.github.com/repos/huggingface/datasets/issues/197/labels{/name} | json:[] | value:NONE | value:2020-05-28T08:19:28Z | json:{"login": "antmarakis", "id": 17463361, "node_id": "MDQ6VXNlcjE3NDYzMzYx", "avatar_url": "https://avatars.githubusercontent.com/u/17463361?v=4", "gravatar_id": "", "url": "https://api.github.com/users/antmarakis", "html_url": "https://github.com/antmarakis", "followers_url": "https://api.github.com/users/antmaraki... | value:MDU6SXNzdWU2MjQ5NjY5MDQ= | true | ||||||||
value:2020-05-26T21:04:55Z | value:https://api.github.com/repos/huggingface/datasets/issues/196/timeline | value:13 | value:https://api.github.com/repos/huggingface/datasets | json:{"login": "lhoestq", "id": 42851186, "node_id": "MDQ6VXNlcjQyODUxMTg2", "avatar_url": "https://avatars.githubusercontent.com/u/42851186?v=4", "gravatar_id": "", "url": "https://api.github.com/users/lhoestq", "html_url": "https://github.com/lhoestq", "followers_url": "https://api.github.com/users/lhoestq/followers"... | value:closed | value:https://github.com/huggingface/datasets/pull/196 | value:https://api.github.com/repos/huggingface/datasets/issues/196/comments | value:As said in #194, we should raise an error if the config name has bad characters.
Bad characters are those that are not allowed for directory names on windows. | value:False | value:https://api.github.com/repos/huggingface/datasets/issues/196 | json:[] | value:196 | value:Check invalid config name | value:624901266 | json:[] | value:False | json:{"url": "https://api.github.com/repos/huggingface/datasets/issues/196/reactions", "total_count": 0, "+1": 0, "-1": 0, "laugh": 0, "hooray": 0, "confused": 0, "heart": 0, "rocket": 0, "eyes": 0} | json:{"url": "https://api.github.com/repos/huggingface/datasets/pulls/196", "html_url": "https://github.com/huggingface/datasets/pull/196", "diff_url": "https://github.com/huggingface/datasets/pull/196.diff", "patch_url": "https://github.com/huggingface/datasets/pull/196.patch", "merged_at": "2020-05-26T21:04:55Z"} | value:https://api.github.com/repos/huggingface/datasets/issues/196/events | value:2020-05-26T13:52:51Z | value:https://api.github.com/repos/huggingface/datasets/issues/196/labels{/name} | json:[] | value:MEMBER | value:2020-05-26T21:04:56Z | json:{"login": "lhoestq", "id": 42851186, "node_id": "MDQ6VXNlcjQyODUxMTg2", "avatar_url": "https://avatars.githubusercontent.com/u/42851186?v=4", "gravatar_id": "", "url": "https://api.github.com/users/lhoestq", "html_url": "https://github.com/lhoestq", "followers_url": "https://api.github.com/users/lhoestq/followers"... | value:MDExOlB1bGxSZXF1ZXN0NDIzMjIwMjIw | true | |||||||||
value:2020-05-26T14:38:27Z | value:https://api.github.com/repos/huggingface/datasets/issues/195/timeline | value:1 | value:https://api.github.com/repos/huggingface/datasets | json:{"login": "patrickvonplaten", "id": 23423619, "node_id": "MDQ6VXNlcjIzNDIzNjE5", "avatar_url": "https://avatars.githubusercontent.com/u/23423619?v=4", "gravatar_id": "", "url": "https://api.github.com/users/patrickvonplaten", "html_url": "https://github.com/patrickvonplaten", "followers_url": "https://api.github.c... | value:closed | value:https://github.com/huggingface/datasets/pull/195 | value:https://api.github.com/repos/huggingface/datasets/issues/195/comments | value:Qanta: #194 introduces a case that was not noticed before. This change in code helps community users to have an easier time creating the dummy data. | value:False | value:https://api.github.com/repos/huggingface/datasets/issues/195 | json:[] | value:195 | value:[Dummy data command] add new case to command | value:624858686 | json:[] | value:False | json:{"url": "https://api.github.com/repos/huggingface/datasets/issues/195/reactions", "total_count": 0, "+1": 0, "-1": 0, "laugh": 0, "hooray": 0, "confused": 0, "heart": 0, "rocket": 0, "eyes": 0} | json:{"url": "https://api.github.com/repos/huggingface/datasets/pulls/195", "html_url": "https://github.com/huggingface/datasets/pull/195", "diff_url": "https://github.com/huggingface/datasets/pull/195.diff", "patch_url": "https://github.com/huggingface/datasets/pull/195.patch", "merged_at": "2020-05-26T14:38:27Z"} | value:https://api.github.com/repos/huggingface/datasets/issues/195/events | value:2020-05-26T12:50:47Z | value:https://api.github.com/repos/huggingface/datasets/issues/195/labels{/name} | json:[] | value:CONTRIBUTOR | value:2020-05-26T14:38:28Z | json:{"login": "patrickvonplaten", "id": 23423619, "node_id": "MDQ6VXNlcjIzNDIzNjE5", "avatar_url": "https://avatars.githubusercontent.com/u/23423619?v=4", "gravatar_id": "", "url": "https://api.github.com/users/patrickvonplaten", "html_url": "https://github.com/patrickvonplaten", "followers_url": "https://api.github.c... | value:MDExOlB1bGxSZXF1ZXN0NDIzMTg1NTAy | true | |||||||||
value:2020-05-26T13:16:20Z | value:https://api.github.com/repos/huggingface/datasets/issues/194/timeline | value:3 | value:https://api.github.com/repos/huggingface/datasets | json:{"login": "patrickvonplaten", "id": 23423619, "node_id": "MDQ6VXNlcjIzNDIzNjE5", "avatar_url": "https://avatars.githubusercontent.com/u/23423619?v=4", "gravatar_id": "", "url": "https://api.github.com/users/patrickvonplaten", "html_url": "https://github.com/patrickvonplaten", "followers_url": "https://api.github.c... | value:closed | value:https://github.com/huggingface/datasets/pull/194 | value:https://api.github.com/repos/huggingface/datasets/issues/194/comments | value:Fixes dummy data for #169 @EntilZha | value:False | value:https://api.github.com/repos/huggingface/datasets/issues/194 | json:[] | value:194 | value:Add Dataset: Qanta | value:624854897 | json:[] | value:False | json:{"url": "https://api.github.com/repos/huggingface/datasets/issues/194/reactions", "total_count": 0, "+1": 0, "-1": 0, "laugh": 0, "hooray": 0, "confused": 0, "heart": 0, "rocket": 0, "eyes": 0} | json:{"url": "https://api.github.com/repos/huggingface/datasets/pulls/194", "html_url": "https://github.com/huggingface/datasets/pull/194", "diff_url": "https://github.com/huggingface/datasets/pull/194.diff", "patch_url": "https://github.com/huggingface/datasets/pull/194.patch", "merged_at": "2020-05-26T13:16:20Z"} | value:https://api.github.com/repos/huggingface/datasets/issues/194/events | value:2020-05-26T12:44:35Z | value:https://api.github.com/repos/huggingface/datasets/issues/194/labels{/name} | json:[] | value:CONTRIBUTOR | value:2020-05-26T16:58:17Z | json:{"login": "patrickvonplaten", "id": 23423619, "node_id": "MDQ6VXNlcjIzNDIzNjE5", "avatar_url": "https://avatars.githubusercontent.com/u/23423619?v=4", "gravatar_id": "", "url": "https://api.github.com/users/patrickvonplaten", "html_url": "https://github.com/patrickvonplaten", "followers_url": "https://api.github.c... | value:MDExOlB1bGxSZXF1ZXN0NDIzMTgyNDM5 | true | |||||||||
value:2020-10-27T15:28:11Z | value:https://api.github.com/repos/huggingface/datasets/issues/193/timeline | json:{"total": 0, "completed": 0, "percent_completed": 0} | value:7 | value:https://api.github.com/repos/huggingface/datasets | json:{"login": "yjernite", "id": 10469459, "node_id": "MDQ6VXNlcjEwNDY5NDU5", "avatar_url": "https://avatars.githubusercontent.com/u/10469459?v=4", "gravatar_id": "", "url": "https://api.github.com/users/yjernite", "html_url": "https://github.com/yjernite", "followers_url": "https://api.github.com/users/yjernite/follow... | value:completed | value:closed | value:https://github.com/huggingface/datasets/issues/193 | json:{"login": "lhoestq", "id": 42851186, "node_id": "MDQ6VXNlcjQyODUxMTg2", "avatar_url": "https://avatars.githubusercontent.com/u/42851186?v=4", "gravatar_id": "", "url": "https://api.github.com/users/lhoestq", "html_url": "https://github.com/lhoestq", "followers_url": "https://api.github.com/users/lhoestq/followers"... | value:https://api.github.com/repos/huggingface/datasets/issues/193/comments | value:In the example notebook, the TF Dataset is built using `from_tensor_slices()` :
```python
columns = ['input_ids', 'token_type_ids', 'attention_mask', 'start_positions', 'end_positions']
train_tf_dataset.set_format(type='tensorflow', columns=columns)
features = {x: train_tf_dataset[x] for x in columns[:3]}
... | value:https://api.github.com/repos/huggingface/datasets/issues/193 | json:[] | value:193 | value:[Tensorflow] Use something else than `from_tensor_slices()` | value:624655558 | json:[] | json:{"blocked_by": 0, "total_blocked_by": 0, "blocking": 0, "total_blocking": 0} | value:False | json:{"url": "https://api.github.com/repos/huggingface/datasets/issues/193/reactions", "total_count": 0, "+1": 0, "-1": 0, "laugh": 0, "hooray": 0, "confused": 0, "heart": 0, "rocket": 0, "eyes": 0} | value:https://api.github.com/repos/huggingface/datasets/issues/193/events | value:2020-05-26T07:19:14Z | value:https://api.github.com/repos/huggingface/datasets/issues/193/labels{/name} | json:[{"login": "lhoestq", "id": 42851186, "node_id": "MDQ6VXNlcjQyODUxMTg2", "avatar_url": "https://avatars.githubusercontent.com/u/42851186?v=4", "gravatar_id": "", "url": "https://api.github.com/users/lhoestq", "html_url": "https://github.com/lhoestq", "followers_url": "https://api.github.com/users/lhoestq/followers... | value:NONE | value:2020-10-27T15:28:11Z | json:{"login": "astariul", "id": 43774355, "node_id": "MDQ6VXNlcjQzNzc0MzU1", "avatar_url": "https://avatars.githubusercontent.com/u/43774355?v=4", "gravatar_id": "", "url": "https://api.github.com/users/astariul", "html_url": "https://github.com/astariul", "followers_url": "https://api.github.com/users/astariul/follow... | value:MDU6SXNzdWU2MjQ2NTU1NTg= | true | |||||||
value:2020-10-27T15:20:22Z | value:https://api.github.com/repos/huggingface/datasets/issues/192/timeline | json:{"total": 0, "completed": 0, "percent_completed": 0} | value:4 | value:https://api.github.com/repos/huggingface/datasets | json:{"login": "yjernite", "id": 10469459, "node_id": "MDQ6VXNlcjEwNDY5NDU5", "avatar_url": "https://avatars.githubusercontent.com/u/10469459?v=4", "gravatar_id": "", "url": "https://api.github.com/users/yjernite", "html_url": "https://github.com/yjernite", "followers_url": "https://api.github.com/users/yjernite/follow... | value:completed | value:closed | value:https://github.com/huggingface/datasets/issues/192 | value:https://api.github.com/repos/huggingface/datasets/issues/192/comments | value:Hi guys, I have gathered and preprocessed about 2GB of COVID papers from CORD dataset @ Kggle. I have seen you have a text dataset as "Crime and punishment" in Apache arrow format. Do you have any script to do it from a raw txt file (preprocessed as for BERT like) or any guide?
Is the worth of send it to you and... | value:https://api.github.com/repos/huggingface/datasets/issues/192 | json:[] | value:192 | value:[Question] Create Apache Arrow dataset from raw text file | value:624397592 | json:[] | json:{"blocked_by": 0, "total_blocked_by": 0, "blocking": 0, "total_blocking": 0} | value:False | json:{"url": "https://api.github.com/repos/huggingface/datasets/issues/192/reactions", "total_count": 0, "+1": 0, "-1": 0, "laugh": 0, "hooray": 0, "confused": 0, "heart": 0, "rocket": 0, "eyes": 0} | value:https://api.github.com/repos/huggingface/datasets/issues/192/events | value:2020-05-25T16:42:47Z | value:https://api.github.com/repos/huggingface/datasets/issues/192/labels{/name} | json:[] | value:CONTRIBUTOR | value:2021-12-18T01:45:34Z | json:{"login": "mrm8488", "id": 3653789, "node_id": "MDQ6VXNlcjM2NTM3ODk=", "avatar_url": "https://avatars.githubusercontent.com/u/3653789?v=4", "gravatar_id": "", "url": "https://api.github.com/users/mrm8488", "html_url": "https://github.com/mrm8488", "followers_url": "https://api.github.com/users/mrm8488/followers", ... | value:MDU6SXNzdWU2MjQzOTc1OTI= | true | ||||||||
value:2020-05-25T16:39:58Z | value:https://api.github.com/repos/huggingface/datasets/issues/191/timeline | value:0 | value:https://api.github.com/repos/huggingface/datasets | json:{"login": "patrickvonplaten", "id": 23423619, "node_id": "MDQ6VXNlcjIzNDIzNjE5", "avatar_url": "https://avatars.githubusercontent.com/u/23423619?v=4", "gravatar_id": "", "url": "https://api.github.com/users/patrickvonplaten", "html_url": "https://github.com/patrickvonplaten", "followers_url": "https://api.github.c... | value:closed | value:https://github.com/huggingface/datasets/pull/191 | value:https://api.github.com/repos/huggingface/datasets/issues/191/comments | value:@mariamabarham - was still about to upload this. Should have waited with my comment a bit more :D | value:False | value:https://api.github.com/repos/huggingface/datasets/issues/191 | json:[] | value:191 | value:[Squad es] add dataset_infos | value:624394936 | json:[] | value:False | json:{"url": "https://api.github.com/repos/huggingface/datasets/issues/191/reactions", "total_count": 0, "+1": 0, "-1": 0, "laugh": 0, "hooray": 0, "confused": 0, "heart": 0, "rocket": 0, "eyes": 0} | json:{"url": "https://api.github.com/repos/huggingface/datasets/pulls/191", "html_url": "https://github.com/huggingface/datasets/pull/191", "diff_url": "https://github.com/huggingface/datasets/pull/191.diff", "patch_url": "https://github.com/huggingface/datasets/pull/191.patch", "merged_at": "2020-05-25T16:39:58Z"} | value:https://api.github.com/repos/huggingface/datasets/issues/191/events | value:2020-05-25T16:35:52Z | value:https://api.github.com/repos/huggingface/datasets/issues/191/labels{/name} | json:[] | value:CONTRIBUTOR | value:2020-05-25T16:39:59Z | json:{"login": "patrickvonplaten", "id": 23423619, "node_id": "MDQ6VXNlcjIzNDIzNjE5", "avatar_url": "https://avatars.githubusercontent.com/u/23423619?v=4", "gravatar_id": "", "url": "https://api.github.com/users/patrickvonplaten", "html_url": "https://github.com/patrickvonplaten", "followers_url": "https://api.github.c... | value:MDExOlB1bGxSZXF1ZXN0NDIyODI3MDMy | true | |||||||||
value:2020-05-25T16:28:45Z | value:https://api.github.com/repos/huggingface/datasets/issues/190/timeline | value:5 | value:https://api.github.com/repos/huggingface/datasets | json:{"login": "mariamabarham", "id": 38249783, "node_id": "MDQ6VXNlcjM4MjQ5Nzgz", "avatar_url": "https://avatars.githubusercontent.com/u/38249783?v=4", "gravatar_id": "", "url": "https://api.github.com/users/mariamabarham", "html_url": "https://github.com/mariamabarham", "followers_url": "https://api.github.com/users/... | value:closed | value:https://github.com/huggingface/datasets/pull/190 | value:https://api.github.com/repos/huggingface/datasets/issues/190/comments | value:This PR add the Spanish Squad versions 1 and 2 datasets.
Fixes #164 | value:False | value:https://api.github.com/repos/huggingface/datasets/issues/190 | json:[] | value:190 | value:add squad Spanish v1 and v2 | value:624124600 | json:[] | value:False | json:{"url": "https://api.github.com/repos/huggingface/datasets/issues/190/reactions", "total_count": 0, "+1": 0, "-1": 0, "laugh": 0, "hooray": 0, "confused": 0, "heart": 0, "rocket": 0, "eyes": 0} | json:{"url": "https://api.github.com/repos/huggingface/datasets/pulls/190", "html_url": "https://github.com/huggingface/datasets/pull/190", "diff_url": "https://github.com/huggingface/datasets/pull/190.diff", "patch_url": "https://github.com/huggingface/datasets/pull/190.patch", "merged_at": "2020-05-25T16:28:45Z"} | value:https://api.github.com/repos/huggingface/datasets/issues/190/events | value:2020-05-25T08:08:40Z | value:https://api.github.com/repos/huggingface/datasets/issues/190/labels{/name} | json:[] | value:CONTRIBUTOR | value:2020-05-25T16:28:46Z | json:{"login": "mariamabarham", "id": 38249783, "node_id": "MDQ6VXNlcjM4MjQ5Nzgz", "avatar_url": "https://avatars.githubusercontent.com/u/38249783?v=4", "gravatar_id": "", "url": "https://api.github.com/users/mariamabarham", "html_url": "https://github.com/mariamabarham", "followers_url": "https://api.github.com/users/... | value:MDExOlB1bGxSZXF1ZXN0NDIyNjA4NzAw | true | |||||||||
value:2020-05-25T18:38:28Z | value:https://api.github.com/repos/huggingface/datasets/issues/189/timeline | json:{"total": 0, "completed": 0, "percent_completed": 0} | value:2 | value:https://api.github.com/repos/huggingface/datasets | json:{"login": "sarahwie", "id": 8027676, "node_id": "MDQ6VXNlcjgwMjc2NzY=", "avatar_url": "https://avatars.githubusercontent.com/u/8027676?v=4", "gravatar_id": "", "url": "https://api.github.com/users/sarahwie", "html_url": "https://github.com/sarahwie", "followers_url": "https://api.github.com/users/sarahwie/follower... | value:completed | value:closed | value:https://github.com/huggingface/datasets/issues/189 | value:https://api.github.com/repos/huggingface/datasets/issues/189/comments | value:Hello, I am wondering what the equivalent formatting of a dataset should be to allow for multiple-choice answering prediction, BERT-style. Previously, this was done by passing a list of `InputFeatures` to the dataloader instead of a list of `InputFeature`, where `InputFeatures` contained lists of length equal to ... | value:https://api.github.com/repos/huggingface/datasets/issues/189 | json:[] | value:189 | value:[Question] BERT-style multiple choice formatting | value:624048881 | json:[] | json:{"blocked_by": 0, "total_blocked_by": 0, "blocking": 0, "total_blocking": 0} | value:False | json:{"url": "https://api.github.com/repos/huggingface/datasets/issues/189/reactions", "total_count": 0, "+1": 0, "-1": 0, "laugh": 0, "hooray": 0, "confused": 0, "heart": 0, "rocket": 0, "eyes": 0} | value:https://api.github.com/repos/huggingface/datasets/issues/189/events | value:2020-05-25T05:11:05Z | value:https://api.github.com/repos/huggingface/datasets/issues/189/labels{/name} | json:[] | value:NONE | value:2020-05-25T18:38:28Z | json:{"login": "sarahwie", "id": 8027676, "node_id": "MDQ6VXNlcjgwMjc2NzY=", "avatar_url": "https://avatars.githubusercontent.com/u/8027676?v=4", "gravatar_id": "", "url": "https://api.github.com/users/sarahwie", "html_url": "https://github.com/sarahwie", "followers_url": "https://api.github.com/users/sarahwie/follower... | value:MDU6SXNzdWU2MjQwNDg4ODE= | true | ||||||||
value:2020-05-24T18:53:48Z | value:https://api.github.com/repos/huggingface/datasets/issues/188/timeline | json:{"total": 0, "completed": 0, "percent_completed": 0} | value:3 | value:https://api.github.com/repos/huggingface/datasets | json:{"login": "tylerroost", "id": 31251196, "node_id": "MDQ6VXNlcjMxMjUxMTk2", "avatar_url": "https://avatars.githubusercontent.com/u/31251196?v=4", "gravatar_id": "", "url": "https://api.github.com/users/tylerroost", "html_url": "https://github.com/tylerroost", "followers_url": "https://api.github.com/users/tylerroos... | value:completed | value:closed | value:https://github.com/huggingface/datasets/issues/188 | value:https://api.github.com/repos/huggingface/datasets/issues/188/comments | value:Currently only the algebra_linear_1d is supported. Is there a timeline for making the other modules supported. If no timeline is established, how can I help? | value:https://api.github.com/repos/huggingface/datasets/issues/188 | json:[] | value:188 | value:When will the remaining math_dataset modules be added as dataset objects | value:623890430 | json:[] | json:{"blocked_by": 0, "total_blocked_by": 0, "blocking": 0, "total_blocking": 0} | value:False | json:{"url": "https://api.github.com/repos/huggingface/datasets/issues/188/reactions", "total_count": 0, "+1": 0, "-1": 0, "laugh": 0, "hooray": 0, "confused": 0, "heart": 0, "rocket": 0, "eyes": 0} | value:https://api.github.com/repos/huggingface/datasets/issues/188/events | value:2020-05-24T15:46:52Z | value:https://api.github.com/repos/huggingface/datasets/issues/188/labels{/name} | json:[] | value:NONE | value:2020-05-24T18:53:48Z | json:{"login": "tylerroost", "id": 31251196, "node_id": "MDQ6VXNlcjMxMjUxMTk2", "avatar_url": "https://avatars.githubusercontent.com/u/31251196?v=4", "gravatar_id": "", "url": "https://api.github.com/users/tylerroost", "html_url": "https://github.com/tylerroost", "followers_url": "https://api.github.com/users/tylerroos... | value:MDU6SXNzdWU2MjM4OTA0MzA= | true | ||||||||
value:2020-05-25T00:12:02Z | value:https://api.github.com/repos/huggingface/datasets/issues/187/timeline | json:{"total": 0, "completed": 0, "percent_completed": 0} | value:2 | value:https://api.github.com/repos/huggingface/datasets | json:{"login": "richarddwang", "id": 17963619, "node_id": "MDQ6VXNlcjE3OTYzNjE5", "avatar_url": "https://avatars.githubusercontent.com/u/17963619?v=4", "gravatar_id": "", "url": "https://api.github.com/users/richarddwang", "html_url": "https://github.com/richarddwang", "followers_url": "https://api.github.com/users/ric... | value:completed | value:closed | value:https://github.com/huggingface/datasets/issues/187 | value:https://api.github.com/repos/huggingface/datasets/issues/187/comments | value:When `nlp.load_dataset('wikipedia')`, I got
* `WARNING:nlp.builder:Trying to generate a dataset using Apache Beam, yet no Beam Runner or PipelineOptions() has been provided. Please pass a nlp.DownloadConfig(beam_runner=...) object to the builder.download_and_prepare(download_config=...) method. Default values wi... | value:https://api.github.com/repos/huggingface/datasets/issues/187 | json:[] | value:187 | value:[Question] How to load wikipedia ? Beam runner ? | value:623627800 | json:[] | json:{"blocked_by": 0, "total_blocked_by": 0, "blocking": 0, "total_blocking": 0} | value:False | json:{"url": "https://api.github.com/repos/huggingface/datasets/issues/187/reactions", "total_count": 0, "+1": 0, "-1": 0, "laugh": 0, "hooray": 0, "confused": 0, "heart": 0, "rocket": 0, "eyes": 0} | value:https://api.github.com/repos/huggingface/datasets/issues/187/events | value:2020-05-23T10:18:52Z | value:https://api.github.com/repos/huggingface/datasets/issues/187/labels{/name} | json:[] | value:CONTRIBUTOR | value:2020-05-25T00:12:02Z | json:{"login": "richarddwang", "id": 17963619, "node_id": "MDQ6VXNlcjE3OTYzNjE5", "avatar_url": "https://avatars.githubusercontent.com/u/17963619?v=4", "gravatar_id": "", "url": "https://api.github.com/users/richarddwang", "html_url": "https://github.com/richarddwang", "followers_url": "https://api.github.com/users/ric... | value:MDU6SXNzdWU2MjM2Mjc4MDA= | true | ||||||||
value:2020-05-23T20:22:17Z | value:https://api.github.com/repos/huggingface/datasets/issues/186/timeline | json:{"total": 0, "completed": 0, "percent_completed": 0} | value:2 | value:https://api.github.com/repos/huggingface/datasets | json:{"login": "zphang", "id": 1668462, "node_id": "MDQ6VXNlcjE2Njg0NjI=", "avatar_url": "https://avatars.githubusercontent.com/u/1668462?v=4", "gravatar_id": "", "url": "https://api.github.com/users/zphang", "html_url": "https://github.com/zphang", "followers_url": "https://api.github.com/users/zphang/followers", "fol... | value:completed | value:closed | value:https://github.com/huggingface/datasets/issues/186 | value:https://api.github.com/repos/huggingface/datasets/issues/186/comments | value:Sample code:
```python
import nlp
dataset = nlp.load_dataset('boolq')
def func1(x):
return x
def func2(x):
return None
train_output = dataset["train"].map(func1)
valid_output = dataset["validation"].map(func1)
print()
print(len(train_output), len(valid_output))
# Output: 9427 9427
```... | value:https://api.github.com/repos/huggingface/datasets/issues/186 | json:[] | value:186 | value:Weird-ish: Not creating unique caches for different phases | value:623595180 | json:[] | json:{"blocked_by": 0, "total_blocked_by": 0, "blocking": 0, "total_blocking": 0} | value:False | json:{"url": "https://api.github.com/repos/huggingface/datasets/issues/186/reactions", "total_count": 0, "+1": 0, "-1": 0, "laugh": 0, "hooray": 0, "confused": 0, "heart": 0, "rocket": 0, "eyes": 0} | value:https://api.github.com/repos/huggingface/datasets/issues/186/events | value:2020-05-23T06:40:58Z | value:https://api.github.com/repos/huggingface/datasets/issues/186/labels{/name} | json:[] | value:NONE | value:2020-05-23T20:22:18Z | json:{"login": "zphang", "id": 1668462, "node_id": "MDQ6VXNlcjE2Njg0NjI=", "avatar_url": "https://avatars.githubusercontent.com/u/1668462?v=4", "gravatar_id": "", "url": "https://api.github.com/users/zphang", "html_url": "https://github.com/zphang", "followers_url": "https://api.github.com/users/zphang/followers", "fol... | value:MDU6SXNzdWU2MjM1OTUxODA= | true | ||||||||
value:2020-05-22T14:06:34Z | value:https://api.github.com/repos/huggingface/datasets/issues/185/timeline | value:1 | value:https://api.github.com/repos/huggingface/datasets | json:{"login": "patrickvonplaten", "id": 23423619, "node_id": "MDQ6VXNlcjIzNDIzNjE5", "avatar_url": "https://avatars.githubusercontent.com/u/23423619?v=4", "gravatar_id": "", "url": "https://api.github.com/users/patrickvonplaten", "html_url": "https://github.com/patrickvonplaten", "followers_url": "https://api.github.c... | value:closed | value:https://github.com/huggingface/datasets/pull/185 | value:https://api.github.com/repos/huggingface/datasets/issues/185/comments | value:### Dummy data command
This PR adds a new command `python nlp-cli dummy_data <path_to_dataset_folder>` that gives in-detail instructions on how to add the dummy data files.
It would be great if you can try it out by moving the current dummy_data folder of any dataset in `./datasets` with `mv datasets/<dat... | value:False | value:https://api.github.com/repos/huggingface/datasets/issues/185 | json:[] | value:185 | value:[Commands] In-detail instructions to create dummy data folder | value:623172484 | json:[] | value:False | json:{"url": "https://api.github.com/repos/huggingface/datasets/issues/185/reactions", "total_count": 0, "+1": 0, "-1": 0, "laugh": 0, "hooray": 0, "confused": 0, "heart": 0, "rocket": 0, "eyes": 0} | json:{"url": "https://api.github.com/repos/huggingface/datasets/pulls/185", "html_url": "https://github.com/huggingface/datasets/pull/185", "diff_url": "https://github.com/huggingface/datasets/pull/185.diff", "patch_url": "https://github.com/huggingface/datasets/pull/185.patch", "merged_at": "2020-05-22T14:06:34Z"} | value:https://api.github.com/repos/huggingface/datasets/issues/185/events | value:2020-05-22T12:26:25Z | value:https://api.github.com/repos/huggingface/datasets/issues/185/labels{/name} | json:[] | value:CONTRIBUTOR | value:2020-05-22T14:06:35Z | json:{"login": "patrickvonplaten", "id": 23423619, "node_id": "MDQ6VXNlcjIzNDIzNjE5", "avatar_url": "https://avatars.githubusercontent.com/u/23423619?v=4", "gravatar_id": "", "url": "https://api.github.com/users/patrickvonplaten", "html_url": "https://github.com/patrickvonplaten", "followers_url": "https://api.github.c... | value:MDExOlB1bGxSZXF1ZXN0NDIxODkxNjY2 | true | |||||||||
value:2020-05-28T08:31:18Z | value:https://api.github.com/repos/huggingface/datasets/issues/184/timeline | value:0 | value:https://api.github.com/repos/huggingface/datasets | json:{"login": "lhoestq", "id": 42851186, "node_id": "MDQ6VXNlcjQyODUxMTg2", "avatar_url": "https://avatars.githubusercontent.com/u/42851186?v=4", "gravatar_id": "", "url": "https://api.github.com/users/lhoestq", "html_url": "https://github.com/lhoestq", "followers_url": "https://api.github.com/users/lhoestq/followers"... | value:closed | value:https://github.com/huggingface/datasets/pull/184 | value:https://api.github.com/repos/huggingface/datasets/issues/184/comments | value:**`default __iter__ needs IndexError`**.
When I want to create a wrapper of arrow dataset to adapt to fastai,
I don't know how to initialize it, so I didn't use inheritance but use object composition.
I wrote sth like this.
```
clas HF_dataset():
def __init__(self, arrow_dataset):
self.dset = arrow... | value:False | value:https://api.github.com/repos/huggingface/datasets/issues/184 | json:[] | value:184 | value:Use IndexError instead of ValueError when index out of range | value:623120929 | json:[] | value:False | json:{"url": "https://api.github.com/repos/huggingface/datasets/issues/184/reactions", "total_count": 0, "+1": 0, "-1": 0, "laugh": 0, "hooray": 0, "confused": 0, "heart": 0, "rocket": 0, "eyes": 0} | json:{"url": "https://api.github.com/repos/huggingface/datasets/pulls/184", "html_url": "https://github.com/huggingface/datasets/pull/184", "diff_url": "https://github.com/huggingface/datasets/pull/184.diff", "patch_url": "https://github.com/huggingface/datasets/pull/184.patch", "merged_at": "2020-05-28T08:31:18Z"} | value:https://api.github.com/repos/huggingface/datasets/issues/184/events | value:2020-05-22T10:43:42Z | value:https://api.github.com/repos/huggingface/datasets/issues/184/labels{/name} | json:[] | value:CONTRIBUTOR | value:2020-05-28T08:31:18Z | json:{"login": "richarddwang", "id": 17963619, "node_id": "MDQ6VXNlcjE3OTYzNjE5", "avatar_url": "https://avatars.githubusercontent.com/u/17963619?v=4", "gravatar_id": "", "url": "https://api.github.com/users/richarddwang", "html_url": "https://github.com/richarddwang", "followers_url": "https://api.github.com/users/ric... | value:MDExOlB1bGxSZXF1ZXN0NDIxODQ5MTQ3 | true | |||||||||
value:2020-05-22T22:14:05Z | value:https://api.github.com/repos/huggingface/datasets/issues/183/timeline | json:{"total": 0, "completed": 0, "percent_completed": 0} | value:2 | value:https://api.github.com/repos/huggingface/datasets | json:{"login": "richarddwang", "id": 17963619, "node_id": "MDQ6VXNlcjE3OTYzNjE5", "avatar_url": "https://avatars.githubusercontent.com/u/17963619?v=4", "gravatar_id": "", "url": "https://api.github.com/users/richarddwang", "html_url": "https://github.com/richarddwang", "followers_url": "https://api.github.com/users/ric... | value:completed | value:closed | value:https://github.com/huggingface/datasets/issues/183 | json:{"login": "lhoestq", "id": 42851186, "node_id": "MDQ6VXNlcjQyODUxMTg2", "avatar_url": "https://avatars.githubusercontent.com/u/42851186?v=4", "gravatar_id": "", "url": "https://api.github.com/users/lhoestq", "html_url": "https://github.com/lhoestq", "followers_url": "https://api.github.com/users/lhoestq/followers"... | value:https://api.github.com/repos/huggingface/datasets/issues/183/comments | value:```
ax = nlp.load_dataset('glue', 'ax')
for i in range(30): print(ax['test'][i]['label'], end=', ')
```
```
-1, -1, -1, -1, -1, -1, -1, -1, -1, -1, -1, -1, -1, -1, -1, -1, -1, -1, -1, -1, -1, -1, -1, -1, -1, -1, -1, -1, -1, -1,
``` | value:https://api.github.com/repos/huggingface/datasets/issues/183 | json:[] | value:183 | value:[Bug] labels of glue/ax are all -1 | value:623054270 | json:[] | json:{"blocked_by": 0, "total_blocked_by": 0, "blocking": 0, "total_blocking": 0} | value:False | json:{"url": "https://api.github.com/repos/huggingface/datasets/issues/183/reactions", "total_count": 0, "+1": 0, "-1": 0, "laugh": 0, "hooray": 0, "confused": 0, "heart": 0, "rocket": 0, "eyes": 0} | value:https://api.github.com/repos/huggingface/datasets/issues/183/events | value:2020-05-22T08:43:36Z | value:https://api.github.com/repos/huggingface/datasets/issues/183/labels{/name} | json:[{"login": "lhoestq", "id": 42851186, "node_id": "MDQ6VXNlcjQyODUxMTg2", "avatar_url": "https://avatars.githubusercontent.com/u/42851186?v=4", "gravatar_id": "", "url": "https://api.github.com/users/lhoestq", "html_url": "https://github.com/lhoestq", "followers_url": "https://api.github.com/users/lhoestq/followers... | value:CONTRIBUTOR | value:2020-05-22T22:14:05Z | json:{"login": "richarddwang", "id": 17963619, "node_id": "MDQ6VXNlcjE3OTYzNjE5", "avatar_url": "https://avatars.githubusercontent.com/u/17963619?v=4", "gravatar_id": "", "url": "https://api.github.com/users/richarddwang", "html_url": "https://github.com/richarddwang", "followers_url": "https://api.github.com/users/ric... | value:MDU6SXNzdWU2MjMwNTQyNzA= | true | |||||||
value:2020-05-22T16:38:23Z | value:https://api.github.com/repos/huggingface/datasets/issues/182/timeline | value:0 | value:https://api.github.com/repos/huggingface/datasets | json:{"login": "patrickvonplaten", "id": 23423619, "node_id": "MDQ6VXNlcjIzNDIzNjE5", "avatar_url": "https://avatars.githubusercontent.com/u/23423619?v=4", "gravatar_id": "", "url": "https://api.github.com/users/patrickvonplaten", "html_url": "https://github.com/patrickvonplaten", "followers_url": "https://api.github.c... | value:closed | value:https://github.com/huggingface/datasets/pull/182 | json:{"login": "patrickvonplaten", "id": 23423619, "node_id": "MDQ6VXNlcjIzNDIzNjE5", "avatar_url": "https://avatars.githubusercontent.com/u/23423619?v=4", "gravatar_id": "", "url": "https://api.github.com/users/patrickvonplaten", "html_url": "https://github.com/patrickvonplaten", "followers_url": "https://api.github.c... | value:https://api.github.com/repos/huggingface/datasets/issues/182/comments | value:Updated the URL for Newsroom download so it's more robust to future changes. | value:False | value:https://api.github.com/repos/huggingface/datasets/issues/182 | json:[] | value:182 | value:Update newsroom.py | value:622646770 | json:[] | value:False | json:{"url": "https://api.github.com/repos/huggingface/datasets/issues/182/reactions", "total_count": 0, "+1": 0, "-1": 0, "laugh": 0, "hooray": 0, "confused": 0, "heart": 0, "rocket": 0, "eyes": 0} | json:{"url": "https://api.github.com/repos/huggingface/datasets/pulls/182", "html_url": "https://github.com/huggingface/datasets/pull/182", "diff_url": "https://github.com/huggingface/datasets/pull/182.diff", "patch_url": "https://github.com/huggingface/datasets/pull/182.patch", "merged_at": "2020-05-22T16:38:23Z"} | value:https://api.github.com/repos/huggingface/datasets/issues/182/events | value:2020-05-21T17:07:43Z | value:https://api.github.com/repos/huggingface/datasets/issues/182/labels{/name} | json:[{"login": "patrickvonplaten", "id": 23423619, "node_id": "MDQ6VXNlcjIzNDIzNjE5", "avatar_url": "https://avatars.githubusercontent.com/u/23423619?v=4", "gravatar_id": "", "url": "https://api.github.com/users/patrickvonplaten", "html_url": "https://github.com/patrickvonplaten", "followers_url": "https://api.github.... | value:CONTRIBUTOR | value:2020-05-22T16:38:23Z | json:{"login": "yoavartzi", "id": 3289873, "node_id": "MDQ6VXNlcjMyODk4NzM=", "avatar_url": "https://avatars.githubusercontent.com/u/3289873?v=4", "gravatar_id": "", "url": "https://api.github.com/users/yoavartzi", "html_url": "https://github.com/yoavartzi", "followers_url": "https://api.github.com/users/yoavartzi/foll... | value:MDExOlB1bGxSZXF1ZXN0NDIxNDcxMjg4 | true | ||||||||
value:2020-06-18T22:14:42Z | value:https://api.github.com/repos/huggingface/datasets/issues/181/timeline | json:{"total": 0, "completed": 0, "percent_completed": 0} | value:6 | value:https://api.github.com/repos/huggingface/datasets | json:{"login": "lhoestq", "id": 42851186, "node_id": "MDQ6VXNlcjQyODUxMTg2", "avatar_url": "https://avatars.githubusercontent.com/u/42851186?v=4", "gravatar_id": "", "url": "https://api.github.com/users/lhoestq", "html_url": "https://github.com/lhoestq", "followers_url": "https://api.github.com/users/lhoestq/followers"... | value:completed | value:closed | value:https://github.com/huggingface/datasets/issues/181 | value:https://api.github.com/repos/huggingface/datasets/issues/181/comments | value:I look into `nlp-cli` and `user.py` to learn how to upload my own data.
It is supposed to work like this
- Register to get username, password at huggingface.co
- `nlp-cli login` and type username, passworld
- I have a single file to upload at `./ttc/ttc_freq_extra.csv`
- `nlp-cli upload ttc/ttc_freq_extra.... | value:https://api.github.com/repos/huggingface/datasets/issues/181 | json:[] | value:181 | value:Cannot upload my own dataset | value:622634420 | json:[] | json:{"blocked_by": 0, "total_blocked_by": 0, "blocking": 0, "total_blocking": 0} | value:False | json:{"url": "https://api.github.com/repos/huggingface/datasets/issues/181/reactions", "total_count": 0, "+1": 0, "-1": 0, "laugh": 0, "hooray": 0, "confused": 0, "heart": 0, "rocket": 0, "eyes": 0} | value:https://api.github.com/repos/huggingface/datasets/issues/181/events | value:2020-05-21T16:45:52Z | value:https://api.github.com/repos/huggingface/datasets/issues/181/labels{/name} | json:[] | value:NONE | value:2020-06-18T22:14:42Z | json:{"login": "korakot", "id": 3155646, "node_id": "MDQ6VXNlcjMxNTU2NDY=", "avatar_url": "https://avatars.githubusercontent.com/u/3155646?v=4", "gravatar_id": "", "url": "https://api.github.com/users/korakot", "html_url": "https://github.com/korakot", "followers_url": "https://api.github.com/users/korakot/followers", ... | value:MDU6SXNzdWU2MjI2MzQ0MjA= | true | ||||||||
value:2020-05-22T16:35:14Z | value:https://api.github.com/repos/huggingface/datasets/issues/180/timeline | value:0 | value:https://api.github.com/repos/huggingface/datasets | json:{"login": "patrickvonplaten", "id": 23423619, "node_id": "MDQ6VXNlcjIzNDIzNjE5", "avatar_url": "https://avatars.githubusercontent.com/u/23423619?v=4", "gravatar_id": "", "url": "https://api.github.com/users/patrickvonplaten", "html_url": "https://github.com/patrickvonplaten", "followers_url": "https://api.github.c... | value:closed | value:https://github.com/huggingface/datasets/pull/180 | value:https://api.github.com/repos/huggingface/datasets/issues/180/comments | value:powered by https://github.com/sourcerer-io/hall-of-fame | value:False | value:https://api.github.com/repos/huggingface/datasets/issues/180 | json:[] | value:180 | value:Add hall of fame | value:622556861 | json:[] | value:False | json:{"url": "https://api.github.com/repos/huggingface/datasets/issues/180/reactions", "total_count": 0, "+1": 0, "-1": 0, "laugh": 0, "hooray": 0, "confused": 0, "heart": 0, "rocket": 0, "eyes": 0} | json:{"url": "https://api.github.com/repos/huggingface/datasets/pulls/180", "html_url": "https://github.com/huggingface/datasets/pull/180", "diff_url": "https://github.com/huggingface/datasets/pull/180.diff", "patch_url": "https://github.com/huggingface/datasets/pull/180.patch", "merged_at": "2020-05-22T16:35:14Z"} | value:https://api.github.com/repos/huggingface/datasets/issues/180/events | value:2020-05-21T14:53:48Z | value:https://api.github.com/repos/huggingface/datasets/issues/180/labels{/name} | json:[] | value:MEMBER | value:2020-05-22T16:35:16Z | json:{"login": "clmnt", "id": 821155, "node_id": "MDQ6VXNlcjgyMTE1NQ==", "avatar_url": "https://avatars.githubusercontent.com/u/821155?v=4", "gravatar_id": "", "url": "https://api.github.com/users/clmnt", "html_url": "https://github.com/clmnt", "followers_url": "https://api.github.com/users/clmnt/followers", "following... | value:MDExOlB1bGxSZXF1ZXN0NDIxMzk5Nzg2 | true | |||||||||
value:2020-05-22T13:31:07Z | value:https://api.github.com/repos/huggingface/datasets/issues/179/timeline | json:{"total": 0, "completed": 0, "percent_completed": 0} | value:2 | value:https://api.github.com/repos/huggingface/datasets | json:{"login": "yjernite", "id": 10469459, "node_id": "MDQ6VXNlcjEwNDY5NDU5", "avatar_url": "https://avatars.githubusercontent.com/u/10469459?v=4", "gravatar_id": "", "url": "https://api.github.com/users/yjernite", "html_url": "https://github.com/yjernite", "followers_url": "https://api.github.com/users/yjernite/follow... | value:completed | value:closed | value:https://github.com/huggingface/datasets/issues/179 | json:{"login": "lhoestq", "id": 42851186, "node_id": "MDQ6VXNlcjQyODUxMTg2", "avatar_url": "https://avatars.githubusercontent.com/u/42851186?v=4", "gravatar_id": "", "url": "https://api.github.com/users/lhoestq", "html_url": "https://github.com/lhoestq", "followers_url": "https://api.github.com/users/lhoestq/followers"... | value:https://api.github.com/repos/huggingface/datasets/issues/179/comments | value:Currently, the name of an nlp.NamedSplit is parsed in arrow_reader.py and used as the instruction.
This makes it impossible to have several training sets, which can occur when:
- A dataset corresponds to a collection of sub-datasets
- A dataset was built in stages, adding new examples at each stage
Would ... | value:https://api.github.com/repos/huggingface/datasets/issues/179 | json:[] | value:179 | value:[Feature request] separate split name and split instructions | value:622525410 | json:[] | json:{"blocked_by": 0, "total_blocked_by": 0, "blocking": 0, "total_blocking": 0} | value:False | json:{"url": "https://api.github.com/repos/huggingface/datasets/issues/179/reactions", "total_count": 0, "+1": 0, "-1": 0, "laugh": 0, "hooray": 0, "confused": 0, "heart": 0, "rocket": 0, "eyes": 0} | value:https://api.github.com/repos/huggingface/datasets/issues/179/events | value:2020-05-21T14:10:51Z | value:https://api.github.com/repos/huggingface/datasets/issues/179/labels{/name} | json:[{"login": "lhoestq", "id": 42851186, "node_id": "MDQ6VXNlcjQyODUxMTg2", "avatar_url": "https://avatars.githubusercontent.com/u/42851186?v=4", "gravatar_id": "", "url": "https://api.github.com/users/lhoestq", "html_url": "https://github.com/lhoestq", "followers_url": "https://api.github.com/users/lhoestq/followers... | value:MEMBER | value:2020-05-22T13:31:08Z | json:{"login": "yjernite", "id": 10469459, "node_id": "MDQ6VXNlcjEwNDY5NDU5", "avatar_url": "https://avatars.githubusercontent.com/u/10469459?v=4", "gravatar_id": "", "url": "https://api.github.com/users/yjernite", "html_url": "https://github.com/yjernite", "followers_url": "https://api.github.com/users/yjernite/follow... | value:MDU6SXNzdWU2MjI1MjU0MTA= | true | |||||||
value:2020-05-20T18:18:50Z | value:https://api.github.com/repos/huggingface/datasets/issues/178/timeline | value:0 | value:https://api.github.com/repos/huggingface/datasets | json:{"login": "patrickvonplaten", "id": 23423619, "node_id": "MDQ6VXNlcjIzNDIzNjE5", "avatar_url": "https://avatars.githubusercontent.com/u/23423619?v=4", "gravatar_id": "", "url": "https://api.github.com/users/patrickvonplaten", "html_url": "https://github.com/patrickvonplaten", "followers_url": "https://api.github.c... | value:closed | value:https://github.com/huggingface/datasets/pull/178 | value:https://api.github.com/repos/huggingface/datasets/issues/178/comments | value:`nlp.load("xsum")` now leads to the following error message:

I guess the manual download instructions for `xsum` can also be improved. | value:False | value:https://api.github.com/repos/huggingface/datasets/issues/178 | json:[] | value:178 | value:[Manual data] improve error message for manual data in general | value:621979849 | json:[] | value:False | json:{"url": "https://api.github.com/repos/huggingface/datasets/issues/178/reactions", "total_count": 0, "+1": 0, "-1": 0, "laugh": 0, "hooray": 0, "confused": 0, "heart": 0, "rocket": 0, "eyes": 0} | json:{"url": "https://api.github.com/repos/huggingface/datasets/pulls/178", "html_url": "https://github.com/huggingface/datasets/pull/178", "diff_url": "https://github.com/huggingface/datasets/pull/178.diff", "patch_url": "https://github.com/huggingface/datasets/pull/178.patch", "merged_at": "2020-05-20T18:18:50Z"} | value:https://api.github.com/repos/huggingface/datasets/issues/178/events | value:2020-05-20T18:10:45Z | value:https://api.github.com/repos/huggingface/datasets/issues/178/labels{/name} | json:[] | value:CONTRIBUTOR | value:2020-05-20T18:18:52Z | json:{"login": "patrickvonplaten", "id": 23423619, "node_id": "MDQ6VXNlcjIzNDIzNjE5", "avatar_url": "https://avatars.githubusercontent.com/u/23423619?v=4", "gravatar_id": "", "url": "https://api.github.com/users/patrickvonplaten", "html_url": "https://github.com/patrickvonplaten", "followers_url": "https://api.github.c... | value:MDExOlB1bGxSZXF1ZXN0NDIwOTMyMDI5 | true | |||||||||
value:2020-05-20T18:16:49Z | value:https://api.github.com/repos/huggingface/datasets/issues/177/timeline | value:0 | value:https://api.github.com/repos/huggingface/datasets | json:{"login": "patrickvonplaten", "id": 23423619, "node_id": "MDQ6VXNlcjIzNDIzNjE5", "avatar_url": "https://avatars.githubusercontent.com/u/23423619?v=4", "gravatar_id": "", "url": "https://api.github.com/users/patrickvonplaten", "html_url": "https://github.com/patrickvonplaten", "followers_url": "https://api.github.c... | value:closed | value:https://github.com/huggingface/datasets/pull/177 | value:https://api.github.com/repos/huggingface/datasets/issues/177/comments | value: | value:False | value:https://api.github.com/repos/huggingface/datasets/issues/177 | json:[] | value:177 | value:Xsum manual download instruction | value:621975368 | json:[] | value:False | json:{"url": "https://api.github.com/repos/huggingface/datasets/issues/177/reactions", "total_count": 0, "+1": 0, "-1": 0, "laugh": 0, "hooray": 0, "confused": 0, "heart": 0, "rocket": 0, "eyes": 0} | json:{"url": "https://api.github.com/repos/huggingface/datasets/pulls/177", "html_url": "https://github.com/huggingface/datasets/pull/177", "diff_url": "https://github.com/huggingface/datasets/pull/177.diff", "patch_url": "https://github.com/huggingface/datasets/pull/177.patch", "merged_at": "2020-05-20T18:16:49Z"} | value:https://api.github.com/repos/huggingface/datasets/issues/177/events | value:2020-05-20T18:02:41Z | value:https://api.github.com/repos/huggingface/datasets/issues/177/labels{/name} | json:[] | value:CONTRIBUTOR | value:2020-05-20T18:16:50Z | json:{"login": "mariamabarham", "id": 38249783, "node_id": "MDQ6VXNlcjM4MjQ5Nzgz", "avatar_url": "https://avatars.githubusercontent.com/u/38249783?v=4", "gravatar_id": "", "url": "https://api.github.com/users/mariamabarham", "html_url": "https://github.com/mariamabarham", "followers_url": "https://api.github.com/users/... | value:MDExOlB1bGxSZXF1ZXN0NDIwOTI4MzE0 | true | |||||||||
value:2020-05-20T18:17:18Z | value:https://api.github.com/repos/huggingface/datasets/issues/176/timeline | value:0 | value:https://api.github.com/repos/huggingface/datasets | json:{"login": "patrickvonplaten", "id": 23423619, "node_id": "MDQ6VXNlcjIzNDIzNjE5", "avatar_url": "https://avatars.githubusercontent.com/u/23423619?v=4", "gravatar_id": "", "url": "https://api.github.com/users/patrickvonplaten", "html_url": "https://github.com/patrickvonplaten", "followers_url": "https://api.github.c... | value:closed | value:https://github.com/huggingface/datasets/pull/176 | value:https://api.github.com/repos/huggingface/datasets/issues/176/comments | value:Clean mock download manager class.
The print function was not of much help I think.
We should think about adding a command that creates the dummy folder structure for the user. | value:False | value:https://api.github.com/repos/huggingface/datasets/issues/176 | json:[] | value:176 | value:[Tests] Refactor MockDownloadManager | value:621934638 | json:[] | value:False | json:{"url": "https://api.github.com/repos/huggingface/datasets/issues/176/reactions", "total_count": 0, "+1": 0, "-1": 0, "laugh": 0, "hooray": 0, "confused": 0, "heart": 0, "rocket": 0, "eyes": 0} | json:{"url": "https://api.github.com/repos/huggingface/datasets/pulls/176", "html_url": "https://github.com/huggingface/datasets/pull/176", "diff_url": "https://github.com/huggingface/datasets/pull/176.diff", "patch_url": "https://github.com/huggingface/datasets/pull/176.patch", "merged_at": "2020-05-20T18:17:18Z"} | value:https://api.github.com/repos/huggingface/datasets/issues/176/events | value:2020-05-20T17:07:36Z | value:https://api.github.com/repos/huggingface/datasets/issues/176/labels{/name} | json:[] | value:CONTRIBUTOR | value:2020-05-20T18:17:19Z | json:{"login": "patrickvonplaten", "id": 23423619, "node_id": "MDQ6VXNlcjIzNDIzNjE5", "avatar_url": "https://avatars.githubusercontent.com/u/23423619?v=4", "gravatar_id": "", "url": "https://api.github.com/users/patrickvonplaten", "html_url": "https://github.com/patrickvonplaten", "followers_url": "https://api.github.c... | value:MDExOlB1bGxSZXF1ZXN0NDIwODkzNDky | true | |||||||||
value:2020-05-20T18:18:50Z | value:https://api.github.com/repos/huggingface/datasets/issues/175/timeline | json:{"total": 0, "completed": 0, "percent_completed": 0} | value:0 | value:https://api.github.com/repos/huggingface/datasets | json:{"login": "patrickvonplaten", "id": 23423619, "node_id": "MDQ6VXNlcjIzNDIzNjE5", "avatar_url": "https://avatars.githubusercontent.com/u/23423619?v=4", "gravatar_id": "", "url": "https://api.github.com/users/patrickvonplaten", "html_url": "https://github.com/patrickvonplaten", "followers_url": "https://api.github.c... | value:completed | value:closed | value:https://github.com/huggingface/datasets/issues/175 | value:https://api.github.com/repos/huggingface/datasets/issues/175/comments | value:v 0.1.0 from pip
```python
import nlp
xsum = nlp.load_dataset('xsum')
```
Issue is `dl_manager.manual_dir`is `None`
```python
---------------------------------------------------------------------------
TypeError Traceback (most recent call last)
<ipython-input-42-8... | value:https://api.github.com/repos/huggingface/datasets/issues/175 | json:[] | value:175 | value:[Manual data dir] Error message: nlp.load_dataset('xsum') -> TypeError | value:621929428 | json:[] | json:{"blocked_by": 0, "total_blocked_by": 0, "blocking": 0, "total_blocking": 0} | value:False | json:{"url": "https://api.github.com/repos/huggingface/datasets/issues/175/reactions", "total_count": 0, "+1": 0, "-1": 0, "laugh": 0, "hooray": 0, "confused": 0, "heart": 0, "rocket": 0, "eyes": 0} | value:https://api.github.com/repos/huggingface/datasets/issues/175/events | value:2020-05-20T17:00:32Z | value:https://api.github.com/repos/huggingface/datasets/issues/175/labels{/name} | json:[] | value:CONTRIBUTOR | value:2020-05-20T18:18:50Z | json:{"login": "sshleifer", "id": 6045025, "node_id": "MDQ6VXNlcjYwNDUwMjU=", "avatar_url": "https://avatars.githubusercontent.com/u/6045025?v=4", "gravatar_id": "", "url": "https://api.github.com/users/sshleifer", "html_url": "https://github.com/sshleifer", "followers_url": "https://api.github.com/users/sshleifer/foll... | value:MDU6SXNzdWU2MjE5Mjk0Mjg= | true | ||||||||
value:2020-05-20T17:43:46Z | value:https://api.github.com/repos/huggingface/datasets/issues/174/timeline | json:{"total": 0, "completed": 0, "percent_completed": 0} | value:0 | value:https://api.github.com/repos/huggingface/datasets | json:{"login": "sshleifer", "id": 6045025, "node_id": "MDQ6VXNlcjYwNDUwMjU=", "avatar_url": "https://avatars.githubusercontent.com/u/6045025?v=4", "gravatar_id": "", "url": "https://api.github.com/users/sshleifer", "html_url": "https://github.com/sshleifer", "followers_url": "https://api.github.com/users/sshleifer/foll... | value:completed | value:closed | value:https://github.com/huggingface/datasets/issues/174 | value:https://api.github.com/repos/huggingface/datasets/issues/174/comments | value: | value:https://api.github.com/repos/huggingface/datasets/issues/174 | json:[] | value:174 | value:nlp.load_dataset('xsum') -> TypeError | value:621928403 | json:[] | json:{"blocked_by": 0, "total_blocked_by": 0, "blocking": 0, "total_blocking": 0} | value:False | json:{"url": "https://api.github.com/repos/huggingface/datasets/issues/174/reactions", "total_count": 0, "+1": 0, "-1": 0, "laugh": 0, "hooray": 0, "confused": 0, "heart": 0, "rocket": 0, "eyes": 0} | value:https://api.github.com/repos/huggingface/datasets/issues/174/events | value:2020-05-20T16:59:09Z | value:https://api.github.com/repos/huggingface/datasets/issues/174/labels{/name} | json:[] | value:CONTRIBUTOR | value:2020-05-20T17:43:46Z | json:{"login": "sshleifer", "id": 6045025, "node_id": "MDQ6VXNlcjYwNDUwMjU=", "avatar_url": "https://avatars.githubusercontent.com/u/6045025?v=4", "gravatar_id": "", "url": "https://api.github.com/users/sshleifer", "html_url": "https://github.com/sshleifer", "followers_url": "https://api.github.com/users/sshleifer/foll... | value:MDU6SXNzdWU2MjE5Mjg0MDM= | true | ||||||||
value:2020-05-22T16:34:35Z | value:https://api.github.com/repos/huggingface/datasets/issues/173/timeline | value:2 | value:https://api.github.com/repos/huggingface/datasets | json:{"login": "lhoestq", "id": 42851186, "node_id": "MDQ6VXNlcjQyODUxMTg2", "avatar_url": "https://avatars.githubusercontent.com/u/42851186?v=4", "gravatar_id": "", "url": "https://api.github.com/users/lhoestq", "html_url": "https://github.com/lhoestq", "followers_url": "https://api.github.com/users/lhoestq/followers"... | value:closed | value:https://github.com/huggingface/datasets/pull/173 | value:https://api.github.com/repos/huggingface/datasets/issues/173/comments | value:All the dummy data used for tests were duplicated. For each dataset, we had one zip file but also its extracted directory. I removed all these directories
Furthermore instead of extracting next to the dummy_data.zip file, we extract in the temp `cached_dir` used for tests, so that all the extracted directories... | value:False | value:https://api.github.com/repos/huggingface/datasets/issues/173 | json:[] | value:173 | value:Rm extracted test dirs | value:621764932 | json:[] | value:False | json:{"url": "https://api.github.com/repos/huggingface/datasets/issues/173/reactions", "total_count": 0, "+1": 0, "-1": 0, "laugh": 0, "hooray": 0, "confused": 0, "heart": 0, "rocket": 0, "eyes": 0} | json:{"url": "https://api.github.com/repos/huggingface/datasets/pulls/173", "html_url": "https://github.com/huggingface/datasets/pull/173", "diff_url": "https://github.com/huggingface/datasets/pull/173.diff", "patch_url": "https://github.com/huggingface/datasets/pull/173.patch", "merged_at": "2020-05-22T16:34:35Z"} | value:https://api.github.com/repos/huggingface/datasets/issues/173/events | value:2020-05-20T13:30:48Z | value:https://api.github.com/repos/huggingface/datasets/issues/173/labels{/name} | json:[] | value:MEMBER | value:2020-05-22T16:34:36Z | json:{"login": "lhoestq", "id": 42851186, "node_id": "MDQ6VXNlcjQyODUxMTg2", "avatar_url": "https://avatars.githubusercontent.com/u/42851186?v=4", "gravatar_id": "", "url": "https://api.github.com/users/lhoestq", "html_url": "https://github.com/lhoestq", "followers_url": "https://api.github.com/users/lhoestq/followers"... | value:MDExOlB1bGxSZXF1ZXN0NDIwNzUyNzQy | true | |||||||||
value:2020-05-23T11:27:52Z | value:https://api.github.com/repos/huggingface/datasets/issues/172/timeline | json:{"total": 0, "completed": 0, "percent_completed": 0} | value:2 | value:https://api.github.com/repos/huggingface/datasets | json:{"login": "lhoestq", "id": 42851186, "node_id": "MDQ6VXNlcjQyODUxMTg2", "avatar_url": "https://avatars.githubusercontent.com/u/42851186?v=4", "gravatar_id": "", "url": "https://api.github.com/users/lhoestq", "html_url": "https://github.com/lhoestq", "followers_url": "https://api.github.com/users/lhoestq/followers"... | value:completed | value:closed | value:https://github.com/huggingface/datasets/issues/172 | json:{"login": "lhoestq", "id": 42851186, "node_id": "MDQ6VXNlcjQyODUxMTg2", "avatar_url": "https://avatars.githubusercontent.com/u/42851186?v=4", "gravatar_id": "", "url": "https://api.github.com/users/lhoestq", "html_url": "https://github.com/lhoestq", "followers_url": "https://api.github.com/users/lhoestq/followers"... | value:https://api.github.com/repos/huggingface/datasets/issues/172/comments | value:Cloning in a windows environment is not working because of use of special character '?' in folder name ..
Please consider changing the folder name ....
Reference to folder -
nlp/datasets/cnn_dailymail/dummy/3.0.0/3.0.0/dummy_data-zip-extracted/dummy_data/uc?export=download&id=0BwmD_VLjROrfM1BxdkxVaTY2bWs/daily... | value:https://api.github.com/repos/huggingface/datasets/issues/172 | json:[] | value:172 | value:Clone not working on Windows environment | value:621377386 | json:[] | json:{"blocked_by": 0, "total_blocked_by": 0, "blocking": 0, "total_blocking": 0} | value:False | json:{"url": "https://api.github.com/repos/huggingface/datasets/issues/172/reactions", "total_count": 0, "+1": 0, "-1": 0, "laugh": 0, "hooray": 0, "confused": 0, "heart": 0, "rocket": 0, "eyes": 0} | value:https://api.github.com/repos/huggingface/datasets/issues/172/events | value:2020-05-20T00:45:14Z | value:https://api.github.com/repos/huggingface/datasets/issues/172/labels{/name} | json:[{"login": "lhoestq", "id": 42851186, "node_id": "MDQ6VXNlcjQyODUxMTg2", "avatar_url": "https://avatars.githubusercontent.com/u/42851186?v=4", "gravatar_id": "", "url": "https://api.github.com/users/lhoestq", "html_url": "https://github.com/lhoestq", "followers_url": "https://api.github.com/users/lhoestq/followers... | value:CONTRIBUTOR | value:2020-05-23T12:49:13Z | json:{"login": "codehunk628", "id": 51091425, "node_id": "MDQ6VXNlcjUxMDkxNDI1", "avatar_url": "https://avatars.githubusercontent.com/u/51091425?v=4", "gravatar_id": "", "url": "https://api.github.com/users/codehunk628", "html_url": "https://github.com/codehunk628", "followers_url": "https://api.github.com/users/codehu... | value:MDU6SXNzdWU2MjEzNzczODY= | true | |||||||
value:2020-05-22T13:36:48Z | value:https://api.github.com/repos/huggingface/datasets/issues/171/timeline | value:5 | value:https://api.github.com/repos/huggingface/datasets | json:{"login": "lhoestq", "id": 42851186, "node_id": "MDQ6VXNlcjQyODUxMTg2", "avatar_url": "https://avatars.githubusercontent.com/u/42851186?v=4", "gravatar_id": "", "url": "https://api.github.com/users/lhoestq", "html_url": "https://github.com/lhoestq", "followers_url": "https://api.github.com/users/lhoestq/followers"... | value:closed | value:https://github.com/huggingface/datasets/pull/171 | value:https://api.github.com/repos/huggingface/datasets/issues/171/comments | value:The format of the squad metric was wrong.
This should fix #143
I tested with
```python3
predictions = [
{'id': '56be4db0acb8001400a502ec', 'prediction_text': 'Denver Broncos'}
]
references = [
{'answers': [{'text': 'Denver Broncos'}], 'id': '56be4db0acb8001400a502ec'}
]
``` | value:False | value:https://api.github.com/repos/huggingface/datasets/issues/171 | json:[] | value:171 | value:fix squad metric format | value:621199128 | json:[] | value:False | json:{"url": "https://api.github.com/repos/huggingface/datasets/issues/171/reactions", "total_count": 0, "+1": 0, "-1": 0, "laugh": 0, "hooray": 0, "confused": 0, "heart": 0, "rocket": 0, "eyes": 0} | json:{"url": "https://api.github.com/repos/huggingface/datasets/pulls/171", "html_url": "https://github.com/huggingface/datasets/pull/171", "diff_url": "https://github.com/huggingface/datasets/pull/171.diff", "patch_url": "https://github.com/huggingface/datasets/pull/171.patch", "merged_at": "2020-05-22T13:36:48Z"} | value:https://api.github.com/repos/huggingface/datasets/issues/171/events | value:2020-05-19T18:37:36Z | value:https://api.github.com/repos/huggingface/datasets/issues/171/labels{/name} | json:[] | value:MEMBER | value:2020-05-22T13:36:50Z | json:{"login": "lhoestq", "id": 42851186, "node_id": "MDQ6VXNlcjQyODUxMTg2", "avatar_url": "https://avatars.githubusercontent.com/u/42851186?v=4", "gravatar_id": "", "url": "https://api.github.com/users/lhoestq", "html_url": "https://github.com/lhoestq", "followers_url": "https://api.github.com/users/lhoestq/followers"... | value:MDExOlB1bGxSZXF1ZXN0NDIwMjk0ODM0 | true | |||||||||
value:2020-05-20T12:23:08Z | value:https://api.github.com/repos/huggingface/datasets/issues/170/timeline | value:0 | value:https://api.github.com/repos/huggingface/datasets | json:{"login": "lhoestq", "id": 42851186, "node_id": "MDQ6VXNlcjQyODUxMTg2", "avatar_url": "https://avatars.githubusercontent.com/u/42851186?v=4", "gravatar_id": "", "url": "https://api.github.com/users/lhoestq", "html_url": "https://github.com/lhoestq", "followers_url": "https://api.github.com/users/lhoestq/followers"... | value:closed | value:https://github.com/huggingface/datasets/pull/170 | value:https://api.github.com/repos/huggingface/datasets/issues/170/comments | value:What we have now as the `anli` dataset is actually the αNLI dataset from the ART challenge dataset. This name is confusing because `anli` is also the name of adversarial NLI (see [https://github.com/facebookresearch/anli](https://github.com/facebookresearch/anli)).
I renamed the current `anli` dataset by `art`... | value:False | value:https://api.github.com/repos/huggingface/datasets/issues/170 | json:[] | value:170 | value:Rename anli dataset | value:621119747 | json:[] | value:False | json:{"url": "https://api.github.com/repos/huggingface/datasets/issues/170/reactions", "total_count": 0, "+1": 0, "-1": 0, "laugh": 0, "hooray": 0, "confused": 0, "heart": 0, "rocket": 0, "eyes": 0} | json:{"url": "https://api.github.com/repos/huggingface/datasets/pulls/170", "html_url": "https://github.com/huggingface/datasets/pull/170", "diff_url": "https://github.com/huggingface/datasets/pull/170.diff", "patch_url": "https://github.com/huggingface/datasets/pull/170.patch", "merged_at": "2020-05-20T12:23:07Z"} | value:https://api.github.com/repos/huggingface/datasets/issues/170/events | value:2020-05-19T16:26:57Z | value:https://api.github.com/repos/huggingface/datasets/issues/170/labels{/name} | json:[] | value:MEMBER | value:2020-05-20T12:23:09Z | json:{"login": "lhoestq", "id": 42851186, "node_id": "MDQ6VXNlcjQyODUxMTg2", "avatar_url": "https://avatars.githubusercontent.com/u/42851186?v=4", "gravatar_id": "", "url": "https://api.github.com/users/lhoestq", "html_url": "https://github.com/lhoestq", "followers_url": "https://api.github.com/users/lhoestq/followers"... | value:MDExOlB1bGxSZXF1ZXN0NDIwMjMwMDIx | true | |||||||||
value:2020-05-26T12:52:31Z | value:https://api.github.com/repos/huggingface/datasets/issues/169/timeline | value:5 | value:https://api.github.com/repos/huggingface/datasets | json:{"login": "patrickvonplaten", "id": 23423619, "node_id": "MDQ6VXNlcjIzNDIzNjE5", "avatar_url": "https://avatars.githubusercontent.com/u/23423619?v=4", "gravatar_id": "", "url": "https://api.github.com/users/patrickvonplaten", "html_url": "https://github.com/patrickvonplaten", "followers_url": "https://api.github.c... | value:closed | value:https://github.com/huggingface/datasets/pull/169 | json:{"login": "patrickvonplaten", "id": 23423619, "node_id": "MDQ6VXNlcjIzNDIzNjE5", "avatar_url": "https://avatars.githubusercontent.com/u/23423619?v=4", "gravatar_id": "", "url": "https://api.github.com/users/patrickvonplaten", "html_url": "https://github.com/patrickvonplaten", "followers_url": "https://api.github.c... | value:https://api.github.com/repos/huggingface/datasets/issues/169/comments | value:This PR adds the qanta question answering datasets from [Quizbowl: The Case for Incremental Question Answering](https://arxiv.org/abs/1904.04792) and [Trick Me If You Can: Human-in-the-loop Generation of Adversarial Question Answering Examples](https://www.aclweb.org/anthology/Q19-1029/) (adversarial fold)
Thi... | value:False | value:https://api.github.com/repos/huggingface/datasets/issues/169 | json:[] | value:169 | value:Adding Qanta (Quizbowl) Dataset | value:621099682 | json:[] | value:False | json:{"url": "https://api.github.com/repos/huggingface/datasets/issues/169/reactions", "total_count": 0, "+1": 0, "-1": 0, "laugh": 0, "hooray": 0, "confused": 0, "heart": 0, "rocket": 0, "eyes": 0} | json:{"url": "https://api.github.com/repos/huggingface/datasets/pulls/169", "html_url": "https://github.com/huggingface/datasets/pull/169", "diff_url": "https://github.com/huggingface/datasets/pull/169.diff", "patch_url": "https://github.com/huggingface/datasets/pull/169.patch", "merged_at": null} | value:https://api.github.com/repos/huggingface/datasets/issues/169/events | value:2020-05-19T16:03:01Z | value:https://api.github.com/repos/huggingface/datasets/issues/169/labels{/name} | json:[{"login": "patrickvonplaten", "id": 23423619, "node_id": "MDQ6VXNlcjIzNDIzNjE5", "avatar_url": "https://avatars.githubusercontent.com/u/23423619?v=4", "gravatar_id": "", "url": "https://api.github.com/users/patrickvonplaten", "html_url": "https://github.com/patrickvonplaten", "followers_url": "https://api.github.... | value:CONTRIBUTOR | value:2020-05-26T12:52:31Z | json:{"login": "EntilZha", "id": 1382460, "node_id": "MDQ6VXNlcjEzODI0NjA=", "avatar_url": "https://avatars.githubusercontent.com/u/1382460?v=4", "gravatar_id": "", "url": "https://api.github.com/users/EntilZha", "html_url": "https://github.com/EntilZha", "followers_url": "https://api.github.com/users/EntilZha/follower... | value:MDExOlB1bGxSZXF1ZXN0NDIwMjE1NDkw | true | ||||||||
value:2020-05-26T21:46:52Z | value:https://api.github.com/repos/huggingface/datasets/issues/168/timeline | json:{"total": 0, "completed": 0, "percent_completed": 0} | value:6 | value:https://api.github.com/repos/huggingface/datasets | json:{"login": "lhoestq", "id": 42851186, "node_id": "MDQ6VXNlcjQyODUxMTg2", "avatar_url": "https://avatars.githubusercontent.com/u/42851186?v=4", "gravatar_id": "", "url": "https://api.github.com/users/lhoestq", "html_url": "https://github.com/lhoestq", "followers_url": "https://api.github.com/users/lhoestq/followers"... | value:completed | value:closed | value:https://github.com/huggingface/datasets/issues/168 | value:https://api.github.com/repos/huggingface/datasets/issues/168/comments | value:Loading the 'wikitext' dataset fails with Attribute error:
Code to reproduce (From example notebook):
import nlp
wikitext_dataset = nlp.load_dataset('wikitext')
Error:
---------------------------------------------------------------------------
AttributeError Traceback (mos... | value:https://api.github.com/repos/huggingface/datasets/issues/168 | json:[] | value:168 | value:Loading 'wikitext' dataset fails | value:620959819 | json:[] | json:{"blocked_by": 0, "total_blocked_by": 0, "blocking": 0, "total_blocking": 0} | value:False | json:{"url": "https://api.github.com/repos/huggingface/datasets/issues/168/reactions", "total_count": 0, "+1": 0, "-1": 0, "laugh": 0, "hooray": 0, "confused": 0, "heart": 0, "rocket": 0, "eyes": 0} | value:https://api.github.com/repos/huggingface/datasets/issues/168/events | value:2020-05-19T13:04:29Z | value:https://api.github.com/repos/huggingface/datasets/issues/168/labels{/name} | json:[] | value:NONE | value:2020-05-26T21:46:52Z | json:{"login": "itay1itzhak", "id": 25987633, "node_id": "MDQ6VXNlcjI1OTg3NjMz", "avatar_url": "https://avatars.githubusercontent.com/u/25987633?v=4", "gravatar_id": "", "url": "https://api.github.com/users/itay1itzhak", "html_url": "https://github.com/itay1itzhak", "followers_url": "https://api.github.com/users/itay1i... | value:MDU6SXNzdWU2MjA5NTk4MTk= | true | ||||||||
value:2020-05-19T16:17:10Z | value:https://api.github.com/repos/huggingface/datasets/issues/167/timeline | value:1 | value:https://api.github.com/repos/huggingface/datasets | json:{"login": "patrickvonplaten", "id": 23423619, "node_id": "MDQ6VXNlcjIzNDIzNjE5", "avatar_url": "https://avatars.githubusercontent.com/u/23423619?v=4", "gravatar_id": "", "url": "https://api.github.com/users/patrickvonplaten", "html_url": "https://github.com/patrickvonplaten", "followers_url": "https://api.github.c... | value:closed | value:https://github.com/huggingface/datasets/pull/167 | value:https://api.github.com/repos/huggingface/datasets/issues/167/comments | value:This PR separates AWS and Local tests to remove these ugly statements in the script:
```python
if "/" not in dataset_name:
logging.info("Skip {} because it is a canonical dataset")
return
```
To run a `aws` test, one should now run the following command:
```python
pyt... | value:False | value:https://api.github.com/repos/huggingface/datasets/issues/167 | json:[] | value:167 | value:[Tests] refactor tests | value:620908786 | json:[] | value:False | json:{"url": "https://api.github.com/repos/huggingface/datasets/issues/167/reactions", "total_count": 0, "+1": 0, "-1": 0, "laugh": 0, "hooray": 0, "confused": 0, "heart": 0, "rocket": 0, "eyes": 0} | json:{"url": "https://api.github.com/repos/huggingface/datasets/pulls/167", "html_url": "https://github.com/huggingface/datasets/pull/167", "diff_url": "https://github.com/huggingface/datasets/pull/167.diff", "patch_url": "https://github.com/huggingface/datasets/pull/167.patch", "merged_at": "2020-05-19T16:17:10Z"} | value:https://api.github.com/repos/huggingface/datasets/issues/167/events | value:2020-05-19T11:43:32Z | value:https://api.github.com/repos/huggingface/datasets/issues/167/labels{/name} | json:[] | value:CONTRIBUTOR | value:2020-05-19T16:17:12Z | json:{"login": "patrickvonplaten", "id": 23423619, "node_id": "MDQ6VXNlcjIzNDIzNjE5", "avatar_url": "https://avatars.githubusercontent.com/u/23423619?v=4", "gravatar_id": "", "url": "https://api.github.com/users/patrickvonplaten", "html_url": "https://github.com/patrickvonplaten", "followers_url": "https://api.github.c... | value:MDExOlB1bGxSZXF1ZXN0NDIwMDY0NDMw | true | |||||||||
value:2020-06-23T15:07:32Z | value:https://api.github.com/repos/huggingface/datasets/issues/166/timeline | json:{"total": 0, "completed": 0, "percent_completed": 0} | value:4 | value:https://api.github.com/repos/huggingface/datasets | json:{"login": "lhoestq", "id": 42851186, "node_id": "MDQ6VXNlcjQyODUxMTg2", "avatar_url": "https://avatars.githubusercontent.com/u/42851186?v=4", "gravatar_id": "", "url": "https://api.github.com/users/lhoestq", "html_url": "https://github.com/lhoestq", "followers_url": "https://api.github.com/users/lhoestq/followers"... | value:completed | value:closed | value:https://github.com/huggingface/datasets/issues/166 | value:https://api.github.com/repos/huggingface/datasets/issues/166/comments | value:Could maybe be a `dataset.shuffle(generator=None, seed=None)` signature method.
Also, we could maybe have a clear indication of which method modify in-place and which methods return/cache a modified dataset. I kinda like torch conversion of having an underscore suffix for all the methods which modify a dataset... | value:https://api.github.com/repos/huggingface/datasets/issues/166 | json:[] | value:166 | value:Add a method to shuffle a dataset | value:620850218 | json:[{"id": 2067400324, "node_id": "MDU6TGFiZWwyMDY3NDAwMzI0", "url": "https://api.github.com/repos/huggingface/datasets/labels/generic%20discussion", "name": "generic discussion", "color": "c5def5", "default": false, "description": "Generic discussion on the library", "archived_at": null, "archived_by": null}] | json:{"blocked_by": 0, "total_blocked_by": 0, "blocking": 0, "total_blocking": 0} | value:False | json:{"url": "https://api.github.com/repos/huggingface/datasets/issues/166/reactions", "total_count": 0, "+1": 0, "-1": 0, "laugh": 0, "hooray": 0, "confused": 0, "heart": 0, "rocket": 0, "eyes": 0} | value:https://api.github.com/repos/huggingface/datasets/issues/166/events | value:2020-05-19T10:08:46Z | value:https://api.github.com/repos/huggingface/datasets/issues/166/labels{/name} | json:[] | value:MEMBER | value:2020-06-23T15:07:33Z | json:{"login": "thomwolf", "id": 7353373, "node_id": "MDQ6VXNlcjczNTMzNzM=", "avatar_url": "https://avatars.githubusercontent.com/u/7353373?v=4", "gravatar_id": "", "url": "https://api.github.com/users/thomwolf", "html_url": "https://github.com/thomwolf", "followers_url": "https://api.github.com/users/thomwolf/follower... | value:MDU6SXNzdWU2MjA4NTAyMTg= | true | ||||||||
value:2020-05-20T12:23:07Z | value:https://api.github.com/repos/huggingface/datasets/issues/165/timeline | json:{"total": 0, "completed": 0, "percent_completed": 0} | value:0 | value:https://api.github.com/repos/huggingface/datasets | json:{"login": "lhoestq", "id": 42851186, "node_id": "MDQ6VXNlcjQyODUxMTg2", "avatar_url": "https://avatars.githubusercontent.com/u/42851186?v=4", "gravatar_id": "", "url": "https://api.github.com/users/lhoestq", "html_url": "https://github.com/lhoestq", "followers_url": "https://api.github.com/users/lhoestq/followers"... | value:completed | value:closed | value:https://github.com/huggingface/datasets/issues/165 | value:https://api.github.com/repos/huggingface/datasets/issues/165/comments | value:Can I recommend the following:
For ANLI, use https://github.com/facebookresearch/anli. As that paper says, "Our dataset is not
to be confused with abductive NLI (Bhagavatula et al., 2019), which calls itself αNLI, or ART.".
Indeed, the paper cited under what is currently called anli says in the abstract "... | value:https://api.github.com/repos/huggingface/datasets/issues/165 | json:[] | value:165 | value:ANLI | value:620758221 | json:[] | json:{"blocked_by": 0, "total_blocked_by": 0, "blocking": 0, "total_blocking": 0} | value:False | json:{"url": "https://api.github.com/repos/huggingface/datasets/issues/165/reactions", "total_count": 0, "+1": 0, "-1": 0, "laugh": 0, "hooray": 0, "confused": 0, "heart": 0, "rocket": 0, "eyes": 0} | value:https://api.github.com/repos/huggingface/datasets/issues/165/events | value:2020-05-19T07:50:57Z | value:https://api.github.com/repos/huggingface/datasets/issues/165/labels{/name} | json:[] | value:NONE | value:2020-05-20T12:23:07Z | json:{"login": "douwekiela", "id": 6024930, "node_id": "MDQ6VXNlcjYwMjQ5MzA=", "avatar_url": "https://avatars.githubusercontent.com/u/6024930?v=4", "gravatar_id": "", "url": "https://api.github.com/users/douwekiela", "html_url": "https://github.com/douwekiela", "followers_url": "https://api.github.com/users/douwekiela/... | value:MDU6SXNzdWU2MjA3NTgyMjE= | true | ||||||||
value:2020-05-25T16:28:45Z | value:https://api.github.com/repos/huggingface/datasets/issues/164/timeline | json:{"total": 0, "completed": 0, "percent_completed": 0} | value:2 | value:https://api.github.com/repos/huggingface/datasets | json:{"login": "mariamabarham", "id": 38249783, "node_id": "MDQ6VXNlcjM4MjQ5Nzgz", "avatar_url": "https://avatars.githubusercontent.com/u/38249783?v=4", "gravatar_id": "", "url": "https://api.github.com/users/mariamabarham", "html_url": "https://github.com/mariamabarham", "followers_url": "https://api.github.com/users/... | value:completed | value:closed | value:https://github.com/huggingface/datasets/issues/164 | value:https://api.github.com/repos/huggingface/datasets/issues/164/comments | value:Hi guys,
In order to cover multilingual support a little step could be adding standard Datasets used for Spanish NER and POS tasks.
I can provide it in raw and preprocessed formats. | value:https://api.github.com/repos/huggingface/datasets/issues/164 | json:[] | value:164 | value:Add Spanish POR and NER Datasets | value:620540250 | json:[{"id": 2067376369, "node_id": "MDU6TGFiZWwyMDY3Mzc2MzY5", "url": "https://api.github.com/repos/huggingface/datasets/labels/dataset%20request", "name": "dataset request", "color": "e99695", "default": false, "description": "Requesting to add a new dataset", "archived_at": null, "archived_by": null}] | json:{"blocked_by": 0, "total_blocked_by": 0, "blocking": 0, "total_blocking": 0} | value:False | json:{"url": "https://api.github.com/repos/huggingface/datasets/issues/164/reactions", "total_count": 0, "+1": 0, "-1": 0, "laugh": 0, "hooray": 0, "confused": 0, "heart": 0, "rocket": 0, "eyes": 0} | value:https://api.github.com/repos/huggingface/datasets/issues/164/events | value:2020-05-18T22:18:21Z | value:https://api.github.com/repos/huggingface/datasets/issues/164/labels{/name} | json:[] | value:CONTRIBUTOR | value:2020-05-25T16:28:45Z | json:{"login": "mrm8488", "id": 3653789, "node_id": "MDQ6VXNlcjM2NTM3ODk=", "avatar_url": "https://avatars.githubusercontent.com/u/3653789?v=4", "gravatar_id": "", "url": "https://api.github.com/users/mrm8488", "html_url": "https://github.com/mrm8488", "followers_url": "https://api.github.com/users/mrm8488/followers", ... | value:MDU6SXNzdWU2MjA1NDAyNTA= | true | ||||||||
value:2020-06-16T18:52:06Z | value:https://api.github.com/repos/huggingface/datasets/issues/163/timeline | json:{"total": 0, "completed": 0, "percent_completed": 0} | value:10 | value:https://api.github.com/repos/huggingface/datasets | json:{"login": "sarahwie", "id": 8027676, "node_id": "MDQ6VXNlcjgwMjc2NzY=", "avatar_url": "https://avatars.githubusercontent.com/u/8027676?v=4", "gravatar_id": "", "url": "https://api.github.com/users/sarahwie", "html_url": "https://github.com/sarahwie", "followers_url": "https://api.github.com/users/sarahwie/follower... | value:completed | value:closed | value:https://github.com/huggingface/datasets/issues/163 | value:https://api.github.com/repos/huggingface/datasets/issues/163/comments | value:I noticed the second release of cos-e (v1.11) is included in this repo. I wanted to request inclusion of v1.0, since this is the version on which results are reported on in [the paper](https://www.aclweb.org/anthology/P19-1487/), and v1.11 has noted [annotation](https://github.com/salesforce/cos-e/issues/2) [issu... | value:https://api.github.com/repos/huggingface/datasets/issues/163 | json:[] | value:163 | value:[Feature request] Add cos-e v1.0 | value:620534307 | json:[{"id": 2067376369, "node_id": "MDU6TGFiZWwyMDY3Mzc2MzY5", "url": "https://api.github.com/repos/huggingface/datasets/labels/dataset%20request", "name": "dataset request", "color": "e99695", "default": false, "description": "Requesting to add a new dataset", "archived_at": null, "archived_by": null}] | json:{"blocked_by": 0, "total_blocked_by": 0, "blocking": 0, "total_blocking": 0} | value:False | json:{"url": "https://api.github.com/repos/huggingface/datasets/issues/163/reactions", "total_count": 0, "+1": 0, "-1": 0, "laugh": 0, "hooray": 0, "confused": 0, "heart": 0, "rocket": 0, "eyes": 0} | value:https://api.github.com/repos/huggingface/datasets/issues/163/events | value:2020-05-18T22:05:26Z | value:https://api.github.com/repos/huggingface/datasets/issues/163/labels{/name} | json:[] | value:NONE | value:2020-06-16T23:15:25Z | json:{"login": "sarahwie", "id": 8027676, "node_id": "MDQ6VXNlcjgwMjc2NzY=", "avatar_url": "https://avatars.githubusercontent.com/u/8027676?v=4", "gravatar_id": "", "url": "https://api.github.com/users/sarahwie", "html_url": "https://github.com/sarahwie", "followers_url": "https://api.github.com/users/sarahwie/follower... | value:MDU6SXNzdWU2MjA1MzQzMDc= | true | ||||||||
value:2020-05-18T21:36:20Z | value:https://api.github.com/repos/huggingface/datasets/issues/162/timeline | value:3 | value:https://api.github.com/repos/huggingface/datasets | json:{"login": "lhoestq", "id": 42851186, "node_id": "MDQ6VXNlcjQyODUxMTg2", "avatar_url": "https://avatars.githubusercontent.com/u/42851186?v=4", "gravatar_id": "", "url": "https://api.github.com/users/lhoestq", "html_url": "https://github.com/lhoestq", "followers_url": "https://api.github.com/users/lhoestq/followers"... | value:closed | value:https://github.com/huggingface/datasets/pull/162 | value:https://api.github.com/repos/huggingface/datasets/issues/162/comments | value:Fix the `.map` issue in #160.
This makes sure it takes the previous files when computing the hash. | value:False | value:https://api.github.com/repos/huggingface/datasets/issues/162 | json:[] | value:162 | value:fix prev files hash in map | value:620513554 | json:[] | value:False | json:{"url": "https://api.github.com/repos/huggingface/datasets/issues/162/reactions", "total_count": 0, "+1": 0, "-1": 0, "laugh": 0, "hooray": 0, "confused": 0, "heart": 0, "rocket": 0, "eyes": 0} | json:{"url": "https://api.github.com/repos/huggingface/datasets/pulls/162", "html_url": "https://github.com/huggingface/datasets/pull/162", "diff_url": "https://github.com/huggingface/datasets/pull/162.diff", "patch_url": "https://github.com/huggingface/datasets/pull/162.patch", "merged_at": "2020-05-18T21:36:20Z"} | value:https://api.github.com/repos/huggingface/datasets/issues/162/events | value:2020-05-18T21:20:51Z | value:https://api.github.com/repos/huggingface/datasets/issues/162/labels{/name} | json:[] | value:MEMBER | value:2020-05-18T21:36:21Z | json:{"login": "lhoestq", "id": 42851186, "node_id": "MDQ6VXNlcjQyODUxMTg2", "avatar_url": "https://avatars.githubusercontent.com/u/42851186?v=4", "gravatar_id": "", "url": "https://api.github.com/users/lhoestq", "html_url": "https://github.com/lhoestq", "followers_url": "https://api.github.com/users/lhoestq/followers"... | value:MDExOlB1bGxSZXF1ZXN0NDE5NzQ4Mzky | true | |||||||||
value:https://api.github.com/repos/huggingface/datasets/issues/161/timeline | json:{"total": 0, "completed": 0, "percent_completed": 0} | value:13 | value:https://api.github.com/repos/huggingface/datasets | value:open | value:https://github.com/huggingface/datasets/issues/161 | json:{"login": "patrickvonplaten", "id": 23423619, "node_id": "MDQ6VXNlcjIzNDIzNjE5", "avatar_url": "https://avatars.githubusercontent.com/u/23423619?v=4", "gravatar_id": "", "url": "https://api.github.com/users/patrickvonplaten", "html_url": "https://github.com/patrickvonplaten", "followers_url": "https://api.github.c... | value:https://api.github.com/repos/huggingface/datasets/issues/161/comments | value:Hi, I'm working on adding a dataset and ran into an error due to `download` not being defined on `MockDataLoaderManager`, but being defined in `nlp/utils/download_manager.py`. The readme step running this: `RUN_SLOW=1 pytest tests/test_dataset_common.py::DatasetTest::test_load_real_dataset_localmydatasetname` tri... | value:https://api.github.com/repos/huggingface/datasets/issues/161 | json:[] | value:161 | value:Discussion on version identifier & MockDataLoaderManager for test data | value:620487535 | json:[{"id": 2067400324, "node_id": "MDU6TGFiZWwyMDY3NDAwMzI0", "url": "https://api.github.com/repos/huggingface/datasets/labels/generic%20discussion", "name": "generic discussion", "color": "c5def5", "default": false, "description": "Generic discussion on the library", "archived_at": null, "archived_by": null}] | json:{"blocked_by": 0, "total_blocked_by": 0, "blocking": 0, "total_blocking": 0} | value:False | json:{"url": "https://api.github.com/repos/huggingface/datasets/issues/161/reactions", "total_count": 0, "+1": 0, "-1": 0, "laugh": 0, "hooray": 0, "confused": 0, "heart": 0, "rocket": 0, "eyes": 0} | value:https://api.github.com/repos/huggingface/datasets/issues/161/events | value:2020-05-18T20:31:30Z | value:https://api.github.com/repos/huggingface/datasets/issues/161/labels{/name} | json:[{"login": "patrickvonplaten", "id": 23423619, "node_id": "MDQ6VXNlcjIzNDIzNjE5", "avatar_url": "https://avatars.githubusercontent.com/u/23423619?v=4", "gravatar_id": "", "url": "https://api.github.com/users/patrickvonplaten", "html_url": "https://github.com/patrickvonplaten", "followers_url": "https://api.github.... | value:CONTRIBUTOR | value:2026-05-21T23:24:46Z | json:{"login": "EntilZha", "id": 1382460, "node_id": "MDQ6VXNlcjEzODI0NjA=", "avatar_url": "https://avatars.githubusercontent.com/u/1382460?v=4", "gravatar_id": "", "url": "https://api.github.com/users/EntilZha", "html_url": "https://github.com/EntilZha", "followers_url": "https://api.github.com/users/EntilZha/follower... | value:MDU6SXNzdWU2MjA0ODc1MzU= | true | ||||||||||
value:2020-05-18T21:36:20Z | value:https://api.github.com/repos/huggingface/datasets/issues/160/timeline | json:{"total": 0, "completed": 0, "percent_completed": 0} | value:7 | value:https://api.github.com/repos/huggingface/datasets | json:{"login": "lhoestq", "id": 42851186, "node_id": "MDQ6VXNlcjQyODUxMTg2", "avatar_url": "https://avatars.githubusercontent.com/u/42851186?v=4", "gravatar_id": "", "url": "https://api.github.com/users/lhoestq", "html_url": "https://github.com/lhoestq", "followers_url": "https://api.github.com/users/lhoestq/followers"... | value:completed | value:closed | value:https://github.com/huggingface/datasets/issues/160 | json:{"login": "lhoestq", "id": 42851186, "node_id": "MDQ6VXNlcjQyODUxMTg2", "avatar_url": "https://avatars.githubusercontent.com/u/42851186?v=4", "gravatar_id": "", "url": "https://api.github.com/users/lhoestq", "html_url": "https://github.com/lhoestq", "followers_url": "https://api.github.com/users/lhoestq/followers"... | value:https://api.github.com/repos/huggingface/datasets/issues/160/comments | value:hello,
I am working on a program that uses the `nlp` library with the `SST2` dataset.
The rough outline of the program is:
```
import nlp as nlp_datasets
...
parser.add_argument('--dataset', help='HuggingFace Datasets id', default=['glue', 'sst2'], nargs='+')
...
dataset = nlp_datasets.load_dataset(... | value:https://api.github.com/repos/huggingface/datasets/issues/160 | json:[] | value:160 | value:caching in map causes same result to be returned for train, validation and test | value:620448236 | json:[{"id": 2067388877, "node_id": "MDU6TGFiZWwyMDY3Mzg4ODc3", "url": "https://api.github.com/repos/huggingface/datasets/labels/dataset%20bug", "name": "dataset bug", "color": "2edb81", "default": false, "description": "A bug in a dataset script provided in the library", "archived_at": null, "archived_by": null}] | json:{"blocked_by": 0, "total_blocked_by": 0, "blocking": 0, "total_blocking": 0} | value:False | json:{"url": "https://api.github.com/repos/huggingface/datasets/issues/160/reactions", "total_count": 0, "+1": 0, "-1": 0, "laugh": 0, "hooray": 0, "confused": 0, "heart": 0, "rocket": 0, "eyes": 0} | value:https://api.github.com/repos/huggingface/datasets/issues/160/events | value:2020-05-18T19:22:03Z | value:https://api.github.com/repos/huggingface/datasets/issues/160/labels{/name} | json:[{"login": "lhoestq", "id": 42851186, "node_id": "MDQ6VXNlcjQyODUxMTg2", "avatar_url": "https://avatars.githubusercontent.com/u/42851186?v=4", "gravatar_id": "", "url": "https://api.github.com/users/lhoestq", "html_url": "https://github.com/lhoestq", "followers_url": "https://api.github.com/users/lhoestq/followers... | value:NONE | value:2020-05-18T21:36:20Z | json:{"login": "dpressel", "id": 247881, "node_id": "MDQ6VXNlcjI0Nzg4MQ==", "avatar_url": "https://avatars.githubusercontent.com/u/247881?v=4", "gravatar_id": "", "url": "https://api.github.com/users/dpressel", "html_url": "https://github.com/dpressel", "followers_url": "https://api.github.com/users/dpressel/followers"... | value:MDU6SXNzdWU2MjA0NDgyMzY= | true | |||||||
value:2020-05-18T18:37:07Z | value:https://api.github.com/repos/huggingface/datasets/issues/159/timeline | json:{"total": 0, "completed": 0, "percent_completed": 0} | value:1 | value:https://api.github.com/repos/huggingface/datasets | json:{"login": "Tahsin-Mayeesha", "id": 17886829, "node_id": "MDQ6VXNlcjE3ODg2ODI5", "avatar_url": "https://avatars.githubusercontent.com/u/17886829?v=4", "gravatar_id": "", "url": "https://api.github.com/users/Tahsin-Mayeesha", "html_url": "https://github.com/Tahsin-Mayeesha", "followers_url": "https://api.github.com/... | value:completed | value:closed | value:https://github.com/huggingface/datasets/issues/159 | value:https://api.github.com/repos/huggingface/datasets/issues/159/comments | value: | value:https://api.github.com/repos/huggingface/datasets/issues/159 | json:[] | value:159 | value:How can we add more datasets to nlp library? | value:620420700 | json:[] | json:{"blocked_by": 0, "total_blocked_by": 0, "blocking": 0, "total_blocking": 0} | value:False | json:{"url": "https://api.github.com/repos/huggingface/datasets/issues/159/reactions", "total_count": 0, "+1": 0, "-1": 0, "laugh": 0, "hooray": 0, "confused": 0, "heart": 0, "rocket": 0, "eyes": 0} | value:https://api.github.com/repos/huggingface/datasets/issues/159/events | value:2020-05-18T18:35:31Z | value:https://api.github.com/repos/huggingface/datasets/issues/159/labels{/name} | json:[] | value:NONE | value:2020-05-18T18:37:08Z | json:{"login": "Tahsin-Mayeesha", "id": 17886829, "node_id": "MDQ6VXNlcjE3ODg2ODI5", "avatar_url": "https://avatars.githubusercontent.com/u/17886829?v=4", "gravatar_id": "", "url": "https://api.github.com/users/Tahsin-Mayeesha", "html_url": "https://github.com/Tahsin-Mayeesha", "followers_url": "https://api.github.com/... | value:MDU6SXNzdWU2MjA0MjA3MDA= | true | ||||||||
value:2020-05-19T07:34:56Z | value:https://api.github.com/repos/huggingface/datasets/issues/158/timeline | value:0 | value:https://api.github.com/repos/huggingface/datasets | json:{"login": "mariamabarham", "id": 38249783, "node_id": "MDQ6VXNlcjM4MjQ5Nzgz", "avatar_url": "https://avatars.githubusercontent.com/u/38249783?v=4", "gravatar_id": "", "url": "https://api.github.com/users/mariamabarham", "html_url": "https://github.com/mariamabarham", "followers_url": "https://api.github.com/users/... | value:closed | value:https://github.com/huggingface/datasets/pull/158 | value:https://api.github.com/repos/huggingface/datasets/issues/158/comments | value:This PR adds the Toronto Books Corpus.
.
It on consider TMX and plain text files (Moses) defined in the table **Statistics and TMX/Moses Downloads** [here](http://opus.nlpl.eu/Books.php ) | value:False | value:https://api.github.com/repos/huggingface/datasets/issues/158 | json:[] | value:158 | value:add Toronto Books Corpus | value:620396658 | json:[] | value:False | json:{"url": "https://api.github.com/repos/huggingface/datasets/issues/158/reactions", "total_count": 0, "+1": 0, "-1": 0, "laugh": 0, "hooray": 0, "confused": 0, "heart": 0, "rocket": 0, "eyes": 0} | json:{"url": "https://api.github.com/repos/huggingface/datasets/pulls/158", "html_url": "https://github.com/huggingface/datasets/pull/158", "diff_url": "https://github.com/huggingface/datasets/pull/158.diff", "patch_url": "https://github.com/huggingface/datasets/pull/158.patch", "merged_at": null} | value:https://api.github.com/repos/huggingface/datasets/issues/158/events | value:2020-05-18T17:54:45Z | value:https://api.github.com/repos/huggingface/datasets/issues/158/labels{/name} | json:[] | value:CONTRIBUTOR | value:2020-06-11T07:49:15Z | json:{"login": "mariamabarham", "id": 38249783, "node_id": "MDQ6VXNlcjM4MjQ5Nzgz", "avatar_url": "https://avatars.githubusercontent.com/u/38249783?v=4", "gravatar_id": "", "url": "https://api.github.com/users/mariamabarham", "html_url": "https://github.com/mariamabarham", "followers_url": "https://api.github.com/users/... | value:MDExOlB1bGxSZXF1ZXN0NDE5NjUyNTQy | true | |||||||||
value:2020-06-05T08:08:58Z | value:https://api.github.com/repos/huggingface/datasets/issues/157/timeline | json:{"total": 0, "completed": 0, "percent_completed": 0} | value:11 | value:https://api.github.com/repos/huggingface/datasets | json:{"login": "patrickvonplaten", "id": 23423619, "node_id": "MDQ6VXNlcjIzNDIzNjE5", "avatar_url": "https://avatars.githubusercontent.com/u/23423619?v=4", "gravatar_id": "", "url": "https://api.github.com/users/patrickvonplaten", "html_url": "https://github.com/patrickvonplaten", "followers_url": "https://api.github.c... | value:completed | value:closed | value:https://github.com/huggingface/datasets/issues/157 | json:{"login": "patrickvonplaten", "id": 23423619, "node_id": "MDQ6VXNlcjIzNDIzNjE5", "avatar_url": "https://avatars.githubusercontent.com/u/23423619?v=4", "gravatar_id": "", "url": "https://api.github.com/users/patrickvonplaten", "html_url": "https://github.com/patrickvonplaten", "followers_url": "https://api.github.c... | value:https://api.github.com/repos/huggingface/datasets/issues/157/comments | value:I'm trying to load datasets from nlp but there seems to have error saying
"TypeError: list_() takes exactly one argument (2 given)"
gist can be found here
https://gist.github.com/saahiluppal/c4b878f330b10b9ab9762bc0776c0a6a | value:https://api.github.com/repos/huggingface/datasets/issues/157 | json:[] | value:157 | value:nlp.load_dataset() gives "TypeError: list_() takes exactly one argument (2 given)" | value:620356542 | json:[] | json:{"blocked_by": 0, "total_blocked_by": 0, "blocking": 0, "total_blocking": 0} | value:False | json:{"url": "https://api.github.com/repos/huggingface/datasets/issues/157/reactions", "total_count": 0, "+1": 0, "-1": 0, "laugh": 0, "hooray": 0, "confused": 0, "heart": 0, "rocket": 0, "eyes": 0} | value:https://api.github.com/repos/huggingface/datasets/issues/157/events | value:2020-05-18T16:46:38Z | value:https://api.github.com/repos/huggingface/datasets/issues/157/labels{/name} | json:[{"login": "patrickvonplaten", "id": 23423619, "node_id": "MDQ6VXNlcjIzNDIzNjE5", "avatar_url": "https://avatars.githubusercontent.com/u/23423619?v=4", "gravatar_id": "", "url": "https://api.github.com/users/patrickvonplaten", "html_url": "https://github.com/patrickvonplaten", "followers_url": "https://api.github.... | value:NONE | value:2020-06-05T08:08:58Z | json:{"login": "saahiluppal", "id": 47444392, "node_id": "MDQ6VXNlcjQ3NDQ0Mzky", "avatar_url": "https://avatars.githubusercontent.com/u/47444392?v=4", "gravatar_id": "", "url": "https://api.github.com/users/saahiluppal", "html_url": "https://github.com/saahiluppal", "followers_url": "https://api.github.com/users/saahil... | value:MDU6SXNzdWU2MjAzNTY1NDI= | true | |||||||
value:2020-07-23T16:41:55Z | value:https://api.github.com/repos/huggingface/datasets/issues/156/timeline | json:{"total": 0, "completed": 0, "percent_completed": 0} | value:7 | value:https://api.github.com/repos/huggingface/datasets | json:{"login": "lhoestq", "id": 42851186, "node_id": "MDQ6VXNlcjQyODUxMTg2", "avatar_url": "https://avatars.githubusercontent.com/u/42851186?v=4", "gravatar_id": "", "url": "https://api.github.com/users/lhoestq", "html_url": "https://github.com/lhoestq", "followers_url": "https://api.github.com/users/lhoestq/followers"... | value:completed | value:closed | value:https://github.com/huggingface/datasets/issues/156 | json:{"login": "patrickvonplaten", "id": 23423619, "node_id": "MDQ6VXNlcjIzNDIzNjE5", "avatar_url": "https://avatars.githubusercontent.com/u/23423619?v=4", "gravatar_id": "", "url": "https://api.github.com/users/patrickvonplaten", "html_url": "https://github.com/patrickvonplaten", "followers_url": "https://api.github.c... | value:https://api.github.com/repos/huggingface/datasets/issues/156/comments | value:The following snippet produces a syntax error:
```
import nlp
dataset = nlp.load_dataset('wmt14')
print(dataset['train'][0])
```
```
Traceback (most recent call last):
File "/home/tom/.local/lib/python3.6/site-packages/IPython/core/interactiveshell.py", line 3326, in run_code
exec(code_obj,... | value:https://api.github.com/repos/huggingface/datasets/issues/156 | json:[] | value:156 | value:SyntaxError with WMT datasets | value:620263687 | json:[] | json:{"blocked_by": 0, "total_blocked_by": 0, "blocking": 0, "total_blocking": 0} | value:False | json:{"url": "https://api.github.com/repos/huggingface/datasets/issues/156/reactions", "total_count": 0, "+1": 0, "-1": 0, "laugh": 0, "hooray": 0, "confused": 0, "heart": 0, "rocket": 0, "eyes": 0} | value:https://api.github.com/repos/huggingface/datasets/issues/156/events | value:2020-05-18T14:38:18Z | value:https://api.github.com/repos/huggingface/datasets/issues/156/labels{/name} | json:[{"login": "patrickvonplaten", "id": 23423619, "node_id": "MDQ6VXNlcjIzNDIzNjE5", "avatar_url": "https://avatars.githubusercontent.com/u/23423619?v=4", "gravatar_id": "", "url": "https://api.github.com/users/patrickvonplaten", "html_url": "https://github.com/patrickvonplaten", "followers_url": "https://api.github.... | value:NONE | value:2020-07-23T16:41:55Z | json:{"login": "tomhosking", "id": 9419158, "node_id": "MDQ6VXNlcjk0MTkxNTg=", "avatar_url": "https://avatars.githubusercontent.com/u/9419158?v=4", "gravatar_id": "", "url": "https://api.github.com/users/tomhosking", "html_url": "https://github.com/tomhosking", "followers_url": "https://api.github.com/users/tomhosking/... | value:MDU6SXNzdWU2MjAyNjM2ODc= | true | |||||||
value:2020-05-28T08:31:57Z | value:https://api.github.com/repos/huggingface/datasets/issues/155/timeline | value:1 | value:https://api.github.com/repos/huggingface/datasets | json:{"login": "lhoestq", "id": 42851186, "node_id": "MDQ6VXNlcjQyODUxMTg2", "avatar_url": "https://avatars.githubusercontent.com/u/42851186?v=4", "gravatar_id": "", "url": "https://api.github.com/users/lhoestq", "html_url": "https://github.com/lhoestq", "followers_url": "https://api.github.com/users/lhoestq/followers"... | value:closed | value:https://github.com/huggingface/datasets/pull/155 | value:https://api.github.com/repos/huggingface/datasets/issues/155/comments | value:Include more links and fix typos in README | value:False | value:https://api.github.com/repos/huggingface/datasets/issues/155 | json:[] | value:155 | value:Include more links in README, fix typos | value:620067946 | json:[] | value:False | json:{"url": "https://api.github.com/repos/huggingface/datasets/issues/155/reactions", "total_count": 0, "+1": 0, "-1": 0, "laugh": 0, "hooray": 0, "confused": 0, "heart": 0, "rocket": 0, "eyes": 0} | json:{"url": "https://api.github.com/repos/huggingface/datasets/pulls/155", "html_url": "https://github.com/huggingface/datasets/pull/155", "diff_url": "https://github.com/huggingface/datasets/pull/155.diff", "patch_url": "https://github.com/huggingface/datasets/pull/155.patch", "merged_at": "2020-05-28T08:31:57Z"} | value:https://api.github.com/repos/huggingface/datasets/issues/155/events | value:2020-05-18T09:47:08Z | value:https://api.github.com/repos/huggingface/datasets/issues/155/labels{/name} | json:[] | value:CONTRIBUTOR | value:2020-05-28T08:31:57Z | json:{"login": "bharatr21", "id": 13381361, "node_id": "MDQ6VXNlcjEzMzgxMzYx", "avatar_url": "https://avatars.githubusercontent.com/u/13381361?v=4", "gravatar_id": "", "url": "https://api.github.com/users/bharatr21", "html_url": "https://github.com/bharatr21", "followers_url": "https://api.github.com/users/bharatr21/fo... | value:MDExOlB1bGxSZXF1ZXN0NDE5Mzg1ODM0 | true | |||||||||
value:2020-05-18T10:12:27Z | value:https://api.github.com/repos/huggingface/datasets/issues/154/timeline | value:0 | value:https://api.github.com/repos/huggingface/datasets | json:{"login": "mariamabarham", "id": 38249783, "node_id": "MDQ6VXNlcjM4MjQ5Nzgz", "avatar_url": "https://avatars.githubusercontent.com/u/38249783?v=4", "gravatar_id": "", "url": "https://api.github.com/users/mariamabarham", "html_url": "https://github.com/mariamabarham", "followers_url": "https://api.github.com/users/... | value:closed | value:https://github.com/huggingface/datasets/pull/154 | value:https://api.github.com/repos/huggingface/datasets/issues/154/comments | value:This PR adds the Ubuntu Dialog Corpus datasets version 2.0. | value:False | value:https://api.github.com/repos/huggingface/datasets/issues/154 | json:[] | value:154 | value:add Ubuntu Dialogs Corpus datasets | value:620059066 | json:[] | value:False | json:{"url": "https://api.github.com/repos/huggingface/datasets/issues/154/reactions", "total_count": 0, "+1": 0, "-1": 0, "laugh": 0, "hooray": 0, "confused": 0, "heart": 0, "rocket": 0, "eyes": 0} | json:{"url": "https://api.github.com/repos/huggingface/datasets/pulls/154", "html_url": "https://github.com/huggingface/datasets/pull/154", "diff_url": "https://github.com/huggingface/datasets/pull/154.diff", "patch_url": "https://github.com/huggingface/datasets/pull/154.patch", "merged_at": "2020-05-18T10:12:27Z"} | value:https://api.github.com/repos/huggingface/datasets/issues/154/events | value:2020-05-18T09:34:48Z | value:https://api.github.com/repos/huggingface/datasets/issues/154/labels{/name} | json:[] | value:CONTRIBUTOR | value:2020-05-18T10:12:28Z | json:{"login": "mariamabarham", "id": 38249783, "node_id": "MDQ6VXNlcjM4MjQ5Nzgz", "avatar_url": "https://avatars.githubusercontent.com/u/38249783?v=4", "gravatar_id": "", "url": "https://api.github.com/users/mariamabarham", "html_url": "https://github.com/mariamabarham", "followers_url": "https://api.github.com/users/... | value:MDExOlB1bGxSZXF1ZXN0NDE5Mzc4Mzgw | true | |||||||||
value:https://api.github.com/repos/huggingface/datasets/issues/153/timeline | json:{"total": 0, "completed": 0, "percent_completed": 0} | value:4 | value:https://api.github.com/repos/huggingface/datasets | value:open | value:https://github.com/huggingface/datasets/issues/153 | value:https://api.github.com/repos/huggingface/datasets/issues/153/comments | value:Meta-datasets are interesting in terms of standardized benchmarks but they also have specific behaviors, in particular in terms of attribution and authorship. It's very important that each specific dataset inside a meta dataset is properly referenced and the citation/specific homepage/etc are very visible and acc... | value:https://api.github.com/repos/huggingface/datasets/issues/153 | json:[] | value:153 | value:Meta-datasets (GLUE/XTREME/...) – Special care to attributions and citations | value:619972246 | json:[{"id": 2067400324, "node_id": "MDU6TGFiZWwyMDY3NDAwMzI0", "url": "https://api.github.com/repos/huggingface/datasets/labels/generic%20discussion", "name": "generic discussion", "color": "c5def5", "default": false, "description": "Generic discussion on the library", "archived_at": null, "archived_by": null}] | json:{"blocked_by": 0, "total_blocked_by": 0, "blocking": 0, "total_blocking": 0} | value:False | json:{"url": "https://api.github.com/repos/huggingface/datasets/issues/153/reactions", "total_count": 0, "+1": 0, "-1": 0, "laugh": 0, "hooray": 0, "confused": 0, "heart": 0, "rocket": 0, "eyes": 0} | value:https://api.github.com/repos/huggingface/datasets/issues/153/events | value:2020-05-18T07:24:22Z | value:https://api.github.com/repos/huggingface/datasets/issues/153/labels{/name} | json:[] | value:MEMBER | value:2020-05-18T21:18:16Z | json:{"login": "thomwolf", "id": 7353373, "node_id": "MDQ6VXNlcjczNTMzNzM=", "avatar_url": "https://avatars.githubusercontent.com/u/7353373?v=4", "gravatar_id": "", "url": "https://api.github.com/users/thomwolf", "html_url": "https://github.com/thomwolf", "followers_url": "https://api.github.com/users/thomwolf/follower... | value:MDU6SXNzdWU2MTk5NzIyNDY= | true | |||||||||||
value:2020-05-27T22:09:12Z | value:https://api.github.com/repos/huggingface/datasets/issues/152/timeline | value:5 | value:https://api.github.com/repos/huggingface/datasets | json:{"login": "lhoestq", "id": 42851186, "node_id": "MDQ6VXNlcjQyODUxMTg2", "avatar_url": "https://avatars.githubusercontent.com/u/42851186?v=4", "gravatar_id": "", "url": "https://api.github.com/users/lhoestq", "html_url": "https://github.com/lhoestq", "followers_url": "https://api.github.com/users/lhoestq/followers"... | value:closed | value:https://github.com/huggingface/datasets/pull/152 | value:https://api.github.com/repos/huggingface/datasets/issues/152/comments | value:Fixes #130 by adding a name check to the Glue class | value:False | value:https://api.github.com/repos/huggingface/datasets/issues/152 | json:[] | value:152 | value:Add GLUE config name check | value:619971900 | json:[] | value:False | json:{"url": "https://api.github.com/repos/huggingface/datasets/issues/152/reactions", "total_count": 0, "+1": 0, "-1": 0, "laugh": 0, "hooray": 0, "confused": 0, "heart": 0, "rocket": 0, "eyes": 0} | json:{"url": "https://api.github.com/repos/huggingface/datasets/pulls/152", "html_url": "https://github.com/huggingface/datasets/pull/152", "diff_url": "https://github.com/huggingface/datasets/pull/152.diff", "patch_url": "https://github.com/huggingface/datasets/pull/152.patch", "merged_at": null} | value:https://api.github.com/repos/huggingface/datasets/issues/152/events | value:2020-05-18T07:23:43Z | value:https://api.github.com/repos/huggingface/datasets/issues/152/labels{/name} | json:[] | value:CONTRIBUTOR | value:2020-05-27T22:09:12Z | json:{"login": "bharatr21", "id": 13381361, "node_id": "MDQ6VXNlcjEzMzgxMzYx", "avatar_url": "https://avatars.githubusercontent.com/u/13381361?v=4", "gravatar_id": "", "url": "https://api.github.com/users/bharatr21", "html_url": "https://github.com/bharatr21", "followers_url": "https://api.github.com/users/bharatr21/fo... | value:MDExOlB1bGxSZXF1ZXN0NDE5MzA4OTE2 | true | |||||||||
value:2020-05-18T07:21:51Z | value:https://api.github.com/repos/huggingface/datasets/issues/151/timeline | value:0 | value:https://api.github.com/repos/huggingface/datasets | json:{"login": "jplu", "id": 959590, "node_id": "MDQ6VXNlcjk1OTU5MA==", "avatar_url": "https://avatars.githubusercontent.com/u/959590?v=4", "gravatar_id": "", "url": "https://api.github.com/users/jplu", "html_url": "https://github.com/jplu", "followers_url": "https://api.github.com/users/jplu/followers", "following_url... | value:closed | value:https://github.com/huggingface/datasets/pull/151 | value:https://api.github.com/repos/huggingface/datasets/issues/151/comments | value: | value:False | value:https://api.github.com/repos/huggingface/datasets/issues/151 | json:[] | value:151 | value:Fix JSON tests. | value:619968480 | json:[] | value:False | json:{"url": "https://api.github.com/repos/huggingface/datasets/issues/151/reactions", "total_count": 0, "+1": 0, "-1": 0, "laugh": 0, "hooray": 0, "confused": 0, "heart": 0, "rocket": 0, "eyes": 0} | json:{"url": "https://api.github.com/repos/huggingface/datasets/pulls/151", "html_url": "https://github.com/huggingface/datasets/pull/151", "diff_url": "https://github.com/huggingface/datasets/pull/151.diff", "patch_url": "https://github.com/huggingface/datasets/pull/151.patch", "merged_at": "2020-05-18T07:21:51Z"} | value:https://api.github.com/repos/huggingface/datasets/issues/151/events | value:2020-05-18T07:17:38Z | value:https://api.github.com/repos/huggingface/datasets/issues/151/labels{/name} | json:[] | value:CONTRIBUTOR | value:2020-05-18T07:21:52Z | json:{"login": "jplu", "id": 959590, "node_id": "MDQ6VXNlcjk1OTU5MA==", "avatar_url": "https://avatars.githubusercontent.com/u/959590?v=4", "gravatar_id": "", "url": "https://api.github.com/users/jplu", "html_url": "https://github.com/jplu", "followers_url": "https://api.github.com/users/jplu/followers", "following_url... | value:MDExOlB1bGxSZXF1ZXN0NDE5MzA2MTYz | true | |||||||||
value:2020-05-26T20:37:59Z | value:https://api.github.com/repos/huggingface/datasets/issues/150/timeline | value:4 | value:https://api.github.com/repos/huggingface/datasets | json:{"login": "lhoestq", "id": 42851186, "node_id": "MDQ6VXNlcjQyODUxMTg2", "avatar_url": "https://avatars.githubusercontent.com/u/42851186?v=4", "gravatar_id": "", "url": "https://api.github.com/users/lhoestq", "html_url": "https://github.com/lhoestq", "followers_url": "https://api.github.com/users/lhoestq/followers"... | value:closed | value:https://github.com/huggingface/datasets/pull/150 | value:https://api.github.com/repos/huggingface/datasets/issues/150/comments | value:Hi,
this PR adds the WNUT 17 dataset to `nlp`.
> Emerging and Rare entity recognition
> This shared task focuses on identifying unusual, previously-unseen entities in the context of emerging discussions. Named entities form the basis of many modern approaches to other tasks (like event clustering and summa... | value:False | value:https://api.github.com/repos/huggingface/datasets/issues/150 | json:[] | value:150 | value:Add WNUT 17 NER dataset | value:619809645 | json:[] | value:False | json:{"url": "https://api.github.com/repos/huggingface/datasets/issues/150/reactions", "total_count": 1, "+1": 0, "-1": 0, "laugh": 0, "hooray": 0, "confused": 0, "heart": 0, "rocket": 1, "eyes": 0} | json:{"url": "https://api.github.com/repos/huggingface/datasets/pulls/150", "html_url": "https://github.com/huggingface/datasets/pull/150", "diff_url": "https://github.com/huggingface/datasets/pull/150.diff", "patch_url": "https://github.com/huggingface/datasets/pull/150.patch", "merged_at": "2020-05-26T20:37:59Z"} | value:https://api.github.com/repos/huggingface/datasets/issues/150/events | value:2020-05-17T22:19:04Z | value:https://api.github.com/repos/huggingface/datasets/issues/150/labels{/name} | json:[] | value:CONTRIBUTOR | value:2020-05-26T20:37:59Z | json:{"login": "stefan-it", "id": 20651387, "node_id": "MDQ6VXNlcjIwNjUxMzg3", "avatar_url": "https://avatars.githubusercontent.com/u/20651387?v=4", "gravatar_id": "", "url": "https://api.github.com/users/stefan-it", "html_url": "https://github.com/stefan-it", "followers_url": "https://api.github.com/users/stefan-it/fo... | value:MDExOlB1bGxSZXF1ZXN0NDE5MTgyODU4 | true | |||||||||
value:2020-05-18T17:01:46Z | value:https://api.github.com/repos/huggingface/datasets/issues/149/timeline | json:{"total": 0, "completed": 0, "percent_completed": 0} | value:1 | value:https://api.github.com/repos/huggingface/datasets | json:{"login": "danth", "id": 28959268, "node_id": "MDQ6VXNlcjI4OTU5MjY4", "avatar_url": "https://avatars.githubusercontent.com/u/28959268?v=4", "gravatar_id": "", "url": "https://api.github.com/users/danth", "html_url": "https://github.com/danth", "followers_url": "https://api.github.com/users/danth/followers", "follo... | value:completed | value:closed | value:https://github.com/huggingface/datasets/issues/149 | value:https://api.github.com/repos/huggingface/datasets/issues/149/comments | value:https://github.com/rkadlec/ubuntu-ranking-dataset-creator or http://dataset.cs.mcgill.ca/ubuntu-corpus-1.0/ | value:https://api.github.com/repos/huggingface/datasets/issues/149 | json:[] | value:149 | value:[Feature request] Add Ubuntu Dialogue Corpus dataset | value:619735739 | json:[{"id": 2067376369, "node_id": "MDU6TGFiZWwyMDY3Mzc2MzY5", "url": "https://api.github.com/repos/huggingface/datasets/labels/dataset%20request", "name": "dataset request", "color": "e99695", "default": false, "description": "Requesting to add a new dataset", "archived_at": null, "archived_by": null}] | json:{"blocked_by": 0, "total_blocked_by": 0, "blocking": 0, "total_blocking": 0} | value:False | json:{"url": "https://api.github.com/repos/huggingface/datasets/issues/149/reactions", "total_count": 0, "+1": 0, "-1": 0, "laugh": 0, "hooray": 0, "confused": 0, "heart": 0, "rocket": 0, "eyes": 0} | value:https://api.github.com/repos/huggingface/datasets/issues/149/events | value:2020-05-17T15:42:39Z | value:https://api.github.com/repos/huggingface/datasets/issues/149/labels{/name} | json:[] | value:NONE | value:2020-05-18T17:01:46Z | json:{"login": "danth", "id": 28959268, "node_id": "MDQ6VXNlcjI4OTU5MjY4", "avatar_url": "https://avatars.githubusercontent.com/u/28959268?v=4", "gravatar_id": "", "url": "https://api.github.com/users/danth", "html_url": "https://github.com/danth", "followers_url": "https://api.github.com/users/danth/followers", "follo... | value:MDU6SXNzdWU2MTk3MzU3Mzk= | true | ||||||||
value:2020-05-18T07:38:33Z | value:https://api.github.com/repos/huggingface/datasets/issues/148/timeline | json:{"total": 0, "completed": 0, "percent_completed": 0} | value:2 | value:https://api.github.com/repos/huggingface/datasets | json:{"login": "lhoestq", "id": 42851186, "node_id": "MDQ6VXNlcjQyODUxMTg2", "avatar_url": "https://avatars.githubusercontent.com/u/42851186?v=4", "gravatar_id": "", "url": "https://api.github.com/users/lhoestq", "html_url": "https://github.com/lhoestq", "followers_url": "https://api.github.com/users/lhoestq/followers"... | value:completed | value:closed | value:https://github.com/huggingface/datasets/issues/148 | value:https://api.github.com/repos/huggingface/datasets/issues/148/comments | value:# Reproduce
In Colab,
```
%pip install -q nlp
%pip install -q apache_beam mwparserfromhell
dataset = nlp.load_dataset('wikipedia')
```
get
```
Downloading and preparing dataset wikipedia/20200501.aa (download: Unknown size, generated: Unknown size, total: Unknown size) to /root/.cache/huggingface/data... | value:https://api.github.com/repos/huggingface/datasets/issues/148 | json:[] | value:148 | value:_download_and_prepare() got an unexpected keyword argument 'verify_infos' | value:619590555 | json:[{"id": 2067388877, "node_id": "MDU6TGFiZWwyMDY3Mzg4ODc3", "url": "https://api.github.com/repos/huggingface/datasets/labels/dataset%20bug", "name": "dataset bug", "color": "2edb81", "default": false, "description": "A bug in a dataset script provided in the library", "archived_at": null, "archived_by": null}] | json:{"blocked_by": 0, "total_blocked_by": 0, "blocking": 0, "total_blocking": 0} | value:False | json:{"url": "https://api.github.com/repos/huggingface/datasets/issues/148/reactions", "total_count": 2, "+1": 2, "-1": 0, "laugh": 0, "hooray": 0, "confused": 0, "heart": 0, "rocket": 0, "eyes": 0} | value:https://api.github.com/repos/huggingface/datasets/issues/148/events | value:2020-05-17T01:48:53Z | value:https://api.github.com/repos/huggingface/datasets/issues/148/labels{/name} | json:[] | value:CONTRIBUTOR | value:2020-05-18T07:38:33Z | json:{"login": "richarddwang", "id": 17963619, "node_id": "MDQ6VXNlcjE3OTYzNjE5", "avatar_url": "https://avatars.githubusercontent.com/u/17963619?v=4", "gravatar_id": "", "url": "https://api.github.com/users/richarddwang", "html_url": "https://github.com/richarddwang", "followers_url": "https://api.github.com/users/ric... | value:MDU6SXNzdWU2MTk1OTA1NTU= | true | ||||||||
value:2020-06-18T16:23:23Z | value:https://api.github.com/repos/huggingface/datasets/issues/147/timeline | json:{"total": 0, "completed": 0, "percent_completed": 0} | value:2 | value:https://api.github.com/repos/huggingface/datasets | json:{"login": "lhoestq", "id": 42851186, "node_id": "MDQ6VXNlcjQyODUxMTg2", "avatar_url": "https://avatars.githubusercontent.com/u/42851186?v=4", "gravatar_id": "", "url": "https://api.github.com/users/lhoestq", "html_url": "https://github.com/lhoestq", "followers_url": "https://api.github.com/users/lhoestq/followers"... | value:completed | value:closed | value:https://github.com/huggingface/datasets/issues/147 | value:https://api.github.com/repos/huggingface/datasets/issues/147/comments | value:It would be nice if we could use sklearn `train_test_split` to quickly generate subsets from the dataset objects returned by `nlp.load_dataset`. At the moment the code:
```python
data = nlp.load_dataset('imdb', cache_dir=data_cache)
f_half, s_half = train_test_split(data['train'], test_size=0.5, random_state... | value:https://api.github.com/repos/huggingface/datasets/issues/147 | json:[] | value:147 | value:Error with sklearn train_test_split | value:619581907 | json:[{"id": 1935892871, "node_id": "MDU6TGFiZWwxOTM1ODkyODcx", "url": "https://api.github.com/repos/huggingface/datasets/labels/enhancement", "name": "enhancement", "color": "a2eeef", "default": true, "description": "New feature or request", "archived_at": null, "archived_by": null}] | json:{"blocked_by": 0, "total_blocked_by": 0, "blocking": 0, "total_blocking": 0} | value:False | json:{"url": "https://api.github.com/repos/huggingface/datasets/issues/147/reactions", "total_count": 0, "+1": 0, "-1": 0, "laugh": 0, "hooray": 0, "confused": 0, "heart": 0, "rocket": 0, "eyes": 0} | value:https://api.github.com/repos/huggingface/datasets/issues/147/events | value:2020-05-17T00:28:24Z | value:https://api.github.com/repos/huggingface/datasets/issues/147/labels{/name} | json:[] | value:NONE | value:2020-06-18T16:23:23Z | json:{"login": "ClonedOne", "id": 6853743, "node_id": "MDQ6VXNlcjY4NTM3NDM=", "avatar_url": "https://avatars.githubusercontent.com/u/6853743?v=4", "gravatar_id": "", "url": "https://api.github.com/users/ClonedOne", "html_url": "https://github.com/ClonedOne", "followers_url": "https://api.github.com/users/ClonedOne/foll... | value:MDU6SXNzdWU2MTk1ODE5MDc= | true | ||||||||
value:2020-05-17T22:22:09Z | value:https://api.github.com/repos/huggingface/datasets/issues/146/timeline | value:0 | value:https://api.github.com/repos/huggingface/datasets | json:{"login": "thomwolf", "id": 7353373, "node_id": "MDQ6VXNlcjczNTMzNzM=", "avatar_url": "https://avatars.githubusercontent.com/u/7353373?v=4", "gravatar_id": "", "url": "https://api.github.com/users/thomwolf", "html_url": "https://github.com/thomwolf", "followers_url": "https://api.github.com/users/thomwolf/follower... | value:closed | value:https://github.com/huggingface/datasets/pull/146 | value:https://api.github.com/repos/huggingface/datasets/issues/146/comments | value:This PR adds [BERTScore](https://arxiv.org/abs/1904.09675) to metrics.
Here is an example of how to use it.
```sh
import nlp
bertscore = nlp.load_metric('metrics/bertscore') # or simply nlp.load_metric('bertscore') after this is added to huggingface's s3 bucket
predictions = ['example', 'fruit']
reference... | value:False | value:https://api.github.com/repos/huggingface/datasets/issues/146 | json:[] | value:146 | value:Add BERTScore to metrics | value:619564653 | json:[] | value:False | json:{"url": "https://api.github.com/repos/huggingface/datasets/issues/146/reactions", "total_count": 3, "+1": 0, "-1": 0, "laugh": 0, "hooray": 0, "confused": 0, "heart": 3, "rocket": 0, "eyes": 0} | json:{"url": "https://api.github.com/repos/huggingface/datasets/pulls/146", "html_url": "https://github.com/huggingface/datasets/pull/146", "diff_url": "https://github.com/huggingface/datasets/pull/146.diff", "patch_url": "https://github.com/huggingface/datasets/pull/146.patch", "merged_at": "2020-05-17T22:22:09Z"} | value:https://api.github.com/repos/huggingface/datasets/issues/146/events | value:2020-05-16T22:09:39Z | value:https://api.github.com/repos/huggingface/datasets/issues/146/labels{/name} | json:[] | value:CONTRIBUTOR | value:2020-05-17T22:22:10Z | json:{"login": "felixgwu", "id": 7753366, "node_id": "MDQ6VXNlcjc3NTMzNjY=", "avatar_url": "https://avatars.githubusercontent.com/u/7753366?v=4", "gravatar_id": "", "url": "https://api.github.com/users/felixgwu", "html_url": "https://github.com/felixgwu", "followers_url": "https://api.github.com/users/felixgwu/follower... | value:MDExOlB1bGxSZXF1ZXN0NDE5MDI5MjUx | true | |||||||||
value:2020-05-16T13:54:22Z | value:https://api.github.com/repos/huggingface/datasets/issues/145/timeline | value:0 | value:https://api.github.com/repos/huggingface/datasets | json:{"login": "patrickvonplaten", "id": 23423619, "node_id": "MDQ6VXNlcjIzNDIzNjE5", "avatar_url": "https://avatars.githubusercontent.com/u/23423619?v=4", "gravatar_id": "", "url": "https://api.github.com/users/patrickvonplaten", "html_url": "https://github.com/patrickvonplaten", "followers_url": "https://api.github.c... | value:closed | value:https://github.com/huggingface/datasets/pull/145 | value:https://api.github.com/repos/huggingface/datasets/issues/145/comments | value:I forgot to add this line in PR #145 . | value:False | value:https://api.github.com/repos/huggingface/datasets/issues/145 | json:[] | value:145 | value:[AWS Tests] Follow-up PR from #144 | value:619480549 | json:[] | value:False | json:{"url": "https://api.github.com/repos/huggingface/datasets/issues/145/reactions", "total_count": 0, "+1": 0, "-1": 0, "laugh": 0, "hooray": 0, "confused": 0, "heart": 0, "rocket": 0, "eyes": 0} | json:{"url": "https://api.github.com/repos/huggingface/datasets/pulls/145", "html_url": "https://github.com/huggingface/datasets/pull/145", "diff_url": "https://github.com/huggingface/datasets/pull/145.diff", "patch_url": "https://github.com/huggingface/datasets/pull/145.patch", "merged_at": "2020-05-16T13:54:22Z"} | value:https://api.github.com/repos/huggingface/datasets/issues/145/events | value:2020-05-16T13:53:46Z | value:https://api.github.com/repos/huggingface/datasets/issues/145/labels{/name} | json:[] | value:CONTRIBUTOR | value:2020-05-16T13:54:23Z | json:{"login": "patrickvonplaten", "id": 23423619, "node_id": "MDQ6VXNlcjIzNDIzNjE5", "avatar_url": "https://avatars.githubusercontent.com/u/23423619?v=4", "gravatar_id": "", "url": "https://api.github.com/users/patrickvonplaten", "html_url": "https://github.com/patrickvonplaten", "followers_url": "https://api.github.c... | value:MDExOlB1bGxSZXF1ZXN0NDE4OTcxMjg0 | true | |||||||||
value:2020-05-16T13:44:33Z | value:https://api.github.com/repos/huggingface/datasets/issues/144/timeline | value:0 | value:https://api.github.com/repos/huggingface/datasets | json:{"login": "patrickvonplaten", "id": 23423619, "node_id": "MDQ6VXNlcjIzNDIzNjE5", "avatar_url": "https://avatars.githubusercontent.com/u/23423619?v=4", "gravatar_id": "", "url": "https://api.github.com/users/patrickvonplaten", "html_url": "https://github.com/patrickvonplaten", "followers_url": "https://api.github.c... | value:closed | value:https://github.com/huggingface/datasets/pull/144 | value:https://api.github.com/repos/huggingface/datasets/issues/144/comments | value:AWS tests should in general not run for canonical datasets. Only local tests will run in this case. This way a PR is able to pass when adding a new dataset.
This PR changes to logic to the following:
1) All datasets that are present in `nlp/datasets` are tested only locally. This way when one adds a canoni... | value:False | value:https://api.github.com/repos/huggingface/datasets/issues/144 | json:[] | value:144 | value:[AWS tests] AWS test should not run for canonical datasets | value:619477367 | json:[] | value:False | json:{"url": "https://api.github.com/repos/huggingface/datasets/issues/144/reactions", "total_count": 0, "+1": 0, "-1": 0, "laugh": 0, "hooray": 0, "confused": 0, "heart": 0, "rocket": 0, "eyes": 0} | json:{"url": "https://api.github.com/repos/huggingface/datasets/pulls/144", "html_url": "https://github.com/huggingface/datasets/pull/144", "diff_url": "https://github.com/huggingface/datasets/pull/144.diff", "patch_url": "https://github.com/huggingface/datasets/pull/144.patch", "merged_at": "2020-05-16T13:44:33Z"} | value:https://api.github.com/repos/huggingface/datasets/issues/144/events | value:2020-05-16T13:39:30Z | value:https://api.github.com/repos/huggingface/datasets/issues/144/labels{/name} | json:[] | value:CONTRIBUTOR | value:2020-05-16T13:44:34Z | json:{"login": "patrickvonplaten", "id": 23423619, "node_id": "MDQ6VXNlcjIzNDIzNjE5", "avatar_url": "https://avatars.githubusercontent.com/u/23423619?v=4", "gravatar_id": "", "url": "https://api.github.com/users/patrickvonplaten", "html_url": "https://github.com/patrickvonplaten", "followers_url": "https://api.github.c... | value:MDExOlB1bGxSZXF1ZXN0NDE4OTY5NjA1 | true | |||||||||
value:2020-05-22T13:36:48Z | value:https://api.github.com/repos/huggingface/datasets/issues/143/timeline | json:{"total": 0, "completed": 0, "percent_completed": 0} | value:1 | value:https://api.github.com/repos/huggingface/datasets | json:{"login": "lhoestq", "id": 42851186, "node_id": "MDQ6VXNlcjQyODUxMTg2", "avatar_url": "https://avatars.githubusercontent.com/u/42851186?v=4", "gravatar_id": "", "url": "https://api.github.com/users/lhoestq", "html_url": "https://github.com/lhoestq", "followers_url": "https://api.github.com/users/lhoestq/followers"... | value:completed | value:closed | value:https://github.com/huggingface/datasets/issues/143 | value:https://api.github.com/repos/huggingface/datasets/issues/143/comments | value:`squad_metric.compute` is giving following error
```
ArrowTypeError: Could not convert [{'text': 'Denver Broncos'}, {'text': 'Denver Broncos'}, {'text': 'Denver Broncos'}] with type list: was not a dict, tuple, or recognized null value for conversion to struct type
```
This is how my predictions and referen... | value:https://api.github.com/repos/huggingface/datasets/issues/143 | json:[] | value:143 | value:ArrowTypeError in squad metrics | value:619457641 | json:[{"id": 2067393914, "node_id": "MDU6TGFiZWwyMDY3MzkzOTE0", "url": "https://api.github.com/repos/huggingface/datasets/labels/metric%20bug", "name": "metric bug", "color": "25b21e", "default": false, "description": "A bug in a metric script", "archived_at": null, "archived_by": null}] | json:{"blocked_by": 0, "total_blocked_by": 0, "blocking": 0, "total_blocking": 0} | value:False | json:{"url": "https://api.github.com/repos/huggingface/datasets/issues/143/reactions", "total_count": 0, "+1": 0, "-1": 0, "laugh": 0, "hooray": 0, "confused": 0, "heart": 0, "rocket": 0, "eyes": 0} | value:https://api.github.com/repos/huggingface/datasets/issues/143/events | value:2020-05-16T12:06:37Z | value:https://api.github.com/repos/huggingface/datasets/issues/143/labels{/name} | json:[] | value:CONTRIBUTOR | value:2020-05-22T13:38:52Z | json:{"login": "patil-suraj", "id": 27137566, "node_id": "MDQ6VXNlcjI3MTM3NTY2", "avatar_url": "https://avatars.githubusercontent.com/u/27137566?v=4", "gravatar_id": "", "url": "https://api.github.com/users/patil-suraj", "html_url": "https://github.com/patil-suraj", "followers_url": "https://api.github.com/users/patil-... | value:MDU6SXNzdWU2MTk0NTc2NDE= | true |
Subsets and Splits
No community queries yet
The top public SQL queries from the community will appear here once available.