
owner stringclasses 14
values | repo stringclasses 14
values | id int64 116k 4.61B | issue_number int32 1 181k | author stringlengths 1 39 | body stringlengths 1 262k | created_at timestamp[us]date 2000-06-06 02:40:44 2026-06-02 20:16:18 | updated_at timestamp[us]date 2000-06-06 02:40:44 2026-06-02 20:22:56 | reactions unknown | author_association stringclasses 5
values |
|---|---|---|---|---|---|---|---|---|---|
ClickHouse | ClickHouse | 351,539,486 | 1,636 | bobrik | Having `mark_cache_min_lifetime` as an argument `Context::setMarkCache` would make this bug impossible. | 2017-12-13T22:02:25 | 2017-12-13T22:02:25 | {} | CONTRIBUTOR |
ClickHouse | ClickHouse | 351,721,675 | 1,638 | lamberken | @ztlpn thank you very match | 2017-12-14T14:13:01 | 2017-12-14T14:13:01 | {} | CONTRIBUTOR |
ClickHouse | ClickHouse | 352,547,268 | 1,662 | alexey-milovidov | Отлично, спасибо! | 2017-12-18T20:24:00 | 2017-12-18T20:24:00 | {} | MEMBER |
ClickHouse | ClickHouse | 352,744,975 | 1,661 | Slind14 | ok, so in order for it work in real time I would need to use FINAL in the query? Isn't the solution with a second table and join faster, then and especially more accurate? | 2017-12-19T13:13:09 | 2017-12-19T13:13:09 | {} | NONE |
ClickHouse | ClickHouse | 352,973,507 | 1,632 | kshvakov | Совсем не отдает обратно ? Так быть не должно, но, если у вас 54310, то там есть проблема с нереплицируемыми таблицами MergeTree, там как раз есть утечка памяти | 2017-12-20T06:05:03 | 2017-12-20T06:05:03 | {} | CONTRIBUTOR |
ClickHouse | ClickHouse | 351,609,510 | 1,637 | silviucpp | Sure,
Any instructions on how I can run the tests from sql file to generate the
reference file and also to test that test is ok ? | 2017-12-14T05:01:41 | 2017-12-14T05:14:23 | {} | CONTRIBUTOR |
ClickHouse | ClickHouse | 352,213,413 | 1,637 | alexey-milovidov | > What I do usually is paste the commands into clickhouse console and copypaste output to the reference file. I'm sure there's a nicer way, but I forgot cc @ludv1x
```
clickhouse-client -n < test.sql > test.reference
``` | 2017-12-16T21:35:22 | 2017-12-16T21:35:22 | {} | MEMBER |
ClickHouse | ClickHouse | 352,214,257 | 1,656 | alexey-milovidov | > Or do you see any other way to implement what I need without running query 1 two times
You can also save the result to a temporary table. Reading from that temporary table and building a set, should be relatively cheap, if the temporary table is not very large. | 2017-12-16T21:50:18 | 2017-12-16T21:50:18 | {} | MEMBER |
ClickHouse | ClickHouse | 352,430,836 | 1,657 | KochetovNicolai | Error says that ClickHouse can't resolve name `clickhouse-6`. It should be not ClickHouse, but Docker problem.
For example, you can attach to running container
```
docker exec -it clickhouse-7 bash
```
and check if `clickhouse-6` can be resolved
```
apt update
apt install inetutils-ping
ping clickhouse-6
``` | 2017-12-18T13:51:29 | 2017-12-18T13:51:29 | {} | MEMBER |
ClickHouse | ClickHouse | 352,682,522 | 1,659 | tacyuuhon | Maybe I've made it wrong.
I think it's going to work like the Kafka replication mode.
So, I corrected the wrong config. Let it work again.
> config.xml
```
<remote_servers>
<server_logs>
<shard>
<internal_replication>true</internal_replication>
<replica>
<host>CLICK0001</host>
... | 2017-12-19T09:09:00 | 2017-12-19T09:09:00 | {} | NONE |
ClickHouse | ClickHouse | 353,283,772 | 1,637 | silviucpp | Great job ! Don't forget to close the github issue once merged in master | 2017-12-21T08:00:03 | 2017-12-21T08:00:25 | {} | CONTRIBUTOR |
ClickHouse | ClickHouse | 351,525,769 | 1,565 | alexey-milovidov | 0dd0d76b1 | 2017-12-13T21:09:49 | 2017-12-13T21:09:49 | {} | MEMBER |
ClickHouse | ClickHouse | 351,536,857 | 1,637 | silviucpp | @alexey-milovidov can you please review this and also add a test in the project for this scenario to make sure won't break in the future as well.
I don't know yet what's the procedure to add tests and run them over the project but I'll figure out one day when I'll have more time :)
| 2017-12-13T21:52:48 | 2017-12-13T21:52:48 | {} | CONTRIBUTOR |
ClickHouse | ClickHouse | 351,630,369 | 1,639 | wenerme | I'm not sure is stable is stable, I will update this issues to include the compile error that I found. | 2017-12-14T07:29:26 | 2017-12-14T07:29:26 | {} | NONE |
ClickHouse | ClickHouse | 351,994,793 | 1,648 | silviucpp | @alexey-milovidov any sugestion on how we fix this ? for me at least in this point seems clear that deadlock occur when a task it's scheduled by zookeper completion callback and in the same time same task it's waiting on an async zookeper operation to complete via a future.
One idea I have is to call from zookeper c... | 2017-12-15T12:32:05 | 2017-12-15T13:17:36 | {} | CONTRIBUTOR |
ClickHouse | ClickHouse | 352,108,173 | 1,563 | filimonov | @proller i saw you've added a test cases. I didn't finish that monkey test session actually (it was slow, need to adjust it a bit, but currently have not too much time). More cases which were found before i've killed that:
```
visitParamExtractFloat('',CAST('\0' AS Nullable(String)))
visitParamExtractFloat('',CAST(N... | 2017-12-15T20:48:13 | 2017-12-15T20:48:13 | {} | CONTRIBUTOR |
ClickHouse | ClickHouse | 352,556,840 | 1,660 | filimonov | There was quite big migration of docs from one format to another. During such a migrations some edits can be lost.
Generally the best way is to change in both languages at the same time. But it requires perfect knowedge of both languages, which is not quite common.
But fortunatelly git is a really nice tool to de... | 2017-12-18T21:03:49 | 2017-12-18T21:03:49 | {} | CONTRIBUTOR |
ClickHouse | ClickHouse | 352,749,988 | 1,661 | Slind14 | Its only was seen/wasn't seen. I don't think a dictionary would help here. I'm using 0/1 for that or with the join a left join exists check.
At this time I do not have the amount of data necessary to run a proper test, hence I'm looking for best practices :) Currently it's in the millions/month, but ultimately it shou... | 2017-12-19T13:33:00 | 2017-12-19T13:41:31 | {} | NONE |
ClickHouse | ClickHouse | 352,872,290 | 1,641 | alexey-milovidov | :+1: | 2017-12-19T20:09:26 | 2017-12-19T20:09:26 | {} | MEMBER |
ClickHouse | ClickHouse | 351,581,272 | 1,637 | vavrusa | @silviucpp you can add a test file like this one https://github.com/yandex/ClickHouse/blob/master/dbms/tests/queries/0_stateless/00453_top_k.sql with expected output like here https://github.com/yandex/ClickHouse/blob/master/dbms/tests/queries/0_stateless/00453_top_k.reference | 2017-12-14T01:36:25 | 2017-12-14T01:36:25 | {} | CONTRIBUTOR |
ClickHouse | ClickHouse | 352,568,994 | 1,563 | alexey-milovidov | Now all fixed in master. | 2017-12-18T21:51:10 | 2017-12-18T21:51:10 | {
"+1": 4
} | MEMBER |
ClickHouse | ClickHouse | 353,140,907 | 1,678 | KochetovNicolai | Even for the same query on the same data the order of parts which are reading is not fixed. (Also, some parts may be merged between queries.)
If the order of parts is not fixed, the order of summation is also arbitrary. For floating point numbers different orders may get slightly different results.
If you want to g... | 2017-12-20T18:13:30 | 2017-12-20T18:13:30 | {} | MEMBER |
ClickHouse | ClickHouse | 351,649,609 | 1,637 | silviucpp | OK I added test files based on your instructions... I guess are fine as time I'm not sure how to test them | 2017-12-14T09:02:55 | 2017-12-14T09:02:55 | {} | CONTRIBUTOR |
ClickHouse | ClickHouse | 353,090,499 | 1,667 | lamberken | ok, I see. | 2017-12-20T15:17:15 | 2017-12-20T15:17:15 | {} | CONTRIBUTOR |
ClickHouse | ClickHouse | 353,104,662 | 1,665 | alexey-milovidov | @filimonov That's totally correct and does not related to rough parsing.
Example:
```
$ python
Python 2.7.13 (default, Nov 23 2017, 15:37:09)
[GCC 6.3.0 20170406] on linux2
Type "help", "copyright", "credits" or "license" for more information.
>>> 20 + 0.000001 + 0.0000001
20.000001100000002
```
```
$ n... | 2017-12-20T16:04:35 | 2017-12-20T16:04:56 | {} | MEMBER |
ClickHouse | ClickHouse | 353,155,158 | 1,654 | vavrusa | Rebased and addressed comments. | 2017-12-20T19:10:41 | 2017-12-20T19:10:41 | {} | CONTRIBUTOR |
ClickHouse | ClickHouse | 351,609,272 | 1,630 | silviucpp | Hello,
I don’t want to be rude at all but maybe it’s time for some continuous
integration that makes builds after each commit in master on all supported
platforms in order to make sure build always works.
If you break something you can see in minutes | 2017-12-14T04:59:43 | 2017-12-14T05:15:16 | {} | CONTRIBUTOR |
ClickHouse | ClickHouse | 351,635,133 | 1,630 | silviucpp | oh btw I don't use High Sierra the project is not compiling with clang even on Sierra because optional is still under experimental namespace and this was reverted in : 01e8adbfff697bb41fa53b729164a77601fe72a5 | 2017-12-14T07:55:50 | 2017-12-14T07:55:50 | {} | CONTRIBUTOR |
ClickHouse | ClickHouse | 351,992,176 | 1,648 | silviucpp | My initial conclusion (still working) is:
Zookeper it's using 1 thread to deliver the callbacks. Inside the callback is calling the schedule method for a task that it's already in progress (lock is acquired) . The task also it's waiting for a an async zookeper operation completion via a `future`
For here we have ... | 2017-12-15T12:17:23 | 2017-12-15T12:28:33 | {} | CONTRIBUTOR |
ClickHouse | ClickHouse | 352,216,329 | 1,656 | silviucpp | You totally lost me :) I thought that what I need to do is to:
1. add in Set.h a method to dump the set content into a Block
```c++
Block Set::dumpElements()
{
std::unique_lock<std::shared_mutex> lock(rwlock);
if(data_types.empty())
return Block();
Block block;
DataTypePtr type = ... | 2017-12-16T22:27:05 | 2017-12-16T22:27:05 | {} | CONTRIBUTOR |
ClickHouse | ClickHouse | 352,717,167 | 1,657 | KochetovNicolai | > if ck-6, ck-7, ck-8, ck-9 are physical machines, not docker containers.
> when the ck-6 crash, Will the above error happen again?
Yes, it should help. Also, it should be possible to make Docker work.
> and ck-6 ck-8 are relicas, ck-8 is alive, why still throw error?
If ck-8 is alive, and is ck-6 is down, data... | 2017-12-19T11:10:28 | 2017-12-19T11:10:28 | {} | MEMBER |
ClickHouse | ClickHouse | 352,722,021 | 1,664 | KochetovNicolai | 1. Let's say that you want to insert into and read from distributed table on `clickhouse-6` node. At the first way, you will always use `clickhouse-6` and `clickhouse-7`. At the second way, for each query `clickhouse-7` or `clickhouse-9` can be chosen (`clickhouse-6` is local, so it has priority under `clickhouse-8`). ... | 2017-12-19T11:29:38 | 2017-12-19T11:29:38 | {} | MEMBER |
ClickHouse | ClickHouse | 352,739,726 | 1,661 | filimonov | Each insert create it's own part. Later small parts are merged together and bigger parts appear which will also be merged later. That's why it's called MergeTree. During each merge data is sorted according to primary key. If you're using Replacing / Collapsing merge tree - duplicate rows are removed during Merges. If y... | 2017-12-19T12:48:41 | 2017-12-19T12:48:41 | {
"+1": 29,
"laugh": 1
} | CONTRIBUTOR |
ClickHouse | ClickHouse | 353,155,807 | 1,677 | silviucpp | Hello @KochetovNicolai ,
Thanks a lot for your answers. In my case partition is toDate(timestamp) so becomes pointless
I initially thought it helps on selecting the partitions that needs to scan but seems only primary key is used. Also in case the primary key is composed from multiple fields when I filter it matter... | 2017-12-20T19:13:10 | 2017-12-20T19:13:10 | {} | CONTRIBUTOR |
ClickHouse | ClickHouse | 353,144,270 | 1,665 | filimonov | Yep. I know about that innacuracy of floats, just was surprised that float summing is not associative (changing order of summing 3 elements in that case you get different result).
May be some adjusting of floats formatting (like in php / perl / go) can make everybody happy. (may be switched by option). But probably... | 2017-12-20T18:27:37 | 2017-12-20T19:14:41 | {} | CONTRIBUTOR |
ClickHouse | ClickHouse | 351,581,715 | 1,625 | vavrusa | Yes, it will fix issue with last block not being written on exit (there's a 7500ms flush interval, which you may or may not hit). I don't know about starting offsets, maybe it's going to be supported in the extended configuration tracked in this ticket: https://github.com/yandex/ClickHouse/issues/1402 | 2017-12-14T01:39:12 | 2017-12-14T01:39:12 | {} | CONTRIBUTOR |
ClickHouse | ClickHouse | 351,618,828 | 1,630 | vavrusa | I suggested Travis since it's free and supports OS X, maybe you can contribute a `.travis.yml` if @proller or someone with access to the repo is willing to enable it on the repo? | 2017-12-14T06:14:34 | 2017-12-14T06:14:34 | {} | CONTRIBUTOR |
ClickHouse | ClickHouse | 351,641,252 | 1,595 | vaslv | Works! Use https://github.com/Altinity/clickhouse-rpm on centos 7 with mysqlcommunity | 2017-12-14T08:25:55 | 2017-12-14T08:25:55 | {} | NONE |
ClickHouse | ClickHouse | 352,193,911 | 1,543 | theseusyang | OK @KochetovNicolai | 2017-12-16T16:31:31 | 2017-12-16T16:31:31 | {} | NONE |
ClickHouse | ClickHouse | 351,696,105 | 1,510 | silviucpp | This was fixed ? | 2017-12-14T12:21:43 | 2017-12-14T12:21:43 | {} | CONTRIBUTOR |
ClickHouse | ClickHouse | 352,019,917 | 1,648 | silviucpp | So I have a fix that finally seems not blocking any longer during my load tests:
Change scheduleAfter in the following mode (we can make it void)
```c++
bool BackgroundSchedulePool::TaskInfo::scheduleAfter(size_t ms)
{
pool.scheduleDelayedTask(shared_from_this(), ms);
return true;
}
```
and call ... | 2017-12-15T14:32:50 | 2017-12-15T14:33:25 | {} | CONTRIBUTOR |
ClickHouse | ClickHouse | 352,404,167 | 1,659 | silviucpp | I've run in the same issues with two machines that were not on the same os (one osx and one ubuntu) | 2017-12-18T11:48:30 | 2017-12-18T11:48:30 | {} | CONTRIBUTOR |
ClickHouse | ClickHouse | 352,867,603 | 1,648 | alexey-milovidov | Looks reasonable. Thank you! | 2017-12-19T19:51:01 | 2017-12-19T19:51:01 | {} | MEMBER |
ClickHouse | ClickHouse | 353,009,879 | 1,675 | filimonov | > @Jaxvk I think you need a proxy.
As I understand proxy will not help in described case. It's a matter of choosing healthy replica for distributed requests inside cluster, not about connecting to the cluster from outside.
> Can configure the clickhouse-server don't to accept request when it copying data from oth... | 2017-12-20T09:23:24 | 2017-12-20T09:23:35 | {} | CONTRIBUTOR |
ClickHouse | ClickHouse | 353,011,360 | 1,672 | filimonov | Unfortunately docs are a bit obsolete.
Date range already expanded to store dates up to 2106 (since version 1.1.54310). :) | 2017-12-20T09:29:47 | 2017-12-20T09:29:47 | {} | CONTRIBUTOR |
ClickHouse | ClickHouse | 351,636,987 | 1,638 | alxark | Hello. Shard configuration doesn't setup any replication between tables, it's only a map for distributed engine to know where to search data. In your case: if you will not setup Replicated* Engine on IP1 and IP2 you will have 2 different data sets on your servers. That means that when you will query distributed table y... | 2017-12-14T08:05:40 | 2017-12-14T08:05:40 | {
"laugh": 2
} | NONE |
ClickHouse | ClickHouse | 351,653,897 | 1,625 | GroundTech | @tobad357
I have started to test the Kafka storage engine. Haven't configured the materialized view, just the Kafka table and seeing all message including the last few in a batch.
However, performance seems not very good. I am getting about 3K message per second with a table about 180 columns (kafka topic only 1 ... | 2017-12-14T09:21:15 | 2017-12-14T09:21:15 | {} | NONE |
ClickHouse | ClickHouse | 352,411,813 | 1,657 | lamberken | @ztlpn :smiley: | 2017-12-18T12:25:56 | 2017-12-18T12:25:56 | {} | CONTRIBUTOR |
ClickHouse | ClickHouse | 352,735,316 | 1,665 | silviucpp | @KochetovNicolai probably it's better to implement as well an accurate parser even if it's slower and users can enable it from config | 2017-12-19T12:27:03 | 2017-12-19T12:27:16 | {} | CONTRIBUTOR |
ClickHouse | ClickHouse | 352,834,567 | 1,668 | alexey-milovidov | 1029b2a5e | 2017-12-19T17:48:16 | 2017-12-19T17:48:16 | {} | MEMBER |
ClickHouse | ClickHouse | 353,018,818 | 1,665 | filimonov | That works weird:
```sql
:) select toFloat64(20 + 0.000001 + 0.0000001) x;
┌──────────────────x─┐
│ 20.000001100000002 │
└────────────────────┘
:) select toFloat64( 0.000001 + 0.0000001 + 20) x;
┌──────────x─┐
│ 20.0000011 │
└────────────┘
:) select toFloat64( 0.0000001 + 0.000001 + 20) x;
┌──────────x─┐... | 2017-12-20T09:58:11 | 2017-12-20T10:01:36 | {} | CONTRIBUTOR |
ClickHouse | ClickHouse | 353,057,717 | 1,667 | KochetovNicolai | Yes, `replicated_deduplication_window` is for every `Replicated*MergeTree` engine. | 2017-12-20T13:03:59 | 2017-12-20T13:03:59 | {} | MEMBER |
ClickHouse | ClickHouse | 351,519,804 | 1,578 | alexey-milovidov | Please move `Client.cpp` changes to separate pull request.
The implementation is still incorrect, because "Parse error" message is inconsistent with the message from `tryParseQuery` function. | 2017-12-13T20:57:46 | 2017-12-13T20:57:46 | {} | MEMBER |
ClickHouse | ClickHouse | 351,733,811 | 1,639 | wenerme | /host/contrib/libcityhash/src/city.cc:261:3: error: 'ssize_t' was not declared in this scope
ssize_t -> size_t
----
```
/host/contrib/libcctz/src/time_zone_info.cc:64:20: error: invalid conversion from 'int' to 'char*' [-fpermissive]
return strerror_r(errnum, buf, buflen);
```
change to
```c
strerr... | 2017-12-14T14:56:03 | 2017-12-14T14:56:03 | {} | NONE |
ClickHouse | ClickHouse | 352,214,390 | 1,656 | alexey-milovidov | > Are you interested in a PR that will add read support for set storage?
Yes, I'm interested (though Set storage is not frequently used feature).
Also I have intent to generalize "key extracting and manipulation" code in `Aggregator`, `Set`, `Join` and `arrayEnumerateUniq`. There are similar, but slightly different... | 2017-12-16T21:52:35 | 2017-12-16T21:52:35 | {} | MEMBER |
ClickHouse | ClickHouse | 352,568,644 | 1,654 | vavrusa | Vendored the fixed librdkafka version containing https://github.com/edenhill/librdkafka/pull/1592 | 2017-12-18T21:49:44 | 2017-12-18T21:49:44 | {} | CONTRIBUTOR |
ClickHouse | ClickHouse | 352,978,315 | 1,632 | yurchenkosv | Огромное спасибо за ответ! Действительно, версия 54310. Будем пробовать обновиться до v1.1.54318-stable. | 2017-12-20T06:38:18 | 2017-12-20T06:38:18 | {} | NONE |
ClickHouse | ClickHouse | 353,030,350 | 1,637 | silviucpp | @alexey-milovidov I fixed the memory leak you mentioned | 2017-12-20T10:47:42 | 2017-12-20T10:47:42 | {} | CONTRIBUTOR |
ClickHouse | ClickHouse | 351,582,063 | 1,630 | vavrusa | There's no reason to be rude about it, it's not like the authors owe you a working OS X build. That being said, *don't* upgrade to High Sierra, there's a bug with gcc-7 and some headers in High Sierra: https://github.com/yandex/ClickHouse/issues/1474
I've been trying to fix the clang build to work on some stuff toda... | 2017-12-14T01:41:53 | 2017-12-14T01:41:53 | {} | CONTRIBUTOR |
ClickHouse | ClickHouse | 351,618,430 | 1,637 | vavrusa | What I do usually is paste the commands into clickhouse console and copypaste output to the reference file. I'm sure there's a nicer way, but I forgot cc @ludv1x | 2017-12-14T06:11:36 | 2017-12-14T06:11:36 | {} | CONTRIBUTOR |
ClickHouse | ClickHouse | 351,634,741 | 1,630 | silviucpp | yes travis is a very good idea. This brings lot of benefits. | 2017-12-14T07:53:58 | 2017-12-14T07:53:58 | {} | CONTRIBUTOR |
ClickHouse | ClickHouse | 352,875,817 | 1,648 | alexey-milovidov | The issue is closed automatically as pull request is merged :) | 2017-12-19T20:23:48 | 2017-12-19T20:23:48 | {} | MEMBER |
ClickHouse | ClickHouse | 353,148,586 | 1,677 | KochetovNicolai | 1. No, you still need to batch the inserts on the client side.
By default, when you insert data into distributed table, it firstly stores inserted batch as a part on local file system (or set of parts). Then, distributed table sends each part to remote node.
When `distributed_directory_monitor_batch_inserts` is ena... | 2017-12-20T18:45:01 | 2017-12-20T18:45:01 | {} | MEMBER |
ClickHouse | ClickHouse | 353,192,072 | 1,674 | alexey-milovidov | Thank you! | 2017-12-20T21:48:30 | 2017-12-20T21:48:30 | {} | MEMBER |
ClickHouse | ClickHouse | 351,688,230 | 1,638 | ztlpn | There can be four different combinations. Let us consider them one by one.
1. Non-replicated tables, `internal_replication=false`. Data inserted into the Distributed table is inserted into both local tables and if there are no problems during inserts, the data on both local tables stays in sync. We call this "poor m... | 2017-12-14T11:43:55 | 2017-12-14T11:46:54 | {
"hooray": 3
} | CONTRIBUTOR |
ClickHouse | ClickHouse | 352,442,919 | 1,657 | lamberken | @KochetovNicolai , thank you
if ck-6, ck-7, ck-8, ck-9 are physical machines, not docker containers.
when the ck-6 crash, Will the above error happen again? :sake:
and ck-6 ck-8 are relicas, ck-8 is alive, why still throw error?
| 2017-12-18T14:36:52 | 2017-12-18T14:59:55 | {} | CONTRIBUTOR |
ClickHouse | ClickHouse | 352,548,416 | 1,660 | alexey-milovidov | > developers write Russian documentation, then tech writers from Yandex translate it.
Exactly.
Right now, https://github.com/krishnevsky has finished translating all accumulated changes and we are going to publish them after we will solve some minor technical issues. Then the process of translation will go smooth... | 2017-12-18T20:28:58 | 2017-12-18T20:28:58 | {} | MEMBER |
ClickHouse | ClickHouse | 353,003,364 | 1,675 | tacyuuhon | @Jaxvk I think you need a proxy.
Maybe [chproxy](https://github.com/Vertamedia/chproxy) can help you.
| 2017-12-20T08:55:55 | 2017-12-20T08:55:55 | {} | NONE |
ClickHouse | ClickHouse | 353,151,464 | 1,678 | filimonov | Floating-point arithmetics inacuracy is [well-known issue](https://en.wikipedia.org/wiki/Floating-point_arithmetic#Accuracy_problems). That is the reason why some databases implement DECIMAL data types, and some languages (like Java) don't allow direct float comprison (only by special syntax with some defined precision... | 2017-12-20T18:56:48 | 2017-12-20T19:06:46 | {} | CONTRIBUTOR |
ClickHouse | ClickHouse | 353,316,162 | 1,625 | GroundTech | @tobad357 With kafkacat as a dummy consumer such as kafkacat, I can reach 60K messages per second with single partition, much faster than through the kafka clickhouse storage. | 2017-12-21T10:29:08 | 2017-12-21T10:29:08 | {} | NONE |
ClickHouse | ClickHouse | 352,496,712 | 1,660 | AlekSi | Are you sure? Last time I asked about that, I was told that developers write Russian documentation, then tech writers from Yandex translate it. So no changes should be made to English docs as they will be overwritten. | 2017-12-18T17:28:55 | 2017-12-18T17:28:55 | {} | NONE |
ClickHouse | ClickHouse | 352,729,131 | 1,664 | lamberken | @KochetovNicolai I see, thank you. :+1: | 2017-12-19T11:57:52 | 2017-12-19T11:57:52 | {} | CONTRIBUTOR |
ClickHouse | ClickHouse | 353,009,941 | 1,666 | AlexMAS | @filimonov Thank you. Nice to hear that it works fine.
P.s. To the developers: If there are nothing to add, this issue can be closed. | 2017-12-20T09:23:39 | 2017-12-20T09:23:39 | {} | CONTRIBUTOR |
ClickHouse | ClickHouse | 353,015,760 | 1,464 | tacyuuhon | I think the use of volume will have a performance impact on IO.
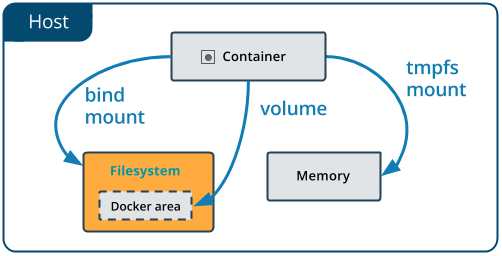
If use the volume. I think it looks like this.
Container -> Storage Drive -> Filesystem
doc: [Use bind mounts](https://docs.docker.com/engi... | 2017-12-20T09:46:48 | 2017-12-20T09:46:48 | {} | NONE |
ClickHouse | ClickHouse | 351,814,411 | 1,644 | vavrusa | @ztlpn Could that work with the new CREATE TABLE syntax? | 2017-12-14T19:39:17 | 2017-12-14T19:39:17 | {} | CONTRIBUTOR |
ClickHouse | ClickHouse | 352,103,924 | 1,257 | proller | fixed here fa65bdcf4847fdf7a5a16a6d25f46798432bec41 | 2017-12-15T20:28:07 | 2017-12-15T20:28:07 | {} | CONTRIBUTOR |
ClickHouse | ClickHouse | 352,434,498 | 1,563 | filimonov | More monkeytest crashes:
```
positionCaseInsensitiveUTF8('',CAST('\0' AS Nullable(String)))
coalesce(CAST('\0' AS Nullable(String)),'')
less(CAST(1 AS Int8),CAST( 0 AS Nullable(Int8)))
and(CAST(1 AS Int8),CAST( 0 AS Nullable(Int8)))
visitParamExtractBool('',CAST('\0' AS Nullable(String)))
notEquals(CAST(1 AS I... | 2017-12-18T14:05:50 | 2017-12-18T14:05:50 | {} | CONTRIBUTOR |
ClickHouse | ClickHouse | 352,471,576 | 1,660 | filimonov | You can help the project by translating that page. Documentation is inside docs folder of the main Clickchouse repo. | 2017-12-18T16:04:37 | 2017-12-18T16:04:37 | {} | CONTRIBUTOR |
ClickHouse | ClickHouse | 352,553,203 | 1,661 | filimonov | Did you check CollapsingMergeTree or ReplacingMergeTree? Both allows you to put new version of existing row at any time. During background merge process older version of row get replaced/collapsed. If you will add FINAL clause to your selects you will always get freshest row. Without FINAL clause you can get 2 variants... | 2017-12-18T20:48:39 | 2017-12-18T20:51:56 | {} | CONTRIBUTOR |
ClickHouse | ClickHouse | 352,659,510 | 1,663 | bobrik | @vavrusa pointed that I should add `active = 1` to `where` and that worked. | 2017-12-19T07:15:28 | 2017-12-19T07:15:28 | {} | CONTRIBUTOR |
ClickHouse | ClickHouse | 352,730,365 | 1,666 | filimonov | I never looked in code how exactly it works, but I'm using UNION ALL a lot and it just works - fast and without any problems. The way how clickhouse store data in ONE table (multiple parts which should be read at the same time) is quite similar to the case when you need to read multiple tables.
The only problem for ... | 2017-12-19T12:03:37 | 2017-12-19T12:04:30 | {} | CONTRIBUTOR |
ClickHouse | ClickHouse | 352,748,230 | 1,661 | filimonov | The best way is to try. Each case is different - test on **your** data with **your** requests and **your** load is always the best way to check which approach suits you the best.
If your list of _seen_ records is small - you can even use dictionary for that. | 2017-12-19T13:27:45 | 2017-12-19T13:27:45 | {} | CONTRIBUTOR |
ClickHouse | ClickHouse | 352,776,916 | 1,667 | KochetovNicolai | Primary key in ClickHouse uses for sorting and it may duplicate. As MergeTree, as ReplicaedMergeTree doesn't delete data with the same primary key.
Only ReplicatedMergeTree deletes duplicating **parts** if they are exactly the same. You can add timestamp to your data to avoid situations when you want to insert the sam... | 2017-12-19T14:45:09 | 2017-12-19T14:45:09 | {} | MEMBER |
ClickHouse | ClickHouse | 352,801,662 | 1,625 | tobad357 | @GroundTech how many messages per second can you read from your kafka with a dummy consumer?
I would guess you are hitting the upper limit on what kafka can deliver when only using one partition | 2017-12-19T15:58:57 | 2017-12-19T15:58:57 | {} | NONE |
ClickHouse | ClickHouse | 352,832,455 | 1,670 | alexey-milovidov | Thank you! | 2017-12-19T17:40:51 | 2017-12-19T17:40:51 | {} | MEMBER |
ClickHouse | ClickHouse | 352,930,399 | 1,667 | lamberken | @KochetovNicolai :+1:
in addition, if set `replicated_deduplication_window=0`, it also affect
`ReplicatedCollapsingMergeTree` `ReplicatedAggregatingMergeTree` `ReplicatedSummingMergeTree` engines? | 2017-12-20T00:41:18 | 2017-12-20T01:21:01 | {} | CONTRIBUTOR |
ClickHouse | ClickHouse | 351,536,949 | 1,028 | silviucpp | Should be fixed by https://github.com/yandex/ClickHouse/pull/1637 | 2017-12-13T21:53:07 | 2017-12-13T21:53:07 | {} | CONTRIBUTOR |
ClickHouse | ClickHouse | 351,676,601 | 1,638 | lamberken | @alxark @ztlpn
hi, What does this sentence mean in the picture? ---> write data to all of the replicas
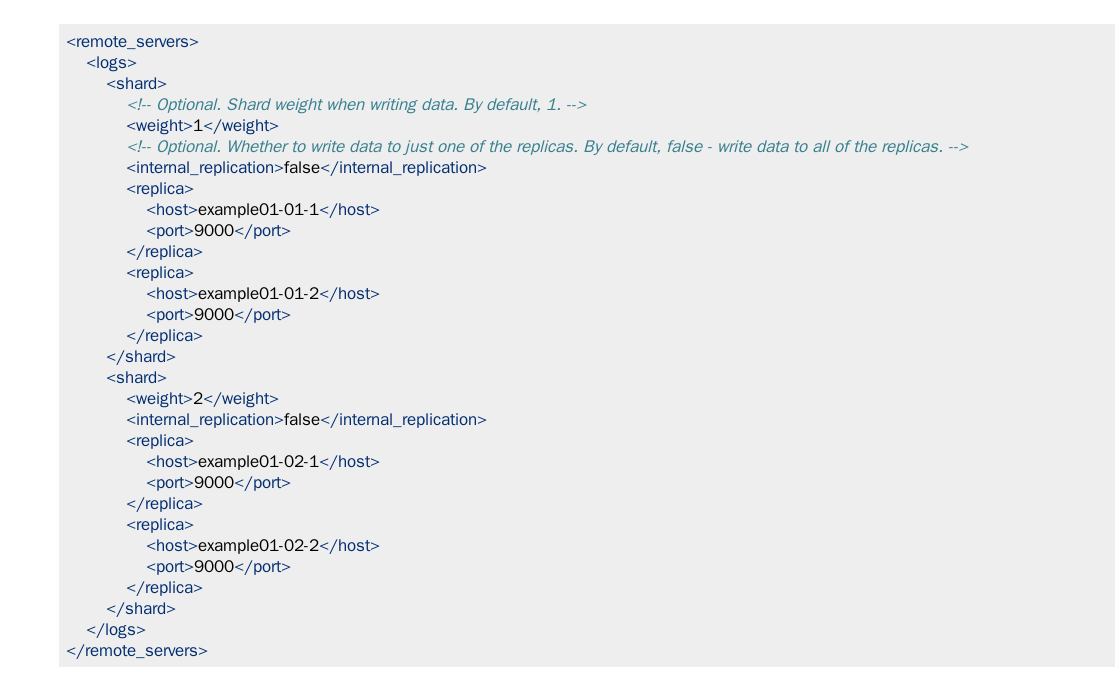
here is the clickhouse`s document
. | 2017-12-16T21:48:23 | 2017-12-16T21:48:40 | {} | MEMBER |
ClickHouse | ClickHouse | 352,720,028 | 1,657 | lamberken | @KochetovNicolai thank you. | 2017-12-19T11:19:43 | 2017-12-19T11:19:43 | {} | CONTRIBUTOR |
ClickHouse | ClickHouse | 352,725,586 | 1,665 | KochetovNicolai | It's expected behavior. ClickHouse use fast and not very precise parser.
More precisely, string `'20.0000011'` is parsed as `20 + 0.000001 + 0.000001 = 20.000001 + 0.0000001 = 20.000001100000002` for float64. | 2017-12-19T11:43:40 | 2017-12-19T11:43:40 | {} | MEMBER |
ClickHouse | ClickHouse | 352,841,596 | 1,654 | alexey-milovidov | Cool!
I will glance through the modifications right now... | 2017-12-19T18:14:11 | 2017-12-19T18:14:11 | {} | MEMBER |
ClickHouse | ClickHouse | 352,867,956 | 1,648 | silviucpp | I'll close. I already tested a lot this and fix seems good and no performance regression | 2017-12-19T19:52:20 | 2017-12-19T19:52:20 | {} | CONTRIBUTOR |
ClickHouse | ClickHouse | 353,148,528 | 1,679 | alexey-milovidov | :+1: | 2017-12-20T18:44:47 | 2017-12-20T18:44:47 | {} | MEMBER |
Subsets and Splits
No community queries yet
The top public SQL queries from the community will appear here once available.