
url stringlengths 58 61 | repository_url stringclasses 1
value | labels_url stringlengths 72 75 | comments_url stringlengths 67 70 | events_url stringlengths 65 68 | html_url stringlengths 48 51 | id int64 600M 5.65B | node_id stringlengths 18 24 | number int64 2 8.71k | title stringlengths 2 290 | user dict | labels listlengths 0 4 | state stringclasses 2
values | locked bool 1
class | assignees listlengths 0 4 | milestone dict | comments listlengths 1 30 | created_at stringdate 2020-04-14 18:18:51 2026-09-30 14:11:42 | updated_at stringdate 2020-04-29 09:23:05 2026-09-30 23:50:47 | closed_at stringlengths 19 19 ⌀ | assignee dict | author_association stringclasses 4
values | issue_field_values listlengths 0 0 | type stringclasses 0
values | active_lock_reason stringclasses 0
values | draft bool 0
classes | pull_request dict | body stringlengths 0 228k ⌀ | closed_by dict | reactions dict | timeline_url stringlengths 67 70 | performed_via_github_app dict | state_reason stringclasses 4
values | sub_issues_summary stringclasses 1
value | issue_dependencies_summary stringclasses 1
value | pinned_comment stringclasses 0
values | is_pull_request bool 1
class |
|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|
https://api.github.com/repos/huggingface/datasets/issues/7389 | https://api.github.com/repos/huggingface/datasets | https://api.github.com/repos/huggingface/datasets/issues/7389/labels{/name} | https://api.github.com/repos/huggingface/datasets/issues/7389/comments | https://api.github.com/repos/huggingface/datasets/issues/7389/events | https://github.com/huggingface/datasets/issues/7389 | 2,843,592,606 | I_kwDODunzps6pfcee | 7,389 | Getting statistics about filtered examples | {
"login": "jonathanasdf",
"id": 511073,
"node_id": "MDQ6VXNlcjUxMTA3Mw==",
"avatar_url": "https://avatars.githubusercontent.com/u/511073?v=4",
"gravatar_id": "",
"url": "https://api.github.com/users/jonathanasdf",
"html_url": "https://github.com/jonathanasdf",
"followers_url": "https://api.github.com/u... | [] | closed | false | [] | null | [
"You can actually track a running sum in map() or filter() :)\n\n```python\nnum_filtered = 0\n\ndef f(x):\n global num_filtered\n condition = len(x[\"text\"]) < 1000\n if not condition:\n num_filtered += 1\n return condition\n\nds = ds.filter(f)\nprint(num_filtered)\n```\n\nand if you want to use... | 2025-02-10 20:48:29 | 2025-02-11 20:44:15 | 2025-02-11 20:44:13 | null | NONE | [] | null | null | null | null | @lhoestq wondering if the team has thought about this and if there are any recommendations?
Currently when processing datasets some examples are bound to get filtered out, whether it's due to bad format, or length is too long, or any other custom filters that might be getting applied. Let's just focus on the filter by... | {
"login": "jonathanasdf",
"id": 511073,
"node_id": "MDQ6VXNlcjUxMTA3Mw==",
"avatar_url": "https://avatars.githubusercontent.com/u/511073?v=4",
"gravatar_id": "",
"url": "https://api.github.com/users/jonathanasdf",
"html_url": "https://github.com/jonathanasdf",
"followers_url": "https://api.github.com/u... | {
"url": "https://api.github.com/repos/huggingface/datasets/issues/7389/reactions",
"total_count": 0,
"+1": 0,
"-1": 0,
"laugh": 0,
"hooray": 0,
"confused": 0,
"heart": 0,
"rocket": 0,
"eyes": 0
} | https://api.github.com/repos/huggingface/datasets/issues/7389/timeline | null | completed | {"total":0,"completed":0,"percent_completed":0} | {"blocked_by":0,"total_blocked_by":0,"blocking":0,"total_blocking":0} | null | false |
https://api.github.com/repos/huggingface/datasets/issues/7388 | https://api.github.com/repos/huggingface/datasets | https://api.github.com/repos/huggingface/datasets/issues/7388/labels{/name} | https://api.github.com/repos/huggingface/datasets/issues/7388/comments | https://api.github.com/repos/huggingface/datasets/issues/7388/events | https://github.com/huggingface/datasets/issues/7388 | 2,843,188,499 | I_kwDODunzps6pd50T | 7,388 | OSError: [Errno 22] Invalid argument forbidden character | {
"login": "langflogit",
"id": 124634542,
"node_id": "U_kgDOB23Frg",
"avatar_url": "https://avatars.githubusercontent.com/u/124634542?v=4",
"gravatar_id": "",
"url": "https://api.github.com/users/langflogit",
"html_url": "https://github.com/langflogit",
"followers_url": "https://api.github.com/users/lan... | [] | closed | false | [] | null | [
"You can probably copy the dataset in your HF account and rename the files (without having to download them to your disk). Or alternatively feel free to open a Pull Request to this dataset with the renamed file",
"Thank you, that will help me work around this problem"
] | 2025-02-10 17:46:31 | 2025-02-11 13:42:32 | 2025-02-11 13:42:30 | null | NONE | [] | null | null | null | null | ### Describe the bug
I'm on Windows and i'm trying to load a datasets but i'm having title error because files in the repository are named with charactere like < >which can't be in a name file. Could it be possible to load this datasets but removing those charactere ?
### Steps to reproduce the bug
load_dataset("CAT... | {
"login": "langflogit",
"id": 124634542,
"node_id": "U_kgDOB23Frg",
"avatar_url": "https://avatars.githubusercontent.com/u/124634542?v=4",
"gravatar_id": "",
"url": "https://api.github.com/users/langflogit",
"html_url": "https://github.com/langflogit",
"followers_url": "https://api.github.com/users/lan... | {
"url": "https://api.github.com/repos/huggingface/datasets/issues/7388/reactions",
"total_count": 0,
"+1": 0,
"-1": 0,
"laugh": 0,
"hooray": 0,
"confused": 0,
"heart": 0,
"rocket": 0,
"eyes": 0
} | https://api.github.com/repos/huggingface/datasets/issues/7388/timeline | null | completed | {"total":0,"completed":0,"percent_completed":0} | {"blocked_by":0,"total_blocked_by":0,"blocking":0,"total_blocking":0} | null | false |
https://api.github.com/repos/huggingface/datasets/issues/7387 | https://api.github.com/repos/huggingface/datasets | https://api.github.com/repos/huggingface/datasets/issues/7387/labels{/name} | https://api.github.com/repos/huggingface/datasets/issues/7387/comments | https://api.github.com/repos/huggingface/datasets/issues/7387/events | https://github.com/huggingface/datasets/issues/7387 | 2,841,228,048 | I_kwDODunzps6pWbMQ | 7,387 | Dynamic adjusting dataloader sampling weight | {
"login": "whc688",
"id": 72799643,
"node_id": "MDQ6VXNlcjcyNzk5NjQz",
"avatar_url": "https://avatars.githubusercontent.com/u/72799643?v=4",
"gravatar_id": "",
"url": "https://api.github.com/users/whc688",
"html_url": "https://github.com/whc688",
"followers_url": "https://api.github.com/users/whc688/fo... | [] | open | false | [] | null | [
"You mean based on a condition that has to be checked on-the-fly during training ? Otherwise if you know in advance after how many samples you need to change the sampling you can simply concatenate the two mixes",
"Yes, like during training, if one data sample's prediction is consistently wrong, its sampling weig... | 2025-02-10 03:18:47 | 2025-03-07 14:06:54 | null | null | NONE | [] | null | null | null | null | Hi,
Thanks for your wonderful work! I'm wondering is there a way to dynamically adjust the sampling weight of each data in the dataset during training? Looking forward to your reply, thanks again. | null | {
"url": "https://api.github.com/repos/huggingface/datasets/issues/7387/reactions",
"total_count": 0,
"+1": 0,
"-1": 0,
"laugh": 0,
"hooray": 0,
"confused": 0,
"heart": 0,
"rocket": 0,
"eyes": 0
} | https://api.github.com/repos/huggingface/datasets/issues/7387/timeline | null | null | {"total":0,"completed":0,"percent_completed":0} | {"blocked_by":0,"total_blocked_by":0,"blocking":0,"total_blocking":0} | null | false |
https://api.github.com/repos/huggingface/datasets/issues/7386 | https://api.github.com/repos/huggingface/datasets | https://api.github.com/repos/huggingface/datasets/issues/7386/labels{/name} | https://api.github.com/repos/huggingface/datasets/issues/7386/comments | https://api.github.com/repos/huggingface/datasets/issues/7386/events | https://github.com/huggingface/datasets/issues/7386 | 2,840,032,524 | I_kwDODunzps6pR3UM | 7,386 | Add bookfolder Dataset Builder for Digital Book Formats | {
"login": "shikanime",
"id": 22115108,
"node_id": "MDQ6VXNlcjIyMTE1MTA4",
"avatar_url": "https://avatars.githubusercontent.com/u/22115108?v=4",
"gravatar_id": "",
"url": "https://api.github.com/users/shikanime",
"html_url": "https://github.com/shikanime",
"followers_url": "https://api.github.com/users/... | [
{
"id": 1935892871,
"node_id": "MDU6TGFiZWwxOTM1ODkyODcx",
"url": "https://api.github.com/repos/huggingface/datasets/labels/enhancement",
"name": "enhancement",
"color": "a2eeef",
"default": true,
"description": "New feature or request",
"archived_at": null,
"archived_by": null
... | closed | false | [] | null | [
"On second thought, probably not a good idea."
] | 2025-02-08 14:27:55 | 2025-02-08 14:30:10 | 2025-02-08 14:30:09 | null | NONE | [] | null | null | null | null | ### Feature request
This feature proposes adding a new dataset builder called bookfolder to the datasets library. This builder would allow users to easily load datasets consisting of various digital book formats, including: AZW, AZW3, CB7, CBR, CBT, CBZ, EPUB, MOBI, and PDF.
### Motivation
Currently, loading dataset... | {
"login": "shikanime",
"id": 22115108,
"node_id": "MDQ6VXNlcjIyMTE1MTA4",
"avatar_url": "https://avatars.githubusercontent.com/u/22115108?v=4",
"gravatar_id": "",
"url": "https://api.github.com/users/shikanime",
"html_url": "https://github.com/shikanime",
"followers_url": "https://api.github.com/users/... | {
"url": "https://api.github.com/repos/huggingface/datasets/issues/7386/reactions",
"total_count": 0,
"+1": 0,
"-1": 0,
"laugh": 0,
"hooray": 0,
"confused": 0,
"heart": 0,
"rocket": 0,
"eyes": 0
} | https://api.github.com/repos/huggingface/datasets/issues/7386/timeline | null | completed | {"total":0,"completed":0,"percent_completed":0} | {"blocked_by":0,"total_blocked_by":0,"blocking":0,"total_blocking":0} | null | false |
https://api.github.com/repos/huggingface/datasets/issues/7381 | https://api.github.com/repos/huggingface/datasets | https://api.github.com/repos/huggingface/datasets/issues/7381/labels{/name} | https://api.github.com/repos/huggingface/datasets/issues/7381/comments | https://api.github.com/repos/huggingface/datasets/issues/7381/events | https://github.com/huggingface/datasets/issues/7381 | 2,815,649,092 | I_kwDODunzps6n02VE | 7,381 | Iterating over values of a column in the IterableDataset | {
"login": "TopCoder2K",
"id": 47208659,
"node_id": "MDQ6VXNlcjQ3MjA4NjU5",
"avatar_url": "https://avatars.githubusercontent.com/u/47208659?v=4",
"gravatar_id": "",
"url": "https://api.github.com/users/TopCoder2K",
"html_url": "https://github.com/TopCoder2K",
"followers_url": "https://api.github.com/use... | [
{
"id": 1935892871,
"node_id": "MDU6TGFiZWwxOTM1ODkyODcx",
"url": "https://api.github.com/repos/huggingface/datasets/labels/enhancement",
"name": "enhancement",
"color": "a2eeef",
"default": true,
"description": "New feature or request",
"archived_at": null,
"archived_by": null
... | closed | false | [
{
"login": "TopCoder2K",
"id": 47208659,
"node_id": "MDQ6VXNlcjQ3MjA4NjU5",
"avatar_url": "https://avatars.githubusercontent.com/u/47208659?v=4",
"gravatar_id": "",
"url": "https://api.github.com/users/TopCoder2K",
"html_url": "https://github.com/TopCoder2K",
"followers_url": "https:... | null | [
"I'd be in favor of that ! I saw many people implementing their own iterables that wrap a dataset just to iterate on a single column, that would make things more practical.\n\nKinda related: https://github.com/huggingface/datasets/issues/5847",
"(For anyone's information, I'm going on vacation for the next 3 week... | 2025-01-28 13:17:36 | 2025-05-22 18:00:04 | 2025-05-22 18:00:04 | {
"login": "TopCoder2K",
"id": 47208659,
"node_id": "MDQ6VXNlcjQ3MjA4NjU5",
"avatar_url": "https://avatars.githubusercontent.com/u/47208659?v=4",
"gravatar_id": "",
"url": "https://api.github.com/users/TopCoder2K",
"html_url": "https://github.com/TopCoder2K",
"followers_url": "https://api.github.com/use... | CONTRIBUTOR | [] | null | null | null | null | ### Feature request
I would like to be able to iterate (and re-iterate if needed) over a column of an `IterableDataset` instance. The following example shows the supposed API:
```python
def gen():
yield {"text": "Good", "label": 0}
yield {"text": "Bad", "label": 1}
ds = IterableDataset.from_generator(gen)
tex... | {
"login": "TopCoder2K",
"id": 47208659,
"node_id": "MDQ6VXNlcjQ3MjA4NjU5",
"avatar_url": "https://avatars.githubusercontent.com/u/47208659?v=4",
"gravatar_id": "",
"url": "https://api.github.com/users/TopCoder2K",
"html_url": "https://github.com/TopCoder2K",
"followers_url": "https://api.github.com/use... | {
"url": "https://api.github.com/repos/huggingface/datasets/issues/7381/reactions",
"total_count": 1,
"+1": 1,
"-1": 0,
"laugh": 0,
"hooray": 0,
"confused": 0,
"heart": 0,
"rocket": 0,
"eyes": 0
} | https://api.github.com/repos/huggingface/datasets/issues/7381/timeline | null | completed | {"total":0,"completed":0,"percent_completed":0} | {"blocked_by":0,"total_blocked_by":0,"blocking":0,"total_blocking":0} | null | false |
https://api.github.com/repos/huggingface/datasets/issues/7378 | https://api.github.com/repos/huggingface/datasets | https://api.github.com/repos/huggingface/datasets/issues/7378/labels{/name} | https://api.github.com/repos/huggingface/datasets/issues/7378/comments | https://api.github.com/repos/huggingface/datasets/issues/7378/events | https://github.com/huggingface/datasets/issues/7378 | 2,802,957,388 | I_kwDODunzps6nEbxM | 7,378 | Allow pushing config version to hub | {
"login": "momeara",
"id": 129072,
"node_id": "MDQ6VXNlcjEyOTA3Mg==",
"avatar_url": "https://avatars.githubusercontent.com/u/129072?v=4",
"gravatar_id": "",
"url": "https://api.github.com/users/momeara",
"html_url": "https://github.com/momeara",
"followers_url": "https://api.github.com/users/momeara/fo... | [
{
"id": 1935892871,
"node_id": "MDU6TGFiZWwxOTM1ODkyODcx",
"url": "https://api.github.com/repos/huggingface/datasets/labels/enhancement",
"name": "enhancement",
"color": "a2eeef",
"default": true,
"description": "New feature or request",
"archived_at": null,
"archived_by": null
... | open | false | [] | null | [
"Hi ! This sounds reasonable to me, feel free to open a PR :)"
] | 2025-01-21 22:35:07 | 2025-01-30 13:56:56 | null | null | NONE | [] | null | null | null | null | ### Feature request
Currently, when datasets are created, they can be versioned by passing the `version` argument to `load_dataset(...)`. For example creating `outcomes.csv` on the command line
```
echo "id,value\n1,0\n2,0\n3,1\n4,1\n" > outcomes.csv
```
and creating it
```
import datasets
dataset = datasets.load_dat... | null | {
"url": "https://api.github.com/repos/huggingface/datasets/issues/7378/reactions",
"total_count": 0,
"+1": 0,
"-1": 0,
"laugh": 0,
"hooray": 0,
"confused": 0,
"heart": 0,
"rocket": 0,
"eyes": 0
} | https://api.github.com/repos/huggingface/datasets/issues/7378/timeline | null | null | {"total":0,"completed":0,"percent_completed":0} | {"blocked_by":0,"total_blocked_by":0,"blocking":0,"total_blocking":0} | null | false |
https://api.github.com/repos/huggingface/datasets/issues/7377 | https://api.github.com/repos/huggingface/datasets | https://api.github.com/repos/huggingface/datasets/issues/7377/labels{/name} | https://api.github.com/repos/huggingface/datasets/issues/7377/comments | https://api.github.com/repos/huggingface/datasets/issues/7377/events | https://github.com/huggingface/datasets/issues/7377 | 2,802,723,285 | I_kwDODunzps6nDinV | 7,377 | Support for sparse arrays with the Arrow Sparse Tensor format? | {
"login": "JulesGM",
"id": 3231217,
"node_id": "MDQ6VXNlcjMyMzEyMTc=",
"avatar_url": "https://avatars.githubusercontent.com/u/3231217?v=4",
"gravatar_id": "",
"url": "https://api.github.com/users/JulesGM",
"html_url": "https://github.com/JulesGM",
"followers_url": "https://api.github.com/users/JulesGM/... | [
{
"id": 1935892871,
"node_id": "MDU6TGFiZWwxOTM1ODkyODcx",
"url": "https://api.github.com/repos/huggingface/datasets/labels/enhancement",
"name": "enhancement",
"color": "a2eeef",
"default": true,
"description": "New feature or request",
"archived_at": null,
"archived_by": null
... | open | false | [] | null | [
"Hi ! Unfortunately the Sparse Tensor structure in Arrow is not part of the Arrow format (yes it's confusing...), so it's not possible to use it in `datasets`. It's a separate structure that doesn't correspond to any type or extension type in Arrow.\n\nThe Arrow community recently added an extension type for fixed ... | 2025-01-21 20:14:35 | 2026-02-03 23:05:02 | null | null | NONE | [] | null | null | null | null | ### Feature request
AI in biology is becoming a big thing. One thing that would be a huge benefit to the field that Huggingface Datasets doesn't currently have is native support for **sparse arrays**.
Arrow has support for sparse tensors.
https://arrow.apache.org/docs/format/Other.html#sparse-tensor
It would be ... | null | {
"url": "https://api.github.com/repos/huggingface/datasets/issues/7377/reactions",
"total_count": 4,
"+1": 2,
"-1": 0,
"laugh": 0,
"hooray": 0,
"confused": 0,
"heart": 0,
"rocket": 0,
"eyes": 2
} | https://api.github.com/repos/huggingface/datasets/issues/7377/timeline | null | null | {"total":0,"completed":0,"percent_completed":0} | {"blocked_by":0,"total_blocked_by":0,"blocking":0,"total_blocking":0} | null | false |
https://api.github.com/repos/huggingface/datasets/issues/7375 | https://api.github.com/repos/huggingface/datasets | https://api.github.com/repos/huggingface/datasets/issues/7375/labels{/name} | https://api.github.com/repos/huggingface/datasets/issues/7375/comments | https://api.github.com/repos/huggingface/datasets/issues/7375/events | https://github.com/huggingface/datasets/issues/7375 | 2,800,609,218 | I_kwDODunzps6m7efC | 7,375 | vllm批量推理报错 | {
"login": "YuShengzuishuai",
"id": 51228154,
"node_id": "MDQ6VXNlcjUxMjI4MTU0",
"avatar_url": "https://avatars.githubusercontent.com/u/51228154?v=4",
"gravatar_id": "",
"url": "https://api.github.com/users/YuShengzuishuai",
"html_url": "https://github.com/YuShengzuishuai",
"followers_url": "https://api... | [] | open | false | [] | null | [
"Make sure you have installed a recent version of `soundfile`"
] | 2025-01-21 03:22:23 | 2025-01-30 14:02:40 | null | null | NONE | [] | null | null | null | null | ### Describe the bug

### Steps to reproduce the bug
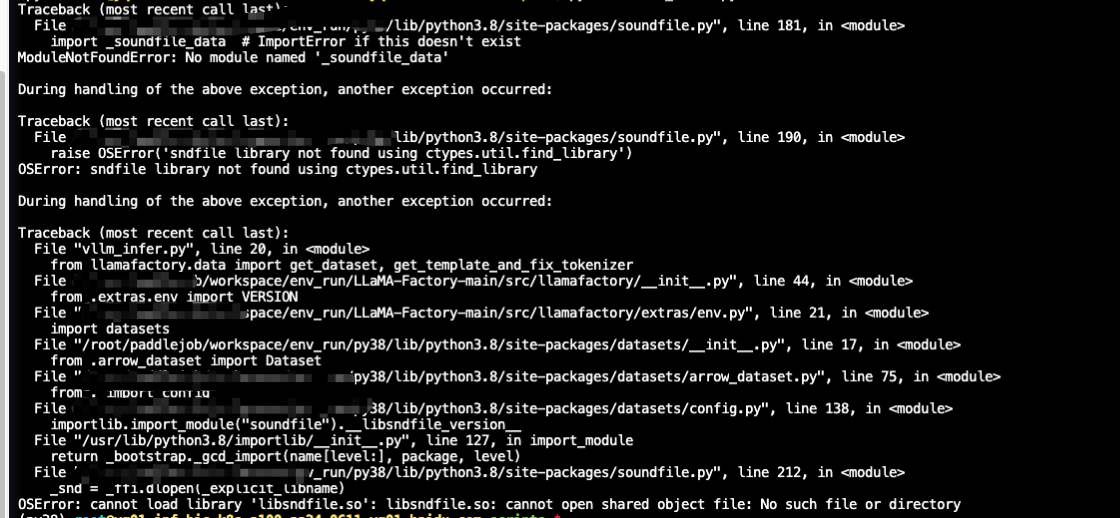
### Expected behavior
\n\n\n\nAdding a img from memray\nhttps://gist.github.com/sam-hey/00c958f13fb0f7b54d17197fe353002f",
"I'm having the same issue where c... | 2025-01-16 16:33:10 | 2025-03-27 17:40:59 | null | null | NONE | [] | null | null | null | null | ### Describe the bug
When loading a dataset from disk, concatenating it, and starting the training process, the RAM usage progressively increases until the kernel terminates the process due to excessive memory consumption.
https://github.com/huggingface/datasets/issues/2276
### Steps to reproduce the bug
```python
... | null | {
"url": "https://api.github.com/repos/huggingface/datasets/issues/7373/reactions",
"total_count": 0,
"+1": 0,
"-1": 0,
"laugh": 0,
"hooray": 0,
"confused": 0,
"heart": 0,
"rocket": 0,
"eyes": 0
} | https://api.github.com/repos/huggingface/datasets/issues/7373/timeline | null | null | {"total":0,"completed":0,"percent_completed":0} | {"blocked_by":0,"total_blocked_by":0,"blocking":0,"total_blocking":0} | null | false |
https://api.github.com/repos/huggingface/datasets/issues/7371 | https://api.github.com/repos/huggingface/datasets | https://api.github.com/repos/huggingface/datasets/issues/7371/labels{/name} | https://api.github.com/repos/huggingface/datasets/issues/7371/comments | https://api.github.com/repos/huggingface/datasets/issues/7371/events | https://github.com/huggingface/datasets/issues/7371 | 2,790,549,889 | I_kwDODunzps6mVGmB | 7,371 | 500 Server error with pushing a dataset | {
"login": "martinmatak",
"id": 7677814,
"node_id": "MDQ6VXNlcjc2Nzc4MTQ=",
"avatar_url": "https://avatars.githubusercontent.com/u/7677814?v=4",
"gravatar_id": "",
"url": "https://api.github.com/users/martinmatak",
"html_url": "https://github.com/martinmatak",
"followers_url": "https://api.github.com/us... | [] | open | false | [] | null | [
"EDIT: seems to be all good now. I'll add a comment if the error happens again within the next 48 hours. If it doesn't, I'll just close the topic."
] | 2025-01-15 18:23:02 | 2025-01-15 20:06:05 | null | null | NONE | [] | null | null | null | null | ### Describe the bug
Suddenly, I started getting this error message saying it was an internal error.
`Error creating/pushing dataset: 500 Server Error: Internal Server Error for url: https://huggingface.co/api/datasets/ll4ma-lab/grasp-dataset/commit/main (Request ID: Root=1-6787f0b7-66d5bd45413e481c4c2fb22d;670d04ff-... | null | {
"url": "https://api.github.com/repos/huggingface/datasets/issues/7371/reactions",
"total_count": 0,
"+1": 0,
"-1": 0,
"laugh": 0,
"hooray": 0,
"confused": 0,
"heart": 0,
"rocket": 0,
"eyes": 0
} | https://api.github.com/repos/huggingface/datasets/issues/7371/timeline | null | null | {"total":0,"completed":0,"percent_completed":0} | {"blocked_by":0,"total_blocked_by":0,"blocking":0,"total_blocking":0} | null | false |
https://api.github.com/repos/huggingface/datasets/issues/7369 | https://api.github.com/repos/huggingface/datasets | https://api.github.com/repos/huggingface/datasets/issues/7369/labels{/name} | https://api.github.com/repos/huggingface/datasets/issues/7369/comments | https://api.github.com/repos/huggingface/datasets/issues/7369/events | https://github.com/huggingface/datasets/issues/7369 | 2,787,193,238 | I_kwDODunzps6mITGW | 7,369 | Importing dataset gives unhelpful error message when filenames in metadata.csv are not found in the directory | {
"login": "svencornetsdegroot",
"id": 38278139,
"node_id": "MDQ6VXNlcjM4Mjc4MTM5",
"avatar_url": "https://avatars.githubusercontent.com/u/38278139?v=4",
"gravatar_id": "",
"url": "https://api.github.com/users/svencornetsdegroot",
"html_url": "https://github.com/svencornetsdegroot",
"followers_url": "ht... | [] | open | false | [] | null | [
"I'd prefer even more verbose errors; like `\"file123.mp3\" is referenced in metadata.csv, but not found in the data directory '/path/to/audiofolder' ! (and 100+ more missing files)` Or something along those lines."
] | 2025-01-14 13:53:21 | 2025-01-14 15:05:51 | null | null | NONE | [] | null | null | null | null | ### Describe the bug
While importing an audiofolder dataset, where the names of the audiofiles don't correspond to the filenames in the metadata.csv, we get an unclear error message that is not helpful for the debugging, i.e.
```
ValueError: Instruction "train" corresponds to no data!
```
### Steps to reproduce the ... | null | {
"url": "https://api.github.com/repos/huggingface/datasets/issues/7369/reactions",
"total_count": 1,
"+1": 1,
"-1": 0,
"laugh": 0,
"hooray": 0,
"confused": 0,
"heart": 0,
"rocket": 0,
"eyes": 0
} | https://api.github.com/repos/huggingface/datasets/issues/7369/timeline | null | null | {"total":0,"completed":0,"percent_completed":0} | {"blocked_by":0,"total_blocked_by":0,"blocking":0,"total_blocking":0} | null | false |
https://api.github.com/repos/huggingface/datasets/issues/7364 | https://api.github.com/repos/huggingface/datasets | https://api.github.com/repos/huggingface/datasets/issues/7364/labels{/name} | https://api.github.com/repos/huggingface/datasets/issues/7364/comments | https://api.github.com/repos/huggingface/datasets/issues/7364/events | https://github.com/huggingface/datasets/issues/7364 | 2,776,929,268 | I_kwDODunzps6lhJP0 | 7,364 | API endpoints for gated dataset access requests | {
"login": "jerome-white",
"id": 6140840,
"node_id": "MDQ6VXNlcjYxNDA4NDA=",
"avatar_url": "https://avatars.githubusercontent.com/u/6140840?v=4",
"gravatar_id": "",
"url": "https://api.github.com/users/jerome-white",
"html_url": "https://github.com/jerome-white",
"followers_url": "https://api.github.com... | [
{
"id": 1935892871,
"node_id": "MDU6TGFiZWwxOTM1ODkyODcx",
"url": "https://api.github.com/repos/huggingface/datasets/labels/enhancement",
"name": "enhancement",
"color": "a2eeef",
"default": true,
"description": "New feature or request",
"archived_at": null,
"archived_by": null
... | closed | false | [] | null | [
"Looks like a [similar feature request](https://github.com/huggingface/huggingface_hub/issues/1198) was made to the HF Hub team. Is handling this at the Hub level more appropriate?\r\n\r\n(As an aside, I've gotten the [HTTP-based solution](https://github.com/huggingface/huggingface_hub/issues/1198#issuecomment-1905... | 2025-01-09 06:21:20 | 2025-01-09 11:17:40 | 2025-01-09 11:17:20 | null | NONE | [] | null | null | null | null | ### Feature request
I would like a programatic way of requesting access to gated datasets. The current solution to gain access forces me to visit a website and physically click an "agreement" button (as per the [documentation](https://huggingface.co/docs/hub/en/datasets-gated#access-gated-datasets-as-a-user)).
An i... | {
"login": "jerome-white",
"id": 6140840,
"node_id": "MDQ6VXNlcjYxNDA4NDA=",
"avatar_url": "https://avatars.githubusercontent.com/u/6140840?v=4",
"gravatar_id": "",
"url": "https://api.github.com/users/jerome-white",
"html_url": "https://github.com/jerome-white",
"followers_url": "https://api.github.com... | {
"url": "https://api.github.com/repos/huggingface/datasets/issues/7364/reactions",
"total_count": 0,
"+1": 0,
"-1": 0,
"laugh": 0,
"hooray": 0,
"confused": 0,
"heart": 0,
"rocket": 0,
"eyes": 0
} | https://api.github.com/repos/huggingface/datasets/issues/7364/timeline | null | not_planned | {"total":0,"completed":0,"percent_completed":0} | {"blocked_by":0,"total_blocked_by":0,"blocking":0,"total_blocking":0} | null | false |
https://api.github.com/repos/huggingface/datasets/issues/7363 | https://api.github.com/repos/huggingface/datasets | https://api.github.com/repos/huggingface/datasets/issues/7363/labels{/name} | https://api.github.com/repos/huggingface/datasets/issues/7363/comments | https://api.github.com/repos/huggingface/datasets/issues/7363/events | https://github.com/huggingface/datasets/issues/7363 | 2,774,090,012 | I_kwDODunzps6lWUEc | 7,363 | ImportError: To support decoding images, please install 'Pillow'. | {
"login": "jamessdixon",
"id": 1394644,
"node_id": "MDQ6VXNlcjEzOTQ2NDQ=",
"avatar_url": "https://avatars.githubusercontent.com/u/1394644?v=4",
"gravatar_id": "",
"url": "https://api.github.com/users/jamessdixon",
"html_url": "https://github.com/jamessdixon",
"followers_url": "https://api.github.com/us... | [] | open | false | [] | null | [
"what's your `pip show Pillow` output",
"same issue.. my pip show Pillow output as below:\n\n```\nName: pillow\nVersion: 11.1.0\nSummary: Python Imaging Library (Fork)\nHome-page: https://python-pillow.github.io/\nAuthor: \nAuthor-email: \"Jeffrey A. Clark\" <aclark@aclark.net>\nLicense: MIT-CMU\nLocation: [/opt/... | 2025-01-08 02:22:57 | 2025-05-28 14:56:53 | null | null | NONE | [] | null | null | null | null | ### Describe the bug
Following this tutorial locally using a macboko and VSCode: https://huggingface.co/docs/diffusers/en/tutorials/basic_training
This line of code: for i, image in enumerate(dataset[:4]["image"]):
throws: ImportError: To support decoding images, please install 'Pillow'.
Pillow is installed.
###... | null | {
"url": "https://api.github.com/repos/huggingface/datasets/issues/7363/reactions",
"total_count": 0,
"+1": 0,
"-1": 0,
"laugh": 0,
"hooray": 0,
"confused": 0,
"heart": 0,
"rocket": 0,
"eyes": 0
} | https://api.github.com/repos/huggingface/datasets/issues/7363/timeline | null | null | {"total":0,"completed":0,"percent_completed":0} | {"blocked_by":0,"total_blocked_by":0,"blocking":0,"total_blocking":0} | null | false |
https://api.github.com/repos/huggingface/datasets/issues/7362 | https://api.github.com/repos/huggingface/datasets | https://api.github.com/repos/huggingface/datasets/issues/7362/labels{/name} | https://api.github.com/repos/huggingface/datasets/issues/7362/comments | https://api.github.com/repos/huggingface/datasets/issues/7362/events | https://github.com/huggingface/datasets/issues/7362 | 2,773,731,829 | I_kwDODunzps6lU8n1 | 7,362 | HuggingFace CLI dataset download raises error | {
"login": "ajayvohra2005",
"id": 3870355,
"node_id": "MDQ6VXNlcjM4NzAzNTU=",
"avatar_url": "https://avatars.githubusercontent.com/u/3870355?v=4",
"gravatar_id": "",
"url": "https://api.github.com/users/ajayvohra2005",
"html_url": "https://github.com/ajayvohra2005",
"followers_url": "https://api.github.... | [] | closed | false | [] | null | [
"I got the same error and was able to resolve it by upgrading from 2.15.0 to 3.2.0.",
"> I got the same error and was able to resolve it by upgrading from 2.15.0 to 3.2.0.\r\n\r\nWhat is needed is upgrading `huggingface-hub==0.27.1`. `datasets` does not appear to have anything to do with the error. The upgrade is... | 2025-01-07 21:03:30 | 2025-01-08 15:00:37 | 2025-01-08 14:35:52 | null | NONE | [] | null | null | null | null | ### Describe the bug
Trying to download Hugging Face datasets using Hugging Face CLI raises error. This error only started after December 27th, 2024. For example:
```
huggingface-cli download --repo-type dataset gboleda/wikicorpus
Traceback (most recent call last):
File "/home/ubuntu/test_venv/bin/huggingface... | {
"login": "lhoestq",
"id": 42851186,
"node_id": "MDQ6VXNlcjQyODUxMTg2",
"avatar_url": "https://avatars.githubusercontent.com/u/42851186?v=4",
"gravatar_id": "",
"url": "https://api.github.com/users/lhoestq",
"html_url": "https://github.com/lhoestq",
"followers_url": "https://api.github.com/users/lhoest... | {
"url": "https://api.github.com/repos/huggingface/datasets/issues/7362/reactions",
"total_count": 3,
"+1": 3,
"-1": 0,
"laugh": 0,
"hooray": 0,
"confused": 0,
"heart": 0,
"rocket": 0,
"eyes": 0
} | https://api.github.com/repos/huggingface/datasets/issues/7362/timeline | null | completed | {"total":0,"completed":0,"percent_completed":0} | {"blocked_by":0,"total_blocked_by":0,"blocking":0,"total_blocking":0} | null | false |
https://api.github.com/repos/huggingface/datasets/issues/7360 | https://api.github.com/repos/huggingface/datasets | https://api.github.com/repos/huggingface/datasets/issues/7360/labels{/name} | https://api.github.com/repos/huggingface/datasets/issues/7360/comments | https://api.github.com/repos/huggingface/datasets/issues/7360/events | https://github.com/huggingface/datasets/issues/7360 | 2,771,751,406 | I_kwDODunzps6lNZHu | 7,360 | error when loading dataset in Hugging Face: NoneType error is not callable | {
"login": "nanu23333",
"id": 189343338,
"node_id": "U_kgDOC0kmag",
"avatar_url": "https://avatars.githubusercontent.com/u/189343338?v=4",
"gravatar_id": "",
"url": "https://api.github.com/users/nanu23333",
"html_url": "https://github.com/nanu23333",
"followers_url": "https://api.github.com/users/nanu23... | [] | open | false | [] | null | [
"Hi ! I couldn't reproduce on my side, can you try deleting your cache at `~/.cache/huggingface/modules/datasets_modules/datasets/InstaDeepAI--nucleotide_transformer_downstream_tasks_revised` and try again ? For some reason `datasets` wasn't able to find the DatasetBuilder class in the python script of this dataset... | 2025-01-07 02:11:36 | 2025-02-24 13:32:52 | null | null | NONE | [] | null | null | null | null | ### Describe the bug
I met an error when running a notebook provide by Hugging Face, and met the error.
```
---------------------------------------------------------------------------
TypeError Traceback (most recent call last)
Cell In[2], line 5
3 # Load the enhancers dat... | null | {
"url": "https://api.github.com/repos/huggingface/datasets/issues/7360/reactions",
"total_count": 0,
"+1": 0,
"-1": 0,
"laugh": 0,
"hooray": 0,
"confused": 0,
"heart": 0,
"rocket": 0,
"eyes": 0
} | https://api.github.com/repos/huggingface/datasets/issues/7360/timeline | null | null | {"total":0,"completed":0,"percent_completed":0} | {"blocked_by":0,"total_blocked_by":0,"blocking":0,"total_blocking":0} | null | false |
https://api.github.com/repos/huggingface/datasets/issues/7359 | https://api.github.com/repos/huggingface/datasets | https://api.github.com/repos/huggingface/datasets/issues/7359/labels{/name} | https://api.github.com/repos/huggingface/datasets/issues/7359/comments | https://api.github.com/repos/huggingface/datasets/issues/7359/events | https://github.com/huggingface/datasets/issues/7359 | 2,771,137,842 | I_kwDODunzps6lLDUy | 7,359 | There are multiple 'mteb/arguana' configurations in the cache: default, corpus, queries with HF_HUB_OFFLINE=1 | {
"login": "Bhavya6187",
"id": 723146,
"node_id": "MDQ6VXNlcjcyMzE0Ng==",
"avatar_url": "https://avatars.githubusercontent.com/u/723146?v=4",
"gravatar_id": "",
"url": "https://api.github.com/users/Bhavya6187",
"html_url": "https://github.com/Bhavya6187",
"followers_url": "https://api.github.com/users/B... | [] | open | false | [] | null | [
"Related to https://github.com/embeddings-benchmark/mteb/issues/1714"
] | 2025-01-06 17:42:49 | 2025-01-06 17:43:31 | null | null | NONE | [] | null | null | null | null | ### Describe the bug
Hey folks,
I am trying to run this code -
```python
from datasets import load_dataset, get_dataset_config_names
ds = load_dataset("mteb/arguana")
```
with HF_HUB_OFFLINE=1
But I get the following error -
```python
Using the latest cached version of the dataset since mteb/arguana... | null | {
"url": "https://api.github.com/repos/huggingface/datasets/issues/7359/reactions",
"total_count": 0,
"+1": 0,
"-1": 0,
"laugh": 0,
"hooray": 0,
"confused": 0,
"heart": 0,
"rocket": 0,
"eyes": 0
} | https://api.github.com/repos/huggingface/datasets/issues/7359/timeline | null | null | {"total":0,"completed":0,"percent_completed":0} | {"blocked_by":0,"total_blocked_by":0,"blocking":0,"total_blocking":0} | null | false |
https://api.github.com/repos/huggingface/datasets/issues/7357 | https://api.github.com/repos/huggingface/datasets | https://api.github.com/repos/huggingface/datasets/issues/7357/labels{/name} | https://api.github.com/repos/huggingface/datasets/issues/7357/comments | https://api.github.com/repos/huggingface/datasets/issues/7357/events | https://github.com/huggingface/datasets/issues/7357 | 2,770,456,127 | I_kwDODunzps6lIc4_ | 7,357 | Python process aborded with GIL issue when using image dataset | {
"login": "AlexKoff88",
"id": 25342812,
"node_id": "MDQ6VXNlcjI1MzQyODEy",
"avatar_url": "https://avatars.githubusercontent.com/u/25342812?v=4",
"gravatar_id": "",
"url": "https://api.github.com/users/AlexKoff88",
"html_url": "https://github.com/AlexKoff88",
"followers_url": "https://api.github.com/use... | [] | open | false | [] | null | [
"The issue seems to come from `pyarrow`, I opened an issue on their side at https://github.com/apache/arrow/issues/45214",
"I \"solved\" this by setting a low batch_size for load_datasets()",
"datasets==3.1.0 works\ndatasets==4.1.1 fails",
"If you want to use latest version over 3.1.0, a temporary fix is to m... | 2025-01-06 11:29:30 | 2026-04-04 07:09:22 | null | null | NONE | [] | null | null | null | null | ### Describe the bug
The issue is visible only with the latest `datasets==3.2.0`.
When using image dataset the Python process gets aborted right before the exit with the following error:
```
Fatal Python error: PyGILState_Release: thread state 0x7fa1f409ade0 must be current when releasing
Python runtime state: f... | null | {
"url": "https://api.github.com/repos/huggingface/datasets/issues/7357/reactions",
"total_count": 4,
"+1": 4,
"-1": 0,
"laugh": 0,
"hooray": 0,
"confused": 0,
"heart": 0,
"rocket": 0,
"eyes": 0
} | https://api.github.com/repos/huggingface/datasets/issues/7357/timeline | null | null | {"total":0,"completed":0,"percent_completed":0} | {"blocked_by":0,"total_blocked_by":0,"blocking":0,"total_blocking":0} | null | false |
https://api.github.com/repos/huggingface/datasets/issues/7356 | https://api.github.com/repos/huggingface/datasets | https://api.github.com/repos/huggingface/datasets/issues/7356/labels{/name} | https://api.github.com/repos/huggingface/datasets/issues/7356/comments | https://api.github.com/repos/huggingface/datasets/issues/7356/events | https://github.com/huggingface/datasets/issues/7356 | 2,770,095,103 | I_kwDODunzps6lHEv_ | 7,356 | How about adding a feature to pass the key when performing map on DatasetDict? | {
"login": "jp1924",
"id": 93233241,
"node_id": "U_kgDOBY6gWQ",
"avatar_url": "https://avatars.githubusercontent.com/u/93233241?v=4",
"gravatar_id": "",
"url": "https://api.github.com/users/jp1924",
"html_url": "https://github.com/jp1924",
"followers_url": "https://api.github.com/users/jp1924/followers"... | [
{
"id": 1935892871,
"node_id": "MDU6TGFiZWwxOTM1ODkyODcx",
"url": "https://api.github.com/repos/huggingface/datasets/labels/enhancement",
"name": "enhancement",
"color": "a2eeef",
"default": true,
"description": "New feature or request",
"archived_at": null,
"archived_by": null
... | closed | false | [] | null | [
"@lhoestq \r\nIf it's okay with you, can I work on this?",
"Hi ! Can you give an example of what it would look like to use this new feature ?\r\n\r\nNote that currently you can already do\r\n\r\n```python\r\nds[\"train\"] = ds[\"train\"].map(process_train)\r\nds[\"test\"] = ds[\"test\"].map(process_test)\r\n```",... | 2025-01-06 08:13:52 | 2025-03-24 10:57:47 | 2025-03-24 10:57:47 | null | CONTRIBUTOR | [] | null | null | null | null | ### Feature request
Add a feature to pass the key of the DatasetDict when performing map
### Motivation
I often preprocess using map on DatasetDict.
Sometimes, I need to preprocess train and valid data differently depending on the task.
So, I thought it would be nice to pass the key (like train, valid) when perf... | {
"login": "jp1924",
"id": 93233241,
"node_id": "U_kgDOBY6gWQ",
"avatar_url": "https://avatars.githubusercontent.com/u/93233241?v=4",
"gravatar_id": "",
"url": "https://api.github.com/users/jp1924",
"html_url": "https://github.com/jp1924",
"followers_url": "https://api.github.com/users/jp1924/followers"... | {
"url": "https://api.github.com/repos/huggingface/datasets/issues/7356/reactions",
"total_count": 0,
"+1": 0,
"-1": 0,
"laugh": 0,
"hooray": 0,
"confused": 0,
"heart": 0,
"rocket": 0,
"eyes": 0
} | https://api.github.com/repos/huggingface/datasets/issues/7356/timeline | null | completed | {"total":0,"completed":0,"percent_completed":0} | {"blocked_by":0,"total_blocked_by":0,"blocking":0,"total_blocking":0} | null | false |
https://api.github.com/repos/huggingface/datasets/issues/7355 | https://api.github.com/repos/huggingface/datasets | https://api.github.com/repos/huggingface/datasets/issues/7355/labels{/name} | https://api.github.com/repos/huggingface/datasets/issues/7355/comments | https://api.github.com/repos/huggingface/datasets/issues/7355/events | https://github.com/huggingface/datasets/issues/7355 | 2,768,958,211 | I_kwDODunzps6lCvMD | 7,355 | Not available datasets[audio] on python 3.13 | {
"login": "sergiosinlimites",
"id": 70306948,
"node_id": "MDQ6VXNlcjcwMzA2OTQ4",
"avatar_url": "https://avatars.githubusercontent.com/u/70306948?v=4",
"gravatar_id": "",
"url": "https://api.github.com/users/sergiosinlimites",
"html_url": "https://github.com/sergiosinlimites",
"followers_url": "https://... | [] | open | false | [] | null | [
"It looks like an issue with `numba` which can't be installed on 3.13 ? `numba` is a dependency of `librosa`, used to decode audio files",
"There seems that `uv` cannot resolve \n\n```bhas\nuv add -n datasets[audio] huggingface-hub[hf-transfer] transformers\n```\n\nThe problem is again `librosa` which depends on ... | 2025-01-04 18:37:08 | 2025-06-28 00:26:19 | null | null | NONE | [] | null | null | null | null | ### Describe the bug
This is the error I got, it seems numba package does not support python 3.13
PS C:\Users\sergi\Documents> pip install datasets[audio]
Defaulting to user installation because normal site-packages is not writeable
Collecting datasets[audio]
Using cached datasets-3.2.0-py3-none-any.whl.metada... | null | {
"url": "https://api.github.com/repos/huggingface/datasets/issues/7355/reactions",
"total_count": 1,
"+1": 1,
"-1": 0,
"laugh": 0,
"hooray": 0,
"confused": 0,
"heart": 0,
"rocket": 0,
"eyes": 0
} | https://api.github.com/repos/huggingface/datasets/issues/7355/timeline | null | null | {"total":0,"completed":0,"percent_completed":0} | {"blocked_by":0,"total_blocked_by":0,"blocking":0,"total_blocking":0} | null | false |
https://api.github.com/repos/huggingface/datasets/issues/7354 | https://api.github.com/repos/huggingface/datasets | https://api.github.com/repos/huggingface/datasets/issues/7354/labels{/name} | https://api.github.com/repos/huggingface/datasets/issues/7354/comments | https://api.github.com/repos/huggingface/datasets/issues/7354/events | https://github.com/huggingface/datasets/issues/7354 | 2,768,955,917 | I_kwDODunzps6lCuoN | 7,354 | A module that was compiled using NumPy 1.x cannot be run in NumPy 2.0.2 as it may crash. To support both 1.x and 2.x versions of NumPy, modules must be compiled with NumPy 2.0. Some module may need to rebuild instead e.g. with 'pybind11>=2.12'. | {
"login": "jamessdixon",
"id": 1394644,
"node_id": "MDQ6VXNlcjEzOTQ2NDQ=",
"avatar_url": "https://avatars.githubusercontent.com/u/1394644?v=4",
"gravatar_id": "",
"url": "https://api.github.com/users/jamessdixon",
"html_url": "https://github.com/jamessdixon",
"followers_url": "https://api.github.com/us... | [] | closed | false | [] | null | [
"recreated .venv and run this: pip install diffusers[training]==0.11.1"
] | 2025-01-04 18:30:17 | 2025-01-08 02:20:58 | 2025-01-08 02:20:58 | null | NONE | [] | null | null | null | null | ### Describe the bug
Following this tutorial: https://huggingface.co/docs/diffusers/en/tutorials/basic_training and running it locally using VSCode on my MacBook. The first line in the tutorial fails: from datasets import load_dataset
dataset = load_dataset('huggan/smithsonian_butterflies_subset', split="train"). w... | {
"login": "jamessdixon",
"id": 1394644,
"node_id": "MDQ6VXNlcjEzOTQ2NDQ=",
"avatar_url": "https://avatars.githubusercontent.com/u/1394644?v=4",
"gravatar_id": "",
"url": "https://api.github.com/users/jamessdixon",
"html_url": "https://github.com/jamessdixon",
"followers_url": "https://api.github.com/us... | {
"url": "https://api.github.com/repos/huggingface/datasets/issues/7354/reactions",
"total_count": 0,
"+1": 0,
"-1": 0,
"laugh": 0,
"hooray": 0,
"confused": 0,
"heart": 0,
"rocket": 0,
"eyes": 0
} | https://api.github.com/repos/huggingface/datasets/issues/7354/timeline | null | completed | {"total":0,"completed":0,"percent_completed":0} | {"blocked_by":0,"total_blocked_by":0,"blocking":0,"total_blocking":0} | null | false |
https://api.github.com/repos/huggingface/datasets/issues/7347 | https://api.github.com/repos/huggingface/datasets | https://api.github.com/repos/huggingface/datasets/issues/7347/labels{/name} | https://api.github.com/repos/huggingface/datasets/issues/7347/comments | https://api.github.com/repos/huggingface/datasets/issues/7347/events | https://github.com/huggingface/datasets/issues/7347 | 2,760,282,339 | I_kwDODunzps6khpDj | 7,347 | Converting Arrow to WebDataset TAR Format for Offline Use | {
"login": "katie312",
"id": 91370128,
"node_id": "MDQ6VXNlcjkxMzcwMTI4",
"avatar_url": "https://avatars.githubusercontent.com/u/91370128?v=4",
"gravatar_id": "",
"url": "https://api.github.com/users/katie312",
"html_url": "https://github.com/katie312",
"followers_url": "https://api.github.com/users/kat... | [
{
"id": 1935892871,
"node_id": "MDU6TGFiZWwxOTM1ODkyODcx",
"url": "https://api.github.com/repos/huggingface/datasets/labels/enhancement",
"name": "enhancement",
"color": "a2eeef",
"default": true,
"description": "New feature or request",
"archived_at": null,
"archived_by": null
... | closed | false | [] | null | [
"Hi,\r\n\r\nI've downloaded an Arrow-formatted dataset offline using the hugggingface's datasets library by:\r\n\r\nimport json\r\nfrom datasets import load_dataset\r\n\r\ndataset = load_dataset(\"pixparse/cc3m-wds\")\r\ndataset.save_to_disk(\"./cc3m_1\")\r\n\r\n\r\nnow I need to convert it to WebDataset's TAR form... | 2024-12-27 01:40:44 | 2024-12-31 17:38:00 | 2024-12-28 15:38:03 | null | NONE | [] | null | null | null | null | ### Feature request
Hi,
I've downloaded an Arrow-formatted dataset offline using the hugggingface's datasets library by:
```
import json
from datasets import load_dataset
dataset = load_dataset("pixparse/cc3m-wds")
dataset.save_to_disk("./cc3m_1")
```
now I need to convert it to WebDataset's TAR form... | {
"login": "katie312",
"id": 91370128,
"node_id": "MDQ6VXNlcjkxMzcwMTI4",
"avatar_url": "https://avatars.githubusercontent.com/u/91370128?v=4",
"gravatar_id": "",
"url": "https://api.github.com/users/katie312",
"html_url": "https://github.com/katie312",
"followers_url": "https://api.github.com/users/kat... | {
"url": "https://api.github.com/repos/huggingface/datasets/issues/7347/reactions",
"total_count": 0,
"+1": 0,
"-1": 0,
"laugh": 0,
"hooray": 0,
"confused": 0,
"heart": 0,
"rocket": 0,
"eyes": 0
} | https://api.github.com/repos/huggingface/datasets/issues/7347/timeline | null | completed | {"total":0,"completed":0,"percent_completed":0} | {"blocked_by":0,"total_blocked_by":0,"blocking":0,"total_blocking":0} | null | false |
https://api.github.com/repos/huggingface/datasets/issues/7346 | https://api.github.com/repos/huggingface/datasets | https://api.github.com/repos/huggingface/datasets/issues/7346/labels{/name} | https://api.github.com/repos/huggingface/datasets/issues/7346/comments | https://api.github.com/repos/huggingface/datasets/issues/7346/events | https://github.com/huggingface/datasets/issues/7346 | 2,758,752,118 | I_kwDODunzps6kbzd2 | 7,346 | OSError: Invalid flatbuffers message. | {
"login": "antecede",
"id": 46232487,
"node_id": "MDQ6VXNlcjQ2MjMyNDg3",
"avatar_url": "https://avatars.githubusercontent.com/u/46232487?v=4",
"gravatar_id": "",
"url": "https://api.github.com/users/antecede",
"html_url": "https://github.com/antecede",
"followers_url": "https://api.github.com/users/ant... | [] | closed | false | [] | null | [
"Thanks for reporting, it looks like an issue with `pyarrow.ipc.open_stream`\r\n\r\nCan you try installing `datasets` from this pull request and see if it helps ? https://github.com/huggingface/datasets/pull/7348",
"> Thanks for reporting, it looks like an issue with `pyarrow.ipc.open_stream`\r\n> \r\n> Can you t... | 2024-12-25 11:38:52 | 2025-01-09 14:25:29 | 2025-01-09 14:25:05 | null | NONE | [] | null | null | null | null | ### Describe the bug
When loading a large 2D data (1000 × 1152) with a large number of (2,000 data in this case) in `load_dataset`, the error message `OSError: Invalid flatbuffers message` is reported.
When only 300 pieces of data of this size (1000 × 1152) are stored, they can be loaded correctly.
When 2,00... | {
"login": "lhoestq",
"id": 42851186,
"node_id": "MDQ6VXNlcjQyODUxMTg2",
"avatar_url": "https://avatars.githubusercontent.com/u/42851186?v=4",
"gravatar_id": "",
"url": "https://api.github.com/users/lhoestq",
"html_url": "https://github.com/lhoestq",
"followers_url": "https://api.github.com/users/lhoest... | {
"url": "https://api.github.com/repos/huggingface/datasets/issues/7346/reactions",
"total_count": 0,
"+1": 0,
"-1": 0,
"laugh": 0,
"hooray": 0,
"confused": 0,
"heart": 0,
"rocket": 0,
"eyes": 0
} | https://api.github.com/repos/huggingface/datasets/issues/7346/timeline | null | completed | {"total":0,"completed":0,"percent_completed":0} | {"blocked_by":0,"total_blocked_by":0,"blocking":0,"total_blocking":0} | null | false |
https://api.github.com/repos/huggingface/datasets/issues/7345 | https://api.github.com/repos/huggingface/datasets | https://api.github.com/repos/huggingface/datasets/issues/7345/labels{/name} | https://api.github.com/repos/huggingface/datasets/issues/7345/comments | https://api.github.com/repos/huggingface/datasets/issues/7345/events | https://github.com/huggingface/datasets/issues/7345 | 2,758,585,709 | I_kwDODunzps6kbK1t | 7,345 | Different behaviour of IterableDataset.map vs Dataset.map with remove_columns | {
"login": "vttrifonov",
"id": 12157034,
"node_id": "MDQ6VXNlcjEyMTU3MDM0",
"avatar_url": "https://avatars.githubusercontent.com/u/12157034?v=4",
"gravatar_id": "",
"url": "https://api.github.com/users/vttrifonov",
"html_url": "https://github.com/vttrifonov",
"followers_url": "https://api.github.com/use... | [] | closed | false | [] | null | [
"Good catch ! Do you think you can open a PR to fix this issue ?"
] | 2024-12-25 07:36:48 | 2025-01-07 11:56:42 | 2025-01-07 11:56:42 | null | CONTRIBUTOR | [] | null | null | null | null | ### Describe the bug
The following code
```python
import datasets as hf
ds1 = hf.Dataset.from_list([{'i': i} for i in [0,1]])
#ds1 = ds1.to_iterable_dataset()
ds2 = ds1.map(
lambda i: {'i': i+1},
input_columns = ['i'],
remove_columns = ['i']
)
list(ds2)
```
produces
```python
[{'i': ... | {
"login": "lhoestq",
"id": 42851186,
"node_id": "MDQ6VXNlcjQyODUxMTg2",
"avatar_url": "https://avatars.githubusercontent.com/u/42851186?v=4",
"gravatar_id": "",
"url": "https://api.github.com/users/lhoestq",
"html_url": "https://github.com/lhoestq",
"followers_url": "https://api.github.com/users/lhoest... | {
"url": "https://api.github.com/repos/huggingface/datasets/issues/7345/reactions",
"total_count": 0,
"+1": 0,
"-1": 0,
"laugh": 0,
"hooray": 0,
"confused": 0,
"heart": 0,
"rocket": 0,
"eyes": 0
} | https://api.github.com/repos/huggingface/datasets/issues/7345/timeline | null | completed | {"total":0,"completed":0,"percent_completed":0} | {"blocked_by":0,"total_blocked_by":0,"blocking":0,"total_blocking":0} | null | false |
https://api.github.com/repos/huggingface/datasets/issues/7344 | https://api.github.com/repos/huggingface/datasets | https://api.github.com/repos/huggingface/datasets/issues/7344/labels{/name} | https://api.github.com/repos/huggingface/datasets/issues/7344/comments | https://api.github.com/repos/huggingface/datasets/issues/7344/events | https://github.com/huggingface/datasets/issues/7344 | 2,754,735,951 | I_kwDODunzps6kMe9P | 7,344 | HfHubHTTPError: 429 Client Error: Too Many Requests for URL when trying to access SlimPajama-627B or c4 on TPUs | {
"login": "clankur",
"id": 9397233,
"node_id": "MDQ6VXNlcjkzOTcyMzM=",
"avatar_url": "https://avatars.githubusercontent.com/u/9397233?v=4",
"gravatar_id": "",
"url": "https://api.github.com/users/clankur",
"html_url": "https://github.com/clankur",
"followers_url": "https://api.github.com/users/clankur/... | [] | closed | false | [] | null | [
"Hi ! This is due to your old version of `datasets` which calls HF with `expand=True`, an option that is strongly rate limited.\r\n\r\nRecent versions of `datasets` don't rely on this anymore, you can fix your issue by upgrading `datasets` :)\r\n\r\n```\r\npip install -U datasets\r\n```\r\n\r\nYou can also get maxi... | 2024-12-22 16:30:07 | 2025-01-15 05:32:00 | 2025-01-15 05:31:58 | null | NONE | [] | null | null | null | null | ### Describe the bug
I am trying to run some trainings on Google's TPUs using Huggingface's DataLoader on [SlimPajama-627B](https://huggingface.co/datasets/cerebras/SlimPajama-627B) and [c4](https://huggingface.co/datasets/allenai/c4), but I end up running into `429 Client Error: Too Many Requests for URL` error when ... | {
"login": "clankur",
"id": 9397233,
"node_id": "MDQ6VXNlcjkzOTcyMzM=",
"avatar_url": "https://avatars.githubusercontent.com/u/9397233?v=4",
"gravatar_id": "",
"url": "https://api.github.com/users/clankur",
"html_url": "https://github.com/clankur",
"followers_url": "https://api.github.com/users/clankur/... | {
"url": "https://api.github.com/repos/huggingface/datasets/issues/7344/reactions",
"total_count": 0,
"+1": 0,
"-1": 0,
"laugh": 0,
"hooray": 0,
"confused": 0,
"heart": 0,
"rocket": 0,
"eyes": 0
} | https://api.github.com/repos/huggingface/datasets/issues/7344/timeline | null | completed | {"total":0,"completed":0,"percent_completed":0} | {"blocked_by":0,"total_blocked_by":0,"blocking":0,"total_blocking":0} | null | false |
https://api.github.com/repos/huggingface/datasets/issues/7343 | https://api.github.com/repos/huggingface/datasets | https://api.github.com/repos/huggingface/datasets/issues/7343/labels{/name} | https://api.github.com/repos/huggingface/datasets/issues/7343/comments | https://api.github.com/repos/huggingface/datasets/issues/7343/events | https://github.com/huggingface/datasets/issues/7343 | 2,750,525,823 | I_kwDODunzps6j8bF_ | 7,343 | [Bug] Inconsistent behavior of data_files and data_dir in load_dataset method. | {
"login": "JasonCZH4",
"id": 74161960,
"node_id": "MDQ6VXNlcjc0MTYxOTYw",
"avatar_url": "https://avatars.githubusercontent.com/u/74161960?v=4",
"gravatar_id": "",
"url": "https://api.github.com/users/JasonCZH4",
"html_url": "https://github.com/JasonCZH4",
"followers_url": "https://api.github.com/users/... | [] | closed | false | [] | null | [
"Hi ! `data_files` with a list is equivalent to `data_files={\"train\": data_files}` with a train test only.\r\n\r\nWhen no split are specified, they are inferred based on file names, and files with no apparent split are ignored",
"Thanks for your reply!\r\n`files with no apparent split are ignored`. Is there a o... | 2024-12-19 14:31:27 | 2025-01-03 15:54:09 | 2025-01-03 15:54:09 | null | NONE | [] | null | null | null | null | ### Describe the bug
Inconsistent operation of data_files and data_dir in load_dataset method.
### Steps to reproduce the bug
# First
I have three files, named 'train.json', 'val.json', 'test.json'.
Each one has a simple dict `{text:'aaa'}`.
Their path are `/data/train.json`, `/data/val.json`, `/data/test.jso... | {
"login": "JasonCZH4",
"id": 74161960,
"node_id": "MDQ6VXNlcjc0MTYxOTYw",
"avatar_url": "https://avatars.githubusercontent.com/u/74161960?v=4",
"gravatar_id": "",
"url": "https://api.github.com/users/JasonCZH4",
"html_url": "https://github.com/JasonCZH4",
"followers_url": "https://api.github.com/users/... | {
"url": "https://api.github.com/repos/huggingface/datasets/issues/7343/reactions",
"total_count": 0,
"+1": 0,
"-1": 0,
"laugh": 0,
"hooray": 0,
"confused": 0,
"heart": 0,
"rocket": 0,
"eyes": 0
} | https://api.github.com/repos/huggingface/datasets/issues/7343/timeline | null | completed | {"total":0,"completed":0,"percent_completed":0} | {"blocked_by":0,"total_blocked_by":0,"blocking":0,"total_blocking":0} | null | false |
https://api.github.com/repos/huggingface/datasets/issues/7337 | https://api.github.com/repos/huggingface/datasets | https://api.github.com/repos/huggingface/datasets/issues/7337/labels{/name} | https://api.github.com/repos/huggingface/datasets/issues/7337/comments | https://api.github.com/repos/huggingface/datasets/issues/7337/events | https://github.com/huggingface/datasets/issues/7337 | 2,744,877,569 | I_kwDODunzps6jm4IB | 7,337 | One or several metadata.jsonl were found, but not in the same directory or in a parent directory of | {
"login": "mst272",
"id": 67250532,
"node_id": "MDQ6VXNlcjY3MjUwNTMy",
"avatar_url": "https://avatars.githubusercontent.com/u/67250532?v=4",
"gravatar_id": "",
"url": "https://api.github.com/users/mst272",
"html_url": "https://github.com/mst272",
"followers_url": "https://api.github.com/users/mst272/fo... | [] | open | false | [] | null | [
"Hmmm I double checked in the source code and I found a contradiction: in the current implementation the metadata file is ignored if it's not in the same archive as the zip image somehow:\r\n\r\nhttps://github.com/huggingface/datasets/blob/caa705e8bf4bedf1a956f48b545283b2ca14170a/src/datasets/packaged_modules/folde... | 2024-12-17 12:58:43 | 2025-01-03 15:28:13 | null | null | NONE | [] | null | null | null | null | ### Describe the bug
ImageFolder with metadata.jsonl error. I downloaded liuhaotian/LLaVA-CC3M-Pretrain-595K locally from Hugging Face. According to the tutorial in https://huggingface.co/docs/datasets/image_dataset#image-captioning, only put images.zip and metadata.jsonl containing information in the same folder. How... | null | {
"url": "https://api.github.com/repos/huggingface/datasets/issues/7337/reactions",
"total_count": 0,
"+1": 0,
"-1": 0,
"laugh": 0,
"hooray": 0,
"confused": 0,
"heart": 0,
"rocket": 0,
"eyes": 0
} | https://api.github.com/repos/huggingface/datasets/issues/7337/timeline | null | null | {"total":0,"completed":0,"percent_completed":0} | {"blocked_by":0,"total_blocked_by":0,"blocking":0,"total_blocking":0} | null | false |
https://api.github.com/repos/huggingface/datasets/issues/7334 | https://api.github.com/repos/huggingface/datasets | https://api.github.com/repos/huggingface/datasets/issues/7334/labels{/name} | https://api.github.com/repos/huggingface/datasets/issues/7334/comments | https://api.github.com/repos/huggingface/datasets/issues/7334/events | https://github.com/huggingface/datasets/issues/7334 | 2,740,266,503 | I_kwDODunzps6jVSYH | 7,334 | TypeError: Value.__init__() missing 1 required positional argument: 'dtype' | {
"login": "ghost",
"id": 10137,
"node_id": "MDQ6VXNlcjEwMTM3",
"avatar_url": "https://avatars.githubusercontent.com/u/10137?v=4",
"gravatar_id": "",
"url": "https://api.github.com/users/ghost",
"html_url": "https://github.com/ghost",
"followers_url": "https://api.github.com/users/ghost/followers",
"f... | [] | open | false | [] | null | [
"same error \n```\ndata = load_dataset('/opt/deepseek_R1_finetune/hf_datasets/openai/gsm8k', 'main')[split] \n```",
"> same error\n> \n> ```\n> data = load_dataset('/opt/deepseek_R1_finetune/hf_datasets/openai/gsm8k', 'main')[split] \n> ```\n\nhttps://github.com/huggingface/open-r1/issues/204 this help me",
"S... | 2024-12-15 04:08:46 | 2025-10-30 09:05:53 | null | null | NONE | [] | null | null | null | null | ### Describe the bug
ds = load_dataset(
"./xxx.py",
name="default",
split="train",
)
The datasets does not support debugging locally anymore...
### Steps to reproduce the bug
```
from datasets import load_dataset
ds = load_dataset(
"./repo.py",
name="default",
split="train",
)
... | null | {
"url": "https://api.github.com/repos/huggingface/datasets/issues/7334/reactions",
"total_count": 1,
"+1": 1,
"-1": 0,
"laugh": 0,
"hooray": 0,
"confused": 0,
"heart": 0,
"rocket": 0,
"eyes": 0
} | https://api.github.com/repos/huggingface/datasets/issues/7334/timeline | null | null | {"total":0,"completed":0,"percent_completed":0} | {"blocked_by":0,"total_blocked_by":0,"blocking":0,"total_blocking":0} | null | false |
https://api.github.com/repos/huggingface/datasets/issues/7327 | https://api.github.com/repos/huggingface/datasets | https://api.github.com/repos/huggingface/datasets/issues/7327/labels{/name} | https://api.github.com/repos/huggingface/datasets/issues/7327/comments | https://api.github.com/repos/huggingface/datasets/issues/7327/events | https://github.com/huggingface/datasets/issues/7327 | 2,738,514,909 | I_kwDODunzps6jOmvd | 7,327 | .map() is not caching and ram goes OOM | {
"login": "simeneide",
"id": 7136076,
"node_id": "MDQ6VXNlcjcxMzYwNzY=",
"avatar_url": "https://avatars.githubusercontent.com/u/7136076?v=4",
"gravatar_id": "",
"url": "https://api.github.com/users/simeneide",
"html_url": "https://github.com/simeneide",
"followers_url": "https://api.github.com/users/si... | [] | open | false | [] | null | [
"I have the same issue - any update on this?"
] | 2024-12-13 14:22:56 | 2025-02-10 10:42:38 | null | null | NONE | [] | null | null | null | null | ### Describe the bug
Im trying to run a fairly simple map that is converting a dataset into numpy arrays. however, it just piles up on memory and doesnt write to disk. Ive tried multiple cache techniques such as specifying the cache dir, setting max mem, +++ but none seem to work. What am I missing here?
### Steps to... | null | {
"url": "https://api.github.com/repos/huggingface/datasets/issues/7327/reactions",
"total_count": 4,
"+1": 4,
"-1": 0,
"laugh": 0,
"hooray": 0,
"confused": 0,
"heart": 0,
"rocket": 0,
"eyes": 0
} | https://api.github.com/repos/huggingface/datasets/issues/7327/timeline | null | null | {"total":0,"completed":0,"percent_completed":0} | {"blocked_by":0,"total_blocked_by":0,"blocking":0,"total_blocking":0} | null | false |
https://api.github.com/repos/huggingface/datasets/issues/7326 | https://api.github.com/repos/huggingface/datasets | https://api.github.com/repos/huggingface/datasets/issues/7326/labels{/name} | https://api.github.com/repos/huggingface/datasets/issues/7326/comments | https://api.github.com/repos/huggingface/datasets/issues/7326/events | https://github.com/huggingface/datasets/issues/7326 | 2,738,188,902 | I_kwDODunzps6jNXJm | 7,326 | Remove upper bound for fsspec | {
"login": "fellhorn",
"id": 26092524,
"node_id": "MDQ6VXNlcjI2MDkyNTI0",
"avatar_url": "https://avatars.githubusercontent.com/u/26092524?v=4",
"gravatar_id": "",
"url": "https://api.github.com/users/fellhorn",
"html_url": "https://github.com/fellhorn",
"followers_url": "https://api.github.com/users/fel... | [] | open | false | [] | null | [
"Unfortunately `fsspec` versioning allows breaking changes across version and there is no way we can keep it without constrains at the moment. It already broke `datasets` once in the past. Maybe one day once `fsspec` decides on a stable and future proof API but I don't think this will happen anytime soon\r\n\r\nedi... | 2024-12-13 11:35:12 | 2025-01-03 15:34:37 | null | null | NONE | [] | null | null | null | null | ### Describe the bug
As also raised by @cyyever in https://github.com/huggingface/datasets/pull/7296 and @NeilGirdhar in https://github.com/huggingface/datasets/commit/d5468836fe94e8be1ae093397dd43d4a2503b926#commitcomment-140952162 , `datasets` has a problematic version constraint on `fsspec`.
In our case this c... | null | {
"url": "https://api.github.com/repos/huggingface/datasets/issues/7326/reactions",
"total_count": 3,
"+1": 0,
"-1": 0,
"laugh": 0,
"hooray": 0,
"confused": 0,
"heart": 3,
"rocket": 0,
"eyes": 0
} | https://api.github.com/repos/huggingface/datasets/issues/7326/timeline | null | null | {"total":0,"completed":0,"percent_completed":0} | {"blocked_by":0,"total_blocked_by":0,"blocking":0,"total_blocking":0} | null | false |
https://api.github.com/repos/huggingface/datasets/issues/7323 | https://api.github.com/repos/huggingface/datasets | https://api.github.com/repos/huggingface/datasets/issues/7323/labels{/name} | https://api.github.com/repos/huggingface/datasets/issues/7323/comments | https://api.github.com/repos/huggingface/datasets/issues/7323/events | https://github.com/huggingface/datasets/issues/7323 | 2,736,008,698 | I_kwDODunzps6jFC36 | 7,323 | Unexpected cache behaviour using load_dataset | {
"login": "Moritz-Wirth",
"id": 74349080,
"node_id": "MDQ6VXNlcjc0MzQ5MDgw",
"avatar_url": "https://avatars.githubusercontent.com/u/74349080?v=4",
"gravatar_id": "",
"url": "https://api.github.com/users/Moritz-Wirth",
"html_url": "https://github.com/Moritz-Wirth",
"followers_url": "https://api.github.c... | [] | closed | false | [] | null | [
"Hi ! Since `datasets` 3.x, the `datasets` specific files are in `cache_dir=` and the HF files are cached using `huggingface_hub` and you can set its cache directory using the `HF_HOME` environment variable.\r\n\r\nThey are independent, for example you can delete the Hub cache (containing downloaded files) but sti... | 2024-12-12 14:03:00 | 2025-01-31 11:34:24 | 2025-01-31 11:34:24 | null | NONE | [] | null | null | null | null | ### Describe the bug
Following the (Cache management)[https://huggingface.co/docs/datasets/en/cache] docu and previous behaviour from datasets version 2.18.0, one is able to change the cache directory. Previously, all downloaded/extracted/etc files were found in this folder. As i have recently update to the latest v... | {
"login": "Moritz-Wirth",
"id": 74349080,
"node_id": "MDQ6VXNlcjc0MzQ5MDgw",
"avatar_url": "https://avatars.githubusercontent.com/u/74349080?v=4",
"gravatar_id": "",
"url": "https://api.github.com/users/Moritz-Wirth",
"html_url": "https://github.com/Moritz-Wirth",
"followers_url": "https://api.github.c... | {
"url": "https://api.github.com/repos/huggingface/datasets/issues/7323/reactions",
"total_count": 0,
"+1": 0,
"-1": 0,
"laugh": 0,
"hooray": 0,
"confused": 0,
"heart": 0,
"rocket": 0,
"eyes": 0
} | https://api.github.com/repos/huggingface/datasets/issues/7323/timeline | null | completed | {"total":0,"completed":0,"percent_completed":0} | {"blocked_by":0,"total_blocked_by":0,"blocking":0,"total_blocking":0} | null | false |
https://api.github.com/repos/huggingface/datasets/issues/7322 | https://api.github.com/repos/huggingface/datasets | https://api.github.com/repos/huggingface/datasets/issues/7322/labels{/name} | https://api.github.com/repos/huggingface/datasets/issues/7322/comments | https://api.github.com/repos/huggingface/datasets/issues/7322/events | https://github.com/huggingface/datasets/issues/7322 | 2,732,254,868 | I_kwDODunzps6i2uaU | 7,322 | ArrowInvalid: JSON parse error: Column() changed from object to array in row 0 | {
"login": "Polarisamoon",
"id": 41767521,
"node_id": "MDQ6VXNlcjQxNzY3NTIx",
"avatar_url": "https://avatars.githubusercontent.com/u/41767521?v=4",
"gravatar_id": "",
"url": "https://api.github.com/users/Polarisamoon",
"html_url": "https://github.com/Polarisamoon",
"followers_url": "https://api.github.c... | [] | open | false | [] | null | [
"Hi ! `datasets` uses Arrow under the hood which expects each column and array to have fixed types that don't change across rows of a dataset, which is why we get this error. This dataset in particular doesn't have a format compatible with Arrow unfortunately. Don't hesitate to open a discussion or PR on HF to fix ... | 2024-12-11 08:41:39 | 2025-07-15 13:06:55 | null | null | NONE | [] | null | null | null | null | ### Describe the bug
Encountering an error while loading the ```liuhaotian/LLaVA-Instruct-150K dataset```.
### Steps to reproduce the bug
```
from datasets import load_dataset
fw =load_dataset("liuhaotian/LLaVA-Instruct-150K")
```
Error:
```
ArrowInvalid Traceback (most recen... | null | {
"url": "https://api.github.com/repos/huggingface/datasets/issues/7322/reactions",
"total_count": 2,
"+1": 1,
"-1": 0,
"laugh": 0,
"hooray": 0,
"confused": 0,
"heart": 0,
"rocket": 0,
"eyes": 1
} | https://api.github.com/repos/huggingface/datasets/issues/7322/timeline | null | null | {"total":0,"completed":0,"percent_completed":0} | {"blocked_by":0,"total_blocked_by":0,"blocking":0,"total_blocking":0} | null | false |
https://api.github.com/repos/huggingface/datasets/issues/7321 | https://api.github.com/repos/huggingface/datasets | https://api.github.com/repos/huggingface/datasets/issues/7321/labels{/name} | https://api.github.com/repos/huggingface/datasets/issues/7321/comments | https://api.github.com/repos/huggingface/datasets/issues/7321/events | https://github.com/huggingface/datasets/issues/7321 | 2,731,626,760 | I_kwDODunzps6i0VEI | 7,321 | ImportError: cannot import name 'set_caching_enabled' from 'datasets' | {
"login": "sankexin",
"id": 33318353,
"node_id": "MDQ6VXNlcjMzMzE4MzUz",
"avatar_url": "https://avatars.githubusercontent.com/u/33318353?v=4",
"gravatar_id": "",
"url": "https://api.github.com/users/sankexin",
"html_url": "https://github.com/sankexin",
"followers_url": "https://api.github.com/users/san... | [] | open | false | [] | null | [
"pip install datasets==2.18.0",
"Hi ! I think you need to update axolotl"
] | 2024-12-11 01:58:46 | 2024-12-11 13:32:15 | null | null | NONE | [] | null | null | null | null | ### Describe the bug
Traceback (most recent call last):
File "/usr/local/lib/python3.10/runpy.py", line 187, in _run_module_as_main
mod_name, mod_spec, code = _get_module_details(mod_name, _Error)
File "/usr/local/lib/python3.10/runpy.py", line 110, in _get_module_details
__import__(pkg_name)
File "... | null | {
"url": "https://api.github.com/repos/huggingface/datasets/issues/7321/reactions",
"total_count": 0,
"+1": 0,
"-1": 0,
"laugh": 0,
"hooray": 0,
"confused": 0,
"heart": 0,
"rocket": 0,
"eyes": 0
} | https://api.github.com/repos/huggingface/datasets/issues/7321/timeline | null | null | {"total":0,"completed":0,"percent_completed":0} | {"blocked_by":0,"total_blocked_by":0,"blocking":0,"total_blocking":0} | null | false |
https://api.github.com/repos/huggingface/datasets/issues/7320 | https://api.github.com/repos/huggingface/datasets | https://api.github.com/repos/huggingface/datasets/issues/7320/labels{/name} | https://api.github.com/repos/huggingface/datasets/issues/7320/comments | https://api.github.com/repos/huggingface/datasets/issues/7320/events | https://github.com/huggingface/datasets/issues/7320 | 2,731,112,100 | I_kwDODunzps6iyXak | 7,320 | ValueError: You should supply an encoding or a list of encodings to this method that includes input_ids, but you provided ['label'] | {
"login": "atrompeterog",
"id": 38381084,
"node_id": "MDQ6VXNlcjM4MzgxMDg0",
"avatar_url": "https://avatars.githubusercontent.com/u/38381084?v=4",
"gravatar_id": "",
"url": "https://api.github.com/users/atrompeterog",
"html_url": "https://github.com/atrompeterog",
"followers_url": "https://api.github.c... | [] | closed | false | [] | null | [
"Now i have other error"
] | 2024-12-10 20:23:11 | 2024-12-10 23:22:23 | 2024-12-10 23:22:23 | null | NONE | [] | null | null | null | null | ### Describe the bug
I am trying to create a PEFT model from DISTILBERT model, and run a training loop. However, the trainer.train() is giving me this error: ValueError: You should supply an encoding or a list of encodings to this method that includes input_ids, but you provided ['label']
Here is my code:
### St... | {
"login": "atrompeterog",
"id": 38381084,
"node_id": "MDQ6VXNlcjM4MzgxMDg0",
"avatar_url": "https://avatars.githubusercontent.com/u/38381084?v=4",
"gravatar_id": "",
"url": "https://api.github.com/users/atrompeterog",
"html_url": "https://github.com/atrompeterog",
"followers_url": "https://api.github.c... | {
"url": "https://api.github.com/repos/huggingface/datasets/issues/7320/reactions",
"total_count": 0,
"+1": 0,
"-1": 0,
"laugh": 0,
"hooray": 0,
"confused": 0,
"heart": 0,
"rocket": 0,
"eyes": 0
} | https://api.github.com/repos/huggingface/datasets/issues/7320/timeline | null | completed | {"total":0,"completed":0,"percent_completed":0} | {"blocked_by":0,"total_blocked_by":0,"blocking":0,"total_blocking":0} | null | false |
https://api.github.com/repos/huggingface/datasets/issues/7318 | https://api.github.com/repos/huggingface/datasets | https://api.github.com/repos/huggingface/datasets/issues/7318/labels{/name} | https://api.github.com/repos/huggingface/datasets/issues/7318/comments | https://api.github.com/repos/huggingface/datasets/issues/7318/events | https://github.com/huggingface/datasets/issues/7318 | 2,730,676,278 | I_kwDODunzps6iwtA2 | 7,318 | Introduce support for PDFs | {
"login": "yabramuvdi",
"id": 4812761,
"node_id": "MDQ6VXNlcjQ4MTI3NjE=",
"avatar_url": "https://avatars.githubusercontent.com/u/4812761?v=4",
"gravatar_id": "",
"url": "https://api.github.com/users/yabramuvdi",
"html_url": "https://github.com/yabramuvdi",
"followers_url": "https://api.github.com/users... | [
{
"id": 1935892871,
"node_id": "MDU6TGFiZWwxOTM1ODkyODcx",
"url": "https://api.github.com/repos/huggingface/datasets/labels/enhancement",
"name": "enhancement",
"color": "a2eeef",
"default": true,
"description": "New feature or request",
"archived_at": null,
"archived_by": null
... | open | false | [] | null | [
"#self-assign",
"Awesome ! Let me know if you have any question or if I can help :)\r\n\r\ncc @AndreaFrancis as well for viz",
"Other candidates libraries for the Pdf type: PyMuPDF pypdf and pdfplumber\r\n\r\nEDIT: Pymupdf looks like a good choice when it comes to maturity + performance + versatility BUT the li... | 2024-12-10 16:59:48 | 2024-12-12 18:38:13 | null | null | CONTRIBUTOR | [] | null | null | null | null | ### Feature request
The idea (discussed in the Discord server with @lhoestq ) is to have a Pdf type like Image/Audio/Video. For example [Video](https://github.com/huggingface/datasets/blob/main/src/datasets/features/video.py) was recently added and contains how to decode a video file encoded in a dictionary like {"pat... | null | {
"url": "https://api.github.com/repos/huggingface/datasets/issues/7318/reactions",
"total_count": 1,
"+1": 0,
"-1": 0,
"laugh": 0,
"hooray": 0,
"confused": 0,
"heart": 1,
"rocket": 0,
"eyes": 0
} | https://api.github.com/repos/huggingface/datasets/issues/7318/timeline | null | null | {"total":0,"completed":0,"percent_completed":0} | {"blocked_by":0,"total_blocked_by":0,"blocking":0,"total_blocking":0} | null | false |
https://api.github.com/repos/huggingface/datasets/issues/7313 | https://api.github.com/repos/huggingface/datasets | https://api.github.com/repos/huggingface/datasets/issues/7313/labels{/name} | https://api.github.com/repos/huggingface/datasets/issues/7313/comments | https://api.github.com/repos/huggingface/datasets/issues/7313/events | https://github.com/huggingface/datasets/issues/7313 | 2,726,240,634 | I_kwDODunzps6ifyF6 | 7,313 | Cannot create a dataset with relative audio path | {
"login": "sedol1339",
"id": 5188731,
"node_id": "MDQ6VXNlcjUxODg3MzE=",
"avatar_url": "https://avatars.githubusercontent.com/u/5188731?v=4",
"gravatar_id": "",
"url": "https://api.github.com/users/sedol1339",
"html_url": "https://github.com/sedol1339",
"followers_url": "https://api.github.com/users/se... | [] | open | false | [] | null | [
"Hello ! when you `cast_column` you need the paths to be absolute paths or relative paths to your working directory, not the original dataset directory.\r\n\r\nThough I'd recommend structuring your dataset as an AudioFolder which automatically links a metadata.jsonl or csv to the audio files via relative paths **wi... | 2024-12-09 07:34:20 | 2025-04-19 07:13:08 | null | null | NONE | [] | null | null | null | null | ### Describe the bug
Hello! I want to create a dataset of parquet files, with audios stored as separate .mp3 files. However, it says "No such file or directory" (see the reproducing code).
### Steps to reproduce the bug
Creating a dataset
```
from pathlib import Path
from datasets import Dataset, load_datas... | null | {
"url": "https://api.github.com/repos/huggingface/datasets/issues/7313/reactions",
"total_count": 0,
"+1": 0,
"-1": 0,
"laugh": 0,
"hooray": 0,
"confused": 0,
"heart": 0,
"rocket": 0,
"eyes": 0
} | https://api.github.com/repos/huggingface/datasets/issues/7313/timeline | null | null | {"total":0,"completed":0,"percent_completed":0} | {"blocked_by":0,"total_blocked_by":0,"blocking":0,"total_blocking":0} | null | false |
https://api.github.com/repos/huggingface/datasets/issues/7311 | https://api.github.com/repos/huggingface/datasets | https://api.github.com/repos/huggingface/datasets/issues/7311/labels{/name} | https://api.github.com/repos/huggingface/datasets/issues/7311/comments | https://api.github.com/repos/huggingface/datasets/issues/7311/events | https://github.com/huggingface/datasets/issues/7311 | 2,725,002,630 | I_kwDODunzps6ibD2G | 7,311 | How to get the original dataset name with username? | {
"login": "npuichigo",
"id": 11533479,
"node_id": "MDQ6VXNlcjExNTMzNDc5",
"avatar_url": "https://avatars.githubusercontent.com/u/11533479?v=4",
"gravatar_id": "",
"url": "https://api.github.com/users/npuichigo",
"html_url": "https://github.com/npuichigo",
"followers_url": "https://api.github.com/users/... | [
{
"id": 1935892871,
"node_id": "MDU6TGFiZWwxOTM1ODkyODcx",
"url": "https://api.github.com/repos/huggingface/datasets/labels/enhancement",
"name": "enhancement",
"color": "a2eeef",
"default": true,
"description": "New feature or request",
"archived_at": null,
"archived_by": null
... | open | false | [] | null | [
"Hi ! why not pass the dataset id to Ray and let it check the parquet files ? Or pass the parquet files lists directly ?",
"I'm not sure why ray design an API like this to accept a `Dataset` object, so they need to verify the `Dataset` is the original one and use the `DatasetInfo` to query the huggingface hub. I'... | 2024-12-08 07:18:14 | 2025-01-09 10:48:02 | null | null | CONTRIBUTOR | [] | null | null | null | null | ### Feature request
The issue is related to ray data https://github.com/ray-project/ray/issues/49008 which it requires to check if the dataset is the original one just after `load_dataset` and parquet files are already available on hf hub.
The solution used now is to get the dataset name, config and split, then `... | null | {
"url": "https://api.github.com/repos/huggingface/datasets/issues/7311/reactions",
"total_count": 0,
"+1": 0,
"-1": 0,
"laugh": 0,
"hooray": 0,
"confused": 0,
"heart": 0,
"rocket": 0,
"eyes": 0
} | https://api.github.com/repos/huggingface/datasets/issues/7311/timeline | null | null | {"total":0,"completed":0,"percent_completed":0} | {"blocked_by":0,"total_blocked_by":0,"blocking":0,"total_blocking":0} | null | false |
https://api.github.com/repos/huggingface/datasets/issues/7310 | https://api.github.com/repos/huggingface/datasets | https://api.github.com/repos/huggingface/datasets/issues/7310/labels{/name} | https://api.github.com/repos/huggingface/datasets/issues/7310/comments | https://api.github.com/repos/huggingface/datasets/issues/7310/events | https://github.com/huggingface/datasets/issues/7310 | 2,724,830,603 | I_kwDODunzps6iaZ2L | 7,310 | Enable the Audio Feature to decode / read with an offset + duration | {
"login": "TParcollet",
"id": 11910731,
"node_id": "MDQ6VXNlcjExOTEwNzMx",
"avatar_url": "https://avatars.githubusercontent.com/u/11910731?v=4",
"gravatar_id": "",
"url": "https://api.github.com/users/TParcollet",
"html_url": "https://github.com/TParcollet",
"followers_url": "https://api.github.com/use... | [
{
"id": 1935892871,
"node_id": "MDU6TGFiZWwxOTM1ODkyODcx",
"url": "https://api.github.com/repos/huggingface/datasets/labels/enhancement",
"name": "enhancement",
"color": "a2eeef",
"default": true,
"description": "New feature or request",
"archived_at": null,
"archived_by": null
... | open | false | [] | null | [
"Hi ! What about having audio + start + duration columns and enable something like this ?\r\n\r\n```python\r\nfor example in ds:\r\n array = example[\"audio\"].read(start=example[\"start\"], frames=example[\"duration\"])\r\n```",
"Hi @lhoestq, this would work with a file-based dataset but would be terrible for... | 2024-12-07 22:01:44 | 2024-12-09 21:09:46 | null | null | NONE | [] | null | null | null | null | ### Feature request
For most large speech dataset, we do not wish to generate hundreds of millions of small audio samples. Instead, it is quite common to provide larger audio files with frame offset (soundfile start and stop arguments). We should be able to pass these arguments to Audio() (column ID corresponding in t... | null | {
"url": "https://api.github.com/repos/huggingface/datasets/issues/7310/reactions",
"total_count": 0,
"+1": 0,
"-1": 0,
"laugh": 0,
"hooray": 0,
"confused": 0,
"heart": 0,
"rocket": 0,
"eyes": 0
} | https://api.github.com/repos/huggingface/datasets/issues/7310/timeline | null | null | {"total":0,"completed":0,"percent_completed":0} | {"blocked_by":0,"total_blocked_by":0,"blocking":0,"total_blocking":0} | null | false |
https://api.github.com/repos/huggingface/datasets/issues/7315 | https://api.github.com/repos/huggingface/datasets | https://api.github.com/repos/huggingface/datasets/issues/7315/labels{/name} | https://api.github.com/repos/huggingface/datasets/issues/7315/comments | https://api.github.com/repos/huggingface/datasets/issues/7315/events | https://github.com/huggingface/datasets/issues/7315 | 2,729,738,963 | I_kwDODunzps6itILT | 7,315 | Allow manual configuration of Dataset Viewer for datasets not created with the `datasets` library | {
"login": "diarray-hub",
"id": 114512099,
"node_id": "U_kgDOBtNQ4w",
"avatar_url": "https://avatars.githubusercontent.com/u/114512099?v=4",
"gravatar_id": "",
"url": "https://api.github.com/users/diarray-hub",
"html_url": "https://github.com/diarray-hub",
"followers_url": "https://api.github.com/users/... | [] | open | false | [] | null | [
"Hi @diarray-hub , thanks for opening the issue :) Let me ping @lhoestq and @severo from the dataset viewer team :hugs: ",
"amazing :)",
"Hi ! why not modify the manifest.json file directly ? this way users see in the viewer the dataset as is instead which makes it easier to use using e.g. the `datasets` librar... | 2024-12-07 16:37:12 | 2024-12-11 11:05:22 | null | null | NONE | [] | null | null | null | null | #### **Problem Description**
Currently, the Hugging Face Dataset Viewer automatically interprets dataset fields for datasets created with the `datasets` library. However, for datasets pushed directly via `git`, the Viewer:
- Defaults to generic columns like `label` with `null` values if no explicit mapping is provide... | null | {
"url": "https://api.github.com/repos/huggingface/datasets/issues/7315/reactions",
"total_count": 0,
"+1": 0,
"-1": 0,
"laugh": 0,
"hooray": 0,
"confused": 0,
"heart": 0,
"rocket": 0,
"eyes": 0
} | https://api.github.com/repos/huggingface/datasets/issues/7315/timeline | null | null | {"total":0,"completed":0,"percent_completed":0} | {"blocked_by":0,"total_blocked_by":0,"blocking":0,"total_blocking":0} | null | false |
https://api.github.com/repos/huggingface/datasets/issues/7305 | https://api.github.com/repos/huggingface/datasets | https://api.github.com/repos/huggingface/datasets/issues/7305/labels{/name} | https://api.github.com/repos/huggingface/datasets/issues/7305/comments | https://api.github.com/repos/huggingface/datasets/issues/7305/events | https://github.com/huggingface/datasets/issues/7305 | 2,715,907,267 | I_kwDODunzps6h4XTD | 7,305 | Build Documentation Test Fails Due to "Bad Credentials" Error | {
"login": "ruidazeng",
"id": 31152346,
"node_id": "MDQ6VXNlcjMxMTUyMzQ2",
"avatar_url": "https://avatars.githubusercontent.com/u/31152346?v=4",
"gravatar_id": "",
"url": "https://api.github.com/users/ruidazeng",
"html_url": "https://github.com/ruidazeng",
"followers_url": "https://api.github.com/users/... | [] | open | false | [] | null | [
"how were you able to fix this please?",
"> how were you able to fix this please?\r\n\r\nI was not able to fix this."
] | 2024-12-03 20:22:54 | 2025-01-08 22:38:14 | null | null | CONTRIBUTOR | [] | null | null | null | null | ### Describe the bug
The `Build documentation / build / build_main_documentation (push)` job is consistently failing during the "Syncing repository" step. The error occurs when attempting to determine the default branch name, resulting in "Bad credentials" errors.
### Steps to reproduce the bug
1. Trigger the `build... | null | {
"url": "https://api.github.com/repos/huggingface/datasets/issues/7305/reactions",
"total_count": 0,
"+1": 0,
"-1": 0,
"laugh": 0,
"hooray": 0,
"confused": 0,
"heart": 0,
"rocket": 0,
"eyes": 0
} | https://api.github.com/repos/huggingface/datasets/issues/7305/timeline | null | null | {"total":0,"completed":0,"percent_completed":0} | {"blocked_by":0,"total_blocked_by":0,"blocking":0,"total_blocking":0} | null | false |
https://api.github.com/repos/huggingface/datasets/issues/7303 | https://api.github.com/repos/huggingface/datasets | https://api.github.com/repos/huggingface/datasets/issues/7303/labels{/name} | https://api.github.com/repos/huggingface/datasets/issues/7303/comments | https://api.github.com/repos/huggingface/datasets/issues/7303/events | https://github.com/huggingface/datasets/issues/7303 | 2,705,729,696 | I_kwDODunzps6hRiig | 7,303 | DataFilesNotFoundError for datasets LM1B | {
"login": "hml1996-fight",
"id": 72264324,
"node_id": "MDQ6VXNlcjcyMjY0MzI0",
"avatar_url": "https://avatars.githubusercontent.com/u/72264324?v=4",
"gravatar_id": "",
"url": "https://api.github.com/users/hml1996-fight",
"html_url": "https://github.com/hml1996-fight",
"followers_url": "https://api.githu... | [] | closed | false | [] | null | [
"Hi ! Can you try with a more recent version of `datasets` ? Also you might need to pass trust_remote_code=True since it's a script based dataset"
] | 2024-11-29 17:27:45 | 2024-12-11 13:22:47 | 2024-12-11 13:22:47 | null | NONE | [] | null | null | null | null | ### Describe the bug
Cannot load the dataset https://huggingface.co/datasets/billion-word-benchmark/lm1b
### Steps to reproduce the bug
`dataset = datasets.load_dataset('lm1b', split=split)`
### Expected behavior
`Traceback (most recent call last):
File "/home/hml/projects/DeepLearning/Generative_model/Diffusio... | {
"login": "hml1996-fight",
"id": 72264324,
"node_id": "MDQ6VXNlcjcyMjY0MzI0",
"avatar_url": "https://avatars.githubusercontent.com/u/72264324?v=4",
"gravatar_id": "",
"url": "https://api.github.com/users/hml1996-fight",
"html_url": "https://github.com/hml1996-fight",
"followers_url": "https://api.githu... | {
"url": "https://api.github.com/repos/huggingface/datasets/issues/7303/reactions",
"total_count": 0,
"+1": 0,
"-1": 0,
"laugh": 0,
"hooray": 0,
"confused": 0,
"heart": 0,
"rocket": 0,
"eyes": 0
} | https://api.github.com/repos/huggingface/datasets/issues/7303/timeline | null | completed | {"total":0,"completed":0,"percent_completed":0} | {"blocked_by":0,"total_blocked_by":0,"blocking":0,"total_blocking":0} | null | false |
https://api.github.com/repos/huggingface/datasets/issues/7297 | https://api.github.com/repos/huggingface/datasets | https://api.github.com/repos/huggingface/datasets/issues/7297/labels{/name} | https://api.github.com/repos/huggingface/datasets/issues/7297/comments | https://api.github.com/repos/huggingface/datasets/issues/7297/events | https://github.com/huggingface/datasets/issues/7297 | 2,683,977,430 | I_kwDODunzps6f-j7W | 7,297 | wrong return type for `IterableDataset.shard()` | {
"login": "ysngshn",
"id": 47225236,
"node_id": "MDQ6VXNlcjQ3MjI1MjM2",
"avatar_url": "https://avatars.githubusercontent.com/u/47225236?v=4",
"gravatar_id": "",
"url": "https://api.github.com/users/ysngshn",
"html_url": "https://github.com/ysngshn",
"followers_url": "https://api.github.com/users/ysngsh... | [] | closed | false | [] | null | [
"Oops my bad ! thanks for reporting"
] | 2024-11-22 17:25:46 | 2024-12-03 14:27:27 | 2024-12-03 14:27:03 | null | NONE | [] | null | null | null | null | ### Describe the bug
`IterableDataset.shard()` has the wrong typing for its return as `"Dataset"`. It should be `"IterableDataset"`. Makes my IDE unhappy.
### Steps to reproduce the bug
look at [the source code](https://github.com/huggingface/datasets/blob/main/src/datasets/iterable_dataset.py#L2668)?
### Expected ... | {
"login": "lhoestq",
"id": 42851186,
"node_id": "MDQ6VXNlcjQyODUxMTg2",
"avatar_url": "https://avatars.githubusercontent.com/u/42851186?v=4",
"gravatar_id": "",
"url": "https://api.github.com/users/lhoestq",
"html_url": "https://github.com/lhoestq",
"followers_url": "https://api.github.com/users/lhoest... | {
"url": "https://api.github.com/repos/huggingface/datasets/issues/7297/reactions",
"total_count": 0,
"+1": 0,
"-1": 0,
"laugh": 0,
"hooray": 0,
"confused": 0,
"heart": 0,
"rocket": 0,
"eyes": 0
} | https://api.github.com/repos/huggingface/datasets/issues/7297/timeline | null | completed | {"total":0,"completed":0,"percent_completed":0} | {"blocked_by":0,"total_blocked_by":0,"blocking":0,"total_blocking":0} | null | false |
https://api.github.com/repos/huggingface/datasets/issues/7292 | https://api.github.com/repos/huggingface/datasets | https://api.github.com/repos/huggingface/datasets/issues/7292/labels{/name} | https://api.github.com/repos/huggingface/datasets/issues/7292/comments | https://api.github.com/repos/huggingface/datasets/issues/7292/events | https://github.com/huggingface/datasets/issues/7292 | 2,664,250,855 | I_kwDODunzps6ezT3n | 7,292 | DataFilesNotFoundError for datasets `OpenMol/PubChemSFT` | {
"login": "xnuohz",
"id": 17878022,
"node_id": "MDQ6VXNlcjE3ODc4MDIy",
"avatar_url": "https://avatars.githubusercontent.com/u/17878022?v=4",
"gravatar_id": "",
"url": "https://api.github.com/users/xnuohz",
"html_url": "https://github.com/xnuohz",
"followers_url": "https://api.github.com/users/xnuohz/fo... | [] | closed | false | [] | null | [
"Hi ! If the dataset owner uses `push_to_hub()` instead of `save_to_disk()` and upload the local files it will fix the issue.\r\nRight now `datasets` sees the train/test/valid pickle files but they are not supported file formats.",
"Alternatively you can load the arrow file instead:\r\n\r\n```python\r\nfrom datas... | 2024-11-16 11:54:31 | 2024-11-19 00:53:00 | 2024-11-19 00:52:59 | null | NONE | [] | null | null | null | null | ### Describe the bug
Cannot load the dataset https://huggingface.co/datasets/OpenMol/PubChemSFT
### Steps to reproduce the bug
```
from datasets import load_dataset
dataset = load_dataset('OpenMol/PubChemSFT')
```
### Expected behavior
```
-----------------------------------------------------------------------... | {
"login": "xnuohz",
"id": 17878022,
"node_id": "MDQ6VXNlcjE3ODc4MDIy",
"avatar_url": "https://avatars.githubusercontent.com/u/17878022?v=4",
"gravatar_id": "",
"url": "https://api.github.com/users/xnuohz",
"html_url": "https://github.com/xnuohz",
"followers_url": "https://api.github.com/users/xnuohz/fo... | {
"url": "https://api.github.com/repos/huggingface/datasets/issues/7292/reactions",
"total_count": 0,
"+1": 0,
"-1": 0,
"laugh": 0,
"hooray": 0,
"confused": 0,
"heart": 0,
"rocket": 0,
"eyes": 0
} | https://api.github.com/repos/huggingface/datasets/issues/7292/timeline | null | completed | {"total":0,"completed":0,"percent_completed":0} | {"blocked_by":0,"total_blocked_by":0,"blocking":0,"total_blocking":0} | null | false |
https://api.github.com/repos/huggingface/datasets/issues/7291 | https://api.github.com/repos/huggingface/datasets | https://api.github.com/repos/huggingface/datasets/issues/7291/labels{/name} | https://api.github.com/repos/huggingface/datasets/issues/7291/comments | https://api.github.com/repos/huggingface/datasets/issues/7291/events | https://github.com/huggingface/datasets/issues/7291 | 2,662,244,643 | I_kwDODunzps6erqEj | 7,291 | Why return_tensors='pt' doesn't work? | {
"login": "bw-wang19",
"id": 86752851,
"node_id": "MDQ6VXNlcjg2NzUyODUx",
"avatar_url": "https://avatars.githubusercontent.com/u/86752851?v=4",
"gravatar_id": "",
"url": "https://api.github.com/users/bw-wang19",
"html_url": "https://github.com/bw-wang19",
"followers_url": "https://api.github.com/users/... | [] | open | false | [] | null | [
"Hi ! `datasets` uses Arrow as storage backend which is agnostic to deep learning frameworks like torch. If you want to get torch tensors back, you need to do `dataset = dataset.with_format(\"torch\")`",
"> Hi ! `datasets` uses Arrow as storage backend which is agnostic to deep learning frameworks like torch. If ... | 2024-11-15 15:01:23 | 2024-11-18 13:47:08 | null | null | NONE | [] | null | null | null | null | ### Describe the bug
I tried to add input_ids to dataset with map(), and I used the return_tensors='pt', but why I got the callback with the type of List?

### Steps to reproduce the bug
: 32%|███▏ | 47752224/147853764 [15:32:54<132:28:34, 209.89 examples/s]\r\nSaving the dataset (1540/4775 shards): 32%|███▏ | 47754224/14785... | 2024-11-14 05:25:13 | 2025-11-24 09:43:03 | null | null | NONE | [] | null | null | null | null | ### Describe the bug
Hi, I'm encountered a small issue when saving datasets that led to the saving taking up to multiple hours.
Specifically, [`Dataset.save_to_disk`](https://huggingface.co/docs/datasets/main/en/package_reference/main_classes#datasets.Dataset.save_to_disk) is a lot slower when using `num_proc>1` than... | null | {
"url": "https://api.github.com/repos/huggingface/datasets/issues/7290/reactions",
"total_count": 0,
"+1": 0,
"-1": 0,
"laugh": 0,
"hooray": 0,
"confused": 0,
"heart": 0,
"rocket": 0,
"eyes": 0
} | https://api.github.com/repos/huggingface/datasets/issues/7290/timeline | null | null | {"total":0,"completed":0,"percent_completed":0} | {"blocked_by":0,"total_blocked_by":0,"blocking":0,"total_blocking":0} | null | false |
https://api.github.com/repos/huggingface/datasets/issues/7289 | https://api.github.com/repos/huggingface/datasets | https://api.github.com/repos/huggingface/datasets/issues/7289/labels{/name} | https://api.github.com/repos/huggingface/datasets/issues/7289/comments | https://api.github.com/repos/huggingface/datasets/issues/7289/events | https://github.com/huggingface/datasets/issues/7289 | 2,648,019,507 | I_kwDODunzps6d1ZIz | 7,289 | Dataset viewer displays wrong statists | {
"login": "speedcell4",
"id": 3585459,
"node_id": "MDQ6VXNlcjM1ODU0NTk=",
"avatar_url": "https://avatars.githubusercontent.com/u/3585459?v=4",
"gravatar_id": "",
"url": "https://api.github.com/users/speedcell4",
"html_url": "https://github.com/speedcell4",
"followers_url": "https://api.github.com/users... | [] | closed | false | [] | null | [
"i think this issue is more for https://github.com/huggingface/dataset-viewer"
] | 2024-11-11 03:29:27 | 2024-11-13 13:02:25 | 2024-11-13 13:02:25 | null | NONE | [] | null | null | null | null | ### Describe the bug
In [my dataset](https://huggingface.co/datasets/speedcell4/opus-unigram2), there is a column called `lang2`, and there are 94 different classes in total, but the viewer says there are 83 values only. This issue only arises in the `train` split. The total number of values is also 94 in the `test`... | {
"login": "speedcell4",
"id": 3585459,
"node_id": "MDQ6VXNlcjM1ODU0NTk=",
"avatar_url": "https://avatars.githubusercontent.com/u/3585459?v=4",
"gravatar_id": "",
"url": "https://api.github.com/users/speedcell4",
"html_url": "https://github.com/speedcell4",
"followers_url": "https://api.github.com/users... | {
"url": "https://api.github.com/repos/huggingface/datasets/issues/7289/reactions",
"total_count": 0,
"+1": 0,
"-1": 0,
"laugh": 0,
"hooray": 0,
"confused": 0,
"heart": 0,
"rocket": 0,
"eyes": 0
} | https://api.github.com/repos/huggingface/datasets/issues/7289/timeline | null | completed | {"total":0,"completed":0,"percent_completed":0} | {"blocked_by":0,"total_blocked_by":0,"blocking":0,"total_blocking":0} | null | false |
https://api.github.com/repos/huggingface/datasets/issues/7287 | https://api.github.com/repos/huggingface/datasets | https://api.github.com/repos/huggingface/datasets/issues/7287/labels{/name} | https://api.github.com/repos/huggingface/datasets/issues/7287/comments | https://api.github.com/repos/huggingface/datasets/issues/7287/events | https://github.com/huggingface/datasets/issues/7287 | 2,646,958,393 | I_kwDODunzps6dxWE5 | 7,287 | Support for identifier-based automated split construction | {
"login": "alex-hh",
"id": 5719745,
"node_id": "MDQ6VXNlcjU3MTk3NDU=",
"avatar_url": "https://avatars.githubusercontent.com/u/5719745?v=4",
"gravatar_id": "",
"url": "https://api.github.com/users/alex-hh",
"html_url": "https://github.com/alex-hh",
"followers_url": "https://api.github.com/users/alex-hh/... | [
{
"id": 1935892871,
"node_id": "MDU6TGFiZWwxOTM1ODkyODcx",
"url": "https://api.github.com/repos/huggingface/datasets/labels/enhancement",
"name": "enhancement",
"color": "a2eeef",
"default": true,
"description": "New feature or request",
"archived_at": null,
"archived_by": null
... | open | false | [] | null | [
"Hi ! You can already configure the README.md to have multiple sets of splits, e.g.\r\n\r\n```yaml\r\nconfigs:\r\n- config_name: my_first_set_of_split\r\n data_files:\r\n - split: train\r\n path: *.csv\r\n- config_name: my_second_set_of_split\r\n data_files:\r\n - split: train\r\n path: train-*.csv\r\n -... | 2024-11-10 07:45:19 | 2024-11-19 14:37:02 | null | null | CONTRIBUTOR | [] | null | null | null | null | ### Feature request
As far as I understand, automated construction of splits for hub datasets is currently based on either file names or directory structure ([as described here](https://huggingface.co/docs/datasets/en/repository_structure))
It would seem to be pretty useful to also allow splits to be based on ide... | null | {
"url": "https://api.github.com/repos/huggingface/datasets/issues/7287/reactions",
"total_count": 0,
"+1": 0,
"-1": 0,
"laugh": 0,
"hooray": 0,
"confused": 0,
"heart": 0,
"rocket": 0,
"eyes": 0
} | https://api.github.com/repos/huggingface/datasets/issues/7287/timeline | null | null | {"total":0,"completed":0,"percent_completed":0} | {"blocked_by":0,"total_blocked_by":0,"blocking":0,"total_blocking":0} | null | false |
https://api.github.com/repos/huggingface/datasets/issues/7281 | https://api.github.com/repos/huggingface/datasets | https://api.github.com/repos/huggingface/datasets/issues/7281/labels{/name} | https://api.github.com/repos/huggingface/datasets/issues/7281/comments | https://api.github.com/repos/huggingface/datasets/issues/7281/events | https://github.com/huggingface/datasets/issues/7281 | 2,640,346,339 | I_kwDODunzps6dYHzj | 7,281 | File not found error | {
"login": "MichielBontenbal",
"id": 37507786,
"node_id": "MDQ6VXNlcjM3NTA3Nzg2",
"avatar_url": "https://avatars.githubusercontent.com/u/37507786?v=4",
"gravatar_id": "",
"url": "https://api.github.com/users/MichielBontenbal",
"html_url": "https://github.com/MichielBontenbal",
"followers_url": "https://... | [] | open | false | [] | null | [
"Link to the dataset: https://huggingface.co/datasets/MichielBontenbal/UrbanSounds "
] | 2024-11-07 09:04:49 | 2024-11-07 09:22:43 | null | null | NONE | [] | null | null | null | null | ### Describe the bug
I get a FileNotFoundError:
<img width="944" alt="image" src="https://github.com/user-attachments/assets/1336bc08-06f6-4682-a3c0-071ff65efa87">
### Steps to reproduce the bug
See screenshot.
### Expected behavior
I want to load one audiofile from the dataset.
### Environmen... | null | {
"url": "https://api.github.com/repos/huggingface/datasets/issues/7281/reactions",
"total_count": 0,
"+1": 0,
"-1": 0,
"laugh": 0,
"hooray": 0,
"confused": 0,
"heart": 0,
"rocket": 0,
"eyes": 0
} | https://api.github.com/repos/huggingface/datasets/issues/7281/timeline | null | null | {"total":0,"completed":0,"percent_completed":0} | {"blocked_by":0,"total_blocked_by":0,"blocking":0,"total_blocking":0} | null | false |
https://api.github.com/repos/huggingface/datasets/issues/7280 | https://api.github.com/repos/huggingface/datasets | https://api.github.com/repos/huggingface/datasets/issues/7280/labels{/name} | https://api.github.com/repos/huggingface/datasets/issues/7280/comments | https://api.github.com/repos/huggingface/datasets/issues/7280/events | https://github.com/huggingface/datasets/issues/7280 | 2,639,977,077 | I_kwDODunzps6dWtp1 | 7,280 | Add filename in error message when ReadError or similar occur | {
"login": "elisa-aleman",
"id": 37046039,
"node_id": "MDQ6VXNlcjM3MDQ2MDM5",
"avatar_url": "https://avatars.githubusercontent.com/u/37046039?v=4",
"gravatar_id": "",
"url": "https://api.github.com/users/elisa-aleman",
"html_url": "https://github.com/elisa-aleman",
"followers_url": "https://api.github.c... | [] | open | false | [] | null | [
"Hi Elisa, please share the error traceback here, and if you manage to find the location in the `datasets` code where the error occurs, feel free to open a PR to add the necessary logging / improve the error message.",
"> please share the error traceback\n\nI don't have access to it but it should be during [this ... | 2024-11-07 06:00:53 | 2026-07-22 12:52:39 | null | null | NONE | [] | null | null | null | null | Please update error messages to include relevant information for debugging when loading datasets with `load_dataset()` that may have a few corrupted files.
Whenever downloading a full dataset, some files might be corrupted (either at the source or from downloading corruption).
However the errors often only let me k... | null | {
"url": "https://api.github.com/repos/huggingface/datasets/issues/7280/reactions",
"total_count": 0,
"+1": 0,
"-1": 0,
"laugh": 0,
"hooray": 0,
"confused": 0,
"heart": 0,
"rocket": 0,
"eyes": 0
} | https://api.github.com/repos/huggingface/datasets/issues/7280/timeline | null | null | {"total":0,"completed":0,"percent_completed":0} | {"blocked_by":0,"total_blocked_by":0,"blocking":0,"total_blocking":0} | null | false |
https://api.github.com/repos/huggingface/datasets/issues/7276 | https://api.github.com/repos/huggingface/datasets | https://api.github.com/repos/huggingface/datasets/issues/7276/labels{/name} | https://api.github.com/repos/huggingface/datasets/issues/7276/comments | https://api.github.com/repos/huggingface/datasets/issues/7276/events | https://github.com/huggingface/datasets/issues/7276 | 2,631,917,431 | I_kwDODunzps6c3993 | 7,276 | Accessing audio dataset value throws Format not recognised error | {
"login": "fawazahmed0",
"id": 20347013,
"node_id": "MDQ6VXNlcjIwMzQ3MDEz",
"avatar_url": "https://avatars.githubusercontent.com/u/20347013?v=4",
"gravatar_id": "",
"url": "https://api.github.com/users/fawazahmed0",
"html_url": "https://github.com/fawazahmed0",
"followers_url": "https://api.github.com/... | [] | open | false | [] | null | [
"Hi ! can you try if this works ?\r\n\r\n```python\r\nimport soundfile as sf\r\n\r\nwith open('C:\\\\Users\\\\Nawaz-Server\\\\.cache\\\\huggingface\\\\hub\\\\datasets--fawazahmed0--bug-audio\\\\snapshots\\\\fab1398431fed1c0a2a7bff0945465bab8b5daef\\\\data\\\\Ghamadi\\\\037136.mp3', 'rb') as f:\r\n print(sf.read(... | 2024-11-04 05:59:13 | 2024-11-09 18:51:52 | null | null | NONE | [] | null | null | null | null | ### Describe the bug
Accessing audio dataset value throws `Format not recognised error`
### Steps to reproduce the bug
**code:**
```py
from datasets import load_dataset
dataset = load_dataset("fawazahmed0/bug-audio")
for data in dataset["train"]:
print(data)
```
**output:**
```bash
(mypy) ... | null | {
"url": "https://api.github.com/repos/huggingface/datasets/issues/7276/reactions",
"total_count": 0,
"+1": 0,
"-1": 0,
"laugh": 0,
"hooray": 0,
"confused": 0,
"heart": 0,
"rocket": 0,
"eyes": 0
} | https://api.github.com/repos/huggingface/datasets/issues/7276/timeline | null | null | {"total":0,"completed":0,"percent_completed":0} | {"blocked_by":0,"total_blocked_by":0,"blocking":0,"total_blocking":0} | null | false |
https://api.github.com/repos/huggingface/datasets/issues/7269 | https://api.github.com/repos/huggingface/datasets | https://api.github.com/repos/huggingface/datasets/issues/7269/labels{/name} | https://api.github.com/repos/huggingface/datasets/issues/7269/comments | https://api.github.com/repos/huggingface/datasets/issues/7269/events | https://github.com/huggingface/datasets/issues/7269 | 2,626,873,843 | I_kwDODunzps6ckunz | 7,269 | Memory leak when streaming | {
"login": "Jourdelune",
"id": 64205064,
"node_id": "MDQ6VXNlcjY0MjA1MDY0",
"avatar_url": "https://avatars.githubusercontent.com/u/64205064?v=4",
"gravatar_id": "",
"url": "https://api.github.com/users/Jourdelune",
"html_url": "https://github.com/Jourdelune",
"followers_url": "https://api.github.com/use... | [] | open | false | [] | null | [
"I seem to have encountered the same problem when loading non streaming datasets. load_from_disk. Causing hundreds of GB of memory, but the dataset actually only has 50GB",
"FYI when streaming parquet data, only one row group per worker is loaded in memory at a time.\r\n\r\nBtw for datasets of embeddings you can ... | 2024-10-31 13:33:52 | 2025-12-19 07:48:08 | null | null | NONE | [] | null | null | null | null | ### Describe the bug
I try to use a dataset with streaming=True, the issue I have is that the RAM usage becomes higher and higher until it is no longer sustainable.
I understand that huggingface store data in ram during the streaming, and more worker in dataloader there are, more a lot of shard will be stored in ... | null | {
"url": "https://api.github.com/repos/huggingface/datasets/issues/7269/reactions",
"total_count": 3,
"+1": 3,
"-1": 0,
"laugh": 0,
"hooray": 0,
"confused": 0,
"heart": 0,
"rocket": 0,
"eyes": 0
} | https://api.github.com/repos/huggingface/datasets/issues/7269/timeline | null | null | {"total":0,"completed":0,"percent_completed":0} | {"blocked_by":0,"total_blocked_by":0,"blocking":0,"total_blocking":0} | null | false |
https://api.github.com/repos/huggingface/datasets/issues/7268 | https://api.github.com/repos/huggingface/datasets | https://api.github.com/repos/huggingface/datasets/issues/7268/labels{/name} | https://api.github.com/repos/huggingface/datasets/issues/7268/comments | https://api.github.com/repos/huggingface/datasets/issues/7268/events | https://github.com/huggingface/datasets/issues/7268 | 2,626,664,687 | I_kwDODunzps6cj7jv | 7,268 | load_from_disk | {
"login": "ghaith-mq",
"id": 71670961,
"node_id": "MDQ6VXNlcjcxNjcwOTYx",
"avatar_url": "https://avatars.githubusercontent.com/u/71670961?v=4",
"gravatar_id": "",
"url": "https://api.github.com/users/ghaith-mq",
"html_url": "https://github.com/ghaith-mq",
"followers_url": "https://api.github.com/users/... | [] | open | false | [] | null | [
"Hello, It's an interesting issue here. I have the same problem, I have a local dataset and I want to push the dataset to the hub but huggingface does a copy of it.\r\n\r\n```py\r\nfrom datasets import load_dataset\r\n\r\ndataset = load_dataset(\"webdataset\", data_files=\"/media/works/data/*.tar\") # copy here\r\n... | 2024-10-31 11:51:56 | 2025-07-01 08:42:17 | null | null | NONE | [] | null | null | null | null | ### Describe the bug
I have data saved with save_to_disk. The data is big (700Gb). When I try loading it, the only option is load_from_disk, and this function copies the data to a tmp directory, causing me to run out of disk space. Is there an alternative solution to that?
### Steps to reproduce the bug
when trying ... | null | {
"url": "https://api.github.com/repos/huggingface/datasets/issues/7268/reactions",
"total_count": 0,
"+1": 0,
"-1": 0,
"laugh": 0,
"hooray": 0,
"confused": 0,
"heart": 0,
"rocket": 0,
"eyes": 0
} | https://api.github.com/repos/huggingface/datasets/issues/7268/timeline | null | null | {"total":0,"completed":0,"percent_completed":0} | {"blocked_by":0,"total_blocked_by":0,"blocking":0,"total_blocking":0} | null | false |
https://api.github.com/repos/huggingface/datasets/issues/7267 | https://api.github.com/repos/huggingface/datasets | https://api.github.com/repos/huggingface/datasets/issues/7267/labels{/name} | https://api.github.com/repos/huggingface/datasets/issues/7267/comments | https://api.github.com/repos/huggingface/datasets/issues/7267/events | https://github.com/huggingface/datasets/issues/7267 | 2,626,490,029 | I_kwDODunzps6cjQ6t | 7,267 | Source installation fails on Macintosh with python 3.10 | {
"login": "mayankagarwals",
"id": 39498938,
"node_id": "MDQ6VXNlcjM5NDk4OTM4",
"avatar_url": "https://avatars.githubusercontent.com/u/39498938?v=4",
"gravatar_id": "",
"url": "https://api.github.com/users/mayankagarwals",
"html_url": "https://github.com/mayankagarwals",
"followers_url": "https://api.gi... | [] | open | false | [] | null | [
"I encountered the same problem on M1, a workaround I did was to simply comment out the dependency:\r\n\r\n```python\r\n...\r\n \"zstandard\",\r\n \"polars[timezone]>=0.20.0\",\r\n # \"decord==0.6.0\",\r\n]\r\n```\r\n\r\nThis worked for me as the adjustments I did to the code do not use the dependency, but... | 2024-10-31 10:18:45 | 2024-11-04 22:18:06 | null | null | NONE | [] | null | null | null | null | ### Describe the bug
Hi,
Decord is a dev dependency not maintained since couple years.
It does not have an ARM package available rendering it uninstallable on non-intel based macs
Suggestion is to move to eva-decord (https://github.com/georgia-tech-db/eva-decord) which doesnt have this problem.
Happy to... | null | {
"url": "https://api.github.com/repos/huggingface/datasets/issues/7267/reactions",
"total_count": 0,
"+1": 0,
"-1": 0,
"laugh": 0,
"hooray": 0,
"confused": 0,
"heart": 0,
"rocket": 0,
"eyes": 0
} | https://api.github.com/repos/huggingface/datasets/issues/7267/timeline | null | null | {"total":0,"completed":0,"percent_completed":0} | {"blocked_by":0,"total_blocked_by":0,"blocking":0,"total_blocking":0} | null | false |
https://api.github.com/repos/huggingface/datasets/issues/7266 | https://api.github.com/repos/huggingface/datasets | https://api.github.com/repos/huggingface/datasets/issues/7266/labels{/name} | https://api.github.com/repos/huggingface/datasets/issues/7266/comments | https://api.github.com/repos/huggingface/datasets/issues/7266/events | https://github.com/huggingface/datasets/issues/7266 | 2,624,666,087 | I_kwDODunzps6ccTnn | 7,266 | The dataset viewer should be available soon. Please retry later. | {
"login": "viiika",
"id": 39821659,
"node_id": "MDQ6VXNlcjM5ODIxNjU5",
"avatar_url": "https://avatars.githubusercontent.com/u/39821659?v=4",
"gravatar_id": "",
"url": "https://api.github.com/users/viiika",
"html_url": "https://github.com/viiika",
"followers_url": "https://api.github.com/users/viiika/fo... | [] | closed | false | [] | null | [
"Waiting is all you need. 10 hours later, it works."
] | 2024-10-30 16:32:00 | 2024-10-31 03:48:11 | 2024-10-31 03:48:10 | null | NONE | [] | null | null | null | null | ### Describe the bug
After waiting for 2 hours, it still presents ``The dataset viewer should be available soon. Please retry later.''
### Steps to reproduce the bug
dataset link: https://huggingface.co/datasets/BryanW/HI_EDIT
### Expected behavior
Present the dataset viewer.
### Environment info
NA | {
"login": "viiika",
"id": 39821659,
"node_id": "MDQ6VXNlcjM5ODIxNjU5",
"avatar_url": "https://avatars.githubusercontent.com/u/39821659?v=4",
"gravatar_id": "",
"url": "https://api.github.com/users/viiika",
"html_url": "https://github.com/viiika",
"followers_url": "https://api.github.com/users/viiika/fo... | {
"url": "https://api.github.com/repos/huggingface/datasets/issues/7266/reactions",
"total_count": 0,
"+1": 0,
"-1": 0,
"laugh": 0,
"hooray": 0,
"confused": 0,
"heart": 0,
"rocket": 0,
"eyes": 0
} | https://api.github.com/repos/huggingface/datasets/issues/7266/timeline | null | completed | {"total":0,"completed":0,"percent_completed":0} | {"blocked_by":0,"total_blocked_by":0,"blocking":0,"total_blocking":0} | null | false |
https://api.github.com/repos/huggingface/datasets/issues/7261 | https://api.github.com/repos/huggingface/datasets | https://api.github.com/repos/huggingface/datasets/issues/7261/labels{/name} | https://api.github.com/repos/huggingface/datasets/issues/7261/comments | https://api.github.com/repos/huggingface/datasets/issues/7261/events | https://github.com/huggingface/datasets/issues/7261 | 2,620,510,840 | I_kwDODunzps6cMdJ4 | 7,261 | Cannot load the cache when mapping the dataset | {
"login": "zhangn77",
"id": 43033959,
"node_id": "MDQ6VXNlcjQzMDMzOTU5",
"avatar_url": "https://avatars.githubusercontent.com/u/43033959?v=4",
"gravatar_id": "",
"url": "https://api.github.com/users/zhangn77",
"html_url": "https://github.com/zhangn77",
"followers_url": "https://api.github.com/users/zha... | [] | open | false | [] | null | [
"@zhangn77 Hi ,have you solved this problem? I encountered the same issue during training. Could we discuss it?",
"I also encountered the same problem, why is that?"
] | 2024-10-29 08:29:40 | 2025-03-24 13:27:55 | null | null | NONE | [] | null | null | null | null | ### Describe the bug
I'm training the flux controlnet. The train_dataset.map() takes long time to finish. However, when I killed one training process and want to restart a new training with the same dataset. I can't reuse the mapped result even I defined the cache dir for the dataset.
with accelerator.main_process_... | null | {
"url": "https://api.github.com/repos/huggingface/datasets/issues/7261/reactions",
"total_count": 0,
"+1": 0,
"-1": 0,
"laugh": 0,
"hooray": 0,
"confused": 0,
"heart": 0,
"rocket": 0,
"eyes": 0
} | https://api.github.com/repos/huggingface/datasets/issues/7261/timeline | null | null | {"total":0,"completed":0,"percent_completed":0} | {"blocked_by":0,"total_blocked_by":0,"blocking":0,"total_blocking":0} | null | false |
https://api.github.com/repos/huggingface/datasets/issues/7260 | https://api.github.com/repos/huggingface/datasets | https://api.github.com/repos/huggingface/datasets/issues/7260/labels{/name} | https://api.github.com/repos/huggingface/datasets/issues/7260/comments | https://api.github.com/repos/huggingface/datasets/issues/7260/events | https://github.com/huggingface/datasets/issues/7260 | 2,620,014,285 | I_kwDODunzps6cKj7N | 7,260 | cache can't cleaned or disabled | {
"login": "charliedream1",
"id": 15007828,
"node_id": "MDQ6VXNlcjE1MDA3ODI4",
"avatar_url": "https://avatars.githubusercontent.com/u/15007828?v=4",
"gravatar_id": "",
"url": "https://api.github.com/users/charliedream1",
"html_url": "https://github.com/charliedream1",
"followers_url": "https://api.githu... | [] | open | false | [] | null | [
"Hey I have a similar problem and found a workaround using [temporary directories](https://docs.python.org/3/library/tempfile.html):\r\n\r\n```python\r\nfrom tempfile import TemporaryDirectory\r\n\r\nwith TemporaryDirectory() as cache_dir:\r\n data = load_dataset('json', data_files=save_local_path, split='train'... | 2024-10-29 03:15:28 | 2024-12-11 09:04:52 | null | null | NONE | [] | null | null | null | null | ### Describe the bug
I tried following ways, the cache can't be disabled.
I got 2T data, but I also got more than 2T cache file. I got pressure on storage. I need to diable cache or cleaned immediately after processed. Following ways are all not working, please give some help!
```python
from datasets import ... | null | {
"url": "https://api.github.com/repos/huggingface/datasets/issues/7260/reactions",
"total_count": 2,
"+1": 2,
"-1": 0,
"laugh": 0,
"hooray": 0,
"confused": 0,
"heart": 0,
"rocket": 0,
"eyes": 0
} | https://api.github.com/repos/huggingface/datasets/issues/7260/timeline | null | null | {"total":0,"completed":0,"percent_completed":0} | {"blocked_by":0,"total_blocked_by":0,"blocking":0,"total_blocking":0} | null | false |
https://api.github.com/repos/huggingface/datasets/issues/7254 | https://api.github.com/repos/huggingface/datasets | https://api.github.com/repos/huggingface/datasets/issues/7254/labels{/name} | https://api.github.com/repos/huggingface/datasets/issues/7254/comments | https://api.github.com/repos/huggingface/datasets/issues/7254/events | https://github.com/huggingface/datasets/issues/7254 | 2,616,174,996 | I_kwDODunzps6b76mU | 7,254 | mismatch for datatypes when providing `Features` with `Array2D` and user specified `dtype` and using with_format("numpy") | {
"login": "Akhil-CM",
"id": 97193607,
"node_id": "U_kgDOBcsOhw",
"avatar_url": "https://avatars.githubusercontent.com/u/97193607?v=4",
"gravatar_id": "",
"url": "https://api.github.com/users/Akhil-CM",
"html_url": "https://github.com/Akhil-CM",
"followers_url": "https://api.github.com/users/Akhil-CM/fo... | [] | open | false | [] | null | [
"It seems that https://github.com/huggingface/datasets/issues/5517 is exactly the same issue.\r\n\r\nIt was mentioned there that this would be fixed in version 3.x"
] | 2024-10-26 22:06:27 | 2024-10-26 22:07:37 | null | null | NONE | [] | null | null | null | null | ### Describe the bug
If the user provides a `Features` type value to `datasets.Dataset` with members having `Array2D` with a value for `dtype`, it is not respected during `with_format("numpy")` which should return a `np.array` with `dtype` that the user provided for `Array2D`. It seems for floats, it will be set to `f... | null | {
"url": "https://api.github.com/repos/huggingface/datasets/issues/7254/reactions",
"total_count": 0,
"+1": 0,
"-1": 0,
"laugh": 0,
"hooray": 0,
"confused": 0,
"heart": 0,
"rocket": 0,
"eyes": 0
} | https://api.github.com/repos/huggingface/datasets/issues/7254/timeline | null | null | {"total":0,"completed":0,"percent_completed":0} | {"blocked_by":0,"total_blocked_by":0,"blocking":0,"total_blocking":0} | null | false |
https://api.github.com/repos/huggingface/datasets/issues/7248 | https://api.github.com/repos/huggingface/datasets | https://api.github.com/repos/huggingface/datasets/issues/7248/labels{/name} | https://api.github.com/repos/huggingface/datasets/issues/7248/comments | https://api.github.com/repos/huggingface/datasets/issues/7248/events | https://github.com/huggingface/datasets/issues/7248 | 2,609,926,089 | I_kwDODunzps6bkE_J | 7,248 | ModuleNotFoundError: No module named 'datasets.tasks' | {
"login": "shoowadoo",
"id": 93593941,
"node_id": "U_kgDOBZQhVQ",
"avatar_url": "https://avatars.githubusercontent.com/u/93593941?v=4",
"gravatar_id": "",
"url": "https://api.github.com/users/shoowadoo",
"html_url": "https://github.com/shoowadoo",
"followers_url": "https://api.github.com/users/shoowado... | [] | open | false | [] | null | [
"tasks was removed in v3: #6999 \r\n\r\nI also don't see why TextClassification is imported, since it's not used after. So the fix is simple: delete this line.",
"I opened https://huggingface.co/datasets/knowledgator/events_classification_biotech/discussions/7 to remove the line, hopefully the dataset owner will ... | 2024-10-23 21:58:25 | 2024-10-24 17:00:19 | null | null | NONE | [] | null | null | null | null | ### Describe the bug
---------------------------------------------------------------------------
ModuleNotFoundError Traceback (most recent call last)
[<ipython-input-9-13b5f31bd391>](https://bcb6shpazyu-496ff2e9c6d22116-0-colab.googleusercontent.com/outputframe.html?vrz=colab_20241022-060119_R... | null | {
"url": "https://api.github.com/repos/huggingface/datasets/issues/7248/reactions",
"total_count": 1,
"+1": 1,
"-1": 0,
"laugh": 0,
"hooray": 0,
"confused": 0,
"heart": 0,
"rocket": 0,
"eyes": 0
} | https://api.github.com/repos/huggingface/datasets/issues/7248/timeline | null | null | {"total":0,"completed":0,"percent_completed":0} | {"blocked_by":0,"total_blocked_by":0,"blocking":0,"total_blocking":0} | null | false |
https://api.github.com/repos/huggingface/datasets/issues/7243 | https://api.github.com/repos/huggingface/datasets | https://api.github.com/repos/huggingface/datasets/issues/7243/labels{/name} | https://api.github.com/repos/huggingface/datasets/issues/7243/comments | https://api.github.com/repos/huggingface/datasets/issues/7243/events | https://github.com/huggingface/datasets/issues/7243 | 2,602,853,172 | I_kwDODunzps6bJGM0 | 7,243 | ArrayXD with None as leading dim incompatible with DatasetCardData | {
"login": "alex-hh",
"id": 5719745,
"node_id": "MDQ6VXNlcjU3MTk3NDU=",
"avatar_url": "https://avatars.githubusercontent.com/u/5719745?v=4",
"gravatar_id": "",
"url": "https://api.github.com/users/alex-hh",
"html_url": "https://github.com/alex-hh",
"followers_url": "https://api.github.com/users/alex-hh/... | [] | open | false | [] | null | [
"It looks like `CardData` in `huggingface_hub` removes None values where it shouldn't. Indeed it calls `_remove_none` on the return of `to_dict()`:\r\n\r\n```python\r\n def to_dict(self) -> Dict[str, Any]:\r\n \"\"\"Converts CardData to a dict.\r\n\r\n Returns:\r\n `dict`: CardData repre... | 2024-10-21 15:08:13 | 2024-10-22 14:18:10 | null | null | CONTRIBUTOR | [] | null | null | null | null | ### Describe the bug
Creating a dataset with ArrayXD features leads to errors when downloading from hub due to DatasetCardData removing the Nones
@lhoestq
### Steps to reproduce the bug
```python
import numpy as np
from datasets import Array2D, Dataset, Features, load_dataset
def examples_generator():... | null | {
"url": "https://api.github.com/repos/huggingface/datasets/issues/7243/reactions",
"total_count": 1,
"+1": 0,
"-1": 0,
"laugh": 0,
"hooray": 0,
"confused": 0,
"heart": 1,
"rocket": 0,
"eyes": 0
} | https://api.github.com/repos/huggingface/datasets/issues/7243/timeline | null | null | {"total":0,"completed":0,"percent_completed":0} | {"blocked_by":0,"total_blocked_by":0,"blocking":0,"total_blocking":0} | null | false |
https://api.github.com/repos/huggingface/datasets/issues/7241 | https://api.github.com/repos/huggingface/datasets | https://api.github.com/repos/huggingface/datasets/issues/7241/labels{/name} | https://api.github.com/repos/huggingface/datasets/issues/7241/comments | https://api.github.com/repos/huggingface/datasets/issues/7241/events | https://github.com/huggingface/datasets/issues/7241 | 2,599,899,156 | I_kwDODunzps6a91AU | 7,241 | `push_to_hub` overwrite argument | {
"login": "ceferisbarov",
"id": 60838378,
"node_id": "MDQ6VXNlcjYwODM4Mzc4",
"avatar_url": "https://avatars.githubusercontent.com/u/60838378?v=4",
"gravatar_id": "",
"url": "https://api.github.com/users/ceferisbarov",
"html_url": "https://github.com/ceferisbarov",
"followers_url": "https://api.github.c... | [
{
"id": 1935892871,
"node_id": "MDU6TGFiZWwxOTM1ODkyODcx",
"url": "https://api.github.com/repos/huggingface/datasets/labels/enhancement",
"name": "enhancement",
"color": "a2eeef",
"default": true,
"description": "New feature or request",
"archived_at": null,
"archived_by": null
... | closed | false | [] | null | [
"Hi ! Do you mean deleting all the files ? or erasing the repository git history before push_to_hub ?",
"Hi! I meant the latter.",
"I don't think there is a `huggingface_hub` utility to erase the git history, cc @Wauplin maybe ?",
"What is the goal exactly of deleting all the git history without deleting the ... | 2024-10-20 03:23:26 | 2024-10-24 17:39:08 | 2024-10-24 17:39:08 | null | NONE | [] | null | null | null | null | ### Feature request
Add an `overwrite` argument to the `push_to_hub` method.
### Motivation
I want to overwrite a repo without deleting it on Hugging Face. Is this possible? I couldn't find anything in the documentation or tutorials.
### Your contribution
I can create a PR. | {
"login": "ceferisbarov",
"id": 60838378,
"node_id": "MDQ6VXNlcjYwODM4Mzc4",
"avatar_url": "https://avatars.githubusercontent.com/u/60838378?v=4",
"gravatar_id": "",
"url": "https://api.github.com/users/ceferisbarov",
"html_url": "https://github.com/ceferisbarov",
"followers_url": "https://api.github.c... | {
"url": "https://api.github.com/repos/huggingface/datasets/issues/7241/reactions",
"total_count": 0,
"+1": 0,
"-1": 0,
"laugh": 0,
"hooray": 0,
"confused": 0,
"heart": 0,
"rocket": 0,
"eyes": 0
} | https://api.github.com/repos/huggingface/datasets/issues/7241/timeline | null | completed | {"total":0,"completed":0,"percent_completed":0} | {"blocked_by":0,"total_blocked_by":0,"blocking":0,"total_blocking":0} | null | false |
https://api.github.com/repos/huggingface/datasets/issues/7238 | https://api.github.com/repos/huggingface/datasets | https://api.github.com/repos/huggingface/datasets/issues/7238/labels{/name} | https://api.github.com/repos/huggingface/datasets/issues/7238/comments | https://api.github.com/repos/huggingface/datasets/issues/7238/events | https://github.com/huggingface/datasets/issues/7238 | 2,598,409,993 | I_kwDODunzps6a4JcJ | 7,238 | incompatibily issue when using load_dataset with datasets==3.0.1 | {
"login": "jupiterMJM",
"id": 74985234,
"node_id": "MDQ6VXNlcjc0OTg1MjM0",
"avatar_url": "https://avatars.githubusercontent.com/u/74985234?v=4",
"gravatar_id": "",
"url": "https://api.github.com/users/jupiterMJM",
"html_url": "https://github.com/jupiterMJM",
"followers_url": "https://api.github.com/use... | [] | open | false | [] | null | [
"Hi! I'm also getting the same issue - have you been able to find a solution to this? ",
"From what I remember, I stayed at the \"downgraded\" version of dataset (2.21.0)"
] | 2024-10-18 21:25:23 | 2024-12-09 09:49:32 | null | null | NONE | [] | null | null | null | null | ### Describe the bug
There is a bug when using load_dataset with dataset version at 3.0.1 .
Please see below in the "steps to reproduce the bug".
To resolve the bug, I had to downgrade to version 2.21.0
OS: Ubuntu 24 (AWS instance)
Python: same bug under 3.12 and 3.10
The error I had was:
Traceback (most rec... | null | {
"url": "https://api.github.com/repos/huggingface/datasets/issues/7238/reactions",
"total_count": 0,
"+1": 0,
"-1": 0,
"laugh": 0,
"hooray": 0,
"confused": 0,
"heart": 0,
"rocket": 0,
"eyes": 0
} | https://api.github.com/repos/huggingface/datasets/issues/7238/timeline | null | null | {"total":0,"completed":0,"percent_completed":0} | {"blocked_by":0,"total_blocked_by":0,"blocking":0,"total_blocking":0} | null | false |
https://api.github.com/repos/huggingface/datasets/issues/7222 | https://api.github.com/repos/huggingface/datasets | https://api.github.com/repos/huggingface/datasets/issues/7222/labels{/name} | https://api.github.com/repos/huggingface/datasets/issues/7222/comments | https://api.github.com/repos/huggingface/datasets/issues/7222/events | https://github.com/huggingface/datasets/issues/7222 | 2,582,678,033 | I_kwDODunzps6Z8IoR | 7,222 | TypeError: Couldn't cast array of type string to null in long json | {
"login": "nokados",
"id": 5142577,
"node_id": "MDQ6VXNlcjUxNDI1Nzc=",
"avatar_url": "https://avatars.githubusercontent.com/u/5142577?v=4",
"gravatar_id": "",
"url": "https://api.github.com/users/nokados",
"html_url": "https://github.com/nokados",
"followers_url": "https://api.github.com/users/nokados/... | [] | open | false | [] | null | [
"I am encountering this same issue. It seems that the library manages to recognise an optional column (but not **exclusively** null) if there is at least one non-null instance within the same file. For example, given a `test_0.jsonl` file:\r\n```json\r\n{\"a\": \"a1\", \"b\": \"b1\", \"c\": null, \"d\": null}\r\n{\... | 2024-10-12 08:14:59 | 2025-09-26 11:54:48 | null | null | NONE | [] | null | null | null | null | ### Describe the bug
In general, changing the type from string to null is allowed within a dataset — there are even examples of this in the documentation.
However, if the dataset is large and unevenly distributed, this allowance stops working. The schema gets locked in after reading a chunk.
Consequently, if al... | null | {
"url": "https://api.github.com/repos/huggingface/datasets/issues/7222/reactions",
"total_count": 0,
"+1": 0,
"-1": 0,
"laugh": 0,
"hooray": 0,
"confused": 0,
"heart": 0,
"rocket": 0,
"eyes": 0
} | https://api.github.com/repos/huggingface/datasets/issues/7222/timeline | null | null | {"total":0,"completed":0,"percent_completed":0} | {"blocked_by":0,"total_blocked_by":0,"blocking":0,"total_blocking":0} | null | false |
https://api.github.com/repos/huggingface/datasets/issues/7220 | https://api.github.com/repos/huggingface/datasets | https://api.github.com/repos/huggingface/datasets/issues/7220/labels{/name} | https://api.github.com/repos/huggingface/datasets/issues/7220/comments | https://api.github.com/repos/huggingface/datasets/issues/7220/events | https://github.com/huggingface/datasets/issues/7220 | 2,582,036,110 | I_kwDODunzps6Z5r6O | 7,220 | Custom features not compatible with special encoding/decoding logic | {
"login": "alex-hh",
"id": 5719745,
"node_id": "MDQ6VXNlcjU3MTk3NDU=",
"avatar_url": "https://avatars.githubusercontent.com/u/5719745?v=4",
"gravatar_id": "",
"url": "https://api.github.com/users/alex-hh",
"html_url": "https://github.com/alex-hh",
"followers_url": "https://api.github.com/users/alex-hh/... | [] | open | false | [] | null | [
"I think you can fix this simply by replacing the line with hardcoded features with `hastattr(schema, \"encode_example\")` actually",
"#7284 "
] | 2024-10-11 19:20:11 | 2024-11-08 15:10:58 | null | null | CONTRIBUTOR | [] | null | null | null | null | ### Describe the bug
It is possible to register custom features using datasets.features.features.register_feature (https://github.com/huggingface/datasets/pull/6727)
However such features are not compatible with Features.encode_example/decode_example if they require special encoding / decoding logic because encod... | null | {
"url": "https://api.github.com/repos/huggingface/datasets/issues/7220/reactions",
"total_count": 0,
"+1": 0,
"-1": 0,
"laugh": 0,
"hooray": 0,
"confused": 0,
"heart": 0,
"rocket": 0,
"eyes": 0
} | https://api.github.com/repos/huggingface/datasets/issues/7220/timeline | null | null | {"total":0,"completed":0,"percent_completed":0} | {"blocked_by":0,"total_blocked_by":0,"blocking":0,"total_blocking":0} | null | false |
https://api.github.com/repos/huggingface/datasets/issues/7217 | https://api.github.com/repos/huggingface/datasets | https://api.github.com/repos/huggingface/datasets/issues/7217/labels{/name} | https://api.github.com/repos/huggingface/datasets/issues/7217/comments | https://api.github.com/repos/huggingface/datasets/issues/7217/events | https://github.com/huggingface/datasets/issues/7217 | 2,581,095,098 | I_kwDODunzps6Z2GK6 | 7,217 | ds.map(f, num_proc=10) is slower than df.apply | {
"login": "lanlanlanlanlanlan365",
"id": 178981231,
"node_id": "U_kgDOCqsJbw",
"avatar_url": "https://avatars.githubusercontent.com/u/178981231?v=4",
"gravatar_id": "",
"url": "https://api.github.com/users/lanlanlanlanlanlan365",
"html_url": "https://github.com/lanlanlanlanlanlan365",
"followers_url": ... | [] | open | false | [] | null | [
"Hi ! `map()` reads all the columns and writes the resulting dataset with all the columns as well, while df.column_name.apply only reads and writes one column and does it in memory. So this is speed difference is actually expected.\r\n\r\nMoreover using multiprocessing on a dataset that lives in memory (from_pandas... | 2024-10-11 11:04:05 | 2025-02-28 21:21:01 | null | null | NONE | [] | null | null | null | null | ### Describe the bug
pandas columns: song_id, song_name
ds = Dataset.from_pandas(df)
def has_cover(song_name):
if song_name is None or pd.isna(song_name):
return False
return 'cover' in song_name.lower()
df['has_cover'] = df.song_name.progress_apply(has_cover)
ds = ds.map(lambda x: {'has_cov... | null | {
"url": "https://api.github.com/repos/huggingface/datasets/issues/7217/reactions",
"total_count": 0,
"+1": 0,
"-1": 0,
"laugh": 0,
"hooray": 0,
"confused": 0,
"heart": 0,
"rocket": 0,
"eyes": 0
} | https://api.github.com/repos/huggingface/datasets/issues/7217/timeline | null | null | {"total":0,"completed":0,"percent_completed":0} | {"blocked_by":0,"total_blocked_by":0,"blocking":0,"total_blocking":0} | null | false |
https://api.github.com/repos/huggingface/datasets/issues/7214 | https://api.github.com/repos/huggingface/datasets | https://api.github.com/repos/huggingface/datasets/issues/7214/labels{/name} | https://api.github.com/repos/huggingface/datasets/issues/7214/comments | https://api.github.com/repos/huggingface/datasets/issues/7214/events | https://github.com/huggingface/datasets/issues/7214 | 2,578,743,713 | I_kwDODunzps6ZtIGh | 7,214 | Formatted map + with_format(None) changes array dtype for iterable datasets | {
"login": "alex-hh",
"id": 5719745,
"node_id": "MDQ6VXNlcjU3MTk3NDU=",
"avatar_url": "https://avatars.githubusercontent.com/u/5719745?v=4",
"gravatar_id": "",
"url": "https://api.github.com/users/alex-hh",
"html_url": "https://github.com/alex-hh",
"followers_url": "https://api.github.com/users/alex-hh/... | [] | open | false | [] | null | [
"possibly due to this logic:\r\n\r\n```python\r\n def _arrow_array_to_numpy(self, pa_array: pa.Array) -> np.ndarray:\r\n if isinstance(pa_array, pa.ChunkedArray):\r\n if isinstance(pa_array.type, _ArrayXDExtensionType):\r\n # don't call to_pylist() to preserve dtype of the fixed-... | 2024-10-10 12:45:16 | 2024-10-12 16:55:57 | null | null | CONTRIBUTOR | [] | null | null | null | null | ### Describe the bug
When applying with_format -> map -> with_format(None), array dtypes seem to change, even if features are passed
### Steps to reproduce the bug
```python
features=Features(**{"array0": Array3D((None, 10, 10), dtype="float32")})
dataset = Dataset.from_dict({f"array0": [np.zeros((100,10,10... | null | {
"url": "https://api.github.com/repos/huggingface/datasets/issues/7214/reactions",
"total_count": 0,
"+1": 0,
"-1": 0,
"laugh": 0,
"hooray": 0,
"confused": 0,
"heart": 0,
"rocket": 0,
"eyes": 0
} | https://api.github.com/repos/huggingface/datasets/issues/7214/timeline | null | null | {"total":0,"completed":0,"percent_completed":0} | {"blocked_by":0,"total_blocked_by":0,"blocking":0,"total_blocking":0} | null | false |
https://api.github.com/repos/huggingface/datasets/issues/7208 | https://api.github.com/repos/huggingface/datasets | https://api.github.com/repos/huggingface/datasets/issues/7208/labels{/name} | https://api.github.com/repos/huggingface/datasets/issues/7208/comments | https://api.github.com/repos/huggingface/datasets/issues/7208/events | https://github.com/huggingface/datasets/issues/7208 | 2,575,484,256 | I_kwDODunzps6ZgsVg | 7,208 | Iterable dataset.filter should not override features | {
"login": "alex-hh",
"id": 5719745,
"node_id": "MDQ6VXNlcjU3MTk3NDU=",
"avatar_url": "https://avatars.githubusercontent.com/u/5719745?v=4",
"gravatar_id": "",
"url": "https://api.github.com/users/alex-hh",
"html_url": "https://github.com/alex-hh",
"followers_url": "https://api.github.com/users/alex-hh/... | [] | closed | false | [] | null | [
"closed by https://github.com/huggingface/datasets/pull/7209, thanks @alex-hh !"
] | 2024-10-09 10:23:45 | 2024-10-09 16:08:46 | 2024-10-09 16:08:45 | null | CONTRIBUTOR | [] | null | null | null | null | ### Describe the bug
When calling filter on an iterable dataset, the features get set to None
### Steps to reproduce the bug
import numpy as np
import time
from datasets import Dataset, Features, Array3D
```python
features=Features(**{"array0": Array3D((None, 10, 10), dtype="float32"), "array1": Array3D((None,... | {
"login": "lhoestq",
"id": 42851186,
"node_id": "MDQ6VXNlcjQyODUxMTg2",
"avatar_url": "https://avatars.githubusercontent.com/u/42851186?v=4",
"gravatar_id": "",
"url": "https://api.github.com/users/lhoestq",
"html_url": "https://github.com/lhoestq",
"followers_url": "https://api.github.com/users/lhoest... | {
"url": "https://api.github.com/repos/huggingface/datasets/issues/7208/reactions",
"total_count": 0,
"+1": 0,
"-1": 0,
"laugh": 0,
"hooray": 0,
"confused": 0,
"heart": 0,
"rocket": 0,
"eyes": 0
} | https://api.github.com/repos/huggingface/datasets/issues/7208/timeline | null | completed | {"total":0,"completed":0,"percent_completed":0} | {"blocked_by":0,"total_blocked_by":0,"blocking":0,"total_blocking":0} | null | false |
https://api.github.com/repos/huggingface/datasets/issues/7206 | https://api.github.com/repos/huggingface/datasets | https://api.github.com/repos/huggingface/datasets/issues/7206/labels{/name} | https://api.github.com/repos/huggingface/datasets/issues/7206/comments | https://api.github.com/repos/huggingface/datasets/issues/7206/events | https://github.com/huggingface/datasets/issues/7206 | 2,573,567,467 | I_kwDODunzps6ZZYXr | 7,206 | Slow iteration for iterable dataset with numpy formatting for array data | {
"login": "alex-hh",
"id": 5719745,
"node_id": "MDQ6VXNlcjU3MTk3NDU=",
"avatar_url": "https://avatars.githubusercontent.com/u/5719745?v=4",
"gravatar_id": "",
"url": "https://api.github.com/users/alex-hh",
"html_url": "https://github.com/alex-hh",
"followers_url": "https://api.github.com/users/alex-hh/... | [] | open | false | [] | null | [
"The below easily eats up 32G of RAM. Leaving it for a while bricked the laptop with 16GB.\r\n\r\n```\r\ndataset = load_dataset(\"Voxel51/OxfordFlowers102\", data_dir=\"data\").with_format(\"numpy\")\r\nprocessed_dataset = dataset.map(lambda x: x)\r\n```\r\n\r\n` of images from a single directory where `train.png` image exists | {
"login": "SagiPolaczek",
"id": 56922146,
"node_id": "MDQ6VXNlcjU2OTIyMTQ2",
"avatar_url": "https://avatars.githubusercontent.com/u/56922146?v=4",
"gravatar_id": "",
"url": "https://api.github.com/users/SagiPolaczek",
"html_url": "https://github.com/SagiPolaczek",
"followers_url": "https://api.github.c... | [] | open | false | [] | null | [
"#self-assign",
"#self-assign"
] | 2024-10-07 09:14:17 | 2026-06-10 01:14:37 | null | null | NONE | [] | null | null | null | null | ### Describe the bug
Hey!
Firstly, thanks for maintaining such framework!
I had a small issue, where I wanted to load a custom dataset of image+text captioning. I had all of my images in a single directory, and one of the images had the name `train.png`. Then, the loaded dataset had only this image.
I guess it'... | null | {
"url": "https://api.github.com/repos/huggingface/datasets/issues/7201/reactions",
"total_count": 0,
"+1": 0,
"-1": 0,
"laugh": 0,
"hooray": 0,
"confused": 0,
"heart": 0,
"rocket": 0,
"eyes": 0
} | https://api.github.com/repos/huggingface/datasets/issues/7201/timeline | null | null | {"total":0,"completed":0,"percent_completed":0} | {"blocked_by":0,"total_blocked_by":0,"blocking":0,"total_blocking":0} | null | false |
https://api.github.com/repos/huggingface/datasets/issues/7197 | https://api.github.com/repos/huggingface/datasets | https://api.github.com/repos/huggingface/datasets/issues/7197/labels{/name} | https://api.github.com/repos/huggingface/datasets/issues/7197/comments | https://api.github.com/repos/huggingface/datasets/issues/7197/events | https://github.com/huggingface/datasets/issues/7197 | 2,565,924,788 | I_kwDODunzps6Y8Oe0 | 7,197 | ConnectionError: Couldn't reach 'allenai/c4' on the Hub (ConnectionError)数据集下不下来,怎么回事 | {
"login": "Mrgengli",
"id": 114299344,
"node_id": "U_kgDOBtAR0A",
"avatar_url": "https://avatars.githubusercontent.com/u/114299344?v=4",
"gravatar_id": "",
"url": "https://api.github.com/users/Mrgengli",
"html_url": "https://github.com/Mrgengli",
"followers_url": "https://api.github.com/users/Mrgengli/... | [] | open | false | [] | null | [
"Also cant download \"allenai/c4\", but with different error reported:\r\n```\r\nTraceback (most recent call last): ... | 2024-10-04 09:33:25 | 2025-02-26 02:26:16 | null | null | NONE | [] | null | null | null | null | ### Describe the bug
from datasets import load_dataset
print("11")
traindata = load_dataset('ptb_text_only', 'penn_treebank', split='train')
print("22")
valdata = load_dataset('ptb_text_only',
'penn_treebank',
split='validation')
### Steps to reproduce the b... | null | {
"url": "https://api.github.com/repos/huggingface/datasets/issues/7197/reactions",
"total_count": 0,
"+1": 0,
"-1": 0,
"laugh": 0,
"hooray": 0,
"confused": 0,
"heart": 0,
"rocket": 0,
"eyes": 0
} | https://api.github.com/repos/huggingface/datasets/issues/7197/timeline | null | null | {"total":0,"completed":0,"percent_completed":0} | {"blocked_by":0,"total_blocked_by":0,"blocking":0,"total_blocking":0} | null | false |
https://api.github.com/repos/huggingface/datasets/issues/7196 | https://api.github.com/repos/huggingface/datasets | https://api.github.com/repos/huggingface/datasets/issues/7196/labels{/name} | https://api.github.com/repos/huggingface/datasets/issues/7196/comments | https://api.github.com/repos/huggingface/datasets/issues/7196/events | https://github.com/huggingface/datasets/issues/7196 | 2,564,218,566 | I_kwDODunzps6Y1t7G | 7,196 | concatenate_datasets does not preserve shuffling state | {
"login": "alex-hh",
"id": 5719745,
"node_id": "MDQ6VXNlcjU3MTk3NDU=",
"avatar_url": "https://avatars.githubusercontent.com/u/5719745?v=4",
"gravatar_id": "",
"url": "https://api.github.com/users/alex-hh",
"html_url": "https://github.com/alex-hh",
"followers_url": "https://api.github.com/users/alex-hh/... | [] | closed | false | [] | null | [
"It also does preserve `split_by_node`, so in the meantime you should call `shuffle` or `split_by_node` AFTER `interleave_datasets` or `concatenate_datasets`"
] | 2024-10-03 14:30:38 | 2026-02-04 18:55:36 | 2026-02-04 18:55:36 | null | CONTRIBUTOR | [] | null | null | null | null | ### Describe the bug
After concatenate datasets on an iterable dataset, the shuffling state is destroyed, similar to #7156
This means concatenation cant be used for resolving uneven numbers of samples across devices when using iterable datasets in a distributed setting as discussed in #6623
I also noticed th... | {
"login": "lhoestq",
"id": 42851186,
"node_id": "MDQ6VXNlcjQyODUxMTg2",
"avatar_url": "https://avatars.githubusercontent.com/u/42851186?v=4",
"gravatar_id": "",
"url": "https://api.github.com/users/lhoestq",
"html_url": "https://github.com/lhoestq",
"followers_url": "https://api.github.com/users/lhoest... | {
"url": "https://api.github.com/repos/huggingface/datasets/issues/7196/reactions",
"total_count": 0,
"+1": 0,
"-1": 0,
"laugh": 0,
"hooray": 0,
"confused": 0,
"heart": 0,
"rocket": 0,
"eyes": 0
} | https://api.github.com/repos/huggingface/datasets/issues/7196/timeline | null | completed | {"total":0,"completed":0,"percent_completed":0} | {"blocked_by":0,"total_blocked_by":0,"blocking":0,"total_blocking":0} | null | false |
https://api.github.com/repos/huggingface/datasets/issues/7195 | https://api.github.com/repos/huggingface/datasets | https://api.github.com/repos/huggingface/datasets/issues/7195/labels{/name} | https://api.github.com/repos/huggingface/datasets/issues/7195/comments | https://api.github.com/repos/huggingface/datasets/issues/7195/events | https://github.com/huggingface/datasets/issues/7195 | 2,564,070,809 | I_kwDODunzps6Y1J2Z | 7,195 | Add support for 3D datasets | {
"login": "severo",
"id": 1676121,
"node_id": "MDQ6VXNlcjE2NzYxMjE=",
"avatar_url": "https://avatars.githubusercontent.com/u/1676121?v=4",
"gravatar_id": "",
"url": "https://api.github.com/users/severo",
"html_url": "https://github.com/severo",
"followers_url": "https://api.github.com/users/severo/foll... | [
{
"id": 1935892871,
"node_id": "MDU6TGFiZWwxOTM1ODkyODcx",
"url": "https://api.github.com/repos/huggingface/datasets/labels/enhancement",
"name": "enhancement",
"color": "a2eeef",
"default": true,
"description": "New feature or request",
"archived_at": null,
"archived_by": null
... | open | false | [
{
"login": "severo",
"id": 1676121,
"node_id": "MDQ6VXNlcjE2NzYxMjE=",
"avatar_url": "https://avatars.githubusercontent.com/u/1676121?v=4",
"gravatar_id": "",
"url": "https://api.github.com/users/severo",
"html_url": "https://github.com/severo",
"followers_url": "https://api.github.c... | null | [
"maybe related: https://github.com/huggingface/datasets/issues/6388",
"Also look at https://github.com/huggingface/dataset-viewer/blob/f5fd117ceded990a7766e705bba1203fa907d6ad/services/worker/src/worker/job_runners/dataset/modalities.py#L241 which lists the 3D file formats that will assign the 3D modality to a da... | 2024-10-03 13:27:44 | 2024-10-04 09:23:36 | null | {
"login": "severo",
"id": 1676121,
"node_id": "MDQ6VXNlcjE2NzYxMjE=",
"avatar_url": "https://avatars.githubusercontent.com/u/1676121?v=4",
"gravatar_id": "",
"url": "https://api.github.com/users/severo",
"html_url": "https://github.com/severo",
"followers_url": "https://api.github.com/users/severo/foll... | CONTRIBUTOR | [] | null | null | null | null | See https://huggingface.co/datasets/allenai/objaverse for example | null | {
"url": "https://api.github.com/repos/huggingface/datasets/issues/7195/reactions",
"total_count": 0,
"+1": 0,
"-1": 0,
"laugh": 0,
"hooray": 0,
"confused": 0,
"heart": 0,
"rocket": 0,
"eyes": 0
} | https://api.github.com/repos/huggingface/datasets/issues/7195/timeline | null | null | {"total":0,"completed":0,"percent_completed":0} | {"blocked_by":0,"total_blocked_by":0,"blocking":0,"total_blocking":0} | null | false |
https://api.github.com/repos/huggingface/datasets/issues/7194 | https://api.github.com/repos/huggingface/datasets | https://api.github.com/repos/huggingface/datasets/issues/7194/labels{/name} | https://api.github.com/repos/huggingface/datasets/issues/7194/comments | https://api.github.com/repos/huggingface/datasets/issues/7194/events | https://github.com/huggingface/datasets/issues/7194 | 2,563,364,199 | I_kwDODunzps6YydVn | 7,194 | datasets.exceptions.DatasetNotFoundError for private dataset | {
"login": "kdutia",
"id": 20212179,
"node_id": "MDQ6VXNlcjIwMjEyMTc5",
"avatar_url": "https://avatars.githubusercontent.com/u/20212179?v=4",
"gravatar_id": "",
"url": "https://api.github.com/users/kdutia",
"html_url": "https://github.com/kdutia",
"followers_url": "https://api.github.com/users/kdutia/fo... | [] | closed | false | [] | null | [
"Actually there is no such dataset available, that is why you are getting that error.",
"Fixed with @kdutia in Slack chat. Generating a new token fixed this issue. "
] | 2024-10-03 07:49:36 | 2024-10-03 10:09:28 | 2024-10-03 10:09:28 | null | NONE | [] | null | null | null | null | ### Describe the bug
The following Python code tries to download a private dataset and fails with the error `datasets.exceptions.DatasetNotFoundError: Dataset 'ClimatePolicyRadar/all-document-text-data-weekly' doesn't exist on the Hub or cannot be accessed.`. Downloading a public dataset doesn't work.
``` py
fro... | {
"login": "davanstrien",
"id": 8995957,
"node_id": "MDQ6VXNlcjg5OTU5NTc=",
"avatar_url": "https://avatars.githubusercontent.com/u/8995957?v=4",
"gravatar_id": "",
"url": "https://api.github.com/users/davanstrien",
"html_url": "https://github.com/davanstrien",
"followers_url": "https://api.github.com/us... | {
"url": "https://api.github.com/repos/huggingface/datasets/issues/7194/reactions",
"total_count": 0,
"+1": 0,
"-1": 0,
"laugh": 0,
"hooray": 0,
"confused": 0,
"heart": 0,
"rocket": 0,
"eyes": 0
} | https://api.github.com/repos/huggingface/datasets/issues/7194/timeline | null | completed | {"total":0,"completed":0,"percent_completed":0} | {"blocked_by":0,"total_blocked_by":0,"blocking":0,"total_blocking":0} | null | false |
https://api.github.com/repos/huggingface/datasets/issues/7193 | https://api.github.com/repos/huggingface/datasets | https://api.github.com/repos/huggingface/datasets/issues/7193/labels{/name} | https://api.github.com/repos/huggingface/datasets/issues/7193/comments | https://api.github.com/repos/huggingface/datasets/issues/7193/events | https://github.com/huggingface/datasets/issues/7193 | 2,562,392,887 | I_kwDODunzps6YuwM3 | 7,193 | Support of num_workers (multiprocessing) in map for IterableDataset | {
"login": "getao",
"id": 12735658,
"node_id": "MDQ6VXNlcjEyNzM1NjU4",
"avatar_url": "https://avatars.githubusercontent.com/u/12735658?v=4",
"gravatar_id": "",
"url": "https://api.github.com/users/getao",
"html_url": "https://github.com/getao",
"followers_url": "https://api.github.com/users/getao/follow... | [
{
"id": 1935892871,
"node_id": "MDU6TGFiZWwxOTM1ODkyODcx",
"url": "https://api.github.com/repos/huggingface/datasets/labels/enhancement",
"name": "enhancement",
"color": "a2eeef",
"default": true,
"description": "New feature or request",
"archived_at": null,
"archived_by": null
... | open | false | [] | null | [
"I was curious about the same - since map is applied on the fly I was assuming that setting num_workers>1 in DataLoader would effectively do the map in parallel, have you tried that?"
] | 2024-10-02 18:34:04 | 2024-10-03 09:54:15 | null | null | NONE | [] | null | null | null | null | ### Feature request
Currently, IterableDataset doesn't support setting num_worker in .map(), which results in slow processing here. Could we add support for it? As .map() can be run in the batch fashion (e.g., batch_size is default to 1000 in datasets), it seems to be doable for IterableDataset as the regular Dataset.... | null | {
"url": "https://api.github.com/repos/huggingface/datasets/issues/7193/reactions",
"total_count": 0,
"+1": 0,
"-1": 0,
"laugh": 0,
"hooray": 0,
"confused": 0,
"heart": 0,
"rocket": 0,
"eyes": 0
} | https://api.github.com/repos/huggingface/datasets/issues/7193/timeline | null | null | {"total":0,"completed":0,"percent_completed":0} | {"blocked_by":0,"total_blocked_by":0,"blocking":0,"total_blocking":0} | null | false |
https://api.github.com/repos/huggingface/datasets/issues/7192 | https://api.github.com/repos/huggingface/datasets | https://api.github.com/repos/huggingface/datasets/issues/7192/labels{/name} | https://api.github.com/repos/huggingface/datasets/issues/7192/comments | https://api.github.com/repos/huggingface/datasets/issues/7192/events | https://github.com/huggingface/datasets/issues/7192 | 2,562,289,642 | I_kwDODunzps6YuW_q | 7,192 | Add repeat() for iterable datasets | {
"login": "alex-hh",
"id": 5719745,
"node_id": "MDQ6VXNlcjU3MTk3NDU=",
"avatar_url": "https://avatars.githubusercontent.com/u/5719745?v=4",
"gravatar_id": "",
"url": "https://api.github.com/users/alex-hh",
"html_url": "https://github.com/alex-hh",
"followers_url": "https://api.github.com/users/alex-hh/... | [
{
"id": 1935892871,
"node_id": "MDU6TGFiZWwxOTM1ODkyODcx",
"url": "https://api.github.com/repos/huggingface/datasets/labels/enhancement",
"name": "enhancement",
"color": "a2eeef",
"default": true,
"description": "New feature or request",
"archived_at": null,
"archived_by": null
... | closed | false | [] | null | [
"perhaps concatenate_datasets can already be used to achieve almost the same effect? ",
"`concatenate_datasets` does the job when there is a finite number of repetitions, but in case of `.repeat()` forever we need a new logic in `iterable_dataset.py`",
"done in https://github.com/huggingface/datasets/pull/7198"... | 2024-10-02 17:48:13 | 2025-03-18 10:48:33 | 2025-03-18 10:48:32 | null | CONTRIBUTOR | [] | null | null | null | null | ### Feature request
It would be useful to be able to straightforwardly repeat iterable datasets indefinitely, to provide complete control over starting and ending of iteration to the user.
An IterableDataset.repeat(n) function could do this automatically
### Motivation
This feature was discussed in this iss... | {
"login": "lhoestq",
"id": 42851186,
"node_id": "MDQ6VXNlcjQyODUxMTg2",
"avatar_url": "https://avatars.githubusercontent.com/u/42851186?v=4",
"gravatar_id": "",
"url": "https://api.github.com/users/lhoestq",
"html_url": "https://github.com/lhoestq",
"followers_url": "https://api.github.com/users/lhoest... | {
"url": "https://api.github.com/repos/huggingface/datasets/issues/7192/reactions",
"total_count": 0,
"+1": 0,
"-1": 0,
"laugh": 0,
"hooray": 0,
"confused": 0,
"heart": 0,
"rocket": 0,
"eyes": 0
} | https://api.github.com/repos/huggingface/datasets/issues/7192/timeline | null | completed | {"total":0,"completed":0,"percent_completed":0} | {"blocked_by":0,"total_blocked_by":0,"blocking":0,"total_blocking":0} | null | false |
https://api.github.com/repos/huggingface/datasets/issues/7190 | https://api.github.com/repos/huggingface/datasets | https://api.github.com/repos/huggingface/datasets/issues/7190/labels{/name} | https://api.github.com/repos/huggingface/datasets/issues/7190/comments | https://api.github.com/repos/huggingface/datasets/issues/7190/events | https://github.com/huggingface/datasets/issues/7190 | 2,562,162,725 | I_kwDODunzps6Yt4Al | 7,190 | Datasets conflicts with fsspec 2024.9 | {
"login": "cw-igormorgado",
"id": 162599174,
"node_id": "U_kgDOCbERBg",
"avatar_url": "https://avatars.githubusercontent.com/u/162599174?v=4",
"gravatar_id": "",
"url": "https://api.github.com/users/cw-igormorgado",
"html_url": "https://github.com/cw-igormorgado",
"followers_url": "https://api.github.c... | [] | open | false | [] | null | [
"Yes, I need to use the latest version of fsspec and datasets for my usecase. \r\nhttps://github.com/fsspec/s3fs/pull/888#issuecomment-2404204606\r\nhttps://github.com/apache/arrow/issues/34363#issuecomment-2403553473\r\n\r\nlast version where things install without conflict is: 2.14.4\r\n\r\nSo this issue starts f... | 2024-10-02 16:43:46 | 2024-10-10 07:33:18 | null | null | NONE | [] | null | null | null | null | ### Describe the bug
Installing both in latest versions are not possible
`pip install "datasets==3.0.1" "fsspec==2024.9.0"`
But using older version of datasets is ok
`pip install "datasets==1.24.4" "fsspec==2024.9.0"`
### Steps to reproduce the bug
`pip install "datasets==3.0.1" "fsspec==2024.9.0"`
#... | null | {
"url": "https://api.github.com/repos/huggingface/datasets/issues/7190/reactions",
"total_count": 0,
"+1": 0,
"-1": 0,
"laugh": 0,
"hooray": 0,
"confused": 0,
"heart": 0,
"rocket": 0,
"eyes": 0
} | https://api.github.com/repos/huggingface/datasets/issues/7190/timeline | null | null | {"total":0,"completed":0,"percent_completed":0} | {"blocked_by":0,"total_blocked_by":0,"blocking":0,"total_blocking":0} | null | false |
https://api.github.com/repos/huggingface/datasets/issues/7185 | https://api.github.com/repos/huggingface/datasets | https://api.github.com/repos/huggingface/datasets/issues/7185/labels{/name} | https://api.github.com/repos/huggingface/datasets/issues/7185/comments | https://api.github.com/repos/huggingface/datasets/issues/7185/events | https://github.com/huggingface/datasets/issues/7185 | 2,558,508,748 | I_kwDODunzps6Yf77M | 7,185 | CI benchmarks are broken | {
"login": "albertvillanova",
"id": 8515462,
"node_id": "MDQ6VXNlcjg1MTU0NjI=",
"avatar_url": "https://avatars.githubusercontent.com/u/8515462?v=4",
"gravatar_id": "",
"url": "https://api.github.com/users/albertvillanova",
"html_url": "https://github.com/albertvillanova",
"followers_url": "https://api.g... | [
{
"id": 4296013012,
"node_id": "LA_kwDODunzps8AAAABAA_01A",
"url": "https://api.github.com/repos/huggingface/datasets/labels/maintenance",
"name": "maintenance",
"color": "d4c5f9",
"default": false,
"description": "Maintenance tasks",
"archived_at": null,
"archived_by": null
}
... | closed | false | [] | null | [
"Fixed by #7205"
] | 2024-10-01 08:16:08 | 2024-10-09 16:07:48 | 2024-10-09 16:07:48 | null | MEMBER | [] | null | null | null | null | Since Aug 30, 2024, CI benchmarks are broken: https://github.com/huggingface/datasets/actions/runs/11108421214/job/30861323975
```
{"level":"error","message":"Resource not accessible by integration","name":"HttpError","request":{"body":"{\"body\":\"<details>\\n<summary>Show benchmarks</summary>\\n\\nPyArrow==8.0.0\\n... | {
"login": "albertvillanova",
"id": 8515462,
"node_id": "MDQ6VXNlcjg1MTU0NjI=",
"avatar_url": "https://avatars.githubusercontent.com/u/8515462?v=4",
"gravatar_id": "",
"url": "https://api.github.com/users/albertvillanova",
"html_url": "https://github.com/albertvillanova",
"followers_url": "https://api.g... | {
"url": "https://api.github.com/repos/huggingface/datasets/issues/7185/reactions",
"total_count": 0,
"+1": 0,
"-1": 0,
"laugh": 0,
"hooray": 0,
"confused": 0,
"heart": 0,
"rocket": 0,
"eyes": 0
} | https://api.github.com/repos/huggingface/datasets/issues/7185/timeline | null | completed | {"total":0,"completed":0,"percent_completed":0} | {"blocked_by":0,"total_blocked_by":0,"blocking":0,"total_blocking":0} | null | false |
https://api.github.com/repos/huggingface/datasets/issues/7180 | https://api.github.com/repos/huggingface/datasets | https://api.github.com/repos/huggingface/datasets/issues/7180/labels{/name} | https://api.github.com/repos/huggingface/datasets/issues/7180/comments | https://api.github.com/repos/huggingface/datasets/issues/7180/events | https://github.com/huggingface/datasets/issues/7180 | 2,554,244,750 | I_kwDODunzps6YPq6O | 7,180 | Memory leak when wrapping datasets into PyTorch Dataset without explicit deletion | {
"login": "iamwangyabin",
"id": 38123329,
"node_id": "MDQ6VXNlcjM4MTIzMzI5",
"avatar_url": "https://avatars.githubusercontent.com/u/38123329?v=4",
"gravatar_id": "",
"url": "https://api.github.com/users/iamwangyabin",
"html_url": "https://github.com/iamwangyabin",
"followers_url": "https://api.github.c... | [] | closed | false | [] | null | [
"> I've encountered a memory leak when wrapping the HuggingFace dataset into a PyTorch Dataset. The RAM usage constantly increases during iteration if items are not explicitly deleted after use.\r\n\r\nDatasets are memory mapped so they work like SWAP memory. In particular as long as you have RAM available the data... | 2024-09-28 14:00:47 | 2024-09-30 12:07:56 | 2024-09-30 12:07:56 | null | NONE | [] | null | null | null | null | ### Describe the bug
I've encountered a memory leak when wrapping the HuggingFace dataset into a PyTorch Dataset. The RAM usage constantly increases during iteration if items are not explicitly deleted after use.
### Steps to reproduce the bug
Steps to reproduce:
Create a PyTorch Dataset wrapper f... | {
"login": "iamwangyabin",
"id": 38123329,
"node_id": "MDQ6VXNlcjM4MTIzMzI5",
"avatar_url": "https://avatars.githubusercontent.com/u/38123329?v=4",
"gravatar_id": "",
"url": "https://api.github.com/users/iamwangyabin",
"html_url": "https://github.com/iamwangyabin",
"followers_url": "https://api.github.c... | {
"url": "https://api.github.com/repos/huggingface/datasets/issues/7180/reactions",
"total_count": 0,
"+1": 0,
"-1": 0,
"laugh": 0,
"hooray": 0,
"confused": 0,
"heart": 0,
"rocket": 0,
"eyes": 0
} | https://api.github.com/repos/huggingface/datasets/issues/7180/timeline | null | completed | {"total":0,"completed":0,"percent_completed":0} | {"blocked_by":0,"total_blocked_by":0,"blocking":0,"total_blocking":0} | null | false |
https://api.github.com/repos/huggingface/datasets/issues/7175 | https://api.github.com/repos/huggingface/datasets | https://api.github.com/repos/huggingface/datasets/issues/7175/labels{/name} | https://api.github.com/repos/huggingface/datasets/issues/7175/comments | https://api.github.com/repos/huggingface/datasets/issues/7175/events | https://github.com/huggingface/datasets/issues/7175 | 2,550,957,337 | I_kwDODunzps6YDIUZ | 7,175 | [FSTimeoutError] load_dataset | {
"login": "cosmo3769",
"id": 53268607,
"node_id": "MDQ6VXNlcjUzMjY4NjA3",
"avatar_url": "https://avatars.githubusercontent.com/u/53268607?v=4",
"gravatar_id": "",
"url": "https://api.github.com/users/cosmo3769",
"html_url": "https://github.com/cosmo3769",
"followers_url": "https://api.github.com/users/... | [] | closed | false | [] | null | [
"Is this `FSTimeoutError` due to download network issue from remote resource (from where it is being accessed)?",
"It seems to happen for all datasets, not just a specific one, and especially for versions after 3.0. (3.0.0, 3.0.1 have this problem)\r\n\r\nI had the same error on a different dataset, but after dow... | 2024-09-26 15:42:29 | 2025-02-01 09:09:35 | 2024-09-30 17:28:35 | null | NONE | [] | null | null | null | null | ### Describe the bug
When using `load_dataset`to load [HuggingFaceM4/VQAv2](https://huggingface.co/datasets/HuggingFaceM4/VQAv2), I am getting `FSTimeoutError`.
### Error
```
TimeoutError:
The above exception was the direct cause of the following exception:
FSTimeoutError Trac... | {
"login": "cosmo3769",
"id": 53268607,
"node_id": "MDQ6VXNlcjUzMjY4NjA3",
"avatar_url": "https://avatars.githubusercontent.com/u/53268607?v=4",
"gravatar_id": "",
"url": "https://api.github.com/users/cosmo3769",
"html_url": "https://github.com/cosmo3769",
"followers_url": "https://api.github.com/users/... | {
"url": "https://api.github.com/repos/huggingface/datasets/issues/7175/reactions",
"total_count": 0,
"+1": 0,
"-1": 0,
"laugh": 0,
"hooray": 0,
"confused": 0,
"heart": 0,
"rocket": 0,
"eyes": 0
} | https://api.github.com/repos/huggingface/datasets/issues/7175/timeline | null | completed | {"total":0,"completed":0,"percent_completed":0} | {"blocked_by":0,"total_blocked_by":0,"blocking":0,"total_blocking":0} | null | false |
https://api.github.com/repos/huggingface/datasets/issues/7168 | https://api.github.com/repos/huggingface/datasets | https://api.github.com/repos/huggingface/datasets/issues/7168/labels{/name} | https://api.github.com/repos/huggingface/datasets/issues/7168/comments | https://api.github.com/repos/huggingface/datasets/issues/7168/events | https://github.com/huggingface/datasets/issues/7168 | 2,546,710,631 | I_kwDODunzps6Xy7hn | 7,168 | sd1.5 diffusers controlnet training script gives new error | {
"login": "Night1099",
"id": 90132896,
"node_id": "MDQ6VXNlcjkwMTMyODk2",
"avatar_url": "https://avatars.githubusercontent.com/u/90132896?v=4",
"gravatar_id": "",
"url": "https://api.github.com/users/Night1099",
"html_url": "https://github.com/Night1099",
"followers_url": "https://api.github.com/users/... | [] | closed | false | [] | null | [
"not sure why the issue is formatting oddly",
"I guess this is a dupe of\r\n\r\nhttps://github.com/huggingface/datasets/issues/7071",
"this turned out to be because of a bad image in dataset",
"@Night1099 could you spiecify what exactly was wrong with your image in the dataset? I think im facing the same issu... | 2024-09-25 01:42:49 | 2025-09-16 15:38:01 | 2024-09-30 05:24:02 | null | NONE | [] | null | null | null | null | ### Describe the bug
This will randomly pop up during training now
```
Traceback (most recent call last):
File "/workspace/diffusers/examples/controlnet/train_controlnet.py", line 1192, in <module>
main(args)
File "/workspace/diffusers/examples/controlnet/train_controlnet.py", line 1041, in main
... | {
"login": "Night1099",
"id": 90132896,
"node_id": "MDQ6VXNlcjkwMTMyODk2",
"avatar_url": "https://avatars.githubusercontent.com/u/90132896?v=4",
"gravatar_id": "",
"url": "https://api.github.com/users/Night1099",
"html_url": "https://github.com/Night1099",
"followers_url": "https://api.github.com/users/... | {
"url": "https://api.github.com/repos/huggingface/datasets/issues/7168/reactions",
"total_count": 0,
"+1": 0,
"-1": 0,
"laugh": 0,
"hooray": 0,
"confused": 0,
"heart": 0,
"rocket": 0,
"eyes": 0
} | https://api.github.com/repos/huggingface/datasets/issues/7168/timeline | null | completed | {"total":0,"completed":0,"percent_completed":0} | {"blocked_by":0,"total_blocked_by":0,"blocking":0,"total_blocking":0} | null | false |
https://api.github.com/repos/huggingface/datasets/issues/7167 | https://api.github.com/repos/huggingface/datasets | https://api.github.com/repos/huggingface/datasets/issues/7167/labels{/name} | https://api.github.com/repos/huggingface/datasets/issues/7167/comments | https://api.github.com/repos/huggingface/datasets/issues/7167/events | https://github.com/huggingface/datasets/issues/7167 | 2,546,708,014 | I_kwDODunzps6Xy64u | 7,167 | Error Mapping on sd3, sdxl and upcoming flux controlnet training scripts in diffusers | {
"login": "Night1099",
"id": 90132896,
"node_id": "MDQ6VXNlcjkwMTMyODk2",
"avatar_url": "https://avatars.githubusercontent.com/u/90132896?v=4",
"gravatar_id": "",
"url": "https://api.github.com/users/Night1099",
"html_url": "https://github.com/Night1099",
"followers_url": "https://api.github.com/users/... | [] | closed | false | [] | null | [
"this is happening on large datasets, if anyone happens upon this i was able to fix by changing\r\n\r\n```\r\ntrain_dataset = train_dataset.map(compute_embeddings_fn, batched=True, new_fingerprint=new_fingerprint)\r\n```\r\n\r\nto\r\n\r\n```\r\ntrain_dataset = train_dataset.map(compute_embeddings_fn, batched=True, ... | 2024-09-25 01:39:51 | 2024-09-30 05:28:15 | 2024-09-30 05:28:04 | null | NONE | [] | null | null | null | null | ### Describe the bug
```
Map: 6%|██████ | 8000/138120 [19:27<5:16:36, 6.85 examples/s]
Traceback (most recent call last):
File "/workspace/diffusers/examples/controlnet/train_controlnet_sd3.py", line 1416, in <mod... | {
"login": "Night1099",
"id": 90132896,
"node_id": "MDQ6VXNlcjkwMTMyODk2",
"avatar_url": "https://avatars.githubusercontent.com/u/90132896?v=4",
"gravatar_id": "",
"url": "https://api.github.com/users/Night1099",
"html_url": "https://github.com/Night1099",
"followers_url": "https://api.github.com/users/... | {
"url": "https://api.github.com/repos/huggingface/datasets/issues/7167/reactions",
"total_count": 0,
"+1": 0,
"-1": 0,
"laugh": 0,
"hooray": 0,
"confused": 0,
"heart": 0,
"rocket": 0,
"eyes": 0
} | https://api.github.com/repos/huggingface/datasets/issues/7167/timeline | null | completed | {"total":0,"completed":0,"percent_completed":0} | {"blocked_by":0,"total_blocked_by":0,"blocking":0,"total_blocking":0} | null | false |
https://api.github.com/repos/huggingface/datasets/issues/7164 | https://api.github.com/repos/huggingface/datasets | https://api.github.com/repos/huggingface/datasets/issues/7164/labels{/name} | https://api.github.com/repos/huggingface/datasets/issues/7164/comments | https://api.github.com/repos/huggingface/datasets/issues/7164/events | https://github.com/huggingface/datasets/issues/7164 | 2,544,757,297 | I_kwDODunzps6Xreox | 7,164 | fsspec.exceptions.FSTimeoutError when downloading dataset | {
"login": "timonmerk",
"id": 38216460,
"node_id": "MDQ6VXNlcjM4MjE2NDYw",
"avatar_url": "https://avatars.githubusercontent.com/u/38216460?v=4",
"gravatar_id": "",
"url": "https://api.github.com/users/timonmerk",
"html_url": "https://github.com/timonmerk",
"followers_url": "https://api.github.com/users/... | [] | closed | false | [] | null | [
"Hi ! If you check the dataset loading script [here](https://huggingface.co/datasets/openslr/librispeech_asr/blob/main/librispeech_asr.py) you'll see that it downloads the data from OpenSLR, and apparently their storage has timeout issues. It would be great to ultimately host the dataset on Hugging Face instead.\r\... | 2024-09-24 08:45:05 | 2025-07-28 14:58:49 | 2025-07-28 14:58:49 | null | NONE | [] | null | null | null | null | ### Describe the bug
I am trying to download the `librispeech_asr` `clean` dataset, which results in a `FSTimeoutError` exception after downloading around 61% of the data.
### Steps to reproduce the bug
```
import datasets
datasets.load_dataset("librispeech_asr", "clean")
```
The output is as follows:
> Dow... | {
"login": "lhoestq",
"id": 42851186,
"node_id": "MDQ6VXNlcjQyODUxMTg2",
"avatar_url": "https://avatars.githubusercontent.com/u/42851186?v=4",
"gravatar_id": "",
"url": "https://api.github.com/users/lhoestq",
"html_url": "https://github.com/lhoestq",
"followers_url": "https://api.github.com/users/lhoest... | {
"url": "https://api.github.com/repos/huggingface/datasets/issues/7164/reactions",
"total_count": 0,
"+1": 0,
"-1": 0,
"laugh": 0,
"hooray": 0,
"confused": 0,
"heart": 0,
"rocket": 0,
"eyes": 0
} | https://api.github.com/repos/huggingface/datasets/issues/7164/timeline | null | completed | {"total":0,"completed":0,"percent_completed":0} | {"blocked_by":0,"total_blocked_by":0,"blocking":0,"total_blocking":0} | null | false |
https://api.github.com/repos/huggingface/datasets/issues/7163 | https://api.github.com/repos/huggingface/datasets | https://api.github.com/repos/huggingface/datasets/issues/7163/labels{/name} | https://api.github.com/repos/huggingface/datasets/issues/7163/comments | https://api.github.com/repos/huggingface/datasets/issues/7163/events | https://github.com/huggingface/datasets/issues/7163 | 2,542,361,234 | I_kwDODunzps6XiVqS | 7,163 | Set explicit seed in iterable dataset ddp shuffling example | {
"login": "alex-hh",
"id": 5719745,
"node_id": "MDQ6VXNlcjU3MTk3NDU=",
"avatar_url": "https://avatars.githubusercontent.com/u/5719745?v=4",
"gravatar_id": "",
"url": "https://api.github.com/users/alex-hh",
"html_url": "https://github.com/alex-hh",
"followers_url": "https://api.github.com/users/alex-hh/... | [] | closed | false | [] | null | [
"thanks for reporting !"
] | 2024-09-23 11:34:06 | 2024-09-24 14:40:15 | 2024-09-24 14:40:15 | null | CONTRIBUTOR | [] | null | null | null | null | ### Describe the bug
In the examples section of the iterable dataset docs https://huggingface.co/docs/datasets/en/package_reference/main_classes#datasets.IterableDataset
the ddp example shuffles without seeding
```python
from datasets.distributed import split_dataset_by_node
ids = ds.to_iterable_dataset(num_sh... | {
"login": "lhoestq",
"id": 42851186,
"node_id": "MDQ6VXNlcjQyODUxMTg2",
"avatar_url": "https://avatars.githubusercontent.com/u/42851186?v=4",
"gravatar_id": "",
"url": "https://api.github.com/users/lhoestq",
"html_url": "https://github.com/lhoestq",
"followers_url": "https://api.github.com/users/lhoest... | {
"url": "https://api.github.com/repos/huggingface/datasets/issues/7163/reactions",
"total_count": 0,
"+1": 0,
"-1": 0,
"laugh": 0,
"hooray": 0,
"confused": 0,
"heart": 0,
"rocket": 0,
"eyes": 0
} | https://api.github.com/repos/huggingface/datasets/issues/7163/timeline | null | completed | {"total":0,"completed":0,"percent_completed":0} | {"blocked_by":0,"total_blocked_by":0,"blocking":0,"total_blocking":0} | null | false |
https://api.github.com/repos/huggingface/datasets/issues/7159 | https://api.github.com/repos/huggingface/datasets | https://api.github.com/repos/huggingface/datasets/issues/7159/labels{/name} | https://api.github.com/repos/huggingface/datasets/issues/7159/comments | https://api.github.com/repos/huggingface/datasets/issues/7159/events | https://github.com/huggingface/datasets/issues/7159 | 2,541,865,613 | I_kwDODunzps6XgcqN | 7,159 | JSON lines with missing struct fields raise TypeError: Couldn't cast array | {
"login": "albertvillanova",
"id": 8515462,
"node_id": "MDQ6VXNlcjg1MTU0NjI=",
"avatar_url": "https://avatars.githubusercontent.com/u/8515462?v=4",
"gravatar_id": "",
"url": "https://api.github.com/users/albertvillanova",
"html_url": "https://github.com/albertvillanova",
"followers_url": "https://api.g... | [
{
"id": 1935892857,
"node_id": "MDU6TGFiZWwxOTM1ODkyODU3",
"url": "https://api.github.com/repos/huggingface/datasets/labels/bug",
"name": "bug",
"color": "d73a4a",
"default": true,
"description": "Something isn't working",
"archived_at": null,
"archived_by": null
}
] | closed | false | [
{
"login": "albertvillanova",
"id": 8515462,
"node_id": "MDQ6VXNlcjg1MTU0NjI=",
"avatar_url": "https://avatars.githubusercontent.com/u/8515462?v=4",
"gravatar_id": "",
"url": "https://api.github.com/users/albertvillanova",
"html_url": "https://github.com/albertvillanova",
"followers_... | null | [
"Hello,\r\n\r\nI have still the same issue when loading the dataset with the new version:\r\n[https://huggingface.co/datasets/wikimedia/structured-wikipedia/discussions/5](https://huggingface.co/datasets/wikimedia/structured-wikipedia/discussions/5)\r\n\r\nI have downloaded and unzipped the wikimedia/structured-wik... | 2024-09-23 07:57:58 | 2024-10-21 08:07:07 | 2024-09-23 11:09:18 | {
"login": "albertvillanova",
"id": 8515462,
"node_id": "MDQ6VXNlcjg1MTU0NjI=",
"avatar_url": "https://avatars.githubusercontent.com/u/8515462?v=4",
"gravatar_id": "",
"url": "https://api.github.com/users/albertvillanova",
"html_url": "https://github.com/albertvillanova",
"followers_url": "https://api.g... | MEMBER | [] | null | null | null | null | JSON lines with missing struct fields raise TypeError: Couldn't cast array of type.
See example: https://huggingface.co/datasets/wikimedia/structured-wikipedia/discussions/5
One would expect that the struct missing fields are added with null values. | {
"login": "albertvillanova",
"id": 8515462,
"node_id": "MDQ6VXNlcjg1MTU0NjI=",
"avatar_url": "https://avatars.githubusercontent.com/u/8515462?v=4",
"gravatar_id": "",
"url": "https://api.github.com/users/albertvillanova",
"html_url": "https://github.com/albertvillanova",
"followers_url": "https://api.g... | {
"url": "https://api.github.com/repos/huggingface/datasets/issues/7159/reactions",
"total_count": 0,
"+1": 0,
"-1": 0,
"laugh": 0,
"hooray": 0,
"confused": 0,
"heart": 0,
"rocket": 0,
"eyes": 0
} | https://api.github.com/repos/huggingface/datasets/issues/7159/timeline | null | completed | {"total":0,"completed":0,"percent_completed":0} | {"blocked_by":0,"total_blocked_by":0,"blocking":0,"total_blocking":0} | null | false |
https://api.github.com/repos/huggingface/datasets/issues/7156 | https://api.github.com/repos/huggingface/datasets | https://api.github.com/repos/huggingface/datasets/issues/7156/labels{/name} | https://api.github.com/repos/huggingface/datasets/issues/7156/comments | https://api.github.com/repos/huggingface/datasets/issues/7156/events | https://github.com/huggingface/datasets/issues/7156 | 2,539,360,617 | I_kwDODunzps6XW5Fp | 7,156 | interleave_datasets resets shuffle state | {
"login": "jonathanasdf",
"id": 511073,
"node_id": "MDQ6VXNlcjUxMTA3Mw==",
"avatar_url": "https://avatars.githubusercontent.com/u/511073?v=4",
"gravatar_id": "",
"url": "https://api.github.com/users/jonathanasdf",
"html_url": "https://github.com/jonathanasdf",
"followers_url": "https://api.github.com/u... | [] | open | false | [] | null | [
"It also does preserve `split_by_node`, so in the meantime you should call `shuffle` or `split_by_node` AFTER `interleave_datasets` or `concatenate_datasets`"
] | 2024-09-20 17:57:54 | 2025-03-18 10:56:25 | null | null | NONE | [] | null | null | null | null | ### Describe the bug
```
import datasets
import torch.utils.data
def gen(shards):
yield {"shards": shards}
def main():
dataset = datasets.IterableDataset.from_generator(
gen,
gen_kwargs={'shards': list(range(25))}
)
dataset = dataset.shuffle(buffer_size=1)
dataset... | null | {
"url": "https://api.github.com/repos/huggingface/datasets/issues/7156/reactions",
"total_count": 0,
"+1": 0,
"-1": 0,
"laugh": 0,
"hooray": 0,
"confused": 0,
"heart": 0,
"rocket": 0,
"eyes": 0
} | https://api.github.com/repos/huggingface/datasets/issues/7156/timeline | null | null | {"total":0,"completed":0,"percent_completed":0} | {"blocked_by":0,"total_blocked_by":0,"blocking":0,"total_blocking":0} | null | false |
https://api.github.com/repos/huggingface/datasets/issues/7155 | https://api.github.com/repos/huggingface/datasets | https://api.github.com/repos/huggingface/datasets/issues/7155/labels{/name} | https://api.github.com/repos/huggingface/datasets/issues/7155/comments | https://api.github.com/repos/huggingface/datasets/issues/7155/events | https://github.com/huggingface/datasets/issues/7155 | 2,533,641,870 | I_kwDODunzps6XBE6O | 7,155 | Dataset viewer not working! Failure due to more than 32 splits. | {
"login": "sleepingcat4",
"id": 81933585,
"node_id": "MDQ6VXNlcjgxOTMzNTg1",
"avatar_url": "https://avatars.githubusercontent.com/u/81933585?v=4",
"gravatar_id": "",
"url": "https://api.github.com/users/sleepingcat4",
"html_url": "https://github.com/sleepingcat4",
"followers_url": "https://api.github.c... | [] | closed | false | [] | null | [
"I have fixed it! But I would appreciate a new feature wheere I could iterate over and see what each file looks like. "
] | 2024-09-18 12:43:21 | 2024-09-18 13:20:03 | 2024-09-18 13:20:03 | null | NONE | [] | null | null | null | null | Hello guys,
I have a dataset and I didn't know I couldn't upload more than 32 splits. Now, my dataset viewer is not working. I don't have the dataset locally on my node anymore and recreating would take a week. And I have to publish the dataset coming Monday. I read about the practice, how I can resolve it and avoi... | {
"login": "sleepingcat4",
"id": 81933585,
"node_id": "MDQ6VXNlcjgxOTMzNTg1",
"avatar_url": "https://avatars.githubusercontent.com/u/81933585?v=4",
"gravatar_id": "",
"url": "https://api.github.com/users/sleepingcat4",
"html_url": "https://github.com/sleepingcat4",
"followers_url": "https://api.github.c... | {
"url": "https://api.github.com/repos/huggingface/datasets/issues/7155/reactions",
"total_count": 0,
"+1": 0,
"-1": 0,
"laugh": 0,
"hooray": 0,
"confused": 0,
"heart": 0,
"rocket": 0,
"eyes": 0
} | https://api.github.com/repos/huggingface/datasets/issues/7155/timeline | null | completed | {"total":0,"completed":0,"percent_completed":0} | {"blocked_by":0,"total_blocked_by":0,"blocking":0,"total_blocking":0} | null | false |
https://api.github.com/repos/huggingface/datasets/issues/7149 | https://api.github.com/repos/huggingface/datasets | https://api.github.com/repos/huggingface/datasets/issues/7149/labels{/name} | https://api.github.com/repos/huggingface/datasets/issues/7149/comments | https://api.github.com/repos/huggingface/datasets/issues/7149/events | https://github.com/huggingface/datasets/issues/7149 | 2,524,497,448 | I_kwDODunzps6WeMYo | 7,149 | Datasets Unknown Keyword Argument Error - task_templates | {
"login": "varungupta31",
"id": 51288316,
"node_id": "MDQ6VXNlcjUxMjg4MzE2",
"avatar_url": "https://avatars.githubusercontent.com/u/51288316?v=4",
"gravatar_id": "",
"url": "https://api.github.com/users/varungupta31",
"html_url": "https://github.com/varungupta31",
"followers_url": "https://api.github.c... | [] | closed | false | [
{
"login": "albertvillanova",
"id": 8515462,
"node_id": "MDQ6VXNlcjg1MTU0NjI=",
"avatar_url": "https://avatars.githubusercontent.com/u/8515462?v=4",
"gravatar_id": "",
"url": "https://api.github.com/users/albertvillanova",
"html_url": "https://github.com/albertvillanova",
"followers_... | null | [
"Thanks, for reporting.\r\n\r\nWe have been fixing most Hub datasets to remove the deprecated (and now non-supported) task templates, but we missed the \"facebook/winoground\".\r\n\r\nIt is fixed now: https://huggingface.co/datasets/facebook/winoground/discussions/8\r\n\r\n",
"Hello @albertvillanova \r\n\r\nI got... | 2024-09-13 10:30:57 | 2025-03-06 07:11:55 | 2024-09-13 14:10:48 | {
"login": "albertvillanova",
"id": 8515462,
"node_id": "MDQ6VXNlcjg1MTU0NjI=",
"avatar_url": "https://avatars.githubusercontent.com/u/8515462?v=4",
"gravatar_id": "",
"url": "https://api.github.com/users/albertvillanova",
"html_url": "https://github.com/albertvillanova",
"followers_url": "https://api.g... | NONE | [] | null | null | null | null | ### Describe the bug
Issue
```python
from datasets import load_dataset
examples = load_dataset('facebook/winoground', use_auth_token=<YOUR USER ACCESS TOKEN>)
```
Gives error
```
TypeError: DatasetInfo.__init__() got an unexpected keyword argument 'task_templates'
```
A simple downgrade to lower `data... | {
"login": "albertvillanova",
"id": 8515462,
"node_id": "MDQ6VXNlcjg1MTU0NjI=",
"avatar_url": "https://avatars.githubusercontent.com/u/8515462?v=4",
"gravatar_id": "",
"url": "https://api.github.com/users/albertvillanova",
"html_url": "https://github.com/albertvillanova",
"followers_url": "https://api.g... | {
"url": "https://api.github.com/repos/huggingface/datasets/issues/7149/reactions",
"total_count": 0,
"+1": 0,
"-1": 0,
"laugh": 0,
"hooray": 0,
"confused": 0,
"heart": 0,
"rocket": 0,
"eyes": 0
} | https://api.github.com/repos/huggingface/datasets/issues/7149/timeline | null | completed | {"total":0,"completed":0,"percent_completed":0} | {"blocked_by":0,"total_blocked_by":0,"blocking":0,"total_blocking":0} | null | false |
https://api.github.com/repos/huggingface/datasets/issues/7148 | https://api.github.com/repos/huggingface/datasets | https://api.github.com/repos/huggingface/datasets/issues/7148/labels{/name} | https://api.github.com/repos/huggingface/datasets/issues/7148/comments | https://api.github.com/repos/huggingface/datasets/issues/7148/events | https://github.com/huggingface/datasets/issues/7148 | 2,523,833,413 | I_kwDODunzps6WbqRF | 7,148 | Bug: Error when downloading mteb/mtop_domain | {
"login": "ZiyiXia",
"id": 77958037,
"node_id": "MDQ6VXNlcjc3OTU4MDM3",
"avatar_url": "https://avatars.githubusercontent.com/u/77958037?v=4",
"gravatar_id": "",
"url": "https://api.github.com/users/ZiyiXia",
"html_url": "https://github.com/ZiyiXia",
"followers_url": "https://api.github.com/users/ZiyiXi... | [] | closed | false | [] | null | [
"Could you please try with `force_redownload` instead?\r\nEDIT:\r\n```python\r\ndata = load_dataset(\"mteb/mtop_domain\", \"en\", download_mode=\"force_redownload\")\r\n```",
"Seems the error is still there",
"I am not able to reproduce the issue:\r\n```python\r\nIn [1]: from datasets import load_dataset\r\n\r\... | 2024-09-13 04:09:39 | 2024-09-14 15:11:35 | 2024-09-14 15:11:35 | null | NONE | [] | null | null | null | null | ### Describe the bug
When downloading the dataset "mteb/mtop_domain", ran into the following error:
```
Traceback (most recent call last):
File "/share/project/xzy/test/test_download.py", line 3, in <module>
data = load_dataset("mteb/mtop_domain", "en", trust_remote_code=True)
File "/opt/conda/lib/pytho... | {
"login": "albertvillanova",
"id": 8515462,
"node_id": "MDQ6VXNlcjg1MTU0NjI=",
"avatar_url": "https://avatars.githubusercontent.com/u/8515462?v=4",
"gravatar_id": "",
"url": "https://api.github.com/users/albertvillanova",
"html_url": "https://github.com/albertvillanova",
"followers_url": "https://api.g... | {
"url": "https://api.github.com/repos/huggingface/datasets/issues/7148/reactions",
"total_count": 0,
"+1": 0,
"-1": 0,
"laugh": 0,
"hooray": 0,
"confused": 0,
"heart": 0,
"rocket": 0,
"eyes": 0
} | https://api.github.com/repos/huggingface/datasets/issues/7148/timeline | null | completed | {"total":0,"completed":0,"percent_completed":0} | {"blocked_by":0,"total_blocked_by":0,"blocking":0,"total_blocking":0} | null | false |
https://api.github.com/repos/huggingface/datasets/issues/7147 | https://api.github.com/repos/huggingface/datasets | https://api.github.com/repos/huggingface/datasets/issues/7147/labels{/name} | https://api.github.com/repos/huggingface/datasets/issues/7147/comments | https://api.github.com/repos/huggingface/datasets/issues/7147/events | https://github.com/huggingface/datasets/issues/7147 | 2,523,129,465 | I_kwDODunzps6WY-Z5 | 7,147 | IterableDataset strange deadlock | {
"login": "jonathanasdf",
"id": 511073,
"node_id": "MDQ6VXNlcjUxMTA3Mw==",
"avatar_url": "https://avatars.githubusercontent.com/u/511073?v=4",
"gravatar_id": "",
"url": "https://api.github.com/users/jonathanasdf",
"html_url": "https://github.com/jonathanasdf",
"followers_url": "https://api.github.com/u... | [] | closed | false | [] | null | [
"Yes `interleave_datasets` seems to have an issue with shuffling, could you open a new issue on this ?\r\n\r\nThen regarding the deadlock, it has to do with interleave_dataset with probabilities=[1, 0] with workers that may contain an empty dataset in first position (it can be empty since you distribute 1024 shard ... | 2024-09-12 18:59:33 | 2024-09-23 09:32:27 | 2024-09-21 17:37:34 | null | NONE | [] | null | null | null | null | ### Describe the bug
```
import datasets
import torch.utils.data
num_shards = 1024
def gen(shards):
for shard in shards:
if shard < 25:
yield {"shard": shard}
def main():
dataset = datasets.IterableDataset.from_generator(
gen,
gen_kwargs={"shards": lis... | {
"login": "jonathanasdf",
"id": 511073,
"node_id": "MDQ6VXNlcjUxMTA3Mw==",
"avatar_url": "https://avatars.githubusercontent.com/u/511073?v=4",
"gravatar_id": "",
"url": "https://api.github.com/users/jonathanasdf",
"html_url": "https://github.com/jonathanasdf",
"followers_url": "https://api.github.com/u... | {
"url": "https://api.github.com/repos/huggingface/datasets/issues/7147/reactions",
"total_count": 0,
"+1": 0,
"-1": 0,
"laugh": 0,
"hooray": 0,
"confused": 0,
"heart": 0,
"rocket": 0,
"eyes": 0
} | https://api.github.com/repos/huggingface/datasets/issues/7147/timeline | null | completed | {"total":0,"completed":0,"percent_completed":0} | {"blocked_by":0,"total_blocked_by":0,"blocking":0,"total_blocking":0} | null | false |
https://api.github.com/repos/huggingface/datasets/issues/7142 | https://api.github.com/repos/huggingface/datasets | https://api.github.com/repos/huggingface/datasets/issues/7142/labels{/name} | https://api.github.com/repos/huggingface/datasets/issues/7142/comments | https://api.github.com/repos/huggingface/datasets/issues/7142/events | https://github.com/huggingface/datasets/issues/7142 | 2,512,244,938 | I_kwDODunzps6VvdDK | 7,142 | Specifying datatype when adding a column to a dataset. | {
"login": "varadhbhatnagar",
"id": 20443618,
"node_id": "MDQ6VXNlcjIwNDQzNjE4",
"avatar_url": "https://avatars.githubusercontent.com/u/20443618?v=4",
"gravatar_id": "",
"url": "https://api.github.com/users/varadhbhatnagar",
"html_url": "https://github.com/varadhbhatnagar",
"followers_url": "https://api... | [
{
"id": 1935892871,
"node_id": "MDU6TGFiZWwxOTM1ODkyODcx",
"url": "https://api.github.com/repos/huggingface/datasets/labels/enhancement",
"name": "enhancement",
"color": "a2eeef",
"default": true,
"description": "New feature or request",
"archived_at": null,
"archived_by": null
... | closed | false | [] | null | [
"#self-assign"
] | 2024-09-08 07:34:24 | 2024-09-17 03:46:32 | 2024-09-17 03:46:32 | null | CONTRIBUTOR | [] | null | null | null | null | ### Feature request
There should be a way to specify the datatype of a column in `datasets.add_column()`.
### Motivation
To specify a custom datatype, we have to use `datasets.add_column()` followed by `datasets.cast_column()` which is slow for large datasets. Another workaround is to pass a `numpy.array()` of desi... | {
"login": "varadhbhatnagar",
"id": 20443618,
"node_id": "MDQ6VXNlcjIwNDQzNjE4",
"avatar_url": "https://avatars.githubusercontent.com/u/20443618?v=4",
"gravatar_id": "",
"url": "https://api.github.com/users/varadhbhatnagar",
"html_url": "https://github.com/varadhbhatnagar",
"followers_url": "https://api... | {
"url": "https://api.github.com/repos/huggingface/datasets/issues/7142/reactions",
"total_count": 0,
"+1": 0,
"-1": 0,
"laugh": 0,
"hooray": 0,
"confused": 0,
"heart": 0,
"rocket": 0,
"eyes": 0
} | https://api.github.com/repos/huggingface/datasets/issues/7142/timeline | null | completed | {"total":0,"completed":0,"percent_completed":0} | {"blocked_by":0,"total_blocked_by":0,"blocking":0,"total_blocking":0} | null | false |
https://api.github.com/repos/huggingface/datasets/issues/7141 | https://api.github.com/repos/huggingface/datasets | https://api.github.com/repos/huggingface/datasets/issues/7141/labels{/name} | https://api.github.com/repos/huggingface/datasets/issues/7141/comments | https://api.github.com/repos/huggingface/datasets/issues/7141/events | https://github.com/huggingface/datasets/issues/7141 | 2,510,797,653 | I_kwDODunzps6Vp7tV | 7,141 | Older datasets throwing safety errors with 2.21.0 | {
"login": "alvations",
"id": 1050316,
"node_id": "MDQ6VXNlcjEwNTAzMTY=",
"avatar_url": "https://avatars.githubusercontent.com/u/1050316?v=4",
"gravatar_id": "",
"url": "https://api.github.com/users/alvations",
"html_url": "https://github.com/alvations",
"followers_url": "https://api.github.com/users/al... | [] | closed | false | [] | null | [
"I am also getting this error with this dataset: https://huggingface.co/datasets/google/IFEval",
"Me too, didn't have this issue few hours ago.",
"same observation. I even downgraded `datasets==2.20.0` and `huggingface_hub==0.23.5` leading me to believe it's an issue on the server.\r\n\r\nany known workarounds?... | 2024-09-06 16:26:30 | 2024-09-06 21:14:14 | 2024-09-06 19:09:29 | null | NONE | [] | null | null | null | null | ### Describe the bug
The dataset loading was throwing some safety errors for this popular dataset `wmt14`.
[in]:
```
import datasets
# train_data = datasets.load_dataset("wmt14", "de-en", split="train")
train_data = datasets.load_dataset("wmt14", "de-en", split="train")
val_data = datasets.load_dataset(... | {
"login": "muellerzr",
"id": 7831895,
"node_id": "MDQ6VXNlcjc4MzE4OTU=",
"avatar_url": "https://avatars.githubusercontent.com/u/7831895?v=4",
"gravatar_id": "",
"url": "https://api.github.com/users/muellerzr",
"html_url": "https://github.com/muellerzr",
"followers_url": "https://api.github.com/users/mu... | {
"url": "https://api.github.com/repos/huggingface/datasets/issues/7141/reactions",
"total_count": 29,
"+1": 26,
"-1": 0,
"laugh": 0,
"hooray": 0,
"confused": 3,
"heart": 0,
"rocket": 0,
"eyes": 0
} | https://api.github.com/repos/huggingface/datasets/issues/7141/timeline | null | completed | {"total":0,"completed":0,"percent_completed":0} | {"blocked_by":0,"total_blocked_by":0,"blocking":0,"total_blocking":0} | null | false |
https://api.github.com/repos/huggingface/datasets/issues/7139 | https://api.github.com/repos/huggingface/datasets | https://api.github.com/repos/huggingface/datasets/issues/7139/labels{/name} | https://api.github.com/repos/huggingface/datasets/issues/7139/comments | https://api.github.com/repos/huggingface/datasets/issues/7139/events | https://github.com/huggingface/datasets/issues/7139 | 2,508,078,858 | I_kwDODunzps6Vfj8K | 7,139 | Use load_dataset to load imagenet-1K But find a empty dataset | {
"login": "fscdc",
"id": 105094708,
"node_id": "U_kgDOBkOeNA",
"avatar_url": "https://avatars.githubusercontent.com/u/105094708?v=4",
"gravatar_id": "",
"url": "https://api.github.com/users/fscdc",
"html_url": "https://github.com/fscdc",
"followers_url": "https://api.github.com/users/fscdc/followers",
... | [] | open | false | [] | null | [
"Imagenet-1k is a gated dataset which means you’ll have to agree to share your contact info to access it. Have you tried this yet? Once you have, you can sign in with your user token (you can find this in your Hugging Face account settings) when prompted by running.\r\n\r\n```\r\nhuggingface-cli login\r\ntrain_set... | 2024-09-05 15:12:22 | 2024-10-09 04:02:41 | null | null | NONE | [] | null | null | null | null | ### Describe the bug
```python
def get_dataset(data_path, train_folder="train", val_folder="val"):
traindir = os.path.join(data_path, train_folder)
valdir = os.path.join(data_path, val_folder)
def transform_val_examples(examples):
transform = Compose([
Resize(256),
... | null | {
"url": "https://api.github.com/repos/huggingface/datasets/issues/7139/reactions",
"total_count": 0,
"+1": 0,
"-1": 0,
"laugh": 0,
"hooray": 0,
"confused": 0,
"heart": 0,
"rocket": 0,
"eyes": 0
} | https://api.github.com/repos/huggingface/datasets/issues/7139/timeline | null | null | {"total":0,"completed":0,"percent_completed":0} | {"blocked_by":0,"total_blocked_by":0,"blocking":0,"total_blocking":0} | null | false |
https://api.github.com/repos/huggingface/datasets/issues/7138 | https://api.github.com/repos/huggingface/datasets | https://api.github.com/repos/huggingface/datasets/issues/7138/labels{/name} | https://api.github.com/repos/huggingface/datasets/issues/7138/comments | https://api.github.com/repos/huggingface/datasets/issues/7138/events | https://github.com/huggingface/datasets/issues/7138 | 2,507,738,308 | I_kwDODunzps6VeQzE | 7,138 | Cache only changed columns? | {
"login": "Modexus",
"id": 37351874,
"node_id": "MDQ6VXNlcjM3MzUxODc0",
"avatar_url": "https://avatars.githubusercontent.com/u/37351874?v=4",
"gravatar_id": "",
"url": "https://api.github.com/users/Modexus",
"html_url": "https://github.com/Modexus",
"followers_url": "https://api.github.com/users/Modexu... | [
{
"id": 1935892871,
"node_id": "MDU6TGFiZWwxOTM1ODkyODcx",
"url": "https://api.github.com/repos/huggingface/datasets/labels/enhancement",
"name": "enhancement",
"color": "a2eeef",
"default": true,
"description": "New feature or request",
"archived_at": null,
"archived_by": null
... | open | false | [] | null | [
"so I guess a workaround to this is to simply remove all columns except the ones to cache and then add them back with `concatenate_datasets(..., axis=1)`.",
"yes this is the right workaround. We're keeping the cache like this to make it easier for people to delete intermediate cache files"
] | 2024-09-05 12:56:47 | 2024-09-20 13:27:20 | null | null | CONTRIBUTOR | [] | null | null | null | null | ### Feature request
Cache only the actual changes to the dataset i.e. changed columns.
### Motivation
I realized that caching actually saves the complete dataset again.
This is especially problematic for image datasets if one wants to only change another column e.g. some metadata and then has to save 5 TB again.
#... | null | {
"url": "https://api.github.com/repos/huggingface/datasets/issues/7138/reactions",
"total_count": 0,
"+1": 0,
"-1": 0,
"laugh": 0,
"hooray": 0,
"confused": 0,
"heart": 0,
"rocket": 0,
"eyes": 0
} | https://api.github.com/repos/huggingface/datasets/issues/7138/timeline | null | null | {"total":0,"completed":0,"percent_completed":0} | {"blocked_by":0,"total_blocked_by":0,"blocking":0,"total_blocking":0} | null | false |
https://api.github.com/repos/huggingface/datasets/issues/7137 | https://api.github.com/repos/huggingface/datasets | https://api.github.com/repos/huggingface/datasets/issues/7137/labels{/name} | https://api.github.com/repos/huggingface/datasets/issues/7137/comments | https://api.github.com/repos/huggingface/datasets/issues/7137/events | https://github.com/huggingface/datasets/issues/7137 | 2,506,851,048 | I_kwDODunzps6Va4Lo | 7,137 | [BUG] dataset_info sequence unexpected behavior in README.md YAML | {
"login": "ain-soph",
"id": 13214530,
"node_id": "MDQ6VXNlcjEzMjE0NTMw",
"avatar_url": "https://avatars.githubusercontent.com/u/13214530?v=4",
"gravatar_id": "",
"url": "https://api.github.com/users/ain-soph",
"html_url": "https://github.com/ain-soph",
"followers_url": "https://api.github.com/users/ain... | [] | closed | false | [] | null | [
"The non-sequence case works well (`dict[str, str]` instead of `list[dict[str, str]]`), which makes me believe it shall be a bug for `sequence` and my proposed behavior shall be expected.\r\n```\r\ndataset_info:\r\n- config_name: default\r\n features:\r\n - name: answers\r\n dtype:\r\n - name: text\r\n ... | 2024-09-05 06:06:06 | 2025-07-07 09:20:29 | 2025-07-04 19:50:59 | null | CONTRIBUTOR | [] | null | null | null | null | ### Describe the bug
When working on `dataset_info` yaml, I find my data column with format `list[dict[str, str]]` cannot be coded correctly.
My data looks like
```
{"answers":[{"text": "ADDRESS", "label": "abc"}]}
```
My `dataset_info` in README.md is:
```
dataset_info:
- config_name: default
feature... | {
"login": "ain-soph",
"id": 13214530,
"node_id": "MDQ6VXNlcjEzMjE0NTMw",
"avatar_url": "https://avatars.githubusercontent.com/u/13214530?v=4",
"gravatar_id": "",
"url": "https://api.github.com/users/ain-soph",
"html_url": "https://github.com/ain-soph",
"followers_url": "https://api.github.com/users/ain... | {
"url": "https://api.github.com/repos/huggingface/datasets/issues/7137/reactions",
"total_count": 0,
"+1": 0,
"-1": 0,
"laugh": 0,
"hooray": 0,
"confused": 0,
"heart": 0,
"rocket": 0,
"eyes": 0
} | https://api.github.com/repos/huggingface/datasets/issues/7137/timeline | null | completed | {"total":0,"completed":0,"percent_completed":0} | {"blocked_by":0,"total_blocked_by":0,"blocking":0,"total_blocking":0} | null | false |
https://api.github.com/repos/huggingface/datasets/issues/7135 | https://api.github.com/repos/huggingface/datasets | https://api.github.com/repos/huggingface/datasets/issues/7135/labels{/name} | https://api.github.com/repos/huggingface/datasets/issues/7135/comments | https://api.github.com/repos/huggingface/datasets/issues/7135/events | https://github.com/huggingface/datasets/issues/7135 | 2,503,318,328 | I_kwDODunzps6VNZs4 | 7,135 | Bug: Type Mismatch in Dataset Mapping | {
"login": "marko1616",
"id": 45327989,
"node_id": "MDQ6VXNlcjQ1MzI3OTg5",
"avatar_url": "https://avatars.githubusercontent.com/u/45327989?v=4",
"gravatar_id": "",
"url": "https://api.github.com/users/marko1616",
"html_url": "https://github.com/marko1616",
"followers_url": "https://api.github.com/users/... | [] | open | false | [] | null | [
"By the way, following code is working. This show the inconsistentcy.\r\n```python\r\nfrom datasets import Dataset\r\n\r\n# Original data\r\ndata = {\r\n 'text': ['Hello', 'world', 'this', 'is', 'a', 'test'],\r\n 'label': [0, 1, 0, 1, 1, 0]\r\n}\r\n\r\n# Creating a Dataset object\r\ndataset = Dataset.from_dic... | 2024-09-03 16:37:01 | 2024-09-05 14:09:05 | null | null | NONE | [] | null | null | null | null | # Issue: Type Mismatch in Dataset Mapping
## Description
There is an issue with the `map` function in the `datasets` library where the mapped output does not reflect the expected type change. After applying a mapping function to convert an integer label to a string, the resulting type remains an integer instead of ... | null | {
"url": "https://api.github.com/repos/huggingface/datasets/issues/7135/reactions",
"total_count": 0,
"+1": 0,
"-1": 0,
"laugh": 0,
"hooray": 0,
"confused": 0,
"heart": 0,
"rocket": 0,
"eyes": 0
} | https://api.github.com/repos/huggingface/datasets/issues/7135/timeline | null | null | {"total":0,"completed":0,"percent_completed":0} | {"blocked_by":0,"total_blocked_by":0,"blocking":0,"total_blocking":0} | null | false |
https://api.github.com/repos/huggingface/datasets/issues/7128 | https://api.github.com/repos/huggingface/datasets | https://api.github.com/repos/huggingface/datasets/issues/7128/labels{/name} | https://api.github.com/repos/huggingface/datasets/issues/7128/comments | https://api.github.com/repos/huggingface/datasets/issues/7128/events | https://github.com/huggingface/datasets/issues/7128 | 2,490,274,775 | I_kwDODunzps6UbpPX | 7,128 | Filter Large Dataset Entry by Entry | {
"login": "QiyaoWei",
"id": 36057290,
"node_id": "MDQ6VXNlcjM2MDU3Mjkw",
"avatar_url": "https://avatars.githubusercontent.com/u/36057290?v=4",
"gravatar_id": "",
"url": "https://api.github.com/users/QiyaoWei",
"html_url": "https://github.com/QiyaoWei",
"followers_url": "https://api.github.com/users/Qiy... | [
{
"id": 1935892871,
"node_id": "MDU6TGFiZWwxOTM1ODkyODcx",
"url": "https://api.github.com/repos/huggingface/datasets/labels/enhancement",
"name": "enhancement",
"color": "a2eeef",
"default": true,
"description": "New feature or request",
"archived_at": null,
"archived_by": null
... | open | false | [] | null | [
"Hi ! you can do\r\n\r\n```python\r\nfiltered_dataset = dataset.filter(filter_function)\r\n```\r\n\r\non a subset:\r\n\r\n```python\r\nfiltered_subset = dataset.select(range(10_000)).filter(filter_function)\r\n```\r\n",
"Jumping on this as it seems relevant - when I use the `filter` method, it often results in an... | 2024-08-27 20:31:09 | 2024-10-07 23:37:44 | null | null | NONE | [] | null | null | null | null | ### Feature request
I am not sure if this is a new feature, but I wanted to post this problem here, and hear if others have ways of optimizing and speeding up this process.
Let's say I have a really large dataset that I cannot load into memory. At this point, I am only aware of `streaming=True` to load the dataset.... | null | {
"url": "https://api.github.com/repos/huggingface/datasets/issues/7128/reactions",
"total_count": 0,
"+1": 0,
"-1": 0,
"laugh": 0,
"hooray": 0,
"confused": 0,
"heart": 0,
"rocket": 0,
"eyes": 0
} | https://api.github.com/repos/huggingface/datasets/issues/7128/timeline | null | null | {"total":0,"completed":0,"percent_completed":0} | {"blocked_by":0,"total_blocked_by":0,"blocking":0,"total_blocking":0} | null | false |
https://api.github.com/repos/huggingface/datasets/issues/7127 | https://api.github.com/repos/huggingface/datasets | https://api.github.com/repos/huggingface/datasets/issues/7127/labels{/name} | https://api.github.com/repos/huggingface/datasets/issues/7127/comments | https://api.github.com/repos/huggingface/datasets/issues/7127/events | https://github.com/huggingface/datasets/issues/7127 | 2,486,524,966 | I_kwDODunzps6UNVwm | 7,127 | Caching shuffles by np.random.Generator results in unintiutive behavior | {
"login": "el-hult",
"id": 11832922,
"node_id": "MDQ6VXNlcjExODMyOTIy",
"avatar_url": "https://avatars.githubusercontent.com/u/11832922?v=4",
"gravatar_id": "",
"url": "https://api.github.com/users/el-hult",
"html_url": "https://github.com/el-hult",
"followers_url": "https://api.github.com/users/el-hul... | [] | closed | false | [] | null | [
"I first thought this was a mistake of mine, and also posted on stack overflow. https://stackoverflow.com/questions/78913797/iterating-a-huggingface-dataset-from-disk-using-generator-seems-broken-how-to-d \r\n\r\nIt seems to me the issue is the caching step in \r\n\r\nhttps://github.com/huggingface/datasets/blob/be... | 2024-08-26 10:29:48 | 2026-09-10 13:34:25 | 2026-09-10 13:34:25 | null | NONE | [] | null | null | null | null | ### Describe the bug
Create a dataset. Save it to disk. Load from disk. Shuffle, usning a `np.random.Generator`. Iterate. Shuffle again. Iterate. The iterates are different since the supplied np.random.Generator has progressed between the shuffles.
Load dataset from disk again. Shuffle and Iterate. See same result ... | {
"login": "lhoestq",
"id": 42851186,
"node_id": "MDQ6VXNlcjQyODUxMTg2",
"avatar_url": "https://avatars.githubusercontent.com/u/42851186?v=4",
"gravatar_id": "",
"url": "https://api.github.com/users/lhoestq",
"html_url": "https://github.com/lhoestq",
"followers_url": "https://api.github.com/users/lhoest... | {
"url": "https://api.github.com/repos/huggingface/datasets/issues/7127/reactions",
"total_count": 0,
"+1": 0,
"-1": 0,
"laugh": 0,
"hooray": 0,
"confused": 0,
"heart": 0,
"rocket": 0,
"eyes": 0
} | https://api.github.com/repos/huggingface/datasets/issues/7127/timeline | null | completed | {"total":0,"completed":0,"percent_completed":0} | {"blocked_by":0,"total_blocked_by":0,"blocking":0,"total_blocking":0} | null | false |
https://api.github.com/repos/huggingface/datasets/issues/7123 | https://api.github.com/repos/huggingface/datasets | https://api.github.com/repos/huggingface/datasets/issues/7123/labels{/name} | https://api.github.com/repos/huggingface/datasets/issues/7123/comments | https://api.github.com/repos/huggingface/datasets/issues/7123/events | https://github.com/huggingface/datasets/issues/7123 | 2,484,003,937 | I_kwDODunzps6UDuRh | 7,123 | Make dataset viewer more flexible in displaying metadata alongside images | {
"login": "egrace479",
"id": 38985481,
"node_id": "MDQ6VXNlcjM4OTg1NDgx",
"avatar_url": "https://avatars.githubusercontent.com/u/38985481?v=4",
"gravatar_id": "",
"url": "https://api.github.com/users/egrace479",
"html_url": "https://github.com/egrace479",
"followers_url": "https://api.github.com/users/... | [
{
"id": 1935892871,
"node_id": "MDU6TGFiZWwxOTM1ODkyODcx",
"url": "https://api.github.com/repos/huggingface/datasets/labels/enhancement",
"name": "enhancement",
"color": "a2eeef",
"default": true,
"description": "New feature or request",
"archived_at": null,
"archived_by": null
... | open | false | [] | null | [
"Note that you can already have one directory per subset just for the metadata, e.g.\r\n\r\n```\r\nconfigs:\r\n - config_name: subset0\r\n data_files:\r\n - subset0/metadata.csv\r\n - images/*.jpg\r\n - config_name: subset1\r\n data_files:\r\n - subset1/metadata.csv\r\n - images/*.jpg\r\... | 2024-08-23 22:56:01 | 2024-10-17 09:13:47 | null | null | NONE | [] | null | null | null | null | ### Feature request
To display images with their associated metadata in the dataset viewer, a `metadata.csv` file is required. In the case of a dataset with multiple subsets, this would require the CSVs to be contained in the same folder as the images since they all need to be named `metadata.csv`. The request is th... | null | {
"url": "https://api.github.com/repos/huggingface/datasets/issues/7123/reactions",
"total_count": 0,
"+1": 0,
"-1": 0,
"laugh": 0,
"hooray": 0,
"confused": 0,
"heart": 0,
"rocket": 0,
"eyes": 0
} | https://api.github.com/repos/huggingface/datasets/issues/7123/timeline | null | null | {"total":0,"completed":0,"percent_completed":0} | {"blocked_by":0,"total_blocked_by":0,"blocking":0,"total_blocking":0} | null | false |
https://api.github.com/repos/huggingface/datasets/issues/7117 | https://api.github.com/repos/huggingface/datasets | https://api.github.com/repos/huggingface/datasets/issues/7117/labels{/name} | https://api.github.com/repos/huggingface/datasets/issues/7117/comments | https://api.github.com/repos/huggingface/datasets/issues/7117/events | https://github.com/huggingface/datasets/issues/7117 | 2,476,555,659 | I_kwDODunzps6TnT2L | 7,117 | Audio dataset load everything in RAM and is very slow | {
"login": "Jourdelune",
"id": 64205064,
"node_id": "MDQ6VXNlcjY0MjA1MDY0",
"avatar_url": "https://avatars.githubusercontent.com/u/64205064?v=4",
"gravatar_id": "",
"url": "https://api.github.com/users/Jourdelune",
"html_url": "https://github.com/Jourdelune",
"followers_url": "https://api.github.com/use... | [] | open | false | [] | null | [
"Hi ! I think the issue comes from the fact that you return `row` entirely, and therefore the dataset has to re-encode the audio data in `row`.\r\n\r\nCan you try this instead ?\r\n\r\n```python\r\n# map the dataset\r\ndef transcribe_audio(row):\r\n audio = row[\"audio\"] # get the audio but do nothing with it\... | 2024-08-20 21:18:12 | 2024-08-26 13:11:55 | null | null | NONE | [] | null | null | null | null | Hello, I'm working with an audio dataset. I want to transcribe the audio that the dataset contain, and for that I use whisper. My issue is that the dataset load everything in the RAM when I map the dataset, obviously, when RAM usage is too high, the program crashes.
To fix this issue, I'm using writer_batch_size tha... | null | {
"url": "https://api.github.com/repos/huggingface/datasets/issues/7117/reactions",
"total_count": 0,
"+1": 0,
"-1": 0,
"laugh": 0,
"hooray": 0,
"confused": 0,
"heart": 0,
"rocket": 0,
"eyes": 0
} | https://api.github.com/repos/huggingface/datasets/issues/7117/timeline | null | null | {"total":0,"completed":0,"percent_completed":0} | {"blocked_by":0,"total_blocked_by":0,"blocking":0,"total_blocking":0} | null | false |
https://api.github.com/repos/huggingface/datasets/issues/7116 | https://api.github.com/repos/huggingface/datasets | https://api.github.com/repos/huggingface/datasets/issues/7116/labels{/name} | https://api.github.com/repos/huggingface/datasets/issues/7116/comments | https://api.github.com/repos/huggingface/datasets/issues/7116/events | https://github.com/huggingface/datasets/issues/7116 | 2,475,522,721 | I_kwDODunzps6TjXqh | 7,116 | datasets cannot handle nested json if features is given. | {
"login": "ljw20180420",
"id": 38550511,
"node_id": "MDQ6VXNlcjM4NTUwNTEx",
"avatar_url": "https://avatars.githubusercontent.com/u/38550511?v=4",
"gravatar_id": "",
"url": "https://api.github.com/users/ljw20180420",
"html_url": "https://github.com/ljw20180420",
"followers_url": "https://api.github.com/... | [] | closed | false | [] | null | [
"Hi ! `Sequence` has a weird behavior for dictionaries (from tensorflow-datasets), use a regular list instead:\r\n\r\n```python\r\nds = datasets.load_dataset('json', data_files=\"./temp.json\", features=datasets.Features({\r\n 'ref1': datasets.Value('string'),\r\n 'ref2': datasets.Value('string'),\r\n 'cut... | 2024-08-20 12:27:49 | 2024-09-03 10:18:23 | 2024-09-03 10:18:07 | null | NONE | [] | null | null | null | null | ### Describe the bug
I have a json named temp.json.
```json
{"ref1": "ABC", "ref2": "DEF", "cuts":[{"cut1": 3, "cut2": 5}]}
```
I want to load it.
```python
ds = datasets.load_dataset('json', data_files="./temp.json", features=datasets.Features({
'ref1': datasets.Value('string'),
'ref2': datasets.Value... | {
"login": "ljw20180420",
"id": 38550511,
"node_id": "MDQ6VXNlcjM4NTUwNTEx",
"avatar_url": "https://avatars.githubusercontent.com/u/38550511?v=4",
"gravatar_id": "",
"url": "https://api.github.com/users/ljw20180420",
"html_url": "https://github.com/ljw20180420",
"followers_url": "https://api.github.com/... | {
"url": "https://api.github.com/repos/huggingface/datasets/issues/7116/reactions",
"total_count": 0,
"+1": 0,
"-1": 0,
"laugh": 0,
"hooray": 0,
"confused": 0,
"heart": 0,
"rocket": 0,
"eyes": 0
} | https://api.github.com/repos/huggingface/datasets/issues/7116/timeline | null | completed | {"total":0,"completed":0,"percent_completed":0} | {"blocked_by":0,"total_blocked_by":0,"blocking":0,"total_blocking":0} | null | false |
https://api.github.com/repos/huggingface/datasets/issues/7115 | https://api.github.com/repos/huggingface/datasets | https://api.github.com/repos/huggingface/datasets/issues/7115/labels{/name} | https://api.github.com/repos/huggingface/datasets/issues/7115/comments | https://api.github.com/repos/huggingface/datasets/issues/7115/events | https://github.com/huggingface/datasets/issues/7115 | 2,475,363,142 | I_kwDODunzps6TiwtG | 7,115 | module 'pyarrow.lib' has no attribute 'ListViewType' | {
"login": "ghost",
"id": 10137,
"node_id": "MDQ6VXNlcjEwMTM3",
"avatar_url": "https://avatars.githubusercontent.com/u/10137?v=4",
"gravatar_id": "",
"url": "https://api.github.com/users/ghost",
"html_url": "https://github.com/ghost",
"followers_url": "https://api.github.com/users/ghost/followers",
"f... | [] | closed | false | [] | null | [
"https://github.com/neurafusionai/Hugging_Face/blob/main/meta_opt_350m_customer_support_lora_v1.ipynb\r\n\r\ncouldnt train because of GPU\r\nI didnt pip install datasets -U\r\nbut looks like restarting worked"
] | 2024-08-20 11:05:44 | 2024-09-10 06:51:08 | 2024-09-10 06:51:08 | null | NONE | [] | null | null | null | null | ### Describe the bug
Code:
`!pipuninstall -y pyarrow
!pip install --no-cache-dir pyarrow
!pip uninstall -y pyarrow
!pip install pyarrow --no-cache-dir
!pip install --upgrade datasets transformers pyarrow
!pip install pyarrow.parquet
! pip install pyarrow-core libparquet
!pip install pyarrow --no-cache-di... | {
"login": "albertvillanova",
"id": 8515462,
"node_id": "MDQ6VXNlcjg1MTU0NjI=",
"avatar_url": "https://avatars.githubusercontent.com/u/8515462?v=4",
"gravatar_id": "",
"url": "https://api.github.com/users/albertvillanova",
"html_url": "https://github.com/albertvillanova",
"followers_url": "https://api.g... | {
"url": "https://api.github.com/repos/huggingface/datasets/issues/7115/reactions",
"total_count": 0,
"+1": 0,
"-1": 0,
"laugh": 0,
"hooray": 0,
"confused": 0,
"heart": 0,
"rocket": 0,
"eyes": 0
} | https://api.github.com/repos/huggingface/datasets/issues/7115/timeline | null | completed | {"total":0,"completed":0,"percent_completed":0} | {"blocked_by":0,"total_blocked_by":0,"blocking":0,"total_blocking":0} | null | false |
https://api.github.com/repos/huggingface/datasets/issues/7113 | https://api.github.com/repos/huggingface/datasets | https://api.github.com/repos/huggingface/datasets/issues/7113/labels{/name} | https://api.github.com/repos/huggingface/datasets/issues/7113/comments | https://api.github.com/repos/huggingface/datasets/issues/7113/events | https://github.com/huggingface/datasets/issues/7113 | 2,475,029,640 | I_kwDODunzps6ThfSI | 7,113 | Stream dataset does not iterate if the batch size is larger than the dataset size (related to drop_last_batch) | {
"login": "memray",
"id": 4197249,
"node_id": "MDQ6VXNlcjQxOTcyNDk=",
"avatar_url": "https://avatars.githubusercontent.com/u/4197249?v=4",
"gravatar_id": "",
"url": "https://api.github.com/users/memray",
"html_url": "https://github.com/memray",
"followers_url": "https://api.github.com/users/memray/foll... | [] | closed | false | [] | null | [
"That's expected behavior, it's also the same in `torch`:\r\n\r\n```python\r\n>>> list(DataLoader(list(range(5)), batch_size=10, drop_last=True))\r\n[]\r\n```"
] | 2024-08-20 08:26:40 | 2024-08-26 04:24:11 | 2024-08-26 04:24:10 | null | NONE | [] | null | null | null | null | ### Describe the bug
Hi there,
I use streaming and interleaving to combine multiple datasets saved in jsonl files. The size of dataset can vary (from 100ish to 100k-ish). I use dataset.map() and a big batch size to reduce the IO cost. It was working fine with datasets-2.16.1 but this problem shows up after I upgr... | {
"login": "albertvillanova",
"id": 8515462,
"node_id": "MDQ6VXNlcjg1MTU0NjI=",
"avatar_url": "https://avatars.githubusercontent.com/u/8515462?v=4",
"gravatar_id": "",
"url": "https://api.github.com/users/albertvillanova",
"html_url": "https://github.com/albertvillanova",
"followers_url": "https://api.g... | {
"url": "https://api.github.com/repos/huggingface/datasets/issues/7113/reactions",
"total_count": 0,
"+1": 0,
"-1": 0,
"laugh": 0,
"hooray": 0,
"confused": 0,
"heart": 0,
"rocket": 0,
"eyes": 0
} | https://api.github.com/repos/huggingface/datasets/issues/7113/timeline | null | completed | {"total":0,"completed":0,"percent_completed":0} | {"blocked_by":0,"total_blocked_by":0,"blocking":0,"total_blocking":0} | null | false |
Subsets and Splits
No community queries yet
The top public SQL queries from the community will appear here once available.