
_id large_stringlengths 24 24 | hash large_stringlengths 16 16 | vocab_hash large_stringlengths 16 16 | vocab_size int64 1 2.4M | model_type large_stringclasses 4
values | num_merges float64 0 4.41M ⌀ | has_normalizer bool 2
classes | has_pre_tokenizer bool 2
classes | has_post_processor bool 2
classes | has_decoder bool 2
classes | num_added_tokens int64 0 479k | normalizer_type large_stringclasses 11
values | pre_tokenizer_type large_stringclasses 10
values | decoder_type large_stringclasses 9
values | normalizer_types listlengths 0 11.3k ⌀ | pre_tokenizer_types listlengths 1 35 ⌀ | decoder_types listlengths 0 24 ⌀ | tokenizer_id int64 0 24.8k | id large_stringlengths 7 122 | author stringlengths 2 41 ⌀ | base_models dict | downloads int64 0 206M | downloads_all_time int64 0 2.81B | gated stringclasses 3
values | created_at timestamp[us, tz=UTC]date 2022-03-02 23:29:04 2025-11-03 14:41:54 | last_modified timestamp[us, tz=UTC]date 2020-12-11 21:34:15 2026-03-29 10:14:05 ⌀ | library_name stringclasses 36
values | likes int64 0 13.1k | trending_score float64 0 47 | model_index stringlengths 30 911k ⌀ | pipeline_tag stringclasses 46
values | safetensors stringlengths 30 122 ⌀ | siblings listlengths 0 10k ⌀ | sha stringlengths 40 40 ⌀ | tags listlengths 2 1.82k ⌀ | gguf stringclasses 789
values | config stringlengths 2 53.7k ⌀ | transformers_info dict | card_data stringlengths 234 905k ⌀ | card stringlengths 0 638k ⌀ | spaces null | licenses listlengths 1 3 ⌀ | datasets listlengths 1 289 ⌀ | languages listlengths 1 1.81k ⌀ | safetensors_params float64 0 1,019B ⌀ | gguf_params float64 0 122B ⌀ | metrics listlengths 1 15 ⌀ | architectures listlengths 1 6 ⌀ | tasks listlengths 1 6 ⌀ | modalities listlengths 1 4 ⌀ | input_modalities listlengths 1 3 ⌀ | output_modalities listlengths 1 4 ⌀ |
|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|
687a0ed7e5feb2efc39a96e2 | 247b76e6aa48f448 | 70bd27c212bc339c | 50,265 | BPE | 50,000 | false | true | true | true | 5 | null | ByteLevel | ByteLevel | null | [
"ByteLevel"
] | [
"ByteLevel"
] | 432 | OpenMed/OpenMed-NER-DNADetect-SuperMedical-125M | OpenMed | null | 185,946 | 1,891,893 | False | 2025-07-18T09:07:35Z | 2025-08-05T09:46:01Z | transformers | 0 | 0 | null | token-classification | {"parameters": {"BF16": 124063499}, "total": 124063499} | [
".gitattributes",
"README.md",
"config.json",
"merges.txt",
"model.safetensors",
"openmed_vs_sota_grouped_bars.png",
"special_tokens_map.json",
"test_results.json",
"tokenizer.json",
"tokenizer_config.json",
"vocab.json"
] | 2c0f34199a82a1c49283491ffffe869c44116434 | [
"transformers",
"safetensors",
"roberta",
"token-classification",
"named-entity-recognition",
"biomedical-nlp",
"protein-recognition",
"gene-recognition",
"molecular-biology",
"genomics",
"dna",
"rna",
"cell_line",
"cell_type",
"protein",
"en",
"arxiv:2508.01630",
"license:apache-2... | null | {"architectures": ["RobertaForTokenClassification"], "model_type": "roberta", "tokenizer_config": {"bos_token": "<s>", "cls_token": "<s>", "eos_token": "</s>", "mask_token": "<mask>", "pad_token": "<pad>", "sep_token": "</s>", "unk_token": "<unk>"}} | {
"auto_model": "AutoModelForTokenClassification",
"custom_class": null,
"pipeline_tag": "token-classification",
"processor": "AutoTokenizer"
} | {"base_model": null, "datasets": null, "eval_results": null, "language": ["en"], "library_name": null, "license": "apache-2.0", "license_name": null, "license_link": null, "metrics": null, "model_name": null, "pipeline_tag": null, "tags": ["token-classification", "named-entity-recognition", "biomedical-nlp", "transform... | # 🧬 [OpenMed-NER-DNADetect-SuperMedical-125M](https://huggingface.co/OpenMed/OpenMed-NER-DNADetect-SuperMedical-125M)
**Specialized model for Biomedical Entity Recognition - Proteins, DNA, RNA, cell lines, and cell types**
[](https://opensource.or... | null | [
"apache-2.0"
] | null | [
"en"
] | 124,063,499 | null | null | [
"roberta",
"AutoModelForTokenClassification",
"RobertaForTokenClassification"
] | [
"token-classification"
] | [
"text"
] | [
"text"
] | [
"logits"
] |
621ffdc136468d709f17eeb6 | 787f7cf5bfa1a4ee | edab60f922c71503 | 32,100 | Unigram | null | true | true | true | true | 103 | Sequence | Metaspace | Metaspace | [
"Precompiled",
"Replace"
] | [
"Metaspace"
] | [
"Metaspace"
] | 433 | pierreguillou/t5-base-qa-squad-v1.1-portuguese | pierreguillou | null | 31 | 658,784 | False | 2022-03-02T23:29:05Z | 2022-01-27T14:38:28Z | transformers | 25 | 0 | [{"name": "checkpoints", "results": [{"task": {"name": "text2text-generation", "type": "text2text-generation"}, "dataset": {"name": "squad", "type": "squad"}, "metrics": [{"name": "f1", "type": "f1", "value": 79.3, "verified": false}, {"name": "exact-match", "type": "exact-match", "value": 67.3983, "verified": false}]}... | null | null | [
".gitattributes",
"README.md",
"config.json",
"pytorch_model.bin",
"special_tokens_map.json",
"spiece.model",
"tokenizer.json",
"tokenizer_config.json",
"training_args.bin"
] | 21c3e49be1ce1a083ba4278427dc7799592ab33c | [
"transformers",
"pytorch",
"t5",
"text2text-generation",
"qa",
"pt",
"dataset:squad",
"dataset:squad_v1_pt",
"model-index",
"text-generation-inference",
"endpoints_compatible",
"deploy:azure",
"region:us"
] | null | {"architectures": ["T5ForConditionalGeneration"], "model_type": "t5", "tokenizer_config": {"eos_token": "</s>", "unk_token": "<unk>", "pad_token": "<pad>"}} | {
"auto_model": "AutoModelForSeq2SeqLM",
"custom_class": null,
"pipeline_tag": "text2text-generation",
"processor": "AutoTokenizer"
} | {"datasets": ["squad", "squad_v1_pt"], "language": ["pt"], "metrics": ["precision", "recall", "f1", "accuracy", "squad"], "tags": ["text2text-generation", "t5", "pytorch", "qa"], "widget": [{"text": "question: Quando come\u00e7ou a pandemia de Covid-19 no mundo? context: A pandemia de COVID-19, tamb\u00e9m conhecida co... | # T5 base finetuned for Question Answering (QA) on SQUaD v1.1 Portuguese
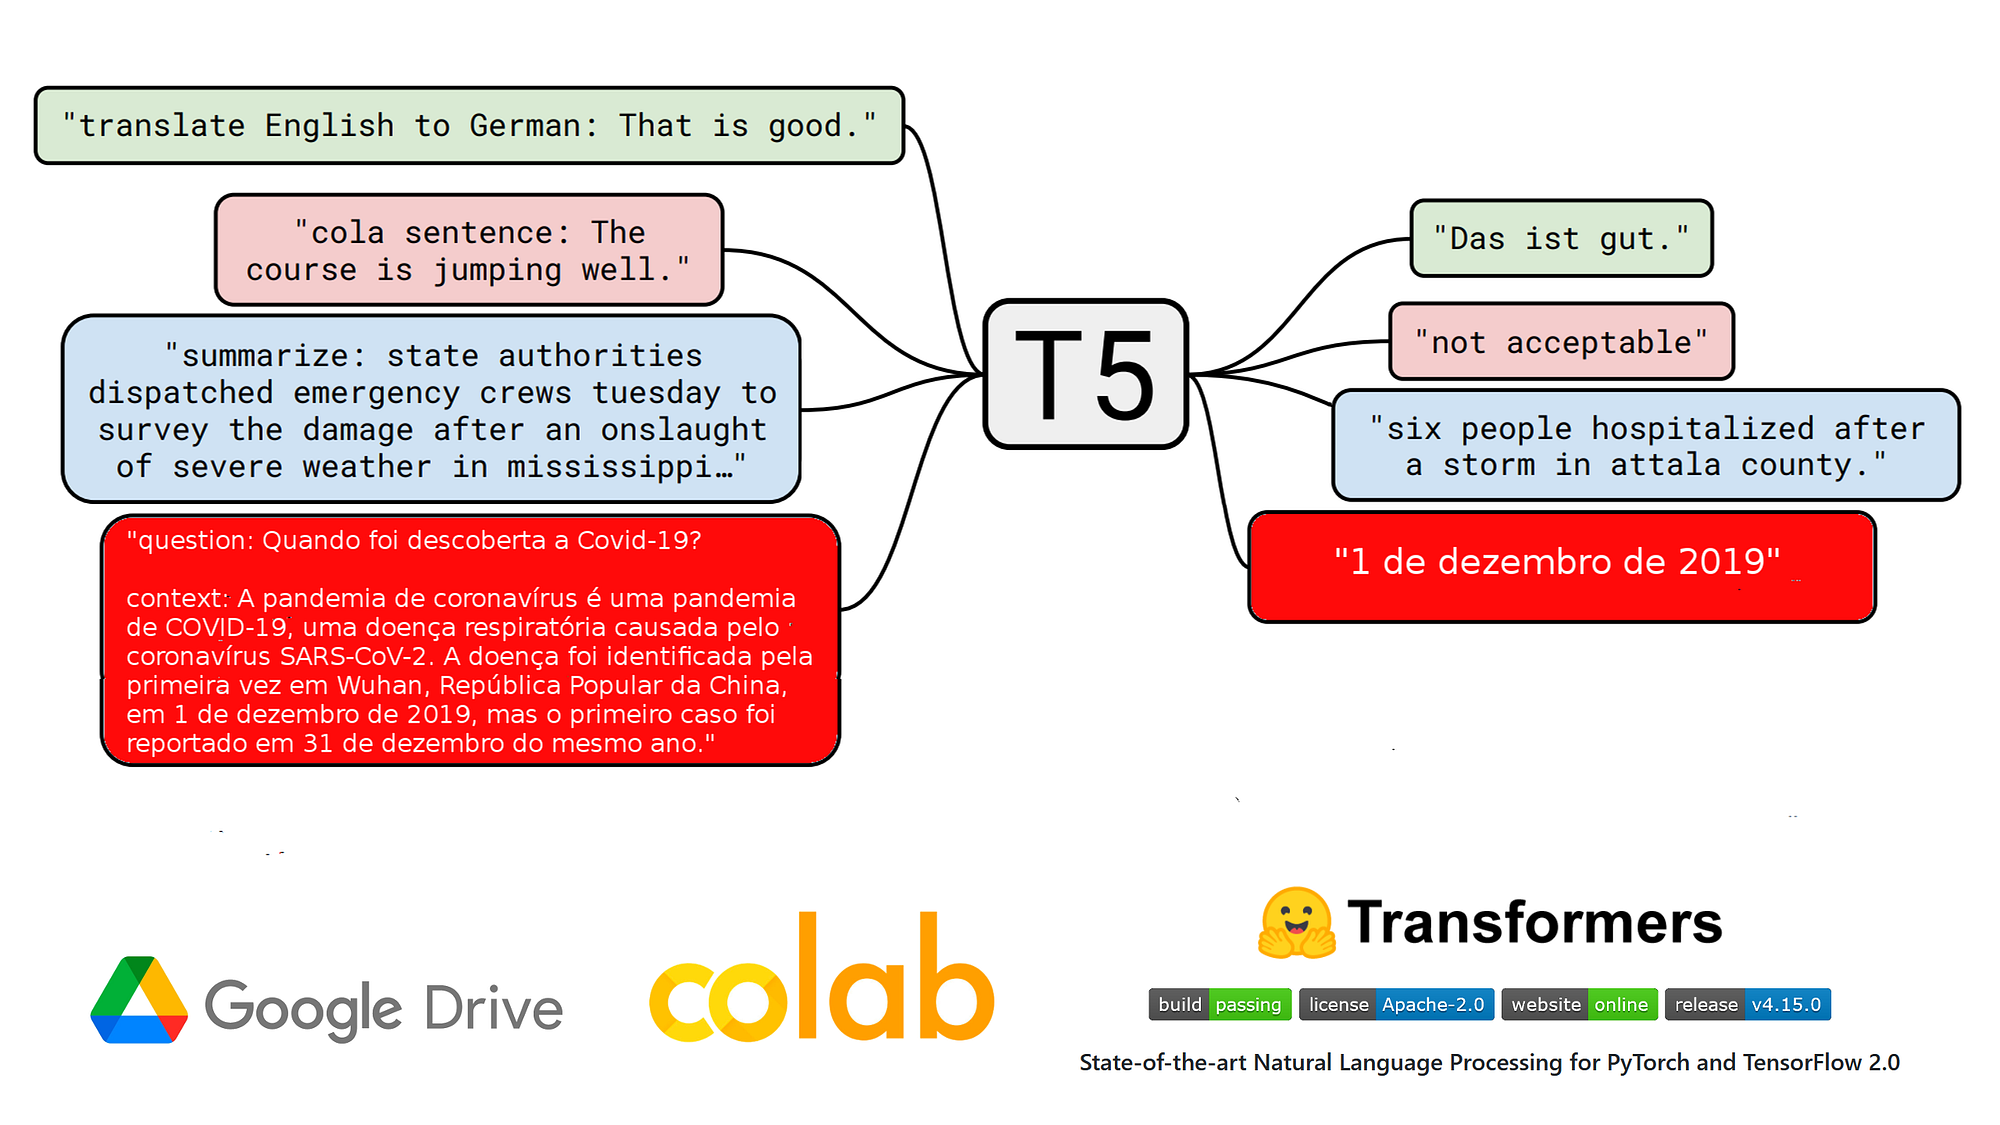
## Introduction
**t5-base-qa-squad-v1.1-portuguese** is a QA model ... | null | null | [
"squad",
"squad_v1_pt"
] | [
"pt"
] | null | null | [
"precision",
"recall",
"f1",
"accuracy",
"squad"
] | [
"t5",
"T5ForConditionalGeneration",
"AutoModelForSeq2SeqLM"
] | [
"text2text-generation"
] | null | null | null |
6878144f4a0209cc20db45b5 | 5b8a6156b5b6e013 | 535fa14da0af647c | 30,522 | WordPiece | null | true | true | true | true | 5 | BertNormalizer | BertPreTokenizer | WordPiece | [
"BertNormalizer"
] | [
"BertPreTokenizer"
] | [
"WordPiece"
] | 37 | OpenMed/OpenMed-NER-SpeciesDetect-ElectraMed-109M | OpenMed | null | 186,217 | 1,884,062 | False | 2025-07-16T21:06:23Z | 2025-08-05T09:42:49Z | transformers | 0 | 0 | null | token-classification | {"parameters": {"BF16": 108893955}, "total": 108893955} | [
".gitattributes",
"README.md",
"config.json",
"model.safetensors",
"openmed_vs_sota_grouped_bars.png",
"special_tokens_map.json",
"test_results.json",
"tokenizer.json",
"tokenizer_config.json",
"vocab.txt"
] | 4d3afc5804a03728a6d87be1f6ffea7186dbf9d7 | [
"transformers",
"safetensors",
"bert",
"token-classification",
"named-entity-recognition",
"biomedical-nlp",
"species-recognition",
"taxonomy",
"organism-identification",
"biology",
"species",
"en",
"arxiv:2508.01630",
"license:apache-2.0",
"endpoints_compatible",
"region:us"
] | null | {"architectures": ["BertForTokenClassification"], "model_type": "bert", "tokenizer_config": {"cls_token": "[CLS]", "mask_token": "[MASK]", "pad_token": "[PAD]", "sep_token": "[SEP]", "unk_token": "[UNK]"}} | {
"auto_model": "AutoModelForTokenClassification",
"custom_class": null,
"pipeline_tag": "token-classification",
"processor": "AutoTokenizer"
} | {"base_model": null, "datasets": null, "eval_results": null, "language": ["en"], "library_name": null, "license": "apache-2.0", "license_name": null, "license_link": null, "metrics": null, "model_name": null, "pipeline_tag": null, "tags": ["token-classification", "named-entity-recognition", "biomedical-nlp", "transform... | null | null | [
"apache-2.0"
] | null | [
"en"
] | 108,893,955 | null | null | [
"AutoModelForTokenClassification",
"BertForTokenClassification",
"bert"
] | [
"token-classification"
] | [
"text"
] | [
"text"
] | [
"logits"
] |
67c35bd50e998b1f7c4d3139 | b86074a73431b347 | 1fe366e13272caa0 | 262,145 | BPE | 514,906 | true | true | true | true | 6,415 | Replace | Split | Sequence | [
"Replace"
] | [
"Split"
] | [
"Replace",
"ByteFallback",
"Fuse"
] | 434 | google/gemma-3-12b-pt | google | null | 29,439 | 800,205 | manual | 2025-03-01T19:11:17Z | 2025-03-21T16:12:21Z | transformers | 88 | 0 | null | image-text-to-text | {"parameters": {"BF16": 12187325040}, "total": 12187325040} | [
".gitattributes",
"README.md",
"added_tokens.json",
"config.json",
"generation_config.json",
"model-00001-of-00005.safetensors",
"model-00002-of-00005.safetensors",
"model-00003-of-00005.safetensors",
"model-00004-of-00005.safetensors",
"model-00005-of-00005.safetensors",
"model.safetensors.inde... | 295efb63d01a7017928f273a94ebb86105c9526f | [
"transformers",
"safetensors",
"gemma3",
"image-text-to-text",
"arxiv:1905.07830",
"arxiv:1905.10044",
"arxiv:1911.11641",
"arxiv:1904.09728",
"arxiv:1705.03551",
"arxiv:1911.01547",
"arxiv:1907.10641",
"arxiv:1903.00161",
"arxiv:2009.03300",
"arxiv:2304.06364",
"arxiv:2103.03874",
"ar... | null | {"architectures": ["Gemma3ForConditionalGeneration"], "model_type": "gemma3", "tokenizer_config": {"bos_token": "<bos>", "eos_token": "<eos>", "pad_token": "<pad>", "unk_token": "<unk>", "use_default_system_prompt": false}} | {
"auto_model": "AutoModelForImageTextToText",
"custom_class": null,
"pipeline_tag": "image-text-to-text",
"processor": "AutoProcessor"
} | {"base_model": "google/gemma-3-12b", "datasets": null, "eval_results": null, "language": null, "library_name": "transformers", "license": "gemma", "license_name": null, "license_link": null, "metrics": null, "model_name": null, "pipeline_tag": "image-text-to-text", "tags": null, "extra_gated_heading": "Access Gemma on ... | null | null | [
"gemma"
] | null | null | 12,187,325,040 | null | null | [
"AutoModelForImageTextToText",
"Gemma3ForConditionalGeneration",
"gemma3"
] | [
"image-text-to-text"
] | [
"multimodal"
] | [
"text",
"image"
] | [
"text"
] |
659948208982abaa5cb94873 | 71140a663949f258 | 8a01c02d4d0a401c | 119,547 | WordPiece | null | true | true | true | true | 5 | BertNormalizer | BertPreTokenizer | WordPiece | [
"BertNormalizer"
] | [
"BertPreTokenizer"
] | [
"WordPiece"
] | 9 | OpenAlex/bert-base-multilingual-cased-finetuned-openalex-topic-classification-title-abstract | OpenAlex | {
"models": [
{
"_id": "621ffdc036468d709f174336",
"id": "google-bert/bert-base-multilingual-cased"
}
],
"relation": "finetune"
} | 1,484 | 725,486 | False | 2024-01-06T12:31:28Z | 2024-05-13T18:19:52Z | transformers | 10 | 0 | [{"name": "bert-base-multilingual-cased-finetuned-openalex-topic-classification-title-abstract", "results": []}] | text-classification | {"parameters": {"F32": 181330089}, "total": 181330089} | [
".gitattributes",
"README.md",
"config.json",
"model.safetensors",
"special_tokens_map.json",
"tf_model.h5",
"tokenizer.json",
"tokenizer_config.json",
"vocab.txt"
] | 7856c776a1d10ae58ee91045af0776807910de96 | [
"transformers",
"tf",
"safetensors",
"bert",
"text-classification",
"base_model:google-bert/bert-base-multilingual-cased",
"base_model:finetune:google-bert/bert-base-multilingual-cased",
"license:apache-2.0",
"text-embeddings-inference",
"endpoints_compatible",
"deploy:azure",
"region:us"
] | null | {"architectures": ["BertForSequenceClassification"], "model_type": "bert", "tokenizer_config": {"cls_token": "[CLS]", "mask_token": "[MASK]", "pad_token": "[PAD]", "sep_token": "[SEP]", "unk_token": "[UNK]"}} | {
"auto_model": "AutoModelForSequenceClassification",
"custom_class": null,
"pipeline_tag": "text-classification",
"processor": "AutoTokenizer"
} | {"base_model": "bert-base-multilingual-cased", "datasets": null, "eval_results": [], "language": null, "library_name": null, "license": "apache-2.0", "license_name": null, "license_link": null, "metrics": null, "model_name": "bert-base-multilingual-cased-finetuned-openalex-topic-classification-title-abstract", "pipelin... | # bert-base-multilingual-cased-finetuned-openalex-topic-classification-title-abstract
This model is a fine-tuned version of [bert-base-multilingual-cased](https://huggingface.co/bert-base-multilingual-cased) on a labeled dataset provided by [CWTS](https://www.cwts.nl/) (for labeled data: [CWTS Labeled Data](https://ze... | null | [
"apache-2.0"
] | null | null | 181,330,089 | null | null | [
"BertForSequenceClassification",
"bert",
"AutoModelForSequenceClassification"
] | [
"text-classification"
] | [
"text"
] | [
"text"
] | [
"logits"
] |
6579ae292f03cfb1b55619c6 | 88cd37e502d27a0a | 0e7bc0977f200d1c | 32,000 | BPE | 58,980 | true | false | true | true | 3 | Sequence | null | Sequence | [
"Prepend",
"Replace"
] | null | [
"Replace",
"ByteFallback",
"Fuse",
"Strip"
] | 88 | TheBloke/SOLAR-10.7B-Instruct-v1.0-AWQ | TheBloke | {
"models": [
{
"_id": "6578547a0766f274f3d2974f",
"id": "upstage/SOLAR-10.7B-Instruct-v1.0"
}
],
"relation": "quantized"
} | 85 | 656,984 | False | 2023-12-13T13:14:17Z | 2023-12-13T13:40:15Z | transformers | 5 | 0 | null | text-generation | {"parameters": {"I32": 10468982784, "F16": 262541312}, "total": 10731524096} | [
".gitattributes",
"README.md",
"config.json",
"generation_config.json",
"model.safetensors",
"quant_config.json",
"special_tokens_map.json",
"tokenizer.json",
"tokenizer.model",
"tokenizer_config.json"
] | 705460d297ca8b63b33d9a9f5c66326e7fa67d97 | [
"transformers",
"safetensors",
"llama",
"text-generation",
"conversational",
"base_model:upstage/SOLAR-10.7B-Instruct-v1.0",
"base_model:quantized:upstage/SOLAR-10.7B-Instruct-v1.0",
"license:apache-2.0",
"text-generation-inference",
"4-bit",
"awq",
"region:us"
] | null | {"architectures": ["LlamaForCausalLM"], "model_type": "llama", "quantization_config": {"bits": 4, "quant_method": "awq"}, "tokenizer_config": {"chat_template": "{% for message in messages %}{% if message['role'] == 'system' %}{% if message['content']%}{{'### System:\n' + message['content']+'\n\n'}}{% endif %}{% elif me... | {
"auto_model": "AutoModelForCausalLM",
"custom_class": null,
"pipeline_tag": "text-generation",
"processor": "AutoTokenizer"
} | {"base_model": "upstage/SOLAR-10.7B-Instruct-v1.0", "datasets": null, "eval_results": null, "language": null, "library_name": null, "license": "apache-2.0", "license_name": null, "license_link": null, "metrics": null, "model_name": "Solar 10.7B Instruct v1.0", "pipeline_tag": null, "tags": null, "inference": false, "mo... | <!-- markdownlint-disable MD041 -->
<!-- header start -->
<!-- 200823 -->
<div style="width: auto; margin-left: auto; margin-right: auto">
<img src="https://i.imgur.com/EBdldam.jpg" alt="TheBlokeAI" style="width: 100%; min-width: 400px; display: block; margin: auto;">
</div>
<div style="display: flex; justify-content:... | null | [
"apache-2.0"
] | null | null | 10,731,524,096 | null | null | [
"AutoModelForCausalLM",
"llama",
"LlamaForCausalLM"
] | [
"text-generation"
] | [
"text"
] | [
"text"
] | [
"text"
] |
689c5b2fb34c2fc90e285872 | 90801a62b3b42e51 | 322029f216c8964e | 131,072 | BPE | 269,443 | false | true | true | true | 1,000 | null | Sequence | ByteLevel | null | [
"Split",
"ByteLevel"
] | [
"ByteLevel"
] | 435 | swiss-ai/Apertus-8B-Instruct-2509 | swiss-ai | {
"models": [
{
"_id": "68b63f5f24016a224c0de14e",
"id": "swiss-ai/Apertus-8B-2509"
}
],
"relation": "finetune"
} | 168,153 | 2,069,548 | False | 2025-08-13T09:30:23Z | 2025-11-14T11:00:08Z | transformers | 443 | 2 | null | text-generation | null | [
".gitattributes",
"LICENSE.txt",
"README.md",
"USAGE_POLICY.md",
"chat_template.jinja",
"config.json",
"generation_config.json",
"model-00001-of-00004.safetensors",
"model-00002-of-00004.safetensors",
"model-00003-of-00004.safetensors",
"model-00004-of-00004.safetensors",
"model.safetensors.in... | cdb3e4f4ad41e0cc394bb92c302ac2eed57e9586 | [
"transformers",
"safetensors",
"apertus",
"text-generation",
"multilingual",
"compliant",
"swiss-ai",
"conversational",
"arxiv:2509.14233",
"base_model:swiss-ai/Apertus-8B-2509",
"base_model:finetune:swiss-ai/Apertus-8B-2509",
"license:apache-2.0",
"endpoints_compatible",
"deploy:azure",
... | null | {"architectures": ["ApertusForCausalLM"], "model_type": "apertus", "tokenizer_config": {"bos_token": "<s>", "eos_token": "<|assistant_end|>", "pad_token": "<pad>", "unk_token": "<unk>"}, "chat_template_jinja": "{%- macro render_typescript_type(param_spec, required_params, is_nullable=false) -%}\n {%- if param_spec.t... | {
"auto_model": "AutoModelForCausalLM",
"custom_class": null,
"pipeline_tag": "text-generation",
"processor": "AutoTokenizer"
} | {"base_model": ["swiss-ai/Apertus-8B-2509"], "datasets": null, "eval_results": null, "language": null, "library_name": "transformers", "license": "apache-2.0", "license_name": null, "license_link": null, "metrics": null, "model_name": null, "pipeline_tag": "text-generation", "tags": ["multilingual", "compliant", "swiss... | null | null | [
"apache-2.0"
] | null | null | null | null | null | [
"ApertusForCausalLM",
"AutoModelForCausalLM",
"apertus"
] | [
"text-generation"
] | [
"text"
] | [
"text"
] | [
"text"
] |
6753d2148fe46a77afe11a67 | 1e0a2493163c0c63 | 6622292dca275a2d | 128,256 | BPE | 280,147 | false | true | true | true | 256 | null | Sequence | ByteLevel | null | [
"Split",
"ByteLevel"
] | [
"ByteLevel"
] | 18 | ibnzterrell/Meta-Llama-3.3-70B-Instruct-AWQ-INT4 | ibnzterrell | {
"models": [
{
"_id": "6745f28f9333dfcc06268b1e",
"id": "meta-llama/Llama-3.3-70B-Instruct"
}
],
"relation": "quantized"
} | 104,700 | 1,239,330 | False | 2024-12-07T04:41:56Z | 2024-12-07T05:12:13Z | transformers | 30 | 0 | null | text-generation | {"parameters": {"I32": 68451041280, "F16": 2102665216}, "total": 70553706496} | [
".gitattributes",
"README.md",
"config.json",
"generation_config.json",
"model-00001-of-00009.safetensors",
"model-00002-of-00009.safetensors",
"model-00003-of-00009.safetensors",
"model-00004-of-00009.safetensors",
"model-00005-of-00009.safetensors",
"model-00006-of-00009.safetensors",
"model-0... | a3c28ea93c041acfaadb85401ad6493749a5aa04 | [
"transformers",
"safetensors",
"llama",
"text-generation",
"llama-3.3",
"meta",
"autoawq",
"conversational",
"en",
"fr",
"it",
"pt",
"hi",
"es",
"th",
"de",
"base_model:meta-llama/Llama-3.3-70B-Instruct",
"base_model:quantized:meta-llama/Llama-3.3-70B-Instruct",
"license:llama3.3... | null | {"architectures": ["LlamaForCausalLM"], "model_type": "llama", "quantization_config": {"bits": 4, "quant_method": "awq"}, "tokenizer_config": {"bos_token": "<|begin_of_text|>", "chat_template": "{{- bos_token }}\n{%- if custom_tools is defined %}\n {%- set tools = custom_tools %}\n{%- endif %}\n{%- if not tools_in_u... | {
"auto_model": "AutoModelForCausalLM",
"custom_class": null,
"pipeline_tag": "text-generation",
"processor": "AutoTokenizer"
} | {"base_model": ["meta-llama/Llama-3.3-70B-Instruct"], "datasets": null, "eval_results": null, "language": ["en", "fr", "it", "pt", "hi", "es", "th", "de"], "library_name": "transformers", "license": "llama3.3", "license_name": null, "license_link": null, "metrics": null, "model_name": null, "pipeline_tag": "text-genera... | ## Quantized Model Information
> [!IMPORTANT]
> This repository is an AWQ 4-bit quantized version of [`meta-llama/Llama-3.3-70B-Instruct`](https://huggingface.co/meta-llama/Llama-3.3-70B-Instruct), originally released by Meta AI.
This model was quantized using [AutoAWQ](https://github.com/casper-hansen/AutoAWQ) from ... | null | [
"llama3.3"
] | null | [
"en",
"fr",
"it",
"pt",
"hi",
"es",
"th",
"de"
] | 70,553,706,496 | null | null | [
"AutoModelForCausalLM",
"llama",
"LlamaForCausalLM"
] | [
"text-generation"
] | [
"text"
] | [
"text"
] | [
"text"
] |
645e9075340d0b66d14352ed | 30094a1eabdbef67 | db117e9883c4d0ab | 50,257 | BPE | 50,000 | false | true | true | true | 1 | null | ByteLevel | ByteLevel | null | [
"ByteLevel"
] | [
"ByteLevel"
] | 4 | roneneldan/TinyStories-33M | roneneldan | null | 57,258 | 808,355 | False | 2023-05-12T19:16:05Z | 2024-08-12T13:27:10Z | transformers | 108 | 0 | null | text-generation | null | [
".gitattributes",
"README.md",
"config.json",
"merges.txt",
"pytorch_model.bin",
"special_tokens_map.json",
"tokenizer.json",
"tokenizer_config.json",
"vocab.json"
] | 2ad0a164221b7c4d21cac7c46aec74f6f98dbfc8 | [
"transformers",
"pytorch",
"gpt_neo",
"text-generation",
"dataset:roneneldan/TinyStories",
"arxiv:2305.07759",
"endpoints_compatible",
"region:us"
] | null | {"architectures": ["GPTNeoForCausalLM"], "model_type": "gpt_neo", "tokenizer_config": {"bos_token": {"__type": "AddedToken", "content": "<|endoftext|>", "lstrip": false, "normalized": true, "rstrip": false, "single_word": false}, "eos_token": {"__type": "AddedToken", "content": "<|endoftext|>", "lstrip": false, "normal... | {
"auto_model": "AutoModelForCausalLM",
"custom_class": null,
"pipeline_tag": "text-generation",
"processor": "AutoTokenizer"
} | {"base_model": null, "datasets": ["roneneldan/TinyStories"], "eval_results": null, "language": null, "library_name": null, "license": null, "license_name": null, "license_link": null, "metrics": null, "model_name": null, "pipeline_tag": null, "tags": null} | Model trained on the TinyStories Dataset, see https://arxiv.org/abs/2305.07759
Based on GPT-Neo architecture.
License: mit
---
hyperparams used to train this model:
```
lr = 5e-4,
lr_schedule = constant,
wd=0.1,
adam_beta1=0.9, adam_beta2 = 0.95,
context_length=512,
batch_size=80,
gradient_accumulation_steps=16
``... | null | null | [
"roneneldan/TinyStories"
] | null | null | null | null | [
"gpt_neo",
"AutoModelForCausalLM",
"GPTNeoForCausalLM"
] | [
"text-generation"
] | [
"text"
] | [
"text"
] | [
"text"
] |
65436c415670dd57b77bc737 | 66aff645b233404a | 0e4a6f76168da02d | 57,226 | WordPiece | null | true | true | true | true | 5 | BertNormalizer | BertPreTokenizer | WordPiece | [
"BertNormalizer"
] | [
"BertPreTokenizer"
] | [
"WordPiece"
] | 436 | Seznam/retromae-small-cs | Seznam | null | 759 | 656,131 | False | 2023-11-02T09:30:41Z | 2024-10-18T17:14:11Z | transformers | 6 | 0 | null | sentence-similarity | null | [
".gitattributes",
"README.md",
"config.json",
"pytorch_model.bin",
"special_tokens_map.json",
"tokenizer.json",
"tokenizer_config.json",
"vocab.txt"
] | c9696feffb314a7f104b4be71e46dc197c193232 | [
"transformers",
"pytorch",
"bert",
"feature-extraction",
"sentence-similarity",
"cs",
"arxiv:2311.13921",
"license:cc-by-4.0",
"text-embeddings-inference",
"endpoints_compatible",
"deploy:azure",
"region:us"
] | null | {"architectures": ["BertModel"], "model_type": "bert", "tokenizer_config": {"cls_token": "[CLS]", "mask_token": "[MASK]", "pad_token": "[PAD]", "sep_token": "[SEP]", "unk_token": "[UNK]"}} | {
"auto_model": "AutoModel",
"custom_class": null,
"pipeline_tag": "feature-extraction",
"processor": "AutoTokenizer"
} | {"base_model": null, "datasets": null, "eval_results": null, "language": ["cs"], "library_name": null, "license": "cc-by-4.0", "license_name": null, "license_link": null, "metrics": null, "model_name": null, "pipeline_tag": "sentence-similarity", "tags": null} | ## RetroMAE
RetroMAE-Small is a BERT-small model pre-trained with the [RetroMAE](https://ojs.aaai.org/index.php/AAAI/article/download/30307/32315) objective on a Czech web corpus.
This model was created at Seznam.cz as part of a project to create high-quality small Czech semantic embedding models. These models perfor... | null | [
"cc-by-4.0"
] | null | [
"cs"
] | null | null | null | [
"BertModel",
"AutoModel",
"bert"
] | [
"sentence-similarity",
"feature-extraction"
] | [
"text",
"multimodal"
] | [
"text"
] | [
"logits",
"embeddings"
] |
67b79cc230e38c400f496b93 | b86074a73431b347 | 1fe366e13272caa0 | 262,145 | BPE | 514,906 | true | true | true | true | 6,415 | Replace | Split | Sequence | [
"Replace"
] | [
"Split"
] | [
"Replace",
"ByteFallback",
"Fuse"
] | 434 | google/gemma-3-1b-pt | google | null | 63,602 | 896,369 | manual | 2025-02-20T21:21:06Z | 2025-03-21T16:14:00Z | transformers | 187 | 0 | null | text-generation | null | [
".gitattributes",
"README.md",
"added_tokens.json",
"config.json",
"generation_config.json",
"model.safetensors",
"special_tokens_map.json",
"tokenizer.json",
"tokenizer.model",
"tokenizer_config.json"
] | fcf18a2a879aab110ca39f8bffbccd5d49d8eb29 | [
"transformers",
"safetensors",
"gemma3_text",
"text-generation",
"arxiv:1905.07830",
"arxiv:1905.10044",
"arxiv:1911.11641",
"arxiv:1904.09728",
"arxiv:1705.03551",
"arxiv:1911.01547",
"arxiv:1907.10641",
"arxiv:1903.00161",
"arxiv:2009.03300",
"arxiv:2304.06364",
"arxiv:2103.03874",
"... | null | {"architectures": ["Gemma3ForCausalLM"], "model_type": "gemma3_text", "tokenizer_config": {"bos_token": "<bos>", "eos_token": "<eos>", "pad_token": "<pad>", "unk_token": "<unk>", "use_default_system_prompt": false}} | {
"auto_model": "AutoModelForCausalLM",
"custom_class": null,
"pipeline_tag": "text-generation",
"processor": "AutoTokenizer"
} | {"base_model": null, "datasets": null, "eval_results": null, "language": null, "library_name": "transformers", "license": "gemma", "license_name": null, "license_link": null, "metrics": null, "model_name": null, "pipeline_tag": "text-generation", "tags": null, "extra_gated_heading": "Access Gemma on Hugging Face", "ext... | null | null | [
"gemma"
] | null | null | null | null | null | [
"gemma3_text",
"AutoModelForCausalLM",
"Gemma3ForCausalLM"
] | [
"text-generation"
] | [
"text"
] | [
"text"
] | [
"text"
] |
67aaf6fe385da1f07cd40b05 | 7ec8239dd3bcce7b | 46a701b36ce8cd6c | 49,280 | BPE | 48,900 | false | true | false | true | 145 | null | Sequence | ByteLevel | null | [
"Digits",
"ByteLevel"
] | [
"ByteLevel"
] | 242 | HuggingFaceTB/SmolVLM2-500M-Video-Instruct | HuggingFaceTB | {
"models": [
{
"_id": "678e5cb387ba422cae1fe649",
"id": "HuggingFaceTB/SmolVLM-500M-Instruct"
}
],
"relation": "quantized"
} | 282,892 | 1,447,765 | False | 2025-02-11T07:06:38Z | 2025-04-08T07:25:40Z | transformers | 124 | 1 | null | image-text-to-text | null | [
".gitattributes",
"README.md",
"added_tokens.json",
"chat_template.json",
"config.json",
"generation_config.json",
"merges.txt",
"model.safetensors",
"onnx/decoder_model_merged.onnx",
"onnx/decoder_model_merged_bnb4.onnx",
"onnx/decoder_model_merged_fp16.onnx",
"onnx/decoder_model_merged_int8.... | 7b375e1b73b11138ff12fe22c8f2822d8fe03467 | [
"transformers",
"onnx",
"safetensors",
"smolvlm",
"image-text-to-text",
"conversational",
"en",
"dataset:HuggingFaceM4/the_cauldron",
"dataset:HuggingFaceM4/Docmatix",
"dataset:lmms-lab/LLaVA-OneVision-Data",
"dataset:lmms-lab/M4-Instruct-Data",
"dataset:HuggingFaceFV/finevideo",
"dataset:MA... | null | {"architectures": ["SmolVLMForConditionalGeneration"], "model_type": "smolvlm", "processor_config": {"chat_template": "<|im_start|>{% for message in messages %}{{message['role'] | capitalize}}{% if message['content'][0]['type'] == 'image' %}{{':'}}{% else %}{{': '}}{% endif %}{% for line in message['content'] %}{% if l... | {
"auto_model": "AutoModelForImageTextToText",
"custom_class": null,
"pipeline_tag": "image-text-to-text",
"processor": "AutoProcessor"
} | {"base_model": ["HuggingFaceTB/SmolVLM-500M-Instruct"], "datasets": ["HuggingFaceM4/the_cauldron", "HuggingFaceM4/Docmatix", "lmms-lab/LLaVA-OneVision-Data", "lmms-lab/M4-Instruct-Data", "HuggingFaceFV/finevideo", "MAmmoTH-VL/MAmmoTH-VL-Instruct-12M", "lmms-lab/LLaVA-Video-178K", "orrzohar/Video-STaR", "Mutonix/Vript",... | null | null | [
"apache-2.0"
] | [
"HuggingFaceM4/the_cauldron",
"HuggingFaceM4/Docmatix",
"lmms-lab/LLaVA-OneVision-Data",
"lmms-lab/M4-Instruct-Data",
"HuggingFaceFV/finevideo",
"MAmmoTH-VL/MAmmoTH-VL-Instruct-12M",
"lmms-lab/LLaVA-Video-178K",
"orrzohar/Video-STaR",
"Mutonix/Vript",
"TIGER-Lab/VISTA-400K",
"Enxin/MovieChat-1K_... | [
"en"
] | null | null | null | [
"AutoModelForImageTextToText",
"SmolVLMForConditionalGeneration",
"smolvlm"
] | [
"image-text-to-text"
] | [
"multimodal"
] | [
"text",
"image"
] | [
"text"
] |
63460638a8c2ff9f137aef4f | 04f5fbc309982132 | ef4806e2ade9022f | 32,100 | Unigram | null | true | true | true | true | 103 | Sequence | Metaspace | Metaspace | [
"Precompiled",
"Replace"
] | [
"Metaspace"
] | [
"Metaspace"
] | 259 | MingZhong/unieval-fact | MingZhong | null | 4,249 | 688,603 | False | 2022-10-12T00:11:36Z | 2022-10-14T01:10:31Z | transformers | 3 | 0 | null | null | null | [
".gitattributes",
"README.md",
"config.json",
"optimizer.pt",
"pytorch_model.bin",
"rng_state_0.pth",
"rng_state_1.pth",
"scheduler.pt",
"special_tokens_map.json",
"spiece.model",
"tokenizer.json",
"tokenizer_config.json",
"training_args.bin"
] | 68e455e999299042881b0cf7f22f45fc7458481f | [
"transformers",
"pytorch",
"t5",
"text2text-generation",
"arxiv:2210.07197",
"text-generation-inference",
"endpoints_compatible",
"deploy:azure",
"region:us"
] | null | {"architectures": ["T5ForConditionalGeneration"], "model_type": "t5", "tokenizer_config": {"eos_token": "</s>", "unk_token": "<unk>", "pad_token": "<pad>"}} | {
"auto_model": "AutoModelForSeq2SeqLM",
"custom_class": null,
"pipeline_tag": "text2text-generation",
"processor": "AutoTokenizer"
} | null | Pre-trained evaluator in EMNLP 2022 paper
*[Towards a Unified Multi-Dimensional Evaluator for Text Generation](https://arxiv.org/abs/2210.07197)*
## Introduction
**Multi-dimensional evaluation** is the dominant paradigm for human evaluation in Natural Language Generation (NLG), i.e., evaluating the generated text fr... | null | null | null | null | null | null | null | [
"t5",
"T5ForConditionalGeneration",
"AutoModelForSeq2SeqLM"
] | [
"text2text-generation"
] | null | null | null |
64e4ce2d9bec7890e2cf17c6 | 587fb56d9ccfa363 | 47f335ba286f08ee | 32,102 | Unigram | null | true | true | true | true | 105 | Sequence | Metaspace | Metaspace | [
"Precompiled",
"Replace"
] | [
"Metaspace"
] | [
"Metaspace"
] | 437 | vabatista/question-generation-t5-small-pt-br-2 | vabatista | null | 8 | 646,810 | False | 2023-08-22T15:03:09Z | 2024-09-25T13:26:39Z | transformers | 0 | 0 | null | text-generation | null | [
".gitattributes",
"README.md",
"added_tokens.json",
"config.json",
"pytorch_model.bin",
"special_tokens_map.json",
"spiece.model",
"tokenizer.json",
"tokenizer_config.json"
] | 1c6cc17ed05f67f40c31a5c19cd37962875fbb30 | [
"transformers",
"pytorch",
"t5",
"feature-extraction",
"text2text-generation",
"pt",
"dataset:squad",
"license:afl-3.0",
"text-generation-inference",
"endpoints_compatible",
"region:us"
] | null | {"architectures": ["T5Model"], "model_type": "t5", "tokenizer_config": {"eos_token": "</s>", "pad_token": "<pad>", "unk_token": "<unk>"}} | {
"auto_model": "AutoModel",
"custom_class": null,
"pipeline_tag": "feature-extraction",
"processor": "AutoTokenizer"
} | {"base_model": null, "datasets": ["squad"], "eval_results": null, "language": ["pt"], "library_name": null, "license": "afl-3.0", "license_name": null, "license_link": null, "metrics": null, "model_name": null, "pipeline_tag": "text2text-generation", "tags": null, "widget": [{"text": "My name is Julien and I like to", ... | # Model Card for Model ID
<!-- Provide a quick summary of what the model is/does. -->
This model is intended to be used generating questions and answers from brazilian portuguese text passages,
so you can finetune another BERT model into your generated triples (context-question-answer) for extractive question answeri... | null | [
"afl-3.0"
] | [
"squad"
] | [
"pt"
] | null | null | null | [
"t5",
"T5Model",
"AutoModel"
] | [
"feature-extraction",
"text-generation"
] | [
"text",
"multimodal"
] | [
"text"
] | [
"text",
"embeddings"
] |
662b2a970bf3904a3d8129c6 | bc75b1072bca086b | b48c4f1fb87798c9 | 32,038 | BPE | 61,249 | true | false | true | true | 41 | Sequence | null | Sequence | [
"Prepend",
"Replace"
] | null | [
"Replace",
"ByteFallback",
"Fuse",
"Strip"
] | 136 | renwoshin/Phi-3-mini-128k-instruct-onnx-tf | renwoshin | null | 16 | 646,387 | False | 2024-04-26T04:16:23Z | 2024-04-26T04:45:13Z | transformers | 1 | 0 | null | text-generation | null | [
".gitattributes",
"LICENSE",
"README.md",
"added_tokens.json",
"config.json",
"onnx/decoder_model_merged_quantized.onnx",
"onnx/decoder_model_merged_quantized.onnx.data",
"special_tokens_map.json",
"tokenizer.json",
"tokenizer.model",
"tokenizer_config.json"
] | b605e9db6846d020f4f9ce27f6870c038dd211a7 | [
"transformers",
"onnx",
"phi",
"text-generation",
"ONNX",
"DML",
"ONNXRuntime",
"phi3",
"nlp",
"conversational",
"custom_code",
"arxiv:2306.00978",
"license:mit",
"endpoints_compatible",
"region:us"
] | null | {"architectures": ["Phi3ForCausalLM"], "auto_map": {"AutoConfig": "configuration_phi3.Phi3Config", "AutoModelForCausalLM": "modeling_phi3.Phi3ForCausalLM"}, "model_type": "phi", "tokenizer_config": {"bos_token": "<s>", "chat_template": "{{ bos_token }}{% for message in messages %}{{'<|' + message['role'] + '|>' + '\n' ... | {
"auto_model": "AutoModelForCausalLM",
"custom_class": null,
"pipeline_tag": "text-generation",
"processor": "AutoTokenizer"
} | {"base_model": null, "datasets": null, "eval_results": null, "language": null, "library_name": null, "license": "mit", "license_name": null, "license_link": null, "metrics": null, "model_name": null, "pipeline_tag": "text-generation", "tags": ["ONNX", "DML", "ONNXRuntime", "phi3", "nlp", "conversational", "custom_code"... | # Phi-3 Mini-128K-Instruct ONNX models
<!-- Provide a quick summary of what the model is/does. -->
This repository hosts the optimized versions of [Phi-3-mini-128k-instruct](https://aka.ms/phi3-mini-128k-instruct) to accelerate inference with ONNX Runtime.
Phi-3 Mini is a lightweight, state-of-the-art open model buil... | null | [
"mit"
] | null | null | null | null | null | [
"AutoModelForCausalLM",
"phi",
"Phi3ForCausalLM"
] | [
"text-generation"
] | [
"text"
] | [
"text"
] | [
"text"
] |
66f466782f66635def443fff | 8e316423c2276392 | c07e6b923a6fe857 | 128,257 | BPE | 280,147 | false | true | true | true | 257 | null | Sequence | ByteLevel | null | [
"Split",
"ByteLevel"
] | [
"ByteLevel"
] | 278 | unsloth/Llama-3.2-11B-Vision-Instruct-bnb-4bit | unsloth | {
"models": [
{
"_id": "66eb042015688c55aba845ac",
"id": "meta-llama/Llama-3.2-11B-Vision-Instruct"
}
],
"relation": "quantized"
} | 13,301 | 1,199,916 | False | 2024-09-25T19:37:28Z | 2024-12-10T02:49:03Z | transformers | 80 | 0 | null | image-text-to-text | {"parameters": {"F32": 724112, "BF16": 1128179235, "U8": 9840409910}, "total": 10969313257} | [
".gitattributes",
"README.md",
"chat_template.json",
"config.json",
"generation_config.json",
"model-00001-of-00002.safetensors",
"model-00002-of-00002.safetensors",
"model.safetensors.index.json",
"preprocessor_config.json",
"special_tokens_map.json",
"tokenizer.json",
"tokenizer_config.json"... | 25bca24a9e42116fe4a687fba648124be4af45f6 | [
"transformers",
"safetensors",
"mllama",
"image-text-to-text",
"llama-3",
"llama",
"meta",
"facebook",
"unsloth",
"multimodal",
"vision",
"pytorch",
"conversational",
"en",
"base_model:meta-llama/Llama-3.2-11B-Vision-Instruct",
"base_model:quantized:meta-llama/Llama-3.2-11B-Vision-Inst... | null | {"architectures": ["MllamaForConditionalGeneration"], "model_type": "mllama", "quantization_config": {"load_in_4bit": true, "load_in_8bit": false, "quant_method": "bitsandbytes"}, "processor_config": {"chat_template": "{{- bos_token }}\n{%- if custom_tools is defined %}\n {%- set tools = custom_tools %}\n{%- endif %... | {
"auto_model": "AutoModelForImageTextToText",
"custom_class": null,
"pipeline_tag": "image-text-to-text",
"processor": "AutoProcessor"
} | {"base_model": "meta-llama/Llama-3.2-11B-Vision-Instruct", "datasets": null, "eval_results": null, "language": ["en"], "library_name": "transformers", "license": "llama3.2", "license_name": null, "license_link": null, "metrics": null, "model_name": null, "pipeline_tag": null, "tags": ["llama-3", "llama", "meta", "faceb... | ## ***See [our collection](https://huggingface.co/collections/unsloth/vision-multimodal-models-673eb9908fc2cb3deebd2fa3) for vision models including Llama 3.2, Llava, Qwen2-VL and Pixtral.***
# Finetune Llama 3.2, Gemma 2, Mistral 2-5x faster with 70% less memory via Unsloth!
We have a free Google Colab Tesla T4 not... | null | [
"llama3.2"
] | null | [
"en"
] | 10,969,313,257 | null | null | [
"AutoModelForImageTextToText",
"MllamaForConditionalGeneration",
"mllama"
] | [
"image-text-to-text"
] | [
"multimodal"
] | [
"text",
"image"
] | [
"text"
] |
65b92feaddafc3f8a5e5fe25 | 34093184d10f76a9 | 35b001f3a491f9f9 | 151,646 | BPE | 151,387 | true | true | true | true | 3 | NFC | Sequence | ByteLevel | [
"NFC"
] | [
"Split",
"ByteLevel"
] | [
"ByteLevel"
] | 53 | Qwen/Qwen1.5-14B-Chat | Qwen | null | 21,337 | 734,598 | False | 2024-01-30T17:20:42Z | 2024-04-30T07:22:51Z | transformers | 113 | 0 | null | text-generation | {"parameters": {"BF16": 14167290880}, "total": 14167290880} | [
".gitattributes",
"LICENSE",
"README.md",
"config.json",
"generation_config.json",
"merges.txt",
"model-00001-of-00008.safetensors",
"model-00002-of-00008.safetensors",
"model-00003-of-00008.safetensors",
"model-00004-of-00008.safetensors",
"model-00005-of-00008.safetensors",
"model-00006-of-0... | 9492b22871f43e975435455f5c616c77fe7a50ec | [
"transformers",
"safetensors",
"qwen2",
"text-generation",
"chat",
"conversational",
"en",
"arxiv:2309.16609",
"license:other",
"text-generation-inference",
"endpoints_compatible",
"deploy:azure",
"region:us"
] | null | {"architectures": ["Qwen2ForCausalLM"], "model_type": "qwen2", "tokenizer_config": {"bos_token": null, "chat_template": "{% for message in messages %}{% if loop.first and messages[0]['role'] != 'system' %}{{ '<|im_start|>system\nYou are a helpful assistant.<|im_end|>\n' }}{% endif %}{{'<|im_start|>' + message['role'] +... | {
"auto_model": "AutoModelForCausalLM",
"custom_class": null,
"pipeline_tag": "text-generation",
"processor": "AutoTokenizer"
} | {"base_model": null, "datasets": null, "eval_results": null, "language": ["en"], "library_name": null, "license": "other", "license_name": "tongyi-qianwen", "license_link": "https://huggingface.co/Qwen/Qwen1.5-14B-Chat/blob/main/LICENSE", "metrics": null, "model_name": null, "pipeline_tag": "text-generation", "tags": [... | # Qwen1.5-14B-Chat
## Introduction
Qwen1.5 is the beta version of Qwen2, a transformer-based decoder-only language model pretrained on a large amount of data. In comparison with the previous released Qwen, the improvements include:
* 8 model sizes, including 0.5B, 1.8B, 4B, 7B, 14B, 32B and 72B dense models, and a... | null | [
"other",
"tongyi-qianwen",
"https://huggingface.co/Qwen/Qwen1.5-14B-Chat/blob/main/LICENSE"
] | null | [
"en"
] | 14,167,290,880 | null | null | [
"AutoModelForCausalLM",
"Qwen2ForCausalLM",
"qwen2"
] | [
"text-generation"
] | [
"text"
] | [
"text"
] | [
"text"
] |
65af85a83e876a6389a03b48 | 5a2db10fc72e4c3f | 43cab03c9c1379fb | 30,528 | WordPiece | null | true | true | true | true | 5 | BertNormalizer | BertPreTokenizer | WordPiece | [
"BertNormalizer"
] | [
"BertPreTokenizer"
] | [
"WordPiece"
] | 438 | jinaai/jina-colbert-v1-en | jinaai | null | 280 | 645,735 | False | 2024-01-23T09:23:52Z | 2025-01-06T16:23:57Z | transformers | 100 | 0 | null | null | {"parameters": {"F32": 137466624}, "total": 137466624} | [
".gitattributes",
"README.md",
"artifact.metadata",
"config.json",
"model.safetensors",
"special_tokens_map.json",
"tokenizer.json",
"tokenizer_config.json",
"vocab.txt"
] | 31bb5a4d063a793f4aaaf6ecb9bf4ef1879ddf7d | [
"transformers",
"safetensors",
"bert",
"ColBERT",
"passage-retrieval",
"custom_code",
"en",
"dataset:ms_marco",
"arxiv:2310.19923",
"arxiv:2108.12409",
"arxiv:2004.12832",
"arxiv:2112.01488",
"license:apache-2.0",
"endpoints_compatible",
"region:us"
] | null | {"architectures": ["HF_ColBERT"], "auto_map": {"AutoConfig": "jinaai/jina-bert-implementation--configuration_bert.JinaBertConfig", "AutoModel": "jinaai/jina-bert-implementation--modeling_bert.JinaBertModel", "AutoModelForMaskedLM": "jinaai/jina-bert-implementation--modeling_bert.JinaBertForMaskedLM", "AutoModelForSeque... | {
"auto_model": "HF_ColBERT",
"custom_class": null,
"pipeline_tag": null,
"processor": "AutoTokenizer"
} | {"base_model": null, "datasets": ["ms_marco"], "eval_results": null, "language": ["en"], "library_name": null, "license": "apache-2.0", "license_name": null, "license_link": null, "metrics": null, "model_name": null, "pipeline_tag": null, "tags": ["ColBERT", "passage-retrieval"]} | <br><br>
<p align="center">
<img src="https://huggingface.co/datasets/jinaai/documentation-images/resolve/main/logo.webp" alt="Jina AI: Your Search Foundation, Supercharged!" width="150px">
</p>
<p align="center">
<b>Trained by <a href="https://jina.ai/"><b>Jina AI</b></a>.</b>
</p>
# Jina-ColBERT
**Jina-ColBERT i... | null | [
"apache-2.0"
] | [
"ms_marco"
] | [
"en"
] | 137,466,624 | null | null | [
"HF_ColBERT",
"bert"
] | [
null
] | null | null | null |
6374e3e5cc5cc31768835f54 | a2eba66f56003a7a | 830fa437e6f588f3 | 50,000 | BPE | 49,721 | true | true | false | true | 23 | NFKC | Sequence | ByteLevel | [
"NFKC"
] | [
"Split",
"Digits",
"Split",
"Split",
"ByteLevel"
] | [
"ByteLevel"
] | 439 | facebook/galactica-125m | facebook | null | 2,583 | 660,361 | False | 2022-11-16T13:21:41Z | 2023-06-27T19:00:15Z | transformers | 39 | 0 | null | text-generation | {"parameters": {"F16": 125030400}, "total": 125030400} | [
".gitattributes",
"README.md",
"config.json",
"generation_config.json",
"model.safetensors",
"pytorch_model.bin",
"special_tokens_map.json",
"tokenizer.json",
"tokenizer_config.json"
] | 6ea4f4f29afc4b0e4c80ecd45fb4af0355bd9c1d | [
"transformers",
"pytorch",
"safetensors",
"opt",
"text-generation",
"galactica",
"arxiv:1810.03993",
"license:cc-by-nc-4.0",
"text-generation-inference",
"deploy:azure",
"region:us"
] | null | {"architectures": ["OPTForCausalLM"], "model_type": "opt", "tokenizer_config": {}} | {
"auto_model": "AutoModelForCausalLM",
"custom_class": null,
"pipeline_tag": "text-generation",
"processor": "AutoTokenizer"
} | {"base_model": null, "datasets": null, "eval_results": null, "language": null, "library_name": null, "license": "cc-by-nc-4.0", "license_name": null, "license_link": null, "metrics": null, "model_name": null, "pipeline_tag": null, "tags": ["galactica"], "widget": [{"text": "The Transformer architecture [START_REF]"}, {... | 
# GALACTICA 125M (mini)
Model card from the original [repo](https://github.com/paperswithcode/galai/blob/main/docs/model_card.md)
Following [Mitchell et al. (2018)](https://arxiv.org/abs/1810.03993), this model ca... | null | [
"cc-by-nc-4.0"
] | null | null | 125,030,400 | null | null | [
"OPTForCausalLM",
"AutoModelForCausalLM",
"opt"
] | [
"text-generation"
] | [
"text"
] | [
"text"
] | [
"text"
] |
672b1f9a250205b317ab81e5 | 848b60b6cd304b65 | ffc911e785abe60e | 151,665 | BPE | 151,387 | true | true | true | true | 22 | NFC | Sequence | ByteLevel | [
"NFC"
] | [
"Split",
"ByteLevel"
] | [
"ByteLevel"
] | 15 | Qwen/Qwen2.5-Coder-14B-Instruct | Qwen | {
"models": [
{
"_id": "672dec6fca6d5a4563cf6db0",
"id": "Qwen/Qwen2.5-Coder-14B"
}
],
"relation": "finetune"
} | 770,016 | 2,282,082 | False | 2024-11-06T07:49:46Z | 2025-01-12T02:02:59Z | transformers | 144 | 0 | null | text-generation | {"parameters": {"BF16": 14770033664}, "total": 14770033664} | [
".gitattributes",
"LICENSE",
"README.md",
"config.json",
"generation_config.json",
"merges.txt",
"model-00001-of-00006.safetensors",
"model-00002-of-00006.safetensors",
"model-00003-of-00006.safetensors",
"model-00004-of-00006.safetensors",
"model-00005-of-00006.safetensors",
"model-00006-of-0... | aedcc2d42b622764e023cf882b6652e646b95671 | [
"transformers",
"safetensors",
"qwen2",
"text-generation",
"code",
"codeqwen",
"chat",
"qwen",
"qwen-coder",
"conversational",
"en",
"arxiv:2409.12186",
"arxiv:2309.00071",
"arxiv:2407.10671",
"base_model:Qwen/Qwen2.5-Coder-14B",
"base_model:finetune:Qwen/Qwen2.5-Coder-14B",
"license... | null | {"architectures": ["Qwen2ForCausalLM"], "model_type": "qwen2", "tokenizer_config": {"bos_token": null, "chat_template": "{%- if tools %}\n {{- '<|im_start|>system\\n' }}\n {%- if messages[0]['role'] == 'system' %}\n {{- messages[0]['content'] }}\n {%- else %}\n {{- 'You are Qwen, created by Aliba... | {
"auto_model": "AutoModelForCausalLM",
"custom_class": null,
"pipeline_tag": "text-generation",
"processor": "AutoTokenizer"
} | {"base_model": ["Qwen/Qwen2.5-Coder-14B"], "datasets": null, "eval_results": null, "language": ["en"], "library_name": "transformers", "license": "apache-2.0", "license_name": null, "license_link": "https://huggingface.co/Qwen/Qwen2.5-Coder-14B-Instruct/blob/main/LICENSE", "metrics": null, "model_name": null, "pipeline... | # Qwen2.5-Coder-14B-Instruct
<a href="https://chat.qwenlm.ai/" target="_blank" style="margin: 2px;">
<img alt="Chat" src="https://img.shields.io/badge/%F0%9F%92%9C%EF%B8%8F%20Qwen%20Chat%20-536af5" style="display: inline-block; vertical-align: middle;"/>
</a>
## Introduction
Qwen2.5-Coder is the latest series of ... | null | [
"apache-2.0",
"https://huggingface.co/Qwen/Qwen2.5-Coder-14B-Instruct/blob/main/LICENSE"
] | null | [
"en"
] | 14,770,033,664 | null | null | [
"AutoModelForCausalLM",
"Qwen2ForCausalLM",
"qwen2"
] | [
"text-generation"
] | [
"text"
] | [
"text"
] | [
"text"
] |
621ffdc136468d709f17b611 | ed7b346ae536b711 | 7135f15e02b88987 | 96,103 | Unigram | null | true | true | true | true | 7 | Sequence | Sequence | Metaspace | [
"Precompiled",
"Replace"
] | [
"WhitespaceSplit",
"Metaspace"
] | [
"Metaspace"
] | 440 | google/bigbird-pegasus-large-arxiv | google | null | 7,309 | 661,196 | False | 2022-03-02T23:29:05Z | 2023-01-24T16:36:41Z | transformers | 64 | 0 | [{"name": "google/bigbird-pegasus-large-arxiv", "results": [{"task": {"type": "summarization", "name": "Summarization"}, "dataset": {"name": "scientific_papers", "type": "scientific_papers", "config": "pubmed", "split": "test"}, "metrics": [{"name": "ROUGE-1", "type": "rouge", "value": 36.0276, "verified": false}, {"na... | summarization | null | [
".gitattributes",
"README.md",
"config.json",
"generation_config.json",
"pytorch_model.bin",
"special_tokens_map.json",
"spiece.model",
"tokenizer.json",
"tokenizer_config.json"
] | c5ae494f3d319933617d513f8491c5be87f5d35b | [
"transformers",
"pytorch",
"bigbird_pegasus",
"text2text-generation",
"summarization",
"en",
"dataset:scientific_papers",
"arxiv:2007.14062",
"license:apache-2.0",
"model-index",
"endpoints_compatible",
"deploy:azure",
"region:us"
] | null | {"architectures": ["BigBirdPegasusForConditionalGeneration"], "model_type": "bigbird_pegasus", "tokenizer_config": {"pad_token": {"content": "<pad>", "single_word": false, "lstrip": false, "rstrip": false, "normalized": true, "__type": "AddedToken"}, "eos_token": {"content": "</s>", "single_word": false, "lstrip": fals... | {
"auto_model": "AutoModelForSeq2SeqLM",
"custom_class": null,
"pipeline_tag": "text2text-generation",
"processor": "AutoTokenizer"
} | {"datasets": ["scientific_papers"], "language": "en", "license": "apache-2.0", "tags": ["summarization"], "model-index": [{"name": "google/bigbird-pegasus-large-arxiv", "results": [{"task": {"type": "summarization", "name": "Summarization"}, "dataset": {"name": "scientific_papers", "type": "scientific_papers", "config"... | # BigBirdPegasus model (large)
BigBird, is a sparse-attention based transformer which extends Transformer based models, such as BERT to much longer sequences. Moreover, BigBird comes along with a theoretical understanding of the capabilities of a complete transformer that the sparse model can handle.
BigBird was int... | null | [
"apache-2.0"
] | [
"scientific_papers"
] | [
"en"
] | null | null | null | [
"bigbird_pegasus",
"BigBirdPegasusForConditionalGeneration",
"AutoModelForSeq2SeqLM"
] | [
"text2text-generation",
"summarization"
] | [
"text"
] | [
"text"
] | [
"text"
] |
628ba79dfc0078a72e3a98b7 | 9172612ea9646de4 | 70bd27c212bc339c | 50,265 | BPE | 50,000 | false | true | true | true | 5 | null | ByteLevel | ByteLevel | null | [
"ByteLevel"
] | [
"ByteLevel"
] | 441 | oliverguhr/spelling-correction-english-base | oliverguhr | null | 4,907 | 670,930 | False | 2022-05-23T15:26:21Z | 2023-12-18T08:46:53Z | transformers | 77 | 0 | null | null | {"parameters": {"F32": 139470681}, "total": 139470681} | [
".gitattributes",
"README.md",
"all_results.json",
"config.json",
"merges.txt",
"model.safetensors",
"onnx/added_tokens.json",
"onnx/config.json",
"onnx/decoder_model.onnx",
"onnx/decoder_model_merged.onnx",
"onnx/decoder_with_past_model.onnx",
"onnx/encoder_model.onnx",
"onnx/generation_con... | 0e3958355a09d2816ed2701fdc2f4471d46c320e | [
"transformers",
"pytorch",
"tensorboard",
"onnx",
"safetensors",
"bart",
"text2text-generation",
"en",
"license:mit",
"endpoints_compatible",
"deploy:azure",
"region:us"
] | null | {"architectures": ["BartForConditionalGeneration"], "model_type": "bart", "tokenizer_config": {"bos_token": "<s>", "eos_token": "</s>", "sep_token": "</s>", "cls_token": "<s>", "unk_token": "<unk>", "pad_token": "<pad>", "mask_token": "<mask>"}} | {
"auto_model": "AutoModelForSeq2SeqLM",
"custom_class": null,
"pipeline_tag": "text2text-generation",
"processor": "AutoTokenizer"
} | {"base_model": null, "datasets": null, "eval_results": null, "language": ["en"], "library_name": null, "license": "mit", "license_name": null, "license_link": null, "metrics": ["cer"], "model_name": null, "pipeline_tag": null, "tags": null, "widget": [{"text": "lets do a comparsion", "example_title": "1"}, {"text": "Th... | This is an experimental model that should fix your typos and punctuation.
If you like to run your own experiments or train for a different language, have a look at [the code](https://github.com/oliverguhr/spelling).
## Model description
This is a proof of concept spelling correction model for English.
## Intended u... | null | [
"mit"
] | null | [
"en"
] | 139,470,681 | null | [
"cer"
] | [
"bart",
"BartForConditionalGeneration",
"AutoModelForSeq2SeqLM"
] | [
"text2text-generation"
] | null | null | null |
6466ebf0e65dce8e4333a1e4 | 5630b80c6f9ea88d | 06c5ce10233917b3 | 64,100 | Unigram | null | true | true | true | true | 104 | Sequence | Metaspace | Metaspace | [
"Precompiled",
"Replace"
] | [
"Metaspace"
] | [
"Metaspace"
] | 442 | KETI-AIR-Downstream/long-ke-t5-base-summarization | KETI-AIR-Downstream | {
"models": [
{
"_id": "63d1fd4e244709c85d4a0fca",
"id": "KETI-AIR/long-ke-t5-base"
}
],
"relation": "finetune"
} | 10 | 641,930 | False | 2023-05-19T03:24:32Z | 2023-09-18T01:28:19Z | transformers | 1 | 0 | [{"name": "summarization_all", "results": [{"task": {"type": "summarization", "name": "Summarization"}, "dataset": {"name": "jsonl_dataset_sum.py", "type": "jsonl_dataset_sum.py", "config": "null", "split": "None"}, "metrics": [{"type": "rouge", "value": 21.7197, "name": "Rouge1", "verified": false}]}]}] | null | {"parameters": {"F32": 296696448}, "total": 296696448} | [
".gitattributes",
"README.md",
"config.json",
"model.safetensors",
"pytorch_model.bin",
"special_tokens_map.json",
"spiece.model",
"tokenizer.json",
"tokenizer_config.json"
] | 62499925e1556d05db646bb212ad4bfadd90bf4c | [
"transformers",
"pytorch",
"safetensors",
"longt5",
"text2text-generation",
"generated_from_trainer",
"ko",
"dataset:jsonl_dataset_sum.py",
"base_model:KETI-AIR/long-ke-t5-base",
"base_model:finetune:KETI-AIR/long-ke-t5-base",
"license:artistic-2.0",
"model-index",
"endpoints_compatible",
... | null | {"architectures": ["LongT5ForConditionalGeneration"], "model_type": "longt5", "tokenizer_config": {"bos_token": "<s>", "eos_token": "</s>", "pad_token": "<pad>", "unk_token": "<unk>"}} | {
"auto_model": "AutoModelForSeq2SeqLM",
"custom_class": null,
"pipeline_tag": "text2text-generation",
"processor": "AutoTokenizer"
} | {"base_model": "KETI-AIR/long-ke-t5-base", "datasets": ["jsonl_dataset_sum.py"], "language": ["ko"], "license": "artistic-2.0", "metrics": ["rouge"], "tags": ["generated_from_trainer"], "widget": [{"text": "summarization-num_lines-1: \ud604\ub300\uc790\ub3d9\ucc28\ub294 18\uc77c(\ud604\uc9c0 \uc2dc\uac04) \uc774\ud0c8\... | <!-- This model card has been generated automatically according to the information the Trainer had access to. You
should probably proofread and complete it, then remove this comment. -->
# summarization_all
This model is a fine-tuned version of [KETI-AIR/long-ke-t5-base](https://huggingface.co/KETI-AIR/long-ke-t5-bas... | null | [
"artistic-2.0"
] | [
"jsonl_dataset_sum.py"
] | [
"ko"
] | 296,696,448 | null | [
"rouge"
] | [
"AutoModelForSeq2SeqLM",
"longt5",
"LongT5ForConditionalGeneration"
] | [
"text2text-generation"
] | null | null | null |
64898aec195a6f09f62c326a | 3a732ab237c338af | c21f0239d1cf0f86 | 65,024 | BPE | 64,784 | false | true | false | true | 12 | null | Sequence | ByteLevel | null | [
"Punctuation",
"ByteLevel",
"Digits",
"Split"
] | [
"ByteLevel"
] | 45 | h2oai/h2ogpt-gm-oasst1-en-2048-falcon-7b-v3 | h2oai | null | 183 | 642,088 | False | 2023-06-14T09:39:56Z | 2024-03-24T10:37:28Z | transformers | 74 | 0 | null | text-generation | null | [
".gitattributes",
"README.md",
"cfg.yaml",
"config.json",
"configuration_RW.py",
"generation_config.json",
"h2oai_pipeline.py",
"modelling_RW.py",
"pytorch_model-00001-of-00002.bin",
"pytorch_model-00002-of-00002.bin",
"pytorch_model.bin.index.json",
"special_tokens_map.json",
"tokenizer.jso... | 52845e80f8e78ab6a53be5a679d6f81716f946cd | [
"transformers",
"pytorch",
"RefinedWebModel",
"text-generation",
"gpt",
"llm",
"large language model",
"h2o-llmstudio",
"custom_code",
"en",
"dataset:OpenAssistant/oasst1",
"license:apache-2.0",
"text-generation-inference",
"region:us"
] | null | {"architectures": ["RWForCausalLM"], "auto_map": {"AutoConfig": "configuration_RW.RWConfig", "AutoModel": "modelling_RW.RWModel", "AutoModelForCausalLM": "modelling_RW.RWForCausalLM", "AutoModelForQuestionAnswering": "modelling_RW.RWForQuestionAnswering", "AutoModelForSequenceClassification": "modelling_RW.RWForSequenc... | {
"auto_model": "AutoModelForCausalLM",
"custom_class": "modelling_RW.RWForCausalLM",
"pipeline_tag": "text-generation",
"processor": null
} | {"base_model": null, "datasets": ["OpenAssistant/oasst1"], "eval_results": null, "language": ["en"], "library_name": "transformers", "license": "apache-2.0", "license_name": null, "license_link": null, "metrics": null, "model_name": null, "pipeline_tag": null, "tags": ["gpt", "llm", "large language model", "h2o-llmstud... | # Model Card
## Summary
This model was trained using [H2O LLM Studio](https://github.com/h2oai/h2o-llmstudio).
- Base model: [tiiuae/falcon-7b](https://huggingface.co/tiiuae/falcon-7b)
- Dataset preparation: [OpenAssistant/oasst1](https://github.com/h2oai/h2o-llmstudio/blob/1935d84d9caafed3ee686ad2733eb02d2abfce57/app... | null | [
"apache-2.0"
] | [
"OpenAssistant/oasst1"
] | [
"en"
] | null | null | null | [
"AutoModelForCausalLM",
"RWForCausalLM",
"RefinedWebModel",
"modelling_RW.RWForCausalLM"
] | [
"text-generation"
] | [
"text"
] | [
"text"
] | [
"text"
] |
621ffdc036468d709f175df9 | f68a233b6e1cafdd | 7a200ecd99c055f3 | 42,000 | WordPiece | null | true | true | true | true | 110 | Sequence | BertPreTokenizer | WordPiece | [
"Replace",
"BertNormalizer"
] | [
"BertPreTokenizer"
] | [
"WordPiece"
] | 247 | HooshvareLab/distilbert-fa-zwnj-base-ner | HooshvareLab | null | 11 | 639,549 | False | 2022-03-02T23:29:04Z | 2021-03-21T14:32:29Z | transformers | 4 | 0 | null | token-classification | null | [
".gitattributes",
"README.md",
"config.json",
"pytorch_model.bin",
"special_tokens_map.json",
"tf_model.h5",
"tokenizer.json",
"tokenizer_config.json",
"vocab.txt"
] | 36ccd9aa3dd64c3a83c76de0b8cc5b3f6fa3dc30 | [
"transformers",
"pytorch",
"tf",
"distilbert",
"token-classification",
"fa",
"endpoints_compatible",
"deploy:azure",
"region:us"
] | null | {"architectures": ["DistilBertForTokenClassification"], "model_type": "distilbert", "tokenizer_config": {"unk_token": "[UNK]", "sep_token": "[SEP]", "pad_token": "[PAD]", "cls_token": "[CLS]", "mask_token": "[MASK]"}} | {
"auto_model": "AutoModelForTokenClassification",
"custom_class": null,
"pipeline_tag": "token-classification",
"processor": "AutoTokenizer"
} | {"base_model": null, "datasets": null, "eval_results": null, "language": "fa", "library_name": null, "license": null, "license_name": null, "license_link": null, "metrics": null, "model_name": null, "pipeline_tag": null, "tags": null} | # DistilbertNER
This model fine-tuned for the Named Entity Recognition (NER) task on a mixed NER dataset collected from [ARMAN](https://github.com/HaniehP/PersianNER), [PEYMA](http://nsurl.org/2019-2/tasks/task-7-named-entity-recognition-ner-for-farsi/), and [WikiANN](https://elisa-ie.github.io/wikiann/) that covered ... | null | null | null | [
"fa"
] | null | null | null | [
"AutoModelForTokenClassification",
"distilbert",
"DistilBertForTokenClassification"
] | [
"token-classification"
] | [
"text"
] | [
"text"
] | [
"logits"
] |
63b2b58554211fcd0626176d | 53ecf467267e2824 | 535fa14da0af647c | 30,522 | WordPiece | null | true | true | true | true | 5 | BertNormalizer | BertPreTokenizer | WordPiece | [
"BertNormalizer"
] | [
"BertPreTokenizer"
] | [
"WordPiece"
] | 0 | microsoft/git-large-coco | microsoft | null | 7,789 | 656,721 | False | 2023-01-02T10:44:21Z | 2023-06-26T19:50:47Z | transformers | 104 | 0 | null | image-to-text | {"parameters": {"I64": 1281, "F32": 394196026}, "total": 394197307} | [
".gitattributes",
"README.md",
"config.json",
"generation_config.json",
"model.safetensors",
"preprocessor_config.json",
"pytorch_model.bin",
"special_tokens_map.json",
"tokenizer.json",
"tokenizer_config.json",
"vocab.txt"
] | b644b0b41274649f87de8846fa15f9a22dad7583 | [
"transformers",
"pytorch",
"safetensors",
"git",
"image-text-to-text",
"vision",
"image-captioning",
"image-to-text",
"en",
"arxiv:2205.14100",
"license:mit",
"endpoints_compatible",
"region:us"
] | null | {"architectures": ["GitForCausalLM"], "model_type": "git", "tokenizer_config": {"cls_token": "[CLS]", "mask_token": "[MASK]", "pad_token": "[PAD]", "sep_token": "[SEP]", "unk_token": "[UNK]"}} | {
"auto_model": "AutoModelForImageTextToText",
"custom_class": null,
"pipeline_tag": "image-text-to-text",
"processor": "AutoProcessor"
} | {"base_model": null, "datasets": null, "eval_results": null, "language": "en", "library_name": null, "license": "mit", "license_name": null, "license_link": null, "metrics": null, "model_name": "microsoft/git-large-coco", "pipeline_tag": "image-to-text", "tags": ["vision", "image-captioning"]} | # GIT (GenerativeImage2Text), large-sized, fine-tuned on COCO
GIT (short for GenerativeImage2Text) model, large-sized version, fine-tuned on COCO. It was introduced in the paper [GIT: A Generative Image-to-text Transformer for Vision and Language](https://arxiv.org/abs/2205.14100) by Wang et al. and first released in ... | null | [
"mit"
] | null | [
"en"
] | 394,197,307 | null | null | [
"AutoModelForImageTextToText",
"GitForCausalLM",
"git"
] | [
"image-text-to-text",
"image-to-text"
] | [
"multimodal"
] | [
"text",
"image"
] | [
"text"
] |
654c3a0b7824e2bb58e6624c | 827f6451ef99df30 | dd84a2b1ff97657d | 250,002 | Unigram | null | true | true | true | true | 5 | Precompiled | Sequence | Metaspace | [
"Precompiled"
] | [
"WhitespaceSplit",
"Metaspace"
] | [
"Metaspace"
] | 355 | rollerhafeezh-amikom/xlm-roberta-base-ner-silvanus | rollerhafeezh-amikom | {
"models": [
{
"_id": "621ffdc036468d709f174364",
"id": "FacebookAI/xlm-roberta-base"
}
],
"relation": "finetune"
} | 437 | 637,966 | False | 2023-11-09T01:46:51Z | 2024-04-12T07:23:14Z | transformers | 1 | 0 | [{"name": "xlm-roberta-base-ner-silvanus", "results": [{"task": {"name": "Token Classification", "type": "token-classification"}, "dataset": {"name": "id_nergrit_corpus", "type": "id_nergrit_corpus", "config": "ner", "split": "validation", "args": "ner"}, "metrics": [{"name": "Precision", "type": "precision", "value": ... | token-classification | {"parameters": {"F32": 277458439}, "total": 277458439} | [
".gitattributes",
"README.md",
"config.json",
"model.safetensors",
"runs/Nov09_01-46-49_server-cvis/events.out.tfevents.1699494412.server-cvis.365352.0",
"runs/Nov09_04-21-49_server-cvis/events.out.tfevents.1699503712.server-cvis.365352.1",
"runs/Nov09_06-17-38_server-cvis/events.out.tfevents.1699510669... | 44d67e82b7599ee203cb718ebafd6ef25e615dcf | [
"transformers",
"tensorboard",
"safetensors",
"xlm-roberta",
"token-classification",
"silvanus",
"id",
"en",
"es",
"it",
"sk",
"arxiv:1911.02116",
"base_model:FacebookAI/xlm-roberta-base",
"base_model:finetune:FacebookAI/xlm-roberta-base",
"license:mit",
"model-index",
"endpoints_com... | null | {"architectures": ["XLMRobertaForTokenClassification"], "model_type": "xlm-roberta", "tokenizer_config": {"bos_token": "<s>", "cls_token": "<s>", "eos_token": "</s>", "mask_token": "<mask>", "pad_token": "<pad>", "sep_token": "</s>", "unk_token": "<unk>"}} | {
"auto_model": "AutoModelForTokenClassification",
"custom_class": null,
"pipeline_tag": "token-classification",
"processor": "AutoTokenizer"
} | {"base_model": "xlm-roberta-base", "language": ["id", "en", "es", "it", "sk"], "license": "mit", "metrics": ["precision", "recall", "f1", "accuracy"], "pipeline_tag": "token-classification", "tags": ["silvanus"], "widget": [{"text": "Kebakaran hutan dan lahan terus terjadi dan semakin meluas di Kota Palangkaraya, Kalim... | <!-- This model card has been generated automatically according to the information the Trainer had access to. You
should probably proofread and complete it, then remove this comment. -->
# xlm-roberta-base-ner-silvanus
This model is a fine-tuned version of [xlm-roberta-base](https://huggingface.co/xlm-roberta-base) o... | null | [
"mit"
] | null | [
"id",
"en",
"es",
"it",
"sk"
] | 277,458,439 | null | [
"precision",
"recall",
"f1",
"accuracy"
] | [
"XLMRobertaForTokenClassification",
"AutoModelForTokenClassification",
"xlm-roberta"
] | [
"token-classification"
] | [
"text"
] | [
"text"
] | [
"logits"
] |
644677e41173e85ac7f10745 | cb3f886e13ad7505 | 1f1d26e73b02d1f3 | 49,152 | BPE | 48,891 | false | true | false | true | 19 | null | Sequence | ByteLevel | null | [
"Digits",
"ByteLevel"
] | [
"ByteLevel"
] | 70 | bigcode/starcoder | bigcode | null | 9,760 | 674,568 | auto | 2023-04-24T12:36:52Z | 2024-10-08T20:53:18Z | transformers | 2,929 | 3 | [{"name": "StarCoder", "results": [{"task": {"type": "text-generation"}, "dataset": {"type": "openai_humaneval", "name": "HumanEval (Prompted)"}, "metrics": [{"name": "pass@1", "type": "pass@1", "value": 0.408, "verified": false}]}, {"task": {"type": "text-generation"}, "dataset": {"type": "openai_humaneval", "name": "... | text-generation | {"parameters": {"F32": 15819446272}, "total": 15819446272} | [
".gitattributes",
"README.md",
"config.json",
"generation_config.json",
"merges.txt",
"model-00001-of-00007.safetensors",
"model-00002-of-00007.safetensors",
"model-00003-of-00007.safetensors",
"model-00004-of-00007.safetensors",
"model-00005-of-00007.safetensors",
"model-00006-of-00007.safetens... | 827cd7721231872c152e3faef5cae1b22964ed58 | [
"transformers",
"pytorch",
"safetensors",
"gpt_bigcode",
"text-generation",
"code",
"dataset:bigcode/the-stack-dedup",
"arxiv:1911.02150",
"arxiv:2205.14135",
"arxiv:2207.14255",
"arxiv:2305.06161",
"license:bigcode-openrail-m",
"model-index",
"text-generation-inference",
"endpoints_comp... | null | {"architectures": ["GPTBigCodeForCausalLM"], "model_type": "gpt_bigcode", "tokenizer_config": {"bos_token": "<|endoftext|>", "eos_token": "<|endoftext|>", "unk_token": "<|endoftext|>"}} | {
"auto_model": "AutoModelForCausalLM",
"custom_class": null,
"pipeline_tag": "text-generation",
"processor": "AutoTokenizer"
} | {"datasets": ["bigcode/the-stack-dedup"], "library_name": "transformers", "license": "bigcode-openrail-m", "metrics": ["code_eval"], "pipeline_tag": "text-generation", "tags": ["code"], "inference": true, "widget": [{"text": "def print_hello_world():", "example_title": "Hello world", "group": "Python"}], "extra_gated_p... | null | null | [
"bigcode-openrail-m"
] | [
"bigcode/the-stack-dedup"
] | null | 15,819,446,272 | null | [
"code_eval"
] | [
"gpt_bigcode",
"AutoModelForCausalLM",
"GPTBigCodeForCausalLM"
] | [
"text-generation"
] | [
"text"
] | [
"text"
] | [
"text"
] |
63181b89212fce5a3cdd9c47 | 417178c4b242ef32 | e9c2ff5e848a7383 | 35,000 | WordPiece | null | true | true | true | true | 5 | BertNormalizer | BertPreTokenizer | WordPiece | [
"BertNormalizer"
] | [
"BertPreTokenizer"
] | [
"WordPiece"
] | 443 | circulus/koelectra-polite-v1 | circulus | null | 37,373 | 733,165 | False | 2022-09-07T04:18:17Z | 2022-09-07T09:04:34Z | transformers | 0 | 0 | null | text-classification | null | [
".gitattributes",
"config.json",
"pytorch_model.bin",
"special_tokens_map.json",
"tokenizer.json",
"tokenizer_config.json",
"vocab.txt"
] | 46a101d9780b90bfb1755fcc89bc06b0ea46f806 | [
"transformers",
"pytorch",
"electra",
"text-classification",
"endpoints_compatible",
"deploy:azure",
"region:us"
] | null | {"architectures": ["ElectraForSequenceClassification"], "model_type": "electra", "tokenizer_config": {"cls_token": "[CLS]", "mask_token": "[MASK]", "pad_token": "[PAD]", "sep_token": "[SEP]", "unk_token": "[UNK]"}} | {
"auto_model": "AutoModelForSequenceClassification",
"custom_class": null,
"pipeline_tag": "text-classification",
"processor": "AutoTokenizer"
} | null | null | null | null | null | null | null | null | null | [
"ElectraForSequenceClassification",
"AutoModelForSequenceClassification",
"electra"
] | [
"text-classification"
] | [
"text"
] | [
"text"
] | [
"logits"
] |
6877f63d1bcd9a3f6019dd8d | e034328a2d067fa5 | daab2a732bab72e2 | 128,001 | Unigram | null | true | true | true | true | 5 | Sequence | Sequence | Metaspace | [
"Strip",
"Precompiled",
"Replace"
] | [
"Metaspace"
] | [
"Metaspace"
] | 237 | OpenMed/OpenMed-NER-DiseaseDetect-SuperClinical-434M | OpenMed | null | 163,954 | 1,469,866 | False | 2025-07-16T18:58:05Z | 2025-08-05T09:34:31Z | transformers | 6 | 0 | null | token-classification | {"parameters": {"BF16": 434015235}, "total": 434015235} | [
".gitattributes",
"README.md",
"added_tokens.json",
"config.json",
"model.safetensors",
"openmed_vs_sota_grouped_bars.png",
"special_tokens_map.json",
"spm.model",
"test_results.json",
"tokenizer.json",
"tokenizer_config.json"
] | da6257021de179e8479c6b336f8bd274b525646f | [
"transformers",
"safetensors",
"deberta-v2",
"token-classification",
"named-entity-recognition",
"biomedical-nlp",
"disease-entity-recognition",
"medical-diagnosis",
"pathology",
"biocuration",
"disease",
"en",
"arxiv:2508.01630",
"license:apache-2.0",
"endpoints_compatible",
"region:u... | null | {"architectures": ["DebertaV2ForTokenClassification"], "model_type": "deberta-v2", "tokenizer_config": {"bos_token": "[CLS]", "cls_token": "[CLS]", "eos_token": "[SEP]", "mask_token": "[MASK]", "pad_token": "[PAD]", "sep_token": "[SEP]", "unk_token": "[UNK]"}} | {
"auto_model": "AutoModelForTokenClassification",
"custom_class": null,
"pipeline_tag": "token-classification",
"processor": "AutoTokenizer"
} | {"base_model": null, "datasets": null, "eval_results": null, "language": ["en"], "library_name": null, "license": "apache-2.0", "license_name": null, "license_link": null, "metrics": null, "model_name": null, "pipeline_tag": null, "tags": ["token-classification", "named-entity-recognition", "biomedical-nlp", "transform... | null | null | [
"apache-2.0"
] | null | [
"en"
] | 434,015,235 | null | null | [
"DebertaV2ForTokenClassification",
"AutoModelForTokenClassification",
"deberta-v2"
] | [
"token-classification"
] | [
"text"
] | [
"text"
] | [
"logits"
] |
677f013cfe9f4cd5678fa418 | 7ebc9855769c36cb | 09fc399b14d43f49 | 100,352 | BPE | 100,000 | false | true | false | true | 97 | null | Sequence | ByteLevel | null | [
"Split",
"ByteLevel"
] | [
"ByteLevel"
] | 444 | unsloth/phi-4-unsloth-bnb-4bit | unsloth | {
"models": [
{
"_id": "67597bd1b9cdca50cb621f94",
"id": "microsoft/phi-4"
}
],
"relation": "quantized"
} | 12,275 | 726,276 | False | 2025-01-08T22:50:36Z | 2025-01-13T18:54:31Z | transformers | 64 | 0 | null | text-generation | {"parameters": {"BF16": 1906201600, "F32": 851568, "U8": 13151939214}, "total": 15058992382} | [
".gitattributes",
"README.md",
"config.json",
"generation_config.json",
"merges.txt",
"model-00001-of-00003.safetensors",
"model-00002-of-00003.safetensors",
"model-00003-of-00003.safetensors",
"model.safetensors.index.json",
"special_tokens_map.json",
"tokenizer.json",
"tokenizer_config.json"... | 26dd1bdcaaab6bf52793b1a09b259ceed592d092 | [
"transformers",
"safetensors",
"llama",
"text-generation",
"phi",
"phi4",
"unsloth",
"nlp",
"math",
"code",
"chat",
"conversational",
"en",
"arxiv:2412.08905",
"base_model:microsoft/phi-4",
"base_model:quantized:microsoft/phi-4",
"license:mit",
"text-generation-inference",
"endpo... | null | {"architectures": ["LlamaForCausalLM"], "model_type": "llama", "quantization_config": {"load_in_4bit": true, "load_in_8bit": false, "quant_method": "bitsandbytes"}, "tokenizer_config": {"bos_token": "<|endoftext|>", "chat_template": "{% for message in messages %}{% if (message['role'] == 'system') %}{{'<|im_start|>syst... | {
"auto_model": "AutoModelForCausalLM",
"custom_class": null,
"pipeline_tag": "text-generation",
"processor": "AutoTokenizer"
} | {"base_model": "microsoft/phi-4", "datasets": null, "eval_results": null, "language": ["en"], "library_name": "transformers", "license": "mit", "license_name": null, "license_link": "https://huggingface.co/microsoft/phi-4/resolve/main/LICENSE", "metrics": null, "model_name": null, "pipeline_tag": "text-generation", "ta... | ## See [our collection](https://huggingface.co/collections/unsloth/phi-4-all-versions-677eecf93784e61afe762afa) for versions of Phi-4 including GGUF, 4-bit & more formats.
*Dynamic 4-bit: Unsloth's [Dynamic 4-bit Quants](https://unsloth.ai/blog/dynamic-4bit) selectively avoids quantizing certain parameters, greatly inc... | null | [
"mit",
"https://huggingface.co/microsoft/phi-4/resolve/main/LICENSE"
] | null | [
"en"
] | 15,058,992,382 | null | null | [
"AutoModelForCausalLM",
"llama",
"LlamaForCausalLM"
] | [
"text-generation"
] | [
"text"
] | [
"text"
] | [
"text"
] |
65201767bd82b0a6c8991a98 | d2148bb768dcf67e | 664d254b6eeb0893 | 50,265 | BPE | 50,000 | false | true | true | true | 5 | null | ByteLevel | ByteLevel | null | [
"ByteLevel"
] | [
"ByteLevel"
] | 445 | lakshyakh93/deberta_finetuned_pii | lakshyakh93 | null | 6,547 | 678,590 | False | 2023-10-06T14:19:19Z | 2024-03-08T05:07:37Z | transformers | 60 | 0 | null | token-classification | null | [
".gitattributes",
"README.md",
"added_tokens.json",
"config.json",
"merges.txt",
"optimizer.pt",
"pytorch_model.bin",
"rng_state.pth",
"scheduler.pt",
"special_tokens_map.json",
"tokenizer.json",
"tokenizer_config.json",
"trainer_state.json",
"training_args.bin",
"vocab.json"
] | a038061af92047b0afbbd5ca07d7aa0521789379 | [
"transformers",
"pytorch",
"deberta",
"token-classification",
"en",
"license:mit",
"endpoints_compatible",
"region:us"
] | null | {"architectures": ["DebertaForTokenClassification"], "model_type": "deberta", "tokenizer_config": {"bos_token": "[CLS]", "cls_token": "[CLS]", "eos_token": "[SEP]", "mask_token": "[MASK]", "pad_token": "[PAD]", "sep_token": "[SEP]", "unk_token": "[UNK]"}} | {
"auto_model": "AutoModelForTokenClassification",
"custom_class": null,
"pipeline_tag": "token-classification",
"processor": "AutoTokenizer"
} | {"base_model": null, "datasets": null, "eval_results": null, "language": ["en"], "library_name": null, "license": "mit", "license_name": null, "license_link": null, "metrics": null, "model_name": null, "pipeline_tag": "token-classification", "tags": null} | A finetuned model designed to recognize and classify Personally Identifiable Information (PII) within unstructured text data. This powerful model accurately identifies a wide range of PII categories, such as account names, credit card numbers, emails, phone numbers, and addresses. The model is specifically trained to d... | null | [
"mit"
] | null | [
"en"
] | null | null | null | [
"DebertaForTokenClassification",
"AutoModelForTokenClassification",
"deberta"
] | [
"token-classification"
] | [
"text"
] | [
"text"
] | [
"logits"
] |
628cd93c30d48c565bae4834 | 3d2faa8ffdfba070 | 5f9f736c7dc6fbfa | 28,996 | WordPiece | null | true | true | true | true | 5 | BertNormalizer | BertPreTokenizer | WordPiece | [
"BertNormalizer"
] | [
"BertPreTokenizer"
] | [
"WordPiece"
] | 446 | ismail-lucifer011/autotrain-job_all-903929564 | ismail-lucifer011 | null | 4 | 629,275 | False | 2022-05-24T13:10:20Z | 2022-05-24T14:52:32Z | transformers | 1 | 0 | null | token-classification | null | [
".gitattributes",
"README.md",
"config.json",
"pytorch_model.bin",
"sample_input.pkl",
"special_tokens_map.json",
"tokenizer.json",
"tokenizer_config.json",
"vocab.txt"
] | 3031df2e15619a494dde58715e51498a471799de | [
"transformers",
"pytorch",
"distilbert",
"token-classification",
"en",
"dataset:ismail-lucifer011/autotrain-data-job_all",
"co2_eq_emissions",
"endpoints_compatible",
"deploy:azure",
"region:us"
] | null | {"architectures": ["DistilBertForTokenClassification"], "model_type": "distilbert", "tokenizer_config": {"unk_token": "[UNK]", "sep_token": "[SEP]", "pad_token": "[PAD]", "cls_token": "[CLS]", "mask_token": "[MASK]"}} | {
"auto_model": "AutoModelForTokenClassification",
"custom_class": null,
"pipeline_tag": "token-classification",
"processor": "AutoTokenizer"
} | {"base_model": null, "datasets": ["ismail-lucifer011/autotrain-data-job_all"], "eval_results": null, "language": "en", "library_name": null, "license": null, "license_name": null, "license_link": null, "metrics": null, "model_name": null, "pipeline_tag": null, "tags": null, "widget": [{"text": "I love AutoTrain \ud83e\... | # Model Trained Using AutoTrain
- Problem type: Entity Extraction
- Model ID: 903929564
- CO2 Emissions (in grams): 192.68222884611995
## Validation Metrics
- Loss: 0.0036299973726272583
- Accuracy: 0.9989412009896035
- Precision: 0.9863310000901253
- Recall: 0.9885186672019269
- F1: 0.9874236219367322
## Usage
Yo... | null | null | [
"ismail-lucifer011/autotrain-data-job_all"
] | [
"en"
] | null | null | null | [
"AutoModelForTokenClassification",
"distilbert",
"DistilBertForTokenClassification"
] | [
"token-classification"
] | [
"text"
] | [
"text"
] | [
"logits"
] |
621ffdc036468d709f1764b1 | 6ad670d2742d0236 | 5f06a539f7067498 | 50,400 | BPE | 50,000 | false | true | true | true | 144 | null | ByteLevel | ByteLevel | null | [
"ByteLevel"
] | [
"ByteLevel"
] | 112 | KoboldAI/GPT-J-6B-Janeway | KoboldAI | null | 1,841 | 632,590 | False | 2022-03-02T23:29:04Z | 2022-03-20T12:59:44Z | transformers | 13 | 0 | null | text-generation | null | [
".gitattributes",
"README.md",
"added_tokens.json",
"config.json",
"merges.txt",
"pytorch_model.bin",
"special_tokens_map.json",
"tokenizer.json",
"tokenizer_config.json",
"vocab.json"
] | 036bb03496d648ddc8cf932ad91df8ef1287116c | [
"transformers",
"pytorch",
"gptj",
"text-generation",
"en",
"arxiv:2101.00027",
"license:mit",
"endpoints_compatible",
"deploy:azure",
"region:us"
] | null | {"architectures": ["GPTJForCausalLM"], "model_type": "gptj", "tokenizer_config": {"unk_token": {"content": "<|endoftext|>", "single_word": false, "lstrip": false, "rstrip": false, "normalized": true, "__type": "AddedToken"}, "bos_token": {"content": "<|endoftext|>", "single_word": false, "lstrip": false, "rstrip": fals... | {
"auto_model": "AutoModelForCausalLM",
"custom_class": null,
"pipeline_tag": "text-generation",
"processor": "AutoTokenizer"
} | {"base_model": null, "datasets": null, "eval_results": null, "language": "en", "library_name": null, "license": "mit", "license_name": null, "license_link": null, "metrics": null, "model_name": null, "pipeline_tag": null, "tags": null} | # GPT-J 6B - Janeway
## Model Description
GPT-J 6B-Janeway is a finetune created using EleutherAI's GPT-J 6B model.
## Training data
The training data contains around 2210 ebooks, mostly in the sci-fi and fantasy genres. The dataset is based on the same dataset used by GPT-Neo-2.7B-Picard, with 20% more data in var... | null | [
"mit"
] | null | [
"en"
] | null | null | null | [
"gptj",
"AutoModelForCausalLM",
"GPTJForCausalLM"
] | [
"text-generation"
] | [
"text"
] | [
"text"
] | [
"text"
] |
672f5955f84c8aac97d2929f | 848b60b6cd304b65 | ffc911e785abe60e | 151,665 | BPE | 151,387 | true | true | true | true | 22 | NFC | Sequence | ByteLevel | [
"NFC"
] | [
"Split",
"ByteLevel"
] | [
"ByteLevel"
] | 15 | Qwen/Qwen2.5-Coder-32B-Instruct-AWQ | Qwen | {
"models": [
{
"_id": "672b1f9e956e6880fdb8c1e5",
"id": "Qwen/Qwen2.5-Coder-32B-Instruct"
}
],
"relation": "quantized"
} | 698,934 | 2,850,796 | False | 2024-11-09T12:45:09Z | 2024-11-18T12:55:21Z | transformers | 33 | 0 | null | text-generation | {"parameters": {"I32": 31205621760, "F16": 1558254592}, "total": 32763876352} | [
".gitattributes",
"LICENSE",
"README.md",
"config.json",
"generation_config.json",
"merges.txt",
"model-00001-of-00005.safetensors",
"model-00002-of-00005.safetensors",
"model-00003-of-00005.safetensors",
"model-00004-of-00005.safetensors",
"model-00005-of-00005.safetensors",
"model.safetensor... | 1ed0a6145da0ce550c628e8e8b678f51e695995d | [
"transformers",
"safetensors",
"qwen2",
"text-generation",
"code",
"codeqwen",
"chat",
"qwen",
"qwen-coder",
"conversational",
"en",
"arxiv:2409.12186",
"arxiv:2309.00071",
"arxiv:2407.10671",
"base_model:Qwen/Qwen2.5-Coder-32B-Instruct",
"base_model:quantized:Qwen/Qwen2.5-Coder-32B-In... | null | {"architectures": ["Qwen2ForCausalLM"], "model_type": "qwen2", "quantization_config": {"bits": 4, "quant_method": "awq"}, "tokenizer_config": {"bos_token": null, "chat_template": "{%- if tools %}\n {{- '<|im_start|>system\\n' }}\n {%- if messages[0]['role'] == 'system' %}\n {{- messages[0]['content'] }}\n ... | {
"auto_model": "AutoModelForCausalLM",
"custom_class": null,
"pipeline_tag": "text-generation",
"processor": "AutoTokenizer"
} | {"base_model": ["Qwen/Qwen2.5-Coder-32B-Instruct"], "datasets": null, "eval_results": null, "language": ["en"], "library_name": "transformers", "license": "apache-2.0", "license_name": null, "license_link": "https://huggingface.co/Qwen/Qwen2.5-Coder-32B-Instruct/blob/main/LICENSE", "metrics": null, "model_name": null, ... | # Qwen2.5-Coder-32B-Instruct-AWQ
## Introduction
Qwen2.5-Coder is the latest series of Code-Specific Qwen large language models (formerly known as CodeQwen). As of now, Qwen2.5-Coder has covered six mainstream model sizes, 0.5, 1.5, 3, 7, 14, 32 billion parameters, to meet the needs of different developers. Qwen2.5-C... | null | [
"apache-2.0",
"https://huggingface.co/Qwen/Qwen2.5-Coder-32B-Instruct/blob/main/LICENSE"
] | null | [
"en"
] | 32,763,876,352 | null | null | [
"AutoModelForCausalLM",
"Qwen2ForCausalLM",
"qwen2"
] | [
"text-generation"
] | [
"text"
] | [
"text"
] | [
"text"
] |
628ce3a886d23ad156068964 | fc29ccd738d51f6b | 535fa14da0af647c | 30,522 | WordPiece | null | true | true | true | true | 5 | BertNormalizer | BertPreTokenizer | WordPiece | [
"BertNormalizer"
] | [
"BertPreTokenizer"
] | [
"WordPiece"
] | 1 | ismail-lucifer011/autotrain-name_all-904029577 | ismail-lucifer011 | null | 3 | 627,124 | False | 2022-05-24T13:54:48Z | 2022-05-24T15:43:22Z | transformers | 1 | 0 | null | token-classification | null | [
".gitattributes",
"README.md",
"config.json",
"pytorch_model.bin",
"sample_input.pkl",
"special_tokens_map.json",
"tokenizer.json",
"tokenizer_config.json",
"vocab.txt"
] | 7a0ea3a6b0a2785686b27a4154e26236e7548d5f | [
"transformers",
"pytorch",
"distilbert",
"token-classification",
"en",
"dataset:ismail-lucifer011/autotrain-data-name_all",
"co2_eq_emissions",
"endpoints_compatible",
"deploy:azure",
"region:us"
] | null | {"architectures": ["DistilBertForTokenClassification"], "model_type": "distilbert", "tokenizer_config": {"unk_token": "[UNK]", "sep_token": "[SEP]", "pad_token": "[PAD]", "cls_token": "[CLS]", "mask_token": "[MASK]"}} | {
"auto_model": "AutoModelForTokenClassification",
"custom_class": null,
"pipeline_tag": "token-classification",
"processor": "AutoTokenizer"
} | {"base_model": null, "datasets": ["ismail-lucifer011/autotrain-data-name_all"], "eval_results": null, "language": "en", "library_name": null, "license": null, "license_name": null, "license_link": null, "metrics": null, "model_name": null, "pipeline_tag": null, "tags": null, "widget": [{"text": "I love AutoTrain \ud83e... | # Model Trained Using AutoTrain
- Problem type: Entity Extraction
- Model ID: 904029577
- CO2 Emissions (in grams): 0.8375653425894861
## Validation Metrics
- Loss: 0.0035200684797018766
- Accuracy: 0.9989316041363876
- Precision: 0.9877899024589919
- Recall: 0.9933336010601984
- F1: 0.9905539954046464
## Usage
Yo... | null | null | [
"ismail-lucifer011/autotrain-data-name_all"
] | [
"en"
] | null | null | null | [
"AutoModelForTokenClassification",
"distilbert",
"DistilBertForTokenClassification"
] | [
"token-classification"
] | [
"text"
] | [
"text"
] | [
"logits"
] |
62da9e0cf014388f908830ba | 8e42935d2dbeb45e | daab2a732bab72e2 | 128,001 | Unigram | null | true | true | true | true | 5 | Sequence | Sequence | Metaspace | [
"Strip",
"Precompiled",
"Replace"
] | [
"Metaspace"
] | [
"Metaspace"
] | 204 | deepset/deberta-v3-base-squad2 | deepset | {
"models": [
{
"_id": "621ffdc136468d709f17dee4",
"id": "microsoft/deberta-v3-base"
}
],
"relation": "finetune"
} | 5,377 | 643,576 | False | 2022-07-22T12:54:36Z | 2024-09-24T15:58:07Z | transformers | 21 | 0 | [{"name": "deepset/deberta-v3-base-squad2", "results": [{"task": {"type": "question-answering", "name": "Question Answering"}, "dataset": {"name": "squad_v2", "type": "squad_v2", "config": "squad_v2", "split": "validation"}, "metrics": [{"type": "exact_match", "value": 83.8248, "name": "Exact Match", "verified": true, ... | question-answering | {"parameters": {"I64": 512, "F32": 183833090}, "total": 183833602} | [
".gitattributes",
"README.md",
"added_tokens.json",
"config.json",
"model.safetensors",
"pytorch_model.bin",
"special_tokens_map.json",
"spm.model",
"tokenizer.json",
"tokenizer_config.json"
] | eea39c60cc305c2e4a9504f5ff117294bebb42db | [
"transformers",
"pytorch",
"safetensors",
"deberta-v2",
"question-answering",
"deberta",
"deberta-v3",
"en",
"dataset:squad_v2",
"base_model:microsoft/deberta-v3-base",
"base_model:finetune:microsoft/deberta-v3-base",
"license:cc-by-4.0",
"model-index",
"endpoints_compatible",
"deploy:az... | null | {"architectures": ["DebertaV2ForQuestionAnswering"], "model_type": "deberta-v2", "tokenizer_config": {"bos_token": "[CLS]", "cls_token": "[CLS]", "eos_token": "[SEP]", "mask_token": "[MASK]", "pad_token": "[PAD]", "sep_token": "[SEP]", "unk_token": "[UNK]"}} | {
"auto_model": "AutoModelForQuestionAnswering",
"custom_class": null,
"pipeline_tag": "question-answering",
"processor": "AutoTokenizer"
} | {"base_model": "microsoft/deberta-v3-base", "datasets": ["squad_v2"], "language": "en", "license": "cc-by-4.0", "tags": ["deberta", "deberta-v3"], "model-index": [{"name": "deepset/deberta-v3-base-squad2", "results": [{"task": {"type": "question-answering", "name": "Question Answering"}, "dataset": {"name": "squad_v2",... | # deberta-v3-base for Extractive QA
This is the [deberta-v3-base](https://huggingface.co/microsoft/deberta-v3-base) model, fine-tuned using the [SQuAD2.0](https://huggingface.co/datasets/squad_v2) dataset. It's been trained on question-answer pairs, including unanswerable questions, for the task of Question Answering... | null | [
"cc-by-4.0"
] | [
"squad_v2"
] | [
"en"
] | 183,833,602 | null | null | [
"AutoModelForQuestionAnswering",
"deberta-v2",
"DebertaV2ForQuestionAnswering"
] | [
"question-answering"
] | [
"text"
] | [
"text"
] | [
"text"
] |
621ffdc136468d709f180293 | fc29ccd738d51f6b | 535fa14da0af647c | 30,522 | WordPiece | null | true | true | true | true | 5 | BertNormalizer | BertPreTokenizer | WordPiece | [
"BertNormalizer"
] | [
"BertPreTokenizer"
] | [
"WordPiece"
] | 1 | sentence-transformers/all-MiniLM-L6-v1 | sentence-transformers | null | 4,897 | 639,054 | False | 2022-03-02T23:29:05Z | 2025-03-06T13:19:36Z | sentence-transformers | 17 | 0 | null | sentence-similarity | {"parameters": {"I64": 512, "F32": 22713216}, "total": 22713728} | [
".gitattributes",
"1_Pooling/config.json",
"README.md",
"config.json",
"config_sentence_transformers.json",
"data_config.json",
"model.safetensors",
"modules.json",
"onnx/model.onnx",
"onnx/model_O1.onnx",
"onnx/model_O2.onnx",
"onnx/model_O3.onnx",
"onnx/model_O4.onnx",
"onnx/model_qint8_... | d8ccfb53d087c448cf4f48efed6ea98a01d7e47a | [
"sentence-transformers",
"pytorch",
"onnx",
"safetensors",
"openvino",
"bert",
"feature-extraction",
"sentence-similarity",
"transformers",
"en",
"arxiv:1904.06472",
"arxiv:2102.07033",
"arxiv:2104.08727",
"arxiv:1704.05179",
"arxiv:1810.09305",
"license:apache-2.0",
"text-embeddings... | null | {"architectures": ["BertModel"], "model_type": "bert", "tokenizer_config": {"unk_token": "[UNK]", "sep_token": "[SEP]", "pad_token": "[PAD]", "cls_token": "[CLS]", "mask_token": "[MASK]"}} | {
"auto_model": "AutoModel",
"custom_class": null,
"pipeline_tag": "feature-extraction",
"processor": "AutoTokenizer"
} | {"base_model": null, "datasets": null, "eval_results": null, "language": "en", "library_name": "sentence-transformers", "license": "apache-2.0", "license_name": null, "license_link": null, "metrics": null, "model_name": null, "pipeline_tag": "sentence-similarity", "tags": ["sentence-transformers", "feature-extraction",... | # all-MiniLM-L6-v1
This is a [sentence-transformers](https://www.SBERT.net) model: It maps sentences & paragraphs to a 384 dimensional dense vector space and can be used for tasks like clustering or semantic search.
## Usage (Sentence-Transformers)
Using this model becomes easy when you have [sentence-transformers](ht... | null | [
"apache-2.0"
] | null | [
"en"
] | 22,713,728 | null | null | [
"BertModel",
"AutoModel",
"bert"
] | [
"sentence-similarity",
"feature-extraction"
] | [
"text",
"multimodal"
] | [
"text"
] | [
"logits",
"embeddings"
] |
658e77364a24a38778a2b6fa | 6950482313cc6dd9 | dd84a2b1ff97657d | 250,002 | Unigram | null | true | true | true | true | 5 | Sequence | Metaspace | Metaspace | [
"Precompiled",
"Replace"
] | [
"Metaspace"
] | [
"Metaspace"
] | 68 | maidalun1020/bce-reranker-base_v1 | maidalun1020 | null | 3,955 | 650,123 | False | 2023-12-29T07:37:26Z | 2025-07-22T05:14:26Z | sentence-transformers | 198 | 1 | null | text-classification | null | [
".gitattributes",
"README.md",
"assets/Wechat.jpg",
"assets/rag_eval_multiple_domains_summary.jpg",
"config.json",
"pytorch_model.bin",
"sentencepiece.bpe.model",
"special_tokens_map.json",
"tokenizer.json",
"tokenizer_config.json"
] | eb7650fca1d81e2856fbd0d522488844aa502735 | [
"sentence-transformers",
"pytorch",
"xlm-roberta",
"text-classification",
"transformers",
"en",
"zh",
"ja",
"ko",
"license:apache-2.0",
"text-embeddings-inference",
"endpoints_compatible",
"deploy:azure",
"region:us"
] | null | {"architectures": ["XLMRobertaForSequenceClassification"], "model_type": "xlm-roberta", "tokenizer_config": {"bos_token": "<s>", "cls_token": "<s>", "eos_token": "</s>", "mask_token": "<mask>", "pad_token": "<pad>", "sep_token": "</s>", "unk_token": "<unk>"}} | {
"auto_model": "AutoModelForSequenceClassification",
"custom_class": null,
"pipeline_tag": "text-classification",
"processor": "AutoTokenizer"
} | {"base_model": null, "datasets": null, "eval_results": null, "language": ["en", "zh", "ja", "ko"], "library_name": null, "license": "apache-2.0", "license_name": null, "license_link": null, "metrics": null, "model_name": null, "pipeline_tag": "text-classification", "tags": ["transformers", "sentence-transformers"]} | null | null | [
"apache-2.0"
] | null | [
"en",
"zh",
"ja",
"ko"
] | null | null | null | [
"AutoModelForSequenceClassification",
"XLMRobertaForSequenceClassification",
"xlm-roberta"
] | [
"text-classification"
] | [
"text"
] | [
"text"
] | [
"logits"
] |
62c4cf357cfd2f06059dd893 | 6085f0eaa3d68297 | 155c91d3d4d7bd53 | 30,522 | WordPiece | null | true | true | true | true | 6 | BertNormalizer | BertPreTokenizer | WordPiece | [
"BertNormalizer"
] | [
"BertPreTokenizer"
] | [
"WordPiece"
] | 447 | allenai/ivila-row-layoutlm-finetuned-s2vl-v2 | allenai | null | 1,745 | 662,222 | False | 2022-07-05T23:54:29Z | 2022-10-03T22:05:24Z | transformers | 2 | 0 | null | token-classification | null | [
".gitattributes",
"README.md",
"config.json",
"pytorch_model.bin",
"special_tokens_map.json",
"tokenizer.json",
"tokenizer_config.json",
"vocab.txt"
] | 54ee55d75bad59ce5fc3688fa4c72969165caf0d | [
"transformers",
"pytorch",
"layoutlm",
"token-classification",
"en",
"endpoints_compatible",
"deploy:azure",
"region:us"
] | null | {"architectures": ["LayoutLMForTokenClassification"], "model_type": "layoutlm", "tokenizer_config": {"unk_token": "[UNK]", "sep_token": "[SEP]", "pad_token": "[PAD]", "cls_token": "[CLS]", "mask_token": "[MASK]"}} | {
"auto_model": "AutoModelForTokenClassification",
"custom_class": null,
"pipeline_tag": "token-classification",
"processor": "AutoTokenizer"
} | {"base_model": null, "datasets": null, "eval_results": null, "language": "en", "library_name": null, "license": null, "license_name": null, "license_link": null, "metrics": null, "model_name": null, "pipeline_tag": null, "tags": null} | null | null | null | null | [
"en"
] | null | null | null | [
"layoutlm",
"AutoModelForTokenClassification",
"LayoutLMForTokenClassification"
] | [
"token-classification"
] | [
"text"
] | [
"text"
] | [
"logits"
] |
66eb4fe961228b02f836c3f4 | 848b60b6cd304b65 | ffc911e785abe60e | 151,665 | BPE | 151,387 | true | true | true | true | 22 | NFC | Sequence | ByteLevel | [
"NFC"
] | [
"Split",
"ByteLevel"
] | [
"ByteLevel"
] | 15 | mlx-community/Qwen2.5-Coder-1.5B-Instruct-4bit | mlx-community | {
"models": [
{
"_id": "66eaa052d25d383ddb9a6c5f",
"id": "Qwen/Qwen2.5-Coder-1.5B"
}
],
"relation": "finetune"
} | 830 | 629,670 | False | 2024-09-18T22:10:49Z | 2024-09-18T22:11:12Z | transformers | 2 | 0 | null | text-generation | null | [
".gitattributes",
"README.md",
"added_tokens.json",
"config.json",
"merges.txt",
"model.safetensors",
"model.safetensors.index.json",
"special_tokens_map.json",
"tokenizer.json",
"tokenizer_config.json",
"vocab.json"
] | b3252a2f97102b1fb1571fec2c9b27219a8536be | [
"transformers",
"safetensors",
"qwen2",
"text-generation",
"code",
"codeqwen",
"chat",
"qwen",
"qwen-coder",
"mlx",
"conversational",
"en",
"base_model:Qwen/Qwen2.5-Coder-1.5B",
"base_model:finetune:Qwen/Qwen2.5-Coder-1.5B",
"license:apache-2.0",
"text-generation-inference",
"endpoin... | null | {"architectures": ["Qwen2ForCausalLM"], "model_type": "qwen2", "tokenizer_config": {"bos_token": null, "chat_template": "{%- if tools %}\n {{- '<|im_start|>system\\n' }}\n {%- if messages[0]['role'] == 'system' %}\n {{- messages[0]['content'] }}\n {%- else %}\n {{- 'You are a helpful assistant.' ... | {
"auto_model": "AutoModelForCausalLM",
"custom_class": null,
"pipeline_tag": "text-generation",
"processor": "AutoTokenizer"
} | {"base_model": ["Qwen/Qwen2.5-Coder-1.5B"], "datasets": null, "eval_results": null, "language": ["en"], "library_name": "transformers", "license": "apache-2.0", "license_name": null, "license_link": "https://huggingface.co/Qwen/Qwen2.5-Coder-1.5B-Instruct/blob/main/LICENSE", "metrics": null, "model_name": null, "pipeli... | # mlx-community/Qwen2.5-Coder-1.5B-Instruct-4bit
The Model [mlx-community/Qwen2.5-Coder-1.5B-Instruct-4bit](https://huggingface.co/mlx-community/Qwen2.5-Coder-1.5B-Instruct-4bit) was converted to MLX format from [Qwen/Qwen2.5-Coder-1.5B-Instruct](https://huggingface.co/Qwen/Qwen2.5-Coder-1.5B-Instruct) using mlx-lm ve... | null | [
"apache-2.0",
"https://huggingface.co/Qwen/Qwen2.5-Coder-1.5B-Instruct/blob/main/LICENSE"
] | null | [
"en"
] | null | null | null | [
"AutoModelForCausalLM",
"Qwen2ForCausalLM",
"qwen2"
] | [
"text-generation"
] | [
"text"
] | [
"text"
] | [
"text"
] |
67962595a08d7b966abd37e9 | aeec37df2d25338d | 39a833f1b18a9553 | 100,590 | BPE | 99,757 | true | true | true | true | 590 | Sequence | Sequence | ByteLevel | [] | [
"Split",
"Split",
"Split",
"Split",
"Split",
"Digits",
"ByteLevel"
] | [
"ByteLevel"
] | 448 | deepseek-ai/Janus-Pro-1B | deepseek-ai | null | 5,674 | 665,792 | False | 2025-01-26T12:07:49Z | 2025-02-01T08:00:32Z | transformers | 473 | 0 | null | any-to-any | null | [
".gitattributes",
"README.md",
"config.json",
"janus_pro_teaser1.png",
"janus_pro_teaser2.png",
"preprocessor_config.json",
"processor_config.json",
"pytorch_model.bin",
"special_tokens_map.json",
"tokenizer.json",
"tokenizer_config.json"
] | 960ab33191f61342a4c60ae74d8dc356a39fafcb | [
"transformers",
"pytorch",
"multi_modality",
"muiltimodal",
"text-to-image",
"unified-model",
"any-to-any",
"arxiv:2501.17811",
"license:mit",
"endpoints_compatible",
"region:us"
] | null | {"architectures": ["MultiModalityCausalLM"], "model_type": "multi_modality", "tokenizer_config": {"bos_token": "<\uff5cbegin\u2581of\u2581sentence\uff5c>", "eos_token": "<\uff5cend\u2581of\u2581sentence\uff5c>", "pad_token": null, "unk_token": null, "use_default_system_prompt": true}} | {
"auto_model": "MultiModalityCausalLM",
"custom_class": null,
"pipeline_tag": null,
"processor": null
} | {"base_model": null, "datasets": null, "eval_results": null, "language": null, "library_name": "transformers", "license": "mit", "license_name": "deepseek", "license_link": "LICENSE", "metrics": null, "model_name": null, "pipeline_tag": "any-to-any", "tags": ["muiltimodal", "text-to-image", "unified-model"]} | ## 1. Introduction
Janus-Pro is a novel autoregressive framework that unifies multimodal understanding and generation.
It addresses the limitations of previous approaches by decoupling visual encoding into separate pathways, while still utilizing a single, unified transformer architecture for processing. The decoupli... | null | [
"mit",
"deepseek",
"LICENSE"
] | null | null | null | null | null | [
"multi_modality",
"MultiModalityCausalLM"
] | [
null,
"text-to-image",
"any-to-any"
] | [
"vision",
"multimodal"
] | [
"text",
"any"
] | [
"any",
"image"
] |
621ffdc136468d709f1802f0 | 71140a663949f258 | 8a01c02d4d0a401c | 119,547 | WordPiece | null | true | true | true | true | 5 | BertNormalizer | BertPreTokenizer | WordPiece | [
"BertNormalizer"
] | [
"BertPreTokenizer"
] | [
"WordPiece"
] | 9 | sentence-transformers/quora-distilbert-multilingual | sentence-transformers | null | 419 | 630,277 | False | 2022-03-02T23:29:05Z | 2025-03-06T13:24:45Z | sentence-transformers | 7 | 0 | null | sentence-similarity | {"parameters": {"F32": 134734080}, "total": 134734080} | [
".gitattributes",
"1_Pooling/config.json",
"README.md",
"config.json",
"config_sentence_transformers.json",
"model.safetensors",
"modules.json",
"onnx/model.onnx",
"onnx/model_O1.onnx",
"onnx/model_O2.onnx",
"onnx/model_O3.onnx",
"onnx/model_O4.onnx",
"onnx/model_qint8_arm64.onnx",
"onnx/m... | 2e32dee5140b6cbea86dd68195a25d463bfe071b | [
"sentence-transformers",
"pytorch",
"tf",
"onnx",
"safetensors",
"openvino",
"distilbert",
"feature-extraction",
"sentence-similarity",
"transformers",
"arxiv:1908.10084",
"license:apache-2.0",
"text-embeddings-inference",
"endpoints_compatible",
"region:us"
] | null | {"architectures": ["DistilBertModel"], "model_type": "distilbert", "tokenizer_config": {"unk_token": "[UNK]", "sep_token": "[SEP]", "pad_token": "[PAD]", "cls_token": "[CLS]", "mask_token": "[MASK]"}} | {
"auto_model": "AutoModel",
"custom_class": null,
"pipeline_tag": "feature-extraction",
"processor": "AutoTokenizer"
} | {"base_model": null, "datasets": null, "eval_results": null, "language": null, "library_name": "sentence-transformers", "license": "apache-2.0", "license_name": null, "license_link": null, "metrics": null, "model_name": null, "pipeline_tag": "sentence-similarity", "tags": ["sentence-transformers", "feature-extraction",... | # sentence-transformers/quora-distilbert-multilingual
This is a [sentence-transformers](https://www.SBERT.net) model: It maps sentences & paragraphs to a 768 dimensional dense vector space and can be used for tasks like clustering or semantic search.
## Usage (Sentence-Transformers)
Using this model becomes easy w... | null | [
"apache-2.0"
] | null | null | 134,734,080 | null | null | [
"AutoModel",
"distilbert",
"DistilBertModel"
] | [
"sentence-similarity",
"feature-extraction"
] | [
"text",
"multimodal"
] | [
"text"
] | [
"logits",
"embeddings"
] |
67534c2710cacca70af75ae3 | 1e0a2493163c0c63 | 6622292dca275a2d | 128,256 | BPE | 280,147 | false | true | true | true | 256 | null | Sequence | ByteLevel | null | [
"Split",
"ByteLevel"
] | [
"ByteLevel"
] | 18 | casperhansen/llama-3.3-70b-instruct-awq | casperhansen | {
"models": [
{
"_id": "66944fd095c7fa6e68c314ae",
"id": "meta-llama/Llama-3.1-70B"
}
],
"relation": "quantized"
} | 701,297 | 2,056,670 | False | 2024-12-06T19:10:31Z | 2024-12-06T19:24:27Z | transformers | 41 | 0 | null | text-generation | {"parameters": {"I32": 68451041280, "F16": 2102665216}, "total": 70553706496} | [
".gitattributes",
"README.md",
"config.json",
"generation_config.json",
"model-00001-of-00009.safetensors",
"model-00002-of-00009.safetensors",
"model-00003-of-00009.safetensors",
"model-00004-of-00009.safetensors",
"model-00005-of-00009.safetensors",
"model-00006-of-00009.safetensors",
"model-0... | 64d255621f40b42adaf6d1f32a47e1d4534c0f14 | [
"transformers",
"safetensors",
"llama",
"text-generation",
"conversational",
"en",
"fr",
"it",
"pt",
"hi",
"es",
"th",
"de",
"base_model:meta-llama/Llama-3.1-70B",
"base_model:quantized:meta-llama/Llama-3.1-70B",
"license:llama3.3",
"text-generation-inference",
"endpoints_compatibl... | null | {"architectures": ["LlamaForCausalLM"], "model_type": "llama", "quantization_config": {"bits": 4, "quant_method": "awq"}, "tokenizer_config": {"bos_token": "<|begin_of_text|>", "chat_template": "{{- bos_token }}\n{%- if custom_tools is defined %}\n {%- set tools = custom_tools %}\n{%- endif %}\n{%- if not tools_in_u... | {
"auto_model": "AutoModelForCausalLM",
"custom_class": null,
"pipeline_tag": "text-generation",
"processor": "AutoTokenizer"
} | {"base_model": ["meta-llama/Llama-3.1-70B"], "datasets": null, "eval_results": null, "language": ["en", "fr", "it", "pt", "hi", "es", "th", "de"], "library_name": "transformers", "license": "llama3.3", "license_name": null, "license_link": null, "metrics": null, "model_name": null, "pipeline_tag": null, "tags": null} | This is the AWQ version of the Llama 3.3 70B Instruct model. Find more info here: https://github.com/casper-hansen/AutoAWQ.
## Model Information
The Meta Llama 3.3 multilingual large language model (LLM) is a pretrained and instruction tuned generative model in 70B (text in/text out). The Llama 3.3 instruction tuned ... | null | [
"llama3.3"
] | null | [
"en",
"fr",
"it",
"pt",
"hi",
"es",
"th",
"de"
] | 70,553,706,496 | null | null | [
"AutoModelForCausalLM",
"llama",
"LlamaForCausalLM"
] | [
"text-generation"
] | [
"text"
] | [
"text"
] | [
"text"
] |
621ffdc036468d709f1743ec | 7b07d3f5339a7fda | 84fb34b2e1636fc5 | 30,527 | WordPiece | null | true | true | true | true | 6 | BertNormalizer | BertPreTokenizer | WordPiece | [
"BertNormalizer"
] | [
"BertPreTokenizer"
] | [
"WordPiece"
] | 449 | AI-Growth-Lab/PatentSBERTa | AI-Growth-Lab | null | 15,121 | 694,621 | False | 2022-03-02T23:29:04Z | 2023-02-16T18:25:30Z | sentence-transformers | 54 | 1 | null | sentence-similarity | null | [
".gitattributes",
"1_Pooling/config.json",
"README.md",
"config.json",
"config_sentence_transformers.json",
"modules.json",
"pytorch_model.bin",
"sentence_bert_config.json",
"special_tokens_map.json",
"tokenizer.json",
"tokenizer_config.json",
"vocab.txt"
] | 3ff1d553c861d8f5bfd902333d97fc95eb6b4c8f | [
"sentence-transformers",
"pytorch",
"mpnet",
"feature-extraction",
"sentence-similarity",
"transformers",
"arxiv:2103.11933",
"text-embeddings-inference",
"endpoints_compatible",
"deploy:azure",
"region:us"
] | null | {"architectures": ["MPNetModel"], "model_type": "mpnet", "tokenizer_config": {"bos_token": "<s>", "eos_token": "</s>", "sep_token": "</s>", "cls_token": "<s>", "unk_token": "[UNK]", "pad_token": "<pad>", "mask_token": "<mask>"}} | {
"auto_model": "AutoModel",
"custom_class": null,
"pipeline_tag": "feature-extraction",
"processor": "AutoTokenizer"
} | {"base_model": null, "datasets": null, "eval_results": null, "language": null, "library_name": null, "license": null, "license_name": null, "license_link": null, "metrics": null, "model_name": null, "pipeline_tag": "sentence-similarity", "tags": ["sentence-transformers", "feature-extraction", "sentence-similarity", "tr... | # PatentSBERTa
## PatentSBERTa: A Deep NLP based Hybrid Model for Patent Distance and Classification using Augmented SBERT
### Aalborg University Business School, AI: Growth-Lab
https://arxiv.org/abs/2103.11933
https://github.com/AI-Growth-Lab/PatentSBERTa
This is a [sentence-transformers](https://www.SBERT.net... | null | null | null | null | null | null | null | [
"MPNetModel",
"AutoModel",
"mpnet"
] | [
"sentence-similarity",
"feature-extraction"
] | [
"text",
"multimodal"
] | [
"text"
] | [
"logits",
"embeddings"
] |
67adba46aac770ddbb04e7f7 | 616c061030c03d7b | ffc911e785abe60e | 151,665 | BPE | 151,387 | true | true | true | true | 22 | NFC | Sequence | ByteLevel | [
"NFC"
] | [
"Split",
"ByteLevel"
] | [
"ByteLevel"
] | 195 | Qwen/Qwen2.5-VL-72B-Instruct-AWQ | Qwen | {
"models": [
{
"_id": "6797079422990ae89b5aff86",
"id": "Qwen/Qwen2.5-VL-72B-Instruct"
}
],
"relation": "quantized"
} | 62,637 | 1,187,708 | False | 2025-02-13T09:24:22Z | 2025-03-07T10:21:14Z | transformers | 71 | 0 | null | image-text-to-text | {"parameters": {"I32": 70464307200, "BF16": 3197309184, "F16": 819200}, "total": 73662435584} | [
".gitattributes",
"LICENSE",
"README.md",
"added_tokens.json",
"chat_template.json",
"config.json",
"generation_config.json",
"merges.txt",
"model-00001-of-00011.safetensors",
"model-00002-of-00011.safetensors",
"model-00003-of-00011.safetensors",
"model-00004-of-00011.safetensors",
"model-0... | c8b87d4b81f34b6a147577a310d7e75f0698f6c2 | [
"transformers",
"safetensors",
"qwen2_5_vl",
"image-text-to-text",
"multimodal",
"conversational",
"en",
"arxiv:2309.00071",
"arxiv:2409.12191",
"arxiv:2308.12966",
"base_model:Qwen/Qwen2.5-VL-72B-Instruct",
"base_model:quantized:Qwen/Qwen2.5-VL-72B-Instruct",
"license:other",
"text-genera... | null | {"architectures": ["Qwen2_5_VLForConditionalGeneration"], "model_type": "qwen2_5_vl", "quantization_config": {"bits": 4, "quant_method": "awq"}, "processor_config": {"chat_template": "{% set image_count = namespace(value=0) %}{% set video_count = namespace(value=0) %}{% for message in messages %}{% if loop.first and me... | {
"auto_model": "AutoModelForImageTextToText",
"custom_class": null,
"pipeline_tag": "image-text-to-text",
"processor": "AutoProcessor"
} | {"base_model": ["Qwen/Qwen2.5-VL-72B-Instruct"], "datasets": null, "eval_results": null, "language": ["en"], "library_name": "transformers", "license": "other", "license_name": "qwen", "license_link": "https://huggingface.co/Qwen/Qwen2.5-VL-72B-Instruct-AWQ/blob/main/LICENSE", "metrics": null, "model_name": null, "pipe... | # Qwen2.5-VL-72B-Instruct-AWQ
<a href="https://chat.qwenlm.ai/" target="_blank" style="margin: 2px;">
<img alt="Chat" src="https://img.shields.io/badge/%F0%9F%92%9C%EF%B8%8F%20Qwen%20Chat%20-536af5" style="display: inline-block; vertical-align: middle;"/>
</a>
## Introduction
In the past five months since Qwen2-V... | null | [
"other",
"qwen",
"https://huggingface.co/Qwen/Qwen2.5-VL-72B-Instruct-AWQ/blob/main/LICENSE"
] | null | [
"en"
] | 73,662,435,584 | null | null | [
"qwen2_5_vl",
"AutoModelForImageTextToText",
"Qwen2_5_VLForConditionalGeneration"
] | [
"image-text-to-text"
] | [
"multimodal"
] | [
"text",
"image"
] | [
"text"
] |
66cfe01eca7fd5891755004a | 9ce802ff75cac6bf | 6b3612a55f8124d9 | 151,657 | BPE | 151,387 | true | true | true | true | 14 | NFC | Sequence | ByteLevel | [
"NFC"
] | [
"Split",
"ByteLevel"
] | [
"ByteLevel"
] | 340 | Qwen/Qwen2-VL-7B-Instruct-GPTQ-Int4 | Qwen | {
"models": [
{
"_id": "66cee7d175a88154443a4056",
"id": "Qwen/Qwen2-VL-7B-Instruct"
}
],
"relation": "quantized"
} | 44,759 | 683,060 | False | 2024-08-29T02:42:38Z | 2024-09-21T08:41:40Z | transformers | 37 | 0 | null | image-text-to-text | {"parameters": {"I32": 6525288448, "F16": 1766087168}, "total": 8291375616} | [
".gitattributes",
"LICENSE",
"README.md",
"added_tokens.json",
"chat_template.json",
"config.json",
"generation_config.json",
"merges.txt",
"model-00001-of-00002.safetensors",
"model-00002-of-00002.safetensors",
"model.safetensors.index.json",
"preprocessor_config.json",
"quantize_config.jso... | dec510a35a3e9b6481b6427c7a08984df2402535 | [
"transformers",
"safetensors",
"qwen2_vl",
"image-text-to-text",
"multimodal",
"conversational",
"en",
"arxiv:2409.12191",
"arxiv:2308.12966",
"base_model:Qwen/Qwen2-VL-7B-Instruct",
"base_model:quantized:Qwen/Qwen2-VL-7B-Instruct",
"license:apache-2.0",
"text-generation-inference",
"endpo... | null | {"architectures": ["Qwen2VLForConditionalGeneration"], "model_type": "qwen2_vl", "quantization_config": {"bits": 4, "quant_method": "gptq"}, "processor_config": {"chat_template": "{% set image_count = namespace(value=0) %}{% set video_count = namespace(value=0) %}{% for message in messages %}{% if loop.first and messag... | {
"auto_model": "AutoModelForImageTextToText",
"custom_class": null,
"pipeline_tag": "image-text-to-text",
"processor": "AutoProcessor"
} | {"base_model": "Qwen/Qwen2-VL-7B-Instruct", "datasets": null, "eval_results": null, "language": ["en"], "library_name": "transformers", "license": "apache-2.0", "license_name": null, "license_link": null, "metrics": null, "model_name": null, "pipeline_tag": "image-text-to-text", "tags": ["multimodal"]} | # Qwen2-VL-7B-Instruct-GPTQ-Int4
## Introduction
We're excited to unveil **Qwen2-VL**, the latest iteration of our Qwen-VL model, representing nearly a year of innovation.
### What’s New in Qwen2-VL?
#### Key Enhancements:
* **SoTA understanding of images of various resolution & ratio**: Qwen2-VL achieves state-of... | null | [
"apache-2.0"
] | null | [
"en"
] | 8,291,375,616 | null | null | [
"AutoModelForImageTextToText",
"qwen2_vl",
"Qwen2VLForConditionalGeneration"
] | [
"image-text-to-text"
] | [
"multimodal"
] | [
"text",
"image"
] | [
"text"
] |
67ff7b22b5ba13b43f0c3811 | 848b60b6cd304b65 | ffc911e785abe60e | 151,665 | BPE | 151,387 | true | true | true | true | 22 | NFC | Sequence | ByteLevel | [
"NFC"
] | [
"Split",
"ByteLevel"
] | [
"ByteLevel"
] | 15 | ByteDance-Seed/UI-TARS-1.5-7B | ByteDance-Seed | null | 150,091 | 1,602,459 | False | 2025-04-16T09:40:50Z | 2025-04-18T01:35:38Z | transformers | 533 | 4 | null | image-text-to-text | {"parameters": {"F32": 8292166656}, "total": 8292166656} | [
".gitattributes",
"README.md",
"added_tokens.json",
"chat_template.json",
"config.json",
"merges.txt",
"model-00001-of-00007.safetensors",
"model-00002-of-00007.safetensors",
"model-00003-of-00007.safetensors",
"model-00004-of-00007.safetensors",
"model-00005-of-00007.safetensors",
"model-0000... | 683d002dd99d8f95104d31e70391a39348857f4e | [
"transformers",
"safetensors",
"qwen2_5_vl",
"image-text-to-text",
"multimodal",
"gui",
"conversational",
"en",
"arxiv:2501.12326",
"arxiv:2404.07972",
"arxiv:2409.08264",
"arxiv:2401.13919",
"arxiv:2504.01382",
"arxiv:2405.14573",
"arxiv:2410.23218",
"arxiv:2504.07981",
"license:apa... | null | {"architectures": ["Qwen2_5_VLForConditionalGeneration"], "model_type": "qwen2_5_vl", "processor_config": {"chat_template": "{% set image_count = namespace(value=0) %}{% set video_count = namespace(value=0) %}{% for message in messages %}{% if loop.first and message['role'] != 'system' %}<|im_start|>system\nYou are a h... | {
"auto_model": "AutoModelForImageTextToText",
"custom_class": null,
"pipeline_tag": "image-text-to-text",
"processor": "AutoProcessor"
} | {"base_model": null, "datasets": null, "eval_results": null, "language": ["en"], "library_name": "transformers", "license": "apache-2.0", "license_name": null, "license_link": null, "metrics": null, "model_name": null, "pipeline_tag": "image-text-to-text", "tags": ["multimodal", "gui"]} | null | null | [
"apache-2.0"
] | null | [
"en"
] | 8,292,166,656 | null | null | [
"qwen2_5_vl",
"AutoModelForImageTextToText",
"Qwen2_5_VLForConditionalGeneration"
] | [
"image-text-to-text"
] | [
"multimodal"
] | [
"text",
"image"
] | [
"text"
] |
680f75ea384885553e1ab6c1 | 7428ef9ae5ef868f | 67da9c236fa81925 | 151,669 | BPE | 151,387 | true | true | true | true | 26 | NFC | Sequence | ByteLevel | [
"NFC"
] | [
"Split",
"ByteLevel"
] | [
"ByteLevel"
] | 47 | Qwen/Qwen3-8B-FP8 | Qwen | {
"models": [
{
"_id": "680da79d48c19d19cf82ab5e",
"id": "Qwen/Qwen3-8B"
}
],
"relation": "quantized"
} | 203,999 | 1,579,914 | False | 2025-04-28T12:34:50Z | 2025-07-26T03:46:05Z | transformers | 59 | 0 | null | text-generation | {"parameters": {"BF16": 1245391872, "F8_E4M3": 6945767424}, "total": 8191159296} | [
".gitattributes",
"LICENSE",
"README.md",
"config.json",
"generation_config.json",
"merges.txt",
"model-00001-of-00002.safetensors",
"model-00002-of-00002.safetensors",
"model.safetensors.index.json",
"tokenizer.json",
"tokenizer_config.json",
"vocab.json"
] | 220b46e3b2180893580a4454f21f22d3ebb187d3 | [
"transformers",
"safetensors",
"qwen3",
"text-generation",
"conversational",
"arxiv:2309.00071",
"arxiv:2505.09388",
"base_model:Qwen/Qwen3-8B",
"base_model:quantized:Qwen/Qwen3-8B",
"license:apache-2.0",
"text-generation-inference",
"endpoints_compatible",
"fp8",
"region:us"
] | null | {"architectures": ["Qwen3ForCausalLM"], "model_type": "qwen3", "quantization_config": {"quant_method": "fp8"}, "tokenizer_config": {"bos_token": null, "chat_template": "{%- if tools %}\n {{- '<|im_start|>system\\n' }}\n {%- if messages[0].role == 'system' %}\n {{- messages[0].content + '\\n\\n' }}\n {%-... | {
"auto_model": "AutoModelForCausalLM",
"custom_class": null,
"pipeline_tag": "text-generation",
"processor": "AutoTokenizer"
} | {"base_model": ["Qwen/Qwen3-8B"], "datasets": null, "eval_results": null, "language": null, "library_name": "transformers", "license": "apache-2.0", "license_name": null, "license_link": "https://huggingface.co/Qwen/Qwen3-8B-FP8/blob/main/LICENSE", "metrics": null, "model_name": null, "pipeline_tag": "text-generation",... | null | null | [
"apache-2.0",
"https://huggingface.co/Qwen/Qwen3-8B-FP8/blob/main/LICENSE"
] | null | null | 8,191,159,296 | null | null | [
"AutoModelForCausalLM",
"Qwen3ForCausalLM",
"qwen3"
] | [
"text-generation"
] | [
"text"
] | [
"text"
] | [
"text"
] |
628cd2e8ef14f971b699c59c | fc29ccd738d51f6b | 535fa14da0af647c | 30,522 | WordPiece | null | true | true | true | true | 5 | BertNormalizer | BertPreTokenizer | WordPiece | [
"BertNormalizer"
] | [
"BertPreTokenizer"
] | [
"WordPiece"
] | 1 | ismail-lucifer011/autotrain-company_all-903429548 | ismail-lucifer011 | null | 2 | 616,383 | False | 2022-05-24T12:43:20Z | 2022-05-24T14:24:20Z | transformers | 1 | 0 | null | token-classification | null | [
".gitattributes",
"README.md",
"config.json",
"pytorch_model.bin",
"sample_input.pkl",
"special_tokens_map.json",
"tokenizer.json",
"tokenizer_config.json",
"vocab.txt"
] | acbdc6779e48dfde49f2ba77d6f2cfb431333d16 | [
"transformers",
"pytorch",
"distilbert",
"token-classification",
"en",
"dataset:ismail-lucifer011/autotrain-data-company_all",
"co2_eq_emissions",
"endpoints_compatible",
"deploy:azure",
"region:us"
] | null | {"architectures": ["DistilBertForTokenClassification"], "model_type": "distilbert", "tokenizer_config": {"unk_token": "[UNK]", "sep_token": "[SEP]", "pad_token": "[PAD]", "cls_token": "[CLS]", "mask_token": "[MASK]"}} | {
"auto_model": "AutoModelForTokenClassification",
"custom_class": null,
"pipeline_tag": "token-classification",
"processor": "AutoTokenizer"
} | {"base_model": null, "datasets": ["ismail-lucifer011/autotrain-data-company_all"], "eval_results": null, "language": "en", "library_name": null, "license": null, "license_name": null, "license_link": null, "metrics": null, "model_name": null, "pipeline_tag": null, "tags": null, "widget": [{"text": "I love AutoTrain \ud... | # Model Trained Using AutoTrain
- Problem type: Entity Extraction
- Model ID: 903429548
- CO2 Emissions (in grams): 0.848790823793881
## Validation Metrics
- Loss: 0.006148040760308504
- Accuracy: 0.9979930566588805
- Precision: 0.9814944904963571
- Recall: 0.9817210885036588
- F1: 0.9816077764228254
## Usage
You ... | null | null | [
"ismail-lucifer011/autotrain-data-company_all"
] | [
"en"
] | null | null | null | [
"AutoModelForTokenClassification",
"distilbert",
"DistilBertForTokenClassification"
] | [
"token-classification"
] | [
"text"
] | [
"text"
] | [
"logits"
] |
687c528f824adc8c48cfe5a2 | 848b60b6cd304b65 | ffc911e785abe60e | 151,665 | BPE | 151,387 | true | true | true | true | 22 | NFC | Sequence | ByteLevel | [
"NFC"
] | [
"Split",
"ByteLevel"
] | [
"ByteLevel"
] | 15 | trl-internal-testing/tiny-Qwen2_5_VLForConditionalGeneration | trl-internal-testing | null | 435,788 | 1,899,875 | False | 2025-07-20T02:21:03Z | 2026-01-16T11:47:47Z | transformers | 0 | 0 | null | image-text-to-text | {"parameters": {"BF16": 3857728}, "total": 3857728} | [
".gitattributes",
"README.md",
"added_tokens.json",
"chat_template.jinja",
"config.json",
"generation_config.json",
"merges.txt",
"model.safetensors",
"preprocessor_config.json",
"special_tokens_map.json",
"tokenizer.json",
"tokenizer_config.json",
"video_preprocessor_config.json",
"vocab.... | 17459614a625453345ab9dc64238c78cd93ff965 | [
"transformers",
"safetensors",
"qwen2_5_vl",
"image-text-to-text",
"trl",
"conversational",
"text-generation-inference",
"endpoints_compatible",
"region:us"
] | null | {"architectures": ["Qwen2_5_VLForConditionalGeneration"], "model_type": "qwen2_5_vl", "tokenizer_config": {"bos_token": null, "eos_token": "<|im_end|>", "pad_token": "<|endoftext|>", "unk_token": null}, "chat_template_jinja": "{% set image_count = namespace(value=0) %}{% set video_count = namespace(value=0) %}{% for me... | {
"auto_model": "AutoModelForImageTextToText",
"custom_class": null,
"pipeline_tag": "image-text-to-text",
"processor": "AutoProcessor"
} | {"base_model": null, "datasets": null, "eval_results": null, "language": null, "library_name": "transformers", "license": null, "license_name": null, "license_link": null, "metrics": null, "model_name": null, "pipeline_tag": null, "tags": ["trl"]} | # Tiny Qwen2_5_VLForConditionalGeneration
This is a minimal model built for unit tests in the [TRL](https://github.com/huggingface/trl) library. | null | null | null | null | 3,857,728 | null | null | [
"qwen2_5_vl",
"AutoModelForImageTextToText",
"Qwen2_5_VLForConditionalGeneration"
] | [
"image-text-to-text"
] | [
"multimodal"
] | [
"text",
"image"
] | [
"text"
] |
66303852b8d7220d89548ffc | 7a304013cffa7fce | b846cd4ab652f197 | 128,256 | BPE | 280,147 | false | true | true | true | 256 | null | Sequence | ByteLevel | null | [
"Split",
"ByteLevel"
] | [
"ByteLevel"
] | 450 | NousResearch/Hermes-2-Pro-Llama-3-8B | NousResearch | {
"models": [
{
"_id": "66214ebed55e5f677e0d8f3a",
"id": "NousResearch/Meta-Llama-3-8B"
}
],
"relation": "finetune"
} | 19,482 | 690,012 | False | 2024-04-30T00:16:18Z | 2024-09-14T16:29:41Z | transformers | 443 | 1 | [{"name": "Hermes-2-Pro-Llama-3-8B", "results": []}] | text-generation | {"parameters": {"F16": 8030523392}, "total": 8030523392} | [
".gitattributes",
"README.md",
"config.json",
"dpo-adapter/adapter_config.json",
"dpo-adapter/adapter_model.safetensors",
"generation_config.json",
"model-00001-of-00004.safetensors",
"model-00002-of-00004.safetensors",
"model-00003-of-00004.safetensors",
"model-00004-of-00004.safetensors",
"mod... | f798274b30e7d2d4797c369edcc0cc7473b6e6f2 | [
"transformers",
"safetensors",
"llama",
"text-generation",
"Llama-3",
"instruct",
"finetune",
"chatml",
"DPO",
"RLHF",
"gpt4",
"synthetic data",
"distillation",
"function calling",
"json mode",
"axolotl",
"conversational",
"en",
"dataset:teknium/OpenHermes-2.5",
"base_model:Nou... | null | {"architectures": ["LlamaForCausalLM"], "model_type": "llama", "tokenizer_config": {"bos_token": "<|begin_of_text|>", "chat_template": [{"name": "default", "template": "{{bos_token}}{% for message in messages %}{{'<|im_start|>' + message['role'] + '\n' + message['content'] + '<|im_end|>' + '\n'}}{% endfor %}{% if add_g... | {
"auto_model": "AutoModelForCausalLM",
"custom_class": null,
"pipeline_tag": "text-generation",
"processor": "AutoTokenizer"
} | {"base_model": "NousResearch/Meta-Llama-3-8B", "datasets": ["teknium/OpenHermes-2.5"], "eval_results": [], "language": ["en"], "library_name": null, "license": "llama3", "license_name": null, "license_link": null, "metrics": null, "model_name": "Hermes-2-Pro-Llama-3-8B", "pipeline_tag": null, "tags": ["Llama-3", "instr... | # Hermes 2 Pro - Llama-3 8B

## Model Description
Hermes 2 Pro is an upgraded, retrained version of Nous Hermes 2, consisting of an updated and cleaned version of the OpenHermes 2.5 Dataset, as well ... | null | [
"llama3"
] | [
"teknium/OpenHermes-2.5"
] | [
"en"
] | 8,030,523,392 | null | null | [
"AutoModelForCausalLM",
"llama",
"LlamaForCausalLM"
] | [
"text-generation"
] | [
"text"
] | [
"text"
] | [
"text"
] |
644558ebd1460e859d1d34dc | d12c4550c74b522a | 749336c707479b60 | 49,153 | BPE | 48,891 | false | true | false | true | 20 | null | Sequence | ByteLevel | null | [
"Digits",
"ByteLevel"
] | [
"ByteLevel"
] | 451 | bigcode/starpii | bigcode | null | 5,353 | 621,874 | auto | 2023-04-23T16:12:27Z | 2023-07-24T09:43:04Z | transformers | 123 | 0 | null | token-classification | null | [
".gitattributes",
"README.md",
"added_tokens.json",
"config.json",
"merges.txt",
"pytorch_model.bin",
"rng_state.pth",
"scheduler.pt",
"special_tokens_map.json",
"tokenizer.json",
"tokenizer_config.json",
"trainer_state.json",
"training_args.bin",
"vocab.json"
] | 1335e7a1fc3c49be13308687267bd9994435a688 | [
"transformers",
"pytorch",
"bert",
"token-classification",
"code",
"dataset:bigcode/pii-annotated-toloka-donwsample-emails",
"dataset:bigcode/pseudo-labeled-python-data-pii-detection-filtered",
"arxiv:2301.03988",
"endpoints_compatible",
"region:us"
] | null | {"architectures": ["BertForTokenClassification"], "model_type": "bert", "tokenizer_config": {"bos_token": "<|endoftext|>", "eos_token": "<|endoftext|>", "unk_token": "<|endoftext|>"}} | {
"auto_model": "AutoModelForTokenClassification",
"custom_class": null,
"pipeline_tag": "token-classification",
"processor": "AutoTokenizer"
} | {"base_model": null, "datasets": ["bigcode/pii-annotated-toloka-donwsample-emails", "bigcode/pseudo-labeled-python-data-pii-detection-filtered"], "eval_results": null, "language": ["code"], "library_name": null, "license": null, "license_name": null, "license_link": null, "metrics": ["f1"], "model_name": null, "pipelin... | null | null | null | [
"bigcode/pii-annotated-toloka-donwsample-emails",
"bigcode/pseudo-labeled-python-data-pii-detection-filtered"
] | [
"code"
] | null | null | [
"f1"
] | [
"AutoModelForTokenClassification",
"BertForTokenClassification",
"bert"
] | [
"token-classification"
] | [
"text"
] | [
"text"
] | [
"logits"
] |
621ffdc136468d709f17dafb | 324d1780c7dcba21 | 9befc50479ed313c | 31,090 | WordPiece | null | true | true | true | true | 5 | BertNormalizer | BertPreTokenizer | WordPiece | [
"BertNormalizer"
] | [
"BertPreTokenizer"
] | [
"WordPiece"
] | 126 | m3rg-iitd/matscibert | m3rg-iitd | null | 11,069 | 646,733 | False | 2022-03-02T23:29:05Z | 2024-06-22T12:00:54Z | transformers | 27 | 0 | null | fill-mask | {"parameters": {"I64": 512, "F32": 109951090}, "total": 109951602} | [
".gitattributes",
"README.md",
"config.json",
"model.safetensors",
"pytorch_model.bin",
"special_tokens_map.json",
"tokenizer.json",
"tokenizer_config.json",
"vocab.txt"
] | ced9d8f5f208712c4a90f98a246fe32155b29995 | [
"transformers",
"pytorch",
"safetensors",
"bert",
"fill-mask",
"en",
"license:mit",
"endpoints_compatible",
"deploy:azure",
"region:us"
] | null | {"architectures": ["BertForMaskedLM"], "model_type": "bert", "tokenizer_config": {"unk_token": "[UNK]", "sep_token": "[SEP]", "pad_token": "[PAD]", "cls_token": "[CLS]", "mask_token": "[MASK]"}} | {
"auto_model": "AutoModelForMaskedLM",
"custom_class": null,
"pipeline_tag": "fill-mask",
"processor": "AutoTokenizer"
} | {"base_model": null, "datasets": null, "eval_results": null, "language": ["en"], "library_name": "transformers", "license": "mit", "license_name": null, "license_link": null, "metrics": ["accuracy", "f1", "precision", "recall"], "model_name": null, "pipeline_tag": null, "tags": null} | # MatSciBERT
## A Materials Domain Language Model for Text Mining and Information Extraction
This is the pretrained model presented in [MatSciBERT: A materials domain language model for text mining and information extraction](https://rdcu.be/cMAp5), which is a BERT model trained on material science research papers.
T... | null | [
"mit"
] | null | [
"en"
] | 109,951,602 | null | [
"accuracy",
"f1",
"precision",
"recall"
] | [
"AutoModelForMaskedLM",
"bert",
"BertForMaskedLM"
] | [
"fill-mask"
] | [
"text"
] | [
"text"
] | [
"logits"
] |
68781021a5dbb701d7f44ce2 | 87ec02145bad27f5 | dd84a2b1ff97657d | 250,002 | Unigram | null | true | true | true | true | 5 | Sequence | Metaspace | Metaspace | [
"Precompiled",
"Replace"
] | [
"Metaspace"
] | [
"Metaspace"
] | 412 | OpenMed/OpenMed-NER-GenomicDetect-SnowMed-568M | OpenMed | null | 119,905 | 1,325,580 | False | 2025-07-16T20:48:33Z | 2025-08-05T09:41:35Z | transformers | 2 | 0 | null | token-classification | {"parameters": {"BF16": 566708227}, "total": 566708227} | [
".gitattributes",
"README.md",
"config.json",
"model.safetensors",
"openmed_vs_sota_grouped_bars.png",
"sentencepiece.bpe.model",
"special_tokens_map.json",
"test_results.json",
"tokenizer.json",
"tokenizer_config.json"
] | 84c9bec3d8f65f143a21f6c32b4533dc7fb694b1 | [
"transformers",
"safetensors",
"xlm-roberta",
"token-classification",
"named-entity-recognition",
"biomedical-nlp",
"gene-recognition",
"genetics",
"genomics",
"molecular-biology",
"cell-line-name",
"en",
"arxiv:2508.01630",
"license:apache-2.0",
"endpoints_compatible",
"region:us"
] | null | {"architectures": ["XLMRobertaForTokenClassification"], "model_type": "xlm-roberta", "tokenizer_config": {"bos_token": "<s>", "cls_token": "<s>", "eos_token": "</s>", "mask_token": "<mask>", "pad_token": "<pad>", "sep_token": "</s>", "unk_token": "<unk>"}} | {
"auto_model": "AutoModelForTokenClassification",
"custom_class": null,
"pipeline_tag": "token-classification",
"processor": "AutoTokenizer"
} | {"base_model": null, "datasets": null, "eval_results": null, "language": ["en"], "library_name": null, "license": "apache-2.0", "license_name": null, "license_link": null, "metrics": null, "model_name": null, "pipeline_tag": null, "tags": ["token-classification", "named-entity-recognition", "biomedical-nlp", "transform... | null | null | [
"apache-2.0"
] | null | [
"en"
] | 566,708,227 | null | null | [
"XLMRobertaForTokenClassification",
"AutoModelForTokenClassification",
"xlm-roberta"
] | [
"token-classification"
] | [
"text"
] | [
"text"
] | [
"logits"
] |
66a1b262858a536116fb0f0f | c6de6331832e687a | 6622292dca275a2d | 128,256 | BPE | 280,147 | false | true | true | true | 256 | null | Sequence | ByteLevel | null | [
"Split",
"ByteLevel"
] | [
"ByteLevel"
] | 142 | VAGOsolutions/Llama-3.1-SauerkrautLM-8b-Instruct | VAGOsolutions | null | 2,032 | 620,495 | False | 2024-07-25T02:03:14Z | 2024-08-14T15:55:22Z | transformers | 33 | 0 | null | text-generation | {"parameters": {"BF16": 8030261248}, "total": 8030261248} | [
".gitattributes",
"README.md",
"config.json",
"model-00001-of-00005.safetensors",
"model-00002-of-00005.safetensors",
"model-00003-of-00005.safetensors",
"model-00004-of-00005.safetensors",
"model-00005-of-00005.safetensors",
"model.safetensors.index.json",
"special_tokens_map.json",
"tokenizer.... | 221e5f92f9dc5fedaf4556b1be6b20642638643c | [
"transformers",
"safetensors",
"llama",
"text-generation",
"spectrum",
"conversational",
"de",
"en",
"it",
"fr",
"pt",
"es",
"license:llama3.1",
"text-generation-inference",
"endpoints_compatible",
"deploy:azure",
"region:us"
] | null | {"architectures": ["LlamaForCausalLM"], "model_type": "llama", "tokenizer_config": {"bos_token": "<|begin_of_text|>", "chat_template": "{% set loop_messages = messages %}{% for message in loop_messages %}{% set content = '<|start_header_id|>' + message['role'] + '<|end_header_id|>\n\n'+ message['content'] | trim + '<|e... | {
"auto_model": "AutoModelForCausalLM",
"custom_class": null,
"pipeline_tag": "text-generation",
"processor": "AutoTokenizer"
} | {"base_model": null, "datasets": null, "eval_results": null, "language": ["de", "en", "it", "fr", "pt", "es"], "library_name": null, "license": "llama3.1", "license_name": null, "license_link": null, "metrics": null, "model_name": null, "pipeline_tag": null, "tags": ["spectrum"]} | 
## VAGO solutions Llama-3.1-SauerkrautLM-8b-Instruct
**Fine-tuned Model** - *to showcase the potential of resource-efficient Fine-Tuning of Large Language Models u... | null | [
"llama3.1"
] | null | [
"de",
"en",
"it",
"fr",
"pt",
"es"
] | 8,030,261,248 | null | null | [
"AutoModelForCausalLM",
"llama",
"LlamaForCausalLM"
] | [
"text-generation"
] | [
"text"
] | [
"text"
] | [
"text"
] |
65b92fd5dd9400778994c61b | 34093184d10f76a9 | 35b001f3a491f9f9 | 151,646 | BPE | 151,387 | true | true | true | true | 3 | NFC | Sequence | ByteLevel | [
"NFC"
] | [
"Split",
"ByteLevel"
] | [
"ByteLevel"
] | 53 | Qwen/Qwen1.5-1.8B-Chat | Qwen | null | 73,543 | 956,685 | False | 2024-01-30T17:20:21Z | 2024-04-30T07:20:48Z | transformers | 73 | 0 | null | text-generation | {"parameters": {"BF16": 1836828672}, "total": 1836828672} | [
".gitattributes",
"LICENSE",
"README.md",
"config.json",
"generation_config.json",
"merges.txt",
"model.safetensors",
"tokenizer.json",
"tokenizer_config.json",
"vocab.json"
] | e482ee3f73c375a627a16fdf66fd0c8279743ca6 | [
"transformers",
"safetensors",
"qwen2",
"text-generation",
"chat",
"conversational",
"en",
"arxiv:2309.16609",
"license:other",
"text-generation-inference",
"endpoints_compatible",
"deploy:azure",
"region:us"
] | null | {"architectures": ["Qwen2ForCausalLM"], "model_type": "qwen2", "tokenizer_config": {"bos_token": null, "chat_template": "{% for message in messages %}{% if loop.first and messages[0]['role'] != 'system' %}{{ '<|im_start|>system\nYou are a helpful assistant.<|im_end|>\n' }}{% endif %}{{'<|im_start|>' + message['role'] +... | {
"auto_model": "AutoModelForCausalLM",
"custom_class": null,
"pipeline_tag": "text-generation",
"processor": "AutoTokenizer"
} | {"base_model": null, "datasets": null, "eval_results": null, "language": ["en"], "library_name": null, "license": "other", "license_name": "tongyi-qianwen-research", "license_link": "https://huggingface.co/Qwen/Qwen1.5-1.8B-Chat/blob/main/LICENSE", "metrics": null, "model_name": null, "pipeline_tag": "text-generation",... | # Qwen1.5-1.8B-Chat
## Introduction
Qwen1.5 is the beta version of Qwen2, a transformer-based decoder-only language model pretrained on a large amount of data. In comparison with the previous released Qwen, the improvements include:
* 8 model sizes, including 0.5B, 1.8B, 4B, 7B, 14B, 32B and 72B dense models, and ... | null | [
"other",
"tongyi-qianwen-research",
"https://huggingface.co/Qwen/Qwen1.5-1.8B-Chat/blob/main/LICENSE"
] | null | [
"en"
] | 1,836,828,672 | null | null | [
"AutoModelForCausalLM",
"Qwen2ForCausalLM",
"qwen2"
] | [
"text-generation"
] | [
"text"
] | [
"text"
] | [
"text"
] |
650f32c1bfb7dd98bbca4347 | 53ecf467267e2824 | 535fa14da0af647c | 30,522 | WordPiece | null | true | true | true | true | 5 | BertNormalizer | BertPreTokenizer | WordPiece | [
"BertNormalizer"
] | [
"BertPreTokenizer"
] | [
"WordPiece"
] | 0 | ayoubkirouane/BERT-Emotions-Classifier | ayoubkirouane | null | 616 | 615,184 | False | 2023-09-23T18:47:29Z | 2023-09-23T21:35:59Z | transformers | 17 | 0 | null | text-classification | null | [
".gitattributes",
"README.md",
"config.json",
"pytorch_model.bin",
"special_tokens_map.json",
"tokenizer.json",
"tokenizer_config.json",
"vocab.txt"
] | 244e0aa1b839d3c1b4d1f962f5baea341f3fd08f | [
"transformers",
"pytorch",
"bert",
"text-classification",
"en",
"dataset:sem_eval_2018_task_1",
"text-embeddings-inference",
"endpoints_compatible",
"deploy:azure",
"region:us"
] | null | {"architectures": ["BertForSequenceClassification"], "model_type": "bert", "tokenizer_config": {"cls_token": "[CLS]", "mask_token": "[MASK]", "pad_token": "[PAD]", "sep_token": "[SEP]", "unk_token": "[UNK]"}} | {
"auto_model": "AutoModelForSequenceClassification",
"custom_class": null,
"pipeline_tag": "text-classification",
"processor": "AutoTokenizer"
} | {"base_model": null, "datasets": ["sem_eval_2018_task_1"], "eval_results": null, "language": ["en"], "library_name": "transformers", "license": null, "license_name": null, "license_link": null, "metrics": null, "model_name": null, "pipeline_tag": "text-classification", "tags": null} | ## Description
The **BERT-Emotions-Classifier** is a fine-tuned **BERT-based** model designed for multi-label emotion classification. It has been trained on the sem_eval_2018_task_1 dataset, which includes text samples labeled with a variety of emotions, including anger, anticipation, disgust, fear, joy, love, optimism... | null | null | [
"sem_eval_2018_task_1"
] | [
"en"
] | null | null | null | [
"BertForSequenceClassification",
"bert",
"AutoModelForSequenceClassification"
] | [
"text-classification"
] | [
"text"
] | [
"text"
] | [
"logits"
] |
6487204b252cd3fb59ca6485 | f1a266f7df004689 | e11867e1c066bb5b | 250,071 | Unigram | null | true | true | true | true | 74 | Sequence | Metaspace | Metaspace | [
"Precompiled",
"Replace"
] | [
"Metaspace"
] | [
"Metaspace"
] | 452 | Babelscape/mrebel-large | Babelscape | null | 779 | 615,476 | False | 2023-06-12T13:40:27Z | 2023-06-20T15:40:58Z | transformers | 78 | 1 | null | translation | {"parameters": {"F32": 611146967}, "total": 611146967} | [
".gitattributes",
"README.md",
"added_tokens.json",
"config.json",
"model.safetensors",
"pytorch_model.bin",
"sentencepiece.bpe.model",
"special_tokens_map.json",
"tokenizer.json",
"tokenizer_config.json"
] | 50e0587ac7ac87d28b9abd069d72333528a5aa09 | [
"transformers",
"pytorch",
"safetensors",
"mbart",
"text2text-generation",
"seq2seq",
"relation-extraction",
"translation",
"ar",
"ca",
"de",
"el",
"en",
"es",
"fr",
"hi",
"it",
"ja",
"ko",
"nl",
"pl",
"pt",
"ru",
"sv",
"vi",
"zh",
"dataset:Babelscape/SREDFM",
"... | null | {"architectures": ["MBartForConditionalGeneration"], "model_type": "mbart", "tokenizer_config": {"eos_token": "</s>", "sep_token": "</s>", "cls_token": "<s>", "unk_token": "<unk>", "pad_token": "<pad>", "mask_token": {"content": "<mask>", "single_word": false, "lstrip": true, "rstrip": false, "normalized": true, "__typ... | {
"auto_model": "AutoModelForSeq2SeqLM",
"custom_class": null,
"pipeline_tag": "text2text-generation",
"processor": "AutoTokenizer"
} | {"base_model": null, "datasets": ["Babelscape/SREDFM"], "eval_results": null, "language": ["ar", "ca", "de", "el", "en", "es", "fr", "hi", "it", "ja", "ko", "nl", "pl", "pt", "ru", "sv", "vi", "zh"], "library_name": null, "license": "cc-by-nc-sa-4.0", "license_name": null, "license_link": null, "metrics": null, "model_... | # RED<sup>FM</sup>: a Filtered and Multilingual Relation Extraction Dataset
This is a multilingual version of [REBEL](https://huggingface.co/Babelscape/rebel-large). It can be used as a standalone multulingual Relation Extraction system, or as a pretrained system to be tuned on multilingual Relation Extraction dataset... | null | [
"cc-by-nc-sa-4.0"
] | [
"Babelscape/SREDFM"
] | [
"ar",
"ca",
"de",
"el",
"en",
"es",
"fr",
"hi",
"it",
"ja",
"ko",
"nl",
"pl",
"pt",
"ru",
"sv",
"vi",
"zh"
] | 611,146,967 | null | null | [
"AutoModelForSeq2SeqLM",
"MBartForConditionalGeneration",
"mbart"
] | [
"text2text-generation",
"translation"
] | [
"text"
] | [
"text"
] | [
"text"
] |
6515889ab26534355cf05976 | 5ef9eb7677e33416 | 70bd27c212bc339c | 50,265 | BPE | 50,000 | false | true | true | true | 5 | null | ByteLevel | ByteLevel | null | [
"ByteLevel"
] | [
"ByteLevel"
] | 19 | SamLowe/roberta-base-go_emotions-onnx | SamLowe | null | 100,228 | 1,128,076 | False | 2023-09-28T14:07:22Z | 2023-09-29T00:02:20Z | transformers | 26 | 0 | null | text-classification | null | [
".gitattributes",
"README.md",
"config.json",
"merges.txt",
"onnx/config.json",
"onnx/merges.txt",
"onnx/model.onnx",
"onnx/model_quantized.onnx",
"onnx/ort_config.json",
"onnx/ort_config_quantized.json",
"onnx/special_tokens_map.json",
"onnx/tokenizer.json",
"onnx/tokenizer_config.json",
... | 90ee0c1c4796d370e68968687b8ba51fc11224f4 | [
"transformers",
"onnx",
"roberta",
"text-classification",
"int8",
"emotions",
"multi-class-classification",
"multi-label-classification",
"optimum",
"en",
"dataset:go_emotions",
"license:mit",
"text-embeddings-inference",
"region:us"
] | null | {"architectures": ["RobertaForSequenceClassification"], "model_type": "roberta", "tokenizer_config": {"bos_token": "<s>", "cls_token": "<s>", "eos_token": "</s>", "mask_token": "<mask>", "pad_token": "<pad>", "sep_token": "</s>", "unk_token": "<unk>"}} | {
"auto_model": "AutoModelForSequenceClassification",
"custom_class": null,
"pipeline_tag": "text-classification",
"processor": "AutoTokenizer"
} | {"base_model": null, "datasets": ["go_emotions"], "eval_results": null, "language": "en", "library_name": null, "license": "mit", "license_name": null, "license_link": null, "metrics": null, "model_name": null, "pipeline_tag": null, "tags": ["text-classification", "onnx", "int8", "roberta", "emotions", "multi-class-cla... | This model is the ONNX version of [https://huggingface.co/SamLowe/roberta-base-go_emotions](https://huggingface.co/SamLowe/roberta-base-go_emotions).
### Full precision ONNX version
`onnx/model.onnx` is the full precision ONNX version
- that has identical accuracy/metrics to the original Transformers model
- and has... | null | [
"mit"
] | [
"go_emotions"
] | [
"en"
] | null | null | null | [
"roberta",
"AutoModelForSequenceClassification",
"RobertaForSequenceClassification"
] | [
"text-classification"
] | [
"text"
] | [
"text"
] | [
"logits"
] |
687815f71946893db4b13764 | 6a67cbd79bab1e59 | cf1efbe71ef28fc9 | 50,368 | BPE | 50,009 | true | true | true | true | 116 | NFC | ByteLevel | ByteLevel | [
"NFC"
] | [
"ByteLevel"
] | [
"ByteLevel"
] | 395 | OpenMed/OpenMed-NER-PharmaDetect-ModernClinical-149M | OpenMed | null | 154,599 | 1,664,747 | False | 2025-07-16T21:13:27Z | 2025-08-05T09:43:17Z | transformers | 6 | 0 | null | token-classification | null | [
".gitattributes",
"README.md",
"config.json",
"model.safetensors",
"openmed_vs_sota_grouped_bars.png",
"special_tokens_map.json",
"test_results.json",
"tokenizer.json",
"tokenizer_config.json"
] | e6324ece187c7079ee9a67ae43849f0f7e0206cf | [
"transformers",
"safetensors",
"modernbert",
"token-classification",
"named-entity-recognition",
"biomedical-nlp",
"chemical-entity-recognition",
"drug-discovery",
"pharmacology",
"biocuration",
"chem",
"en",
"arxiv:2508.01630",
"license:apache-2.0",
"endpoints_compatible",
"region:us"... | null | {"architectures": ["ModernBertForTokenClassification"], "model_type": "modernbert", "tokenizer_config": {"cls_token": "[CLS]", "mask_token": "[MASK]", "pad_token": "[PAD]", "sep_token": "[SEP]", "unk_token": "[UNK]"}} | {
"auto_model": "AutoModelForTokenClassification",
"custom_class": null,
"pipeline_tag": "token-classification",
"processor": "AutoTokenizer"
} | {"base_model": null, "datasets": null, "eval_results": null, "language": ["en"], "library_name": null, "license": "apache-2.0", "license_name": null, "license_link": null, "metrics": null, "model_name": null, "pipeline_tag": null, "tags": ["token-classification", "named-entity-recognition", "biomedical-nlp", "transform... | null | null | [
"apache-2.0"
] | null | [
"en"
] | null | null | null | [
"AutoModelForTokenClassification",
"ModernBertForTokenClassification",
"modernbert"
] | [
"token-classification"
] | [
"text"
] | [
"text"
] | [
"logits"
] |
624d417f4778284ac5d40d70 | 53ecf467267e2824 | 535fa14da0af647c | 30,522 | WordPiece | null | true | true | true | true | 5 | BertNormalizer | BertPreTokenizer | WordPiece | [
"BertNormalizer"
] | [
"BertPreTokenizer"
] | [
"WordPiece"
] | 0 | Intel/bert-base-uncased-mrpc | Intel | null | 5,927 | 628,527 | False | 2022-04-06T07:30:07Z | 2024-06-21T19:49:09Z | transformers | 2 | 0 | [{"name": "bert-base-uncased-mrpc", "results": [{"task": {"type": "text-classification", "name": "Text Classification"}, "dataset": {"name": "GLUE MRPC", "type": "glue", "args": "mrpc"}, "metrics": [{"type": "accuracy", "value": 0.8602941176470589, "name": "Accuracy", "verified": false}, {"type": "f1", "value": 0.90420... | text-classification | null | [
".gitattributes",
"README.md",
"config.json",
"pytorch_model.bin",
"special_tokens_map.json",
"tokenizer.json",
"tokenizer_config.json",
"vocab.txt"
] | 844e804944328e45c3f3bf69b35467e0ce0b26af | [
"transformers",
"pytorch",
"bert",
"text-classification",
"generated_from_trainer",
"bert-base-uncased",
"fp32",
"en",
"dataset:glue",
"arxiv:1810.04805",
"license:apache-2.0",
"model-index",
"text-embeddings-inference",
"endpoints_compatible",
"deploy:azure",
"region:us"
] | null | {"architectures": ["BertForSequenceClassification"], "model_type": "bert", "tokenizer_config": {"unk_token": "[UNK]", "sep_token": "[SEP]", "pad_token": "[PAD]", "cls_token": "[CLS]", "mask_token": "[MASK]"}} | {
"auto_model": "AutoModelForSequenceClassification",
"custom_class": null,
"pipeline_tag": "text-classification",
"processor": "AutoTokenizer"
} | {"datasets": ["glue"], "language": ["en"], "license": "apache-2.0", "metrics": ["accuracy", "f1"], "tags": ["generated_from_trainer", "bert-base-uncased", "text-classification", "fp32"], "model-index": [{"name": "bert-base-uncased-mrpc", "results": [{"task": {"type": "text-classification", "name": "Text Classification"... | <!-- This model card has been generated automatically according to the information the Trainer had access to. You
should probably proofread and complete it, then remove this comment. -->
# bert-base-uncased-mrpc
This model is a fine-tuned version of [bert-base-uncased](https://huggingface.co/bert-base-uncased) on the... | null | [
"apache-2.0"
] | [
"glue"
] | [
"en"
] | null | null | [
"accuracy",
"f1"
] | [
"BertForSequenceClassification",
"bert",
"AutoModelForSequenceClassification"
] | [
"text-classification"
] | [
"text"
] | [
"text"
] | [
"logits"
] |
6892f34373eb3fc200b601a8 | 7428ef9ae5ef868f | 67da9c236fa81925 | 151,669 | BPE | 151,387 | true | true | true | true | 26 | NFC | Sequence | ByteLevel | [
"NFC"
] | [
"Split",
"ByteLevel"
] | [
"ByteLevel"
] | 47 | Qwen/Qwen3-4B-Thinking-2507-FP8 | Qwen | {
"models": [
{
"_id": "6891e4c34b616cd1bb82f50e",
"id": "Qwen/Qwen3-4B-Thinking-2507"
}
],
"relation": "quantized"
} | 188,273 | 1,491,093 | False | 2025-08-06T06:16:35Z | 2025-08-06T11:07:01Z | transformers | 62 | 0 | null | text-generation | null | [
".gitattributes",
"LICENSE",
"README.md",
"config.json",
"generation_config.json",
"merges.txt",
"model.safetensors",
"tokenizer.json",
"tokenizer_config.json",
"vocab.json"
] | 953532f942706930ec4bb870569932ef63038fdf | [
"transformers",
"safetensors",
"qwen3",
"text-generation",
"conversational",
"arxiv:2505.09388",
"base_model:Qwen/Qwen3-4B-Thinking-2507",
"base_model:quantized:Qwen/Qwen3-4B-Thinking-2507",
"license:apache-2.0",
"text-generation-inference",
"endpoints_compatible",
"fp8",
"deploy:azure",
"... | null | {"architectures": ["Qwen3ForCausalLM"], "model_type": "qwen3", "quantization_config": {"quant_method": "fp8"}, "tokenizer_config": {"bos_token": null, "chat_template": "{%- if tools %}\n {{- '<|im_start|>system\\n' }}\n {%- if messages[0].role == 'system' %}\n {{- messages[0].content + '\\n\\n' }}\n {%-... | {
"auto_model": "AutoModelForCausalLM",
"custom_class": null,
"pipeline_tag": "text-generation",
"processor": "AutoTokenizer"
} | {"base_model": ["Qwen/Qwen3-4B-Thinking-2507"], "datasets": null, "eval_results": null, "language": null, "library_name": "transformers", "license": "apache-2.0", "license_name": null, "license_link": "https://huggingface.co/Qwen/Qwen3-4B-Thinking-2507-FP8/blob/main/LICENSE", "metrics": null, "model_name": null, "pipel... | # Qwen3-4B-Thinking-2507-FP8
<a href="https://chat.qwen.ai/" target="_blank" style="margin: 2px;">
<img alt="Chat" src="https://img.shields.io/badge/%F0%9F%92%9C%EF%B8%8F%20Qwen%20Chat%20-536af5" style="display: inline-block; vertical-align: middle;"/>
</a>
## Highlights
Over the past three months, we have contin... | null | [
"apache-2.0",
"https://huggingface.co/Qwen/Qwen3-4B-Thinking-2507-FP8/blob/main/LICENSE"
] | null | null | null | null | null | [
"AutoModelForCausalLM",
"Qwen3ForCausalLM",
"qwen3"
] | [
"text-generation"
] | [
"text"
] | [
"text"
] | [
"text"
] |
687816210a870ef03725b20c | 099fc7b2924a795c | 5f9f736c7dc6fbfa | 28,996 | WordPiece | null | true | true | true | true | 5 | BertNormalizer | BertPreTokenizer | WordPiece | [
"BertNormalizer"
] | [
"BertPreTokenizer"
] | [
"WordPiece"
] | 453 | OpenMed/OpenMed-NER-BloodCancerDetect-TinyMed-65M | OpenMed | null | 211,818 | 1,839,066 | False | 2025-07-16T21:14:09Z | 2025-08-05T09:43:21Z | transformers | 0 | 0 | null | token-classification | {"parameters": {"BF16": 65193219}, "total": 65193219} | [
".gitattributes",
"README.md",
"config.json",
"model.safetensors",
"openmed_vs_sota_grouped_bars.png",
"special_tokens_map.json",
"test_results.json",
"tokenizer.json",
"tokenizer_config.json",
"vocab.txt"
] | 62684ec5a6a211b91b7d5e33e7e6af95917b93ad | [
"transformers",
"safetensors",
"distilbert",
"token-classification",
"named-entity-recognition",
"biomedical-nlp",
"leukemia",
"hematology",
"cancer",
"clinical-medicine",
"cl",
"en",
"arxiv:2508.01630",
"license:apache-2.0",
"endpoints_compatible",
"region:us"
] | null | {"architectures": ["DistilBertForTokenClassification"], "model_type": "distilbert", "tokenizer_config": {"cls_token": "[CLS]", "mask_token": "[MASK]", "pad_token": "[PAD]", "sep_token": "[SEP]", "unk_token": "[UNK]"}} | {
"auto_model": "AutoModelForTokenClassification",
"custom_class": null,
"pipeline_tag": "token-classification",
"processor": "AutoTokenizer"
} | {"base_model": null, "datasets": null, "eval_results": null, "language": ["en"], "library_name": null, "license": "apache-2.0", "license_name": null, "license_link": null, "metrics": null, "model_name": null, "pipeline_tag": null, "tags": ["token-classification", "named-entity-recognition", "biomedical-nlp", "transform... | null | null | [
"apache-2.0"
] | null | [
"en"
] | 65,193,219 | null | null | [
"AutoModelForTokenClassification",
"distilbert",
"DistilBertForTokenClassification"
] | [
"token-classification"
] | [
"text"
] | [
"text"
] | [
"logits"
] |
662fd4dfd2f21fa96cf9a6f6 | 21a9a365f9765414 | ddde944c7b357600 | 32,011 | BPE | 61,249 | true | false | true | true | 14 | Sequence | null | Sequence | [
"Prepend",
"Replace"
] | null | [
"Replace",
"ByteFallback",
"Fuse",
"Strip"
] | 454 | unsloth/Phi-3-mini-4k-instruct-bnb-4bit | unsloth | null | 40,063 | 776,798 | False | 2024-04-29T17:11:59Z | 2024-09-03T03:45:57Z | transformers | 43 | 0 | null | text-generation | {"parameters": {"F32": 282112, "BF16": 197200896, "U8": 3737201854}, "total": 3934684862} | [
".gitattributes",
"README.md",
"added_tokens.json",
"config.json",
"generation_config.json",
"model.safetensors",
"special_tokens_map.json",
"tokenizer.json",
"tokenizer.model",
"tokenizer_config.json"
] | 81453e5718775630581ab9950e6c0ccf0d7a4177 | [
"transformers",
"safetensors",
"mistral",
"text-generation",
"unsloth",
"phi3",
"phi",
"conversational",
"en",
"license:mit",
"text-generation-inference",
"endpoints_compatible",
"4-bit",
"bitsandbytes",
"region:us"
] | null | {"architectures": ["MistralForCausalLM"], "model_type": "mistral", "quantization_config": {"load_in_4bit": true, "load_in_8bit": false, "quant_method": "bitsandbytes"}, "tokenizer_config": {"bos_token": "<s>", "chat_template": "{% for message in messages %}{% if message['role'] == 'system' %}{{'<|system|>\n' + message[... | {
"auto_model": "AutoModelForCausalLM",
"custom_class": null,
"pipeline_tag": "text-generation",
"processor": "AutoTokenizer"
} | {"base_model": null, "datasets": null, "eval_results": null, "language": ["en"], "library_name": "transformers", "license": "mit", "license_name": null, "license_link": null, "metrics": null, "model_name": null, "pipeline_tag": null, "tags": ["unsloth", "transformers", "phi3", "phi"]} | ## Reminder to use the dev version Transformers:
`pip install git+https://github.com/huggingface/transformers.git`
# Finetune Phi-3.5, Llama 3.1, Mistral 2-5x faster with 70% less memory via Unsloth!
We have a free Google Colab Tesla T4 notebook for Phi-3.5 (mini) here: https://colab.research.google.com/drive/1lN6hPQ... | null | [
"mit"
] | null | [
"en"
] | 3,934,684,862 | null | null | [
"AutoModelForCausalLM",
"mistral",
"MistralForCausalLM"
] | [
"text-generation"
] | [
"text"
] | [
"text"
] | [
"text"
] |
652f0dc05d91b1c2957de551 | f37da7b70f435580 | 84311f7a223ea6ec | 262,144 | Unigram | null | true | false | true | true | 2 | Sequence | null | Sequence | [
"Prepend",
"Replace"
] | null | [
"Replace",
"ByteFallback",
"Fuse",
"Strip"
] | 455 | adept/fuyu-8b | adept | null | 74,747 | 861,510 | False | 2023-10-17T22:42:08Z | 2023-11-04T11:13:11Z | transformers | 1,018 | 0 | null | image-text-to-text | {"parameters": {"BF16": 9408238592}, "total": 9408238592} | [
".gitattributes",
"README.md",
"added_tokens.json",
"architecture.png",
"bus.png",
"chart.png",
"config.json",
"generation_config.json",
"model-00001-of-00002.safetensors",
"model-00002-of-00002.safetensors",
"model.safetensors.index.json",
"preprocessor_config.json",
"skateboard.png",
"sp... | f41defefdb89be0d28cac19d94ce216e37cb6be5 | [
"transformers",
"safetensors",
"fuyu",
"image-text-to-text",
"license:cc-by-nc-4.0",
"endpoints_compatible",
"region:us"
] | null | {"architectures": ["FuyuForCausalLM"], "model_type": "fuyu", "tokenizer_config": {"bos_token": "|ENDOFTEXT|", "eos_token": "|ENDOFTEXT|", "pad_token": null, "unk_token": "<unk>", "use_default_system_prompt": true}} | {
"auto_model": "AutoModelForImageTextToText",
"custom_class": null,
"pipeline_tag": "image-text-to-text",
"processor": "AutoProcessor"
} | {"base_model": null, "datasets": null, "eval_results": null, "language": null, "library_name": null, "license": "cc-by-nc-4.0", "license_name": null, "license_link": null, "metrics": null, "model_name": null, "pipeline_tag": null, "tags": null} | # Fuyu-8B Model Card
We’re releasing Fuyu-8B, a small version of the multimodal model that powers our product. The model is available on HuggingFace. We think Fuyu-8B is exciting because:
1. It has a much simpler architecture and training procedure than other multi-modal models, which makes it easier to understand, sc... | null | [
"cc-by-nc-4.0"
] | null | null | 9,408,238,592 | null | null | [
"AutoModelForImageTextToText",
"FuyuForCausalLM",
"fuyu"
] | [
"image-text-to-text"
] | [
"multimodal"
] | [
"text",
"image"
] | [
"text"
] |
6541e63a5019954eefa3162c | 16e7c4472bd9e4b6 | 2244742552034edc | 32,022 | BPE | 31,757 | true | true | true | true | 22 | Sequence | Sequence | ByteLevel | [] | [
"Split",
"Split",
"Split",
"Split",
"Digits",
"ByteLevel"
] | [
"ByteLevel"
] | 241 | deepseek-ai/deepseek-coder-33b-instruct | deepseek-ai | null | 11,356 | 723,282 | False | 2023-11-01T05:46:34Z | 2024-03-07T08:25:20Z | transformers | 566 | 0 | null | text-generation | {"parameters": {"BF16": 33342991360}, "total": 33342991360} | [
".gitattributes",
"LICENSE",
"README.md",
"config.json",
"generation_config.json",
"model-00001-of-00007.safetensors",
"model-00002-of-00007.safetensors",
"model-00003-of-00007.safetensors",
"model-00004-of-00007.safetensors",
"model-00005-of-00007.safetensors",
"model-00006-of-00007.safetensors... | 61dc97b922b13995e7f83b7c8397701dbf9cfd4c | [
"transformers",
"pytorch",
"safetensors",
"llama",
"text-generation",
"conversational",
"license:other",
"text-generation-inference",
"endpoints_compatible",
"deploy:azure",
"region:us"
] | null | {"architectures": ["LlamaForCausalLM"], "model_type": "llama", "tokenizer_config": {"bos_token": {"__type": "AddedToken", "content": "<\uff5cbegin\u2581of\u2581sentence\uff5c>", "lstrip": false, "normalized": true, "rstrip": false, "single_word": false}, "eos_token": {"__type": "AddedToken", "content": "<|EOT|>", "lstr... | {
"auto_model": "AutoModelForCausalLM",
"custom_class": null,
"pipeline_tag": "text-generation",
"processor": "AutoTokenizer"
} | {"base_model": null, "datasets": null, "eval_results": null, "language": null, "library_name": null, "license": "other", "license_name": "deepseek", "license_link": "LICENSE", "metrics": null, "model_name": null, "pipeline_tag": null, "tags": null} | <p align="center">
<img width="1000px" alt="DeepSeek Coder" src="https://github.com/deepseek-ai/DeepSeek-Coder/blob/main/pictures/logo.png?raw=true">
</p>
<p align="center"><a href="https://www.deepseek.com/">[🏠Homepage]</a> | <a href="https://coder.deepseek.com/">[🤖 Chat with DeepSeek Coder]</a> | <a href="https... | null | [
"other",
"deepseek",
"LICENSE"
] | null | null | 33,342,991,360 | null | null | [
"AutoModelForCausalLM",
"llama",
"LlamaForCausalLM"
] | [
"text-generation"
] | [
"text"
] | [
"text"
] | [
"text"
] |
67a9a7cbb4dd31ae43e788d6 | 848b60b6cd304b65 | ffc911e785abe60e | 151,665 | BPE | 151,387 | true | true | true | true | 22 | NFC | Sequence | ByteLevel | [
"NFC"
] | [
"Split",
"ByteLevel"
] | [
"ByteLevel"
] | 15 | AIDC-AI/Ovis2-1B | AIDC-AI | null | 44,136 | 712,511 | False | 2025-02-10T07:16:27Z | 2025-08-15T15:21:45Z | transformers | 96 | 0 | null | image-text-to-text | {"parameters": {"BF16": 1267417974}, "total": 1267417974} | [
".gitattributes",
"NOTICE",
"README.md",
"added_tokens.json",
"config.json",
"configuration_aimv2.py",
"configuration_ovis.py",
"generation_config.json",
"merges.txt",
"model.safetensors",
"modeling_aimv2.py",
"modeling_ovis.py",
"preprocessor_config.json",
"special_tokens_map.json",
"to... | 642d0807bf09b89ed52ea97230ceab26c9a6ed2d | [
"transformers",
"safetensors",
"ovis",
"text-generation",
"MLLM",
"image-text-to-text",
"conversational",
"custom_code",
"en",
"zh",
"dataset:AIDC-AI/Ovis-dataset",
"arxiv:2405.20797",
"license:apache-2.0",
"region:us"
] | null | {"architectures": ["Ovis"], "auto_map": {"AutoConfig": "configuration_ovis.OvisConfig", "AutoModelForCausalLM": "modeling_ovis.Ovis"}, "model_type": "ovis", "tokenizer_config": {"bos_token": null, "chat_template": "{%- if tools %}\n {{- '<|im_start|>system\\n' }}\n {%- if messages[0]['role'] == 'system' %}\n ... | {
"auto_model": "AutoModelForCausalLM",
"custom_class": "modeling_ovis.Ovis",
"pipeline_tag": "text-generation",
"processor": null
} | {"base_model": null, "datasets": ["AIDC-AI/Ovis-dataset"], "eval_results": null, "language": ["en", "zh"], "library_name": "transformers", "license": "apache-2.0", "license_name": null, "license_link": null, "metrics": null, "model_name": null, "pipeline_tag": "image-text-to-text", "tags": ["MLLM"]} | # Ovis2-1B
<div align="center">
<img src=https://cdn-uploads.huggingface.co/production/uploads/637aebed7ce76c3b834cea37/3IK823BZ8w-mz_QfeYkDn.png width="30%"/>
</div>
<span style="color: #ED7D31; font-size: 22px;">It is recommended to use the latest version: [Ovis2.5](https://huggingface.co/collections/AIDC-AI/ovis2... | null | [
"apache-2.0"
] | [
"AIDC-AI/Ovis-dataset"
] | [
"en",
"zh"
] | 1,267,417,974 | null | null | [
"ovis",
"AutoModelForCausalLM",
"modeling_ovis.Ovis",
"Ovis"
] | [
"image-text-to-text",
"text-generation"
] | [
"text",
"multimodal"
] | [
"text",
"image"
] | [
"text"
] |
6605412c3d1c41c482d00c6b | e23b6bdbe047bb7e | 8bd7d71767538b82 | 32,000 | BPE | 61,249 | true | false | true | true | 3 | Sequence | null | Sequence | [
"Prepend",
"Replace"
] | null | [
"Replace",
"ByteFallback",
"Fuse",
"Strip"
] | 46 | michaelbenayoun/llama-2-tiny-4kv-heads-4layers-random | michaelbenayoun | null | 16,852 | 947,285 | False | 2024-03-28T10:06:36Z | 2025-06-02T14:14:44Z | transformers | 0 | 0 | null | text-generation | {"parameters": {"F32": 8537216}, "total": 8537216} | [
".gitattributes",
"README.md",
"config.json",
"generation_config.json",
"model.safetensors",
"special_tokens_map.json",
"tokenizer.json",
"tokenizer.model",
"tokenizer_config.json"
] | 1df10bbca890a6727747f5233ee63c4df17e5465 | [
"transformers",
"safetensors",
"llama",
"text-generation",
"arxiv:1910.09700",
"text-generation-inference",
"endpoints_compatible",
"deploy:azure",
"region:us"
] | null | {"architectures": ["LlamaForCausalLM"], "model_type": "llama", "tokenizer_config": {"bos_token": "<s>", "eos_token": "</s>", "pad_token": null, "unk_token": "<unk>", "use_default_system_prompt": false}} | {
"auto_model": "AutoModelForCausalLM",
"custom_class": null,
"pipeline_tag": "text-generation",
"processor": "AutoTokenizer"
} | {"base_model": null, "datasets": null, "eval_results": null, "language": null, "library_name": "transformers", "license": null, "license_name": null, "license_link": null, "metrics": null, "model_name": null, "pipeline_tag": null, "tags": []} | # Model Card for Model ID
<!-- Provide a quick summary of what the model is/does. -->
## Model Details
### Model Description
<!-- Provide a longer summary of what this model is. -->
This is the model card of a 🤗 transformers model that has been pushed on the Hub. This model card has been automatically generated... | null | null | null | null | 8,537,216 | null | null | [
"AutoModelForCausalLM",
"llama",
"LlamaForCausalLM"
] | [
"text-generation"
] | [
"text"
] | [
"text"
] | [
"text"
] |
621ffdc036468d709f1753d2 | 53ecf467267e2824 | 535fa14da0af647c | 30,522 | WordPiece | null | true | true | true | true | 5 | BertNormalizer | BertPreTokenizer | WordPiece | [
"BertNormalizer"
] | [
"BertPreTokenizer"
] | [
"WordPiece"
] | 0 | Elron/bleurt-base-128 | Elron | null | 9,214 | 627,005 | False | 2022-03-02T23:29:04Z | 2021-10-04T13:24:42Z | transformers | 3 | 0 | null | text-classification | null | [
".gitattributes",
"README.md",
"config.json",
"pytorch_model.bin",
"special_tokens_map.json",
"tokenizer.json",
"tokenizer_config.json",
"vocab.txt"
] | 3dabe1a4ba7ca2041f5455262780ab797f0f7d0b | [
"transformers",
"pytorch",
"bert",
"text-classification",
"text-embeddings-inference",
"endpoints_compatible",
"deploy:azure",
"region:us"
] | null | {"architectures": ["BertForSequenceClassification"], "model_type": "bert", "tokenizer_config": {"unk_token": "[UNK]", "sep_token": "[SEP]", "pad_token": "[PAD]", "cls_token": "[CLS]", "mask_token": "[MASK]"}} | {
"auto_model": "AutoModelForSequenceClassification",
"custom_class": null,
"pipeline_tag": "text-classification",
"processor": "AutoTokenizer"
} | null | \n## BLEURT
Pytorch version of the original BLEURT models from ACL paper ["BLEURT: Learning Robust Metrics for Text Generation"](https://aclanthology.org/2020.acl-main.704/) by
Thibault Sellam, Dipanjan Das and Ankur P. Parikh of Google Research.
The code for model conversion was originated from [this notebook](http... | null | null | null | null | null | null | null | [
"BertForSequenceClassification",
"bert",
"AutoModelForSequenceClassification"
] | [
"text-classification"
] | [
"text"
] | [
"text"
] | [
"logits"
] |
621ffdc136468d709f17ff93 | 14a8cb12ce5dee8f | 8a01c02d4d0a401c | 119,547 | WordPiece | null | true | true | true | true | 5 | BertNormalizer | BertPreTokenizer | WordPiece | [
"BertNormalizer"
] | [
"BertPreTokenizer"
] | [
"WordPiece"
] | 87 | saattrupdan/nbailab-base-ner-scandi | saattrupdan | null | 60,928 | 873,915 | False | 2022-03-02T23:29:05Z | 2024-12-16T16:21:04Z | transformers | 24 | 0 | [{"name": "nbailab-base-ner-scandi", "results": []}] | token-classification | {"parameters": {"I64": 512, "F32": 177269769}, "total": 177270281} | [
".gitattributes",
".gitignore",
"README.md",
"config.json",
"model.safetensors",
"pytorch_model.bin",
"special_tokens_map.json",
"tokenizer.json",
"tokenizer_config.json",
"training_args.bin",
"vocab.txt"
] | 1a2f925ba13c9b99680dcf52560c955cd29b73ff | [
"transformers",
"pytorch",
"safetensors",
"bert",
"token-classification",
"da",
"no",
"nb",
"nn",
"sv",
"fo",
"is",
"dataset:dane",
"dataset:norne",
"dataset:wikiann",
"dataset:suc3.0",
"arxiv:1911.12146",
"license:mit",
"endpoints_compatible",
"deploy:azure",
"region:us"
] | null | {"architectures": ["BertForTokenClassification"], "model_type": "bert", "tokenizer_config": {"unk_token": "[UNK]", "sep_token": "[SEP]", "pad_token": "[PAD]", "cls_token": "[CLS]", "mask_token": "[MASK]"}} | {
"auto_model": "AutoModelForTokenClassification",
"custom_class": null,
"pipeline_tag": "token-classification",
"processor": "AutoTokenizer"
} | {"base_model": null, "datasets": ["dane", "norne", "wikiann", "suc3.0"], "eval_results": [], "language": ["da", "no", "nb", "nn", "sv", "fo", "is"], "library_name": null, "license": "mit", "license_name": null, "license_link": null, "metrics": null, "model_name": "nbailab-base-ner-scandi", "pipeline_tag": null, "tags":... | # ScandiNER - Named Entity Recognition model for Scandinavian Languages
Check out a demo of the model [here](https://huggingface.co/spaces/alexandrainst/named-entity-recognition).
This model is a fine-tuned version of [NbAiLab/nb-bert-base](https://huggingface.co/NbAiLab/nb-bert-base) for Named Entity Recognition for... | null | [
"mit"
] | [
"dane",
"norne",
"wikiann",
"suc3.0"
] | [
"da",
"no",
"nb",
"nn",
"sv",
"fo",
"is"
] | 177,270,281 | null | null | [
"AutoModelForTokenClassification",
"BertForTokenClassification",
"bert"
] | [
"token-classification"
] | [
"text"
] | [
"text"
] | [
"logits"
] |
621ffdc136468d709f179dd0 | 38e056cdadae4a68 | d831300fa2535eef | 32,005 | Unigram | null | true | true | true | true | 8 | Sequence | Metaspace | Metaspace | [
"Precompiled",
"Strip",
"Replace"
] | [
"Metaspace"
] | [
"Metaspace"
] | 456 | almanach/camembert-large | almanach | null | 36,714 | 761,552 | False | 2022-03-02T23:29:05Z | 2025-08-18T11:48:19Z | transformers | 20 | 0 | null | null | {"parameters": {"F32": 336695557}, "total": 336695557} | [
".gitattributes",
"LICENSE",
"README.md",
"added_tokens.json",
"config.json",
"model.safetensors",
"pytorch_model.bin",
"sentencepiece.bpe.model",
"special_tokens_map.json",
"tokenizer.json",
"tokenizer_config.json"
] | c6e4955c7654931d38dd1b103e8a83fc69e46b53 | [
"transformers",
"pytorch",
"safetensors",
"camembert",
"fr",
"arxiv:1911.03894",
"endpoints_compatible",
"region:us"
] | null | {"model_type": "camembert", "tokenizer_config": {"bos_token": "<s>", "cls_token": "<s>", "eos_token": "</s>", "mask_token": "<mask>", "pad_token": "<pad>", "sep_token": "</s>", "unk_token": "<unk>"}} | {
"auto_model": "AutoModel",
"custom_class": null,
"pipeline_tag": null,
"processor": null
} | {"base_model": null, "datasets": null, "eval_results": null, "language": "fr", "library_name": null, "license": null, "license_name": null, "license_link": null, "metrics": null, "model_name": null, "pipeline_tag": null, "tags": null} | # CamemBERT: a Tasty French Language Model
## Introduction
[CamemBERT](https://arxiv.org/abs/1911.03894) is a state-of-the-art language model for French based on the RoBERTa model.
It is now available on Hugging Face in 6 different versions with varying number of parameters, amount of pretraining data and pretraini... | null | null | null | [
"fr"
] | 336,695,557 | null | null | [
"AutoModel",
"camembert"
] | [
null
] | null | null | null |
6878010b01cf3e805756db82 | 247b76e6aa48f448 | 70bd27c212bc339c | 50,265 | BPE | 50,000 | false | true | true | true | 5 | null | ByteLevel | ByteLevel | null | [
"ByteLevel"
] | [
"ByteLevel"
] | 432 | OpenMed/OpenMed-NER-OrganismDetect-TinyMed-82M | OpenMed | null | 174,677 | 1,729,892 | False | 2025-07-16T19:44:11Z | 2025-08-05T09:36:52Z | transformers | 0 | 0 | null | token-classification | {"parameters": {"BF16": 81530115}, "total": 81530115} | [
".gitattributes",
"README.md",
"config.json",
"merges.txt",
"model.safetensors",
"openmed_vs_sota_grouped_bars.png",
"special_tokens_map.json",
"test_results.json",
"tokenizer.json",
"tokenizer_config.json",
"vocab.json"
] | 80b124106ffac6875e4040a9061dd8ecdfd20cce | [
"transformers",
"safetensors",
"roberta",
"token-classification",
"named-entity-recognition",
"biomedical-nlp",
"species-recognition",
"taxonomy",
"organism-identification",
"biodiversity",
"species",
"en",
"arxiv:2508.01630",
"license:apache-2.0",
"endpoints_compatible",
"region:us"
] | null | {"architectures": ["RobertaForTokenClassification"], "model_type": "roberta", "tokenizer_config": {"bos_token": "<s>", "cls_token": "<s>", "eos_token": "</s>", "mask_token": "<mask>", "pad_token": "<pad>", "sep_token": "</s>", "unk_token": "<unk>"}} | {
"auto_model": "AutoModelForTokenClassification",
"custom_class": null,
"pipeline_tag": "token-classification",
"processor": "AutoTokenizer"
} | {"base_model": null, "datasets": null, "eval_results": null, "language": ["en"], "library_name": null, "license": "apache-2.0", "license_name": null, "license_link": null, "metrics": null, "model_name": null, "pipeline_tag": null, "tags": ["token-classification", "named-entity-recognition", "biomedical-nlp", "transform... | null | null | [
"apache-2.0"
] | null | [
"en"
] | 81,530,115 | null | null | [
"roberta",
"AutoModelForTokenClassification",
"RobertaForTokenClassification"
] | [
"token-classification"
] | [
"text"
] | [
"text"
] | [
"logits"
] |
666c9b35a119281ee0f83870 | 8d65f5c6196e7473 | 0e7bc0977f200d1c | 32,000 | BPE | 58,980 | true | false | true | true | 3 | Sequence | null | Sequence | [
"Prepend",
"Replace"
] | null | [
"Replace",
"ByteFallback",
"Fuse",
"Strip"
] | 423 | Salesforce/SFR-Embedding-2_R | Salesforce | null | 853,500 | 1,975,583 | False | 2024-06-14T19:34:13Z | 2025-02-04T21:05:42Z | sentence-transformers | 94 | 0 | [{"name": "Salesforce/SFR-Embedding-2_R", "results": [{"task": {"type": "Classification"}, "dataset": {"type": "mteb/amazon_counterfactual", "name": "MTEB AmazonCounterfactualClassification (en)", "config": "en", "split": "test", "revision": "e8379541af4e31359cca9fbcf4b00f2671dba205"}, "metrics": [{"type": "accuracy", ... | feature-extraction | {"parameters": {"BF16": 7110660096}, "total": 7110660096} | [
".gitattributes",
"1_Pooling/config.json",
"README.md",
"config.json",
"config_sentence_transformers.json",
"model-00001-of-00003.safetensors",
"model-00002-of-00003.safetensors",
"model-00003-of-00003.safetensors",
"model.safetensors.index.json",
"modules.json",
"sentence_bert_config.json",
"... | f62d15f411ca97b66acc0f34da2a65f3420b55b0 | [
"sentence-transformers",
"safetensors",
"mistral",
"feature-extraction",
"mteb",
"transformers",
"en",
"license:cc-by-nc-4.0",
"model-index",
"text-embeddings-inference",
"endpoints_compatible",
"deploy:azure",
"region:us"
] | null | {"architectures": ["MistralModel"], "model_type": "mistral", "tokenizer_config": {"bos_token": "<s>", "eos_token": "</s>", "pad_token": "</s>", "unk_token": "<unk>", "use_default_system_prompt": false}} | {
"auto_model": "AutoModel",
"custom_class": null,
"pipeline_tag": "feature-extraction",
"processor": "AutoTokenizer"
} | {"language": ["en"], "license": "cc-by-nc-4.0", "tags": ["mteb", "sentence-transformers", "transformers"], "model-index": [{"name": "Salesforce/SFR-Embedding-2_R", "results": [{"task": {"type": "Classification"}, "dataset": {"name": "MTEB AmazonCounterfactualClassification (en)", "type": "mteb/amazon_counterfactual", "... | <h1 align="center">Salesforce/SFR-Embedding-2_R</h1>
**SFR-Embedding by Salesforce Research.**
The model is for **research purposes only**.
More technical details will be updated later. Meanwhile, please refer to our previous work [SFR-Embedding](https://www.salesforce.com/blog/sfr-embedding/) for details.
### Ethi... | null | [
"cc-by-nc-4.0"
] | null | [
"en"
] | 7,110,660,096 | null | null | [
"AutoModel",
"mistral",
"MistralModel"
] | [
"feature-extraction"
] | [
"multimodal"
] | [
"text"
] | [
"embeddings"
] |
678e5cb387ba422cae1fe649 | 7ec8239dd3bcce7b | 46a701b36ce8cd6c | 49,280 | BPE | 48,900 | false | true | false | true | 145 | null | Sequence | ByteLevel | null | [
"Digits",
"ByteLevel"
] | [
"ByteLevel"
] | 242 | HuggingFaceTB/SmolVLM-500M-Instruct | HuggingFaceTB | {
"models": [
{
"_id": "6723890fa6699e634ce61483",
"id": "HuggingFaceTB/SmolLM2-360M-Instruct"
}
],
"relation": "quantized"
} | 39,031 | 730,083 | False | 2025-01-20T14:24:51Z | 2025-04-08T07:26:28Z | transformers | 189 | 0 | null | image-text-to-text | {"parameters": {"BF16": 507482304}, "total": 507482304} | [
".gitattributes",
"README.md",
"added_tokens.json",
"chat_template.json",
"config.json",
"generation_config.json",
"merges.txt",
"model.safetensors",
"onnx/decoder_model_merged.onnx",
"onnx/decoder_model_merged_bnb4.onnx",
"onnx/decoder_model_merged_fp16.onnx",
"onnx/decoder_model_merged_int8.... | a7da5b986cb59b408707209984f360a5f4ad7e47 | [
"transformers",
"onnx",
"safetensors",
"idefics3",
"image-text-to-text",
"conversational",
"en",
"dataset:HuggingFaceM4/the_cauldron",
"dataset:HuggingFaceM4/Docmatix",
"arxiv:2504.05299",
"base_model:HuggingFaceTB/SmolLM2-360M-Instruct",
"base_model:quantized:HuggingFaceTB/SmolLM2-360M-Instru... | null | {"architectures": ["Idefics3ForConditionalGeneration"], "model_type": "idefics3", "processor_config": {"chat_template": "<|im_start|>{% for message in messages %}{{message['role'] | capitalize}}{% if message['content'][0]['type'] == 'image' %}{{':'}}{% else %}{{': '}}{% endif %}{% for line in message['content'] %}{% if... | {
"auto_model": "AutoModelForImageTextToText",
"custom_class": null,
"pipeline_tag": "image-text-to-text",
"processor": "AutoProcessor"
} | {"base_model": ["HuggingFaceTB/SmolLM2-360M-Instruct", "google/siglip-base-patch16-512"], "datasets": ["HuggingFaceM4/the_cauldron", "HuggingFaceM4/Docmatix"], "eval_results": null, "language": ["en"], "library_name": "transformers", "license": "apache-2.0", "license_name": null, "license_link": null, "metrics": null, ... | null | null | [
"apache-2.0"
] | [
"HuggingFaceM4/the_cauldron",
"HuggingFaceM4/Docmatix"
] | [
"en"
] | 507,482,304 | null | null | [
"AutoModelForImageTextToText",
"Idefics3ForConditionalGeneration",
"idefics3"
] | [
"image-text-to-text"
] | [
"multimodal"
] | [
"text",
"image"
] | [
"text"
] |
66f458b04e3f90f536715de8 | 1e0a2493163c0c63 | 6622292dca275a2d | 128,256 | BPE | 280,147 | false | true | true | true | 256 | null | Sequence | ByteLevel | null | [
"Split",
"ByteLevel"
] | [
"ByteLevel"
] | 18 | unsloth/Llama-3.2-1B-bnb-4bit | unsloth | {
"models": [
{
"_id": "66eaebb25fcdca258b9576cb",
"id": "meta-llama/Llama-3.2-1B"
}
],
"relation": "quantized"
} | 16,831 | 641,732 | False | 2024-09-25T18:38:40Z | 2025-06-02T21:10:17Z | transformers | 17 | 0 | null | text-generation | {"parameters": {"F32": 89856, "BF16": 262735872, "U8": 1003525720}, "total": 1266351448} | [
".gitattributes",
"README.md",
"config.json",
"generation_config.json",
"model.safetensors",
"special_tokens_map.json",
"tokenizer.json",
"tokenizer_config.json"
] | c19aba40b57098abca2320dbbb84026dcc24cae4 | [
"transformers",
"safetensors",
"llama",
"text-generation",
"llama-3",
"meta",
"facebook",
"unsloth",
"en",
"base_model:meta-llama/Llama-3.2-1B",
"base_model:quantized:meta-llama/Llama-3.2-1B",
"license:llama3.2",
"text-generation-inference",
"endpoints_compatible",
"4-bit",
"bitsandbyt... | null | {"architectures": ["LlamaForCausalLM"], "model_type": "llama", "quantization_config": {"load_in_4bit": true, "load_in_8bit": false, "quant_method": "bitsandbytes"}, "tokenizer_config": {"bos_token": "<|begin_of_text|>", "eos_token": "<|end_of_text|>", "pad_token": "<|finetune_right_pad_id|>", "unk_token": null}} | {
"auto_model": "AutoModelForCausalLM",
"custom_class": null,
"pipeline_tag": "text-generation",
"processor": "AutoTokenizer"
} | {"base_model": "meta-llama/Llama-3.2-1B", "datasets": null, "eval_results": null, "language": ["en"], "library_name": "transformers", "license": "llama3.2", "license_name": null, "license_link": null, "metrics": null, "model_name": null, "pipeline_tag": null, "tags": ["llama-3", "llama", "meta", "facebook", "unsloth", ... | ## ***See [our collection](https://huggingface.co/collections/unsloth/llama-32-66f46afde4ca573864321a22) for all versions of Llama 3.2 including GGUF, 4-bit and original 16-bit formats.***
# Finetune Llama 3.2, Gemma 2, Mistral 2-5x faster with 70% less memory via Unsloth!
We have a free Google Colab Tesla T4 noteboo... | null | [
"llama3.2"
] | null | [
"en"
] | 1,266,351,448 | null | null | [
"AutoModelForCausalLM",
"llama",
"LlamaForCausalLM"
] | [
"text-generation"
] | [
"text"
] | [
"text"
] | [
"text"
] |
621ffdc136468d709f1799d3 | 820723d44f714bed | 70bd27c212bc339c | 50,265 | BPE | 50,000 | false | true | true | true | 5 | null | ByteLevel | ByteLevel | null | [
"ByteLevel"
] | [
"ByteLevel"
] | 73 | bhadresh-savani/roberta-base-emotion | bhadresh-savani | null | 341 | 626,803 | False | 2022-03-02T23:29:05Z | 2023-03-22T08:48:07Z | transformers | 7 | 0 | [{"name": "bhadresh-savani/roberta-base-emotion", "results": [{"task": {"type": "text-classification", "name": "Text Classification"}, "dataset": {"name": "emotion", "type": "emotion", "config": "default", "split": "test"}, "metrics": [{"type": "accuracy", "value": 0.931, "name": "Accuracy", "verified": true, "verifyTo... | text-classification | {"parameters": {"I64": 514, "F32": 124650246}, "total": 124650760} | [
".gitattributes",
"README.md",
"config.json",
"convert_flax_to_pytorch.py",
"convert_pytorch_to_flax.py",
"convert_pytorch_to_tensorflow.py",
"flax_model.msgpack",
"merges.txt",
"model.safetensors",
"pytorch_model.bin",
"special_tokens_map.json",
"tf_model.h5",
"tokenizer.json",
"tokenizer... | 4569997a1c68e3098eb72cbde91a93621d20ccfb | [
"transformers",
"pytorch",
"tf",
"jax",
"safetensors",
"roberta",
"text-classification",
"emotion",
"en",
"dataset:emotion",
"arxiv:1907.11692",
"license:apache-2.0",
"model-index",
"text-embeddings-inference",
"endpoints_compatible",
"deploy:azure",
"region:us"
] | null | {"architectures": ["RobertaForSequenceClassification"], "model_type": "roberta", "tokenizer_config": {"unk_token": "<unk>", "bos_token": "<s>", "eos_token": "</s>", "sep_token": "</s>", "cls_token": "<s>", "pad_token": "<pad>", "mask_token": "<mask>"}} | {
"auto_model": "AutoModelForSequenceClassification",
"custom_class": null,
"pipeline_tag": "text-classification",
"processor": "AutoTokenizer"
} | {"datasets": ["emotion"], "language": ["en"], "license": "apache-2.0", "metrics": ["Accuracy, F1 Score"], "tags": ["text-classification", "emotion", "pytorch"], "thumbnail": "https://avatars3.githubusercontent.com/u/32437151?s=460&u=4ec59abc8d21d5feea3dab323d23a5860e6996a4&v=4", "model-index": [{"name": "bhadresh-savan... | # robert-base-emotion
## Model description:
[roberta](https://arxiv.org/abs/1907.11692) is Bert with better hyperparameter choices so they said it's Robustly optimized Bert during pretraining.
[roberta-base](https://huggingface.co/roberta-base) finetuned on the emotion dataset using HuggingFace Trainer with below Hyp... | null | [
"apache-2.0"
] | [
"emotion"
] | [
"en"
] | 124,650,760 | null | [
"Accuracy, F1 Score"
] | [
"roberta",
"AutoModelForSequenceClassification",
"RobertaForSequenceClassification"
] | [
"text-classification"
] | [
"text"
] | [
"text"
] | [
"logits"
] |
66eb4305322dcfe9769af375 | 848b60b6cd304b65 | ffc911e785abe60e | 151,665 | BPE | 151,387 | true | true | true | true | 22 | NFC | Sequence | ByteLevel | [
"NFC"
] | [
"Split",
"ByteLevel"
] | [
"ByteLevel"
] | 15 | unsloth/Qwen2.5-3B-Instruct | unsloth | {
"models": [
{
"_id": "66e98d74d4219fc3f1db215f",
"id": "Qwen/Qwen2.5-3B-Instruct"
}
],
"relation": "finetune"
} | 33,102 | 675,019 | False | 2024-09-18T21:15:49Z | 2025-03-06T00:08:34Z | transformers | 16 | 0 | null | text-generation | {"parameters": {"BF16": 3085938688}, "total": 3085938688} | [
".gitattributes",
"README.md",
"added_tokens.json",
"config.json",
"generation_config.json",
"merges.txt",
"model-00001-of-00002.safetensors",
"model-00002-of-00002.safetensors",
"model.safetensors.index.json",
"special_tokens_map.json",
"tokenizer.json",
"tokenizer_config.json",
"vocab.json... | 7548fff1f997f57b2e9e8ab1ec7be96949b00ed0 | [
"transformers",
"safetensors",
"qwen2",
"text-generation",
"unsloth",
"qwen",
"conversational",
"en",
"arxiv:2407.10671",
"base_model:Qwen/Qwen2.5-3B-Instruct",
"base_model:finetune:Qwen/Qwen2.5-3B-Instruct",
"license:other",
"text-generation-inference",
"endpoints_compatible",
"region:u... | null | {"architectures": ["Qwen2ForCausalLM"], "model_type": "qwen2", "tokenizer_config": {"bos_token": null, "chat_template": "{%- if tools %}\n {{- '<|im_start|>system\\n' }}\n {%- if messages[0]['role'] == 'system' %}\n {{- messages[0]['content'] }}\n {%- else %}\n {{- 'You are Qwen, created by Aliba... | {
"auto_model": "AutoModelForCausalLM",
"custom_class": null,
"pipeline_tag": "text-generation",
"processor": "AutoTokenizer"
} | {"base_model": "Qwen/Qwen2.5-3B-Instruct", "datasets": null, "eval_results": null, "language": ["en"], "library_name": "transformers", "license": "other", "license_name": "qwen-research", "license_link": "https://huggingface.co/Qwen/Qwen2.5-3B-Instruct/blob/main/LICENSE", "metrics": null, "model_name": null, "pipeline_... | # Finetune Llama 3.1, Gemma 2, Mistral 2-5x faster with 70% less memory via Unsloth!
We have a Qwen 2.5 (all model sizes) [free Google Colab Tesla T4 notebook](https://colab.research.google.com/drive/1Kose-ucXO1IBaZq5BvbwWieuubP7hxvQ?usp=sharing).
Also a [Qwen 2.5 conversational style notebook](https://colab.research.... | null | [
"other",
"qwen-research",
"https://huggingface.co/Qwen/Qwen2.5-3B-Instruct/blob/main/LICENSE"
] | null | [
"en"
] | 3,085,938,688 | null | null | [
"AutoModelForCausalLM",
"Qwen2ForCausalLM",
"qwen2"
] | [
"text-generation"
] | [
"text"
] | [
"text"
] | [
"text"
] |
658c6ee3539b68adc78a202e | 7df934a5efff44b8 | dd84a2b1ff97657d | 250,002 | Unigram | null | true | true | true | true | 5 | Precompiled | Sequence | Metaspace | [
"Precompiled"
] | [
"WhitespaceSplit",
"Metaspace"
] | [
"Metaspace"
] | 95 | graphistry/news-relevancy-filter | graphistry | null | 9 | 9 | False | 2023-12-27T18:37:23Z | 2023-12-27T18:53:00Z | transformers | 0 | 0 | null | text-classification | {"parameters": {"F32": 117654530}, "total": 117654530} | [
".gitattributes",
"config.json",
"model.safetensors",
"special_tokens_map.json",
"tokenizer.json",
"tokenizer_config.json",
"unigram.json"
] | cd852d1ac61a8df1fa40845337f1cba1cf08d46b | [
"transformers",
"safetensors",
"bert",
"text-classification",
"text-embeddings-inference",
"endpoints_compatible",
"region:us"
] | null | {"architectures": ["BertForSequenceClassification"], "model_type": "bert", "tokenizer_config": {"bos_token": "<s>", "cls_token": "<s>", "eos_token": "</s>", "mask_token": "<mask>", "pad_token": "<pad>", "sep_token": "</s>", "unk_token": "<unk>"}} | {
"auto_model": "AutoModelForSequenceClassification",
"custom_class": null,
"pipeline_tag": "text-classification",
"processor": "AutoTokenizer"
} | null | null | null | null | null | null | 117,654,530 | null | null | [
"BertForSequenceClassification",
"bert",
"AutoModelForSequenceClassification"
] | [
"text-classification"
] | [
"text"
] | [
"text"
] | [
"logits"
] |
669628489396af77764e98b0 | 34093184d10f76a9 | 35b001f3a491f9f9 | 151,646 | BPE | 151,387 | true | true | true | true | 3 | NFC | Sequence | ByteLevel | [
"NFC"
] | [
"Split",
"ByteLevel"
] | [
"ByteLevel"
] | 53 | Qwen/Qwen2-Audio-7B | Qwen | null | 7,270 | 723,606 | False | 2024-07-16T07:59:04Z | 2024-11-20T09:21:08Z | transformers | 165 | 0 | null | audio-text-to-text | null | [
".gitattributes",
"README.md",
"config.json",
"generation_config.json",
"merges.txt",
"model-00001-of-00005.safetensors",
"model-00002-of-00005.safetensors",
"model-00003-of-00005.safetensors",
"model-00004-of-00005.safetensors",
"model-00005-of-00005.safetensors",
"model.safetensors.index.json"... | dd84470756e6277a71d4d7188773a43cde92696e | [
"transformers",
"safetensors",
"qwen2_audio",
"text2text-generation",
"chat",
"audio",
"audio-text-to-text",
"en",
"arxiv:2407.10759",
"arxiv:2311.07919",
"license:apache-2.0",
"endpoints_compatible",
"region:us"
] | null | {"architectures": ["Qwen2AudioForConditionalGeneration"], "model_type": "qwen2_audio", "tokenizer_config": {"bos_token": null, "chat_template": "{% for message in messages %}{% if loop.first and messages[0]['role'] != 'system' %}{{ '<|im_start|>system\nYou are a helpful assistant.<|im_end|>\n' }}{% endif %}{{'<|im_star... | {
"auto_model": "AutoModelForSeq2SeqLM",
"custom_class": null,
"pipeline_tag": "text2text-generation",
"processor": "AutoProcessor"
} | {"base_model": null, "datasets": null, "eval_results": null, "language": ["en"], "library_name": null, "license": "apache-2.0", "license_name": null, "license_link": null, "metrics": null, "model_name": null, "pipeline_tag": null, "tags": ["chat", "audio", "audio-text-to-text"]} | # Qwen2-Audio-7B
## Introduction
Qwen2-Audio is the new series of Qwen large audio-language models. Qwen2-Audio is capable of accepting various audio signal inputs and performing audio analysis or direct textual responses with regard to speech instructions. We introduce two distinct audio interaction modes:
* voice ... | null | [
"apache-2.0"
] | null | [
"en"
] | null | null | null | [
"AutoModelForSeq2SeqLM",
"qwen2_audio",
"Qwen2AudioForConditionalGeneration"
] | [
"text2text-generation",
"audio-text-to-text"
] | null | null | null |
6684012da4ebc8d95608a876 | e23b6bdbe047bb7e | 8bd7d71767538b82 | 32,000 | BPE | 61,249 | true | false | true | true | 3 | Sequence | null | Sequence | [
"Prepend",
"Replace"
] | null | [
"Replace",
"ByteFallback",
"Fuse",
"Strip"
] | 46 | nm-testing/TinyLlama-1.1B-compressed-tensors-kv-cache-scheme | nm-testing | null | 782 | 597,138 | False | 2024-07-02T13:31:25Z | 2026-01-14T08:35:57Z | transformers | 0 | 0 | null | text-generation | {"parameters": {"I64": 308, "F32": 131558444, "I32": 242221056}, "total": 373779808} | [
".gitattributes",
"README.md",
"config.json",
"generation_config.json",
"model.safetensors",
"special_tokens_map.json",
"tokenizer.json",
"tokenizer.model",
"tokenizer_config.json"
] | 6c275465af2c6cb06ee5581d5b6d0bb9cf0a4081 | [
"transformers",
"safetensors",
"llama",
"text-generation",
"text-generation-inference",
"endpoints_compatible",
"compressed-tensors",
"deploy:azure",
"region:us"
] | null | {"architectures": ["LlamaForCausalLM"], "model_type": "llama", "quantization_config": {"quant_method": "compressed-tensors"}, "tokenizer_config": {"bos_token": {"__type": "AddedToken", "content": "<s>", "lstrip": false, "normalized": false, "rstrip": false, "single_word": false}, "eos_token": {"__type": "AddedToken", "... | {
"auto_model": "AutoModelForCausalLM",
"custom_class": null,
"pipeline_tag": "text-generation",
"processor": "AutoTokenizer"
} | null | null | null | null | null | null | 373,779,808 | null | null | [
"AutoModelForCausalLM",
"llama",
"LlamaForCausalLM"
] | [
"text-generation"
] | [
"text"
] | [
"text"
] | [
"text"
] |
6562f5c56ff1b91e282c695c | c97a6495c5454551 | f26f356cd728caa8 | 49,408 | BPE | 48,894 | true | true | true | true | 2 | Sequence | Sequence | ByteLevel | [
"NFC",
"Replace",
"Lowercase"
] | [
"Split",
"ByteLevel"
] | [
"ByteLevel"
] | 2 | LanguageBind/LanguageBind_Audio_FT | LanguageBind | null | 1,824 | 606,944 | False | 2023-11-26T07:37:41Z | 2024-02-01T06:56:41Z | transformers | 2 | 0 | null | zero-shot-image-classification | null | [
".gitattributes",
"README.md",
"config.json",
"merges.txt",
"pytorch_model.bin",
"special_tokens_map.json",
"tokenizer.json",
"tokenizer_config.json",
"vocab.json"
] | 4820c496563c46acfb1ff9a486fae5319f16257e | [
"transformers",
"pytorch",
"LanguageBindAudio",
"zero-shot-image-classification",
"arxiv:2310.01852",
"license:mit",
"endpoints_compatible",
"region:us"
] | null | {"architectures": ["CLIPModel"], "model_type": "LanguageBindAudio", "tokenizer_config": {"bos_token": {"__type": "AddedToken", "content": "<|startoftext|>", "lstrip": false, "normalized": true, "rstrip": false, "single_word": false}, "eos_token": {"__type": "AddedToken", "content": "<|endoftext|>", "lstrip": false, "no... | {
"auto_model": "AutoModelForZeroShotImageClassification",
"custom_class": null,
"pipeline_tag": "zero-shot-image-classification",
"processor": null
} | {"base_model": null, "datasets": null, "eval_results": null, "language": null, "library_name": null, "license": "mit", "license_name": null, "license_link": null, "metrics": null, "model_name": null, "pipeline_tag": null, "tags": null} | <p align="center">
<img src="https://s11.ax1x.com/2024/02/01/pFMDAm9.png" width="250" style="margin-bottom: 0.2;"/>
<p>
<h2 align="center"> <a href="https://arxiv.org/pdf/2310.01852.pdf">【ICLR 2024 🔥】LanguageBind: Extending Video-Language Pretraining to N-modality by Language-based Semantic Alignment</a></h2>
<h5 ... | null | [
"mit"
] | null | null | null | null | null | [
"AutoModelForZeroShotImageClassification",
"CLIPModel",
"LanguageBindAudio"
] | [
"zero-shot-image-classification"
] | [
"multimodal"
] | [
"text",
"image"
] | [
"logits"
] |
63c50d0c9fa5d07c2c2bc467 | 69d9860d38b5c798 | cf7a052aa6fec7ad | 30,000 | BPE | 15,977 | true | true | false | true | 229 | Sequence | Metaspace | Metaspace | [
"NFKC",
"BertNormalizer"
] | [
"Metaspace"
] | [
"Metaspace"
] | 282 | circulus/kobart-letter-v1 | circulus | null | 11,790 | 662,980 | False | 2023-01-16T08:38:36Z | 2023-01-16T08:39:37Z | transformers | 0 | 0 | null | null | null | [
".gitattributes",
"config.json",
"pytorch_model.bin",
"special_tokens_map.json",
"tokenizer.json",
"tokenizer_config.json"
] | 87d105f19c97ba663d612af5f5e135d56cb21f25 | [
"transformers",
"pytorch",
"bart",
"text2text-generation",
"endpoints_compatible",
"region:us"
] | null | {"architectures": ["BartForConditionalGeneration"], "model_type": "bart", "tokenizer_config": {}} | {
"auto_model": "AutoModelForSeq2SeqLM",
"custom_class": null,
"pipeline_tag": "text2text-generation",
"processor": "AutoTokenizer"
} | null | null | null | null | null | null | null | null | null | [
"bart",
"BartForConditionalGeneration",
"AutoModelForSeq2SeqLM"
] | [
"text2text-generation"
] | null | null | null |
63c1ddc81b5c1a514dd25395 | 69d9860d38b5c798 | cf7a052aa6fec7ad | 30,000 | BPE | 15,977 | true | true | false | true | 229 | Sequence | Metaspace | Metaspace | [
"NFKC",
"BertNormalizer"
] | [
"Metaspace"
] | [
"Metaspace"
] | 282 | circulus/kobart-copywrite-v1 | circulus | null | 11,784 | 662,784 | False | 2023-01-13T22:40:08Z | 2023-01-13T22:41:05Z | transformers | 1 | 0 | null | null | null | [
".gitattributes",
"config.json",
"pytorch_model.bin",
"special_tokens_map.json",
"tokenizer.json",
"tokenizer_config.json"
] | 156c5693811b127ef8d14586bd3d37e2cefc2e83 | [
"transformers",
"pytorch",
"bart",
"text2text-generation",
"endpoints_compatible",
"region:us"
] | null | {"architectures": ["BartForConditionalGeneration"], "model_type": "bart", "tokenizer_config": {}} | {
"auto_model": "AutoModelForSeq2SeqLM",
"custom_class": null,
"pipeline_tag": "text2text-generation",
"processor": "AutoTokenizer"
} | null | null | null | null | null | null | null | null | null | [
"bart",
"BartForConditionalGeneration",
"AutoModelForSeq2SeqLM"
] | [
"text2text-generation"
] | null | null | null |
625453370cdcfc004a67230b | 83bf28f8b6767a2f | ae88e903e2b563a1 | 50,295 | BPE | 50,000 | false | true | true | true | 39 | null | ByteLevel | ByteLevel | null | [
"ByteLevel"
] | [
"ByteLevel"
] | 85 | Salesforce/codegen-350M-multi | Salesforce | null | 3,337 | 621,201 | False | 2022-04-11T16:11:35Z | 2025-01-31T20:17:42Z | transformers | 61 | 0 | null | text-generation | null | [
".gitattributes",
"README.md",
"added_tokens.json",
"config.json",
"merges.txt",
"pytorch_model.bin",
"special_tokens_map.json",
"tokenizer.json",
"tokenizer_config.json",
"vocab.json"
] | b25de779e2044ed5e7707505dea0e5a9bb08556a | [
"transformers",
"pytorch",
"codegen",
"text-generation",
"arxiv:2203.13474",
"license:bsd-3-clause",
"endpoints_compatible",
"deploy:azure",
"region:us"
] | null | {"architectures": ["CodeGenForCausalLM"], "model_type": "codegen", "tokenizer_config": {"unk_token": "<|endoftext|>", "bos_token": "<|endoftext|>", "eos_token": "<|endoftext|>"}} | {
"auto_model": "AutoModelForCausalLM",
"custom_class": null,
"pipeline_tag": "text-generation",
"processor": "AutoTokenizer"
} | {"base_model": null, "datasets": null, "eval_results": null, "language": null, "library_name": null, "license": "bsd-3-clause", "license_name": null, "license_link": null, "metrics": null, "model_name": null, "pipeline_tag": null, "tags": null} | # CodeGen (CodeGen-Multi 350M)
## Model description
CodeGen is a family of autoregressive language models for **program synthesis** from the paper: [A Conversational Paradigm for Program Synthesis](https://arxiv.org/abs/2203.13474) by Erik Nijkamp, Bo Pang, Hiroaki Hayashi, Lifu Tu, Huan Wang, Yingbo Zhou, Silvio Sav... | null | [
"bsd-3-clause"
] | null | null | null | null | null | [
"AutoModelForCausalLM",
"codegen",
"CodeGenForCausalLM"
] | [
"text-generation"
] | [
"text"
] | [
"text"
] | [
"text"
] |
67f7f47dbaa44f9416a5d866 | b647996d6543f730 | 7ab62ce4e32550df | 151,674 | BPE | 151,387 | true | true | true | true | 31 | NFC | Sequence | ByteLevel | [
"NFC"
] | [
"Split",
"ByteLevel"
] | [
"ByteLevel"
] | 172 | OpenGVLab/InternVL3-2B | OpenGVLab | {
"models": [
{
"_id": "67ff92d86cbdeca94f39a7a1",
"id": "OpenGVLab/InternVL3-2B-Instruct"
}
],
"relation": "finetune"
} | 39,526 | 797,923 | False | 2025-04-10T16:40:29Z | 2025-09-11T12:49:13Z | transformers | 45 | 0 | null | image-text-to-text | null | [
".gitattributes",
"README.md",
"added_tokens.json",
"config.json",
"configuration_intern_vit.py",
"configuration_internvl_chat.py",
"conversation.py",
"examples/image1.jpg",
"examples/image2.jpg",
"examples/red-panda.mp4",
"generation_config.json",
"merges.txt",
"model.safetensors",
"model... | 899155015275a9b7338c7f4677e19c784e0e5a21 | [
"transformers",
"safetensors",
"internvl_chat",
"feature-extraction",
"internvl",
"custom_code",
"image-text-to-text",
"conversational",
"multilingual",
"dataset:OpenGVLab/MMPR-v1.2",
"arxiv:2312.14238",
"arxiv:2404.16821",
"arxiv:2412.05271",
"arxiv:2411.10442",
"arxiv:2504.10479",
"a... | null | {"architectures": ["InternVLChatModel"], "auto_map": {"AutoConfig": "configuration_internvl_chat.InternVLChatConfig", "AutoModel": "modeling_internvl_chat.InternVLChatModel", "AutoModelForCausalLM": "modeling_internvl_chat.InternVLChatModel"}, "model_type": "internvl_chat", "tokenizer_config": {"bos_token": null, "chat... | {
"auto_model": "AutoModel",
"custom_class": "modeling_internvl_chat.InternVLChatModel",
"pipeline_tag": "feature-extraction",
"processor": null
} | {"base_model": ["OpenGVLab/InternVL3-2B-Instruct"], "datasets": ["OpenGVLab/MMPR-v1.2"], "eval_results": null, "language": ["multilingual"], "library_name": "transformers", "license": "apache-2.0", "license_name": "qwen", "license_link": "https://huggingface.co/Qwen/Qwen2.5-72B-Instruct/blob/main/LICENSE", "metrics": n... | # InternVL3-2B
[\[📂 GitHub\]](https://github.com/OpenGVLab/InternVL) [\[📜 InternVL 1.0\]](https://huggingface.co/papers/2312.14238) [\[📜 InternVL 1.5\]](https://huggingface.co/papers/2404.16821) [\[📜 InternVL 2.5\]](https://huggingface.co/papers/2412.05271) [\[📜 InternVL2.5-MPO\]](https://huggingface.co/paper... | null | [
"apache-2.0",
"qwen",
"https://huggingface.co/Qwen/Qwen2.5-72B-Instruct/blob/main/LICENSE"
] | [
"OpenGVLab/MMPR-v1.2"
] | [
"multilingual"
] | null | null | null | [
"AutoModel",
"internvl_chat",
"InternVLChatModel",
"modeling_internvl_chat.InternVLChatModel"
] | [
"image-text-to-text",
"feature-extraction"
] | [
"multimodal"
] | [
"text",
"image"
] | [
"text",
"embeddings"
] |
621ffdc136468d709f1774f2 | 6cb1e7b9477371bb | 0c920ea67da16983 | 30,522 | WordPiece | null | true | true | true | true | 5 | BertNormalizer | BertPreTokenizer | WordPiece | [
"BertNormalizer"
] | [
"BertPreTokenizer"
] | [
"WordPiece"
] | 457 | Seznam/small-e-czech | Seznam | null | 678 | 590,705 | False | 2022-03-02T23:29:05Z | 2022-08-26T14:05:35Z | transformers | 17 | 0 | null | null | null | [
".gitattributes",
"LICENSE",
"README.md",
"config.json",
"pytorch_model.bin",
"tf_model.h5",
"tokenizer.json",
"tokenizer_config.json",
"vocab.txt"
] | c8d6237db871e7d4bbfa7634f7ad2123422040ca | [
"transformers",
"pytorch",
"tf",
"electra",
"cs",
"arxiv:2003.10555",
"arxiv:2112.01810",
"license:cc-by-4.0",
"endpoints_compatible",
"region:us"
] | null | {"model_type": "electra", "tokenizer_config": {}} | {
"auto_model": "AutoModel",
"custom_class": null,
"pipeline_tag": null,
"processor": null
} | {"base_model": null, "datasets": null, "eval_results": null, "language": "cs", "library_name": null, "license": "cc-by-4.0", "license_name": null, "license_link": null, "metrics": null, "model_name": null, "pipeline_tag": null, "tags": null} | # Small-E-Czech
Small-E-Czech is an [Electra](https://arxiv.org/abs/2003.10555)-small model pretrained on a Czech web corpus created at [Seznam.cz](https://www.seznam.cz/) and introduced in an [IAAI 2022 paper](https://arxiv.org/abs/2112.01810). Like other pretrained models, it should be finetuned on a downstream task... | null | [
"cc-by-4.0"
] | null | [
"cs"
] | null | null | null | [
"AutoModel",
"electra"
] | [
null
] | null | null | null |
630143ad5ea4c617b21ab87e | 79915a66ee4b8a80 | 9e14ca63c90db3f4 | 32,000 | WordPiece | null | true | true | true | true | 5 | BertNormalizer | BertPreTokenizer | WordPiece | [
"BertNormalizer"
] | [
"BertPreTokenizer"
] | [
"WordPiece"
] | 458 | alierenak/berturk_cased_ner | alierenak | null | 25 | 587,425 | False | 2022-08-20T20:27:25Z | 2022-08-20T22:05:15Z | transformers | 0 | 0 | null | token-classification | null | [
".gitattributes",
"README.md",
"config.json",
"pytorch_model.bin",
"special_tokens_map.json",
"tokenizer.json",
"tokenizer_config.json",
"training_args.bin",
"vocab.txt"
] | 9f8b7b3c99005f39ecfbcb982c6acd9a0f3cc79e | [
"transformers",
"pytorch",
"bert",
"token-classification",
"ner",
"berturk",
"turkish",
"tr",
"dataset:MilliyetNER",
"endpoints_compatible",
"region:us"
] | null | {"architectures": ["BertForTokenClassification"], "model_type": "bert", "tokenizer_config": {"unk_token": "[UNK]", "sep_token": "[SEP]", "pad_token": "[PAD]", "cls_token": "[CLS]", "mask_token": "[MASK]"}} | {
"auto_model": "AutoModelForTokenClassification",
"custom_class": null,
"pipeline_tag": "token-classification",
"processor": "AutoTokenizer"
} | {"base_model": null, "datasets": ["MilliyetNER"], "eval_results": null, "language": "tr", "library_name": null, "license": null, "license_name": null, "license_link": null, "metrics": null, "model_name": null, "pipeline_tag": null, "tags": ["ner", "token-classification", "berturk", "turkish"], "widget": [{"text": "T\u0... | # DATASET
MilliyetNER dataset was collected from the Turkish Milliyet newspaper articles between 1997-1998. This dataset is presented by [Tür et al. (2003)](https://www.cambridge.org/core/journals/natural-language-engineering/article/abs/statistical-information-extraction-system-for-turkish/7C288FAFC71D5F0763C1F8CE6646... | null | null | [
"MilliyetNER"
] | [
"tr"
] | null | null | null | [
"AutoModelForTokenClassification",
"BertForTokenClassification",
"bert"
] | [
"token-classification"
] | [
"text"
] | [
"text"
] | [
"logits"
] |
67f6e280f80cab33cab97576 | cdf28af53b0afd34 | 3c94f41626151d20 | 100,352 | BPE | 100,000 | false | true | false | true | 96 | null | Sequence | ByteLevel | null | [
"Split",
"ByteLevel"
] | [
"ByteLevel"
] | 459 | microsoft/Phi-4-reasoning | microsoft | {
"models": [
{
"_id": "67597bd1b9cdca50cb621f94",
"id": "microsoft/phi-4"
}
],
"relation": "finetune"
} | 16,180 | 641,612 | False | 2025-04-09T21:11:28Z | 2025-11-24T16:57:55Z | transformers | 219 | 1 | null | text-generation | null | [
".gitattributes",
"CODE_OF_CONDUCT.md",
"LICENSE",
"README.md",
"SECURITY.md",
"config.json",
"data_summary_card.md",
"generation_config.json",
"model-00001-of-00006.safetensors",
"model-00002-of-00006.safetensors",
"model-00003-of-00006.safetensors",
"model-00004-of-00006.safetensors",
"mod... | 1de18ec97600877ce63dbf60c73b998da99f0195 | [
"transformers",
"safetensors",
"phi3",
"text-generation",
"phi",
"nlp",
"math",
"code",
"chat",
"conversational",
"reasoning",
"en",
"arxiv:2504.21318",
"base_model:microsoft/phi-4",
"base_model:finetune:microsoft/phi-4",
"license:mit",
"text-generation-inference",
"endpoints_compa... | null | {"architectures": ["Phi3ForCausalLM"], "model_type": "phi3", "tokenizer_config": {"bos_token": "<|endoftext|>", "chat_template": "<|im_start|>system<|im_sep|>You are Phi, a language model trained by Microsoft to help users. Your role as an assistant involves thoroughly exploring questions through a systematic thinking ... | {
"auto_model": "AutoModelForCausalLM",
"custom_class": null,
"pipeline_tag": "text-generation",
"processor": "AutoTokenizer"
} | {"base_model": ["microsoft/phi-4"], "datasets": null, "eval_results": null, "language": ["en"], "library_name": "transformers", "license": "mit", "license_name": null, "license_link": "https://huggingface.co/microsoft/Phi-4-reasoning/resolve/main/LICENSE", "metrics": null, "model_name": null, "pipeline_tag": "text-gene... | # Phi-4-reasoning Model Card
[Phi-4-reasoning Technical Report](https://huggingface.co/papers/2504.21318)
## Model Summary
| | |
|-------------------------|------------------------------------------------------... | null | [
"mit",
"https://huggingface.co/microsoft/Phi-4-reasoning/resolve/main/LICENSE"
] | null | [
"en"
] | null | null | null | [
"AutoModelForCausalLM",
"phi3",
"Phi3ForCausalLM"
] | [
"text-generation"
] | [
"text"
] | [
"text"
] | [
"text"
] |
684b11e729c32c69e56d1db9 | c2792a3981a35642 | 9a5b3c15caa98e84 | 262,400 | BPE | 514,906 | true | true | true | true | 6,670 | Replace | Split | Sequence | [
"Replace"
] | [
"Split"
] | [
"Replace",
"ByteFallback",
"Fuse"
] | 406 | google/gemma-3n-E2B-it | google | {
"models": [
{
"_id": "683f3c2354280d882006f816",
"id": "google/gemma-3n-E4B-it"
}
],
"relation": "finetune"
} | 279,054 | 1,756,622 | manual | 2025-06-12T17:44:07Z | 2025-07-14T13:55:52Z | transformers | 289 | 6 | null | image-text-to-text | null | [
".gitattributes",
"README.md",
"chat_template.jinja",
"config.json",
"generation_config.json",
"model-00001-of-00003.safetensors",
"model-00002-of-00003.safetensors",
"model-00003-of-00003.safetensors",
"model.safetensors.index.json",
"notebook.ipynb",
"preprocessor_config.json",
"processor_co... | 5e092ebca197cdcd8d8b195040accf22693501bc | [
"transformers",
"safetensors",
"gemma3n",
"image-text-to-text",
"automatic-speech-recognition",
"automatic-speech-translation",
"audio-text-to-text",
"video-text-to-text",
"conversational",
"arxiv:1905.07830",
"arxiv:1905.10044",
"arxiv:1911.11641",
"arxiv:1904.09728",
"arxiv:1705.03551",
... | null | {"architectures": ["Gemma3nForConditionalGeneration"], "model_type": "gemma3n", "tokenizer_config": {"bos_token": "<bos>", "eos_token": "<eos>", "pad_token": "<pad>", "unk_token": "<unk>", "use_default_system_prompt": false}, "chat_template_jinja": "{{ bos_token }}\n{%- if messages[0]['role'] == 'system' -%}\n {%- i... | {
"auto_model": "AutoModelForImageTextToText",
"custom_class": null,
"pipeline_tag": "image-text-to-text",
"processor": "AutoProcessor"
} | {"base_model": "google/gemma-3n-E4B-it", "datasets": null, "eval_results": null, "language": null, "library_name": "transformers", "license": "gemma", "license_name": null, "license_link": null, "metrics": null, "model_name": null, "pipeline_tag": "image-text-to-text", "tags": ["automatic-speech-recognition", "automati... | null | null | [
"gemma"
] | null | null | null | null | null | [
"AutoModelForImageTextToText",
"gemma3n",
"Gemma3nForConditionalGeneration"
] | [
"image-text-to-text",
"video-text-to-text",
"automatic-speech-recognition"
] | [
"vision",
"multimodal"
] | [
"text",
"audio",
"image"
] | [
"text"
] |
675b0dd2d2424f2994d5e9c9 | 54895f2d8faef315 | e6ffdc5dd5f1fd86 | 256,000 | BPE | 580,604 | true | true | true | true | 249 | Replace | Split | Sequence | [
"Replace"
] | [
"Split"
] | [
"Replace",
"ByteFallback",
"Fuse"
] | 50 | Efficient-Large-Model/gemma-2-2b-it | Efficient-Large-Model | {
"models": [
{
"_id": "66962a41534f204a2b9982fd",
"id": "google/gemma-2-2b"
}
],
"relation": "finetune"
} | 49,168 | 803,640 | False | 2024-12-12T16:22:42Z | 2024-12-13T15:40:59Z | transformers | 3 | 0 | null | text-generation | {"parameters": {"BF16": 2614341888}, "total": 2614341888} | [
".gitattributes",
"README.md",
"config.json",
"gemma-2-2b-it.safetensors",
"generation_config.json",
"model-00001-of-00002.safetensors",
"model-00002-of-00002.safetensors",
"model.safetensors.index.json",
"special_tokens_map.json",
"tokenizer.json",
"tokenizer.model",
"tokenizer_config.json"
] | 569d9809d0c8b6722d4d31b5a77a2ec7a400650a | [
"transformers",
"safetensors",
"gemma2",
"text-generation",
"conversational",
"arxiv:2009.03300",
"arxiv:1905.07830",
"arxiv:1911.11641",
"arxiv:1904.09728",
"arxiv:1905.10044",
"arxiv:1907.10641",
"arxiv:1811.00937",
"arxiv:1809.02789",
"arxiv:1911.01547",
"arxiv:1705.03551",
"arxiv:2... | null | {"architectures": ["Gemma2ForCausalLM"], "model_type": "gemma2", "tokenizer_config": {"bos_token": "<bos>", "chat_template": "{{ bos_token }}{% if messages[0]['role'] == 'system' %}{{ raise_exception('System role not supported') }}{% endif %}{% for message in messages %}{% if (message['role'] == 'user') != (loop.index0... | {
"auto_model": "AutoModelForCausalLM",
"custom_class": null,
"pipeline_tag": "text-generation",
"processor": "AutoTokenizer"
} | {"base_model": "google/gemma-2-2b", "datasets": null, "eval_results": null, "language": null, "library_name": "transformers", "license": "gemma", "license_name": null, "license_link": null, "metrics": null, "model_name": null, "pipeline_tag": "text-generation", "tags": ["conversational"], "extra_gated_heading": "Access... | # Gemma 2 model card
**Model Page**: [Gemma](https://ai.google.dev/gemma/docs/base)
**Resources and Technical Documentation**:
* [Responsible Generative AI Toolkit][rai-toolkit]
* [Gemma on Kaggle][kaggle-gemma]
* [Gemma on Vertex Model Garden][vertex-mg-gemma2]
**Terms of Use**: [Terms][terms]
**Authors**: Google... | null | [
"gemma"
] | null | null | 2,614,341,888 | null | null | [
"AutoModelForCausalLM",
"gemma2",
"Gemma2ForCausalLM"
] | [
"text-generation"
] | [
"text"
] | [
"text"
] | [
"text"
] |
642b7456a8447882afeee44b | 84892a81d307796d | 8bd7d71767538b82 | 32,000 | BPE | 61,249 | true | false | true | true | 3 | Sequence | null | Sequence | [
"Prepend",
"Replace"
] | null | [
"Replace",
"ByteFallback",
"Fuse",
"Strip"
] | 133 | huggyllama/llama-30b | huggyllama | null | 3,960 | 596,114 | False | 2023-04-04T00:50:30Z | 2023-04-07T15:50:57Z | transformers | 48 | 0 | null | text-generation | {"parameters": {"F32": 3840, "F16": 32528943616}, "total": 32528947456} | [
".gitattributes",
"LICENSE",
"README.md",
"config.json",
"generation_config.json",
"model-00001-of-00007.safetensors",
"model-00002-of-00007.safetensors",
"model-00003-of-00007.safetensors",
"model-00004-of-00007.safetensors",
"model-00005-of-00007.safetensors",
"model-00006-of-00007.safetensors... | 2b1edcdb3c7ced7bce6c1aa75c94545777c3118b | [
"transformers",
"pytorch",
"safetensors",
"llama",
"text-generation",
"license:other",
"text-generation-inference",
"endpoints_compatible",
"deploy:azure",
"region:us"
] | null | {"architectures": ["LlamaForCausalLM"], "model_type": "llama", "tokenizer_config": {"bos_token": {"__type": "AddedToken", "content": "<s>", "lstrip": false, "normalized": true, "rstrip": false, "single_word": false}, "eos_token": {"__type": "AddedToken", "content": "</s>", "lstrip": false, "normalized": true, "rstrip":... | {
"auto_model": "AutoModelForCausalLM",
"custom_class": null,
"pipeline_tag": "text-generation",
"processor": "AutoTokenizer"
} | {"base_model": null, "datasets": null, "eval_results": null, "language": null, "library_name": null, "license": "other", "license_name": null, "license_link": null, "metrics": null, "model_name": null, "pipeline_tag": null, "tags": null} | This contains the weights for the LLaMA-30b model. This model is under a non-commercial license (see the LICENSE file).
You should only use this repository if you have been granted access to the model by filling out [this form](https://docs.google.com/forms/d/e/1FAIpQLSfqNECQnMkycAp2jP4Z9TFX0cGR4uf7b_fBxjY_OjhJILlKGA/v... | null | [
"other"
] | null | null | 32,528,947,456 | null | null | [
"AutoModelForCausalLM",
"llama",
"LlamaForCausalLM"
] | [
"text-generation"
] | [
"text"
] | [
"text"
] | [
"text"
] |
64b72139a00eab5bcddae33e | e23b6bdbe047bb7e | 8bd7d71767538b82 | 32,000 | BPE | 61,249 | true | false | true | true | 3 | Sequence | null | Sequence | [
"Prepend",
"Replace"
] | null | [
"Replace",
"ByteFallback",
"Fuse",
"Strip"
] | 46 | TheBloke/Llama-2-70B-Chat-GPTQ | TheBloke | {
"models": [
{
"_id": "64b18d9f3aecf08f78ec75f3",
"id": "meta-llama/Llama-2-70b-chat-hf"
}
],
"relation": "quantized"
} | 2,998 | 595,063 | False | 2023-07-18T23:33:13Z | 2023-09-27T12:44:49Z | transformers | 259 | 0 | null | text-generation | {"parameters": {"F32": 5120, "I32": 68451041280, "F16": 532324352}, "total": 68983370752} | [
".gitattributes",
"LICENSE.txt",
"Notice",
"README.md",
"USE_POLICY.md",
"config.json",
"generation_config.json",
"model.safetensors",
"quantize_config.json",
"special_tokens_map.json",
"tokenizer.json",
"tokenizer.model",
"tokenizer_config.json"
] | ac53ed5e8ebdbbe6db22ecf816e21f55905418df | [
"transformers",
"safetensors",
"llama",
"text-generation",
"facebook",
"meta",
"pytorch",
"llama-2",
"en",
"arxiv:2307.09288",
"base_model:meta-llama/Llama-2-70b-chat-hf",
"base_model:quantized:meta-llama/Llama-2-70b-chat-hf",
"license:llama2",
"text-generation-inference",
"4-bit",
"gp... | null | {"architectures": ["LlamaForCausalLM"], "model_type": "llama", "quantization_config": {"bits": 4, "quant_method": "gptq"}, "tokenizer_config": {"bos_token": {"__type": "AddedToken", "content": "<s>", "lstrip": false, "normalized": true, "rstrip": false, "single_word": false}, "eos_token": {"__type": "AddedToken", "cont... | {
"auto_model": "AutoModelForCausalLM",
"custom_class": null,
"pipeline_tag": "text-generation",
"processor": "AutoTokenizer"
} | {"base_model": "meta-llama/Llama-2-70b-chat-hf", "datasets": null, "eval_results": null, "language": ["en"], "library_name": null, "license": "llama2", "license_name": null, "license_link": null, "metrics": null, "model_name": "Llama 2 70B Chat", "pipeline_tag": "text-generation", "tags": ["facebook", "meta", "pytorch"... | <!-- header start -->
<!-- 200823 -->
<div style="width: auto; margin-left: auto; margin-right: auto">
<img src="https://i.imgur.com/EBdldam.jpg" alt="TheBlokeAI" style="width: 100%; min-width: 400px; display: block; margin: auto;">
</div>
<div style="display: flex; justify-content: space-between; width: 100%;">
<d... | null | [
"llama2"
] | null | [
"en"
] | 68,983,370,752 | null | null | [
"AutoModelForCausalLM",
"llama",
"LlamaForCausalLM"
] | [
"text-generation"
] | [
"text"
] | [
"text"
] | [
"text"
] |
621ffdc136468d709f17a21f | 53ecf467267e2824 | 535fa14da0af647c | 30,522 | WordPiece | null | true | true | true | true | 5 | BertNormalizer | BertPreTokenizer | WordPiece | [
"BertNormalizer"
] | [
"BertPreTokenizer"
] | [
"WordPiece"
] | 0 | cross-encoder/qnli-electra-base | cross-encoder | {
"models": [
{
"_id": "621ffdc136468d709f17b61d",
"id": "google/electra-base-discriminator"
}
],
"relation": "quantized"
} | 50,656 | 840,467 | False | 2022-03-02T23:29:05Z | 2025-04-11T08:51:48Z | sentence-transformers | 4 | 0 | null | text-ranking | {"parameters": {"I64": 512, "F32": 109483009}, "total": 109483521} | [
".gitattributes",
"CEBinaryAccuracyEvaluator_qnli-dev_results.csv",
"README.md",
"config.json",
"model.safetensors",
"onnx/model.onnx",
"onnx/model_O1.onnx",
"onnx/model_O2.onnx",
"onnx/model_O3.onnx",
"onnx/model_O4.onnx",
"onnx/model_qint8_arm64.onnx",
"onnx/model_qint8_avx512.onnx",
"onnx... | c7dea87c98b2269a935686c31336e97e837cbbeb | [
"sentence-transformers",
"pytorch",
"onnx",
"safetensors",
"openvino",
"electra",
"text-classification",
"transformers",
"text-ranking",
"en",
"arxiv:1804.07461",
"base_model:google/electra-base-discriminator",
"base_model:quantized:google/electra-base-discriminator",
"license:apache-2.0",... | null | {"architectures": ["ElectraForSequenceClassification"], "model_type": "electra", "tokenizer_config": {"cls_token": "[CLS]", "mask_token": "[MASK]", "pad_token": "[PAD]", "sep_token": "[SEP]", "unk_token": "[UNK]"}} | {
"auto_model": "AutoModelForSequenceClassification",
"custom_class": null,
"pipeline_tag": "text-classification",
"processor": "AutoTokenizer"
} | {"base_model": ["google/electra-base-discriminator"], "datasets": null, "eval_results": null, "language": ["en"], "library_name": "sentence-transformers", "license": "apache-2.0", "license_name": null, "license_link": null, "metrics": null, "model_name": null, "pipeline_tag": "text-ranking", "tags": ["transformers"]} | null | null | [
"apache-2.0"
] | null | [
"en"
] | 109,483,521 | null | null | [
"ElectraForSequenceClassification",
"AutoModelForSequenceClassification",
"electra"
] | [
"text-ranking",
"text-classification"
] | [
"text"
] | [
"text"
] | [
"logits"
] |
6645f32b67ef7ab8a3e1ad39 | 6e6a83dc4b556c95 | a1f1bd381dcb9329 | 128,256 | BPE | 280,147 | false | true | true | true | 256 | null | Sequence | ByteLevel | null | [
"Split",
"ByteLevel"
] | [
"ByteLevel"
] | 111 | zai-org/cogvlm2-llama3-chat-19B | zai-org | null | 4,499 | 596,406 | False | 2024-05-16T11:51:07Z | 2024-09-03T16:38:05Z | transformers | 220 | 0 | null | text-generation | {"parameters": {"BF16": 19503107328}, "total": 19503107328} | [
".gitattributes",
"LICENSE",
"LLAMA3_LICENSE",
"README.md",
"config.json",
"configuration.json",
"configuration_cogvlm.py",
"generation_config.json",
"model-00001-of-00008.safetensors",
"model-00002-of-00008.safetensors",
"model-00003-of-00008.safetensors",
"model-00004-of-00008.safetensors",
... | f592f291cf528389b2e4776b1e84ecdf6d71fbe3 | [
"transformers",
"safetensors",
"text-generation",
"chat",
"cogvlm2",
"conversational",
"custom_code",
"en",
"arxiv:2408.16500",
"arxiv:2311.03079",
"license:other",
"region:us"
] | null | {"architectures": ["CogVLMForCausalLM"], "auto_map": {"AutoConfig": "configuration_cogvlm.CogVLMConfig", "AutoModelForCausalLM": "modeling_cogvlm.CogVLMForCausalLM"}, "tokenizer_config": {"bos_token": "<|begin_of_text|>", "chat_template": "{% if not add_generation_prompt is defined %}{% set add_generation_prompt = fals... | {
"auto_model": "AutoModelForCausalLM",
"custom_class": "modeling_cogvlm.CogVLMForCausalLM",
"pipeline_tag": "text-generation",
"processor": null
} | {"base_model": null, "datasets": null, "eval_results": null, "language": ["en"], "library_name": null, "license": "other", "license_name": "cogvlm2", "license_link": "https://huggingface.co/THUDM/cogvlm2-llama3-chat-19B/blob/main/LICENSE", "metrics": null, "model_name": null, "pipeline_tag": "text-generation", "tags": ... | null | null | [
"other",
"cogvlm2",
"https://huggingface.co/THUDM/cogvlm2-llama3-chat-19B/blob/main/LICENSE"
] | null | [
"en"
] | 19,503,107,328 | null | null | [
"AutoModelForCausalLM",
"CogVLMForCausalLM",
"modeling_cogvlm.CogVLMForCausalLM"
] | [
"text-generation"
] | [
"text"
] | [
"text"
] | [
"text"
] |
6757d6d1d7c576b59087f2d3 | a96b992324d02e42 | ac8d046cbfff5b57 | 100,018 | BPE | 99,757 | true | true | true | true | 18 | Sequence | Sequence | ByteLevel | [] | [
"Split",
"Split",
"Split",
"Split",
"Split",
"Digits",
"ByteLevel"
] | [
"ByteLevel"
] | 151 | deepseek-ai/DeepSeek-V2.5-1210 | deepseek-ai | null | 825 | 588,359 | False | 2024-12-10T05:51:13Z | 2024-12-11T12:06:11Z | transformers | 256 | 0 | null | text-generation | {"parameters": {"BF16": 235741434880}, "total": 235741434880} | [
".gitattributes",
"LICENSE",
"README.md",
"config.json",
"configuration_deepseek.py",
"generation_config.json",
"model-00001-of-000055.safetensors",
"model-00002-of-000055.safetensors",
"model-00003-of-000055.safetensors",
"model-00004-of-000055.safetensors",
"model-00005-of-000055.safetensors",... | 6f134cbe88cb9284a8ce696e8ac8eefd0bc24ede | [
"transformers",
"safetensors",
"deepseek_v2",
"text-generation",
"conversational",
"custom_code",
"arxiv:2405.04434",
"license:other",
"text-generation-inference",
"endpoints_compatible",
"region:us"
] | null | {"architectures": ["DeepseekV2ForCausalLM"], "auto_map": {"AutoConfig": "configuration_deepseek.DeepseekV2Config", "AutoModel": "modeling_deepseek.DeepseekV2Model", "AutoModelForCausalLM": "modeling_deepseek.DeepseekV2ForCausalLM"}, "model_type": "deepseek_v2", "tokenizer_config": {"bos_token": {"__type": "AddedToken",... | {
"auto_model": "AutoModelForCausalLM",
"custom_class": null,
"pipeline_tag": "text-generation",
"processor": "AutoTokenizer"
} | {"base_model": null, "datasets": null, "eval_results": null, "language": null, "library_name": "transformers", "license": "other", "license_name": "deepseek", "license_link": "https://github.com/deepseek-ai/DeepSeek-V2/blob/main/LICENSE-MODEL", "metrics": null, "model_name": null, "pipeline_tag": null, "tags": null} | <!-- markdownlint-disable first-line-h1 -->
<!-- markdownlint-disable html -->
<!-- markdownlint-disable no-duplicate-header -->
<div align="center">
<img src="https://github.com/deepseek-ai/DeepSeek-V2/blob/main/figures/logo.svg?raw=true" width="60%" alt="DeepSeek-V2" />
</div>
<hr>
<div align="center" style="line-... | null | [
"other",
"deepseek",
"https://github.com/deepseek-ai/DeepSeek-V2/blob/main/LICENSE-MODEL"
] | null | null | 235,741,434,880 | null | null | [
"AutoModelForCausalLM",
"DeepseekV2ForCausalLM",
"deepseek_v2"
] | [
"text-generation"
] | [
"text"
] | [
"text"
] | [
"text"
] |
621ffdc036468d709f17626f | 8a8c94e1a59f5186 | ef4806e2ade9022f | 32,100 | Unigram | null | true | true | true | true | 103 | Precompiled | Sequence | Metaspace | [
"Precompiled"
] | [
"WhitespaceSplit",
"Metaspace"
] | [
"Metaspace"
] | 11 | KES/T5-KES | KES | null | 44 | 582,469 | False | 2022-03-02T23:29:04Z | 2023-04-11T13:37:36Z | transformers | 1 | 0 | null | null | {"parameters": {"F32": 222903552}, "total": 222903552} | [
".gitattributes",
"README.md",
"config.json",
"model.safetensors",
"pytorch_model.bin",
"special_tokens_map.json",
"spiece.model",
"tokenizer.json",
"tokenizer_config.json"
] | ee6899f614a1e9ed09c1d3b1a1b28980fd074ac8 | [
"transformers",
"pytorch",
"safetensors",
"t5",
"text2text-generation",
"sentence correction",
"en",
"dataset:jfleg",
"arxiv:1702.04066",
"license:cc-by-nc-sa-4.0",
"text-generation-inference",
"endpoints_compatible",
"deploy:azure",
"region:us"
] | null | {"architectures": ["T5ForConditionalGeneration"], "model_type": "t5", "tokenizer_config": {"eos_token": "</s>", "unk_token": "<unk>", "pad_token": "<pad>"}} | {
"auto_model": "AutoModelForSeq2SeqLM",
"custom_class": null,
"pipeline_tag": "text2text-generation",
"processor": "AutoTokenizer"
} | {"base_model": null, "datasets": ["jfleg"], "eval_results": null, "language": "en", "library_name": null, "license": "cc-by-nc-sa-4.0", "license_name": null, "license_link": null, "metrics": null, "model_name": null, "pipeline_tag": null, "tags": ["sentence correction", "text2text-generation"]} | # Model
This model utilises T5-base pre-trained model. It was fine tuned using a modified version of the [JFLEG](https://arxiv.org/abs/1702.04066) dataset and [Happy Transformer framework](https://github.com/EricFillion/happy-transformer). This model was fine-tuned for sentence correction on normal English translations... | null | [
"cc-by-nc-sa-4.0"
] | [
"jfleg"
] | [
"en"
] | 222,903,552 | null | null | [
"t5",
"T5ForConditionalGeneration",
"AutoModelForSeq2SeqLM"
] | [
"text2text-generation"
] | null | null | null |
66904daea4d0df7e519ab6aa | 99c712c6ae96150c | a1f1bd381dcb9329 | 128,256 | BPE | 280,147 | false | true | true | true | 256 | null | Sequence | ByteLevel | null | [
"Split",
"ByteLevel"
] | [
"ByteLevel"
] | 460 | RedHatAI/Meta-Llama-3-70B-Instruct-quantized.w4a16 | RedHatAI | {
"models": [
{
"_id": "661f97be9cae93c02393e8ef",
"id": "meta-llama/Meta-Llama-3-70B-Instruct"
}
],
"relation": "quantized"
} | 13 | 582,028 | False | 2024-07-11T21:25:02Z | 2024-08-29T16:00:34Z | transformers | 2 | 0 | null | text-generation | {"parameters": {"I32": 68451041280, "F16": 2102665216}, "total": 70553706496} | [
".gitattributes",
"README.md",
"config.json",
"model.safetensors",
"quantize_config.json",
"special_tokens_map.json",
"tokenizer.json",
"tokenizer_config.json"
] | 8fc8ead75acf5a862f37732a7721abe448f20329 | [
"transformers",
"safetensors",
"llama",
"text-generation",
"conversational",
"en",
"base_model:meta-llama/Meta-Llama-3-70B-Instruct",
"base_model:quantized:meta-llama/Meta-Llama-3-70B-Instruct",
"license:llama3",
"text-generation-inference",
"endpoints_compatible",
"4-bit",
"gptq",
"region... | null | {"architectures": ["LlamaForCausalLM"], "model_type": "llama", "quantization_config": {"bits": 4, "quant_method": "gptq"}, "tokenizer_config": {"bos_token": "<|begin_of_text|>", "chat_template": "{% set loop_messages = messages %}{% for message in loop_messages %}{% set content = '<|start_header_id|>' + message['role']... | {
"auto_model": "AutoModelForCausalLM",
"custom_class": null,
"pipeline_tag": "text-generation",
"processor": "AutoTokenizer"
} | {"base_model": "meta-llama/Meta-Llama-3-70B-Instruct", "datasets": null, "eval_results": null, "language": ["en"], "library_name": null, "license": "llama3", "license_name": null, "license_link": "https://llama.meta.com/llama3/license/", "metrics": null, "model_name": null, "pipeline_tag": "text-generation", "tags": nu... | null | null | [
"llama3",
"https://llama.meta.com/llama3/license/"
] | null | [
"en"
] | 70,553,706,496 | null | null | [
"AutoModelForCausalLM",
"llama",
"LlamaForCausalLM"
] | [
"text-generation"
] | [
"text"
] | [
"text"
] | [
"text"
] |
63c132871584c1120fe93c44 | 6a0d990b55988dc9 | ad4b234fa1a3ca7b | 31,102 | WordPiece | null | true | true | true | true | 5 | BertNormalizer | BertPreTokenizer | WordPiece | [
"BertNormalizer"
] | [
"BertPreTokenizer"
] | [
"WordPiece"
] | 461 | deutsche-telekom/gbert-large-paraphrase-cosine | deutsche-telekom | {
"models": [
{
"_id": "621ffdc136468d709f17a5f1",
"id": "deepset/gbert-large"
}
],
"relation": "finetune"
} | 7,789 | 607,963 | False | 2023-01-13T10:29:27Z | 2024-08-24T05:57:14Z | sentence-transformers | 25 | 0 | null | sentence-similarity | null | [
".gitattributes",
"1_Pooling/config.json",
"LICENSE",
"README.md",
"config.json",
"config_sentence_transformers.json",
"modules.json",
"pytorch_model.bin",
"sentence_bert_config.json",
"special_tokens_map.json",
"tokenizer.json",
"tokenizer_config.json",
"vocab.txt"
] | 53404af70384dccbb7072113a027d26566142f91 | [
"sentence-transformers",
"pytorch",
"bert",
"feature-extraction",
"sentence-similarity",
"transformers",
"setfit",
"de",
"dataset:deutsche-telekom/ger-backtrans-paraphrase",
"base_model:deepset/gbert-large",
"base_model:finetune:deepset/gbert-large",
"license:mit",
"text-embeddings-inference... | null | {"architectures": ["BertModel"], "model_type": "bert", "tokenizer_config": {"cls_token": "[CLS]", "mask_token": "[MASK]", "pad_token": "[PAD]", "sep_token": "[SEP]", "unk_token": "[UNK]"}} | {
"auto_model": "AutoModel",
"custom_class": null,
"pipeline_tag": "feature-extraction",
"processor": "AutoTokenizer"
} | {"base_model": "deepset/gbert-large", "datasets": ["deutsche-telekom/ger-backtrans-paraphrase"], "eval_results": null, "language": ["de"], "library_name": null, "license": "mit", "license_name": null, "license_link": null, "metrics": null, "model_name": null, "pipeline_tag": "sentence-similarity", "tags": ["sentence-tr... | # German BERT large paraphrase cosine
This is a [sentence-transformers](https://www.SBERT.net) model.
It maps sentences & paragraphs (text) into a 1024 dimensional dense vector space.
The model is intended to be used together with [SetFit](https://github.com/huggingface/setfit)
to improve German few-shot text classific... | null | [
"mit"
] | [
"deutsche-telekom/ger-backtrans-paraphrase"
] | [
"de"
] | null | null | null | [
"BertModel",
"AutoModel",
"bert"
] | [
"sentence-similarity",
"feature-extraction"
] | [
"text",
"multimodal"
] | [
"text"
] | [
"logits",
"embeddings"
] |
6376059985ebb45d0453e462 | 6a0d990b55988dc9 | ad4b234fa1a3ca7b | 31,102 | WordPiece | null | true | true | true | true | 5 | BertNormalizer | BertPreTokenizer | WordPiece | [
"BertNormalizer"
] | [
"BertPreTokenizer"
] | [
"WordPiece"
] | 461 | aari1995/German_Semantic_STS_V2 | aari1995 | null | 77,519 | 780,258 | False | 2022-11-17T09:57:45Z | 2024-07-09T09:36:25Z | sentence-transformers | 48 | 0 | [{"name": "German_Semantic_STS_V2", "results": [{"dataset": {"config": "de", "name": "MTEB AmazonCounterfactualClassification", "revision": "e8379541af4e31359cca9fbcf4b00f2671dba205", "split": "test", "type": "mteb/amazon_counterfactual"}, "metrics": [{"type": "accuracy", "value": 67.00214132762312, "verified": false}]... | sentence-similarity | {"parameters": {"I64": 512, "F32": 335735808}, "total": 335736320} | [
".gitattributes",
"1_Pooling/config.json",
"README.md",
"config.json",
"model.safetensors",
"pytorch_model.bin",
"special_tokens_map.json",
"tokenizer.json",
"tokenizer_config.json",
"vocab.txt"
] | 22912542b0ec7a7ef369837e28ffe6352a27afc9 | [
"sentence-transformers",
"pytorch",
"safetensors",
"bert",
"feature-extraction",
"gBERT-large",
"sentence-similarity",
"transformers",
"RAG",
"retrieval augmented generation",
"STS",
"MTEB",
"mteb",
"de",
"dataset:stsb_multi_mt",
"model-index",
"text-embeddings-inference",
"endpoin... | null | {"architectures": ["BertModel"], "model_type": "bert", "tokenizer_config": {"cls_token": "[CLS]", "mask_token": "[MASK]", "pad_token": "[PAD]", "sep_token": "[SEP]", "unk_token": "[UNK]"}} | {
"auto_model": "AutoModel",
"custom_class": null,
"pipeline_tag": "feature-extraction",
"processor": "AutoTokenizer"
} | {"datasets": ["stsb_multi_mt"], "language": ["de"], "pipeline_tag": "sentence-similarity", "tags": ["gBERT-large", "sentence-transformers", "feature-extraction", "sentence-similarity", "transformers", "RAG", "retrieval augmented generation", "STS", "MTEB", "mteb"], "model-index": [{"name": "German_Semantic_STS_V2", "re... | # German_Semantic_STS_V2
**Note:** Check out my new, updated models: [German_Semantic_V3](https://huggingface.co/aari1995/German_Semantic_V3) and [V3b](https://huggingface.co/aari1995/German_Semantic_V3b)!
This model creates german embeddings for semantic use cases.
This is a [sentence-transformers](https://www.SBER... | null | null | [
"stsb_multi_mt"
] | [
"de"
] | 335,736,320 | null | null | [
"BertModel",
"AutoModel",
"bert"
] | [
"sentence-similarity",
"feature-extraction"
] | [
"text",
"multimodal"
] | [
"text"
] | [
"logits",
"embeddings"
] |
Subsets and Splits
No community queries yet
The top public SQL queries from the community will appear here once available.