
_id large_stringlengths 24 24 | hash large_stringlengths 16 16 | vocab_hash large_stringlengths 16 16 | vocab_size int64 1 2.4M | model_type large_stringclasses 4
values | num_merges float64 0 4.41M ⌀ | has_normalizer bool 2
classes | has_pre_tokenizer bool 2
classes | has_post_processor bool 2
classes | has_decoder bool 2
classes | num_added_tokens int64 0 479k | normalizer_type large_stringclasses 11
values | pre_tokenizer_type large_stringclasses 10
values | decoder_type large_stringclasses 9
values | normalizer_types listlengths 0 11.3k ⌀ | pre_tokenizer_types listlengths 1 35 ⌀ | decoder_types listlengths 0 24 ⌀ | tokenizer_id int64 0 24.8k | id large_stringlengths 7 122 | author stringlengths 2 41 ⌀ | base_models dict | downloads int64 0 206M | downloads_all_time int64 0 2.81B | gated stringclasses 3
values | created_at timestamp[us, tz=UTC]date 2022-03-02 23:29:04 2025-11-03 14:41:54 | last_modified timestamp[us, tz=UTC]date 2020-12-11 21:34:15 2026-03-29 10:14:05 ⌀ | library_name stringclasses 36
values | likes int64 0 13.1k | trending_score float64 0 47 | model_index stringlengths 30 911k ⌀ | pipeline_tag stringclasses 46
values | safetensors stringlengths 30 122 ⌀ | siblings listlengths 0 10k ⌀ | sha stringlengths 40 40 ⌀ | tags listlengths 2 1.82k ⌀ | gguf stringclasses 789
values | config stringlengths 2 53.7k ⌀ | transformers_info dict | card_data stringlengths 234 905k ⌀ | card stringlengths 0 638k ⌀ | spaces null | licenses listlengths 1 3 ⌀ | datasets listlengths 1 289 ⌀ | languages listlengths 1 1.81k ⌀ | safetensors_params float64 0 1,019B ⌀ | gguf_params float64 0 122B ⌀ | metrics listlengths 1 15 ⌀ | architectures listlengths 1 6 ⌀ | tasks listlengths 1 6 ⌀ | modalities listlengths 1 4 ⌀ | input_modalities listlengths 1 3 ⌀ | output_modalities listlengths 1 4 ⌀ |
|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|
66bcf58ab8a029b4fdc1a4e3 | cb3f886e13ad7505 | 1f1d26e73b02d1f3 | 49,152 | BPE | 48,891 | false | true | false | true | 19 | null | Sequence | ByteLevel | null | [
"Digits",
"ByteLevel"
] | [
"ByteLevel"
] | 70 | ibm-research/PowerLM-3b | ibm-research | null | 46,760 | 378,715 | False | 2024-08-14T18:20:58Z | 2024-09-16T15:00:42Z | transformers | 20 | 0 | [{"name": "ibm/PowerLM-3b", "results": [{"task": {"type": "text-generation"}, "dataset": {"type": "lm-eval-harness", "name": "ARC"}, "metrics": [{"name": "accuracy-norm", "type": "accuracy-norm", "value": 60.5, "verified": false}]}, {"task": {"type": "text-generation"}, "dataset": {"type": "lm-eval-harness", "name": "B... | text-generation | {"parameters": {"F32": 3512017152}, "total": 3512017152} | [
".gitattributes",
"README.md",
"config.json",
"generation_config.json",
"model-00001-of-00003.safetensors",
"model-00002-of-00003.safetensors",
"model-00003-of-00003.safetensors",
"model.safetensors.index.json",
"special_tokens_map.json",
"tokenizer.json",
"tokenizer_config.json"
] | 38a624db4c8c9dd15d8bfb51845b7b177348e104 | [
"transformers",
"safetensors",
"granite",
"text-generation",
"arxiv:2408.13359",
"license:apache-2.0",
"model-index",
"region:us"
] | null | {"architectures": ["GraniteForCausalLM"], "model_type": "granite", "tokenizer_config": {"bos_token": "<|endoftext|>", "eos_token": "<|endoftext|>", "pad_token": "<|endoftext|>", "unk_token": "<|endoftext|>"}} | {
"auto_model": "AutoModelForCausalLM",
"custom_class": null,
"pipeline_tag": "text-generation",
"processor": "AutoTokenizer"
} | {"library_name": "transformers", "license": "apache-2.0", "pipeline_tag": "text-generation", "inference": false, "model-index": [{"name": "ibm/PowerLM-3b", "results": [{"task": {"type": "text-generation"}, "dataset": {"name": "ARC", "type": "lm-eval-harness"}, "metrics": [{"type": "accuracy-norm", "value": 60.5, "name"... | ## Model Summary
PowerLM-3B is a 3B state-of-the-art small language model trained with the Power learning rate scheduler. It is trained on a mix of open-source and proprietary datasets. PowerLM-3B has shown promising results compared to other models in the size categories across various benchmarks, including natural la... | null | [
"apache-2.0"
] | null | null | 3,512,017,152 | null | null | [
"granite",
"AutoModelForCausalLM",
"GraniteForCausalLM"
] | [
"text-generation"
] | [
"text"
] | [
"text"
] | [
"text"
] |
6865b2bcb1338375bf6e90f6 | 723eef7ebaf1fd48 | 1bfcef7328ad19e6 | 102,400 | BPE | 102,103 | false | true | true | true | 41 | null | ByteLevel | ByteLevel | null | [
"ByteLevel"
] | [
"ByteLevel"
] | 672 | skt/A.X-4.0-Light | skt | null | 12,170 | 297,289 | False | 2025-07-02T22:29:16Z | 2025-07-23T11:38:23Z | transformers | 110 | 0 | [{"name": "A.X-4.0-Light", "results": [{"task": {"type": "generate_until", "name": "mmlu"}, "dataset": {"name": "mmlu (chat CoT)", "type": "hails/mmlu_no_train"}, "metrics": [{"type": "exact_match", "value": 75.43, "name": "exact_match", "verified": false}]}, {"task": {"type": "generate_until", "name": "kmmlu"}, "datas... | text-generation | {"parameters": {"BF16": 7259624960}, "total": 7259624960} | [
".gitattributes",
"LICENSE",
"README.md",
"assets/A.X_logo.png",
"assets/A.X_logo_ko_4x3.png",
"config.json",
"generation_config.json",
"merges.txt",
"model-00001-of-00003.safetensors",
"model-00002-of-00003.safetensors",
"model-00003-of-00003.safetensors",
"model.safetensors.index.json",
"s... | ba21c20ea1b31ded1ec3e2fb432335077dc4be98 | [
"transformers",
"safetensors",
"qwen2",
"text-generation",
"conversational",
"en",
"ko",
"license:apache-2.0",
"model-index",
"text-generation-inference",
"endpoints_compatible",
"region:us"
] | null | {"architectures": ["Qwen2ForCausalLM"], "model_type": "qwen2", "tokenizer_config": {"bos_token": "<|endoftext|>", "chat_template": "{%- if tools is iterable and tools | length > 0 %}\n {{- '<|im_start|><|system|>'}}\n {{- '\ub2f9\uc2e0\uc740 \ub3c4\uad6c \ud638\ucd9c \uae30\ub2a5\u... | {
"auto_model": "AutoModelForCausalLM",
"custom_class": null,
"pipeline_tag": "text-generation",
"processor": "AutoTokenizer"
} | {"language": ["en", "ko"], "library_name": "transformers", "license": "apache-2.0", "license_link": "https://huggingface.co/skt/A.X-4.0-Light/blob/main/LICENSE", "pipeline_tag": "text-generation", "model_id": "skt/A.X-4.0-Light", "developers": "SKT AI Model Lab", "model-index": [{"name": "A.X-4.0-Light", "results": [{"... | null | null | [
"apache-2.0",
"https://huggingface.co/skt/A.X-4.0-Light/blob/main/LICENSE"
] | null | [
"en",
"ko"
] | 7,259,624,960 | null | null | [
"AutoModelForCausalLM",
"Qwen2ForCausalLM",
"qwen2"
] | [
"text-generation"
] | [
"text"
] | [
"text"
] | [
"text"
] |
662fda402f9858ac470512ae | 803e3c8528c55bf1 | a1f1bd381dcb9329 | 128,256 | BPE | 280,147 | false | true | true | true | 256 | null | Sequence | ByteLevel | null | [
"Split",
"ByteLevel"
] | [
"ByteLevel"
] | 352 | Danielbrdz/Barcenas-Llama3-8b-ORPO | Danielbrdz | null | 13,465 | 295,651 | False | 2024-04-29T17:34:56Z | 2024-04-29T18:22:57Z | transformers | 7 | 0 | null | text-generation | {"parameters": {"F16": 8030261248}, "total": 8030261248} | [
".gitattributes",
"LICENSE",
"README.md",
"config.json",
"generation_config.json",
"model-00001-of-00004.safetensors",
"model-00002-of-00004.safetensors",
"model-00003-of-00004.safetensors",
"model-00004-of-00004.safetensors",
"model.safetensors.index.json",
"special_tokens_map.json",
"tokeniz... | 66c848c4526d3db1ec41468c0f73ac4448c6abe9 | [
"transformers",
"safetensors",
"llama",
"text-generation",
"ORPO",
"conversational",
"en",
"license:other",
"text-generation-inference",
"endpoints_compatible",
"deploy:azure",
"region:us"
] | null | {"architectures": ["LlamaForCausalLM"], "model_type": "llama", "tokenizer_config": {"bos_token": "<|begin_of_text|>", "chat_template": "{% set loop_messages = messages %}{% for message in loop_messages %}{% set content = '<|start_header_id|>' + message['role'] + '<|end_header_id|>\n\n'+ message['content'] | trim + '<|e... | {
"auto_model": "AutoModelForCausalLM",
"custom_class": null,
"pipeline_tag": "text-generation",
"processor": "AutoTokenizer"
} | {"base_model": null, "datasets": null, "eval_results": null, "language": ["en"], "library_name": null, "license": "other", "license_name": "llama3", "license_link": "LICENSE", "metrics": null, "model_name": null, "pipeline_tag": null, "tags": ["llama", "ORPO"]} | Barcenas Llama3 8b ORPO
Model trained with the novel new ORPO method, based on the recent Llama 3 8b, specifically: VAGOsolutions/Llama-3-SauerkrautLM-8b-Instruct
The model was trained with the dataset: reciperesearch/dolphin-sft-v0.1-preference which uses Dolphin data with GPT 4 to improve its conversation sections.... | null | [
"other",
"llama3",
"LICENSE"
] | null | [
"en"
] | 8,030,261,248 | null | null | [
"AutoModelForCausalLM",
"llama",
"LlamaForCausalLM"
] | [
"text-generation"
] | [
"text"
] | [
"text"
] | [
"text"
] |
66388c6cd3cfa9306c25a07d | 39b1e434a495263c | a1f1bd381dcb9329 | 128,256 | BPE | 280,147 | false | true | true | true | 256 | null | Sequence | ByteLevel | null | [
"Split",
"ByteLevel"
] | [
"ByteLevel"
] | 349 | TIGER-Lab/MAmmoTH2-8B-Plus | TIGER-Lab | null | 12,110 | 290,588 | False | 2024-05-06T07:53:16Z | 2024-05-22T03:11:32Z | transformers | 22 | 0 | null | text-generation | {"parameters": {"BF16": 8030261248}, "total": 8030261248} | [
".gitattributes",
"README.md",
"config.json",
"generation_config.json",
"model-00001-of-00004.safetensors",
"model-00002-of-00004.safetensors",
"model-00003-of-00004.safetensors",
"model-00004-of-00004.safetensors",
"model.safetensors.index.json",
"special_tokens_map.json",
"tokenizer.json",
"... | 4d5aebd54a39563e3ae464836f6316d3e7b51cc4 | [
"transformers",
"safetensors",
"llama",
"text-generation",
"conversational",
"en",
"dataset:TIGER-Lab/WebInstructSub",
"arxiv:2405.03548",
"license:mit",
"text-generation-inference",
"endpoints_compatible",
"deploy:azure",
"region:us"
] | null | {"architectures": ["LlamaForCausalLM"], "model_type": "llama", "tokenizer_config": {"bos_token": "<|begin_of_text|>", "chat_template": "{% set system_message = 'You are a helpful assistant.' %}{% if messages[0]['role'] == 'system' %}{% set system_message = messages[0]['content'] %}{% endif %}{% if system_message is def... | {
"auto_model": "AutoModelForCausalLM",
"custom_class": null,
"pipeline_tag": "text-generation",
"processor": "AutoTokenizer"
} | {"base_model": null, "datasets": ["TIGER-Lab/WebInstructSub"], "eval_results": null, "language": ["en"], "library_name": "transformers", "license": "mit", "license_name": null, "license_link": null, "metrics": ["accuracy"], "model_name": null, "pipeline_tag": null, "tags": null} | # 🦣 MAmmoTH2: Scaling Instructions from the Web
Project Page: [https://tiger-ai-lab.github.io/MAmmoTH2/](https://tiger-ai-lab.github.io/MAmmoTH2/)
Paper: [https://arxiv.org/pdf/2405.03548](https://arxiv.org/pdf/2405.03548)
Code: [https://github.com/TIGER-AI-Lab/MAmmoTH2](https://github.com/TIGER-AI-Lab/MAmmoTH2)
... | null | [
"mit"
] | [
"TIGER-Lab/WebInstructSub"
] | [
"en"
] | 8,030,261,248 | null | [
"accuracy"
] | [
"AutoModelForCausalLM",
"llama",
"LlamaForCausalLM"
] | [
"text-generation"
] | [
"text"
] | [
"text"
] | [
"text"
] |
67feb243ee2f129010bf56d1 | 46323c0f61df476d | 1fe366e13272caa0 | 262,145 | BPE | 514,906 | true | true | true | true | 6,415 | Replace | Split | Sequence | [
"Replace"
] | [
"Split"
] | [
"Replace",
"ByteFallback",
"Fuse"
] | 49 | mlx-community/gemma-3-1b-it-qat-4bit | mlx-community | {
"models": [
{
"_id": "67ced65c9b9a3df71008da90",
"id": "google/gemma-3-1b-it"
}
],
"relation": "quantized"
} | 57,253 | 414,849 | False | 2025-04-15T19:23:47Z | 2025-04-18T15:50:31Z | transformers | 4 | 0 | null | text-generation | null | [
".gitattributes",
"README.md",
"added_tokens.json",
"config.json",
"model.safetensors",
"model.safetensors.index.json",
"special_tokens_map.json",
"tokenizer.json",
"tokenizer.model",
"tokenizer_config.json"
] | 15fed4eafb456c6fcb2a1165f19ac609670ed14b | [
"transformers",
"safetensors",
"gemma3_text",
"text-generation",
"mlx",
"conversational",
"base_model:google/gemma-3-1b-it",
"base_model:quantized:google/gemma-3-1b-it",
"license:gemma",
"text-generation-inference",
"endpoints_compatible",
"4-bit",
"region:us"
] | null | {"architectures": ["Gemma3ForCausalLM"], "model_type": "gemma3_text", "quantization_config": {"bits": 4}, "tokenizer_config": {"bos_token": "<bos>", "chat_template": "{{ bos_token }}\n{%- if messages[0]['role'] == 'system' -%}\n {%- if messages[0]['content'] is string -%}\n {%- set first_user_prefix = message... | {
"auto_model": "AutoModelForCausalLM",
"custom_class": null,
"pipeline_tag": "text-generation",
"processor": "AutoTokenizer"
} | {"base_model": "google/gemma-3-1b-it", "datasets": null, "eval_results": null, "language": null, "library_name": "transformers", "license": "gemma", "license_name": null, "license_link": null, "metrics": null, "model_name": null, "pipeline_tag": "text-generation", "tags": ["mlx"], "extra_gated_heading": "Access Gemma o... | null | null | [
"gemma"
] | null | null | null | null | null | [
"gemma3_text",
"AutoModelForCausalLM",
"Gemma3ForCausalLM"
] | [
"text-generation"
] | [
"text"
] | [
"text"
] | [
"text"
] |
680f9de987f2627834576d11 | e250e889476a9bb0 | 61a9556e8a833705 | 49,160 | BPE | 48,891 | false | true | true | true | 27 | null | ByteLevel | ByteLevel | null | [
"ByteLevel"
] | [
"ByteLevel"
] | 673 | ibm-granite/granite-speech-3.3-2b | ibm-granite | {
"models": [
{
"_id": "67f65cc77168f9524be92e01",
"id": "ibm-granite/granite-3.3-2b-instruct"
}
],
"relation": "finetune"
} | 204,171 | 902,073 | False | 2025-04-28T15:25:29Z | 2025-08-19T14:14:22Z | transformers | 50 | 1 | null | automatic-speech-recognition | {"parameters": {"BF16": 3009285376}, "total": 3009285376} | [
".gitattributes",
"10226_10111_000000.wav",
"README.md",
"adapter_config.json",
"adapter_model.safetensors",
"added_tokens.json",
"chat_template.jinja",
"config.json",
"generation_config.json",
"merges.txt",
"model-00001-of-00003.safetensors",
"model-00001-of-00004.safetensors",
"model-00002... | 7c638eb1951f8afe3b30766e96ef07fa71f18b20 | [
"transformers",
"safetensors",
"granite_speech",
"automatic-speech-recognition",
"multilingual",
"en",
"fr",
"de",
"es",
"pt",
"arxiv:2505.08699",
"base_model:ibm-granite/granite-3.3-2b-instruct",
"base_model:finetune:ibm-granite/granite-3.3-2b-instruct",
"license:apache-2.0",
"endpoints... | null | {"architectures": ["GraniteSpeechForConditionalGeneration"], "model_type": "granite_speech", "tokenizer_config": {"bos_token": "<|end_of_text|>", "eos_token": "<|end_of_text|>", "pad_token": "<|end_of_text|>", "unk_token": "<|end_of_text|>"}, "chat_template_jinja": "{# Alias tools -> available_tools #}\n{%- if tools an... | {
"auto_model": "AutoModelForSpeechSeq2Seq",
"custom_class": null,
"pipeline_tag": "automatic-speech-recognition",
"processor": "AutoProcessor"
} | {"base_model": ["ibm-granite/granite-3.3-2b-instruct"], "datasets": null, "eval_results": null, "language": ["multilingual", "en", "fr", "de", "es", "pt"], "library_name": "transformers", "license": "apache-2.0", "license_name": null, "license_link": null, "metrics": null, "model_name": null, "pipeline_tag": null, "tag... | # Granite-speech-3.3-2b (revision 3.3.2)
**Model Summary:**
Granite-speech-3.3-2b is a compact and efficient speech-language model, specifically designed for automatic speech recognition (ASR) and automatic speech translation (AST). Granite-speech-3.3-2b uses a two-pass design, unlike integrated models that combine sp... | null | [
"apache-2.0"
] | null | [
"multilingual",
"en",
"fr",
"de",
"es",
"pt"
] | 3,009,285,376 | null | null | [
"GraniteSpeechForConditionalGeneration",
"AutoModelForSpeechSeq2Seq",
"granite_speech"
] | [
"automatic-speech-recognition"
] | [
"multimodal"
] | [
"audio"
] | [
"text"
] |
687806cd4be53e1430e2e6da | b3310d158ab6e0dc | 66be3297e0980489 | 28,895 | WordPiece | null | true | true | true | true | 5 | BertNormalizer | BertPreTokenizer | WordPiece | [
"BertNormalizer"
] | [
"BertPreTokenizer"
] | [
"WordPiece"
] | 409 | OpenMed/OpenMed-NER-AnatomyDetect-PubMed-335M | OpenMed | null | 93,696 | 618,198 | False | 2025-07-16T20:08:45Z | 2025-08-05T09:38:35Z | transformers | 2 | 0 | null | token-classification | {"parameters": {"BF16": 334095363}, "total": 334095363} | [
".gitattributes",
"README.md",
"config.json",
"model.safetensors",
"openmed_vs_sota_grouped_bars.png",
"special_tokens_map.json",
"test_results.json",
"tokenizer.json",
"tokenizer_config.json",
"vocab.txt"
] | 34e40f30c8b1985ffb019bbc32cfe80cd2af1652 | [
"transformers",
"safetensors",
"bert",
"token-classification",
"named-entity-recognition",
"biomedical-nlp",
"anatomical-entity-recognition",
"medical-terminology",
"anatomy",
"healthcare",
"en",
"arxiv:2508.01630",
"license:apache-2.0",
"endpoints_compatible",
"region:us"
] | null | {"architectures": ["BertForTokenClassification"], "model_type": "bert", "tokenizer_config": {"cls_token": "[CLS]", "mask_token": "[MASK]", "pad_token": "[PAD]", "sep_token": "[SEP]", "unk_token": "[UNK]"}} | {
"auto_model": "AutoModelForTokenClassification",
"custom_class": null,
"pipeline_tag": "token-classification",
"processor": "AutoTokenizer"
} | {"base_model": null, "datasets": null, "eval_results": null, "language": ["en"], "library_name": null, "license": "apache-2.0", "license_name": null, "license_link": null, "metrics": null, "model_name": null, "pipeline_tag": null, "tags": ["token-classification", "named-entity-recognition", "biomedical-nlp", "transform... | null | null | [
"apache-2.0"
] | null | [
"en"
] | 334,095,363 | null | null | [
"AutoModelForTokenClassification",
"BertForTokenClassification",
"bert"
] | [
"token-classification"
] | [
"text"
] | [
"text"
] | [
"logits"
] |
681cc6e6185a31e860145a21 | 848b60b6cd304b65 | ffc911e785abe60e | 151,665 | BPE | 151,387 | true | true | true | true | 22 | NFC | Sequence | ByteLevel | [
"NFC"
] | [
"Split",
"ByteLevel"
] | [
"ByteLevel"
] | 15 | BCCard/Qwen2.5-VL-32B-Instruct-FP8-Dynamic | BCCard | {
"models": [
{
"_id": "67dd8463d7019776f5fc5b23",
"id": "Qwen/Qwen2.5-VL-32B-Instruct"
}
],
"relation": "quantized"
} | 101 | 235,359 | False | 2025-05-08T14:59:50Z | 2025-06-20T07:45:43Z | transformers | 5 | 0 | null | image-text-to-text | {"parameters": {"BF16": 1565368576, "F8_E4M3": 31892439040}, "total": 33457807616} | [
".gitattributes",
"README.md",
"added_tokens.json",
"chat_template.json",
"config.json",
"generation_config.json",
"merges.txt",
"model-00001-of-00008.safetensors",
"model-00002-of-00008.safetensors",
"model-00003-of-00008.safetensors",
"model-00004-of-00008.safetensors",
"model-00005-of-00008... | a3dcd69923e5db0bf288bb9614b281696ce35af6 | [
"transformers",
"safetensors",
"qwen2_5_vl",
"image-text-to-text",
"vllm",
"vision",
"fp8",
"conversational",
"en",
"base_model:Qwen/Qwen2.5-VL-32B-Instruct",
"base_model:quantized:Qwen/Qwen2.5-VL-32B-Instruct",
"license:apache-2.0",
"text-generation-inference",
"endpoints_compatible",
"... | null | {"architectures": ["Qwen2_5_VLForConditionalGeneration"], "model_type": "qwen2_5_vl", "quantization_config": {"quant_method": "compressed-tensors"}, "processor_config": {"chat_template": "{% set image_count = namespace(value=0) %}{% set video_count = namespace(value=0) %}{% for message in messages %}{% if loop.first an... | {
"auto_model": "AutoModelForImageTextToText",
"custom_class": null,
"pipeline_tag": "image-text-to-text",
"processor": "AutoProcessor"
} | {"base_model": "Qwen/Qwen2.5-VL-32B-Instruct", "datasets": null, "eval_results": null, "language": ["en"], "library_name": "transformers", "license": "apache-2.0", "license_name": null, "license_link": "https://huggingface.co/datasets/choosealicense/licenses/blob/main/markdown/apache-2.0.md", "metrics": null, "model_na... | # Qwen2.5-VL-32B-Instruct-FP8-Dynamic
## Model Overview
- **Model Architecture:** Qwen2.5-VL-32B-Instruct
- **Input:** Vision-Text
- **Output:** Text
- **Model Optimizations:**
- **Weight quantization:** FP8
- **Activation quantization:** FP8
- **Release Date:** 5/3/2025
- **Version:** 1.0
- **Model Developers... | null | [
"apache-2.0",
"https://huggingface.co/datasets/choosealicense/licenses/blob/main/markdown/apache-2.0.md"
] | null | [
"en"
] | 33,457,807,616 | null | null | [
"qwen2_5_vl",
"AutoModelForImageTextToText",
"Qwen2_5_VLForConditionalGeneration"
] | [
"image-text-to-text"
] | [
"multimodal"
] | [
"text",
"image"
] | [
"text"
] |
669df33d811696bba8166ff3 | 21feada71fab2765 | 12ebeebff692ebb1 | 131,072 | BPE | 269,443 | false | true | true | true | 1,000 | null | Sequence | ByteLevel | null | [
"Split",
"ByteLevel"
] | [
"ByteLevel"
] | 245 | VAGOsolutions/SauerkrautLM-Nemo-12b-Instruct | VAGOsolutions | null | 41,595 | 284,290 | False | 2024-07-22T05:50:53Z | 2024-07-22T06:04:49Z | transformers | 22 | 0 | null | text-generation | {"parameters": {"BF16": 12247782400}, "total": 12247782400} | [
".gitattributes",
"README.md",
"config.json",
"model-00001-of-00005.safetensors",
"model-00002-of-00005.safetensors",
"model-00003-of-00005.safetensors",
"model-00004-of-00005.safetensors",
"model-00005-of-00005.safetensors",
"model.safetensors.index.json",
"special_tokens_map.json",
"tokenizer.... | fcb056465084ab2c71503a0760f46e4be79c985c | [
"transformers",
"safetensors",
"mistral",
"text-generation",
"spectrum",
"conversational",
"de",
"en",
"it",
"fr",
"pt",
"nl",
"ru",
"ar",
"es",
"license:apache-2.0",
"text-generation-inference",
"endpoints_compatible",
"deploy:azure",
"region:us"
] | null | {"architectures": ["MistralForCausalLM"], "model_type": "mistral", "tokenizer_config": {"bos_token": "<s>", "chat_template": "{%- if messages[0]['role'] == 'system' %}\n {%- set system_message = messages[0]['content'] %}\n {%- set loop_messages = messages[1:] %}\n{%- else %}\n {%- set loop_messages = messages ... | {
"auto_model": "AutoModelForCausalLM",
"custom_class": null,
"pipeline_tag": "text-generation",
"processor": "AutoTokenizer"
} | {"base_model": null, "datasets": null, "eval_results": null, "language": ["de", "en", "it", "fr", "pt", "nl", "ru", "ar", "es"], "library_name": null, "license": "apache-2.0", "license_name": null, "license_link": null, "metrics": null, "model_name": null, "pipeline_tag": null, "tags": ["spectrum"]} | 
## VAGO solutions SauerkrautLM-Nemo-12b-Instruct
**Fine-tuned Model** - *to showcase the potential of resource-efficient Fine-Tuning of Large Language Models using **Spectrum Fi... | null | [
"apache-2.0"
] | null | [
"de",
"en",
"it",
"fr",
"pt",
"nl",
"ru",
"ar",
"es"
] | 12,247,782,400 | null | null | [
"AutoModelForCausalLM",
"mistral",
"MistralForCausalLM"
] | [
"text-generation"
] | [
"text"
] | [
"text"
] | [
"text"
] |
6515419971c52d030af9730b | e68b0b111c49dac2 | dd84a2b1ff97657d | 250,002 | Unigram | null | true | true | true | true | 5 | Precompiled | Sequence | Metaspace | [
"Precompiled"
] | [
"WhitespaceSplit",
"Metaspace"
] | [
"Metaspace"
] | 28 | manifesto-project/manifestoberta-xlm-roberta-56policy-topics-sentence-2023-1-1 | manifesto-project | null | 243 | 231,863 | False | 2023-09-28T09:04:25Z | 2024-11-13T13:30:23Z | transformers | 4 | 0 | null | text-classification | {"parameters": {"I64": 514, "F32": 559947832}, "total": 559948346} | [
".gitattributes",
"README.md",
"config.json",
"model.safetensors",
"pytorch_model.bin",
"special_tokens_map.json",
"tokenizer.json",
"tokenizer_config.json",
"training_args.bin"
] | 9a0fbb32b8e838a0f11d4649e675683a09833b26 | [
"transformers",
"pytorch",
"safetensors",
"xlm-roberta",
"text-classification",
"license:bigscience-openrail-m",
"text-embeddings-inference",
"endpoints_compatible",
"region:us"
] | null | {"architectures": ["XLMRobertaForSequenceClassification"], "model_type": "xlm-roberta", "tokenizer_config": {"bos_token": "<s>", "cls_token": "<s>", "eos_token": "</s>", "mask_token": {"__type": "AddedToken", "content": "<mask>", "lstrip": true, "normalized": true, "rstrip": false, "single_word": false}, "pad_token": "... | {
"auto_model": "AutoModelForSequenceClassification",
"custom_class": null,
"pipeline_tag": "text-classification",
"processor": "AutoTokenizer"
} | {"base_model": null, "datasets": null, "eval_results": null, "language": null, "library_name": null, "license": "bigscience-openrail-m", "license_name": null, "license_link": null, "metrics": null, "model_name": null, "pipeline_tag": null, "tags": null, "widget": [{"text": "We will restore funding to the Global Environ... | ## Model description
An xlm-roberta-large model fine-tuned on ~1,6 million annotated statements contained in the [Manifesto Corpus](https://manifesto-project.wzb.eu/information/documents/corpus) (version 2023a).
The model can be used to categorize any type of text into 56 different political topics according to the Ma... | null | [
"bigscience-openrail-m"
] | null | null | 559,948,346 | null | null | [
"AutoModelForSequenceClassification",
"XLMRobertaForSequenceClassification",
"xlm-roberta"
] | [
"text-classification"
] | [
"text"
] | [
"text"
] | [
"logits"
] |
65c387c57da4638981605038 | 88cd37e502d27a0a | 0e7bc0977f200d1c | 32,000 | BPE | 58,980 | true | false | true | true | 3 | Sequence | null | Sequence | [
"Prepend",
"Replace"
] | null | [
"Replace",
"ByteFallback",
"Fuse",
"Strip"
] | 88 | Equall/Saul-7B-Instruct-v1 | Equall | null | 1,751 | 537,387 | False | 2024-02-07T13:38:13Z | 2024-03-10T12:39:32Z | transformers | 111 | 1 | null | text-generation | {"parameters": {"F32": 7241732096}, "total": 7241732096} | [
".gitattributes",
"README.md",
"config.json",
"generation_config.json",
"model-00001-of-00006.safetensors",
"model-00002-of-00006.safetensors",
"model-00003-of-00006.safetensors",
"model-00004-of-00006.safetensors",
"model-00005-of-00006.safetensors",
"model-00006-of-00006.safetensors",
"model.s... | 2133ba7923533934e78f73848045299dd74f08d2 | [
"transformers",
"safetensors",
"mistral",
"text-generation",
"legal",
"conversational",
"en",
"arxiv:2403.03883",
"license:mit",
"text-generation-inference",
"endpoints_compatible",
"deploy:azure",
"region:us"
] | null | {"architectures": ["MistralForCausalLM"], "model_type": "mistral", "tokenizer_config": {"bos_token": "<s>", "eos_token": "</s>", "pad_token": null, "unk_token": "<unk>", "use_default_system_prompt": false, "chat_template": "{{ bos_token }}{% for message in messages %}{% if (message['role'] == 'user') != (loop.index0 % ... | {
"auto_model": "AutoModelForCausalLM",
"custom_class": null,
"pipeline_tag": "text-generation",
"processor": "AutoTokenizer"
} | {"base_model": null, "datasets": null, "eval_results": null, "language": ["en"], "library_name": "transformers", "license": "mit", "license_name": null, "license_link": null, "metrics": null, "model_name": null, "pipeline_tag": null, "tags": ["legal"]} | # Equall/Saul-Instruct-v1
This is the instruct model for Equall/Saul-Instruct-v1, a large instruct language model tailored for Legal domain. This model is obtained by continue pretraining of Mistral-7B.
Checkout our website and register https://equall.ai/
", "config": "xl", "split": "validation", "revision": "a80f460359d1e9a67c006011c94de42a8759430c"}, "metrics": [{"type": "Accuracy", "value": 51.78, "verified": false}]}, {"task": ... | text-generation | {"parameters": {"F32": 1229581312}, "total": 1229581312} | [
".gitattributes",
"README.md",
"config.json",
"model.safetensors",
"onnx/config.json",
"onnx/decoder_model.onnx",
"onnx/decoder_model.onnx_data",
"onnx/decoder_model_merged.onnx",
"onnx/decoder_model_merged.onnx_data",
"onnx/decoder_with_past_model.onnx",
"onnx/decoder_with_past_model.onnx_data"... | c2cdb7dbabf83140e288e60f73a936ed9c5b9ed6 | [
"transformers",
"pytorch",
"onnx",
"safetensors",
"mt5",
"text2text-generation",
"af",
"am",
"ar",
"az",
"be",
"bg",
"bn",
"ca",
"ceb",
"co",
"cs",
"cy",
"da",
"de",
"el",
"en",
"eo",
"es",
"et",
"eu",
"fa",
"fi",
"fil",
"fr",
"fy",
"ga",
"gd",
"gl",... | null | {"architectures": ["MT5ForConditionalGeneration"], "model_type": "mt5", "tokenizer_config": {"eos_token": "</s>", "pad_token": "<pad>", "unk_token": "<unk>"}} | {
"auto_model": "AutoModelForSeq2SeqLM",
"custom_class": null,
"pipeline_tag": "text2text-generation",
"processor": "AutoTokenizer"
} | {"datasets": ["bigscience/xP3", "mc4"], "language": ["af", "am", "ar", "az", "be", "bg", "bn", "ca", "ceb", "co", "cs", "cy", "da", "de", "el", "en", "eo", "es", "et", "eu", "fa", "fi", "fil", "fr", "fy", "ga", "gd", "gl", "gu", "ha", "haw", "hi", "hmn", "ht", "hu", "hy", "ig", "is", "it", "iw", "ja", "jv", "ka", "kk",... | 
# Table of Contents
1. [Model Summary](#model-summary)
2. [Use](#use)
3. [Limitations](#limitations)
4. [Training](#training)
5. [Evaluation](#evaluation)
7. [Citation](#citation)
# Model Summary
> We present BLOOMZ & mT0, a ... | null | [
"apache-2.0"
] | [
"bigscience/xP3",
"mc4"
] | [
"af",
"am",
"ar",
"az",
"be",
"bg",
"bn",
"ca",
"ceb",
"co",
"cs",
"cy",
"da",
"de",
"el",
"en",
"eo",
"es",
"et",
"eu",
"fa",
"fi",
"fil",
"fr",
"fy",
"ga",
"gd",
"gl",
"gu",
"ha",
"haw",
"hi",
"hmn",
"ht",
"hu",
"hy",
"ig",
"is",
"it",
... | 1,229,581,312 | null | null | [
"mt5",
"MT5ForConditionalGeneration",
"AutoModelForSeq2SeqLM"
] | [
"text2text-generation",
"text-generation"
] | [
"text"
] | [
"text"
] | [
"text"
] |
66f583566d1a427c8c1523d1 | 5afd7d59d2aa5e01 | 535fa14da0af647c | 30,522 | WordPiece | null | true | true | true | true | 5 | BertNormalizer | BertPreTokenizer | WordPiece | [
"BertNormalizer"
] | [
"BertPreTokenizer"
] | [
"WordPiece"
] | 125 | sentence-transformers-testing/stsb-bert-tiny-openvino | sentence-transformers-testing | null | 10,024 | 279,387 | False | 2024-09-26T15:52:54Z | 2024-10-03T15:18:00Z | sentence-transformers | 0 | 0 | null | sentence-similarity | {"parameters": {"F32": 4385920}, "total": 4385920} | [
".gitattributes",
"1_Pooling/config.json",
"README.md",
"config.json",
"config_sentence_transformers.json",
"model.safetensors",
"modules.json",
"openvino/openvino_model.bin",
"openvino/openvino_model.xml",
"sentence_bert_config.json",
"special_tokens_map.json",
"tokenizer.json",
"tokenizer_... | 3ac17d14dbb69bbb977f26ad9d511a1883042bbb | [
"sentence-transformers",
"safetensors",
"openvino",
"bert",
"feature-extraction",
"sentence-similarity",
"transformers",
"text-embeddings-inference",
"endpoints_compatible",
"deploy:azure",
"region:us"
] | null | {"architectures": ["BertModel"], "model_type": "bert", "tokenizer_config": {"cls_token": "[CLS]", "mask_token": "[MASK]", "pad_token": "[PAD]", "sep_token": "[SEP]", "unk_token": "[UNK]"}} | {
"auto_model": "AutoModel",
"custom_class": null,
"pipeline_tag": "feature-extraction",
"processor": "AutoTokenizer"
} | {"base_model": null, "datasets": null, "eval_results": null, "language": null, "library_name": "sentence-transformers", "license": null, "license_name": null, "license_link": null, "metrics": null, "model_name": null, "pipeline_tag": "sentence-similarity", "tags": ["sentence-transformers", "feature-extraction", "senten... | # sentence-transformers-testing/stsb-bert-tiny-safetensors
This is a [sentence-transformers](https://www.SBERT.net) model: It maps sentences & paragraphs to a 128 dimensional dense vector space and can be used for tasks like clustering or semantic search.
<!--- Describe your model here -->
## Usage (Sentence-T... | null | null | null | null | 4,385,920 | null | null | [
"BertModel",
"AutoModel",
"bert"
] | [
"sentence-similarity",
"feature-extraction"
] | [
"text",
"multimodal"
] | [
"text"
] | [
"logits",
"embeddings"
] |
621ffdc136468d709f177625 | 820723d44f714bed | 70bd27c212bc339c | 50,265 | BPE | 50,000 | false | true | true | true | 5 | null | ByteLevel | ByteLevel | null | [
"ByteLevel"
] | [
"ByteLevel"
] | 73 | s-nlp/roberta-base-formality-ranker | s-nlp | null | 2,491 | 243,798 | False | 2022-03-02T23:29:05Z | 2023-09-08T08:44:43Z | transformers | 21 | 0 | null | text-classification | {"parameters": {"I64": 514, "F32": 124647170}, "total": 124647684} | [
".gitattributes",
"README.md",
"config.json",
"merges.txt",
"model.safetensors",
"pytorch_model.bin",
"special_tokens_map.json",
"tokenizer.json",
"tokenizer_config.json",
"vocab.json"
] | db9388f420a835ad49c45840adc9850a52240627 | [
"transformers",
"pytorch",
"safetensors",
"roberta",
"text-classification",
"formality",
"en",
"dataset:GYAFC",
"dataset:Pavlick-Tetreault-2016",
"license:cc-by-nc-sa-4.0",
"text-embeddings-inference",
"endpoints_compatible",
"deploy:azure",
"region:us"
] | null | {"architectures": ["RobertaForSequenceClassification"], "model_type": "roberta", "tokenizer_config": {"unk_token": "<unk>", "bos_token": "<s>", "eos_token": "</s>", "sep_token": "</s>", "cls_token": "<s>", "pad_token": "<pad>", "mask_token": "<mask>"}} | {
"auto_model": "AutoModelForSequenceClassification",
"custom_class": null,
"pipeline_tag": "text-classification",
"processor": "AutoTokenizer"
} | {"base_model": null, "datasets": ["GYAFC", "Pavlick-Tetreault-2016"], "eval_results": null, "language": ["en"], "library_name": null, "license": "cc-by-nc-sa-4.0", "license_name": null, "license_link": null, "metrics": null, "model_name": null, "pipeline_tag": null, "tags": ["formality"]} | The model has been trained to predict for English sentences, whether they are formal or informal.
Base model: `roberta-base`
Datasets: [GYAFC](https://github.com/raosudha89/GYAFC-corpus) from [Rao and Tetreault, 2018](https://aclanthology.org/N18-1012) and [online formality corpus](http://www.seas.upenn.edu/~nlp/res... | null | [
"cc-by-nc-sa-4.0"
] | [
"GYAFC",
"Pavlick-Tetreault-2016"
] | [
"en"
] | 124,647,684 | null | null | [
"roberta",
"AutoModelForSequenceClassification",
"RobertaForSequenceClassification"
] | [
"text-classification"
] | [
"text"
] | [
"text"
] | [
"logits"
] |
66d948889d69b5085396601d | 54895f2d8faef315 | e6ffdc5dd5f1fd86 | 256,000 | BPE | 580,604 | true | true | true | true | 249 | Replace | Split | Sequence | [
"Replace"
] | [
"Split"
] | [
"Replace",
"ByteFallback",
"Fuse"
] | 50 | Skywork/Skywork-Reward-Gemma-2-27B | Skywork | {
"models": [
{
"_id": "667928b020ff491d38a652ad",
"id": "google/gemma-2-27b-it"
}
],
"relation": "finetune"
} | 173 | 230,637 | False | 2024-09-05T05:58:32Z | 2024-10-25T01:22:13Z | transformers | 49 | 0 | null | text-classification | {"parameters": {"BF16": 27227132928}, "total": 27227132928} | [
".gitattributes",
"README.md",
"config.json",
"misc/Skywork Community License.pdf",
"misc/Skywork 模型社区许可协议.pdf",
"misc/fig.jpg",
"model-00001-of-00012.safetensors",
"model-00002-of-00012.safetensors",
"model-00003-of-00012.safetensors",
"model-00004-of-00012.safetensors",
"model-00005-of-00012.s... | 776a27d713bf95792c566921304e27ce62762850 | [
"transformers",
"safetensors",
"gemma2",
"text-classification",
"dataset:Skywork/Skywork-Reward-Preference-80K-v0.1",
"arxiv:2410.18451",
"base_model:google/gemma-2-27b-it",
"base_model:finetune:google/gemma-2-27b-it",
"endpoints_compatible",
"deploy:azure",
"region:us"
] | null | {"architectures": ["Gemma2ForSequenceClassification"], "model_type": "gemma2", "tokenizer_config": {"bos_token": "<bos>", "chat_template": "{% if messages[0]['role'] == 'system' %}{{ raise_exception('System role not supported') }}{% endif %}{% for message in messages %}{% if (message['role'] == 'user') != (loop.index0 ... | {
"auto_model": "AutoModelForSequenceClassification",
"custom_class": null,
"pipeline_tag": "text-classification",
"processor": "AutoTokenizer"
} | {"base_model": "google/gemma-2-27b-it", "datasets": ["Skywork/Skywork-Reward-Preference-80K-v0.1"], "eval_results": null, "language": null, "library_name": "transformers", "license": null, "license_name": null, "license_link": null, "metrics": null, "model_name": null, "pipeline_tag": "text-classification", "tags": nul... | <div align="center">
<img src="misc/fig.jpg" width="400"/>
🤗 <a href="https://huggingface.co/Skywork" target="_blank">Hugging Face</a> • 🤖 <a href="https://modelscope.cn/organization/Skywork" target="_blank">ModelScope</a>
<br>
<br>
<br>
</div>
# Skywork Reward Model Series
## Introduction
[**Skywork-Reward-Gemma-... | null | null | [
"Skywork/Skywork-Reward-Preference-80K-v0.1"
] | null | 27,227,132,928 | null | null | [
"Gemma2ForSequenceClassification",
"gemma2",
"AutoModelForSequenceClassification"
] | [
"text-classification"
] | [
"text"
] | [
"text"
] | [
"logits"
] |
687eaa2050b9d9d6d70f18ec | 7428ef9ae5ef868f | 67da9c236fa81925 | 151,669 | BPE | 151,387 | true | true | true | true | 26 | NFC | Sequence | ByteLevel | [
"NFC"
] | [
"Split",
"ByteLevel"
] | [
"ByteLevel"
] | 47 | lmstudio-community/Qwen3-235B-A22B-Instruct-2507-MLX-8bit | lmstudio-community | {
"models": [
{
"_id": "687de260234339fed21e768a",
"id": "Qwen/Qwen3-235B-A22B-Instruct-2507"
}
],
"relation": "quantized"
} | 3,473 | 249,979 | False | 2025-07-21T20:59:12Z | 2025-07-21T21:19:37Z | transformers | 0 | 0 | null | text-generation | {"parameters": {"BF16": 7347449344, "U32": 58773209088}, "total": 235093634560} | [
".gitattributes",
"README.md",
"added_tokens.json",
"chat_template.jinja",
"config.json",
"generation_config.json",
"merges.txt",
"model-00001-of-00048.safetensors",
"model-00002-of-00048.safetensors",
"model-00003-of-00048.safetensors",
"model-00004-of-00048.safetensors",
"model-00005-of-0004... | 9fc3c0315a6841af74c2ba702a3a023f6322d497 | [
"transformers",
"safetensors",
"qwen3_moe",
"text-generation",
"mlx",
"conversational",
"base_model:Qwen/Qwen3-235B-A22B-Instruct-2507",
"base_model:quantized:Qwen/Qwen3-235B-A22B-Instruct-2507",
"license:apache-2.0",
"endpoints_compatible",
"8-bit",
"region:us"
] | null | {"architectures": ["Qwen3MoeForCausalLM"], "model_type": "qwen3_moe", "quantization_config": {"bits": 8}, "tokenizer_config": {"bos_token": null, "eos_token": "<|im_end|>", "pad_token": "<|endoftext|>", "unk_token": null, "chat_template": "{%- if tools %}\n {{- '<|im_start|>system\\n' }}\n {%- if messages[0].role... | {
"auto_model": "AutoModelForCausalLM",
"custom_class": null,
"pipeline_tag": "text-generation",
"processor": "AutoTokenizer"
} | {"base_model": "Qwen/Qwen3-235B-A22B-Instruct-2507", "datasets": null, "eval_results": null, "language": null, "library_name": "transformers", "license": "apache-2.0", "license_name": null, "license_link": "https://huggingface.co/Qwen/Qwen3-235B-A22B-Instruct-2507/blob/main/LICENSE", "metrics": null, "model_name": null... | null | null | [
"apache-2.0",
"https://huggingface.co/Qwen/Qwen3-235B-A22B-Instruct-2507/blob/main/LICENSE"
] | null | null | 235,093,634,560 | null | null | [
"qwen3_moe",
"AutoModelForCausalLM",
"Qwen3MoeForCausalLM"
] | [
"text-generation"
] | [
"text"
] | [
"text"
] | [
"text"
] |
68d0c7259e8b5ab82714ee66 | 7428ef9ae5ef868f | 67da9c236fa81925 | 151,669 | BPE | 151,387 | true | true | true | true | 26 | NFC | Sequence | ByteLevel | [
"NFC"
] | [
"Split",
"ByteLevel"
] | [
"ByteLevel"
] | 47 | Qwen/Qwen3-Next-80B-A3B-Instruct-FP8 | Qwen | {
"models": [
{
"_id": "68c04a8865953b21d7f88ec6",
"id": "Qwen/Qwen3-Next-80B-A3B-Instruct"
}
],
"relation": "quantized"
} | 220,619 | 1,733,564 | False | 2025-09-22T03:48:53Z | 2025-09-22T05:38:44Z | transformers | 82 | 0 | null | text-generation | {"parameters": {"F32": 4921664, "BF16": 688319744, "F8_E4M3": 80636542976}, "total": 81329784384} | [
".gitattributes",
"LICENSE",
"README.md",
"config.json",
"generation_config.json",
"merges.txt",
"model-00001-of-00008.safetensors",
"model-00002-of-00008.safetensors",
"model-00003-of-00008.safetensors",
"model-00004-of-00008.safetensors",
"model-00005-of-00008.safetensors",
"model-00006-of-0... | c5f5f263bdd5cc134092897864e8905d8fe7b928 | [
"transformers",
"safetensors",
"qwen3_next",
"text-generation",
"conversational",
"arxiv:2309.00071",
"arxiv:2404.06654",
"arxiv:2505.09388",
"arxiv:2501.15383",
"base_model:Qwen/Qwen3-Next-80B-A3B-Instruct",
"base_model:quantized:Qwen/Qwen3-Next-80B-A3B-Instruct",
"license:apache-2.0",
"end... | null | {"architectures": ["Qwen3NextForCausalLM"], "model_type": "qwen3_next", "quantization_config": {"quant_method": "fp8"}, "tokenizer_config": {"bos_token": null, "chat_template": "{%- if tools %}\n {{- '<|im_start|>system\\n' }}\n {%- if messages[0].role == 'system' %}\n {{- messages[0].content + '\\n\\n' }}... | {
"auto_model": "AutoModelForCausalLM",
"custom_class": null,
"pipeline_tag": "text-generation",
"processor": "AutoTokenizer"
} | {"base_model": ["Qwen/Qwen3-Next-80B-A3B-Instruct"], "datasets": null, "eval_results": null, "language": null, "library_name": "transformers", "license": "apache-2.0", "license_name": null, "license_link": "https://huggingface.co/Qwen/Qwen3-Next-80B-A3B-Instruct-FP8/blob/main/LICENSE", "metrics": null, "model_name": nu... | null | null | [
"apache-2.0",
"https://huggingface.co/Qwen/Qwen3-Next-80B-A3B-Instruct-FP8/blob/main/LICENSE"
] | null | null | 81,329,784,384 | null | null | [
"qwen3_next",
"Qwen3NextForCausalLM",
"AutoModelForCausalLM"
] | [
"text-generation"
] | [
"text"
] | [
"text"
] | [
"text"
] |
6605392b8d33179e83389976 | 53ecf467267e2824 | 535fa14da0af647c | 30,522 | WordPiece | null | true | true | true | true | 5 | BertNormalizer | BertPreTokenizer | WordPiece | [
"BertNormalizer"
] | [
"BertPreTokenizer"
] | [
"WordPiece"
] | 0 | dwzhu/e5-base-4k | dwzhu | null | 810 | 238,714 | False | 2024-03-28T09:32:27Z | 2024-05-14T08:22:21Z | transformers | 14 | 0 | [{"name": "e5-base-4k", "results": [{"task": {"type": "Classification"}, "dataset": {"type": "mteb/amazon_counterfactual", "name": "MTEB AmazonCounterfactualClassification (en)", "config": "en", "split": "test", "revision": "e8379541af4e31359cca9fbcf4b00f2671dba205"}, "metrics": [{"type": "accuracy", "value": 77.776119... | sentence-similarity | null | [
".gitattributes",
"README.md",
"added_tokens.json",
"config.json",
"pytorch_model.bin",
"special_tokens_map.json",
"tokenizer.json",
"tokenizer_config.json",
"vocab.txt"
] | 1b5664b8cb2bccd8c309429b7bfe5864402e8fbc | [
"transformers",
"pytorch",
"bert",
"feature-extraction",
"mteb",
"sentence-similarity",
"en",
"arxiv:2404.12096",
"arxiv:2104.08663",
"arxiv:2210.07316",
"license:mit",
"model-index",
"text-embeddings-inference",
"endpoints_compatible",
"deploy:azure",
"region:us"
] | null | {"architectures": ["BertModel"], "model_type": "bert", "tokenizer_config": {"cls_token": "[CLS]", "mask_token": "[MASK]", "pad_token": "[PAD]", "sep_token": "[SEP]", "unk_token": "[UNK]"}} | {
"auto_model": "AutoModel",
"custom_class": null,
"pipeline_tag": "feature-extraction",
"processor": "AutoTokenizer"
} | {"language": ["en"], "license": "mit", "tags": ["mteb", "sentence-similarity"], "model-index": [{"name": "e5-base-4k", "results": [{"task": {"type": "Classification"}, "dataset": {"name": "MTEB AmazonCounterfactualClassification (en)", "type": "mteb/amazon_counterfactual", "config": "en", "split": "test", "revision": "... | # E5-base-4k
[LongEmbed: Extending Embedding Models for Long Context Retrieval](https://arxiv.org/abs/2404.12096). Dawei Zhu, Liang Wang, Nan Yang, Yifan Song, Wenhao Wu, Furu Wei, Sujian Li, arxiv 2024. Github Repo for LongEmbed: https://github.com/dwzhu-pku/LongEmbed.
This model has 12 layers and the embedding size... | null | [
"mit"
] | null | [
"en"
] | null | null | null | [
"BertModel",
"AutoModel",
"bert"
] | [
"sentence-similarity",
"feature-extraction"
] | [
"text",
"multimodal"
] | [
"text"
] | [
"logits",
"embeddings"
] |
63d81fe1f8fb9f0e9e13b7bb | eac79eec81977e36 | daab2a732bab72e2 | 128,001 | Unigram | null | true | true | true | true | 5 | Sequence | Sequence | Metaspace | [
"Strip",
"Precompiled",
"Replace"
] | [
"Metaspace"
] | [
"Metaspace"
] | 674 | whispAI/ClaimBuster-DeBERTaV2 | whispAI | null | 40,971 | 400,434 | False | 2023-01-30T19:52:01Z | 2023-01-30T20:14:39Z | transformers | 2 | 0 | null | text-classification | null | [
".gitattributes",
"README.md",
"added_tokens.json",
"config.json",
"pytorch_model.bin",
"special_tokens_map.json",
"spm.model",
"tokenizer.json",
"tokenizer_config.json"
] | c11ea47289daa1d4cf47745bbe38ca7b10568574 | [
"transformers",
"pytorch",
"deberta-v2",
"text-classification",
"autotrain",
"en",
"dataset:lucafrost/autotrain-data-claimbuster",
"co2_eq_emissions",
"text-embeddings-inference",
"endpoints_compatible",
"region:us"
] | null | {"architectures": ["DebertaV2ForSequenceClassification"], "model_type": "deberta-v2", "tokenizer_config": {"bos_token": "[CLS]", "cls_token": "[CLS]", "eos_token": "[SEP]", "mask_token": "[MASK]", "pad_token": "[PAD]", "sep_token": "[SEP]", "unk_token": "[UNK]"}} | {
"auto_model": "AutoModelForSequenceClassification",
"custom_class": null,
"pipeline_tag": "text-classification",
"processor": "AutoTokenizer"
} | {"base_model": null, "datasets": ["lucafrost/autotrain-data-claimbuster"], "eval_results": null, "language": ["en"], "library_name": null, "license": null, "license_name": null, "license_link": null, "metrics": null, "model_name": null, "pipeline_tag": null, "tags": ["autotrain", "text-classification"], "widget": [{"te... | # Model Trained Using AutoTrain
- Problem type: Multi-class Classification
- Model ID: 3165789318
- CO2 Emissions (in grams): 23.1023
## Validation Metrics
- Loss: 0.405
- Accuracy: 0.842
- Macro F1: 0.753
- Micro F1: 0.842
- Weighted F1: 0.843
- Macro Precision: 0.750
- Micro Precision: 0.842
- Weighted Precision: ... | null | null | [
"lucafrost/autotrain-data-claimbuster"
] | [
"en"
] | null | null | null | [
"AutoModelForSequenceClassification",
"deberta-v2",
"DebertaV2ForSequenceClassification"
] | [
"text-classification"
] | [
"text"
] | [
"text"
] | [
"logits"
] |
6390c4a2d00f25601f441851 | 8a8c94e1a59f5186 | ef4806e2ade9022f | 32,100 | Unigram | null | true | true | true | true | 103 | Precompiled | Sequence | Metaspace | [
"Precompiled"
] | [
"WhitespaceSplit",
"Metaspace"
] | [
"Metaspace"
] | 11 | google/t5_xxl_true_nli_mixture | google | null | 4,691 | 246,399 | False | 2022-12-07T16:51:46Z | 2023-03-23T10:55:45Z | transformers | 52 | 0 | null | null | null | [
".gitattributes",
"README.md",
"config.json",
"generation_config.json",
"pytorch_model-00001-of-00005.bin",
"pytorch_model-00002-of-00005.bin",
"pytorch_model-00003-of-00005.bin",
"pytorch_model-00004-of-00005.bin",
"pytorch_model-00005-of-00005.bin",
"pytorch_model.bin.index.json",
"special_tok... | aa6cfe1dd4257853bfdd772992045f41bfc14988 | [
"transformers",
"pytorch",
"t5",
"text2text-generation",
"en",
"dataset:tals/vitaminc",
"dataset:SetFit/mnli",
"dataset:snli",
"dataset:fever",
"dataset:paws",
"dataset:scitail",
"arxiv:2204.04991",
"arxiv:1508.05326",
"arxiv:1904.01130",
"arxiv:2103.08541",
"license:apache-2.0",
"te... | null | {"architectures": ["T5ForConditionalGeneration"], "model_type": "t5", "tokenizer_config": {"eos_token": "</s>", "pad_token": "<pad>", "unk_token": "<unk>"}} | {
"auto_model": "AutoModelForSeq2SeqLM",
"custom_class": null,
"pipeline_tag": "text2text-generation",
"processor": "AutoTokenizer"
} | {"base_model": null, "datasets": ["tals/vitaminc", "SetFit/mnli", "snli", "fever", "paws", "scitail"], "eval_results": null, "language": ["en"], "library_name": null, "license": "apache-2.0", "license_name": null, "license_link": null, "metrics": null, "model_name": null, "pipeline_tag": null, "tags": null} | This is an NLI model based on T5-XXL that predicts a binary label ('1' - Entailment, '0' - No entailment).
It is trained similarly to the NLI model described in the [TRUE paper (Honovich et al, 2022)](https://arxiv.org/pdf/2204.04991.pdf), but using the following datasets instead of ANLI:
- SNLI ([Bowman et al., 2015]... | null | [
"apache-2.0"
] | [
"tals/vitaminc",
"SetFit/mnli",
"snli",
"fever",
"paws",
"scitail"
] | [
"en"
] | null | null | null | [
"t5",
"T5ForConditionalGeneration",
"AutoModelForSeq2SeqLM"
] | [
"text2text-generation"
] | null | null | null |
687ea5b580f794ec4b190ace | 7428ef9ae5ef868f | 67da9c236fa81925 | 151,669 | BPE | 151,387 | true | true | true | true | 26 | NFC | Sequence | ByteLevel | [
"NFC"
] | [
"Split",
"ByteLevel"
] | [
"ByteLevel"
] | 47 | lmstudio-community/Qwen3-235B-A22B-Instruct-2507-MLX-6bit | lmstudio-community | {
"models": [
{
"_id": "687de260234339fed21e768a",
"id": "Qwen/Qwen3-235B-A22B-Instruct-2507"
}
],
"relation": "quantized"
} | 3,392 | 248,983 | False | 2025-07-21T20:40:21Z | 2025-07-21T20:58:33Z | transformers | 0 | 0 | null | text-generation | {"parameters": {"BF16": 7347449344, "U32": 44079906816}, "total": 235093634560} | [
".gitattributes",
"README.md",
"added_tokens.json",
"chat_template.jinja",
"config.json",
"generation_config.json",
"merges.txt",
"model-00001-of-00037.safetensors",
"model-00002-of-00037.safetensors",
"model-00003-of-00037.safetensors",
"model-00004-of-00037.safetensors",
"model-00005-of-0003... | b3feba8e47cbf63cbec479807ba4a3e2ee58e46a | [
"transformers",
"safetensors",
"qwen3_moe",
"text-generation",
"mlx",
"conversational",
"base_model:Qwen/Qwen3-235B-A22B-Instruct-2507",
"base_model:quantized:Qwen/Qwen3-235B-A22B-Instruct-2507",
"license:apache-2.0",
"endpoints_compatible",
"6-bit",
"region:us"
] | null | {"architectures": ["Qwen3MoeForCausalLM"], "model_type": "qwen3_moe", "quantization_config": {"bits": 6}, "tokenizer_config": {"bos_token": null, "eos_token": "<|im_end|>", "pad_token": "<|endoftext|>", "unk_token": null, "chat_template": "{%- if tools %}\n {{- '<|im_start|>system\\n' }}\n {%- if messages[0].role... | {
"auto_model": "AutoModelForCausalLM",
"custom_class": null,
"pipeline_tag": "text-generation",
"processor": "AutoTokenizer"
} | {"base_model": "Qwen/Qwen3-235B-A22B-Instruct-2507", "datasets": null, "eval_results": null, "language": null, "library_name": "transformers", "license": "apache-2.0", "license_name": null, "license_link": "https://huggingface.co/Qwen/Qwen3-235B-A22B-Instruct-2507/blob/main/LICENSE", "metrics": null, "model_name": null... | null | null | [
"apache-2.0",
"https://huggingface.co/Qwen/Qwen3-235B-A22B-Instruct-2507/blob/main/LICENSE"
] | null | null | 235,093,634,560 | null | null | [
"qwen3_moe",
"AutoModelForCausalLM",
"Qwen3MoeForCausalLM"
] | [
"text-generation"
] | [
"text"
] | [
"text"
] | [
"text"
] |
677e939c13a5cb6875d87a6f | 5ace947064ffa175 | de506a080474956b | 256,000 | BPE | 617,759 | true | false | true | true | 5 | Sequence | null | Sequence | [
"Prepend",
"Replace"
] | null | [
"Replace",
"ByteFallback",
"Fuse",
"Strip"
] | 675 | BSC-LT/salamandraTA-7b-instruct | BSC-LT | {
"models": [
{
"_id": "66fa496846d413c380f8a048",
"id": "BSC-LT/salamandra-7b"
}
],
"relation": "finetune"
} | 1,605 | 530,045 | False | 2025-01-08T15:02:52Z | 2025-08-19T11:05:53Z | transformers | 24 | 0 | null | translation | {"parameters": {"BF16": 7768117248}, "total": 7768117248} | [
".gitattributes",
"README.md",
"config.json",
"generation_config.json",
"images/bleu_ca.png",
"images/bleu_en.png",
"images/bleu_es.png",
"images/bleu_eu.png",
"images/bleu_gl.png",
"images/chart.png",
"images/es_xx_bars.png",
"images/geneval.png",
"images/salamandra_header.png",
"images/t... | 6372ffc318284ac9337d3d4e69a63ad9c993b8dd | [
"transformers",
"safetensors",
"llama",
"text-generation",
"translation",
"bg",
"ca",
"cs",
"cy",
"da",
"de",
"el",
"en",
"es",
"et",
"eu",
"fi",
"fr",
"ga",
"gl",
"hr",
"hu",
"it",
"lt",
"lv",
"mt",
"nl",
"nb",
"no",
"nn",
"oc",
"pl",
"pt",
"ro",
... | null | {"architectures": ["LlamaForCausalLM"], "model_type": "llama", "tokenizer_config": {"bos_token": "<s>", "chat_template": "{% for message in messages %}{{'<|im_start|>' + message['role'] + '\n' + message['content'] + '<|im_end|>' + '\n'}}{% endfor %}{% if add_generation_prompt %}{{ '<|im_start|>assistant\n' }}{% endif %... | {
"auto_model": "AutoModelForCausalLM",
"custom_class": null,
"pipeline_tag": "text-generation",
"processor": "AutoTokenizer"
} | {"base_model": ["BSC-LT/salamandra-7b"], "datasets": null, "eval_results": null, "language": ["bg", "ca", "cs", "cy", "da", "de", "el", "en", "es", "et", "eu", "fi", "fr", "ga", "gl", "hr", "hu", "it", "lt", "lv", "mt", "nl", "nb", "no", "nn", "oc", "pl", "pt", "ro", "ru", "sl", "sk", "sr", "sv", "uk", "ast", "an"], "l... | 
# SalamandraTA Model Card
SalamandraTA-7b-instruct is a translation LLM that has been instruction-tuned from SalamandraTA-7b-base.
The base model results from continually pre-training [Salamandra-7b](https://huggingface.co/BSC-LT/salamandra-7b) on parallel data and has not been pu... | null | [
"apache-2.0"
] | null | [
"bg",
"ca",
"cs",
"cy",
"da",
"de",
"el",
"en",
"es",
"et",
"eu",
"fi",
"fr",
"ga",
"gl",
"hr",
"hu",
"it",
"lt",
"lv",
"mt",
"nl",
"nb",
"no",
"nn",
"oc",
"pl",
"pt",
"ro",
"ru",
"sl",
"sk",
"sr",
"sv",
"uk",
"ast",
"an"
] | 7,768,117,248 | null | null | [
"AutoModelForCausalLM",
"llama",
"LlamaForCausalLM"
] | [
"translation",
"text-generation"
] | [
"text"
] | [
"text"
] | [
"text"
] |
6622f08db74a8b40152ba2ad | 803e3c8528c55bf1 | a1f1bd381dcb9329 | 128,256 | BPE | 280,147 | false | true | true | true | 256 | null | Sequence | ByteLevel | null | [
"Split",
"ByteLevel"
] | [
"ByteLevel"
] | 352 | abacusai/Llama-3-Smaug-8B | abacusai | null | 12,290 | 287,297 | False | 2024-04-19T22:30:37Z | 2024-05-19T12:26:31Z | transformers | 90 | 0 | null | text-generation | {"parameters": {"BF16": 8030261248}, "total": 8030261248} | [
".gitattributes",
"README.md",
"config.json",
"generation_config.json",
"model-00001-of-00004.safetensors",
"model-00002-of-00004.safetensors",
"model-00003-of-00004.safetensors",
"model-00004-of-00004.safetensors",
"model.safetensors.index.json",
"special_tokens_map.json",
"tokenizer.json",
"... | fe54a7d42160d3d8fcc3289c8c411fd9dd5e8357 | [
"transformers",
"safetensors",
"llama",
"text-generation",
"conversational",
"dataset:aqua_rat",
"dataset:microsoft/orca-math-word-problems-200k",
"dataset:m-a-p/CodeFeedback-Filtered-Instruction",
"dataset:anon8231489123/ShareGPT_Vicuna_unfiltered",
"arxiv:2402.13228",
"license:llama2",
"text... | null | {"architectures": ["LlamaForCausalLM"], "model_type": "llama", "tokenizer_config": {"bos_token": "<|begin_of_text|>", "chat_template": "{% set loop_messages = messages %}{% for message in loop_messages %}{% set content = '<|start_header_id|>' + message['role'] + '<|end_header_id|>\n\n'+ message['content'] | trim + '<|e... | {
"auto_model": "AutoModelForCausalLM",
"custom_class": null,
"pipeline_tag": "text-generation",
"processor": "AutoTokenizer"
} | {"base_model": null, "datasets": ["aqua_rat", "microsoft/orca-math-word-problems-200k", "m-a-p/CodeFeedback-Filtered-Instruction", "anon8231489123/ShareGPT_Vicuna_unfiltered"], "eval_results": null, "language": null, "library_name": "transformers", "license": "llama2", "license_name": null, "license_link": null, "metri... | # Llama-3-Smaug-8B
### Built with Meta Llama 3

This model was built using the Smaug recipe for improving performance on real world multi-turn conversations applied to
[meta-llama/Meta-Llama-3-8B-... | null | [
"llama2"
] | [
"aqua_rat",
"microsoft/orca-math-word-problems-200k",
"m-a-p/CodeFeedback-Filtered-Instruction",
"anon8231489123/ShareGPT_Vicuna_unfiltered"
] | null | 8,030,261,248 | null | null | [
"AutoModelForCausalLM",
"llama",
"LlamaForCausalLM"
] | [
"text-generation"
] | [
"text"
] | [
"text"
] | [
"text"
] |
6877f6702d32707ed3f19eb8 | e034328a2d067fa5 | daab2a732bab72e2 | 128,001 | Unigram | null | true | true | true | true | 5 | Sequence | Sequence | Metaspace | [
"Strip",
"Precompiled",
"Replace"
] | [
"Metaspace"
] | [
"Metaspace"
] | 237 | OpenMed/OpenMed-NER-BloodCancerDetect-SuperClinical-434M | OpenMed | null | 93,698 | 609,298 | False | 2025-07-16T18:58:56Z | 2025-08-05T09:34:39Z | transformers | 0 | 0 | null | token-classification | {"parameters": {"BF16": 434015235}, "total": 434015235} | [
".gitattributes",
"README.md",
"added_tokens.json",
"config.json",
"model.safetensors",
"openmed_vs_sota_grouped_bars.png",
"special_tokens_map.json",
"spm.model",
"test_results.json",
"tokenizer.json",
"tokenizer_config.json"
] | d82d860f03243dfa4474ad179941ea36652aa6ed | [
"transformers",
"safetensors",
"deberta-v2",
"token-classification",
"named-entity-recognition",
"biomedical-nlp",
"leukemia",
"hematology",
"cancer",
"clinical-medicine",
"cl",
"en",
"arxiv:2508.01630",
"license:apache-2.0",
"endpoints_compatible",
"region:us"
] | null | {"architectures": ["DebertaV2ForTokenClassification"], "model_type": "deberta-v2", "tokenizer_config": {"bos_token": "[CLS]", "cls_token": "[CLS]", "eos_token": "[SEP]", "mask_token": "[MASK]", "pad_token": "[PAD]", "sep_token": "[SEP]", "unk_token": "[UNK]"}} | {
"auto_model": "AutoModelForTokenClassification",
"custom_class": null,
"pipeline_tag": "token-classification",
"processor": "AutoTokenizer"
} | {"base_model": null, "datasets": null, "eval_results": null, "language": ["en"], "library_name": null, "license": "apache-2.0", "license_name": null, "license_link": null, "metrics": null, "model_name": null, "pipeline_tag": null, "tags": ["token-classification", "named-entity-recognition", "biomedical-nlp", "transform... | null | null | [
"apache-2.0"
] | null | [
"en"
] | 434,015,235 | null | null | [
"DebertaV2ForTokenClassification",
"AutoModelForTokenClassification",
"deberta-v2"
] | [
"token-classification"
] | [
"text"
] | [
"text"
] | [
"logits"
] |
64d30f9d5de0bc71ffa15d3f | 6949732424a8d297 | 8bd7d71767538b82 | 32,000 | BPE | 61,249 | true | false | true | true | 3 | Sequence | null | Sequence | [
"Prepend",
"Replace"
] | null | [
"Replace",
"ByteFallback",
"Fuse",
"Strip"
] | 42 | pankajmathur/orca_mini_v3_13b | pankajmathur | null | 1,582 | 236,937 | False | 2023-08-09T04:01:33Z | 2025-01-23T21:43:39Z | transformers | 31 | 0 | [{"name": "orca_mini_v3_13b", "results": [{"task": {"type": "text-generation", "name": "Text Generation"}, "dataset": {"name": "AI2 Reasoning Challenge (25-Shot)", "type": "ai2_arc", "config": "ARC-Challenge", "split": "test", "args": {"num_few_shot": 25}}, "metrics": [{"type": "acc_norm", "value": 63.14, "name": "norm... | text-generation | {"parameters": {"F16": 13015864320}, "total": 13015864320} | [
".gitattributes",
"README.md",
"config.json",
"generation_config.json",
"model-00001-of-00003.safetensors",
"model-00002-of-00003.safetensors",
"model-00003-of-00003.safetensors",
"model.safetensors.index.json",
"orca_minis_small.jpeg",
"pytorch_model-00001-of-00003.bin",
"pytorch_model-00002-of... | 6991ceea9fd37bcc4f648cb42cba3b365509ccff | [
"transformers",
"pytorch",
"safetensors",
"llama",
"text-generation",
"en",
"dataset:psmathur/orca_mini_v1_dataset",
"dataset:ehartford/dolphin",
"arxiv:2306.02707",
"license:other",
"model-index",
"text-generation-inference",
"endpoints_compatible",
"deploy:azure",
"region:us"
] | null | {"architectures": ["LlamaForCausalLM"], "model_type": "llama", "tokenizer_config": {"bos_token": {"__type": "AddedToken", "content": "<s>", "lstrip": false, "normalized": true, "rstrip": false, "single_word": false}, "eos_token": {"__type": "AddedToken", "content": "</s>", "lstrip": false, "normalized": true, "rstrip":... | {
"auto_model": "AutoModelForCausalLM",
"custom_class": null,
"pipeline_tag": "text-generation",
"processor": "AutoTokenizer"
} | {"datasets": ["psmathur/orca_mini_v1_dataset", "ehartford/dolphin"], "language": ["en"], "library_name": "transformers", "license": "other", "pipeline_tag": "text-generation", "model-index": [{"name": "orca_mini_v3_13b", "results": [{"task": {"type": "text-generation", "name": "Text Generation"}, "dataset": {"name": "A... | # orca_mini_v3_13b
A Llama2-13b model trained on Orca Style datasets.
<strong>
"Obsessed with Open Source GenAI's potential? So am I ! Let's Contribute together 🚀 <a href="https://www.linkedin.com/in/pankajam" target... | null | [
"other"
] | [
"psmathur/orca_mini_v1_dataset",
"ehartford/dolphin"
] | [
"en"
] | 13,015,864,320 | null | null | [
"AutoModelForCausalLM",
"llama",
"LlamaForCausalLM"
] | [
"text-generation"
] | [
"text"
] | [
"text"
] | [
"text"
] |
6877fbc02ff24113e3bdfb1b | b3310d158ab6e0dc | 66be3297e0980489 | 28,895 | WordPiece | null | true | true | true | true | 5 | BertNormalizer | BertPreTokenizer | WordPiece | [
"BertNormalizer"
] | [
"BertPreTokenizer"
] | [
"WordPiece"
] | 409 | OpenMed/OpenMed-NER-DiseaseDetect-PubMed-335M | OpenMed | null | 96,605 | 609,740 | False | 2025-07-16T19:21:36Z | 2025-08-05T09:35:01Z | transformers | 0 | 0 | null | token-classification | {"parameters": {"BF16": 334095363}, "total": 334095363} | [
".gitattributes",
"README.md",
"config.json",
"model.safetensors",
"openmed_vs_sota_grouped_bars.png",
"special_tokens_map.json",
"test_results.json",
"tokenizer.json",
"tokenizer_config.json",
"vocab.txt"
] | f75649007fa2e1f872b97dce628fba590e5608f7 | [
"transformers",
"safetensors",
"bert",
"token-classification",
"named-entity-recognition",
"biomedical-nlp",
"disease-entity-recognition",
"medical-diagnosis",
"pathology",
"biocuration",
"disease",
"en",
"arxiv:2508.01630",
"license:apache-2.0",
"endpoints_compatible",
"region:us"
] | null | {"architectures": ["BertForTokenClassification"], "model_type": "bert", "tokenizer_config": {"cls_token": "[CLS]", "mask_token": "[MASK]", "pad_token": "[PAD]", "sep_token": "[SEP]", "unk_token": "[UNK]"}} | {
"auto_model": "AutoModelForTokenClassification",
"custom_class": null,
"pipeline_tag": "token-classification",
"processor": "AutoTokenizer"
} | {"base_model": null, "datasets": null, "eval_results": null, "language": ["en"], "library_name": null, "license": "apache-2.0", "license_name": null, "license_link": null, "metrics": null, "model_name": null, "pipeline_tag": null, "tags": ["token-classification", "named-entity-recognition", "biomedical-nlp", "transform... | null | null | [
"apache-2.0"
] | null | [
"en"
] | 334,095,363 | null | null | [
"AutoModelForTokenClassification",
"BertForTokenClassification",
"bert"
] | [
"token-classification"
] | [
"text"
] | [
"text"
] | [
"logits"
] |
6877f5b023c030042d0f76b7 | 247b76e6aa48f448 | 70bd27c212bc339c | 50,265 | BPE | 50,000 | false | true | true | true | 5 | null | ByteLevel | ByteLevel | null | [
"ByteLevel"
] | [
"ByteLevel"
] | 432 | OpenMed/OpenMed-NER-PharmaDetect-SuperMedical-355M | OpenMed | null | 96,579 | 618,576 | False | 2025-07-16T18:55:44Z | 2025-08-05T09:34:22Z | transformers | 0 | 0 | null | token-classification | {"parameters": {"BF16": 354313219}, "total": 354313219} | [
".gitattributes",
"README.md",
"config.json",
"merges.txt",
"model.safetensors",
"openmed_vs_sota_grouped_bars.png",
"special_tokens_map.json",
"test_results.json",
"tokenizer.json",
"tokenizer_config.json",
"vocab.json"
] | e35c1fbbe448e903f99485a6c488c410ef3a8aed | [
"transformers",
"safetensors",
"roberta",
"token-classification",
"named-entity-recognition",
"biomedical-nlp",
"chemical-entity-recognition",
"drug-discovery",
"pharmacology",
"biocuration",
"chem",
"en",
"arxiv:2508.01630",
"license:apache-2.0",
"endpoints_compatible",
"region:us"
] | null | {"architectures": ["RobertaForTokenClassification"], "model_type": "roberta", "tokenizer_config": {"bos_token": "<s>", "cls_token": "<s>", "eos_token": "</s>", "mask_token": "<mask>", "pad_token": "<pad>", "sep_token": "</s>", "unk_token": "<unk>"}} | {
"auto_model": "AutoModelForTokenClassification",
"custom_class": null,
"pipeline_tag": "token-classification",
"processor": "AutoTokenizer"
} | {"base_model": null, "datasets": null, "eval_results": null, "language": ["en"], "library_name": null, "license": "apache-2.0", "license_name": null, "license_link": null, "metrics": null, "model_name": null, "pipeline_tag": null, "tags": ["token-classification", "named-entity-recognition", "biomedical-nlp", "transform... | null | null | [
"apache-2.0"
] | null | [
"en"
] | 354,313,219 | null | null | [
"roberta",
"AutoModelForTokenClassification",
"RobertaForTokenClassification"
] | [
"token-classification"
] | [
"text"
] | [
"text"
] | [
"logits"
] |
628aa453f47d88a921ff005f | b8db556f1f02dec9 | 7f171e98bdd0da5f | 83,828 | WordPiece | null | true | true | true | true | 5 | BertNormalizer | BertPreTokenizer | WordPiece | [
"BertNormalizer"
] | [
"BertPreTokenizer"
] | [
"WordPiece"
] | 79 | Aniemore/rubert-tiny2-russian-emotion-detection | Aniemore | null | 3,241 | 284,858 | False | 2022-05-22T21:00:03Z | 2023-04-07T18:08:00Z | transformers | 13 | 0 | [{"name": "RuBERT tiny2 For Russian Text Emotion Detection by Ilya Lubenets", "results": [{"task": {"name": "Multilabel Text Classification", "type": "multilabel-text-classification"}, "dataset": {"name": "CEDR M7", "type": "Aniemore/cedr-m7", "args": "ru"}, "metrics": [{"name": "multilabel accuracy", "type": "accuracy... | text-classification | {"parameters": {"I64": 2048, "F32": 29195959}, "total": 29198007} | [
".gitattributes",
"README.md",
"config.json",
"model.safetensors",
"pytorch_model.bin",
"special_tokens_map.json",
"tokenizer.json",
"tokenizer_config.json",
"vocab.txt"
] | a7b5618de479a2f77637393ed2931d48b9618208 | [
"transformers",
"pytorch",
"safetensors",
"bert",
"text-classification",
"russian",
"classification",
"emotion",
"emotion-detection",
"emotion-recognition",
"multiclass",
"ru",
"dataset:Aniemore/cedr-m7",
"doi:10.57967/hf/1275",
"license:mit",
"model-index",
"text-embeddings-inferenc... | null | {"architectures": ["BertForSequenceClassification"], "model_type": "bert", "tokenizer_config": {"unk_token": "[UNK]", "sep_token": "[SEP]", "pad_token": "[PAD]", "cls_token": "[CLS]", "mask_token": "[MASK]"}} | {
"auto_model": "AutoModelForSequenceClassification",
"custom_class": null,
"pipeline_tag": "text-classification",
"processor": "AutoTokenizer"
} | {"datasets": ["Aniemore/cedr-m7"], "language": ["ru"], "license": "mit", "tags": ["russian", "classification", "emotion", "emotion-detection", "emotion-recognition", "multiclass"], "widget": [{"text": "\u041a\u0430\u043a \u0434\u0435\u043b\u0430?"}, {"text": "\u0414\u0443\u0440\u0430\u043a \u0442\u0432\u043e\u0439 \u04... | # First - you should prepare few functions to talk to model
```python
import torch
from transformers import BertForSequenceClassification, AutoTokenizer
LABELS = ['neutral', 'happiness', 'sadness', 'enthusiasm', 'fear', 'anger', 'disgust']
tokenizer = AutoTokenizer.from_pretrained('Aniemore/rubert-tiny2-russian-emoti... | null | [
"mit"
] | [
"Aniemore/cedr-m7"
] | [
"ru"
] | 29,198,007 | null | null | [
"BertForSequenceClassification",
"bert",
"AutoModelForSequenceClassification"
] | [
"text-classification"
] | [
"text"
] | [
"text"
] | [
"logits"
] |
6877f49ff3bc728230f2f2e6 | 099fc7b2924a795c | 5f9f736c7dc6fbfa | 28,996 | WordPiece | null | true | true | true | true | 5 | BertNormalizer | BertPreTokenizer | WordPiece | [
"BertNormalizer"
] | [
"BertPreTokenizer"
] | [
"WordPiece"
] | 453 | OpenMed/OpenMed-NER-OncologyDetect-TinyMed-65M | OpenMed | null | 95,401 | 606,943 | False | 2025-07-16T18:51:11Z | 2025-08-05T09:32:34Z | transformers | 2 | 0 | null | token-classification | {"parameters": {"BF16": 65216289}, "total": 65216289} | [
".gitattributes",
"README.md",
"config.json",
"model.safetensors",
"openmed_vs_sota_grouped_bars.png",
"special_tokens_map.json",
"test_results.json",
"tokenizer.json",
"tokenizer_config.json",
"vocab.txt"
] | 5dd4cdf7ec3200625ed87efcfb5f74699b1eb9b8 | [
"transformers",
"safetensors",
"distilbert",
"token-classification",
"named-entity-recognition",
"biomedical-nlp",
"cancer-genetics",
"oncology",
"gene-regulation",
"cancer-research",
"amino_acid",
"anatomical_system",
"cancer",
"cell",
"cellular_component",
"developing_anatomical_stru... | null | {"architectures": ["DistilBertForTokenClassification"], "model_type": "distilbert", "tokenizer_config": {"cls_token": "[CLS]", "mask_token": "[MASK]", "pad_token": "[PAD]", "sep_token": "[SEP]", "unk_token": "[UNK]"}} | {
"auto_model": "AutoModelForTokenClassification",
"custom_class": null,
"pipeline_tag": "token-classification",
"processor": "AutoTokenizer"
} | {"base_model": null, "datasets": null, "eval_results": null, "language": ["en"], "library_name": null, "license": "apache-2.0", "license_name": null, "license_link": null, "metrics": null, "model_name": null, "pipeline_tag": null, "tags": ["token-classification", "named-entity-recognition", "biomedical-nlp", "transform... | null | null | [
"apache-2.0"
] | null | [
"en"
] | 65,216,289 | null | null | [
"AutoModelForTokenClassification",
"distilbert",
"DistilBertForTokenClassification"
] | [
"token-classification"
] | [
"text"
] | [
"text"
] | [
"logits"
] |
661524817880b7466a45276c | d5d7e75b267de3f9 | f112b46d562db8ec | 122,753 | BPE | 171,540 | true | false | true | true | 15 | Sequence | null | Sequence | [
"Prepend",
"Replace"
] | null | [
"Replace",
"ByteFallback",
"Fuse",
"Strip"
] | 676 | openbmb/MiniCPM-V-2 | openbmb | null | 50,612 | 481,027 | False | 2024-04-09T11:20:33Z | 2025-01-15T10:35:33Z | transformers | 495 | 0 | null | visual-question-answering | {"parameters": {"BF16": 3434965792}, "total": 3434965792} | [
".gitattributes",
"README.md",
"assets/english_menu.gif",
"assets/london_car.gif",
"assets/minicpmv-2-benchmark.png",
"assets/minicpmv-2-peformance2.png",
"assets/minicpmv2-cases_2.png",
"assets/station.gif",
"config.json",
"configuration_minicpm.py",
"generation_config.json",
"model-00001-of-... | b9a02dbfcc87e471b13f8d1c6963747db31427db | [
"transformers",
"safetensors",
"minicpmv",
"feature-extraction",
"visual-question-answering",
"custom_code",
"en",
"zh",
"dataset:HaoyeZhang/RLHF-V-Dataset",
"dataset:Yirany/UniMM-Chat",
"dataset:HuggingFaceM4/VQAv2",
"dataset:liuhaotian/LLaVA-Instruct-150K",
"arxiv:2403.11703",
"arxiv:230... | null | {"architectures": ["MiniCPMV"], "auto_map": {"AutoConfig": "configuration_minicpm.MiniCPMVConfig", "AutoModel": "modeling_minicpmv.MiniCPMV", "AutoModelForCausalLM": "modeling_minicpmv.MiniCPMV"}, "model_type": "minicpmv", "tokenizer_config": {"bos_token": "<s>", "eos_token": "</s>", "pad_token": "<unk>", "unk_token": ... | {
"auto_model": "AutoModel",
"custom_class": "modeling_minicpmv.MiniCPMV",
"pipeline_tag": "feature-extraction",
"processor": null
} | {"base_model": null, "datasets": ["HaoyeZhang/RLHF-V-Dataset", "Yirany/UniMM-Chat", "HuggingFaceM4/VQAv2", "liuhaotian/LLaVA-Instruct-150K"], "eval_results": null, "language": ["en", "zh"], "library_name": null, "license": null, "license_name": null, "license_link": null, "metrics": null, "model_name": null, "pipeline_... | [GitHub](https://github.com/OpenBMB/MiniCPM-V) | [Demo](https://huggingface.co/spaces/openbmb/MiniCPM-V-2)
## News <!-- omit in toc -->
* [2025.01.14] 🔥 We open source [**MiniCPM-o 2.6**](https://huggingface.co/openbmb/MiniCPM-o-2_6), with significant performance improvement over **MiniCPM-V 2.6**, and support real-t... | null | null | [
"HaoyeZhang/RLHF-V-Dataset",
"Yirany/UniMM-Chat",
"HuggingFaceM4/VQAv2",
"liuhaotian/LLaVA-Instruct-150K"
] | [
"en",
"zh"
] | 3,434,965,792 | null | null | [
"AutoModel",
"MiniCPMV",
"minicpmv",
"modeling_minicpmv.MiniCPMV"
] | [
"feature-extraction",
"visual-question-answering"
] | [
"multimodal"
] | [
"text",
"image"
] | [
"logits",
"embeddings"
] |
66f2ef38d77210eae6181bbf | ca52fdd598d2cb33 | d610e6a5759ccfff | 50,285 | BPE | 50,009 | true | true | true | true | 33 | NFC | ByteLevel | ByteLevel | [
"NFC"
] | [
"ByteLevel"
] | [
"ByteLevel"
] | 677 | allenai/MolmoE-1B-0924 | allenai | {
"models": [
{
"_id": "669c043b52cf1c619d8d8962",
"id": "allenai/OLMoE-1B-7B-0924"
}
],
"relation": "finetune"
} | 1,170 | 232,331 | False | 2024-09-24T16:56:24Z | 2025-04-24T17:51:36Z | transformers | 157 | 0 | null | image-text-to-text | null | [
".gitattributes",
"README.md",
"added_tokens.json",
"config.json",
"config_molmoe.py",
"example.py",
"generation_config.json",
"image_preprocessing_molmo.py",
"modeling_molmoe.py",
"molmo_logo.png",
"preprocessing_molmo.py",
"preprocessor_config.json",
"processor_config.json",
"pytorch_mod... | 69e3445d130507eadaa9123e3c411ce17aeb8afa | [
"transformers",
"pytorch",
"molmo",
"text-generation",
"multimodal",
"moe",
"olmo",
"olmoe",
"molmoe",
"image-text-to-text",
"custom_code",
"en",
"dataset:allenai/OLMoE-mix-0924",
"arxiv:2409.17146",
"base_model:allenai/OLMoE-1B-7B-0924",
"base_model:finetune:allenai/OLMoE-1B-7B-0924",... | null | {"auto_map": {"AutoConfig": "config_molmoe.MolmoConfig", "AutoModelForCausalLM": "modeling_molmoe.MolmoForCausalLM"}, "architectures": ["OLMoForCausalLM"], "model_type": "molmo", "tokenizer_config": {"bos_token": null, "eos_token": "<|endoftext|>", "pad_token": "<|padding|>", "unk_token": null}} | {
"auto_model": "AutoModelForCausalLM",
"custom_class": null,
"pipeline_tag": "text-generation",
"processor": null
} | {"base_model": ["openai/clip-vit-large-patch14-336", "allenai/OLMoE-1B-7B-0924"], "datasets": ["allenai/OLMoE-mix-0924"], "eval_results": null, "language": ["en"], "library_name": "transformers", "license": "apache-2.0", "license_name": null, "license_link": null, "metrics": null, "model_name": null, "pipeline_tag": "i... | <img src="molmo_logo.png" alt="Logo for the Molmo Project" style="width: auto; height: 50px;">
# MolmoE 1B
Molmo is a family of open vision-language models developed by the Allen Institute for AI.
Molmo models are trained on PixMo, a dataset of 1 million, highly-curated image-text pairs.
It has state-of-the-art pe... | null | [
"apache-2.0"
] | [
"allenai/OLMoE-mix-0924"
] | [
"en"
] | null | null | null | [
"molmo",
"AutoModelForCausalLM",
"OLMoForCausalLM"
] | [
"image-text-to-text",
"text-generation"
] | [
"text",
"multimodal"
] | [
"text",
"image"
] | [
"text"
] |
67c72cb026926d1f08fe56b1 | b86074a73431b347 | 1fe366e13272caa0 | 262,145 | BPE | 514,906 | true | true | true | true | 6,415 | Replace | Split | Sequence | [
"Replace"
] | [
"Split"
] | [
"Replace",
"ByteFallback",
"Fuse"
] | 434 | google/shieldgemma-2-4b-it | google | {
"models": [
{
"_id": "67b79c6c01ad68cfed14677a",
"id": "google/gemma-3-4b-pt"
}
],
"relation": "finetune"
} | 5,075 | 247,147 | manual | 2025-03-04T16:39:12Z | 2025-04-04T13:41:53Z | transformers | 155 | 2 | null | image-text-to-text | null | [
".gitattributes",
"README.md",
"added_tokens.json",
"chat_template.json",
"config.json",
"model-00001-of-00002.safetensors",
"model-00002-of-00002.safetensors",
"model.safetensors.index.json",
"preprocessor_config.json",
"processor_config.json",
"special_tokens_map.json",
"tokenizer.json",
"... | eaf60452b5fc41a911338a022e628b0c15283897 | [
"transformers",
"safetensors",
"shieldgemma2",
"image-classification",
"image-text-to-text",
"conversational",
"arxiv:2504.01081",
"arxiv:2209.06794",
"base_model:google/gemma-3-4b-pt",
"base_model:finetune:google/gemma-3-4b-pt",
"license:gemma",
"endpoints_compatible",
"region:us"
] | null | {"architectures": ["ShieldGemma2ForImageClassification"], "model_type": "shieldgemma2", "processor_config": {"chat_template": "{{ bos_token }}\n{%- for message in messages -%}\n {%- if message['content'] is iterable -%}\n {%- for item in message['content'] -%}\n {{ '<start_of_turn>user\n' }}\n ... | {
"auto_model": "AutoModelForImageClassification",
"custom_class": null,
"pipeline_tag": "image-classification",
"processor": null
} | {"base_model": "google/gemma-3-4b-pt", "datasets": null, "eval_results": null, "language": null, "library_name": "transformers", "license": "gemma", "license_name": null, "license_link": null, "metrics": null, "model_name": null, "pipeline_tag": "image-text-to-text", "tags": null, "extra_gated_heading": "Access Gemma o... | null | null | [
"gemma"
] | null | null | null | null | null | [
"AutoModelForImageClassification",
"shieldgemma2",
"ShieldGemma2ForImageClassification"
] | [
"image-text-to-text",
"image-classification"
] | [
"vision",
"multimodal"
] | [
"text",
"image"
] | [
"text",
"logits"
] |
66a8a27db812afa43fb0b7ee | 70a2a320361d4ddf | 3dd5f512c30a5400 | 65,024 | BPE | 64,784 | false | true | false | true | 12 | null | Sequence | ByteLevel | null | [
"Punctuation",
"ByteLevel",
"Digits",
"Split"
] | [
"ByteLevel"
] | 678 | tiiuae/falcon-mamba-7b-instruct | tiiuae | {
"models": [
{
"_id": "66976d726d173ec738175582",
"id": "tiiuae/falcon-mamba-7b"
}
],
"relation": "finetune"
} | 47,169 | 302,775 | False | 2024-07-30T08:21:17Z | 2024-12-17T11:11:40Z | transformers | 71 | 1 | null | text-generation | {"parameters": {"BF16": 7272665088}, "total": 7272665088} | [
".gitattributes",
"README.md",
"config.json",
"generation_config.json",
"model-00001-of-00003.safetensors",
"model-00002-of-00003.safetensors",
"model-00003-of-00003.safetensors",
"model.safetensors.index.json",
"special_tokens_map.json",
"tokenizer.json",
"tokenizer_config.json"
] | b250fc9399d14f56aca18e9ea70bbfb1f73479eb | [
"transformers",
"safetensors",
"falcon_mamba",
"text-generation",
"conversational",
"en",
"dataset:tiiuae/falcon-refinedweb",
"dataset:HuggingFaceFW/fineweb-edu",
"arxiv:2312.00752",
"arxiv:2410.05355",
"base_model:tiiuae/falcon-mamba-7b",
"base_model:finetune:tiiuae/falcon-mamba-7b",
"licen... | null | {"architectures": ["FalconMambaForCausalLM"], "model_type": "falcon_mamba", "tokenizer_config": {"bos_token": "<|begin_of_text|>", "chat_template": "{{bos_token}}{% for message in messages %}{{'<|im_start|>' + message['role'] + '\n' + message['content'] + '<|im_end|>' + '\n'}}{% endfor %}{% if add_generation_prompt %}{... | {
"auto_model": "AutoModelForCausalLM",
"custom_class": null,
"pipeline_tag": "text-generation",
"processor": "AutoTokenizer"
} | {"base_model": "tiiuae/falcon-mamba-7b", "datasets": ["tiiuae/falcon-refinedweb", "HuggingFaceFW/fineweb-edu"], "eval_results": null, "language": ["en"], "library_name": null, "license": "other", "license_name": "falcon-mamba-7b-license", "license_link": "https://falconllm.tii.ae/falcon-mamba-7b-terms-and-conditions.ht... | <img src="https://huggingface.co/datasets/tiiuae/documentation-images/resolve/main/falcon_mamba/thumbnail.png" alt="drawing" width="800"/>
**Model card for FalconMamba Instruct model**
# Table of Contents
0. [TL;DR](#TL;DR)
1. [Model Details](#model-details)
2. [Usage](#usage)
3. [Training Details](#training-detail... | null | [
"other",
"falcon-mamba-7b-license",
"https://falconllm.tii.ae/falcon-mamba-7b-terms-and-conditions.html"
] | [
"tiiuae/falcon-refinedweb",
"HuggingFaceFW/fineweb-edu"
] | [
"en"
] | 7,272,665,088 | null | null | [
"AutoModelForCausalLM",
"falcon_mamba",
"FalconMambaForCausalLM"
] | [
"text-generation"
] | [
"text"
] | [
"text"
] | [
"text"
] |
621ffdc136468d709f17a0cf | ad98d16c82bf1100 | cbf42b059ebbcacb | 50,500 | BPE | 50,000 | false | true | true | true | 240 | null | ByteLevel | ByteLevel | null | [
"ByteLevel"
] | [
"ByteLevel"
] | 679 | climatebert/distilroberta-base-climate-f | climatebert | null | 4,252 | 277,230 | False | 2022-03-02T23:29:05Z | 2023-05-04T13:05:20Z | transformers | 39 | 0 | null | fill-mask | {"parameters": {"I64": 514, "F32": 82350916}, "total": 82351430} | [
".gitattributes",
"README.md",
"added_tokens.json",
"config.json",
"merges.txt",
"model.safetensors",
"pytorch_model.bin",
"special_tokens_map.json",
"tokenizer.json",
"tokenizer_config.json",
"vocab.json"
] | e7dd6bb67b16f5dbfb940f7b27ab89d2f289a318 | [
"transformers",
"pytorch",
"safetensors",
"roberta",
"fill-mask",
"climate",
"en",
"arxiv:2110.12010",
"license:apache-2.0",
"endpoints_compatible",
"deploy:azure",
"region:us"
] | null | {"architectures": ["RobertaForMaskedLM"], "model_type": "roberta", "tokenizer_config": {"bos_token": {"__type": "AddedToken", "content": "<s>", "lstrip": false, "normalized": true, "rstrip": false, "single_word": false}, "cls_token": {"__type": "AddedToken", "content": "<s>", "lstrip": false, "normalized": true, "rstri... | {
"auto_model": "AutoModelForMaskedLM",
"custom_class": null,
"pipeline_tag": "fill-mask",
"processor": "AutoTokenizer"
} | {"base_model": null, "datasets": null, "eval_results": null, "language": "en", "library_name": null, "license": "apache-2.0", "license_name": null, "license_link": null, "metrics": null, "model_name": null, "pipeline_tag": null, "tags": ["climate"]} | # Model Card for distilroberta-base-climate-f
## Model Description
This is the ClimateBERT language model based on the FULL-SELECT sample selection strategy.
*Note: We generally recommend choosing this language model over those based on the other sample selection strategies (unless you have good reasons not to). Th... | null | [
"apache-2.0"
] | null | [
"en"
] | 82,351,430 | null | null | [
"roberta",
"AutoModelForMaskedLM",
"RobertaForMaskedLM"
] | [
"fill-mask"
] | [
"text"
] | [
"text"
] | [
"logits"
] |
65ccd54c1d6b1a8361b2b2c4 | 88cd37e502d27a0a | 0e7bc0977f200d1c | 32,000 | BPE | 58,980 | true | false | true | true | 3 | Sequence | null | Sequence | [
"Prepend",
"Replace"
] | null | [
"Replace",
"ByteFallback",
"Fuse",
"Strip"
] | 88 | mlabonne/AlphaMonarch-7B | mlabonne | {
"models": [
{
"_id": "65cc43d5632959d6630da5f8",
"id": "mlabonne/NeuralMonarch-7B"
}
],
"relation": "finetune"
} | 13,004 | 286,349 | False | 2024-02-14T14:59:24Z | 2024-03-28T21:05:30Z | transformers | 148 | 0 | [{"name": "AlphaMonarch-7B", "results": [{"task": {"type": "text-generation", "name": "Text Generation"}, "dataset": {"name": "AI2 Reasoning Challenge (25-Shot)", "type": "ai2_arc", "config": "ARC-Challenge", "split": "test", "args": {"num_few_shot": 25}}, "metrics": [{"type": "acc_norm", "value": 73.04, "name": "norma... | text-generation | {"parameters": {"F16": 7241732096}, "total": 7241732096} | [
".gitattributes",
"README.md",
"config.json",
"generation_config.json",
"model-00001-of-00003.safetensors",
"model-00002-of-00003.safetensors",
"model-00003-of-00003.safetensors",
"model.safetensors.index.json",
"special_tokens_map.json",
"tokenizer.json",
"tokenizer.model",
"tokenizer_config.... | 3de065d84411d74e5b3590f67f52b0b71faf6161 | [
"transformers",
"safetensors",
"mistral",
"text-generation",
"merge",
"lazymergekit",
"dpo",
"rlhf",
"conversational",
"en",
"base_model:mlabonne/NeuralMonarch-7B",
"base_model:finetune:mlabonne/NeuralMonarch-7B",
"license:cc-by-nc-4.0",
"model-index",
"text-generation-inference",
"end... | null | {"architectures": ["MistralForCausalLM"], "model_type": "mistral", "tokenizer_config": {"bos_token": "<s>", "chat_template": "{% for message in messages %}{{bos_token + message['role'] + '\n' + message['content'] + eos_token + '\n'}}{% endfor %}{% if add_generation_prompt %}{{ bos_token + 'assistant\n' }}{% endif %}", ... | {
"auto_model": "AutoModelForCausalLM",
"custom_class": null,
"pipeline_tag": "text-generation",
"processor": "AutoTokenizer"
} | {"base_model": ["mlabonne/NeuralMonarch-7B"], "language": ["en"], "license": "cc-by-nc-4.0", "tags": ["merge", "lazymergekit", "dpo", "rlhf"], "dataset": ["mlabonne/truthy-dpo-v0.1", "mlabonne/distilabel-intel-orca-dpo-pairs", "mlabonne/chatml-OpenHermes2.5-dpo-binarized-alpha"], "model-index": [{"name": "AlphaMonarch-... | 
# 👑 AlphaMonarch-7B
**tl;dr: AlphaMonarch-7B is a new DPO merge that retains all the reasoning abilities of the very best merges and significantly improves its conversational abilities. Kind of th... | null | [
"cc-by-nc-4.0"
] | null | [
"en"
] | 7,241,732,096 | null | null | [
"AutoModelForCausalLM",
"mistral",
"MistralForCausalLM"
] | [
"text-generation"
] | [
"text"
] | [
"text"
] | [
"text"
] |
6493b44698b58d348d46960f | ec935c75e710b6a1 | dc945455af795596 | 32,000 | WordPiece | null | true | true | true | true | 5 | BertNormalizer | BertPreTokenizer | WordPiece | [
"BertNormalizer"
] | [
"BertPreTokenizer"
] | [
"WordPiece"
] | 680 | pongjin/roberta_with_kornli | pongjin | null | 38 | 227,627 | False | 2023-06-22T02:39:02Z | 2023-06-22T05:53:14Z | transformers | 7 | 0 | null | zero-shot-classification | null | [
".gitattributes",
"README.md",
"config.json",
"pytorch_model.bin",
"special_tokens_map.json",
"tokenizer.json",
"tokenizer_config.json",
"training_args.bin",
"vocab.txt"
] | 138378c1fb502754eb27a699a8ad71955c4d9668 | [
"transformers",
"pytorch",
"roberta",
"text-classification",
"zero-shot-classification",
"ko",
"dataset:kor_nli",
"license:apache-2.0",
"endpoints_compatible",
"region:us"
] | null | {"architectures": ["RobertaForSequenceClassification"], "model_type": "roberta", "tokenizer_config": {"bos_token": "[CLS]", "cls_token": "[CLS]", "eos_token": "[SEP]", "mask_token": "[MASK]", "pad_token": "[PAD]", "sep_token": "[SEP]", "unk_token": "[UNK]"}} | {
"auto_model": "AutoModelForSequenceClassification",
"custom_class": null,
"pipeline_tag": "text-classification",
"processor": "AutoTokenizer"
} | {"base_model": null, "datasets": ["kor_nli"], "eval_results": null, "language": ["ko"], "library_name": null, "license": "apache-2.0", "license_name": null, "license_link": null, "metrics": ["accuracy"], "model_name": null, "pipeline_tag": "zero-shot-classification", "tags": null} | **This model has been referred to the following link : https://github.com/Huffon/klue-transformers-tutorial.git**
해당 모델은 위 깃허브를 참고하여 klue/roberta-base 모델을 kor_nli 의 mnli, xnli로 파인튜닝한 모델입니다.
| train_loss | val_loss | acc | epoch | batch | lr |
| --- | --- | --- | --- | --- | --- |
| 0.326 | 0.538 | 0.811 | 3 | 32 | ... | null | [
"apache-2.0"
] | [
"kor_nli"
] | [
"ko"
] | null | null | [
"accuracy"
] | [
"roberta",
"AutoModelForSequenceClassification",
"RobertaForSequenceClassification"
] | [
"zero-shot-classification",
"text-classification"
] | [
"text"
] | [
"text"
] | [
"logits"
] |
655fa5ba0ec0e1618557bf75 | 601ce15c496f4c84 | 70bd27c212bc339c | 50,265 | BPE | 50,000 | false | true | true | true | 5 | null | ByteLevel | ByteLevel | null | [
"ByteLevel"
] | [
"ByteLevel"
] | 681 | ilsilfverskiold/tech-keywords-extractor | ilsilfverskiold | {
"models": [
{
"_id": "621ffdc136468d709f17adb9",
"id": "facebook/bart-large"
}
],
"relation": "finetune"
} | 481 | 236,285 | False | 2023-11-23T19:19:22Z | 2023-11-29T15:17:47Z | transformers | 38 | 0 | [{"name": "tech-keyword-extractor", "results": []}] | null | {"parameters": {"F32": 406341721}, "total": 406341721} | [
".gitattributes",
"README.md",
"config.json",
"generation_config.json",
"merges.txt",
"model.safetensors",
"runs/Nov23_19-02-52_43cd5a96d17e/events.out.tfevents.1700766178.43cd5a96d17e.6371.0",
"runs/Nov23_19-12-17_43cd5a96d17e/events.out.tfevents.1700766738.43cd5a96d17e.6371.1",
"runs/Nov29_13-15-4... | 2f1ab22c4b291db80c5f0bc4ad57236240fb0560 | [
"transformers",
"tensorboard",
"safetensors",
"bart",
"text2text-generation",
"generated_from_trainer",
"base_model:facebook/bart-large",
"base_model:finetune:facebook/bart-large",
"license:apache-2.0",
"endpoints_compatible",
"region:us"
] | null | {"architectures": ["BartForConditionalGeneration"], "model_type": "bart", "tokenizer_config": {"bos_token": "<s>", "cls_token": "<s>", "eos_token": "</s>", "mask_token": "<mask>", "pad_token": "<pad>", "sep_token": "</s>", "unk_token": "<unk>"}} | {
"auto_model": "AutoModelForSeq2SeqLM",
"custom_class": null,
"pipeline_tag": "text2text-generation",
"processor": "AutoTokenizer"
} | {"base_model": "facebook/bart-large", "datasets": null, "eval_results": [], "language": null, "library_name": null, "license": "apache-2.0", "license_name": null, "license_link": null, "metrics": null, "model_name": "tech-keyword-extractor", "pipeline_tag": null, "tags": ["generated_from_trainer"]} | <!-- This model card has been generated automatically according to the information the Trainer had access to. You
should probably proofread and complete it, then remove this comment. -->
# tech-keyword-extractor
This model is a fine-tuned version of [facebook/bart-large](https://huggingface.co/facebook/bart-large) on... | null | [
"apache-2.0"
] | null | null | 406,341,721 | null | null | [
"bart",
"BartForConditionalGeneration",
"AutoModelForSeq2SeqLM"
] | [
"text2text-generation"
] | null | null | null |
63d224c11d49cad8abbcc345 | fdd00aae2081d7ca | ef4806e2ade9022f | 32,100 | Unigram | null | true | true | true | true | 103 | Sequence | Metaspace | Metaspace | [
"Precompiled",
"Replace"
] | [
"Metaspace"
] | [
"Metaspace"
] | 682 | juierror/flan-t5-text2sql-with-schema | juierror | null | 132 | 225,244 | False | 2023-01-26T06:59:13Z | 2024-04-25T06:17:31Z | transformers | 29 | 0 | null | null | {"parameters": {"F32": 247577856}, "total": 247577856} | [
".gitattributes",
"README.md",
"config.json",
"model.safetensors",
"pytorch_model.bin",
"special_tokens_map.json",
"tokenizer.json",
"tokenizer_config.json"
] | 08236376ea4e04ca713e395f90acaa9e2df62d0a | [
"transformers",
"pytorch",
"safetensors",
"t5",
"text2text-generation",
"en",
"dataset:wikisql",
"license:apache-2.0",
"text-generation-inference",
"endpoints_compatible",
"deploy:azure",
"region:us"
] | null | {"architectures": ["T5ForConditionalGeneration"], "model_type": "t5", "tokenizer_config": {"eos_token": "</s>", "pad_token": "<pad>", "unk_token": "<unk>"}} | {
"auto_model": "AutoModelForSeq2SeqLM",
"custom_class": null,
"pipeline_tag": "text2text-generation",
"processor": "AutoTokenizer"
} | {"base_model": null, "datasets": ["wikisql"], "eval_results": null, "language": "en", "library_name": null, "license": "apache-2.0", "license_name": null, "license_link": null, "metrics": null, "model_name": null, "pipeline_tag": null, "tags": null, "widget": [{"text": "question: get people name with age equal 25 table... | There are an upgraded version that support multiple tables and support "<" sign [here](https://huggingface.co/juierror/flan-t5-text2sql-with-schema-v2).
# How to use
```python
from typing import List
from transformers import AutoTokenizer, AutoModelForSeq2SeqLM
tokenizer = AutoTokenizer.from_pretrained("juierror/flan... | null | [
"apache-2.0"
] | [
"wikisql"
] | [
"en"
] | 247,577,856 | null | null | [
"t5",
"T5ForConditionalGeneration",
"AutoModelForSeq2SeqLM"
] | [
"text2text-generation"
] | null | null | null |
687803f7018d8a765752b7af | 1f077a9a0005c931 | dd84a2b1ff97657d | 250,002 | Unigram | null | true | true | true | true | 5 | Precompiled | Sequence | Metaspace | [
"Precompiled"
] | [
"WhitespaceSplit",
"Metaspace"
] | [
"Metaspace"
] | 230 | OpenMed/OpenMed-NER-PharmaDetect-ElectraMed-560M | OpenMed | null | 94,847 | 597,135 | False | 2025-07-16T19:56:39Z | 2025-08-05T09:37:41Z | transformers | 0 | 0 | null | token-classification | {"parameters": {"BF16": 558843907}, "total": 558843907} | [
".gitattributes",
"README.md",
"config.json",
"model.safetensors",
"openmed_vs_sota_grouped_bars.png",
"sentencepiece.bpe.model",
"special_tokens_map.json",
"test_results.json",
"tokenizer.json",
"tokenizer_config.json"
] | de8edc98ae45098e3aecd3f966613a84e2e19d90 | [
"transformers",
"safetensors",
"xlm-roberta",
"token-classification",
"named-entity-recognition",
"biomedical-nlp",
"chemical-entity-recognition",
"drug-discovery",
"pharmacology",
"biocuration",
"chem",
"en",
"arxiv:2508.01630",
"license:apache-2.0",
"endpoints_compatible",
"region:us... | null | {"architectures": ["XLMRobertaForTokenClassification"], "model_type": "xlm-roberta", "tokenizer_config": {"bos_token": "<s>", "cls_token": "<s>", "eos_token": "</s>", "mask_token": "<mask>", "pad_token": "<pad>", "sep_token": "</s>", "unk_token": "<unk>"}} | {
"auto_model": "AutoModelForTokenClassification",
"custom_class": null,
"pipeline_tag": "token-classification",
"processor": "AutoTokenizer"
} | {"base_model": null, "datasets": null, "eval_results": null, "language": ["en"], "library_name": null, "license": "apache-2.0", "license_name": null, "license_link": null, "metrics": null, "model_name": null, "pipeline_tag": null, "tags": ["token-classification", "named-entity-recognition", "biomedical-nlp", "transform... | null | null | [
"apache-2.0"
] | null | [
"en"
] | 558,843,907 | null | null | [
"XLMRobertaForTokenClassification",
"AutoModelForTokenClassification",
"xlm-roberta"
] | [
"token-classification"
] | [
"text"
] | [
"text"
] | [
"logits"
] |
621ffdc136468d709f17c92a | 885d37f387c13c96 | cdf1496e23f46b77 | 32,103 | Unigram | null | true | true | true | true | 103 | Sequence | Sequence | Metaspace | [
"Nmt",
"NFKC",
"Replace",
"Lowercase"
] | [
"Metaspace",
"Digits",
"Punctuation"
] | [
"Metaspace"
] | 683 | gsarti/it5-base-news-summarization | gsarti | null | 299 | 239,554 | False | 2022-03-02T23:29:05Z | 2022-10-18T13:43:57Z | transformers | 6 | 0 | [{"name": "it5-base-news-summarization", "results": [{"task": {"type": "news-summarization", "name": "News Summarization"}, "dataset": {"type": "newssum-it", "name": "NewsSum-IT"}, "metrics": [{"type": "rouge1", "value": 0.339, "name": "Test Rouge1", "verified": false}, {"type": "rouge2", "value": 0.16, "name": "Test R... | summarization | null | [
".gitattributes",
"README.md",
"config.json",
"events.out.tfevents.1642260324.t1v-n-9e38d79e-w-0.1294614.0.v2",
"flax_model.msgpack",
"pytorch_model.bin",
"special_tokens_map.json",
"spiece.model",
"tf_model.h5",
"tokenizer.json",
"tokenizer_config.json"
] | 291a73c2d8eaa00da38801a0795a89f4cd60823a | [
"transformers",
"pytorch",
"tf",
"jax",
"tensorboard",
"t5",
"text2text-generation",
"italian",
"sequence-to-sequence",
"fanpage",
"ilpost",
"summarization",
"it",
"dataset:ARTeLab/fanpage",
"dataset:ARTeLab/ilpost",
"arxiv:2203.03759",
"license:apache-2.0",
"model-index",
"co2_e... | null | {"architectures": ["T5ForConditionalGeneration"], "model_type": "t5", "tokenizer_config": {"eos_token": "</s>", "unk_token": "<unk>", "pad_token": "<pad>"}} | {
"auto_model": "AutoModelForSeq2SeqLM",
"custom_class": null,
"pipeline_tag": "text2text-generation",
"processor": "AutoTokenizer"
} | {"datasets": ["ARTeLab/fanpage", "ARTeLab/ilpost"], "language": ["it"], "license": "apache-2.0", "metrics": ["rouge"], "tags": ["italian", "sequence-to-sequence", "fanpage", "ilpost", "summarization"], "widget": [{"text": "Non lo vuole sposare. E\u2019 quanto emerge all\u2019interno dell\u2019ultima intervista di Raffa... | # IT5 Base for News Summarization ✂️🗞️ 🇮🇹
This repository contains the checkpoint for the [IT5 Base](https://huggingface.co/gsarti/it5-base) model fine-tuned on news summarization on the [Fanpage](https://huggingface.co/datasets/ARTeLab/fanpage) and [Il Post](https://huggingface.co/datasets/ARTeLab/ilpost) corpora ... | null | [
"apache-2.0"
] | [
"ARTeLab/fanpage",
"ARTeLab/ilpost"
] | [
"it"
] | null | null | [
"rouge"
] | [
"t5",
"T5ForConditionalGeneration",
"AutoModelForSeq2SeqLM"
] | [
"text2text-generation",
"summarization"
] | [
"text"
] | [
"text"
] | [
"text"
] |
66a106d442c11f1e0002b8bd | 6e6a83dc4b556c95 | a1f1bd381dcb9329 | 128,256 | BPE | 280,147 | false | true | true | true | 256 | null | Sequence | ByteLevel | null | [
"Split",
"ByteLevel"
] | [
"ByteLevel"
] | 111 | AIDC-AI/Ovis1.5-Llama3-8B | AIDC-AI | null | 38 | 224,683 | False | 2024-07-24T13:51:16Z | 2025-02-26T10:51:48Z | transformers | 27 | 0 | null | image-text-to-text | null | [
".gitattributes",
"README.md",
"config.json",
"configuration_ovis.py",
"generation_config.json",
"modeling_ovis.py",
"preprocessor_config.json",
"pytorch_model-00001-of-00004.bin",
"pytorch_model-00002-of-00004.bin",
"pytorch_model-00003-of-00004.bin",
"pytorch_model-00004-of-00004.bin",
"pyto... | 96e1ad0c86847b123325b8cad3632014de603133 | [
"transformers",
"pytorch",
"ovis",
"text-generation",
"MLLM",
"image-text-to-text",
"conversational",
"custom_code",
"dataset:AIDC-AI/Ovis-dataset",
"arxiv:2405.20797",
"license:apache-2.0",
"region:us"
] | null | {"architectures": ["Ovis"], "auto_map": {"AutoConfig": "configuration_ovis.OvisConfig", "AutoModelForCausalLM": "modeling_ovis.Ovis"}, "model_type": "ovis", "tokenizer_config": {"bos_token": "<|begin_of_text|>", "chat_template": "{% set loop_messages = messages %}{% for message in loop_messages %}{% set content = '<|st... | {
"auto_model": "AutoModelForCausalLM",
"custom_class": "modeling_ovis.Ovis",
"pipeline_tag": "text-generation",
"processor": null
} | {"base_model": null, "datasets": ["AIDC-AI/Ovis-dataset"], "eval_results": null, "language": null, "library_name": "transformers", "license": "apache-2.0", "license_name": null, "license_link": null, "metrics": null, "model_name": null, "pipeline_tag": "image-text-to-text", "tags": ["MLLM"]} | <span style="color: #ED7D31; font-size: 24px;">It is recommended to use the latest version: [Ovis2](https://huggingface.co/collections/AIDC-AI/ovis2-67ab36c7e497429034874464).</span>
## Introduction
Ovis is a novel Multimodal Large Language Model (MLLM) architecture, designed to structurally align visual and textual e... | null | [
"apache-2.0"
] | [
"AIDC-AI/Ovis-dataset"
] | null | null | null | null | [
"ovis",
"AutoModelForCausalLM",
"modeling_ovis.Ovis",
"Ovis"
] | [
"image-text-to-text",
"text-generation"
] | [
"text",
"multimodal"
] | [
"text",
"image"
] | [
"text"
] |
64e2f69558579025cb925d1c | e23b6bdbe047bb7e | 8bd7d71767538b82 | 32,000 | BPE | 61,249 | true | false | true | true | 3 | Sequence | null | Sequence | [
"Prepend",
"Replace"
] | null | [
"Replace",
"ByteFallback",
"Fuse",
"Strip"
] | 46 | yujiepan/llama-2-tiny-random | yujiepan | null | 14,659 | 261,539 | False | 2023-08-21T05:31:01Z | 2024-04-19T13:22:10Z | transformers | 1 | 0 | null | text-generation | {"parameters": {"F32": 2, "F16": 513048}, "total": 513050} | [
".gitattributes",
"README.md",
"config.json",
"generation_config.json",
"model.safetensors",
"openvino_model.bin",
"openvino_model.xml",
"pytorch_model.bin",
"special_tokens_map.json",
"tokenizer.json",
"tokenizer.model",
"tokenizer_config.json"
] | 74bb065d6381fdf9fcde5896cb32267ba2c0ee0a | [
"transformers",
"pytorch",
"safetensors",
"openvino",
"llama",
"text-generation",
"conversational",
"text-generation-inference",
"endpoints_compatible",
"deploy:azure",
"region:us"
] | null | {"architectures": ["LlamaForCausalLM"], "model_type": "llama", "tokenizer_config": {"bos_token": "<s>", "chat_template": "{% if messages[0]['role'] == 'system' %}{% set loop_messages = messages[1:] %}{% set system_message = messages[0]['content'] %}{% else %}{% set loop_messages = messages %}{% set system_message = fal... | {
"auto_model": "AutoModelForCausalLM",
"custom_class": null,
"pipeline_tag": "text-generation",
"processor": "AutoTokenizer"
} | {"base_model": null, "datasets": null, "eval_results": null, "language": null, "library_name": "transformers", "license": null, "license_name": null, "license_link": null, "metrics": null, "model_name": null, "pipeline_tag": "text-generation", "tags": null, "inference": true, "widget": [{"text": "Hello!", "example_titl... | # yujiepan/llama-2-tiny-random
This model is **randomly initialized**, using the config from [meta-llama/Llama-2-7b-chat-hf](https://huggingface.co/yujiepan/llama-2-tiny-random/blob/main/config.json) but with the following modifications:
```json
{
"hidden_size": 8,
"intermediate_size": 32,
"num_attention_heads"... | null | null | null | null | 513,050 | null | null | [
"AutoModelForCausalLM",
"llama",
"LlamaForCausalLM"
] | [
"text-generation"
] | [
"text"
] | [
"text"
] | [
"text"
] |
621ffdc136468d709f17cabf | 71140a663949f258 | 8a01c02d4d0a401c | 119,547 | WordPiece | null | true | true | true | true | 5 | BertNormalizer | BertPreTokenizer | WordPiece | [
"BertNormalizer"
] | [
"BertPreTokenizer"
] | [
"WordPiece"
] | 9 | jb2k/bert-base-multilingual-cased-language-detection | jb2k | null | 415 | 235,901 | False | 2022-03-02T23:29:05Z | 2021-11-24T01:36:01Z | transformers | 14 | 0 | null | text-classification | null | [
".gitattributes",
"README.md",
"config.json",
"pytorch_model.bin",
"special_tokens_map.json",
"tokenizer.json",
"tokenizer_config.json",
"vocab.txt"
] | aa4473be53d456ad2ae216a2048f002dae00c920 | [
"transformers",
"pytorch",
"bert",
"text-classification",
"text-embeddings-inference",
"endpoints_compatible",
"deploy:azure",
"region:us"
] | null | {"architectures": ["BertForSequenceClassification"], "model_type": "bert", "tokenizer_config": {"unk_token": "[UNK]", "sep_token": "[SEP]", "pad_token": "[PAD]", "cls_token": "[CLS]", "mask_token": "[MASK]"}} | {
"auto_model": "AutoModelForSequenceClassification",
"custom_class": null,
"pipeline_tag": "text-classification",
"processor": "AutoTokenizer"
} | null | # bert-base-multilingual-cased-language-detection
A model for language detection with support for 45 languages
## Model description
This model was created by fine-tuning
[bert-base-multilingual-cased](https://huggingface.co/bert-base-multilingual-cased) on the [common language](https://huggingface.co/datasets/common_l... | null | null | null | null | null | null | null | [
"BertForSequenceClassification",
"bert",
"AutoModelForSequenceClassification"
] | [
"text-classification"
] | [
"text"
] | [
"text"
] | [
"logits"
] |
6877f6a2733834bcbc300bdd | d13dc58d71bbfa73 | 291a9305acaae14c | 30,522 | WordPiece | null | true | true | true | true | 5 | BertNormalizer | BertPreTokenizer | WordPiece | [
"BertNormalizer"
] | [
"BertPreTokenizer"
] | [
"WordPiece"
] | 413 | OpenMed/OpenMed-NER-ChemicalDetect-PubMed-109M | OpenMed | null | 91,915 | 588,623 | False | 2025-07-16T18:59:46Z | 2025-08-05T09:34:42Z | transformers | 2 | 0 | null | token-classification | {"parameters": {"BF16": 108893955}, "total": 108893955} | [
".gitattributes",
"README.md",
"config.json",
"model.safetensors",
"openmed_vs_sota_grouped_bars.png",
"special_tokens_map.json",
"test_results.json",
"tokenizer.json",
"tokenizer_config.json",
"vocab.txt"
] | 78f35d7364748515e098a95a857d4c88c38902ae | [
"transformers",
"safetensors",
"bert",
"token-classification",
"named-entity-recognition",
"biomedical-nlp",
"chemical-entity-recognition",
"drug-discovery",
"pharmacology",
"chemistry",
"chem",
"en",
"arxiv:2508.01630",
"license:apache-2.0",
"endpoints_compatible",
"region:us"
] | null | {"architectures": ["BertForTokenClassification"], "model_type": "bert", "tokenizer_config": {"cls_token": "[CLS]", "mask_token": "[MASK]", "pad_token": "[PAD]", "sep_token": "[SEP]", "unk_token": "[UNK]"}} | {
"auto_model": "AutoModelForTokenClassification",
"custom_class": null,
"pipeline_tag": "token-classification",
"processor": "AutoTokenizer"
} | {"base_model": null, "datasets": null, "eval_results": null, "language": ["en"], "library_name": null, "license": "apache-2.0", "license_name": null, "license_link": null, "metrics": null, "model_name": null, "pipeline_tag": null, "tags": ["token-classification", "named-entity-recognition", "biomedical-nlp", "transform... | null | null | [
"apache-2.0"
] | null | [
"en"
] | 108,893,955 | null | null | [
"AutoModelForTokenClassification",
"BertForTokenClassification",
"bert"
] | [
"token-classification"
] | [
"text"
] | [
"text"
] | [
"logits"
] |
621ffdc036468d709f177396 | c4804bb04c995ef1 | ef4806e2ade9022f | 32,100 | Unigram | null | true | true | true | true | 103 | Precompiled | Sequence | Metaspace | [
"Precompiled"
] | [
"WhitespaceSplit",
"Metaspace"
] | [
"Metaspace"
] | 684 | Salesforce/mixqg-large | Salesforce | null | 19 | 224,043 | False | 2022-03-02T23:29:04Z | 2025-01-14T18:58:31Z | transformers | 6 | 0 | null | null | null | [
".gitattributes",
"README.md",
"config.json",
"pytorch_model.bin",
"special_tokens_map.json",
"spiece.model",
"tokenizer.json",
"tokenizer_config.json"
] | 18db77a2c6421be446046673d9cb96af3c7044e5 | [
"transformers",
"pytorch",
"t5",
"text2text-generation",
"en",
"arxiv:2110.08175",
"text-generation-inference",
"endpoints_compatible",
"region:us"
] | null | {"architectures": ["T5ForConditionalGeneration"], "model_type": "t5", "tokenizer_config": {"eos_token": "</s>", "unk_token": "<unk>", "pad_token": "<pad>"}} | {
"auto_model": "AutoModelForSeq2SeqLM",
"custom_class": null,
"pipeline_tag": "text2text-generation",
"processor": "AutoTokenizer"
} | {"base_model": null, "datasets": null, "eval_results": null, "language": "en", "library_name": null, "license": null, "license_name": null, "license_link": null, "metrics": null, "model_name": null, "pipeline_tag": null, "tags": null, "widget": [{"text": "Robert Boyle \\\\n In the late 17th century, Robert Boyle proved... | # MixQG (large-sized model)
MixQG is a new question generation model pre-trained on a collection of QA datasets with a mix of answer types. It was introduced in the paper [MixQG: Neural Question Generation with Mixed Answer Types](https://arxiv.org/abs/2110.08175) and the associated code is released in [this](https://... | null | null | null | [
"en"
] | null | null | null | [
"t5",
"T5ForConditionalGeneration",
"AutoModelForSeq2SeqLM"
] | [
"text2text-generation"
] | null | null | null |
66e97b979b3b62d76297d902 | 848b60b6cd304b65 | ffc911e785abe60e | 151,665 | BPE | 151,387 | true | true | true | true | 22 | NFC | Sequence | ByteLevel | [
"NFC"
] | [
"Split",
"ByteLevel"
] | [
"ByteLevel"
] | 15 | Qwen/Qwen2.5-14B-Instruct-GPTQ-Int8 | Qwen | {
"models": [
{
"_id": "66e81cdaa3681387ffc12b55",
"id": "Qwen/Qwen2.5-14B-Instruct"
}
],
"relation": "quantized"
} | 81,257 | 384,906 | False | 2024-09-17T12:52:39Z | 2024-10-09T12:27:32Z | transformers | 24 | 2 | null | text-generation | {"parameters": {"F16": 1557976064, "I32": 13212057600}, "total": 14770033664} | [
".gitattributes",
"LICENSE",
"README.md",
"config.json",
"generation_config.json",
"merges.txt",
"model-00001-of-00005.safetensors",
"model-00002-of-00005.safetensors",
"model-00003-of-00005.safetensors",
"model-00004-of-00005.safetensors",
"model-00005-of-00005.safetensors",
"model.safetensor... | 801d1799b049765aebe175acb5d529c372e7b1b9 | [
"transformers",
"safetensors",
"qwen2",
"text-generation",
"chat",
"conversational",
"en",
"arxiv:2309.00071",
"arxiv:2407.10671",
"base_model:Qwen/Qwen2.5-14B-Instruct",
"base_model:quantized:Qwen/Qwen2.5-14B-Instruct",
"license:apache-2.0",
"text-generation-inference",
"endpoints_compati... | null | {"architectures": ["Qwen2ForCausalLM"], "model_type": "qwen2", "quantization_config": {"bits": 8, "quant_method": "gptq"}, "tokenizer_config": {"bos_token": null, "chat_template": "{%- if tools %}\n {{- '<|im_start|>system\\n' }}\n {%- if messages[0]['role'] == 'system' %}\n {{- messages[0]['content'] }}\n... | {
"auto_model": "AutoModelForCausalLM",
"custom_class": null,
"pipeline_tag": "text-generation",
"processor": "AutoTokenizer"
} | {"base_model": "Qwen/Qwen2.5-14B-Instruct", "datasets": null, "eval_results": null, "language": ["en"], "library_name": "transformers", "license": "apache-2.0", "license_name": null, "license_link": "https://huggingface.co/Qwen/Qwen2.5-14B-Instruct-GPTQ-Int8/blob/main/LICENSE", "metrics": null, "model_name": null, "pip... | # Qwen2.5-14B-Instruct-GPTQ-Int8
## Introduction
Qwen2.5 is the latest series of Qwen large language models. For Qwen2.5, we release a number of base language models and instruction-tuned language models ranging from 0.5 to 72 billion parameters. Qwen2.5 brings the following improvements upon Qwen2:
- Significantly ... | null | [
"apache-2.0",
"https://huggingface.co/Qwen/Qwen2.5-14B-Instruct-GPTQ-Int8/blob/main/LICENSE"
] | null | [
"en"
] | 14,770,033,664 | null | null | [
"AutoModelForCausalLM",
"Qwen2ForCausalLM",
"qwen2"
] | [
"text-generation"
] | [
"text"
] | [
"text"
] | [
"text"
] |
687a0955ab1a64b84480ade2 | b3310d158ab6e0dc | 66be3297e0980489 | 28,895 | WordPiece | null | true | true | true | true | 5 | BertNormalizer | BertPreTokenizer | WordPiece | [
"BertNormalizer"
] | [
"BertPreTokenizer"
] | [
"WordPiece"
] | 409 | OpenMed/OpenMed-NER-ProteinDetect-BioMed-335M | OpenMed | null | 90,662 | 583,277 | False | 2025-07-18T08:44:05Z | 2025-08-05T09:44:20Z | transformers | 4 | 0 | null | token-classification | {"parameters": {"BF16": 334103563}, "total": 334103563} | [
".gitattributes",
"README.md",
"config.json",
"model.safetensors",
"openmed_vs_sota_grouped_bars.png",
"special_tokens_map.json",
"test_results.json",
"tokenizer.json",
"tokenizer_config.json",
"vocab.txt"
] | ccf144261ac37861e6bba0790e7e53f44bf5d7cf | [
"transformers",
"safetensors",
"bert",
"token-classification",
"named-entity-recognition",
"biomedical-nlp",
"protein-interactions",
"molecular-biology",
"biochemistry",
"systems-biology",
"protein",
"protein_complex",
"protein_enum",
"protein_familiy_or_group",
"protein_variant",
"en"... | null | {"architectures": ["BertForTokenClassification"], "model_type": "bert", "tokenizer_config": {"cls_token": "[CLS]", "mask_token": "[MASK]", "pad_token": "[PAD]", "sep_token": "[SEP]", "unk_token": "[UNK]"}} | {
"auto_model": "AutoModelForTokenClassification",
"custom_class": null,
"pipeline_tag": "token-classification",
"processor": "AutoTokenizer"
} | {"base_model": null, "datasets": null, "eval_results": null, "language": ["en"], "library_name": null, "license": "apache-2.0", "license_name": null, "license_link": null, "metrics": null, "model_name": null, "pipeline_tag": null, "tags": ["token-classification", "named-entity-recognition", "biomedical-nlp", "transform... | null | null | [
"apache-2.0"
] | null | [
"en"
] | 334,103,563 | null | null | [
"AutoModelForTokenClassification",
"BertForTokenClassification",
"bert"
] | [
"token-classification"
] | [
"text"
] | [
"text"
] | [
"logits"
] |
6877fdfa018d8a7657516cdd | fce4c9c0fb3bed35 | 1e78464774d502ca | 128,256 | BPE | 280,147 | false | true | true | true | 256 | null | Sequence | ByteLevel | null | [
"Split",
"ByteLevel"
] | [
"ByteLevel"
] | 658 | OpenMed/OpenMed-NER-GenomeDetect-EuroMed-212M | OpenMed | null | 91,754 | 584,238 | False | 2025-07-16T19:31:06Z | 2025-08-05T09:35:52Z | transformers | 0 | 0 | null | token-classification | {"parameters": {"BF16": 211768323}, "total": 211768323} | [
".gitattributes",
"README.md",
"config.json",
"configuration_eurobert.py",
"model.safetensors",
"modeling_eurobert.py",
"openmed_vs_sota_grouped_bars.png",
"special_tokens_map.json",
"test_results.json",
"tokenizer.json",
"tokenizer_config.json"
] | c99049d7cdcd45a8f1650c3a7a375535705993e6 | [
"transformers",
"safetensors",
"eurobert",
"token-classification",
"named-entity-recognition",
"biomedical-nlp",
"gene-recognition",
"protein-recognition",
"genomics",
"molecular-biology",
"gene/protein",
"custom_code",
"en",
"arxiv:2508.01630",
"license:apache-2.0",
"endpoints_compati... | null | {"architectures": ["EuroBertForTokenClassification"], "auto_map": {"AutoConfig": "configuration_eurobert.EuroBertConfig", "AutoModel": "modeling_eurobert.EuroBertModel", "AutoModelForMaskedLM": "modeling_eurobert.EuroBertForMaskedLM", "AutoModelForPreTraining": "modeling_eurobert.EuroBertPreTrainedModel", "AutoModelFor... | {
"auto_model": "AutoModelForTokenClassification",
"custom_class": null,
"pipeline_tag": "token-classification",
"processor": "AutoTokenizer"
} | {"base_model": null, "datasets": null, "eval_results": null, "language": ["en"], "library_name": null, "license": "apache-2.0", "license_name": null, "license_link": null, "metrics": null, "model_name": null, "pipeline_tag": null, "tags": ["token-classification", "named-entity-recognition", "biomedical-nlp", "transform... | null | null | [
"apache-2.0"
] | null | [
"en"
] | 211,768,323 | null | null | [
"AutoModelForTokenClassification",
"EuroBertForTokenClassification",
"eurobert"
] | [
"token-classification"
] | [
"text"
] | [
"text"
] | [
"logits"
] |
68780d83d4d3cb370d0d8e01 | fce4c9c0fb3bed35 | 1e78464774d502ca | 128,256 | BPE | 280,147 | false | true | true | true | 256 | null | Sequence | ByteLevel | null | [
"Split",
"ByteLevel"
] | [
"ByteLevel"
] | 658 | OpenMed/OpenMed-NER-ProteinDetect-EuroMed-212M | OpenMed | null | 92,176 | 586,616 | False | 2025-07-16T20:37:23Z | 2025-08-05T09:40:38Z | transformers | 0 | 0 | null | token-classification | {"parameters": {"BF16": 211774475}, "total": 211774475} | [
".gitattributes",
"README.md",
"config.json",
"configuration_eurobert.py",
"model.safetensors",
"modeling_eurobert.py",
"openmed_vs_sota_grouped_bars.png",
"special_tokens_map.json",
"test_results.json",
"tokenizer.json",
"tokenizer_config.json"
] | 534b9d8bdce07f282b4bd1176f4a1ea2228de47c | [
"transformers",
"safetensors",
"eurobert",
"token-classification",
"named-entity-recognition",
"biomedical-nlp",
"protein-interactions",
"molecular-biology",
"biochemistry",
"systems-biology",
"protein",
"protein_complex",
"protein_enum",
"protein_familiy_or_group",
"protein_variant",
... | null | {"architectures": ["EuroBertForTokenClassification"], "auto_map": {"AutoConfig": "configuration_eurobert.EuroBertConfig", "AutoModel": "modeling_eurobert.EuroBertModel", "AutoModelForMaskedLM": "modeling_eurobert.EuroBertForMaskedLM", "AutoModelForPreTraining": "modeling_eurobert.EuroBertPreTrainedModel", "AutoModelFor... | {
"auto_model": "AutoModelForTokenClassification",
"custom_class": null,
"pipeline_tag": "token-classification",
"processor": "AutoTokenizer"
} | {"base_model": null, "datasets": null, "eval_results": null, "language": ["en"], "library_name": null, "license": "apache-2.0", "license_name": null, "license_link": null, "metrics": null, "model_name": null, "pipeline_tag": null, "tags": ["token-classification", "named-entity-recognition", "biomedical-nlp", "transform... | null | null | [
"apache-2.0"
] | null | [
"en"
] | 211,774,475 | null | null | [
"AutoModelForTokenClassification",
"EuroBertForTokenClassification",
"eurobert"
] | [
"token-classification"
] | [
"text"
] | [
"text"
] | [
"logits"
] |
640f3a43b63b6f18522c1c6f | cb3f886e13ad7505 | 1f1d26e73b02d1f3 | 49,152 | BPE | 48,891 | false | true | false | true | 19 | null | Sequence | ByteLevel | null | [
"Digits",
"ByteLevel"
] | [
"ByteLevel"
] | 70 | bigcode/starencoder | bigcode | null | 673 | 283,391 | auto | 2023-03-13T14:59:15Z | 2023-05-10T14:52:27Z | transformers | 57 | 0 | null | null | null | [
".gitattributes",
"README.md",
"config.json",
"merges.txt",
"pytorch_model.bin",
"special_tokens_map.json",
"tokenizer.json",
"tokenizer_config.json",
"vocab.json"
] | ad54e8bf302bc64f8429b275def2e54c488c7fc9 | [
"transformers",
"pytorch",
"bert",
"pretraining",
"code",
"arxiv:1810.04805",
"endpoints_compatible",
"region:us"
] | null | {"architectures": ["BertForPreTraining"], "model_type": "bert", "tokenizer_config": {"bos_token": "<|endoftext|>", "eos_token": "<|endoftext|>", "unk_token": "<|endoftext|>"}} | {
"auto_model": "AutoModelForPreTraining",
"custom_class": null,
"pipeline_tag": "pretraining",
"processor": "AutoTokenizer"
} | {"base_model": null, "datasets": null, "eval_results": null, "language": ["code"], "library_name": null, "license": null, "license_name": null, "license_link": null, "metrics": null, "model_name": null, "pipeline_tag": null, "tags": null, "extra_gated_prompt": "## Model License Agreement\nPlease read the BigCode [OpenR... | null | null | null | null | [
"code"
] | null | null | null | [
"bert",
"AutoModelForPreTraining",
"BertForPreTraining"
] | [
"pretraining"
] | null | null | null |
64ad95bcb575c5e27211b27e | 457012c75249dfdc | 3013b08459453976 | 32,002 | BPE | 61,249 | true | false | true | true | 5 | Sequence | null | Sequence | [
"Prepend",
"Replace"
] | null | [
"Replace",
"ByteFallback",
"Fuse",
"Strip"
] | 685 | HuggingFaceM4/idefics-9b | HuggingFaceM4 | null | 1,863 | 339,459 | False | 2023-07-11T17:47:40Z | 2023-10-12T18:45:40Z | transformers | 47 | 0 | null | text-generation | {"parameters": {"F32": 8929682192}, "total": 8929682192} | [
".gitattributes",
"README.md",
"added_tokens.json",
"assets/Figure_Evals_IDEFICS.png",
"assets/IDEFICS.png",
"assets/Idefics_colab.png",
"assets/guarding_baguettes.png",
"config.json",
"generation_config.json",
"model-00001-of-00019.safetensors",
"model-00002-of-00019.safetensors",
"model-0000... | 4986969d084dd36ed0acf20990c64faa7e817df1 | [
"transformers",
"pytorch",
"safetensors",
"idefics",
"image-text-to-text",
"multimodal",
"text",
"image",
"image-to-text",
"text-generation",
"en",
"dataset:HuggingFaceM4/OBELICS",
"dataset:wikipedia",
"dataset:facebook/pmd",
"dataset:laion/laion2B-en",
"arxiv:2204.14198",
"arxiv:230... | null | {"architectures": ["IdeficsForVisionText2Text"], "model_type": "idefics", "tokenizer_config": {"bos_token": "<s>", "eos_token": "</s>", "pad_token": "<unk>", "unk_token": "<unk>", "use_default_system_prompt": true}} | {
"auto_model": "AutoModelForImageTextToText",
"custom_class": null,
"pipeline_tag": "image-text-to-text",
"processor": "AutoProcessor"
} | {"base_model": null, "datasets": ["HuggingFaceM4/OBELICS", "wikipedia", "facebook/pmd", "laion/laion2B-en"], "eval_results": null, "language": "en", "library_name": null, "license": "other", "license_name": null, "license_link": null, "metrics": null, "model_name": null, "pipeline_tag": "text-generation", "tags": ["mul... | <p align="center">
<img src="https://huggingface.co/HuggingFaceM4/idefics-80b/resolve/main/assets/IDEFICS.png" alt="Idefics-Obelics logo" width="200" height="100">
</p>
# IDEFICS
*How do I pronounce the model's name? Watch a [Youtube tutorial](https://www.youtube.com/watch?v=YKO0rWnPN2I&ab_channel=FrenchPronuncia... | null | [
"other"
] | [
"HuggingFaceM4/OBELICS",
"wikipedia",
"facebook/pmd",
"laion/laion2B-en"
] | [
"en"
] | 8,929,682,192 | null | null | [
"AutoModelForImageTextToText",
"idefics",
"IdeficsForVisionText2Text"
] | [
"image-text-to-text",
"image-to-text",
"text-generation"
] | [
"text",
"multimodal"
] | [
"text",
"image"
] | [
"text"
] |
621ffdc136468d709f17ce72 | 324d1780c7dcba21 | 9befc50479ed313c | 31,090 | WordPiece | null | true | true | true | true | 5 | BertNormalizer | BertPreTokenizer | WordPiece | [
"BertNormalizer"
] | [
"BertPreTokenizer"
] | [
"WordPiece"
] | 126 | jsylee/scibert_scivocab_uncased-finetuned-ner | jsylee | null | 4,948 | 245,817 | False | 2022-03-02T23:29:05Z | 2021-11-22T03:52:41Z | transformers | 16 | 0 | null | token-classification | null | [
".gitattributes",
".gitignore",
"README.md",
"config.json",
"pytorch_model.bin",
"special_tokens_map.json",
"tokenizer.json",
"tokenizer_config.json",
"training_args.bin",
"vocab.txt"
] | 609e6d9db9010d9a0780de954f23dd5c2fb0ed25 | [
"transformers",
"pytorch",
"bert",
"token-classification",
"Named Entity Recognition",
"SciBERT",
"Adverse Effect",
"Drug",
"Medical",
"en",
"dataset:ade_corpus_v2",
"endpoints_compatible",
"deploy:azure",
"region:us"
] | null | {"architectures": ["BertForTokenClassification"], "model_type": "bert", "tokenizer_config": {"unk_token": "[UNK]", "sep_token": "[SEP]", "pad_token": "[PAD]", "cls_token": "[CLS]", "mask_token": "[MASK]"}} | {
"auto_model": "AutoModelForTokenClassification",
"custom_class": null,
"pipeline_tag": "token-classification",
"processor": "AutoTokenizer"
} | {"base_model": null, "datasets": ["ade_corpus_v2"], "eval_results": null, "language": ["en"], "library_name": null, "license": null, "license_name": null, "license_link": null, "metrics": null, "model_name": null, "pipeline_tag": null, "tags": ["Named Entity Recognition", "SciBERT", "Adverse Effect", "Drug", "Medical"]... | This is a SciBERT-based model fine-tuned to perform Named Entity Recognition for drug names and adverse drug effects.
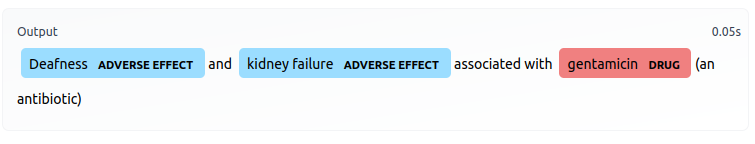
This model classifies input tokens into one of five classes:
- `B-DRUG`... | null | null | [
"ade_corpus_v2"
] | [
"en"
] | null | null | null | [
"AutoModelForTokenClassification",
"BertForTokenClassification",
"bert"
] | [
"token-classification"
] | [
"text"
] | [
"text"
] | [
"logits"
] |
621ffdc136468d709f180853 | 202d53a2dc42b584 | 02f3f31bfd3360f8 | 30,528 | WordPiece | null | true | true | true | true | 5 | BertNormalizer | BertPreTokenizer | WordPiece | [
"BertNormalizer"
] | [
"BertPreTokenizer"
] | [
"WordPiece"
] | 217 | squeezebert/squeezebert-mnli | squeezebert | null | 1,344 | 227,606 | False | 2022-03-02T23:29:05Z | 2020-12-11T22:02:13Z | transformers | 1 | 0 | null | null | null | [
".gitattributes",
"README.md",
"config.json",
"pytorch_model.bin",
"tokenizer.json",
"vocab.txt"
] | dc26cab55cf7cf386a1e711e36e3146362c7cb08 | [
"transformers",
"pytorch",
"squeezebert",
"arxiv:2006.11316",
"arxiv:1904.00962",
"endpoints_compatible",
"region:us"
] | null | {"model_type": "squeezebert"} | {
"auto_model": "AutoModel",
"custom_class": null,
"pipeline_tag": null,
"processor": null
} | null | # SqueezeBERT pretrained model
This model, `squeezebert-mnli`, has been pretrained for the English language using a masked language modeling (MLM) and Sentence Order Prediction (SOP) objective and finetuned on the [Multi-Genre Natural Language Inference (MNLI)](https://cims.nyu.edu/~sbowman/multinli/) dataset.
Squeeze... | null | null | null | null | null | null | null | [
"squeezebert",
"AutoModel"
] | [
null
] | null | null | null |
656e4d813b83d70c30e89c55 | 2cef78fb90b5be2d | 0363d4167c0e2f0e | 32,024 | BPE | 61,260 | true | false | true | true | 15 | Sequence | null | Sequence | [
"Prepend",
"Replace"
] | null | [
"Replace",
"ByteFallback",
"Fuse",
"Strip"
] | 686 | Nexusflow/NexusRaven-V2-13B | Nexusflow | {
"models": [
{
"_id": "64e7867286fc685a30ba3882",
"id": "codellama/CodeLlama-13b-Instruct-hf"
}
],
"relation": "finetune"
} | 96 | 222,389 | False | 2023-12-04T22:06:57Z | 2025-05-01T05:20:13Z | transformers | 470 | 0 | [{"name": "NexusRaven-13B", "results": []}] | text-generation | {"parameters": {"BF16": 13016110080}, "total": 13016110080} | [
".gitattributes",
"LICENSE.txt",
"NexusRaven.png",
"README.md",
"added_tokens.json",
"blog2-fc.png",
"config.json",
"generation_config.json",
"langdemo.py",
"model-00001-of-00003.safetensors",
"model-00002-of-00003.safetensors",
"model-00003-of-00003.safetensors",
"model.safetensors.index.js... | a6b84dc52f4c8f2cd61637f840066f376c629271 | [
"transformers",
"safetensors",
"llama",
"text-generation",
"function calling",
"arxiv:2308.12950",
"base_model:codellama/CodeLlama-13b-Instruct-hf",
"base_model:finetune:codellama/CodeLlama-13b-Instruct-hf",
"license:other",
"text-generation-inference",
"endpoints_compatible",
"region:us"
] | null | {"architectures": ["LlamaForCausalLM"], "model_type": "llama", "tokenizer_config": {"bos_token": {"__type": "AddedToken", "content": "<s>", "lstrip": false, "normalized": true, "rstrip": false, "single_word": false}, "eos_token": {"__type": "AddedToken", "content": "</s>", "lstrip": false, "normalized": true, "rstrip":... | {
"auto_model": "AutoModelForCausalLM",
"custom_class": null,
"pipeline_tag": "text-generation",
"processor": "AutoTokenizer"
} | {"base_model": "codellama/CodeLlama-13b-Instruct-hf", "datasets": null, "eval_results": [], "language": null, "library_name": null, "license": "other", "license_name": null, "license_link": null, "metrics": null, "model_name": "NexusRaven-13B", "pipeline_tag": null, "tags": ["function calling"]} | # NexusRaven-13B: Surpassing GPT-4 for Zero-shot Function Calling
<p align="center">
<a href="https://huggingface.co/Nexusflow" target="_blank">Nexusflow HF</a> - <a href="https://discord.gg/HDSVmNAs3y" target="_blank">Nexusflow Discord</a> - <a href="http://nexusflow.ai/blogs/ravenv2" target="_blank">NexusRaven-V2 blo... | null | [
"other"
] | null | null | 13,016,110,080 | null | null | [
"AutoModelForCausalLM",
"llama",
"LlamaForCausalLM"
] | [
"text-generation"
] | [
"text"
] | [
"text"
] | [
"text"
] |
65351792ed74ace633b0a20b | 53ecf467267e2824 | 535fa14da0af647c | 30,522 | WordPiece | null | true | true | true | true | 5 | BertNormalizer | BertPreTokenizer | WordPiece | [
"BertNormalizer"
] | [
"BertPreTokenizer"
] | [
"WordPiece"
] | 0 | SeanLee97/angle-bert-base-uncased-nli-en-v1 | SeanLee97 | null | 568 | 222,351 | False | 2023-10-22T12:37:38Z | 2023-10-22T13:02:56Z | transformers | 5 | 0 | null | feature-extraction | null | [
".gitattributes",
"README.md",
"added_tokens.json",
"config.json",
"pytorch_model.bin",
"special_tokens_map.json",
"tokenizer.json",
"tokenizer_config.json",
"vocab.txt"
] | 93b5216270e09ad9c05e7e407cc364f574aab4c2 | [
"transformers",
"pytorch",
"bert",
"feature-extraction",
"en",
"dataset:multi_nli",
"dataset:snli",
"arxiv:2309.12871",
"license:mit",
"text-embeddings-inference",
"endpoints_compatible",
"deploy:azure",
"region:us"
] | null | {"architectures": ["BertModel"], "model_type": "bert", "tokenizer_config": {"cls_token": "[CLS]", "mask_token": "[MASK]", "pad_token": "[PAD]", "sep_token": "[SEP]", "unk_token": "[UNK]"}} | {
"auto_model": "AutoModel",
"custom_class": null,
"pipeline_tag": "feature-extraction",
"processor": "AutoTokenizer"
} | {"base_model": null, "datasets": ["multi_nli", "snli"], "eval_results": null, "language": ["en"], "library_name": "transformers", "license": "mit", "license_name": null, "license_link": null, "metrics": ["spearmanr"], "model_name": null, "pipeline_tag": null, "tags": null} | # AnglE📐: Angle-optimized Text Embeddings
> It is Angle 📐, not Angel 👼.
🔥 A New SOTA Model for Semantic Textual Similarity!
Github: https://github.com/SeanLee97/AnglE
<a href="https://arxiv.org/abs/2309.12871">
<img src="https://img.shields.io/badge/Arxiv-2306.06843-yellow.svg?style=flat-square" alt="https... | null | [
"mit"
] | [
"multi_nli",
"snli"
] | [
"en"
] | null | null | [
"spearmanr"
] | [
"BertModel",
"AutoModel",
"bert"
] | [
"feature-extraction"
] | [
"multimodal"
] | [
"text"
] | [
"embeddings"
] |
66f3a54e5294d1cc7c2e5fea | a2538a1bec40dd72 | a84723c241d17887 | 100,283 | BPE | 100,000 | false | true | false | true | 27 | null | Sequence | ByteLevel | null | [
"Split",
"ByteLevel"
] | [
"ByteLevel"
] | 687 | allenai/Molmo-7B-O-0924 | allenai | {
"models": [
{
"_id": "6262c267cbebf7e1ac29e364",
"id": "openai/clip-vit-large-patch14-336"
}
],
"relation": "finetune"
} | 2,323 | 244,234 | False | 2024-09-25T05:53:18Z | 2025-10-09T00:04:57Z | transformers | 163 | 0 | null | image-text-to-text | {"parameters": {"F32": 7665032192}, "total": 7665032192} | [
".gitattributes",
"README.md",
"added_tokens.json",
"config.json",
"config_molmo.py",
"generation_config.json",
"image_preprocessing_molmo.py",
"merges.txt",
"model-00001-of-00007.safetensors",
"model-00002-of-00007.safetensors",
"model-00003-of-00007.safetensors",
"model-00004-of-00007.safete... | 7a8c4bf80c839c243a6908c6ebbb0f1ee576d7ca | [
"transformers",
"safetensors",
"molmo",
"text-generation",
"multimodal",
"olmo",
"pixmo",
"image-text-to-text",
"conversational",
"custom_code",
"en",
"arxiv:2409.17146",
"base_model:openai/clip-vit-large-patch14-336",
"base_model:finetune:openai/clip-vit-large-patch14-336",
"license:apa... | null | {"architectures": ["MolmoForCausalLM"], "auto_map": {"AutoConfig": "config_molmo.MolmoConfig", "AutoModelForCausalLM": "modeling_molmo.MolmoForCausalLM"}, "model_type": "molmo", "tokenizer_config": {"bos_token": "<|endoftext|>", "chat_template": "{% for message in messages -%}\n {%- if (loop.index % 2 == 1 and m... | {
"auto_model": "AutoModelForCausalLM",
"custom_class": "modeling_molmo.MolmoForCausalLM",
"pipeline_tag": "text-generation",
"processor": null
} | {"base_model": ["openai/clip-vit-large-patch14-336", "allenai/OLMo-7B-1124"], "datasets": null, "eval_results": null, "language": ["en"], "library_name": "transformers", "license": "apache-2.0", "license_name": null, "license_link": null, "metrics": null, "model_name": null, "pipeline_tag": "image-text-to-text", "tags"... | <img src="molmo_logo.png" alt="Logo for the Molmo Project" style="width: auto; height: 50px;">
# Molmo 7B-O
Molmo is a family of open vision-language models developed by the Allen Institute for AI.
Molmo models are trained on PixMo, a dataset of 1 million, highly-curated image-text pairs.
It has state-of-the-art pe... | null | [
"apache-2.0"
] | null | [
"en"
] | 7,665,032,192 | null | null | [
"MolmoForCausalLM",
"modeling_molmo.MolmoForCausalLM",
"AutoModelForCausalLM",
"molmo"
] | [
"image-text-to-text",
"text-generation"
] | [
"text",
"multimodal"
] | [
"text",
"image"
] | [
"text"
] |
6515ffbc3e5a12e0ceaefd75 | 5385e084548307e9 | 0e7bc0977f200d1c | 32,000 | BPE | 58,980 | true | false | true | true | 3 | Sequence | null | Sequence | [
"Prepend",
"Replace"
] | null | [
"Replace",
"ByteFallback",
"Fuse",
"Strip"
] | 156 | TheBloke/Mistral-7B-v0.1-GPTQ | TheBloke | {
"models": [
{
"_id": "650aedb6238a644cb93a52c3",
"id": "mistralai/Mistral-7B-v0.1"
}
],
"relation": "quantized"
} | 304 | 221,970 | False | 2023-09-28T22:35:40Z | 2023-09-29T20:49:41Z | transformers | 37 | 0 | null | text-generation | {"parameters": {"I32": 6979321856, "F16": 263786496}, "total": 7243108352} | [
".gitattributes",
"README.md",
"added_tokens.json",
"config.json",
"generation_config.json",
"model.safetensors",
"quantize_config.json",
"special_tokens_map.json",
"tokenizer.json",
"tokenizer.model",
"tokenizer_config.json"
] | 81de15eeac5938bc3b4065dfddf798fe5d215881 | [
"transformers",
"safetensors",
"mistral",
"text-generation",
"pretrained",
"base_model:mistralai/Mistral-7B-v0.1",
"base_model:quantized:mistralai/Mistral-7B-v0.1",
"license:apache-2.0",
"text-generation-inference",
"4-bit",
"gptq",
"deploy:azure",
"region:us"
] | null | {"architectures": ["MistralForCausalLM"], "model_type": "mistral", "quantization_config": {"bits": 4, "quant_method": "gptq"}, "tokenizer_config": {"bos_token": "<s>", "eos_token": "</s>", "pad_token": null, "unk_token": "<unk>", "use_default_system_prompt": true}} | {
"auto_model": "AutoModelForCausalLM",
"custom_class": null,
"pipeline_tag": "text-generation",
"processor": "AutoTokenizer"
} | {"base_model": "mistralai/Mistral-7B-v0.1", "datasets": null, "eval_results": null, "language": null, "library_name": null, "license": "apache-2.0", "license_name": null, "license_link": null, "metrics": null, "model_name": "Mistral 7B v0.1", "pipeline_tag": "text-generation", "tags": ["pretrained"], "inference": false... | <!-- header start -->
<!-- 200823 -->
<div style="width: auto; margin-left: auto; margin-right: auto">
<img src="https://i.imgur.com/EBdldam.jpg" alt="TheBlokeAI" style="width: 100%; min-width: 400px; display: block; margin: auto;">
</div>
<div style="display: flex; justify-content: space-between; width: 100%;">
<d... | null | [
"apache-2.0"
] | null | null | 7,243,108,352 | null | null | [
"AutoModelForCausalLM",
"mistral",
"MistralForCausalLM"
] | [
"text-generation"
] | [
"text"
] | [
"text"
] | [
"text"
] |
621ffdc136468d709f180b83 | aed290a0124eb522 | dd84a2b1ff97657d | 250,002 | Unigram | null | true | true | true | true | 5 | Precompiled | Sequence | Metaspace | [
"Precompiled"
] | [
"WhitespaceSplit",
"Metaspace"
] | [
"Metaspace"
] | 10 | symanto/sn-xlm-roberta-base-snli-mnli-anli-xnli | symanto | null | 143 | 221,528 | False | 2022-03-02T23:29:05Z | 2024-10-24T10:07:49Z | sentence-transformers | 61 | 0 | null | sentence-similarity | {"parameters": {"I64": 514, "F32": 278043648}, "total": 278044162} | [
".gitattributes",
"1_Pooling/config.json",
"LICENSE",
"README.md",
"config.json",
"config_sentence_transformers.json",
"model.safetensors",
"modules.json",
"pytorch_model.bin",
"sentence_bert_config.json",
"sentencepiece.bpe.model",
"special_tokens_map.json",
"tokenizer.json",
"tokenizer_c... | 94affd0a8ac331372f29fc3ea0b3d178d96a6639 | [
"sentence-transformers",
"pytorch",
"safetensors",
"xlm-roberta",
"feature-extraction",
"zero-shot-classification",
"sentence-similarity",
"transformers",
"ar",
"bg",
"de",
"el",
"en",
"es",
"fr",
"ru",
"th",
"tr",
"ur",
"vn",
"zh",
"dataset:SNLI",
"dataset:MNLI",
"data... | null | {"architectures": ["XLMRobertaModel"], "model_type": "xlm-roberta", "tokenizer_config": {"bos_token": "<s>", "eos_token": "</s>", "sep_token": "</s>", "cls_token": "<s>", "unk_token": "<unk>", "pad_token": "<pad>", "mask_token": {"content": "<mask>", "single_word": false, "lstrip": true, "rstrip": false, "normalized": ... | {
"auto_model": "AutoModel",
"custom_class": null,
"pipeline_tag": "feature-extraction",
"processor": "AutoTokenizer"
} | {"base_model": null, "datasets": ["SNLI", "MNLI", "ANLI", "XNLI"], "eval_results": null, "language": ["ar", "bg", "de", "el", "en", "es", "fr", "ru", "th", "tr", "ur", "vn", "zh"], "library_name": null, "license": null, "license_name": null, "license_link": null, "metrics": null, "model_name": null, "pipeline_tag": "se... | A Siamese network model trained for zero-shot and few-shot text classification.
The base model is [xlm-roberta-base](https://huggingface.co/xlm-roberta-base).
It was trained on [SNLI](https://nlp.stanford.edu/projects/snli/), [MNLI](https://cims.nyu.edu/~sbowman/multinli/), [ANLI](https://github.com/facebookresearch/a... | null | null | [
"SNLI",
"MNLI",
"ANLI",
"XNLI"
] | [
"ar",
"bg",
"de",
"el",
"en",
"es",
"fr",
"ru",
"th",
"tr",
"ur",
"vn",
"zh"
] | 278,044,162 | null | null | [
"XLMRobertaModel",
"AutoModel",
"xlm-roberta"
] | [
"sentence-similarity",
"zero-shot-classification",
"feature-extraction"
] | [
"text",
"multimodal"
] | [
"text"
] | [
"logits",
"embeddings"
] |
659ec0a2e0b52a6daf3897cc | e54582e7e5bc56b0 | 0e7bc0977f200d1c | 32,000 | BPE | 58,980 | true | false | true | true | 3 | Sequence | null | Sequence | [
"Prepend",
"Replace"
] | null | [
"Replace",
"ByteFallback",
"Fuse",
"Strip"
] | 688 | invalid-coder/Sakura-SOLAR-Instruct-CarbonVillain-en-10.7B-v2-slerp | invalid-coder | null | 13,521 | 284,505 | False | 2024-01-10T16:06:58Z | 2024-01-10T16:13:44Z | transformers | 0 | 0 | null | text-generation | {"parameters": {"F16": 10731524096}, "total": 10731524096} | [
".gitattributes",
"README.md",
"config.json",
"mergekit_config.yml",
"model-00001-of-00011.safetensors",
"model-00002-of-00011.safetensors",
"model-00003-of-00011.safetensors",
"model-00004-of-00011.safetensors",
"model-00005-of-00011.safetensors",
"model-00006-of-00011.safetensors",
"model-0000... | 39a1c76ddb5fa3a82c5b4071121d2e4866a25300 | [
"transformers",
"safetensors",
"llama",
"text-generation",
"merge",
"mergekit",
"lazymergekit",
"jeonsworld/CarbonVillain-en-10.7B-v2",
"kyujinpy/Sakura-SOLAR-Instruct",
"conversational",
"license:apache-2.0",
"text-generation-inference",
"endpoints_compatible",
"deploy:azure",
"region:u... | null | {"architectures": ["LlamaForCausalLM"], "model_type": "llama", "tokenizer_config": {"bos_token": "<s>", "chat_template": "{% for message in messages %}{% if message['role'] == 'system' %}{% if message['content']%}{{'### System:\n' + message['content']+'\n\n'}}{% endif %}{% elif message['role'] == 'user' %}{{'### User:\... | {
"auto_model": "AutoModelForCausalLM",
"custom_class": null,
"pipeline_tag": "text-generation",
"processor": "AutoTokenizer"
} | {"base_model": null, "datasets": null, "eval_results": null, "language": null, "library_name": null, "license": "apache-2.0", "license_name": null, "license_link": null, "metrics": null, "model_name": null, "pipeline_tag": null, "tags": ["merge", "mergekit", "lazymergekit", "jeonsworld/CarbonVillain-en-10.7B-v2", "kyuj... | # NeuralPipe-7B-slerp
NeuralPipe-7B-slerp is a merge of the following models using [LazyMergekit](https://colab.research.google.com/drive/1obulZ1ROXHjYLn6PPZJwRR6GzgQogxxb?usp=sharing):
* [jeonsworld/CarbonVillain-en-10.7B-v2](https://huggingface.co/jeonsworld/CarbonVillain-en-10.7B-v2)
* [kyujinpy/Sakura-SOLAR-Instru... | null | [
"apache-2.0"
] | null | null | 10,731,524,096 | null | null | [
"AutoModelForCausalLM",
"llama",
"LlamaForCausalLM"
] | [
"text-generation"
] | [
"text"
] | [
"text"
] | [
"text"
] |
63b88008a83d33eaaecea775 | ab569a33d4860288 | 7ce118731980e5c6 | 29,794 | WordPiece | null | true | true | true | true | 5 | BertNormalizer | BertPreTokenizer | WordPiece | [
"BertNormalizer"
] | [
"BertPreTokenizer"
] | [
"WordPiece"
] | 689 | stjiris/bert-large-portuguese-cased-legal-mlm-nli-sts-v1 | stjiris | null | 1,073 | 241,727 | False | 2023-01-06T20:09:44Z | 2024-12-15T23:11:13Z | sentence-transformers | 5 | 0 | [{"name": "BERTimbau", "results": [{"task": {"name": "STS", "type": "STS"}, "metrics": [{"name": "Pearson Correlation - assin Dataset", "type": "Pearson Correlation", "value": 0.7774097897260964, "verified": false}, {"name": "Pearson Correlation - assin2 Dataset", "type": "Pearson Correlation", "value": 0.8097518625809... | sentence-similarity | {"parameters": {"I64": 512, "F32": 334396416}, "total": 334396928} | [
".gitattributes",
"1_Pooling/config.json",
"README.md",
"config.json",
"config_sentence_transformers.json",
"model.safetensors",
"modules.json",
"pytorch_model.bin",
"sentence_bert_config.json",
"similarity_evaluation_Iris_results.csv",
"similarity_evaluation_assin2_results.csv",
"similarity_e... | d9b17cf052dbcfb97fb87711b5a11131ad212770 | [
"sentence-transformers",
"pytorch",
"safetensors",
"bert",
"feature-extraction",
"transformers",
"sentence-similarity",
"pt",
"dataset:stjiris/portuguese-legal-sentences-v0",
"dataset:assin",
"dataset:assin2",
"dataset:stsb_multi_mt",
"dataset:stjiris/IRIS_sts",
"license:mit",
"model-ind... | null | {"architectures": ["BertModel"], "model_type": "bert", "tokenizer_config": {"cls_token": "[CLS]", "mask_token": "[MASK]", "pad_token": "[PAD]", "sep_token": "[SEP]", "unk_token": "[UNK]"}} | {
"auto_model": "AutoModel",
"custom_class": null,
"pipeline_tag": "feature-extraction",
"processor": "AutoTokenizer"
} | {"base_model": null, "datasets": ["stjiris/portuguese-legal-sentences-v0", "assin", "assin2", "stsb_multi_mt", "stjiris/IRIS_sts"], "eval_results": null, "language": ["pt"], "library_name": null, "license": "mit", "license_name": null, "license_link": null, "metrics": null, "model_name": null, "pipeline_tag": "sentence... | [](https://www.inesc-id.pt/projects/PR07005/)
[](https://rufimelo99.github.io/SemanticSearchSystemForS... | null | [
"mit"
] | [
"stjiris/portuguese-legal-sentences-v0",
"assin",
"assin2",
"stsb_multi_mt",
"stjiris/IRIS_sts"
] | [
"pt"
] | 334,396,928 | null | null | [
"BertModel",
"AutoModel",
"bert"
] | [
"sentence-similarity",
"feature-extraction"
] | [
"text",
"multimodal"
] | [
"text"
] | [
"logits",
"embeddings"
] |
6677b01114e2aebef8b8b5de | 53ecf467267e2824 | 535fa14da0af647c | 30,522 | WordPiece | null | true | true | true | true | 5 | BertNormalizer | BertPreTokenizer | WordPiece | [
"BertNormalizer"
] | [
"BertPreTokenizer"
] | [
"WordPiece"
] | 0 | alexc09/MiniLM-L12-H384-uncased_Nvidia-Aegis-AI-Safety | alexc09 | null | 36 | 220,256 | False | 2024-06-23T05:18:09Z | 2024-06-25T08:03:50Z | transformers | 3 | 0 | null | text-classification | {"parameters": {"F32": 33365390}, "total": 33365390} | [
".gitattributes",
"README.md",
"config.json",
"model.safetensors",
"nvidia_test.csv",
"nvidia_train.csv",
"special_tokens_map.json",
"tokenizer.json",
"tokenizer_config.json",
"vocab.txt"
] | 9a1100147a9fae89da4b4a22d9744c51d7a7ea9b | [
"transformers",
"safetensors",
"bert",
"text-classification",
"dataset:nvidia/Aegis-AI-Content-Safety-Dataset-1.0",
"text-embeddings-inference",
"endpoints_compatible",
"region:us"
] | null | {"architectures": ["BertForSequenceClassification"], "model_type": "bert", "tokenizer_config": {"cls_token": "[CLS]", "mask_token": "[MASK]", "pad_token": "[PAD]", "sep_token": "[SEP]", "unk_token": "[UNK]"}} | {
"auto_model": "AutoModelForSequenceClassification",
"custom_class": null,
"pipeline_tag": "text-classification",
"processor": "AutoTokenizer"
} | {"base_model": null, "datasets": ["nvidia/Aegis-AI-Content-Safety-Dataset-1.0"], "eval_results": null, "language": null, "library_name": "transformers", "license": null, "license_name": null, "license_link": null, "metrics": null, "model_name": null, "pipeline_tag": null, "tags": null} | null | null | null | [
"nvidia/Aegis-AI-Content-Safety-Dataset-1.0"
] | null | 33,365,390 | null | null | [
"BertForSequenceClassification",
"bert",
"AutoModelForSequenceClassification"
] | [
"text-classification"
] | [
"text"
] | [
"text"
] | [
"logits"
] |
621ffdc136468d709f1794db | 51b9051196be19d8 | b399f26fd83e3c28 | 64,000 | WordPiece | null | true | true | true | true | 5 | BertNormalizer | BertPreTokenizer | WordPiece | [
"BertNormalizer"
] | [
"BertPreTokenizer"
] | [
"WordPiece"
] | 690 | aubmindlab/bert-base-arabertv02-twitter | aubmindlab | null | 9,503 | 236,287 | False | 2022-03-02T23:29:05Z | 2023-03-23T16:26:59Z | transformers | 8 | 0 | null | fill-mask | {"parameters": {"I64": 512, "F32": 135258880}, "total": 135259392} | [
".gitattributes",
"README.md",
"all_results.json",
"config.json",
"eval_results.json",
"model.safetensors",
"pytorch_model.bin",
"runs/Aug29_21-32-23_660e80775921/1630284783.908466/events.out.tfevents.1630284783.660e80775921.3048.1",
"runs/Aug29_21-32-23_660e80775921/events.out.tfevents.1630284783.6... | 0decc2e761667f0aea7aa94546ada5a32a6e5bb8 | [
"transformers",
"pytorch",
"tensorboard",
"safetensors",
"bert",
"fill-mask",
"ar",
"arxiv:2003.00104",
"endpoints_compatible",
"deploy:azure",
"region:us"
] | null | {"architectures": ["BertForMaskedLM"], "model_type": "bert", "tokenizer_config": {"unk_token": "[UNK]", "sep_token": "[SEP]", "pad_token": "[PAD]", "cls_token": "[CLS]", "mask_token": "[MASK]"}} | {
"auto_model": "AutoModelForMaskedLM",
"custom_class": null,
"pipeline_tag": "fill-mask",
"processor": "AutoTokenizer"
} | {"base_model": null, "datasets": null, "eval_results": null, "language": "ar", "library_name": null, "license": null, "license_name": null, "license_link": null, "metrics": null, "model_name": null, "pipeline_tag": null, "tags": null, "widget": [{"text": " \u0639\u0627\u0635\u0645\u0629 \u0644\u0628\u0646\u0627\u0646 \... | <img src="https://raw.githubusercontent.com/aub-mind/arabert/master/arabert_logo.png" width="100" align="center"/>
# AraBERTv0.2-Twitter
AraBERTv0.2-Twitter-base/large are two new models for Arabic dialects and tweets, trained by continuing the pre-training using the MLM task on ~60M Arabic tweets (filtered from a c... | null | null | null | [
"ar"
] | 135,259,392 | null | null | [
"AutoModelForMaskedLM",
"bert",
"BertForMaskedLM"
] | [
"fill-mask"
] | [
"text"
] | [
"text"
] | [
"logits"
] |
6889e5f55abcd205997902b5 | 7428ef9ae5ef868f | 67da9c236fa81925 | 151,669 | BPE | 151,387 | true | true | true | true | 26 | NFC | Sequence | ByteLevel | [
"NFC"
] | [
"Split",
"ByteLevel"
] | [
"ByteLevel"
] | 47 | QuantTrio/Qwen3-30B-A3B-Instruct-2507-GPTQ-Int8 | QuantTrio | {
"models": [
{
"_id": "6887274f2626398dc2e9f540",
"id": "Qwen/Qwen3-30B-A3B-Instruct-2507"
}
],
"relation": "quantized"
} | 335 | 225,529 | False | 2025-07-30T09:29:25Z | 2025-09-05T08:41:26Z | transformers | 9 | 0 | null | text-generation | {"parameters": {"I32": 29896998912, "F16": 635123712}, "total": 30532122624} | [
".gitattributes",
"README.md",
"config.json",
"configuration.json",
"generation_config.json",
"merges.txt",
"model-00001-of-00007.safetensors",
"model-00002-of-00007.safetensors",
"model-00003-of-00007.safetensors",
"model-00004-of-00007.safetensors",
"model-00005-of-00007.safetensors",
"model... | 2441d7e36d13691bb8d00db390d7bddf9a8ebbe5 | [
"transformers",
"safetensors",
"qwen3_moe",
"text-generation",
"Qwen3",
"GPTQ",
"Int8",
"量化修复",
"vLLM",
"conversational",
"arxiv:2505.09388",
"base_model:Qwen/Qwen3-30B-A3B-Instruct-2507",
"base_model:quantized:Qwen/Qwen3-30B-A3B-Instruct-2507",
"license:apache-2.0",
"endpoints_compatibl... | null | {"architectures": ["Qwen3MoeForCausalLM"], "model_type": "qwen3_moe", "quantization_config": {"quant_method": "gptq", "bits": 8}, "tokenizer_config": {"bos_token": null, "chat_template": "{%- if tools %}\n {{- '<|im_start|>system\\n' }}\n {%- if messages[0].role == 'system' %}\n {{- messages[0].content + '... | {
"auto_model": "AutoModelForCausalLM",
"custom_class": null,
"pipeline_tag": "text-generation",
"processor": "AutoTokenizer"
} | {"base_model": ["Qwen/Qwen3-30B-A3B-Instruct-2507"], "datasets": null, "eval_results": null, "language": null, "library_name": "transformers", "license": "apache-2.0", "license_name": null, "license_link": "https://huggingface.co/Qwen/Qwen3-30B-A3B-Instruct-2507/blob/main/LICENSE", "metrics": null, "model_name": null, ... | # Qwen3-30B-A3B-Instruct-2507-GPTQ-Int8
Base model: [Qwen/Qwen3-30B-A3B-Instruct-2507](https://huggingface.co/Qwen/Qwen3-30B-A3B-Instruct-2507)
### 【vLLM 4-GPU Single Node Launch Command】
<i>Note: When using 4 GPUs, you must include `--enable-expert-parallel` because expert tensor TP must be evenly divisible; for 2 GP... | null | [
"apache-2.0",
"https://huggingface.co/Qwen/Qwen3-30B-A3B-Instruct-2507/blob/main/LICENSE"
] | null | null | 30,532,122,624 | null | null | [
"qwen3_moe",
"AutoModelForCausalLM",
"Qwen3MoeForCausalLM"
] | [
"text-generation"
] | [
"text"
] | [
"text"
] | [
"text"
] |
6617b3e291c336f666738329 | 27abb78c4c74943d | 70bd27c212bc339c | 50,265 | BPE | 50,000 | false | true | true | true | 5 | null | ByteLevel | ByteLevel | null | [
"ByteLevel"
] | [
"ByteLevel"
] | 691 | protectai/MoritzLaurer-roberta-base-zeroshot-v2.0-c-onnx | protectai | {
"models": [
{
"_id": "65fd9fa74254e0834430a340",
"id": "MoritzLaurer/roberta-base-zeroshot-v2.0-c"
}
],
"relation": "quantized"
} | 956 | 234,768 | False | 2024-04-11T09:56:50Z | 2024-04-11T09:57:47Z | transformers | 0 | 0 | null | zero-shot-classification | null | [
".gitattributes",
"README.md",
"config.json",
"merges.txt",
"model.onnx",
"special_tokens_map.json",
"tokenizer.json",
"tokenizer_config.json",
"vocab.json"
] | fde5343dbad32f1a5470890505c72ec656db6dbe | [
"transformers",
"onnx",
"roberta",
"text-classification",
"zero-shot-classification",
"base_model:MoritzLaurer/roberta-base-zeroshot-v2.0-c",
"base_model:quantized:MoritzLaurer/roberta-base-zeroshot-v2.0-c",
"license:apache-2.0",
"region:us"
] | null | {"architectures": ["RobertaForSequenceClassification"], "model_type": "roberta", "tokenizer_config": {"bos_token": "<s>", "cls_token": "<s>", "eos_token": "</s>", "mask_token": "<mask>", "pad_token": "<pad>", "sep_token": "</s>", "unk_token": "<unk>"}} | {
"auto_model": "AutoModelForSequenceClassification",
"custom_class": null,
"pipeline_tag": "text-classification",
"processor": "AutoTokenizer"
} | {"base_model": "MoritzLaurer/roberta-base-zeroshot-v2.0-c", "datasets": null, "eval_results": null, "language": null, "library_name": null, "license": "apache-2.0", "license_name": null, "license_link": null, "metrics": null, "model_name": null, "pipeline_tag": "zero-shot-classification", "tags": null, "inference": fal... | # ONNX version of MoritzLaurer/roberta-base-zeroshot-v2.0-c
**This model is a conversion of [MoritzLaurer/roberta-base-zeroshot-v2.0-c](https://huggingface.co/MoritzLaurer/roberta-base-zeroshot-v2.0-c) to ONNX** format using the [🤗 Optimum](https://huggingface.co/docs/optimum/index) library. | null | [
"apache-2.0"
] | null | null | null | null | null | [
"roberta",
"AutoModelForSequenceClassification",
"RobertaForSequenceClassification"
] | [
"zero-shot-classification",
"text-classification"
] | [
"text"
] | [
"text"
] | [
"logits"
] |
68780cc66136efdc91e554f0 | 87ec02145bad27f5 | dd84a2b1ff97657d | 250,002 | Unigram | null | true | true | true | true | 5 | Sequence | Metaspace | Metaspace | [
"Precompiled",
"Replace"
] | [
"Metaspace"
] | [
"Metaspace"
] | 412 | OpenMed/OpenMed-NER-DiseaseDetect-SnowMed-568M | OpenMed | null | 93,931 | 574,180 | False | 2025-07-16T20:34:14Z | 2025-08-05T09:40:26Z | transformers | 1 | 0 | null | token-classification | {"parameters": {"BF16": 566708227}, "total": 566708227} | [
".gitattributes",
"README.md",
"config.json",
"model.safetensors",
"openmed_vs_sota_grouped_bars.png",
"sentencepiece.bpe.model",
"special_tokens_map.json",
"test_results.json",
"tokenizer.json",
"tokenizer_config.json"
] | 4f6e8a7fb6d8d5f7f856bd99d662d5b4850eb91c | [
"transformers",
"safetensors",
"xlm-roberta",
"token-classification",
"named-entity-recognition",
"biomedical-nlp",
"disease-entity-recognition",
"medical-diagnosis",
"pathology",
"biocuration",
"disease",
"en",
"arxiv:2508.01630",
"license:apache-2.0",
"endpoints_compatible",
"region:... | null | {"architectures": ["XLMRobertaForTokenClassification"], "model_type": "xlm-roberta", "tokenizer_config": {"bos_token": "<s>", "cls_token": "<s>", "eos_token": "</s>", "mask_token": "<mask>", "pad_token": "<pad>", "sep_token": "</s>", "unk_token": "<unk>"}} | {
"auto_model": "AutoModelForTokenClassification",
"custom_class": null,
"pipeline_tag": "token-classification",
"processor": "AutoTokenizer"
} | {"base_model": null, "datasets": null, "eval_results": null, "language": ["en"], "library_name": null, "license": "apache-2.0", "license_name": null, "license_link": null, "metrics": null, "model_name": null, "pipeline_tag": null, "tags": ["token-classification", "named-entity-recognition", "biomedical-nlp", "transform... | null | null | [
"apache-2.0"
] | null | [
"en"
] | 566,708,227 | null | null | [
"XLMRobertaForTokenClassification",
"AutoModelForTokenClassification",
"xlm-roberta"
] | [
"token-classification"
] | [
"text"
] | [
"text"
] | [
"logits"
] |
621ffdc136468d709f17bab9 | 3fb4cf844b1109ce | 036b7e446f5e496c | 32,000 | Unigram | null | true | true | true | true | 9 | Sequence | Metaspace | Metaspace | [
"Replace",
"Replace",
"Replace",
"NFKD",
"StripAccents",
"Precompiled"
] | [
"Metaspace"
] | [
"Metaspace"
] | 692 | hfl/chinese-xlnet-base | hfl | null | 462 | 222,628 | False | 2022-03-02T23:29:05Z | 2021-03-03T01:44:59Z | transformers | 31 | 0 | null | text-generation | null | [
".gitattributes",
"README.md",
"added_tokens.json",
"config.json",
"pytorch_model.bin",
"special_tokens_map.json",
"spiece.model",
"tf_model.h5",
"tokenizer.json",
"tokenizer_config.json"
] | 34b827684078f956411389834966eb55588f5254 | [
"transformers",
"pytorch",
"tf",
"xlnet",
"text-generation",
"zh",
"arxiv:2004.13922",
"license:apache-2.0",
"endpoints_compatible",
"deploy:azure",
"region:us"
] | null | {"architectures": ["XLNetLMHeadModel"], "model_type": "xlnet", "tokenizer_config": {}} | {
"auto_model": "AutoModelForCausalLM",
"custom_class": null,
"pipeline_tag": "text-generation",
"processor": "AutoTokenizer"
} | {"base_model": null, "datasets": null, "eval_results": null, "language": ["zh"], "library_name": null, "license": "apache-2.0", "license_name": null, "license_link": null, "metrics": null, "model_name": null, "pipeline_tag": null, "tags": null} | ## Chinese Pre-Trained XLNet
This project provides a XLNet pre-training model for Chinese, which aims to enrich Chinese natural language processing resources and provide a variety of Chinese pre-training model selection.
We welcome all experts and scholars to download and use this model.
This project is based on CMU/G... | null | [
"apache-2.0"
] | null | [
"zh"
] | null | null | null | [
"AutoModelForCausalLM",
"XLNetLMHeadModel",
"xlnet"
] | [
"text-generation"
] | [
"text"
] | [
"text"
] | [
"text"
] |
67a654ec62bfac05f2b29799 | c18a1b7f98fd57dd | 52e39eeb9639a3fa | 30,000 | WordPiece | null | true | true | true | true | 5 | Sequence | Split | WordPiece | [
"NFD",
"StripAccents"
] | [
"Split"
] | [
"WordPiece"
] | 693 | syssec-utd/py312-pylingual-v1-segmenter | syssec-utd | {
"models": [
{
"_id": "67a5af8ddea89ffe80e5a794",
"id": "syssec-utd/py312-pylingual-v1-mlm"
}
],
"relation": "finetune"
} | 16,766 | 293,899 | False | 2025-02-07T18:46:04Z | 2025-02-08T00:06:40Z | transformers | 0 | 0 | [{"name": "py312-pylingual-v1-segmenter", "results": []}] | token-classification | {"parameters": {"F32": 108493827}, "total": 108493827} | [
".gitattributes",
"README.md",
"config.json",
"model.safetensors",
"runs/Feb07_12-45-11_syssec-ub1/events.out.tfevents.1738953965.syssec-ub1.325571.0",
"special_tokens_map.json",
"tokenizer.json",
"tokenizer_config.json",
"training_args.bin"
] | 70caa2ed79f20e14835f28cdf874d552fb2ba767 | [
"transformers",
"tensorboard",
"safetensors",
"roberta",
"token-classification",
"generated_from_trainer",
"base_model:syssec-utd/py312-pylingual-v1-mlm",
"base_model:finetune:syssec-utd/py312-pylingual-v1-mlm",
"endpoints_compatible",
"region:us"
] | null | {"architectures": ["RobertaForTokenClassification"], "model_type": "roberta", "tokenizer_config": {"cls_token": "[CLS]", "mask_token": "[MASK]", "pad_token": "[PAD]", "sep_token": "[SEP]", "unk_token": "[UNK]"}} | {
"auto_model": "AutoModelForTokenClassification",
"custom_class": null,
"pipeline_tag": "token-classification",
"processor": "AutoTokenizer"
} | {"base_model": "syssec-utd/py312-pylingual-v1-mlm", "datasets": null, "eval_results": [], "language": null, "library_name": "transformers", "license": null, "license_name": null, "license_link": null, "metrics": ["precision", "recall", "f1", "accuracy"], "model_name": "py312-pylingual-v1-segmenter", "pipeline_tag": nul... | null | null | null | null | null | 108,493,827 | null | [
"precision",
"recall",
"f1",
"accuracy"
] | [
"roberta",
"AutoModelForTokenClassification",
"RobertaForTokenClassification"
] | [
"token-classification"
] | [
"text"
] | [
"text"
] | [
"logits"
] |
68780fbff0541aecc3fff4dd | 1f077a9a0005c931 | dd84a2b1ff97657d | 250,002 | Unigram | null | true | true | true | true | 5 | Precompiled | Sequence | Metaspace | [
"Precompiled"
] | [
"WhitespaceSplit",
"Metaspace"
] | [
"Metaspace"
] | 230 | OpenMed/OpenMed-NER-ProteinDetect-ElectraMed-560M | OpenMed | null | 92,741 | 579,557 | False | 2025-07-16T20:46:55Z | 2025-08-05T09:41:27Z | transformers | 0 | 0 | null | token-classification | {"parameters": {"BF16": 558852107}, "total": 558852107} | [
".gitattributes",
"README.md",
"config.json",
"model.safetensors",
"openmed_vs_sota_grouped_bars.png",
"sentencepiece.bpe.model",
"special_tokens_map.json",
"test_results.json",
"tokenizer.json",
"tokenizer_config.json"
] | a895fa7854c20d84d2a724e05df6751f8badae76 | [
"transformers",
"safetensors",
"xlm-roberta",
"token-classification",
"named-entity-recognition",
"biomedical-nlp",
"protein-interactions",
"molecular-biology",
"biochemistry",
"systems-biology",
"protein",
"protein_complex",
"protein_enum",
"protein_familiy_or_group",
"protein_variant",... | null | {"architectures": ["XLMRobertaForTokenClassification"], "model_type": "xlm-roberta", "tokenizer_config": {"bos_token": "<s>", "cls_token": "<s>", "eos_token": "</s>", "mask_token": "<mask>", "pad_token": "<pad>", "sep_token": "</s>", "unk_token": "<unk>"}} | {
"auto_model": "AutoModelForTokenClassification",
"custom_class": null,
"pipeline_tag": "token-classification",
"processor": "AutoTokenizer"
} | {"base_model": null, "datasets": null, "eval_results": null, "language": ["en"], "library_name": null, "license": "apache-2.0", "license_name": null, "license_link": null, "metrics": null, "model_name": null, "pipeline_tag": null, "tags": ["token-classification", "named-entity-recognition", "biomedical-nlp", "transform... | null | null | [
"apache-2.0"
] | null | [
"en"
] | 558,852,107 | null | null | [
"XLMRobertaForTokenClassification",
"AutoModelForTokenClassification",
"xlm-roberta"
] | [
"token-classification"
] | [
"text"
] | [
"text"
] | [
"logits"
] |
687a0fdbf057ae6026624ed3 | 1f077a9a0005c931 | dd84a2b1ff97657d | 250,002 | Unigram | null | true | true | true | true | 5 | Precompiled | Sequence | Metaspace | [
"Precompiled"
] | [
"WhitespaceSplit",
"Metaspace"
] | [
"Metaspace"
] | 230 | OpenMed/OpenMed-NER-OncologyDetect-BigMed-560M | OpenMed | null | 95,745 | 590,886 | False | 2025-07-18T09:11:55Z | 2025-08-05T09:46:19Z | transformers | 2 | 0 | null | token-classification | {"parameters": {"BF16": 558874657}, "total": 558874657} | [
".gitattributes",
"README.md",
"config.json",
"model.safetensors",
"openmed_vs_sota_grouped_bars.png",
"special_tokens_map.json",
"test_results.json",
"tokenizer.json",
"tokenizer_config.json",
"unigram.json"
] | 817033fa4bf56d9de4493563ba7aaf2acd406260 | [
"transformers",
"safetensors",
"xlm-roberta",
"token-classification",
"named-entity-recognition",
"biomedical-nlp",
"cancer-genetics",
"oncology",
"gene-regulation",
"cancer-research",
"amino_acid",
"anatomical_system",
"cancer",
"cell",
"cellular_component",
"developing_anatomical_str... | null | {"architectures": ["XLMRobertaForTokenClassification"], "model_type": "xlm-roberta", "tokenizer_config": {"bos_token": "<s>", "cls_token": "<s>", "eos_token": "</s>", "mask_token": "<mask>", "pad_token": "<pad>", "sep_token": "</s>", "unk_token": "<unk>"}} | {
"auto_model": "AutoModelForTokenClassification",
"custom_class": null,
"pipeline_tag": "token-classification",
"processor": "AutoTokenizer"
} | {"base_model": null, "datasets": null, "eval_results": null, "language": ["en"], "library_name": null, "license": "apache-2.0", "license_name": null, "license_link": null, "metrics": null, "model_name": null, "pipeline_tag": null, "tags": ["token-classification", "named-entity-recognition", "biomedical-nlp", "transform... | # 🧬 [OpenMed-NER-OncologyDetect-BigMed-560M](https://huggingface.co/OpenMed/OpenMed-NER-OncologyDetect-BigMed-560M)
**Specialized model for Cancer Genetics - Cancer-related genetic entities**
[](https://opensource.org/licenses/Apache-2.0)
[![Pytho... | null | [
"apache-2.0"
] | null | [
"en"
] | 558,874,657 | null | null | [
"XLMRobertaForTokenClassification",
"AutoModelForTokenClassification",
"xlm-roberta"
] | [
"token-classification"
] | [
"text"
] | [
"text"
] | [
"logits"
] |
67a6c6889b72585dd187bb39 | a194f8711951bd8e | cd867160a396f993 | 131,072 | BPE | 269,443 | false | true | true | true | 1,000 | null | Sequence | ByteLevel | null | [
"Split",
"ByteLevel"
] | [
"ByteLevel"
] | 407 | nm-testing/pixtral-12b-FP8-dynamic | nm-testing | {
"models": [
{
"_id": "67128efc83362efaae10dcc8",
"id": "mgoin/pixtral-12b"
}
],
"relation": "quantized"
} | 487 | 232,020 | False | 2025-02-08T02:50:48Z | 2025-04-11T20:19:04Z | transformers | 1 | 0 | null | image-text-to-text | null | [
".gitattributes",
"README.md",
"chat_template.json",
"config.json",
"generation_config.json",
"model-00001-of-00003.safetensors",
"model-00002-of-00003.safetensors",
"model-00003-of-00003.safetensors",
"model.safetensors.index.json",
"preprocessor_config.json",
"processor_config.json",
"recipe... | 6627e5c1844832bf50e92d2dcafc5bbdb32798ed | [
"transformers",
"safetensors",
"llava",
"image-text-to-text",
"vllm",
"vision",
"fp8",
"conversational",
"en",
"base_model:mgoin/pixtral-12b",
"base_model:quantized:mgoin/pixtral-12b",
"license:apache-2.0",
"endpoints_compatible",
"compressed-tensors",
"region:us"
] | null | {"architectures": ["LlavaForConditionalGeneration"], "model_type": "llava", "quantization_config": {"quant_method": "compressed-tensors"}, "processor_config": {"chat_template": "{%- if messages[0][\"role\"] == \"system\" %}\n {%- set system_message = messages[0][\"content\"] %}\n {%- set loop_messages = messages[... | {
"auto_model": "AutoModelForImageTextToText",
"custom_class": null,
"pipeline_tag": "image-text-to-text",
"processor": "AutoProcessor"
} | {"base_model": "mgoin/pixtral-12b", "datasets": null, "eval_results": null, "language": ["en"], "library_name": "transformers", "license": "apache-2.0", "license_name": null, "license_link": "https://huggingface.co/datasets/choosealicense/licenses/blob/main/markdown/apache-2.0.md", "metrics": null, "model_name": null, ... | # pixtral-12b-FP8-Dynamic
## Model Overview
- **Model Architecture:** mgoin/pixtral-12b
- **Input:** Vision-Text
- **Output:** Text
- **Model Optimizations:**
- **Weight quantization:** FP8
- **Activation quantization:** FP8
- **Release Date:** 2/24/2025
- **Version:** 1.0
- **Model Developers:** Neural Magic
... | null | [
"apache-2.0",
"https://huggingface.co/datasets/choosealicense/licenses/blob/main/markdown/apache-2.0.md"
] | null | [
"en"
] | null | null | null | [
"AutoModelForImageTextToText",
"LlavaForConditionalGeneration",
"llava"
] | [
"image-text-to-text"
] | [
"multimodal"
] | [
"text",
"image"
] | [
"text"
] |
621ffdc136468d709f179874 | 3ea67e51650d6eb0 | b8f9703d5894c811 | 50,257 | BPE | 50,016 | false | true | true | true | 1 | null | ByteLevel | ByteLevel | null | [
"ByteLevel"
] | [
"ByteLevel"
] | 694 | benjamin/gpt2-wechsel-german | benjamin | null | 1,252 | 220,094 | False | 2022-03-02T23:29:05Z | 2022-07-13T23:44:00Z | transformers | 4 | 0 | null | text-generation | null | [
".gitattributes",
"README.md",
"config.json",
"merges.txt",
"optimizer.pt",
"pytorch_model.bin",
"rng_state_0.pth",
"rng_state_1.pth",
"rng_state_2.pth",
"rng_state_3.pth",
"rng_state_4.pth",
"rng_state_5.pth",
"rng_state_6.pth",
"rng_state_7.pth",
"scheduler.pt",
"special_tokens_map.j... | 47f2b15f445189aa24eb07971e967c646addaf23 | [
"transformers",
"pytorch",
"gpt2",
"text-generation",
"de",
"license:mit",
"text-generation-inference",
"endpoints_compatible",
"region:us"
] | null | {"architectures": ["GPT2LMHeadModel"], "model_type": "gpt2", "tokenizer_config": {"unk_token": "<|endoftext|>", "bos_token": "<|endoftext|>", "eos_token": "<|endoftext|>"}} | {
"auto_model": "AutoModelForCausalLM",
"custom_class": null,
"pipeline_tag": "text-generation",
"processor": "AutoTokenizer"
} | {"base_model": null, "datasets": null, "eval_results": null, "language": "de", "library_name": null, "license": "mit", "license_name": null, "license_link": null, "metrics": null, "model_name": null, "pipeline_tag": null, "tags": null} | # gpt2-wechsel-german
Model trained with WECHSEL: Effective initialization of subword embeddings for cross-lingual transfer of monolingual language models.
See the code here: https://github.com/CPJKU/wechsel
And the paper here: https://aclanthology.org/2022.naacl-main.293/
## Performance
### RoBERTa
| Model | NLI... | null | [
"mit"
] | null | [
"de"
] | null | null | null | [
"GPT2LMHeadModel",
"AutoModelForCausalLM",
"gpt2"
] | [
"text-generation"
] | [
"text"
] | [
"text"
] | [
"text"
] |
651bf4763fa6c4e1829124ee | 592e444e2a382b7f | 0000e6c6a03fba1a | 32,003 | BPE | 61,249 | true | false | true | true | 6 | Sequence | null | Sequence | [
"Prepend",
"Replace"
] | null | [
"Replace",
"ByteFallback",
"Fuse",
"Strip"
] | 332 | TheBloke/TinyLlama-1.1B-Chat-v0.3-AWQ | TheBloke | {
"models": [
{
"_id": "65203de7578e7da0d71891e5",
"id": "TinyLlama/TinyLlama-1.1B-Chat-v0.3"
}
],
"relation": "quantized"
} | 67,058 | 510,473 | False | 2023-10-03T11:01:10Z | 2023-11-09T18:17:42Z | transformers | 4 | 0 | null | text-generation | {"parameters": {"I32": 968884224, "F16": 131176448}, "total": 1100060672} | [
".gitattributes",
"README.md",
"added_tokens.json",
"config.json",
"generation_config.json",
"model.safetensors",
"quant_config.json",
"special_tokens_map.json",
"tokenizer.json",
"tokenizer.model",
"tokenizer_config.json"
] | d87af942d412211c2fe4a6cd6c4964cdd7e93e22 | [
"transformers",
"safetensors",
"llama",
"text-generation",
"en",
"dataset:cerebras/SlimPajama-627B",
"dataset:bigcode/starcoderdata",
"dataset:OpenAssistant/oasst_top1_2023-08-25",
"base_model:TinyLlama/TinyLlama-1.1B-Chat-v0.3",
"base_model:quantized:TinyLlama/TinyLlama-1.1B-Chat-v0.3",
"licens... | null | {"architectures": ["LlamaForCausalLM"], "model_type": "llama", "quantization_config": {"quant_method": "awq", "bits": 4}, "tokenizer_config": {"bos_token": "<s>", "eos_token": "</s>", "pad_token": null, "unk_token": "<unk>", "use_default_system_prompt": true}} | {
"auto_model": "AutoModelForCausalLM",
"custom_class": null,
"pipeline_tag": "text-generation",
"processor": "AutoTokenizer"
} | {"base_model": "PY007/TinyLlama-1.1B-Chat-v0.3", "datasets": ["cerebras/SlimPajama-627B", "bigcode/starcoderdata", "OpenAssistant/oasst_top1_2023-08-25"], "eval_results": null, "language": ["en"], "library_name": null, "license": "apache-2.0", "license_name": null, "license_link": null, "metrics": null, "model_name": "... | <!-- header start -->
<!-- 200823 -->
<div style="width: auto; margin-left: auto; margin-right: auto">
<img src="https://i.imgur.com/EBdldam.jpg" alt="TheBlokeAI" style="width: 100%; min-width: 400px; display: block; margin: auto;">
</div>
<div style="display: flex; justify-content: space-between; width: 100%;">
<d... | null | [
"apache-2.0"
] | [
"cerebras/SlimPajama-627B",
"bigcode/starcoderdata",
"OpenAssistant/oasst_top1_2023-08-25"
] | [
"en"
] | 1,100,060,672 | null | null | [
"AutoModelForCausalLM",
"llama",
"LlamaForCausalLM"
] | [
"text-generation"
] | [
"text"
] | [
"text"
] | [
"text"
] |
6434494e1d83dc03c8e8eee7 | e6993df786dbfe27 | ef4806e2ade9022f | 32,100 | Unigram | null | true | true | true | true | 103 | Sequence | Metaspace | Metaspace | [
"Precompiled",
"Replace"
] | [
"Metaspace"
] | [
"Metaspace"
] | 695 | MBZUAI/LaMini-Flan-T5-248M | MBZUAI | null | 941 | 226,358 | False | 2023-04-10T17:37:18Z | 2023-04-28T12:08:23Z | transformers | 81 | 0 | [{"name": "flan-t5-small-distil-v2", "results": []}] | text-generation | null | [
".gitattributes",
".gitignore",
"README.md",
"config.json",
"generation_config.json",
"pytorch_model.bin",
"special_tokens_map.json",
"spiece.model",
"tokenizer.json",
"tokenizer_config.json",
"training_args.bin"
] | 4e871ba5f20216feaa3b845fc782229cd64eba47 | [
"transformers",
"pytorch",
"t5",
"text2text-generation",
"generated_from_trainer",
"instruction fine-tuning",
"en",
"arxiv:2304.14402",
"license:cc-by-nc-4.0",
"text-generation-inference",
"endpoints_compatible",
"deploy:azure",
"region:us"
] | null | {"architectures": ["T5ForConditionalGeneration"], "model_type": "t5", "tokenizer_config": {"eos_token": "</s>", "pad_token": "<pad>", "unk_token": "<unk>"}} | {
"auto_model": "AutoModelForSeq2SeqLM",
"custom_class": null,
"pipeline_tag": "text2text-generation",
"processor": "AutoTokenizer"
} | {"base_model": null, "datasets": null, "eval_results": [], "language": ["en"], "library_name": null, "license": "cc-by-nc-4.0", "license_name": null, "license_link": null, "metrics": null, "model_name": "flan-t5-small-distil-v2", "pipeline_tag": "text2text-generation", "tags": ["generated_from_trainer", "instruction fi... | <!-- This model card has been generated automatically according to the information the Trainer had access to. You
should probably proofread and complete it, then remove this comment. -->
<p align="center" width="100%">
<a><img src="https://raw.githubusercontent.com/mbzuai-nlp/lamini-lm/main/images/lamini.png" alt=... | null | [
"cc-by-nc-4.0"
] | null | [
"en"
] | null | null | null | [
"t5",
"T5ForConditionalGeneration",
"AutoModelForSeq2SeqLM"
] | [
"text2text-generation",
"text-generation"
] | [
"text"
] | [
"text"
] | [
"text"
] |
67a9e0630710558f7bd85ab5 | 848b60b6cd304b65 | ffc911e785abe60e | 151,665 | BPE | 151,387 | true | true | true | true | 22 | NFC | Sequence | ByteLevel | [
"NFC"
] | [
"Split",
"ByteLevel"
] | [
"ByteLevel"
] | 15 | AIDC-AI/Ovis2-16B | AIDC-AI | null | 312 | 229,480 | False | 2025-02-10T11:17:55Z | 2025-08-15T15:20:51Z | transformers | 98 | 0 | null | image-text-to-text | {"parameters": {"BF16": 16190363126}, "total": 16190363126} | [
".gitattributes",
"NOTICE",
"README.md",
"added_tokens.json",
"config.json",
"configuration_aimv2.py",
"configuration_ovis.py",
"generation_config.json",
"merges.txt",
"model-00001-of-00007.safetensors",
"model-00002-of-00007.safetensors",
"model-00003-of-00007.safetensors",
"model-00004-of-... | 5dea2745b747a63fcf41e934b19653b1b8d6b7e6 | [
"transformers",
"safetensors",
"ovis",
"text-generation",
"MLLM",
"image-text-to-text",
"conversational",
"custom_code",
"en",
"zh",
"dataset:AIDC-AI/Ovis-dataset",
"arxiv:2405.20797",
"license:apache-2.0",
"region:us"
] | null | {"architectures": ["Ovis"], "auto_map": {"AutoConfig": "configuration_ovis.OvisConfig", "AutoModelForCausalLM": "modeling_ovis.Ovis"}, "model_type": "ovis", "tokenizer_config": {"bos_token": null, "chat_template": "{%- if tools %}\n {{- '<|im_start|>system\\n' }}\n {%- if messages[0]['role'] == 'system' %}\n ... | {
"auto_model": "AutoModelForCausalLM",
"custom_class": "modeling_ovis.Ovis",
"pipeline_tag": "text-generation",
"processor": null
} | {"base_model": null, "datasets": ["AIDC-AI/Ovis-dataset"], "eval_results": null, "language": ["en", "zh"], "library_name": "transformers", "license": "apache-2.0", "license_name": null, "license_link": null, "metrics": null, "model_name": null, "pipeline_tag": "image-text-to-text", "tags": ["MLLM"]} | # Ovis2-16B
<div align="center">
<img src=https://cdn-uploads.huggingface.co/production/uploads/637aebed7ce76c3b834cea37/3IK823BZ8w-mz_QfeYkDn.png width="30%"/>
</div>
<span style="color: #ED7D31; font-size: 22px;">It is recommended to use the latest version: [Ovis2.5](https://huggingface.co/collections/AIDC-AI/ovis... | null | [
"apache-2.0"
] | [
"AIDC-AI/Ovis-dataset"
] | [
"en",
"zh"
] | 16,190,363,126 | null | null | [
"ovis",
"AutoModelForCausalLM",
"modeling_ovis.Ovis",
"Ovis"
] | [
"image-text-to-text",
"text-generation"
] | [
"text",
"multimodal"
] | [
"text",
"image"
] | [
"text"
] |
67a41b84f45f400a56687546 | 848b60b6cd304b65 | ffc911e785abe60e | 151,665 | BPE | 151,387 | true | true | true | true | 22 | NFC | Sequence | ByteLevel | [
"NFC"
] | [
"Split",
"ByteLevel"
] | [
"ByteLevel"
] | 15 | unsloth/Qwen2.5-1.5B-Instruct-unsloth-bnb-4bit | unsloth | {
"models": [
{
"_id": "66e98dd5899bdb384bd953b4",
"id": "Qwen/Qwen2.5-1.5B-Instruct"
}
],
"relation": "quantized"
} | 59,497 | 400,328 | False | 2025-02-06T02:16:36Z | 2025-02-06T03:39:20Z | transformers | 5 | 0 | null | text-generation | {"parameters": {"F32": 110416, "BF16": 492254720, "U8": 1084376046}, "total": 1576741182} | [
".gitattributes",
"README.md",
"added_tokens.json",
"config.json",
"generation_config.json",
"merges.txt",
"model.safetensors",
"special_tokens_map.json",
"tokenizer.json",
"tokenizer_config.json",
"vocab.json"
] | 3d254dbee5e3beae81bb8a717ad3a03427a09d26 | [
"transformers",
"safetensors",
"qwen2",
"text-generation",
"unsloth",
"qwen",
"conversational",
"en",
"arxiv:2407.10671",
"base_model:Qwen/Qwen2.5-1.5B-Instruct",
"base_model:quantized:Qwen/Qwen2.5-1.5B-Instruct",
"license:apache-2.0",
"text-generation-inference",
"endpoints_compatible",
... | null | {"architectures": ["Qwen2ForCausalLM"], "model_type": "qwen2", "quantization_config": {"load_in_4bit": true, "load_in_8bit": false, "quant_method": "bitsandbytes"}, "tokenizer_config": {"bos_token": null, "chat_template": "{%- if tools %}\n {{- '<|im_start|>system\\n' }}\n {%- if messages[0]['role'] == 'system' %... | {
"auto_model": "AutoModelForCausalLM",
"custom_class": null,
"pipeline_tag": "text-generation",
"processor": "AutoTokenizer"
} | {"base_model": "Qwen/Qwen2.5-1.5B-Instruct", "datasets": null, "eval_results": null, "language": ["en"], "library_name": "transformers", "license": "apache-2.0", "license_name": null, "license_link": null, "metrics": null, "model_name": null, "pipeline_tag": null, "tags": ["unsloth", "transformers", "qwen"]} | <div>
<p style="margin-bottom: 0;">
<strong>See <a href="https://huggingface.co/collections/unsloth/qwen-25-66fe4c08fb9ada518e8a0d3f">our collection</a> for versions of Qwen2.5 including 4-bit formats.</strong>
</p>
<p style="margin-bottom: 0;">
<em>Unsloth's <a href="https://unsloth.ai/blog/dynamic-4bit"... | null | [
"apache-2.0"
] | null | [
"en"
] | 1,576,741,182 | null | null | [
"AutoModelForCausalLM",
"Qwen2ForCausalLM",
"qwen2"
] | [
"text-generation"
] | [
"text"
] | [
"text"
] | [
"text"
] |
65e6e3534aee97415bd91a5b | b351fb9b156716e3 | 4ac8ff94b4e08373 | 32,002 | BPE | 58,980 | true | false | true | true | 5 | Sequence | null | Sequence | [
"Prepend",
"Replace"
] | null | [
"Replace",
"ByteFallback",
"Fuse",
"Strip"
] | 596 | occiglot/occiglot-7b-de-en-instruct | occiglot | null | 255 | 219,695 | False | 2024-03-05T09:18:11Z | 2024-04-09T16:27:13Z | transformers | 24 | 0 | null | text-generation | {"parameters": {"BF16": 7241748480}, "total": 7241748480} | [
".gitattributes",
"README.md",
"config.json",
"generation_config.json",
"model-00001-of-00003.safetensors",
"model-00002-of-00003.safetensors",
"model-00003-of-00003.safetensors",
"model.safetensors.index.json",
"special_tokens_map.json",
"tokenizer.json",
"tokenizer.model",
"tokenizer_config.... | d039ace486ca9617f6303ceda0ecf919d6b9ac88 | [
"transformers",
"safetensors",
"mistral",
"text-generation",
"conversational",
"en",
"de",
"license:apache-2.0",
"text-generation-inference",
"endpoints_compatible",
"deploy:azure",
"region:us"
] | null | {"architectures": ["MistralForCausalLM"], "model_type": "mistral", "tokenizer_config": {"bos_token": "<s>", "chat_template": "{{'<s>'}}{% if messages[0]['role'] == 'system' %}{% set loop_messages = messages[1:] %}{% set system_message = messages[0]['content'] %}{% else %}{% set loop_messages = messages %}{% set system_... | {
"auto_model": "AutoModelForCausalLM",
"custom_class": null,
"pipeline_tag": "text-generation",
"processor": "AutoTokenizer"
} | {"base_model": null, "datasets": null, "eval_results": null, "language": ["en", "de"], "library_name": null, "license": "apache-2.0", "license_name": null, "license_link": null, "metrics": null, "model_name": null, "pipeline_tag": "text-generation", "tags": null} | 
# Occiglot-7B-DE-EN-Instruct
> A [polyglot](https://en.wikipedia.org/wiki/Multilingualism#In_individuals) language model for the [Occident](https://en.wikipedia.org/wiki/Occident).
>
**Occiglot-7B-DE-EN-Instruct** is a the... | null | [
"apache-2.0"
] | null | [
"en",
"de"
] | 7,241,748,480 | null | null | [
"AutoModelForCausalLM",
"mistral",
"MistralForCausalLM"
] | [
"text-generation"
] | [
"text"
] | [
"text"
] | [
"text"
] |
67b739c9f35b80148784ba4d | 2cdba62b0ecdc386 | c0d8706e90709d09 | 49,155 | BPE | 48,872 | false | true | false | true | 41 | null | Sequence | ByteLevel | null | [
"Digits",
"ByteLevel"
] | [
"ByteLevel"
] | 588 | modularStarEncoder/ModularStarEncoder-finetuned-9 | modularStarEncoder | {
"models": [
{
"_id": "67b50abaa64445f58c6621d8",
"id": "modularStarEncoder/ModularStarEncoder"
}
],
"relation": "finetune"
} | 9 | 249,439 | False | 2025-02-20T14:18:49Z | 2025-05-21T08:25:59Z | transformers | 1 | 0 | null | feature-extraction | {"parameters": {"BF16": 302702081}, "total": 302702081} | [
".gitattributes",
"README.md",
"added_tokens.json",
"config.json",
"config.py",
"merges.txt",
"model.safetensors",
"modularStarEncoder.py",
"special_tokens_map.json",
"tokenizer.json",
"tokenizer_config.json",
"vocab.json"
] | de0cec5052584607138edb0e5f2e537e1e2628d4 | [
"transformers",
"safetensors",
"ModularStarEncoder",
"feature-extraction",
"custom_code",
"dataset:bigcode/the-stack-v2",
"dataset:modularStarEncoder/SynthCode2Code2NL-neardedup",
"arxiv:2503.03008",
"arxiv:2307.16885",
"base_model:modularStarEncoder/ModularStarEncoder",
"base_model:finetune:mod... | null | {"architectures": ["ModularStarEncoder"], "auto_map": {"AutoConfig": "config.ModularStarEncoderConfig", "AutoModel": "modularStarEncoder.ModularStarEncoder"}, "model_type": "ModularStarEncoder", "tokenizer_config": {"bos_token": "<|endoftext|>", "cls_token": "<cls>", "eos_token": "<|endoftext|>", "mask_token": "<mask>"... | {
"auto_model": "AutoModel",
"custom_class": "modularStarEncoder.ModularStarEncoder",
"pipeline_tag": "feature-extraction",
"processor": null
} | {"base_model": ["modularStarEncoder/ModularStarEncoder"], "datasets": ["bigcode/the-stack-v2", "modularStarEncoder/SynthCode2Code2NL-neardedup"], "eval_results": null, "language": null, "library_name": "transformers", "license": "bigcode-openrail-m", "license_name": null, "license_link": null, "metrics": null, "model_n... | # ModularStarEncoder-300M Fine-Tuned model
<!-- Provide a quick summary of what the model is/does. -->
ModularStarEncoder-finetuned-9 is an encoder built on top of [ModularStarEncoder-1B Pre-trained](https://huggingface.co/andreagurioli1995/ModularStarEncoder) on [SynthCoNL](https://huggingface.co/datasets/andreaguri... | null | [
"bigcode-openrail-m"
] | [
"bigcode/the-stack-v2",
"modularStarEncoder/SynthCode2Code2NL-neardedup"
] | null | 302,702,081 | null | null | [
"modularStarEncoder.ModularStarEncoder",
"ModularStarEncoder",
"AutoModel"
] | [
"feature-extraction"
] | [
"multimodal"
] | [
"text"
] | [
"embeddings"
] |
667b94ed81adc76dc72c50f3 | b53c36c9e4922c1f | a1f1bd381dcb9329 | 128,256 | BPE | 280,147 | false | true | true | true | 256 | null | Sequence | ByteLevel | null | [
"Split",
"ByteLevel"
] | [
"ByteLevel"
] | 696 | tokyotech-llm/Llama-3-Swallow-8B-Instruct-v0.1 | tokyotech-llm | null | 10,412 | 296,587 | False | 2024-06-26T04:11:25Z | 2024-10-08T14:05:37Z | transformers | 21 | 0 | null | text-generation | {"parameters": {"BF16": 8030261248}, "total": 8030261248} | [
".gitattributes",
"LICENSE",
"Notice",
"README.md",
"USE_POLICY.md",
"config.json",
"generation_config.json",
"logo.png",
"model-00001-of-00004.safetensors",
"model-00002-of-00004.safetensors",
"model-00003-of-00004.safetensors",
"model-00004-of-00004.safetensors",
"model.safetensors.index.j... | 2ed77ce6f5453bb2f933df18e236ebe0518bee1c | [
"transformers",
"safetensors",
"llama",
"text-generation",
"conversational",
"en",
"ja",
"license:llama3",
"text-generation-inference",
"endpoints_compatible",
"deploy:azure",
"region:us"
] | null | {"architectures": ["LlamaForCausalLM"], "model_type": "llama", "tokenizer_config": {"bos_token": "<|begin_of_text|>", "chat_template": "{% set loop_messages = messages %}{% for message in loop_messages %}{% set content = '<|start_header_id|>' + message['role'] + '<|end_header_id|>\n\n'+ message['content'] | trim + '<|e... | {
"auto_model": "AutoModelForCausalLM",
"custom_class": null,
"pipeline_tag": "text-generation",
"processor": "AutoTokenizer"
} | {"base_model": null, "datasets": null, "eval_results": null, "language": ["en", "ja"], "library_name": "transformers", "license": "llama3", "license_name": null, "license_link": null, "metrics": null, "model_name": null, "pipeline_tag": "text-generation", "tags": null, "model_type": "llama"} | # Llama3 Swallow - Built with Meta Llama 3
Our Swallow model has undergone continual pre-training from the [Llama 3 family](https://huggingface.co/collections/meta-llama/meta-llama-3-66214712577ca38149ebb2b6), primarily with the addition of Japanese language data. The Instruct versions use supervised fine-tuning (SFT)... | null | [
"llama3"
] | null | [
"en",
"ja"
] | 8,030,261,248 | null | null | [
"AutoModelForCausalLM",
"llama",
"LlamaForCausalLM"
] | [
"text-generation"
] | [
"text"
] | [
"text"
] | [
"text"
] |
6753571bc050f63baedf520f | 897e472a76b74290 | ca60ee72fe371096 | 49,155 | BPE | 48,891 | false | true | true | true | 22 | null | ByteLevel | ByteLevel | null | [
"ByteLevel"
] | [
"ByteLevel"
] | 367 | ibm-granite/granite-3.1-2b-instruct | ibm-granite | {
"models": [
{
"_id": "675356e859a4826a6f459979",
"id": "ibm-granite/granite-3.1-2b-base"
}
],
"relation": "finetune"
} | 10,223 | 256,202 | False | 2024-12-06T19:57:15Z | 2025-04-16T14:58:24Z | transformers | 57 | 0 | null | text-generation | null | [
".gitattributes",
"README.md",
"added_tokens.json",
"config.json",
"generation_config.json",
"merges.txt",
"model-00001-of-00002.safetensors",
"model-00002-of-00002.safetensors",
"model.safetensors.index.json",
"special_tokens_map.json",
"tokenizer.json",
"tokenizer_config.json",
"vocab.json... | bbc2aed595bd38bd770263dc3ab831db9794441d | [
"transformers",
"safetensors",
"granite",
"text-generation",
"language",
"granite-3.1",
"conversational",
"arxiv:0000.00000",
"base_model:ibm-granite/granite-3.1-2b-base",
"base_model:finetune:ibm-granite/granite-3.1-2b-base",
"license:apache-2.0",
"region:us"
] | null | {"architectures": ["GraniteForCausalLM"], "model_type": "granite", "tokenizer_config": {"bos_token": "<|end_of_text|>", "chat_template": "{%- if messages[0]['role'] == 'system' %}\n {%- set system_message = messages[0]['content'] %}\n {%- set loop_messages = messages[1:] %}\n{%- else %}\n {%- set system_messag... | {
"auto_model": "AutoModelForCausalLM",
"custom_class": null,
"pipeline_tag": "text-generation",
"processor": "AutoTokenizer"
} | {"base_model": ["ibm-granite/granite-3.1-2b-base"], "datasets": null, "eval_results": null, "language": null, "library_name": "transformers", "license": "apache-2.0", "license_name": null, "license_link": null, "metrics": null, "model_name": null, "pipeline_tag": "text-generation", "tags": ["language", "granite-3.1"], ... | # Granite-3.1-2B-Instruct
**Model Summary:**
Granite-3.1-2B-Instruct is a 2B parameter long-context instruct model finetuned from Granite-3.1-2B-Base using a combination of open source instruction datasets with permissive license and internally collected synthetic datasets tailored for solving long context problems. T... | null | [
"apache-2.0"
] | null | null | null | null | null | [
"granite",
"AutoModelForCausalLM",
"GraniteForCausalLM"
] | [
"text-generation"
] | [
"text"
] | [
"text"
] | [
"text"
] |
621ffdc136468d709f17da5f | cf7a91bce193063b | da848ac4c7c2cca2 | 32,768 | BPE | 32,511 | false | true | true | true | 1 | null | ByteLevel | ByteLevel | null | [
"ByteLevel"
] | [
"ByteLevel"
] | 697 | codeparrot/codeparrot-small | codeparrot | null | 33,808 | 382,050 | False | 2022-03-02T23:29:05Z | 2022-07-03T19:54:59Z | transformers | 33 | 0 | null | text-generation | null | [
".gitattributes",
"README.md",
"codeparrot_training.py",
"config.json",
"log/debug_0.log",
"log/debug_1.log",
"log/debug_10.log",
"log/debug_11.log",
"log/debug_12.log",
"log/debug_13.log",
"log/debug_14.log",
"log/debug_15.log",
"log/debug_2.log",
"log/debug_3.log",
"log/debug_4.log",
... | e7e4f5d39319551a760f07c0e1035e379617c721 | [
"transformers",
"pytorch",
"tensorboard",
"gpt2",
"text-generation",
"code",
"generation",
"dataset:codeparrot/codeparrot-clean",
"dataset:openai_humaneval",
"license:apache-2.0",
"text-generation-inference",
"endpoints_compatible",
"deploy:azure",
"region:us"
] | null | {"architectures": ["GPT2LMHeadModel"], "model_type": "gpt2", "tokenizer_config": {"unk_token": "<|endoftext|>", "bos_token": "<|endoftext|>", "eos_token": "<|endoftext|>"}} | {
"auto_model": "AutoModelForCausalLM",
"custom_class": null,
"pipeline_tag": "text-generation",
"processor": "AutoTokenizer"
} | {"base_model": null, "datasets": ["codeparrot/codeparrot-clean", "openai_humaneval"], "eval_results": null, "language": ["code"], "library_name": null, "license": "apache-2.0", "license_name": null, "license_link": null, "metrics": ["evaluate-metric/code_eval"], "model_name": null, "pipeline_tag": null, "tags": ["code"... | # CodeParrot 🦜 (small)
CodeParrot 🦜 is a GPT-2 model (110M parameters) trained to generate Python code.
## Usage
You can load the CodeParrot model and tokenizer directly in `transformers`:
```Python
from transformers import AutoTokenizer, AutoModelWithLMHead
tokenizer = AutoTokenizer.from_pretrained("codeparro... | null | [
"apache-2.0"
] | [
"codeparrot/codeparrot-clean",
"openai_humaneval"
] | [
"code"
] | null | null | [
"evaluate-metric/code_eval"
] | [
"GPT2LMHeadModel",
"AutoModelForCausalLM",
"gpt2"
] | [
"text-generation"
] | [
"text"
] | [
"text"
] | [
"text"
] |
656ed81c8e7f2775ac027d93 | 18bf361b9aea2bd1 | 893a35bd62abcf4d | 32,002 | BPE | 58,980 | true | false | true | true | 5 | Sequence | null | Sequence | [
"Prepend",
"Replace"
] | null | [
"Replace",
"ByteFallback",
"Fuse",
"Strip"
] | 698 | llava-hf/bakLlava-v1-hf | llava-hf | null | 8,468 | 244,037 | False | 2023-12-05T07:58:20Z | 2025-01-27T11:24:23Z | transformers | 55 | 0 | null | image-text-to-text | {"parameters": {"F16": 7263236096, "F32": 303507456}, "total": 7566743552} | [
".gitattributes",
"README.md",
"added_tokens.json",
"chat_template.json",
"config.json",
"generation_config.json",
"model-00001-of-00004.safetensors",
"model-00002-of-00004.safetensors",
"model-00003-of-00004.safetensors",
"model-00004-of-00004.safetensors",
"model.safetensors.index.json",
"pr... | 3b4599b2bd058a02f86f924ba1bcb38daf25517f | [
"transformers",
"safetensors",
"llava",
"image-text-to-text",
"vision",
"conversational",
"en",
"dataset:liuhaotian/LLaVA-Instruct-150K",
"license:llama2",
"endpoints_compatible",
"region:us"
] | null | {"architectures": ["LlavaForConditionalGeneration"], "model_type": "llava", "processor_config": {"chat_template": "{% for message in messages %}{% if message['role'] == 'user' %}{{ '[INST] ' }}{# Render all images first #}{% for content in message['content'] | selectattr('type', 'equalto', 'image') %}{{ '<image>\n' }}{... | {
"auto_model": "AutoModelForImageTextToText",
"custom_class": null,
"pipeline_tag": "image-text-to-text",
"processor": "AutoProcessor"
} | {"base_model": null, "datasets": ["liuhaotian/LLaVA-Instruct-150K"], "eval_results": null, "language": ["en"], "library_name": null, "license": "llama2", "license_name": null, "license_link": null, "metrics": null, "model_name": null, "pipeline_tag": "image-text-to-text", "tags": ["vision", "image-text-to-text"], "arxi... | # BakLLaVA Model Card
BakLlava is a model that is derived from the original Llava architecture, that uses Mistral-7b as a text backbone.

Below is the model card of BakLlava model 7b, which is copied... | null | [
"llama2"
] | [
"liuhaotian/LLaVA-Instruct-150K"
] | [
"en"
] | 7,566,743,552 | null | null | [
"AutoModelForImageTextToText",
"LlavaForConditionalGeneration",
"llava"
] | [
"image-text-to-text"
] | [
"multimodal"
] | [
"text",
"image"
] | [
"text"
] |
65c4143d0779708efe76b72f | 792d390a1a095ae0 | 1359b6a435750e8a | 66,676 | BPE | 66,529 | false | true | true | true | 2 | null | ByteLevel | ByteLevel | null | [
"ByteLevel"
] | [
"ByteLevel"
] | 699 | daekeun-ml/phi-2-ko-v0.1 | daekeun-ml | null | 258 | 218,005 | False | 2024-02-07T23:37:33Z | 2024-02-12T07:34:49Z | transformers | 26 | 0 | null | text-generation | {"parameters": {"BF16": 2858936436}, "total": 2858936436} | [
".gitattributes",
"README.md",
"config.json",
"configuration_phi.py",
"generation_config.json",
"merges.txt",
"model-00001-of-00002.safetensors",
"model-00002-of-00002.safetensors",
"model.safetensors.index.json",
"modeling_phi.py",
"special_tokens_map.json",
"tokenizer.json",
"tokenizer_con... | 5c366413d429ce7c72ca34fac94db6651d9e8b80 | [
"transformers",
"safetensors",
"phi",
"text-generation",
"custom_code",
"ko",
"en",
"dataset:wikimedia/wikipedia",
"dataset:maywell/korean_textbooks",
"dataset:nampdn-ai/tiny-codes",
"dataset:Open-Orca/OpenOrca",
"license:cc-by-sa-3.0",
"text-generation-inference",
"region:us"
] | null | {"architectures": ["PhiForCausalLM"], "auto_map": {"AutoConfig": "configuration_phi.PhiConfig", "AutoModelForCausalLM": "modeling_phi.PhiForCausalLM"}, "model_type": "phi", "tokenizer_config": {"bos_token": "<|endoftext|>", "eos_token": "<|endoftext|>", "pad_token": "!", "unk_token": "<|endoftext|>"}} | {
"auto_model": "AutoModelForCausalLM",
"custom_class": null,
"pipeline_tag": "text-generation",
"processor": "AutoTokenizer"
} | {"base_model": null, "datasets": ["wikimedia/wikipedia", "maywell/korean_textbooks", "nampdn-ai/tiny-codes", "Open-Orca/OpenOrca"], "eval_results": null, "language": ["ko", "en"], "library_name": "transformers", "license": "cc-by-sa-3.0", "license_name": null, "license_link": null, "metrics": null, "model_name": null, ... | # phi-2-ko-v0.1
## Model Details
This model is a Korean-specific model trained in phi-2 by adding a Korean tokenizer and Korean data. (English is also available.)
Although phi-2 performs very well, it does not support the Korean language and does not have a tokenizer trained on Korean corpous, so tokenizing Korean tex... | null | [
"cc-by-sa-3.0"
] | [
"wikimedia/wikipedia",
"maywell/korean_textbooks",
"nampdn-ai/tiny-codes",
"Open-Orca/OpenOrca"
] | [
"ko",
"en"
] | 2,858,936,436 | null | null | [
"AutoModelForCausalLM",
"phi",
"PhiForCausalLM"
] | [
"text-generation"
] | [
"text"
] | [
"text"
] | [
"text"
] |
6614e19e8cb1d029bac71408 | 53ecf467267e2824 | 535fa14da0af647c | 30,522 | WordPiece | null | true | true | true | true | 5 | BertNormalizer | BertPreTokenizer | WordPiece | [
"BertNormalizer"
] | [
"BertPreTokenizer"
] | [
"WordPiece"
] | 0 | abhijit2111/Pic2Story | abhijit2111 | null | 13 | 228,263 | False | 2024-04-09T06:35:10Z | 2024-04-09T06:42:30Z | transformers | 2 | 0 | null | image-to-text | null | [
".gitattributes",
"README.md",
"config.json",
"gitattributes",
"preprocessor_config.json",
"pytorch_model.bin",
"special_tokens_map.json",
"tf_model.h5",
"tokenizer.json",
"tokenizer_config.json",
"vocab.txt"
] | f628f04c6af39be270558d804b28c5f67b58a672 | [
"transformers",
"pytorch",
"tf",
"blip",
"image-text-to-text",
"image-captioning",
"image-to-text",
"arxiv:2201.12086",
"license:bsd-3-clause",
"endpoints_compatible",
"region:us"
] | null | {"architectures": ["BlipForConditionalGeneration"], "model_type": "blip", "tokenizer_config": {"cls_token": "[CLS]", "mask_token": "[MASK]", "pad_token": "[PAD]", "sep_token": "[SEP]", "unk_token": "[UNK]"}} | {
"auto_model": "AutoModelForImageTextToText",
"custom_class": null,
"pipeline_tag": "image-text-to-text",
"processor": "AutoProcessor"
} | {"base_model": null, "datasets": null, "eval_results": null, "language": null, "library_name": null, "license": "bsd-3-clause", "license_name": null, "license_link": null, "metrics": null, "model_name": null, "pipeline_tag": "image-to-text", "tags": ["image-captioning"], "languages": ["en"]} | This isi the BLIP salesforce large image captioning model with small adjustments to the paramaters on the back end for testing - note in particular the length of reply is increased.
# BLIP: Bootstrapping Language-Image Pre-training for Unified Vision-Language Understanding and Generation
Model card for image caption... | null | [
"bsd-3-clause"
] | null | null | null | null | null | [
"blip",
"AutoModelForImageTextToText",
"BlipForConditionalGeneration"
] | [
"image-text-to-text",
"image-to-text"
] | [
"multimodal"
] | [
"text",
"image"
] | [
"text"
] |
621ffdc136468d709f17a5e7 | 53ecf467267e2824 | 535fa14da0af647c | 30,522 | WordPiece | null | true | true | true | true | 5 | BertNormalizer | BertPreTokenizer | WordPiece | [
"BertNormalizer"
] | [
"BertPreTokenizer"
] | [
"WordPiece"
] | 0 | deepset/bert-small-mm_retrieval-passage_encoder | deepset | null | 3,105 | 222,412 | False | 2022-03-02T23:29:05Z | 2021-10-19T16:14:29Z | transformers | 1 | 0 | null | null | null | [
".gitattributes",
"config.json",
"pytorch_model.bin",
"special_tokens_map.json",
"tokenizer.json",
"tokenizer_config.json",
"vocab.txt"
] | c764744512975bd3823f689601ab0e388a29c366 | [
"transformers",
"pytorch",
"dpr",
"endpoints_compatible",
"region:us"
] | null | {"architectures": ["DPRContextEncoder"], "model_type": "dpr", "tokenizer_config": {"unk_token": "[UNK]", "sep_token": "[SEP]", "pad_token": "[PAD]", "cls_token": "[CLS]", "mask_token": "[MASK]"}} | {
"auto_model": "DPRContextEncoder",
"custom_class": null,
"pipeline_tag": null,
"processor": "AutoTokenizer"
} | null | null | null | null | null | null | null | null | null | [
"DPRContextEncoder",
"dpr"
] | [
null
] | null | null | null |
668fbcec5cb4c07caad7ceac | e2c43495aed6e9fb | e6ffdc5dd5f1fd86 | 256,000 | BPE | 580,604 | true | false | true | true | 217 | Replace | null | Sequence | [
"Replace"
] | null | [
"Replace",
"ByteFallback",
"Fuse"
] | 106 | rtzr/ko-gemma-2-9b-it | rtzr | {
"models": [
{
"_id": "667929f68cc4b2af1e8ad9de",
"id": "google/gemma-2-9b"
}
],
"relation": "finetune"
} | 566 | 228,460 | False | 2024-07-11T11:07:24Z | 2024-07-15T08:35:00Z | transformers | 90 | 0 | null | text-generation | {"parameters": {"BF16": 9241705984}, "total": 9241705984} | [
".gitattributes",
"README.md",
"config.json",
"generation_config.json",
"model-00001-of-00010.safetensors",
"model-00002-of-00010.safetensors",
"model-00003-of-00010.safetensors",
"model-00004-of-00010.safetensors",
"model-00005-of-00010.safetensors",
"model-00006-of-00010.safetensors",
"model-0... | c9aea5c899021d60dc0e0b051b00a504e5d9c7ba | [
"transformers",
"safetensors",
"gemma2",
"text-generation",
"conversational",
"ko",
"arxiv:2305.18290",
"base_model:google/gemma-2-9b",
"base_model:finetune:google/gemma-2-9b",
"license:gemma",
"text-generation-inference",
"endpoints_compatible",
"region:us"
] | null | {"architectures": ["Gemma2ForCausalLM"], "model_type": "gemma2", "tokenizer_config": {"bos_token": "<bos>", "chat_template": "{{ '<bos>' }}{% if messages[0]['role'] == 'system' %}{% set system_message = messages[0]['content'] %}{% endif %}{% if system_message is defined %}{{ system_message }}{% endif %}{% for message i... | {
"auto_model": "AutoModelForCausalLM",
"custom_class": null,
"pipeline_tag": "text-generation",
"processor": "AutoTokenizer"
} | {"base_model": ["google/gemma-2-9b"], "datasets": null, "eval_results": null, "language": ["ko"], "library_name": "transformers", "license": "gemma", "license_name": null, "license_link": null, "metrics": null, "model_name": null, "pipeline_tag": "text-generation", "tags": ["conversational"], "extra_gated_heading": "Ac... | ## Model Details
### Ko-Gemma-2-9B-IT
**[Ko-Gemma-2-9B-IT](https://huggingface.co/rtzr/ko-gemma-2-9b-it)** is a Korean-language conversational model that is part of the Gemma family of models. It is a text-to-text, decoder-only large language model, available in Korean. We fine-tuned this model on a carefully cur... | null | [
"gemma"
] | null | [
"ko"
] | 9,241,705,984 | null | null | [
"AutoModelForCausalLM",
"gemma2",
"Gemma2ForCausalLM"
] | [
"text-generation"
] | [
"text"
] | [
"text"
] | [
"text"
] |
686e36f655f0a8e35a4651f7 | 848b60b6cd304b65 | ffc911e785abe60e | 151,665 | BPE | 151,387 | true | true | true | true | 22 | NFC | Sequence | ByteLevel | [
"NFC"
] | [
"Split",
"ByteLevel"
] | [
"ByteLevel"
] | 15 | AI-MO/Kimina-Prover-72B | AI-MO | {
"models": [
{
"_id": "66e6d0a6126f9577f878c2e9",
"id": "Qwen/Qwen2.5-72B"
}
],
"relation": "finetune"
} | 4,620 | 652,000 | False | 2025-07-09T09:31:34Z | 2025-07-10T11:31:57Z | transformers | 34 | 1 | null | text-generation | {"parameters": {"BF16": 72706203648}, "total": 72706203648} | [
".gitattributes",
"LICENSE.md",
"README.md",
"config.json",
"generation_config.json",
"merges.txt",
"model-00001-of-00037.safetensors",
"model-00002-of-00037.safetensors",
"model-00003-of-00037.safetensors",
"model-00004-of-00037.safetensors",
"model-00005-of-00037.safetensors",
"model-00006-o... | 0667e1c5a5e04a46a840af403520544cc0bf2ede | [
"transformers",
"safetensors",
"qwen2",
"text-generation",
"chat",
"conversational",
"en",
"base_model:Qwen/Qwen2.5-72B",
"base_model:finetune:Qwen/Qwen2.5-72B",
"license:mit",
"text-generation-inference",
"endpoints_compatible",
"region:us"
] | null | {"architectures": ["Qwen2ForCausalLM"], "model_type": "qwen2", "tokenizer_config": {"bos_token": null, "chat_template": "{%- if tools %}\n {{- '<|im_start|>system\\n' }}\n {%- if messages[0]['role'] == 'system' %}\n {{- messages[0]['content'] }}\n {%- else %}\n {{- 'You are Qwen, created by Aliba... | {
"auto_model": "AutoModelForCausalLM",
"custom_class": null,
"pipeline_tag": "text-generation",
"processor": "AutoTokenizer"
} | {"base_model": "Qwen/Qwen2.5-72B", "datasets": null, "eval_results": null, "language": ["en"], "library_name": "transformers", "license": "mit", "license_name": null, "license_link": null, "metrics": null, "model_name": null, "pipeline_tag": null, "tags": ["chat"]} | null | null | [
"mit"
] | null | [
"en"
] | 72,706,203,648 | null | null | [
"AutoModelForCausalLM",
"Qwen2ForCausalLM",
"qwen2"
] | [
"text-generation"
] | [
"text"
] | [
"text"
] | [
"text"
] |
663cd52f34f4cefb3ee42c46 | bcf38225f92f1be7 | a1f1bd381dcb9329 | 128,256 | BPE | 280,147 | false | true | true | true | 256 | null | Sequence | ByteLevel | null | [
"Split",
"ByteLevel"
] | [
"ByteLevel"
] | 700 | uygarkurt/llama-3-merged-linear | uygarkurt | null | 13,375 | 279,349 | False | 2024-05-09T13:52:47Z | 2024-05-24T10:34:42Z | transformers | 6 | 0 | null | text-generation | {"parameters": {"F16": 8030261248}, "total": 8030261248} | [
".gitattributes",
"README.md",
"config.json",
"generation_config.json",
"model-00001-of-00004.safetensors",
"model-00002-of-00004.safetensors",
"model-00003-of-00004.safetensors",
"model-00004-of-00004.safetensors",
"model.safetensors.index.json",
"special_tokens_map.json",
"thumbnail1-button.pn... | 7ff468dde3f91b5e191e3b82ef3b78cf3e886560 | [
"transformers",
"safetensors",
"llama",
"text-generation",
"conversational",
"license:mit",
"text-generation-inference",
"endpoints_compatible",
"deploy:azure",
"region:us"
] | null | {"architectures": ["LlamaForCausalLM"], "model_type": "llama", "tokenizer_config": {"bos_token": "<|begin_of_text|>", "chat_template": "{% set loop_messages = messages %}{% for message in loop_messages %}{% set content = '<|start_header_id|>' + message['role'] + '<|end_header_id|>\n\n'+ message['content'] | trim + '<|e... | {
"auto_model": "AutoModelForCausalLM",
"custom_class": null,
"pipeline_tag": "text-generation",
"processor": "AutoTokenizer"
} | {"base_model": null, "datasets": null, "eval_results": null, "language": null, "library_name": "transformers", "license": "mit", "license_name": null, "license_link": null, "metrics": null, "model_name": null, "pipeline_tag": null, "tags": null} | # LLM Model Merging
## YouTube Tutorial
<div align="center">
<a href="https://youtu.be/gNXBp3wttFU">Model Merging: Merge LLMs to Create Frankestein Models - Python, HuggingFace, Mergekit</a>
<br>
<br>
<a href="https://youtu.be/gNXBp3wttFU">
<img src="./thumbnail1-button.png" height="85%" width=... | null | [
"mit"
] | null | null | 8,030,261,248 | null | null | [
"AutoModelForCausalLM",
"llama",
"LlamaForCausalLM"
] | [
"text-generation"
] | [
"text"
] | [
"text"
] | [
"text"
] |
671277243db2ca4084d6efa9 | c1fc0adde7a41a26 | 8386a692be535934 | 51,866 | BPE | 50,000 | false | true | true | true | 1,609 | null | ByteLevel | ByteLevel | null | [
"ByteLevel"
] | [
"ByteLevel"
] | 594 | kotoba-tech/kotoba-whisper-v2.2 | kotoba-tech | null | 14,876 | 317,834 | False | 2024-10-18T14:56:36Z | 2024-10-23T00:49:36Z | transformers | 97 | 1 | null | automatic-speech-recognition | {"parameters": {"F32": 756405760}, "total": 756405760} | [
".gitattributes",
".gitignore",
"README.md",
"added_tokens.json",
"config.json",
"generation_config.json",
"kotoba_whisper.py",
"merges.txt",
"model.safetensors",
"normalizer.json",
"pipeline/kotoba_whisper.py",
"pipeline/push_pipeline.py",
"pipeline/test_pipeline.py",
"pipeline/test_speak... | 9d33482a0eb9b57f1ad80708e8ac5538246d8355 | [
"transformers",
"safetensors",
"whisper",
"automatic-speech-recognition",
"audio",
"hf-asr-leaderboard",
"ja",
"license:apache-2.0",
"endpoints_compatible",
"deploy:azure",
"region:us"
] | null | {"architectures": ["WhisperForConditionalGeneration"], "model_type": "whisper", "tokenizer_config": {"bos_token": "<|endoftext|>", "eos_token": "<|endoftext|>", "pad_token": "<|endoftext|>", "unk_token": "<|endoftext|>"}} | {
"auto_model": "AutoModelForSpeechSeq2Seq",
"custom_class": null,
"pipeline_tag": "automatic-speech-recognition",
"processor": "AutoProcessor"
} | {"base_model": null, "datasets": null, "eval_results": null, "language": "ja", "library_name": "transformers", "license": "apache-2.0", "license_name": null, "license_link": null, "metrics": null, "model_name": null, "pipeline_tag": "automatic-speech-recognition", "tags": ["audio", "automatic-speech-recognition", "hf-a... | # Kotoba-Whisper-v2.2
_Kotoba-Whisper-v2.2_ is a Japanese ASR model based on [kotoba-tech/kotoba-whisper-v2.0](https://huggingface.co/kotoba-tech/kotoba-whisper-v2.0), with
additional postprocessing stacks integrated as [`pipeline`](https://huggingface.co/docs/transformers/en/main_classes/pipelines). The new features ... | null | [
"apache-2.0"
] | null | [
"ja"
] | 756,405,760 | null | null | [
"WhisperForConditionalGeneration",
"whisper",
"AutoModelForSpeechSeq2Seq"
] | [
"automatic-speech-recognition"
] | [
"multimodal"
] | [
"audio"
] | [
"text"
] |
6557ba3f2ac07d8c00393ddc | 6a4a07acf6212099 | 625319e7b610da21 | 128,001 | Unigram | null | true | true | true | true | 5 | NFKC | Metaspace | Metaspace | [
"NFKC"
] | [
"Metaspace"
] | [
"Metaspace"
] | 229 | sdadas/mmlw-roberta-large | sdadas | null | 4,943 | 270,789 | False | 2023-11-17T19:08:47Z | 2026-02-12T11:05:14Z | sentence-transformers | 13 | 0 | [{"name": "mmlw-roberta-large", "results": [{"task": {"type": "Clustering"}, "dataset": {"type": "PL-MTEB/8tags-clustering", "name": "MTEB 8TagsClustering", "config": "default", "split": "test", "revision": "None"}, "metrics": [{"type": "v_measure", "value": 31.16472823814849, "verified": false}]}, {"task": {"type": "C... | sentence-similarity | {"parameters": {"F32": 434961408}, "total": 434961408} | [
".gitattributes",
"1_Pooling/config.json",
"README.md",
"added_tokens.json",
"config.json",
"config_sentence_transformers.json",
"model.safetensors",
"modules.json",
"pytorch_model.bin",
"sentence_bert_config.json",
"special_tokens_map.json",
"tokenizer.json",
"tokenizer_config.json",
"uni... | 9889556c415e732383f86140f72a6c63a6edcbf5 | [
"sentence-transformers",
"pytorch",
"safetensors",
"roberta",
"feature-extraction",
"sentence-similarity",
"transformers",
"mteb",
"pl",
"license:apache-2.0",
"model-index",
"text-embeddings-inference",
"endpoints_compatible",
"deploy:azure",
"region:us"
] | null | {"architectures": ["RobertaModel"], "model_type": "roberta", "tokenizer_config": {"bos_token": "<s>", "cls_token": "<s>", "eos_token": "</s>", "mask_token": "<mask>", "pad_token": "<pad>", "sep_token": "</s>", "unk_token": "<unk>"}} | {
"auto_model": "AutoModel",
"custom_class": null,
"pipeline_tag": "feature-extraction",
"processor": "AutoTokenizer"
} | {"language": "pl", "license": "apache-2.0", "pipeline_tag": "sentence-similarity", "tags": ["sentence-transformers", "feature-extraction", "sentence-similarity", "transformers", "mteb"], "widget": [{"source_sentence": "zapytanie: Jak do\u017cy\u0107 100 lat?", "sentences": ["Trzeba zdrowo si\u0119 od\u017cywia\u0107 i ... | <h1 align="center">MMLW-roberta-large</h1>
MMLW (muszę mieć lepszą wiadomość) are neural text encoders for Polish.
This is a distilled model that can be used to generate embeddings applicable to many tasks such as semantic similarity, clustering, information retrieval. The model can also serve as a base for further fi... | null | [
"apache-2.0"
] | null | [
"pl"
] | 434,961,408 | null | null | [
"roberta",
"AutoModel",
"RobertaModel"
] | [
"sentence-similarity",
"feature-extraction"
] | [
"text",
"multimodal"
] | [
"text"
] | [
"logits",
"embeddings"
] |
66b418d953a224f2def79ba9 | c97a6495c5454551 | f26f356cd728caa8 | 49,408 | BPE | 48,894 | true | true | true | true | 2 | Sequence | Sequence | ByteLevel | [
"NFC",
"Replace",
"Lowercase"
] | [
"Split",
"ByteLevel"
] | [
"ByteLevel"
] | 2 | Marqo/marqo-fashionCLIP | Marqo | null | 50,165 | 420,221 | False | 2024-08-08T01:01:13Z | 2024-10-12T21:26:43Z | open_clip | 28 | 0 | null | zero-shot-image-classification | {"parameters": {"F32": 149620736}, "total": 149620736} | [
".gitattributes",
"README.md",
"config.json",
"marqo_fashionCLIP.py",
"merges.txt",
"model.safetensors",
"onnx/text_model.onnx",
"onnx/text_model_bnb4.onnx",
"onnx/text_model_fp16.onnx",
"onnx/text_model_int8.onnx",
"onnx/text_model_q4.onnx",
"onnx/text_model_q4f16.onnx",
"onnx/text_model_qu... | 44f4c655124ed71e90cbf528d82f508d69d8a81b | [
"open_clip",
"onnx",
"safetensors",
"clip",
"e-commerce",
"fashion",
"multimodal retrieval",
"transformers.js",
"transformers",
"zero-shot-image-classification",
"custom_code",
"en",
"license:apache-2.0",
"region:us"
] | null | {"auto_map": {"AutoConfig": "marqo_fashionCLIP.MarqoFashionCLIPConfig", "AutoModel": "marqo_fashionCLIP.MarqoFashionCLIP", "AutoProcessor": "marqo_fashionCLIP.CLIPProcessor"}, "model_type": "clip", "tokenizer_config": {"bos_token": "<|startoftext|>", "eos_token": "<|endoftext|>", "pad_token": "!", "unk_token": "<|endof... | {
"auto_model": "AutoModel",
"custom_class": null,
"pipeline_tag": null,
"processor": null
} | {"base_model": null, "datasets": null, "eval_results": null, "language": ["en"], "library_name": "open_clip", "license": "apache-2.0", "license_name": null, "license_link": null, "metrics": ["precision", "recall", "MRR"], "model_name": null, "pipeline_tag": "zero-shot-image-classification", "tags": ["clip", "e-commerce... | [](https://github.com/marqo-ai/marqo-FashionCLIP)
# Marqo-FashionCLIP Model Card
Marqo-FashionCLIP and Marqo-FashionSigLIP outperform the previous state-of-the-art fashion CLIP models (see results below).
Marqo-FashionCLIP leverages Generalised Contrasti... | null | [
"apache-2.0"
] | null | [
"en"
] | 149,620,736 | null | [
"precision",
"recall",
"MRR"
] | [
"AutoModel",
"clip"
] | [
null,
"zero-shot-image-classification"
] | [
"multimodal"
] | [
"text",
"image"
] | [
"logits"
] |
68780165eeb859cad1e4edb3 | 6a67cbd79bab1e59 | cf1efbe71ef28fc9 | 50,368 | BPE | 50,009 | true | true | true | true | 116 | NFC | ByteLevel | ByteLevel | [
"NFC"
] | [
"ByteLevel"
] | [
"ByteLevel"
] | 395 | OpenMed/OpenMed-NER-PharmaDetect-ModernMed-395M | OpenMed | null | 92,528 | 568,933 | False | 2025-07-16T19:45:41Z | 2025-08-05T09:36:58Z | transformers | 0 | 0 | null | token-classification | {"parameters": {"BF16": 395834371}, "total": 395834371} | [
".gitattributes",
"README.md",
"config.json",
"model.safetensors",
"openmed_vs_sota_grouped_bars.png",
"special_tokens_map.json",
"test_results.json",
"tokenizer.json",
"tokenizer_config.json"
] | a8ac7e6aeceb6bfbab8c1f28e14a4d4d089de972 | [
"transformers",
"safetensors",
"modernbert",
"token-classification",
"named-entity-recognition",
"biomedical-nlp",
"chemical-entity-recognition",
"drug-discovery",
"pharmacology",
"biocuration",
"chem",
"en",
"arxiv:2508.01630",
"license:apache-2.0",
"endpoints_compatible",
"region:us"... | null | {"architectures": ["ModernBertForTokenClassification"], "model_type": "modernbert", "tokenizer_config": {"cls_token": "[CLS]", "mask_token": "[MASK]", "pad_token": "[PAD]", "sep_token": "[SEP]", "unk_token": "[UNK]"}} | {
"auto_model": "AutoModelForTokenClassification",
"custom_class": null,
"pipeline_tag": "token-classification",
"processor": "AutoTokenizer"
} | {"base_model": null, "datasets": null, "eval_results": null, "language": ["en"], "library_name": null, "license": "apache-2.0", "license_name": null, "license_link": null, "metrics": null, "model_name": null, "pipeline_tag": null, "tags": ["token-classification", "named-entity-recognition", "biomedical-nlp", "transform... | null | null | [
"apache-2.0"
] | null | [
"en"
] | 395,834,371 | null | null | [
"AutoModelForTokenClassification",
"ModernBertForTokenClassification",
"modernbert"
] | [
"token-classification"
] | [
"text"
] | [
"text"
] | [
"logits"
] |
621ffdc036468d709f1752e0 | 8630f5c21f91f183 | 499e5ab431f13c38 | 32,005 | BPE | 61,442 | true | true | true | true | 7 | Sequence | Metaspace | Metaspace | [
"Precompiled",
"Replace"
] | [
"Metaspace"
] | [
"Metaspace"
] | 701 | EMBEDDIA/sloberta | EMBEDDIA | null | 1,270 | 219,410 | False | 2022-03-02T23:29:04Z | 2021-11-24T13:46:22Z | transformers | 5 | 0 | null | fill-mask | null | [
".gitattributes",
"README.md",
"config.json",
"dict.txt",
"pytorch_model.bin",
"sentencepiece.bpe.model",
"special_tokens_map.json",
"tokenizer.json",
"tokenizer_config.json"
] | 49db152a3bea54016773be3cce126a9b5ece88da | [
"transformers",
"pytorch",
"camembert",
"fill-mask",
"sl",
"license:cc-by-sa-4.0",
"endpoints_compatible",
"deploy:azure",
"region:us"
] | null | {"architectures": ["CamembertForMaskedLM"], "model_type": "camembert", "tokenizer_config": {"bos_token": "<s>", "eos_token": "</s>", "sep_token": "</s>", "cls_token": "<s>", "unk_token": "<unk>", "pad_token": "<pad>", "mask_token": {"content": "<mask>", "single_word": false, "lstrip": true, "rstrip": false, "normalized... | {
"auto_model": "AutoModelForMaskedLM",
"custom_class": null,
"pipeline_tag": "fill-mask",
"processor": "AutoTokenizer"
} | {"base_model": null, "datasets": null, "eval_results": null, "language": ["sl"], "library_name": null, "license": "cc-by-sa-4.0", "license_name": null, "license_link": null, "metrics": null, "model_name": null, "pipeline_tag": null, "tags": null} | # Usage
Load in transformers library with:
```
from transformers import AutoTokenizer, AutoModelForMaskedLM
tokenizer = AutoTokenizer.from_pretrained("EMBEDDIA/sloberta")
model = AutoModelForMaskedLM.from_pretrained("EMBEDDIA/sloberta")
```
# SloBERTa
SloBERTa model is a monolingual Slovene BERT-like model. It... | null | [
"cc-by-sa-4.0"
] | null | [
"sl"
] | null | null | null | [
"CamembertForMaskedLM",
"AutoModelForMaskedLM",
"camembert"
] | [
"fill-mask"
] | [
"text"
] | [
"text"
] | [
"logits"
] |
66608ae3881e548195f6187d | 418f2985b1deb0a3 | 51ffe6e3b0b5db96 | 32,120 | Unigram | null | true | true | true | true | 123 | Precompiled | Sequence | Metaspace | [
"Precompiled"
] | [
"WhitespaceSplit",
"Metaspace"
] | [
"Metaspace"
] | 702 | royweiss1/T5_MiddleSentences | royweiss1 | null | 96,560 | 142,004 | False | 2024-06-05T15:57:23Z | 2024-08-19T16:10:55Z | transformers | 0 | 0 | null | null | null | [
".gitattributes",
"README.md",
"config.json",
"generation_config.json",
"pytorch_model.bin",
"special_tokens_map.json",
"tokenizer.json",
"tokenizer_config.json",
"training_args.bin"
] | 07e2b3fc96bc129eb4a2871e58731c07e889cecc | [
"transformers",
"pytorch",
"t5",
"text2text-generation",
"en",
"dataset:royweiss1/GPT_Keylogger_Dataset",
"license:mit",
"text-generation-inference",
"endpoints_compatible",
"region:us"
] | null | {"architectures": ["T5ForConditionalGeneration"], "model_type": "t5", "tokenizer_config": {"eos_token": "</s>", "pad_token": "<pad>", "unk_token": "<unk>"}} | {
"auto_model": "AutoModelForSeq2SeqLM",
"custom_class": null,
"pipeline_tag": "text2text-generation",
"processor": "AutoTokenizer"
} | {"base_model": null, "datasets": ["royweiss1/GPT_Keylogger_Dataset"], "eval_results": null, "language": ["en"], "library_name": null, "license": "mit", "license_name": null, "license_link": null, "metrics": null, "model_name": null, "pipeline_tag": null, "tags": null} | This is the model used in the USENIX Security 24' paper: "What Was Your Prompt? A Remote Keylogging Attack on AI Assistants".
It is a fine-tune of T5-Large that was trained to decipher ChatGPT's encrypted answers based only on the response's token lengths.
This model is the middle-sentences model. Meaning it was traine... | null | [
"mit"
] | [
"royweiss1/GPT_Keylogger_Dataset"
] | [
"en"
] | null | null | null | [
"t5",
"T5ForConditionalGeneration",
"AutoModelForSeq2SeqLM"
] | [
"text2text-generation"
] | null | null | null |
679bec0acc91acf0b5bab13b | d944255e7d785801 | 2f8c3374367f63f8 | 131,072 | BPE | 269,443 | false | true | true | true | 1,000 | null | Sequence | ByteLevel | null | [
"Split",
"ByteLevel"
] | [
"ByteLevel"
] | 568 | unsloth/Mistral-Small-24B-Instruct-2501 | unsloth | {
"models": [
{
"_id": "6798dbe54a10be7109f954f2",
"id": "mistralai/Mistral-Small-24B-Instruct-2501"
}
],
"relation": "finetune"
} | 10,889 | 340,723 | False | 2025-01-30T21:15:54Z | 2025-02-02T04:55:47Z | transformers | 7 | 0 | null | text-generation | {"parameters": {"BF16": 23572403200}, "total": 23572403200} | [
".gitattributes",
"README.md",
"config.json",
"generation_config.json",
"model-00001-of-00010.safetensors",
"model-00002-of-00010.safetensors",
"model-00003-of-00010.safetensors",
"model-00004-of-00010.safetensors",
"model-00005-of-00010.safetensors",
"model-00006-of-00010.safetensors",
"model-0... | 2eddef095b2d91c22c59cc3ede00ec595e530d16 | [
"transformers",
"safetensors",
"mistral",
"text-generation",
"unsloth",
"mistral-instruct",
"instruct",
"conversational",
"en",
"base_model:mistralai/Mistral-Small-24B-Instruct-2501",
"base_model:finetune:mistralai/Mistral-Small-24B-Instruct-2501",
"license:apache-2.0",
"text-generation-infe... | null | {"architectures": ["MistralForCausalLM"], "model_type": "mistral", "tokenizer_config": {"bos_token": "<s>", "chat_template": "{%- set today = strftime_now(\"%Y-%m-%d\") %}\n{%- set default_system_message = \"You are Mistral Small 3, a Large Language Model (LLM) created by Mistral AI, a French startup headquartered in P... | {
"auto_model": "AutoModelForCausalLM",
"custom_class": null,
"pipeline_tag": "text-generation",
"processor": "AutoTokenizer"
} | {"base_model": "mistralai/Mistral-Small-24B-Instruct-2501", "datasets": null, "eval_results": null, "language": ["en"], "library_name": "transformers", "license": "apache-2.0", "license_name": null, "license_link": null, "metrics": null, "model_name": null, "pipeline_tag": null, "tags": ["unsloth", "transformers", "mis... | # Finetune LLMs 2-5x faster with 70% less memory via Unsloth!
We have a free Google Colab Tesla T4 notebook for Mistral (7B) here: https://colab.research.google.com/github/unslothai/notebooks/blob/main/nb/Mistral_v0.3_(7B)-Conversational.ipynb
[<img src="https://raw.githubusercontent.com/unslothai/unsloth/main/images/... | null | [
"apache-2.0"
] | null | [
"en"
] | 23,572,403,200 | null | null | [
"AutoModelForCausalLM",
"mistral",
"MistralForCausalLM"
] | [
"text-generation"
] | [
"text"
] | [
"text"
] | [
"text"
] |
66f3f9970e5e6af3026dfd4e | 1fa87a4b3e997943 | dd84a2b1ff97657d | 250,002 | Unigram | null | true | true | true | true | 5 | Sequence | Metaspace | Metaspace | [
"Precompiled",
"Strip",
"Replace"
] | [
"Metaspace"
] | [
"Metaspace"
] | 703 | sdadas/polish-reranker-bge-v2 | sdadas | null | 199 | 218,366 | False | 2024-09-25T11:52:55Z | 2025-04-02T15:09:29Z | sentence-transformers | 2 | 0 | null | text-ranking | {"parameters": {"F32": 567755777}, "total": 567755777} | [
".gitattributes",
"README.md",
"config.json",
"configuration_xlm_roberta.py",
"model.safetensors",
"modeling_xlm_roberta.py",
"sentencepiece.bpe.model",
"special_tokens_map.json",
"tokenizer.json",
"tokenizer_config.json"
] | d2d7e2f95ca8353c6cbfe3ebad2e750d7a1d5d1c | [
"sentence-transformers",
"safetensors",
"xlm-roberta",
"text-classification",
"transformers",
"information-retrieval",
"text-ranking",
"custom_code",
"pl",
"arxiv:2402.14318",
"license:gemma",
"text-embeddings-inference",
"endpoints_compatible",
"region:us"
] | null | {"architectures": ["XLMRobertaForSequenceClassification"], "auto_map": {"AutoModel": "modeling_xlm_roberta.XLMRobertaModel", "AutoModelForSequenceClassification": "modeling_xlm_roberta.XLMRobertaForSequenceClassification", "AutoConfig": "modeling_xlm_roberta.XLMRobertaConfig"}, "model_type": "xlm-roberta", "tokenizer_c... | {
"auto_model": "AutoModelForSequenceClassification",
"custom_class": null,
"pipeline_tag": "text-classification",
"processor": "AutoTokenizer"
} | {"base_model": null, "datasets": null, "eval_results": null, "language": "pl", "library_name": "sentence-transformers", "license": "gemma", "license_name": null, "license_link": null, "metrics": null, "model_name": null, "pipeline_tag": "text-ranking", "tags": ["transformers", "information-retrieval"]} | <h1 align="center">polish-reranker-bge-v2</h1>
This is a reranker for Polish based on [BAAI/bge-reranker-v2-m3](https://huggingface.co/BAAI/bge-reranker-v2-m3) and further fine-tuned on large dataset of text pairs:
- We utilised [RankNet loss](https://icml.cc/Conferences/2015/wp-content/uploads/2015/06/icml_ranking.pd... | null | [
"gemma"
] | null | [
"pl"
] | 567,755,777 | null | null | [
"AutoModelForSequenceClassification",
"XLMRobertaForSequenceClassification",
"xlm-roberta"
] | [
"text-ranking",
"text-classification"
] | [
"text"
] | [
"text"
] | [
"logits"
] |
621ffdc136468d709f1794d8 | a4ea8f3be4c3e2c7 | 873dd6f00e997067 | 64,000 | BPE | 63,740 | false | true | true | true | 4 | null | ByteLevel | ByteLevel | null | [
"ByteLevel"
] | [
"ByteLevel"
] | 488 | aubmindlab/aragpt2-mega | aubmindlab | null | 389 | 215,186 | False | 2022-03-02T23:29:05Z | 2024-10-24T11:27:14Z | transformers | 10 | 0 | null | text-generation | {"parameters": {"F32": 1459792896, "U8": 50331648}, "total": 1510124544} | [
".gitattributes",
"LICENSE",
"README.md",
"config.json",
"configuration_aragpt2.py",
"merges.txt",
"model.safetensors",
"modeling_aragpt2.py",
"pytorch_model.bin",
"runs/eval/events.out.tfevents.1608742056.tpu-mother",
"runs/eval/events.out.tfevents.1609188791.tpu-mother",
"runs/eval/events.ou... | 0c129c98931a9d888080c83c410ec67960ea4dff | [
"transformers",
"pytorch",
"tensorboard",
"safetensors",
"aragpt2",
"text-generation",
"custom_code",
"ar",
"dataset:wikipedia",
"dataset:Osian",
"dataset:arabic-billion-words",
"dataset:oscar",
"dataset:Assafir-private",
"arxiv:2012.15520",
"license:other",
"region:us"
] | null | {"architectures": ["AraGPT2LMHeadModel"], "auto_map": {"AutoConfig": "configuration_aragpt2.AraGPT2Config", "AutoModelForCausalLM": "modeling_aragpt2.AraGPT2LMHeadModel", "AutoModel": "modeling_aragpt2.AraGPT2Model"}, "model_type": "aragpt2"} | {
"auto_model": "AutoModelForCausalLM",
"custom_class": "modeling_aragpt2.AraGPT2LMHeadModel",
"pipeline_tag": "text-generation",
"processor": null
} | {"base_model": null, "datasets": ["wikipedia", "Osian", "arabic-billion-words", "oscar", "Assafir-private"], "eval_results": null, "language": "ar", "library_name": null, "license": "other", "license_name": "custom", "license_link": "https://github.com/aub-mind/arabert/blob/master/aragpt2/LICENSE", "metrics": null, "mo... | # Arabic GPT2
<img src="https://raw.githubusercontent.com/aub-mind/arabert/master/AraGPT2.png" width="100" align="left"/>
You can find more information in our paper [AraGPT2](https://arxiv.org/abs/2012.15520)
The code in this repository was used to train all GPT2 variants. The code support training and fine-tuning... | null | [
"other",
"custom",
"https://github.com/aub-mind/arabert/blob/master/aragpt2/LICENSE"
] | [
"wikipedia",
"Osian",
"arabic-billion-words",
"oscar",
"Assafir-private"
] | [
"ar"
] | 1,510,124,544 | null | null | [
"AutoModelForCausalLM",
"AraGPT2LMHeadModel",
"modeling_aragpt2.AraGPT2LMHeadModel",
"aragpt2"
] | [
"text-generation"
] | [
"text"
] | [
"text"
] | [
"text"
] |
6697737fbaad0b91e65b3623 | 53ecf467267e2824 | 535fa14da0af647c | 30,522 | WordPiece | null | true | true | true | true | 5 | BertNormalizer | BertPreTokenizer | WordPiece | [
"BertNormalizer"
] | [
"BertPreTokenizer"
] | [
"WordPiece"
] | 0 | opensearch-project/opensearch-neural-sparse-encoding-v2-distill | opensearch-project | null | 195,433 | 558,883 | False | 2024-07-17T07:32:15Z | 2025-06-30T06:31:38Z | sentence-transformers | 10 | 0 | null | feature-extraction | {"parameters": {"F32": 66985530}, "total": 66985530} | [
".gitattributes",
"1_SpladePooling/config.json",
"README.md",
"config.json",
"config_sentence_transformers.json",
"model.safetensors",
"modules.json",
"pytorch_model.bin",
"sentence_bert_config.json",
"special_tokens_map.json",
"tokenizer.json",
"tokenizer_config.json",
"vocab.txt"
] | 269e6638b2c4f648996691f6d751495285d8f330 | [
"sentence-transformers",
"pytorch",
"safetensors",
"distilbert",
"fill-mask",
"learned sparse",
"opensearch",
"transformers",
"retrieval",
"passage-retrieval",
"query-expansion",
"document-expansion",
"bag-of-words",
"sparse-encoder",
"sparse",
"splade",
"feature-extraction",
"en",... | null | {"architectures": ["DistilBertForMaskedLM"], "model_type": "distilbert", "tokenizer_config": {"cls_token": "[CLS]", "mask_token": "[MASK]", "pad_token": "[PAD]", "sep_token": "[SEP]", "unk_token": "[UNK]"}} | {
"auto_model": "AutoModelForMaskedLM",
"custom_class": null,
"pipeline_tag": "fill-mask",
"processor": "AutoTokenizer"
} | {"base_model": null, "datasets": null, "eval_results": null, "language": "en", "library_name": "sentence-transformers", "license": "apache-2.0", "license_name": null, "license_link": null, "metrics": null, "model_name": null, "pipeline_tag": "feature-extraction", "tags": ["learned sparse", "opensearch", "transformers",... | null | null | [
"apache-2.0"
] | null | [
"en"
] | 66,985,530 | null | null | [
"distilbert",
"AutoModelForMaskedLM",
"DistilBertForMaskedLM"
] | [
"fill-mask",
"feature-extraction"
] | [
"text",
"multimodal"
] | [
"text"
] | [
"logits",
"embeddings"
] |
66869ef922e1db851dc7b9a5 | 8c865886649cbbf2 | e979b3df4a15d906 | 32,001 | BPE | 61,249 | true | false | true | true | 4 | Sequence | null | Sequence | [
"Prepend",
"Replace"
] | null | [
"Replace",
"ByteFallback",
"Fuse",
"Strip"
] | 704 | omni-research/Tarsier-7b | omni-research | null | 79,245 | 470,866 | auto | 2024-07-04T13:09:13Z | 2024-07-05T09:30:10Z | transformers | 25 | 0 | null | text-generation | {"parameters": {"F16": 7063427072}, "total": 7063427072} | [
".gitattributes",
"README.md",
"added_tokens.json",
"config.json",
"model-00001-of-00003.safetensors",
"model-00002-of-00003.safetensors",
"model-00003-of-00003.safetensors",
"model.safetensors.index.json",
"preprocessor_config.json",
"special_tokens_map.json",
"tokenizer.json",
"tokenizer.mod... | b672c01e621e30bc43e8e709e3dee44ef50490ea | [
"transformers",
"safetensors",
"llava",
"text-generation",
"arxiv:2407.00634",
"license:llama2",
"endpoints_compatible",
"region:us"
] | null | {"architectures": ["TarsierForConditionalGeneration"], "model_type": "llava", "tokenizer_config": {"bos_token": "<s>", "eos_token": "</s>", "pad_token": "<unk>", "unk_token": "<unk>", "use_default_system_prompt": false}} | {
"auto_model": "AutoModelForSeq2SeqLM",
"custom_class": null,
"pipeline_tag": "text-generation",
"processor": "AutoProcessor"
} | {"base_model": null, "datasets": null, "eval_results": null, "language": null, "library_name": null, "license": "llama2", "license_name": null, "license_link": null, "metrics": null, "model_name": null, "pipeline_tag": null, "tags": null} | # Tarsier Model Card
## Model details
**Model type:**
Tarsier-7b is one of the Tarsier family -- an open-source large-scale video-language models, which is designed to generate high-quality video descriptions, together with good capability of general video understanding (Tarsier-34b gains SOTA results on 6 open benchm... | null | [
"llama2"
] | null | null | 7,063,427,072 | null | null | [
"TarsierForConditionalGeneration",
"llava",
"AutoModelForSeq2SeqLM"
] | [
"text-generation"
] | [
"text"
] | [
"text"
] | [
"text"
] |
680f797f84e976c24e7a61e3 | 7428ef9ae5ef868f | 67da9c236fa81925 | 151,669 | BPE | 151,387 | true | true | true | true | 26 | NFC | Sequence | ByteLevel | [
"NFC"
] | [
"Split",
"ByteLevel"
] | [
"ByteLevel"
] | 47 | unsloth/Qwen3-4B-Base | unsloth | {
"models": [
{
"_id": "680f0c5b4e1c1da6491f3b9d",
"id": "Qwen/Qwen3-4B-Base"
}
],
"relation": "finetune"
} | 102,467 | 580,252 | False | 2025-04-28T12:50:07Z | 2025-05-13T02:30:06Z | transformers | 5 | 0 | null | text-generation | null | [
".gitattributes",
"README.md",
"added_tokens.json",
"config.json",
"generation_config.json",
"merges.txt",
"model-00001-of-00002.safetensors",
"model-00002-of-00002.safetensors",
"model.safetensors.index.json",
"special_tokens_map.json",
"tokenizer.json",
"tokenizer_config.json",
"vocab.json... | 0573b584bc6b32adc84bb9c91bf9b71bea71fc40 | [
"transformers",
"safetensors",
"qwen3",
"text-generation",
"unsloth",
"base_model:Qwen/Qwen3-4B-Base",
"base_model:finetune:Qwen/Qwen3-4B-Base",
"license:apache-2.0",
"text-generation-inference",
"endpoints_compatible",
"region:us"
] | null | {"architectures": ["Qwen3ForCausalLM"], "model_type": "qwen3", "tokenizer_config": {"bos_token": null, "eos_token": "<|endoftext|>", "pad_token": "<|vision_pad|>", "unk_token": null}} | {
"auto_model": "AutoModelForCausalLM",
"custom_class": null,
"pipeline_tag": "text-generation",
"processor": "AutoTokenizer"
} | {"base_model": ["Qwen/Qwen3-4B-Base"], "datasets": null, "eval_results": null, "language": null, "library_name": "transformers", "license": "apache-2.0", "license_name": null, "license_link": null, "metrics": null, "model_name": null, "pipeline_tag": null, "tags": ["unsloth"]} | # Qwen3-4B-Base
## Qwen3 Highlights
Qwen3 is the latest generation of large language models in Qwen series, offering a comprehensive suite of dense and mixture-of-experts (MoE) models.
Building upon extensive advancements in training data, model architecture, and optimization techniques, Qwen3 delivers the following... | null | [
"apache-2.0"
] | null | null | null | null | null | [
"AutoModelForCausalLM",
"Qwen3ForCausalLM",
"qwen3"
] | [
"text-generation"
] | [
"text"
] | [
"text"
] | [
"text"
] |
67ee17c75e1b098a5e86b3c7 | 8b2ea89605281e7b | 0d1b0351a03fb052 | 200,029 | BPE | 199,742 | false | true | false | true | 14 | null | Sequence | ByteLevel | null | [
"Split",
"ByteLevel"
] | [
"ByteLevel"
] | 140 | katuni4ka/tiny-random-phi-4-multimodal | katuni4ka | null | 583 | 215,036 | False | 2025-04-03T05:08:23Z | 2025-05-23T11:41:41Z | transformers | 0 | 0 | null | image-text-to-text | {"parameters": {"F32": 6463040}, "total": 6463040} | [
".gitattributes",
"README.md",
"added_tokens.json",
"config.json",
"configuration_phi4mm.py",
"generation_config.json",
"merges.txt",
"model.safetensors",
"modeling_phi4mm.py",
"preprocessor_config.json",
"processing_phi4mm.py",
"processor_config.json",
"special_tokens_map.json",
"speech_c... | bf54b23f1a9ffcff304623e6d1ca386081bde3f5 | [
"transformers",
"safetensors",
"phi4mm",
"text-generation",
"image-text-to-text",
"conversational",
"custom_code",
"region:us"
] | null | {"architectures": ["Phi4MMForCausalLM"], "auto_map": {"AutoConfig": "configuration_phi4mm.Phi4MMConfig", "AutoModelForCausalLM": "modeling_phi4mm.Phi4MMForCausalLM", "AutoTokenizer": "Xenova/gpt-4o"}, "model_type": "phi4mm", "tokenizer_config": {"bos_token": "<|endoftext|>", "chat_template": "{% for message in messages... | {
"auto_model": "AutoModelForCausalLM",
"custom_class": "modeling_phi4mm.Phi4MMForCausalLM",
"pipeline_tag": "text-generation",
"processor": null
} | {"base_model": null, "datasets": null, "eval_results": null, "language": null, "library_name": "transformers", "license": null, "license_name": null, "license_link": null, "metrics": null, "model_name": null, "pipeline_tag": "image-text-to-text", "tags": null} | This tiny model is for debugging. It is randomly initialized with the config adapted from [microsoft/Phi-4-multimodal-instruct](https://huggingface.co/microsoft/Phi-4-multimodal-instruct). | null | null | null | null | 6,463,040 | null | null | [
"Phi4MMForCausalLM",
"AutoModelForCausalLM",
"phi4mm",
"modeling_phi4mm.Phi4MMForCausalLM"
] | [
"image-text-to-text",
"text-generation"
] | [
"text",
"multimodal"
] | [
"text",
"image"
] | [
"text"
] |
Subsets and Splits
No community queries yet
The top public SQL queries from the community will appear here once available.