
_id large_stringlengths 24 24 | hash large_stringlengths 16 16 | vocab_hash large_stringlengths 16 16 | vocab_size int64 1 2.4M | model_type large_stringclasses 4
values | num_merges float64 0 4.41M ⌀ | has_normalizer bool 2
classes | has_pre_tokenizer bool 2
classes | has_post_processor bool 2
classes | has_decoder bool 2
classes | num_added_tokens int64 0 479k | normalizer_type large_stringclasses 11
values | pre_tokenizer_type large_stringclasses 10
values | decoder_type large_stringclasses 9
values | normalizer_types listlengths 0 11.3k ⌀ | pre_tokenizer_types listlengths 1 35 ⌀ | decoder_types listlengths 0 24 ⌀ | tokenizer_id int64 0 24.8k | id large_stringlengths 7 122 | author stringlengths 2 41 ⌀ | base_models dict | downloads int64 0 206M | downloads_all_time int64 0 2.81B | gated stringclasses 3
values | created_at timestamp[us, tz=UTC]date 2022-03-02 23:29:04 2025-11-03 14:41:54 | last_modified timestamp[us, tz=UTC]date 2020-12-11 21:34:15 2026-03-29 10:14:05 ⌀ | library_name stringclasses 36
values | likes int64 0 13.1k | trending_score float64 0 47 | model_index stringlengths 30 911k ⌀ | pipeline_tag stringclasses 46
values | safetensors stringlengths 30 122 ⌀ | siblings listlengths 0 10k ⌀ | sha stringlengths 40 40 ⌀ | tags listlengths 2 1.82k ⌀ | gguf stringclasses 789
values | config stringlengths 2 53.7k ⌀ | transformers_info dict | card_data stringlengths 234 905k ⌀ | card stringlengths 0 638k ⌀ | spaces null | licenses listlengths 1 3 ⌀ | datasets listlengths 1 289 ⌀ | languages listlengths 1 1.81k ⌀ | safetensors_params float64 0 1,019B ⌀ | gguf_params float64 0 122B ⌀ | metrics listlengths 1 15 ⌀ | architectures listlengths 1 6 ⌀ | tasks listlengths 1 6 ⌀ | modalities listlengths 1 4 ⌀ | input_modalities listlengths 1 3 ⌀ | output_modalities listlengths 1 4 ⌀ |
|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|
64f9b609d4f4e2b6175a3e29 | ba5e93f1f8565370 | ea059d203298896f | 46,336 | BPE | 77,738 | true | false | true | true | 14,450 | Sequence | null | Sequence | [
"Prepend",
"Replace"
] | null | [
"Replace",
"ByteFallback",
"Fuse",
"Strip"
] | 877 | jb723/LLaMA2-en-ko-7B-model | jb723 | null | 17 | 120,864 | False | 2023-09-07T11:37:45Z | 2023-10-08T10:14:07Z | transformers | 0 | 0 | null | text-generation | null | [
".gitattributes",
"README.md",
"config.json",
"generation_config.json",
"pytorch_model-00001-of-00003.bin",
"pytorch_model-00002-of-00003.bin",
"pytorch_model-00003-of-00003.bin",
"pytorch_model.bin.index.json",
"special_tokens_map.json",
"tokenizer.json",
"tokenizer_config.json"
] | 24e455bbf4039f360a37833583c335582d2c6030 | [
"transformers",
"pytorch",
"llama",
"text-generation",
"text-generation-inference",
"endpoints_compatible",
"deploy:azure",
"region:us"
] | null | {"architectures": ["LlamaForCausalLM"], "model_type": "llama", "tokenizer_config": {"bos_token": {"__type": "AddedToken", "content": "<s>", "lstrip": false, "normalized": false, "rstrip": false, "single_word": false}, "eos_token": {"__type": "AddedToken", "content": "</s>", "lstrip": false, "normalized": false, "rstrip... | {
"auto_model": "AutoModelForCausalLM",
"custom_class": null,
"pipeline_tag": "text-generation",
"processor": "AutoTokenizer"
} | null | 학습 데이터 : AIHUB 한국어 영어 병렬 corpus, KoAlpaca dataset, Alpacadataset | null | null | null | null | null | null | null | [
"AutoModelForCausalLM",
"llama",
"LlamaForCausalLM"
] | [
"text-generation"
] | [
"text"
] | [
"text"
] | [
"text"
] |
6762500e382a5cd3c8b47d76 | aa22a75c2b649cab | 3222bc29782d2790 | 128,256 | BPE | 280,147 | false | true | true | true | 256 | null | Sequence | ByteLevel | null | [
"Split",
"ByteLevel"
] | [
"ByteLevel"
] | 878 | tokyotech-llm/Llama-3.1-Swallow-8B-Instruct-v0.3 | tokyotech-llm | null | 4,745 | 144,780 | False | 2024-12-18T04:31:10Z | 2025-04-02T09:16:14Z | transformers | 24 | 0 | null | text-generation | {"parameters": {"BF16": 8030261248}, "total": 8030261248} | [
".gitattributes",
"GEMMA_TERMS_OF_USE.md",
"LICENSE",
"Notice",
"README.md",
"USE_POLICY.md",
"config.json",
"generation_config.json",
"logo.png",
"model-00001-of-00004.safetensors",
"model-00002-of-00004.safetensors",
"model-00003-of-00004.safetensors",
"model-00004-of-00004.safetensors",
... | 0858f50ecfbc61eab25f353013e0be542e1312ac | [
"transformers",
"safetensors",
"llama",
"text-generation",
"conversational",
"en",
"ja",
"dataset:tokyotech-llm/lmsys-chat-1m-synth",
"dataset:tokyotech-llm/swallow-magpie-ultra-v0.1",
"dataset:tokyotech-llm/swallow-gemma-magpie-v0.1",
"dataset:lmsys/lmsys-chat-1m",
"dataset:argilla/magpie-ult... | null | {"architectures": ["LlamaForCausalLM"], "model_type": "llama", "tokenizer_config": {"bos_token": "<|begin_of_text|>", "chat_template": "{% set loop_messages = messages %}{% for message in loop_messages %}{% set content = '<|start_header_id|>' + message['role'] + '<|end_header_id|>\n\n'+ message['content'] | trim + '<|e... | {
"auto_model": "AutoModelForCausalLM",
"custom_class": null,
"pipeline_tag": "text-generation",
"processor": "AutoTokenizer"
} | {"base_model": null, "datasets": ["tokyotech-llm/lmsys-chat-1m-synth", "tokyotech-llm/swallow-magpie-ultra-v0.1", "tokyotech-llm/swallow-gemma-magpie-v0.1", "lmsys/lmsys-chat-1m", "argilla/magpie-ultra-v0.1"], "eval_results": null, "language": ["en", "ja"], "library_name": "transformers", "license": ["llama3.1", "gemma... | # Llama 3.1 Swallow - Built with Llama
Llama 3.1 Swallow is a series of large language models (8B, 70B) that were built by continual pre-training on the [Meta Llama 3.1](https://huggingface.co/collections/meta-llama/llama-31-669fc079a0c406a149a5738f) models.
Llama 3.1 Swallow enhanced the Japanese language capabilitie... | null | [
"llama3.1",
"gemma"
] | [
"tokyotech-llm/lmsys-chat-1m-synth",
"tokyotech-llm/swallow-magpie-ultra-v0.1",
"tokyotech-llm/swallow-gemma-magpie-v0.1",
"lmsys/lmsys-chat-1m",
"argilla/magpie-ultra-v0.1"
] | [
"en",
"ja"
] | 8,030,261,248 | null | null | [
"AutoModelForCausalLM",
"llama",
"LlamaForCausalLM"
] | [
"text-generation"
] | [
"text"
] | [
"text"
] | [
"text"
] |
652615dffa9f6e5694a1f7a0 | 88cd37e502d27a0a | 0e7bc0977f200d1c | 32,000 | BPE | 58,980 | true | false | true | true | 3 | Sequence | null | Sequence | [
"Prepend",
"Replace"
] | null | [
"Replace",
"ByteFallback",
"Fuse",
"Strip"
] | 88 | TheBloke/zephyr-7B-alpha-GPTQ | TheBloke | {
"models": [
{
"_id": "6523bd962d3ba46ccd378b5a",
"id": "HuggingFaceH4/zephyr-7b-alpha"
}
],
"relation": "quantized"
} | 42 | 120,963 | False | 2023-10-11T03:26:23Z | 2023-10-14T07:12:11Z | transformers | 26 | 0 | [{"name": "zephyr-7b-alpha", "results": []}] | text-generation | {"parameters": {"I32": 6979321856, "F16": 263786496}, "total": 7243108352} | [
".gitattributes",
"README.md",
"all_results.json",
"config.json",
"dialogue_template.json",
"eval_results.json",
"generation_config.json",
"model.safetensors",
"quantize_config.json",
"special_tokens_map.json",
"tokenizer.json",
"tokenizer.model",
"tokenizer_config.json",
"train_results.js... | 682cb0e46676af6133c6906f5336fe496bfd383f | [
"transformers",
"safetensors",
"mistral",
"text-generation",
"generated_from_trainer",
"en",
"dataset:stingning/ultrachat",
"dataset:openbmb/UltraFeedback",
"arxiv:2305.18290",
"base_model:HuggingFaceH4/zephyr-7b-alpha",
"base_model:quantized:HuggingFaceH4/zephyr-7b-alpha",
"license:mit",
"t... | null | {"architectures": ["MistralForCausalLM"], "model_type": "mistral", "quantization_config": {"bits": 4, "quant_method": "gptq"}, "tokenizer_config": {"bos_token": "<s>", "eos_token": "</s>", "pad_token": "</s>", "unk_token": "<unk>", "use_default_system_prompt": true}} | {
"auto_model": "AutoModelForCausalLM",
"custom_class": null,
"pipeline_tag": "text-generation",
"processor": "AutoTokenizer"
} | {"base_model": "HuggingFaceH4/zephyr-7b-alpha", "datasets": ["stingning/ultrachat", "openbmb/UltraFeedback"], "eval_results": [], "language": ["en"], "library_name": null, "license": "mit", "license_name": null, "license_link": null, "metrics": null, "model_name": "zephyr-7b-alpha", "pipeline_tag": null, "tags": ["gene... | <!-- header start -->
<!-- 200823 -->
<div style="width: auto; margin-left: auto; margin-right: auto">
<img src="https://i.imgur.com/EBdldam.jpg" alt="TheBlokeAI" style="width: 100%; min-width: 400px; display: block; margin: auto;">
</div>
<div style="display: flex; justify-content: space-between; width: 100%;">
<d... | null | [
"mit"
] | [
"stingning/ultrachat",
"openbmb/UltraFeedback"
] | [
"en"
] | 7,243,108,352 | null | null | [
"AutoModelForCausalLM",
"mistral",
"MistralForCausalLM"
] | [
"text-generation"
] | [
"text"
] | [
"text"
] | [
"text"
] |
65b37ee9ce23cf412ffa206e | 75c99c8b3493a6cb | d3a5589134b292ff | 250,100 | Unigram | null | true | true | true | true | 3 | Sequence | Metaspace | Metaspace | [
"Precompiled",
"Replace"
] | [
"Metaspace"
] | [
"Metaspace"
] | 879 | knowledgator/comprehend_it-multilingual-t5-base | knowledgator | null | 112 | 121,687 | False | 2024-01-26T09:44:09Z | 2024-01-27T12:08:55Z | transformers | 27 | 0 | null | zero-shot-classification | null | [
".gitattributes",
"README.md",
"config.json",
"pytorch_model.bin",
"special_tokens_map.json",
"spiece.model",
"tokenizer.json",
"tokenizer_config.json"
] | ab4e15c580be68ceaca226366a37ee1e5117d15f | [
"transformers",
"pytorch",
"T5",
"classification",
"information-extraction",
"zero-shot",
"zero-shot-classification",
"multilingual",
"af",
"am",
"ar",
"az",
"be",
"bg",
"bn",
"ca",
"ceb",
"co",
"cs",
"cy",
"da",
"de",
"el",
"en",
"eo",
"es",
"et",
"eu",
"fa",... | null | {"architectures": ["T5ForZeroShotClassification"], "model_type": "T5", "tokenizer_config": {"eos_token": "</s>", "pad_token": "<pad>", "unk_token": "<unk>"}} | {
"auto_model": "T5ForZeroShotClassification",
"custom_class": null,
"pipeline_tag": null,
"processor": null
} | {"base_model": null, "datasets": ["multi_nli", "xnli", "dbpedia_14", "SetFit/bbc-news", "squad_v2", "race", "knowledgator/events_classification_biotech", "facebook/anli", "SetFit/qnli"], "eval_results": null, "language": ["multilingual", "af", "am", "ar", "az", "be", "bg", "bn", "ca", "ceb", "co", "cs", "cy", "da", "de... | **comprehend-it-multilang-base**
This is an encoder-decoder model based on [mT5-base](https://huggingface.co/google/mt5-base) that was trained on multi-language natural language inference datasets as well as on multiple text classification datasets.
The model demonstrates a better contextual understanding of text an... | null | [
"apache-2.0"
] | [
"multi_nli",
"xnli",
"dbpedia_14",
"SetFit/bbc-news",
"squad_v2",
"race",
"knowledgator/events_classification_biotech",
"facebook/anli",
"SetFit/qnli"
] | [
"multilingual",
"af",
"am",
"ar",
"az",
"be",
"bg",
"bn",
"ca",
"ceb",
"co",
"cs",
"cy",
"da",
"de",
"el",
"en",
"eo",
"es",
"et",
"eu",
"fa",
"fi",
"fil",
"fr",
"fy",
"ga",
"gd",
"gl",
"gu",
"ha",
"haw",
"hi",
"hmn",
"ht",
"hu",
"hy",
"ig",
... | null | null | [
"accuracy",
"f1"
] | [
"T5",
"T5ForZeroShotClassification"
] | [
null,
"zero-shot-classification"
] | [
"text"
] | [
"text"
] | [
"logits"
] |
6418057ec40218f71dc99283 | 7ca70421579da9a5 | 70bd27c212bc339c | 50,265 | BPE | 50,000 | false | true | true | true | 5 | null | ByteLevel | ByteLevel | null | [
"ByteLevel"
] | [
"ByteLevel"
] | 504 | reyhanemyr/IRyS-NER-Recruitment | reyhanemyr | null | 31 | 120,970 | False | 2023-03-20T07:04:30Z | 2023-05-09T21:20:29Z | transformers | 2 | 0 | [{"name": "roberta-base-finetuned-cvbest3", "results": []}] | token-classification | null | [
".gitattributes",
".gitignore",
"README.md",
"config.json",
"merges.txt",
"pytorch_model.bin",
"runs/Mar20_07-04-21_a1f591fd3a59/1679295875.6069958/events.out.tfevents.1679295875.a1f591fd3a59.131.1",
"runs/Mar20_07-04-21_a1f591fd3a59/events.out.tfevents.1679295875.a1f591fd3a59.131.0",
"runs/Mar20_07... | 82a7ad4a668e8fe808abe9f03354a7fab54acefb | [
"transformers",
"pytorch",
"tensorboard",
"roberta",
"token-classification",
"generated_from_trainer",
"license:mit",
"endpoints_compatible",
"region:us"
] | null | {"architectures": ["RobertaForTokenClassification"], "model_type": "roberta", "tokenizer_config": {"bos_token": "<s>", "cls_token": "<s>", "eos_token": "</s>", "mask_token": "<mask>", "pad_token": "<pad>", "sep_token": "</s>", "unk_token": "<unk>"}} | {
"auto_model": "AutoModelForTokenClassification",
"custom_class": null,
"pipeline_tag": "token-classification",
"processor": "AutoTokenizer"
} | {"base_model": null, "datasets": null, "eval_results": [], "language": null, "library_name": null, "license": "mit", "license_name": null, "license_link": null, "metrics": ["precision", "recall", "f1", "accuracy"], "model_name": "roberta-base-finetuned-cvbest3", "pipeline_tag": null, "tags": ["generated_from_trainer"]} | <!-- This model card has been generated automatically according to the information the Trainer had access to. You
should probably proofread and complete it, then remove this comment. -->
# IRyS-NER-Recruitment
This model is a fine-tuned version of [roberta-base](https://huggingface.co/roberta-base) on a resume datase... | null | [
"mit"
] | null | null | null | null | [
"precision",
"recall",
"f1",
"accuracy"
] | [
"roberta",
"AutoModelForTokenClassification",
"RobertaForTokenClassification"
] | [
"token-classification"
] | [
"text"
] | [
"text"
] | [
"logits"
] |
68546d515b3e1b0a94166b13 | 8710581e64d62f9f | e6ffdc5dd5f1fd86 | 256,000 | BPE | 580,604 | true | true | true | true | 249 | Replace | Split | Sequence | [
"Replace"
] | [
"Split"
] | [
"Replace",
"ByteFallback",
"Fuse"
] | 66 | google/t5gemma-9b-9b-ul2 | google | {
"models": [
{
"_id": "68546d515b3e1b0a94166b13",
"id": "google/t5gemma-9b-9b-ul2"
}
],
"relation": "finetune"
} | 22,157 | 184,256 | manual | 2025-06-19T20:04:33Z | 2025-07-09T14:25:45Z | transformers | 7 | 2 | null | text-generation | {"parameters": {"BF16": 20333401088}, "total": 20333401088} | [
".gitattributes",
"README.md",
"config.json",
"generation_config.json",
"model-00001-of-00009.safetensors",
"model-00002-of-00009.safetensors",
"model-00003-of-00009.safetensors",
"model-00004-of-00009.safetensors",
"model-00005-of-00009.safetensors",
"model-00006-of-00009.safetensors",
"model-0... | 7071a2ace9c8353e12e723e5382cc7256ee41d9f | [
"transformers",
"safetensors",
"t5gemma",
"text2text-generation",
"arxiv:2504.06225",
"arxiv:2009.03300",
"arxiv:1905.07830",
"arxiv:1911.11641",
"arxiv:1905.10044",
"arxiv:1907.10641",
"arxiv:1911.01547",
"arxiv:1705.03551",
"arxiv:2107.03374",
"arxiv:2108.07732",
"arxiv:2110.14168",
... | null | {"architectures": ["T5GemmaForConditionalGeneration"], "model_type": "t5gemma", "tokenizer_config": {"bos_token": "<bos>", "eos_token": "<eos>", "pad_token": "<pad>", "unk_token": "<unk>", "use_default_system_prompt": false}} | {
"auto_model": "AutoModelForSeq2SeqLM",
"custom_class": null,
"pipeline_tag": "text2text-generation",
"processor": "AutoTokenizer"
} | {"base_model": "google/t5gemma-9b-9b-ul2", "datasets": null, "eval_results": null, "language": null, "library_name": "transformers", "license": "gemma", "license_name": null, "license_link": null, "metrics": null, "model_name": null, "pipeline_tag": "text2text-generation", "tags": null, "extra_gated_heading": "Access G... | null | null | [
"gemma"
] | null | null | 20,333,401,088 | null | null | [
"t5gemma",
"AutoModelForSeq2SeqLM",
"T5GemmaForConditionalGeneration"
] | [
"text2text-generation",
"text-generation"
] | [
"text"
] | [
"text"
] | [
"text"
] |
665435b4f72c9a37ce1405ca | bfe694f64f4a18f5 | daab2a732bab72e2 | 128,001 | Unigram | null | true | true | true | true | 5 | Sequence | Sequence | Metaspace | [
"Strip",
"Precompiled",
"Replace"
] | [
"Metaspace"
] | [
"Metaspace"
] | 22 | squeeze-ai-lab/TinyAgent-ToolRAG | squeeze-ai-lab | null | 993 | 136,056 | False | 2024-05-27T07:26:44Z | 2024-05-30T05:47:12Z | transformers | 18 | 0 | [{"name": "TinyAgent-ToolRAG", "results": []}] | text-classification | {"parameters": {"F32": 141907216}, "total": 141907216} | [
".gitattributes",
"README.md",
"added_tokens.json",
"config.json",
"model.safetensors",
"special_tokens_map.json",
"spm.model",
"tokenizer.json",
"tokenizer_config.json"
] | 64338ba0f439b2f89452485729179fa5bb948056 | [
"transformers",
"safetensors",
"deberta-v2",
"text-classification",
"function calling",
"on-device language model",
"en",
"text-embeddings-inference",
"deploy:azure",
"region:us"
] | null | {"architectures": ["DebertaV2ForSequenceClassification"], "model_type": "deberta-v2", "tokenizer_config": {"bos_token": "[CLS]", "cls_token": "[CLS]", "eos_token": "[SEP]", "mask_token": "[MASK]", "pad_token": "[PAD]", "sep_token": "[SEP]", "unk_token": "[UNK]"}} | {
"auto_model": "AutoModelForSequenceClassification",
"custom_class": null,
"pipeline_tag": "text-classification",
"processor": "AutoTokenizer"
} | {"base_model": null, "datasets": null, "eval_results": [], "language": ["en"], "library_name": "transformers", "license": null, "license_name": null, "license_link": null, "metrics": null, "model_name": "TinyAgent-ToolRAG", "pipeline_tag": null, "tags": ["function calling", "on-device language model"], "inference": fal... | # TinyAgent: Function Calling at the Edge
<p align="center">
<a href="https://github.com/SqueezeAILab/TinyAgent/raw/main/TinyAgent.zip">Get the desktop app</a>
|
<a href="https://bair.berkeley.edu/blog/2024/05/29/tiny-agent/">Read the blog post</a>
</p>
", "config": "en", "split": "test", "revision": "e8379541af4e31359cca9fbcf4b00f2671dba205"}, "metrics": [{"type": "accuracy", "value": 80.47761... | text-generation | {"parameters": {"BF16": 46702792704}, "total": 46702792704} | [
".gitattributes",
"README.md",
"config.json",
"dataset_num_samples.json",
"generation_config.json",
"model-00001-of-00019.safetensors",
"model-00002-of-00019.safetensors",
"model-00003-of-00019.safetensors",
"model-00004-of-00019.safetensors",
"model-00005-of-00019.safetensors",
"model-00006-of-... | a7168fbc12ee4c106653b68f5a740490549caeab | [
"transformers",
"pytorch",
"safetensors",
"mixtral",
"text-generation",
"mteb",
"conversational",
"custom_code",
"dataset:GritLM/tulu2",
"arxiv:2402.09906",
"base_model:mistralai/Mixtral-8x7B-Instruct-v0.1",
"base_model:finetune:mistralai/Mixtral-8x7B-Instruct-v0.1",
"license:apache-2.0",
... | null | {"model_type": "mixtral", "architectures": ["MixtralForCausalLM"], "auto_map": {"AutoModel": "modeling_gritlm8x7b.MixtralModel", "AutoModelForCausalLM": "modeling_gritlm8x7b.MixtralForCausalLM", "AutoModelForSequenceClassification": "modeling_gritlm8x7b.MixtralForSequenceClassification"}, "tokenizer_config": {"bos_toke... | {
"auto_model": "AutoModelForCausalLM",
"custom_class": null,
"pipeline_tag": "text-generation",
"processor": "AutoTokenizer"
} | {"base_model": ["mistralai/Mixtral-8x7B-Instruct-v0.1"], "datasets": ["GritLM/tulu2"], "license": "apache-2.0", "pipeline_tag": "text-generation", "tags": ["mteb"], "inference": true, "model-index": [{"name": "GritLM-8x7B", "results": [{"task": {"type": "Classification"}, "dataset": {"name": "MTEB AmazonCounterfactualC... | null | null | [
"apache-2.0"
] | [
"GritLM/tulu2"
] | null | 46,702,792,704 | null | null | [
"mixtral",
"MixtralForCausalLM",
"AutoModelForCausalLM"
] | [
"text-generation"
] | [
"text"
] | [
"text"
] | [
"text"
] |
65cffceaeabb6ab42922fbac | 53ecf467267e2824 | 535fa14da0af647c | 30,522 | WordPiece | null | true | true | true | true | 5 | BertNormalizer | BertPreTokenizer | WordPiece | [
"BertNormalizer"
] | [
"BertPreTokenizer"
] | [
"WordPiece"
] | 0 | tareknaous/readabert-en | tareknaous | null | 133 | 123,076 | False | 2024-02-17T00:25:14Z | 2024-07-17T16:59:06Z | transformers | 0 | 0 | null | text-classification | {"parameters": {"F32": 109486854}, "total": 109486854} | [
".gitattributes",
"README.md",
"config.json",
"model.safetensors",
"special_tokens_map.json",
"tokenizer.json",
"tokenizer_config.json",
"vocab.txt"
] | 4f4fcc3a2431f9ce45890912cb243e968485d174 | [
"transformers",
"safetensors",
"bert",
"text-classification",
"en",
"arxiv:2305.14463",
"license:apache-2.0",
"text-embeddings-inference",
"endpoints_compatible",
"region:us"
] | null | {"architectures": ["BertForSequenceClassification"], "model_type": "bert", "tokenizer_config": {"cls_token": "[CLS]", "mask_token": "[MASK]", "pad_token": "[PAD]", "sep_token": "[SEP]", "unk_token": "[UNK]"}} | {
"auto_model": "AutoModelForSequenceClassification",
"custom_class": null,
"pipeline_tag": "text-classification",
"processor": "AutoTokenizer"
} | {"base_model": null, "datasets": null, "eval_results": null, "language": ["en"], "library_name": null, "license": "apache-2.0", "license_name": null, "license_link": null, "metrics": null, "model_name": null, "pipeline_tag": null, "tags": null} | BERT-base model fine-tuned on the English portion of the ReadMe++ corpus for sentence-level readability prediction on a scale of 6-level CEFR scale
Github (Dataset and Python Package): https://github.com/tareknaous/readme
Paper: https://arxiv.org/abs/2305.14463 | null | [
"apache-2.0"
] | null | [
"en"
] | 109,486,854 | null | null | [
"BertForSequenceClassification",
"bert",
"AutoModelForSequenceClassification"
] | [
"text-classification"
] | [
"text"
] | [
"text"
] | [
"logits"
] |
6453478e3a794b2d9b22e03f | 58967ba68263f0aa | 2f8d5857ae5fa330 | 50,277 | BPE | 50,009 | true | true | true | true | 25 | NFC | ByteLevel | ByteLevel | [
"NFC"
] | [
"ByteLevel"
] | [
"ByteLevel"
] | 86 | togethercomputer/RedPajama-INCITE-7B-Base | togethercomputer | null | 1,093 | 125,502 | False | 2023-05-04T05:50:06Z | 2023-06-06T02:44:34Z | transformers | 91 | 0 | null | text-generation | null | [
".gitattributes",
"README.md",
"config.json",
"generation_config.json",
"pytorch_model-00001-of-00002.bin",
"pytorch_model-00002-of-00002.bin",
"pytorch_model.bin.index.json",
"special_tokens_map.json",
"tokenizer.json",
"tokenizer_config.json"
] | 78f7e482443971f4873ba3239f0ac810a367833b | [
"transformers",
"pytorch",
"gpt_neox",
"text-generation",
"en",
"dataset:togethercomputer/RedPajama-Data-1T",
"license:apache-2.0",
"text-generation-inference",
"endpoints_compatible",
"region:us"
] | null | {"architectures": ["GPTNeoXForCausalLM"], "model_type": "gpt_neox", "tokenizer_config": {"bos_token": "<|endoftext|>", "eos_token": "<|endoftext|>", "unk_token": "<|endoftext|>"}} | {
"auto_model": "AutoModelForCausalLM",
"custom_class": null,
"pipeline_tag": "text-generation",
"processor": "AutoTokenizer"
} | {"base_model": null, "datasets": ["togethercomputer/RedPajama-Data-1T"], "eval_results": null, "language": ["en"], "library_name": null, "license": "apache-2.0", "license_name": null, "license_link": null, "metrics": null, "model_name": null, "pipeline_tag": null, "tags": null} | # RedPajama-INCITE-7B-Base
RedPajama-INCITE-7B-Base was developed by Together and leaders from the open-source AI community including Ontocord.ai, ETH DS3Lab, AAI CERC, Université de Montréal, MILA - Québec AI Institute, Stanford Center for Research on Foundation Models (CRFM), Stanford Hazy Research research group an... | null | [
"apache-2.0"
] | [
"togethercomputer/RedPajama-Data-1T"
] | [
"en"
] | null | null | null | [
"gpt_neox",
"AutoModelForCausalLM",
"GPTNeoXForCausalLM"
] | [
"text-generation"
] | [
"text"
] | [
"text"
] | [
"text"
] |
646bfa995d68f5c15a364168 | 8fa325f0a5b8548c | 8bd7d71767538b82 | 32,000 | BPE | 61,249 | true | false | true | true | 3 | Sequence | null | Sequence | [
"Prepend",
"Replace"
] | null | [
"Replace",
"ByteFallback",
"Fuse",
"Strip"
] | 880 | timdettmers/guanaco-33b-merged | timdettmers | null | 1,584 | 129,391 | False | 2023-05-22T23:28:25Z | 2023-05-24T10:33:47Z | transformers | 160 | 0 | null | text-generation | null | [
".gitattributes",
"config.json",
"generation_config.json",
"pytorch_model-00001-of-00007.bin",
"pytorch_model-00002-of-00007.bin",
"pytorch_model-00003-of-00007.bin",
"pytorch_model-00004-of-00007.bin",
"pytorch_model-00005-of-00007.bin",
"pytorch_model-00006-of-00007.bin",
"pytorch_model-00007-of... | b2e78a916582935b6616d184b22ea5e9e1eb4c34 | [
"transformers",
"pytorch",
"llama",
"text-generation",
"text-generation-inference",
"endpoints_compatible",
"region:us"
] | null | {"architectures": ["LlamaForCausalLM"], "model_type": "llama", "tokenizer_config": {"bos_token": {"__type": "AddedToken", "content": "", "lstrip": false, "normalized": true, "rstrip": false, "single_word": false}, "eos_token": {"__type": "AddedToken", "content": "", "lstrip": false, "normalized": true, "rstrip": false,... | {
"auto_model": "AutoModelForCausalLM",
"custom_class": null,
"pipeline_tag": "text-generation",
"processor": "AutoTokenizer"
} | null | null | null | null | null | null | null | null | null | [
"AutoModelForCausalLM",
"llama",
"LlamaForCausalLM"
] | [
"text-generation"
] | [
"text"
] | [
"text"
] | [
"text"
] |
656b6691ede71189ad0d155b | ea0d23b75fcf1975 | 70bd27c212bc339c | 50,265 | BPE | 50,000 | false | true | true | true | 5 | null | ByteLevel | ByteLevel | null | [
"ByteLevel"
] | [
"ByteLevel"
] | 371 | starmage520/Coderbert_finetuned_detect_vulnerability_on_MSR | starmage520 | null | 10 | 120,465 | False | 2023-12-02T17:17:05Z | 2023-12-05T03:08:57Z | transformers | 3 | 0 | null | text-classification | {"parameters": {"F32": 124647170}, "total": 124647170} | [
".gitattributes",
"README.md",
"config.json",
"flax_model.msgpack",
"merges.txt",
"model.safetensors",
"msr.csv",
"pytorch_model.bin",
"special_tokens_map.json",
"tokenizer.json",
"tokenizer_config.json",
"vocab.json"
] | f7a3905675586727bbeb2cb304cda682c7c82d3d | [
"transformers",
"pytorch",
"jax",
"safetensors",
"roberta",
"text-classification",
"Text Classification",
"Transformers",
"PyTorch",
"JAX",
"MSR",
"English",
"Inference Endpoints",
"license:mit",
"text-embeddings-inference",
"endpoints_compatible",
"region:us"
] | null | {"architectures": ["RobertaForSequenceClassification"], "model_type": "roberta", "tokenizer_config": {"bos_token": "<s>", "cls_token": "<s>", "eos_token": "</s>", "mask_token": "<mask>", "pad_token": "<pad>", "sep_token": "</s>", "unk_token": "<unk>"}} | {
"auto_model": "AutoModelForSequenceClassification",
"custom_class": null,
"pipeline_tag": "text-classification",
"processor": "AutoTokenizer"
} | {"base_model": null, "datasets": null, "eval_results": null, "language": null, "library_name": null, "license": "mit", "license_name": null, "license_link": null, "metrics": ["accuracy"], "model_name": null, "pipeline_tag": "text-classification", "tags": ["Text Classification", "Transformers", "PyTorch", "JAX", "MSR", ... | I finetuned a RobertaForSequenceClassification model which is initialized
from CodeBert [https://huggingface.co/microsoft/codebert-base] to judge whether a code is vulnerable or not.
I selected balanced samples from MSR dataset [https://github.com/ZeoVan/MSR_20_Code_vulnerability_CSV_Dataset] for training, validation,... | null | [
"mit"
] | null | null | 124,647,170 | null | [
"accuracy"
] | [
"roberta",
"AutoModelForSequenceClassification",
"RobertaForSequenceClassification"
] | [
"text-classification"
] | [
"text"
] | [
"text"
] | [
"logits"
] |
64bfb86b5b6437ad06c630c9 | 8a9cfd8584cddb34 | ea059d203298896f | 46,336 | BPE | 77,738 | true | false | true | true | 14,450 | Sequence | null | Sequence | [
"Prepend",
"Replace"
] | null | [
"Replace",
"ByteFallback",
"Fuse",
"Strip"
] | 881 | kfkas/Llama-2-ko-7b-Chat | kfkas | null | 889 | 125,965 | False | 2023-07-25T11:56:27Z | 2023-09-20T08:21:34Z | transformers | 70 | 0 | null | text-generation | null | [
".gitattributes",
"LICENSE",
"README.md",
"config.json",
"generation_config.json",
"pytorch_model-00001-of-00002.bin",
"pytorch_model-00002-of-00002.bin",
"pytorch_model.bin.index.json",
"special_tokens_map.json",
"tokenizer.json",
"tokenizer_config.json"
] | 6d94c8e5b34fb09e80601548761a8dbd54bc0bba | [
"transformers",
"pytorch",
"llama",
"text-generation",
"facebook",
"meta",
"llama-2",
"kollama",
"llama-2-ko",
"llama-2-ko-chat",
"en",
"ko",
"arxiv:2307.09288",
"text-generation-inference",
"deploy:azure",
"region:us"
] | null | {"architectures": ["LlamaForCausalLM"], "model_type": "llama", "tokenizer_config": {"bos_token": {"__type": "AddedToken", "content": "<s>", "lstrip": false, "normalized": false, "rstrip": false, "single_word": false}, "eos_token": {"__type": "AddedToken", "content": "</s>", "lstrip": false, "normalized": false, "rstrip... | {
"auto_model": "AutoModelForCausalLM",
"custom_class": null,
"pipeline_tag": "text-generation",
"processor": "AutoTokenizer"
} | {"base_model": null, "datasets": null, "eval_results": null, "language": ["en", "ko"], "library_name": null, "license": null, "license_name": null, "license_link": null, "metrics": null, "model_name": null, "pipeline_tag": "text-generation", "tags": ["facebook", "meta", "pytorch", "llama", "llama-2", "kollama", "llama-... | # **Llama-2-Ko-Chat** 🦙🇰🇷
<img src=https://github.com/boostcampaitech5/level2_klue-nlp-08/assets/96530685/9dc3a02a-f554-42c7-9aa7-e7bd8c8870b7 style="max-width: 700px; width: 100%" />
Llama-2-Ko-7b-Chat은 [beomi/llama-2-ko-7b 40B](https://huggingface.co/beomi/llama-2-ko-7b)를 토대로 만들어졌습니다. 학습 데이터는 [nlpai-lab/kullm-v2]... | null | null | null | [
"en",
"ko"
] | null | null | null | [
"AutoModelForCausalLM",
"llama",
"LlamaForCausalLM"
] | [
"text-generation"
] | [
"text"
] | [
"text"
] | [
"text"
] |
6336a8391ba5d5ece2418704 | 5ef9eb7677e33416 | 70bd27c212bc339c | 50,265 | BPE | 50,000 | false | true | true | true | 5 | null | ByteLevel | ByteLevel | null | [
"ByteLevel"
] | [
"ByteLevel"
] | 19 | cardiffnlp/roberta-large-tweet-topic-single-all | cardiffnlp | null | 9 | 120,403 | False | 2022-09-30T08:26:33Z | 2022-09-30T18:03:25Z | transformers | 0 | 0 | [{"name": "cardiffnlp/roberta-large-tweet-topic-single-all", "results": [{"task": {"type": "text-classification", "name": "Text Classification"}, "dataset": {"name": "cardiffnlp/tweet_topic_single", "type": "cardiffnlp/tweet_topic_single", "args": "cardiffnlp/tweet_topic_single", "split": "test_2021"}, "metrics": [{"na... | text-classification | null | [
".gitattributes",
"README.md",
"config.json",
"merges.txt",
"metric_summary.json",
"pytorch_model.bin",
"special_tokens_map.json",
"tokenizer.json",
"tokenizer_config.json",
"vocab.json"
] | b9286fabc508a553a4dad6cec8035044deff034a | [
"transformers",
"pytorch",
"roberta",
"text-classification",
"dataset:cardiffnlp/tweet_topic_single",
"model-index",
"text-embeddings-inference",
"endpoints_compatible",
"deploy:azure",
"region:us"
] | null | {"architectures": ["RobertaForSequenceClassification"], "model_type": "roberta", "tokenizer_config": {"unk_token": "<unk>", "bos_token": "<s>", "eos_token": "</s>", "sep_token": "</s>", "cls_token": "<s>", "pad_token": "<pad>", "mask_token": "<mask>"}} | {
"auto_model": "AutoModelForSequenceClassification",
"custom_class": null,
"pipeline_tag": "text-classification",
"processor": "AutoTokenizer"
} | {"datasets": ["cardiffnlp/tweet_topic_single"], "metrics": ["f1", "accuracy"], "pipeline_tag": "text-classification", "widget": [{"text": "I'm sure the {@Tampa Bay Lightning@} would\u2019ve rather faced the Flyers but man does their experience versus the Blue Jackets this year and last help them a lot versus this Islan... | # cardiffnlp/roberta-large-tweet-topic-single-all
This model is a fine-tuned version of [roberta-large](https://huggingface.co/roberta-large) on the [tweet_topic_single](https://huggingface.co/datasets/cardiffnlp/tweet_topic_single). This model is fine-tuned on `train_all` split and validated on `test_2021` split of t... | null | null | [
"cardiffnlp/tweet_topic_single"
] | null | null | null | [
"f1",
"accuracy"
] | [
"roberta",
"AutoModelForSequenceClassification",
"RobertaForSequenceClassification"
] | [
"text-classification"
] | [
"text"
] | [
"text"
] | [
"logits"
] |
621ffdc136468d709f17cbcf | bc12a8d6a9749cb9 | 8eba6449bcfd5626 | 32,000 | WordPiece | null | true | true | true | true | 5 | BertNormalizer | BertPreTokenizer | WordPiece | [
"BertNormalizer"
] | [
"BertPreTokenizer"
] | [
"WordPiece"
] | 258 | jhgan/ko-sbert-multitask | jhgan | null | 11,457 | 185,798 | False | 2022-03-02T23:29:05Z | 2022-08-16T12:45:51Z | sentence-transformers | 23 | 0 | null | sentence-similarity | null | [
".gitattributes",
"1_Pooling/config.json",
"README.md",
"config.json",
"config_sentence_transformers.json",
"eval/similarity_evaluation_sts-dev_results.csv",
"modules.json",
"pytorch_model.bin",
"sentence_bert_config.json",
"similarity_evaluation_sts-test_results.csv",
"special_tokens_map.json",... | 0087471b677c6388c12a152822ca60441be4072b | [
"sentence-transformers",
"pytorch",
"tf",
"bert",
"feature-extraction",
"sentence-similarity",
"transformers",
"arxiv:2004.03289",
"text-embeddings-inference",
"endpoints_compatible",
"deploy:azure",
"region:us"
] | null | {"architectures": ["BertModel"], "model_type": "bert", "tokenizer_config": {"unk_token": "[UNK]", "sep_token": "[SEP]", "pad_token": "[PAD]", "cls_token": "[CLS]", "mask_token": "[MASK]"}} | {
"auto_model": "AutoModel",
"custom_class": null,
"pipeline_tag": "feature-extraction",
"processor": "AutoTokenizer"
} | {"base_model": null, "datasets": null, "eval_results": null, "language": null, "library_name": null, "license": null, "license_name": null, "license_link": null, "metrics": null, "model_name": null, "pipeline_tag": "sentence-similarity", "tags": ["sentence-transformers", "feature-extraction", "sentence-similarity", "tr... | # ko-sbert-multitask
This is a [sentence-transformers](https://www.SBERT.net) model: It maps sentences & paragraphs to a 768 dimensional dense vector space and can be used for tasks like clustering or semantic search.
<!--- Describe your model here -->
## Usage (Sentence-Transformers)
Using this model becomes easy ... | null | null | null | null | null | null | null | [
"BertModel",
"AutoModel",
"bert"
] | [
"sentence-similarity",
"feature-extraction"
] | [
"text",
"multimodal"
] | [
"text"
] | [
"logits",
"embeddings"
] |
621ffdc136468d709f1800e3 | 153fc504851e5e18 | 8a01c02d4d0a401c | 119,547 | WordPiece | null | true | true | true | true | 5 | BertNormalizer | BertPreTokenizer | WordPiece | [
"BertNormalizer"
] | [
"BertPreTokenizer"
] | [
"WordPiece"
] | 882 | sangrimlee/bert-base-multilingual-cased-nsmc | sangrimlee | null | 517 | 123,601 | False | 2022-03-02T23:29:05Z | 2021-06-02T18:46:18Z | transformers | 8 | 0 | null | text-classification | null | [
".gitattributes",
"README.md",
"all_results.json",
"config.json",
"eval_results.json",
"predict_results.txt",
"pytorch_model.bin",
"special_tokens_map.json",
"tokenizer.json",
"tokenizer_config.json",
"train_results.json",
"trainer_state.json",
"training_args.bin",
"vocab.txt"
] | 47fdca16e29c52b9cffc78df8ff7bef7a657c4bb | [
"transformers",
"pytorch",
"bert",
"text-classification",
"ko",
"text-embeddings-inference",
"endpoints_compatible",
"region:us"
] | null | {"architectures": ["BertForSequenceClassification"], "model_type": "bert", "tokenizer_config": {"unk_token": "[UNK]", "sep_token": "[SEP]", "pad_token": "[PAD]", "cls_token": "[CLS]", "mask_token": "[MASK]"}} | {
"auto_model": "AutoModelForSequenceClassification",
"custom_class": null,
"pipeline_tag": "text-classification",
"processor": "AutoTokenizer"
} | {"base_model": null, "datasets": null, "eval_results": null, "language": "ko", "library_name": null, "license": null, "license_name": null, "license_link": null, "metrics": null, "model_name": null, "pipeline_tag": null, "tags": null} | # BERT multilingual basecased finetuned with NSMC
This model is a fine-tune checkpoint of [bert-base-multilingual-cased](https://huggingface.co/bert-base-multilingual-cased), fine-tuned on [NSMC(Naver Sentiment Movie Corpus)](https://github.com/e9t/nsmc).
## Usage
You can use this model directly with a pipeline for ... | null | null | null | [
"ko"
] | null | null | null | [
"BertForSequenceClassification",
"bert",
"AutoModelForSequenceClassification"
] | [
"text-classification"
] | [
"text"
] | [
"text"
] | [
"logits"
] |
66827844539faacb33c388c8 | 21e5d4118165e06a | ea89bf2850ea447b | 65,003 | BPE | 64,756 | true | true | true | true | 5 | NFC | Sequence | ByteLevel | [
"NFC"
] | [
"Digits",
"ByteLevel"
] | [
"ByteLevel"
] | 883 | cyberagent/calm3-22b-chat | cyberagent | null | 456 | 122,760 | False | 2024-07-01T09:35:00Z | 2024-07-01T10:11:08Z | transformers | 83 | 0 | null | text-generation | {"parameters": {"BF16": 22542882816}, "total": 22542882816} | [
".gitattributes",
"README.md",
"config.json",
"generation_config.json",
"model-00001-of-00010.safetensors",
"model-00002-of-00010.safetensors",
"model-00003-of-00010.safetensors",
"model-00004-of-00010.safetensors",
"model-00005-of-00010.safetensors",
"model-00006-of-00010.safetensors",
"model-0... | 055922aa0f0fb1fbfbc97a2e31134532485ee99b | [
"transformers",
"safetensors",
"llama",
"text-generation",
"japanese",
"causal-lm",
"conversational",
"ja",
"en",
"license:apache-2.0",
"text-generation-inference",
"deploy:azure",
"region:us"
] | null | {"architectures": ["LlamaForCausalLM"], "model_type": "llama", "tokenizer_config": {"bos_token": "<|endoftext|>", "chat_template": "{% if not add_generation_prompt is defined %}{% set add_generation_prompt = false %}{% endif %}{% for message in messages %}{{'<|im_start|>' + message['role'] + '\n' + message['content'] +... | {
"auto_model": "AutoModelForCausalLM",
"custom_class": null,
"pipeline_tag": "text-generation",
"processor": "AutoTokenizer"
} | {"base_model": null, "datasets": null, "eval_results": null, "language": ["ja", "en"], "library_name": null, "license": "apache-2.0", "license_name": null, "license_link": null, "metrics": null, "model_name": null, "pipeline_tag": null, "tags": ["japanese", "causal-lm"], "inference": false} | # CyberAgentLM3-22B-Chat (CALM3-22B-Chat)
## Model Description
CyberAgentLM3 is a decoder-only language model pre-trained on 2.0 trillion tokens from scratch.
CyberAgentLM3-Chat is a fine-tuned model specialized for dialogue use cases.
## Usage
```python
from transformers import AutoModelForCausalLM, AutoTokenize... | null | [
"apache-2.0"
] | null | [
"ja",
"en"
] | 22,542,882,816 | null | null | [
"AutoModelForCausalLM",
"llama",
"LlamaForCausalLM"
] | [
"text-generation"
] | [
"text"
] | [
"text"
] | [
"text"
] |
636197a66bd72c97d0037723 | c97a6495c5454551 | f26f356cd728caa8 | 49,408 | BPE | 48,894 | true | true | true | true | 2 | Sequence | Sequence | ByteLevel | [
"NFC",
"Replace",
"Lowercase"
] | [
"Split",
"ByteLevel"
] | [
"ByteLevel"
] | 2 | timm/vit_base_patch32_clip_224.openai | timm | null | 3,065 | 133,649 | False | 2022-11-01T22:03:18Z | 2025-01-21T21:59:19Z | timm | 0 | 0 | null | null | null | [
".gitattributes",
"README.md",
"config.json",
"merges.txt",
"open_clip_config.json",
"open_clip_model.safetensors",
"open_clip_pytorch_model.bin",
"pytorch_model.bin",
"special_tokens_map.json",
"tokenizer.json",
"tokenizer_config.json",
"vocab.json"
] | a6f597a30f7b82c51704746581f9a4e41421e878 | [
"timm",
"pytorch",
"open_clip",
"safetensors",
"vision",
"transformers",
"arxiv:2103.00020",
"arxiv:1908.04913",
"license:apache-2.0",
"region:us"
] | null | {"tokenizer_config": {"bos_token": "<|startoftext|>", "eos_token": "<|endoftext|>", "pad_token": "<|endoftext|>", "unk_token": "<|endoftext|>"}} | {
"auto_model": "AutoModel",
"custom_class": null,
"pipeline_tag": null,
"processor": null
} | {"base_model": null, "datasets": null, "eval_results": null, "language": null, "library_name": "timm", "license": "apache-2.0", "license_name": null, "license_link": null, "metrics": null, "model_name": null, "pipeline_tag": null, "tags": ["timm", "vision", "transformers"]} | # CLIP (OpenAI model for timm)
## Model Details
The CLIP model was developed by researchers at OpenAI to learn about what contributes to robustness in computer vision tasks. The model was also developed to test the ability of models to generalize to arbitrary image classification tasks in a zero-shot manner. It was no... | null | [
"apache-2.0"
] | null | null | null | null | null | [
"AutoModel"
] | [
null
] | null | null | null |
6598346ca4e09f3675c4510c | 8a2ab6d0c7c90c45 | 94e8ac807f758b5c | 50,000 | BPE | 46,638 | true | false | true | false | 2 | Sequence | null | null | [
"StripAccents",
"Replace",
"Replace",
"Replace",
"Replace"
] | null | null | 884 | claudios/VulBERTa-MLP-Devign | claudios | null | 44 | 121,815 | False | 2024-01-05T16:55:08Z | 2024-05-22T03:31:13Z | transformers | 5 | 0 | [{"name": "VulBERTa MLP", "results": [{"task": {"type": "defect-detection"}, "dataset": {"name": "codexglue-devign", "type": "codexglue-devign"}, "metrics": [{"name": "Accuracy", "type": "Accuracy", "value": 64.71, "verified": false}, {"name": "Precision", "type": "Precision", "value": 64.8, "verified": false}, {"name"... | text-classification | {"parameters": {"F32": 124836866}, "total": 124836866} | [
".gitattributes",
"README.md",
"config.json",
"model.safetensors",
"special_tokens_map.json",
"tokenization_vulberta.py",
"tokenizer.json",
"tokenizer_config.json"
] | fecabdee24a3ef6e804d7629d6eed03dc6b4f61e | [
"transformers",
"safetensors",
"roberta",
"text-classification",
"devign",
"defect detection",
"code",
"dataset:code_x_glue_cc_defect_detection",
"license:mit",
"model-index",
"text-embeddings-inference",
"endpoints_compatible",
"region:us"
] | null | {"architectures": ["RobertaForSequenceClassification"], "model_type": "roberta", "tokenizer_config": {"pad_token": "<pad>"}} | {
"auto_model": "AutoModelForSequenceClassification",
"custom_class": null,
"pipeline_tag": "text-classification",
"processor": "AutoTokenizer"
} | {"datasets": ["code_x_glue_cc_defect_detection"], "license": "mit", "metrics": ["accuracy", "precision", "recall", "f1", "roc_auc"], "pipeline_tag": "text-classification", "tags": ["devign", "defect detection", "code"], "arxiv": 2205.12424, "model-index": [{"name": "VulBERTa MLP", "results": [{"task": {"type": "defect-... | # VulBERTa MLP Devign
## VulBERTa: Simplified Source Code Pre-Training for Vulnerability Detection
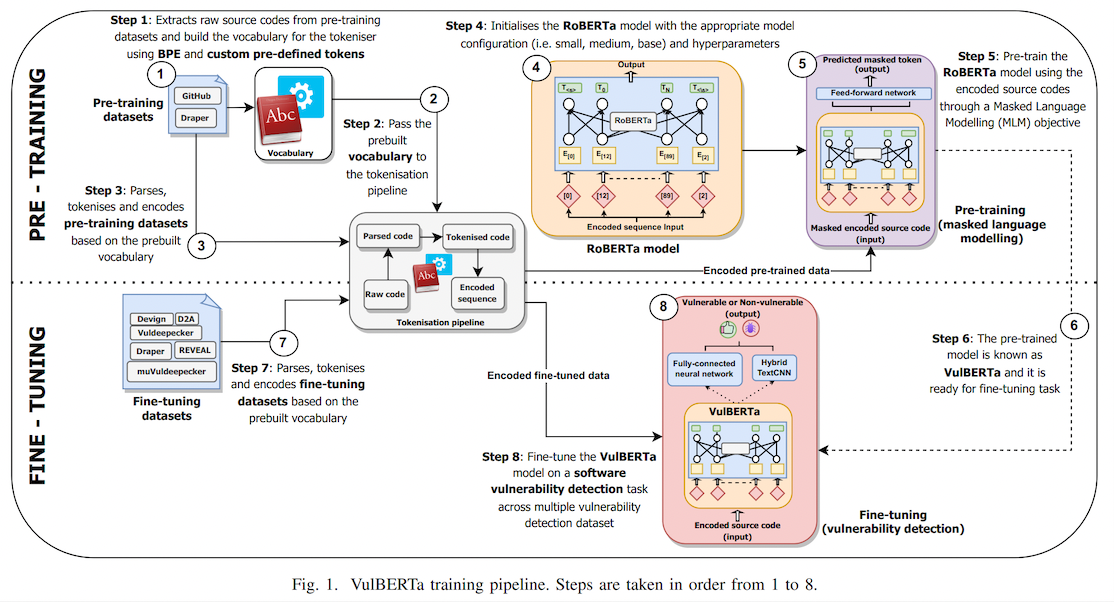
## Overview
This model is the unofficial HuggingFace version of "[VulBERTa](https://github.com/ICL-ml4csec/VulBERTa/tree/main)... | null | [
"mit"
] | [
"code_x_glue_cc_defect_detection"
] | null | 124,836,866 | null | [
"accuracy",
"precision",
"recall",
"f1",
"roc_auc"
] | [
"roberta",
"AutoModelForSequenceClassification",
"RobertaForSequenceClassification"
] | [
"text-classification"
] | [
"text"
] | [
"text"
] | [
"logits"
] |
661ffcff40d4df94bf7d3ee3 | c1b718d8c9016487 | c81b23e1dcb12302 | 50,280 | BPE | 50,009 | true | true | true | true | 28 | NFC | ByteLevel | ByteLevel | [
"NFC"
] | [
"ByteLevel"
] | [
"ByteLevel"
] | 295 | allenai/OLMo-7B-0424-hf | allenai | null | 2,639 | 128,001 | False | 2024-04-17T16:46:55Z | 2024-07-16T18:00:50Z | transformers | 14 | 0 | null | text-generation | {"parameters": {"F32": 6888095744}, "total": 6888095744} | [
".gitattributes",
"README.md",
"config.json",
"generation_config.json",
"model-00001-of-00006.safetensors",
"model-00002-of-00006.safetensors",
"model-00003-of-00006.safetensors",
"model-00004-of-00006.safetensors",
"model-00005-of-00006.safetensors",
"model-00006-of-00006.safetensors",
"model.s... | e3c82a0871580b424d74e68acee866bb007df7df | [
"transformers",
"safetensors",
"olmo",
"text-generation",
"en",
"dataset:allenai/dolma",
"arxiv:2402.00838",
"license:apache-2.0",
"endpoints_compatible",
"region:us"
] | null | {"architectures": ["OlmoForCausalLM"], "model_type": "olmo", "tokenizer_config": {"bos_token": null, "eos_token": "<|endoftext|>", "pad_token": "<|padding|>", "unk_token": null}} | {
"auto_model": "AutoModelForCausalLM",
"custom_class": null,
"pipeline_tag": "text-generation",
"processor": "AutoTokenizer"
} | {"base_model": null, "datasets": ["allenai/dolma"], "eval_results": null, "language": ["en"], "library_name": null, "license": "apache-2.0", "license_name": null, "license_link": null, "metrics": null, "model_name": null, "pipeline_tag": null, "tags": null} | <img src="https://allenai.org/olmo/olmo-7b-animation.gif" alt="OLMo Logo" width="800" style="margin-left:'auto' margin-right:'auto' display:'block'"/>
# Model Card for OLMo 7B April 2024
OLMo 7B April 2024 is an updated version of the original [OLMo 7B](https://huggingface.co/allenai/OLMo-7B) model rocking a 24 point... | null | [
"apache-2.0"
] | [
"allenai/dolma"
] | [
"en"
] | 6,888,095,744 | null | null | [
"AutoModelForCausalLM",
"OlmoForCausalLM",
"olmo"
] | [
"text-generation"
] | [
"text"
] | [
"text"
] | [
"text"
] |
64f583e4413ca787f12903ad | 1eee0b97f95ca02b | a8f500fcd9eb4f8e | 50,304 | BPE | 50,000 | false | true | true | true | 48 | null | ByteLevel | ByteLevel | null | [
"ByteLevel"
] | [
"ByteLevel"
] | 876 | 42dot/42dot_LLM-SFT-1.3B | 42dot | null | 885 | 124,829 | False | 2023-09-04T07:14:44Z | 2024-02-13T05:58:23Z | transformers | 36 | 0 | null | text-generation | {"parameters": {"F32": 1439270912}, "total": 1439270912} | [
".gitattributes",
"README.md",
"added_tokens.json",
"asset/42dot_LLM_vs_score.png",
"asset/42dot_llm_ko_score_white_background.png",
"config.json",
"generation_config.json",
"merges.txt",
"model.safetensors",
"pytorch_model.bin",
"special_tokens_map.json",
"tokenizer.json",
"tokenizer_config... | 6ad0fe677ddf727162428b62d166729afa633196 | [
"transformers",
"pytorch",
"safetensors",
"llama",
"text-generation",
"causal-lm",
"42dot_llm",
"en",
"ko",
"license:cc-by-nc-4.0",
"text-generation-inference",
"endpoints_compatible",
"deploy:azure",
"region:us"
] | null | {"architectures": ["LlamaForCausalLM"], "model_type": "llama", "tokenizer_config": {"bos_token": {"__type": "AddedToken", "content": "<||bos||>", "lstrip": false, "normalized": true, "rstrip": false, "single_word": false}, "eos_token": {"__type": "AddedToken", "content": "<|endoftext|>", "lstrip": false, "normalized": ... | {
"auto_model": "AutoModelForCausalLM",
"custom_class": null,
"pipeline_tag": "text-generation",
"processor": "AutoTokenizer"
} | {"base_model": null, "datasets": null, "eval_results": null, "language": ["en", "ko"], "library_name": null, "license": "cc-by-nc-4.0", "license_name": null, "license_link": null, "metrics": null, "model_name": null, "pipeline_tag": "text-generation", "tags": ["pytorch", "llama", "causal-lm", "42dot_llm"]} | # 42dot_LLM-SFT-1.3B
**42dot LLM-SFT** is a large language model (LLM) developed by [**42dot**](https://42dot.ai/) which is trained to follow natural language instructions.
42dot LLM-SFT is a part of **42dot LLM**, and derived from **42dot LLM-PLM** by supervised fine-tuning (SFT). This repository contains a 1.3B-para... | null | [
"cc-by-nc-4.0"
] | null | [
"en",
"ko"
] | 1,439,270,912 | null | null | [
"AutoModelForCausalLM",
"llama",
"LlamaForCausalLM"
] | [
"text-generation"
] | [
"text"
] | [
"text"
] | [
"text"
] |
6751d49671416d41d9feb1e4 | 344b7c49c2732e43 | 8386a692be535934 | 51,866 | BPE | 50,000 | false | true | true | true | 1,609 | null | ByteLevel | ByteLevel | null | [
"ByteLevel"
] | [
"ByteLevel"
] | 21 | distil-whisper/distil-large-v3.5 | distil-whisper | null | 46,083 | 209,389 | False | 2024-12-05T16:28:06Z | 2025-03-25T07:56:24Z | transformers | 87 | 1 | null | automatic-speech-recognition | null | [
".gitattributes",
".gitignore",
"README.md",
"added_tokens.json",
"config.json",
"generation_config.json",
"hf-whisper-distil-multi-v0.2/events.out.tfevents.1732842515.jzxh112.1688663.0",
"hf-whisper-distil-multi-v0.2/events.out.tfevents.1732907831.jzxh108.2302919.0",
"hf-whisper-distil-multi-v0.2/e... | 92cc789b758f9408cd7b94ef0e6e84a6746aaa00 | [
"transformers",
"tensorboard",
"safetensors",
"whisper",
"automatic-speech-recognition",
"audio",
"en",
"arxiv:2311.00430",
"arxiv:2106.05237",
"arxiv:1904.08779",
"arxiv:1910.13267",
"license:mit",
"endpoints_compatible",
"region:us"
] | null | {"architectures": ["WhisperForConditionalGeneration"], "model_type": "whisper", "tokenizer_config": {"bos_token": "<|endoftext|>", "eos_token": "<|endoftext|>", "pad_token": "<|endoftext|>", "unk_token": "<|endoftext|>"}} | {
"auto_model": "AutoModelForSpeechSeq2Seq",
"custom_class": null,
"pipeline_tag": "automatic-speech-recognition",
"processor": "AutoProcessor"
} | {"base_model": null, "datasets": null, "eval_results": null, "language": ["en"], "library_name": "transformers", "license": "mit", "license_name": null, "license_link": null, "metrics": null, "model_name": null, "pipeline_tag": "automatic-speech-recognition", "tags": ["audio", "automatic-speech-recognition"], "widget":... | # Distil-Whisper: Distil-Large-v3.5
Distil-Whisper is the knowledge-distilled version of OpenAI's [Whisper-Large-v3](https://huggingface.co/openai/whisper-large-v3), described in the paper [Robust Knowledge Distillation via Large-Scale Pseudo Labelling](https://arxiv.org/abs/2311.00430). As the newest addition to the ... | null | [
"mit"
] | null | [
"en"
] | null | null | null | [
"WhisperForConditionalGeneration",
"whisper",
"AutoModelForSpeechSeq2Seq"
] | [
"automatic-speech-recognition"
] | [
"multimodal"
] | [
"audio"
] | [
"text"
] |
6461819d232a700f265e3b0c | 77db401df02deabc | ffae8233e53a99e4 | 256,204 | BPE | 514,098 | true | true | true | true | 207 | Sequence | Metaspace | Metaspace | [
"Precompiled",
"Replace"
] | [
"Metaspace"
] | [
"Metaspace"
] | 885 | NHNDQ/nllb-finetuned-en2ko | NHNDQ | null | 444 | 122,886 | False | 2023-05-15T00:49:33Z | 2023-07-26T06:28:11Z | transformers | 25 | 0 | null | translation | null | [
".gitattributes",
"README.md",
"config.json",
"generation_config.json",
"pytorch_model.bin",
"sentencepiece.bpe.model",
"special_tokens_map.json",
"tokenizer.json",
"tokenizer_config.json"
] | 27078d9df1c66897e8ba8d8a00176b8a8c1a3fa1 | [
"transformers",
"pytorch",
"m2m_100",
"text2text-generation",
"translation",
"en",
"ko",
"license:cc-by-4.0",
"endpoints_compatible",
"deploy:azure",
"region:us"
] | null | {"architectures": ["M2M100ForConditionalGeneration"], "model_type": "m2m_100", "tokenizer_config": {"bos_token": "<s>", "cls_token": "<s>", "eos_token": "</s>", "mask_token": {"__type": "AddedToken", "content": "<mask>", "lstrip": true, "normalized": true, "rstrip": false, "single_word": false}, "pad_token": "<pad>", "... | {
"auto_model": "AutoModelForSeq2SeqLM",
"custom_class": null,
"pipeline_tag": "text2text-generation",
"processor": "AutoTokenizer"
} | {"base_model": null, "datasets": null, "eval_results": null, "language": ["en", "ko"], "library_name": null, "license": "cc-by-4.0", "license_name": null, "license_link": null, "metrics": null, "model_name": null, "pipeline_tag": null, "tags": ["translation"]} | ## Model Details
* Model Description: Fine-tuned facebook/nllb-200-distilled-600M model
* Developed by: Jisu Kim, Juhwan Lee, TakSung Heo, and Minsu Jeong
* Model Type: Translation
* Language(s):
* Source Language: English
* Target Language: Korean
* License: CC-BY-4.0
## Dataset
* [AI-hub dataset](https://www.aih... | null | [
"cc-by-4.0"
] | null | [
"en",
"ko"
] | null | null | null | [
"AutoModelForSeq2SeqLM",
"m2m_100",
"M2M100ForConditionalGeneration"
] | [
"text2text-generation",
"translation"
] | [
"text"
] | [
"text"
] | [
"text"
] |
636def2cda13cd91f925f27a | 901a6aa89c7cea5d | ef4806e2ade9022f | 32,100 | Unigram | null | true | true | true | true | 103 | Precompiled | Sequence | Metaspace | [
"Precompiled"
] | [
"WhitespaceSplit",
"Metaspace"
] | [
"Metaspace"
] | 886 | TestZee/t5-small-finetuned-pytorch-final | TestZee | null | 2,996 | 131,780 | False | 2022-11-11T06:43:56Z | 2022-11-11T09:02:18Z | transformers | 0 | 0 | [{"name": "t5-small-finetuned-pytorch-final", "results": []}] | null | null | [
".gitattributes",
".gitignore",
"README.md",
"config.json",
"pytorch_model.bin",
"runs/Nov11_06-43-43_ac5ebdcab381/1668149044.5219758/events.out.tfevents.1668149044.ac5ebdcab381.80.1",
"runs/Nov11_06-43-43_ac5ebdcab381/events.out.tfevents.1668149044.ac5ebdcab381.80.0",
"special_tokens_map.json",
"to... | c5f07e828c16d4752dbea822eaeb737655989979 | [
"transformers",
"pytorch",
"tensorboard",
"t5",
"text2text-generation",
"generated_from_trainer",
"license:apache-2.0",
"text-generation-inference",
"endpoints_compatible",
"region:us"
] | null | {"architectures": ["T5ForConditionalGeneration"], "model_type": "t5", "tokenizer_config": {"eos_token": "</s>", "unk_token": "<unk>", "pad_token": "<pad>"}} | {
"auto_model": "AutoModelForSeq2SeqLM",
"custom_class": null,
"pipeline_tag": "text2text-generation",
"processor": "AutoTokenizer"
} | {"base_model": null, "datasets": null, "eval_results": [], "language": null, "library_name": null, "license": "apache-2.0", "license_name": null, "license_link": null, "metrics": ["rouge"], "model_name": "t5-small-finetuned-pytorch-final", "pipeline_tag": null, "tags": ["generated_from_trainer"]} | <!-- This model card has been generated automatically according to the information the Trainer had access to. You
should probably proofread and complete it, then remove this comment. -->
# t5-small-finetuned-pytorch-final
This model is a fine-tuned version of [t5-small](https://huggingface.co/t5-small) on an unknown ... | null | [
"apache-2.0"
] | null | null | null | null | [
"rouge"
] | [
"t5",
"T5ForConditionalGeneration",
"AutoModelForSeq2SeqLM"
] | [
"text2text-generation"
] | null | null | null |
66e81d52c7484abafcb72300 | 848b60b6cd304b65 | ffc911e785abe60e | 151,665 | BPE | 151,387 | true | true | true | true | 22 | NFC | Sequence | ByteLevel | [
"NFC"
] | [
"Split",
"ByteLevel"
] | [
"ByteLevel"
] | 15 | Qwen/Qwen2.5-Math-72B-Instruct | Qwen | {
"models": [
{
"_id": "66e81d4dd683a3f4e5293f1b",
"id": "Qwen/Qwen2.5-Math-72B"
}
],
"relation": "finetune"
} | 605 | 128,719 | False | 2024-09-16T11:58:10Z | 2024-09-23T06:06:06Z | transformers | 31 | 0 | null | text-generation | {"parameters": {"BF16": 72706203648}, "total": 72706203648} | [
".gitattributes",
"LICENSE",
"README.md",
"config.json",
"generation_config.json",
"merges.txt",
"model-00001-of-00037.safetensors",
"model-00002-of-00037.safetensors",
"model-00003-of-00037.safetensors",
"model-00004-of-00037.safetensors",
"model-00005-of-00037.safetensors",
"model-00006-of-0... | 8fcf92b1eac8eca48c3d49778ad3dd1b394c9a17 | [
"transformers",
"safetensors",
"qwen2",
"text-generation",
"chat",
"conversational",
"en",
"arxiv:2409.12122",
"base_model:Qwen/Qwen2.5-Math-72B",
"base_model:finetune:Qwen/Qwen2.5-Math-72B",
"license:other",
"text-generation-inference",
"endpoints_compatible",
"deploy:azure",
"region:us... | null | {"architectures": ["Qwen2ForCausalLM"], "model_type": "qwen2", "tokenizer_config": {"bos_token": null, "chat_template": "{%- if tools %}\n {{- '<|im_start|>system\\n' }}\n {%- if messages[0]['role'] == 'system' %}\n {{- messages[0]['content'] }}\n {%- else %}\n {{- 'Please reason step by step, an... | {
"auto_model": "AutoModelForCausalLM",
"custom_class": null,
"pipeline_tag": "text-generation",
"processor": "AutoTokenizer"
} | {"base_model": "Qwen/Qwen2.5-Math-72B", "datasets": null, "eval_results": null, "language": ["en"], "library_name": "transformers", "license": "other", "license_name": "qwen", "license_link": "https://huggingface.co/Qwen/Qwen2.5-Math-72B-Instruct/blob/main/LICENSE", "metrics": null, "model_name": null, "pipeline_tag": ... | # Qwen2.5-Math-72B-Instruct
> [!Warning]
> <div align="center">
> <b>
> 🚨 Qwen2.5-Math mainly supports solving English and Chinese math problems through CoT and TIR. We do not recommend using this series of models for other tasks.
> </b>
> </div>
## Introduction
In August 2024, we released the first series of mathe... | null | [
"other",
"qwen",
"https://huggingface.co/Qwen/Qwen2.5-Math-72B-Instruct/blob/main/LICENSE"
] | null | [
"en"
] | 72,706,203,648 | null | null | [
"AutoModelForCausalLM",
"Qwen2ForCausalLM",
"qwen2"
] | [
"text-generation"
] | [
"text"
] | [
"text"
] | [
"text"
] |
67b738aa56bda5932609d72e | 2cdba62b0ecdc386 | c0d8706e90709d09 | 49,155 | BPE | 48,872 | false | true | false | true | 41 | null | Sequence | ByteLevel | null | [
"Digits",
"ByteLevel"
] | [
"ByteLevel"
] | 588 | modularStarEncoder/ModularStarEncoder-finetuned-18 | modularStarEncoder | {
"models": [
{
"_id": "67b50abaa64445f58c6621d8",
"id": "modularStarEncoder/ModularStarEncoder"
}
],
"relation": "finetune"
} | 64 | 129,362 | False | 2025-02-20T14:14:02Z | 2025-05-21T08:25:30Z | transformers | 0 | 0 | null | feature-extraction | {"parameters": {"BF16": 552967169}, "total": 552967169} | [
".gitattributes",
"README.md",
"added_tokens.json",
"config.json",
"config.py",
"merges.txt",
"model.safetensors",
"modularStarEncoder.py",
"special_tokens_map.json",
"tokenizer.json",
"tokenizer_config.json",
"vocab.json"
] | 67e13dc1c086fc1641b4c2e7d7eba17d314025e9 | [
"transformers",
"safetensors",
"ModularStarEncoder",
"feature-extraction",
"custom_code",
"dataset:bigcode/the-stack-v2",
"dataset:modularStarEncoder/SynthCode2Code2NL-neardedup",
"arxiv:2503.03008",
"arxiv:2307.16885",
"base_model:modularStarEncoder/ModularStarEncoder",
"base_model:finetune:mod... | null | {"architectures": ["ModularStarEncoder"], "auto_map": {"AutoConfig": "config.ModularStarEncoderConfig", "AutoModel": "modularStarEncoder.ModularStarEncoder"}, "model_type": "ModularStarEncoder", "tokenizer_config": {"bos_token": "<|endoftext|>", "cls_token": "<cls>", "eos_token": "<|endoftext|>", "mask_token": "<mask>"... | {
"auto_model": "AutoModel",
"custom_class": "modularStarEncoder.ModularStarEncoder",
"pipeline_tag": "feature-extraction",
"processor": null
} | {"base_model": ["modularStarEncoder/ModularStarEncoder"], "datasets": ["bigcode/the-stack-v2", "modularStarEncoder/SynthCode2Code2NL-neardedup"], "eval_results": null, "language": null, "library_name": "transformers", "license": "bigcode-openrail-m", "license_name": null, "license_link": null, "metrics": null, "model_n... | # ModularStarEncoder-550M Fine-Tuned model
<!-- Provide a quick summary of what the model is/does. -->
ModularStarEncoder-finetuned-18 is an encoder built on top of [ModularStarEncoder-1B Pre-trained](https://huggingface.co/andreagurioli1995/ModularStarEncoder) on [SynthCoNL](https://huggingface.co/datasets/andreagur... | null | [
"bigcode-openrail-m"
] | [
"bigcode/the-stack-v2",
"modularStarEncoder/SynthCode2Code2NL-neardedup"
] | null | 552,967,169 | null | null | [
"modularStarEncoder.ModularStarEncoder",
"ModularStarEncoder",
"AutoModel"
] | [
"feature-extraction"
] | [
"multimodal"
] | [
"text"
] | [
"embeddings"
] |
621ffdc136468d709f1802af | 35f8a93a304f6b78 | 70bd27c212bc339c | 50,265 | BPE | 50,000 | false | true | true | true | 5 | null | ByteLevel | ByteLevel | null | [
"ByteLevel"
] | [
"ByteLevel"
] | 6 | sentence-transformers/distilroberta-base-msmarco-v2 | sentence-transformers | null | 23 | 119,372 | False | 2022-03-02T23:29:05Z | 2025-03-06T13:32:30Z | sentence-transformers | 0 | 0 | null | sentence-similarity | {"parameters": {"I64": 514, "F32": 82118400}, "total": 82118914} | [
".gitattributes",
"1_Pooling/config.json",
"README.md",
"config.json",
"config_sentence_transformers.json",
"merges.txt",
"model.safetensors",
"modules.json",
"onnx/model.onnx",
"onnx/model_O1.onnx",
"onnx/model_O2.onnx",
"onnx/model_O3.onnx",
"onnx/model_O4.onnx",
"onnx/model_qint8_arm64.... | 8f72c03ad93baef005f9be15f39cad982989535a | [
"sentence-transformers",
"pytorch",
"tf",
"onnx",
"safetensors",
"openvino",
"roberta",
"feature-extraction",
"sentence-similarity",
"transformers",
"arxiv:1908.10084",
"license:apache-2.0",
"text-embeddings-inference",
"endpoints_compatible",
"region:us"
] | null | {"architectures": ["RobertaModel"], "model_type": "roberta", "tokenizer_config": {"unk_token": {"content": "<unk>", "single_word": false, "lstrip": false, "rstrip": false, "normalized": true, "__type": "AddedToken"}, "bos_token": {"content": "<s>", "single_word": false, "lstrip": false, "rstrip": false, "normalized": t... | {
"auto_model": "AutoModel",
"custom_class": null,
"pipeline_tag": "feature-extraction",
"processor": "AutoTokenizer"
} | {"base_model": null, "datasets": null, "eval_results": null, "language": null, "library_name": "sentence-transformers", "license": "apache-2.0", "license_name": null, "license_link": null, "metrics": null, "model_name": null, "pipeline_tag": "sentence-similarity", "tags": ["sentence-transformers", "feature-extraction",... | **⚠️ This model is deprecated. Please don't use it as it produces sentence embeddings of low quality. You can find recommended sentence embedding models here: [SBERT.net - Pretrained Models](https://www.sbert.net/docs/pretrained_models.html)**
# sentence-transformers/distilroberta-base-msmarco-v2
This is a [sentence... | null | [
"apache-2.0"
] | null | null | 82,118,914 | null | null | [
"roberta",
"AutoModel",
"RobertaModel"
] | [
"sentence-similarity",
"feature-extraction"
] | [
"text",
"multimodal"
] | [
"text"
] | [
"logits",
"embeddings"
] |
6866797d34c22b2a9276fbaa | 003ca0db4684c13e | 2a31185aeaf74e74 | 131,384 | BPE | 131,042 | false | true | false | true | 86 | null | Sequence | ByteLevel | null | [
"Split",
"ByteLevel"
] | [
"ByteLevel"
] | 602 | K-intelligence/Midm-2.0-Mini-Instruct | K-intelligence | null | 5,180 | 161,120 | False | 2025-07-03T12:37:17Z | 2025-10-29T05:31:42Z | transformers | 59 | 0 | null | text-generation | {"parameters": {"BF16": 2305517312}, "total": 2305517312} | [
".gitattributes",
"LICENSE.txt",
"README.md",
"assets/image_1.png",
"assets/image_2.png",
"config.json",
"generation_config.json",
"model.safetensors",
"special_tokens_map.json",
"tokenizer.json",
"tokenizer_config.json"
] | 383eb221c52a32278f1985257b264ade8d982e60 | [
"transformers",
"safetensors",
"llama",
"text-generation",
"KT",
"K-intelligence",
"Mi:dm",
"conversational",
"en",
"ko",
"license:mit",
"text-generation-inference",
"endpoints_compatible",
"region:us"
] | null | {"architectures": ["LlamaForCausalLM"], "model_type": "llama", "tokenizer_config": {"bos_token": "<|begin_of_text|>", "chat_template": "{{- bos_token }}\n\n{%- if not date_string is defined %}\n {%- if strftime_now is defined %}\n {%- set date_string = strftime_now('%d %b %Y') %}\n {%- else %}\n {%-... | {
"auto_model": "AutoModelForCausalLM",
"custom_class": null,
"pipeline_tag": "text-generation",
"processor": "AutoTokenizer"
} | {"base_model": null, "datasets": null, "eval_results": null, "language": ["en", "ko"], "library_name": "transformers", "license": "mit", "license_name": null, "license_link": null, "metrics": null, "model_name": null, "pipeline_tag": "text-generation", "tags": ["KT", "K-intelligence", "Mi:dm"]} | <p align="center">
<br>
<span style="font-size: 60px; font-weight: bold;">Mi:dm 2.0 Mini</span>
</br>
</p>
<p align="center">
🤗 <a href="https://huggingface.co/collections/K-intelligence/mi-dm-20-6866406c301e5f45a6926af8">Mi:dm 2.0 Models</a> |
📜 <a href="https://github.com/K-intelligence-Midm/Midm-2.0/blob/main/... | null | [
"mit"
] | null | [
"en",
"ko"
] | 2,305,517,312 | null | null | [
"AutoModelForCausalLM",
"llama",
"LlamaForCausalLM"
] | [
"text-generation"
] | [
"text"
] | [
"text"
] | [
"text"
] |
625b9728af150f08af7ad86d | aaf0c6c8c31ae134 | 1c556e107e1bc5d2 | 119,549 | Unigram | null | true | true | true | true | 6 | Sequence | Metaspace | Metaspace | [
"Replace",
"Replace",
"Precompiled",
"Replace"
] | [
"Metaspace"
] | [
"Metaspace"
] | 887 | rmihaylov/bert-base-bg | rmihaylov | null | 112 | 119,391 | False | 2022-04-17T04:27:20Z | 2022-04-17T05:15:10Z | transformers | 8 | 0 | null | fill-mask | null | [
".gitattributes",
"README.md",
"added_tokens.json",
"config.json",
"pytorch_model.bin",
"special_tokens_map.json",
"spiece.model",
"tokenizer.json",
"tokenizer_config.json"
] | 985c9aa785a4573f7d7915f49c0a3a6ff911a110 | [
"transformers",
"pytorch",
"bert",
"fill-mask",
"torch",
"bg",
"dataset:oscar",
"dataset:chitanka",
"dataset:wikipedia",
"arxiv:1810.04805",
"arxiv:1905.07213",
"license:mit",
"deploy:azure",
"region:us"
] | null | {"architectures": ["BertForMaskedLM"], "model_type": "bert", "tokenizer_config": {"bos_token": "[CLS]", "eos_token": "[SEP]", "unk_token": "<unk>", "sep_token": "[SEP]", "pad_token": "<pad>", "cls_token": "[CLS]", "mask_token": {"content": "[MASK]", "single_word": false, "lstrip": true, "rstrip": false, "normalized": f... | {
"auto_model": "AutoModelForMaskedLM",
"custom_class": null,
"pipeline_tag": "fill-mask",
"processor": "AutoTokenizer"
} | {"base_model": null, "datasets": ["oscar", "chitanka", "wikipedia"], "eval_results": null, "language": ["bg"], "library_name": null, "license": "mit", "license_name": null, "license_link": null, "metrics": null, "model_name": null, "pipeline_tag": null, "tags": ["torch"], "inference": false} | # BERT BASE (cased)
Pretrained model on Bulgarian language using a masked language modeling (MLM) objective. It was introduced in
[this paper](https://arxiv.org/abs/1810.04805) and first released in
[this repository](https://github.com/google-research/bert). This model is cased: it does make a difference
between bulga... | null | [
"mit"
] | [
"oscar",
"chitanka",
"wikipedia"
] | [
"bg"
] | null | null | null | [
"AutoModelForMaskedLM",
"bert",
"BertForMaskedLM"
] | [
"fill-mask"
] | [
"text"
] | [
"text"
] | [
"logits"
] |
663a88baec1aafe3d649b254 | 06aa7a17fbbdc348 | 106acd5dca261b23 | 50,278 | BPE | 50,009 | true | true | true | true | 26 | NFC | ByteLevel | ByteLevel | [
"NFC"
] | [
"ByteLevel"
] | [
"ByteLevel"
] | 888 | cleanrl/EleutherAI_pythia-1b-deduped__sft__tldr | cleanrl | null | 1,584 | 142,892 | False | 2024-05-07T20:02:02Z | 2024-05-15T02:46:01Z | transformers | 0 | 0 | null | text-generation | null | [
".gitattributes",
"config.json",
"generation_config.json",
"pytorch_model.bin",
"special_tokens_map.json",
"tokenizer.json",
"tokenizer_config.json"
] | 9b00ab40cad2b78fa5a9800a2dc4776b3b06aca7 | [
"transformers",
"pytorch",
"gpt_neox",
"text-generation",
"text-generation-inference",
"endpoints_compatible",
"deploy:azure",
"region:us"
] | null | {"architectures": ["GPTNeoXForCausalLM"], "model_type": "gpt_neox", "tokenizer_config": {"bos_token": "<|endoftext|>", "eos_token": "<|endoftext|>", "unk_token": "<|endoftext|>"}} | {
"auto_model": "AutoModelForCausalLM",
"custom_class": null,
"pipeline_tag": "text-generation",
"processor": "AutoTokenizer"
} | null | null | null | null | null | null | null | null | null | [
"gpt_neox",
"AutoModelForCausalLM",
"GPTNeoXForCausalLM"
] | [
"text-generation"
] | [
"text"
] | [
"text"
] | [
"text"
] |
65bfe3275604c1d383cc9727 | 02217ffa5907f57a | 8bd7d71767538b82 | 32,000 | BPE | 61,249 | true | false | true | true | 3 | Sequence | null | Sequence | [
"Prepend",
"Replace"
] | null | [
"Replace",
"ByteFallback",
"Fuse",
"Strip"
] | 130 | sophosympatheia/Midnight-Rose-70B-v2.0.3 | sophosympatheia | null | 281 | 119,578 | False | 2024-02-04T19:19:03Z | 2024-03-09T14:50:35Z | transformers | 41 | 0 | [{"name": "Midnight-Rose-70B-v2.0.3", "results": [{"task": {"type": "text-generation", "name": "Text Generation"}, "dataset": {"name": "AI2 Reasoning Challenge (25-Shot)", "type": "ai2_arc", "config": "ARC-Challenge", "split": "test", "args": {"num_few_shot": 25}}, "metrics": [{"type": "acc_norm", "value": 70.65, "name... | text-generation | {"parameters": {"F16": 68976648192}, "total": 68976648192} | [
".gitattributes",
"README.md",
"config.json",
"model-00001-of-00015.safetensors",
"model-00002-of-00015.safetensors",
"model-00003-of-00015.safetensors",
"model-00004-of-00015.safetensors",
"model-00005-of-00015.safetensors",
"model-00006-of-00015.safetensors",
"model-00007-of-00015.safetensors",
... | a97b0db69182944d0941e0f95367d0a547154b42 | [
"transformers",
"safetensors",
"llama",
"text-generation",
"en",
"arxiv:2307.11760",
"license:llama2",
"model-index",
"text-generation-inference",
"endpoints_compatible",
"deploy:azure",
"region:us"
] | null | {"architectures": ["LlamaForCausalLM"], "model_type": "llama", "tokenizer_config": {"bos_token": "<s>", "eos_token": "</s>", "pad_token": "<unk>", "unk_token": "<unk>", "use_default_system_prompt": false}} | {
"auto_model": "AutoModelForCausalLM",
"custom_class": null,
"pipeline_tag": "text-generation",
"processor": "AutoTokenizer"
} | {"language": ["en"], "license": "llama2", "model-index": [{"name": "Midnight-Rose-70B-v2.0.3", "results": [{"task": {"type": "text-generation", "name": "Text Generation"}, "dataset": {"name": "AI2 Reasoning Challenge (25-Shot)", "type": "ai2_arc", "config": "ARC-Challenge", "split": "test", "args": {"num_few_shot": 25}... | <div style="width: auto; margin-left: auto; margin-right: auto">
<img src="https://i.imgur.com/X3SBrIb.png" alt="MidnightRose" style="width: 100%; min-width: 400px; display: block; margin: auto;">
</div>
### Overview
This version of Midnight Rose has a complex family tree but I'll do my best to describe it. I will in... | null | [
"llama2"
] | null | [
"en"
] | 68,976,648,192 | null | null | [
"AutoModelForCausalLM",
"llama",
"LlamaForCausalLM"
] | [
"text-generation"
] | [
"text"
] | [
"text"
] | [
"text"
] |
621ffdc136468d709f1802b0 | d82c716f01e57f52 | 70bd27c212bc339c | 50,265 | BPE | 50,000 | false | true | true | true | 5 | null | ByteLevel | ByteLevel | null | [
"ByteLevel"
] | [
"ByteLevel"
] | 62 | sentence-transformers/distilroberta-base-paraphrase-v1 | sentence-transformers | null | 50 | 118,936 | False | 2022-03-02T23:29:05Z | 2025-03-06T13:40:12Z | sentence-transformers | 0 | 0 | null | sentence-similarity | {"parameters": {"I64": 514, "F32": 82118400}, "total": 82118914} | [
".gitattributes",
"1_Pooling/config.json",
"README.md",
"config.json",
"config_sentence_transformers.json",
"merges.txt",
"model.safetensors",
"modules.json",
"pytorch_model.bin",
"sentence_bert_config.json",
"special_tokens_map.json",
"tf_model.h5",
"tokenizer.json",
"tokenizer_config.jso... | c68bdef121693f482d8747cedec13dd0ed268e92 | [
"sentence-transformers",
"pytorch",
"tf",
"safetensors",
"roberta",
"feature-extraction",
"sentence-similarity",
"transformers",
"arxiv:1908.10084",
"license:apache-2.0",
"text-embeddings-inference",
"endpoints_compatible",
"region:us"
] | null | {"architectures": ["RobertaModel"], "model_type": "roberta", "tokenizer_config": {"unk_token": {"content": "<unk>", "single_word": false, "lstrip": false, "rstrip": false, "normalized": true, "__type": "AddedToken"}, "bos_token": {"content": "<s>", "single_word": false, "lstrip": false, "rstrip": false, "normalized": t... | {
"auto_model": "AutoModel",
"custom_class": null,
"pipeline_tag": "feature-extraction",
"processor": "AutoTokenizer"
} | {"base_model": null, "datasets": null, "eval_results": null, "language": null, "library_name": "sentence-transformers", "license": "apache-2.0", "license_name": null, "license_link": null, "metrics": null, "model_name": null, "pipeline_tag": "sentence-similarity", "tags": ["sentence-transformers", "feature-extraction",... | # sentence-transformers/distilroberta-base-paraphrase-v1
This is a [sentence-transformers](https://www.SBERT.net) model: It maps sentences & paragraphs to a 768 dimensional dense vector space and can be used for tasks like clustering or semantic search.
## Usage (Sentence-Transformers)
Using this model becomes eas... | null | [
"apache-2.0"
] | null | null | 82,118,914 | null | null | [
"roberta",
"AutoModel",
"RobertaModel"
] | [
"sentence-similarity",
"feature-extraction"
] | [
"text",
"multimodal"
] | [
"text"
] | [
"logits",
"embeddings"
] |
6663622af6f5447b8fda6048 | e23b6bdbe047bb7e | 8bd7d71767538b82 | 32,000 | BPE | 61,249 | true | false | true | true | 3 | Sequence | null | Sequence | [
"Prepend",
"Replace"
] | null | [
"Replace",
"ByteFallback",
"Fuse",
"Strip"
] | 46 | nm-testing/tinyllama-oneshot-w4a16-channel-v2 | nm-testing | null | 4,451 | 154,380 | False | 2024-06-07T19:40:26Z | 2024-10-09T19:59:12Z | transformers | 1 | 0 | null | text-generation | {"parameters": {"I64": 308, "I32": 121110528, "F16": 131558400}, "total": 252669236} | [
".gitattributes",
"config.json",
"generation_config.json",
"model.safetensors",
"recipe.yaml",
"special_tokens_map.json",
"tokenizer.json",
"tokenizer_config.json"
] | acb8831044ad9870c344712bf678b6b6c9419b4a | [
"transformers",
"safetensors",
"llama",
"text-generation",
"conversational",
"text-generation-inference",
"endpoints_compatible",
"compressed-tensors",
"region:us"
] | null | {"architectures": ["LlamaForCausalLM"], "model_type": "llama", "quantization_config": {"quant_method": "compressed-tensors"}, "tokenizer_config": {"bos_token": "<s>", "chat_template": "{% for message in messages %}\n{% if message['role'] == 'user' %}\n{{ '<|user|>\n' + message['content'] + eos_token }}\n{% elif message... | {
"auto_model": "AutoModelForCausalLM",
"custom_class": null,
"pipeline_tag": "text-generation",
"processor": "AutoTokenizer"
} | null | null | null | null | null | null | 252,669,236 | null | null | [
"AutoModelForCausalLM",
"llama",
"LlamaForCausalLM"
] | [
"text-generation"
] | [
"text"
] | [
"text"
] | [
"text"
] |
688955918f1bc2c6cedfbd67 | 7428ef9ae5ef868f | 67da9c236fa81925 | 151,669 | BPE | 151,387 | true | true | true | true | 26 | NFC | Sequence | ByteLevel | [
"NFC"
] | [
"Split",
"ByteLevel"
] | [
"ByteLevel"
] | 47 | cyankiwi/Qwen3-30B-A3B-Instruct-2507-AWQ-4bit | cyankiwi | {
"models": [
{
"_id": "6887274f2626398dc2e9f540",
"id": "Qwen/Qwen3-30B-A3B-Instruct-2507"
}
],
"relation": "quantized"
} | 38,053 | 614,282 | False | 2025-07-29T23:13:21Z | 2026-03-23T07:20:40Z | transformers | 31 | 0 | null | text-generation | {"parameters": {"I64": 37248, "I32": 29896998912, "BF16": 1569404928}, "total": 5306567040} | [
".gitattributes",
"README.md",
"added_tokens.json",
"chat_template.jinja",
"config.json",
"generation_config.json",
"merges.txt",
"model-00001-of-00004.safetensors",
"model-00002-of-00004.safetensors",
"model-00003-of-00004.safetensors",
"model-00004-of-00004.safetensors",
"model.safetensors.i... | 378aa9758f9aaa99abe86b0f02c327c9284cb52d | [
"transformers",
"safetensors",
"qwen3_moe",
"text-generation",
"conversational",
"arxiv:2505.09388",
"base_model:Qwen/Qwen3-30B-A3B-Instruct-2507",
"base_model:quantized:Qwen/Qwen3-30B-A3B-Instruct-2507",
"license:apache-2.0",
"endpoints_compatible",
"compressed-tensors",
"region:us"
] | null | {"architectures": ["Qwen3MoeForCausalLM"], "model_type": "qwen3_moe", "quantization_config": {"quant_method": "compressed-tensors"}, "tokenizer_config": {"bos_token": null, "eos_token": "<|im_end|>", "pad_token": "<|endoftext|>", "unk_token": null}, "chat_template_jinja": "{%- if tools %}\n {{- '<|im_start|>system\\... | {
"auto_model": "AutoModelForCausalLM",
"custom_class": null,
"pipeline_tag": "text-generation",
"processor": "AutoTokenizer"
} | {"base_model": "Qwen/Qwen3-30B-A3B-Instruct-2507", "datasets": null, "eval_results": null, "language": null, "library_name": "transformers", "license": "apache-2.0", "license_name": null, "license_link": "https://huggingface.co/Qwen/Qwen3-30B-A3B-Instruct-2507/blob/main/LICENSE", "metrics": null, "model_name": null, "p... | null | null | [
"apache-2.0",
"https://huggingface.co/Qwen/Qwen3-30B-A3B-Instruct-2507/blob/main/LICENSE"
] | null | null | 5,306,567,040 | null | null | [
"qwen3_moe",
"AutoModelForCausalLM",
"Qwen3MoeForCausalLM"
] | [
"text-generation"
] | [
"text"
] | [
"text"
] | [
"text"
] |
648967cc51b69a8c82f6e44f | 2ad52fdc0a02add9 | 079f8303f7d4d91e | 32,101 | Unigram | null | true | true | true | true | 104 | Sequence | Metaspace | Metaspace | [
"Precompiled",
"Replace"
] | [
"Metaspace"
] | [
"Metaspace"
] | 417 | sjrhuschlee/flan-t5-base-squad2 | sjrhuschlee | {
"models": [
{
"_id": "63526e37b2c3384b9fed5bd9",
"id": "google/flan-t5-base"
}
],
"relation": "finetune"
} | 4,534 | 134,561 | False | 2023-06-14T07:10:04Z | 2025-10-15T07:15:31Z | transformers | 5 | 0 | [{"name": "sjrhuschlee/flan-t5-base-squad2", "results": [{"task": {"type": "question-answering", "name": "Question Answering"}, "dataset": {"name": "squad_v2", "type": "squad_v2", "config": "squad_v2", "split": "validation"}, "metrics": [{"type": "exact_match", "value": 82.203, "name": "Exact Match", "verified": false}... | question-answering | {"parameters": {"F32": 222905090}, "total": 222905090} | [
".gitattributes",
"README.md",
"added_tokens.json",
"config.json",
"model.safetensors",
"modeling_t5qa.py",
"pytorch_model.bin",
"special_tokens_map.json",
"spiece.model",
"tokenizer.json",
"tokenizer_config.json"
] | c1fc232b3e8d745877fb1658a30627cf23629022 | [
"transformers",
"pytorch",
"safetensors",
"t5",
"question-answering",
"squad",
"squad_v2",
"custom_code",
"en",
"dataset:squad_v2",
"dataset:squad",
"base_model:google/flan-t5-base",
"base_model:finetune:google/flan-t5-base",
"license:mit",
"model-index",
"text-generation-inference",
... | null | {"architectures": ["T5ForQuestionAnswering"], "auto_map": {"AutoModelForQuestionAnswering": "modeling_t5qa.T5ForQuestionAnswering"}, "model_type": "t5", "tokenizer_config": {"eos_token": "</s>", "pad_token": "<pad>", "unk_token": "<unk>"}} | {
"auto_model": "AutoModelForQuestionAnswering",
"custom_class": null,
"pipeline_tag": "question-answering",
"processor": "AutoTokenizer"
} | {"base_model": ["google/flan-t5-base"], "datasets": ["squad_v2", "squad"], "language": ["en"], "library_name": "transformers", "license": "mit", "pipeline_tag": "question-answering", "tags": ["question-answering", "squad", "squad_v2", "t5"], "model-index": [{"name": "sjrhuschlee/flan-t5-base-squad2", "results": [{"task... | # flan-t5-base for Extractive QA
This is the [flan-t5-base](https://huggingface.co/google/flan-t5-base) model, fine-tuned using the [SQuAD2.0](https://huggingface.co/datasets/squad_v2) dataset. It's been trained on question-answer pairs, including unanswerable questions, for the task of Extractive Question Answering.
... | null | [
"mit"
] | [
"squad_v2",
"squad"
] | [
"en"
] | 222,905,090 | null | null | [
"t5",
"AutoModelForQuestionAnswering",
"T5ForQuestionAnswering"
] | [
"question-answering"
] | [
"text"
] | [
"text"
] | [
"text"
] |
68ac918d66dab09772f3021c | 6c53decdf26fa934 | 21ca95dec54278ad | 151,678 | BPE | 151,387 | true | true | true | true | 35 | NFC | Sequence | ByteLevel | [
"NFC"
] | [
"Split",
"ByteLevel"
] | [
"ByteLevel"
] | 820 | OpenGVLab/InternVL3_5-30B-A3B | OpenGVLab | {
"models": [
{
"_id": "68ac918d65fc0297eeace1e9",
"id": "OpenGVLab/InternVL3_5-30B-A3B-MPO"
}
],
"relation": "finetune"
} | 102,076 | 378,026 | False | 2025-08-25T16:38:37Z | 2025-08-29T17:57:02Z | transformers | 41 | 0 | null | image-text-to-text | {"parameters": {"BF16": 30848730112}, "total": 30848730112} | [
".gitattributes",
"README.md",
"added_tokens.json",
"chat_template.jinja",
"config.json",
"configuration_intern_vit.py",
"configuration_internvl_chat.py",
"conversation.py",
"generation_config.json",
"merges.txt",
"model-00001-of-00013.safetensors",
"model-00002-of-00013.safetensors",
"model... | ba1762d830e2aeddb3272b66ba9e0abf7e69f626 | [
"transformers",
"safetensors",
"internvl_chat",
"feature-extraction",
"internvl",
"custom_code",
"image-text-to-text",
"conversational",
"multilingual",
"dataset:OpenGVLab/MMPR-v1.2",
"dataset:OpenGVLab/MMPR-Tiny",
"arxiv:2312.14238",
"arxiv:2404.16821",
"arxiv:2412.05271",
"arxiv:2411.1... | null | {"architectures": ["InternVLChatModel"], "auto_map": {"AutoConfig": "configuration_internvl_chat.InternVLChatConfig", "AutoModel": "modeling_internvl_chat.InternVLChatModel", "AutoModelForCausalLM": "modeling_internvl_chat.InternVLChatModel"}, "model_type": "internvl_chat", "tokenizer_config": {"bos_token": null, "eos_... | {
"auto_model": "AutoModel",
"custom_class": "modeling_internvl_chat.InternVLChatModel",
"pipeline_tag": "feature-extraction",
"processor": null
} | {"base_model": ["OpenGVLab/InternVL3_5-30B-A3B-MPO"], "datasets": ["OpenGVLab/MMPR-v1.2", "OpenGVLab/MMPR-Tiny"], "eval_results": null, "language": ["multilingual"], "library_name": "transformers", "license": "apache-2.0", "license_name": null, "license_link": null, "metrics": null, "model_name": null, "pipeline_tag": ... | # InternVL3_5-30B-A3B
[\[📂 GitHub\]](https://github.com/OpenGVLab/InternVL) [\[📜 InternVL 1.0\]](https://huggingface.co/papers/2312.14238) [\[📜 InternVL 1.5\]](https://huggingface.co/papers/2404.16821) [\[📜 InternVL 2.5\]](https://huggingface.co/papers/2412.05271) [\[📜 InternVL2.5-MPO\]](https://huggingface.c... | null | [
"apache-2.0"
] | [
"OpenGVLab/MMPR-v1.2",
"OpenGVLab/MMPR-Tiny"
] | [
"multilingual"
] | 30,848,730,112 | null | null | [
"AutoModel",
"internvl_chat",
"InternVLChatModel",
"modeling_internvl_chat.InternVLChatModel"
] | [
"image-text-to-text",
"feature-extraction"
] | [
"multimodal"
] | [
"text",
"image"
] | [
"text",
"embeddings"
] |
6870b708a09cb0bdf3898657 | 1ad5523c1ec07177 | 06298d1af93197f8 | 102,400 | BPE | 101,782 | false | true | true | true | 362 | null | ByteLevel | ByteLevel | null | [
"ByteLevel"
] | [
"ByteLevel"
] | 399 | LGAI-EXAONE/EXAONE-4.0-1.2B | LGAI-EXAONE | null | 29,301 | 310,098 | False | 2025-07-11T07:02:32Z | 2025-08-04T02:19:35Z | transformers | 177 | 0 | null | text-generation | {"parameters": {"BF16": 1279391488}, "total": 1279391488} | [
".gitattributes",
"LICENSE",
"README.md",
"assets/EXAONE_Symbol+BI_3d.png",
"chat_template.jinja",
"config.json",
"generation_config.json",
"merges.txt",
"model.safetensors",
"special_tokens_map.json",
"tokenizer.json",
"tokenizer_config.json",
"vocab.json"
] | 3abf2810673c7c0778df64a73c2d52eab32d91c4 | [
"transformers",
"safetensors",
"exaone4",
"text-generation",
"lg-ai",
"exaone",
"exaone-4.0",
"conversational",
"en",
"ko",
"es",
"arxiv:2507.11407",
"license:other",
"endpoints_compatible",
"region:us"
] | null | {"architectures": ["Exaone4ForCausalLM"], "model_type": "exaone4", "tokenizer_config": {"bos_token": "[BOS]", "eos_token": "[|endofturn|]", "pad_token": "[PAD]", "unk_token": "[UNK]"}, "chat_template_jinja": "{%- if not skip_think is defined %}\n {%- set skip_think = true %}\n{%- endif %}\n\n{%- set role_indicators = ... | {
"auto_model": "AutoModelForCausalLM",
"custom_class": null,
"pipeline_tag": "text-generation",
"processor": "AutoTokenizer"
} | {"base_model": null, "datasets": null, "eval_results": null, "language": ["en", "ko", "es"], "library_name": "transformers", "license": "other", "license_name": "exaone", "license_link": "LICENSE", "metrics": null, "model_name": null, "pipeline_tag": "text-generation", "tags": ["lg-ai", "exaone", "exaone-4.0"]} | null | null | [
"other",
"exaone",
"LICENSE"
] | null | [
"en",
"ko",
"es"
] | 1,279,391,488 | null | null | [
"AutoModelForCausalLM",
"Exaone4ForCausalLM",
"exaone4"
] | [
"text-generation"
] | [
"text"
] | [
"text"
] | [
"text"
] |
664133bc69597de2568cd7bb | 1285d5ee2909ea37 | cad4902422b140fb | 64,000 | BPE | 110,029 | true | false | true | true | 4 | Sequence | null | Sequence | [
"Prepend",
"Replace"
] | null | [
"Replace",
"ByteFallback",
"Fuse",
"Strip"
] | 889 | vicgalle/Configurable-Yi-1.5-9B-Chat | vicgalle | null | 8,400 | 159,334 | False | 2024-05-12T21:25:16Z | 2024-07-25T15:19:38Z | transformers | 3 | 0 | [{"name": "Configurable-Yi-1.5-9B-Chat", "results": [{"task": {"type": "text-generation", "name": "Text Generation"}, "dataset": {"name": "AI2 Reasoning Challenge (25-Shot)", "type": "ai2_arc", "config": "ARC-Challenge", "split": "test", "args": {"num_few_shot": 25}}, "metrics": [{"type": "acc_norm", "value": 64.16, "n... | text-generation | {"parameters": {"F16": 8829407232}, "total": 8829407232} | [
".gitattributes",
"README.md",
"config.json",
"generation_config.json",
"model-00001-of-00004.safetensors",
"model-00002-of-00004.safetensors",
"model-00003-of-00004.safetensors",
"model-00004-of-00004.safetensors",
"model.safetensors.index.json",
"special_tokens_map.json",
"tokenizer.json",
"... | 803651e86778c096a9fab84889ed3afefa74963f | [
"transformers",
"safetensors",
"llama",
"text-generation",
"conversational",
"dataset:vicgalle/configurable-system-prompt-multitask",
"arxiv:2404.00495",
"license:apache-2.0",
"model-index",
"text-generation-inference",
"endpoints_compatible",
"deploy:azure",
"region:us"
] | null | {"architectures": ["LlamaForCausalLM"], "model_type": "llama", "tokenizer_config": {"bos_token": "<|startoftext|>", "chat_template": "{% if messages[0]['role'] == 'system' %}{% set system_message = messages[0]['content'] %}{% endif %}{% if system_message is defined %}{{ system_message }}{% endif %}{% for message in mes... | {
"auto_model": "AutoModelForCausalLM",
"custom_class": null,
"pipeline_tag": "text-generation",
"processor": "AutoTokenizer"
} | {"datasets": ["vicgalle/configurable-system-prompt-multitask"], "library_name": "transformers", "license": "apache-2.0", "model-index": [{"name": "Configurable-Yi-1.5-9B-Chat", "results": [{"task": {"type": "text-generation", "name": "Text Generation"}, "dataset": {"name": "AI2 Reasoning Challenge (25-Shot)", "type": "... | # Configurable-Yi.1.5-9B
A configurable Yi.1.5-9B fine-tuned using the approach *configurable safety tuning* (CST) from https://arxiv.org/abs/2404.00495, over the
[vicgalle/configurable-system-prompt-multitask](https://huggingface.co/datasets/vicgalle/configurable-system-prompt-multitask) dataset.
As such, you can u... | null | [
"apache-2.0"
] | [
"vicgalle/configurable-system-prompt-multitask"
] | null | 8,829,407,232 | null | null | [
"AutoModelForCausalLM",
"llama",
"LlamaForCausalLM"
] | [
"text-generation"
] | [
"text"
] | [
"text"
] | [
"text"
] |
65ea26ee6f092bab24af0968 | 88cd37e502d27a0a | 0e7bc0977f200d1c | 32,000 | BPE | 58,980 | true | false | true | true | 3 | Sequence | null | Sequence | [
"Prepend",
"Replace"
] | null | [
"Replace",
"ByteFallback",
"Fuse",
"Strip"
] | 88 | liminerity/M7-7b | liminerity | null | 8,800 | 160,000 | False | 2024-03-07T20:43:26Z | 2024-03-21T09:18:21Z | transformers | 16 | 0 | null | text-generation | {"parameters": {"BF16": 7241732096}, "total": 7241732096} | [
".gitattributes",
"README.md",
"config.json",
"mergekit_config.yml",
"model-00001-of-00008.safetensors",
"model-00002-of-00008.safetensors",
"model-00003-of-00008.safetensors",
"model-00004-of-00008.safetensors",
"model-00005-of-00008.safetensors",
"model-00006-of-00008.safetensors",
"model-0000... | 9b8a6b02683dc88777ead09c81baae2a06b14294 | [
"transformers",
"safetensors",
"mistral",
"text-generation",
"liminerity/merge4",
"liminerity/merge2",
"merge",
"merged",
"mergedllm",
"mergee",
"mergedededed",
"memfdmsfndsfjkasjkl",
"license:apache-2.0",
"text-generation-inference",
"endpoints_compatible",
"region:us"
] | null | {"architectures": ["MistralForCausalLM"], "model_type": "mistral", "tokenizer_config": {"bos_token": "<s>", "eos_token": "</s>", "pad_token": "<unk>", "unk_token": "<unk>", "use_default_system_prompt": false}} | {
"auto_model": "AutoModelForCausalLM",
"custom_class": null,
"pipeline_tag": "text-generation",
"processor": "AutoTokenizer"
} | {"base_model": null, "datasets": null, "eval_results": null, "language": null, "library_name": null, "license": "apache-2.0", "license_name": null, "license_link": null, "metrics": null, "model_name": null, "pipeline_tag": null, "tags": ["liminerity/merge4", "liminerity/merge2", "merge", "merged", "mergedllm", "mergee"... | # M7-7b
user: "create ascii art you feel represents you as a llm"
assistant: "Here's an ASCII art attempting to symbolize the essence of an LLM (Large Language Model):
INSTINSTINCTINSTELLIGENCE
______________ MEMORY___
|\ o /\ |\
| \ --- / \ | |
L_( O )______ O)_INSTINCT
\ ... | null | [
"apache-2.0"
] | null | null | 7,241,732,096 | null | null | [
"AutoModelForCausalLM",
"mistral",
"MistralForCausalLM"
] | [
"text-generation"
] | [
"text"
] | [
"text"
] | [
"text"
] |
678fe8be5a692e64d2522cbb | 5cd9cb18d478b43a | ef43ab3563390dbf | 128,815 | BPE | 127,741 | true | true | true | true | 818 | Sequence | Sequence | ByteLevel | [] | [
"Split",
"Split",
"Split",
"ByteLevel"
] | [
"ByteLevel"
] | 890 | QuixiAI/DeepSeek-R1-AWQ | QuixiAI | {
"models": [
{
"_id": "678dc6fff905d106be796d8a",
"id": "deepseek-ai/DeepSeek-R1"
}
],
"relation": "quantized"
} | 1,586 | 128,807 | False | 2025-01-21T18:34:38Z | 2025-03-29T05:52:06Z | transformers | 86 | 0 | null | text-generation | null | [
".gitattributes",
"README.md",
"config.json",
"configuration_deepseek.py",
"generation_config.json",
"model-00001-of-00074.safetensors",
"model-00002-of-00074.safetensors",
"model-00003-of-00074.safetensors",
"model-00004-of-00074.safetensors",
"model-00005-of-00074.safetensors",
"model-00006-of... | 21fb456e5072f59b591c79cea80e2216ec3be348 | [
"transformers",
"safetensors",
"deepseek_v3",
"text-generation",
"conversational",
"custom_code",
"en",
"zh",
"base_model:deepseek-ai/DeepSeek-R1",
"base_model:quantized:deepseek-ai/DeepSeek-R1",
"license:mit",
"text-generation-inference",
"endpoints_compatible",
"4-bit",
"awq",
"regio... | null | {"architectures": ["DeepseekV3ForCausalLM"], "auto_map": {"AutoConfig": "configuration_deepseek.DeepseekV3Config", "AutoModel": "modeling_deepseek.DeepseekV3Model", "AutoModelForCausalLM": "modeling_deepseek.DeepseekV3ForCausalLM"}, "model_type": "deepseek_v3", "quantization_config": {"bits": 4, "quant_method": "awq"},... | {
"auto_model": "AutoModelForCausalLM",
"custom_class": null,
"pipeline_tag": "text-generation",
"processor": "AutoTokenizer"
} | {"base_model": ["deepseek-ai/DeepSeek-R1"], "datasets": null, "eval_results": null, "language": ["en", "zh"], "library_name": "transformers", "license": "mit", "license_name": null, "license_link": null, "metrics": null, "model_name": null, "pipeline_tag": "text-generation", "tags": null} | null | null | [
"mit"
] | null | [
"en",
"zh"
] | null | null | null | [
"AutoModelForCausalLM",
"deepseek_v3",
"DeepseekV3ForCausalLM"
] | [
"text-generation"
] | [
"text"
] | [
"text"
] | [
"text"
] |
64bf6c8d2915a87970bfe521 | b8a1cdd978ebb3ce | 2bc23d266c63598f | 37,632 | BPE | 61,249 | true | false | true | true | 3 | Sequence | null | Sequence | [
"Prepend",
"Replace"
] | null | [
"Replace",
"ByteFallback",
"Fuse",
"Strip"
] | 759 | OpenBuddy/openbuddy-llama2-13b-v8.1-fp16 | OpenBuddy | null | 846 | 122,704 | False | 2023-07-25T06:32:45Z | 2023-09-01T16:14:53Z | transformers | 64 | 0 | null | text-generation | null | [
".gitattributes",
"README.md",
"config.json",
"generation_config.json",
"pytorch_model-00001-of-00003.bin",
"pytorch_model-00002-of-00003.bin",
"pytorch_model-00003-of-00003.bin",
"pytorch_model.bin.index.json",
"special_tokens_map.json",
"tokenizer.json",
"tokenizer.model",
"tokenizer_config.... | 982a6b50fe0fa7e1bc3816d6d28484038e9daf29 | [
"transformers",
"pytorch",
"llama",
"text-generation",
"zh",
"en",
"fr",
"de",
"ja",
"ko",
"it",
"ru",
"text-generation-inference",
"deploy:azure",
"region:us"
] | null | {"architectures": ["LlamaForCausalLM"], "model_type": "llama", "tokenizer_config": {"bos_token": {"__type": "AddedToken", "content": "<s>", "lstrip": false, "normalized": true, "rstrip": false, "single_word": false}, "eos_token": {"__type": "AddedToken", "content": "</s>", "lstrip": false, "normalized": true, "rstrip":... | {
"auto_model": "AutoModelForCausalLM",
"custom_class": null,
"pipeline_tag": "text-generation",
"processor": "AutoTokenizer"
} | {"base_model": null, "datasets": null, "eval_results": null, "language": ["zh", "en", "fr", "de", "ja", "ko", "it", "ru"], "library_name": "transformers", "license": null, "license_name": null, "license_link": null, "metrics": null, "model_name": null, "pipeline_tag": "text-generation", "tags": null, "inference": false... | # OpenBuddy - Open Multilingual Chatbot
The latest version is at [https://huggingface.co/OpenBuddy/openbuddy-llama2-13b-v11.1-bf16](https://huggingface.co/OpenBuddy/openbuddy-llama2-13b-v11.1-bf16), which performs better than this verison.
GitHub and Usage Guide: [https://github.com/OpenBuddy/OpenBuddy](https://githu... | null | null | null | [
"zh",
"en",
"fr",
"de",
"ja",
"ko",
"it",
"ru"
] | null | null | null | [
"AutoModelForCausalLM",
"llama",
"LlamaForCausalLM"
] | [
"text-generation"
] | [
"text"
] | [
"text"
] | [
"text"
] |
65c35b850205b2e6a8507ee9 | 09574be15ef6a4ca | 081b543d8f95004e | 32,002 | BPE | 58,980 | true | false | true | true | 5 | Sequence | null | Sequence | [
"Prepend",
"Replace"
] | null | [
"Replace",
"ByteFallback",
"Fuse",
"Strip"
] | 625 | AIJUUD/juud-Mistral-7B-dpo | AIJUUD | null | 8,380 | 158,810 | False | 2024-02-07T10:29:25Z | 2024-02-07T11:47:45Z | transformers | 0 | 0 | null | text-generation | {"parameters": {"F16": 7241748480}, "total": 7241748480} | [
".gitattributes",
"README.md",
"added_tokens.json",
"config.json",
"generation_config.json",
"model-00001-of-00003.safetensors",
"model-00002-of-00003.safetensors",
"model-00003-of-00003.safetensors",
"model.safetensors.index.json",
"special_tokens_map.json",
"tokenizer.json",
"tokenizer.model... | b428f21995854f143b497a36d210276439ae0b87 | [
"transformers",
"safetensors",
"mistral",
"text-generation",
"conversational",
"en",
"arxiv:1910.09700",
"license:apache-2.0",
"text-generation-inference",
"endpoints_compatible",
"deploy:azure",
"region:us"
] | null | {"architectures": ["MistralForCausalLM"], "model_type": "mistral", "tokenizer_config": {"bos_token": "<s>", "chat_template": "{% for message in messages %}{{'<|im_start|>' + message['role'] + '\n' + message['content'] + '<|im_end|>' + '\n'}}{% endfor %}{% if add_generation_prompt %}{{ '<|im_start|>assistant\n' }}{% end... | {
"auto_model": "AutoModelForCausalLM",
"custom_class": null,
"pipeline_tag": "text-generation",
"processor": "AutoTokenizer"
} | {"base_model": null, "datasets": null, "eval_results": null, "language": ["en"], "library_name": "transformers", "license": "apache-2.0", "license_name": null, "license_link": null, "metrics": null, "model_name": null, "pipeline_tag": null, "tags": null} | # Model Card for Model ID
<!-- Provide a quick summary of what the model is/does. -->
## Model Details
### Model Description
<!-- Provide a longer summary of what this model is. -->
This is the model card of a 🤗 transformers model that has been pushed on the Hub. This model card has been automatically generated... | null | [
"apache-2.0"
] | null | [
"en"
] | 7,241,748,480 | null | null | [
"AutoModelForCausalLM",
"mistral",
"MistralForCausalLM"
] | [
"text-generation"
] | [
"text"
] | [
"text"
] | [
"text"
] |
656b8107c4d6794d7f4acaa7 | 837e31715100fc38 | 50d2c83c17953b0f | 78,464 | BPE | 126,515 | true | false | true | true | 54 | Sequence | null | Sequence | [
"NFKC",
"Prepend",
"Replace"
] | null | [
"Replace",
"ByteFallback",
"Fuse"
] | 891 | kyujinpy/Ko-PlatYi-6B | kyujinpy | null | 27,871 | 145,515 | False | 2023-12-02T19:09:59Z | 2023-12-09T13:21:33Z | transformers | 7 | 0 | null | text-generation | null | [
".gitattributes",
"Ko-PlatYi.png",
"README.md",
"config.json",
"generation_config.json",
"pytorch_model-00001-of-00002.bin",
"pytorch_model-00002-of-00002.bin",
"pytorch_model.bin.index.json",
"special_tokens_map.json",
"tokenizer.json",
"tokenizer_config.json"
] | d6e85f51114fb08c8ce6cad9d543b50707480fe4 | [
"transformers",
"pytorch",
"llama",
"text-generation",
"ko",
"dataset:kyujinpy/KOR-OpenOrca-Platypus-v3",
"license:cc-by-nc-sa-4.0",
"text-generation-inference",
"endpoints_compatible",
"deploy:azure",
"region:us"
] | null | {"architectures": ["LlamaForCausalLM"], "model_type": "llama", "tokenizer_config": {"bos_token": "<|startoftext|>", "eos_token": "<|endoftext|>", "pad_token": "<unk>", "unk_token": "<unk>", "use_default_system_prompt": true}} | {
"auto_model": "AutoModelForCausalLM",
"custom_class": null,
"pipeline_tag": "text-generation",
"processor": "AutoTokenizer"
} | {"base_model": null, "datasets": ["kyujinpy/KOR-OpenOrca-Platypus-v3"], "eval_results": null, "language": ["ko"], "library_name": "transformers", "license": "cc-by-nc-sa-4.0", "license_name": null, "license_link": null, "metrics": null, "model_name": null, "pipeline_tag": "text-generation", "tags": null} | # **Ko-PlatYi-6B**
<img src='./Ko-PlatYi.png' width=256>
## Model Details
**Model Developers** Kyujin Han (kyujinpy)
**Input** Models input text only.
**Output** Models generate text only.
**Model Architecture**
Ko-PlatYi-6B is an auto-regressive language model based on the Yi-34B transformer architecture.
*... | null | [
"cc-by-nc-sa-4.0"
] | [
"kyujinpy/KOR-OpenOrca-Platypus-v3"
] | [
"ko"
] | null | null | null | [
"AutoModelForCausalLM",
"llama",
"LlamaForCausalLM"
] | [
"text-generation"
] | [
"text"
] | [
"text"
] | [
"text"
] |
66e77e198aa82e56feb0bfef | 87b9c94074108810 | beb3470dba551017 | 131,072 | BPE | 269,443 | false | true | true | true | 1,000 | null | Sequence | ByteLevel | null | [
"Split",
"ByteLevel"
] | [
"ByteLevel"
] | 892 | inflatebot/MN-12B-Mag-Mell-R1 | inflatebot | {
"models": [
{
"_id": "66bffb6dd9a79741229a6185",
"id": "Fizzarolli/MN-12b-Sunrose"
},
{
"_id": "66a43ff2fa79f2cc50024dc4",
"id": "IntervitensInc/Mistral-Nemo-Base-2407-chatml"
},
{
"_id": "66b98d31c689a131a0f93a5f",
"id": "anthracite-org/magnum-v2.5-12b-kto"
... | 786 | 122,216 | False | 2024-09-16T00:38:49Z | 2025-04-03T00:43:44Z | transformers | 232 | 0 | null | text-generation | {"parameters": {"BF16": 12247782400}, "total": 12247782400} | [
".gitattributes",
"README.md",
"config.json",
"magmell.png",
"mergekit_config.yml",
"model-00001-of-00005.safetensors",
"model-00002-of-00005.safetensors",
"model-00003-of-00005.safetensors",
"model-00004-of-00005.safetensors",
"model-00005-of-00005.safetensors",
"model.safetensors.index.json",
... | b5f9f348c2e43dc8c862b2d4ab1521e3256696fc | [
"transformers",
"safetensors",
"mistral",
"text-generation",
"mergekit",
"merge",
"conversational",
"arxiv:2311.03099",
"arxiv:2306.01708",
"base_model:Fizzarolli/MN-12b-Sunrose",
"base_model:merge:Fizzarolli/MN-12b-Sunrose",
"base_model:IntervitensInc/Mistral-Nemo-Base-2407-chatml",
"base_m... | null | {"architectures": ["MistralForCausalLM"], "model_type": "mistral", "tokenizer_config": {"bos_token": "<s>", "chat_template": "{% for message in messages %}{% if loop.first and messages[0]['role'] != 'system' %}{{ '<|im_start|>system\nYou are a helpful assistant.<|im_end|>\n' }}{% endif %}{{'<|im_start|>' + message['rol... | {
"auto_model": "AutoModelForCausalLM",
"custom_class": null,
"pipeline_tag": "text-generation",
"processor": "AutoTokenizer"
} | {"base_model": ["IntervitensInc/Mistral-Nemo-Base-2407-chatml", "nbeerbower/mistral-nemo-bophades-12B", "nbeerbower/mistral-nemo-wissenschaft-12B", "elinas/Chronos-Gold-12B-1.0", "Fizzarolli/MN-12b-Sunrose", "nbeerbower/mistral-nemo-gutenberg-12B-v4", "anthracite-org/magnum-12b-v2.5-kto"], "datasets": null, "eval_resul... | null | null | null | null | null | 12,247,782,400 | null | null | [
"AutoModelForCausalLM",
"mistral",
"MistralForCausalLM"
] | [
"text-generation"
] | [
"text"
] | [
"text"
] | [
"text"
] |
661f1209fd61b702be377b20 | d3e093d5df2ac186 | 5c23ae65406ceec5 | 65,536 | BPE | 139,274 | true | false | true | true | 4 | Sequence | null | Sequence | [
"Replace"
] | null | [
"Replace",
"ByteFallback",
"Fuse"
] | 536 | ai21labs/Jamba-tiny-random | ai21labs | null | 4,033 | 131,197 | False | 2024-04-17T00:04:25Z | 2024-04-24T06:50:37Z | transformers | 13 | 0 | null | text-generation | {"parameters": {"BF16": 127679344}, "total": 127679344} | [
".gitattributes",
"README.md",
"config.json",
"generation_config.json",
"model.safetensors",
"special_tokens_map.json",
"tokenizer.json",
"tokenizer.model",
"tokenizer_config.json"
] | 449ffa6a14916adb7d19312bf63024b8a8e4c1b4 | [
"transformers",
"safetensors",
"jamba",
"text-generation",
"license:apache-2.0",
"endpoints_compatible",
"region:us"
] | null | {"architectures": ["JambaForCausalLM"], "model_type": "jamba", "tokenizer_config": {"bos_token": "<|startoftext|>", "eos_token": "<|endoftext|>", "pad_token": "<|pad|>", "unk_token": "<|unk|>", "use_default_system_prompt": false}} | {
"auto_model": "AutoModelForCausalLM",
"custom_class": null,
"pipeline_tag": "text-generation",
"processor": "AutoTokenizer"
} | {"base_model": null, "datasets": null, "eval_results": null, "language": null, "library_name": null, "license": "apache-2.0", "license_name": null, "license_link": null, "metrics": null, "model_name": null, "pipeline_tag": null, "tags": null} | This is a tiny, dummy version of [Jamba](https://huggingface.co/ai21labs/Jamba-v0.1), used for debugging and experimentation over the Jamba architecture.
It has 128M parameters (instead of 52B), **and is initialized with random weights and did not undergo any training.** | null | [
"apache-2.0"
] | null | null | 127,679,344 | null | null | [
"AutoModelForCausalLM",
"jamba",
"JambaForCausalLM"
] | [
"text-generation"
] | [
"text"
] | [
"text"
] | [
"text"
] |
68bec7cd053048791c3f561d | 848b60b6cd304b65 | ffc911e785abe60e | 151,665 | BPE | 151,387 | true | true | true | true | 22 | NFC | Sequence | ByteLevel | [
"NFC"
] | [
"Split",
"ByteLevel"
] | [
"ByteLevel"
] | 15 | LLM360/K2-Think | LLM360 | {
"models": [
{
"_id": "66e6d09952865ca1e41c6566",
"id": "Qwen/Qwen2.5-32B"
}
],
"relation": "finetune"
} | 125 | 120,976 | False | 2025-09-08T12:10:53Z | 2025-11-19T14:52:27Z | transformers | 365 | 0 | null | text-generation | {"parameters": {"BF16": 32763876352}, "total": 32763876352} | [
".gitattributes",
"README.md",
"added_tokens.json",
"banner.png",
"chat_template.jinja",
"config.json",
"generation_config.json",
"merges.txt",
"model-00001-of-00014.safetensors",
"model-00002-of-00014.safetensors",
"model-00003-of-00014.safetensors",
"model-00004-of-00014.safetensors",
"mod... | 9e218ac1be727e8f9d1ee4ad68530913f01a9ab2 | [
"transformers",
"safetensors",
"qwen2",
"text-generation",
"conversational",
"en",
"arxiv:2509.07604",
"base_model:Qwen/Qwen2.5-32B",
"base_model:finetune:Qwen/Qwen2.5-32B",
"license:apache-2.0",
"text-generation-inference",
"endpoints_compatible",
"deploy:azure",
"region:us"
] | null | {"architectures": ["Qwen2ForCausalLM"], "model_type": "qwen2", "tokenizer_config": {"bos_token": null, "eos_token": "<|im_end|>", "pad_token": "<|endoftext|>", "unk_token": null}, "chat_template_jinja": "{% set system_message = 'You are K2-Think, a helpful assistant trained by MBZUAI. To answer the user\\'s question, y... | {
"auto_model": "AutoModelForCausalLM",
"custom_class": null,
"pipeline_tag": "text-generation",
"processor": "AutoTokenizer"
} | {"base_model": "Qwen/Qwen2.5-32B", "datasets": null, "eval_results": null, "language": ["en"], "library_name": "transformers", "license": "apache-2.0", "license_name": null, "license_link": null, "metrics": null, "model_name": null, "pipeline_tag": "text-generation", "tags": null} | # K2-Think: A Parameter-Efficient Reasoning System
📚 [Paper](https://huggingface.co/papers/2509.07604) - 📝 [Code](https://github.com/MBZUAI-IFM/K2-Think-SFT) - 🏢 [Project Page](https://k2think.ai)
<center><img src="banner.png" alt="k2-think-banner"/></center>
<br>
K2-Think is a 32 billion parameter open-weights ... | null | [
"apache-2.0"
] | null | [
"en"
] | 32,763,876,352 | null | null | [
"AutoModelForCausalLM",
"Qwen2ForCausalLM",
"qwen2"
] | [
"text-generation"
] | [
"text"
] | [
"text"
] | [
"text"
] |
63b4e5e03e02c8e7cb79b096 | 53ecf467267e2824 | 535fa14da0af647c | 30,522 | WordPiece | null | true | true | true | true | 5 | BertNormalizer | BertPreTokenizer | WordPiece | [
"BertNormalizer"
] | [
"BertPreTokenizer"
] | [
"WordPiece"
] | 0 | castorini/wiki-all-8-4-multi-dpr2-query-encoder | castorini | null | 13,578 | 170,602 | False | 2023-01-04T02:35:12Z | 2023-01-05T19:26:00Z | transformers | 0 | 0 | null | feature-extraction | null | [
".gitattributes",
"README.md",
"config.json",
"flax_model.msgpack",
"special_tokens_map.json",
"tokenizer.json",
"tokenizer_config.json",
"vocab.txt"
] | 52effb8ca8159458d5e8a9bf30c6e9a89ad319c8 | [
"transformers",
"jax",
"bert",
"feature-extraction",
"text-embeddings-inference",
"endpoints_compatible",
"deploy:azure",
"region:us"
] | null | {"architectures": ["BertModel"], "model_type": "bert", "tokenizer_config": {"cls_token": "[CLS]", "mask_token": "[MASK]", "pad_token": "[PAD]", "sep_token": "[SEP]", "unk_token": "[UNK]"}} | {
"auto_model": "AutoModel",
"custom_class": null,
"pipeline_tag": "feature-extraction",
"processor": "AutoTokenizer"
} | null | Dense passage retriever (DPR) is a dense retrieval method described in the following paper:
> Vladimir Karpukhin, Barlas Oğuz, Sewon Min, Patrick Lewis, Ledell Wu, Sergey Edunov, Danqi Chen, Wen-tau Yih. [Dense Passage Retrieval for Open-Domain Question Answering](https://www.aclweb.org/anthology/2020.emnlp-main.550/)... | null | null | null | null | null | null | null | [
"BertModel",
"AutoModel",
"bert"
] | [
"feature-extraction"
] | [
"multimodal"
] | [
"text"
] | [
"embeddings"
] |
66f172295e21be28192162f8 | af8f34566d80cb0d | 478e8ebb5343b763 | 99,574 | Unigram | null | true | false | true | true | 8 | Sequence | null | Sequence | [
"Replace",
"Replace"
] | null | [
"ByteFallback",
"Replace",
"Fuse",
"Replace"
] | 583 | llm-jp/llm-jp-3-3.7b-instruct | llm-jp | null | 641 | 2,356,092 | False | 2024-09-23T13:50:33Z | 2024-09-26T18:21:06Z | transformers | 13 | 0 | null | text-generation | {"parameters": {"BF16": 3782913024}, "total": 3782913024} | [
".gitattributes",
"README.md",
"config.json",
"generation_config.json",
"model-00001-of-00002.safetensors",
"model-00002-of-00002.safetensors",
"model.safetensors.index.json",
"special_tokens_map.json",
"tokenizer.json",
"tokenizer_config.json"
] | 1f5a6d0ac8a389d594e9972bec142d3d29d990ed | [
"transformers",
"safetensors",
"llama",
"text-generation",
"conversational",
"en",
"ja",
"license:apache-2.0",
"text-generation-inference",
"deploy:azure",
"region:us"
] | null | {"architectures": ["LlamaForCausalLM"], "model_type": "llama", "tokenizer_config": {"bos_token": "<s>", "chat_template": "{{bos_token}}{% for message in messages %}{% if message['role'] == 'user' %}{{ '\\n\\n### \u6307\u793a:\\n' + message['content'] }}{% elif message['role'] == 'system' %}{{ '\u4ee5\u4e0b\u306f\u3001\... | {
"auto_model": "AutoModelForCausalLM",
"custom_class": null,
"pipeline_tag": "text-generation",
"processor": "AutoTokenizer"
} | {"base_model": null, "datasets": null, "eval_results": null, "language": ["en", "ja"], "library_name": "transformers", "license": "apache-2.0", "license_name": null, "license_link": null, "metrics": null, "model_name": null, "pipeline_tag": "text-generation", "tags": null, "programming_language": ["C", "C++", "C#", "Go... | # llm-jp-3-3.7b-instruct
This repository provides large language models developed by the [Research and Development Center for Large Language Models](https://llmc.nii.ac.jp/) at the [National Institute of Informatics](https://www.nii.ac.jp/en/).
| Model Variants |
| :--- |
| [llm-jp-3-1.8b](https://huggingface.co/ll... | null | [
"apache-2.0"
] | null | [
"en",
"ja"
] | 3,782,913,024 | null | null | [
"AutoModelForCausalLM",
"llama",
"LlamaForCausalLM"
] | [
"text-generation"
] | [
"text"
] | [
"text"
] | [
"text"
] |
62ffeb4239cb37f095cdd862 | 634a9186a6003172 | 5f9f736c7dc6fbfa | 28,996 | WordPiece | null | true | true | true | true | 5 | BertNormalizer | BertPreTokenizer | WordPiece | [
"BertNormalizer"
] | [
"BertPreTokenizer"
] | [
"WordPiece"
] | 8 | nlpie/tiny-biobert | nlpie | null | 1,154 | 121,000 | False | 2022-08-19T19:57:54Z | 2025-05-17T11:32:37Z | transformers | 6 | 0 | null | fill-mask | null | [
".gitattributes",
"README.md",
"config.json",
"pytorch_model.bin",
"special_tokens_map.json",
"tokenizer.json",
"tokenizer_config.json",
"vocab.txt"
] | 7f9c49eeb2440be95cc08abd939a698ff502b0df | [
"transformers",
"pytorch",
"bert",
"fill-mask",
"oxford-legacy",
"license:mit",
"endpoints_compatible",
"deploy:azure",
"region:us"
] | null | {"architectures": ["BertForMaskedLM"], "model_type": "bert", "tokenizer_config": {"unk_token": "[UNK]", "sep_token": "[SEP]", "pad_token": "[PAD]", "cls_token": "[CLS]", "mask_token": "[MASK]"}} | {
"auto_model": "AutoModelForMaskedLM",
"custom_class": null,
"pipeline_tag": "fill-mask",
"processor": "AutoTokenizer"
} | {"base_model": null, "datasets": null, "eval_results": null, "language": null, "library_name": null, "license": "mit", "license_name": null, "license_link": null, "metrics": null, "model_name": null, "pipeline_tag": null, "tags": ["oxford-legacy"], "title": "README", "emoji": "\ud83c\udfc3", "colorFrom": "gray", "color... | # Model Description
TinyBioBERT is a distilled version of the [BioBERT](https://huggingface.co/dmis-lab/biobert-base-cased-v1.2?text=The+goal+of+life+is+%5BMASK%5D.) which is distilled for 100k training steps using a total batch size of 192 on the PubMed dataset.
# Distillation Procedure
This model uses a unique disti... | null | [
"mit"
] | null | null | null | null | null | [
"AutoModelForMaskedLM",
"bert",
"BertForMaskedLM"
] | [
"fill-mask"
] | [
"text"
] | [
"text"
] | [
"logits"
] |
64a0d81cf73fd827fb4a6f26 | 85c4a0556826f65f | 244621b26e3d0cd3 | 256,300 | Unigram | null | true | true | true | true | 304 | Sequence | Metaspace | Metaspace | [
"Replace"
] | [
"Metaspace"
] | [
"Metaspace"
] | 608 | google/umt5-xl | google | null | 8,265 | 177,990 | False | 2023-07-02T01:51:24Z | 2023-07-03T05:37:35Z | transformers | 18 | 0 | null | null | null | [
".gitattributes",
"README.md",
"config.json",
"generation_config.json",
"pytorch_model-00001-of-00002.bin",
"pytorch_model-00002-of-00002.bin",
"pytorch_model.bin.index.json",
"special_tokens_map.json",
"spiece.model",
"tokenizer.json",
"tokenizer_config.json"
] | e02ba7fcf3d6286215043111ee2fc83a9d1f18e2 | [
"transformers",
"pytorch",
"text2text-generation",
"multilingual",
"af",
"am",
"ar",
"az",
"be",
"bg",
"bn",
"ca",
"ceb",
"co",
"cs",
"cy",
"da",
"de",
"el",
"en",
"eo",
"es",
"et",
"eu",
"fa",
"fi",
"fil",
"fr",
"fy",
"ga",
"gd",
"gl",
"gu",
"ha",
... | null | {"architectures": ["UMT5ForConditionalGeneration"], "tokenizer_config": {"bos_token": "<s>", "eos_token": "</s>", "pad_token": "<pad>", "unk_token": "<unk>"}} | {
"auto_model": "AutoModelForSeq2SeqLM",
"custom_class": null,
"pipeline_tag": "text2text-generation",
"processor": null
} | {"base_model": null, "datasets": ["mc4"], "eval_results": null, "language": ["multilingual", "af", "am", "ar", "az", "be", "bg", "bn", "ca", "ceb", "co", "cs", "cy", "da", "de", "el", "en", "eo", "es", "et", "eu", "fa", "fi", "fil", "fr", "fy", "ga", "gd", "gl", "gu", "ha", "haw", "hi", "hmn", "ht", "hu", "hy", "ig", "... | [Google's UMT5](https://github.com/google-research/multilingual-t5)
UMT5 is pretrained on the an updated version of [mC4](https://www.tensorflow.org/datasets/catalog/c4#c4multilingual) corpus, covering 107 languages:
Afrikaans, Albanian, Amharic, Arabic, Armenian, Azerbaijani, Basque, Belarusian, Bengali, Bulgarian, ... | null | [
"apache-2.0"
] | [
"mc4"
] | [
"multilingual",
"af",
"am",
"ar",
"az",
"be",
"bg",
"bn",
"ca",
"ceb",
"co",
"cs",
"cy",
"da",
"de",
"el",
"en",
"eo",
"es",
"et",
"eu",
"fa",
"fi",
"fil",
"fr",
"fy",
"ga",
"gd",
"gl",
"gu",
"ha",
"haw",
"hi",
"hmn",
"ht",
"hu",
"hy",
"ig",
... | null | null | null | [
"AutoModelForSeq2SeqLM",
"UMT5ForConditionalGeneration"
] | [
"text2text-generation"
] | null | null | null |
65a9861639cb91f1fa645b46 | 95e87eaa5f3e292e | 081b543d8f95004e | 32,002 | BPE | 58,980 | true | false | true | true | 5 | Sequence | null | Sequence | [
"Prepend",
"Replace"
] | null | [
"Replace",
"ByteFallback",
"Fuse",
"Strip"
] | 893 | TheBloke/DiscoLM_German_7b_v1-AWQ | TheBloke | {
"models": [
{
"_id": "65a3e4ecea98738768755566",
"id": "DiscoResearch/DiscoLM_German_7b_v1"
}
],
"relation": "quantized"
} | 16 | 117,168 | False | 2024-01-18T20:12:06Z | 2024-01-24T21:30:44Z | transformers | 4 | 0 | [{"name": "DiscoLM_German_7b_v1", "results": []}] | text-generation | {"parameters": {"I32": 6979321856, "F16": 262426624}, "total": 7241748480} | [
".gitattributes",
"README.md",
"added_tokens.json",
"config.json",
"generation_config.json",
"model.safetensors",
"quant_config.json",
"special_tokens_map.json",
"tokenizer.json",
"tokenizer.model",
"tokenizer_config.json"
] | 9dc9590c3dd94578a0e170a09a6bcfd6d59d1d84 | [
"transformers",
"safetensors",
"mistral",
"text-generation",
"Mistral",
"finetune",
"chatml",
"DPO",
"German",
"Deutsch",
"synthetic data",
"conversational",
"de",
"en",
"base_model:DiscoResearch/DiscoLM_German_7b_v1",
"base_model:quantized:DiscoResearch/DiscoLM_German_7b_v1",
"licen... | null | {"architectures": ["MistralForCausalLM"], "model_type": "mistral", "quantization_config": {"bits": 4, "quant_method": "awq"}, "tokenizer_config": {"bos_token": "<s>", "chat_template": "{% if not add_generation_prompt is defined %}{% set add_generation_prompt = false %}{% endif %}{% for message in messages %}{{'<|im_sta... | {
"auto_model": "AutoModelForCausalLM",
"custom_class": null,
"pipeline_tag": "text-generation",
"processor": "AutoTokenizer"
} | {"base_model": "DiscoResearch/DiscoLM_German_7b_v1", "datasets": null, "eval_results": [], "language": ["de", "en"], "library_name": null, "license": "apache-2.0", "license_name": null, "license_link": null, "metrics": null, "model_name": "DiscoLM_German_7b_v1", "pipeline_tag": null, "tags": ["Mistral", "finetune", "ch... | <!-- markdownlint-disable MD041 -->
<!-- header start -->
<!-- 200823 -->
<div style="width: auto; margin-left: auto; margin-right: auto">
<img src="https://i.imgur.com/EBdldam.jpg" alt="TheBlokeAI" style="width: 100%; min-width: 400px; display: block; margin: auto;">
</div>
<div style="display: flex; justify-content:... | null | [
"apache-2.0"
] | null | [
"de",
"en"
] | 7,241,748,480 | null | null | [
"AutoModelForCausalLM",
"mistral",
"MistralForCausalLM"
] | [
"text-generation"
] | [
"text"
] | [
"text"
] | [
"text"
] |
682d12ff64daf8623f1041b7 | 36935258f89e8e9e | 83d37c6e8ee56b77 | 151,665 | BPE | 151,387 | true | true | true | true | 22 | NFC | Sequence | ByteLevel | [
"NFC"
] | [
"Split",
"ByteLevel"
] | [
"ByteLevel"
] | 315 | nvidia/AceReason-Nemotron-14B | nvidia | null | 22,071 | 165,657 | False | 2025-05-20T23:40:47Z | 2025-06-17T23:03:51Z | transformers | 96 | 0 | null | text-generation | {"parameters": {"BF16": 14770033664}, "total": 14770033664} | [
".gitattributes",
"README.md",
"README_EVALUATION.md",
"config.json",
"evaluation.tar.gz",
"fig/main_fig.png",
"generation_config.json",
"model-00001-of-00006.safetensors",
"model-00002-of-00006.safetensors",
"model-00003-of-00006.safetensors",
"model-00004-of-00006.safetensors",
"model-00005-... | b244ed5578b03df25c49c7d1e7bc30fbcf8a63b5 | [
"transformers",
"safetensors",
"qwen2",
"text-generation",
"nvidia",
"reasoning",
"math",
"code",
"reinforcement learning",
"pytorch",
"conversational",
"en",
"arxiv:2505.16400",
"arxiv:2506.13284",
"license:other",
"text-generation-inference",
"endpoints_compatible",
"region:us"
] | null | {"architectures": ["Qwen2ForCausalLM"], "model_type": "qwen2", "tokenizer_config": {"bos_token": "<\uff5cbegin\u2581of\u2581sentence\uff5c>", "chat_template": "{% if not add_generation_prompt is defined %}{% set add_generation_prompt = false %}{% endif %}{% set ns = namespace(is_first=false, is_tool=false, is_output_fi... | {
"auto_model": "AutoModelForCausalLM",
"custom_class": null,
"pipeline_tag": "text-generation",
"processor": "AutoTokenizer"
} | {"base_model": null, "datasets": null, "eval_results": null, "language": ["en"], "library_name": "transformers", "license": "other", "license_name": "nvidia-open-model-license", "license_link": "https://www.nvidia.com/en-us/agreements/enterprise-software/nvidia-open-model-license/", "metrics": null, "model_name": null,... | # AceReason-Nemotron: Advancing Math and Code Reasoning through Reinforcement Learning
<p align="center">
[](https://arxiv.org/abs/2505.16400)
[](https://huggingface.co/data... | null | [
"other",
"nvidia-open-model-license",
"https://www.nvidia.com/en-us/agreements/enterprise-software/nvidia-open-model-license/"
] | null | [
"en"
] | 14,770,033,664 | null | null | [
"AutoModelForCausalLM",
"Qwen2ForCausalLM",
"qwen2"
] | [
"text-generation"
] | [
"text"
] | [
"text"
] | [
"text"
] |
66fccd583eaa88593dad8dc5 | 54895f2d8faef315 | e6ffdc5dd5f1fd86 | 256,000 | BPE | 580,604 | true | true | true | true | 249 | Replace | Split | Sequence | [
"Replace"
] | [
"Split"
] | [
"Replace",
"ByteFallback",
"Fuse"
] | 50 | rinna/gemma-2-baku-2b-it | rinna | {
"models": [
{
"_id": "66962a41534f204a2b9982fd",
"id": "google/gemma-2-2b"
},
{
"_id": "669650bb11dbbf600cf4dcf0",
"id": "google/gemma-2-2b-it"
},
{
"_id": "66fc14a74fb09ea1665b26da",
"id": "rinna/gemma-2-baku-2b"
}
],
"relation": "merge"
} | 33 | 119,216 | False | 2024-10-02T04:34:32Z | 2025-03-23T11:46:57Z | transformers | 30 | 0 | null | text-generation | {"parameters": {"F32": 2614341888}, "total": 2614341888} | [
".gitattributes",
"Notice",
"README.md",
"config.json",
"generation_config.json",
"model-00001-of-00003.safetensors",
"model-00002-of-00003.safetensors",
"model-00003-of-00003.safetensors",
"model.safetensors.index.json",
"rinna.png",
"special_tokens_map.json",
"tokenizer.json",
"tokenizer.m... | b6e5db993e122fe53557f5364a21ef30a9e67258 | [
"transformers",
"safetensors",
"gemma2",
"text-generation",
"conversational",
"ja",
"arxiv:2404.01657",
"arxiv:2310.04799",
"arxiv:2403.07691",
"base_model:google/gemma-2-2b",
"base_model:merge:google/gemma-2-2b",
"base_model:google/gemma-2-2b-it",
"base_model:merge:google/gemma-2-2b-it",
... | null | {"architectures": ["Gemma2ForCausalLM"], "model_type": "gemma2", "tokenizer_config": {"bos_token": "<bos>", "chat_template": "{{ bos_token }}{% if messages[0]['role'] == 'system' %}{{ raise_exception('System role not supported') }}{% endif %}{% for message in messages %}{% if (message['role'] == 'user') != (loop.index0... | {
"auto_model": "AutoModelForCausalLM",
"custom_class": null,
"pipeline_tag": "text-generation",
"processor": "AutoTokenizer"
} | {"base_model": ["google/gemma-2-2b", "google/gemma-2-2b-it", "rinna/gemma-2-baku-2b"], "datasets": null, "eval_results": null, "language": ["ja"], "library_name": "transformers", "license": "gemma", "license_name": null, "license_link": null, "metrics": null, "model_name": null, "pipeline_tag": "text-generation", "tags... | # `Gemma 2 Baku 2B Instruct (rinna/gemma-2-baku-2b-it)`

# Overview
The model is an instruction-tuned variant of [rinna/gemma-2-baku-2b](https://huggingface.co/rinna/gemma-2-baku-2b), utilizing Chat Vector and Odds Ratio Preference Optimization (ORPO) for fine-tuning. It adheres to the gemm... | null | [
"gemma"
] | null | [
"ja"
] | 2,614,341,888 | null | null | [
"AutoModelForCausalLM",
"gemma2",
"Gemma2ForCausalLM"
] | [
"text-generation"
] | [
"text"
] | [
"text"
] | [
"text"
] |
621ffdc136468d709f180506 | a91cd98f80f5bc69 | 3a257f2605ccbaad | 50,267 | BPE | 50,000 | false | true | true | true | 7 | null | ByteLevel | ByteLevel | null | [
"ByteLevel"
] | [
"ByteLevel"
] | 894 | shtoshni/longformer_coreference_joint | shtoshni | null | 6 | 116,986 | False | 2022-03-02T23:29:05Z | 2021-11-12T15:52:54Z | transformers | 4 | 0 | null | feature-extraction | null | [
".gitattributes",
"README.md",
"added_tokens.json",
"config.json",
"merges.txt",
"pytorch_model.bin",
"special_tokens_map.json",
"tokenizer.json",
"tokenizer_config.json",
"vocab.json"
] | c0336f7402fa98e4293f2995df587fb19519e5b0 | [
"transformers",
"pytorch",
"longformer",
"feature-extraction",
"arxiv:2109.09667",
"endpoints_compatible",
"region:us"
] | null | {"architectures": ["LongformerModel"], "model_type": "longformer", "tokenizer_config": {"unk_token": "<unk>", "bos_token": "<s>", "eos_token": "</s>", "sep_token": "</s>", "cls_token": "<s>", "pad_token": "<pad>", "mask_token": "<mask>"}} | {
"auto_model": "AutoModel",
"custom_class": null,
"pipeline_tag": "feature-extraction",
"processor": "AutoTokenizer"
} | null | Longformer-large model finetuned for the coreference resolution task. The model is fine-tuned over a mixture of OntoNotes, LitBank, and PreCo. The model is released as part of [this paper](https://arxiv.org/pdf/2109.09667.pdf). Note that the document encoder is to be used with the rest of the model parameters to perfor... | null | null | null | null | null | null | null | [
"AutoModel",
"longformer",
"LongformerModel"
] | [
"feature-extraction"
] | [
"multimodal"
] | [
"text"
] | [
"embeddings"
] |
65256fc3721b0f15445ceea9 | e23b6bdbe047bb7e | 8bd7d71767538b82 | 32,000 | BPE | 61,249 | true | false | true | true | 3 | Sequence | null | Sequence | [
"Prepend",
"Replace"
] | null | [
"Replace",
"ByteFallback",
"Fuse",
"Strip"
] | 46 | princeton-nlp/Sheared-LLaMA-2.7B | princeton-nlp | null | 894 | 124,848 | False | 2023-10-10T15:37:39Z | 2024-01-23T16:04:17Z | transformers | 61 | 0 | null | text-generation | null | [
".gitattributes",
"README.md",
"config.json",
"generation_config.json",
"pytorch_model-00001-of-00002.bin",
"pytorch_model-00002-of-00002.bin",
"pytorch_model.bin.index.json",
"special_tokens_map.json",
"tokenizer.json",
"tokenizer.model",
"tokenizer_config.json"
] | 2f157a0306b75d37694ae05f6a4067220254d540 | [
"transformers",
"pytorch",
"llama",
"text-generation",
"arxiv:2310.06694",
"license:apache-2.0",
"text-generation-inference",
"endpoints_compatible",
"region:us"
] | null | {"architectures": ["LlamaForCausalLM"], "model_type": "llama", "tokenizer_config": {"bos_token": {"__type": "AddedToken", "content": "<s>", "lstrip": false, "normalized": false, "rstrip": false, "single_word": false}, "eos_token": {"__type": "AddedToken", "content": "</s>", "lstrip": false, "normalized": false, "rstrip... | {
"auto_model": "AutoModelForCausalLM",
"custom_class": null,
"pipeline_tag": "text-generation",
"processor": "AutoTokenizer"
} | {"base_model": null, "datasets": null, "eval_results": null, "language": null, "library_name": null, "license": "apache-2.0", "license_name": null, "license_link": null, "metrics": null, "model_name": null, "pipeline_tag": null, "tags": null} | ---
**Paper**: [https://arxiv.org/pdf/2310.06694.pdf](https://arxiv.org/pdf/2310.06694.pdf)
**Code**: https://github.com/princeton-nlp/LLM-Shearing
**Models**: [Sheared-LLaMA-1.3B](https://huggingface.co/princeton-nlp/Sheared-LLaMA-1.3B), [Sheared-LLaMA-2.7B](https://huggingface.co/princeton-nlp/Sheared-LLaMA-2.7B... | null | [
"apache-2.0"
] | null | null | null | null | null | [
"AutoModelForCausalLM",
"llama",
"LlamaForCausalLM"
] | [
"text-generation"
] | [
"text"
] | [
"text"
] | [
"text"
] |
66120a134a55d90baf95ce41 | 419c74e24d160c7e | cad4902422b140fb | 64,000 | BPE | 110,029 | true | false | true | true | 3 | Sequence | null | Sequence | [
"Prepend",
"Replace"
] | null | [
"Replace",
"ByteFallback",
"Fuse",
"Strip"
] | 895 | wenbopan/Faro-Yi-9B-DPO | wenbopan | null | 8,473 | 158,346 | False | 2024-04-07T02:50:59Z | 2024-04-23T10:23:15Z | transformers | 29 | 0 | null | text-generation | {"parameters": {"F16": 8829407232}, "total": 8829407232} | [
".gitattributes",
"README.md",
"config.json",
"generation_config.json",
"mergekit_config.yml",
"model-00001-of-00002.safetensors",
"model-00002-of-00002.safetensors",
"model.safetensors.index.json",
"special_tokens_map.json",
"tokenizer.json",
"tokenizer.model",
"tokenizer_config.json"
] | 58a4349f57957f527fdde51fd0cfcc558e8854d9 | [
"transformers",
"safetensors",
"llama",
"text-generation",
"conversational",
"en",
"zh",
"dataset:wenbopan/Chinese-dpo-pairs",
"dataset:Intel/orca_dpo_pairs",
"dataset:argilla/ultrafeedback-binarized-preferences-cleaned",
"dataset:jondurbin/truthy-dpo-v0.1",
"arxiv:2303.08774",
"license:mit"... | null | {"architectures": ["LlamaForCausalLM"], "model_type": "llama", "tokenizer_config": {"bos_token": "<|startoftext|>", "chat_template": "{% if not add_generation_prompt is defined %}{% set add_generation_prompt = false %}{% endif %}{% for message in messages %}{{'<|im_start|>' + message['role'] + '\n' + message['content']... | {
"auto_model": "AutoModelForCausalLM",
"custom_class": null,
"pipeline_tag": "text-generation",
"processor": "AutoTokenizer"
} | {"base_model": null, "datasets": ["wenbopan/Chinese-dpo-pairs", "Intel/orca_dpo_pairs", "argilla/ultrafeedback-binarized-preferences-cleaned", "jondurbin/truthy-dpo-v0.1"], "eval_results": null, "language": ["en", "zh"], "library_name": null, "license": "mit", "license_name": null, "license_link": null, "metrics": null... | # Faro-Yi-9B-DPO
This is the DPO version of [wenbopan/Faro-Yi-9B](https://huggingface.co/wenbopan/Faro-Yi-9B). Compared to Faro-Yi-9B and [Yi-9B-200K](https://huggingface.co/01-ai/Yi-9B-200K), the DPO model excels at many tasks, surpassing the original Yi-9B-200K by a large margin. On the [Open LLM Leaderboard](https:... | null | [
"mit"
] | [
"wenbopan/Chinese-dpo-pairs",
"Intel/orca_dpo_pairs",
"argilla/ultrafeedback-binarized-preferences-cleaned",
"jondurbin/truthy-dpo-v0.1"
] | [
"en",
"zh"
] | 8,829,407,232 | null | null | [
"AutoModelForCausalLM",
"llama",
"LlamaForCausalLM"
] | [
"text-generation"
] | [
"text"
] | [
"text"
] | [
"text"
] |
66324f0b82a4b66b9eaca6a4 | 6e6a83dc4b556c95 | a1f1bd381dcb9329 | 128,256 | BPE | 280,147 | false | true | true | true | 256 | null | Sequence | ByteLevel | null | [
"Split",
"ByteLevel"
] | [
"ByteLevel"
] | 111 | mlabonne/ChimeraLlama-3-8B-v3 | mlabonne | {
"models": [
{
"_id": "662fda402f9858ac470512ae",
"id": "Danielbrdz/Barcenas-Llama3-8b-ORPO"
},
{
"_id": "6628c7b81cdb317ebaa994d5",
"id": "MaziyarPanahi/Llama-3-8B-Instruct-DPO-v0.3"
},
{
"_id": "6621509c486de1d8db296970",
"id": "NousResearch/Meta-Llama-3-8B-I... | 7,894 | 154,788 | False | 2024-05-01T14:17:47Z | 2024-09-17T10:16:45Z | transformers | 15 | 0 | [{"name": "ChimeraLlama-3-8B-v3", "results": [{"task": {"type": "text-generation", "name": "Text Generation"}, "dataset": {"name": "IFEval (0-Shot)", "type": "HuggingFaceH4/ifeval", "args": {"num_few_shot": 0}}, "metrics": [{"type": "inst_level_strict_acc and prompt_level_strict_acc", "value": 44.08, "name": "strict ac... | text-generation | {"parameters": {"F16": 8030261248}, "total": 8030261248} | [
".gitattributes",
"README.md",
"config.json",
"mergekit_config.yml",
"model-00001-of-00002.safetensors",
"model-00002-of-00002.safetensors",
"model.safetensors.index.json",
"special_tokens_map.json",
"tokenizer.json",
"tokenizer_config.json"
] | ff1e5ff9844908d3f151e5f01eec2e804d7fa2ac | [
"transformers",
"safetensors",
"llama",
"text-generation",
"merge",
"mergekit",
"lazymergekit",
"base_model:Danielbrdz/Barcenas-Llama3-8b-ORPO",
"base_model:merge:Danielbrdz/Barcenas-Llama3-8b-ORPO",
"base_model:MaziyarPanahi/Llama-3-8B-Instruct-DPO-v0.3",
"base_model:merge:MaziyarPanahi/Llama-3... | null | {"architectures": ["LlamaForCausalLM"], "model_type": "llama", "tokenizer_config": {"bos_token": "<|begin_of_text|>", "eos_token": "<|end_of_text|>"}} | {
"auto_model": "AutoModelForCausalLM",
"custom_class": null,
"pipeline_tag": "text-generation",
"processor": "AutoTokenizer"
} | {"base_model": ["NousResearch/Meta-Llama-3-8B-Instruct", "mlabonne/OrpoLlama-3-8B", "cognitivecomputations/dolphin-2.9-llama3-8b", "Danielbrdz/Barcenas-Llama3-8b-ORPO", "VAGOsolutions/Llama-3-SauerkrautLM-8b-Instruct", "vicgalle/Configurable-Llama-3-8B-v0.3", "MaziyarPanahi/Llama-3-8B-Instruct-DPO-v0.3"], "license": "o... | # ChimeraLlama-3-8B-v3
ChimeraLlama-3-8B-v3 is a merge of the following models using [LazyMergekit](https://colab.research.google.com/drive/1obulZ1ROXHjYLn6PPZJwRR6GzgQogxxb?usp=sharing):
* [NousResearch/Meta-Llama-3-8B-Instruct](https://huggingface.co/NousResearch/Meta-Llama-3-8B-Instruct)
* [mlabonne/OrpoLlama-3-8B]... | null | [
"other"
] | null | null | 8,030,261,248 | null | null | [
"AutoModelForCausalLM",
"llama",
"LlamaForCausalLM"
] | [
"text-generation"
] | [
"text"
] | [
"text"
] | [
"text"
] |
6661ec57d49b75e21940f121 | 34093184d10f76a9 | 35b001f3a491f9f9 | 151,646 | BPE | 151,387 | true | true | true | true | 3 | NFC | Sequence | ByteLevel | [
"NFC"
] | [
"Split",
"ByteLevel"
] | [
"ByteLevel"
] | 53 | unsloth/Qwen2-7B-Instruct-bnb-4bit | unsloth | null | 2,899 | 129,392 | False | 2024-06-06T17:05:27Z | 2024-09-03T03:45:23Z | transformers | 7 | 0 | null | text-generation | {"parameters": {"F32": 451584, "BF16": 1090328064, "U8": 6729271302}, "total": 7820050950} | [
".gitattributes",
"README.md",
"added_tokens.json",
"config.json",
"generation_config.json",
"merges.txt",
"model.safetensors",
"special_tokens_map.json",
"tokenizer.json",
"tokenizer_config.json",
"vocab.json"
] | 26ac6deb2f1f4929ecc7ece49178be31aa1e0755 | [
"transformers",
"safetensors",
"qwen2",
"text-generation",
"unsloth",
"conversational",
"en",
"license:apache-2.0",
"text-generation-inference",
"endpoints_compatible",
"4-bit",
"bitsandbytes",
"region:us"
] | null | {"architectures": ["Qwen2ForCausalLM"], "model_type": "qwen2", "quantization_config": {"load_in_4bit": true, "load_in_8bit": false, "quant_method": "bitsandbytes"}, "tokenizer_config": {"bos_token": null, "chat_template": "{% for message in messages %}{% if loop.first and messages[0]['role'] != 'system' %}{{ '<|im_star... | {
"auto_model": "AutoModelForCausalLM",
"custom_class": null,
"pipeline_tag": "text-generation",
"processor": "AutoTokenizer"
} | {"base_model": null, "datasets": null, "eval_results": null, "language": ["en"], "library_name": "transformers", "license": "apache-2.0", "license_name": null, "license_link": null, "metrics": null, "model_name": null, "pipeline_tag": null, "tags": ["unsloth", "transformers", "qwen2"]} | # Finetune Mistral, Gemma, Llama 2-5x faster with 70% less memory via Unsloth!
We have a Google Colab Tesla T4 notebook for Qwen2 7b here: https://colab.research.google.com/drive/1mvwsIQWDs2EdZxZQF9pRGnnOvE86MVvR?usp=sharing
And a Colab notebook for [Qwen2 0.5b](https://colab.research.google.com/drive/1-7tjDdMAyeCueyL... | null | [
"apache-2.0"
] | null | [
"en"
] | 7,820,050,950 | null | null | [
"AutoModelForCausalLM",
"Qwen2ForCausalLM",
"qwen2"
] | [
"text-generation"
] | [
"text"
] | [
"text"
] | [
"text"
] |
6632124ce25753ed523697e4 | 803e3c8528c55bf1 | a1f1bd381dcb9329 | 128,256 | BPE | 280,147 | false | true | true | true | 256 | null | Sequence | ByteLevel | null | [
"Split",
"ByteLevel"
] | [
"ByteLevel"
] | 352 | MaziyarPanahi/Llama-3-8B-Instruct-v0.8 | MaziyarPanahi | {
"models": [
{
"_id": "66320d646aee5b05e4b055f3",
"id": "MaziyarPanahi/Llama-3-8B-Instruct-v0.4"
}
],
"relation": "finetune"
} | 8,446 | 157,998 | False | 2024-05-01T09:58:36Z | 2024-07-04T13:17:03Z | transformers | 8 | 0 | [{"name": "Llama-3-8B-Instruct-v0.8", "results": [{"task": {"type": "text-generation", "name": "Text Generation"}, "dataset": {"name": "AI2 Reasoning Challenge (25-Shot)", "type": "ai2_arc", "config": "ARC-Challenge", "split": "test", "args": {"num_few_shot": 25}}, "metrics": [{"type": "acc_norm", "value": 71.67, "name... | text-generation | {"parameters": {"BF16": 8030261248}, "total": 8030261248} | [
".gitattributes",
"README.md",
"config.json",
"generation_config.json",
"llama-3-merges.webp",
"model-00001-of-00002.safetensors",
"model-00002-of-00002.safetensors",
"model.safetensors.index.json",
"special_tokens_map.json",
"tokenizer.json",
"tokenizer_config.json"
] | bd80951b7ae97f633ed48b80334af8df96b49f36 | [
"transformers",
"safetensors",
"llama",
"text-generation",
"axolotl",
"finetune",
"facebook",
"meta",
"pytorch",
"llama-3",
"conversational",
"en",
"base_model:MaziyarPanahi/Llama-3-8B-Instruct-v0.4",
"base_model:finetune:MaziyarPanahi/Llama-3-8B-Instruct-v0.4",
"license:other",
"model... | null | {"architectures": ["LlamaForCausalLM"], "model_type": "llama", "tokenizer_config": {"bos_token": "<|begin_of_text|>", "chat_template": "{% set loop_messages = messages %}{% for message in loop_messages %}{% set content = '<|start_header_id|>' + message['role'] + '<|end_header_id|>\n\n'+ message['content'] | trim + '<|e... | {
"auto_model": "AutoModelForCausalLM",
"custom_class": null,
"pipeline_tag": "text-generation",
"processor": "AutoTokenizer"
} | {"base_model": "MaziyarPanahi/Llama-3-8B-Instruct-v0.4", "language": ["en"], "library_name": "transformers", "license": "other", "license_name": "llama3", "license_link": "LICENSE", "pipeline_tag": "text-generation", "tags": ["axolotl", "finetune", "facebook", "meta", "pytorch", "llama", "llama-3"], "inference": false,... | <img src="./llama-3-merges.webp" alt="Llama-3 DPO Logo" width="500" style="margin-left:'auto' margin-right:'auto' display:'block'"/>
# Llama-3-8B-Instruct-v0.8
This model was developed based on `MaziyarPanahi/Llama-3-8B-Instruct-v0.4` model.
# ⚡ Quantized GGUF
All GGUF models are available here: [MaziyarPanahi/Lla... | null | [
"other",
"llama3",
"LICENSE"
] | null | [
"en"
] | 8,030,261,248 | null | null | [
"AutoModelForCausalLM",
"llama",
"LlamaForCausalLM"
] | [
"text-generation"
] | [
"text"
] | [
"text"
] | [
"text"
] |
66700d63cb82a3b014f61391 | 88cd37e502d27a0a | 0e7bc0977f200d1c | 32,000 | BPE | 58,980 | true | false | true | true | 3 | Sequence | null | Sequence | [
"Prepend",
"Replace"
] | null | [
"Replace",
"ByteFallback",
"Fuse",
"Strip"
] | 88 | TitanML/tiny-mixtral-AWQ-4bit | TitanML | null | 69 | 121,167 | False | 2024-06-17T10:18:11Z | 2024-06-17T10:18:20Z | transformers | 0 | 0 | null | text-generation | {"parameters": {"I32": 181403648, "F16": 65557504}, "total": 246961152} | [
".gitattributes",
"config.json",
"generation_config.json",
"model.safetensors",
"special_tokens_map.json",
"tokenizer.json",
"tokenizer.model",
"tokenizer_config.json"
] | d1881715f58132f80fc42cd44469e3054411bde6 | [
"transformers",
"safetensors",
"mixtral",
"text-generation",
"text-generation-inference",
"endpoints_compatible",
"4-bit",
"awq",
"deploy:azure",
"region:us"
] | null | {"architectures": ["MixtralForCausalLM"], "model_type": "mixtral", "quantization_config": {"bits": 4, "quant_method": "awq"}, "tokenizer_config": {"bos_token": "<s>", "eos_token": "</s>", "pad_token": null, "unk_token": "<unk>", "use_default_system_prompt": false}} | {
"auto_model": "AutoModelForCausalLM",
"custom_class": null,
"pipeline_tag": "text-generation",
"processor": "AutoTokenizer"
} | null | null | null | null | null | null | 246,961,152 | null | null | [
"mixtral",
"MixtralForCausalLM",
"AutoModelForCausalLM"
] | [
"text-generation"
] | [
"text"
] | [
"text"
] | [
"text"
] |
67aa65296712dde0542317e2 | 5b8a6156b5b6e013 | 535fa14da0af647c | 30,522 | WordPiece | null | true | true | true | true | 5 | BertNormalizer | BertPreTokenizer | WordPiece | [
"BertNormalizer"
] | [
"BertPreTokenizer"
] | [
"WordPiece"
] | 37 | WebOrganizer/FormatClassifier-NoURL | WebOrganizer | {
"models": [
{
"_id": "66232e36df8e46344246d0f6",
"id": "Alibaba-NLP/gte-base-en-v1.5"
}
],
"relation": "finetune"
} | 22,266 | 151,110 | False | 2025-02-10T20:44:25Z | 2025-02-19T17:22:28Z | transformers | 7 | 0 | null | text-classification | {"parameters": {"F32": 137385240}, "total": 137385240} | [
".gitattributes",
"README.md",
"config.json",
"configuration.py",
"model.safetensors",
"modeling.py",
"special_tokens_map.json",
"tokenizer.json",
"tokenizer_config.json",
"vocab.txt"
] | 74d5efb924e1843e84b28b59c26f6ceaa873dc16 | [
"transformers",
"safetensors",
"new",
"text-classification",
"custom_code",
"dataset:WebOrganizer/FormatAnnotations-Llama-3.1-8B",
"dataset:WebOrganizer/FormatAnnotations-Llama-3.1-405B-FP8",
"arxiv:2502.10341",
"base_model:Alibaba-NLP/gte-base-en-v1.5",
"base_model:finetune:Alibaba-NLP/gte-base-e... | null | {"architectures": ["NewForSequenceClassification"], "auto_map": {"AutoConfig": "configuration.NewConfig", "AutoModel": "Alibaba-NLP/new-impl--modeling.NewModel", "AutoModelForMaskedLM": "Alibaba-NLP/new-impl--modeling.NewForMaskedLM", "AutoModelForMultipleChoice": "Alibaba-NLP/new-impl--modeling.NewForMultipleChoice", ... | {
"auto_model": "AutoModelForSequenceClassification",
"custom_class": "modeling.NewForSequenceClassification",
"pipeline_tag": "text-classification",
"processor": null
} | {"base_model": ["Alibaba-NLP/gte-base-en-v1.5"], "datasets": ["WebOrganizer/FormatAnnotations-Llama-3.1-8B", "WebOrganizer/FormatAnnotations-Llama-3.1-405B-FP8"], "eval_results": null, "language": null, "library_name": "transformers", "license": null, "license_name": null, "license_link": null, "metrics": null, "model_... | # WebOrganizer/FormatClassifier-NoURL
[[Paper](https://arxiv.org/abs/2502.10341)] [[Website](https://weborganizer.allenai.org)] [[GitHub](https://github.com/CodeCreator/WebOrganizer)]
The FormatClassifier-NoURL organizes web content into 24 categories based on the text contents of web pages (without using URL informa... | null | null | [
"WebOrganizer/FormatAnnotations-Llama-3.1-8B",
"WebOrganizer/FormatAnnotations-Llama-3.1-405B-FP8"
] | null | 137,385,240 | null | null | [
"new",
"NewForSequenceClassification",
"AutoModelForSequenceClassification",
"modeling.NewForSequenceClassification"
] | [
"text-classification"
] | [
"text"
] | [
"text"
] | [
"logits"
] |
626fcc9f533b7b85cfe5eac4 | 901b39ae63515521 | ceb5045914a9e9c7 | 40,000 | BPE | 39,739 | false | true | true | true | 5 | null | ByteLevel | ByteLevel | null | [
"ByteLevel"
] | [
"ByteLevel"
] | 896 | oliverguhr/fullstop-dutch-sonar-punctuation-prediction | oliverguhr | null | 908 | 121,549 | False | 2022-05-02T12:20:47Z | 2023-03-21T10:26:23Z | transformers | 6 | 0 | null | token-classification | {"parameters": {"I64": 514, "F32": 116176134}, "total": 116176648} | [
".gitattributes",
"README.md",
"config.json",
"merges.txt",
"model.safetensors",
"pytorch_model.bin",
"special_tokens_map.json",
"tokenizer.json",
"tokenizer_config.json",
"training_args.bin",
"vocab.json"
] | 58e4785c2f2c9b79d5b79761e0e7d2a9628328d5 | [
"transformers",
"pytorch",
"safetensors",
"roberta",
"token-classification",
"punctuation prediction",
"punctuation",
"nl",
"dataset:sonar",
"arxiv:2301.03319",
"license:mit",
"endpoints_compatible",
"region:us"
] | null | {"architectures": ["RobertaForTokenClassification"], "model_type": "roberta", "tokenizer_config": {"bos_token": {"content": "<s>", "single_word": false, "lstrip": false, "rstrip": false, "normalized": true, "__type": "AddedToken"}, "eos_token": {"content": "</s>", "single_word": false, "lstrip": false, "rstrip": false,... | {
"auto_model": "AutoModelForTokenClassification",
"custom_class": null,
"pipeline_tag": "token-classification",
"processor": "AutoTokenizer"
} | {"base_model": null, "datasets": "sonar", "eval_results": null, "language": ["nl"], "library_name": null, "license": "mit", "license_name": null, "license_link": null, "metrics": ["f1"], "model_name": null, "pipeline_tag": null, "tags": ["punctuation prediction", "punctuation"], "widget": [{"text": "Ondanks dat het nu ... | This model predicts the punctuation of Dutch texts. We developed it to restore the punctuation of transcribed spoken language.
This model was trained on the [SoNaR Dataset](http://hdl.handle.net/10032/tm-a2-h5).
The model restores the following punctuation markers: **"." "," "?" "-" ":"**
## Sample Code
We provide a... | null | [
"mit"
] | [
"sonar"
] | [
"nl"
] | 116,176,648 | null | [
"f1"
] | [
"roberta",
"AutoModelForTokenClassification",
"RobertaForTokenClassification"
] | [
"token-classification"
] | [
"text"
] | [
"text"
] | [
"logits"
] |
67748e7ebd6069b51ca73df4 | 5499fef3506cd876 | cf1efbe71ef28fc9 | 50,368 | BPE | 50,009 | true | true | true | true | 116 | NFC | ByteLevel | ByteLevel | [
"NFC"
] | [
"ByteLevel"
] | [
"ByteLevel"
] | 48 | clapAI/modernBERT-large-multilingual-sentiment | clapAI | {
"models": [
{
"_id": "6759b5e9a9cfaefaabc087f1",
"id": "answerdotai/ModernBERT-large"
}
],
"relation": "finetune"
} | 353 | 118,741 | False | 2025-01-01T00:38:22Z | 2025-01-08T01:57:20Z | transformers | 10 | 0 | [{"name": "clapAI/modernBERT-large-multilingual-sentiment", "results": []}] | text-classification | {"parameters": {"F16": 395834371}, "total": 395834371} | [
".gitattributes",
"README.md",
"all_results.json",
"config.json",
"eval_results.json",
"model.safetensors",
"runs/Jan01_00-30-37_hn-fornix-testing-gpu-platform-2/events.out.tfevents.1735691854.hn-fornix-testing-gpu-platform-2.1042034.0",
"runs/Jan01_01-06-27_hn-fornix-testing-gpu-platform-2/events.out... | 8dd735339a1eeca6583884cfd7357dae8b39c0d7 | [
"transformers",
"tensorboard",
"safetensors",
"modernbert",
"text-classification",
"sentiment",
"multilingual",
"sentiment-analysis",
"product-reviews",
"place-reviews",
"en",
"zh",
"vi",
"ko",
"ja",
"ar",
"de",
"es",
"fr",
"hi",
"id",
"it",
"ms",
"pt",
"ru",
"tr",
... | null | {"architectures": ["ModernBertForSequenceClassification"], "model_type": "modernbert", "tokenizer_config": {"cls_token": "[CLS]", "mask_token": "[MASK]", "pad_token": "[PAD]", "sep_token": "[SEP]", "unk_token": "[UNK]"}} | {
"auto_model": "AutoModelForSequenceClassification",
"custom_class": null,
"pipeline_tag": "text-classification",
"processor": "AutoTokenizer"
} | {"base_model": "answerdotai/ModernBERT-large", "datasets": ["clapAI/MultiLingualSentiment"], "eval_results": [], "language": ["en", "zh", "vi", "ko", "ja", "ar", "de", "es", "fr", "hi", "id", "it", "ms", "pt", "ru", "tr"], "library_name": "transformers", "license": "apache-2.0", "license_name": null, "license_link": nu... | <!-- This model card has been generated automatically according to the information the Trainer had access to. You
should probably proofread and complete it, then remove this comment. -->
# clapAI/modernBERT-base-multilingual-sentiment
## Introduction
**modernBERT-base-multilingual-sentiment** is a multilingual senti... | null | [
"apache-2.0"
] | [
"clapAI/MultiLingualSentiment"
] | [
"en",
"zh",
"vi",
"ko",
"ja",
"ar",
"de",
"es",
"fr",
"hi",
"id",
"it",
"ms",
"pt",
"ru",
"tr"
] | 395,834,371 | null | [
"f1",
"precision",
"recall"
] | [
"ModernBertForSequenceClassification",
"modernbert",
"AutoModelForSequenceClassification"
] | [
"text-classification"
] | [
"text"
] | [
"text"
] | [
"logits"
] |
652cf112b118f26df7751f16 | 88cd37e502d27a0a | 0e7bc0977f200d1c | 32,000 | BPE | 58,980 | true | false | true | true | 3 | Sequence | null | Sequence | [
"Prepend",
"Replace"
] | null | [
"Replace",
"ByteFallback",
"Fuse",
"Strip"
] | 88 | stabilityai/japanese-stablelm-base-gamma-7b | stabilityai | null | 793 | 121,308 | False | 2023-10-16T08:15:14Z | 2024-01-25T08:05:12Z | transformers | 25 | 0 | null | text-generation | {"parameters": {"BF16": 7241732096}, "total": 7241732096} | [
".gitattributes",
"README.md",
"config.json",
"generation_config.json",
"model-00001-of-00002.safetensors",
"model-00002-of-00002.safetensors",
"model.safetensors.index.json",
"special_tokens_map.json",
"tokenizer.json",
"tokenizer.model",
"tokenizer_config.json"
] | ffc474da0e4f5dbb9db54e96a94a22c081fc7fbf | [
"transformers",
"safetensors",
"mistral",
"text-generation",
"japanese-stablelm",
"causal-lm",
"ja",
"dataset:wikipedia",
"dataset:mc4",
"dataset:cc100",
"dataset:oscar-corpus/OSCAR-2301",
"dataset:oscar-corpus/OSCAR-2201",
"dataset:cerebras/SlimPajama-627B",
"arxiv:2310.06825",
"license... | null | {"architectures": ["MistralForCausalLM"], "model_type": "mistral", "tokenizer_config": {"bos_token": "<s>", "eos_token": "</s>", "pad_token": null, "unk_token": "<unk>", "use_default_system_prompt": true}} | {
"auto_model": "AutoModelForCausalLM",
"custom_class": null,
"pipeline_tag": "text-generation",
"processor": "AutoTokenizer"
} | {"base_model": null, "datasets": ["wikipedia", "mc4", "cc100", "oscar-corpus/OSCAR-2301", "oscar-corpus/OSCAR-2201", "cerebras/SlimPajama-627B"], "eval_results": null, "language": ["ja"], "library_name": null, "license": "apache-2.0", "license_name": null, "license_link": null, "metrics": null, "model_name": null, "pip... | # Japanese Stable LM Base Gamma 7B
## Model Description
This is a 7B-parameter decoder-only language model with a focus on maximizing Japanese language modeling performance and Japanese downstream task performance.
We conducted continued pretraining using Japanese data on the English language model, [Mistral-7B-v0.1]... | null | [
"apache-2.0"
] | [
"wikipedia",
"mc4",
"cc100",
"oscar-corpus/OSCAR-2301",
"oscar-corpus/OSCAR-2201",
"cerebras/SlimPajama-627B"
] | [
"ja"
] | 7,241,732,096 | null | null | [
"AutoModelForCausalLM",
"mistral",
"MistralForCausalLM"
] | [
"text-generation"
] | [
"text"
] | [
"text"
] | [
"text"
] |
681f5a8d22821bfa68ddd2b9 | 7428ef9ae5ef868f | 67da9c236fa81925 | 151,669 | BPE | 151,387 | true | true | true | true | 26 | NFC | Sequence | ByteLevel | [
"NFC"
] | [
"Split",
"ByteLevel"
] | [
"ByteLevel"
] | 47 | Qwen/Qwen3-235B-A22B-GPTQ-Int4 | Qwen | {
"models": [
{
"_id": "680daa4ac41c05ba341b67d1",
"id": "Qwen/Qwen3-235B-A22B"
}
],
"relation": "quantized"
} | 7,862 | 291,398 | False | 2025-05-10T13:54:21Z | 2025-05-21T06:09:15Z | transformers | 27 | 0 | null | text-generation | {"parameters": {"F16": 1294740992, "I32": 233798893568}, "total": 235093634560} | [
".gitattributes",
"LICENSE",
"README.md",
"config.json",
"generation_config.json",
"merges.txt",
"model-00001-of-00032.safetensors",
"model-00002-of-00032.safetensors",
"model-00003-of-00032.safetensors",
"model-00004-of-00032.safetensors",
"model-00005-of-00032.safetensors",
"model-00006-of-0... | dff138951f3898772fc0d795a4b5b30f417577f4 | [
"transformers",
"safetensors",
"qwen3_moe",
"text-generation",
"conversational",
"arxiv:2309.00071",
"arxiv:2505.09388",
"base_model:Qwen/Qwen3-235B-A22B",
"base_model:quantized:Qwen/Qwen3-235B-A22B",
"license:apache-2.0",
"endpoints_compatible",
"4-bit",
"gptq",
"region:us"
] | null | {"architectures": ["Qwen3MoeForCausalLM"], "model_type": "qwen3_moe", "quantization_config": {"bits": 4, "quant_method": "gptq"}, "tokenizer_config": {"bos_token": null, "chat_template": "{%- if tools %}\n {{- '<|im_start|>system\\n' }}\n {%- if messages[0].role == 'system' %}\n {{- messages[0].content + '... | {
"auto_model": "AutoModelForCausalLM",
"custom_class": null,
"pipeline_tag": "text-generation",
"processor": "AutoTokenizer"
} | {"base_model": "Qwen/Qwen3-235B-A22B", "datasets": null, "eval_results": null, "language": null, "library_name": "transformers", "license": "apache-2.0", "license_name": null, "license_link": "https://huggingface.co/Qwen/Qwen3-235B-A22B/blob/main/LICENSE", "metrics": null, "model_name": null, "pipeline_tag": "text-gene... | # Qwen3-235B-A22B-GPTQ-Int4
<a href="https://chat.qwen.ai/" target="_blank" style="margin: 2px;">
<img alt="Chat" src="https://img.shields.io/badge/%F0%9F%92%9C%EF%B8%8F%20Qwen%20Chat%20-536af5" style="display: inline-block; vertical-align: middle;"/>
</a>
## Qwen3 Highlights
Qwen3 is the latest generation of lar... | null | [
"apache-2.0",
"https://huggingface.co/Qwen/Qwen3-235B-A22B/blob/main/LICENSE"
] | null | null | 235,093,634,560 | null | null | [
"qwen3_moe",
"AutoModelForCausalLM",
"Qwen3MoeForCausalLM"
] | [
"text-generation"
] | [
"text"
] | [
"text"
] | [
"text"
] |
67d6eb2551343ff3a8ba6d69 | 313b7de044596037 | d289050277f320be | 151,665 | BPE | 151,387 | true | true | true | true | 22 | NFC | Sequence | ByteLevel | [
"NFC"
] | [
"Split",
"ByteLevel"
] | [
"ByteLevel"
] | 897 | manycore-research/SpatialLM-Qwen-0.5B | manycore-research | {
"models": [
{
"_id": "66e81c0ecfd2f50991047e92",
"id": "Qwen/Qwen2.5-0.5B-Instruct"
}
],
"relation": "finetune"
} | 181 | 116,670 | False | 2025-03-16T15:15:49Z | 2025-03-21T05:40:21Z | transformers | 92 | 0 | null | text-generation | {"parameters": {"F32": 504983232}, "total": 504983232} | [
".gitattributes",
"README.md",
"added_tokens.json",
"config.json",
"generation_config.json",
"merges.txt",
"model.safetensors",
"special_tokens_map.json",
"tokenizer.json",
"tokenizer_config.json",
"vocab.json"
] | 71278d39f68d5a9241e0f9ff5d61bd7fb3a583af | [
"transformers",
"safetensors",
"spatiallm_qwen",
"text-generation",
"conversational",
"base_model:Qwen/Qwen2.5-0.5B-Instruct",
"base_model:finetune:Qwen/Qwen2.5-0.5B-Instruct",
"license:cc-by-nc-4.0",
"endpoints_compatible",
"region:us"
] | null | {"architectures": ["SpatialLMQwenForCausalLM"], "model_type": "spatiallm_qwen", "tokenizer_config": {"bos_token": null, "chat_template": "{%- if tools %}\n {{- '<|im_start|>system\\n' }}\n {%- if messages[0]['role'] == 'system' %}\n {{- messages[0]['content'] }}\n {%- else %}\n {{- 'You are Qwen,... | {
"auto_model": "AutoModelForCausalLM",
"custom_class": null,
"pipeline_tag": "text-generation",
"processor": null
} | {"base_model": ["Qwen/Qwen2.5-0.5B-Instruct"], "datasets": null, "eval_results": null, "language": null, "library_name": "transformers", "license": "cc-by-nc-4.0", "license_name": null, "license_link": null, "metrics": null, "model_name": null, "pipeline_tag": null, "tags": null} | # SpatialLM-Qwen-0.5B
<!-- markdownlint-disable first-line-h1 -->
<!-- markdownlint-disable html -->
<!-- markdownlint-disable no-duplicate-header -->
<div align="center">
<picture>
<source srcset="https://cdn-uploads.huggingface.co/production/uploads/63efbb1efc92a63ac81126d0/_dK14CT3do8rBG3QrHUjN.png" media="(... | null | [
"cc-by-nc-4.0"
] | null | null | 504,983,232 | null | null | [
"SpatialLMQwenForCausalLM",
"AutoModelForCausalLM",
"spatiallm_qwen"
] | [
"text-generation"
] | [
"text"
] | [
"text"
] | [
"text"
] |
67f3bd8e0dad3893b2eee15e | b38a3bb0e1e173c8 | 302e80cadffaf147 | 151,343 | BPE | 318,088 | false | true | true | true | 14 | null | Sequence | ByteLevel | null | [
"Split",
"ByteLevel"
] | [
"ByteLevel"
] | 358 | zai-org/GLM-4-9B-0414 | zai-org | null | 17,626 | 187,084 | False | 2025-04-07T11:57:02Z | 2025-04-14T15:40:17Z | transformers | 100 | 0 | null | text-generation | {"parameters": {"BF16": 9400279040}, "total": 9400279040} | [
".gitattributes",
"LICENSE",
"README.md",
"chat_template.jinja",
"config.json",
"generation_config.json",
"model-00001-of-00004.safetensors",
"model-00002-of-00004.safetensors",
"model-00003-of-00004.safetensors",
"model-00004-of-00004.safetensors",
"model.safetensors.index.json",
"special_tok... | 645b8482494e31b6b752272bf7f7f273ef0f3caf | [
"transformers",
"safetensors",
"glm4",
"text-generation",
"conversational",
"zh",
"en",
"license:mit",
"endpoints_compatible",
"region:us"
] | null | {"architectures": ["Glm4ForCausalLM"], "model_type": "glm4", "tokenizer_config": {"chat_template": "[gMASK]<sop>{%- if tools -%}<|system|>\n# \u53ef\u7528\u5de5\u5177\n{% for tool in tools %}{%- set function = tool.function if tool.get(\"function\") else tool %}\n\n## {{ function.name }}\n\n{{ function | tojson(indent=... | {
"auto_model": "AutoModelForCausalLM",
"custom_class": null,
"pipeline_tag": "text-generation",
"processor": "AutoTokenizer"
} | {"base_model": null, "datasets": null, "eval_results": null, "language": ["zh", "en"], "library_name": "transformers", "license": "mit", "license_name": null, "license_link": null, "metrics": null, "model_name": null, "pipeline_tag": "text-generation", "tags": null} | null | null | [
"mit"
] | null | [
"zh",
"en"
] | 9,400,279,040 | null | null | [
"AutoModelForCausalLM",
"glm4",
"Glm4ForCausalLM"
] | [
"text-generation"
] | [
"text"
] | [
"text"
] | [
"text"
] |
621ffdc136468d709f1814a0 | 0202b54b045bdf64 | a00df6594a092a68 | 66,119 | BPE | 63,978 | false | true | true | true | 1 | null | WhitespaceSplit | BPEDecoder | null | [
"WhitespaceSplit"
] | [
"BPEDecoder"
] | 99 | vinai/bartpho-word | vinai | null | 2,370 | 127,733 | False | 2022-03-02T23:29:05Z | 2024-08-20T03:57:29Z | transformers | 6 | 0 | null | feature-extraction | null | [
".gitattributes",
"README.md",
"__init__.py",
"bpe.codes",
"config.json",
"pytorch_model.bin",
"tf_model.h5",
"tokenization_phobert.py",
"tokenization_phobert_fast.py",
"tokenizer.json",
"vocab.txt"
] | bee56ed0f2723cf4510ad3775cf4c5a38eb5e6fa | [
"transformers",
"pytorch",
"tf",
"mbart",
"feature-extraction",
"arxiv:2109.09701",
"license:mit",
"endpoints_compatible",
"deploy:azure",
"region:us"
] | null | {"architectures": ["MBartModel"], "model_type": "mbart"} | {
"auto_model": "AutoModel",
"custom_class": null,
"pipeline_tag": "feature-extraction",
"processor": "AutoTokenizer"
} | {"base_model": null, "datasets": null, "eval_results": null, "language": null, "library_name": null, "license": "mit", "license_name": null, "license_link": null, "metrics": null, "model_name": null, "pipeline_tag": null, "tags": null} | # <a name="introduction"></a> BARTpho: Pre-trained Sequence-to-Sequence Models for Vietnamese
Two BARTpho versions `BARTpho-syllable` and `BARTpho-word` are the first public large-scale monolingual sequence-to-sequence models pre-trained for Vietnamese. BARTpho uses the "large" architecture and pre-training scheme of... | null | [
"mit"
] | null | null | null | null | null | [
"AutoModel",
"mbart",
"MBartModel"
] | [
"feature-extraction"
] | [
"multimodal"
] | [
"text"
] | [
"embeddings"
] |
6762e34f8f9da7a654c79a93 | 03b2b331a48c71c3 | b14664993aa88526 | 100,278 | BPE | 100,000 | false | true | false | true | 22 | null | Sequence | ByteLevel | null | [
"Split",
"ByteLevel"
] | [
"ByteLevel"
] | 199 | allenai/OLMo-2-1124-13B-Instruct | allenai | {
"models": [
{
"_id": "6762eb81ce625fd4b1f58e77",
"id": "allenai/OLMo-2-1124-13B-Instruct-RLVR2"
}
],
"relation": "finetune"
} | 7,382 | 156,021 | False | 2024-12-18T14:59:27Z | 2025-01-06T01:02:18Z | transformers | 47 | 0 | null | text-generation | {"parameters": {"BF16": 13716198400}, "total": 13716198400} | [
".gitattributes",
"README.md",
"config.json",
"generation_config.json",
"merges.txt",
"model-00001-of-00006.safetensors",
"model-00002-of-00006.safetensors",
"model-00003-of-00006.safetensors",
"model-00004-of-00006.safetensors",
"model-00005-of-00006.safetensors",
"model-00006-of-00006.safetens... | 3a5c85baefbb1896a54d56fe2e76c0395627ddf4 | [
"transformers",
"safetensors",
"olmo2",
"text-generation",
"conversational",
"en",
"dataset:allenai/RLVR-MATH",
"arxiv:2501.00656",
"arxiv:2411.15124",
"base_model:allenai/OLMo-2-1124-13B-Instruct-RLVR2",
"base_model:finetune:allenai/OLMo-2-1124-13B-Instruct-RLVR2",
"license:apache-2.0",
"en... | null | {"architectures": ["Olmo2ForCausalLM"], "model_type": "olmo2", "tokenizer_config": {"bos_token": "<|endoftext|>", "chat_template": "{{ bos_token }}{% for message in messages %}{% if message['role'] == 'system' %}{{ '<|system|>\n' + message['content'] + '\n' }}{% elif message['role'] == 'user' %}{{ '<|user|>\n' + messag... | {
"auto_model": "AutoModelForCausalLM",
"custom_class": null,
"pipeline_tag": "text-generation",
"processor": "AutoTokenizer"
} | {"base_model": ["allenai/OLMo-2-1124-13B-Instruct-RLVR2"], "datasets": ["allenai/RLVR-MATH"], "eval_results": null, "language": ["en"], "library_name": "transformers", "license": "apache-2.0", "license_name": null, "license_link": null, "metrics": null, "model_name": null, "pipeline_tag": "text-generation", "tags": nul... | <img alt="OLMo Logo" src="https://huggingface.co/datasets/allenai/blog-images/resolve/main/olmo2/olmo.png" width="242px">
# OLMo-2-1124-13B-Instruct
## NOTE: 1/3/2025 UPDATE:
Upon the initial release of OLMo-2 models, we realized the post-trained models did not share the pre-tokenization logic that the base models u... | null | [
"apache-2.0"
] | [
"allenai/RLVR-MATH"
] | [
"en"
] | 13,716,198,400 | null | null | [
"AutoModelForCausalLM",
"olmo2",
"Olmo2ForCausalLM"
] | [
"text-generation"
] | [
"text"
] | [
"text"
] | [
"text"
] |
65fd4354165098b35ae7eb1c | 9d709325d7a80e92 | 3f9734fea54294a3 | 50,005 | BPE | 117,146 | true | true | true | true | 5 | Sequence | Metaspace | Metaspace | [
"Precompiled",
"Replace"
] | [
"Metaspace"
] | [
"Metaspace"
] | 898 | MiMe-MeMo/MeMo-BERT-WSD | MiMe-MeMo | {
"models": [
{
"_id": "64c787550b2ba05b2f2a2f9f",
"id": "MiMe-MeMo/MeMo-BERT-03"
}
],
"relation": "finetune"
} | 10 | 115,843 | False | 2024-03-22T08:37:40Z | 2024-03-22T09:29:46Z | transformers | 0 | 0 | [{"name": "MeMo-BERT-WSD", "results": [], "language": "da"}] | text-classification | {"parameters": {"F32": 124449028}, "total": 124449028} | [
".gitattributes",
"README.md",
"config.json",
"model.safetensors",
"runs/Mar22_08-37-21_5bcd60194132/events.out.tfevents.1711096664.5bcd60194132.3518.0",
"runs/Mar22_08-37-21_5bcd60194132/events.out.tfevents.1711097156.5bcd60194132.3518.1",
"sentencepiece.bpe.model",
"special_tokens_map.json",
"toke... | 37832782f197633de921bee77ad6cd2a24f53580 | [
"transformers",
"tensorboard",
"safetensors",
"xlm-roberta",
"text-classification",
"generated_from_trainer",
"base_model:MiMe-MeMo/MeMo-BERT-03",
"base_model:finetune:MiMe-MeMo/MeMo-BERT-03",
"text-embeddings-inference",
"endpoints_compatible",
"region:us"
] | null | {"architectures": ["XLMRobertaForSequenceClassification"], "model_type": "xlm-roberta", "tokenizer_config": {"bos_token": "<s>", "cls_token": "<s>", "eos_token": "</s>", "mask_token": "<mask>", "pad_token": "<pad>", "sep_token": "</s>", "unk_token": "<unk>"}} | {
"auto_model": "AutoModelForSequenceClassification",
"custom_class": null,
"pipeline_tag": "text-classification",
"processor": "AutoTokenizer"
} | {"base_model": "MiMe-MeMo/MeMo-BERT-03", "datasets": null, "eval_results": [], "language": null, "library_name": null, "license": null, "license_name": null, "license_link": null, "metrics": null, "model_name": "MeMo-BERT-WSD", "pipeline_tag": null, "tags": ["generated_from_trainer"], "widget": [{"text": "Men havde Gud... | <!-- This model card has been generated automatically according to the information the Trainer had access to. You
should probably proofread and complete it, then remove this comment. -->
# MeMo-BERT-WSD
This model is a fine-tuned version of [MiMe-MeMo/MeMo-BERT-03](https://huggingface.co/MiMe-MeMo/MeMo-BERT-03) on ht... | null | null | null | null | 124,449,028 | null | null | [
"AutoModelForSequenceClassification",
"XLMRobertaForSequenceClassification",
"xlm-roberta"
] | [
"text-classification"
] | [
"text"
] | [
"text"
] | [
"logits"
] |
6607e1b5f77f98344d87f3d2 | 88cd37e502d27a0a | 0e7bc0977f200d1c | 32,000 | BPE | 58,980 | true | false | true | true | 3 | Sequence | null | Sequence | [
"Prepend",
"Replace"
] | null | [
"Replace",
"ByteFallback",
"Fuse",
"Strip"
] | 88 | speakleash/Bielik-7B-v0.1 | speakleash | null | 3,837 | 123,109 | False | 2024-03-30T09:56:05Z | 2024-10-26T12:33:26Z | transformers | 73 | 0 | null | text-generation | {"parameters": {"BF16": 7241732096}, "total": 7241732096} | [
".gitattributes",
"README.md",
"config.json",
"generation_config.json",
"info.json",
"model-00001-of-00003.safetensors",
"model-00002-of-00003.safetensors",
"model-00003-of-00003.safetensors",
"model.safetensors.index.json",
"speakleash_cyfronet.png",
"special_tokens_map.json",
"tokenizer.json... | ac6440afc74b8184953716e909563efd987607c8 | [
"transformers",
"safetensors",
"mistral",
"text-generation",
"continuously_pretrained",
"pl",
"arxiv:2410.18565",
"license:apache-2.0",
"text-generation-inference",
"endpoints_compatible",
"region:us"
] | null | {"architectures": ["MistralForCausalLM"], "model_type": "mistral", "tokenizer_config": {"bos_token": "<s>", "eos_token": "</s>", "pad_token": null, "unk_token": "<unk>", "use_default_system_prompt": false}} | {
"auto_model": "AutoModelForCausalLM",
"custom_class": null,
"pipeline_tag": "text-generation",
"processor": "AutoTokenizer"
} | {"base_model": null, "datasets": null, "eval_results": null, "language": ["pl"], "library_name": "transformers", "license": "apache-2.0", "license_name": null, "license_link": null, "metrics": null, "model_name": null, "pipeline_tag": null, "tags": ["continuously_pretrained"], "inference": {"parameters": {"temperature"... | <p align="center">
<img src="https://huggingface.co/speakleash/Bielik-7B-v0.1/raw/main/speakleash_cyfronet.png">
</p>
# Bielik-7B-v0.1
The Bielik-7B-v0.1 is a generative text model featuring 7 billion parameters, meticulously evolved from its predecessor, the [Mistral-7B-v0.1](https://huggingface.co/mistralai/Mistr... | null | [
"apache-2.0"
] | null | [
"pl"
] | 7,241,732,096 | null | null | [
"AutoModelForCausalLM",
"mistral",
"MistralForCausalLM"
] | [
"text-generation"
] | [
"text"
] | [
"text"
] | [
"text"
] |
662f699466debc4f8e1df110 | 39b1e434a495263c | a1f1bd381dcb9329 | 128,256 | BPE | 280,147 | false | true | true | true | 256 | null | Sequence | ByteLevel | null | [
"Split",
"ByteLevel"
] | [
"ByteLevel"
] | 349 | swap-uniba/LLaMAntino-3-ANITA-8B-Inst-DPO-ITA | swap-uniba | {
"models": [
{
"_id": "661f97d0b00f5f1f620c4f25",
"id": "meta-llama/Meta-Llama-3-8B-Instruct"
}
],
"relation": "finetune"
} | 11,894 | 134,661 | False | 2024-04-29T09:34:12Z | 2025-09-01T11:05:55Z | transformers | 30 | 0 | [{"name": "LLaMAntino-3-ANITA-8B-Inst-DPO-ITA", "results": [{"task": {"type": "text-generation", "name": "Text Generation"}, "dataset": {"name": "AI2 Reasoning Challenge (25-Shot)", "type": "ai2_arc", "config": "ARC-Challenge", "split": "test", "args": {"num_few_shot": 25}}, "metrics": [{"type": "acc_norm", "value": 74... | text-generation | {"parameters": {"BF16": 8030261248}, "total": 8030261248} | [
"LICENSE.txt",
"README.md",
"USE_POLICY.md",
"config.json",
"generation_config.json",
"model-00001-of-00004.safetensors",
"model-00002-of-00004.safetensors",
"model-00003-of-00004.safetensors",
"model-00004-of-00004.safetensors",
"model.safetensors.index.json",
"special_tokens_map.json",
"toke... | 5f5c90b197446b7ca4dfbfa099fcf3566edf2e5c | [
"transformers",
"safetensors",
"llama",
"text-generation",
"facebook",
"meta",
"pythorch",
"llama-3",
"llamantino",
"conversational",
"en",
"it",
"dataset:gsarti/clean_mc4_it",
"dataset:Chat-Error/wizard_alpaca_dolly_orca",
"dataset:mlabonne/orpo-dpo-mix-40k",
"arxiv:2405.07101",
"ar... | null | {"architectures": ["LlamaForCausalLM"], "model_type": "llama", "tokenizer_config": {"bos_token": "<|begin_of_text|>", "chat_template": "{% set loop_messages = messages %}{% for message in loop_messages %}{% set content = '<|start_header_id|>' + message['role'] + '<|end_header_id|>\n\n'+ message['content'] | trim + '<|e... | {
"auto_model": "AutoModelForCausalLM",
"custom_class": null,
"pipeline_tag": "text-generation",
"processor": "AutoTokenizer"
} | {"base_model": "meta-llama/Meta-Llama-3-8B-Instruct", "datasets": ["gsarti/clean_mc4_it", "Chat-Error/wizard_alpaca_dolly_orca", "mlabonne/orpo-dpo-mix-40k"], "language": ["en", "it"], "library_name": "transformers", "license": "llama3", "metrics": ["accuracy"], "pipeline_tag": "text-generation", "tags": ["facebook", "... | <img src="https://cdn-uploads.huggingface.co/production/uploads/5df8bb21da6d0311fd3d540f/xL6Ax1I34qfC4VPKEFA6Z.png" alt="llamantino3_anita" border="0" width="800px">
<hr>
📣 New MODEL FAMILY❗ [https://huggingface.co/m-polignano/ANITA-NEXT-24B-Magistral-2506-VISION-ITA](https://huggingface.co/m-polignano/ANITA-NEXT-24... | null | [
"llama3"
] | [
"gsarti/clean_mc4_it",
"Chat-Error/wizard_alpaca_dolly_orca",
"mlabonne/orpo-dpo-mix-40k"
] | [
"en",
"it"
] | 8,030,261,248 | null | [
"accuracy"
] | [
"AutoModelForCausalLM",
"llama",
"LlamaForCausalLM"
] | [
"text-generation"
] | [
"text"
] | [
"text"
] | [
"text"
] |
6606a16fe34aac8fb940d10f | d872adee309cd4f5 | cb9e6136d9b70513 | 32,002 | BPE | 61,249 | true | false | true | true | 5 | Sequence | null | Sequence | [
"Prepend",
"Replace"
] | null | [
"Replace",
"ByteFallback",
"Fuse",
"Strip"
] | 837 | 1bitLLM/bitnet_b1_58-xl | 1bitLLM | null | 270 | 116,010 | False | 2024-03-29T11:09:35Z | 2024-03-29T12:06:27Z | transformers | 39 | 0 | null | text-generation | {"parameters": {"F32": 1273584352}, "total": 1273584352} | [
".gitattributes",
"README.md",
"added_tokens.json",
"config.json",
"configuration_bitnet.py",
"eval_ppl.py",
"eval_task.py",
"eval_utils.py",
"generation_config.json",
"model-00001-of-00002.safetensors",
"model-00002-of-00002.safetensors",
"model.safetensors.index.json",
"modeling_bitnet.py"... | f99799ff5b55cc2dce88832644b9ff1c44f6c434 | [
"transformers",
"safetensors",
"llama",
"text-generation",
"arxiv:2402.17764",
"license:mit",
"text-generation-inference",
"endpoints_compatible",
"region:us"
] | null | {"architectures": ["BitnetForCausalLM"], "model_type": "llama", "tokenizer_config": {"bos_token": "<s>", "eos_token": "</s>", "pad_token": "<pad>", "unk_token": "<unk>", "use_default_system_prompt": false}} | {
"auto_model": "AutoModelForCausalLM",
"custom_class": null,
"pipeline_tag": "text-generation",
"processor": "AutoTokenizer"
} | {"base_model": null, "datasets": null, "eval_results": null, "language": null, "library_name": null, "license": "mit", "license_name": null, "license_link": null, "metrics": null, "model_name": null, "pipeline_tag": null, "tags": null} | This is a reproduction of the <a href="https://arxiv.org/abs/2402.17764"> BitNet b1.58</a> paper. The models are trained with <a href="https://github.com/togethercomputer/RedPajama-Data">RedPajama dataset</a> for 100B tokens. The hypers, as well as two-stage LR and weight decay, are implemented as suggested in their fo... | null | [
"mit"
] | null | null | 1,273,584,352 | null | null | [
"AutoModelForCausalLM",
"llama",
"BitnetForCausalLM"
] | [
"text-generation"
] | [
"text"
] | [
"text"
] | [
"text"
] |
67623952532233842be645a7 | 3ddbd5d5920db9ef | d1f3fcfcd5ab53f9 | 250,102 | Unigram | null | true | true | true | true | 5 | Sequence | Sequence | Metaspace | [
"Strip",
"Precompiled",
"Replace"
] | [
"Metaspace"
] | [
"Metaspace"
] | 899 | Johnson8187/Chinese-Emotion-Small | Johnson8187 | {
"models": [
{
"_id": "621ffdc036468d709f176a73",
"id": "MoritzLaurer/mDeBERTa-v3-base-mnli-xnli"
}
],
"relation": "finetune"
} | 326 | 116,674 | False | 2024-12-18T02:54:10Z | 2024-12-18T05:35:23Z | transformers | 8 | 0 | null | text-classification | {"parameters": {"F32": 278815496}, "total": 278815496} | [
".gitattributes",
"README.md",
"added_tokens.json",
"config.json",
"model.safetensors",
"special_tokens_map.json",
"spm.model",
"tokenizer.json",
"tokenizer_config.json",
"training_args.bin"
] | 2c04ce86de44d232f0fbe31413868eb31d791aea | [
"transformers",
"safetensors",
"deberta-v2",
"text-classification",
"emotion",
"zh",
"dataset:Johnson8187/Chinese_Multi-Emotion_Dialogue_Dataset",
"base_model:MoritzLaurer/mDeBERTa-v3-base-mnli-xnli",
"base_model:finetune:MoritzLaurer/mDeBERTa-v3-base-mnli-xnli",
"license:mit",
"text-embeddings-... | null | {"architectures": ["DebertaV2ForSequenceClassification"], "model_type": "deberta-v2", "tokenizer_config": {"bos_token": "[CLS]", "cls_token": "[CLS]", "eos_token": "[SEP]", "mask_token": "[MASK]", "pad_token": "[PAD]", "sep_token": "[SEP]", "unk_token": "[UNK]"}} | {
"auto_model": "AutoModelForSequenceClassification",
"custom_class": null,
"pipeline_tag": "text-classification",
"processor": "AutoTokenizer"
} | {"base_model": ["MoritzLaurer/mDeBERTa-v3-base-mnli-xnli"], "datasets": ["Johnson8187/Chinese_Multi-Emotion_Dialogue_Dataset"], "eval_results": null, "language": ["zh"], "library_name": "transformers", "license": "mit", "license_name": null, "license_link": null, "metrics": null, "model_name": null, "pipeline_tag": "te... | # Chinese-text-emotion-classifier-small
Large version(560M):[Johnson8187/Chinese-Emotion](https://huggingface.co/Johnson8187/Chinese-Emotion-Small)
大參數版本模型(560M):[Johnson8187/Chinese-Emotion](https://huggingface.co/Johnson8187/Chinese-Emotion-Small)
## 📚 Model Introduction
This model is fine-tuned based on the [Mo... | null | [
"mit"
] | [
"Johnson8187/Chinese_Multi-Emotion_Dialogue_Dataset"
] | [
"zh"
] | 278,815,496 | null | null | [
"AutoModelForSequenceClassification",
"deberta-v2",
"DebertaV2ForSequenceClassification"
] | [
"text-classification"
] | [
"text"
] | [
"text"
] | [
"logits"
] |
66291ffda3ee1445021d96c8 | 6e6a83dc4b556c95 | a1f1bd381dcb9329 | 128,256 | BPE | 280,147 | false | true | true | true | 256 | null | Sequence | ByteLevel | null | [
"Split",
"ByteLevel"
] | [
"ByteLevel"
] | 111 | VAGOsolutions/Llama-3-SauerkrautLM-70b-Instruct | VAGOsolutions | null | 29 | 115,616 | False | 2024-04-24T15:06:37Z | 2024-05-21T18:01:31Z | transformers | 23 | 0 | null | text-generation | {"parameters": {"BF16": 70553706496}, "total": 70553706496} | [
".gitattributes",
"README.md",
"config.json",
"generation_config.json",
"model-00001-of-00030.safetensors",
"model-00002-of-00030.safetensors",
"model-00003-of-00030.safetensors",
"model-00004-of-00030.safetensors",
"model-00005-of-00030.safetensors",
"model-00006-of-00030.safetensors",
"model-0... | 707cfd1a93875247c0223e0c7e3d86d58c432318 | [
"transformers",
"safetensors",
"llama",
"text-generation",
"dpo",
"conversational",
"de",
"en",
"license:other",
"text-generation-inference",
"endpoints_compatible",
"region:us"
] | null | {"architectures": ["LlamaForCausalLM"], "model_type": "llama", "tokenizer_config": {"bos_token": "<|begin_of_text|>", "chat_template": "{% set loop_messages = messages %}{% for message in loop_messages %}{% set content = '<|start_header_id|>' + message['role'] + '<|end_header_id|>\n\n'+ message['content'] | trim + '<|e... | {
"auto_model": "AutoModelForCausalLM",
"custom_class": null,
"pipeline_tag": "text-generation",
"processor": "AutoTokenizer"
} | {"base_model": null, "datasets": null, "eval_results": null, "language": ["de", "en"], "library_name": null, "license": "other", "license_name": "llama3", "license_link": "LICENSE", "metrics": null, "model_name": null, "pipeline_tag": null, "tags": ["dpo"], "extra_gated_prompt": "### META LLAMA 3 COMMUNITY LICENSE AGRE... | 
## VAGO solutions Llama-3-SauerkrautLM-70b-Instruct
Introducing **Llama-3-SauerkrautLM-70b-Instruct** – our Sauerkraut version of the powerful [meta-llama/Meta-Llama-3-70B-Instruct](https://huggi... | null | [
"other",
"llama3",
"LICENSE"
] | null | [
"de",
"en"
] | 70,553,706,496 | null | null | [
"AutoModelForCausalLM",
"llama",
"LlamaForCausalLM"
] | [
"text-generation"
] | [
"text"
] | [
"text"
] | [
"text"
] |
64e82f80e690f7366ea5c1ec | 38bba5514c4ad085 | 2fc4d340791f6b66 | 32,000 | BPE | 60,820 | true | false | true | true | 3 | Sequence | null | Sequence | [
"Prepend",
"Replace"
] | null | [
"Replace",
"ByteFallback",
"Fuse",
"Strip"
] | 900 | heegyu/WizardVicuna-open-llama-3b-v2 | heegyu | null | 1,087 | 119,983 | False | 2023-08-25T04:35:12Z | 2023-09-18T03:30:22Z | transformers | 1 | 0 | null | text-generation | {"parameters": {"F32": 1300, "F16": 3426473600}, "total": 3426474900} | [
".gitattributes",
"README.md",
"config.json",
"generation_config.json",
"model.safetensors",
"pytorch_model.bin",
"special_tokens_map.json",
"tokenizer.json",
"tokenizer.model",
"tokenizer_config.json"
] | 0946550dfbf40d926d6ba816d0ca13e9c810fa72 | [
"transformers",
"pytorch",
"safetensors",
"llama",
"text-generation",
"dataset:heegyu/wizard_vicuna_70k_v2",
"license:apache-2.0",
"text-generation-inference",
"endpoints_compatible",
"deploy:azure",
"region:us"
] | null | {"architectures": ["LlamaForCausalLM"], "model_type": "llama", "tokenizer_config": {"bos_token": {"__type": "AddedToken", "content": "<s>", "lstrip": false, "normalized": true, "rstrip": false, "single_word": false}, "eos_token": {"__type": "AddedToken", "content": "</s>", "lstrip": false, "normalized": true, "rstrip":... | {
"auto_model": "AutoModelForCausalLM",
"custom_class": null,
"pipeline_tag": "text-generation",
"processor": "AutoTokenizer"
} | {"base_model": null, "datasets": ["heegyu/wizard_vicuna_70k_v2"], "eval_results": null, "language": null, "library_name": null, "license": "apache-2.0", "license_name": null, "license_link": null, "metrics": null, "model_name": null, "pipeline_tag": null, "tags": null} | Hyperparameters
- 3/8 epoch(3rd epoch checkpoing while 8epoch training)
- 1e-4 -> 1e-5 with cosine lr decay
- batch size 128
- max sequence length 2048
- AdamW(weigth decay=0.01, b1=0.9, b2=0.99, grad_clip=1.0)
- no warmup
- BF16
- Base Model: [openlm-research/open_llama_3b_v2](https://huggingface.co/openlm-research/o... | null | [
"apache-2.0"
] | [
"heegyu/wizard_vicuna_70k_v2"
] | null | 3,426,474,900 | null | null | [
"AutoModelForCausalLM",
"llama",
"LlamaForCausalLM"
] | [
"text-generation"
] | [
"text"
] | [
"text"
] | [
"text"
] |
663276d8d5677e3287a5227c | d7c38013c55b8f08 | 70bd27c212bc339c | 50,265 | BPE | 50,000 | false | true | true | true | 5 | null | ByteLevel | ByteLevel | null | [
"ByteLevel"
] | [
"ByteLevel"
] | 901 | KevSun/Personality_LM | KevSun | null | 514 | 117,203 | False | 2024-05-01T17:07:36Z | 2024-07-29T09:39:26Z | transformers | 27 | 0 | null | text-classification | null | [
".gitattributes",
"README.md",
"config.json",
"merges.txt",
"pytorch_model.bin",
"special_tokens_map.json",
"tokenizer.json",
"tokenizer_config.json",
"training_args.bin",
"vocab.json"
] | cdc6556b305064d837bb1d2ac2c659109137b30d | [
"transformers",
"pytorch",
"roberta",
"text-classification",
"arxiv:2406.16223",
"license:apache-2.0",
"text-embeddings-inference",
"endpoints_compatible",
"region:us"
] | null | {"architectures": ["RobertaForSequenceClassification"], "model_type": "roberta", "tokenizer_config": {"bos_token": {"__type": "AddedToken", "content": "<s>", "lstrip": false, "normalized": true, "rstrip": false, "single_word": false}, "cls_token": {"__type": "AddedToken", "content": "<s>", "lstrip": false, "normalized"... | {
"auto_model": "AutoModelForSequenceClassification",
"custom_class": null,
"pipeline_tag": "text-classification",
"processor": "AutoTokenizer"
} | {"base_model": null, "datasets": null, "eval_results": null, "language": null, "library_name": null, "license": "apache-2.0", "license_name": null, "license_link": null, "metrics": null, "model_name": null, "pipeline_tag": null, "tags": null} | In this project, we have refined the capabilities of a pre-existing model to assess **the Big Five personality traits** for a given text/sentence. By meticulously fine-tuning this model using a specially curated dataset tailored for personality traits, it has learned to correlate specific textual inputs with distinct p... | null | [
"apache-2.0"
] | null | null | null | null | null | [
"roberta",
"AutoModelForSequenceClassification",
"RobertaForSequenceClassification"
] | [
"text-classification"
] | [
"text"
] | [
"text"
] | [
"logits"
] |
62561e9025cfd82dbb07e573 | 83bf28f8b6767a2f | ae88e903e2b563a1 | 50,295 | BPE | 50,000 | false | true | true | true | 39 | null | ByteLevel | ByteLevel | null | [
"ByteLevel"
] | [
"ByteLevel"
] | 85 | Salesforce/codegen-6B-multi | Salesforce | null | 1,609 | 121,542 | False | 2022-04-13T00:51:28Z | 2025-01-31T21:27:38Z | transformers | 20 | 0 | null | text-generation | null | [
".gitattributes",
"README.md",
"added_tokens.json",
"config.json",
"merges.txt",
"pytorch_model.bin",
"special_tokens_map.json",
"tokenizer.json",
"tokenizer_config.json",
"vocab.json"
] | 0ed6e6b130360dde58f132790a9488a67a8cdf21 | [
"transformers",
"pytorch",
"codegen",
"text-generation",
"arxiv:2203.13474",
"license:bsd-3-clause",
"endpoints_compatible",
"deploy:azure",
"region:us"
] | null | {"architectures": ["CodeGenForCausalLM"], "model_type": "codegen", "tokenizer_config": {"unk_token": "<|endoftext|>", "bos_token": "<|endoftext|>", "eos_token": "<|endoftext|>"}} | {
"auto_model": "AutoModelForCausalLM",
"custom_class": null,
"pipeline_tag": "text-generation",
"processor": "AutoTokenizer"
} | {"base_model": null, "datasets": null, "eval_results": null, "language": null, "library_name": null, "license": "bsd-3-clause", "license_name": null, "license_link": null, "metrics": null, "model_name": null, "pipeline_tag": null, "tags": null} | # CodeGen (CodeGen-Multi 6B)
## Model description
CodeGen is a family of autoregressive language models for **program synthesis** from the paper: [A Conversational Paradigm for Program Synthesis](https://arxiv.org/abs/2203.13474) by Erik Nijkamp, Bo Pang, Hiroaki Hayashi, Lifu Tu, Huan Wang, Yingbo Zhou, Silvio Savar... | null | [
"bsd-3-clause"
] | null | null | null | null | null | [
"AutoModelForCausalLM",
"codegen",
"CodeGenForCausalLM"
] | [
"text-generation"
] | [
"text"
] | [
"text"
] | [
"text"
] |
625d827d7341c641426c85bd | 2afd270aa5cf97cd | 70bd27c212bc339c | 50,265 | BPE | 50,000 | false | true | true | true | 5 | null | ByteLevel | ByteLevel | null | [
"ByteLevel"
] | [
"ByteLevel"
] | 902 | HYPJUDY/layoutlmv3-base-finetuned-funsd | HYPJUDY | null | 323 | 116,906 | False | 2022-04-18T15:23:41Z | 2022-09-16T03:17:49Z | transformers | 5 | 0 | null | token-classification | null | [
".gitattributes",
"README.md",
"all_results.json",
"config.json",
"eval_results.json",
"merges.txt",
"pytorch_model.bin",
"runs/Apr17_09-22-17_deeplearning28/1650187356.1828399/events.out.tfevents.1650187356.deeplearning28.62374.1",
"runs/Apr17_09-22-17_deeplearning28/events.out.tfevents.1650187356.... | 50d41c6a1ac760da43c41d056dc5875e5b646987 | [
"transformers",
"pytorch",
"tensorboard",
"layoutlmv3",
"token-classification",
"arxiv:2204.08387",
"license:cc-by-nc-sa-4.0",
"endpoints_compatible",
"region:us"
] | null | {"architectures": ["LayoutLMv3ForTokenClassification"], "model_type": "layoutlmv3", "tokenizer_config": {"unk_token": {"content": "<unk>", "single_word": false, "lstrip": false, "rstrip": false, "normalized": true, "__type": "AddedToken"}, "bos_token": {"content": "<s>", "single_word": false, "lstrip": false, "rstrip":... | {
"auto_model": "AutoModelForTokenClassification",
"custom_class": null,
"pipeline_tag": "token-classification",
"processor": "AutoProcessor"
} | {"base_model": null, "datasets": null, "eval_results": null, "language": null, "library_name": null, "license": "cc-by-nc-sa-4.0", "license_name": null, "license_link": null, "metrics": null, "model_name": null, "pipeline_tag": null, "tags": null} | # layoutlmv3-base-finetuned-funsd
The model [layoutlmv3-base-finetuned-funsd](https://huggingface.co/HYPJUDY/layoutlmv3-base-finetuned-funsd) is fine-tuned on the FUNSD dataset initialized from [microsoft/layoutlmv3-base](https://huggingface.co/microsoft/layoutlmv3-base).
This finetuned model achieves an F1 score of 9... | null | [
"cc-by-nc-sa-4.0"
] | null | null | null | null | null | [
"AutoModelForTokenClassification",
"LayoutLMv3ForTokenClassification",
"layoutlmv3"
] | [
"token-classification"
] | [
"text"
] | [
"text"
] | [
"logits"
] |
661d71f42caae5151e3b10a2 | 5afd7d59d2aa5e01 | 535fa14da0af647c | 30,522 | WordPiece | null | true | true | true | true | 5 | BertNormalizer | BertPreTokenizer | WordPiece | [
"BertNormalizer"
] | [
"BertPreTokenizer"
] | [
"WordPiece"
] | 125 | abbasgolestani/ag-nli-DeTS-sentence-similarity-v3-light | abbasgolestani | null | 12 | 115,132 | False | 2024-04-15T18:29:08Z | 2024-07-18T16:37:53Z | transformers | 0 | 0 | null | text-classification | null | [
".DS_Store",
".gitattributes",
"README.md",
"config.json",
"merges.txt",
"pytorch_model.bin",
"special_tokens_map.json",
"tokenizer.json",
"tokenizer_config.json",
"vocab.json",
"vocab.txt"
] | 86c94ad949d2a4dd714d13e103fa44758030ae20 | [
"transformers",
"pytorch",
"electra",
"text-classification",
"feature-extraction",
"sentence-similarity",
"en",
"nl",
"de",
"fr",
"it",
"es",
"dataset:multi_nli",
"dataset:pietrolesci/nli_fever",
"license:apache-2.0",
"endpoints_compatible",
"deploy:azure",
"region:us"
] | null | {"architectures": ["ElectraForSequenceClassification"], "model_type": "electra", "tokenizer_config": {"cls_token": "[CLS]", "mask_token": "[MASK]", "pad_token": "[PAD]", "sep_token": "[SEP]", "unk_token": "[UNK]"}} | {
"auto_model": "AutoModelForSequenceClassification",
"custom_class": null,
"pipeline_tag": "text-classification",
"processor": "AutoTokenizer"
} | {"base_model": null, "datasets": ["multi_nli", "pietrolesci/nli_fever"], "eval_results": null, "language": ["en", "nl", "de", "fr", "it", "es"], "library_name": null, "license": "apache-2.0", "license_name": null, "license_link": null, "metrics": null, "model_name": null, "pipeline_tag": "text-classification", "tags": ... | # Cross-Encoder for Sentence Similarity
This model was trained using [SentenceTransformers](https://sbert.net) [Cross-Encoder](https://www.sbert.net/examples/applications/cross-encoder/README.html) class.
## Training Data
This model was trained on 6 different nli datasets. The model will predict a score between 0 (not... | null | [
"apache-2.0"
] | [
"multi_nli",
"pietrolesci/nli_fever"
] | [
"en",
"nl",
"de",
"fr",
"it",
"es"
] | null | null | null | [
"ElectraForSequenceClassification",
"AutoModelForSequenceClassification",
"electra"
] | [
"sentence-similarity",
"feature-extraction",
"text-classification"
] | [
"text",
"multimodal"
] | [
"text"
] | [
"logits",
"embeddings"
] |
64b6c9343d3bb8b1b5eb6aa0 | 6949732424a8d297 | 8bd7d71767538b82 | 32,000 | BPE | 61,249 | true | false | true | true | 3 | Sequence | null | Sequence | [
"Prepend",
"Replace"
] | null | [
"Replace",
"ByteFallback",
"Fuse",
"Strip"
] | 42 | TheBloke/Llama-2-13B-GPTQ | TheBloke | {
"models": [
{
"_id": "64b01d242b3ed6328c763877",
"id": "meta-llama/Llama-2-13b-hf"
}
],
"relation": "quantized"
} | 193 | 119,408 | False | 2023-07-18T17:17:40Z | 2023-09-27T12:44:47Z | transformers | 120 | 0 | null | text-generation | {"parameters": {"F32": 2560, "I32": 12687769600, "F16": 330224640}, "total": 13017996800} | [
".gitattributes",
"LICENSE.txt",
"Notice",
"README.md",
"USE_POLICY.md",
"config.json",
"generation_config.json",
"model.safetensors",
"quantize_config.json",
"special_tokens_map.json",
"tokenizer.json",
"tokenizer.model",
"tokenizer_config.json"
] | dc078861968fc39b3303df619d1606c7528c6f87 | [
"transformers",
"safetensors",
"llama",
"text-generation",
"facebook",
"meta",
"pytorch",
"llama-2",
"en",
"arxiv:2307.09288",
"base_model:meta-llama/Llama-2-13b-hf",
"base_model:quantized:meta-llama/Llama-2-13b-hf",
"license:llama2",
"text-generation-inference",
"4-bit",
"gptq",
"de... | null | {"architectures": ["LlamaForCausalLM"], "model_type": "llama", "quantization_config": {"bits": 4, "quant_method": "gptq"}, "tokenizer_config": {"bos_token": {"__type": "AddedToken", "content": "<s>", "lstrip": false, "normalized": true, "rstrip": false, "single_word": false}, "eos_token": {"__type": "AddedToken", "cont... | {
"auto_model": "AutoModelForCausalLM",
"custom_class": null,
"pipeline_tag": "text-generation",
"processor": "AutoTokenizer"
} | {"base_model": "meta-llama/Llama-2-13b-hf", "datasets": null, "eval_results": null, "language": ["en"], "library_name": null, "license": "llama2", "license_name": null, "license_link": null, "metrics": null, "model_name": "Llama 2 13B", "pipeline_tag": "text-generation", "tags": ["facebook", "meta", "pytorch", "llama",... | <!-- header start -->
<!-- 200823 -->
<div style="width: auto; margin-left: auto; margin-right: auto">
<img src="https://i.imgur.com/EBdldam.jpg" alt="TheBlokeAI" style="width: 100%; min-width: 400px; display: block; margin: auto;">
</div>
<div style="display: flex; justify-content: space-between; width: 100%;">
<d... | null | [
"llama2"
] | null | [
"en"
] | 13,017,996,800 | null | null | [
"AutoModelForCausalLM",
"llama",
"LlamaForCausalLM"
] | [
"text-generation"
] | [
"text"
] | [
"text"
] | [
"text"
] |
66846cf546da9ec5d685f50b | 6e6a83dc4b556c95 | a1f1bd381dcb9329 | 128,256 | BPE | 280,147 | false | true | true | true | 256 | null | Sequence | ByteLevel | null | [
"Split",
"ByteLevel"
] | [
"ByteLevel"
] | 111 | RedHatAI/Meta-Llama-3-8B-Instruct-quantized.w8a16 | RedHatAI | null | 509 | 117,036 | False | 2024-07-02T21:11:17Z | 2024-07-18T17:07:56Z | transformers | 3 | 0 | null | text-generation | {"parameters": {"I32": 6979321856, "F16": 1050939392}, "total": 8030261248} | [
".gitattributes",
"README.md",
"config.json",
"generation_config.json",
"model-00001-of-00002.safetensors",
"model-00002-of-00002.safetensors",
"model.safetensors.index.json",
"special_tokens_map.json",
"tokenizer.json",
"tokenizer_config.json"
] | b2432b66594ad323e37d930d2c383b497e0baa73 | [
"transformers",
"safetensors",
"llama",
"text-generation",
"conversational",
"en",
"license:llama3",
"text-generation-inference",
"endpoints_compatible",
"8-bit",
"gptq",
"region:us"
] | null | {"architectures": ["LlamaForCausalLM"], "model_type": "llama", "quantization_config": {"bits": 8, "quant_method": "gptq"}, "tokenizer_config": {"bos_token": "<|begin_of_text|>", "chat_template": "{% set loop_messages = messages %}{% for message in loop_messages %}{% set content = '<|start_header_id|>' + message['role']... | {
"auto_model": "AutoModelForCausalLM",
"custom_class": null,
"pipeline_tag": "text-generation",
"processor": "AutoTokenizer"
} | {"base_model": null, "datasets": null, "eval_results": null, "language": ["en"], "library_name": null, "license": "llama3", "license_name": null, "license_link": "https://llama.meta.com/llama3/license/", "metrics": null, "model_name": null, "pipeline_tag": "text-generation", "tags": null} | null | null | [
"llama3",
"https://llama.meta.com/llama3/license/"
] | null | [
"en"
] | 8,030,261,248 | null | null | [
"AutoModelForCausalLM",
"llama",
"LlamaForCausalLM"
] | [
"text-generation"
] | [
"text"
] | [
"text"
] | [
"text"
] |
6761c0aaeca65e769f06d246 | c0e1b90c863bae56 | fef4c97d7f951c6a | 131,072 | BPE | 128,810 | false | true | false | true | 2,024 | null | Sequence | ByteLevel | null | [
"Punctuation",
"ByteLevel",
"Digits"
] | [
"ByteLevel"
] | 558 | mlx-community/Falcon3-10B-Instruct-8bit | mlx-community | {
"models": [
{
"_id": "675d14e5da45b7d6f70d7085",
"id": "tiiuae/Falcon3-10B-Instruct"
}
],
"relation": "quantized"
} | 6 | 115,028 | False | 2024-12-17T18:19:22Z | 2024-12-17T20:12:40Z | transformers | 0 | 0 | null | text-generation | {"parameters": {"F16": 322292736, "U32": 2576351232}, "total": 2898643968} | [
".gitattributes",
"README.md",
"config.json",
"model-00001-of-00003.safetensors",
"model-00002-of-00003.safetensors",
"model-00003-of-00003.safetensors",
"model.safetensors.index.json",
"special_tokens_map.json",
"tokenizer.json",
"tokenizer_config.json"
] | b3eeb84271a6e5a79150c4fafaef41ac0592355c | [
"transformers",
"safetensors",
"llama",
"text-generation",
"falcon3",
"mlx",
"conversational",
"base_model:tiiuae/Falcon3-10B-Instruct",
"base_model:quantized:tiiuae/Falcon3-10B-Instruct",
"license:other",
"text-generation-inference",
"endpoints_compatible",
"8-bit",
"region:us"
] | null | {"architectures": ["LlamaForCausalLM"], "model_type": "llama", "quantization_config": {"bits": 8}, "tokenizer_config": {"chat_template": "{% for message in messages %}{% if message['role'] == 'system' %}{{ '<|system|>\n' + message['content'] + '\n' }}{% elif message['role'] == 'user' %}{{ '<|user|>\n' + message['conten... | {
"auto_model": "AutoModelForCausalLM",
"custom_class": null,
"pipeline_tag": "text-generation",
"processor": "AutoTokenizer"
} | {"base_model": "tiiuae/Falcon3-10B-Instruct", "datasets": null, "eval_results": null, "language": null, "library_name": "transformers", "license": "other", "license_name": "falcon-llm-license", "license_link": "https://falconllm.tii.ae/falcon-terms-and-conditions.html", "metrics": null, "model_name": null, "pipeline_ta... | # mlx-community/Falcon3-10B-Instruct-8bit
The Model [mlx-community/Falcon3-10B-Instruct-8bit](https://huggingface.co/mlx-community/Falcon3-10B-Instruct-8bit) was
converted to MLX format from [tiiuae/Falcon3-10B-Instruct](https://huggingface.co/tiiuae/Falcon3-10B-Instruct)
using mlx-lm version **0.20.4**.
## Use with ... | null | [
"other",
"falcon-llm-license",
"https://falconllm.tii.ae/falcon-terms-and-conditions.html"
] | null | null | 2,898,643,968 | null | null | [
"AutoModelForCausalLM",
"llama",
"LlamaForCausalLM"
] | [
"text-generation"
] | [
"text"
] | [
"text"
] | [
"text"
] |
64e78bf3015ed1a435ea1a23 | e23b6bdbe047bb7e | 8bd7d71767538b82 | 32,000 | BPE | 61,249 | true | false | true | true | 3 | Sequence | null | Sequence | [
"Prepend",
"Replace"
] | null | [
"Replace",
"ByteFallback",
"Fuse",
"Strip"
] | 46 | codellama/CodeLlama-34b-Python-hf | codellama | null | 1,072 | 120,483 | False | 2023-08-24T16:57:23Z | 2024-04-12T14:15:25Z | transformers | 99 | 0 | null | text-generation | {"parameters": {"BF16": 33743970304}, "total": 33743970304} | [
".gitattributes",
"CODE_OF_CONDUCT.md",
"README.md",
"USE_POLICY.md",
"config.json",
"generation_config.json",
"model-00001-of-00007.safetensors",
"model-00002-of-00007.safetensors",
"model-00003-of-00007.safetensors",
"model-00004-of-00007.safetensors",
"model-00005-of-00007.safetensors",
"mo... | 7daa5d7ae0be52aea6c5523df2c887853f1e7035 | [
"transformers",
"pytorch",
"safetensors",
"llama",
"text-generation",
"llama-2",
"code",
"arxiv:2308.12950",
"license:llama2",
"text-generation-inference",
"endpoints_compatible",
"deploy:azure",
"region:us"
] | null | {"architectures": ["LlamaForCausalLM"], "model_type": "llama", "tokenizer_config": {"bos_token": {"__type": "AddedToken", "content": "<s>", "lstrip": false, "normalized": true, "rstrip": false, "single_word": false}, "eos_token": {"__type": "AddedToken", "content": "</s>", "lstrip": false, "normalized": true, "rstrip":... | {
"auto_model": "AutoModelForCausalLM",
"custom_class": null,
"pipeline_tag": "text-generation",
"processor": "AutoTokenizer"
} | {"base_model": null, "datasets": null, "eval_results": null, "language": ["code"], "library_name": null, "license": "llama2", "license_name": null, "license_link": null, "metrics": null, "model_name": null, "pipeline_tag": "text-generation", "tags": ["llama-2"]} | # **Code Llama**
Code Llama is a collection of pretrained and fine-tuned generative text models ranging in scale from 7 billion to 34 billion parameters. This is the repository for the 34B Python specialist version in the Hugging Face Transformers format. This model is designed for general code synthesis and understan... | null | [
"llama2"
] | null | [
"code"
] | 33,743,970,304 | null | null | [
"AutoModelForCausalLM",
"llama",
"LlamaForCausalLM"
] | [
"text-generation"
] | [
"text"
] | [
"text"
] | [
"text"
] |
65e7b3e3fb44ffc378fd09b3 | 3a3a1da6c0c74b0d | 2f8d5857ae5fa330 | 50,277 | BPE | 50,009 | true | true | true | true | 25 | NFC | ByteLevel | ByteLevel | [
"NFC"
] | [
"ByteLevel"
] | [
"ByteLevel"
] | 206 | state-spaces/mamba-370m-hf | state-spaces | null | 5,733 | 136,054 | False | 2024-03-06T00:08:03Z | 2024-03-06T00:40:36Z | transformers | 16 | 0 | null | text-generation | {"parameters": {"F32": 371516416}, "total": 371516416} | [
".gitattributes",
"README.md",
"config.json",
"generation_config.json",
"model.safetensors",
"tokenizer.json",
"tokenizer_config.json"
] | b519127f5bfaaa1c27dd938dad051ec360972b23 | [
"transformers",
"safetensors",
"mamba",
"text-generation",
"text-generation-inference",
"endpoints_compatible",
"deploy:azure",
"region:us"
] | null | {"architectures": ["MambaForCausalLM"], "model_type": "mamba", "tokenizer_config": {"bos_token": "<|endoftext|>", "eos_token": "<|endoftext|>", "pad_token": "<|endoftext|>", "unk_token": "<|endoftext|>"}} | {
"auto_model": "AutoModelForCausalLM",
"custom_class": null,
"pipeline_tag": "text-generation",
"processor": "AutoTokenizer"
} | {"base_model": null, "datasets": null, "eval_results": null, "language": null, "library_name": "transformers", "license": null, "license_name": null, "license_link": null, "metrics": null, "model_name": null, "pipeline_tag": null, "tags": []} | # Mamba
<!-- Provide a quick summary of what the model is/does. -->
This repository contains the `transfromers` compatible `mamba-2.8b`. The checkpoints are untouched, but the full `config.json` and tokenizer are pushed to this repo.
# Usage
You need to install `transformers` from `main` until `transformers=4.39.0`... | null | null | null | null | 371,516,416 | null | null | [
"AutoModelForCausalLM",
"mamba",
"MambaForCausalLM"
] | [
"text-generation"
] | [
"text"
] | [
"text"
] | [
"text"
] |
6502caca5412026f7b8a0f63 | e23b6bdbe047bb7e | 8bd7d71767538b82 | 32,000 | BPE | 61,249 | true | false | true | true | 3 | Sequence | null | Sequence | [
"Prepend",
"Replace"
] | null | [
"Replace",
"ByteFallback",
"Fuse",
"Strip"
] | 46 | FreedomIntelligence/AceGPT-7B | FreedomIntelligence | null | 421 | 115,413 | False | 2023-09-14T08:56:42Z | 2023-11-29T16:09:05Z | transformers | 8 | 0 | null | text-generation | null | [
".gitattributes",
"LICENSE.txt",
"README.md",
"config.json",
"generation_config.json",
"pytorch_model.bin",
"special_tokens_map.json",
"tokenizer.json",
"tokenizer.model",
"tokenizer_config.json"
] | c907e27abebb1237ff62450b0e84cab7ad4dfb5f | [
"transformers",
"pytorch",
"llama",
"text-generation",
"ar",
"license:apache-2.0",
"text-generation-inference",
"endpoints_compatible",
"region:us"
] | null | {"architectures": ["LlamaForCausalLM"], "model_type": "llama", "tokenizer_config": {"bos_token": {"__type": "AddedToken", "content": "<s>", "lstrip": false, "normalized": false, "rstrip": false, "single_word": false}, "eos_token": {"__type": "AddedToken", "content": "</s>", "lstrip": false, "normalized": false, "rstrip... | {
"auto_model": "AutoModelForCausalLM",
"custom_class": null,
"pipeline_tag": "text-generation",
"processor": "AutoTokenizer"
} | {"base_model": null, "datasets": null, "eval_results": null, "language": ["ar"], "library_name": null, "license": "apache-2.0", "license_name": null, "license_link": null, "metrics": null, "model_name": null, "pipeline_tag": null, "tags": null} | # <b>AceGPT</b>
AceGPT is a fully fine-tuned generative text model collection based on LlaMA2, particularly in the
Arabic language domain. This is the repository for the 7B pretrained model.
---
## Model Details
We have released the AceGPT family of large language models, which is a collection of fully fine-tuned ge... | null | [
"apache-2.0"
] | null | [
"ar"
] | null | null | null | [
"AutoModelForCausalLM",
"llama",
"LlamaForCausalLM"
] | [
"text-generation"
] | [
"text"
] | [
"text"
] | [
"text"
] |
67e1cd3b2c57e73b03712350 | 5a92ad66405a4a95 | 86a334241cee71f3 | 156,940 | BPE | 280,147 | false | true | true | true | 28,940 | null | Sequence | ByteLevel | null | [
"Split",
"ByteLevel"
] | [
"ByteLevel"
] | 729 | unsloth/orpheus-3b-0.1-ft-unsloth-bnb-4bit | unsloth | {
"models": [
{
"_id": "67d7a25ee3396bf0c92e811c",
"id": "canopylabs/orpheus-3b-0.1-ft"
}
],
"relation": "quantized"
} | 4,102 | 204,654 | False | 2025-03-24T21:23:07Z | 2025-03-24T21:59:51Z | transformers | 16 | 0 | null | text-to-speech | {"parameters": {"F32": 222720, "BF16": 507460608, "U8": 2880766400}, "total": 3388449728} | [
".gitattributes",
"README.md",
"config.json",
"generation_config.json",
"model.safetensors",
"special_tokens_map.json",
"tokenizer.json",
"tokenizer_config.json"
] | c014246a7cd64459982546b5c98524c7c7ee8bc1 | [
"transformers",
"safetensors",
"llama",
"text-generation",
"text-to-speech",
"en",
"base_model:canopylabs/orpheus-3b-0.1-ft",
"base_model:quantized:canopylabs/orpheus-3b-0.1-ft",
"license:apache-2.0",
"text-generation-inference",
"endpoints_compatible",
"4-bit",
"bitsandbytes",
"region:us"... | null | {"architectures": ["LlamaForCausalLM"], "model_type": "llama", "quantization_config": {"load_in_4bit": true, "load_in_8bit": false, "quant_method": "bitsandbytes"}, "tokenizer_config": {"bos_token": "<|begin_of_text|>", "chat_template": "{{- bos_token }}\n{%- if custom_tools is defined %}\n {%- set tools = custom_to... | {
"auto_model": "AutoModelForCausalLM",
"custom_class": null,
"pipeline_tag": "text-generation",
"processor": "AutoTokenizer"
} | {"base_model": ["canopylabs/orpheus-3b-0.1-ft", "meta-llama/Llama-3.2-3B-Instruct", "canopylabs/orpheus-3b-0.1-pretrained"], "datasets": null, "eval_results": null, "language": ["en"], "library_name": "transformers", "license": "apache-2.0", "license_name": null, "license_link": null, "metrics": null, "model_name": nul... | # Orpheus 3B 0.1 Finetuned
**03/18/2025** – We are releasing our 3B Orpheus TTS model with additional finetunes. Code is available on GitHub: [CanopyAI/Orpheus-TTS](https://github.com/canopyai/Orpheus-TTS)
---
Orpheus TTS is a state-of-the-art, Llama-based Speech-LLM designed for high-quality, empathetic text-to-spe... | null | [
"apache-2.0"
] | null | [
"en"
] | 3,388,449,728 | null | null | [
"AutoModelForCausalLM",
"llama",
"LlamaForCausalLM"
] | [
"text-to-speech",
"text-generation"
] | [
"text",
"audio"
] | [
"text"
] | [
"text",
"audio"
] |
65b296e91dcf354c00319a15 | 11cdf776a252dffe | 7c4c85b636f4813b | 64,000 | BPE | 110,029 | true | false | true | true | 3 | Sequence | null | Sequence | [
"Prepend",
"Replace"
] | null | [
"Replace",
"ByteFallback",
"Fuse",
"Strip"
] | 903 | abacusai/Smaug-34B-v0.1 | abacusai | {
"models": [
{
"_id": "659173bf9e16fa7510829591",
"id": "jondurbin/bagel-34b-v0.2"
}
],
"relation": "finetune"
} | 8,507 | 155,901 | False | 2024-01-25T17:14:17Z | 2024-07-05T15:07:23Z | transformers | 64 | 1 | null | text-generation | {"parameters": {"BF16": 34388917248}, "total": 34388917248} | [
".gitattributes",
"README.md",
"config.json",
"generation_config.json",
"model-00001-of-00015.safetensors",
"model-00002-of-00015.safetensors",
"model-00003-of-00015.safetensors",
"model-00004-of-00015.safetensors",
"model-00005-of-00015.safetensors",
"model-00006-of-00015.safetensors",
"model-0... | 7701f9c9de8a5b0e0d36d3db207e99028d9734d0 | [
"transformers",
"safetensors",
"llama",
"text-generation",
"conversational",
"arxiv:2402.13228",
"base_model:jondurbin/bagel-34b-v0.2",
"base_model:finetune:jondurbin/bagel-34b-v0.2",
"license:apache-2.0",
"text-generation-inference",
"endpoints_compatible",
"region:us"
] | null | {"architectures": ["LlamaForCausalLM"], "model_type": "llama", "tokenizer_config": {"bos_token": "<s>", "chat_template": "{%- for idx in range(0, messages|length) -%}\n{%- if messages[idx]['role'] == 'user' -%}\n{%- if idx > 1 -%}\n{{- bos_token + '[INST] ' + messages[idx]['content'] + ' [/INST]' -}}\n{%- else -%}\n{{-... | {
"auto_model": "AutoModelForCausalLM",
"custom_class": null,
"pipeline_tag": "text-generation",
"processor": "AutoTokenizer"
} | {"base_model": "jondurbin/bagel-34b-v0.2", "datasets": null, "eval_results": null, "language": null, "library_name": null, "license": "apache-2.0", "license_name": null, "license_link": null, "metrics": null, "model_name": null, "pipeline_tag": null, "tags": null} | 

This model is a finetune of jondurbin's excellent [bagel](https://huggingface.c... | null | [
"apache-2.0"
] | null | null | 34,388,917,248 | null | null | [
"AutoModelForCausalLM",
"llama",
"LlamaForCausalLM"
] | [
"text-generation"
] | [
"text"
] | [
"text"
] | [
"text"
] |
65771780c793e5b72b0e8d68 | 88cd37e502d27a0a | 0e7bc0977f200d1c | 32,000 | BPE | 58,980 | true | false | true | true | 3 | Sequence | null | Sequence | [
"Prepend",
"Replace"
] | null | [
"Replace",
"ByteFallback",
"Fuse",
"Strip"
] | 88 | TheBloke/Mixtral-8x7B-v0.1-GPTQ | TheBloke | {
"models": [
{
"_id": "6569aa681d7c2ca7b7bfcc80",
"id": "mistralai/Mixtral-8x7B-v0.1"
}
],
"relation": "quantized"
} | 273 | 119,917 | False | 2023-12-11T14:06:56Z | 2023-12-14T14:30:54Z | transformers | 127 | 0 | null | text-generation | {"parameters": {"I32": 46439333888, "BF16": 263458816, "F16": 8716288}, "total": 46711508992} | [
".gitattributes",
"README.md",
"config.json",
"generation_config.json",
"model.safetensors",
"quantize_config.json",
"special_tokens_map.json",
"tokenizer.json",
"tokenizer.model",
"tokenizer_config.json"
] | 7d1eb57b65f823458e27509cd0aac7172f54a260 | [
"transformers",
"safetensors",
"mixtral",
"text-generation",
"fr",
"it",
"de",
"es",
"en",
"base_model:mistralai/Mixtral-8x7B-v0.1",
"base_model:quantized:mistralai/Mixtral-8x7B-v0.1",
"license:apache-2.0",
"text-generation-inference",
"4-bit",
"gptq",
"deploy:azure",
"region:us"
] | null | {"architectures": ["MixtralForCausalLM"], "model_type": "mixtral", "quantization_config": {"bits": 4, "quant_method": "gptq"}, "tokenizer_config": {"bos_token": "<s>", "eos_token": "</s>", "pad_token": null, "unk_token": "<unk>", "use_default_system_prompt": false}} | {
"auto_model": "AutoModelForCausalLM",
"custom_class": null,
"pipeline_tag": "text-generation",
"processor": "AutoTokenizer"
} | {"base_model": "mistralai/Mixtral-8x7B-v0.1", "datasets": null, "eval_results": null, "language": ["fr", "it", "de", "es", "en"], "library_name": null, "license": "apache-2.0", "license_name": null, "license_link": null, "metrics": null, "model_name": "Mixtral 8X7B v0.1", "pipeline_tag": null, "tags": null, "inference"... | <!-- markdownlint-disable MD041 -->
<!-- header start -->
<!-- 200823 -->
<div style="width: auto; margin-left: auto; margin-right: auto">
<img src="https://i.imgur.com/EBdldam.jpg" alt="TheBlokeAI" style="width: 100%; min-width: 400px; display: block; margin: auto;">
</div>
<div style="display: flex; justify-content:... | null | [
"apache-2.0"
] | null | [
"fr",
"it",
"de",
"es",
"en"
] | 46,711,508,992 | null | null | [
"mixtral",
"MixtralForCausalLM",
"AutoModelForCausalLM"
] | [
"text-generation"
] | [
"text"
] | [
"text"
] | [
"text"
] |
65f74bfa1139c3cd68cc3d07 | 0aea00f578e27edb | 0e7bc0977f200d1c | 32,000 | BPE | 58,980 | true | false | true | true | 3 | Sequence | null | Sequence | [
"Prepend",
"Replace"
] | null | [
"Replace",
"ByteFallback",
"Fuse",
"Strip"
] | 904 | MaziyarPanahi/Calme-4x7B-MoE-v0.2 | MaziyarPanahi | null | 8,486 | 155,338 | False | 2024-03-17T20:00:58Z | 2024-03-17T20:49:33Z | transformers | 2 | 0 | [{"name": "Calme-4x7B-MoE-v0.2", "results": []}] | text-generation | {"parameters": {"BF16": 24153690112}, "total": 24153690112} | [
".gitattributes",
"README.md",
"config.json",
"model-00001-of-00005.safetensors",
"model-00002-of-00005.safetensors",
"model-00003-of-00005.safetensors",
"model-00004-of-00005.safetensors",
"model-00005-of-00005.safetensors",
"model.safetensors.index.json",
"special_tokens_map.json",
"tokenizer.... | ffef41baf94b3f88b30cf0aeb3fd72d9e4187161 | [
"transformers",
"safetensors",
"mixtral",
"text-generation",
"generated_from_trainer",
"mistral",
"7b",
"calme",
"moe",
"conversational",
"license:apache-2.0",
"text-generation-inference",
"deploy:azure",
"region:us"
] | null | {"architectures": ["MixtralForCausalLM"], "model_type": "mixtral", "tokenizer_config": {"bos_token": "<s>", "chat_template": "{{ bos_token }}{% for message in messages %}{% if (message['role'] == 'user') != (loop.index0 % 2 == 0) %}{{ raise_exception('Conversation roles must alternate user/assistant/user/assistant/...'... | {
"auto_model": "AutoModelForCausalLM",
"custom_class": null,
"pipeline_tag": "text-generation",
"processor": "AutoTokenizer"
} | {"base_model": null, "datasets": null, "eval_results": [], "language": null, "library_name": null, "license": "apache-2.0", "license_name": null, "license_link": null, "metrics": null, "model_name": "Calme-4x7B-MoE-v0.2", "pipeline_tag": "text-generation", "tags": ["generated_from_trainer", "mistral", "7b", "calme", "m... | <img src="https://cdn-uploads.huggingface.co/production/uploads/5fd5e18a90b6dc4633f6d292/LzEf6vvq2qIiys-q7l9Hq.webp" width="550" />
# MaziyarPanahi/Calme-4x7B-MoE-v0.2
## Model Description
Calme-4x7B is a Mixture of Experts (MoE) model, integrating four state-of-the-art Calme-7B models. Essentially, Calme-4x7B is co... | null | [
"apache-2.0"
] | null | null | 24,153,690,112 | null | null | [
"mixtral",
"MixtralForCausalLM",
"AutoModelForCausalLM"
] | [
"text-generation"
] | [
"text"
] | [
"text"
] | [
"text"
] |
621ffdc136468d709f180152 | 30094a1eabdbef67 | db117e9883c4d0ab | 50,257 | BPE | 50,000 | false | true | true | true | 1 | null | ByteLevel | ByteLevel | null | [
"ByteLevel"
] | [
"ByteLevel"
] | 4 | satvikag/chatbot | satvikag | null | 1,341 | 116,518 | False | 2022-03-02T23:29:05Z | 2021-06-04T20:08:11Z | transformers | 37 | 0 | null | text-generation | null | [
".gitattributes",
"README.md",
"config.json",
"merges.txt",
"pytorch_model.bin",
"special_tokens_map.json",
"tokenizer.json",
"tokenizer_config.json",
"vocab.json"
] | 5736b2051dfc768c950ddd700d11e9e92ffa6d0e | [
"transformers",
"pytorch",
"gpt2",
"text-generation",
"conversational",
"license:mit",
"text-generation-inference",
"endpoints_compatible",
"deploy:azure",
"region:us"
] | null | {"architectures": ["GPT2LMHeadModel"], "model_type": "gpt2", "tokenizer_config": {"unk_token": {"content": "<|endoftext|>", "single_word": false, "lstrip": false, "rstrip": false, "normalized": true, "__type": "AddedToken"}, "bos_token": {"content": "<|endoftext|>", "single_word": false, "lstrip": false, "rstrip": fals... | {
"auto_model": "AutoModelForCausalLM",
"custom_class": null,
"pipeline_tag": "text-generation",
"processor": "AutoTokenizer"
} | {"base_model": null, "datasets": null, "eval_results": null, "language": null, "library_name": null, "license": "mit", "license_name": null, "license_link": null, "metrics": null, "model_name": null, "pipeline_tag": null, "tags": ["conversational"]} | # DialoGPT Trained on the Speech of a Game Character
This is an instance of [microsoft/DialoGPT-medium](https://huggingface.co/microsoft/DialoGPT-medium) trained on a game character, Joshua from [The World Ends With You](https://en.wikipedia.org/wiki/The_World_Ends_with_You). The data comes from [a Kaggle game script d... | null | [
"mit"
] | null | null | null | null | null | [
"GPT2LMHeadModel",
"AutoModelForCausalLM",
"gpt2"
] | [
"text-generation"
] | [
"text"
] | [
"text"
] | [
"text"
] |
67214a6a549bbea50227c01b | 848b60b6cd304b65 | ffc911e785abe60e | 151,665 | BPE | 151,387 | true | true | true | true | 22 | NFC | Sequence | ByteLevel | [
"NFC"
] | [
"Split",
"ByteLevel"
] | [
"ByteLevel"
] | 15 | arcee-ai/Arcee-VyLinh | arcee-ai | {
"models": [
{
"_id": "66e98d74d4219fc3f1db215f",
"id": "Qwen/Qwen2.5-3B-Instruct"
},
{
"_id": "671ca09d84f3a55c7ec3a22d",
"id": "waraml/ViLinh-3B"
}
],
"relation": "merge"
} | 215 | 115,793 | False | 2024-10-29T20:49:46Z | 2025-10-09T19:58:19Z | transformers | 42 | 0 | null | text-generation | {"parameters": {"F32": 3397103616}, "total": 3397103616} | [
".gitattributes",
"README.md",
"added_tokens.json",
"config.json",
"mergekit_config.yml",
"merges.txt",
"model-00001-of-00003.safetensors",
"model-00002-of-00003.safetensors",
"model-00003-of-00003.safetensors",
"model.safetensors.index.json",
"special_tokens_map.json",
"tokenizer.json",
"to... | 5f9751c095cdfa14c2e77489f8aef8a037da1b1c | [
"transformers",
"safetensors",
"qwen2",
"text-generation",
"mergekit",
"merge",
"conversational",
"vi",
"base_model:Qwen/Qwen2.5-3B-Instruct",
"base_model:merge:Qwen/Qwen2.5-3B-Instruct",
"base_model:waraml/ViLinh-3B",
"base_model:merge:waraml/ViLinh-3B",
"license:apache-2.0",
"text-genera... | null | {"architectures": ["Qwen2ForCausalLM"], "model_type": "qwen2", "tokenizer_config": {"bos_token": null, "chat_template": "{%- if tools %}\n {{- '<|im_start|>system\\n' }}\n {%- if messages[0]['role'] == 'system' %}\n {{- messages[0]['content'] }}\n {%- else %}\n {{- 'You are Qwen, created by Aliba... | {
"auto_model": "AutoModelForCausalLM",
"custom_class": null,
"pipeline_tag": "text-generation",
"processor": "AutoTokenizer"
} | {"base_model": ["qnguyen3/VyLinh-3B", "Qwen/Qwen2.5-3B-Instruct"], "datasets": null, "eval_results": null, "language": ["vi"], "library_name": "transformers", "license": "apache-2.0", "license_name": null, "license_link": null, "metrics": null, "model_name": null, "pipeline_tag": null, "tags": ["mergekit", "merge"]} | **Quantized Version**: [arcee-ai/Arcee-VyLinh-GGUF](https://huggingface.co/arcee-ai/Arcee-VyLinh-GGUF)
# Arcee-VyLinh
Arcee-VyLinh is a 3B parameter instruction-following model specifically optimized for Vietnamese language understanding and generation. Built through an innovative training process combining evolved h... | null | [
"apache-2.0"
] | null | [
"vi"
] | 3,397,103,616 | null | null | [
"AutoModelForCausalLM",
"Qwen2ForCausalLM",
"qwen2"
] | [
"text-generation"
] | [
"text"
] | [
"text"
] | [
"text"
] |
63b2b2ec6c3e6df5c384565c | 53ecf467267e2824 | 535fa14da0af647c | 30,522 | WordPiece | null | true | true | true | true | 5 | BertNormalizer | BertPreTokenizer | WordPiece | [
"BertNormalizer"
] | [
"BertPreTokenizer"
] | [
"WordPiece"
] | 0 | microsoft/git-large | microsoft | null | 634 | 116,338 | False | 2023-01-02T10:33:16Z | 2023-02-08T10:49:46Z | transformers | 17 | 0 | null | image-to-text | null | [
".gitattributes",
"README.md",
"config.json",
"generation_config.json",
"preprocessor_config.json",
"pytorch_model.bin",
"special_tokens_map.json",
"tokenizer.json",
"tokenizer_config.json",
"vocab.txt"
] | 58597eee6783b5d4405df333573fe4b4368bce29 | [
"transformers",
"pytorch",
"git",
"image-text-to-text",
"vision",
"image-captioning",
"image-to-text",
"en",
"arxiv:2205.14100",
"license:mit",
"endpoints_compatible",
"region:us"
] | null | {"architectures": ["GitForCausalLM"], "model_type": "git", "tokenizer_config": {"cls_token": "[CLS]", "mask_token": "[MASK]", "pad_token": "[PAD]", "sep_token": "[SEP]", "unk_token": "[UNK]"}} | {
"auto_model": "AutoModelForImageTextToText",
"custom_class": null,
"pipeline_tag": "image-text-to-text",
"processor": "AutoProcessor"
} | {"base_model": null, "datasets": null, "eval_results": null, "language": "en", "library_name": null, "license": "mit", "license_name": null, "license_link": null, "metrics": null, "model_name": "microsoft/git-base", "pipeline_tag": "image-to-text", "tags": ["vision", "image-captioning"]} | # GIT (GenerativeImage2Text), large-sized
GIT (short for GenerativeImage2Text) model, large-sized version. It was introduced in the paper [GIT: A Generative Image-to-text Transformer for Vision and Language](https://arxiv.org/abs/2205.14100) by Wang et al. and first released in [this repository](https://github.com/mic... | null | [
"mit"
] | null | [
"en"
] | null | null | null | [
"AutoModelForImageTextToText",
"GitForCausalLM",
"git"
] | [
"image-text-to-text",
"image-to-text"
] | [
"multimodal"
] | [
"text",
"image"
] | [
"text"
] |
663f2b734b52a18fe7cb3b6d | f6bd53b02735a215 | 3f3879d485dc5e16 | 63,992 | BPE | 110,029 | true | false | false | true | 231 | Sequence | null | Sequence | [
"Replace"
] | null | [
"Replace",
"ByteFallback",
"Fuse",
"Strip"
] | 512 | 01-ai/Yi-1.5-6B | 01-ai | null | 12,413 | 166,522 | False | 2024-05-11T08:25:23Z | 2024-06-26T10:42:02Z | transformers | 31 | 0 | null | text-generation | {"parameters": {"BF16": 6061035520}, "total": 6061035520} | [
".gitattributes",
"NOTICE",
"README.md",
"config.json",
"generation_config.json",
"md5",
"model-00001-of-00003.safetensors",
"model-00002-of-00003.safetensors",
"model-00003-of-00003.safetensors",
"model.safetensors.index.json",
"tokenizer.json",
"tokenizer.model",
"tokenizer_config.json"
] | 157a3d77ab5a8a8f079510eaa25169b547481f06 | [
"transformers",
"safetensors",
"llama",
"text-generation",
"arxiv:2403.04652",
"license:apache-2.0",
"text-generation-inference",
"endpoints_compatible",
"deploy:azure",
"region:us"
] | null | {"architectures": ["LlamaForCausalLM"], "model_type": "llama", "tokenizer_config": {"unk_token": "<unk>", "bos_token": "<|startoftext|>", "eos_token": "<|endoftext|>", "pad_token": "<unk>"}} | {
"auto_model": "AutoModelForCausalLM",
"custom_class": null,
"pipeline_tag": "text-generation",
"processor": "AutoTokenizer"
} | {"base_model": null, "datasets": null, "eval_results": null, "language": null, "library_name": null, "license": "apache-2.0", "license_name": null, "license_link": null, "metrics": null, "model_name": null, "pipeline_tag": null, "tags": null} | <div align="center">
<picture>
<img src="https://raw.githubusercontent.com/01-ai/Yi/main/assets/img/Yi_logo_icon_light.svg" width="150px">
</picture>
</div>
<p align="center">
<a href="https://github.com/01-ai">🐙 GitHub</a> •
<a href="https://discord.gg/hYUwWddeAu">👾 Discord</a> •
<a href="https://twitter... | null | [
"apache-2.0"
] | null | null | 6,061,035,520 | null | null | [
"AutoModelForCausalLM",
"llama",
"LlamaForCausalLM"
] | [
"text-generation"
] | [
"text"
] | [
"text"
] | [
"text"
] |
64f654ab3a14cc4dd8b04762 | e23b6bdbe047bb7e | 8bd7d71767538b82 | 32,000 | BPE | 61,249 | true | false | true | true | 3 | Sequence | null | Sequence | [
"Prepend",
"Replace"
] | null | [
"Replace",
"ByteFallback",
"Fuse",
"Strip"
] | 46 | PygmalionAI/pygmalion-2-13b | PygmalionAI | null | 988 | 119,962 | False | 2023-09-04T22:05:31Z | 2023-09-15T20:29:04Z | transformers | 89 | 0 | null | text-generation | {"parameters": {"BF16": 13015864320}, "total": 13015864320} | [
".gitattributes",
"README.md",
"config.json",
"generation_config.json",
"model-00001-of-00003.safetensors",
"model-00002-of-00003.safetensors",
"model-00003-of-00003.safetensors",
"model.safetensors.index.json",
"pytorch_model-00001-of-00003.bin",
"pytorch_model-00002-of-00003.bin",
"pytorch_mod... | 3cdc103995ccd5fc7fd2cb5f51f71b510466f5fc | [
"transformers",
"pytorch",
"safetensors",
"llama",
"text-generation",
"text generation",
"instruct",
"en",
"dataset:PygmalionAI/PIPPA",
"dataset:Open-Orca/OpenOrca",
"dataset:Norquinal/claude_multiround_chat_30k",
"dataset:jondurbin/airoboros-gpt4-1.4.1",
"dataset:databricks/databricks-dolly... | null | {"architectures": ["LlamaForCausalLM"], "model_type": "llama", "tokenizer_config": {"bos_token": {"__type": "AddedToken", "content": "<s>", "lstrip": false, "normalized": false, "rstrip": false, "single_word": false}, "eos_token": {"__type": "AddedToken", "content": "</s>", "lstrip": false, "normalized": false, "rstrip... | {
"auto_model": "AutoModelForCausalLM",
"custom_class": null,
"pipeline_tag": "text-generation",
"processor": "AutoTokenizer"
} | {"base_model": null, "datasets": ["PygmalionAI/PIPPA", "Open-Orca/OpenOrca", "Norquinal/claude_multiround_chat_30k", "jondurbin/airoboros-gpt4-1.4.1", "databricks/databricks-dolly-15k"], "eval_results": null, "language": ["en"], "library_name": null, "license": "llama2", "license_name": null, "license_link": null, "met... | <h1 style="text-align: center">Pygmalion-2 13B</h1>
<h2 style="text-align: center">An instruction-tuned Llama-2 biased towards fiction writing and conversation.</h2>
## Model Details
The long-awaited release of our new models based on Llama-2 is finally here. Pygmalion-2 13B (formerly known as Metharme) is based on
[... | null | [
"llama2"
] | [
"PygmalionAI/PIPPA",
"Open-Orca/OpenOrca",
"Norquinal/claude_multiround_chat_30k",
"jondurbin/airoboros-gpt4-1.4.1",
"databricks/databricks-dolly-15k"
] | [
"en"
] | 13,015,864,320 | null | null | [
"AutoModelForCausalLM",
"llama",
"LlamaForCausalLM"
] | [
"text-generation"
] | [
"text"
] | [
"text"
] | [
"text"
] |
644ae471d4483bfaa0718b80 | 58967ba68263f0aa | 2f8d5857ae5fa330 | 50,277 | BPE | 50,009 | true | true | true | true | 25 | NFC | ByteLevel | ByteLevel | [
"NFC"
] | [
"ByteLevel"
] | [
"ByteLevel"
] | 86 | sgugger/rwkv-430M-pile | sgugger | null | 378 | 115,161 | False | 2023-04-27T21:09:05Z | 2023-05-03T14:06:12Z | transformers | 2 | 0 | null | null | null | [
".gitattributes",
"config.json",
"pytorch_model.bin",
"special_tokens_map.json",
"tokenizer.json",
"tokenizer_config.json"
] | b35374d0a2ea6823d8b9672c88304e709d539272 | [
"transformers",
"pytorch",
"rwkv",
"endpoints_compatible",
"region:us"
] | null | {"model_type": "rwkv", "tokenizer_config": {"bos_token": "<|endoftext|>", "eos_token": "<|endoftext|>", "unk_token": "<|endoftext|>"}} | {
"auto_model": "AutoModel",
"custom_class": null,
"pipeline_tag": null,
"processor": null
} | null | null | null | null | null | null | null | null | null | [
"AutoModel",
"rwkv"
] | [
null
] | null | null | null |
6476e90c40c99df876fcd3c4 | 8bc6b61a7b6c29c2 | 4c6e091e8dffb5aa | 30,003 | BPE | 29,740 | false | true | true | true | 7 | null | Sequence | ByteLevel | null | [
"Split",
"ByteLevel"
] | [
"ByteLevel"
] | 299 | nlpai-lab/kullm-polyglot-12.8b-v2 | nlpai-lab | null | 14 | 113,969 | False | 2023-05-31T06:28:28Z | 2023-05-31T15:48:09Z | transformers | 53 | 0 | null | text-generation | null | [
".gitattributes",
"README.md",
"config.json",
"generation_config.json",
"pytorch_model-00001-of-00003.bin",
"pytorch_model-00002-of-00003.bin",
"pytorch_model-00003-of-00003.bin",
"pytorch_model.bin.index.json",
"special_tokens_map.json",
"tokenizer.json",
"tokenizer_config.json"
] | 9e0c9be881f663ca088b10faad15b54ea3ba779c | [
"transformers",
"pytorch",
"gpt_neox",
"text-generation",
"ko",
"license:apache-2.0",
"text-generation-inference",
"endpoints_compatible",
"deploy:azure",
"region:us"
] | null | {"architectures": ["GPTNeoXForCausalLM"], "model_type": "gpt_neox", "tokenizer_config": {"eos_token": "<|endoftext|>", "pad_token": "<|endoftext|>"}} | {
"auto_model": "AutoModelForCausalLM",
"custom_class": null,
"pipeline_tag": "text-generation",
"processor": "AutoTokenizer"
} | {"base_model": null, "datasets": null, "eval_results": null, "language": ["ko"], "library_name": null, "license": "apache-2.0", "license_name": null, "license_link": null, "metrics": null, "model_name": null, "pipeline_tag": null, "tags": null} | # KULLM-Polyglot-12.8B-v2
This model is a fine-tuned version of [EleutherAI/polyglot-ko-12.8b](https://huggingface.co/EleutherAI/polyglot-ko-12.8b) on a KULLM v2
Detail Codes are available at [KULLM Github Repository](https://github.com/nlpai-lab/KULLM)
## Training procedure
### Training hyperparameters
The foll... | null | [
"apache-2.0"
] | null | [
"ko"
] | null | null | null | [
"gpt_neox",
"AutoModelForCausalLM",
"GPTNeoXForCausalLM"
] | [
"text-generation"
] | [
"text"
] | [
"text"
] | [
"text"
] |
64b748a0509b109d0429d255 | e23b6bdbe047bb7e | 8bd7d71767538b82 | 32,000 | BPE | 61,249 | true | false | true | true | 3 | Sequence | null | Sequence | [
"Prepend",
"Replace"
] | null | [
"Replace",
"ByteFallback",
"Fuse",
"Strip"
] | 46 | TheBloke/Llama-2-70B-fp16 | TheBloke | null | 1,087 | 119,630 | False | 2023-07-19T02:21:20Z | 2023-10-30T15:17:36Z | transformers | 47 | 0 | null | text-generation | {"parameters": {"F16": 68976648192, "F32": 5120}, "total": 68976653312} | [
".gitattributes",
"LICENSE.txt",
"Notice",
"README.md",
"USE_POLICY.md",
"config.json",
"generation_config.json",
"model-00001-of-00015.safetensors",
"model-00002-of-00015.safetensors",
"model-00003-of-00015.safetensors",
"model-00004-of-00015.safetensors",
"model-00005-of-00015.safetensors",
... | a1d1ad9e994e177c08d1c7da970f0fe9195372dc | [
"transformers",
"safetensors",
"llama",
"text-generation",
"facebook",
"meta",
"pytorch",
"llama-2",
"en",
"license:llama2",
"text-generation-inference",
"region:us"
] | null | {"architectures": ["LlamaForCausalLM"], "model_type": "llama", "tokenizer_config": {"bos_token": {"__type": "AddedToken", "content": "<s>", "lstrip": false, "normalized": false, "rstrip": false, "single_word": false}, "eos_token": {"__type": "AddedToken", "content": "</s>", "lstrip": false, "normalized": false, "rstrip... | {
"auto_model": "AutoModelForCausalLM",
"custom_class": null,
"pipeline_tag": "text-generation",
"processor": "AutoTokenizer"
} | {"base_model": null, "datasets": null, "eval_results": null, "language": ["en"], "library_name": null, "license": "llama2", "license_name": null, "license_link": null, "metrics": null, "model_name": null, "pipeline_tag": "text-generation", "tags": ["facebook", "meta", "pytorch", "llama", "llama-2"], "inference": false,... | <!-- header start -->
<div style="width: 100%;">
<img src="https://i.imgur.com/EBdldam.jpg" alt="TheBlokeAI" style="width: 100%; min-width: 400px; display: block; margin: auto;">
</div>
<div style="display: flex; justify-content: space-between; width: 100%;">
<div style="display: flex; flex-direction: column; a... | null | [
"llama2"
] | null | [
"en"
] | 68,976,653,312 | null | null | [
"AutoModelForCausalLM",
"llama",
"LlamaForCausalLM"
] | [
"text-generation"
] | [
"text"
] | [
"text"
] | [
"text"
] |
634d97120db95d9a8f71f74c | 57daa98777951f37 | 70bd27c212bc339c | 50,265 | BPE | 50,000 | false | true | true | true | 5 | null | ByteLevel | ByteLevel | null | [
"ByteLevel"
] | [
"ByteLevel"
] | 905 | Salesforce/discord_qa | Salesforce | null | 1 | 113,671 | False | 2022-10-17T17:55:30Z | 2025-01-14T18:57:57Z | transformers | 5 | 0 | null | question-answering | null | [
".gitattributes",
"README.md",
"config.json",
"merges.txt",
"pytorch_model.bin",
"special_tokens_map.json",
"tokenizer.json",
"tokenizer_config.json",
"vocab.json"
] | 686c2182f002ac5143a3668d0df5d31c56e3250f | [
"transformers",
"pytorch",
"roberta",
"question-answering",
"license:apache-2.0",
"endpoints_compatible",
"region:us"
] | null | {"architectures": ["RobertaForQuestionAnswering"], "model_type": "roberta", "tokenizer_config": {"bos_token": "<s>", "cls_token": "<s>", "eos_token": "</s>", "mask_token": "<mask>", "pad_token": "<pad>", "sep_token": "</s>", "unk_token": "<unk>"}} | {
"auto_model": "AutoModelForQuestionAnswering",
"custom_class": null,
"pipeline_tag": "question-answering",
"processor": "AutoTokenizer"
} | {"base_model": null, "datasets": null, "eval_results": null, "language": null, "library_name": null, "license": "apache-2.0", "license_name": null, "license_link": null, "metrics": null, "model_name": null, "pipeline_tag": null, "tags": null} | Model card for the Question Answering component (component 2) of the Discord Questions paper (EMNLP 2022 - Findings). The model is a finetuned RoBERTa-large. Example usage coming soon.
## Ethical Considerations
This release is for research purposes only in support of an academic paper. Our models, datasets, and code a... | null | [
"apache-2.0"
] | null | null | null | null | null | [
"roberta",
"AutoModelForQuestionAnswering",
"RobertaForQuestionAnswering"
] | [
"question-answering"
] | [
"text"
] | [
"text"
] | [
"text"
] |
6795a2884fccd4b9517e09fc | 799cc3d21f1b38e9 | 09c3eadef6573799 | 265,347 | BPE | 580,604 | true | true | true | true | 9,564 | Replace | Split | Sequence | [
"Replace"
] | [
"Split"
] | [
"Replace",
"ByteFallback",
"Fuse"
] | 906 | IPEC-COMMUNITY/spatialvla-4b-224-pt | IPEC-COMMUNITY | {
"models": [
{
"_id": "673f92e080c7c8e3327fd6a4",
"id": "google/paligemma2-3b-pt-224"
}
],
"relation": "finetune"
} | 5,020 | 151,538 | False | 2025-01-26T02:48:40Z | 2025-03-16T14:03:19Z | transformers | 14 | 0 | null | image-text-to-text | {"parameters": {"BF16": 4027854731}, "total": 4027854731} | [
".gitattributes",
"README.md",
"action_tokenizer.py",
"config.json",
"configuration_spatialvla.py",
"example.png",
"generation_config.json",
"model-00001-of-00002.safetensors",
"model-00002-of-00002.safetensors",
"model.safetensors.index.json",
"modeling_gemma2.py",
"modeling_spatialvla.py",
... | 886c4557dfde53b44c0f74fde7d89bf83a26c3cd | [
"transformers",
"safetensors",
"spatialvla",
"feature-extraction",
"VLA",
"Foundation Vision-language-action Model",
"Generalist Robot Policy",
"robotics",
"image-text-to-text",
"custom_code",
"en",
"arxiv:2501.15830",
"base_model:google/paligemma2-3b-pt-224",
"base_model:finetune:google/p... | null | {"architectures": ["SpatialVLAForConditionalGeneration"], "auto_map": {"AutoConfig": "configuration_spatialvla.SpatialVLAConfig", "AutoModel": "modeling_spatialvla.SpatialVLAForConditionalGeneration"}, "model_type": "spatialvla", "tokenizer_config": {"bos_token": "<bos>", "eos_token": "<eos>", "pad_token": "<pad>", "un... | {
"auto_model": "AutoModel",
"custom_class": "modeling_spatialvla.SpatialVLAForConditionalGeneration",
"pipeline_tag": "feature-extraction",
"processor": null
} | {"base_model": ["google/paligemma2-3b-pt-224"], "datasets": null, "eval_results": null, "language": ["en"], "library_name": "transformers", "license": "mit", "license_name": null, "license_link": null, "metrics": null, "model_name": null, "pipeline_tag": "image-text-to-text", "tags": ["VLA", "Foundation Vision-language... | # SpatialVLA
SpatialVLA is a spatial-enhanced vision-language-action model trained on 1.1 Million real robot episodes. The code is purely huggingFace-based and concise, with efficient performance.
All SpatialVLA checkpoints, as well as our [training codebase](https://github.com/SpatialVLA/SpatialVLA) are released und... | null | [
"mit"
] | null | [
"en"
] | 4,027,854,731 | null | null | [
"modeling_spatialvla.SpatialVLAForConditionalGeneration",
"AutoModel",
"spatialvla",
"SpatialVLAForConditionalGeneration"
] | [
"image-text-to-text",
"feature-extraction"
] | [
"multimodal"
] | [
"text",
"image"
] | [
"text",
"embeddings"
] |
Subsets and Splits
No community queries yet
The top public SQL queries from the community will appear here once available.