


Duplicate from fudan-generative-ai/hallo2
Browse filesCo-authored-by: AricGamma <AricGamma@users.noreply.huggingface.co>
- .gitattributes +37 -0
- CodeFormer/codeformer.pth +3 -0
- CodeFormer/vqgan_code1024.pth +3 -0
- README.md +416 -0
- audio_separator/Kim_Vocal_2.onnx +3 -0
- audio_separator/download_checks.json +231 -0
- audio_separator/mdx_model_data.json +384 -0
- audio_separator/vr_model_data.json +137 -0
- face_analysis/models/1k3d68.onnx +3 -0
- face_analysis/models/2d106det.onnx +3 -0
- face_analysis/models/face_landmarker_v2_with_blendshapes.task +3 -0
- face_analysis/models/genderage.onnx +3 -0
- face_analysis/models/glintr100.onnx +3 -0
- face_analysis/models/scrfd_10g_bnkps.onnx +3 -0
- facelib/detection_Resnet50_Final.pth +3 -0
- facelib/detection_mobilenet0.25_Final.pth +3 -0
- facelib/parsing_parsenet.pth +3 -0
- facelib/yolov5l-face.pth +3 -0
- facelib/yolov5n-face.pth +3 -0
- hallo2/net.pth +3 -0
- hallo2/net_g.pth +3 -0
- motion_module/mm_sd_v15_v2.ckpt +3 -0
- realesrgan/RealESRGAN_x2plus.pth +3 -0
- sd-vae-ft-mse/README.md +83 -0
- sd-vae-ft-mse/config.json +29 -0
- sd-vae-ft-mse/diffusion_pytorch_model.safetensors +3 -0
- stable-diffusion-v1-5/unet/config.json +36 -0
- stable-diffusion-v1-5/unet/diffusion_pytorch_model.safetensors +3 -0
- wav2vec/wav2vec2-base-960h/README.md +128 -0
- wav2vec/wav2vec2-base-960h/config.json +77 -0
- wav2vec/wav2vec2-base-960h/feature_extractor_config.json +8 -0
- wav2vec/wav2vec2-base-960h/model.safetensors +3 -0
- wav2vec/wav2vec2-base-960h/preprocessor_config.json +8 -0
- wav2vec/wav2vec2-base-960h/special_tokens_map.json +1 -0
- wav2vec/wav2vec2-base-960h/tokenizer_config.json +1 -0
- wav2vec/wav2vec2-base-960h/vocab.json +1 -0
.gitattributes
ADDED
|
@@ -0,0 +1,37 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
*.7z filter=lfs diff=lfs merge=lfs -text
|
| 2 |
+
*.arrow filter=lfs diff=lfs merge=lfs -text
|
| 3 |
+
*.bin filter=lfs diff=lfs merge=lfs -text
|
| 4 |
+
*.bz2 filter=lfs diff=lfs merge=lfs -text
|
| 5 |
+
*.ckpt filter=lfs diff=lfs merge=lfs -text
|
| 6 |
+
*.ftz filter=lfs diff=lfs merge=lfs -text
|
| 7 |
+
*.gz filter=lfs diff=lfs merge=lfs -text
|
| 8 |
+
*.h5 filter=lfs diff=lfs merge=lfs -text
|
| 9 |
+
*.joblib filter=lfs diff=lfs merge=lfs -text
|
| 10 |
+
*.lfs.* filter=lfs diff=lfs merge=lfs -text
|
| 11 |
+
*.mlmodel filter=lfs diff=lfs merge=lfs -text
|
| 12 |
+
*.model filter=lfs diff=lfs merge=lfs -text
|
| 13 |
+
*.msgpack filter=lfs diff=lfs merge=lfs -text
|
| 14 |
+
*.npy filter=lfs diff=lfs merge=lfs -text
|
| 15 |
+
*.npz filter=lfs diff=lfs merge=lfs -text
|
| 16 |
+
*.onnx filter=lfs diff=lfs merge=lfs -text
|
| 17 |
+
*.ot filter=lfs diff=lfs merge=lfs -text
|
| 18 |
+
*.parquet filter=lfs diff=lfs merge=lfs -text
|
| 19 |
+
*.pb filter=lfs diff=lfs merge=lfs -text
|
| 20 |
+
*.pickle filter=lfs diff=lfs merge=lfs -text
|
| 21 |
+
*.pkl filter=lfs diff=lfs merge=lfs -text
|
| 22 |
+
*.pt filter=lfs diff=lfs merge=lfs -text
|
| 23 |
+
*.pth filter=lfs diff=lfs merge=lfs -text
|
| 24 |
+
*.rar filter=lfs diff=lfs merge=lfs -text
|
| 25 |
+
*.safetensors filter=lfs diff=lfs merge=lfs -text
|
| 26 |
+
saved_model/**/* filter=lfs diff=lfs merge=lfs -text
|
| 27 |
+
*.tar.* filter=lfs diff=lfs merge=lfs -text
|
| 28 |
+
*.tar filter=lfs diff=lfs merge=lfs -text
|
| 29 |
+
*.tflite filter=lfs diff=lfs merge=lfs -text
|
| 30 |
+
*.tgz filter=lfs diff=lfs merge=lfs -text
|
| 31 |
+
*.wasm filter=lfs diff=lfs merge=lfs -text
|
| 32 |
+
*.xz filter=lfs diff=lfs merge=lfs -text
|
| 33 |
+
*.zip filter=lfs diff=lfs merge=lfs -text
|
| 34 |
+
*.zst filter=lfs diff=lfs merge=lfs -text
|
| 35 |
+
*tfevents* filter=lfs diff=lfs merge=lfs -text
|
| 36 |
+
*.task filter=lfs diff=lfs merge=lfs -text
|
| 37 |
+
|
CodeFormer/codeformer.pth
ADDED
|
@@ -0,0 +1,3 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
version https://git-lfs.github.com/spec/v1
|
| 2 |
+
oid sha256:1009e537e0c2a07d4cabce6355f53cb66767cd4b4297ec7a4a64ca4b8a5684b7
|
| 3 |
+
size 376637898
|
CodeFormer/vqgan_code1024.pth
ADDED
|
@@ -0,0 +1,3 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
version https://git-lfs.github.com/spec/v1
|
| 2 |
+
oid sha256:4d1c6741b3cffcbdc2cd1a12b2c3c2442282e042d5de66909cb643d4fa31b20f
|
| 3 |
+
size 255078528
|
README.md
ADDED
|
@@ -0,0 +1,416 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
---
|
| 2 |
+
library_name: hallo
|
| 3 |
+
license: mit
|
| 4 |
+
---
|
| 5 |
+
<h1 align='center'>Hallo2: Long-Duration and High-Resolution Audio-driven Portrait Image Animation</h1>
|
| 6 |
+
|
| 7 |
+
<div align='center'>
|
| 8 |
+
<a href='https://github.com/cuijh26' target='_blank'>Jiahao Cui</a><sup>1*</sup> 
|
| 9 |
+
<a href='https://github.com/crystallee-ai' target='_blank'>Hui Li</a><sup>1*</sup> 
|
| 10 |
+
<a href='https://yoyo000.github.io/' target='_blank'>Yao Yao</a><sup>3</sup> 
|
| 11 |
+
<a href='http://zhuhao.cc/home/' target='_blank'>Hao Zhu</a><sup>3</sup> 
|
| 12 |
+
<a href='https://github.com/NinoNeumann' target='_blank'>Hanlin Shang</a><sup>1</sup> 
|
| 13 |
+
<a href='https://github.com/Kaihui-Cheng' target='_blank'>Kaihui Cheng</a><sup>1</sup> 
|
| 14 |
+
<a href='' target='_blank'>Hang Zhou</a><sup>2</sup> 
|
| 15 |
+
</div>
|
| 16 |
+
<div align='center'>
|
| 17 |
+
<a href='https://sites.google.com/site/zhusiyucs/home' target='_blank'>Siyu Zhu</a><sup>1✉️</sup> 
|
| 18 |
+
<a href='https://jingdongwang2017.github.io/' target='_blank'>Jingdong Wang</a><sup>2</sup> 
|
| 19 |
+
</div>
|
| 20 |
+
|
| 21 |
+
<div align='center'>
|
| 22 |
+
<sup>1</sup>Fudan University  <sup>2</sup>Baidu Inc  <sup>3</sup>Nanjing University
|
| 23 |
+
</div>
|
| 24 |
+
|
| 25 |
+
<br>
|
| 26 |
+
<div align='center'>
|
| 27 |
+
<a href='https://github.com/fudan-generative-vision/hallo2'><img src='https://img.shields.io/github/stars/fudan-generative-vision/hallo2?style=social'></a>
|
| 28 |
+
<a href='https://fudan-generative-vision.github.io/hallo2/#/'><img src='https://img.shields.io/badge/Project-HomePage-Green'></a>
|
| 29 |
+
<a href='https://arxiv.org/abs/2410.07718'><img src='https://img.shields.io/badge/Paper-Arxiv-red'></a>
|
| 30 |
+
<a href='https://huggingface.co/fudan-generative-ai/hallo2'><img src='https://img.shields.io/badge/%F0%9F%A4%97%20HuggingFace-Model-yellow'></a>
|
| 31 |
+
<a href='assets/wechat.jpeg'><img src='https://badges.aleen42.com/src/wechat.svg'></a>
|
| 32 |
+
</div>
|
| 33 |
+
<br>
|
| 34 |
+
|
| 35 |
+
## 📸 Showcase
|
| 36 |
+
|
| 37 |
+
<table class="center">
|
| 38 |
+
<tr>
|
| 39 |
+
<td style="text-align: center"><b>Tailor Swift Speech @ NYU (4K, 23 minutes)</b></td>
|
| 40 |
+
<td style="text-align: center"><b>Johan Rockstrom Speech @ TED (4K, 18 minutes)</b></td>
|
| 41 |
+
</tr>
|
| 42 |
+
<tr>
|
| 43 |
+
<td style="text-align: center"><a target="_blank" href="https://cdn.aondata.work/hallo2/videos/showcases/TailorSpeech.mp4"><img src="https://cdn.aondata.work/hallo2/videos/showcases/gifs/TailorSpeechGIF.gif"></a></td>
|
| 44 |
+
<td style="text-align: center"><a target="_blank" href="https://cdn.aondata.work/hallo2/videos/showcases/TEDSpeech.mp4"><img src="https://cdn.aondata.work/hallo2/videos/showcases/gifs/TEDSpeechGIF.gif"></a></td>
|
| 45 |
+
</tr>
|
| 46 |
+
<tr>
|
| 47 |
+
<td style="text-align: center"><b>Churchill's Iron Curtain Speech (4K, 4 minutes)</b></td>
|
| 48 |
+
<td style="text-align: center"><b>An LLM Course from Stanford (4K, up to 1 hour)</b></td>
|
| 49 |
+
</tr>
|
| 50 |
+
<tr>
|
| 51 |
+
<td style="text-align: center"><a target="_blank" href="https://cdn.aondata.work/hallo2/videos/showcases/DarkestHour.mp4"><img src="https://cdn.aondata.work/hallo2/videos/showcases/gifs/DarkestHour.gif"></a></td>
|
| 52 |
+
<td style="text-align: center"><a target="_blank" href="https://cdn.aondata.work/hallo2/videos/showcases/LLMCourse.mp4"><img src="https://cdn.aondata.work/hallo2/videos/showcases/gifs/LLMCourseGIF.gif"></a></td>
|
| 53 |
+
</tr>
|
| 54 |
+
</table>
|
| 55 |
+
|
| 56 |
+
Visit our [project page](https://fudan-generative-vision.github.io/hallo2/#/) to view more cases.
|
| 57 |
+
|
| 58 |
+
## 🔧️ Framework
|
| 59 |
+
|
| 60 |
+
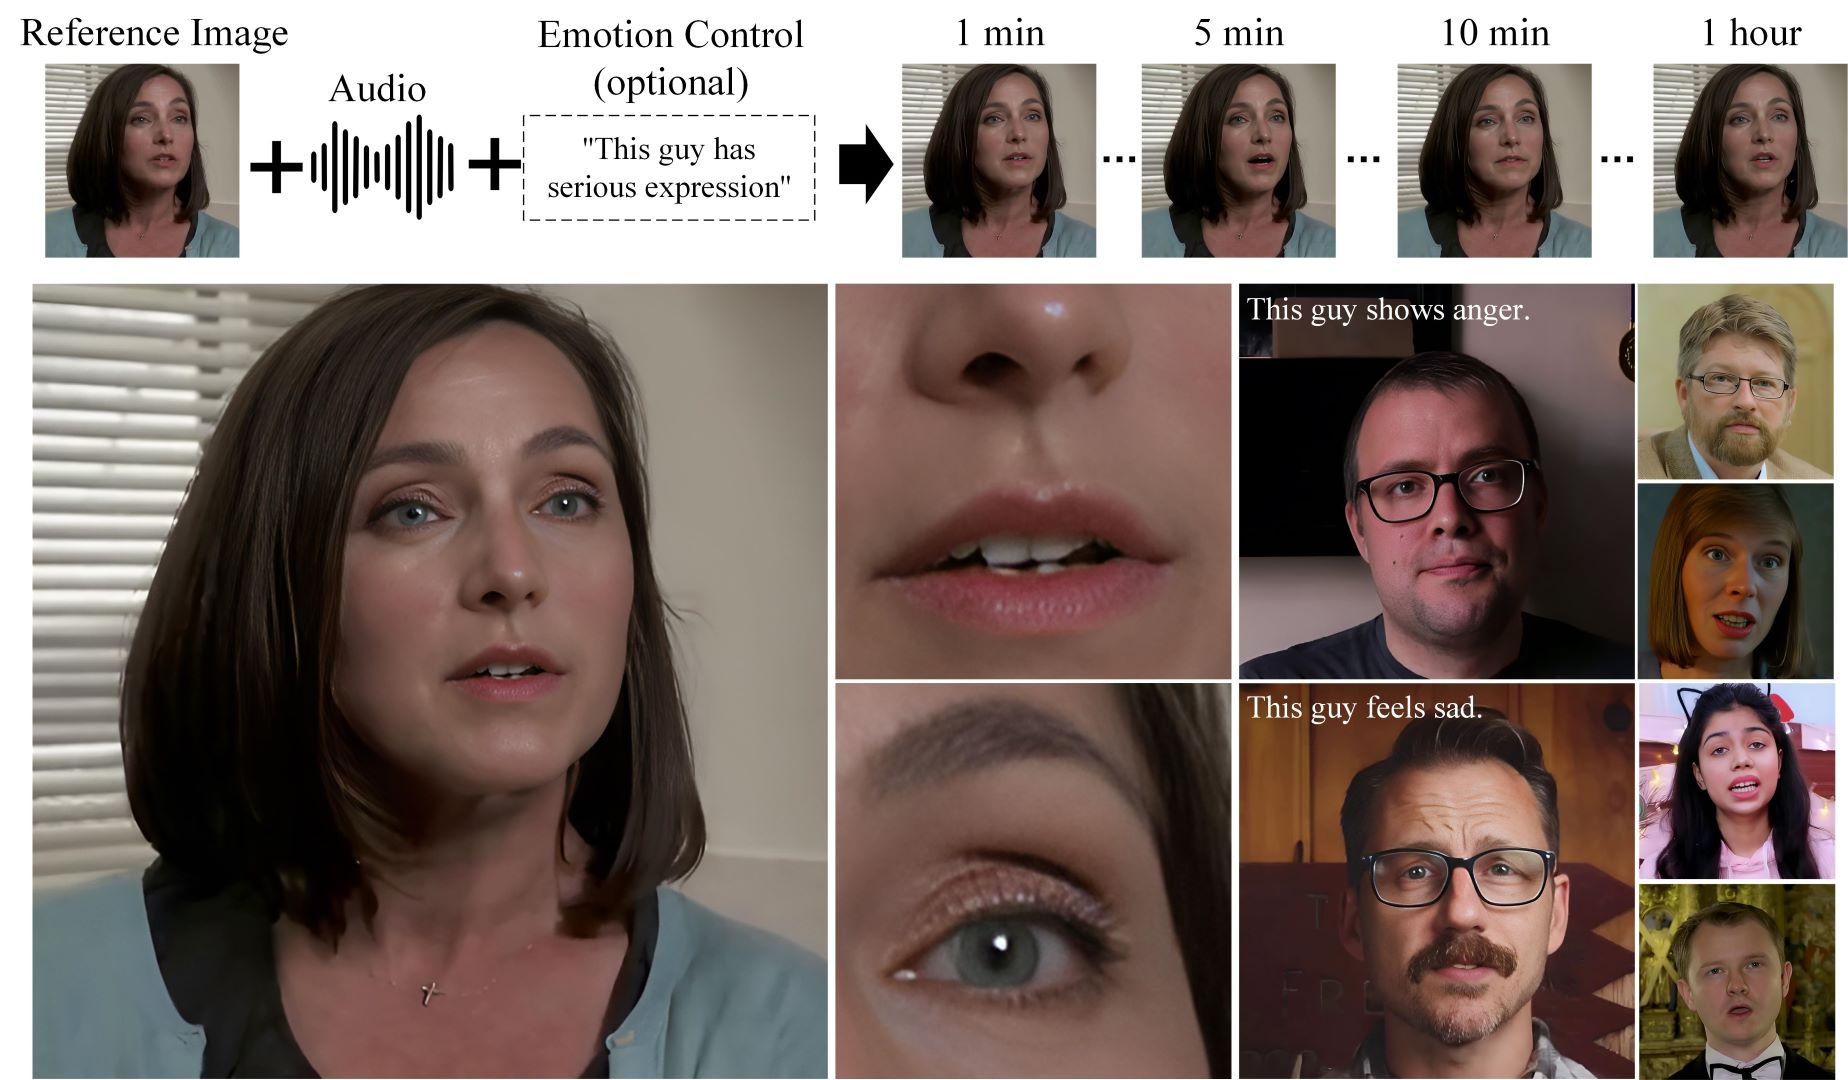
|
| 61 |
+
|
| 62 |
+
## ⚙️ Installation
|
| 63 |
+
|
| 64 |
+
- System requirement: Ubuntu 20.04/Ubuntu 22.04, Cuda 11.8
|
| 65 |
+
- Tested GPUs: A100
|
| 66 |
+
|
| 67 |
+
Create conda environment:
|
| 68 |
+
|
| 69 |
+
```bash
|
| 70 |
+
conda create -n hallo python=3.10
|
| 71 |
+
conda activate hallo
|
| 72 |
+
```
|
| 73 |
+
|
| 74 |
+
Install packages with `pip`
|
| 75 |
+
|
| 76 |
+
```bash
|
| 77 |
+
pip install torch==2.2.2 torchvision==0.17.2 torchaudio==2.2.2 --index-url https://download.pytorch.org/whl/cu118
|
| 78 |
+
pip install -r requirements.txt
|
| 79 |
+
```
|
| 80 |
+
|
| 81 |
+
Besides, ffmpeg is also needed:
|
| 82 |
+
|
| 83 |
+
```bash
|
| 84 |
+
apt-get install ffmpeg
|
| 85 |
+
```
|
| 86 |
+
|
| 87 |
+
### 📥 Download Pretrained Models
|
| 88 |
+
|
| 89 |
+
You can easily get all pretrained models required by inference from our [HuggingFace repo](https://huggingface.co/fudan-generative-ai/hallo2).
|
| 90 |
+
|
| 91 |
+
Clone the pretrained models into `${PROJECT_ROOT}/pretrained_models` directory by cmd below:
|
| 92 |
+
|
| 93 |
+
```shell
|
| 94 |
+
git lfs install
|
| 95 |
+
git clone https://huggingface.co/fudan-generative-ai/hallo2 pretrained_models
|
| 96 |
+
```
|
| 97 |
+
|
| 98 |
+
Or you can download them separately from their source repo:
|
| 99 |
+
|
| 100 |
+
- [hallo](https://huggingface.co/fudan-generative-ai/hallo2/tree/main/hallo2): Our checkpoints consist of denoising UNet, face locator, image & audio proj.
|
| 101 |
+
- [audio_separator](https://huggingface.co/huangjackson/Kim_Vocal_2): Kim*Vocal_2 MDX-Net vocal removal model. (\_Thanks to [KimberleyJensen](https://github.com/KimberleyJensen)*)
|
| 102 |
+
- [insightface](https://github.com/deepinsight/insightface/tree/master/python-package#model-zoo): 2D and 3D Face Analysis placed into `pretrained_models/face_analysis/models/`. (_Thanks to deepinsight_)
|
| 103 |
+
- [face landmarker](https://storage.googleapis.com/mediapipe-models/face_landmarker/face_landmarker/float16/1/face_landmarker.task): Face detection & mesh model from [mediapipe](https://ai.google.dev/edge/mediapipe/solutions/vision/face_landmarker#models) placed into `pretrained_models/face_analysis/models`.
|
| 104 |
+
- [motion module](https://github.com/guoyww/AnimateDiff/blob/main/README.md#202309-animatediff-v2): motion module from [AnimateDiff](https://github.com/guoyww/AnimateDiff). (_Thanks to [guoyww](https://github.com/guoyww)_).
|
| 105 |
+
- [sd-vae-ft-mse](https://huggingface.co/stabilityai/sd-vae-ft-mse): Weights are intended to be used with the diffusers library. (_Thanks to [stablilityai](https://huggingface.co/stabilityai)_)
|
| 106 |
+
- [StableDiffusion V1.5](https://huggingface.co/runwayml/stable-diffusion-v1-5): Initialized and fine-tuned from Stable-Diffusion-v1-2. (_Thanks to [runwayml](https://huggingface.co/runwayml)_)
|
| 107 |
+
- [wav2vec](https://huggingface.co/facebook/wav2vec2-base-960h): wav audio to vector model from [Facebook](https://huggingface.co/facebook/wav2vec2-base-960h).
|
| 108 |
+
- [facelib](https://github.com/sczhou/CodeFormer/releases/tag/v0.1.0): pretrained face parse models
|
| 109 |
+
- [realesrgan](https://github.com/sczhou/CodeFormer/releases/download/v0.1.0/RealESRGAN_x2plus.pth): background upsample model
|
| 110 |
+
- [CodeFormer](https://github.com/sczhou/CodeFormer/releases/download/v0.1.0): pretrained [Codeformer](https://github.com/sczhou/CodeFormer) model, it's optional to download it, only if you want to train our video super-resolution model from scratch
|
| 111 |
+
|
| 112 |
+
Finally, these pretrained models should be organized as follows:
|
| 113 |
+
|
| 114 |
+
```text
|
| 115 |
+
./pretrained_models/
|
| 116 |
+
|-- audio_separator/
|
| 117 |
+
| |-- download_checks.json
|
| 118 |
+
| |-- mdx_model_data.json
|
| 119 |
+
| |-- vr_model_data.json
|
| 120 |
+
| `-- Kim_Vocal_2.onnx
|
| 121 |
+
|-- CodeFormer/
|
| 122 |
+
| |-- codeformer.pth
|
| 123 |
+
| `-- vqgan_code1024.pth
|
| 124 |
+
|-- face_analysis/
|
| 125 |
+
| `-- models/
|
| 126 |
+
| |-- face_landmarker_v2_with_blendshapes.task # face landmarker model from mediapipe
|
| 127 |
+
| |-- 1k3d68.onnx
|
| 128 |
+
| |-- 2d106det.onnx
|
| 129 |
+
| |-- genderage.onnx
|
| 130 |
+
| |-- glintr100.onnx
|
| 131 |
+
| `-- scrfd_10g_bnkps.onnx
|
| 132 |
+
|-- facelib
|
| 133 |
+
| |-- detection_mobilenet0.25_Final.pth
|
| 134 |
+
| |-- detection_Resnet50_Final.pth
|
| 135 |
+
| |-- parsing_parsenet.pth
|
| 136 |
+
| |-- yolov5l-face.pth
|
| 137 |
+
| `-- yolov5n-face.pth
|
| 138 |
+
|-- hallo2
|
| 139 |
+
| |-- net_g.pth
|
| 140 |
+
| `-- net.pth
|
| 141 |
+
|-- motion_module/
|
| 142 |
+
| `-- mm_sd_v15_v2.ckpt
|
| 143 |
+
|-- realesrgan
|
| 144 |
+
| `-- RealESRGAN_x2plus.pth
|
| 145 |
+
|-- sd-vae-ft-mse/
|
| 146 |
+
| |-- config.json
|
| 147 |
+
| `-- diffusion_pytorch_model.safetensors
|
| 148 |
+
|-- stable-diffusion-v1-5/
|
| 149 |
+
| `-- unet/
|
| 150 |
+
| |-- config.json
|
| 151 |
+
| `-- diffusion_pytorch_model.safetensors
|
| 152 |
+
`-- wav2vec/
|
| 153 |
+
`-- wav2vec2-base-960h/
|
| 154 |
+
|-- config.json
|
| 155 |
+
|-- feature_extractor_config.json
|
| 156 |
+
|-- model.safetensors
|
| 157 |
+
|-- preprocessor_config.json
|
| 158 |
+
|-- special_tokens_map.json
|
| 159 |
+
|-- tokenizer_config.json
|
| 160 |
+
`-- vocab.json
|
| 161 |
+
```
|
| 162 |
+
|
| 163 |
+
### 🛠️ Prepare Inference Data
|
| 164 |
+
|
| 165 |
+
Hallo has a few simple requirements for input data:
|
| 166 |
+
|
| 167 |
+
For the source image:
|
| 168 |
+
|
| 169 |
+
1. It should be cropped into squares.
|
| 170 |
+
2. The face should be the main focus, making up 50%-70% of the image.
|
| 171 |
+
3. The face should be facing forward, with a rotation angle of less than 30° (no side profiles).
|
| 172 |
+
|
| 173 |
+
For the driving audio:
|
| 174 |
+
|
| 175 |
+
1. It must be in WAV format.
|
| 176 |
+
2. It must be in English since our training datasets are only in this language.
|
| 177 |
+
3. Ensure the vocals are clear; background music is acceptable.
|
| 178 |
+
|
| 179 |
+
We have provided [some samples](examples/) for your reference.
|
| 180 |
+
|
| 181 |
+
### 🎮 Run Inference
|
| 182 |
+
|
| 183 |
+
#### Long-Duration animation
|
| 184 |
+
|
| 185 |
+
Simply to run the `scripts/inference_long.py` and change `source_image`, `driving_audio` and `save_path` in the config file:
|
| 186 |
+
|
| 187 |
+
```bash
|
| 188 |
+
python scripts/inference_long.py --config ./configs/inference/long.yaml
|
| 189 |
+
```
|
| 190 |
+
|
| 191 |
+
Animation results will be saved at `save_path`. You can find more examples for inference at [examples folder](https://github.com/fudan-generative-vision/hallo2/tree/main/examples).
|
| 192 |
+
|
| 193 |
+
For more options:
|
| 194 |
+
|
| 195 |
+
```shell
|
| 196 |
+
usage: inference_long.py [-h] [-c CONFIG] [--source_image SOURCE_IMAGE] [--driving_audio DRIVING_AUDIO] [--pose_weight POSE_WEIGHT]
|
| 197 |
+
[--face_weight FACE_WEIGHT] [--lip_weight LIP_WEIGHT] [--face_expand_ratio FACE_EXPAND_RATIO]
|
| 198 |
+
|
| 199 |
+
options:
|
| 200 |
+
-h, --help show this help message and exit
|
| 201 |
+
-c CONFIG, --config CONFIG
|
| 202 |
+
--source_image SOURCE_IMAGE
|
| 203 |
+
source image
|
| 204 |
+
--driving_audio DRIVING_AUDIO
|
| 205 |
+
driving audio
|
| 206 |
+
--pose_weight POSE_WEIGHT
|
| 207 |
+
weight of pose
|
| 208 |
+
--face_weight FACE_WEIGHT
|
| 209 |
+
weight of face
|
| 210 |
+
--lip_weight LIP_WEIGHT
|
| 211 |
+
weight of lip
|
| 212 |
+
--face_expand_ratio FACE_EXPAND_RATIO
|
| 213 |
+
face region
|
| 214 |
+
```
|
| 215 |
+
|
| 216 |
+
#### High-Resolution animation
|
| 217 |
+
|
| 218 |
+
Simply to run the `scripts/video_sr.py` and pass `input_video` and `output_path`:
|
| 219 |
+
|
| 220 |
+
```bash
|
| 221 |
+
python scripts/video_sr.py --input_path [input_video] --output_path [output_dir] --bg_upsampler realesrgan --face_upsample -w 1 -s 4
|
| 222 |
+
```
|
| 223 |
+
|
| 224 |
+
Animation results will be saved at `output_dir`.
|
| 225 |
+
|
| 226 |
+
For more options:
|
| 227 |
+
|
| 228 |
+
```shell
|
| 229 |
+
usage: video_sr.py [-h] [-i INPUT_PATH] [-o OUTPUT_PATH] [-w FIDELITY_WEIGHT] [-s UPSCALE] [--has_aligned] [--only_center_face] [--draw_box]
|
| 230 |
+
[--detection_model DETECTION_MODEL] [--bg_upsampler BG_UPSAMPLER] [--face_upsample] [--bg_tile BG_TILE] [--suffix SUFFIX]
|
| 231 |
+
|
| 232 |
+
options:
|
| 233 |
+
-h, --help show this help message and exit
|
| 234 |
+
-i INPUT_PATH, --input_path INPUT_PATH
|
| 235 |
+
Input video
|
| 236 |
+
-o OUTPUT_PATH, --output_path OUTPUT_PATH
|
| 237 |
+
Output folder.
|
| 238 |
+
-w FIDELITY_WEIGHT, --fidelity_weight FIDELITY_WEIGHT
|
| 239 |
+
Balance the quality and fidelity. Default: 0.5
|
| 240 |
+
-s UPSCALE, --upscale UPSCALE
|
| 241 |
+
The final upsampling scale of the image. Default: 2
|
| 242 |
+
--has_aligned Input are cropped and aligned faces. Default: False
|
| 243 |
+
--only_center_face Only restore the center face. Default: False
|
| 244 |
+
--draw_box Draw the bounding box for the detected faces. Default: False
|
| 245 |
+
--detection_model DETECTION_MODEL
|
| 246 |
+
Face detector. Optional: retinaface_resnet50, retinaface_mobile0.25, YOLOv5l, YOLOv5n. Default: retinaface_resnet50
|
| 247 |
+
--bg_upsampler BG_UPSAMPLER
|
| 248 |
+
Background upsampler. Optional: realesrgan
|
| 249 |
+
--face_upsample Face upsampler after enhancement. Default: False
|
| 250 |
+
--bg_tile BG_TILE Tile size for background sampler. Default: 400
|
| 251 |
+
--suffix SUFFIX Suffix of the restored faces. Default: None
|
| 252 |
+
```
|
| 253 |
+
|
| 254 |
+
> NOTICE: The High-Resolution animation feature is a modified version of [CodeFormer](https://github.com/sczhou/CodeFormer). When using or redistributing this feature, please comply with the [S-Lab License 1.0](https://github.com/sczhou/CodeFormer?tab=License-1-ov-file). We kindly request that you respect the terms of this license in any usage or redistribution of this component.
|
| 255 |
+
|
| 256 |
+
## Training
|
| 257 |
+
|
| 258 |
+
### Long-Duration animation
|
| 259 |
+
|
| 260 |
+
#### prepare data for training
|
| 261 |
+
|
| 262 |
+
The training data, which utilizes some talking-face videos similar to the source images used for inference, also needs to meet the following requirements:
|
| 263 |
+
|
| 264 |
+
1. It should be cropped into squares.
|
| 265 |
+
2. The face should be the main focus, making up 50%-70% of the image.
|
| 266 |
+
3. The face should be facing forward, with a rotation angle of less than 30° (no side profiles).
|
| 267 |
+
|
| 268 |
+
Organize your raw videos into the following directory structure:
|
| 269 |
+
|
| 270 |
+
```text
|
| 271 |
+
dataset_name/
|
| 272 |
+
|-- videos/
|
| 273 |
+
| |-- 0001.mp4
|
| 274 |
+
| |-- 0002.mp4
|
| 275 |
+
| |-- 0003.mp4
|
| 276 |
+
| `-- 0004.mp4
|
| 277 |
+
```
|
| 278 |
+
|
| 279 |
+
You can use any `dataset_name`, but ensure the `videos` directory is named as shown above.
|
| 280 |
+
|
| 281 |
+
Next, process the videos with the following commands:
|
| 282 |
+
|
| 283 |
+
```bash
|
| 284 |
+
python -m scripts.data_preprocess --input_dir dataset_name/videos --step 1
|
| 285 |
+
python -m scripts.data_preprocess --input_dir dataset_name/videos --step 2
|
| 286 |
+
```
|
| 287 |
+
|
| 288 |
+
**Note:** Execute steps 1 and 2 sequentially as they perform different tasks. Step 1 converts videos into frames, extracts audio from each video, and generates the necessary masks. Step 2 generates face embeddings using InsightFace and audio embeddings using Wav2Vec, and requires a GPU. For parallel processing, use the `-p` and `-r` arguments. The `-p` argument specifies the total number of instances to launch, dividing the data into `p` parts. The `-r` argument specifies which part the current process should handle. You need to manually launch multiple instances with different values for `-r`.
|
| 289 |
+
|
| 290 |
+
Generate the metadata JSON files with the following commands:
|
| 291 |
+
|
| 292 |
+
```bash
|
| 293 |
+
python scripts/extract_meta_info_stage1.py -r path/to/dataset -n dataset_name
|
| 294 |
+
python scripts/extract_meta_info_stage2.py -r path/to/dataset -n dataset_name
|
| 295 |
+
```
|
| 296 |
+
|
| 297 |
+
Replace `path/to/dataset` with the path to the parent directory of `videos`, such as `dataset_name` in the example above. This will generate `dataset_name_stage1.json` and `dataset_name_stage2.json` in the `./data` directory.
|
| 298 |
+
|
| 299 |
+
#### Training
|
| 300 |
+
|
| 301 |
+
Update the data meta path settings in the configuration YAML files, `configs/train/stage1.yaml` and `configs/train/stage2_long.yaml`:
|
| 302 |
+
|
| 303 |
+
```yaml
|
| 304 |
+
#stage1.yaml
|
| 305 |
+
data:
|
| 306 |
+
meta_paths:
|
| 307 |
+
- ./data/dataset_name_stage1.json
|
| 308 |
+
|
| 309 |
+
#stage2.yaml
|
| 310 |
+
data:
|
| 311 |
+
meta_paths:
|
| 312 |
+
- ./data/dataset_name_stage2.json
|
| 313 |
+
```
|
| 314 |
+
|
| 315 |
+
Start training with the following command:
|
| 316 |
+
|
| 317 |
+
```shell
|
| 318 |
+
accelerate launch -m \
|
| 319 |
+
--config_file accelerate_config.yaml \
|
| 320 |
+
--machine_rank 0 \
|
| 321 |
+
--main_process_ip 0.0.0.0 \
|
| 322 |
+
--main_process_port 20055 \
|
| 323 |
+
--num_machines 1 \
|
| 324 |
+
--num_processes 8 \
|
| 325 |
+
scripts.train_stage1 --config ./configs/train/stage1.yaml
|
| 326 |
+
```
|
| 327 |
+
|
| 328 |
+
##### Accelerate Usage Explanation
|
| 329 |
+
|
| 330 |
+
The `accelerate launch` command is used to start the training process with distributed settings.
|
| 331 |
+
|
| 332 |
+
```shell
|
| 333 |
+
accelerate launch [arguments] {training_script} --{training_script-argument-1} --{training_script-argument-2} ...
|
| 334 |
+
```
|
| 335 |
+
|
| 336 |
+
**Arguments for Accelerate:**
|
| 337 |
+
|
| 338 |
+
- `-m, --module`: Interpret the launch script as a Python module.
|
| 339 |
+
- `--config_file`: Configuration file for Hugging Face Accelerate.
|
| 340 |
+
- `--machine_rank`: Rank of the current machine in a multi-node setup.
|
| 341 |
+
- `--main_process_ip`: IP address of the master node.
|
| 342 |
+
- `--main_process_port`: Port of the master node.
|
| 343 |
+
- `--num_machines`: Total number of nodes participating in the training.
|
| 344 |
+
- `--num_processes`: Total number of processes for training, matching the total number of GPUs across all machines.
|
| 345 |
+
|
| 346 |
+
**Arguments for Training:**
|
| 347 |
+
|
| 348 |
+
- `{training_script}`: The training script, such as `scripts.train_stage1` or `scripts.train_stage2`.
|
| 349 |
+
- `--{training_script-argument-1}`: Arguments specific to the training script. Our training scripts accept one argument, `--config`, to specify the training configuration file.
|
| 350 |
+
|
| 351 |
+
For multi-node training, you need to manually run the command with different `machine_rank` on each node separately.
|
| 352 |
+
|
| 353 |
+
For more settings, refer to the [Accelerate documentation](https://huggingface.co/docs/accelerate/en/index).
|
| 354 |
+
|
| 355 |
+
### High-Resolution animation
|
| 356 |
+
|
| 357 |
+
#### Training
|
| 358 |
+
|
| 359 |
+
##### prepare data for training
|
| 360 |
+
|
| 361 |
+
We use the VFHQ dataset for training, you can download from its [homepage](https://liangbinxie.github.io/projects/vfhq/). Then updata `dataroot_gt` in `./configs/train/video_sr.yaml`.
|
| 362 |
+
|
| 363 |
+
#### training
|
| 364 |
+
|
| 365 |
+
Start training with the following command:
|
| 366 |
+
|
| 367 |
+
```shell
|
| 368 |
+
python -m torch.distributed.launch --nproc_per_node=8 --master_port=4322 \
|
| 369 |
+
basicsr/train.py -opt ./configs/train/video_sr.yaml \
|
| 370 |
+
--launcher pytorch
|
| 371 |
+
```
|
| 372 |
+
|
| 373 |
+
## 📝 Citation
|
| 374 |
+
|
| 375 |
+
If you find our work useful for your research, please consider citing the paper:
|
| 376 |
+
|
| 377 |
+
```
|
| 378 |
+
@misc{cui2024hallo2,
|
| 379 |
+
title={Hallo2: Long-Duration and High-Resolution Audio-driven Portrait Image Animation},
|
| 380 |
+
author={Jiahao Cui and Hui Li and Yao Yao and Hao Zhu and Hanlin Shang and Kaihui Cheng and Hang Zhou and Siyu Zhu and️ Jingdong Wang},
|
| 381 |
+
year={2024},
|
| 382 |
+
eprint={2410.07718},
|
| 383 |
+
archivePrefix={arXiv},
|
| 384 |
+
primaryClass={cs.CV}
|
| 385 |
+
}
|
| 386 |
+
```
|
| 387 |
+
|
| 388 |
+
## 🌟 Opportunities Available
|
| 389 |
+
|
| 390 |
+
Multiple research positions are open at the **Generative Vision Lab, Fudan University**! Include:
|
| 391 |
+
|
| 392 |
+
- Research assistant
|
| 393 |
+
- Postdoctoral researcher
|
| 394 |
+
- PhD candidate
|
| 395 |
+
- Master students
|
| 396 |
+
|
| 397 |
+
Interested individuals are encouraged to contact us at [siyuzhu@fudan.edu.cn](mailto://siyuzhu@fudan.edu.cn) for further information.
|
| 398 |
+
|
| 399 |
+
## ⚠️ Social Risks and Mitigations
|
| 400 |
+
|
| 401 |
+
The development of portrait image animation technologies driven by audio inputs poses social risks, such as the ethical implications of creating realistic portraits that could be misused for deepfakes. To mitigate these risks, it is crucial to establish ethical guidelines and responsible use practices. Privacy and consent concerns also arise from using individuals' images and voices. Addressing these involves transparent data usage policies, informed consent, and safeguarding privacy rights. By addressing these risks and implementing mitigations, the research aims to ensure the responsible and ethical development of this technology.
|
| 402 |
+
|
| 403 |
+
## 🤗 Acknowledgements
|
| 404 |
+
|
| 405 |
+
We would like to thank the contributors to the [magic-animate](https://github.com/magic-research/magic-animate), [AnimateDiff](https://github.com/guoyww/AnimateDiff), [ultimatevocalremovergui](https://github.com/Anjok07/ultimatevocalremovergui), [AniPortrait](https://github.com/Zejun-Yang/AniPortrait) and [Moore-AnimateAnyone](https://github.com/MooreThreads/Moore-AnimateAnyone) repositories, for their open research and exploration.
|
| 406 |
+
|
| 407 |
+
If we missed any open-source projects or related articles, we would like to complement the acknowledgement of this specific work immediately.
|
| 408 |
+
|
| 409 |
+
## 👏 Community Contributors
|
| 410 |
+
|
| 411 |
+
Thank you to all the contributors who have helped to make this project better!
|
| 412 |
+
|
| 413 |
+
<a href="https://github.com/fudan-generative-vision/hallo2/graphs/contributors">
|
| 414 |
+
<img src="https://contrib.rocks/image?repo=fudan-generative-vision/hallo2" />
|
| 415 |
+
</a>
|
| 416 |
+
|
audio_separator/Kim_Vocal_2.onnx
ADDED
|
@@ -0,0 +1,3 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
version https://git-lfs.github.com/spec/v1
|
| 2 |
+
oid sha256:ce74ef3b6a6024ce44211a07be9cf8bc6d87728cc852a68ab34eb8e58cde9c8b
|
| 3 |
+
size 66759214
|
audio_separator/download_checks.json
ADDED
|
@@ -0,0 +1,231 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
{
|
| 2 |
+
"current_version": "UVR_Patch_10_6_23_4_27",
|
| 3 |
+
"current_version_ocl": "UVR_Patch_10_6_23_4_27",
|
| 4 |
+
"current_version_mac": "UVR_Patch_10_6_23_4_27",
|
| 5 |
+
"current_version_linux": "UVR_Patch_10_6_23_4_27",
|
| 6 |
+
"vr_download_list": {
|
| 7 |
+
"VR Arch Single Model v5: 1_HP-UVR": "1_HP-UVR.pth",
|
| 8 |
+
"VR Arch Single Model v5: 2_HP-UVR": "2_HP-UVR.pth",
|
| 9 |
+
"VR Arch Single Model v5: 3_HP-Vocal-UVR": "3_HP-Vocal-UVR.pth",
|
| 10 |
+
"VR Arch Single Model v5: 4_HP-Vocal-UVR": "4_HP-Vocal-UVR.pth",
|
| 11 |
+
"VR Arch Single Model v5: 5_HP-Karaoke-UVR": "5_HP-Karaoke-UVR.pth",
|
| 12 |
+
"VR Arch Single Model v5: 6_HP-Karaoke-UVR": "6_HP-Karaoke-UVR.pth",
|
| 13 |
+
"VR Arch Single Model v5: 7_HP2-UVR": "7_HP2-UVR.pth",
|
| 14 |
+
"VR Arch Single Model v5: 8_HP2-UVR": "8_HP2-UVR.pth",
|
| 15 |
+
"VR Arch Single Model v5: 9_HP2-UVR": "9_HP2-UVR.pth",
|
| 16 |
+
"VR Arch Single Model v5: 10_SP-UVR-2B-32000-1": "10_SP-UVR-2B-32000-1.pth",
|
| 17 |
+
"VR Arch Single Model v5: 11_SP-UVR-2B-32000-2": "11_SP-UVR-2B-32000-2.pth",
|
| 18 |
+
"VR Arch Single Model v5: 12_SP-UVR-3B-44100": "12_SP-UVR-3B-44100.pth",
|
| 19 |
+
"VR Arch Single Model v5: 13_SP-UVR-4B-44100-1": "13_SP-UVR-4B-44100-1.pth",
|
| 20 |
+
"VR Arch Single Model v5: 14_SP-UVR-4B-44100-2": "14_SP-UVR-4B-44100-2.pth",
|
| 21 |
+
"VR Arch Single Model v5: 15_SP-UVR-MID-44100-1": "15_SP-UVR-MID-44100-1.pth",
|
| 22 |
+
"VR Arch Single Model v5: 16_SP-UVR-MID-44100-2": "16_SP-UVR-MID-44100-2.pth",
|
| 23 |
+
"VR Arch Single Model v5: 17_HP-Wind_Inst-UVR": "17_HP-Wind_Inst-UVR.pth",
|
| 24 |
+
"VR Arch Single Model v5: UVR-De-Echo-Aggressive by FoxJoy": "UVR-De-Echo-Aggressive.pth",
|
| 25 |
+
"VR Arch Single Model v5: UVR-De-Echo-Normal by FoxJoy": "UVR-De-Echo-Normal.pth",
|
| 26 |
+
"VR Arch Single Model v5: UVR-DeEcho-DeReverb by FoxJoy": "UVR-DeEcho-DeReverb.pth",
|
| 27 |
+
"VR Arch Single Model v5: UVR-DeNoise-Lite by FoxJoy": "UVR-DeNoise-Lite.pth",
|
| 28 |
+
"VR Arch Single Model v5: UVR-DeNoise by FoxJoy": "UVR-DeNoise.pth",
|
| 29 |
+
"VR Arch Single Model v5: UVR-BVE-4B_SN-44100-1": "UVR-BVE-4B_SN-44100-1.pth",
|
| 30 |
+
"VR Arch Single Model v4: MGM_HIGHEND_v4": "MGM_HIGHEND_v4.pth",
|
| 31 |
+
"VR Arch Single Model v4: MGM_LOWEND_A_v4": "MGM_LOWEND_A_v4.pth",
|
| 32 |
+
"VR Arch Single Model v4: MGM_LOWEND_B_v4": "MGM_LOWEND_B_v4.pth",
|
| 33 |
+
"VR Arch Single Model v4: MGM_MAIN_v4": "MGM_MAIN_v4.pth"
|
| 34 |
+
},
|
| 35 |
+
|
| 36 |
+
"mdx_download_list": {
|
| 37 |
+
"MDX-Net Model: UVR-MDX-NET Inst HQ 1": "UVR-MDX-NET-Inst_HQ_1.onnx",
|
| 38 |
+
"MDX-Net Model: UVR-MDX-NET Inst HQ 2": "UVR-MDX-NET-Inst_HQ_2.onnx",
|
| 39 |
+
"MDX-Net Model: UVR-MDX-NET Inst HQ 3": "UVR-MDX-NET-Inst_HQ_3.onnx",
|
| 40 |
+
"MDX-Net Model: UVR-MDX-NET Inst HQ 4": "UVR-MDX-NET-Inst_HQ_4.onnx",
|
| 41 |
+
"MDX-Net Model: UVR-MDX-NET Main": "UVR_MDXNET_Main.onnx",
|
| 42 |
+
"MDX-Net Model: UVR-MDX-NET Inst Main": "UVR-MDX-NET-Inst_Main.onnx",
|
| 43 |
+
"MDX-Net Model: UVR-MDX-NET 1": "UVR_MDXNET_1_9703.onnx",
|
| 44 |
+
"MDX-Net Model: UVR-MDX-NET 2": "UVR_MDXNET_2_9682.onnx",
|
| 45 |
+
"MDX-Net Model: UVR-MDX-NET 3": "UVR_MDXNET_3_9662.onnx",
|
| 46 |
+
"MDX-Net Model: UVR-MDX-NET Inst 1": "UVR-MDX-NET-Inst_1.onnx",
|
| 47 |
+
"MDX-Net Model: UVR-MDX-NET Inst 2": "UVR-MDX-NET-Inst_2.onnx",
|
| 48 |
+
"MDX-Net Model: UVR-MDX-NET Inst 3": "UVR-MDX-NET-Inst_3.onnx",
|
| 49 |
+
"MDX-Net Model: UVR-MDX-NET Karaoke": "UVR_MDXNET_KARA.onnx",
|
| 50 |
+
"MDX-Net Model: UVR-MDX-NET Karaoke 2": "UVR_MDXNET_KARA_2.onnx",
|
| 51 |
+
"MDX-Net Model: UVR_MDXNET_9482": "UVR_MDXNET_9482.onnx",
|
| 52 |
+
"MDX-Net Model: UVR-MDX-NET Voc FT": "UVR-MDX-NET-Voc_FT.onnx",
|
| 53 |
+
"MDX-Net Model: Kim Vocal 1": "Kim_Vocal_1.onnx",
|
| 54 |
+
"MDX-Net Model: Kim Vocal 2": "Kim_Vocal_2.onnx",
|
| 55 |
+
"MDX-Net Model: Kim Inst": "Kim_Inst.onnx",
|
| 56 |
+
"MDX-Net Model: Reverb HQ By FoxJoy": "Reverb_HQ_By_FoxJoy.onnx",
|
| 57 |
+
"MDX-Net Model: UVR-MDX-NET Crowd HQ 1 By Aufr33": "UVR-MDX-NET_Crowd_HQ_1.onnx",
|
| 58 |
+
"MDX-Net Model: kuielab_a_vocals": "kuielab_a_vocals.onnx",
|
| 59 |
+
"MDX-Net Model: kuielab_a_other": "kuielab_a_other.onnx",
|
| 60 |
+
"MDX-Net Model: kuielab_a_bass": "kuielab_a_bass.onnx",
|
| 61 |
+
"MDX-Net Model: kuielab_a_drums": "kuielab_a_drums.onnx",
|
| 62 |
+
"MDX-Net Model: kuielab_b_vocals": "kuielab_b_vocals.onnx",
|
| 63 |
+
"MDX-Net Model: kuielab_b_other": "kuielab_b_other.onnx",
|
| 64 |
+
"MDX-Net Model: kuielab_b_bass": "kuielab_b_bass.onnx",
|
| 65 |
+
"MDX-Net Model: kuielab_b_drums": "kuielab_b_drums.onnx"
|
| 66 |
+
},
|
| 67 |
+
|
| 68 |
+
"demucs_download_list":{
|
| 69 |
+
|
| 70 |
+
"Demucs v4: htdemucs_ft":{
|
| 71 |
+
"f7e0c4bc-ba3fe64a.th":"https://dl.fbaipublicfiles.com/demucs/hybrid_transformer/f7e0c4bc-ba3fe64a.th",
|
| 72 |
+
"d12395a8-e57c48e6.th":"https://dl.fbaipublicfiles.com/demucs/hybrid_transformer/d12395a8-e57c48e6.th",
|
| 73 |
+
"92cfc3b6-ef3bcb9c.th":"https://dl.fbaipublicfiles.com/demucs/hybrid_transformer/92cfc3b6-ef3bcb9c.th",
|
| 74 |
+
"04573f0d-f3cf25b2.th":"https://dl.fbaipublicfiles.com/demucs/hybrid_transformer/04573f0d-f3cf25b2.th",
|
| 75 |
+
"htdemucs_ft.yaml": "https://github.com/TRvlvr/model_repo/releases/download/all_public_uvr_models/htdemucs_ft.yaml"
|
| 76 |
+
},
|
| 77 |
+
|
| 78 |
+
"Demucs v4: htdemucs":{
|
| 79 |
+
"955717e8-8726e21a.th": "https://dl.fbaipublicfiles.com/demucs/hybrid_transformer/955717e8-8726e21a.th",
|
| 80 |
+
"htdemucs.yaml": "https://github.com/TRvlvr/model_repo/releases/download/all_public_uvr_models/htdemucs.yaml"
|
| 81 |
+
},
|
| 82 |
+
|
| 83 |
+
"Demucs v4: hdemucs_mmi":{
|
| 84 |
+
"75fc33f5-1941ce65.th": "https://dl.fbaipublicfiles.com/demucs/hybrid_transformer/75fc33f5-1941ce65.th",
|
| 85 |
+
"hdemucs_mmi.yaml": "https://github.com/TRvlvr/model_repo/releases/download/all_public_uvr_models/hdemucs_mmi.yaml"
|
| 86 |
+
},
|
| 87 |
+
"Demucs v4: htdemucs_6s":{
|
| 88 |
+
"5c90dfd2-34c22ccb.th": "https://dl.fbaipublicfiles.com/demucs/hybrid_transformer/5c90dfd2-34c22ccb.th",
|
| 89 |
+
"htdemucs_6s.yaml": "https://github.com/TRvlvr/model_repo/releases/download/all_public_uvr_models/htdemucs_6s.yaml"
|
| 90 |
+
},
|
| 91 |
+
"Demucs v3: mdx":{
|
| 92 |
+
"0d19c1c6-0f06f20e.th": "https://dl.fbaipublicfiles.com/demucs/mdx_final/0d19c1c6-0f06f20e.th",
|
| 93 |
+
"7ecf8ec1-70f50cc9.th": "https://dl.fbaipublicfiles.com/demucs/mdx_final/7ecf8ec1-70f50cc9.th",
|
| 94 |
+
"c511e2ab-fe698775.th": "https://dl.fbaipublicfiles.com/demucs/mdx_final/c511e2ab-fe698775.th",
|
| 95 |
+
"7d865c68-3d5dd56b.th": "https://dl.fbaipublicfiles.com/demucs/mdx_final/7d865c68-3d5dd56b.th",
|
| 96 |
+
"mdx.yaml": "https://raw.githubusercontent.com/facebookresearch/demucs/main/demucs/remote/mdx.yaml"
|
| 97 |
+
},
|
| 98 |
+
|
| 99 |
+
"Demucs v3: mdx_q":{
|
| 100 |
+
"6b9c2ca1-3fd82607.th": "https://dl.fbaipublicfiles.com/demucs/mdx_final/6b9c2ca1-3fd82607.th",
|
| 101 |
+
"b72baf4e-8778635e.th": "https://dl.fbaipublicfiles.com/demucs/mdx_final/b72baf4e-8778635e.th",
|
| 102 |
+
"42e558d4-196e0e1b.th": "https://dl.fbaipublicfiles.com/demucs/mdx_final/42e558d4-196e0e1b.th",
|
| 103 |
+
"305bc58f-18378783.th": "https://dl.fbaipublicfiles.com/demucs/mdx_final/305bc58f-18378783.th",
|
| 104 |
+
"mdx_q.yaml": "https://raw.githubusercontent.com/facebookresearch/demucs/main/demucs/remote/mdx_q.yaml"
|
| 105 |
+
},
|
| 106 |
+
|
| 107 |
+
"Demucs v3: mdx_extra":{
|
| 108 |
+
"e51eebcc-c1b80bdd.th": "https://dl.fbaipublicfiles.com/demucs/mdx_final/e51eebcc-c1b80bdd.th",
|
| 109 |
+
"a1d90b5c-ae9d2452.th": "https://dl.fbaipublicfiles.com/demucs/mdx_final/a1d90b5c-ae9d2452.th",
|
| 110 |
+
"5d2d6c55-db83574e.th": "https://dl.fbaipublicfiles.com/demucs/mdx_final/5d2d6c55-db83574e.th",
|
| 111 |
+
"cfa93e08-61801ae1.th": "https://dl.fbaipublicfiles.com/demucs/mdx_final/cfa93e08-61801ae1.th",
|
| 112 |
+
"mdx_extra.yaml": "https://raw.githubusercontent.com/facebookresearch/demucs/main/demucs/remote/mdx_extra.yaml"
|
| 113 |
+
},
|
| 114 |
+
|
| 115 |
+
"Demucs v3: mdx_extra_q": {
|
| 116 |
+
"83fc094f-4a16d450.th": "https://dl.fbaipublicfiles.com/demucs/mdx_final/83fc094f-4a16d450.th",
|
| 117 |
+
"464b36d7-e5a9386e.th": "https://dl.fbaipublicfiles.com/demucs/mdx_final/464b36d7-e5a9386e.th",
|
| 118 |
+
"14fc6a69-a89dd0ee.th": "https://dl.fbaipublicfiles.com/demucs/mdx_final/14fc6a69-a89dd0ee.th",
|
| 119 |
+
"7fd6ef75-a905dd85.th": "https://dl.fbaipublicfiles.com/demucs/mdx_final/7fd6ef75-a905dd85.th",
|
| 120 |
+
"mdx_extra_q.yaml": "https://raw.githubusercontent.com/facebookresearch/demucs/main/demucs/remote/mdx_extra_q.yaml"
|
| 121 |
+
},
|
| 122 |
+
|
| 123 |
+
"Demucs v3: UVR Model":{
|
| 124 |
+
"ebf34a2db.th": "https://github.com/TRvlvr/model_repo/releases/download/all_public_uvr_models/ebf34a2db.th",
|
| 125 |
+
"UVR_Demucs_Model_1.yaml": "https://github.com/TRvlvr/model_repo/releases/download/all_public_uvr_models/UVR_Demucs_Model_1.yaml"
|
| 126 |
+
},
|
| 127 |
+
|
| 128 |
+
"Demucs v3: repro_mdx_a":{
|
| 129 |
+
"9a6b4851-03af0aa6.th": "https://dl.fbaipublicfiles.com/demucs/mdx_final/9a6b4851-03af0aa6.th",
|
| 130 |
+
"1ef250f1-592467ce.th": "https://dl.fbaipublicfiles.com/demucs/mdx_final/1ef250f1-592467ce.th",
|
| 131 |
+
"fa0cb7f9-100d8bf4.th": "https://dl.fbaipublicfiles.com/demucs/mdx_final/fa0cb7f9-100d8bf4.th",
|
| 132 |
+
"902315c2-b39ce9c9.th": "https://dl.fbaipublicfiles.com/demucs/mdx_final/902315c2-b39ce9c9.th",
|
| 133 |
+
"repro_mdx_a.yaml": "https://github.com/TRvlvr/model_repo/releases/download/all_public_uvr_models/repro_mdx_a.yaml"
|
| 134 |
+
},
|
| 135 |
+
|
| 136 |
+
"Demucs v3: repro_mdx_a_time_only":{
|
| 137 |
+
"9a6b4851-03af0aa6.th":"https://dl.fbaipublicfiles.com/demucs/mdx_final/9a6b4851-03af0aa6.th",
|
| 138 |
+
"1ef250f1-592467ce.th":"https://dl.fbaipublicfiles.com/demucs/mdx_final/1ef250f1-592467ce.th",
|
| 139 |
+
"repro_mdx_a_time_only.yaml": "https://github.com/TRvlvr/model_repo/releases/download/all_public_uvr_models/repro_mdx_a_time_only.yaml"
|
| 140 |
+
},
|
| 141 |
+
|
| 142 |
+
"Demucs v3: repro_mdx_a_hybrid_only":{
|
| 143 |
+
"fa0cb7f9-100d8bf4.th":"https://dl.fbaipublicfiles.com/demucs/mdx_final/fa0cb7f9-100d8bf4.th",
|
| 144 |
+
"902315c2-b39ce9c9.th":"https://dl.fbaipublicfiles.com/demucs/mdx_final/902315c2-b39ce9c9.th",
|
| 145 |
+
"repro_mdx_a_hybrid_only.yaml": "https://github.com/TRvlvr/model_repo/releases/download/all_public_uvr_models/repro_mdx_a_hybrid_only.yaml"
|
| 146 |
+
},
|
| 147 |
+
|
| 148 |
+
"Demucs v2: demucs": {
|
| 149 |
+
"demucs-e07c671f.th": "https://dl.fbaipublicfiles.com/demucs/v3.0/demucs-e07c671f.th"
|
| 150 |
+
},
|
| 151 |
+
|
| 152 |
+
"Demucs v2: demucs_extra": {
|
| 153 |
+
"demucs_extra-3646af93.th":"https://dl.fbaipublicfiles.com/demucs/v3.0/demucs_extra-3646af93.th"
|
| 154 |
+
},
|
| 155 |
+
|
| 156 |
+
"Demucs v2: demucs48_hq": {
|
| 157 |
+
"demucs48_hq-28a1282c.th":"https://dl.fbaipublicfiles.com/demucs/v3.0/demucs48_hq-28a1282c.th"
|
| 158 |
+
},
|
| 159 |
+
|
| 160 |
+
"Demucs v2: tasnet": {
|
| 161 |
+
"tasnet-beb46fac.th":"https://dl.fbaipublicfiles.com/demucs/v3.0/tasnet-beb46fac.th"
|
| 162 |
+
},
|
| 163 |
+
|
| 164 |
+
"Demucs v2: tasnet_extra": {
|
| 165 |
+
"tasnet_extra-df3777b2.th":"https://dl.fbaipublicfiles.com/demucs/v3.0/tasnet_extra-df3777b2.th"
|
| 166 |
+
},
|
| 167 |
+
|
| 168 |
+
"Demucs v2: demucs_unittest": {
|
| 169 |
+
"demucs_unittest-09ebc15f.th":"https://dl.fbaipublicfiles.com/demucs/v3.0/demucs_unittest-09ebc15f.th"
|
| 170 |
+
},
|
| 171 |
+
|
| 172 |
+
"Demucs v1: demucs": {
|
| 173 |
+
"demucs.th":"https://dl.fbaipublicfiles.com/demucs/v2.0/demucs.th"
|
| 174 |
+
},
|
| 175 |
+
|
| 176 |
+
"Demucs v1: demucs_extra": {
|
| 177 |
+
"demucs_extra.th":"https://dl.fbaipublicfiles.com/demucs/v2.0/demucs_extra.th"
|
| 178 |
+
},
|
| 179 |
+
|
| 180 |
+
"Demucs v1: light": {
|
| 181 |
+
"light.th":"https://dl.fbaipublicfiles.com/demucs/v2.0/light.th"
|
| 182 |
+
},
|
| 183 |
+
|
| 184 |
+
"Demucs v1: light_extra": {
|
| 185 |
+
"light_extra.th":"https://dl.fbaipublicfiles.com/demucs/v2.0/light_extra.th"
|
| 186 |
+
},
|
| 187 |
+
|
| 188 |
+
"Demucs v1: tasnet": {
|
| 189 |
+
"tasnet.th":"https://dl.fbaipublicfiles.com/demucs/v2.0/tasnet.th"
|
| 190 |
+
},
|
| 191 |
+
|
| 192 |
+
"Demucs v1: tasnet_extra": {
|
| 193 |
+
"tasnet_extra.th":"https://dl.fbaipublicfiles.com/demucs/v2.0/tasnet_extra.th"
|
| 194 |
+
}
|
| 195 |
+
},
|
| 196 |
+
|
| 197 |
+
"mdx_download_vip_list": {
|
| 198 |
+
"MDX-Net Model VIP: UVR-MDX-NET_Main_340": "UVR-MDX-NET_Main_340.onnx",
|
| 199 |
+
"MDX-Net Model VIP: UVR-MDX-NET_Main_390": "UVR-MDX-NET_Main_390.onnx",
|
| 200 |
+
"MDX-Net Model VIP: UVR-MDX-NET_Main_406": "UVR-MDX-NET_Main_406.onnx",
|
| 201 |
+
"MDX-Net Model VIP: UVR-MDX-NET_Main_427": "UVR-MDX-NET_Main_427.onnx",
|
| 202 |
+
"MDX-Net Model VIP: UVR-MDX-NET_Main_438": "UVR-MDX-NET_Main_438.onnx",
|
| 203 |
+
"MDX-Net Model VIP: UVR-MDX-NET_Inst_82_beta": "UVR-MDX-NET_Inst_82_beta.onnx",
|
| 204 |
+
"MDX-Net Model VIP: UVR-MDX-NET_Inst_90_beta": "UVR-MDX-NET_Inst_90_beta.onnx",
|
| 205 |
+
"MDX-Net Model VIP: UVR-MDX-NET_Inst_187_beta": "UVR-MDX-NET_Inst_187_beta.onnx",
|
| 206 |
+
"MDX-Net Model VIP: UVR-MDX-NET-Inst_full_292": "UVR-MDX-NET-Inst_full_292.onnx"
|
| 207 |
+
},
|
| 208 |
+
|
| 209 |
+
"mdx23_download_list": {
|
| 210 |
+
"MDX23C Model: MDX23C_D1581": {"MDX23C_D1581.ckpt":"model_2_stem_061321.yaml"}
|
| 211 |
+
},
|
| 212 |
+
|
| 213 |
+
"mdx23c_download_list": {
|
| 214 |
+
"MDX23C Model: MDX23C-InstVoc HQ": {"MDX23C-8KFFT-InstVoc_HQ.ckpt":"model_2_stem_full_band_8k.yaml"}
|
| 215 |
+
},
|
| 216 |
+
|
| 217 |
+
"roformer_download_list": {
|
| 218 |
+
"Roformer Model: BS-Roformer-Viperx-1297": {"model_bs_roformer_ep_317_sdr_12.9755.ckpt":"model_bs_roformer_ep_317_sdr_12.9755.yaml"},
|
| 219 |
+
"Roformer Model: BS-Roformer-Viperx-1296": {"model_bs_roformer_ep_368_sdr_12.9628.ckpt":"model_bs_roformer_ep_368_sdr_12.9628.yaml"},
|
| 220 |
+
"Roformer Model: BS-Roformer-Viperx-1053": {"model_bs_roformer_ep_937_sdr_10.5309.ckpt":"model_bs_roformer_ep_937_sdr_10.5309.yaml"},
|
| 221 |
+
"Roformer Model: Mel-Roformer-Viperx-1143": {"model_mel_band_roformer_ep_3005_sdr_11.4360.ckpt":"model_mel_band_roformer_ep_3005_sdr_11.4360.yaml"}
|
| 222 |
+
},
|
| 223 |
+
|
| 224 |
+
"mdx23c_download_vip_list": {
|
| 225 |
+
"MDX23C Model VIP: MDX23C_D1581": {"MDX23C_D1581.ckpt":"model_2_stem_061321.yaml"},
|
| 226 |
+
"MDX23C Model VIP: MDX23C-InstVoc HQ 2": {"MDX23C-8KFFT-InstVoc_HQ_2.ckpt":"model_2_stem_full_band_8k.yaml"}
|
| 227 |
+
},
|
| 228 |
+
|
| 229 |
+
"vr_download_vip_list": [],
|
| 230 |
+
"demucs_download_vip_list": []
|
| 231 |
+
}
|
audio_separator/mdx_model_data.json
ADDED
|
@@ -0,0 +1,384 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
{
|
| 2 |
+
"0ddfc0eb5792638ad5dc27850236c246": {
|
| 3 |
+
"compensate": 1.035,
|
| 4 |
+
"mdx_dim_f_set": 2048,
|
| 5 |
+
"mdx_dim_t_set": 8,
|
| 6 |
+
"mdx_n_fft_scale_set": 6144,
|
| 7 |
+
"primary_stem": "Vocals"
|
| 8 |
+
},
|
| 9 |
+
"26d308f91f3423a67dc69a6d12a8793d": {
|
| 10 |
+
"compensate": 1.035,
|
| 11 |
+
"mdx_dim_f_set": 2048,
|
| 12 |
+
"mdx_dim_t_set": 9,
|
| 13 |
+
"mdx_n_fft_scale_set": 8192,
|
| 14 |
+
"primary_stem": "Other"
|
| 15 |
+
},
|
| 16 |
+
"2cdd429caac38f0194b133884160f2c6": {
|
| 17 |
+
"compensate": 1.045,
|
| 18 |
+
"mdx_dim_f_set": 3072,
|
| 19 |
+
"mdx_dim_t_set": 8,
|
| 20 |
+
"mdx_n_fft_scale_set": 7680,
|
| 21 |
+
"primary_stem": "Instrumental"
|
| 22 |
+
},
|
| 23 |
+
"2f5501189a2f6db6349916fabe8c90de": {
|
| 24 |
+
"compensate": 1.035,
|
| 25 |
+
"mdx_dim_f_set": 2048,
|
| 26 |
+
"mdx_dim_t_set": 8,
|
| 27 |
+
"mdx_n_fft_scale_set": 6144,
|
| 28 |
+
"primary_stem": "Vocals",
|
| 29 |
+
"is_karaoke": true
|
| 30 |
+
},
|
| 31 |
+
"398580b6d5d973af3120df54cee6759d": {
|
| 32 |
+
"compensate": 1.75,
|
| 33 |
+
"mdx_dim_f_set": 3072,
|
| 34 |
+
"mdx_dim_t_set": 8,
|
| 35 |
+
"mdx_n_fft_scale_set": 7680,
|
| 36 |
+
"primary_stem": "Vocals"
|
| 37 |
+
},
|
| 38 |
+
"488b3e6f8bd3717d9d7c428476be2d75": {
|
| 39 |
+
"compensate": 1.035,
|
| 40 |
+
"mdx_dim_f_set": 3072,
|
| 41 |
+
"mdx_dim_t_set": 8,
|
| 42 |
+
"mdx_n_fft_scale_set": 7680,
|
| 43 |
+
"primary_stem": "Instrumental"
|
| 44 |
+
},
|
| 45 |
+
"4910e7827f335048bdac11fa967772f9": {
|
| 46 |
+
"compensate": 1.035,
|
| 47 |
+
"mdx_dim_f_set": 2048,
|
| 48 |
+
"mdx_dim_t_set": 7,
|
| 49 |
+
"mdx_n_fft_scale_set": 4096,
|
| 50 |
+
"primary_stem": "Drums"
|
| 51 |
+
},
|
| 52 |
+
"53c4baf4d12c3e6c3831bb8f5b532b93": {
|
| 53 |
+
"compensate": 1.043,
|
| 54 |
+
"mdx_dim_f_set": 3072,
|
| 55 |
+
"mdx_dim_t_set": 8,
|
| 56 |
+
"mdx_n_fft_scale_set": 7680,
|
| 57 |
+
"primary_stem": "Vocals"
|
| 58 |
+
},
|
| 59 |
+
"5d343409ef0df48c7d78cce9f0106781": {
|
| 60 |
+
"compensate": 1.075,
|
| 61 |
+
"mdx_dim_f_set": 3072,
|
| 62 |
+
"mdx_dim_t_set": 8,
|
| 63 |
+
"mdx_n_fft_scale_set": 7680,
|
| 64 |
+
"primary_stem": "Vocals"
|
| 65 |
+
},
|
| 66 |
+
"5f6483271e1efb9bfb59e4a3e6d4d098": {
|
| 67 |
+
"compensate": 1.035,
|
| 68 |
+
"mdx_dim_f_set": 2048,
|
| 69 |
+
"mdx_dim_t_set": 9,
|
| 70 |
+
"mdx_n_fft_scale_set": 6144,
|
| 71 |
+
"primary_stem": "Vocals"
|
| 72 |
+
},
|
| 73 |
+
"65ab5919372a128e4167f5e01a8fda85": {
|
| 74 |
+
"compensate": 1.035,
|
| 75 |
+
"mdx_dim_f_set": 2048,
|
| 76 |
+
"mdx_dim_t_set": 8,
|
| 77 |
+
"mdx_n_fft_scale_set": 8192,
|
| 78 |
+
"primary_stem": "Other"
|
| 79 |
+
},
|
| 80 |
+
"6703e39f36f18aa7855ee1047765621d": {
|
| 81 |
+
"compensate": 1.035,
|
| 82 |
+
"mdx_dim_f_set": 2048,
|
| 83 |
+
"mdx_dim_t_set": 9,
|
| 84 |
+
"mdx_n_fft_scale_set": 16384,
|
| 85 |
+
"primary_stem": "Bass"
|
| 86 |
+
},
|
| 87 |
+
"6b31de20e84392859a3d09d43f089515": {
|
| 88 |
+
"compensate": 1.035,
|
| 89 |
+
"mdx_dim_f_set": 2048,
|
| 90 |
+
"mdx_dim_t_set": 8,
|
| 91 |
+
"mdx_n_fft_scale_set": 6144,
|
| 92 |
+
"primary_stem": "Vocals"
|
| 93 |
+
},
|
| 94 |
+
"867595e9de46f6ab699008295df62798": {
|
| 95 |
+
"compensate": 1.03,
|
| 96 |
+
"mdx_dim_f_set": 3072,
|
| 97 |
+
"mdx_dim_t_set": 8,
|
| 98 |
+
"mdx_n_fft_scale_set": 7680,
|
| 99 |
+
"primary_stem": "Vocals"
|
| 100 |
+
},
|
| 101 |
+
"a3cd63058945e777505c01d2507daf37": {
|
| 102 |
+
"compensate": 1.03,
|
| 103 |
+
"mdx_dim_f_set": 2048,
|
| 104 |
+
"mdx_dim_t_set": 8,
|
| 105 |
+
"mdx_n_fft_scale_set": 6144,
|
| 106 |
+
"primary_stem": "Vocals"
|
| 107 |
+
},
|
| 108 |
+
"b33d9b3950b6cbf5fe90a32608924700": {
|
| 109 |
+
"compensate": 1.03,
|
| 110 |
+
"mdx_dim_f_set": 3072,
|
| 111 |
+
"mdx_dim_t_set": 8,
|
| 112 |
+
"mdx_n_fft_scale_set": 7680,
|
| 113 |
+
"primary_stem": "Vocals"
|
| 114 |
+
},
|
| 115 |
+
"c3b29bdce8c4fa17ec609e16220330ab": {
|
| 116 |
+
"compensate": 1.035,
|
| 117 |
+
"mdx_dim_f_set": 2048,
|
| 118 |
+
"mdx_dim_t_set": 8,
|
| 119 |
+
"mdx_n_fft_scale_set": 16384,
|
| 120 |
+
"primary_stem": "Bass"
|
| 121 |
+
},
|
| 122 |
+
"ceed671467c1f64ebdfac8a2490d0d52": {
|
| 123 |
+
"compensate": 1.035,
|
| 124 |
+
"mdx_dim_f_set": 3072,
|
| 125 |
+
"mdx_dim_t_set": 8,
|
| 126 |
+
"mdx_n_fft_scale_set": 7680,
|
| 127 |
+
"primary_stem": "Instrumental"
|
| 128 |
+
},
|
| 129 |
+
"d2a1376f310e4f7fa37fb9b5774eb701": {
|
| 130 |
+
"compensate": 1.035,
|
| 131 |
+
"mdx_dim_f_set": 3072,
|
| 132 |
+
"mdx_dim_t_set": 8,
|
| 133 |
+
"mdx_n_fft_scale_set": 7680,
|
| 134 |
+
"primary_stem": "Instrumental"
|
| 135 |
+
},
|
| 136 |
+
"d7bff498db9324db933d913388cba6be": {
|
| 137 |
+
"compensate": 1.035,
|
| 138 |
+
"mdx_dim_f_set": 2048,
|
| 139 |
+
"mdx_dim_t_set": 8,
|
| 140 |
+
"mdx_n_fft_scale_set": 6144,
|
| 141 |
+
"primary_stem": "Vocals"
|
| 142 |
+
},
|
| 143 |
+
"d94058f8c7f1fae4164868ae8ae66b20": {
|
| 144 |
+
"compensate": 1.035,
|
| 145 |
+
"mdx_dim_f_set": 2048,
|
| 146 |
+
"mdx_dim_t_set": 8,
|
| 147 |
+
"mdx_n_fft_scale_set": 6144,
|
| 148 |
+
"primary_stem": "Vocals"
|
| 149 |
+
},
|
| 150 |
+
"dc41ede5961d50f277eb846db17f5319": {
|
| 151 |
+
"compensate": 1.035,
|
| 152 |
+
"mdx_dim_f_set": 2048,
|
| 153 |
+
"mdx_dim_t_set": 9,
|
| 154 |
+
"mdx_n_fft_scale_set": 4096,
|
| 155 |
+
"primary_stem": "Drums"
|
| 156 |
+
},
|
| 157 |
+
"e5572e58abf111f80d8241d2e44e7fa4": {
|
| 158 |
+
"compensate": 1.028,
|
| 159 |
+
"mdx_dim_f_set": 3072,
|
| 160 |
+
"mdx_dim_t_set": 8,
|
| 161 |
+
"mdx_n_fft_scale_set": 7680,
|
| 162 |
+
"primary_stem": "Instrumental"
|
| 163 |
+
},
|
| 164 |
+
"e7324c873b1f615c35c1967f912db92a": {
|
| 165 |
+
"compensate": 1.03,
|
| 166 |
+
"mdx_dim_f_set": 3072,
|
| 167 |
+
"mdx_dim_t_set": 8,
|
| 168 |
+
"mdx_n_fft_scale_set": 7680,
|
| 169 |
+
"primary_stem": "Vocals"
|
| 170 |
+
},
|
| 171 |
+
"1c56ec0224f1d559c42fd6fd2a67b154": {
|
| 172 |
+
"compensate": 1.025,
|
| 173 |
+
"mdx_dim_f_set": 2048,
|
| 174 |
+
"mdx_dim_t_set": 8,
|
| 175 |
+
"mdx_n_fft_scale_set": 5120,
|
| 176 |
+
"primary_stem": "Instrumental"
|
| 177 |
+
},
|
| 178 |
+
"f2df6d6863d8f435436d8b561594ff49": {
|
| 179 |
+
"compensate": 1.035,
|
| 180 |
+
"mdx_dim_f_set": 3072,
|
| 181 |
+
"mdx_dim_t_set": 8,
|
| 182 |
+
"mdx_n_fft_scale_set": 7680,
|
| 183 |
+
"primary_stem": "Instrumental"
|
| 184 |
+
},
|
| 185 |
+
"b06327a00d5e5fbc7d96e1781bbdb596": {
|
| 186 |
+
"compensate": 1.035,
|
| 187 |
+
"mdx_dim_f_set": 3072,
|
| 188 |
+
"mdx_dim_t_set": 8,
|
| 189 |
+
"mdx_n_fft_scale_set": 6144,
|
| 190 |
+
"primary_stem": "Instrumental"
|
| 191 |
+
},
|
| 192 |
+
"94ff780b977d3ca07c7a343dab2e25dd": {
|
| 193 |
+
"compensate": 1.039,
|
| 194 |
+
"mdx_dim_f_set": 3072,
|
| 195 |
+
"mdx_dim_t_set": 8,
|
| 196 |
+
"mdx_n_fft_scale_set": 6144,
|
| 197 |
+
"primary_stem": "Instrumental"
|
| 198 |
+
},
|
| 199 |
+
"73492b58195c3b52d34590d5474452f6": {
|
| 200 |
+
"compensate": 1.043,
|
| 201 |
+
"mdx_dim_f_set": 3072,
|
| 202 |
+
"mdx_dim_t_set": 8,
|
| 203 |
+
"mdx_n_fft_scale_set": 7680,
|
| 204 |
+
"primary_stem": "Vocals"
|
| 205 |
+
},
|
| 206 |
+
"970b3f9492014d18fefeedfe4773cb42": {
|
| 207 |
+
"compensate": 1.009,
|
| 208 |
+
"mdx_dim_f_set": 3072,
|
| 209 |
+
"mdx_dim_t_set": 8,
|
| 210 |
+
"mdx_n_fft_scale_set": 7680,
|
| 211 |
+
"primary_stem": "Vocals"
|
| 212 |
+
},
|
| 213 |
+
"1d64a6d2c30f709b8c9b4ce1366d96ee": {
|
| 214 |
+
"compensate": 1.065,
|
| 215 |
+
"mdx_dim_f_set": 2048,
|
| 216 |
+
"mdx_dim_t_set": 8,
|
| 217 |
+
"mdx_n_fft_scale_set": 5120,
|
| 218 |
+
"primary_stem": "Instrumental",
|
| 219 |
+
"is_karaoke": true
|
| 220 |
+
},
|
| 221 |
+
"203f2a3955221b64df85a41af87cf8f0": {
|
| 222 |
+
"compensate": 1.035,
|
| 223 |
+
"mdx_dim_f_set": 3072,
|
| 224 |
+
"mdx_dim_t_set": 8,
|
| 225 |
+
"mdx_n_fft_scale_set": 6144,
|
| 226 |
+
"primary_stem": "Instrumental"
|
| 227 |
+
},
|
| 228 |
+
"291c2049608edb52648b96e27eb80e95": {
|
| 229 |
+
"compensate": 1.035,
|
| 230 |
+
"mdx_dim_f_set": 3072,
|
| 231 |
+
"mdx_dim_t_set": 8,
|
| 232 |
+
"mdx_n_fft_scale_set": 6144,
|
| 233 |
+
"primary_stem": "Instrumental"
|
| 234 |
+
},
|
| 235 |
+
"ead8d05dab12ec571d67549b3aab03fc": {
|
| 236 |
+
"compensate": 1.035,
|
| 237 |
+
"mdx_dim_f_set": 3072,
|
| 238 |
+
"mdx_dim_t_set": 8,
|
| 239 |
+
"mdx_n_fft_scale_set": 6144,
|
| 240 |
+
"primary_stem": "Instrumental"
|
| 241 |
+
},
|
| 242 |
+
"cc63408db3d80b4d85b0287d1d7c9632": {
|
| 243 |
+
"compensate": 1.033,
|
| 244 |
+
"mdx_dim_f_set": 3072,
|
| 245 |
+
"mdx_dim_t_set": 8,
|
| 246 |
+
"mdx_n_fft_scale_set": 6144,
|
| 247 |
+
"primary_stem": "Instrumental"
|
| 248 |
+
},
|
| 249 |
+
"cd5b2989ad863f116c855db1dfe24e39": {
|
| 250 |
+
"compensate": 1.035,
|
| 251 |
+
"mdx_dim_f_set": 3072,
|
| 252 |
+
"mdx_dim_t_set": 9,
|
| 253 |
+
"mdx_n_fft_scale_set": 6144,
|
| 254 |
+
"primary_stem": "Reverb"
|
| 255 |
+
},
|
| 256 |
+
"55657dd70583b0fedfba5f67df11d711": {
|
| 257 |
+
"compensate": 1.022,
|
| 258 |
+
"mdx_dim_f_set": 3072,
|
| 259 |
+
"mdx_dim_t_set": 8,
|
| 260 |
+
"mdx_n_fft_scale_set": 6144,
|
| 261 |
+
"primary_stem": "Instrumental"
|
| 262 |
+
},
|
| 263 |
+
"b6bccda408a436db8500083ef3491e8b": {
|
| 264 |
+
"compensate": 1.02,
|
| 265 |
+
"mdx_dim_f_set": 3072,
|
| 266 |
+
"mdx_dim_t_set": 8,
|
| 267 |
+
"mdx_n_fft_scale_set": 7680,
|
| 268 |
+
"primary_stem": "Instrumental"
|
| 269 |
+
},
|
| 270 |
+
"8a88db95c7fb5dbe6a095ff2ffb428b1": {
|
| 271 |
+
"compensate": 1.026,
|
| 272 |
+
"mdx_dim_f_set": 2048,
|
| 273 |
+
"mdx_dim_t_set": 8,
|
| 274 |
+
"mdx_n_fft_scale_set": 5120,
|
| 275 |
+
"primary_stem": "Instrumental"
|
| 276 |
+
},
|
| 277 |
+
"b78da4afc6512f98e4756f5977f5c6b9": {
|
| 278 |
+
"compensate": 1.021,
|
| 279 |
+
"mdx_dim_f_set": 3072,
|
| 280 |
+
"mdx_dim_t_set": 8,
|
| 281 |
+
"mdx_n_fft_scale_set": 7680,
|
| 282 |
+
"primary_stem": "Instrumental"
|
| 283 |
+
},
|
| 284 |
+
"77d07b2667ddf05b9e3175941b4454a0": {
|
| 285 |
+
"compensate": 1.021,
|
| 286 |
+
"mdx_dim_f_set": 3072,
|
| 287 |
+
"mdx_dim_t_set": 8,
|
| 288 |
+
"mdx_n_fft_scale_set": 7680,
|
| 289 |
+
"primary_stem": "Vocals"
|
| 290 |
+
},
|
| 291 |
+
"0f2a6bc5b49d87d64728ee40e23bceb1": {
|
| 292 |
+
"compensate": 1.019,
|
| 293 |
+
"mdx_dim_f_set": 2560,
|
| 294 |
+
"mdx_dim_t_set": 8,
|
| 295 |
+
"mdx_n_fft_scale_set": 5120,
|
| 296 |
+
"primary_stem": "Instrumental"
|
| 297 |
+
},
|
| 298 |
+
"b02be2d198d4968a121030cf8950b492": {
|
| 299 |
+
"compensate": 1.020,
|
| 300 |
+
"mdx_dim_f_set": 2560,
|
| 301 |
+
"mdx_dim_t_set": 8,
|
| 302 |
+
"mdx_n_fft_scale_set": 5120,
|
| 303 |
+
"primary_stem": "No Crowd"
|
| 304 |
+
},
|
| 305 |
+
"2154254ee89b2945b97a7efed6e88820": {
|
| 306 |
+
"config_yaml": "model_2_stem_061321.yaml"
|
| 307 |
+
},
|
| 308 |
+
"063aadd735d58150722926dcbf5852a9": {
|
| 309 |
+
"config_yaml": "model_2_stem_061321.yaml"
|
| 310 |
+
},
|
| 311 |
+
"c09f714d978b41d718facfe3427e6001": {
|
| 312 |
+
"config_yaml": "model_2_stem_061321.yaml"
|
| 313 |
+
},
|
| 314 |
+
"fe96801369f6a148df2720f5ced88c19": {
|
| 315 |
+
"config_yaml": "model3.yaml"
|
| 316 |
+
},
|
| 317 |
+
"02e8b226f85fb566e5db894b9931c640": {
|
| 318 |
+
"config_yaml": "model2.yaml"
|
| 319 |
+
},
|
| 320 |
+
"e3de6d861635ab9c1d766149edd680d6": {
|
| 321 |
+
"config_yaml": "model1.yaml"
|
| 322 |
+
},
|
| 323 |
+
"3f2936c554ab73ce2e396d54636bd373": {
|
| 324 |
+
"config_yaml": "modelB.yaml"
|
| 325 |
+
},
|
| 326 |
+
"890d0f6f82d7574bca741a9e8bcb8168": {
|
| 327 |
+
"config_yaml": "modelB.yaml"
|
| 328 |
+
},
|
| 329 |
+
"63a3cb8c37c474681049be4ad1ba8815": {
|
| 330 |
+
"config_yaml": "modelB.yaml"
|
| 331 |
+
},
|
| 332 |
+
"a7fc5d719743c7fd6b61bd2b4d48b9f0": {
|
| 333 |
+
"config_yaml": "modelA.yaml"
|
| 334 |
+
},
|
| 335 |
+
"3567f3dee6e77bf366fcb1c7b8bc3745": {
|
| 336 |
+
"config_yaml": "modelA.yaml"
|
| 337 |
+
},
|
| 338 |
+
"a28f4d717bd0d34cd2ff7a3b0a3d065e": {
|
| 339 |
+
"config_yaml": "modelA.yaml"
|
| 340 |
+
},
|
| 341 |
+
"c9971a18da20911822593dc81caa8be9": {
|
| 342 |
+
"config_yaml": "sndfx.yaml"
|
| 343 |
+
},
|
| 344 |
+
"57d94d5ed705460d21c75a5ac829a605": {
|
| 345 |
+
"config_yaml": "sndfx.yaml"
|
| 346 |
+
},
|
| 347 |
+
"e7a25f8764f25a52c1b96c4946e66ba2": {
|
| 348 |
+
"config_yaml": "sndfx.yaml"
|
| 349 |
+
},
|
| 350 |
+
"104081d24e37217086ce5fde09147ee1": {
|
| 351 |
+
"config_yaml": "model_2_stem_061321.yaml"
|
| 352 |
+
},
|
| 353 |
+
"1e6165b601539f38d0a9330f3facffeb": {
|
| 354 |
+
"config_yaml": "model_2_stem_061321.yaml"
|
| 355 |
+
},
|
| 356 |
+
"fe0108464ce0d8271be5ab810891bd7c": {
|
| 357 |
+
"config_yaml": "model_2_stem_full_band.yaml"
|
| 358 |
+
},
|
| 359 |
+
"e9b82ec90ee56c507a3a982f1555714c": {
|
| 360 |
+
"config_yaml": "model_2_stem_full_band_2.yaml"
|
| 361 |
+
},
|
| 362 |
+
"99b6ceaae542265a3b6d657bf9fde79f": {
|
| 363 |
+
"config_yaml": "model_2_stem_full_band_8k.yaml"
|
| 364 |
+
},
|
| 365 |
+
"116f6f9dabb907b53d847ed9f7a9475f": {
|
| 366 |
+
"config_yaml": "model_2_stem_full_band_8k.yaml"
|
| 367 |
+
},
|
| 368 |
+
"53f707017bfcbb56f5e1bfac420d6732": {
|
| 369 |
+
"config_yaml": "model_bs_roformer_ep_317_sdr_12.9755.yaml",
|
| 370 |
+
"is_roformer": true
|
| 371 |
+
},
|
| 372 |
+
"63e41acc264bf681a73aa9f7e5f606cc": {
|
| 373 |
+
"config_yaml": "model_mel_band_roformer_ep_3005_sdr_11.4360.yaml",
|
| 374 |
+
"is_roformer": true
|
| 375 |
+
},
|
| 376 |
+
"e733736763234047587931fc35322fd9": {
|
| 377 |
+
"config_yaml": "model_bs_roformer_ep_937_sdr_10.5309.yaml",
|
| 378 |
+
"is_roformer": true
|
| 379 |
+
},
|
| 380 |
+
"d789065adfd747d6f585b27b495bcdae": {
|
| 381 |
+
"config_yaml": "model_bs_roformer_ep_368_sdr_12.9628.yaml",
|
| 382 |
+
"is_roformer": true
|
| 383 |
+
}
|
| 384 |
+
}
|
audio_separator/vr_model_data.json
ADDED
|
@@ -0,0 +1,137 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
{
|
| 2 |
+
"0d0e6d143046b0eecc41a22e60224582": {
|
| 3 |
+
"vr_model_param": "3band_44100_mid",
|
| 4 |
+
"primary_stem": "Instrumental"
|
| 5 |
+
},
|
| 6 |
+
"18b52f873021a0af556fb4ecd552bb8e": {
|
| 7 |
+
"vr_model_param": "2band_32000",
|
| 8 |
+
"primary_stem": "Instrumental"
|
| 9 |
+
},
|
| 10 |
+
"1fc66027c82b499c7d8f55f79e64cadc": {
|
| 11 |
+
"vr_model_param": "2band_32000",
|
| 12 |
+
"primary_stem": "Instrumental"
|
| 13 |
+
},
|
| 14 |
+
"2aa34fbc01f8e6d2bf509726481e7142": {
|
| 15 |
+
"vr_model_param": "4band_44100",
|
| 16 |
+
"primary_stem": "No Piano"
|
| 17 |
+
},
|
| 18 |
+
"3e18f639b11abea7361db1a4a91c2559": {
|
| 19 |
+
"vr_model_param": "4band_44100",
|
| 20 |
+
"primary_stem": "Instrumental"
|
| 21 |
+
},
|
| 22 |
+
"570b5f50054609a17741369a35007ddd": {
|
| 23 |
+
"vr_model_param": "4band_v3",
|
| 24 |
+
"primary_stem": "Instrumental"
|
| 25 |
+
},
|
| 26 |
+
"5a6e24c1b530f2dab045a522ef89b751": {
|
| 27 |
+
"vr_model_param": "1band_sr44100_hl512",
|
| 28 |
+
"primary_stem": "Instrumental"
|
| 29 |
+
},
|
| 30 |
+
"6b5916069a49be3fe29d4397ecfd73fa": {
|
| 31 |
+
"vr_model_param": "3band_44100_msb2",
|
| 32 |
+
"primary_stem": "Instrumental",
|
| 33 |
+
"is_karaoke": true
|
| 34 |
+
},
|
| 35 |
+
"74b3bc5fa2b69f29baf7839b858bc679": {
|
| 36 |
+
"vr_model_param": "4band_44100",
|
| 37 |
+
"primary_stem": "Instrumental"
|
| 38 |
+
},
|
| 39 |
+
"827213b316df36b52a1f3d04fec89369": {
|
| 40 |
+
"vr_model_param": "4band_44100",
|
| 41 |
+
"primary_stem": "Instrumental"
|
| 42 |
+
},
|
| 43 |
+
"911d4048eee7223eca4ee0efb7d29256": {
|
| 44 |
+
"vr_model_param": "4band_44100",
|
| 45 |
+
"primary_stem": "Vocals"
|
| 46 |
+
},
|
| 47 |
+
"941f3f7f0b0341f12087aacdfef644b1": {
|
| 48 |
+
"vr_model_param": "4band_v2",
|
| 49 |
+
"primary_stem": "Instrumental"
|
| 50 |
+
},
|
| 51 |
+
"a02827cf69d75781a35c0e8a327f3195": {
|
| 52 |
+
"vr_model_param": "1band_sr33075_hl384",
|
| 53 |
+
"primary_stem": "Instrumental"
|
| 54 |
+
},
|
| 55 |
+
"b165fbff113c959dba5303b74c6484bc": {
|
| 56 |
+
"vr_model_param": "3band_44100",
|
| 57 |
+
"primary_stem": "Instrumental"
|
| 58 |
+
},
|
| 59 |
+
"b5f988cd3e891dca7253bf5f0f3427c7": {
|
| 60 |
+
"vr_model_param": "4band_44100",
|
| 61 |
+
"primary_stem": "Instrumental"
|
| 62 |
+
},
|
| 63 |
+
"b99c35723bc35cb11ed14a4780006a80": {
|
| 64 |
+
"vr_model_param": "1band_sr44100_hl1024",
|
| 65 |
+
"primary_stem": "Instrumental"
|
| 66 |
+
},
|
| 67 |
+
"ba02fd25b71d620eebbdb49e18e4c336": {
|
| 68 |
+
"vr_model_param": "3band_44100_mid",
|
| 69 |
+
"primary_stem": "Instrumental"
|
| 70 |
+
},
|
| 71 |
+
"c4476ef424d8cba65f38d8d04e8514e2": {
|
| 72 |
+
"vr_model_param": "3band_44100_msb2",
|
| 73 |
+
"primary_stem": "Instrumental"
|
| 74 |
+
},
|
| 75 |
+
"da2d37b8be2972e550a409bae08335aa": {
|
| 76 |
+
"vr_model_param": "4band_44100",
|
| 77 |
+
"primary_stem": "Vocals"
|
| 78 |
+
},
|
| 79 |
+
"db57205d3133e39df8e050b435a78c80": {
|
| 80 |
+
"vr_model_param": "4band_44100",
|
| 81 |
+
"primary_stem": "Instrumental"
|
| 82 |
+
},
|
| 83 |
+
"ea83b08e32ec2303456fe50659035f69": {
|
| 84 |
+
"vr_model_param": "4band_v3",
|
| 85 |
+
"primary_stem": "Instrumental"
|
| 86 |
+
},
|
| 87 |
+
"f6ea8473ff86017b5ebd586ccacf156b": {
|
| 88 |
+
"vr_model_param": "4band_v2_sn",
|
| 89 |
+
"primary_stem": "Instrumental",
|
| 90 |
+
"is_karaoke": true
|
| 91 |
+
},
|
| 92 |
+
"fd297a61eafc9d829033f8b987c39a3d": {
|
| 93 |
+
"vr_model_param": "1band_sr32000_hl512",
|
| 94 |
+
"primary_stem": "Instrumental"
|
| 95 |
+
},
|
| 96 |
+
"0ec76fd9e65f81d8b4fbd13af4826ed8": {
|
| 97 |
+
"vr_model_param": "4band_v3",
|
| 98 |
+
"primary_stem": "No Woodwinds"
|
| 99 |
+
},
|
| 100 |
+
"0fb9249ffe4ffc38d7b16243f394c0ff": {
|
| 101 |
+
"vr_model_param": "4band_v3",
|
| 102 |
+
"primary_stem": "No Reverb"
|
| 103 |
+
},
|
| 104 |
+
"6857b2972e1754913aad0c9a1678c753": {
|
| 105 |
+
"vr_model_param": "4band_v3",
|
| 106 |
+
"primary_stem": "No Echo",
|
| 107 |
+
"nout": 48,
|
| 108 |
+
"nout_lstm": 128
|
| 109 |
+
},
|
| 110 |
+
"f200a145434efc7dcf0cd093f517ed52": {
|
| 111 |
+
"vr_model_param": "4band_v3",
|
| 112 |
+
"primary_stem": "No Echo",
|
| 113 |
+
"nout": 48,
|
| 114 |
+
"nout_lstm": 128
|
| 115 |
+
},
|
| 116 |
+
"44c55d8b5d2e3edea98c2b2bf93071c7": {
|
| 117 |
+
"vr_model_param": "4band_v3",
|
| 118 |
+
"primary_stem": "Noise",
|
| 119 |
+
"nout": 48,
|
| 120 |
+
"nout_lstm": 128
|
| 121 |
+
},
|
| 122 |
+
"51ea8c43a6928ed3c10ef5cb2707d57b": {
|
| 123 |
+
"vr_model_param": "1band_sr44100_hl1024",
|
| 124 |
+
"primary_stem": "Noise",
|
| 125 |
+
"nout": 16,
|
| 126 |
+
"nout_lstm": 128
|
| 127 |
+
},
|
| 128 |
+
"944950a9c5963a5eb70b445d67b7068a": {
|
| 129 |
+
"vr_model_param": "4band_v3_sn",
|
| 130 |
+
"primary_stem": "Vocals",
|
| 131 |
+
"nout": 64,
|
| 132 |
+
"nout_lstm": 128,
|
| 133 |
+
"is_karaoke": false,
|
| 134 |
+
"is_bv_model": true,
|
| 135 |
+
"is_bv_model_rebalanced": 0.9
|
| 136 |
+
}
|
| 137 |
+
}
|
face_analysis/models/1k3d68.onnx
ADDED
|
@@ -0,0 +1,3 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
version https://git-lfs.github.com/spec/v1
|
| 2 |
+
oid sha256:df5c06b8a0c12e422b2ed8947b8869faa4105387f199c477af038aa01f9a45cc
|
| 3 |
+
size 143607619
|
face_analysis/models/2d106det.onnx
ADDED
|
@@ -0,0 +1,3 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
version https://git-lfs.github.com/spec/v1
|
| 2 |
+
oid sha256:f001b856447c413801ef5c42091ed0cd516fcd21f2d6b79635b1e733a7109dbf
|
| 3 |
+
size 5030888
|
face_analysis/models/face_landmarker_v2_with_blendshapes.task
ADDED
|
@@ -0,0 +1,3 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
version https://git-lfs.github.com/spec/v1
|
| 2 |
+
oid sha256:64184e229b263107bc2b804c6625db1341ff2bb731874b0bcc2fe6544e0bc9ff
|
| 3 |
+
size 3758596
|
face_analysis/models/genderage.onnx
ADDED
|
@@ -0,0 +1,3 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
version https://git-lfs.github.com/spec/v1
|
| 2 |
+
oid sha256:4fde69b1c810857b88c64a335084f1c3fe8f01246c9a191b48c7bb756d6652fb
|
| 3 |
+
size 1322532
|
face_analysis/models/glintr100.onnx
ADDED
|
@@ -0,0 +1,3 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
version https://git-lfs.github.com/spec/v1
|
| 2 |
+
oid sha256:4ab1d6435d639628a6f3e5008dd4f929edf4c4124b1a7169e1048f9fef534cdf
|
| 3 |
+
size 260665334
|
face_analysis/models/scrfd_10g_bnkps.onnx
ADDED
|
@@ -0,0 +1,3 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
version https://git-lfs.github.com/spec/v1
|
| 2 |
+
oid sha256:5838f7fe053675b1c7a08b633df49e7af5495cee0493c7dcf6697200b85b5b91
|
| 3 |
+
size 16923827
|
facelib/detection_Resnet50_Final.pth
ADDED
|
@@ -0,0 +1,3 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
version https://git-lfs.github.com/spec/v1
|
| 2 |
+
oid sha256:6d1de9c2944f2ccddca5f5e010ea5ae64a39845a86311af6fdf30841b0a5a16d
|
| 3 |
+
size 109497761
|
facelib/detection_mobilenet0.25_Final.pth
ADDED
|
@@ -0,0 +1,3 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
version https://git-lfs.github.com/spec/v1
|
| 2 |
+
oid sha256:2979b33ffafda5d74b6948cd7a5b9a7a62f62b949cef24e95fd15d2883a65220
|
| 3 |
+
size 1789735
|
facelib/parsing_parsenet.pth
ADDED
|
@@ -0,0 +1,3 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
version https://git-lfs.github.com/spec/v1
|
| 2 |
+
oid sha256:3d558d8d0e42c20224f13cf5a29c79eba2d59913419f945545d8cf7b72920de2
|
| 3 |
+
size 85331193
|
facelib/yolov5l-face.pth
ADDED
|
@@ -0,0 +1,3 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
version https://git-lfs.github.com/spec/v1
|
| 2 |
+
oid sha256:1ba9d2125fda4d823df5152b9fc2903c59aa76c0d3771e02bcf13a56a282cf96
|
| 3 |
+
size 186973013
|
facelib/yolov5n-face.pth
ADDED
|
@@ -0,0 +1,3 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
version https://git-lfs.github.com/spec/v1
|
| 2 |
+
oid sha256:d2bbfbe9f36cf1ec345dc69658d7209e5448a676d946f1bf7818ac50d4489357
|
| 3 |
+
size 7145625
|
hallo2/net.pth
ADDED
|
@@ -0,0 +1,3 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
version https://git-lfs.github.com/spec/v1
|
| 2 |
+
oid sha256:dcd387cb755079462a91218ac316274f9addc61728925eeee15ae893c89f55c5
|
| 3 |
+
size 4850767602
|
hallo2/net_g.pth
ADDED
|
@@ -0,0 +1,3 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
version https://git-lfs.github.com/spec/v1
|
| 2 |
+
oid sha256:14af97eedd53b2a5632def52692b645fbb9306d178afa6c8bece021a60ec7ad1
|
| 3 |
+
size 904732980
|
motion_module/mm_sd_v15_v2.ckpt
ADDED
|
@@ -0,0 +1,3 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
version https://git-lfs.github.com/spec/v1
|
| 2 |
+
oid sha256:69ed0f5fef82b110aca51bcab73b21104242bc65d6ab4b8b2a2a94d31cad1bf0
|
| 3 |
+
size 1817888431
|
realesrgan/RealESRGAN_x2plus.pth
ADDED
|
@@ -0,0 +1,3 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
version https://git-lfs.github.com/spec/v1
|
| 2 |
+
oid sha256:49fafd45f8fd7aa8d31ab2a22d14d91b536c34494a5cfe31eb5d89c2fa266abb
|
| 3 |
+
size 67061725
|
sd-vae-ft-mse/README.md
ADDED
|
@@ -0,0 +1,83 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
---
|
| 2 |
+
license: mit
|
| 3 |
+
tags:
|
| 4 |
+
- stable-diffusion
|
| 5 |
+
- stable-diffusion-diffusers
|
| 6 |
+
inference: false
|
| 7 |
+
---
|
| 8 |
+
# Improved Autoencoders
|
| 9 |
+
|
| 10 |
+
## Utilizing
|
| 11 |
+
These weights are intended to be used with the [🧨 diffusers library](https://github.com/huggingface/diffusers). If you are looking for the model to use with the original [CompVis Stable Diffusion codebase](https://github.com/CompVis/stable-diffusion), [come here](https://huggingface.co/stabilityai/sd-vae-ft-mse-original).
|
| 12 |
+
|
| 13 |
+
#### How to use with 🧨 diffusers
|
| 14 |
+
You can integrate this fine-tuned VAE decoder to your existing `diffusers` workflows, by including a `vae` argument to the `StableDiffusionPipeline`
|
| 15 |
+
```py
|
| 16 |
+
from diffusers.models import AutoencoderKL
|
| 17 |
+
from diffusers import StableDiffusionPipeline
|
| 18 |
+
|
| 19 |
+
model = "CompVis/stable-diffusion-v1-4"
|
| 20 |
+
vae = AutoencoderKL.from_pretrained("stabilityai/sd-vae-ft-mse")
|
| 21 |
+
pipe = StableDiffusionPipeline.from_pretrained(model, vae=vae)
|
| 22 |
+
```
|
| 23 |
+
|
| 24 |
+
## Decoder Finetuning
|
| 25 |
+
We publish two kl-f8 autoencoder versions, finetuned from the original [kl-f8 autoencoder](https://github.com/CompVis/latent-diffusion#pretrained-autoencoding-models) on a 1:1 ratio of [LAION-Aesthetics](https://laion.ai/blog/laion-aesthetics/) and LAION-Humans, an unreleased subset containing only SFW images of humans. The intent was to fine-tune on the Stable Diffusion training set (the autoencoder was originally trained on OpenImages) but also enrich the dataset with images of humans to improve the reconstruction of faces.
|
| 26 |
+
The first, _ft-EMA_, was resumed from the original checkpoint, trained for 313198 steps and uses EMA weights. It uses the same loss configuration as the original checkpoint (L1 + LPIPS).
|
| 27 |
+
The second, _ft-MSE_, was resumed from _ft-EMA_ and uses EMA weights and was trained for another 280k steps using a different loss, with more emphasis
|
| 28 |
+
on MSE reconstruction (MSE + 0.1 * LPIPS). It produces somewhat ``smoother'' outputs. The batch size for both versions was 192 (16 A100s, batch size 12 per GPU).
|
| 29 |
+
To keep compatibility with existing models, only the decoder part was finetuned; the checkpoints can be used as a drop-in replacement for the existing autoencoder.
|
| 30 |
+
|
| 31 |
+
_Original kl-f8 VAE vs f8-ft-EMA vs f8-ft-MSE_
|
| 32 |
+
|
| 33 |
+
## Evaluation
|
| 34 |
+
### COCO 2017 (256x256, val, 5000 images)
|
| 35 |
+
| Model | train steps | rFID | PSNR | SSIM | PSIM | Link | Comments
|
| 36 |
+
|----------|---------|------|--------------|---------------|---------------|-----------------------------------------------------------------------------------|-------------------------------------------------------------------------------------------------|
|
| 37 |
+
| | | | | | | | |
|
| 38 |
+
| original | 246803 | 4.99 | 23.4 +/- 3.8 | 0.69 +/- 0.14 | 1.01 +/- 0.28 | https://ommer-lab.com/files/latent-diffusion/kl-f8.zip | as used in SD |
|
| 39 |
+
| ft-EMA | 560001 | 4.42 | 23.8 +/- 3.9 | 0.69 +/- 0.13 | 0.96 +/- 0.27 | https://huggingface.co/stabilityai/sd-vae-ft-ema-original/resolve/main/vae-ft-ema-560000-ema-pruned.ckpt | slightly better overall, with EMA |
|
| 40 |
+
| ft-MSE | 840001 | 4.70 | 24.5 +/- 3.7 | 0.71 +/- 0.13 | 0.92 +/- 0.27 | https://huggingface.co/stabilityai/sd-vae-ft-mse-original/resolve/main/vae-ft-mse-840000-ema-pruned.ckpt | resumed with EMA from ft-EMA, emphasis on MSE (rec. loss = MSE + 0.1 * LPIPS), smoother outputs |
|
| 41 |
+
|
| 42 |
+
|
| 43 |
+
### LAION-Aesthetics 5+ (256x256, subset, 10000 images)
|
| 44 |
+
| Model | train steps | rFID | PSNR | SSIM | PSIM | Link | Comments
|
| 45 |
+
|----------|-----------|------|--------------|---------------|---------------|-----------------------------------------------------------------------------------|-------------------------------------------------------------------------------------------------|
|
| 46 |
+
| | | | | | | | |
|
| 47 |
+
| original | 246803 | 2.61 | 26.0 +/- 4.4 | 0.81 +/- 0.12 | 0.75 +/- 0.36 | https://ommer-lab.com/files/latent-diffusion/kl-f8.zip | as used in SD |
|
| 48 |
+
| ft-EMA | 560001 | 1.77 | 26.7 +/- 4.8 | 0.82 +/- 0.12 | 0.67 +/- 0.34 | https://huggingface.co/stabilityai/sd-vae-ft-ema-original/resolve/main/vae-ft-ema-560000-ema-pruned.ckpt | slightly better overall, with EMA |
|
| 49 |
+
| ft-MSE | 840001 | 1.88 | 27.3 +/- 4.7 | 0.83 +/- 0.11 | 0.65 +/- 0.34 | https://huggingface.co/stabilityai/sd-vae-ft-mse-original/resolve/main/vae-ft-mse-840000-ema-pruned.ckpt | resumed with EMA from ft-EMA, emphasis on MSE (rec. loss = MSE + 0.1 * LPIPS), smoother outputs |
|
| 50 |
+
|
| 51 |
+
|
| 52 |
+
### Visual
|
| 53 |
+
_Visualization of reconstructions on 256x256 images from the COCO2017 validation dataset._
|
| 54 |
+
|
| 55 |
+
<p align="center">
|
| 56 |
+
<br>
|
| 57 |
+
<b>
|
| 58 |
+
256x256: ft-EMA (left), ft-MSE (middle), original (right)</b>
|
| 59 |
+
</p>
|
| 60 |
+
|
| 61 |
+
<p align="center">
|
| 62 |
+
<img src=https://huggingface.co/stabilityai/stable-diffusion-decoder-finetune/resolve/main/eval/ae-decoder-tuning-reconstructions/merged/00025_merged.png />
|
| 63 |
+
</p>
|
| 64 |
+
|
| 65 |
+
<p align="center">
|
| 66 |
+
<img src=https://huggingface.co/stabilityai/stable-diffusion-decoder-finetune/resolve/main/eval/ae-decoder-tuning-reconstructions/merged/00011_merged.png />
|
| 67 |
+
</p>
|
| 68 |
+
|
| 69 |
+
<p align="center">
|
| 70 |
+
<img src=https://huggingface.co/stabilityai/stable-diffusion-decoder-finetune/resolve/main/eval/ae-decoder-tuning-reconstructions/merged/00037_merged.png />
|
| 71 |
+
</p>
|
| 72 |
+
|
| 73 |
+
<p align="center">
|
| 74 |
+
<img src=https://huggingface.co/stabilityai/stable-diffusion-decoder-finetune/resolve/main/eval/ae-decoder-tuning-reconstructions/merged/00043_merged.png />
|
| 75 |
+
</p>
|
| 76 |
+
|
| 77 |
+
<p align="center">
|
| 78 |
+
<img src=https://huggingface.co/stabilityai/stable-diffusion-decoder-finetune/resolve/main/eval/ae-decoder-tuning-reconstructions/merged/00053_merged.png />
|
| 79 |
+
</p>
|
| 80 |
+
|
| 81 |
+
<p align="center">
|
| 82 |
+
<img src=https://huggingface.co/stabilityai/stable-diffusion-decoder-finetune/resolve/main/eval/ae-decoder-tuning-reconstructions/merged/00029_merged.png />
|
| 83 |
+
</p>
|
sd-vae-ft-mse/config.json
ADDED
|
@@ -0,0 +1,29 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
{
|
| 2 |
+
"_class_name": "AutoencoderKL",
|
| 3 |
+
"_diffusers_version": "0.4.2",
|
| 4 |
+
"act_fn": "silu",
|
| 5 |
+
"block_out_channels": [
|
| 6 |
+
128,
|
| 7 |
+
256,
|
| 8 |
+
512,
|
| 9 |
+
512
|
| 10 |
+
],
|
| 11 |
+
"down_block_types": [
|
| 12 |
+
"DownEncoderBlock2D",
|
| 13 |
+
"DownEncoderBlock2D",
|
| 14 |
+
"DownEncoderBlock2D",
|
| 15 |
+
"DownEncoderBlock2D"
|
| 16 |
+
],
|
| 17 |
+
"in_channels": 3,
|
| 18 |
+
"latent_channels": 4,
|
| 19 |
+
"layers_per_block": 2,
|
| 20 |
+
"norm_num_groups": 32,
|
| 21 |
+
"out_channels": 3,
|
| 22 |
+
"sample_size": 256,
|
| 23 |
+
"up_block_types": [
|
| 24 |
+
"UpDecoderBlock2D",
|
| 25 |
+
"UpDecoderBlock2D",
|
| 26 |
+
"UpDecoderBlock2D",
|
| 27 |
+
"UpDecoderBlock2D"
|
| 28 |
+
]
|
| 29 |
+
}
|
sd-vae-ft-mse/diffusion_pytorch_model.safetensors
ADDED
|
@@ -0,0 +1,3 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
version https://git-lfs.github.com/spec/v1
|
| 2 |
+
oid sha256:a1d993488569e928462932c8c38a0760b874d166399b14414135bd9c42df5815
|
| 3 |
+
size 334643276
|
stable-diffusion-v1-5/unet/config.json
ADDED
|
@@ -0,0 +1,36 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
{
|
| 2 |
+
"_class_name": "UNet2DConditionModel",
|
| 3 |
+
"_diffusers_version": "0.6.0",
|
| 4 |
+
"act_fn": "silu",
|
| 5 |
+
"attention_head_dim": 8,
|
| 6 |
+
"block_out_channels": [
|
| 7 |
+
320,
|
| 8 |
+
640,
|
| 9 |
+
1280,
|
| 10 |
+
1280
|
| 11 |
+
],
|
| 12 |
+
"center_input_sample": false,
|
| 13 |
+
"cross_attention_dim": 768,
|
| 14 |
+
"down_block_types": [
|
| 15 |
+
"CrossAttnDownBlock2D",
|
| 16 |
+
"CrossAttnDownBlock2D",
|
| 17 |
+
"CrossAttnDownBlock2D",
|
| 18 |
+
"DownBlock2D"
|
| 19 |
+
],
|
| 20 |
+
"downsample_padding": 1,
|
| 21 |
+
"flip_sin_to_cos": true,
|
| 22 |
+
"freq_shift": 0,
|
| 23 |
+
"in_channels": 4,
|
| 24 |
+
"layers_per_block": 2,
|
| 25 |
+
"mid_block_scale_factor": 1,
|
| 26 |
+
"norm_eps": 1e-05,
|
| 27 |
+
"norm_num_groups": 32,
|
| 28 |
+
"out_channels": 4,
|
| 29 |
+
"sample_size": 64,
|
| 30 |
+
"up_block_types": [
|
| 31 |
+
"UpBlock2D",
|
| 32 |
+
"CrossAttnUpBlock2D",
|
| 33 |
+
"CrossAttnUpBlock2D",
|
| 34 |
+
"CrossAttnUpBlock2D"
|
| 35 |
+
]
|
| 36 |
+
}
|
stable-diffusion-v1-5/unet/diffusion_pytorch_model.safetensors
ADDED
|
@@ -0,0 +1,3 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
version https://git-lfs.github.com/spec/v1
|
| 2 |
+
oid sha256:19da7aaa4b880e59d56843f1fcb4dd9b599c28a1d9d9af7c1143057c8ffae9f1
|
| 3 |
+
size 3438167540
|
wav2vec/wav2vec2-base-960h/README.md
ADDED
|
@@ -0,0 +1,128 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
---
|
| 2 |
+
language: en
|
| 3 |
+
datasets:
|
| 4 |
+
- librispeech_asr
|
| 5 |
+
tags:
|
| 6 |
+
- audio
|
| 7 |
+
- automatic-speech-recognition
|
| 8 |
+
- hf-asr-leaderboard
|
| 9 |
+
license: apache-2.0
|
| 10 |
+
widget:
|
| 11 |
+
- example_title: Librispeech sample 1
|
| 12 |
+
src: https://cdn-media.huggingface.co/speech_samples/sample1.flac
|
| 13 |
+
- example_title: Librispeech sample 2
|
| 14 |
+
src: https://cdn-media.huggingface.co/speech_samples/sample2.flac
|
| 15 |
+
model-index:
|
| 16 |
+
- name: wav2vec2-base-960h
|
| 17 |
+
results:
|
| 18 |
+
- task:
|
| 19 |
+
name: Automatic Speech Recognition
|
| 20 |
+
type: automatic-speech-recognition
|
| 21 |
+
dataset:
|
| 22 |
+
name: LibriSpeech (clean)
|
| 23 |
+
type: librispeech_asr
|
| 24 |
+
config: clean
|
| 25 |
+
split: test
|
| 26 |
+
args:
|
| 27 |
+
language: en
|
| 28 |
+
metrics:
|
| 29 |
+
- name: Test WER
|
| 30 |
+
type: wer
|
| 31 |
+
value: 3.4
|
| 32 |
+
- task:
|
| 33 |
+
name: Automatic Speech Recognition
|
| 34 |
+
type: automatic-speech-recognition
|
| 35 |
+
dataset:
|
| 36 |
+
name: LibriSpeech (other)
|
| 37 |
+
type: librispeech_asr
|
| 38 |
+
config: other
|
| 39 |
+
split: test
|
| 40 |
+
args:
|
| 41 |
+
language: en
|
| 42 |
+
metrics:
|
| 43 |
+
- name: Test WER
|
| 44 |
+
type: wer
|
| 45 |
+
value: 8.6
|
| 46 |
+
---
|
| 47 |
+
|
| 48 |
+
# Wav2Vec2-Base-960h
|
| 49 |
+
|
| 50 |
+
[Facebook's Wav2Vec2](https://ai.facebook.com/blog/wav2vec-20-learning-the-structure-of-speech-from-raw-audio/)
|
| 51 |
+
|
| 52 |
+
The base model pretrained and fine-tuned on 960 hours of Librispeech on 16kHz sampled speech audio. When using the model
|
| 53 |
+
make sure that your speech input is also sampled at 16Khz.
|
| 54 |
+
|
| 55 |
+
[Paper](https://arxiv.org/abs/2006.11477)
|
| 56 |
+
|
| 57 |
+
Authors: Alexei Baevski, Henry Zhou, Abdelrahman Mohamed, Michael Auli
|
| 58 |
+
|
| 59 |
+
**Abstract**
|
| 60 |
+
|
| 61 |
+
We show for the first time that learning powerful representations from speech audio alone followed by fine-tuning on transcribed speech can outperform the best semi-supervised methods while being conceptually simpler. wav2vec 2.0 masks the speech input in the latent space and solves a contrastive task defined over a quantization of the latent representations which are jointly learned. Experiments using all labeled data of Librispeech achieve 1.8/3.3 WER on the clean/other test sets. When lowering the amount of labeled data to one hour, wav2vec 2.0 outperforms the previous state of the art on the 100 hour subset while using 100 times less labeled data. Using just ten minutes of labeled data and pre-training on 53k hours of unlabeled data still achieves 4.8/8.2 WER. This demonstrates the feasibility of speech recognition with limited amounts of labeled data.
|
| 62 |
+
|
| 63 |
+
The original model can be found under https://github.com/pytorch/fairseq/tree/master/examples/wav2vec#wav2vec-20.
|
| 64 |
+
|
| 65 |
+
|
| 66 |
+
# Usage
|
| 67 |
+
|
| 68 |
+
To transcribe audio files the model can be used as a standalone acoustic model as follows:
|
| 69 |
+
|
| 70 |
+
```python
|
| 71 |
+
from transformers import Wav2Vec2Processor, Wav2Vec2ForCTC
|
| 72 |
+
from datasets import load_dataset
|
| 73 |
+
import torch
|
| 74 |
+
|
| 75 |
+
# load model and tokenizer
|
| 76 |
+
processor = Wav2Vec2Processor.from_pretrained("facebook/wav2vec2-base-960h")
|
| 77 |
+
model = Wav2Vec2ForCTC.from_pretrained("facebook/wav2vec2-base-960h")
|
| 78 |
+
|
| 79 |
+
# load dummy dataset and read soundfiles
|
| 80 |
+
ds = load_dataset("patrickvonplaten/librispeech_asr_dummy", "clean", split="validation")
|
| 81 |
+
|
| 82 |
+
# tokenize
|
| 83 |
+
input_values = processor(ds[0]["audio"]["array"], return_tensors="pt", padding="longest").input_values # Batch size 1
|
| 84 |
+
|
| 85 |
+
# retrieve logits
|
| 86 |
+
logits = model(input_values).logits
|
| 87 |
+
|
| 88 |
+
# take argmax and decode
|
| 89 |
+
predicted_ids = torch.argmax(logits, dim=-1)
|
| 90 |
+
transcription = processor.batch_decode(predicted_ids)
|
| 91 |
+
```
|
| 92 |
+
|
| 93 |
+
## Evaluation
|
| 94 |
+
|
| 95 |
+
This code snippet shows how to evaluate **facebook/wav2vec2-base-960h** on LibriSpeech's "clean" and "other" test data.
|
| 96 |
+
|
| 97 |
+
```python
|
| 98 |
+
from datasets import load_dataset
|
| 99 |
+
from transformers import Wav2Vec2ForCTC, Wav2Vec2Processor
|
| 100 |
+
import torch
|
| 101 |
+
from jiwer import wer
|
| 102 |
+
|
| 103 |
+
|
| 104 |
+
librispeech_eval = load_dataset("librispeech_asr", "clean", split="test")
|
| 105 |
+
|
| 106 |
+
model = Wav2Vec2ForCTC.from_pretrained("facebook/wav2vec2-base-960h").to("cuda")
|
| 107 |
+
processor = Wav2Vec2Processor.from_pretrained("facebook/wav2vec2-base-960h")
|
| 108 |
+
|
| 109 |
+
def map_to_pred(batch):
|
| 110 |
+
input_values = processor(batch["audio"]["array"], return_tensors="pt", padding="longest").input_values
|
| 111 |
+
with torch.no_grad():
|
| 112 |
+
logits = model(input_values.to("cuda")).logits
|
| 113 |
+
|
| 114 |
+
predicted_ids = torch.argmax(logits, dim=-1)
|
| 115 |
+
transcription = processor.batch_decode(predicted_ids)
|
| 116 |
+
batch["transcription"] = transcription
|
| 117 |
+
return batch
|
| 118 |
+
|
| 119 |
+
result = librispeech_eval.map(map_to_pred, batched=True, batch_size=1, remove_columns=["audio"])
|
| 120 |
+
|
| 121 |
+
print("WER:", wer(result["text"], result["transcription"]))
|
| 122 |
+
```
|
| 123 |
+
|
| 124 |
+
*Result (WER)*:
|
| 125 |
+
|
| 126 |
+
| "clean" | "other" |
|
| 127 |
+
|---|---|
|
| 128 |
+
| 3.4 | 8.6 |
|
wav2vec/wav2vec2-base-960h/config.json
ADDED
|
@@ -0,0 +1,77 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
{
|
| 2 |
+
"_name_or_path": "facebook/wav2vec2-base-960h",
|
| 3 |
+
"activation_dropout": 0.1,
|
| 4 |
+
"apply_spec_augment": true,
|
| 5 |
+
"architectures": [
|
| 6 |
+
"Wav2Vec2ForCTC"
|
| 7 |
+
],
|
| 8 |
+
"attention_dropout": 0.1,
|
| 9 |
+
"bos_token_id": 1,
|
| 10 |
+
"codevector_dim": 256,
|
| 11 |
+
"contrastive_logits_temperature": 0.1,
|
| 12 |
+
"conv_bias": false,
|
| 13 |
+
"conv_dim": [
|
| 14 |
+
512,
|
| 15 |
+
512,
|
| 16 |
+
512,
|
| 17 |
+
512,
|
| 18 |
+
512,
|
| 19 |
+
512,
|
| 20 |
+
512
|
| 21 |
+
],
|
| 22 |
+
"conv_kernel": [
|
| 23 |
+
10,
|
| 24 |
+
3,
|
| 25 |
+
3,
|
| 26 |
+
3,
|
| 27 |
+
3,
|
| 28 |
+
2,
|
| 29 |
+
2
|
| 30 |
+
],
|
| 31 |
+
"conv_stride": [
|
| 32 |
+
5,
|
| 33 |
+
2,
|
| 34 |
+
2,
|
| 35 |
+
2,
|
| 36 |
+
2,
|
| 37 |
+
2,
|
| 38 |
+
2
|
| 39 |
+
],
|
| 40 |
+
"ctc_loss_reduction": "sum",
|
| 41 |
+
"ctc_zero_infinity": false,
|
| 42 |
+
"diversity_loss_weight": 0.1,
|
| 43 |
+
"do_stable_layer_norm": false,
|
| 44 |
+
"eos_token_id": 2,
|
| 45 |
+
"feat_extract_activation": "gelu",
|
| 46 |
+
"feat_extract_dropout": 0.0,
|
| 47 |
+
"feat_extract_norm": "group",
|
| 48 |
+
"feat_proj_dropout": 0.1,
|
| 49 |
+
"feat_quantizer_dropout": 0.0,
|
| 50 |
+
"final_dropout": 0.1,
|
| 51 |
+
"gradient_checkpointing": false,
|
| 52 |
+
"hidden_act": "gelu",
|
| 53 |
+
"hidden_dropout": 0.1,
|
| 54 |
+
"hidden_dropout_prob": 0.1,
|
| 55 |
+
"hidden_size": 768,
|
| 56 |
+
"initializer_range": 0.02,
|
| 57 |
+
"intermediate_size": 3072,
|
| 58 |
+
"layer_norm_eps": 1e-05,
|
| 59 |
+
"layerdrop": 0.1,
|
| 60 |
+
"mask_feature_length": 10,
|
| 61 |
+
"mask_feature_prob": 0.0,
|
| 62 |
+
"mask_time_length": 10,
|
| 63 |
+
"mask_time_prob": 0.05,
|
| 64 |
+
"model_type": "wav2vec2",
|
| 65 |
+
"num_attention_heads": 12,
|
| 66 |
+
"num_codevector_groups": 2,
|
| 67 |
+
"num_codevectors_per_group": 320,
|
| 68 |
+
"num_conv_pos_embedding_groups": 16,
|
| 69 |
+
"num_conv_pos_embeddings": 128,
|
| 70 |
+
"num_feat_extract_layers": 7,
|
| 71 |
+
"num_hidden_layers": 12,
|
| 72 |
+
"num_negatives": 100,
|
| 73 |
+
"pad_token_id": 0,
|
| 74 |
+
"proj_codevector_dim": 256,
|
| 75 |
+
"transformers_version": "4.7.0.dev0",
|
| 76 |
+
"vocab_size": 32
|
| 77 |
+
}
|
wav2vec/wav2vec2-base-960h/feature_extractor_config.json
ADDED
|
@@ -0,0 +1,8 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
{
|
| 2 |
+
"do_normalize": true,
|
| 3 |
+
"feature_dim": 1,
|
| 4 |
+
"padding_side": "right",
|
| 5 |
+
"padding_value": 0.0,
|
| 6 |
+
"return_attention_mask": false,
|
| 7 |
+
"sampling_rate": 16000
|
| 8 |
+
}
|
wav2vec/wav2vec2-base-960h/model.safetensors
ADDED
|
@@ -0,0 +1,3 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
version https://git-lfs.github.com/spec/v1
|
| 2 |
+
oid sha256:8aa76ab2243c81747a1f832954586bc566090c83a0ac167df6f31f0fa917d74a
|
| 3 |
+
size 377607901
|
wav2vec/wav2vec2-base-960h/preprocessor_config.json
ADDED
|
@@ -0,0 +1,8 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
{
|
| 2 |
+
"do_normalize": true,
|
| 3 |
+
"feature_size": 1,
|
| 4 |
+
"padding_side": "right",
|
| 5 |
+
"padding_value": 0.0,
|
| 6 |
+
"return_attention_mask": false,
|
| 7 |
+
"sampling_rate": 16000
|
| 8 |
+
}
|
wav2vec/wav2vec2-base-960h/special_tokens_map.json
ADDED
|
@@ -0,0 +1 @@
|
|
|
|
|
|
|
| 1 |
+
{"bos_token": "<s>", "eos_token": "</s>", "unk_token": "<unk>", "pad_token": "<pad>"}
|
wav2vec/wav2vec2-base-960h/tokenizer_config.json
ADDED
|
@@ -0,0 +1 @@
|
|
|
|
|
|
|
| 1 |
+
{"unk_token": "<unk>", "bos_token": "<s>", "eos_token": "</s>", "pad_token": "<pad>", "do_lower_case": false, "return_attention_mask": false, "do_normalize": true}
|
wav2vec/wav2vec2-base-960h/vocab.json
ADDED
|
@@ -0,0 +1 @@
|
|
|
|
|
|
|
| 1 |
+
{"<pad>": 0, "<s>": 1, "</s>": 2, "<unk>": 3, "|": 4, "E": 5, "T": 6, "A": 7, "O": 8, "N": 9, "I": 10, "H": 11, "S": 12, "R": 13, "D": 14, "L": 15, "U": 16, "M": 17, "W": 18, "C": 19, "F": 20, "G": 21, "Y": 22, "P": 23, "B": 24, "V": 25, "K": 26, "'": 27, "X": 28, "J": 29, "Q": 30, "Z": 31}
|