

File size: 1,661 Bytes
adb2297 95a6df1 c6b791b 95a6df1 c6b791b 95a6df1 7558a8b 95a6df1 24dcb3b 95a6df1 24dcb3b 95a6df1 7558a8b 95a6df1 7558a8b 95a6df1 adb2297 7558a8b 95a6df1 adb2297 | 1 2 3 4 5 6 7 8 9 10 11 12 13 14 15 16 17 18 19 20 21 22 23 24 25 26 27 28 29 30 31 32 33 34 35 36 37 38 39 40 41 42 43 44 45 46 47 48 49 50 51 52 53 | ---
license: creativeml-openrail-m
thumbnail: "https://huggingface.co/dallinmackay/Van-Gogh-diffusion/resolve/main/preview1.jpg"
tags:
- stable-diffusion
- text-to-image
---
### Van Gogh Diffusion
This is a fine-tuned Stable Diffusion model (based on v1.5) trained on 60 paintings of Van Gogh.
It is a mix of portraits and landscape.
Use the token **_vangh_** in your prompts to use the style (e.g., "vangh, beautiful woman at sunset").
--
**Character rendered with this model:**
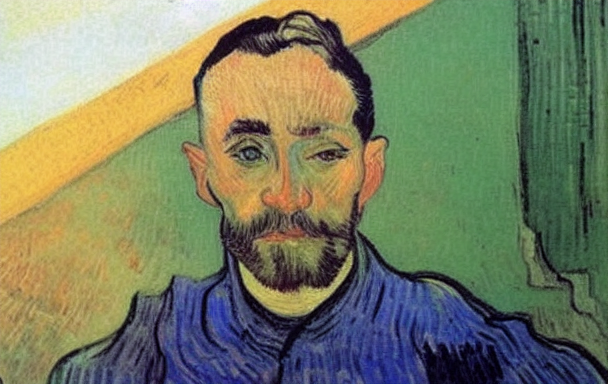
_prompt and settings used: **vangh, man**
--
**Landscapes/miscellaneous rendered with this model:**
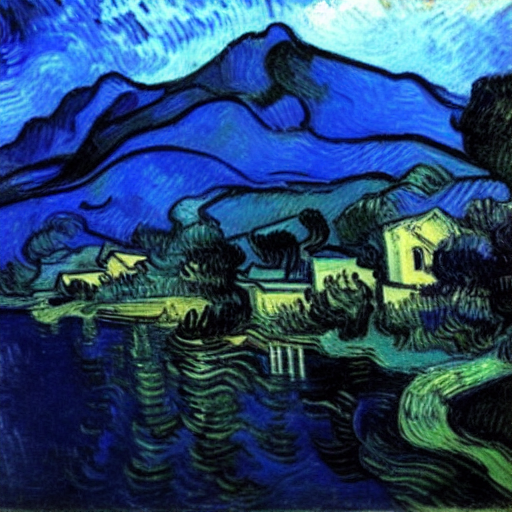
_prompt and settings used: **vangh, landscape of lake, houses and mountains**
--
This model was trained with Dreambooth, using TheLastBen colab notebook
--
### 🧨 Diffusers
This model can be used just like any other Stable Diffusion model. For more information,
please have a look at the [Stable Diffusion](https://huggingface.co/docs/diffusers/api/pipelines/stable_diffusion).
You can also export the model to [ONNX](https://huggingface.co/docs/diffusers/optimization/onnx), [MPS](https://huggingface.co/docs/diffusers/optimization/mps) and/or [FLAX/JAX]().
```python
from diffusers import StableDiffusionPipeline
import torch
model_id = "hazwan/vg-session"
pipe = StableDiffusionPipeline.from_pretrained(model_id, torch_dtype=torch.float16)
pipe = pipe.to("cuda")
prompt = "vangh, beautiful woman at sunset"
image = pipe(prompt).images[0]
image.save("./woman.png")
```
|