

Commit ·
fcf80ba
0
Parent(s):
Duplicate from RunDiffusion/Juggernaut-Z-Image
Browse filesCo-authored-by: RunDiffusion <RunDiffusion@users.noreply.huggingface.co>
- .gitattributes +43 -0
- Juggernaut_Z_V1_FP8_e4m3fn.safetensors +3 -0
- Juggernaut_Z_V1_by_RunDiffusion.safetensors +3 -0
- Juggernaut_Z_V1_by_RunDiffusion_fp16.safetensors +3 -0
- Juggernaut_Z_V1_by_RunDiffusion_q4_k_m-002.gguf +3 -0
- Juggernaut_Z_V1_by_RunDiffusion_q4_k_s-001.gguf +3 -0
- Juggernaut_Z_V1_by_RunDiffusion_q5_k_m-003.gguf +3 -0
- Juggernaut_Z_V1_by_RunDiffusion_q5_k_s-005.gguf +3 -0
- Juggernaut_Z_V1_by_RunDiffusion_q6_k-004.gguf +3 -0
- Juggernaut_Z_V1_by_RunDiffusion_q8_0.gguf +3 -0
- README.md +180 -0
- assets/RD_Mark.png +0 -0
- model_index.json +25 -0
- scheduler/scheduler_config.json +18 -0
- text_encoder/config.json +30 -0
- text_encoder/generation_config.json +13 -0
- text_encoder/model-00001-of-00003.safetensors +3 -0
- text_encoder/model-00002-of-00003.safetensors +3 -0
- text_encoder/model-00003-of-00003.safetensors +3 -0
- text_encoder/model.safetensors.index.json +405 -0
- tokenizer/chat_template.jinja +89 -0
- tokenizer/tokenizer.json +3 -0
- tokenizer/tokenizer_config.json +29 -0
- transformer/config.json +33 -0
- transformer/diffusion_pytorch_model-00001-of-00002.safetensors +3 -0
- transformer/diffusion_pytorch_model-00002-of-00002.safetensors +3 -0
- transformer/diffusion_pytorch_model.safetensors.index.json +528 -0
- vae/config.json +38 -0
- vae/diffusion_pytorch_model.safetensors +3 -0
.gitattributes
ADDED
|
@@ -0,0 +1,43 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
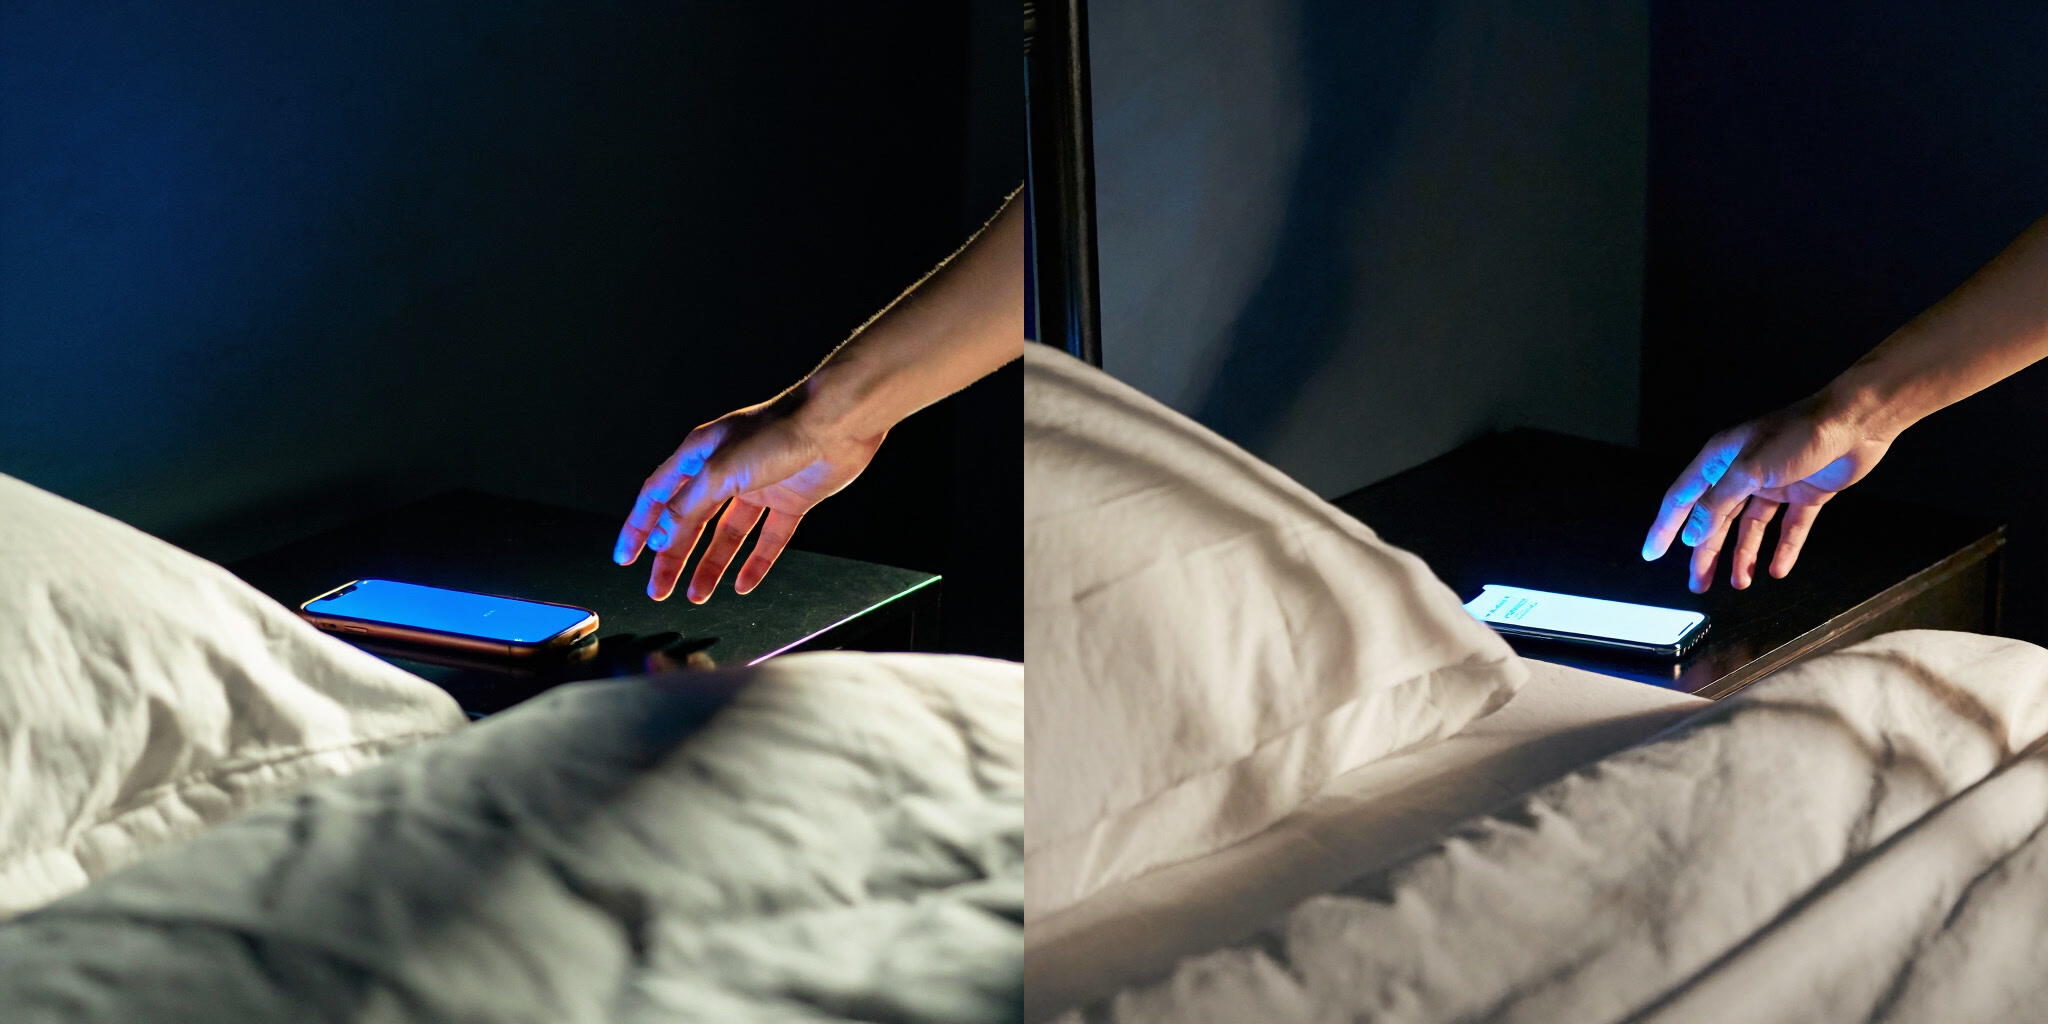
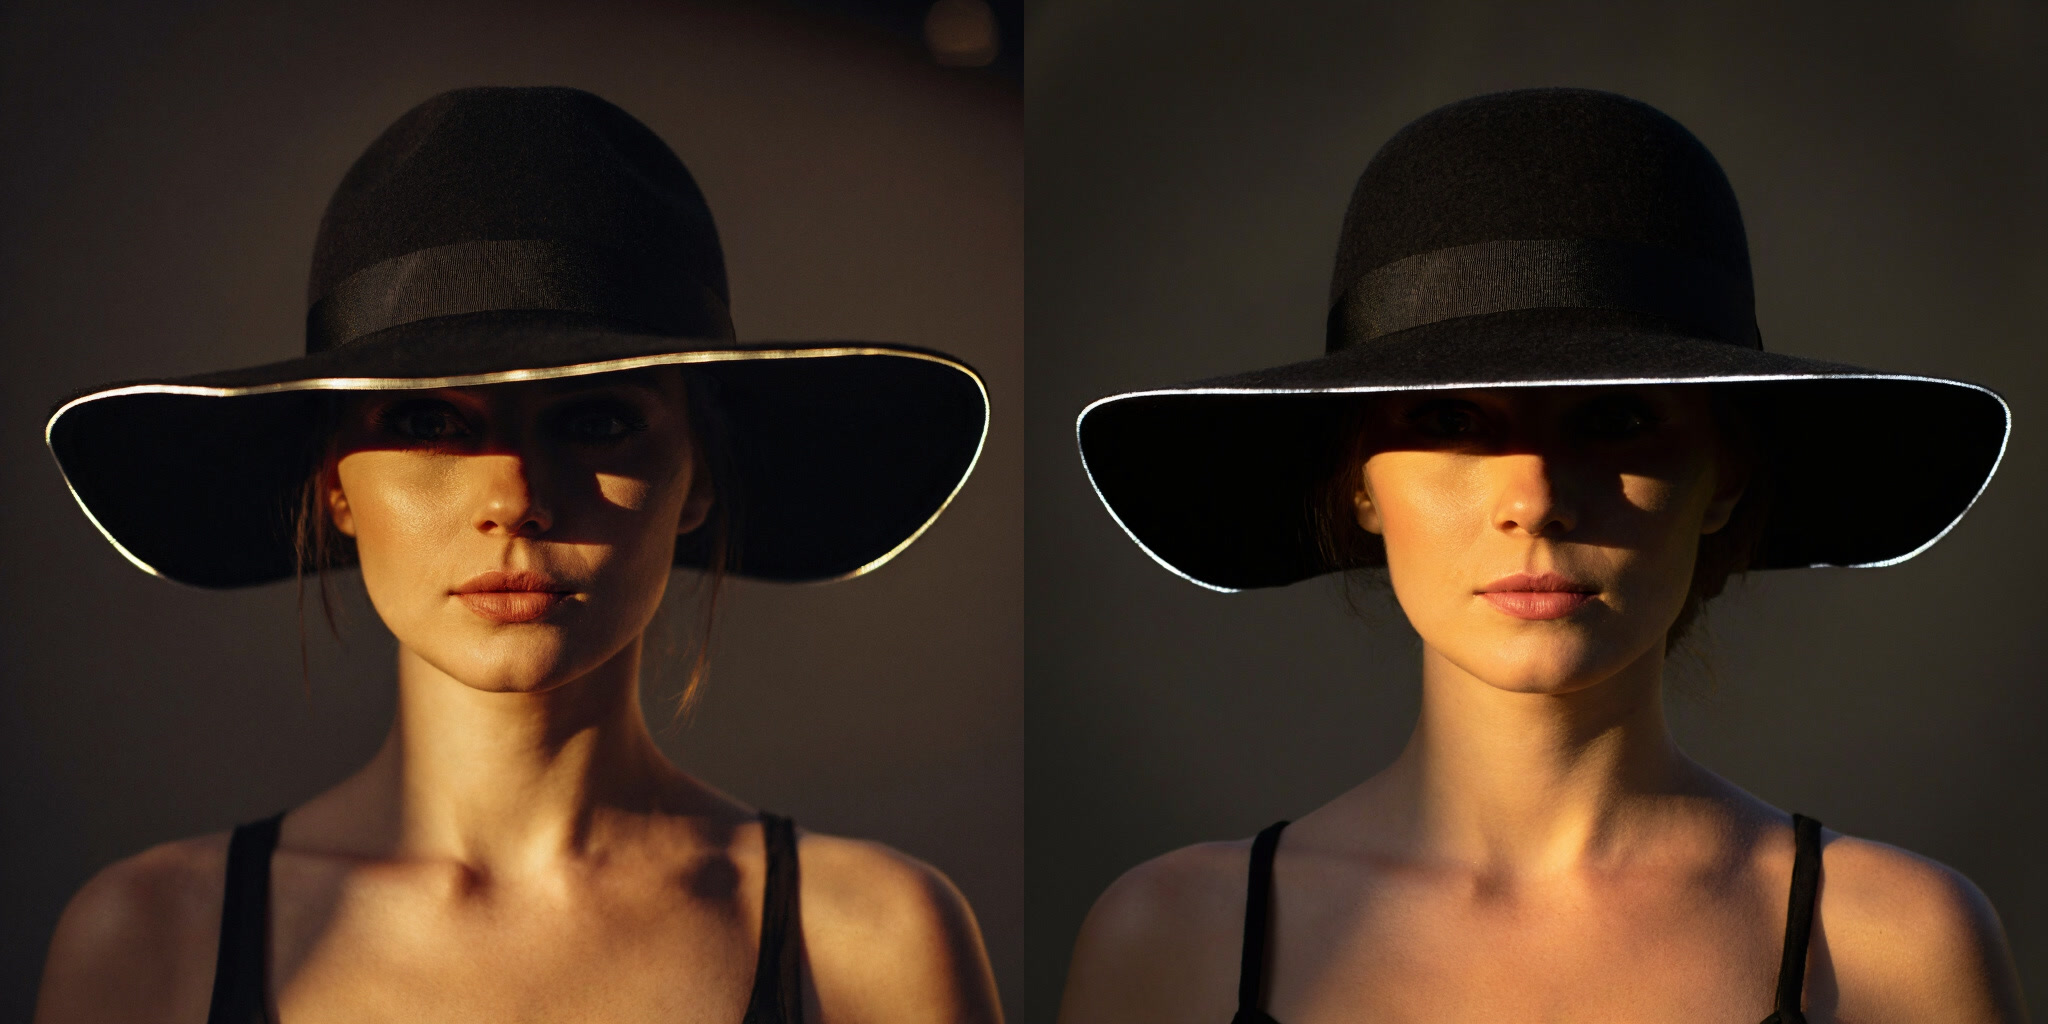
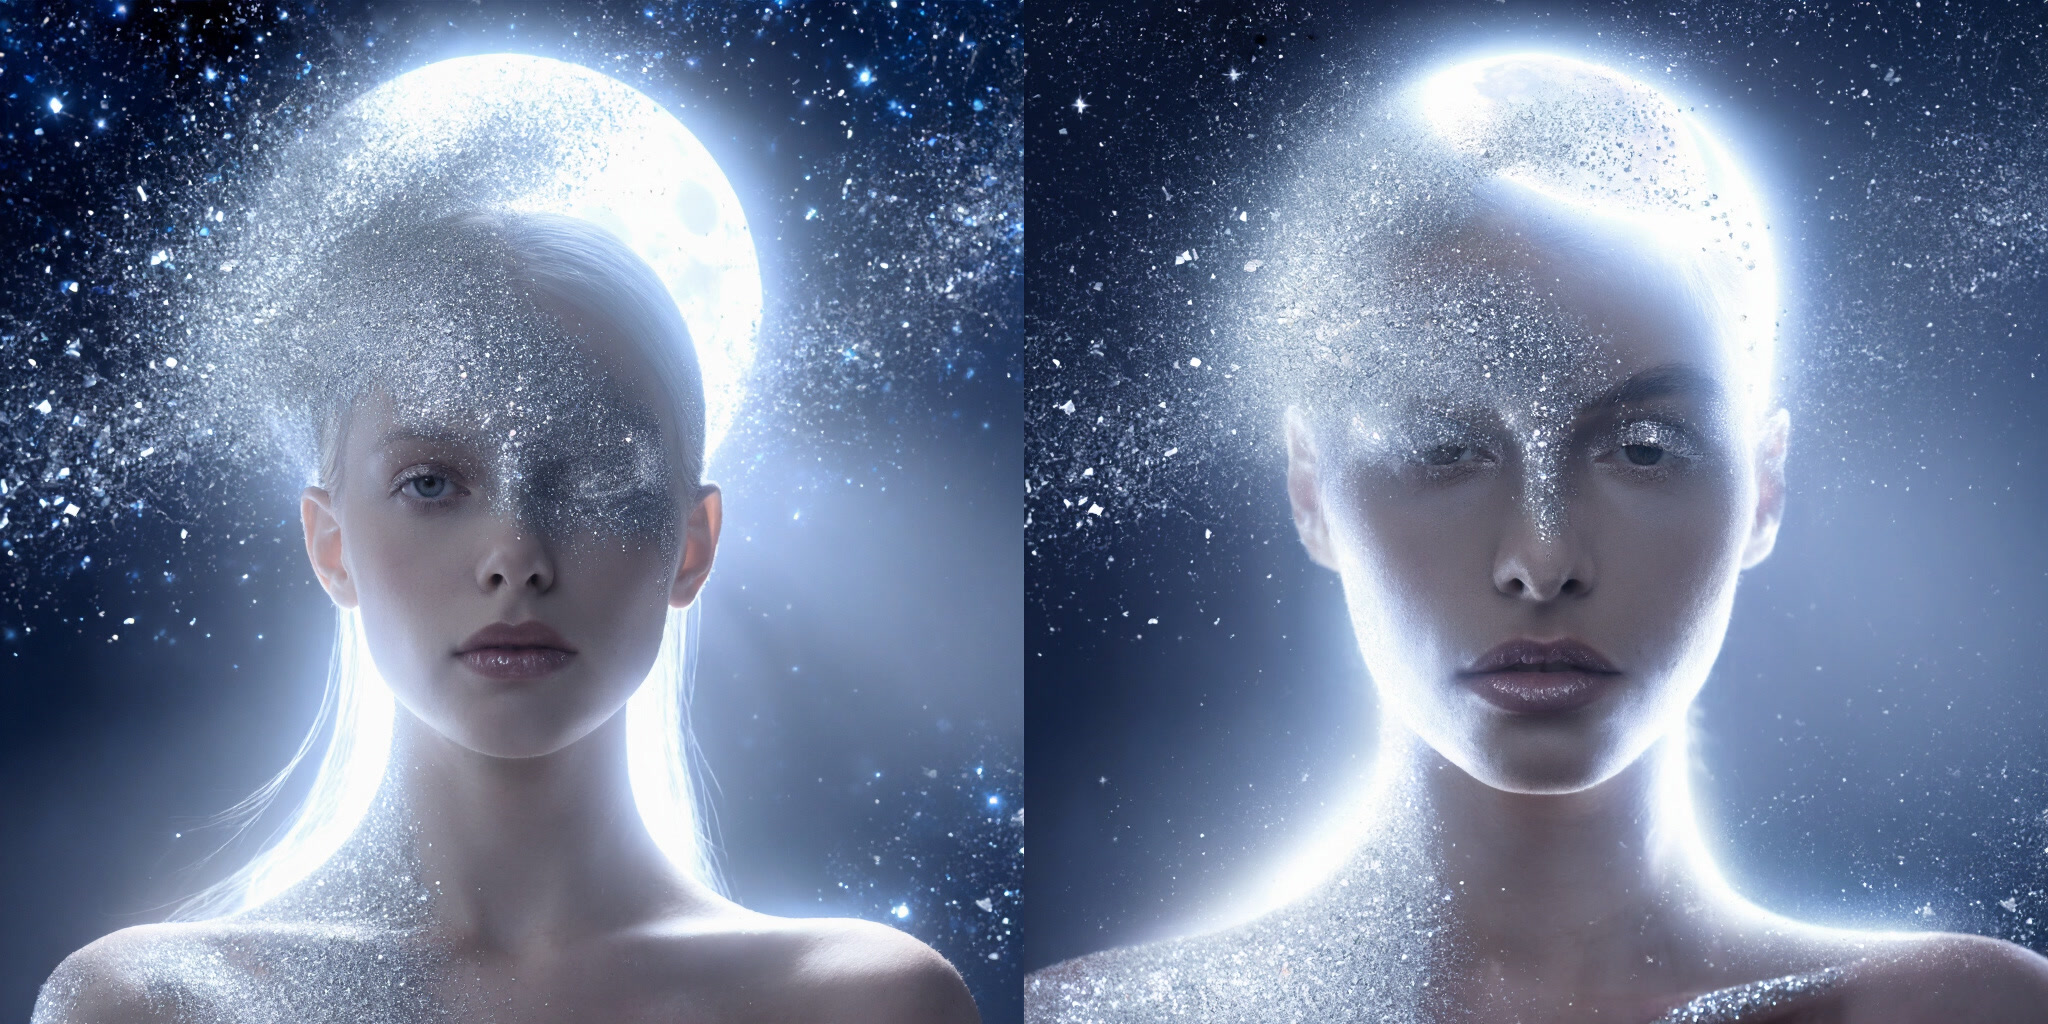
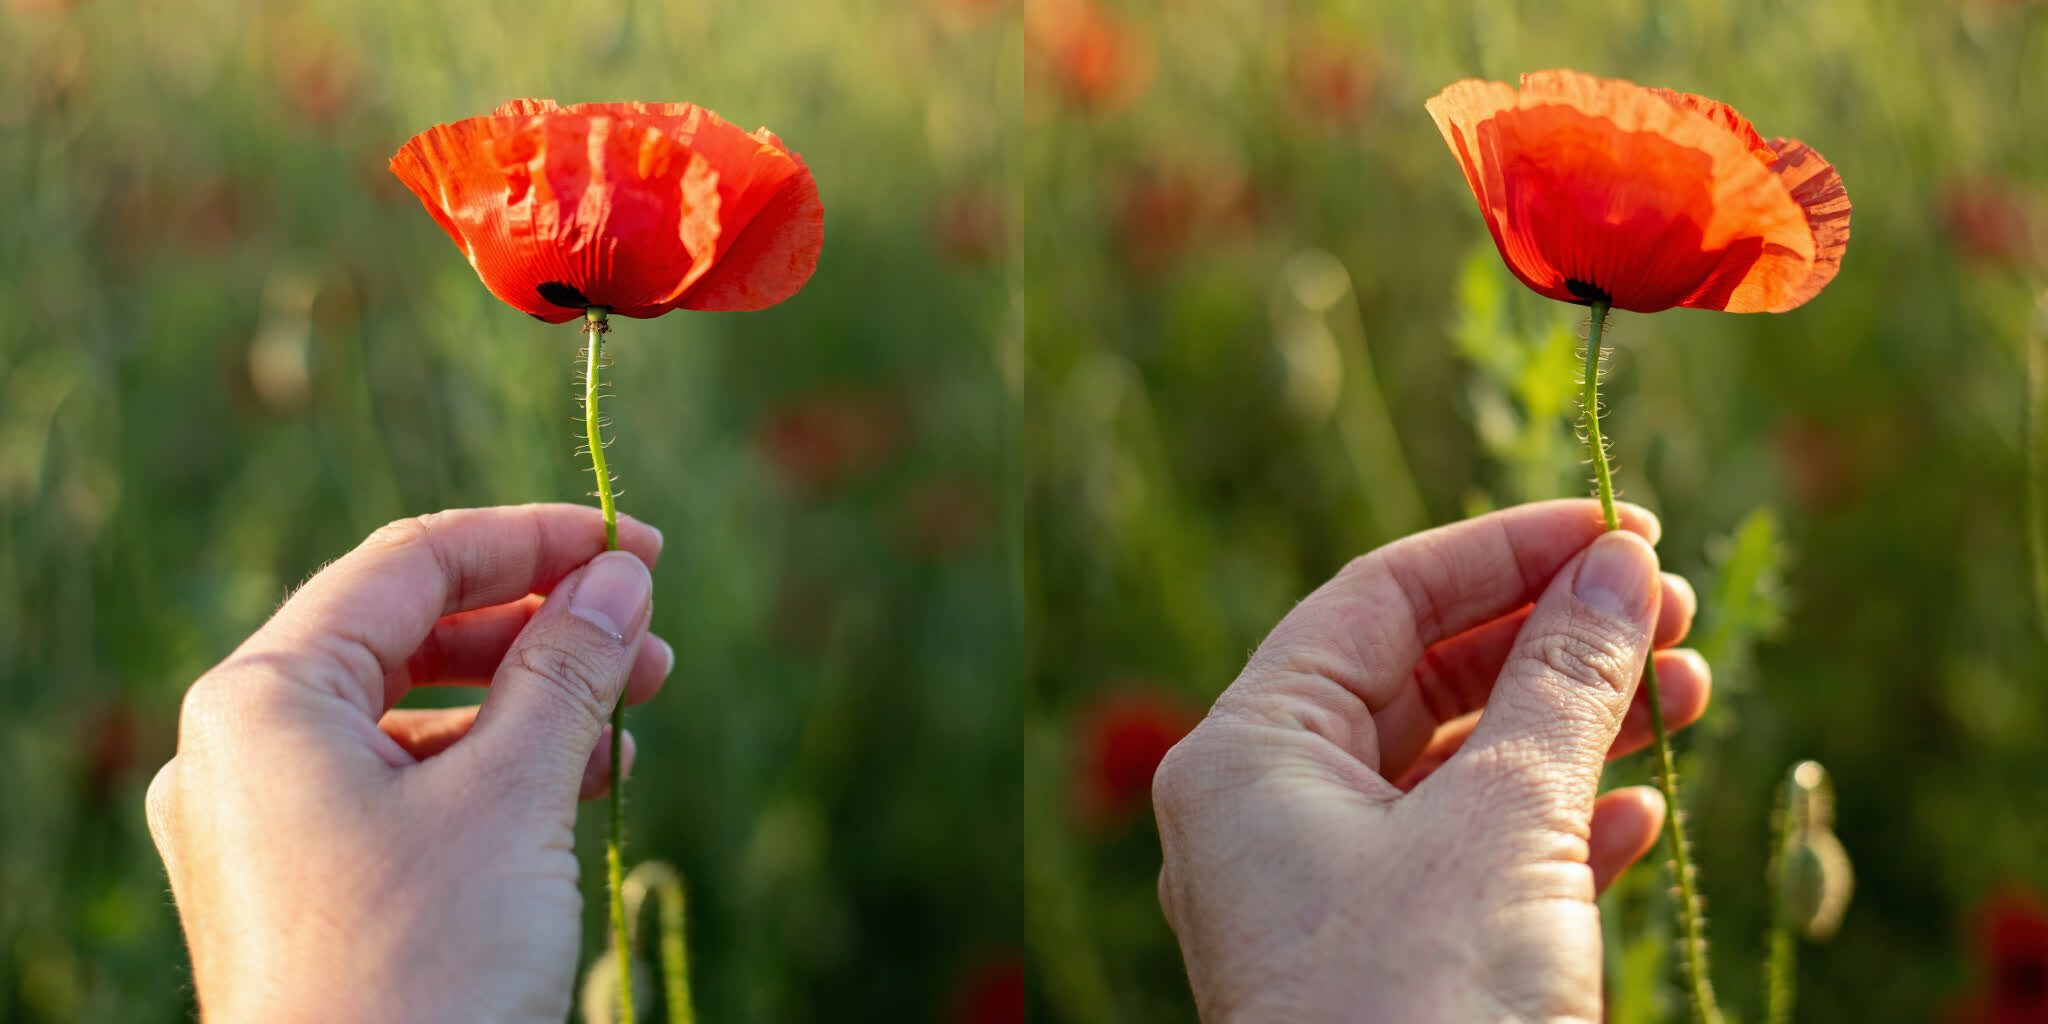
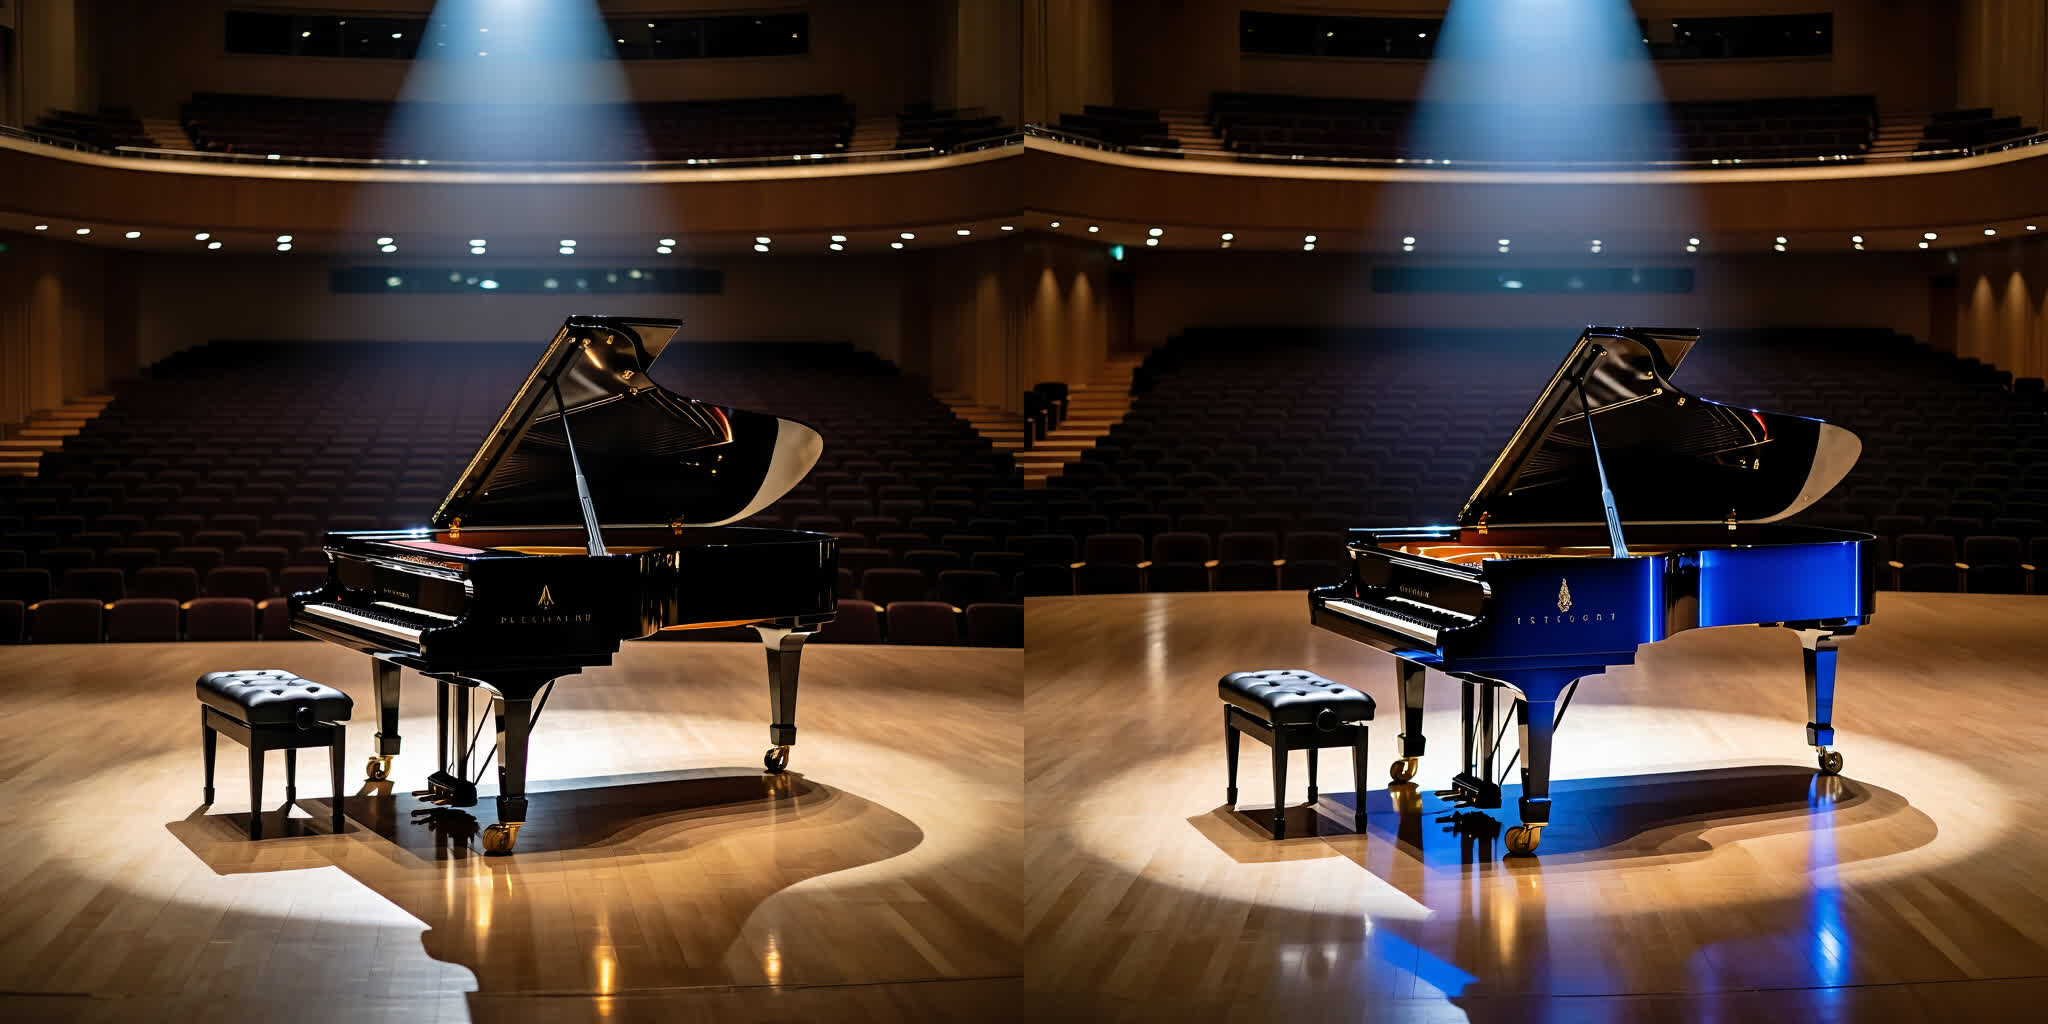
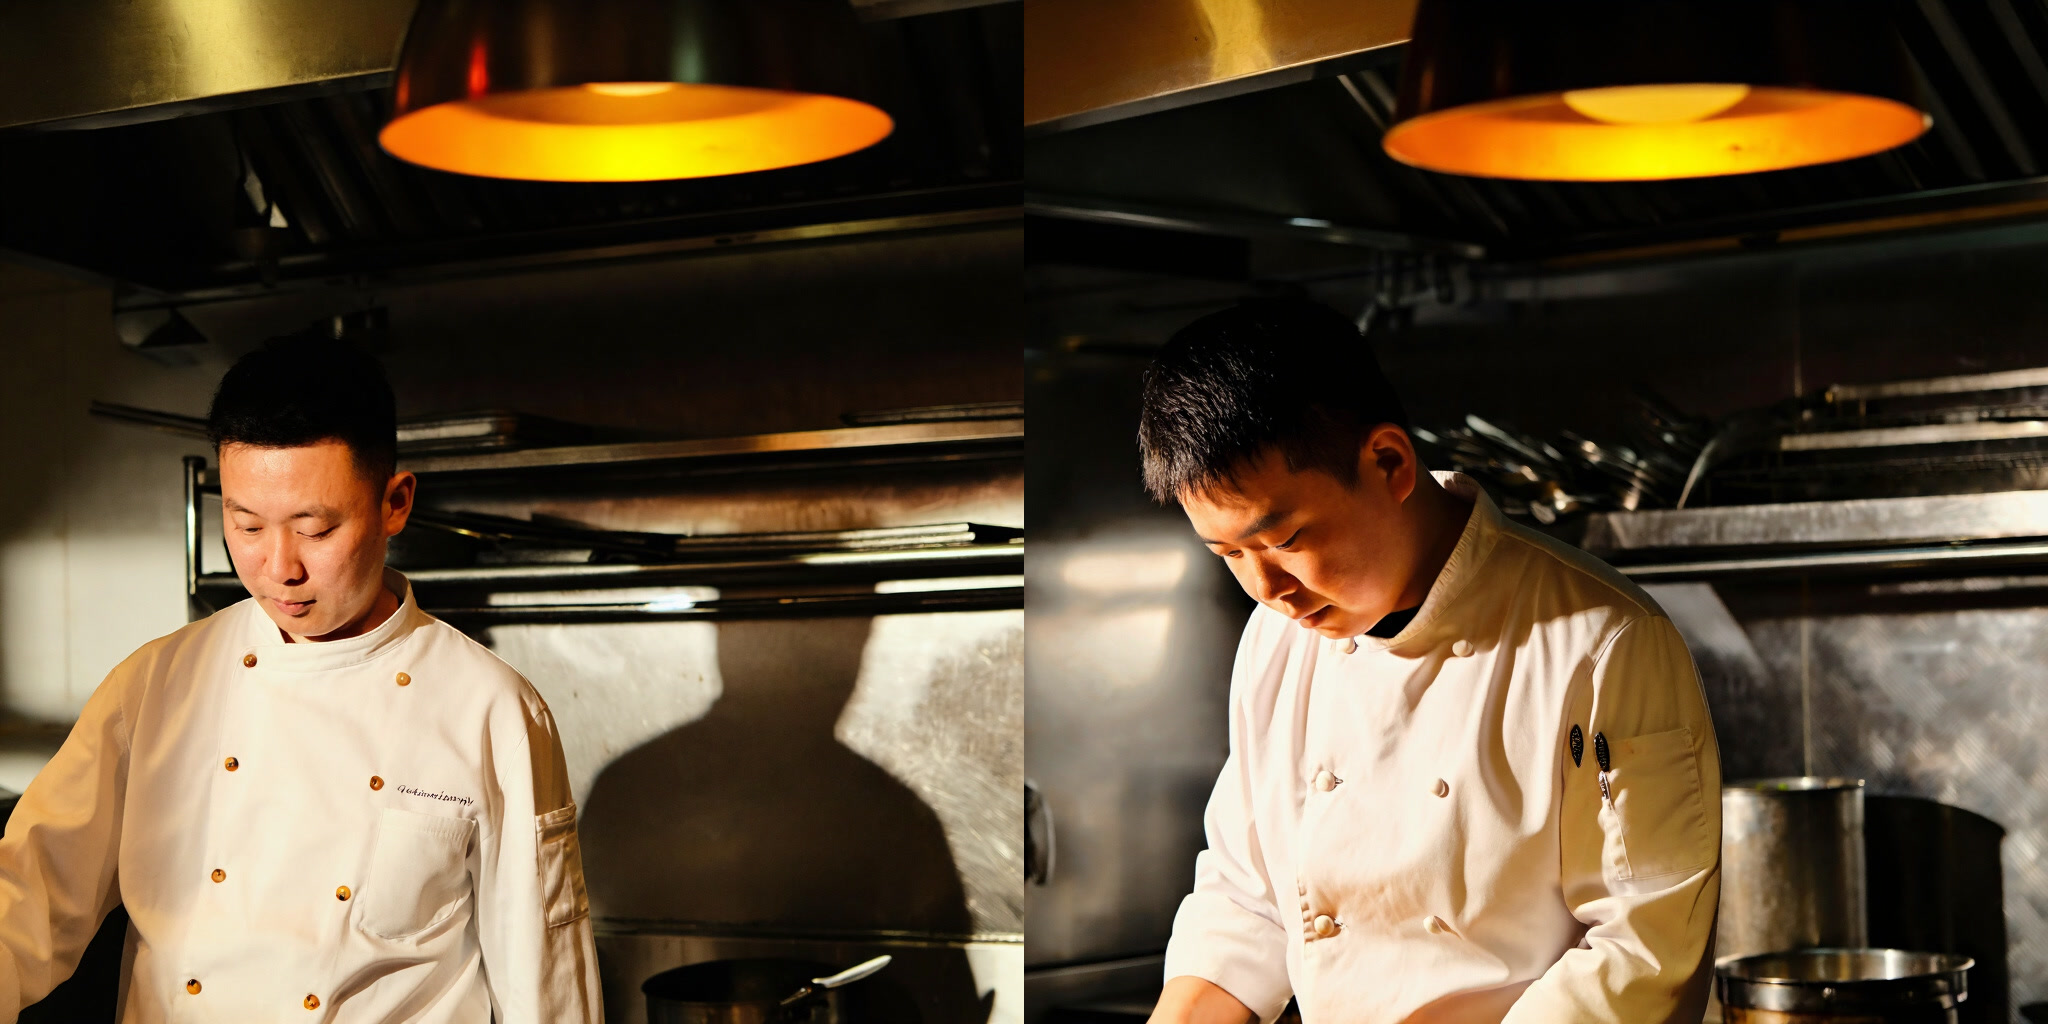
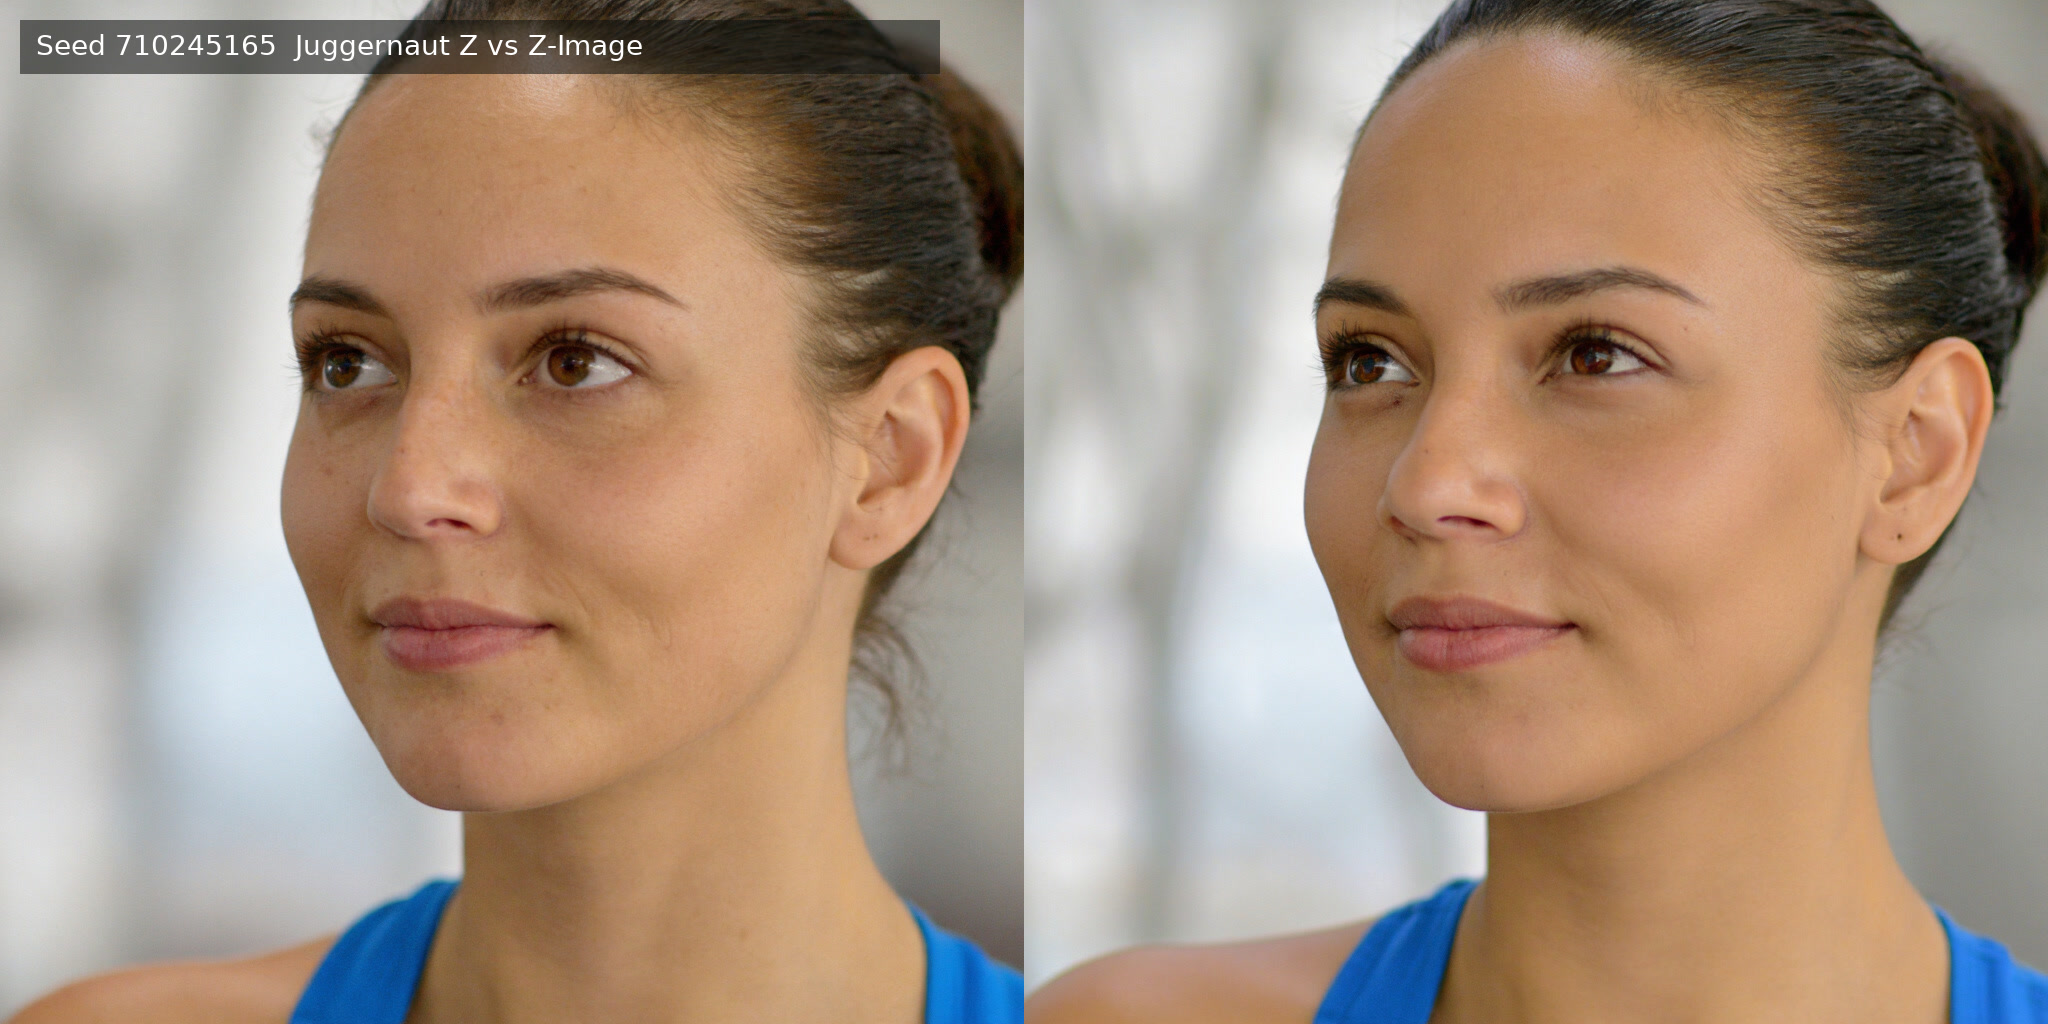
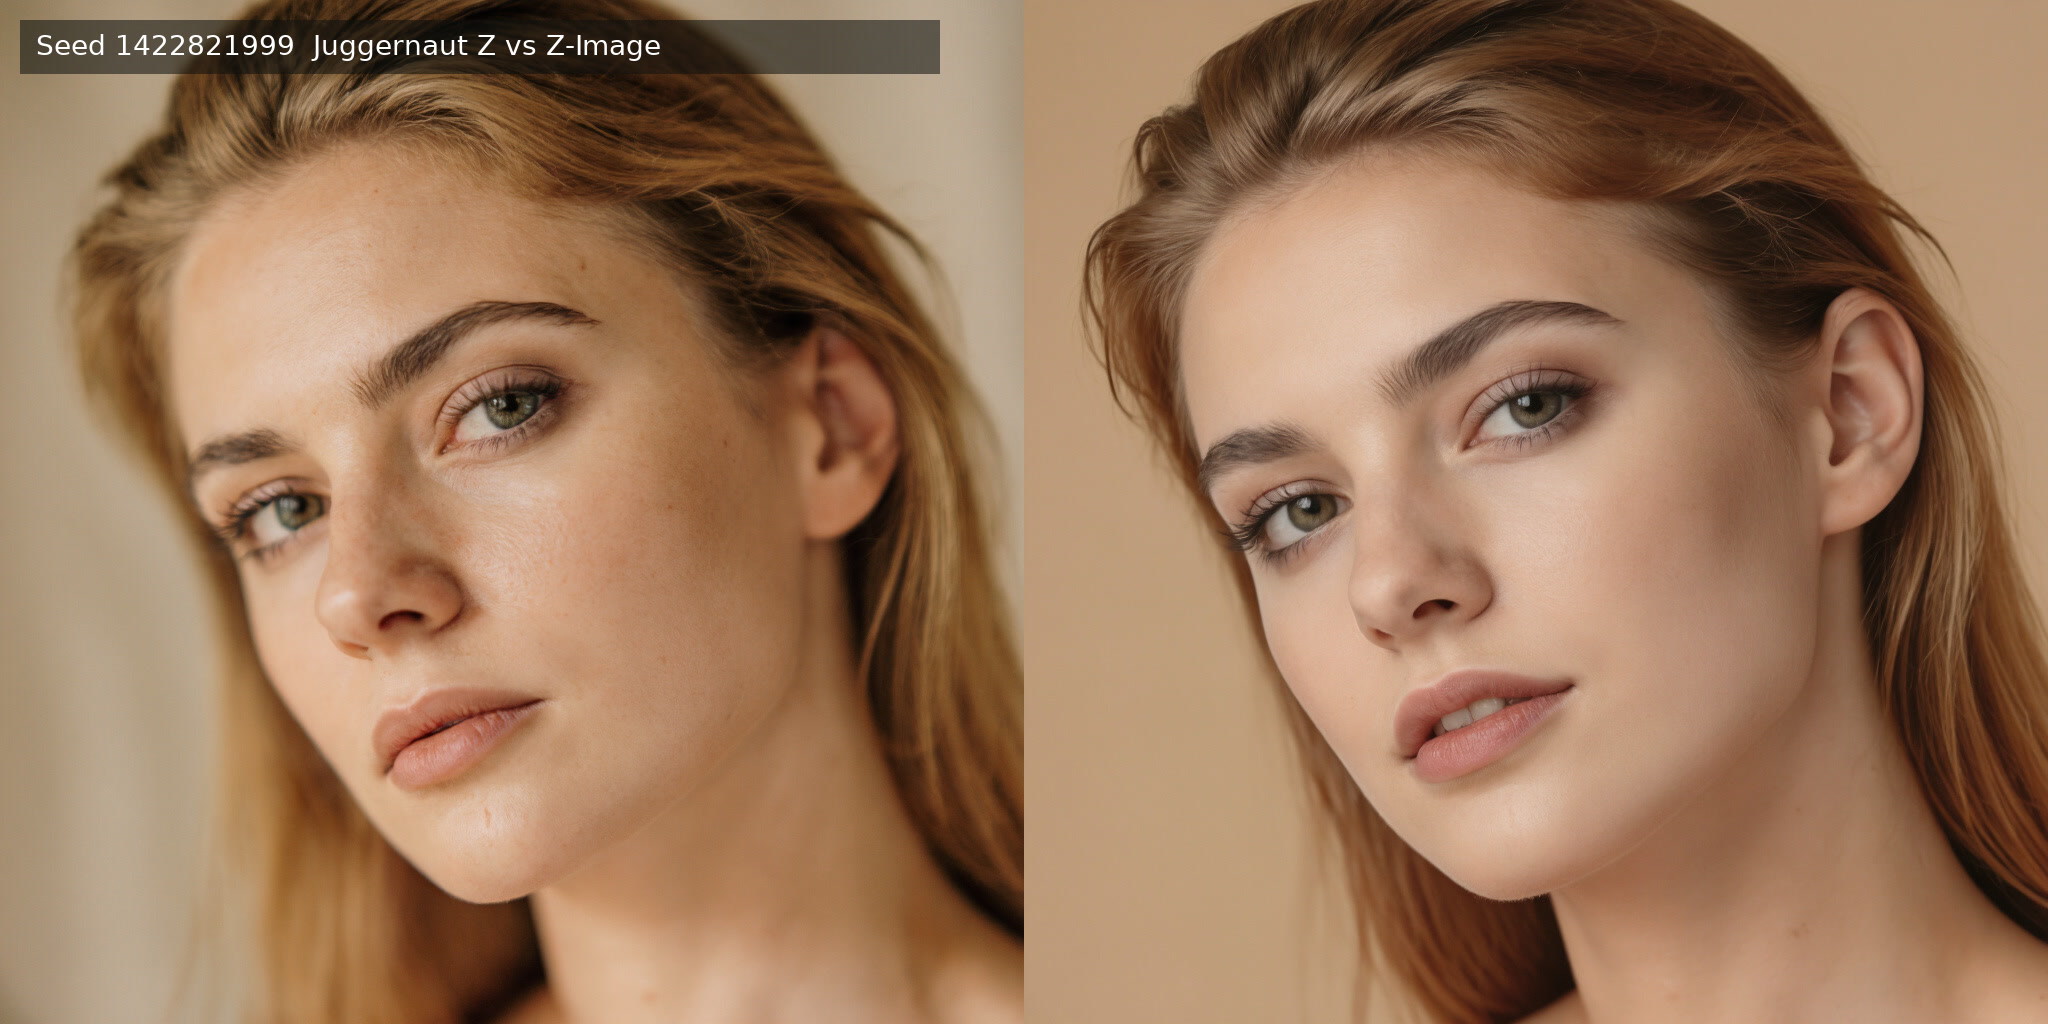
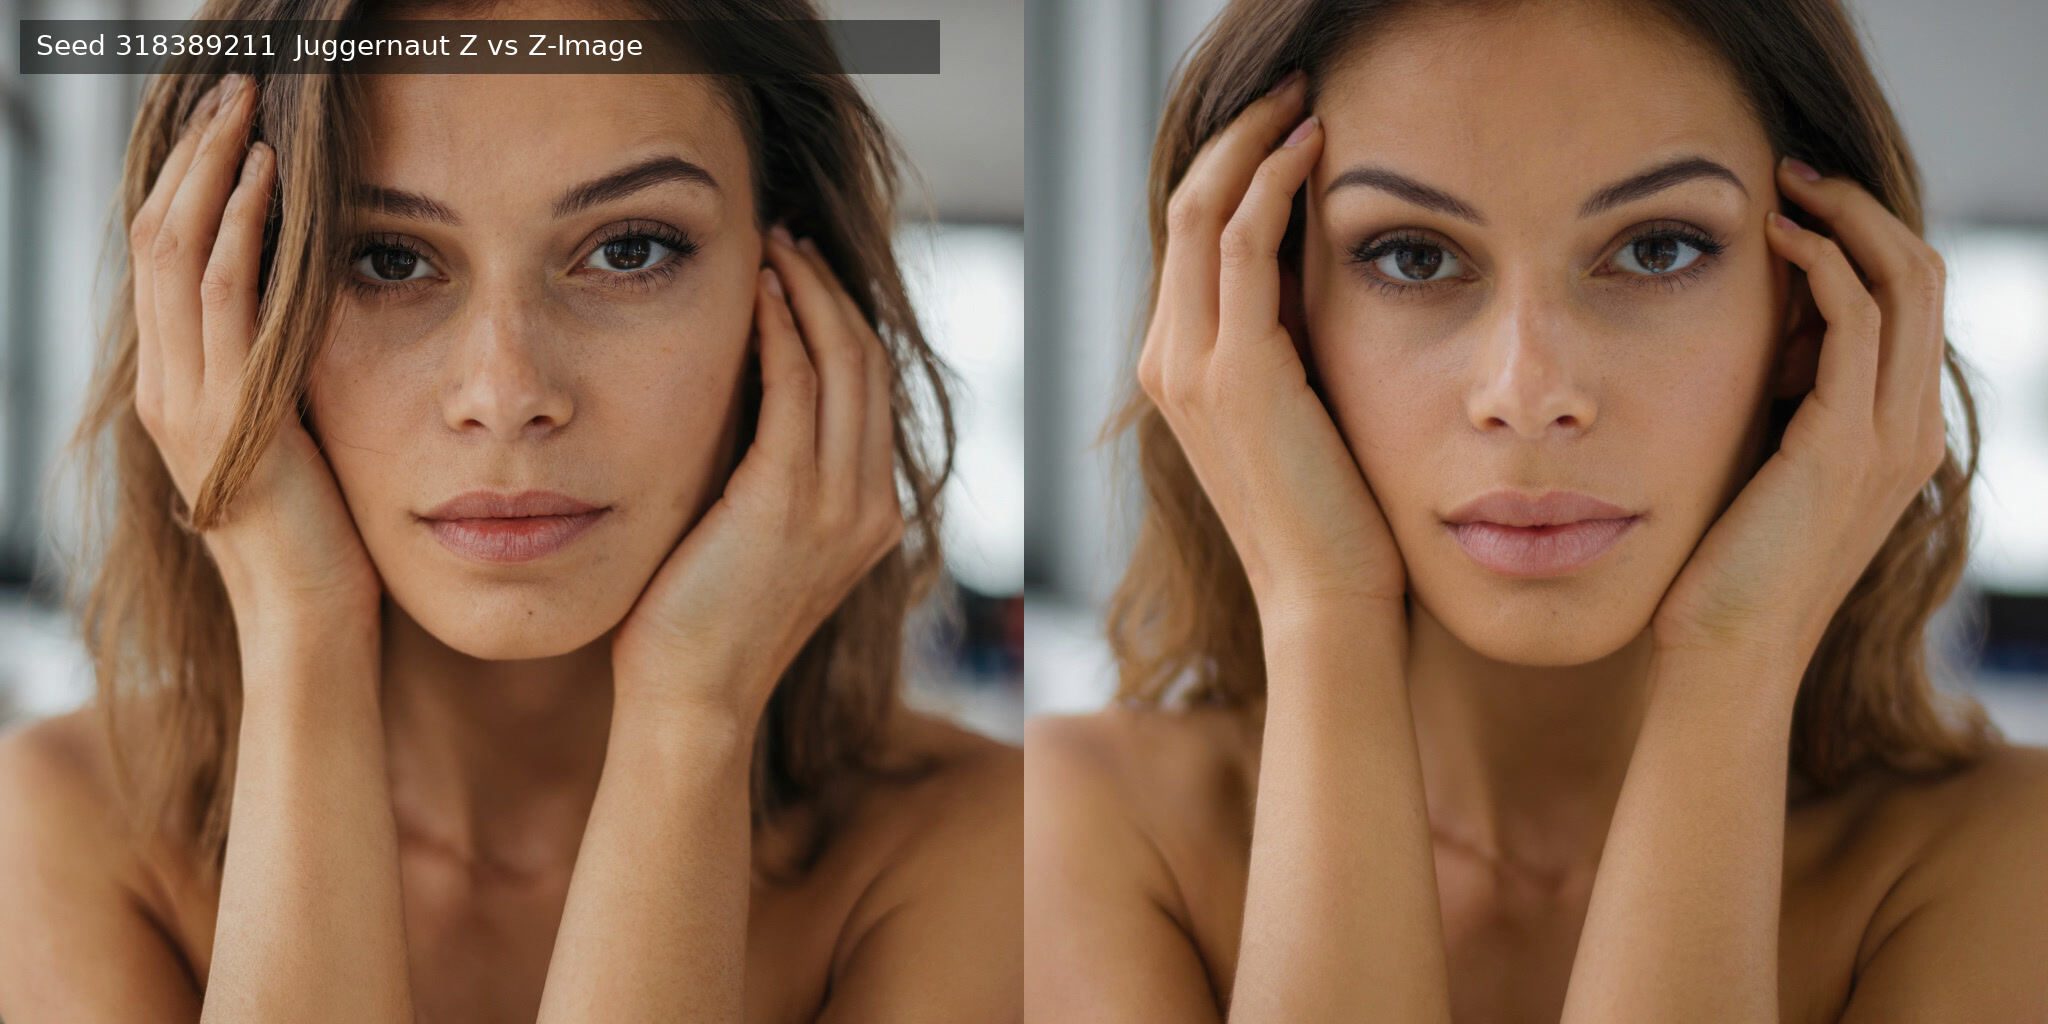
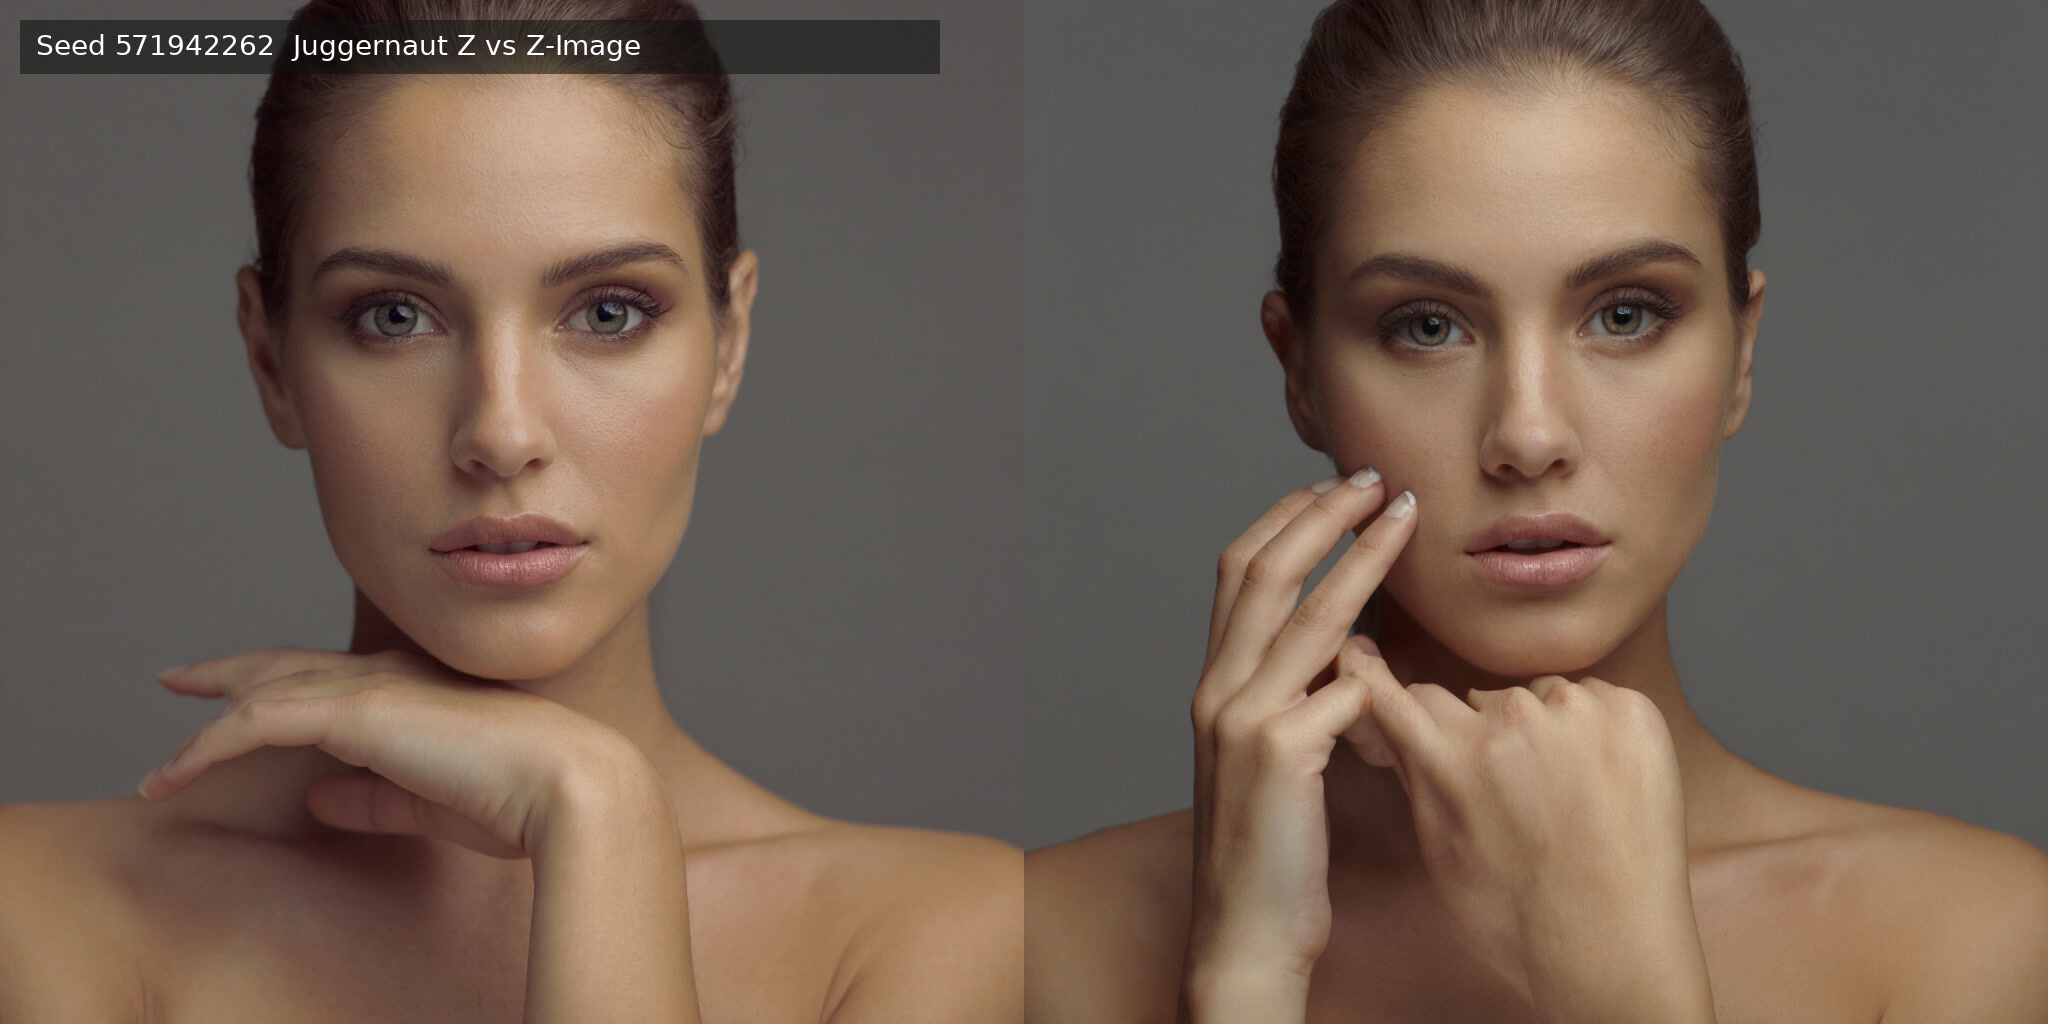
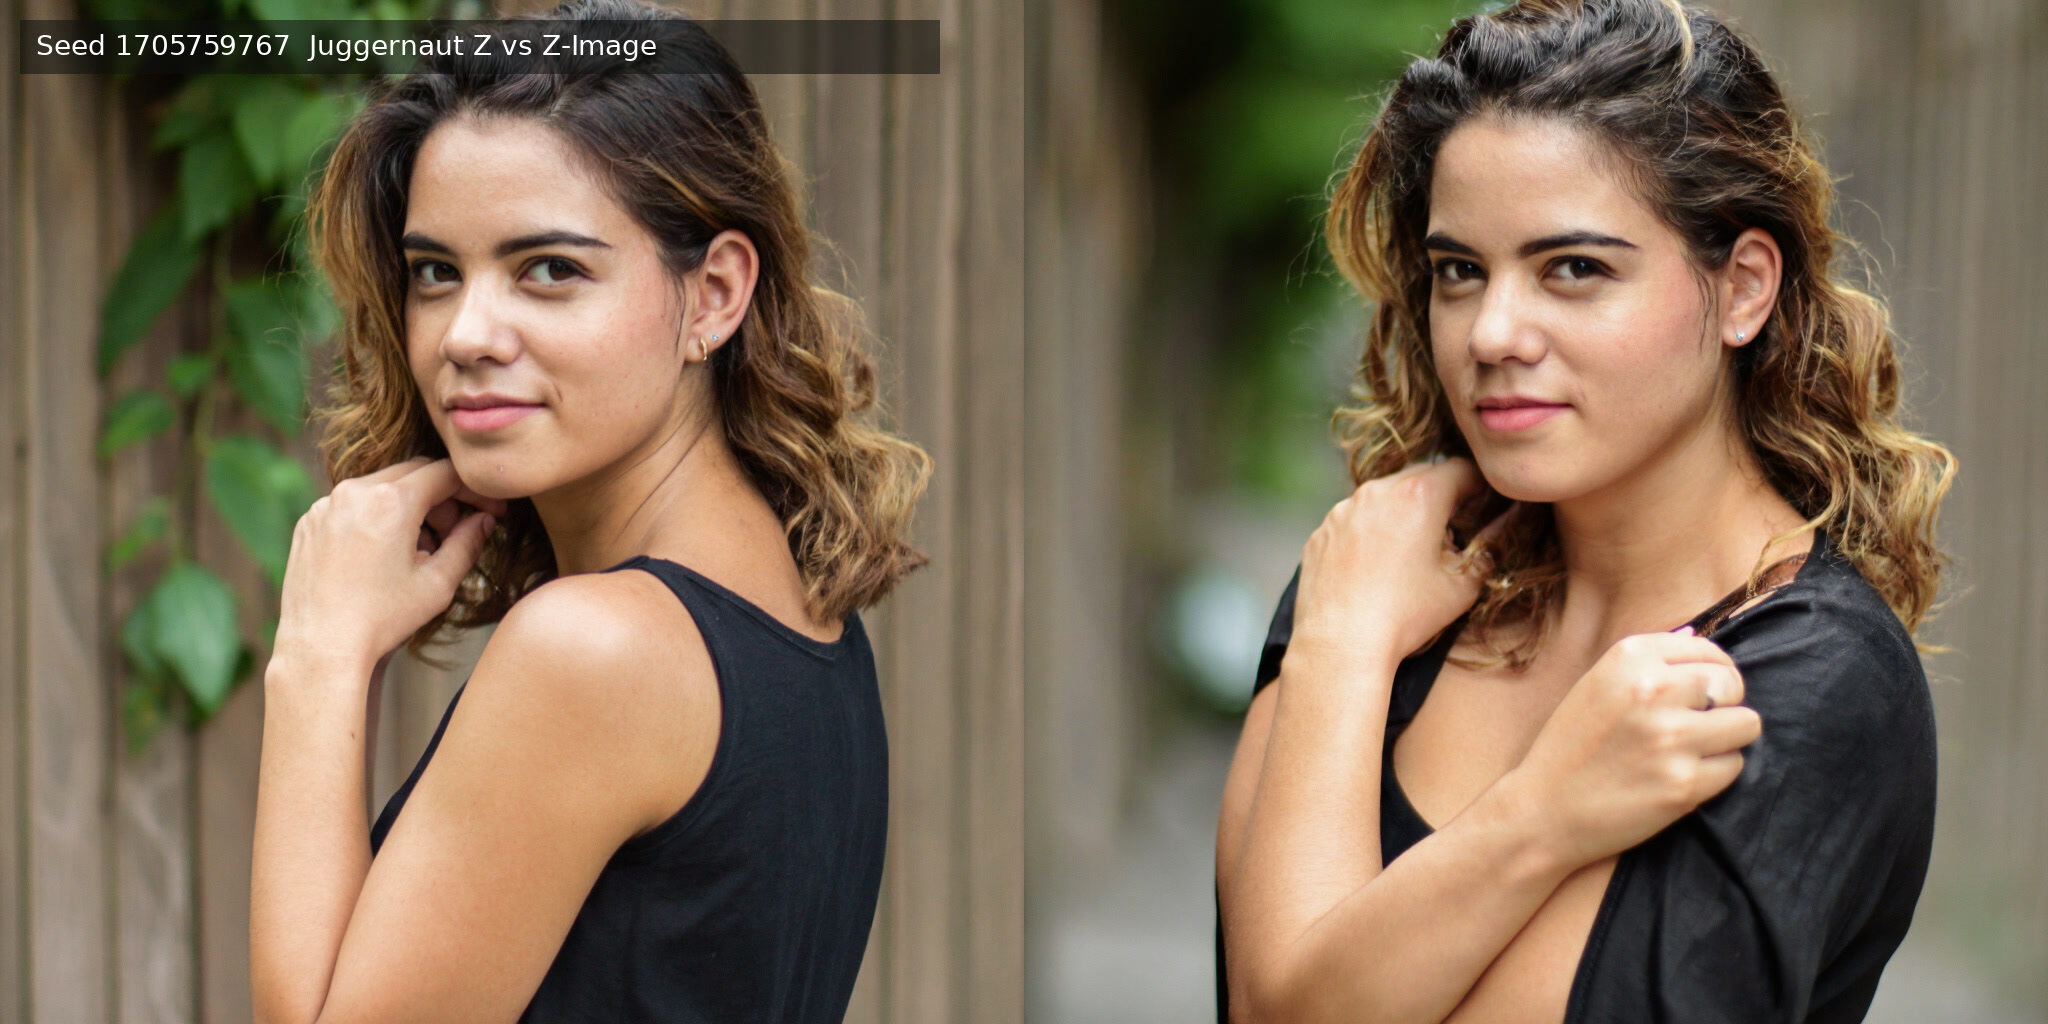
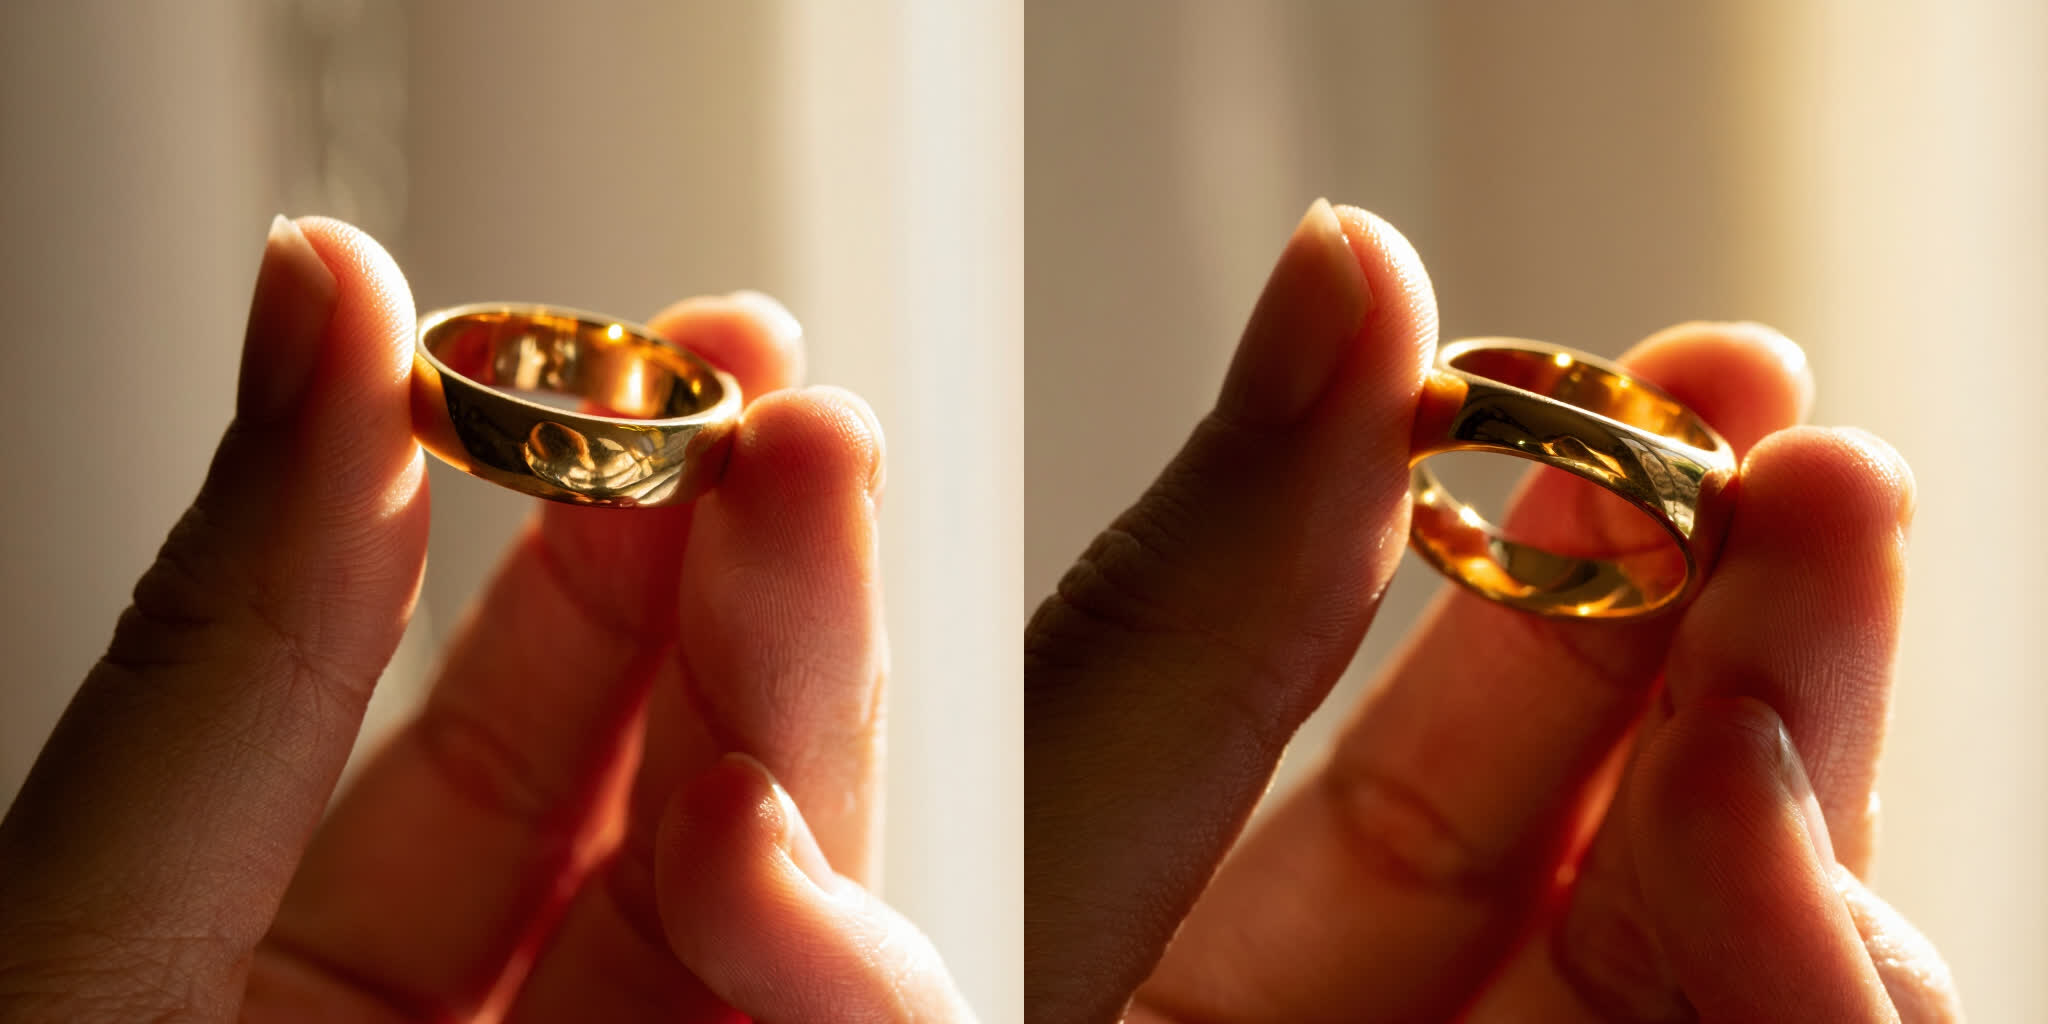
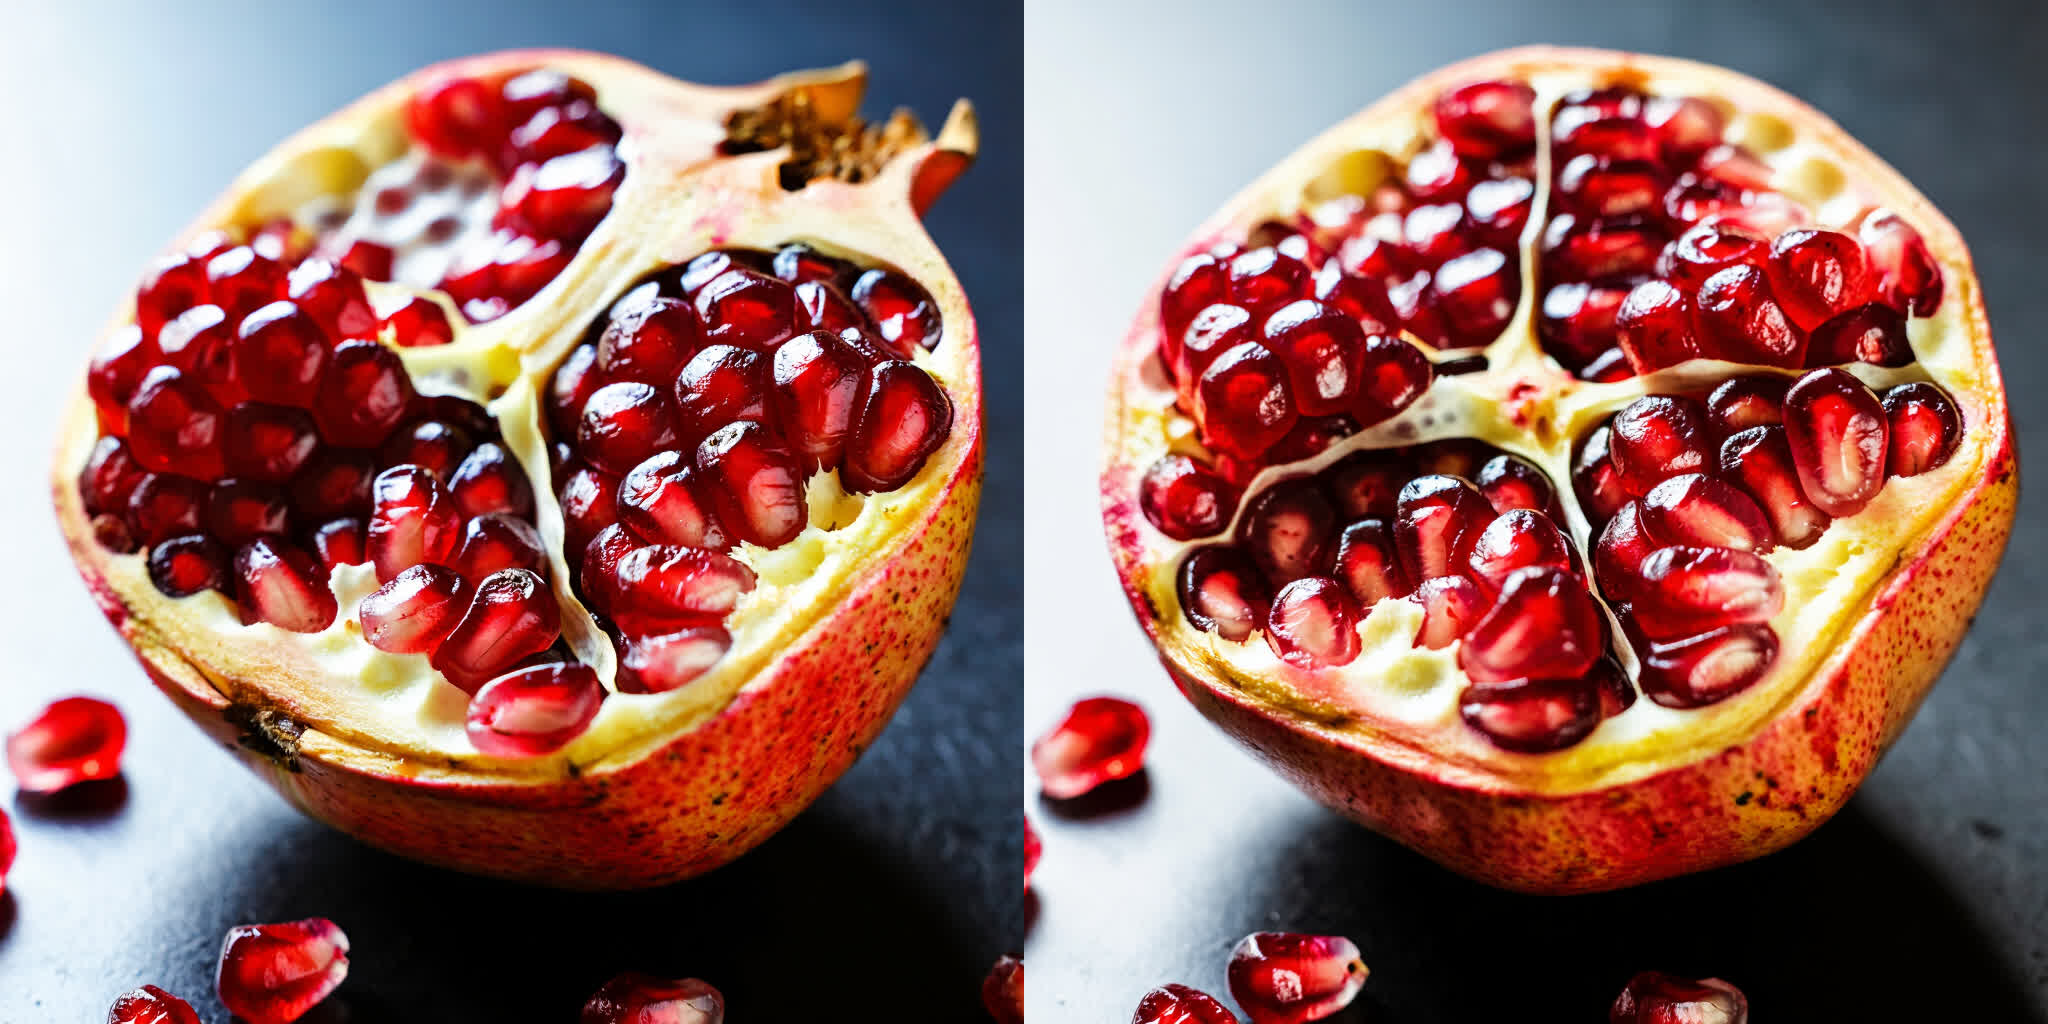
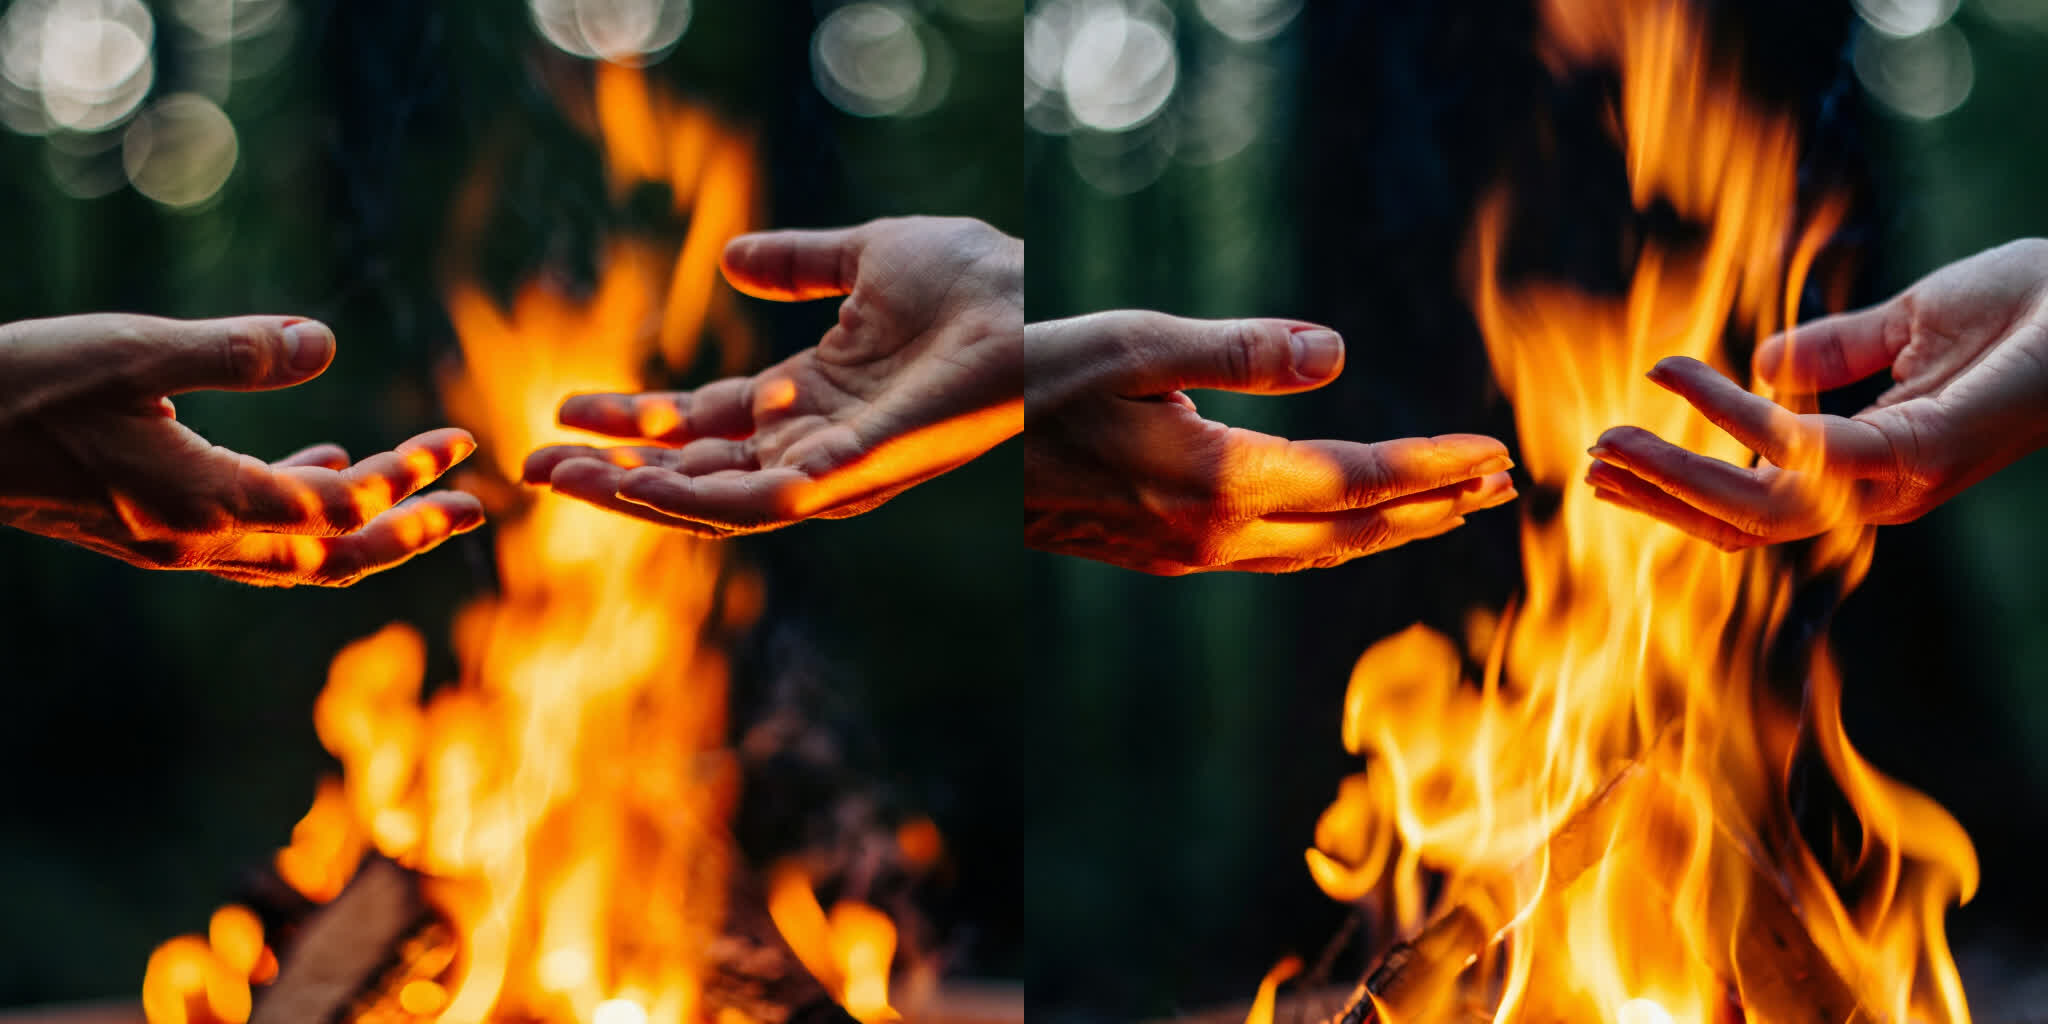
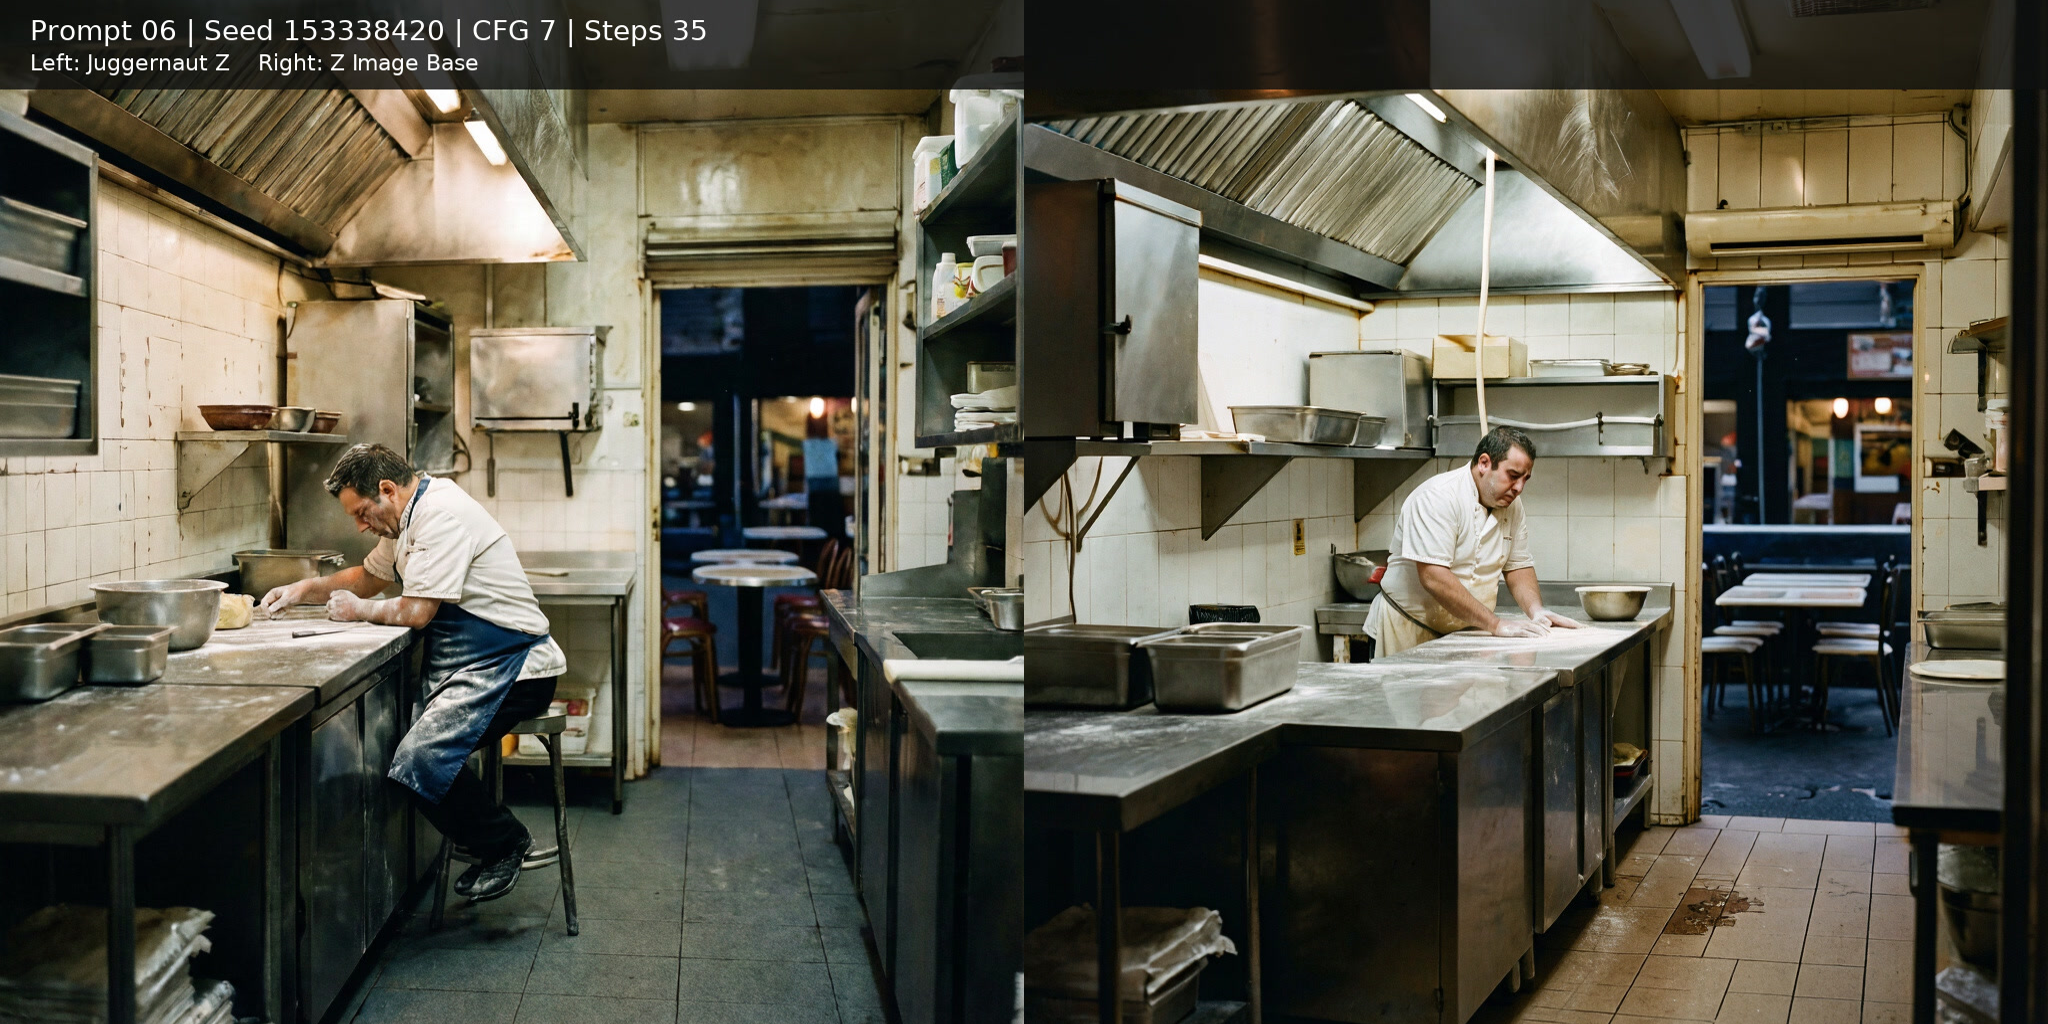
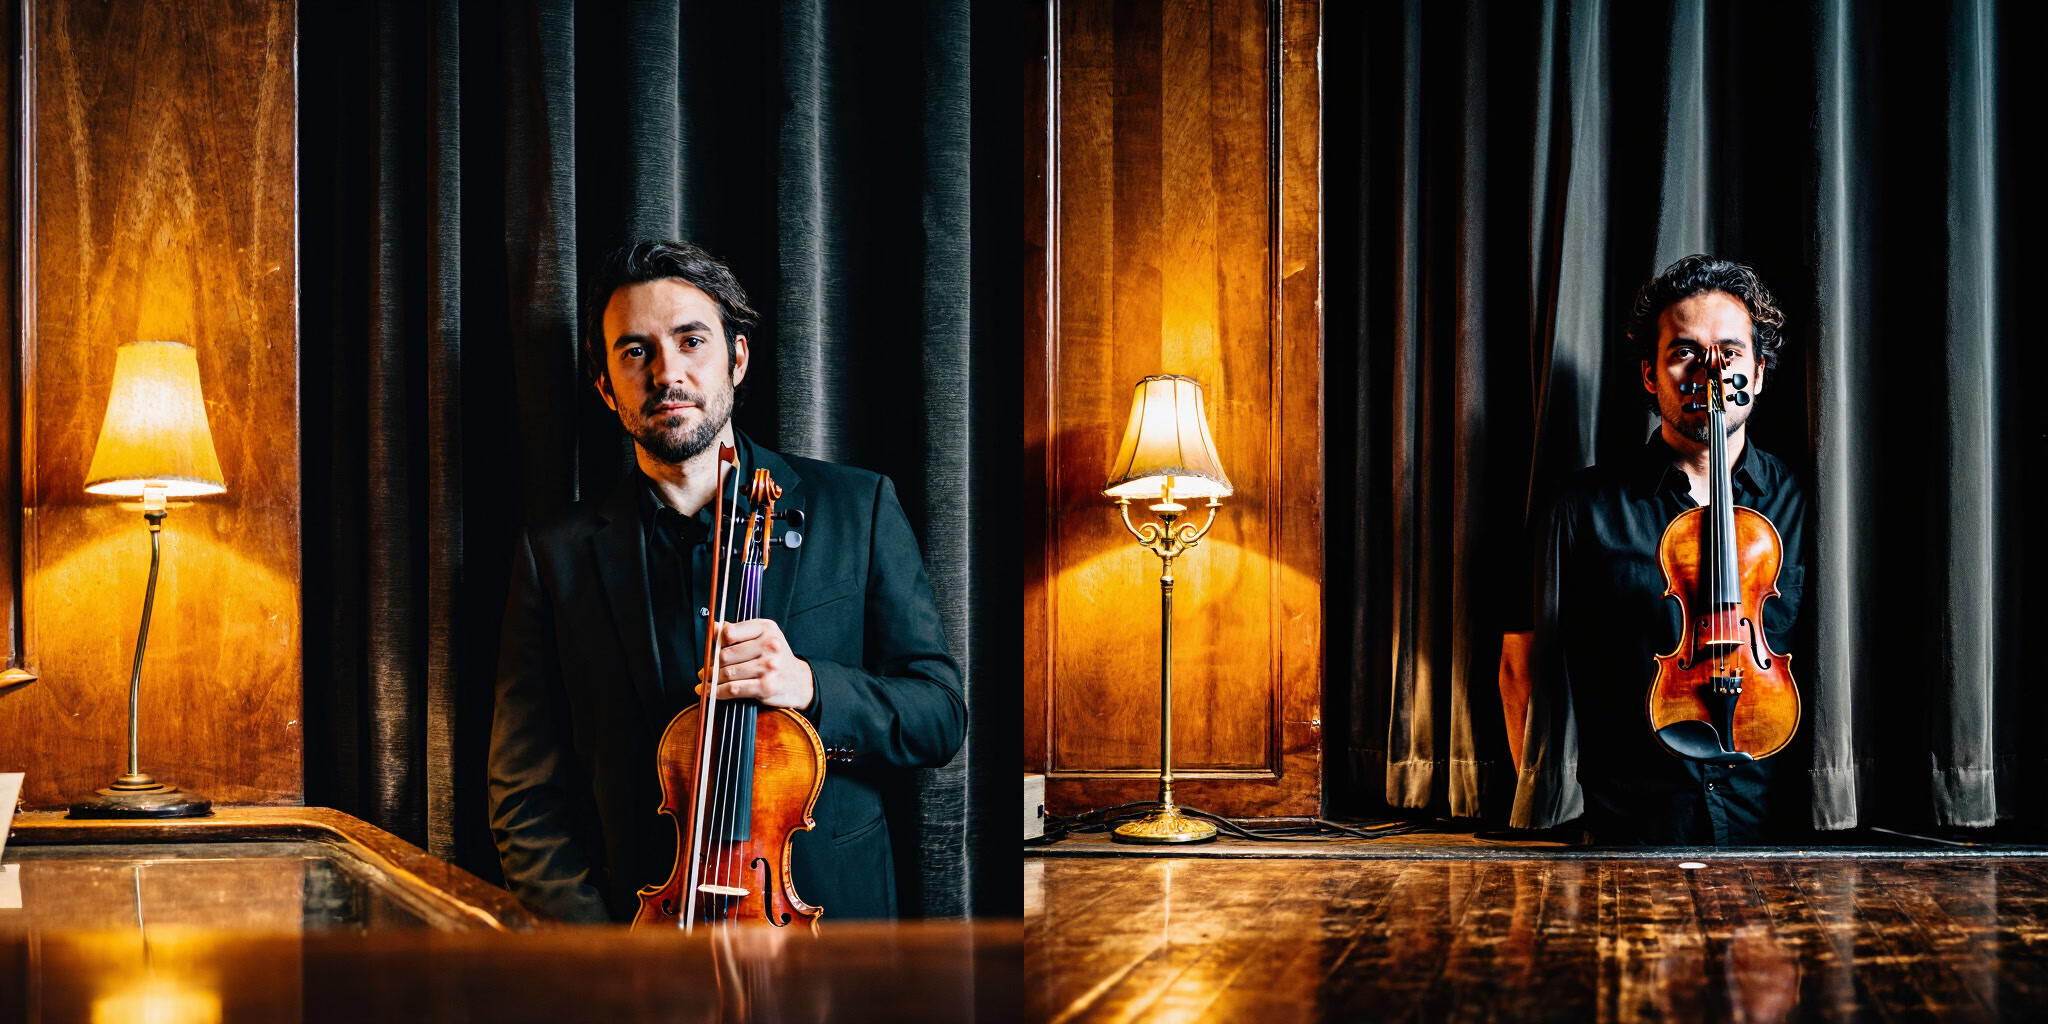
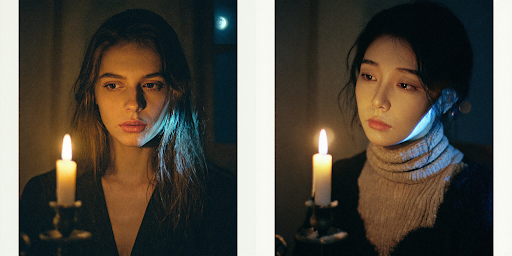
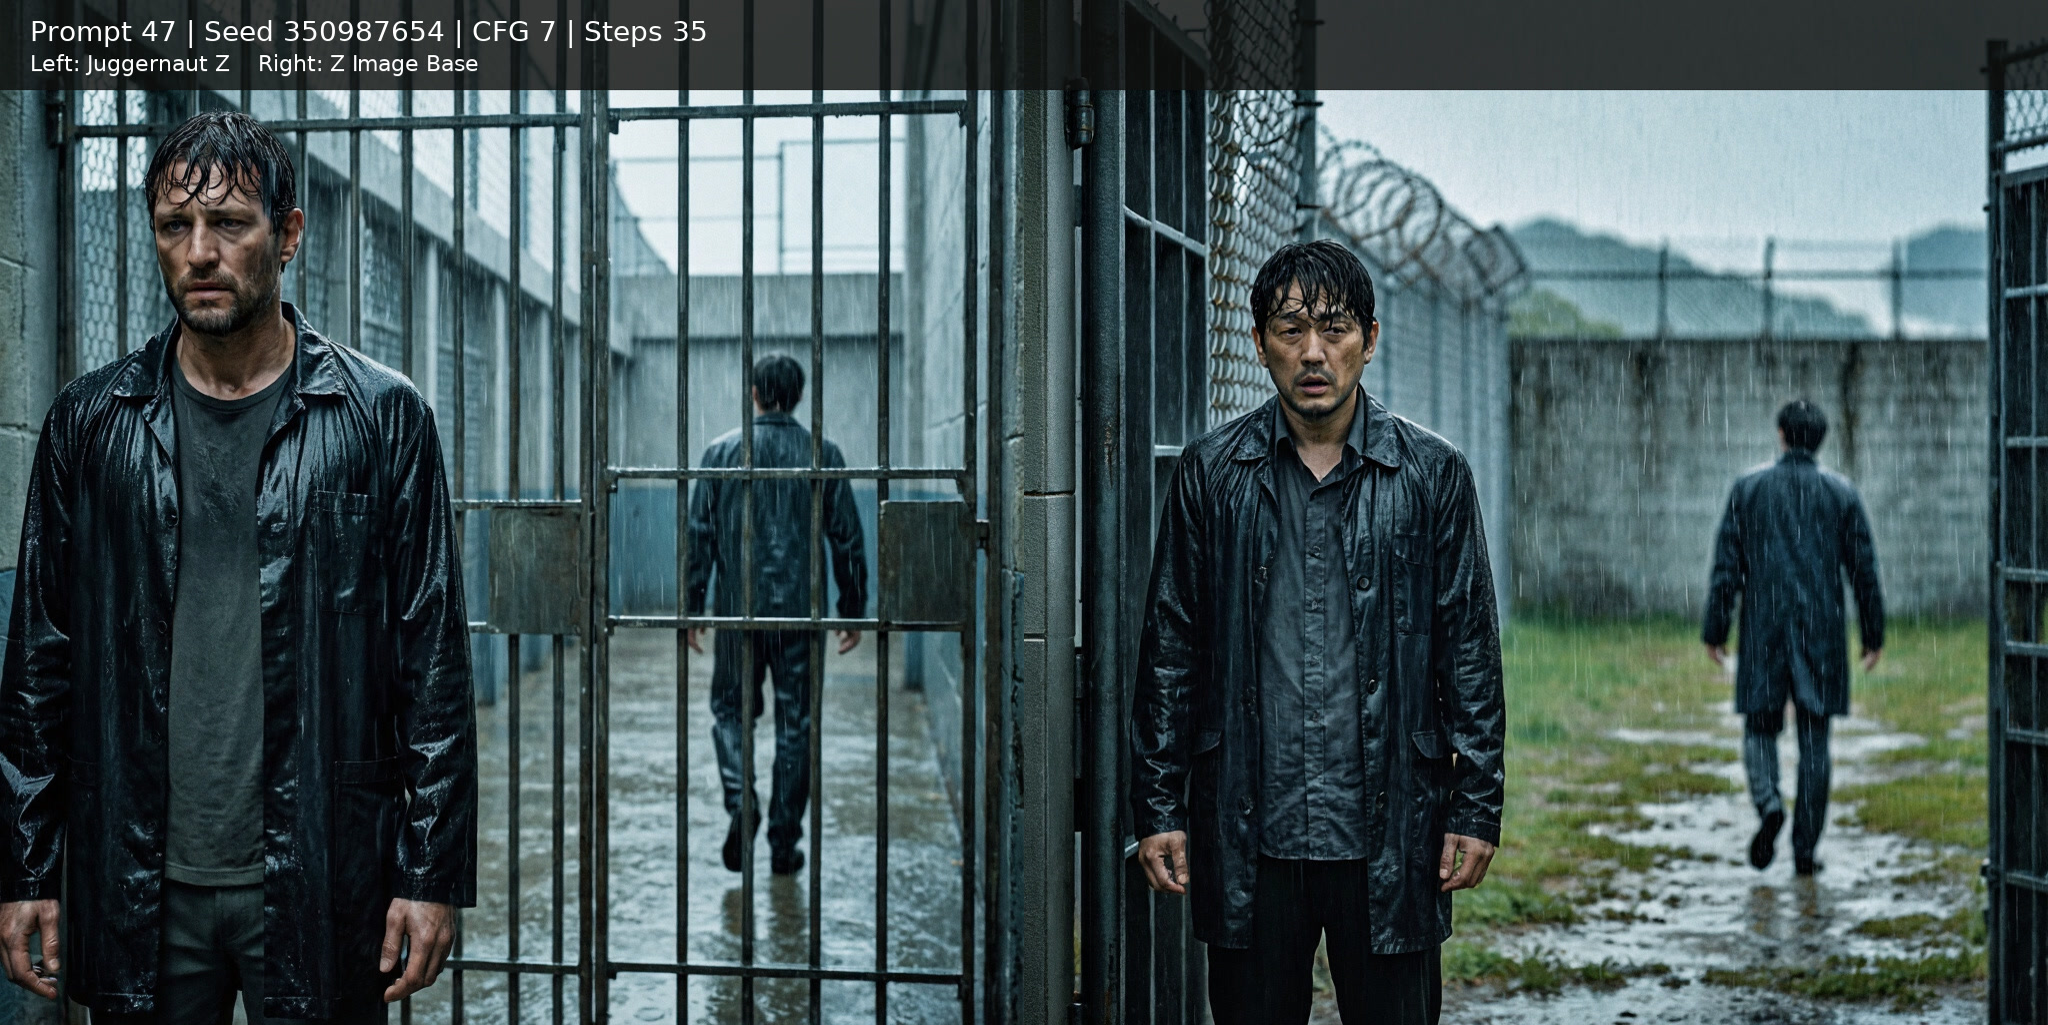
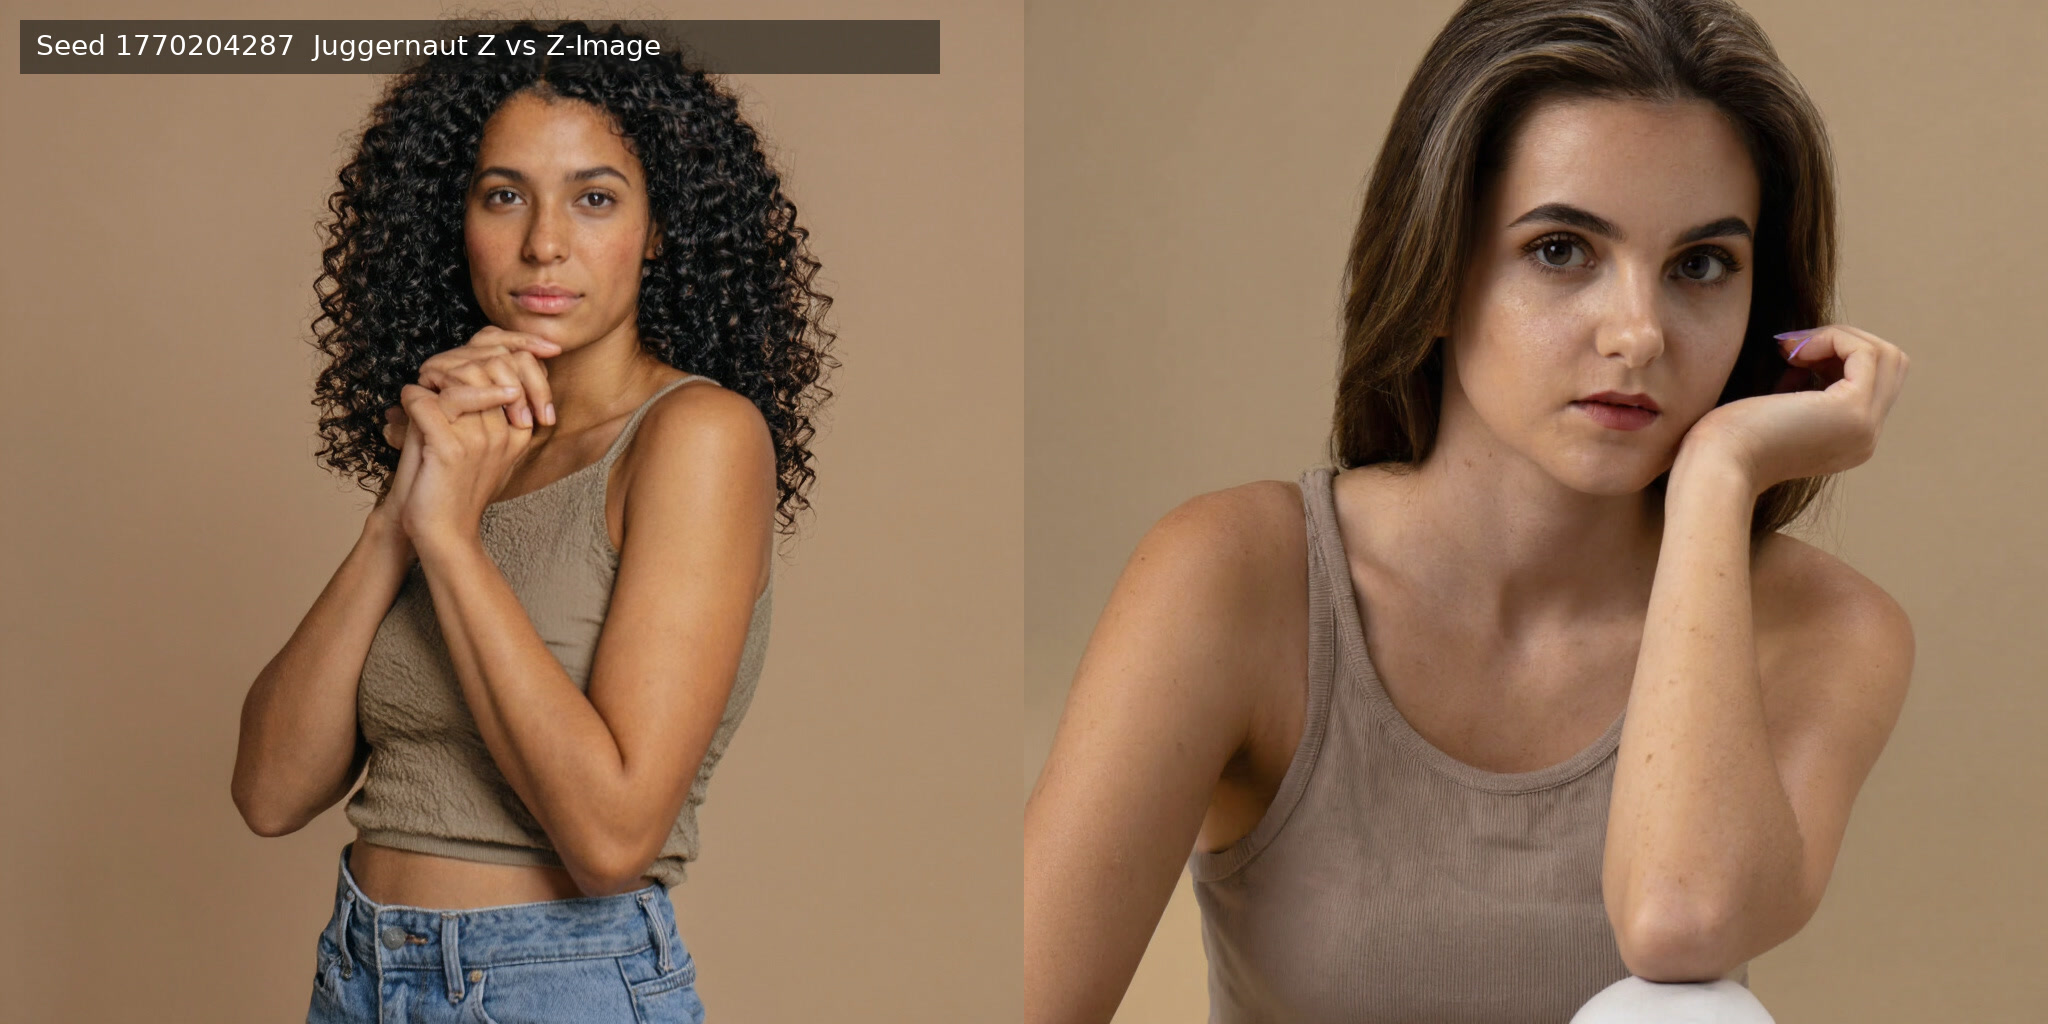
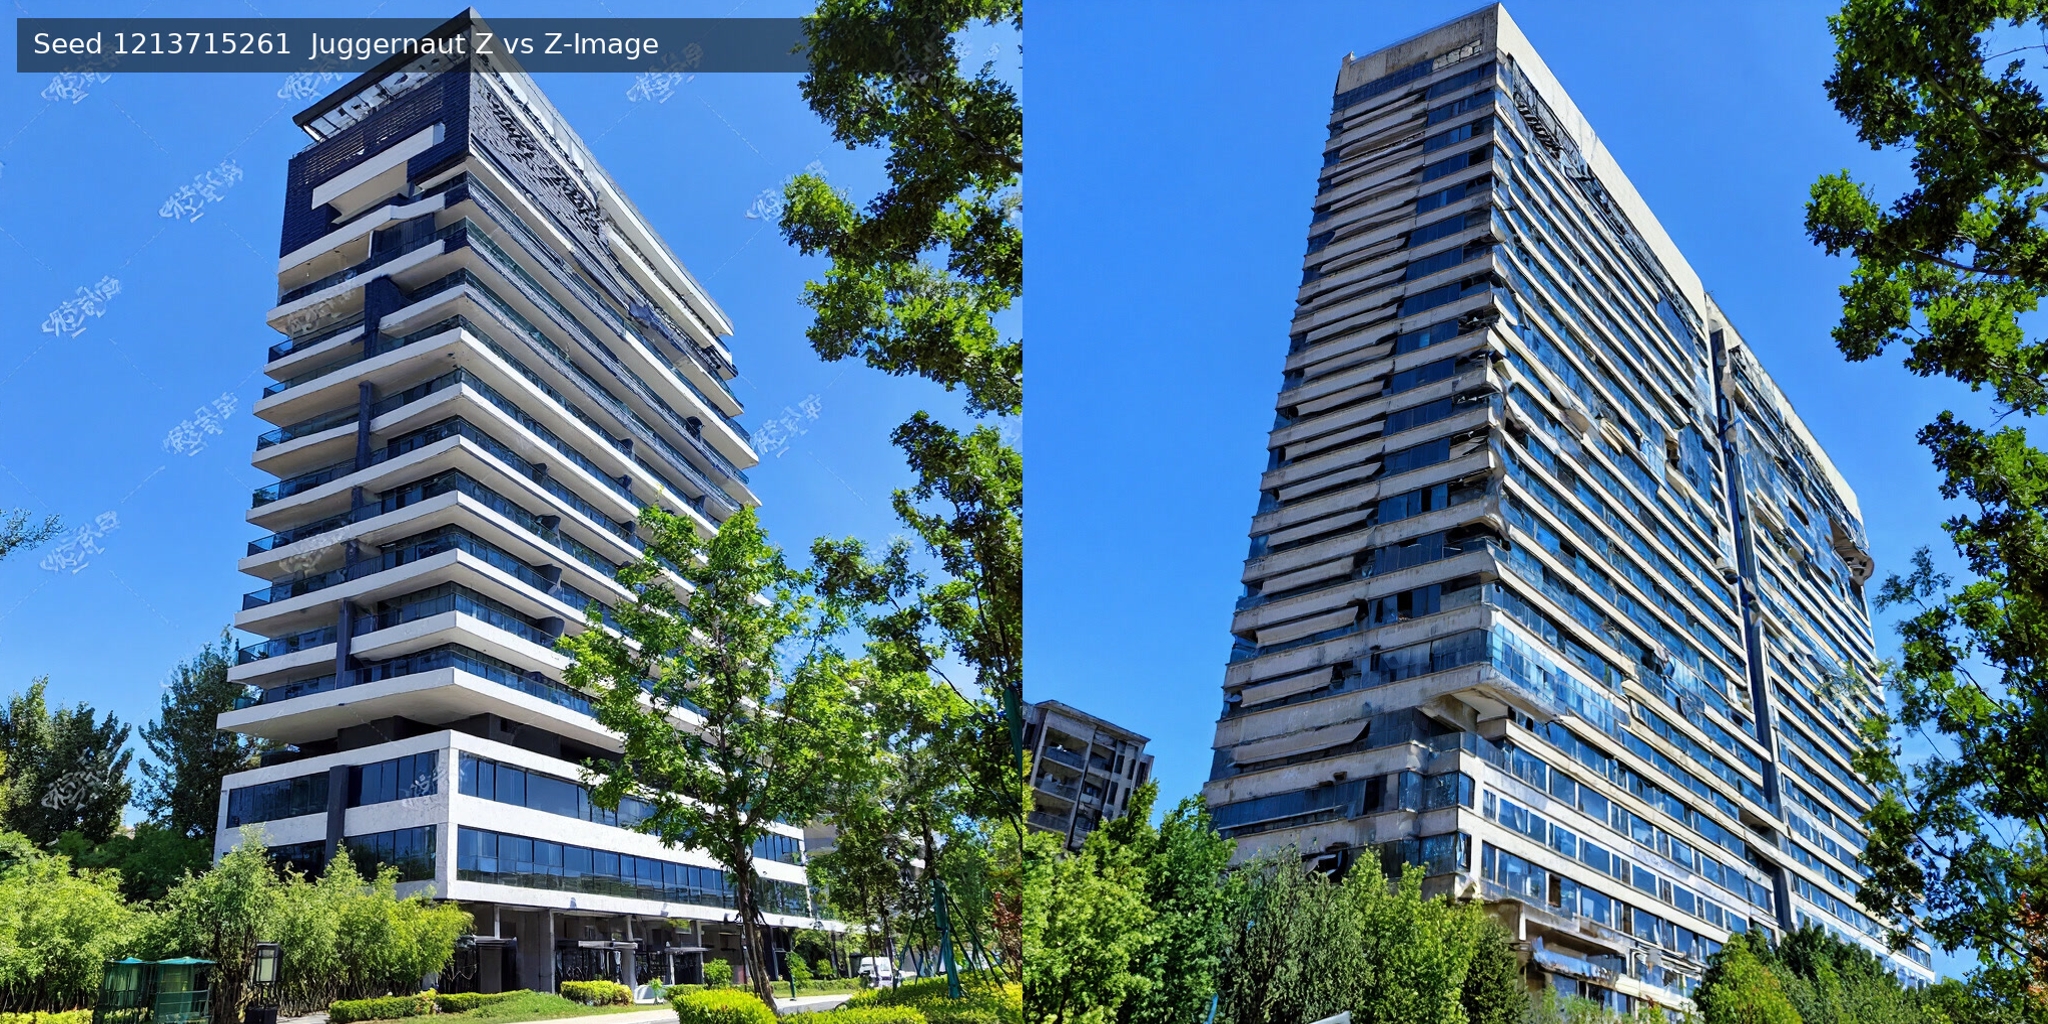
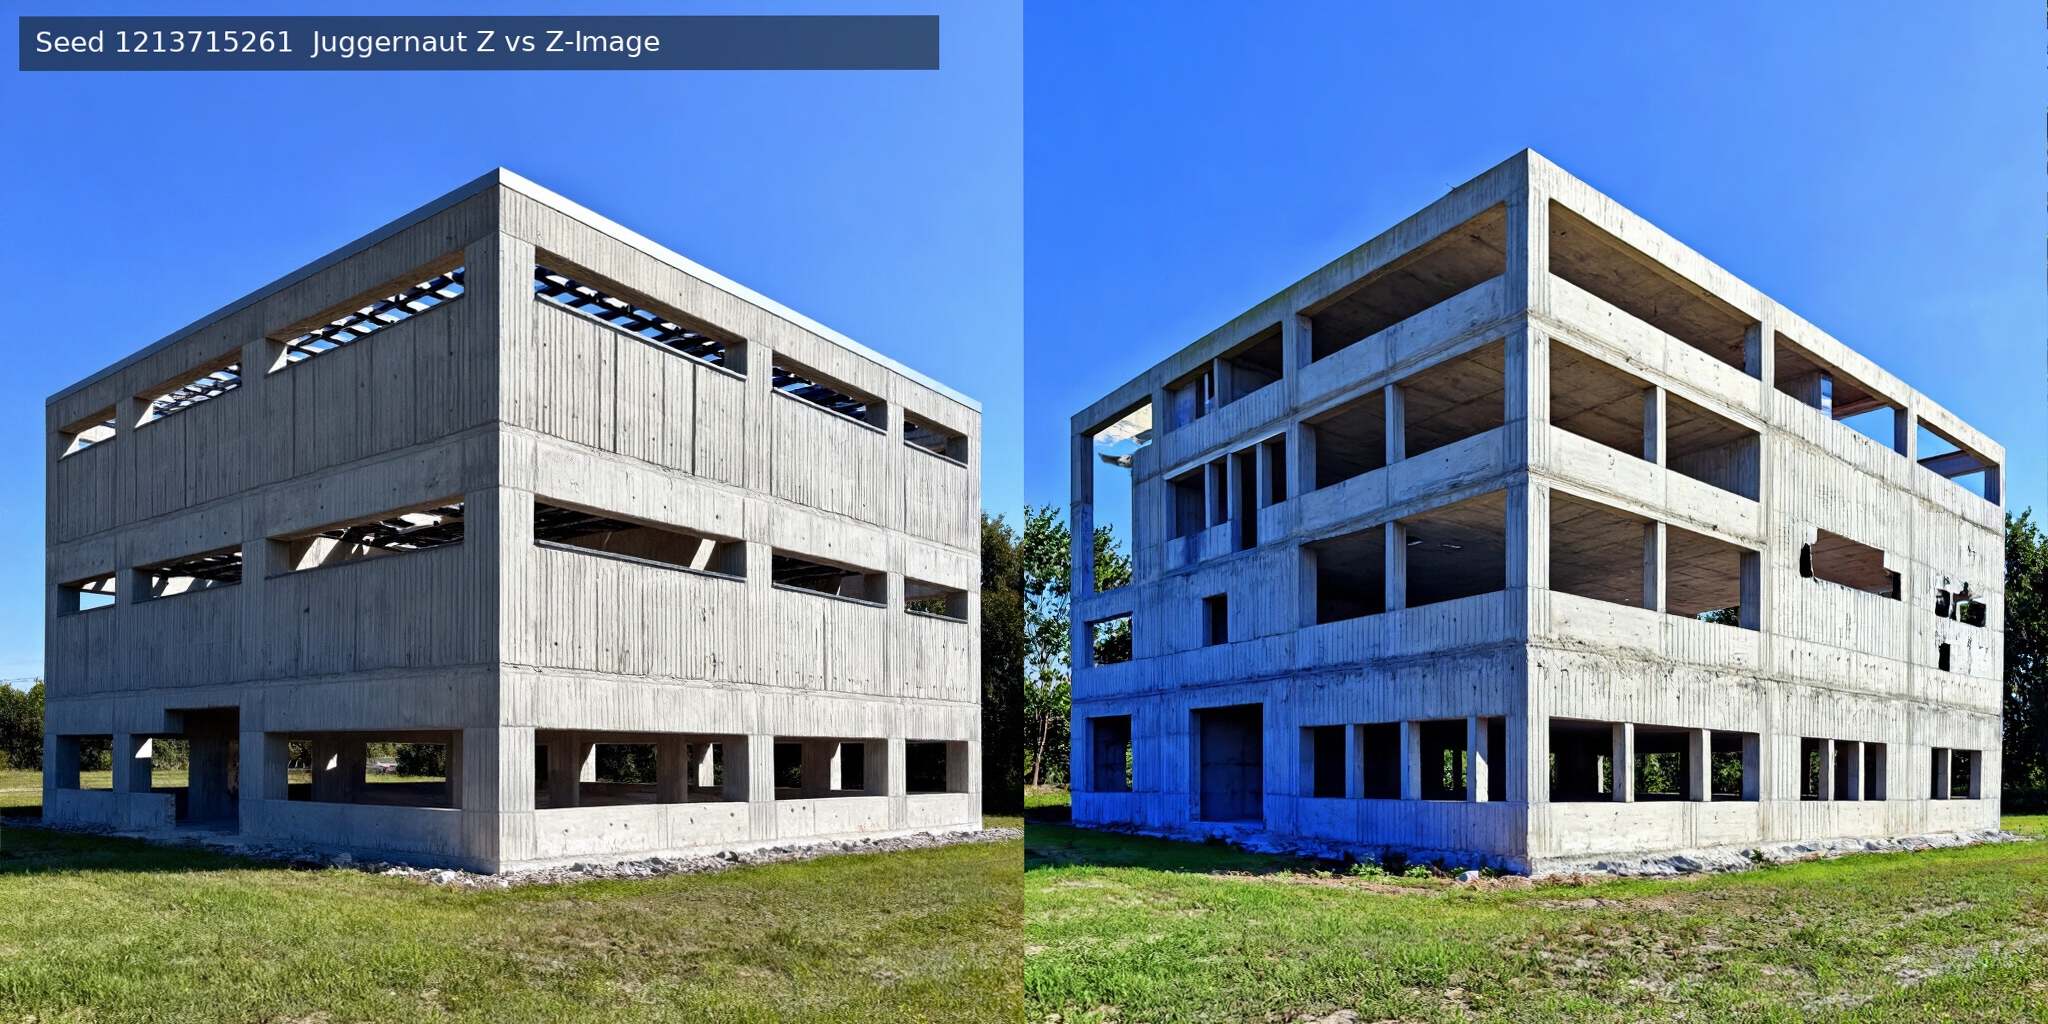
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
*.7z filter=lfs diff=lfs merge=lfs -text
|
| 2 |
+
*.arrow filter=lfs diff=lfs merge=lfs -text
|
| 3 |
+
*.bin filter=lfs diff=lfs merge=lfs -text
|
| 4 |
+
*.bz2 filter=lfs diff=lfs merge=lfs -text
|
| 5 |
+
*.ckpt filter=lfs diff=lfs merge=lfs -text
|
| 6 |
+
*.ftz filter=lfs diff=lfs merge=lfs -text
|
| 7 |
+
*.gz filter=lfs diff=lfs merge=lfs -text
|
| 8 |
+
*.h5 filter=lfs diff=lfs merge=lfs -text
|
| 9 |
+
*.joblib filter=lfs diff=lfs merge=lfs -text
|
| 10 |
+
*.lfs.* filter=lfs diff=lfs merge=lfs -text
|
| 11 |
+
*.mlmodel filter=lfs diff=lfs merge=lfs -text
|
| 12 |
+
*.model filter=lfs diff=lfs merge=lfs -text
|
| 13 |
+
*.msgpack filter=lfs diff=lfs merge=lfs -text
|
| 14 |
+
*.npy filter=lfs diff=lfs merge=lfs -text
|
| 15 |
+
*.npz filter=lfs diff=lfs merge=lfs -text
|
| 16 |
+
*.onnx filter=lfs diff=lfs merge=lfs -text
|
| 17 |
+
*.ot filter=lfs diff=lfs merge=lfs -text
|
| 18 |
+
*.parquet filter=lfs diff=lfs merge=lfs -text
|
| 19 |
+
*.pb filter=lfs diff=lfs merge=lfs -text
|
| 20 |
+
*.pickle filter=lfs diff=lfs merge=lfs -text
|
| 21 |
+
*.pkl filter=lfs diff=lfs merge=lfs -text
|
| 22 |
+
*.pt filter=lfs diff=lfs merge=lfs -text
|
| 23 |
+
*.pth filter=lfs diff=lfs merge=lfs -text
|
| 24 |
+
*.rar filter=lfs diff=lfs merge=lfs -text
|
| 25 |
+
*.safetensors filter=lfs diff=lfs merge=lfs -text
|
| 26 |
+
saved_model/**/* filter=lfs diff=lfs merge=lfs -text
|
| 27 |
+
*.tar.* filter=lfs diff=lfs merge=lfs -text
|
| 28 |
+
*.tar filter=lfs diff=lfs merge=lfs -text
|
| 29 |
+
*.tflite filter=lfs diff=lfs merge=lfs -text
|
| 30 |
+
*.tgz filter=lfs diff=lfs merge=lfs -text
|
| 31 |
+
*.wasm filter=lfs diff=lfs merge=lfs -text
|
| 32 |
+
*.xz filter=lfs diff=lfs merge=lfs -text
|
| 33 |
+
*.zip filter=lfs diff=lfs merge=lfs -text
|
| 34 |
+
*.zst filter=lfs diff=lfs merge=lfs -text
|
| 35 |
+
*tfevents* filter=lfs diff=lfs merge=lfs -text
|
| 36 |
+
Juggernaut_Z_V1_by_RunDiffusion_q4_k_s-001.gguf filter=lfs diff=lfs merge=lfs -text
|
| 37 |
+
Juggernaut_Z_V1_by_RunDiffusion_q4_k_m-002.gguf filter=lfs diff=lfs merge=lfs -text
|
| 38 |
+
Juggernaut_Z_V1_by_RunDiffusion_q5_k_s-005.gguf filter=lfs diff=lfs merge=lfs -text
|
| 39 |
+
Juggernaut_Z_V1_by_RunDiffusion_q5_k_m-003.gguf filter=lfs diff=lfs merge=lfs -text
|
| 40 |
+
Juggernaut_Z_V1_by_RunDiffusion_q6_k-004.gguf filter=lfs diff=lfs merge=lfs -text
|
| 41 |
+
Juggernaut_Z_V1_by_RunDiffusion_q8_0.gguf filter=lfs diff=lfs merge=lfs -text
|
| 42 |
+
diffusers/tokenizer/tokenizer.json filter=lfs diff=lfs merge=lfs -text
|
| 43 |
+
tokenizer/tokenizer.json filter=lfs diff=lfs merge=lfs -text
|
Juggernaut_Z_V1_FP8_e4m3fn.safetensors
ADDED
|
@@ -0,0 +1,3 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
version https://git-lfs.github.com/spec/v1
|
| 2 |
+
oid sha256:27c019bbb2c9a189b20842918a3672859b7b674771eb7e6dedcf826291bd00f4
|
| 3 |
+
size 6154958752
|
Juggernaut_Z_V1_by_RunDiffusion.safetensors
ADDED
|
@@ -0,0 +1,3 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
version https://git-lfs.github.com/spec/v1
|
| 2 |
+
oid sha256:1eecc7c80377b0691776196f0f2f4644fc340260f9cf1a1b22192e2dc166b651
|
| 3 |
+
size 12309866400
|
Juggernaut_Z_V1_by_RunDiffusion_fp16.safetensors
ADDED
|
@@ -0,0 +1,3 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
version https://git-lfs.github.com/spec/v1
|
| 2 |
+
oid sha256:aab0c5252b5ad99c225e9bcece4a46fd80f855ff463ab7d3c9bb2ccacdd75af6
|
| 3 |
+
size 12309865944
|
Juggernaut_Z_V1_by_RunDiffusion_q4_k_m-002.gguf
ADDED
|
@@ -0,0 +1,3 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
version https://git-lfs.github.com/spec/v1
|
| 2 |
+
oid sha256:c781e7be88ef7ed956094cc7ea29859585b631ae7349d71c07a285245d5a9d26
|
| 3 |
+
size 5151107136
|
Juggernaut_Z_V1_by_RunDiffusion_q4_k_s-001.gguf
ADDED
|
@@ -0,0 +1,3 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
version https://git-lfs.github.com/spec/v1
|
| 2 |
+
oid sha256:5ad674cf3dab0fcfd1384ab65746a2cc976a8c1cf1487e050926c7ece6d02c63
|
| 3 |
+
size 4828547136
|
Juggernaut_Z_V1_by_RunDiffusion_q5_k_m-003.gguf
ADDED
|
@@ -0,0 +1,3 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
version https://git-lfs.github.com/spec/v1
|
| 2 |
+
oid sha256:f6a7673ff91e34da8c3d5969c630c0ae48db5dba0b48adb24198c7ab34067304
|
| 3 |
+
size 5677571136
|
Juggernaut_Z_V1_by_RunDiffusion_q5_k_s-005.gguf
ADDED
|
@@ -0,0 +1,3 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
version https://git-lfs.github.com/spec/v1
|
| 2 |
+
oid sha256:68d6e7cb50d02caf6dfbac5b0307d679e2876948e12d6578d864d1231a8ec1ce
|
| 3 |
+
size 5344643136
|
Juggernaut_Z_V1_by_RunDiffusion_q6_k-004.gguf
ADDED
|
@@ -0,0 +1,3 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
version https://git-lfs.github.com/spec/v1
|
| 2 |
+
oid sha256:04f06f3d09bf45d61836e6b828c07f9163747ec18c7a28306ad8ac25967b9340
|
| 3 |
+
size 6049667136
|
Juggernaut_Z_V1_by_RunDiffusion_q8_0.gguf
ADDED
|
@@ -0,0 +1,3 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
version https://git-lfs.github.com/spec/v1
|
| 2 |
+
oid sha256:ad0f9e1b0f0da9455036bebc62ccc9bca93d0d681452a6576ba611cb4070bd7c
|
| 3 |
+
size 7335299136
|
README.md
ADDED
|
@@ -0,0 +1,180 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
---
|
| 2 |
+
license: cc-by-nc-4.0
|
| 3 |
+
language:
|
| 4 |
+
- en
|
| 5 |
+
pipeline_tag: text-to-image
|
| 6 |
+
base_model: Tongyi-MAI/Z-Image
|
| 7 |
+
tags:
|
| 8 |
+
- gguf
|
| 9 |
+
- safetensors
|
| 10 |
+
- text-to-image
|
| 11 |
+
- rundiffusion
|
| 12 |
+
- z-image
|
| 13 |
+
---
|
| 14 |
+
|
| 15 |
+
<div align="center">
|
| 16 |
+
|
| 17 |
+
<a href="https://www.rundiffusion.com/?utm_source=huggingface&utm_medium=model_card&utm_campaign=juggernaut_z_v1&utm_content=header_logo">
|
| 18 |
+
<img src="https://huggingface.co/RunDiffusion/Juggernaut-Z-Image/resolve/main/assets/RD_Mark.png" alt="RunDiffusion" width="110" />
|
| 19 |
+
</a>
|
| 20 |
+
|
| 21 |
+
<h1>Juggernaut Z by RunDiffusion</h1>
|
| 22 |
+
|
| 23 |
+
<p><i>A cinematic fine-tune of Z-Image Base — tuned for presentation-ready output.</i></p>
|
| 24 |
+
|
| 25 |
+
<p>
|
| 26 |
+
<a href="https://www.rundiffusion.com/juggernaut-z?utm_source=huggingface&utm_medium=model_card&utm_campaign=juggernaut_z_v1&utm_content=cta_primary"><img alt="Try Juggernaut Z" src="https://img.shields.io/badge/%E2%96%B6%20Try%20Juggernaut%20Z-7C3AED?style=for-the-badge&labelColor=7C3AED"></a> <a href="https://www.rundiffusion.com/juggernaut-z-prompt-guide?utm_source=huggingface&utm_medium=model_card&utm_campaign=juggernaut_z_v1&utm_content=prompt_guide_badge"><img alt="Prompt Guide" src="https://img.shields.io/badge/Prompt%20Guide-1f1f23?style=for-the-badge"></a> <a href="https://huggingface.co/Tongyi-MAI/Z-Image"><img alt="Base Model: Z-Image" src="https://img.shields.io/badge/%F0%9F%A4%97%20Base%20Model-Z--Image-FFD21E?style=for-the-badge&labelColor=1f1f23"></a> <img alt="License: CC BY-NC 4.0" src="https://img.shields.io/badge/License-CC%20BY--NC%204.0-2ea44f?style=for-the-badge">
|
| 27 |
+
</p>
|
| 28 |
+
|
| 29 |
+
</div>
|
| 30 |
+
|
| 31 |
+
<p align="center">
|
| 32 |
+
<img src="https://www.rundiffusion.com/images/juggernaut-z/hero-image.jpg" alt="Juggernaut Z hero" />
|
| 33 |
+
</p>
|
| 34 |
+
|
| 35 |
+
> Juggernaut Z is a fine-tune of **Z-Image Base** by **Team Juggernaut**, trained by **KandooAI**, and released through **RunDiffusion**. It is tuned for stronger lighting, sharper focus, more refined skin texture, and more cinematic atmosphere — out of the box.
|
| 36 |
+
|
| 37 |
+
This repository hosts the official RunDiffusion release artifacts: full-precision weights, FP16 and FP8 variants, and a full set of GGUF quantizations.
|
| 38 |
+
|
| 39 |
+
---
|
| 40 |
+
|
| 41 |
+
## Highlights
|
| 42 |
+
|
| 43 |
+
- More dramatic, cinematic **lighting** out of the box
|
| 44 |
+
- Sharper **focus** and a more deliberate camera feel
|
| 45 |
+
- Cleaner **portraits** with more natural skin texture
|
| 46 |
+
- Improved **anatomy** and structural integrity
|
| 47 |
+
- Better representation across **ethnicities** by default
|
| 48 |
+
- Tuned for editorial, concept, and cinematic work
|
| 49 |
+
|
| 50 |
+
## Comparisons
|
| 51 |
+
|
| 52 |
+
All sets below show **Juggernaut Z (left)** vs **Z-Image Base (right)**. Source: the [RunDiffusion Juggernaut Z announcement](https://www.rundiffusion.com/juggernaut-z?utm_source=huggingface&utm_medium=model_card&utm_campaign=juggernaut_z_v1&utm_content=comparison_source).
|
| 53 |
+
|
| 54 |
+
### Lighting
|
| 55 |
+
|
| 56 |
+
More dramatic, cinematic lighting out of the box.
|
| 57 |
+
|
| 58 |
+
|
| 59 |
+
|
| 60 |
+
|
| 61 |
+
|
| 62 |
+
|
| 63 |
+
|
| 64 |
+
|
| 65 |
+
### Skin & Texture
|
| 66 |
+
|
| 67 |
+
Cleaner, more natural-looking skin — especially in close-up portraits.
|
| 68 |
+
|
| 69 |
+
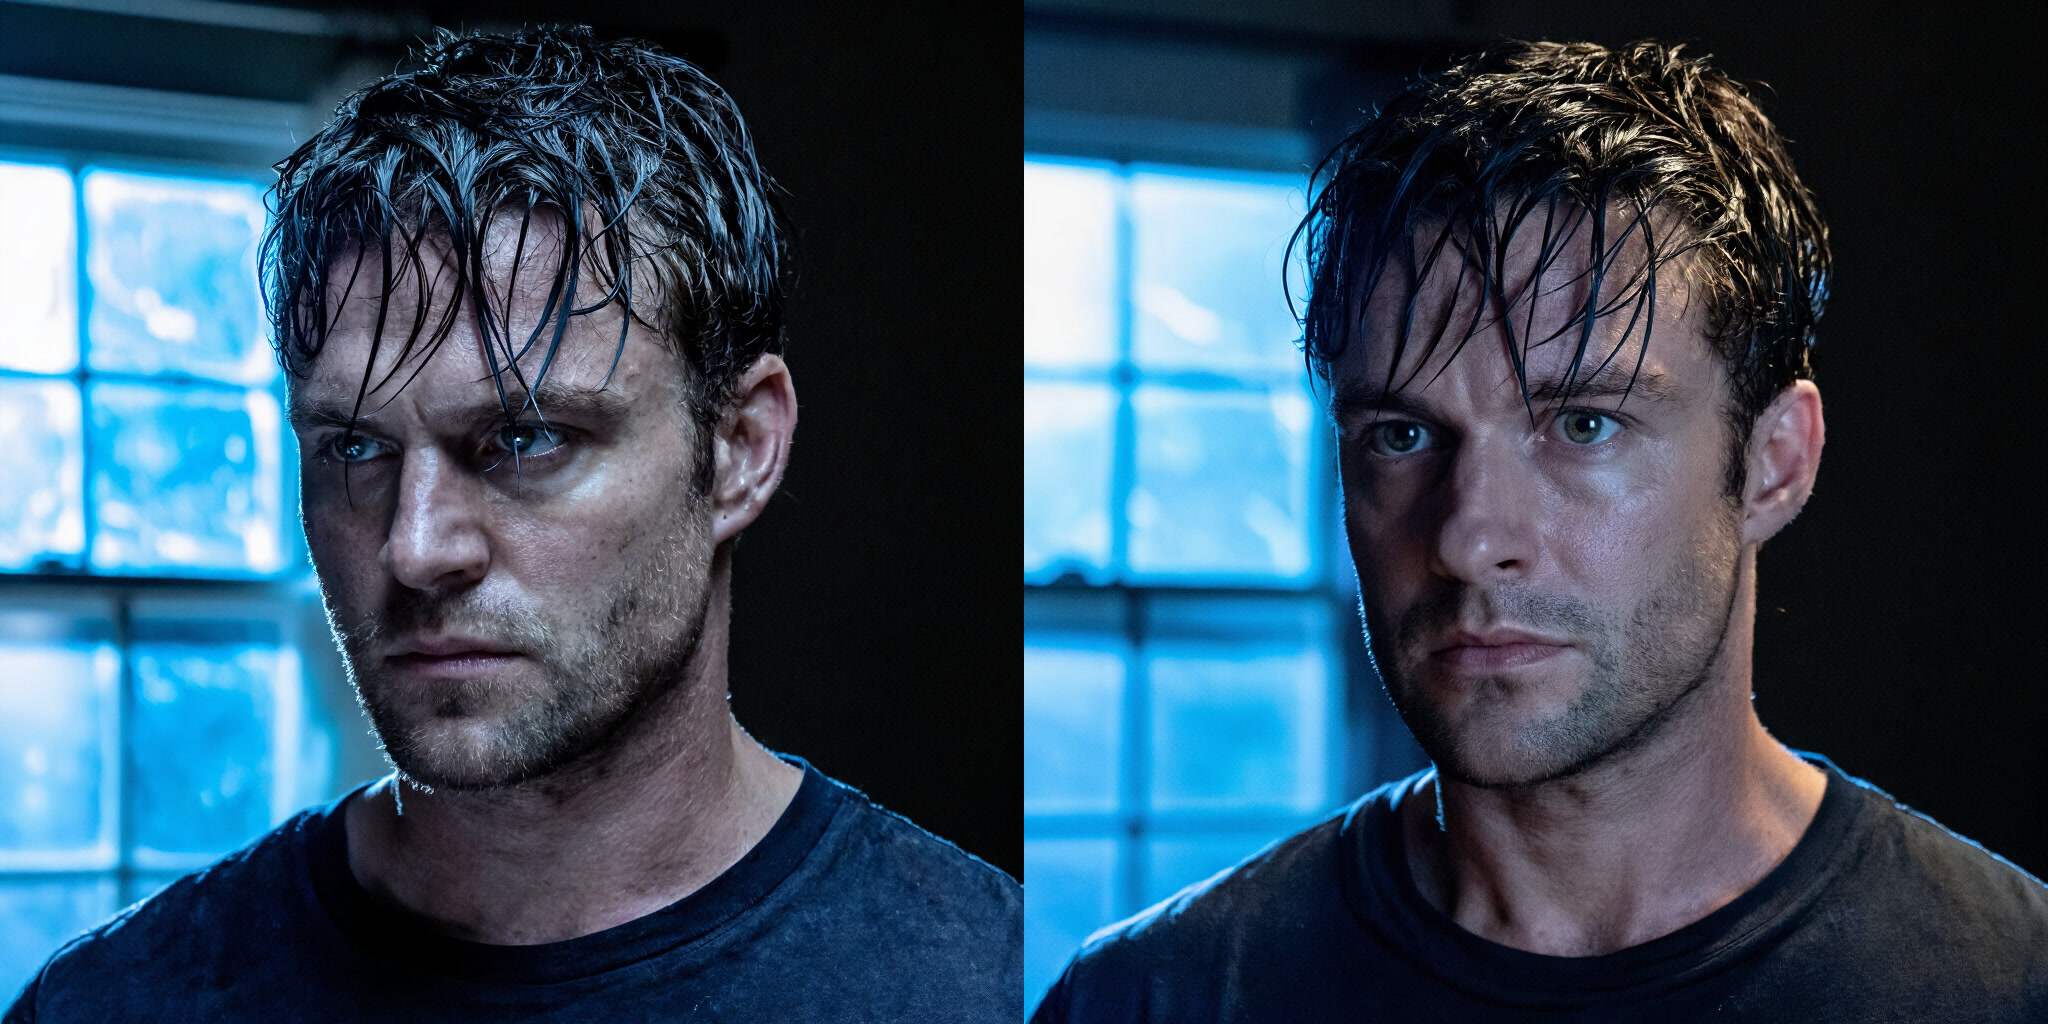
|
| 70 |
+
|
| 71 |
+
|
| 72 |
+
|
| 73 |
+
|
| 74 |
+
### Anatomy
|
| 75 |
+
|
| 76 |
+
Cleaner anatomy and more consistent structural detail across a wide range of subjects.
|
| 77 |
+
|
| 78 |
+
|
| 79 |
+
|
| 80 |
+
|
| 81 |
+
|
| 82 |
+
|
| 83 |
+
### Composition
|
| 84 |
+
|
| 85 |
+
Improved subject and object placement within scenes, with further work planned for v2.
|
| 86 |
+
|
| 87 |
+
|
| 88 |
+
|
| 89 |
+
|
| 90 |
+
|
| 91 |
+
### Diversity
|
| 92 |
+
|
| 93 |
+
More balanced results across ethnic backgrounds, with better representation by default.
|
| 94 |
+
|
| 95 |
+
|
| 96 |
+
|
| 97 |
+
|
| 98 |
+
|
| 99 |
+
|
| 100 |
+
### Architecture
|
| 101 |
+
|
| 102 |
+
Cleaner structural lines and more coherent material rendering.
|
| 103 |
+
|
| 104 |
+
|
| 105 |
+
|
| 106 |
+
|
| 107 |
+
## Recommended Settings
|
| 108 |
+
|
| 109 |
+
| Parameter | Default | Range |
|
| 110 |
+
| --- | --- | --- |
|
| 111 |
+
| CFG | `6` | `6 – 9` |
|
| 112 |
+
| Steps | `35` | `25 – 45` |
|
| 113 |
+
|
| 114 |
+
## Good Fit For
|
| 115 |
+
|
| 116 |
+
- Portraits with cleaner facial detail and stronger focus
|
| 117 |
+
- Cinematic scenes with strong lighting and atmosphere
|
| 118 |
+
- Concept development and visual exploration
|
| 119 |
+
- Editorial and fashion work that benefits from a polished finish
|
| 120 |
+
|
| 121 |
+
## Files In This Repo
|
| 122 |
+
|
| 123 |
+
| File | Format | Notes |
|
| 124 |
+
| --- | --- | --- |
|
| 125 |
+
| `Juggernaut_Z_V1_by_RunDiffusion.safetensors` | safetensors (bf16) | Original release weights |
|
| 126 |
+
| `Juggernaut_Z_V1_by_RunDiffusion_fp16.safetensors` | safetensors (fp16) | Half-precision |
|
| 127 |
+
| `Juggernaut_Z_V1_FP8_e4m3fn.safetensors` | safetensors (fp8 e4m3fn) | Lower VRAM footprint |
|
| 128 |
+
| `Juggernaut_Z_V1_by_RunDiffusion_q8_0.gguf` | GGUF · q8_0 | Highest-quality quant |
|
| 129 |
+
| `Juggernaut_Z_V1_by_RunDiffusion_q6_k-004.gguf` | GGUF · q6_k | |
|
| 130 |
+
| `Juggernaut_Z_V1_by_RunDiffusion_q5_k_m-003.gguf` | GGUF · q5_k_m | |
|
| 131 |
+
| `Juggernaut_Z_V1_by_RunDiffusion_q5_k_s-005.gguf` | GGUF · q5_k_s | |
|
| 132 |
+
| `Juggernaut_Z_V1_by_RunDiffusion_q4_k_m-002.gguf` | GGUF · q4_k_m | |
|
| 133 |
+
| `Juggernaut_Z_V1_by_RunDiffusion_q4_k_s-001.gguf` | GGUF · q4_k_s | Smallest footprint |
|
| 134 |
+
| `model_index.json` + `transformer/`, `text_encoder/`, `tokenizer/`, `vae/`, `scheduler/` | 🤗 Diffusers format | Loaded by `DiffusionPipeline.from_pretrained("RunDiffusion/Juggernaut-Z-Image")` |
|
| 135 |
+
|
| 136 |
+
Use the `.safetensors` variants with the workflow that matches your local inference stack. Use the `.gguf` variants with a GGUF-compatible runtime. Use the Diffusers component layout with the 🤗 Diffusers library — see below.
|
| 137 |
+
|
| 138 |
+
## Use with 🤗 Diffusers
|
| 139 |
+
|
| 140 |
+
The repo includes `model_index.json` and the standard 🤗 Diffusers component directories (`transformer/`, `text_encoder/`, `tokenizer/`, `vae/`, `scheduler/`) at the root, exported as a `ZImagePipeline`. Load it with:
|
| 141 |
+
|
| 142 |
+
```python
|
| 143 |
+
from diffusers import DiffusionPipeline
|
| 144 |
+
import torch
|
| 145 |
+
|
| 146 |
+
pipe = DiffusionPipeline.from_pretrained(
|
| 147 |
+
"RunDiffusion/Juggernaut-Z-Image",
|
| 148 |
+
torch_dtype=torch.bfloat16,
|
| 149 |
+
).to("cuda")
|
| 150 |
+
|
| 151 |
+
image = pipe(
|
| 152 |
+
"a cinematic portrait, dramatic lighting",
|
| 153 |
+
guidance_scale=6.0,
|
| 154 |
+
num_inference_steps=35,
|
| 155 |
+
).images[0]
|
| 156 |
+
image.save("output.png")
|
| 157 |
+
```
|
| 158 |
+
|
| 159 |
+
`from_pretrained` only downloads files declared in `model_index.json`, so it will not pull the standalone `.safetensors` / `.gguf` variants at the repo root. Requires a version of `diffusers` that includes `ZImagePipeline` support (verified against `diffusers` 0.37.1 and 0.38.0). Commercial use of the model and its outputs is restricted under CC BY-NC 4.0 — see [License & Commercial Use](#license--commercial-use) below.
|
| 160 |
+
|
| 161 |
+
## Links
|
| 162 |
+
|
| 163 |
+
- **Run Juggernaut Z on RunDiffusion** → [rundiffusion.com/juggernaut-z](https://www.rundiffusion.com/juggernaut-z?utm_source=huggingface&utm_medium=model_card&utm_campaign=juggernaut_z_v1&utm_content=footer_run)
|
| 164 |
+
- **Prompt guide** → [Juggernaut Z Prompt Guide](https://www.rundiffusion.com/juggernaut-z-prompt-guide?utm_source=huggingface&utm_medium=model_card&utm_campaign=juggernaut_z_v1&utm_content=footer_prompt_guide)
|
| 165 |
+
- **Base model** → [Tongyi-MAI/Z-Image](https://huggingface.co/Tongyi-MAI/Z-Image)
|
| 166 |
+
|
| 167 |
+
## Attribution
|
| 168 |
+
|
| 169 |
+
Juggernaut Z is built on Z-Image Base — credit for the upstream base model belongs to the Z-Image team. This fine-tuned release is by **Team Juggernaut**, with training by **KandooAI**, published by **RunDiffusion**.
|
| 170 |
+
|
| 171 |
+
## License & Commercial Use
|
| 172 |
+
|
| 173 |
+
Juggernaut Z is released under **[CC BY-NC 4.0](https://creativecommons.org/licenses/by-nc/4.0/)**:
|
| 174 |
+
|
| 175 |
+
- **BY** — attribute RunDiffusion / Team Juggernaut / KandooAI when sharing output.
|
| 176 |
+
- **NC** — **non-commercial use only**. You may not use the model — or its outputs in a workflow — for commercial purposes without a license.
|
| 177 |
+
|
| 178 |
+
You are free to fine-tune, merge, build LoRAs, and otherwise modify the model for non-commercial purposes.
|
| 179 |
+
|
| 180 |
+
**For commercial licensing**, custom models, business inquiries, or consultation, contact **[juggernaut@rundiffusion.com](mailto:juggernaut@rundiffusion.com)**.
|
assets/RD_Mark.png
ADDED

|
model_index.json
ADDED
|
@@ -0,0 +1,25 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
{
|
| 2 |
+
"_class_name": "ZImagePipeline",
|
| 3 |
+
"_diffusers_version": "0.37.1",
|
| 4 |
+
"_name_or_path": "Tongyi-MAI/Z-Image",
|
| 5 |
+
"scheduler": [
|
| 6 |
+
"diffusers",
|
| 7 |
+
"FlowMatchEulerDiscreteScheduler"
|
| 8 |
+
],
|
| 9 |
+
"text_encoder": [
|
| 10 |
+
"transformers",
|
| 11 |
+
"Qwen3Model"
|
| 12 |
+
],
|
| 13 |
+
"tokenizer": [
|
| 14 |
+
"transformers",
|
| 15 |
+
"Qwen2Tokenizer"
|
| 16 |
+
],
|
| 17 |
+
"transformer": [
|
| 18 |
+
"diffusers",
|
| 19 |
+
"ZImageTransformer2DModel"
|
| 20 |
+
],
|
| 21 |
+
"vae": [
|
| 22 |
+
"diffusers",
|
| 23 |
+
"AutoencoderKL"
|
| 24 |
+
]
|
| 25 |
+
}
|
scheduler/scheduler_config.json
ADDED
|
@@ -0,0 +1,18 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
{
|
| 2 |
+
"_class_name": "FlowMatchEulerDiscreteScheduler",
|
| 3 |
+
"_diffusers_version": "0.37.1",
|
| 4 |
+
"base_image_seq_len": 256,
|
| 5 |
+
"base_shift": 0.5,
|
| 6 |
+
"invert_sigmas": false,
|
| 7 |
+
"max_image_seq_len": 4096,
|
| 8 |
+
"max_shift": 1.15,
|
| 9 |
+
"num_train_timesteps": 1000,
|
| 10 |
+
"shift": 6.0,
|
| 11 |
+
"shift_terminal": null,
|
| 12 |
+
"stochastic_sampling": false,
|
| 13 |
+
"time_shift_type": "exponential",
|
| 14 |
+
"use_beta_sigmas": false,
|
| 15 |
+
"use_dynamic_shifting": false,
|
| 16 |
+
"use_exponential_sigmas": false,
|
| 17 |
+
"use_karras_sigmas": false
|
| 18 |
+
}
|
text_encoder/config.json
ADDED
|
@@ -0,0 +1,30 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
{
|
| 2 |
+
"architectures": [
|
| 3 |
+
"Qwen3ForCausalLM"
|
| 4 |
+
],
|
| 5 |
+
"attention_bias": false,
|
| 6 |
+
"attention_dropout": 0.0,
|
| 7 |
+
"bos_token_id": 151643,
|
| 8 |
+
"eos_token_id": 151645,
|
| 9 |
+
"head_dim": 128,
|
| 10 |
+
"hidden_act": "silu",
|
| 11 |
+
"hidden_size": 2560,
|
| 12 |
+
"initializer_range": 0.02,
|
| 13 |
+
"intermediate_size": 9728,
|
| 14 |
+
"max_position_embeddings": 40960,
|
| 15 |
+
"max_window_layers": 36,
|
| 16 |
+
"model_type": "qwen3",
|
| 17 |
+
"num_attention_heads": 32,
|
| 18 |
+
"num_hidden_layers": 36,
|
| 19 |
+
"num_key_value_heads": 8,
|
| 20 |
+
"rms_norm_eps": 1e-06,
|
| 21 |
+
"rope_scaling": null,
|
| 22 |
+
"rope_theta": 1000000,
|
| 23 |
+
"sliding_window": null,
|
| 24 |
+
"tie_word_embeddings": true,
|
| 25 |
+
"torch_dtype": "bfloat16",
|
| 26 |
+
"transformers_version": "4.51.0",
|
| 27 |
+
"use_cache": true,
|
| 28 |
+
"use_sliding_window": false,
|
| 29 |
+
"vocab_size": 151936
|
| 30 |
+
}
|
text_encoder/generation_config.json
ADDED
|
@@ -0,0 +1,13 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
{
|
| 2 |
+
"bos_token_id": 151643,
|
| 3 |
+
"do_sample": true,
|
| 4 |
+
"eos_token_id": [
|
| 5 |
+
151645,
|
| 6 |
+
151643
|
| 7 |
+
],
|
| 8 |
+
"pad_token_id": 151643,
|
| 9 |
+
"temperature": 0.6,
|
| 10 |
+
"top_k": 20,
|
| 11 |
+
"top_p": 0.95,
|
| 12 |
+
"transformers_version": "4.51.0"
|
| 13 |
+
}
|
text_encoder/model-00001-of-00003.safetensors
ADDED
|
@@ -0,0 +1,3 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
version https://git-lfs.github.com/spec/v1
|
| 2 |
+
oid sha256:328a91d3122359d5547f9d79521205bc0a46e1f79a792dfe650e99fc2d651223
|
| 3 |
+
size 3957900840
|
text_encoder/model-00002-of-00003.safetensors
ADDED
|
@@ -0,0 +1,3 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
version https://git-lfs.github.com/spec/v1
|
| 2 |
+
oid sha256:6cd087b316306a68c562436b5492edbcf6e16c6dba3a1308279caa5a58e21ca5
|
| 3 |
+
size 3987450520
|
text_encoder/model-00003-of-00003.safetensors
ADDED
|
@@ -0,0 +1,3 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
version https://git-lfs.github.com/spec/v1
|
| 2 |
+
oid sha256:7ca841ee75b9c61267c0c6148fd8d096d3d21b6d3e161256a9b878154f91fc52
|
| 3 |
+
size 99630640
|
text_encoder/model.safetensors.index.json
ADDED
|
@@ -0,0 +1,405 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
{
|
| 2 |
+
"metadata": {
|
| 3 |
+
"total_size": 8044936192
|
| 4 |
+
},
|
| 5 |
+
"weight_map": {
|
| 6 |
+
"model.embed_tokens.weight": "model-00001-of-00003.safetensors",
|
| 7 |
+
"model.layers.0.input_layernorm.weight": "model-00001-of-00003.safetensors",
|
| 8 |
+
"model.layers.0.mlp.down_proj.weight": "model-00001-of-00003.safetensors",
|
| 9 |
+
"model.layers.0.mlp.gate_proj.weight": "model-00001-of-00003.safetensors",
|
| 10 |
+
"model.layers.0.mlp.up_proj.weight": "model-00001-of-00003.safetensors",
|
| 11 |
+
"model.layers.0.post_attention_layernorm.weight": "model-00001-of-00003.safetensors",
|
| 12 |
+
"model.layers.0.self_attn.k_norm.weight": "model-00001-of-00003.safetensors",
|
| 13 |
+
"model.layers.0.self_attn.k_proj.weight": "model-00001-of-00003.safetensors",
|
| 14 |
+
"model.layers.0.self_attn.o_proj.weight": "model-00001-of-00003.safetensors",
|
| 15 |
+
"model.layers.0.self_attn.q_norm.weight": "model-00001-of-00003.safetensors",
|
| 16 |
+
"model.layers.0.self_attn.q_proj.weight": "model-00001-of-00003.safetensors",
|
| 17 |
+
"model.layers.0.self_attn.v_proj.weight": "model-00001-of-00003.safetensors",
|
| 18 |
+
"model.layers.1.input_layernorm.weight": "model-00001-of-00003.safetensors",
|
| 19 |
+
"model.layers.1.mlp.down_proj.weight": "model-00001-of-00003.safetensors",
|
| 20 |
+
"model.layers.1.mlp.gate_proj.weight": "model-00001-of-00003.safetensors",
|
| 21 |
+
"model.layers.1.mlp.up_proj.weight": "model-00001-of-00003.safetensors",
|
| 22 |
+
"model.layers.1.post_attention_layernorm.weight": "model-00001-of-00003.safetensors",
|
| 23 |
+
"model.layers.1.self_attn.k_norm.weight": "model-00001-of-00003.safetensors",
|
| 24 |
+
"model.layers.1.self_attn.k_proj.weight": "model-00001-of-00003.safetensors",
|
| 25 |
+
"model.layers.1.self_attn.o_proj.weight": "model-00001-of-00003.safetensors",
|
| 26 |
+
"model.layers.1.self_attn.q_norm.weight": "model-00001-of-00003.safetensors",
|
| 27 |
+
"model.layers.1.self_attn.q_proj.weight": "model-00001-of-00003.safetensors",
|
| 28 |
+
"model.layers.1.self_attn.v_proj.weight": "model-00001-of-00003.safetensors",
|
| 29 |
+
"model.layers.10.input_layernorm.weight": "model-00001-of-00003.safetensors",
|
| 30 |
+
"model.layers.10.mlp.down_proj.weight": "model-00001-of-00003.safetensors",
|
| 31 |
+
"model.layers.10.mlp.gate_proj.weight": "model-00001-of-00003.safetensors",
|
| 32 |
+
"model.layers.10.mlp.up_proj.weight": "model-00001-of-00003.safetensors",
|
| 33 |
+
"model.layers.10.post_attention_layernorm.weight": "model-00001-of-00003.safetensors",
|
| 34 |
+
"model.layers.10.self_attn.k_norm.weight": "model-00001-of-00003.safetensors",
|
| 35 |
+
"model.layers.10.self_attn.k_proj.weight": "model-00001-of-00003.safetensors",
|
| 36 |
+
"model.layers.10.self_attn.o_proj.weight": "model-00001-of-00003.safetensors",
|
| 37 |
+
"model.layers.10.self_attn.q_norm.weight": "model-00001-of-00003.safetensors",
|
| 38 |
+
"model.layers.10.self_attn.q_proj.weight": "model-00001-of-00003.safetensors",
|
| 39 |
+
"model.layers.10.self_attn.v_proj.weight": "model-00001-of-00003.safetensors",
|
| 40 |
+
"model.layers.11.input_layernorm.weight": "model-00001-of-00003.safetensors",
|
| 41 |
+
"model.layers.11.mlp.down_proj.weight": "model-00001-of-00003.safetensors",
|
| 42 |
+
"model.layers.11.mlp.gate_proj.weight": "model-00001-of-00003.safetensors",
|
| 43 |
+
"model.layers.11.mlp.up_proj.weight": "model-00001-of-00003.safetensors",
|
| 44 |
+
"model.layers.11.post_attention_layernorm.weight": "model-00001-of-00003.safetensors",
|
| 45 |
+
"model.layers.11.self_attn.k_norm.weight": "model-00001-of-00003.safetensors",
|
| 46 |
+
"model.layers.11.self_attn.k_proj.weight": "model-00001-of-00003.safetensors",
|
| 47 |
+
"model.layers.11.self_attn.o_proj.weight": "model-00001-of-00003.safetensors",
|
| 48 |
+
"model.layers.11.self_attn.q_norm.weight": "model-00001-of-00003.safetensors",
|
| 49 |
+
"model.layers.11.self_attn.q_proj.weight": "model-00001-of-00003.safetensors",
|
| 50 |
+
"model.layers.11.self_attn.v_proj.weight": "model-00001-of-00003.safetensors",
|
| 51 |
+
"model.layers.12.input_layernorm.weight": "model-00001-of-00003.safetensors",
|
| 52 |
+
"model.layers.12.mlp.down_proj.weight": "model-00001-of-00003.safetensors",
|
| 53 |
+
"model.layers.12.mlp.gate_proj.weight": "model-00001-of-00003.safetensors",
|
| 54 |
+
"model.layers.12.mlp.up_proj.weight": "model-00001-of-00003.safetensors",
|
| 55 |
+
"model.layers.12.post_attention_layernorm.weight": "model-00001-of-00003.safetensors",
|
| 56 |
+
"model.layers.12.self_attn.k_norm.weight": "model-00001-of-00003.safetensors",
|
| 57 |
+
"model.layers.12.self_attn.k_proj.weight": "model-00001-of-00003.safetensors",
|
| 58 |
+
"model.layers.12.self_attn.o_proj.weight": "model-00001-of-00003.safetensors",
|
| 59 |
+
"model.layers.12.self_attn.q_norm.weight": "model-00001-of-00003.safetensors",
|
| 60 |
+
"model.layers.12.self_attn.q_proj.weight": "model-00001-of-00003.safetensors",
|
| 61 |
+
"model.layers.12.self_attn.v_proj.weight": "model-00001-of-00003.safetensors",
|
| 62 |
+
"model.layers.13.input_layernorm.weight": "model-00001-of-00003.safetensors",
|
| 63 |
+
"model.layers.13.mlp.down_proj.weight": "model-00001-of-00003.safetensors",
|
| 64 |
+
"model.layers.13.mlp.gate_proj.weight": "model-00001-of-00003.safetensors",
|
| 65 |
+
"model.layers.13.mlp.up_proj.weight": "model-00001-of-00003.safetensors",
|
| 66 |
+
"model.layers.13.post_attention_layernorm.weight": "model-00001-of-00003.safetensors",
|
| 67 |
+
"model.layers.13.self_attn.k_norm.weight": "model-00001-of-00003.safetensors",
|
| 68 |
+
"model.layers.13.self_attn.k_proj.weight": "model-00001-of-00003.safetensors",
|
| 69 |
+
"model.layers.13.self_attn.o_proj.weight": "model-00001-of-00003.safetensors",
|
| 70 |
+
"model.layers.13.self_attn.q_norm.weight": "model-00001-of-00003.safetensors",
|
| 71 |
+
"model.layers.13.self_attn.q_proj.weight": "model-00001-of-00003.safetensors",
|
| 72 |
+
"model.layers.13.self_attn.v_proj.weight": "model-00001-of-00003.safetensors",
|
| 73 |
+
"model.layers.14.input_layernorm.weight": "model-00001-of-00003.safetensors",
|
| 74 |
+
"model.layers.14.mlp.down_proj.weight": "model-00001-of-00003.safetensors",
|
| 75 |
+
"model.layers.14.mlp.gate_proj.weight": "model-00001-of-00003.safetensors",
|
| 76 |
+
"model.layers.14.mlp.up_proj.weight": "model-00001-of-00003.safetensors",
|
| 77 |
+
"model.layers.14.post_attention_layernorm.weight": "model-00001-of-00003.safetensors",
|
| 78 |
+
"model.layers.14.self_attn.k_norm.weight": "model-00001-of-00003.safetensors",
|
| 79 |
+
"model.layers.14.self_attn.k_proj.weight": "model-00001-of-00003.safetensors",
|
| 80 |
+
"model.layers.14.self_attn.o_proj.weight": "model-00001-of-00003.safetensors",
|
| 81 |
+
"model.layers.14.self_attn.q_norm.weight": "model-00001-of-00003.safetensors",
|
| 82 |
+
"model.layers.14.self_attn.q_proj.weight": "model-00001-of-00003.safetensors",
|
| 83 |
+
"model.layers.14.self_attn.v_proj.weight": "model-00001-of-00003.safetensors",
|
| 84 |
+
"model.layers.15.input_layernorm.weight": "model-00002-of-00003.safetensors",
|
| 85 |
+
"model.layers.15.mlp.down_proj.weight": "model-00002-of-00003.safetensors",
|
| 86 |
+
"model.layers.15.mlp.gate_proj.weight": "model-00001-of-00003.safetensors",
|
| 87 |
+
"model.layers.15.mlp.up_proj.weight": "model-00001-of-00003.safetensors",
|
| 88 |
+
"model.layers.15.post_attention_layernorm.weight": "model-00002-of-00003.safetensors",
|
| 89 |
+
"model.layers.15.self_attn.k_norm.weight": "model-00001-of-00003.safetensors",
|
| 90 |
+
"model.layers.15.self_attn.k_proj.weight": "model-00001-of-00003.safetensors",
|
| 91 |
+
"model.layers.15.self_attn.o_proj.weight": "model-00001-of-00003.safetensors",
|
| 92 |
+
"model.layers.15.self_attn.q_norm.weight": "model-00001-of-00003.safetensors",
|
| 93 |
+
"model.layers.15.self_attn.q_proj.weight": "model-00001-of-00003.safetensors",
|
| 94 |
+
"model.layers.15.self_attn.v_proj.weight": "model-00001-of-00003.safetensors",
|
| 95 |
+
"model.layers.16.input_layernorm.weight": "model-00002-of-00003.safetensors",
|
| 96 |
+
"model.layers.16.mlp.down_proj.weight": "model-00002-of-00003.safetensors",
|
| 97 |
+
"model.layers.16.mlp.gate_proj.weight": "model-00002-of-00003.safetensors",
|
| 98 |
+
"model.layers.16.mlp.up_proj.weight": "model-00002-of-00003.safetensors",
|
| 99 |
+
"model.layers.16.post_attention_layernorm.weight": "model-00002-of-00003.safetensors",
|
| 100 |
+
"model.layers.16.self_attn.k_norm.weight": "model-00002-of-00003.safetensors",
|
| 101 |
+
"model.layers.16.self_attn.k_proj.weight": "model-00002-of-00003.safetensors",
|
| 102 |
+
"model.layers.16.self_attn.o_proj.weight": "model-00002-of-00003.safetensors",
|
| 103 |
+
"model.layers.16.self_attn.q_norm.weight": "model-00002-of-00003.safetensors",
|
| 104 |
+
"model.layers.16.self_attn.q_proj.weight": "model-00002-of-00003.safetensors",
|
| 105 |
+
"model.layers.16.self_attn.v_proj.weight": "model-00002-of-00003.safetensors",
|
| 106 |
+
"model.layers.17.input_layernorm.weight": "model-00002-of-00003.safetensors",
|
| 107 |
+
"model.layers.17.mlp.down_proj.weight": "model-00002-of-00003.safetensors",
|
| 108 |
+
"model.layers.17.mlp.gate_proj.weight": "model-00002-of-00003.safetensors",
|
| 109 |
+
"model.layers.17.mlp.up_proj.weight": "model-00002-of-00003.safetensors",
|
| 110 |
+
"model.layers.17.post_attention_layernorm.weight": "model-00002-of-00003.safetensors",
|
| 111 |
+
"model.layers.17.self_attn.k_norm.weight": "model-00002-of-00003.safetensors",
|
| 112 |
+
"model.layers.17.self_attn.k_proj.weight": "model-00002-of-00003.safetensors",
|
| 113 |
+
"model.layers.17.self_attn.o_proj.weight": "model-00002-of-00003.safetensors",
|
| 114 |
+
"model.layers.17.self_attn.q_norm.weight": "model-00002-of-00003.safetensors",
|
| 115 |
+
"model.layers.17.self_attn.q_proj.weight": "model-00002-of-00003.safetensors",
|
| 116 |
+
"model.layers.17.self_attn.v_proj.weight": "model-00002-of-00003.safetensors",
|
| 117 |
+
"model.layers.18.input_layernorm.weight": "model-00002-of-00003.safetensors",
|
| 118 |
+
"model.layers.18.mlp.down_proj.weight": "model-00002-of-00003.safetensors",
|
| 119 |
+
"model.layers.18.mlp.gate_proj.weight": "model-00002-of-00003.safetensors",
|
| 120 |
+
"model.layers.18.mlp.up_proj.weight": "model-00002-of-00003.safetensors",
|
| 121 |
+
"model.layers.18.post_attention_layernorm.weight": "model-00002-of-00003.safetensors",
|
| 122 |
+
"model.layers.18.self_attn.k_norm.weight": "model-00002-of-00003.safetensors",
|
| 123 |
+
"model.layers.18.self_attn.k_proj.weight": "model-00002-of-00003.safetensors",
|
| 124 |
+
"model.layers.18.self_attn.o_proj.weight": "model-00002-of-00003.safetensors",
|
| 125 |
+
"model.layers.18.self_attn.q_norm.weight": "model-00002-of-00003.safetensors",
|
| 126 |
+
"model.layers.18.self_attn.q_proj.weight": "model-00002-of-00003.safetensors",
|
| 127 |
+
"model.layers.18.self_attn.v_proj.weight": "model-00002-of-00003.safetensors",
|
| 128 |
+
"model.layers.19.input_layernorm.weight": "model-00002-of-00003.safetensors",
|
| 129 |
+
"model.layers.19.mlp.down_proj.weight": "model-00002-of-00003.safetensors",
|
| 130 |
+
"model.layers.19.mlp.gate_proj.weight": "model-00002-of-00003.safetensors",
|
| 131 |
+
"model.layers.19.mlp.up_proj.weight": "model-00002-of-00003.safetensors",
|
| 132 |
+
"model.layers.19.post_attention_layernorm.weight": "model-00002-of-00003.safetensors",
|
| 133 |
+
"model.layers.19.self_attn.k_norm.weight": "model-00002-of-00003.safetensors",
|
| 134 |
+
"model.layers.19.self_attn.k_proj.weight": "model-00002-of-00003.safetensors",
|
| 135 |
+
"model.layers.19.self_attn.o_proj.weight": "model-00002-of-00003.safetensors",
|
| 136 |
+
"model.layers.19.self_attn.q_norm.weight": "model-00002-of-00003.safetensors",
|
| 137 |
+
"model.layers.19.self_attn.q_proj.weight": "model-00002-of-00003.safetensors",
|
| 138 |
+
"model.layers.19.self_attn.v_proj.weight": "model-00002-of-00003.safetensors",
|
| 139 |
+
"model.layers.2.input_layernorm.weight": "model-00001-of-00003.safetensors",
|
| 140 |
+
"model.layers.2.mlp.down_proj.weight": "model-00001-of-00003.safetensors",
|
| 141 |
+
"model.layers.2.mlp.gate_proj.weight": "model-00001-of-00003.safetensors",
|
| 142 |
+
"model.layers.2.mlp.up_proj.weight": "model-00001-of-00003.safetensors",
|
| 143 |
+
"model.layers.2.post_attention_layernorm.weight": "model-00001-of-00003.safetensors",
|
| 144 |
+
"model.layers.2.self_attn.k_norm.weight": "model-00001-of-00003.safetensors",
|
| 145 |
+
"model.layers.2.self_attn.k_proj.weight": "model-00001-of-00003.safetensors",
|
| 146 |
+
"model.layers.2.self_attn.o_proj.weight": "model-00001-of-00003.safetensors",
|
| 147 |
+
"model.layers.2.self_attn.q_norm.weight": "model-00001-of-00003.safetensors",
|
| 148 |
+
"model.layers.2.self_attn.q_proj.weight": "model-00001-of-00003.safetensors",
|
| 149 |
+
"model.layers.2.self_attn.v_proj.weight": "model-00001-of-00003.safetensors",
|
| 150 |
+
"model.layers.20.input_layernorm.weight": "model-00002-of-00003.safetensors",
|
| 151 |
+
"model.layers.20.mlp.down_proj.weight": "model-00002-of-00003.safetensors",
|
| 152 |
+
"model.layers.20.mlp.gate_proj.weight": "model-00002-of-00003.safetensors",
|
| 153 |
+
"model.layers.20.mlp.up_proj.weight": "model-00002-of-00003.safetensors",
|
| 154 |
+
"model.layers.20.post_attention_layernorm.weight": "model-00002-of-00003.safetensors",
|
| 155 |
+
"model.layers.20.self_attn.k_norm.weight": "model-00002-of-00003.safetensors",
|
| 156 |
+
"model.layers.20.self_attn.k_proj.weight": "model-00002-of-00003.safetensors",
|
| 157 |
+
"model.layers.20.self_attn.o_proj.weight": "model-00002-of-00003.safetensors",
|
| 158 |
+
"model.layers.20.self_attn.q_norm.weight": "model-00002-of-00003.safetensors",
|
| 159 |
+
"model.layers.20.self_attn.q_proj.weight": "model-00002-of-00003.safetensors",
|
| 160 |
+
"model.layers.20.self_attn.v_proj.weight": "model-00002-of-00003.safetensors",
|
| 161 |
+
"model.layers.21.input_layernorm.weight": "model-00002-of-00003.safetensors",
|
| 162 |
+
"model.layers.21.mlp.down_proj.weight": "model-00002-of-00003.safetensors",
|
| 163 |
+
"model.layers.21.mlp.gate_proj.weight": "model-00002-of-00003.safetensors",
|
| 164 |
+
"model.layers.21.mlp.up_proj.weight": "model-00002-of-00003.safetensors",
|
| 165 |
+
"model.layers.21.post_attention_layernorm.weight": "model-00002-of-00003.safetensors",
|
| 166 |
+
"model.layers.21.self_attn.k_norm.weight": "model-00002-of-00003.safetensors",
|
| 167 |
+
"model.layers.21.self_attn.k_proj.weight": "model-00002-of-00003.safetensors",
|
| 168 |
+
"model.layers.21.self_attn.o_proj.weight": "model-00002-of-00003.safetensors",
|
| 169 |
+
"model.layers.21.self_attn.q_norm.weight": "model-00002-of-00003.safetensors",
|
| 170 |
+
"model.layers.21.self_attn.q_proj.weight": "model-00002-of-00003.safetensors",
|
| 171 |
+
"model.layers.21.self_attn.v_proj.weight": "model-00002-of-00003.safetensors",
|
| 172 |
+
"model.layers.22.input_layernorm.weight": "model-00002-of-00003.safetensors",
|
| 173 |
+
"model.layers.22.mlp.down_proj.weight": "model-00002-of-00003.safetensors",
|
| 174 |
+
"model.layers.22.mlp.gate_proj.weight": "model-00002-of-00003.safetensors",
|
| 175 |
+
"model.layers.22.mlp.up_proj.weight": "model-00002-of-00003.safetensors",
|
| 176 |
+
"model.layers.22.post_attention_layernorm.weight": "model-00002-of-00003.safetensors",
|
| 177 |
+
"model.layers.22.self_attn.k_norm.weight": "model-00002-of-00003.safetensors",
|
| 178 |
+
"model.layers.22.self_attn.k_proj.weight": "model-00002-of-00003.safetensors",
|
| 179 |
+
"model.layers.22.self_attn.o_proj.weight": "model-00002-of-00003.safetensors",
|
| 180 |
+
"model.layers.22.self_attn.q_norm.weight": "model-00002-of-00003.safetensors",
|
| 181 |
+
"model.layers.22.self_attn.q_proj.weight": "model-00002-of-00003.safetensors",
|
| 182 |
+
"model.layers.22.self_attn.v_proj.weight": "model-00002-of-00003.safetensors",
|
| 183 |
+
"model.layers.23.input_layernorm.weight": "model-00002-of-00003.safetensors",
|
| 184 |
+
"model.layers.23.mlp.down_proj.weight": "model-00002-of-00003.safetensors",
|
| 185 |
+
"model.layers.23.mlp.gate_proj.weight": "model-00002-of-00003.safetensors",
|
| 186 |
+
"model.layers.23.mlp.up_proj.weight": "model-00002-of-00003.safetensors",
|
| 187 |
+
"model.layers.23.post_attention_layernorm.weight": "model-00002-of-00003.safetensors",
|
| 188 |
+
"model.layers.23.self_attn.k_norm.weight": "model-00002-of-00003.safetensors",
|
| 189 |
+
"model.layers.23.self_attn.k_proj.weight": "model-00002-of-00003.safetensors",
|
| 190 |
+
"model.layers.23.self_attn.o_proj.weight": "model-00002-of-00003.safetensors",
|
| 191 |
+
"model.layers.23.self_attn.q_norm.weight": "model-00002-of-00003.safetensors",
|
| 192 |
+
"model.layers.23.self_attn.q_proj.weight": "model-00002-of-00003.safetensors",
|
| 193 |
+
"model.layers.23.self_attn.v_proj.weight": "model-00002-of-00003.safetensors",
|
| 194 |
+
"model.layers.24.input_layernorm.weight": "model-00002-of-00003.safetensors",
|
| 195 |
+
"model.layers.24.mlp.down_proj.weight": "model-00002-of-00003.safetensors",
|
| 196 |
+
"model.layers.24.mlp.gate_proj.weight": "model-00002-of-00003.safetensors",
|
| 197 |
+
"model.layers.24.mlp.up_proj.weight": "model-00002-of-00003.safetensors",
|
| 198 |
+
"model.layers.24.post_attention_layernorm.weight": "model-00002-of-00003.safetensors",
|
| 199 |
+
"model.layers.24.self_attn.k_norm.weight": "model-00002-of-00003.safetensors",
|
| 200 |
+
"model.layers.24.self_attn.k_proj.weight": "model-00002-of-00003.safetensors",
|
| 201 |
+
"model.layers.24.self_attn.o_proj.weight": "model-00002-of-00003.safetensors",
|
| 202 |
+
"model.layers.24.self_attn.q_norm.weight": "model-00002-of-00003.safetensors",
|
| 203 |
+
"model.layers.24.self_attn.q_proj.weight": "model-00002-of-00003.safetensors",
|
| 204 |
+
"model.layers.24.self_attn.v_proj.weight": "model-00002-of-00003.safetensors",
|
| 205 |
+
"model.layers.25.input_layernorm.weight": "model-00002-of-00003.safetensors",
|
| 206 |
+
"model.layers.25.mlp.down_proj.weight": "model-00002-of-00003.safetensors",
|
| 207 |
+
"model.layers.25.mlp.gate_proj.weight": "model-00002-of-00003.safetensors",
|
| 208 |
+
"model.layers.25.mlp.up_proj.weight": "model-00002-of-00003.safetensors",
|
| 209 |
+
"model.layers.25.post_attention_layernorm.weight": "model-00002-of-00003.safetensors",
|
| 210 |
+
"model.layers.25.self_attn.k_norm.weight": "model-00002-of-00003.safetensors",
|
| 211 |
+
"model.layers.25.self_attn.k_proj.weight": "model-00002-of-00003.safetensors",
|
| 212 |
+
"model.layers.25.self_attn.o_proj.weight": "model-00002-of-00003.safetensors",
|
| 213 |
+
"model.layers.25.self_attn.q_norm.weight": "model-00002-of-00003.safetensors",
|
| 214 |
+
"model.layers.25.self_attn.q_proj.weight": "model-00002-of-00003.safetensors",
|
| 215 |
+
"model.layers.25.self_attn.v_proj.weight": "model-00002-of-00003.safetensors",
|
| 216 |
+
"model.layers.26.input_layernorm.weight": "model-00002-of-00003.safetensors",
|
| 217 |
+
"model.layers.26.mlp.down_proj.weight": "model-00002-of-00003.safetensors",
|
| 218 |
+
"model.layers.26.mlp.gate_proj.weight": "model-00002-of-00003.safetensors",
|
| 219 |
+
"model.layers.26.mlp.up_proj.weight": "model-00002-of-00003.safetensors",
|
| 220 |
+
"model.layers.26.post_attention_layernorm.weight": "model-00002-of-00003.safetensors",
|
| 221 |
+
"model.layers.26.self_attn.k_norm.weight": "model-00002-of-00003.safetensors",
|
| 222 |
+
"model.layers.26.self_attn.k_proj.weight": "model-00002-of-00003.safetensors",
|
| 223 |
+
"model.layers.26.self_attn.o_proj.weight": "model-00002-of-00003.safetensors",
|
| 224 |
+
"model.layers.26.self_attn.q_norm.weight": "model-00002-of-00003.safetensors",
|
| 225 |
+
"model.layers.26.self_attn.q_proj.weight": "model-00002-of-00003.safetensors",
|
| 226 |
+
"model.layers.26.self_attn.v_proj.weight": "model-00002-of-00003.safetensors",
|
| 227 |
+
"model.layers.27.input_layernorm.weight": "model-00002-of-00003.safetensors",
|
| 228 |
+
"model.layers.27.mlp.down_proj.weight": "model-00002-of-00003.safetensors",
|
| 229 |
+
"model.layers.27.mlp.gate_proj.weight": "model-00002-of-00003.safetensors",
|
| 230 |
+
"model.layers.27.mlp.up_proj.weight": "model-00002-of-00003.safetensors",
|
| 231 |
+
"model.layers.27.post_attention_layernorm.weight": "model-00002-of-00003.safetensors",
|
| 232 |
+
"model.layers.27.self_attn.k_norm.weight": "model-00002-of-00003.safetensors",
|
| 233 |
+
"model.layers.27.self_attn.k_proj.weight": "model-00002-of-00003.safetensors",
|
| 234 |
+
"model.layers.27.self_attn.o_proj.weight": "model-00002-of-00003.safetensors",
|
| 235 |
+
"model.layers.27.self_attn.q_norm.weight": "model-00002-of-00003.safetensors",
|
| 236 |
+
"model.layers.27.self_attn.q_proj.weight": "model-00002-of-00003.safetensors",
|
| 237 |
+
"model.layers.27.self_attn.v_proj.weight": "model-00002-of-00003.safetensors",
|
| 238 |
+
"model.layers.28.input_layernorm.weight": "model-00002-of-00003.safetensors",
|
| 239 |
+
"model.layers.28.mlp.down_proj.weight": "model-00002-of-00003.safetensors",
|
| 240 |
+
"model.layers.28.mlp.gate_proj.weight": "model-00002-of-00003.safetensors",
|
| 241 |
+
"model.layers.28.mlp.up_proj.weight": "model-00002-of-00003.safetensors",
|
| 242 |
+
"model.layers.28.post_attention_layernorm.weight": "model-00002-of-00003.safetensors",
|
| 243 |
+
"model.layers.28.self_attn.k_norm.weight": "model-00002-of-00003.safetensors",
|
| 244 |
+
"model.layers.28.self_attn.k_proj.weight": "model-00002-of-00003.safetensors",
|
| 245 |
+
"model.layers.28.self_attn.o_proj.weight": "model-00002-of-00003.safetensors",
|
| 246 |
+
"model.layers.28.self_attn.q_norm.weight": "model-00002-of-00003.safetensors",
|
| 247 |
+
"model.layers.28.self_attn.q_proj.weight": "model-00002-of-00003.safetensors",
|
| 248 |
+
"model.layers.28.self_attn.v_proj.weight": "model-00002-of-00003.safetensors",
|
| 249 |
+
"model.layers.29.input_layernorm.weight": "model-00002-of-00003.safetensors",
|
| 250 |
+
"model.layers.29.mlp.down_proj.weight": "model-00002-of-00003.safetensors",
|
| 251 |
+
"model.layers.29.mlp.gate_proj.weight": "model-00002-of-00003.safetensors",
|
| 252 |
+
"model.layers.29.mlp.up_proj.weight": "model-00002-of-00003.safetensors",
|
| 253 |
+
"model.layers.29.post_attention_layernorm.weight": "model-00002-of-00003.safetensors",
|
| 254 |
+
"model.layers.29.self_attn.k_norm.weight": "model-00002-of-00003.safetensors",
|
| 255 |
+
"model.layers.29.self_attn.k_proj.weight": "model-00002-of-00003.safetensors",
|
| 256 |
+
"model.layers.29.self_attn.o_proj.weight": "model-00002-of-00003.safetensors",
|
| 257 |
+
"model.layers.29.self_attn.q_norm.weight": "model-00002-of-00003.safetensors",
|
| 258 |
+
"model.layers.29.self_attn.q_proj.weight": "model-00002-of-00003.safetensors",
|
| 259 |
+
"model.layers.29.self_attn.v_proj.weight": "model-00002-of-00003.safetensors",
|
| 260 |
+
"model.layers.3.input_layernorm.weight": "model-00001-of-00003.safetensors",
|
| 261 |
+
"model.layers.3.mlp.down_proj.weight": "model-00001-of-00003.safetensors",
|
| 262 |
+
"model.layers.3.mlp.gate_proj.weight": "model-00001-of-00003.safetensors",
|
| 263 |
+
"model.layers.3.mlp.up_proj.weight": "model-00001-of-00003.safetensors",
|
| 264 |
+
"model.layers.3.post_attention_layernorm.weight": "model-00001-of-00003.safetensors",
|
| 265 |
+
"model.layers.3.self_attn.k_norm.weight": "model-00001-of-00003.safetensors",
|
| 266 |
+
"model.layers.3.self_attn.k_proj.weight": "model-00001-of-00003.safetensors",
|
| 267 |
+
"model.layers.3.self_attn.o_proj.weight": "model-00001-of-00003.safetensors",
|
| 268 |
+
"model.layers.3.self_attn.q_norm.weight": "model-00001-of-00003.safetensors",
|
| 269 |
+
"model.layers.3.self_attn.q_proj.weight": "model-00001-of-00003.safetensors",
|
| 270 |
+
"model.layers.3.self_attn.v_proj.weight": "model-00001-of-00003.safetensors",
|
| 271 |
+
"model.layers.30.input_layernorm.weight": "model-00002-of-00003.safetensors",
|
| 272 |
+
"model.layers.30.mlp.down_proj.weight": "model-00002-of-00003.safetensors",
|
| 273 |
+
"model.layers.30.mlp.gate_proj.weight": "model-00002-of-00003.safetensors",
|
| 274 |
+
"model.layers.30.mlp.up_proj.weight": "model-00002-of-00003.safetensors",
|
| 275 |
+
"model.layers.30.post_attention_layernorm.weight": "model-00002-of-00003.safetensors",
|
| 276 |
+
"model.layers.30.self_attn.k_norm.weight": "model-00002-of-00003.safetensors",
|
| 277 |
+
"model.layers.30.self_attn.k_proj.weight": "model-00002-of-00003.safetensors",
|
| 278 |
+
"model.layers.30.self_attn.o_proj.weight": "model-00002-of-00003.safetensors",
|
| 279 |
+
"model.layers.30.self_attn.q_norm.weight": "model-00002-of-00003.safetensors",
|
| 280 |
+
"model.layers.30.self_attn.q_proj.weight": "model-00002-of-00003.safetensors",
|
| 281 |
+
"model.layers.30.self_attn.v_proj.weight": "model-00002-of-00003.safetensors",
|
| 282 |
+
"model.layers.31.input_layernorm.weight": "model-00002-of-00003.safetensors",
|
| 283 |
+
"model.layers.31.mlp.down_proj.weight": "model-00002-of-00003.safetensors",
|
| 284 |
+
"model.layers.31.mlp.gate_proj.weight": "model-00002-of-00003.safetensors",
|
| 285 |
+
"model.layers.31.mlp.up_proj.weight": "model-00002-of-00003.safetensors",
|
| 286 |
+
"model.layers.31.post_attention_layernorm.weight": "model-00002-of-00003.safetensors",
|
| 287 |
+
"model.layers.31.self_attn.k_norm.weight": "model-00002-of-00003.safetensors",
|
| 288 |
+
"model.layers.31.self_attn.k_proj.weight": "model-00002-of-00003.safetensors",
|
| 289 |
+
"model.layers.31.self_attn.o_proj.weight": "model-00002-of-00003.safetensors",
|
| 290 |
+
"model.layers.31.self_attn.q_norm.weight": "model-00002-of-00003.safetensors",
|
| 291 |
+
"model.layers.31.self_attn.q_proj.weight": "model-00002-of-00003.safetensors",
|
| 292 |
+
"model.layers.31.self_attn.v_proj.weight": "model-00002-of-00003.safetensors",
|
| 293 |
+
"model.layers.32.input_layernorm.weight": "model-00002-of-00003.safetensors",
|
| 294 |
+
"model.layers.32.mlp.down_proj.weight": "model-00002-of-00003.safetensors",
|
| 295 |
+
"model.layers.32.mlp.gate_proj.weight": "model-00002-of-00003.safetensors",
|
| 296 |
+
"model.layers.32.mlp.up_proj.weight": "model-00002-of-00003.safetensors",
|
| 297 |
+
"model.layers.32.post_attention_layernorm.weight": "model-00002-of-00003.safetensors",
|
| 298 |
+
"model.layers.32.self_attn.k_norm.weight": "model-00002-of-00003.safetensors",
|
| 299 |
+
"model.layers.32.self_attn.k_proj.weight": "model-00002-of-00003.safetensors",
|
| 300 |
+
"model.layers.32.self_attn.o_proj.weight": "model-00002-of-00003.safetensors",
|
| 301 |
+
"model.layers.32.self_attn.q_norm.weight": "model-00002-of-00003.safetensors",
|
| 302 |
+
"model.layers.32.self_attn.q_proj.weight": "model-00002-of-00003.safetensors",
|
| 303 |
+
"model.layers.32.self_attn.v_proj.weight": "model-00002-of-00003.safetensors",
|
| 304 |
+
"model.layers.33.input_layernorm.weight": "model-00002-of-00003.safetensors",
|
| 305 |
+
"model.layers.33.mlp.down_proj.weight": "model-00002-of-00003.safetensors",
|
| 306 |
+
"model.layers.33.mlp.gate_proj.weight": "model-00002-of-00003.safetensors",
|
| 307 |
+
"model.layers.33.mlp.up_proj.weight": "model-00002-of-00003.safetensors",
|
| 308 |
+
"model.layers.33.post_attention_layernorm.weight": "model-00002-of-00003.safetensors",
|
| 309 |
+
"model.layers.33.self_attn.k_norm.weight": "model-00002-of-00003.safetensors",
|
| 310 |
+
"model.layers.33.self_attn.k_proj.weight": "model-00002-of-00003.safetensors",
|
| 311 |
+
"model.layers.33.self_attn.o_proj.weight": "model-00002-of-00003.safetensors",
|
| 312 |
+
"model.layers.33.self_attn.q_norm.weight": "model-00002-of-00003.safetensors",
|
| 313 |
+
"model.layers.33.self_attn.q_proj.weight": "model-00002-of-00003.safetensors",
|
| 314 |
+
"model.layers.33.self_attn.v_proj.weight": "model-00002-of-00003.safetensors",
|
| 315 |
+
"model.layers.34.input_layernorm.weight": "model-00002-of-00003.safetensors",
|
| 316 |
+
"model.layers.34.mlp.down_proj.weight": "model-00002-of-00003.safetensors",
|
| 317 |
+
"model.layers.34.mlp.gate_proj.weight": "model-00002-of-00003.safetensors",
|
| 318 |
+
"model.layers.34.mlp.up_proj.weight": "model-00002-of-00003.safetensors",
|
| 319 |
+
"model.layers.34.post_attention_layernorm.weight": "model-00002-of-00003.safetensors",
|
| 320 |
+
"model.layers.34.self_attn.k_norm.weight": "model-00002-of-00003.safetensors",
|
| 321 |
+
"model.layers.34.self_attn.k_proj.weight": "model-00002-of-00003.safetensors",
|
| 322 |
+
"model.layers.34.self_attn.o_proj.weight": "model-00002-of-00003.safetensors",
|
| 323 |
+
"model.layers.34.self_attn.q_norm.weight": "model-00002-of-00003.safetensors",
|
| 324 |
+
"model.layers.34.self_attn.q_proj.weight": "model-00002-of-00003.safetensors",
|
| 325 |
+
"model.layers.34.self_attn.v_proj.weight": "model-00002-of-00003.safetensors",
|
| 326 |
+
"model.layers.35.input_layernorm.weight": "model-00003-of-00003.safetensors",
|
| 327 |
+
"model.layers.35.mlp.down_proj.weight": "model-00003-of-00003.safetensors",
|
| 328 |
+
"model.layers.35.mlp.gate_proj.weight": "model-00002-of-00003.safetensors",
|
| 329 |
+
"model.layers.35.mlp.up_proj.weight": "model-00003-of-00003.safetensors",
|
| 330 |
+
"model.layers.35.post_attention_layernorm.weight": "model-00003-of-00003.safetensors",
|
| 331 |
+
"model.layers.35.self_attn.k_norm.weight": "model-00002-of-00003.safetensors",
|
| 332 |
+
"model.layers.35.self_attn.k_proj.weight": "model-00002-of-00003.safetensors",
|
| 333 |
+
"model.layers.35.self_attn.o_proj.weight": "model-00002-of-00003.safetensors",
|
| 334 |
+
"model.layers.35.self_attn.q_norm.weight": "model-00002-of-00003.safetensors",
|
| 335 |
+
"model.layers.35.self_attn.q_proj.weight": "model-00002-of-00003.safetensors",
|
| 336 |
+
"model.layers.35.self_attn.v_proj.weight": "model-00002-of-00003.safetensors",
|
| 337 |
+
"model.layers.4.input_layernorm.weight": "model-00001-of-00003.safetensors",
|
| 338 |
+
"model.layers.4.mlp.down_proj.weight": "model-00001-of-00003.safetensors",
|
| 339 |
+
"model.layers.4.mlp.gate_proj.weight": "model-00001-of-00003.safetensors",
|
| 340 |
+
"model.layers.4.mlp.up_proj.weight": "model-00001-of-00003.safetensors",
|
| 341 |
+
"model.layers.4.post_attention_layernorm.weight": "model-00001-of-00003.safetensors",
|
| 342 |
+
"model.layers.4.self_attn.k_norm.weight": "model-00001-of-00003.safetensors",
|
| 343 |
+
"model.layers.4.self_attn.k_proj.weight": "model-00001-of-00003.safetensors",
|
| 344 |
+
"model.layers.4.self_attn.o_proj.weight": "model-00001-of-00003.safetensors",
|
| 345 |
+
"model.layers.4.self_attn.q_norm.weight": "model-00001-of-00003.safetensors",
|
| 346 |
+
"model.layers.4.self_attn.q_proj.weight": "model-00001-of-00003.safetensors",
|
| 347 |
+
"model.layers.4.self_attn.v_proj.weight": "model-00001-of-00003.safetensors",
|
| 348 |
+
"model.layers.5.input_layernorm.weight": "model-00001-of-00003.safetensors",
|
| 349 |
+
"model.layers.5.mlp.down_proj.weight": "model-00001-of-00003.safetensors",
|
| 350 |
+
"model.layers.5.mlp.gate_proj.weight": "model-00001-of-00003.safetensors",
|
| 351 |
+
"model.layers.5.mlp.up_proj.weight": "model-00001-of-00003.safetensors",
|
| 352 |
+
"model.layers.5.post_attention_layernorm.weight": "model-00001-of-00003.safetensors",
|
| 353 |
+
"model.layers.5.self_attn.k_norm.weight": "model-00001-of-00003.safetensors",
|
| 354 |
+
"model.layers.5.self_attn.k_proj.weight": "model-00001-of-00003.safetensors",
|
| 355 |
+
"model.layers.5.self_attn.o_proj.weight": "model-00001-of-00003.safetensors",
|
| 356 |
+
"model.layers.5.self_attn.q_norm.weight": "model-00001-of-00003.safetensors",
|
| 357 |
+
"model.layers.5.self_attn.q_proj.weight": "model-00001-of-00003.safetensors",
|
| 358 |
+
"model.layers.5.self_attn.v_proj.weight": "model-00001-of-00003.safetensors",
|
| 359 |
+
"model.layers.6.input_layernorm.weight": "model-00001-of-00003.safetensors",
|
| 360 |
+
"model.layers.6.mlp.down_proj.weight": "model-00001-of-00003.safetensors",
|
| 361 |
+
"model.layers.6.mlp.gate_proj.weight": "model-00001-of-00003.safetensors",
|
| 362 |
+
"model.layers.6.mlp.up_proj.weight": "model-00001-of-00003.safetensors",
|
| 363 |
+
"model.layers.6.post_attention_layernorm.weight": "model-00001-of-00003.safetensors",
|
| 364 |
+
"model.layers.6.self_attn.k_norm.weight": "model-00001-of-00003.safetensors",
|
| 365 |
+
"model.layers.6.self_attn.k_proj.weight": "model-00001-of-00003.safetensors",
|
| 366 |
+
"model.layers.6.self_attn.o_proj.weight": "model-00001-of-00003.safetensors",
|
| 367 |
+
"model.layers.6.self_attn.q_norm.weight": "model-00001-of-00003.safetensors",
|
| 368 |
+
"model.layers.6.self_attn.q_proj.weight": "model-00001-of-00003.safetensors",
|
| 369 |
+
"model.layers.6.self_attn.v_proj.weight": "model-00001-of-00003.safetensors",
|
| 370 |
+
"model.layers.7.input_layernorm.weight": "model-00001-of-00003.safetensors",
|
| 371 |
+
"model.layers.7.mlp.down_proj.weight": "model-00001-of-00003.safetensors",
|
| 372 |
+
"model.layers.7.mlp.gate_proj.weight": "model-00001-of-00003.safetensors",
|
| 373 |
+
"model.layers.7.mlp.up_proj.weight": "model-00001-of-00003.safetensors",
|
| 374 |
+
"model.layers.7.post_attention_layernorm.weight": "model-00001-of-00003.safetensors",
|
| 375 |
+
"model.layers.7.self_attn.k_norm.weight": "model-00001-of-00003.safetensors",
|
| 376 |
+
"model.layers.7.self_attn.k_proj.weight": "model-00001-of-00003.safetensors",
|
| 377 |
+
"model.layers.7.self_attn.o_proj.weight": "model-00001-of-00003.safetensors",
|
| 378 |
+
"model.layers.7.self_attn.q_norm.weight": "model-00001-of-00003.safetensors",
|
| 379 |
+
"model.layers.7.self_attn.q_proj.weight": "model-00001-of-00003.safetensors",
|
| 380 |
+
"model.layers.7.self_attn.v_proj.weight": "model-00001-of-00003.safetensors",
|
| 381 |
+
"model.layers.8.input_layernorm.weight": "model-00001-of-00003.safetensors",
|
| 382 |
+
"model.layers.8.mlp.down_proj.weight": "model-00001-of-00003.safetensors",
|
| 383 |
+
"model.layers.8.mlp.gate_proj.weight": "model-00001-of-00003.safetensors",
|
| 384 |
+
"model.layers.8.mlp.up_proj.weight": "model-00001-of-00003.safetensors",
|
| 385 |
+
"model.layers.8.post_attention_layernorm.weight": "model-00001-of-00003.safetensors",
|
| 386 |
+
"model.layers.8.self_attn.k_norm.weight": "model-00001-of-00003.safetensors",
|
| 387 |
+
"model.layers.8.self_attn.k_proj.weight": "model-00001-of-00003.safetensors",
|
| 388 |
+
"model.layers.8.self_attn.o_proj.weight": "model-00001-of-00003.safetensors",
|
| 389 |
+
"model.layers.8.self_attn.q_norm.weight": "model-00001-of-00003.safetensors",
|
| 390 |
+
"model.layers.8.self_attn.q_proj.weight": "model-00001-of-00003.safetensors",
|
| 391 |
+
"model.layers.8.self_attn.v_proj.weight": "model-00001-of-00003.safetensors",
|
| 392 |
+
"model.layers.9.input_layernorm.weight": "model-00001-of-00003.safetensors",
|
| 393 |
+
"model.layers.9.mlp.down_proj.weight": "model-00001-of-00003.safetensors",
|
| 394 |
+
"model.layers.9.mlp.gate_proj.weight": "model-00001-of-00003.safetensors",
|
| 395 |
+
"model.layers.9.mlp.up_proj.weight": "model-00001-of-00003.safetensors",
|
| 396 |
+
"model.layers.9.post_attention_layernorm.weight": "model-00001-of-00003.safetensors",
|
| 397 |
+
"model.layers.9.self_attn.k_norm.weight": "model-00001-of-00003.safetensors",
|
| 398 |
+
"model.layers.9.self_attn.k_proj.weight": "model-00001-of-00003.safetensors",
|
| 399 |
+
"model.layers.9.self_attn.o_proj.weight": "model-00001-of-00003.safetensors",
|
| 400 |
+
"model.layers.9.self_attn.q_norm.weight": "model-00001-of-00003.safetensors",
|
| 401 |
+
"model.layers.9.self_attn.q_proj.weight": "model-00001-of-00003.safetensors",
|
| 402 |
+
"model.layers.9.self_attn.v_proj.weight": "model-00001-of-00003.safetensors",
|
| 403 |
+
"model.norm.weight": "model-00003-of-00003.safetensors"
|
| 404 |
+
}
|
| 405 |
+
}
|
tokenizer/chat_template.jinja
ADDED
|
@@ -0,0 +1,89 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
{%- if tools %}
|
| 2 |
+
{{- '<|im_start|>system\n' }}
|
| 3 |
+
{%- if messages[0].role == 'system' %}
|
| 4 |
+
{{- messages[0].content + '\n\n' }}
|
| 5 |
+
{%- endif %}
|
| 6 |
+
{{- "# Tools\n\nYou may call one or more functions to assist with the user query.\n\nYou are provided with function signatures within <tools></tools> XML tags:\n<tools>" }}
|
| 7 |
+
{%- for tool in tools %}
|
| 8 |
+
{{- "\n" }}
|
| 9 |
+
{{- tool | tojson }}
|
| 10 |
+
{%- endfor %}
|
| 11 |
+
{{- "\n</tools>\n\nFor each function call, return a json object with function name and arguments within <tool_call></tool_call> XML tags:\n<tool_call>\n{\"name\": <function-name>, \"arguments\": <args-json-object>}\n</tool_call><|im_end|>\n" }}
|
| 12 |
+
{%- else %}
|
| 13 |
+
{%- if messages[0].role == 'system' %}
|
| 14 |
+
{{- '<|im_start|>system\n' + messages[0].content + '<|im_end|>\n' }}
|
| 15 |
+
{%- endif %}
|
| 16 |
+
{%- endif %}
|
| 17 |
+
{%- set ns = namespace(multi_step_tool=true, last_query_index=messages|length - 1) %}
|
| 18 |
+
{%- for message in messages[::-1] %}
|
| 19 |
+
{%- set index = (messages|length - 1) - loop.index0 %}
|
| 20 |
+
{%- if ns.multi_step_tool and message.role == "user" and message.content is string and not(message.content.startswith('<tool_response>') and message.content.endswith('</tool_response>')) %}
|
| 21 |
+
{%- set ns.multi_step_tool = false %}
|
| 22 |
+
{%- set ns.last_query_index = index %}
|
| 23 |
+
{%- endif %}
|
| 24 |
+
{%- endfor %}
|
| 25 |
+
{%- for message in messages %}
|
| 26 |
+
{%- if message.content is string %}
|
| 27 |
+
{%- set content = message.content %}
|
| 28 |
+
{%- else %}
|
| 29 |
+
{%- set content = '' %}
|
| 30 |
+
{%- endif %}
|
| 31 |
+
{%- if (message.role == "user") or (message.role == "system" and not loop.first) %}
|
| 32 |
+
{{- '<|im_start|>' + message.role + '\n' + content + '<|im_end|>' + '\n' }}
|
| 33 |
+
{%- elif message.role == "assistant" %}
|
| 34 |
+
{%- set reasoning_content = '' %}
|
| 35 |
+
{%- if message.reasoning_content is string %}
|
| 36 |
+
{%- set reasoning_content = message.reasoning_content %}
|
| 37 |
+
{%- else %}
|
| 38 |
+
{%- if '</think>' in content %}
|
| 39 |
+
{%- set reasoning_content = content.split('</think>')[0].rstrip('\n').split('<think>')[-1].lstrip('\n') %}
|
| 40 |
+
{%- set content = content.split('</think>')[-1].lstrip('\n') %}
|
| 41 |
+
{%- endif %}
|
| 42 |
+
{%- endif %}
|
| 43 |
+
{%- if loop.index0 > ns.last_query_index %}
|
| 44 |
+
{%- if loop.last or (not loop.last and reasoning_content) %}
|
| 45 |
+
{{- '<|im_start|>' + message.role + '\n<think>\n' + reasoning_content.strip('\n') + '\n</think>\n\n' + content.lstrip('\n') }}
|
| 46 |
+
{%- else %}
|
| 47 |
+
{{- '<|im_start|>' + message.role + '\n' + content }}
|
| 48 |
+
{%- endif %}
|
| 49 |
+
{%- else %}
|
| 50 |
+
{{- '<|im_start|>' + message.role + '\n' + content }}
|
| 51 |
+
{%- endif %}
|
| 52 |
+
{%- if message.tool_calls %}
|
| 53 |
+
{%- for tool_call in message.tool_calls %}
|
| 54 |
+
{%- if (loop.first and content) or (not loop.first) %}
|
| 55 |
+
{{- '\n' }}
|
| 56 |
+
{%- endif %}
|
| 57 |
+
{%- if tool_call.function %}
|
| 58 |
+
{%- set tool_call = tool_call.function %}
|
| 59 |
+
{%- endif %}
|
| 60 |
+
{{- '<tool_call>\n{"name": "' }}
|
| 61 |
+
{{- tool_call.name }}
|
| 62 |
+
{{- '", "arguments": ' }}
|
| 63 |
+
{%- if tool_call.arguments is string %}
|
| 64 |
+
{{- tool_call.arguments }}
|
| 65 |
+
{%- else %}
|
| 66 |
+
{{- tool_call.arguments | tojson }}
|
| 67 |
+
{%- endif %}
|
| 68 |
+
{{- '}\n</tool_call>' }}
|
| 69 |
+
{%- endfor %}
|
| 70 |
+
{%- endif %}
|
| 71 |
+
{{- '<|im_end|>\n' }}
|
| 72 |
+
{%- elif message.role == "tool" %}
|
| 73 |
+
{%- if loop.first or (messages[loop.index0 - 1].role != "tool") %}
|
| 74 |
+
{{- '<|im_start|>user' }}
|
| 75 |
+
{%- endif %}
|
| 76 |
+
{{- '\n<tool_response>\n' }}
|
| 77 |
+
{{- content }}
|
| 78 |
+
{{- '\n</tool_response>' }}
|
| 79 |
+
{%- if loop.last or (messages[loop.index0 + 1].role != "tool") %}
|
| 80 |
+
{{- '<|im_end|>\n' }}
|
| 81 |
+
{%- endif %}
|
| 82 |
+
{%- endif %}
|
| 83 |
+
{%- endfor %}
|
| 84 |
+
{%- if add_generation_prompt %}
|
| 85 |
+
{{- '<|im_start|>assistant\n' }}
|
| 86 |
+
{%- if enable_thinking is defined and enable_thinking is false %}
|
| 87 |
+
{{- '<think>\n\n</think>\n\n' }}
|
| 88 |
+
{%- endif %}
|
| 89 |
+
{%- endif %}
|
tokenizer/tokenizer.json
ADDED
|
@@ -0,0 +1,3 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
version https://git-lfs.github.com/spec/v1
|
| 2 |
+
oid sha256:be75606093db2094d7cd20f3c2f385c212750648bd6ea4fb2bf507a6a4c55506
|
| 3 |
+
size 11422650
|
tokenizer/tokenizer_config.json
ADDED
|
@@ -0,0 +1,29 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
{
|
| 2 |
+
"add_prefix_space": false,
|
| 3 |
+
"backend": "tokenizers",
|
| 4 |
+
"bos_token": null,
|
| 5 |
+
"clean_up_tokenization_spaces": false,
|
| 6 |
+
"eos_token": "<|im_end|>",
|
| 7 |
+
"errors": "replace",
|
| 8 |
+
"extra_special_tokens": [
|
| 9 |
+
"<|im_start|>",
|
| 10 |
+
"<|im_end|>",
|
| 11 |
+
"<|object_ref_start|>",
|
| 12 |
+
"<|object_ref_end|>",
|
| 13 |
+
"<|box_start|>",
|
| 14 |
+
"<|box_end|>",
|
| 15 |
+
"<|quad_start|>",
|
| 16 |
+
"<|quad_end|>",
|
| 17 |
+
"<|vision_start|>",
|
| 18 |
+
"<|vision_end|>",
|
| 19 |
+
"<|vision_pad|>",
|
| 20 |
+
"<|image_pad|>",
|
| 21 |
+
"<|video_pad|>"
|
| 22 |
+
],
|
| 23 |
+
"is_local": true,
|
| 24 |
+
"model_max_length": 131072,
|
| 25 |
+
"pad_token": "<|endoftext|>",
|
| 26 |
+
"split_special_tokens": false,
|
| 27 |
+
"tokenizer_class": "Qwen2Tokenizer",
|
| 28 |
+
"unk_token": null
|
| 29 |
+
}
|
transformer/config.json
ADDED
|
@@ -0,0 +1,33 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
{
|
| 2 |
+
"_class_name": "ZImageTransformer2DModel",
|
| 3 |
+
"_diffusers_version": "0.37.1",
|
| 4 |
+
"_name_or_path": "/root/.cache/huggingface/hub/models--Tongyi-MAI--Z-Image/snapshots/04cc4abb7c5069926f75c9bfde9ef43d49423021/transformer",
|
| 5 |
+
"all_f_patch_size": [
|
| 6 |
+
1
|
| 7 |
+
],
|
| 8 |
+
"all_patch_size": [
|
| 9 |
+
2
|
| 10 |
+
],
|
| 11 |
+
"axes_dims": [
|
| 12 |
+
32,
|
| 13 |
+
48,
|
| 14 |
+
48
|
| 15 |
+
],
|
| 16 |
+
"axes_lens": [
|
| 17 |
+
1536,
|
| 18 |
+
512,
|
| 19 |
+
512
|
| 20 |
+
],
|
| 21 |
+
"cap_feat_dim": 2560,
|
| 22 |
+
"dim": 3840,
|
| 23 |
+
"in_channels": 16,
|
| 24 |
+
"n_heads": 30,
|
| 25 |
+
"n_kv_heads": 30,
|
| 26 |
+
"n_layers": 30,
|
| 27 |
+
"n_refiner_layers": 2,
|
| 28 |
+
"norm_eps": 1e-05,
|
| 29 |
+
"qk_norm": true,
|
| 30 |
+
"rope_theta": 256.0,
|
| 31 |
+
"siglip_feat_dim": null,
|
| 32 |
+
"t_scale": 1000.0
|
| 33 |
+
}
|
transformer/diffusion_pytorch_model-00001-of-00002.safetensors
ADDED
|
@@ -0,0 +1,3 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
version https://git-lfs.github.com/spec/v1
|
| 2 |
+
oid sha256:cf55f833c40c83288be91cb2842feeae59e1fa081bab34edfeb584e6e23c97b6
|
| 3 |
+
size 9973726720
|
transformer/diffusion_pytorch_model-00002-of-00002.safetensors
ADDED
|
@@ -0,0 +1,3 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
version https://git-lfs.github.com/spec/v1
|
| 2 |
+
oid sha256:9e826da94fbbb9d2658d73da86266891e63930e83f5915fbb4b5383a5b43c725
|
| 3 |
+
size 2336146632
|
transformer/diffusion_pytorch_model.safetensors.index.json
ADDED
|
@@ -0,0 +1,528 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
{
|
| 2 |
+
"metadata": {
|
| 3 |
+
"total_size": 12309817472
|
| 4 |
+
},
|
| 5 |
+
"weight_map": {
|
| 6 |
+
"all_final_layer.2-1.adaLN_modulation.1.bias": "diffusion_pytorch_model-00001-of-00002.safetensors",
|
| 7 |
+
"all_final_layer.2-1.adaLN_modulation.1.weight": "diffusion_pytorch_model-00001-of-00002.safetensors",
|
| 8 |
+
"all_final_layer.2-1.linear.bias": "diffusion_pytorch_model-00001-of-00002.safetensors",
|
| 9 |
+
"all_final_layer.2-1.linear.weight": "diffusion_pytorch_model-00001-of-00002.safetensors",
|
| 10 |
+
"all_x_embedder.2-1.bias": "diffusion_pytorch_model-00001-of-00002.safetensors",
|
| 11 |
+
"all_x_embedder.2-1.weight": "diffusion_pytorch_model-00001-of-00002.safetensors",
|
| 12 |
+
"cap_embedder.0.weight": "diffusion_pytorch_model-00001-of-00002.safetensors",
|
| 13 |
+
"cap_embedder.1.bias": "diffusion_pytorch_model-00001-of-00002.safetensors",
|
| 14 |
+
"cap_embedder.1.weight": "diffusion_pytorch_model-00001-of-00002.safetensors",
|
| 15 |
+
"cap_pad_token": "diffusion_pytorch_model-00001-of-00002.safetensors",
|
| 16 |
+
"context_refiner.0.attention.norm_k.weight": "diffusion_pytorch_model-00001-of-00002.safetensors",
|
| 17 |
+
"context_refiner.0.attention.norm_q.weight": "diffusion_pytorch_model-00001-of-00002.safetensors",
|
| 18 |
+
"context_refiner.0.attention.to_k.weight": "diffusion_pytorch_model-00001-of-00002.safetensors",
|
| 19 |
+
"context_refiner.0.attention.to_out.0.weight": "diffusion_pytorch_model-00001-of-00002.safetensors",
|
| 20 |
+
"context_refiner.0.attention.to_q.weight": "diffusion_pytorch_model-00001-of-00002.safetensors",
|
| 21 |
+
"context_refiner.0.attention.to_v.weight": "diffusion_pytorch_model-00001-of-00002.safetensors",
|
| 22 |
+
"context_refiner.0.attention_norm1.weight": "diffusion_pytorch_model-00001-of-00002.safetensors",
|
| 23 |
+
"context_refiner.0.attention_norm2.weight": "diffusion_pytorch_model-00001-of-00002.safetensors",
|
| 24 |
+
"context_refiner.0.feed_forward.w1.weight": "diffusion_pytorch_model-00001-of-00002.safetensors",
|
| 25 |
+
"context_refiner.0.feed_forward.w2.weight": "diffusion_pytorch_model-00001-of-00002.safetensors",
|
| 26 |
+
"context_refiner.0.feed_forward.w3.weight": "diffusion_pytorch_model-00001-of-00002.safetensors",
|
| 27 |
+
"context_refiner.0.ffn_norm1.weight": "diffusion_pytorch_model-00001-of-00002.safetensors",
|
| 28 |
+
"context_refiner.0.ffn_norm2.weight": "diffusion_pytorch_model-00001-of-00002.safetensors",
|
| 29 |
+
"context_refiner.1.attention.norm_k.weight": "diffusion_pytorch_model-00001-of-00002.safetensors",
|
| 30 |
+
"context_refiner.1.attention.norm_q.weight": "diffusion_pytorch_model-00001-of-00002.safetensors",
|
| 31 |
+
"context_refiner.1.attention.to_k.weight": "diffusion_pytorch_model-00001-of-00002.safetensors",
|
| 32 |
+
"context_refiner.1.attention.to_out.0.weight": "diffusion_pytorch_model-00001-of-00002.safetensors",
|
| 33 |
+
"context_refiner.1.attention.to_q.weight": "diffusion_pytorch_model-00001-of-00002.safetensors",
|
| 34 |
+
"context_refiner.1.attention.to_v.weight": "diffusion_pytorch_model-00001-of-00002.safetensors",
|
| 35 |
+
"context_refiner.1.attention_norm1.weight": "diffusion_pytorch_model-00001-of-00002.safetensors",
|
| 36 |
+
"context_refiner.1.attention_norm2.weight": "diffusion_pytorch_model-00001-of-00002.safetensors",
|
| 37 |
+
"context_refiner.1.feed_forward.w1.weight": "diffusion_pytorch_model-00001-of-00002.safetensors",
|
| 38 |
+
"context_refiner.1.feed_forward.w2.weight": "diffusion_pytorch_model-00001-of-00002.safetensors",
|
| 39 |
+
"context_refiner.1.feed_forward.w3.weight": "diffusion_pytorch_model-00001-of-00002.safetensors",
|
| 40 |
+
"context_refiner.1.ffn_norm1.weight": "diffusion_pytorch_model-00001-of-00002.safetensors",
|
| 41 |
+
"context_refiner.1.ffn_norm2.weight": "diffusion_pytorch_model-00001-of-00002.safetensors",
|
| 42 |
+
"layers.0.adaLN_modulation.0.bias": "diffusion_pytorch_model-00001-of-00002.safetensors",
|
| 43 |
+
"layers.0.adaLN_modulation.0.weight": "diffusion_pytorch_model-00001-of-00002.safetensors",
|
| 44 |
+
"layers.0.attention.norm_k.weight": "diffusion_pytorch_model-00001-of-00002.safetensors",
|
| 45 |
+
"layers.0.attention.norm_q.weight": "diffusion_pytorch_model-00001-of-00002.safetensors",
|
| 46 |
+
"layers.0.attention.to_k.weight": "diffusion_pytorch_model-00001-of-00002.safetensors",
|
| 47 |
+
"layers.0.attention.to_out.0.weight": "diffusion_pytorch_model-00001-of-00002.safetensors",
|
| 48 |
+
"layers.0.attention.to_q.weight": "diffusion_pytorch_model-00001-of-00002.safetensors",
|
| 49 |
+
"layers.0.attention.to_v.weight": "diffusion_pytorch_model-00001-of-00002.safetensors",
|
| 50 |
+
"layers.0.attention_norm1.weight": "diffusion_pytorch_model-00001-of-00002.safetensors",
|
| 51 |
+
"layers.0.attention_norm2.weight": "diffusion_pytorch_model-00001-of-00002.safetensors",
|
| 52 |
+
"layers.0.feed_forward.w1.weight": "diffusion_pytorch_model-00001-of-00002.safetensors",
|
| 53 |
+
"layers.0.feed_forward.w2.weight": "diffusion_pytorch_model-00001-of-00002.safetensors",
|
| 54 |
+
"layers.0.feed_forward.w3.weight": "diffusion_pytorch_model-00001-of-00002.safetensors",
|
| 55 |
+
"layers.0.ffn_norm1.weight": "diffusion_pytorch_model-00001-of-00002.safetensors",
|
| 56 |
+
"layers.0.ffn_norm2.weight": "diffusion_pytorch_model-00001-of-00002.safetensors",
|
| 57 |
+
"layers.1.adaLN_modulation.0.bias": "diffusion_pytorch_model-00001-of-00002.safetensors",
|
| 58 |
+
"layers.1.adaLN_modulation.0.weight": "diffusion_pytorch_model-00001-of-00002.safetensors",
|
| 59 |
+
"layers.1.attention.norm_k.weight": "diffusion_pytorch_model-00001-of-00002.safetensors",
|
| 60 |
+
"layers.1.attention.norm_q.weight": "diffusion_pytorch_model-00001-of-00002.safetensors",
|
| 61 |
+
"layers.1.attention.to_k.weight": "diffusion_pytorch_model-00001-of-00002.safetensors",
|
| 62 |
+
"layers.1.attention.to_out.0.weight": "diffusion_pytorch_model-00001-of-00002.safetensors",
|
| 63 |
+
"layers.1.attention.to_q.weight": "diffusion_pytorch_model-00001-of-00002.safetensors",
|
| 64 |
+
"layers.1.attention.to_v.weight": "diffusion_pytorch_model-00001-of-00002.safetensors",
|
| 65 |
+
"layers.1.attention_norm1.weight": "diffusion_pytorch_model-00001-of-00002.safetensors",
|
| 66 |
+
"layers.1.attention_norm2.weight": "diffusion_pytorch_model-00001-of-00002.safetensors",
|
| 67 |
+
"layers.1.feed_forward.w1.weight": "diffusion_pytorch_model-00001-of-00002.safetensors",
|
| 68 |
+
"layers.1.feed_forward.w2.weight": "diffusion_pytorch_model-00001-of-00002.safetensors",
|
| 69 |
+
"layers.1.feed_forward.w3.weight": "diffusion_pytorch_model-00001-of-00002.safetensors",
|
| 70 |
+
"layers.1.ffn_norm1.weight": "diffusion_pytorch_model-00001-of-00002.safetensors",
|
| 71 |
+
"layers.1.ffn_norm2.weight": "diffusion_pytorch_model-00001-of-00002.safetensors",
|
| 72 |
+
"layers.10.adaLN_modulation.0.bias": "diffusion_pytorch_model-00001-of-00002.safetensors",
|
| 73 |
+
"layers.10.adaLN_modulation.0.weight": "diffusion_pytorch_model-00001-of-00002.safetensors",
|
| 74 |
+
"layers.10.attention.norm_k.weight": "diffusion_pytorch_model-00001-of-00002.safetensors",
|
| 75 |
+
"layers.10.attention.norm_q.weight": "diffusion_pytorch_model-00001-of-00002.safetensors",
|
| 76 |
+
"layers.10.attention.to_k.weight": "diffusion_pytorch_model-00001-of-00002.safetensors",
|
| 77 |
+
"layers.10.attention.to_out.0.weight": "diffusion_pytorch_model-00001-of-00002.safetensors",
|
| 78 |
+
"layers.10.attention.to_q.weight": "diffusion_pytorch_model-00001-of-00002.safetensors",
|
| 79 |
+
"layers.10.attention.to_v.weight": "diffusion_pytorch_model-00001-of-00002.safetensors",
|
| 80 |
+
"layers.10.attention_norm1.weight": "diffusion_pytorch_model-00001-of-00002.safetensors",
|
| 81 |
+
"layers.10.attention_norm2.weight": "diffusion_pytorch_model-00001-of-00002.safetensors",
|
| 82 |
+
"layers.10.feed_forward.w1.weight": "diffusion_pytorch_model-00001-of-00002.safetensors",
|
| 83 |
+
"layers.10.feed_forward.w2.weight": "diffusion_pytorch_model-00001-of-00002.safetensors",
|
| 84 |
+
"layers.10.feed_forward.w3.weight": "diffusion_pytorch_model-00001-of-00002.safetensors",
|
| 85 |
+
"layers.10.ffn_norm1.weight": "diffusion_pytorch_model-00001-of-00002.safetensors",
|
| 86 |
+
"layers.10.ffn_norm2.weight": "diffusion_pytorch_model-00001-of-00002.safetensors",
|
| 87 |
+
"layers.11.adaLN_modulation.0.bias": "diffusion_pytorch_model-00001-of-00002.safetensors",
|
| 88 |
+
"layers.11.adaLN_modulation.0.weight": "diffusion_pytorch_model-00001-of-00002.safetensors",
|
| 89 |
+
"layers.11.attention.norm_k.weight": "diffusion_pytorch_model-00001-of-00002.safetensors",
|
| 90 |
+
"layers.11.attention.norm_q.weight": "diffusion_pytorch_model-00001-of-00002.safetensors",
|
| 91 |
+
"layers.11.attention.to_k.weight": "diffusion_pytorch_model-00001-of-00002.safetensors",
|
| 92 |
+
"layers.11.attention.to_out.0.weight": "diffusion_pytorch_model-00001-of-00002.safetensors",
|
| 93 |
+
"layers.11.attention.to_q.weight": "diffusion_pytorch_model-00001-of-00002.safetensors",
|
| 94 |
+
"layers.11.attention.to_v.weight": "diffusion_pytorch_model-00001-of-00002.safetensors",
|
| 95 |
+
"layers.11.attention_norm1.weight": "diffusion_pytorch_model-00001-of-00002.safetensors",
|
| 96 |
+
"layers.11.attention_norm2.weight": "diffusion_pytorch_model-00001-of-00002.safetensors",
|
| 97 |
+
"layers.11.feed_forward.w1.weight": "diffusion_pytorch_model-00001-of-00002.safetensors",
|
| 98 |
+
"layers.11.feed_forward.w2.weight": "diffusion_pytorch_model-00001-of-00002.safetensors",
|
| 99 |
+
"layers.11.feed_forward.w3.weight": "diffusion_pytorch_model-00001-of-00002.safetensors",
|
| 100 |
+
"layers.11.ffn_norm1.weight": "diffusion_pytorch_model-00001-of-00002.safetensors",
|
| 101 |
+
"layers.11.ffn_norm2.weight": "diffusion_pytorch_model-00001-of-00002.safetensors",
|
| 102 |
+
"layers.12.adaLN_modulation.0.bias": "diffusion_pytorch_model-00001-of-00002.safetensors",
|
| 103 |
+
"layers.12.adaLN_modulation.0.weight": "diffusion_pytorch_model-00001-of-00002.safetensors",
|
| 104 |
+
"layers.12.attention.norm_k.weight": "diffusion_pytorch_model-00001-of-00002.safetensors",
|
| 105 |
+
"layers.12.attention.norm_q.weight": "diffusion_pytorch_model-00001-of-00002.safetensors",
|
| 106 |
+
"layers.12.attention.to_k.weight": "diffusion_pytorch_model-00001-of-00002.safetensors",
|
| 107 |
+
"layers.12.attention.to_out.0.weight": "diffusion_pytorch_model-00001-of-00002.safetensors",
|
| 108 |
+
"layers.12.attention.to_q.weight": "diffusion_pytorch_model-00001-of-00002.safetensors",
|
| 109 |
+
"layers.12.attention.to_v.weight": "diffusion_pytorch_model-00001-of-00002.safetensors",
|
| 110 |
+
"layers.12.attention_norm1.weight": "diffusion_pytorch_model-00001-of-00002.safetensors",
|
| 111 |
+
"layers.12.attention_norm2.weight": "diffusion_pytorch_model-00001-of-00002.safetensors",
|
| 112 |
+
"layers.12.feed_forward.w1.weight": "diffusion_pytorch_model-00001-of-00002.safetensors",
|
| 113 |
+
"layers.12.feed_forward.w2.weight": "diffusion_pytorch_model-00001-of-00002.safetensors",
|
| 114 |
+
"layers.12.feed_forward.w3.weight": "diffusion_pytorch_model-00001-of-00002.safetensors",
|
| 115 |
+
"layers.12.ffn_norm1.weight": "diffusion_pytorch_model-00001-of-00002.safetensors",
|
| 116 |
+
"layers.12.ffn_norm2.weight": "diffusion_pytorch_model-00001-of-00002.safetensors",
|
| 117 |
+
"layers.13.adaLN_modulation.0.bias": "diffusion_pytorch_model-00001-of-00002.safetensors",
|
| 118 |
+
"layers.13.adaLN_modulation.0.weight": "diffusion_pytorch_model-00001-of-00002.safetensors",
|
| 119 |
+
"layers.13.attention.norm_k.weight": "diffusion_pytorch_model-00001-of-00002.safetensors",
|
| 120 |
+
"layers.13.attention.norm_q.weight": "diffusion_pytorch_model-00001-of-00002.safetensors",
|
| 121 |
+
"layers.13.attention.to_k.weight": "diffusion_pytorch_model-00001-of-00002.safetensors",
|
| 122 |
+
"layers.13.attention.to_out.0.weight": "diffusion_pytorch_model-00001-of-00002.safetensors",
|
| 123 |
+
"layers.13.attention.to_q.weight": "diffusion_pytorch_model-00001-of-00002.safetensors",
|
| 124 |
+
"layers.13.attention.to_v.weight": "diffusion_pytorch_model-00001-of-00002.safetensors",
|
| 125 |
+
"layers.13.attention_norm1.weight": "diffusion_pytorch_model-00001-of-00002.safetensors",
|
| 126 |
+
"layers.13.attention_norm2.weight": "diffusion_pytorch_model-00001-of-00002.safetensors",
|
| 127 |
+
"layers.13.feed_forward.w1.weight": "diffusion_pytorch_model-00001-of-00002.safetensors",
|
| 128 |
+
"layers.13.feed_forward.w2.weight": "diffusion_pytorch_model-00001-of-00002.safetensors",
|
| 129 |
+
"layers.13.feed_forward.w3.weight": "diffusion_pytorch_model-00001-of-00002.safetensors",
|
| 130 |
+
"layers.13.ffn_norm1.weight": "diffusion_pytorch_model-00001-of-00002.safetensors",
|
| 131 |
+
"layers.13.ffn_norm2.weight": "diffusion_pytorch_model-00001-of-00002.safetensors",
|
| 132 |
+
"layers.14.adaLN_modulation.0.bias": "diffusion_pytorch_model-00001-of-00002.safetensors",
|
| 133 |
+
"layers.14.adaLN_modulation.0.weight": "diffusion_pytorch_model-00001-of-00002.safetensors",
|
| 134 |
+
"layers.14.attention.norm_k.weight": "diffusion_pytorch_model-00001-of-00002.safetensors",
|
| 135 |
+
"layers.14.attention.norm_q.weight": "diffusion_pytorch_model-00001-of-00002.safetensors",
|
| 136 |
+
"layers.14.attention.to_k.weight": "diffusion_pytorch_model-00001-of-00002.safetensors",
|
| 137 |
+
"layers.14.attention.to_out.0.weight": "diffusion_pytorch_model-00001-of-00002.safetensors",
|
| 138 |
+
"layers.14.attention.to_q.weight": "diffusion_pytorch_model-00001-of-00002.safetensors",
|
| 139 |
+
"layers.14.attention.to_v.weight": "diffusion_pytorch_model-00001-of-00002.safetensors",
|
| 140 |
+
"layers.14.attention_norm1.weight": "diffusion_pytorch_model-00001-of-00002.safetensors",
|
| 141 |
+
"layers.14.attention_norm2.weight": "diffusion_pytorch_model-00001-of-00002.safetensors",
|
| 142 |
+
"layers.14.feed_forward.w1.weight": "diffusion_pytorch_model-00001-of-00002.safetensors",
|
| 143 |
+
"layers.14.feed_forward.w2.weight": "diffusion_pytorch_model-00001-of-00002.safetensors",
|
| 144 |
+
"layers.14.feed_forward.w3.weight": "diffusion_pytorch_model-00001-of-00002.safetensors",
|
| 145 |
+
"layers.14.ffn_norm1.weight": "diffusion_pytorch_model-00001-of-00002.safetensors",
|
| 146 |
+
"layers.14.ffn_norm2.weight": "diffusion_pytorch_model-00001-of-00002.safetensors",
|
| 147 |
+
"layers.15.adaLN_modulation.0.bias": "diffusion_pytorch_model-00001-of-00002.safetensors",
|
| 148 |
+
"layers.15.adaLN_modulation.0.weight": "diffusion_pytorch_model-00001-of-00002.safetensors",
|
| 149 |
+
"layers.15.attention.norm_k.weight": "diffusion_pytorch_model-00001-of-00002.safetensors",
|
| 150 |
+
"layers.15.attention.norm_q.weight": "diffusion_pytorch_model-00001-of-00002.safetensors",
|
| 151 |
+
"layers.15.attention.to_k.weight": "diffusion_pytorch_model-00001-of-00002.safetensors",
|
| 152 |
+
"layers.15.attention.to_out.0.weight": "diffusion_pytorch_model-00001-of-00002.safetensors",
|
| 153 |
+
"layers.15.attention.to_q.weight": "diffusion_pytorch_model-00001-of-00002.safetensors",
|
| 154 |
+
"layers.15.attention.to_v.weight": "diffusion_pytorch_model-00001-of-00002.safetensors",
|
| 155 |
+
"layers.15.attention_norm1.weight": "diffusion_pytorch_model-00001-of-00002.safetensors",
|
| 156 |
+
"layers.15.attention_norm2.weight": "diffusion_pytorch_model-00001-of-00002.safetensors",
|
| 157 |
+
"layers.15.feed_forward.w1.weight": "diffusion_pytorch_model-00001-of-00002.safetensors",
|
| 158 |
+
"layers.15.feed_forward.w2.weight": "diffusion_pytorch_model-00001-of-00002.safetensors",
|
| 159 |
+
"layers.15.feed_forward.w3.weight": "diffusion_pytorch_model-00001-of-00002.safetensors",
|
| 160 |
+
"layers.15.ffn_norm1.weight": "diffusion_pytorch_model-00001-of-00002.safetensors",
|
| 161 |
+
"layers.15.ffn_norm2.weight": "diffusion_pytorch_model-00001-of-00002.safetensors",
|
| 162 |
+
"layers.16.adaLN_modulation.0.bias": "diffusion_pytorch_model-00001-of-00002.safetensors",
|
| 163 |
+
"layers.16.adaLN_modulation.0.weight": "diffusion_pytorch_model-00001-of-00002.safetensors",
|
| 164 |
+
"layers.16.attention.norm_k.weight": "diffusion_pytorch_model-00001-of-00002.safetensors",
|
| 165 |
+
"layers.16.attention.norm_q.weight": "diffusion_pytorch_model-00001-of-00002.safetensors",
|
| 166 |
+
"layers.16.attention.to_k.weight": "diffusion_pytorch_model-00001-of-00002.safetensors",
|
| 167 |
+
"layers.16.attention.to_out.0.weight": "diffusion_pytorch_model-00001-of-00002.safetensors",
|
| 168 |
+
"layers.16.attention.to_q.weight": "diffusion_pytorch_model-00001-of-00002.safetensors",
|
| 169 |
+
"layers.16.attention.to_v.weight": "diffusion_pytorch_model-00001-of-00002.safetensors",
|
| 170 |
+
"layers.16.attention_norm1.weight": "diffusion_pytorch_model-00001-of-00002.safetensors",
|
| 171 |
+
"layers.16.attention_norm2.weight": "diffusion_pytorch_model-00001-of-00002.safetensors",
|
| 172 |
+
"layers.16.feed_forward.w1.weight": "diffusion_pytorch_model-00001-of-00002.safetensors",
|
| 173 |
+
"layers.16.feed_forward.w2.weight": "diffusion_pytorch_model-00001-of-00002.safetensors",
|
| 174 |
+
"layers.16.feed_forward.w3.weight": "diffusion_pytorch_model-00001-of-00002.safetensors",
|
| 175 |
+
"layers.16.ffn_norm1.weight": "diffusion_pytorch_model-00001-of-00002.safetensors",
|
| 176 |
+
"layers.16.ffn_norm2.weight": "diffusion_pytorch_model-00001-of-00002.safetensors",
|
| 177 |
+
"layers.17.adaLN_modulation.0.bias": "diffusion_pytorch_model-00001-of-00002.safetensors",
|
| 178 |
+
"layers.17.adaLN_modulation.0.weight": "diffusion_pytorch_model-00001-of-00002.safetensors",
|
| 179 |
+
"layers.17.attention.norm_k.weight": "diffusion_pytorch_model-00001-of-00002.safetensors",
|
| 180 |
+
"layers.17.attention.norm_q.weight": "diffusion_pytorch_model-00001-of-00002.safetensors",
|
| 181 |
+
"layers.17.attention.to_k.weight": "diffusion_pytorch_model-00001-of-00002.safetensors",
|
| 182 |
+
"layers.17.attention.to_out.0.weight": "diffusion_pytorch_model-00001-of-00002.safetensors",
|
| 183 |
+
"layers.17.attention.to_q.weight": "diffusion_pytorch_model-00001-of-00002.safetensors",
|
| 184 |
+
"layers.17.attention.to_v.weight": "diffusion_pytorch_model-00001-of-00002.safetensors",
|
| 185 |
+
"layers.17.attention_norm1.weight": "diffusion_pytorch_model-00001-of-00002.safetensors",
|
| 186 |
+
"layers.17.attention_norm2.weight": "diffusion_pytorch_model-00001-of-00002.safetensors",
|
| 187 |
+
"layers.17.feed_forward.w1.weight": "diffusion_pytorch_model-00001-of-00002.safetensors",
|
| 188 |
+
"layers.17.feed_forward.w2.weight": "diffusion_pytorch_model-00001-of-00002.safetensors",
|
| 189 |
+
"layers.17.feed_forward.w3.weight": "diffusion_pytorch_model-00001-of-00002.safetensors",
|
| 190 |
+
"layers.17.ffn_norm1.weight": "diffusion_pytorch_model-00001-of-00002.safetensors",
|
| 191 |
+
"layers.17.ffn_norm2.weight": "diffusion_pytorch_model-00001-of-00002.safetensors",
|
| 192 |
+
"layers.18.adaLN_modulation.0.bias": "diffusion_pytorch_model-00001-of-00002.safetensors",
|
| 193 |
+
"layers.18.adaLN_modulation.0.weight": "diffusion_pytorch_model-00001-of-00002.safetensors",
|
| 194 |
+
"layers.18.attention.norm_k.weight": "diffusion_pytorch_model-00001-of-00002.safetensors",
|
| 195 |
+
"layers.18.attention.norm_q.weight": "diffusion_pytorch_model-00001-of-00002.safetensors",
|
| 196 |
+
"layers.18.attention.to_k.weight": "diffusion_pytorch_model-00001-of-00002.safetensors",
|
| 197 |
+
"layers.18.attention.to_out.0.weight": "diffusion_pytorch_model-00001-of-00002.safetensors",
|
| 198 |
+
"layers.18.attention.to_q.weight": "diffusion_pytorch_model-00001-of-00002.safetensors",
|
| 199 |
+
"layers.18.attention.to_v.weight": "diffusion_pytorch_model-00001-of-00002.safetensors",
|
| 200 |
+
"layers.18.attention_norm1.weight": "diffusion_pytorch_model-00001-of-00002.safetensors",
|
| 201 |
+
"layers.18.attention_norm2.weight": "diffusion_pytorch_model-00001-of-00002.safetensors",
|
| 202 |
+
"layers.18.feed_forward.w1.weight": "diffusion_pytorch_model-00001-of-00002.safetensors",
|
| 203 |
+
"layers.18.feed_forward.w2.weight": "diffusion_pytorch_model-00001-of-00002.safetensors",
|
| 204 |
+
"layers.18.feed_forward.w3.weight": "diffusion_pytorch_model-00001-of-00002.safetensors",
|
| 205 |
+
"layers.18.ffn_norm1.weight": "diffusion_pytorch_model-00001-of-00002.safetensors",
|
| 206 |
+
"layers.18.ffn_norm2.weight": "diffusion_pytorch_model-00001-of-00002.safetensors",
|
| 207 |
+
"layers.19.adaLN_modulation.0.bias": "diffusion_pytorch_model-00001-of-00002.safetensors",
|
| 208 |
+
"layers.19.adaLN_modulation.0.weight": "diffusion_pytorch_model-00001-of-00002.safetensors",
|
| 209 |
+
"layers.19.attention.norm_k.weight": "diffusion_pytorch_model-00001-of-00002.safetensors",
|
| 210 |
+
"layers.19.attention.norm_q.weight": "diffusion_pytorch_model-00001-of-00002.safetensors",
|
| 211 |
+
"layers.19.attention.to_k.weight": "diffusion_pytorch_model-00001-of-00002.safetensors",
|
| 212 |
+
"layers.19.attention.to_out.0.weight": "diffusion_pytorch_model-00001-of-00002.safetensors",
|
| 213 |
+
"layers.19.attention.to_q.weight": "diffusion_pytorch_model-00001-of-00002.safetensors",
|
| 214 |
+
"layers.19.attention.to_v.weight": "diffusion_pytorch_model-00001-of-00002.safetensors",
|
| 215 |
+
"layers.19.attention_norm1.weight": "diffusion_pytorch_model-00001-of-00002.safetensors",
|
| 216 |
+
"layers.19.attention_norm2.weight": "diffusion_pytorch_model-00001-of-00002.safetensors",
|
| 217 |
+
"layers.19.feed_forward.w1.weight": "diffusion_pytorch_model-00001-of-00002.safetensors",
|
| 218 |
+
"layers.19.feed_forward.w2.weight": "diffusion_pytorch_model-00001-of-00002.safetensors",
|
| 219 |
+
"layers.19.feed_forward.w3.weight": "diffusion_pytorch_model-00001-of-00002.safetensors",
|
| 220 |
+
"layers.19.ffn_norm1.weight": "diffusion_pytorch_model-00001-of-00002.safetensors",
|
| 221 |
+
"layers.19.ffn_norm2.weight": "diffusion_pytorch_model-00001-of-00002.safetensors",
|
| 222 |
+
"layers.2.adaLN_modulation.0.bias": "diffusion_pytorch_model-00001-of-00002.safetensors",
|
| 223 |
+
"layers.2.adaLN_modulation.0.weight": "diffusion_pytorch_model-00001-of-00002.safetensors",
|
| 224 |
+
"layers.2.attention.norm_k.weight": "diffusion_pytorch_model-00001-of-00002.safetensors",
|
| 225 |
+
"layers.2.attention.norm_q.weight": "diffusion_pytorch_model-00001-of-00002.safetensors",
|
| 226 |
+
"layers.2.attention.to_k.weight": "diffusion_pytorch_model-00001-of-00002.safetensors",
|
| 227 |
+
"layers.2.attention.to_out.0.weight": "diffusion_pytorch_model-00001-of-00002.safetensors",
|
| 228 |
+
"layers.2.attention.to_q.weight": "diffusion_pytorch_model-00001-of-00002.safetensors",
|
| 229 |
+
"layers.2.attention.to_v.weight": "diffusion_pytorch_model-00001-of-00002.safetensors",
|
| 230 |
+
"layers.2.attention_norm1.weight": "diffusion_pytorch_model-00001-of-00002.safetensors",
|
| 231 |
+
"layers.2.attention_norm2.weight": "diffusion_pytorch_model-00001-of-00002.safetensors",
|
| 232 |
+
"layers.2.feed_forward.w1.weight": "diffusion_pytorch_model-00001-of-00002.safetensors",
|
| 233 |
+
"layers.2.feed_forward.w2.weight": "diffusion_pytorch_model-00001-of-00002.safetensors",
|
| 234 |
+
"layers.2.feed_forward.w3.weight": "diffusion_pytorch_model-00001-of-00002.safetensors",
|
| 235 |
+
"layers.2.ffn_norm1.weight": "diffusion_pytorch_model-00001-of-00002.safetensors",
|
| 236 |
+
"layers.2.ffn_norm2.weight": "diffusion_pytorch_model-00001-of-00002.safetensors",
|
| 237 |
+
"layers.20.adaLN_modulation.0.bias": "diffusion_pytorch_model-00001-of-00002.safetensors",
|
| 238 |
+
"layers.20.adaLN_modulation.0.weight": "diffusion_pytorch_model-00001-of-00002.safetensors",
|
| 239 |
+
"layers.20.attention.norm_k.weight": "diffusion_pytorch_model-00001-of-00002.safetensors",
|
| 240 |
+
"layers.20.attention.norm_q.weight": "diffusion_pytorch_model-00001-of-00002.safetensors",
|
| 241 |
+
"layers.20.attention.to_k.weight": "diffusion_pytorch_model-00001-of-00002.safetensors",
|
| 242 |
+
"layers.20.attention.to_out.0.weight": "diffusion_pytorch_model-00001-of-00002.safetensors",
|
| 243 |
+
"layers.20.attention.to_q.weight": "diffusion_pytorch_model-00001-of-00002.safetensors",
|
| 244 |
+
"layers.20.attention.to_v.weight": "diffusion_pytorch_model-00001-of-00002.safetensors",
|
| 245 |
+
"layers.20.attention_norm1.weight": "diffusion_pytorch_model-00001-of-00002.safetensors",
|
| 246 |
+
"layers.20.attention_norm2.weight": "diffusion_pytorch_model-00001-of-00002.safetensors",
|
| 247 |
+
"layers.20.feed_forward.w1.weight": "diffusion_pytorch_model-00001-of-00002.safetensors",
|
| 248 |
+
"layers.20.feed_forward.w2.weight": "diffusion_pytorch_model-00001-of-00002.safetensors",
|
| 249 |
+
"layers.20.feed_forward.w3.weight": "diffusion_pytorch_model-00001-of-00002.safetensors",
|
| 250 |
+
"layers.20.ffn_norm1.weight": "diffusion_pytorch_model-00001-of-00002.safetensors",
|
| 251 |
+
"layers.20.ffn_norm2.weight": "diffusion_pytorch_model-00001-of-00002.safetensors",
|
| 252 |
+
"layers.21.adaLN_modulation.0.bias": "diffusion_pytorch_model-00001-of-00002.safetensors",
|
| 253 |
+
"layers.21.adaLN_modulation.0.weight": "diffusion_pytorch_model-00001-of-00002.safetensors",
|
| 254 |
+
"layers.21.attention.norm_k.weight": "diffusion_pytorch_model-00001-of-00002.safetensors",
|
| 255 |
+
"layers.21.attention.norm_q.weight": "diffusion_pytorch_model-00001-of-00002.safetensors",
|
| 256 |
+
"layers.21.attention.to_k.weight": "diffusion_pytorch_model-00001-of-00002.safetensors",
|
| 257 |
+
"layers.21.attention.to_out.0.weight": "diffusion_pytorch_model-00001-of-00002.safetensors",
|
| 258 |
+
"layers.21.attention.to_q.weight": "diffusion_pytorch_model-00001-of-00002.safetensors",
|
| 259 |
+
"layers.21.attention.to_v.weight": "diffusion_pytorch_model-00001-of-00002.safetensors",
|
| 260 |
+
"layers.21.attention_norm1.weight": "diffusion_pytorch_model-00001-of-00002.safetensors",
|
| 261 |
+
"layers.21.attention_norm2.weight": "diffusion_pytorch_model-00001-of-00002.safetensors",
|
| 262 |
+
"layers.21.feed_forward.w1.weight": "diffusion_pytorch_model-00001-of-00002.safetensors",
|
| 263 |
+
"layers.21.feed_forward.w2.weight": "diffusion_pytorch_model-00001-of-00002.safetensors",
|
| 264 |
+
"layers.21.feed_forward.w3.weight": "diffusion_pytorch_model-00001-of-00002.safetensors",
|
| 265 |
+
"layers.21.ffn_norm1.weight": "diffusion_pytorch_model-00001-of-00002.safetensors",
|
| 266 |
+
"layers.21.ffn_norm2.weight": "diffusion_pytorch_model-00001-of-00002.safetensors",
|
| 267 |
+
"layers.22.adaLN_modulation.0.bias": "diffusion_pytorch_model-00001-of-00002.safetensors",
|
| 268 |
+
"layers.22.adaLN_modulation.0.weight": "diffusion_pytorch_model-00001-of-00002.safetensors",
|
| 269 |
+
"layers.22.attention.norm_k.weight": "diffusion_pytorch_model-00001-of-00002.safetensors",
|
| 270 |
+
"layers.22.attention.norm_q.weight": "diffusion_pytorch_model-00001-of-00002.safetensors",
|
| 271 |
+
"layers.22.attention.to_k.weight": "diffusion_pytorch_model-00001-of-00002.safetensors",
|
| 272 |
+
"layers.22.attention.to_out.0.weight": "diffusion_pytorch_model-00001-of-00002.safetensors",
|
| 273 |
+
"layers.22.attention.to_q.weight": "diffusion_pytorch_model-00001-of-00002.safetensors",
|
| 274 |
+
"layers.22.attention.to_v.weight": "diffusion_pytorch_model-00001-of-00002.safetensors",
|
| 275 |
+
"layers.22.attention_norm1.weight": "diffusion_pytorch_model-00001-of-00002.safetensors",
|
| 276 |
+
"layers.22.attention_norm2.weight": "diffusion_pytorch_model-00001-of-00002.safetensors",
|
| 277 |
+
"layers.22.feed_forward.w1.weight": "diffusion_pytorch_model-00001-of-00002.safetensors",
|
| 278 |
+
"layers.22.feed_forward.w2.weight": "diffusion_pytorch_model-00001-of-00002.safetensors",
|
| 279 |
+
"layers.22.feed_forward.w3.weight": "diffusion_pytorch_model-00001-of-00002.safetensors",
|
| 280 |
+
"layers.22.ffn_norm1.weight": "diffusion_pytorch_model-00001-of-00002.safetensors",
|
| 281 |
+
"layers.22.ffn_norm2.weight": "diffusion_pytorch_model-00001-of-00002.safetensors",
|
| 282 |
+
"layers.23.adaLN_modulation.0.bias": "diffusion_pytorch_model-00002-of-00002.safetensors",
|
| 283 |
+
"layers.23.adaLN_modulation.0.weight": "diffusion_pytorch_model-00002-of-00002.safetensors",
|
| 284 |
+
"layers.23.attention.norm_k.weight": "diffusion_pytorch_model-00001-of-00002.safetensors",
|
| 285 |
+
"layers.23.attention.norm_q.weight": "diffusion_pytorch_model-00001-of-00002.safetensors",
|
| 286 |
+
"layers.23.attention.to_k.weight": "diffusion_pytorch_model-00001-of-00002.safetensors",
|
| 287 |
+
"layers.23.attention.to_out.0.weight": "diffusion_pytorch_model-00001-of-00002.safetensors",
|
| 288 |
+
"layers.23.attention.to_q.weight": "diffusion_pytorch_model-00001-of-00002.safetensors",
|
| 289 |
+
"layers.23.attention.to_v.weight": "diffusion_pytorch_model-00001-of-00002.safetensors",
|
| 290 |
+
"layers.23.attention_norm1.weight": "diffusion_pytorch_model-00002-of-00002.safetensors",
|
| 291 |
+
"layers.23.attention_norm2.weight": "diffusion_pytorch_model-00002-of-00002.safetensors",
|
| 292 |
+
"layers.23.feed_forward.w1.weight": "diffusion_pytorch_model-00001-of-00002.safetensors",
|
| 293 |
+
"layers.23.feed_forward.w2.weight": "diffusion_pytorch_model-00002-of-00002.safetensors",
|
| 294 |
+
"layers.23.feed_forward.w3.weight": "diffusion_pytorch_model-00002-of-00002.safetensors",
|
| 295 |
+
"layers.23.ffn_norm1.weight": "diffusion_pytorch_model-00002-of-00002.safetensors",
|
| 296 |
+
"layers.23.ffn_norm2.weight": "diffusion_pytorch_model-00002-of-00002.safetensors",
|
| 297 |
+
"layers.24.adaLN_modulation.0.bias": "diffusion_pytorch_model-00002-of-00002.safetensors",
|
| 298 |
+
"layers.24.adaLN_modulation.0.weight": "diffusion_pytorch_model-00002-of-00002.safetensors",
|
| 299 |
+
"layers.24.attention.norm_k.weight": "diffusion_pytorch_model-00002-of-00002.safetensors",
|
| 300 |
+
"layers.24.attention.norm_q.weight": "diffusion_pytorch_model-00002-of-00002.safetensors",
|
| 301 |
+
"layers.24.attention.to_k.weight": "diffusion_pytorch_model-00002-of-00002.safetensors",
|
| 302 |
+
"layers.24.attention.to_out.0.weight": "diffusion_pytorch_model-00002-of-00002.safetensors",
|
| 303 |
+
"layers.24.attention.to_q.weight": "diffusion_pytorch_model-00002-of-00002.safetensors",
|
| 304 |
+
"layers.24.attention.to_v.weight": "diffusion_pytorch_model-00002-of-00002.safetensors",
|
| 305 |
+
"layers.24.attention_norm1.weight": "diffusion_pytorch_model-00002-of-00002.safetensors",
|
| 306 |
+
"layers.24.attention_norm2.weight": "diffusion_pytorch_model-00002-of-00002.safetensors",
|
| 307 |
+
"layers.24.feed_forward.w1.weight": "diffusion_pytorch_model-00002-of-00002.safetensors",
|
| 308 |
+
"layers.24.feed_forward.w2.weight": "diffusion_pytorch_model-00002-of-00002.safetensors",
|
| 309 |
+
"layers.24.feed_forward.w3.weight": "diffusion_pytorch_model-00002-of-00002.safetensors",
|
| 310 |
+
"layers.24.ffn_norm1.weight": "diffusion_pytorch_model-00002-of-00002.safetensors",
|
| 311 |
+
"layers.24.ffn_norm2.weight": "diffusion_pytorch_model-00002-of-00002.safetensors",
|
| 312 |
+
"layers.25.adaLN_modulation.0.bias": "diffusion_pytorch_model-00002-of-00002.safetensors",
|
| 313 |
+
"layers.25.adaLN_modulation.0.weight": "diffusion_pytorch_model-00002-of-00002.safetensors",
|
| 314 |
+
"layers.25.attention.norm_k.weight": "diffusion_pytorch_model-00002-of-00002.safetensors",
|
| 315 |
+
"layers.25.attention.norm_q.weight": "diffusion_pytorch_model-00002-of-00002.safetensors",
|
| 316 |
+
"layers.25.attention.to_k.weight": "diffusion_pytorch_model-00002-of-00002.safetensors",
|
| 317 |
+
"layers.25.attention.to_out.0.weight": "diffusion_pytorch_model-00002-of-00002.safetensors",
|
| 318 |
+
"layers.25.attention.to_q.weight": "diffusion_pytorch_model-00002-of-00002.safetensors",
|
| 319 |
+
"layers.25.attention.to_v.weight": "diffusion_pytorch_model-00002-of-00002.safetensors",
|
| 320 |
+
"layers.25.attention_norm1.weight": "diffusion_pytorch_model-00002-of-00002.safetensors",
|
| 321 |
+
"layers.25.attention_norm2.weight": "diffusion_pytorch_model-00002-of-00002.safetensors",
|
| 322 |
+
"layers.25.feed_forward.w1.weight": "diffusion_pytorch_model-00002-of-00002.safetensors",
|
| 323 |
+
"layers.25.feed_forward.w2.weight": "diffusion_pytorch_model-00002-of-00002.safetensors",
|
| 324 |
+
"layers.25.feed_forward.w3.weight": "diffusion_pytorch_model-00002-of-00002.safetensors",
|
| 325 |
+
"layers.25.ffn_norm1.weight": "diffusion_pytorch_model-00002-of-00002.safetensors",
|
| 326 |
+
"layers.25.ffn_norm2.weight": "diffusion_pytorch_model-00002-of-00002.safetensors",
|
| 327 |
+
"layers.26.adaLN_modulation.0.bias": "diffusion_pytorch_model-00002-of-00002.safetensors",
|
| 328 |
+
"layers.26.adaLN_modulation.0.weight": "diffusion_pytorch_model-00002-of-00002.safetensors",
|
| 329 |
+
"layers.26.attention.norm_k.weight": "diffusion_pytorch_model-00002-of-00002.safetensors",
|
| 330 |
+
"layers.26.attention.norm_q.weight": "diffusion_pytorch_model-00002-of-00002.safetensors",
|
| 331 |
+
"layers.26.attention.to_k.weight": "diffusion_pytorch_model-00002-of-00002.safetensors",
|
| 332 |
+
"layers.26.attention.to_out.0.weight": "diffusion_pytorch_model-00002-of-00002.safetensors",
|
| 333 |
+
"layers.26.attention.to_q.weight": "diffusion_pytorch_model-00002-of-00002.safetensors",
|
| 334 |
+
"layers.26.attention.to_v.weight": "diffusion_pytorch_model-00002-of-00002.safetensors",
|
| 335 |
+
"layers.26.attention_norm1.weight": "diffusion_pytorch_model-00002-of-00002.safetensors",
|
| 336 |
+
"layers.26.attention_norm2.weight": "diffusion_pytorch_model-00002-of-00002.safetensors",
|
| 337 |
+
"layers.26.feed_forward.w1.weight": "diffusion_pytorch_model-00002-of-00002.safetensors",
|
| 338 |
+
"layers.26.feed_forward.w2.weight": "diffusion_pytorch_model-00002-of-00002.safetensors",
|
| 339 |
+
"layers.26.feed_forward.w3.weight": "diffusion_pytorch_model-00002-of-00002.safetensors",
|
| 340 |
+
"layers.26.ffn_norm1.weight": "diffusion_pytorch_model-00002-of-00002.safetensors",
|
| 341 |
+
"layers.26.ffn_norm2.weight": "diffusion_pytorch_model-00002-of-00002.safetensors",
|
| 342 |
+
"layers.27.adaLN_modulation.0.bias": "diffusion_pytorch_model-00002-of-00002.safetensors",
|
| 343 |
+
"layers.27.adaLN_modulation.0.weight": "diffusion_pytorch_model-00002-of-00002.safetensors",
|
| 344 |
+
"layers.27.attention.norm_k.weight": "diffusion_pytorch_model-00002-of-00002.safetensors",
|
| 345 |
+
"layers.27.attention.norm_q.weight": "diffusion_pytorch_model-00002-of-00002.safetensors",
|
| 346 |
+
"layers.27.attention.to_k.weight": "diffusion_pytorch_model-00002-of-00002.safetensors",
|
| 347 |
+
"layers.27.attention.to_out.0.weight": "diffusion_pytorch_model-00002-of-00002.safetensors",
|
| 348 |
+
"layers.27.attention.to_q.weight": "diffusion_pytorch_model-00002-of-00002.safetensors",
|
| 349 |
+
"layers.27.attention.to_v.weight": "diffusion_pytorch_model-00002-of-00002.safetensors",
|
| 350 |
+
"layers.27.attention_norm1.weight": "diffusion_pytorch_model-00002-of-00002.safetensors",
|
| 351 |
+
"layers.27.attention_norm2.weight": "diffusion_pytorch_model-00002-of-00002.safetensors",
|
| 352 |
+
"layers.27.feed_forward.w1.weight": "diffusion_pytorch_model-00002-of-00002.safetensors",
|
| 353 |
+
"layers.27.feed_forward.w2.weight": "diffusion_pytorch_model-00002-of-00002.safetensors",
|
| 354 |
+
"layers.27.feed_forward.w3.weight": "diffusion_pytorch_model-00002-of-00002.safetensors",
|
| 355 |
+
"layers.27.ffn_norm1.weight": "diffusion_pytorch_model-00002-of-00002.safetensors",
|
| 356 |
+
"layers.27.ffn_norm2.weight": "diffusion_pytorch_model-00002-of-00002.safetensors",
|
| 357 |
+
"layers.28.adaLN_modulation.0.bias": "diffusion_pytorch_model-00002-of-00002.safetensors",
|
| 358 |
+
"layers.28.adaLN_modulation.0.weight": "diffusion_pytorch_model-00002-of-00002.safetensors",
|
| 359 |
+
"layers.28.attention.norm_k.weight": "diffusion_pytorch_model-00002-of-00002.safetensors",
|
| 360 |
+
"layers.28.attention.norm_q.weight": "diffusion_pytorch_model-00002-of-00002.safetensors",
|
| 361 |
+
"layers.28.attention.to_k.weight": "diffusion_pytorch_model-00002-of-00002.safetensors",
|
| 362 |
+
"layers.28.attention.to_out.0.weight": "diffusion_pytorch_model-00002-of-00002.safetensors",
|
| 363 |
+
"layers.28.attention.to_q.weight": "diffusion_pytorch_model-00002-of-00002.safetensors",
|
| 364 |
+
"layers.28.attention.to_v.weight": "diffusion_pytorch_model-00002-of-00002.safetensors",
|
| 365 |
+
"layers.28.attention_norm1.weight": "diffusion_pytorch_model-00002-of-00002.safetensors",
|
| 366 |
+
"layers.28.attention_norm2.weight": "diffusion_pytorch_model-00002-of-00002.safetensors",
|
| 367 |
+
"layers.28.feed_forward.w1.weight": "diffusion_pytorch_model-00002-of-00002.safetensors",
|
| 368 |
+
"layers.28.feed_forward.w2.weight": "diffusion_pytorch_model-00002-of-00002.safetensors",
|
| 369 |
+
"layers.28.feed_forward.w3.weight": "diffusion_pytorch_model-00002-of-00002.safetensors",
|
| 370 |
+
"layers.28.ffn_norm1.weight": "diffusion_pytorch_model-00002-of-00002.safetensors",
|
| 371 |
+
"layers.28.ffn_norm2.weight": "diffusion_pytorch_model-00002-of-00002.safetensors",
|
| 372 |
+
"layers.29.adaLN_modulation.0.bias": "diffusion_pytorch_model-00002-of-00002.safetensors",
|
| 373 |
+
"layers.29.adaLN_modulation.0.weight": "diffusion_pytorch_model-00002-of-00002.safetensors",
|
| 374 |
+
"layers.29.attention.norm_k.weight": "diffusion_pytorch_model-00002-of-00002.safetensors",
|
| 375 |
+
"layers.29.attention.norm_q.weight": "diffusion_pytorch_model-00002-of-00002.safetensors",
|
| 376 |
+
"layers.29.attention.to_k.weight": "diffusion_pytorch_model-00002-of-00002.safetensors",
|
| 377 |
+
"layers.29.attention.to_out.0.weight": "diffusion_pytorch_model-00002-of-00002.safetensors",
|
| 378 |
+
"layers.29.attention.to_q.weight": "diffusion_pytorch_model-00002-of-00002.safetensors",
|
| 379 |
+
"layers.29.attention.to_v.weight": "diffusion_pytorch_model-00002-of-00002.safetensors",
|
| 380 |
+
"layers.29.attention_norm1.weight": "diffusion_pytorch_model-00002-of-00002.safetensors",
|
| 381 |
+
"layers.29.attention_norm2.weight": "diffusion_pytorch_model-00002-of-00002.safetensors",
|
| 382 |
+
"layers.29.feed_forward.w1.weight": "diffusion_pytorch_model-00002-of-00002.safetensors",
|
| 383 |
+
"layers.29.feed_forward.w2.weight": "diffusion_pytorch_model-00002-of-00002.safetensors",
|
| 384 |
+
"layers.29.feed_forward.w3.weight": "diffusion_pytorch_model-00002-of-00002.safetensors",
|
| 385 |
+
"layers.29.ffn_norm1.weight": "diffusion_pytorch_model-00002-of-00002.safetensors",
|
| 386 |
+
"layers.29.ffn_norm2.weight": "diffusion_pytorch_model-00002-of-00002.safetensors",
|
| 387 |
+
"layers.3.adaLN_modulation.0.bias": "diffusion_pytorch_model-00001-of-00002.safetensors",
|
| 388 |
+
"layers.3.adaLN_modulation.0.weight": "diffusion_pytorch_model-00001-of-00002.safetensors",
|
| 389 |
+
"layers.3.attention.norm_k.weight": "diffusion_pytorch_model-00001-of-00002.safetensors",
|
| 390 |
+
"layers.3.attention.norm_q.weight": "diffusion_pytorch_model-00001-of-00002.safetensors",
|
| 391 |
+
"layers.3.attention.to_k.weight": "diffusion_pytorch_model-00001-of-00002.safetensors",
|
| 392 |
+
"layers.3.attention.to_out.0.weight": "diffusion_pytorch_model-00001-of-00002.safetensors",
|
| 393 |
+
"layers.3.attention.to_q.weight": "diffusion_pytorch_model-00001-of-00002.safetensors",
|
| 394 |
+
"layers.3.attention.to_v.weight": "diffusion_pytorch_model-00001-of-00002.safetensors",
|
| 395 |
+
"layers.3.attention_norm1.weight": "diffusion_pytorch_model-00001-of-00002.safetensors",
|
| 396 |
+
"layers.3.attention_norm2.weight": "diffusion_pytorch_model-00001-of-00002.safetensors",
|
| 397 |
+
"layers.3.feed_forward.w1.weight": "diffusion_pytorch_model-00001-of-00002.safetensors",
|
| 398 |
+
"layers.3.feed_forward.w2.weight": "diffusion_pytorch_model-00001-of-00002.safetensors",
|
| 399 |
+
"layers.3.feed_forward.w3.weight": "diffusion_pytorch_model-00001-of-00002.safetensors",
|
| 400 |
+
"layers.3.ffn_norm1.weight": "diffusion_pytorch_model-00001-of-00002.safetensors",
|
| 401 |
+
"layers.3.ffn_norm2.weight": "diffusion_pytorch_model-00001-of-00002.safetensors",
|
| 402 |
+
"layers.4.adaLN_modulation.0.bias": "diffusion_pytorch_model-00001-of-00002.safetensors",
|
| 403 |
+
"layers.4.adaLN_modulation.0.weight": "diffusion_pytorch_model-00001-of-00002.safetensors",
|
| 404 |
+
"layers.4.attention.norm_k.weight": "diffusion_pytorch_model-00001-of-00002.safetensors",
|
| 405 |
+
"layers.4.attention.norm_q.weight": "diffusion_pytorch_model-00001-of-00002.safetensors",
|
| 406 |
+
"layers.4.attention.to_k.weight": "diffusion_pytorch_model-00001-of-00002.safetensors",
|
| 407 |
+
"layers.4.attention.to_out.0.weight": "diffusion_pytorch_model-00001-of-00002.safetensors",
|
| 408 |
+
"layers.4.attention.to_q.weight": "diffusion_pytorch_model-00001-of-00002.safetensors",
|
| 409 |
+
"layers.4.attention.to_v.weight": "diffusion_pytorch_model-00001-of-00002.safetensors",
|
| 410 |
+
"layers.4.attention_norm1.weight": "diffusion_pytorch_model-00001-of-00002.safetensors",
|
| 411 |
+
"layers.4.attention_norm2.weight": "diffusion_pytorch_model-00001-of-00002.safetensors",
|
| 412 |
+
"layers.4.feed_forward.w1.weight": "diffusion_pytorch_model-00001-of-00002.safetensors",
|
| 413 |
+
"layers.4.feed_forward.w2.weight": "diffusion_pytorch_model-00001-of-00002.safetensors",
|
| 414 |
+
"layers.4.feed_forward.w3.weight": "diffusion_pytorch_model-00001-of-00002.safetensors",
|
| 415 |
+
"layers.4.ffn_norm1.weight": "diffusion_pytorch_model-00001-of-00002.safetensors",
|
| 416 |
+
"layers.4.ffn_norm2.weight": "diffusion_pytorch_model-00001-of-00002.safetensors",
|
| 417 |
+
"layers.5.adaLN_modulation.0.bias": "diffusion_pytorch_model-00001-of-00002.safetensors",
|
| 418 |
+
"layers.5.adaLN_modulation.0.weight": "diffusion_pytorch_model-00001-of-00002.safetensors",
|
| 419 |
+
"layers.5.attention.norm_k.weight": "diffusion_pytorch_model-00001-of-00002.safetensors",
|
| 420 |
+
"layers.5.attention.norm_q.weight": "diffusion_pytorch_model-00001-of-00002.safetensors",
|
| 421 |
+
"layers.5.attention.to_k.weight": "diffusion_pytorch_model-00001-of-00002.safetensors",
|
| 422 |
+
"layers.5.attention.to_out.0.weight": "diffusion_pytorch_model-00001-of-00002.safetensors",
|
| 423 |
+
"layers.5.attention.to_q.weight": "diffusion_pytorch_model-00001-of-00002.safetensors",
|
| 424 |
+
"layers.5.attention.to_v.weight": "diffusion_pytorch_model-00001-of-00002.safetensors",
|
| 425 |
+
"layers.5.attention_norm1.weight": "diffusion_pytorch_model-00001-of-00002.safetensors",
|
| 426 |
+
"layers.5.attention_norm2.weight": "diffusion_pytorch_model-00001-of-00002.safetensors",
|
| 427 |
+
"layers.5.feed_forward.w1.weight": "diffusion_pytorch_model-00001-of-00002.safetensors",
|
| 428 |
+
"layers.5.feed_forward.w2.weight": "diffusion_pytorch_model-00001-of-00002.safetensors",
|
| 429 |
+
"layers.5.feed_forward.w3.weight": "diffusion_pytorch_model-00001-of-00002.safetensors",
|
| 430 |
+
"layers.5.ffn_norm1.weight": "diffusion_pytorch_model-00001-of-00002.safetensors",
|
| 431 |
+
"layers.5.ffn_norm2.weight": "diffusion_pytorch_model-00001-of-00002.safetensors",
|
| 432 |
+
"layers.6.adaLN_modulation.0.bias": "diffusion_pytorch_model-00001-of-00002.safetensors",
|
| 433 |
+
"layers.6.adaLN_modulation.0.weight": "diffusion_pytorch_model-00001-of-00002.safetensors",
|
| 434 |
+
"layers.6.attention.norm_k.weight": "diffusion_pytorch_model-00001-of-00002.safetensors",
|
| 435 |
+
"layers.6.attention.norm_q.weight": "diffusion_pytorch_model-00001-of-00002.safetensors",
|
| 436 |
+
"layers.6.attention.to_k.weight": "diffusion_pytorch_model-00001-of-00002.safetensors",
|
| 437 |
+
"layers.6.attention.to_out.0.weight": "diffusion_pytorch_model-00001-of-00002.safetensors",
|
| 438 |
+
"layers.6.attention.to_q.weight": "diffusion_pytorch_model-00001-of-00002.safetensors",
|
| 439 |
+
"layers.6.attention.to_v.weight": "diffusion_pytorch_model-00001-of-00002.safetensors",
|
| 440 |
+
"layers.6.attention_norm1.weight": "diffusion_pytorch_model-00001-of-00002.safetensors",
|
| 441 |
+
"layers.6.attention_norm2.weight": "diffusion_pytorch_model-00001-of-00002.safetensors",
|
| 442 |
+
"layers.6.feed_forward.w1.weight": "diffusion_pytorch_model-00001-of-00002.safetensors",
|
| 443 |
+
"layers.6.feed_forward.w2.weight": "diffusion_pytorch_model-00001-of-00002.safetensors",
|
| 444 |
+
"layers.6.feed_forward.w3.weight": "diffusion_pytorch_model-00001-of-00002.safetensors",
|
| 445 |
+
"layers.6.ffn_norm1.weight": "diffusion_pytorch_model-00001-of-00002.safetensors",
|
| 446 |
+
"layers.6.ffn_norm2.weight": "diffusion_pytorch_model-00001-of-00002.safetensors",
|
| 447 |
+
"layers.7.adaLN_modulation.0.bias": "diffusion_pytorch_model-00001-of-00002.safetensors",
|
| 448 |
+
"layers.7.adaLN_modulation.0.weight": "diffusion_pytorch_model-00001-of-00002.safetensors",
|
| 449 |
+
"layers.7.attention.norm_k.weight": "diffusion_pytorch_model-00001-of-00002.safetensors",
|
| 450 |
+
"layers.7.attention.norm_q.weight": "diffusion_pytorch_model-00001-of-00002.safetensors",
|
| 451 |
+
"layers.7.attention.to_k.weight": "diffusion_pytorch_model-00001-of-00002.safetensors",
|
| 452 |
+
"layers.7.attention.to_out.0.weight": "diffusion_pytorch_model-00001-of-00002.safetensors",
|
| 453 |
+
"layers.7.attention.to_q.weight": "diffusion_pytorch_model-00001-of-00002.safetensors",
|
| 454 |
+
"layers.7.attention.to_v.weight": "diffusion_pytorch_model-00001-of-00002.safetensors",
|
| 455 |
+
"layers.7.attention_norm1.weight": "diffusion_pytorch_model-00001-of-00002.safetensors",
|
| 456 |
+
"layers.7.attention_norm2.weight": "diffusion_pytorch_model-00001-of-00002.safetensors",
|
| 457 |
+
"layers.7.feed_forward.w1.weight": "diffusion_pytorch_model-00001-of-00002.safetensors",
|
| 458 |
+
"layers.7.feed_forward.w2.weight": "diffusion_pytorch_model-00001-of-00002.safetensors",
|
| 459 |
+
"layers.7.feed_forward.w3.weight": "diffusion_pytorch_model-00001-of-00002.safetensors",
|
| 460 |
+
"layers.7.ffn_norm1.weight": "diffusion_pytorch_model-00001-of-00002.safetensors",
|
| 461 |
+
"layers.7.ffn_norm2.weight": "diffusion_pytorch_model-00001-of-00002.safetensors",
|
| 462 |
+
"layers.8.adaLN_modulation.0.bias": "diffusion_pytorch_model-00001-of-00002.safetensors",
|
| 463 |
+
"layers.8.adaLN_modulation.0.weight": "diffusion_pytorch_model-00001-of-00002.safetensors",
|
| 464 |
+
"layers.8.attention.norm_k.weight": "diffusion_pytorch_model-00001-of-00002.safetensors",
|
| 465 |
+
"layers.8.attention.norm_q.weight": "diffusion_pytorch_model-00001-of-00002.safetensors",
|
| 466 |
+
"layers.8.attention.to_k.weight": "diffusion_pytorch_model-00001-of-00002.safetensors",
|
| 467 |
+
"layers.8.attention.to_out.0.weight": "diffusion_pytorch_model-00001-of-00002.safetensors",
|
| 468 |
+
"layers.8.attention.to_q.weight": "diffusion_pytorch_model-00001-of-00002.safetensors",
|
| 469 |
+
"layers.8.attention.to_v.weight": "diffusion_pytorch_model-00001-of-00002.safetensors",
|
| 470 |
+
"layers.8.attention_norm1.weight": "diffusion_pytorch_model-00001-of-00002.safetensors",
|
| 471 |
+
"layers.8.attention_norm2.weight": "diffusion_pytorch_model-00001-of-00002.safetensors",
|
| 472 |
+
"layers.8.feed_forward.w1.weight": "diffusion_pytorch_model-00001-of-00002.safetensors",
|
| 473 |
+
"layers.8.feed_forward.w2.weight": "diffusion_pytorch_model-00001-of-00002.safetensors",
|
| 474 |
+
"layers.8.feed_forward.w3.weight": "diffusion_pytorch_model-00001-of-00002.safetensors",
|
| 475 |
+
"layers.8.ffn_norm1.weight": "diffusion_pytorch_model-00001-of-00002.safetensors",
|
| 476 |
+
"layers.8.ffn_norm2.weight": "diffusion_pytorch_model-00001-of-00002.safetensors",
|
| 477 |
+
"layers.9.adaLN_modulation.0.bias": "diffusion_pytorch_model-00001-of-00002.safetensors",
|
| 478 |
+
"layers.9.adaLN_modulation.0.weight": "diffusion_pytorch_model-00001-of-00002.safetensors",
|
| 479 |
+
"layers.9.attention.norm_k.weight": "diffusion_pytorch_model-00001-of-00002.safetensors",
|
| 480 |
+
"layers.9.attention.norm_q.weight": "diffusion_pytorch_model-00001-of-00002.safetensors",
|
| 481 |
+
"layers.9.attention.to_k.weight": "diffusion_pytorch_model-00001-of-00002.safetensors",
|
| 482 |
+
"layers.9.attention.to_out.0.weight": "diffusion_pytorch_model-00001-of-00002.safetensors",
|
| 483 |
+
"layers.9.attention.to_q.weight": "diffusion_pytorch_model-00001-of-00002.safetensors",
|
| 484 |
+
"layers.9.attention.to_v.weight": "diffusion_pytorch_model-00001-of-00002.safetensors",
|
| 485 |
+
"layers.9.attention_norm1.weight": "diffusion_pytorch_model-00001-of-00002.safetensors",
|
| 486 |
+
"layers.9.attention_norm2.weight": "diffusion_pytorch_model-00001-of-00002.safetensors",
|
| 487 |
+
"layers.9.feed_forward.w1.weight": "diffusion_pytorch_model-00001-of-00002.safetensors",
|
| 488 |
+
"layers.9.feed_forward.w2.weight": "diffusion_pytorch_model-00001-of-00002.safetensors",
|
| 489 |
+
"layers.9.feed_forward.w3.weight": "diffusion_pytorch_model-00001-of-00002.safetensors",
|
| 490 |
+
"layers.9.ffn_norm1.weight": "diffusion_pytorch_model-00001-of-00002.safetensors",
|
| 491 |
+
"layers.9.ffn_norm2.weight": "diffusion_pytorch_model-00001-of-00002.safetensors",
|
| 492 |
+
"noise_refiner.0.adaLN_modulation.0.bias": "diffusion_pytorch_model-00001-of-00002.safetensors",
|
| 493 |
+
"noise_refiner.0.adaLN_modulation.0.weight": "diffusion_pytorch_model-00001-of-00002.safetensors",
|
| 494 |
+
"noise_refiner.0.attention.norm_k.weight": "diffusion_pytorch_model-00001-of-00002.safetensors",
|
| 495 |
+
"noise_refiner.0.attention.norm_q.weight": "diffusion_pytorch_model-00001-of-00002.safetensors",
|
| 496 |
+
"noise_refiner.0.attention.to_k.weight": "diffusion_pytorch_model-00001-of-00002.safetensors",
|
| 497 |
+
"noise_refiner.0.attention.to_out.0.weight": "diffusion_pytorch_model-00001-of-00002.safetensors",
|
| 498 |
+
"noise_refiner.0.attention.to_q.weight": "diffusion_pytorch_model-00001-of-00002.safetensors",
|
| 499 |
+
"noise_refiner.0.attention.to_v.weight": "diffusion_pytorch_model-00001-of-00002.safetensors",
|
| 500 |
+
"noise_refiner.0.attention_norm1.weight": "diffusion_pytorch_model-00001-of-00002.safetensors",
|
| 501 |
+
"noise_refiner.0.attention_norm2.weight": "diffusion_pytorch_model-00001-of-00002.safetensors",
|
| 502 |
+
"noise_refiner.0.feed_forward.w1.weight": "diffusion_pytorch_model-00001-of-00002.safetensors",
|
| 503 |
+
"noise_refiner.0.feed_forward.w2.weight": "diffusion_pytorch_model-00001-of-00002.safetensors",
|
| 504 |
+
"noise_refiner.0.feed_forward.w3.weight": "diffusion_pytorch_model-00001-of-00002.safetensors",
|
| 505 |
+
"noise_refiner.0.ffn_norm1.weight": "diffusion_pytorch_model-00001-of-00002.safetensors",
|
| 506 |
+
"noise_refiner.0.ffn_norm2.weight": "diffusion_pytorch_model-00001-of-00002.safetensors",
|
| 507 |
+
"noise_refiner.1.adaLN_modulation.0.bias": "diffusion_pytorch_model-00001-of-00002.safetensors",
|
| 508 |
+
"noise_refiner.1.adaLN_modulation.0.weight": "diffusion_pytorch_model-00001-of-00002.safetensors",
|
| 509 |
+
"noise_refiner.1.attention.norm_k.weight": "diffusion_pytorch_model-00001-of-00002.safetensors",
|
| 510 |
+
"noise_refiner.1.attention.norm_q.weight": "diffusion_pytorch_model-00001-of-00002.safetensors",
|
| 511 |
+
"noise_refiner.1.attention.to_k.weight": "diffusion_pytorch_model-00001-of-00002.safetensors",
|
| 512 |
+
"noise_refiner.1.attention.to_out.0.weight": "diffusion_pytorch_model-00001-of-00002.safetensors",
|
| 513 |
+
"noise_refiner.1.attention.to_q.weight": "diffusion_pytorch_model-00001-of-00002.safetensors",
|
| 514 |
+
"noise_refiner.1.attention.to_v.weight": "diffusion_pytorch_model-00001-of-00002.safetensors",
|
| 515 |
+
"noise_refiner.1.attention_norm1.weight": "diffusion_pytorch_model-00001-of-00002.safetensors",
|
| 516 |
+
"noise_refiner.1.attention_norm2.weight": "diffusion_pytorch_model-00001-of-00002.safetensors",
|
| 517 |
+
"noise_refiner.1.feed_forward.w1.weight": "diffusion_pytorch_model-00001-of-00002.safetensors",
|
| 518 |
+
"noise_refiner.1.feed_forward.w2.weight": "diffusion_pytorch_model-00001-of-00002.safetensors",
|
| 519 |
+
"noise_refiner.1.feed_forward.w3.weight": "diffusion_pytorch_model-00001-of-00002.safetensors",
|
| 520 |
+
"noise_refiner.1.ffn_norm1.weight": "diffusion_pytorch_model-00001-of-00002.safetensors",
|
| 521 |
+
"noise_refiner.1.ffn_norm2.weight": "diffusion_pytorch_model-00001-of-00002.safetensors",
|
| 522 |
+
"t_embedder.mlp.0.bias": "diffusion_pytorch_model-00001-of-00002.safetensors",
|
| 523 |
+
"t_embedder.mlp.0.weight": "diffusion_pytorch_model-00001-of-00002.safetensors",
|
| 524 |
+
"t_embedder.mlp.2.bias": "diffusion_pytorch_model-00001-of-00002.safetensors",
|
| 525 |
+
"t_embedder.mlp.2.weight": "diffusion_pytorch_model-00001-of-00002.safetensors",
|
| 526 |
+
"x_pad_token": "diffusion_pytorch_model-00001-of-00002.safetensors"
|
| 527 |
+
}
|
| 528 |
+
}
|
vae/config.json
ADDED
|
@@ -0,0 +1,38 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
{
|
| 2 |
+
"_class_name": "AutoencoderKL",
|
| 3 |
+
"_diffusers_version": "0.37.1",
|
| 4 |
+
"_name_or_path": "/root/.cache/huggingface/hub/models--Tongyi-MAI--Z-Image/snapshots/04cc4abb7c5069926f75c9bfde9ef43d49423021/vae",
|
| 5 |
+
"act_fn": "silu",
|
| 6 |
+
"block_out_channels": [
|
| 7 |
+
128,
|
| 8 |
+
256,
|
| 9 |
+
512,
|
| 10 |
+
512
|
| 11 |
+
],
|
| 12 |
+
"down_block_types": [
|
| 13 |
+
"DownEncoderBlock2D",
|
| 14 |
+
"DownEncoderBlock2D",
|
| 15 |
+
"DownEncoderBlock2D",
|
| 16 |
+
"DownEncoderBlock2D"
|
| 17 |
+
],
|
| 18 |
+
"force_upcast": true,
|
| 19 |
+
"in_channels": 3,
|
| 20 |
+
"latent_channels": 16,
|
| 21 |
+
"latents_mean": null,
|
| 22 |
+
"latents_std": null,
|
| 23 |
+
"layers_per_block": 2,
|
| 24 |
+
"mid_block_add_attention": true,
|
| 25 |
+
"norm_num_groups": 32,
|
| 26 |
+
"out_channels": 3,
|
| 27 |
+
"sample_size": 1024,
|
| 28 |
+
"scaling_factor": 0.3611,
|
| 29 |
+
"shift_factor": 0.1159,
|
| 30 |
+
"up_block_types": [
|
| 31 |
+
"UpDecoderBlock2D",
|
| 32 |
+
"UpDecoderBlock2D",
|
| 33 |
+
"UpDecoderBlock2D",
|
| 34 |
+
"UpDecoderBlock2D"
|
| 35 |
+
],
|
| 36 |
+
"use_post_quant_conv": false,
|
| 37 |
+
"use_quant_conv": false
|
| 38 |
+
}
|
vae/diffusion_pytorch_model.safetensors
ADDED
|
@@ -0,0 +1,3 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
version https://git-lfs.github.com/spec/v1
|
| 2 |
+
oid sha256:f58ad0fbb7e0621871b778bf36a6faeb2c46a79adb32b898b60acd1f9560f890
|
| 3 |
+
size 167666654
|