

Delete README.md
Browse files
README.md
DELETED
|
@@ -1,57 +0,0 @@
|
|
| 1 |
-
---
|
| 2 |
-
license: mit
|
| 3 |
-
pipeline_tag: document-question-answering
|
| 4 |
-
tags:
|
| 5 |
-
- donut
|
| 6 |
-
- image-to-text
|
| 7 |
-
- vision
|
| 8 |
-
widget:
|
| 9 |
-
- text: "What is the invoice number?"
|
| 10 |
-
src: "https://huggingface.co/spaces/impira/docquery/resolve/2359223c1837a7587402bda0f2643382a6eefeab/invoice.png"
|
| 11 |
-
- text: "What is the purchase amount?"
|
| 12 |
-
src: "https://huggingface.co/spaces/impira/docquery/resolve/2359223c1837a7587402bda0f2643382a6eefeab/contract.jpeg"
|
| 13 |
-
---
|
| 14 |
-
|
| 15 |
-
# Donut (base-sized model, fine-tuned on DocVQA)
|
| 16 |
-
|
| 17 |
-
Donut model fine-tuned on DocVQA. It was introduced in the paper [OCR-free Document Understanding Transformer](https://arxiv.org/abs/2111.15664) by Geewok et al. and first released in [this repository](https://github.com/clovaai/donut).
|
| 18 |
-
|
| 19 |
-
Disclaimer: The team releasing Donut did not write a model card for this model so this model card has been written by the Hugging Face team.
|
| 20 |
-
|
| 21 |
-
## Model description
|
| 22 |
-
|
| 23 |
-
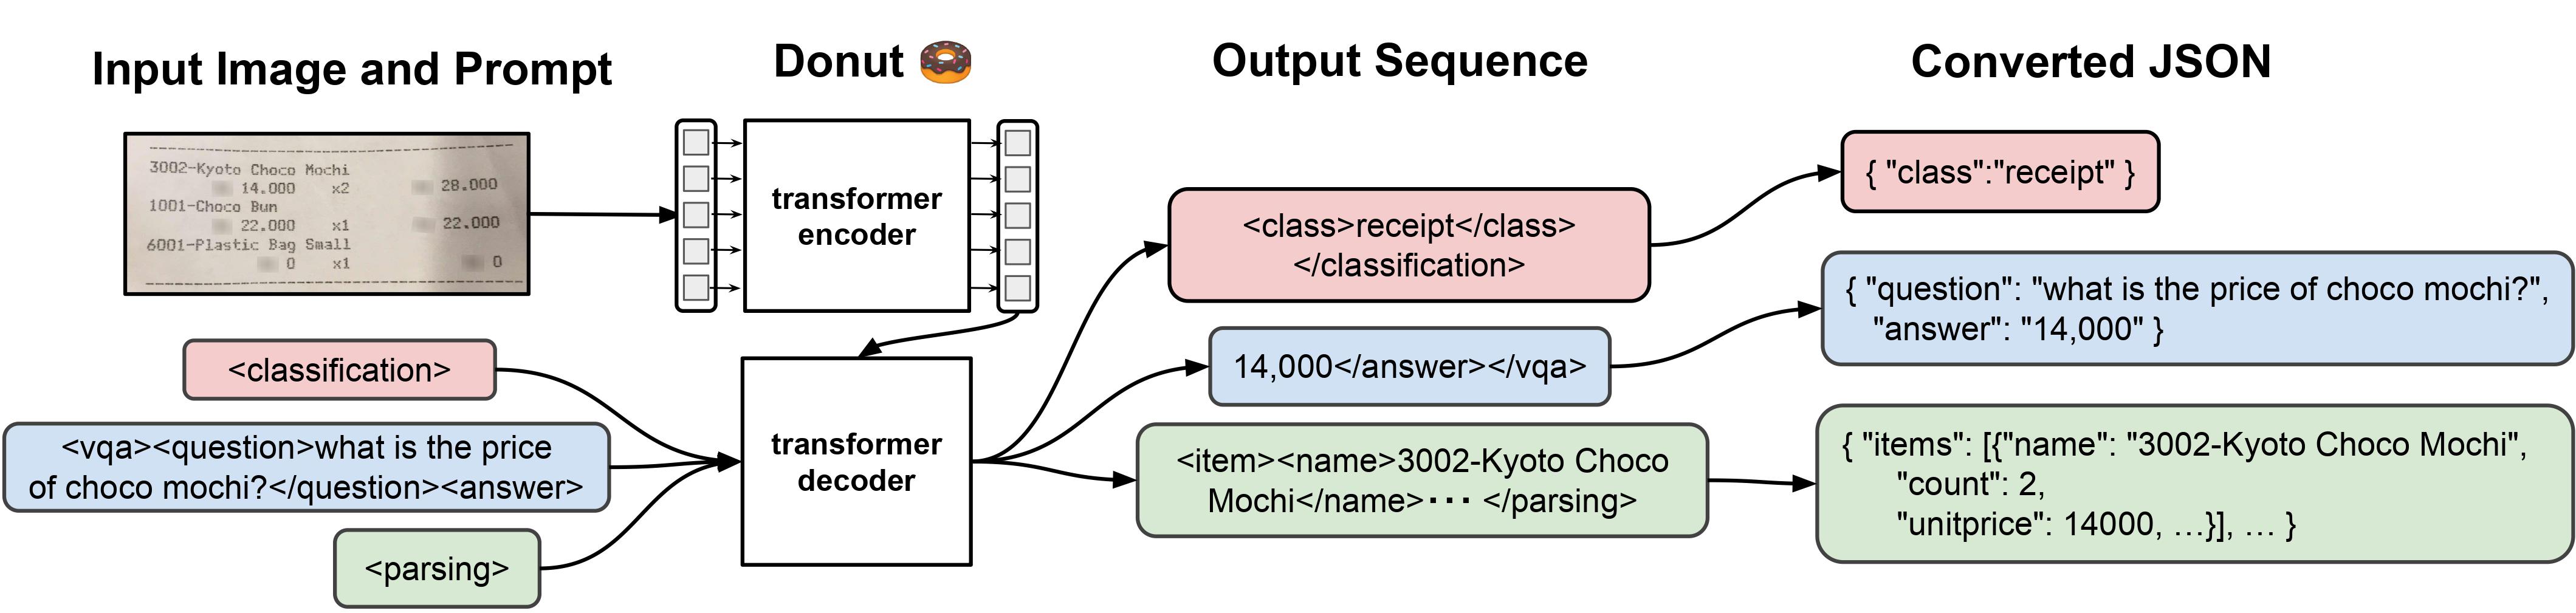
Donut consists of a vision encoder (Swin Transformer) and a text decoder (BART). Given an image, the encoder first encodes the image into a tensor of embeddings (of shape batch_size, seq_len, hidden_size), after which the decoder autoregressively generates text, conditioned on the encoding of the encoder.
|
| 24 |
-
|
| 25 |
-
|
| 26 |
-
|
| 27 |
-
## Intended uses & limitations
|
| 28 |
-
|
| 29 |
-
This model is fine-tuned on DocVQA, a document visual question answering dataset.
|
| 30 |
-
|
| 31 |
-
We refer to the [documentation](https://huggingface.co/docs/transformers/main/en/model_doc/donut) which includes code examples.
|
| 32 |
-
|
| 33 |
-
### BibTeX entry and citation info
|
| 34 |
-
|
| 35 |
-
```bibtex
|
| 36 |
-
@article{DBLP:journals/corr/abs-2111-15664,
|
| 37 |
-
author = {Geewook Kim and
|
| 38 |
-
Teakgyu Hong and
|
| 39 |
-
Moonbin Yim and
|
| 40 |
-
Jinyoung Park and
|
| 41 |
-
Jinyeong Yim and
|
| 42 |
-
Wonseok Hwang and
|
| 43 |
-
Sangdoo Yun and
|
| 44 |
-
Dongyoon Han and
|
| 45 |
-
Seunghyun Park},
|
| 46 |
-
title = {Donut: Document Understanding Transformer without {OCR}},
|
| 47 |
-
journal = {CoRR},
|
| 48 |
-
volume = {abs/2111.15664},
|
| 49 |
-
year = {2021},
|
| 50 |
-
url = {https://arxiv.org/abs/2111.15664},
|
| 51 |
-
eprinttype = {arXiv},
|
| 52 |
-
eprint = {2111.15664},
|
| 53 |
-
timestamp = {Thu, 02 Dec 2021 10:50:44 +0100},
|
| 54 |
-
biburl = {https://dblp.org/rec/journals/corr/abs-2111-15664.bib},
|
| 55 |
-
bibsource = {dblp computer science bibliography, https://dblp.org}
|
| 56 |
-
}
|
| 57 |
-
```
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|