


Duplicate from SoMarkAI/OXR-1.0
Browse filesCo-authored-by: SoulCode <Soul-Code@users.noreply.huggingface.co>
- .eval_results/olmocrbench.yaml +44 -0
- .gitattributes +3 -0
- .gitignore +44 -0
- LICENSE +140 -0
- README.md +350 -0
- added_tokens.json +28 -0
- chat_template.jinja +18 -0
- config.json +109 -0
- configuration_oxr.py +100 -0
- generation_config.json +8 -0
- layout_analysis/README.md +33 -0
- layout_analysis/last.pth +3 -0
- layout_analysis/metadata.json +29 -0
- merges.txt +0 -0
- model.safetensors +3 -0
- modeling_oxr.py +1037 -0
- plugins/vllm/README.md +30 -0
- plugins/vllm/oxr_vllm/__init__.py +11 -0
- plugins/vllm/oxr_vllm/oxr_model.py +660 -0
- plugins/vllm/oxr_vllm/oxr_processor.py +384 -0
- plugins/vllm/pyproject.toml +16 -0
- preprocessor_config.json +24 -0
- special_tokens_map.json +31 -0
- tokenizer.json +3 -0
- tokenizer_config.json +240 -0
- vocab.json +0 -0
.eval_results/olmocrbench.yaml
ADDED
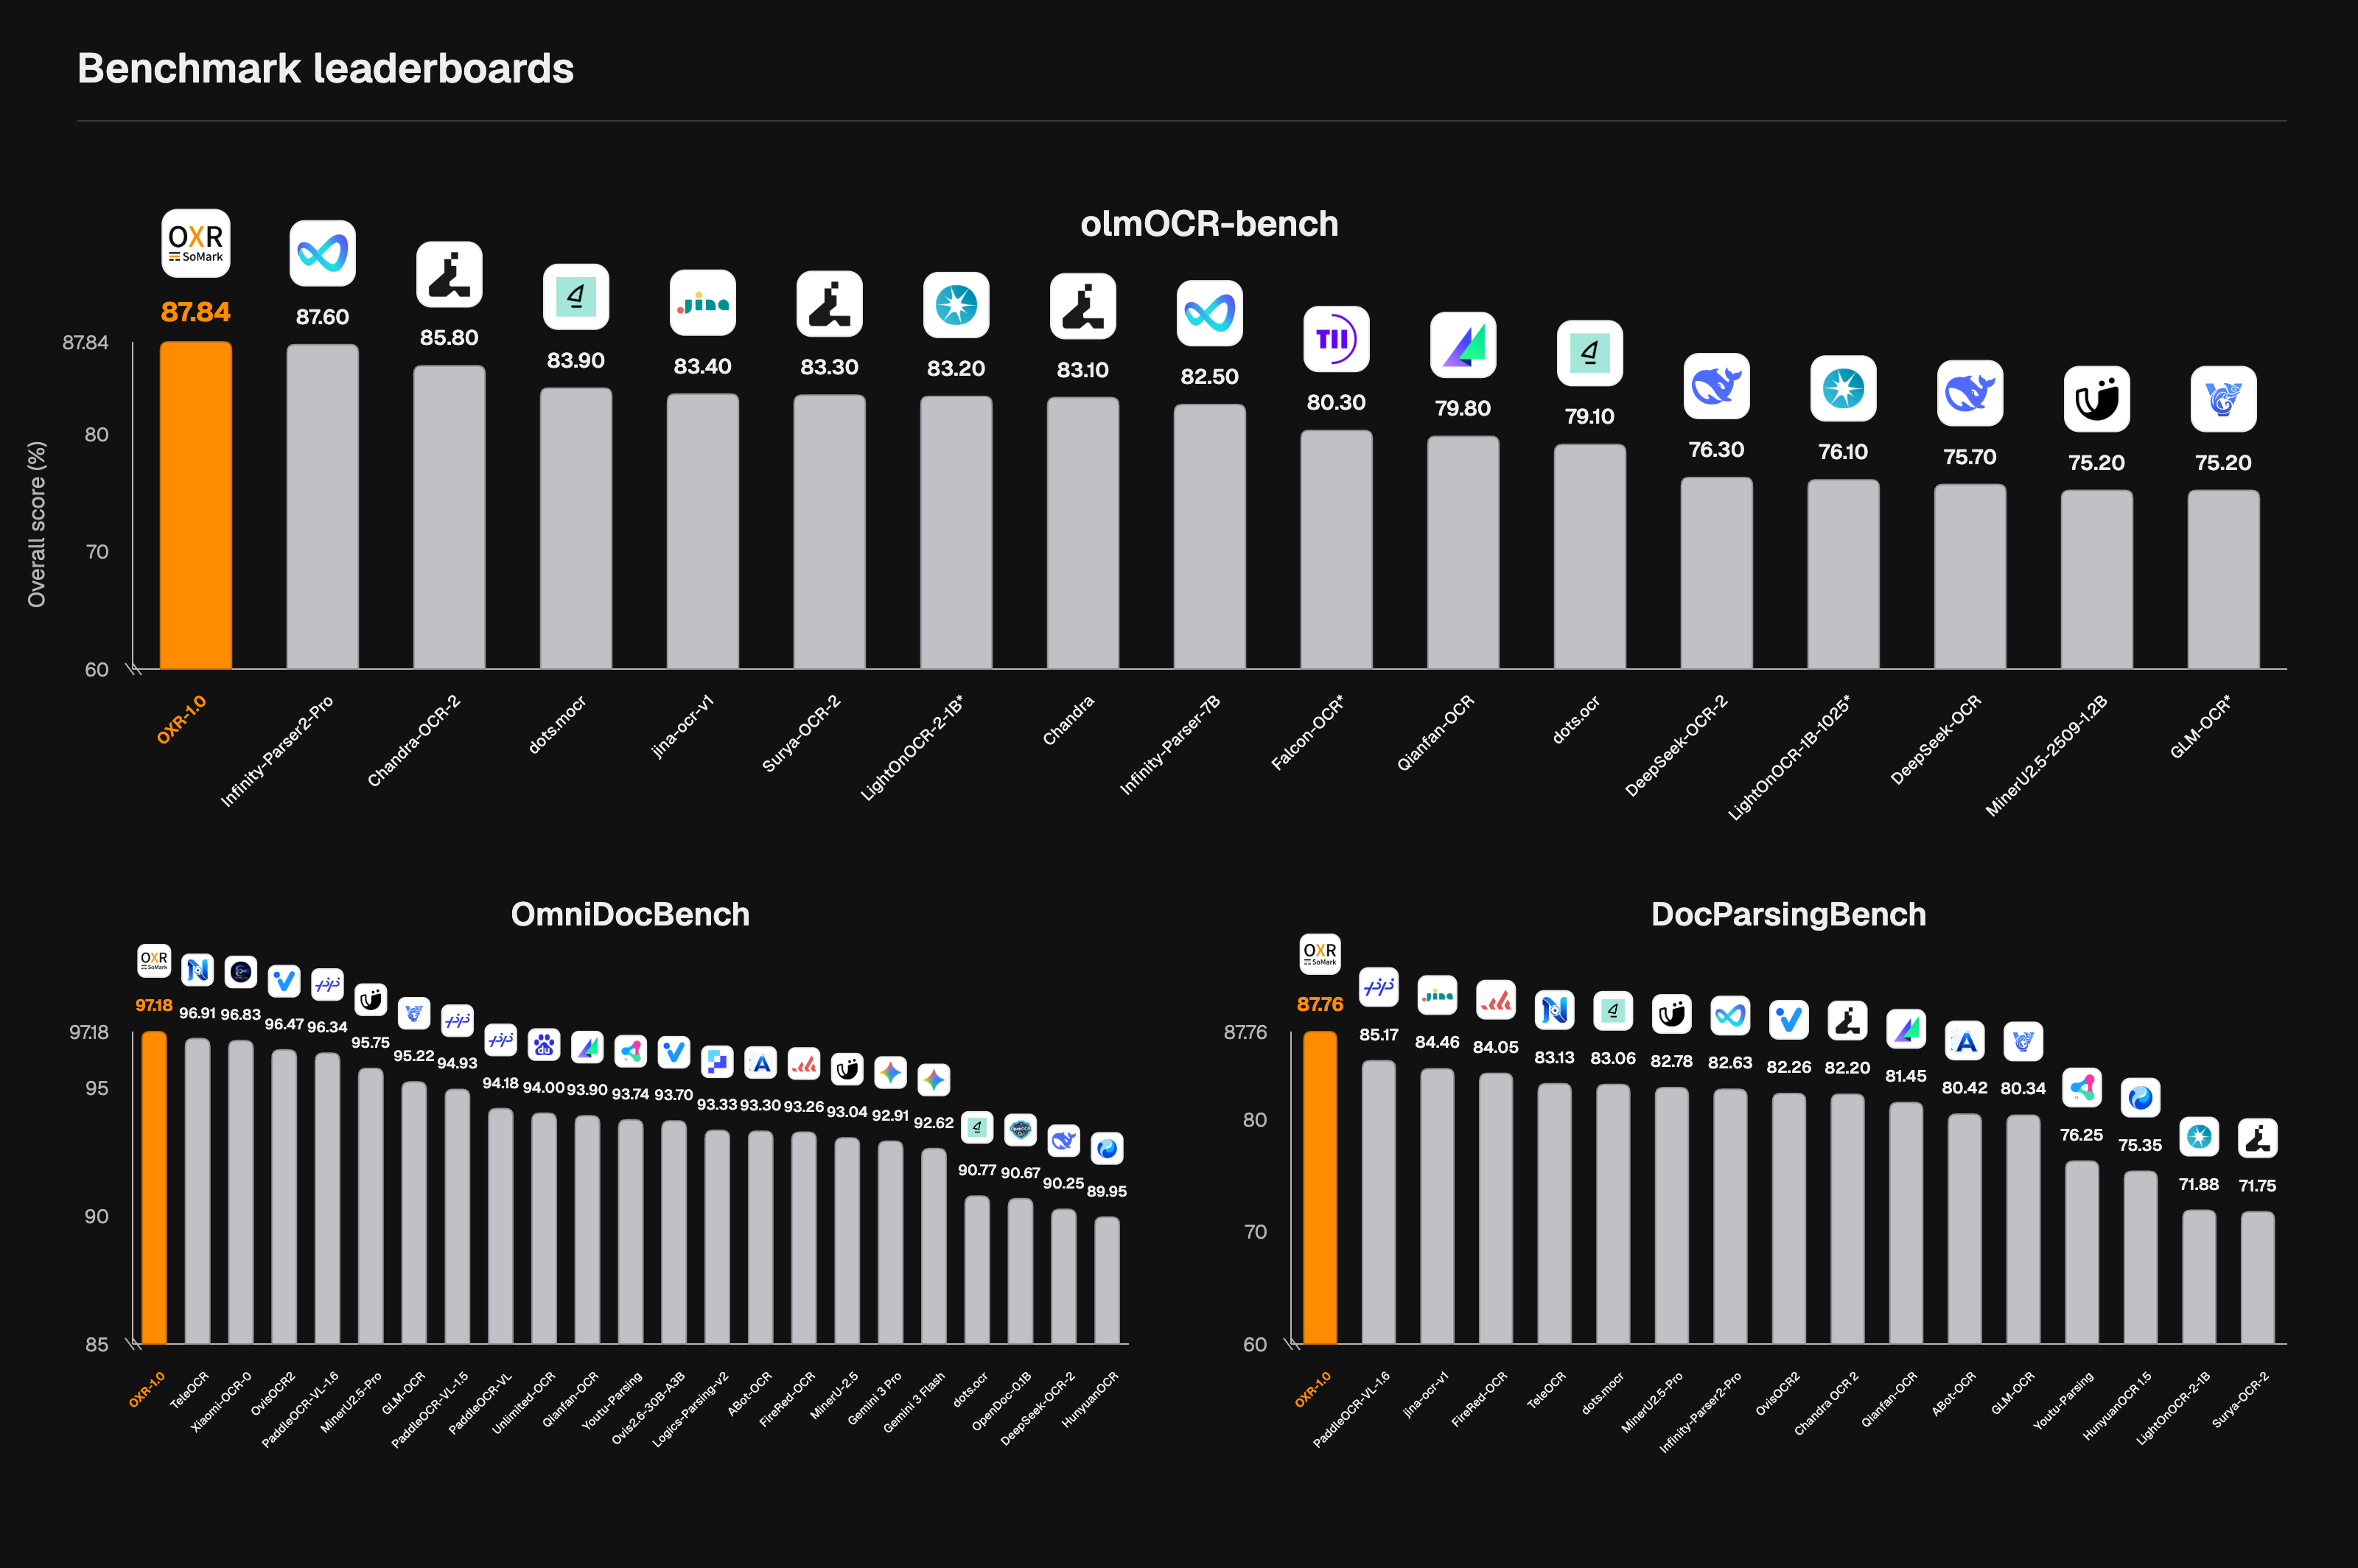
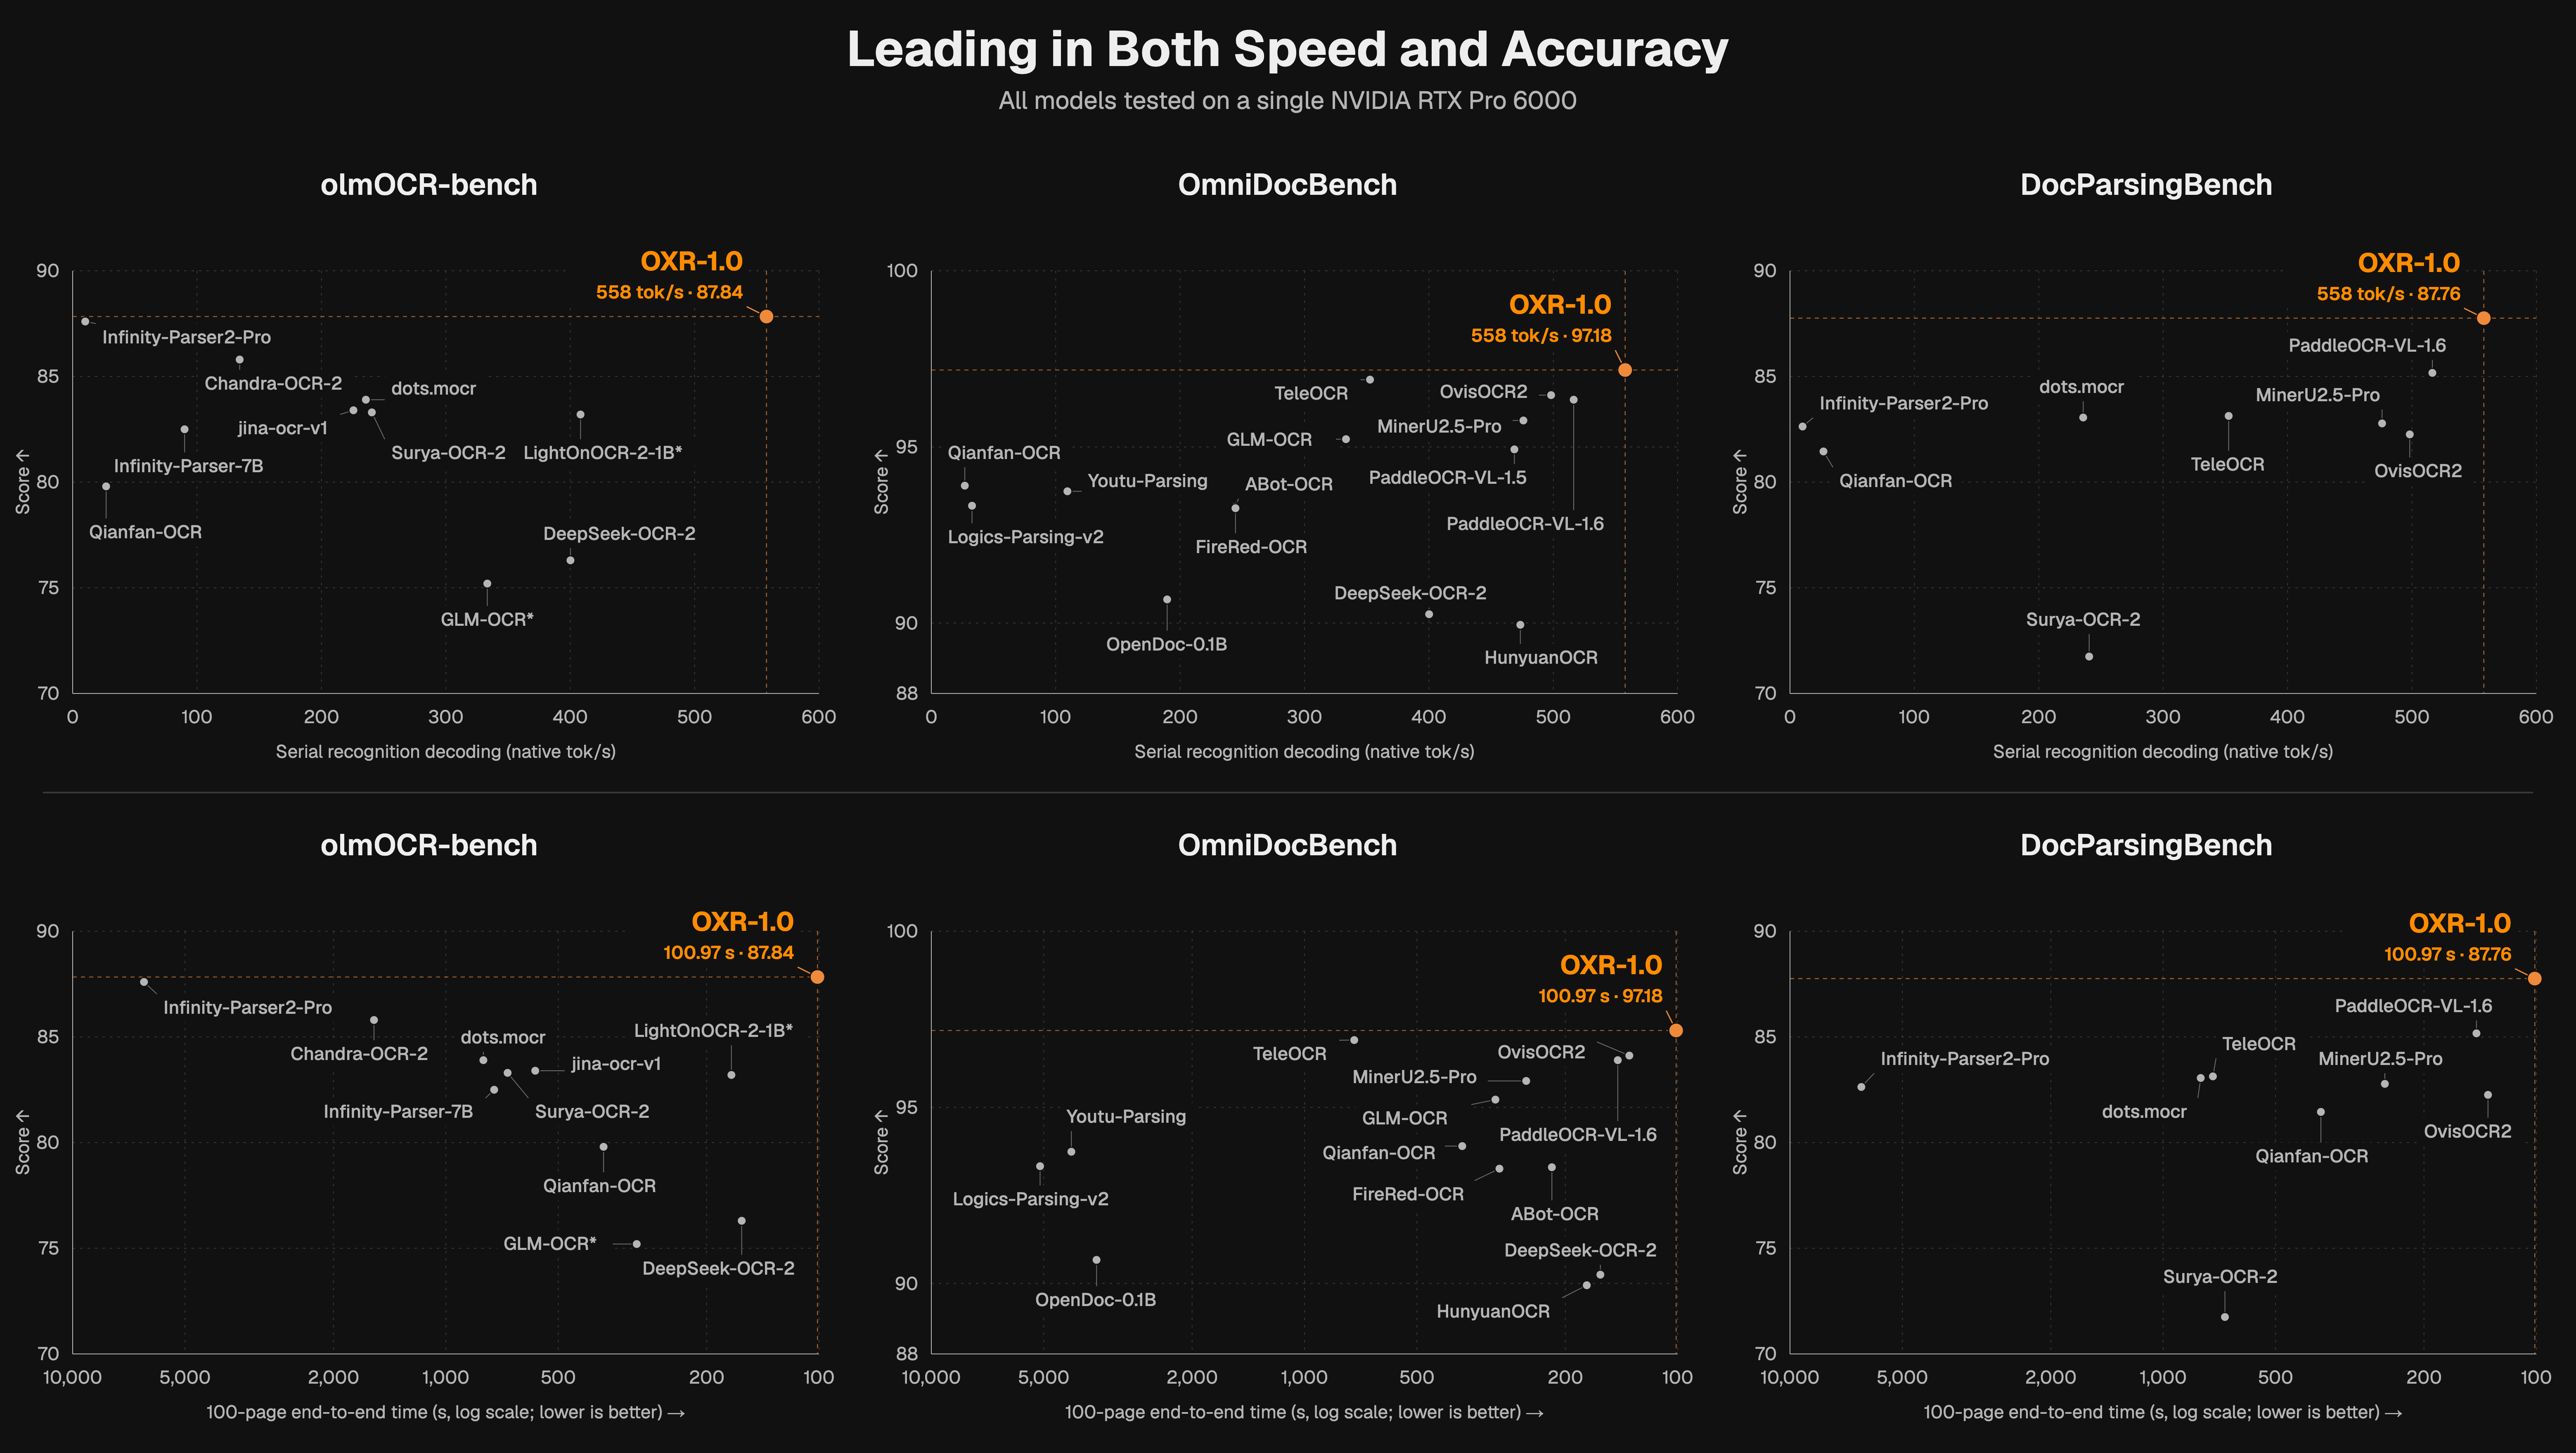
|
@@ -0,0 +1,44 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
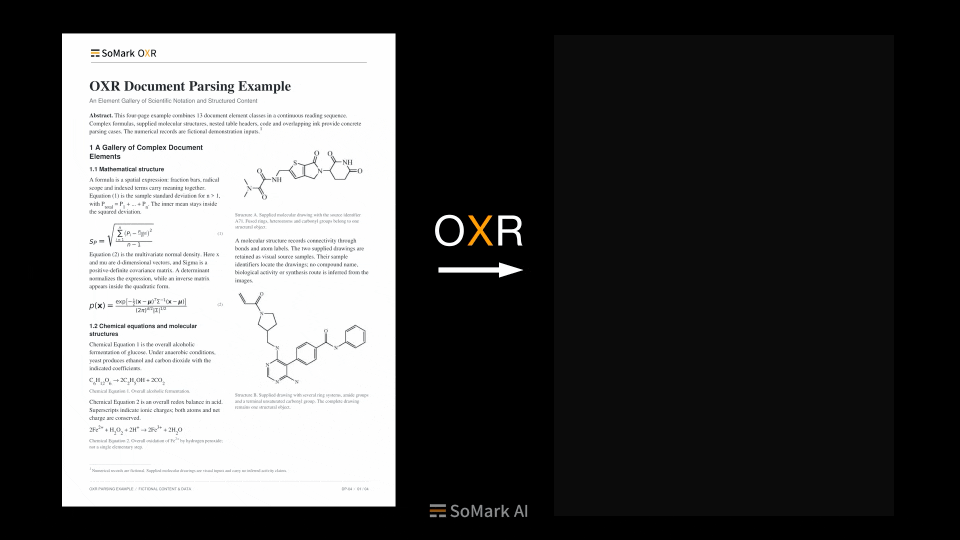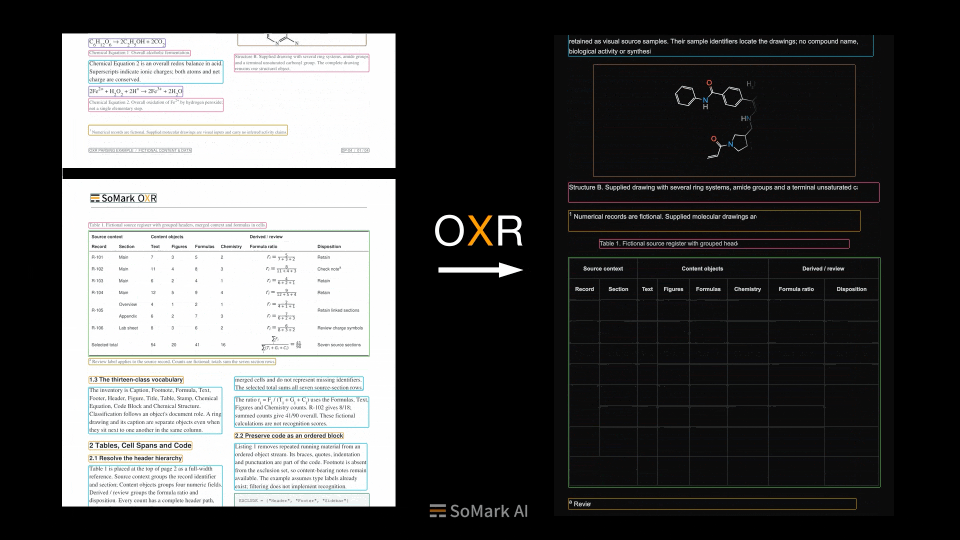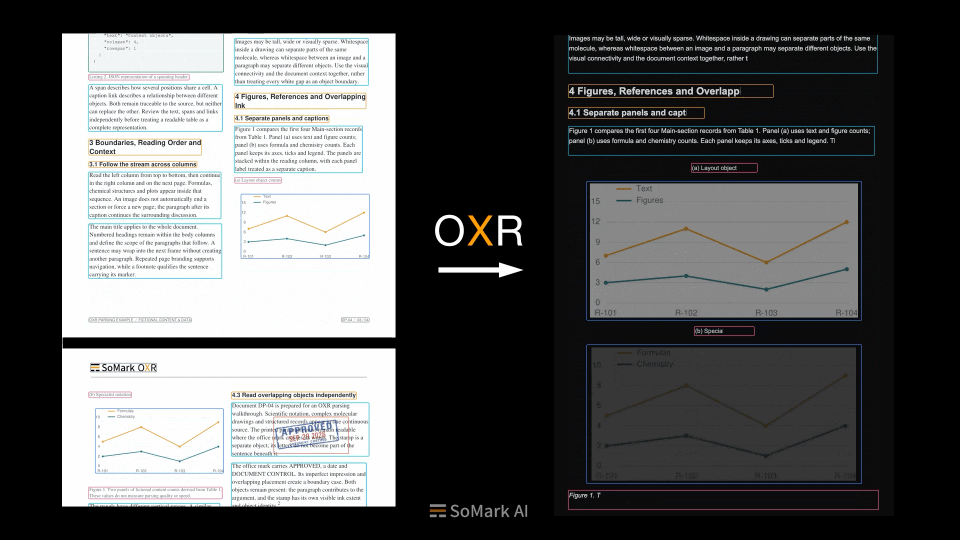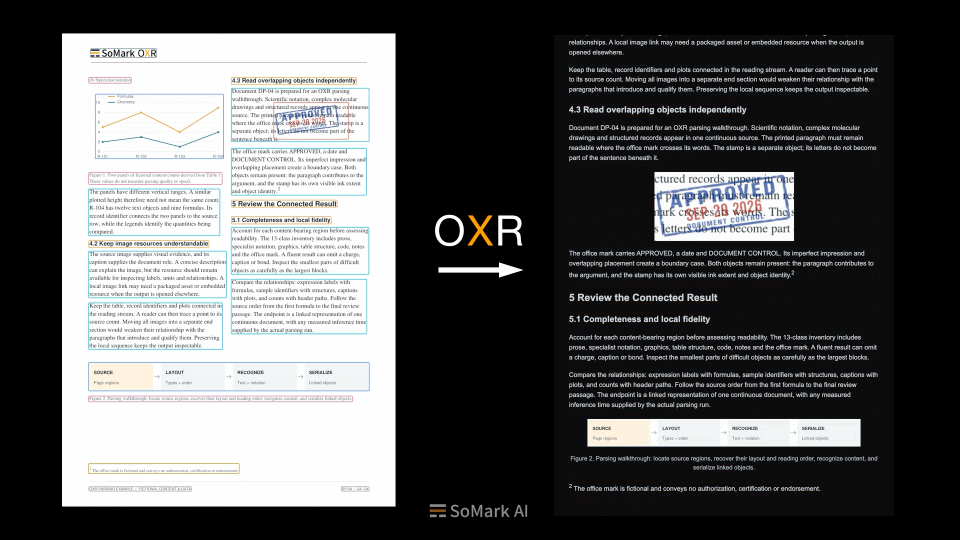
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
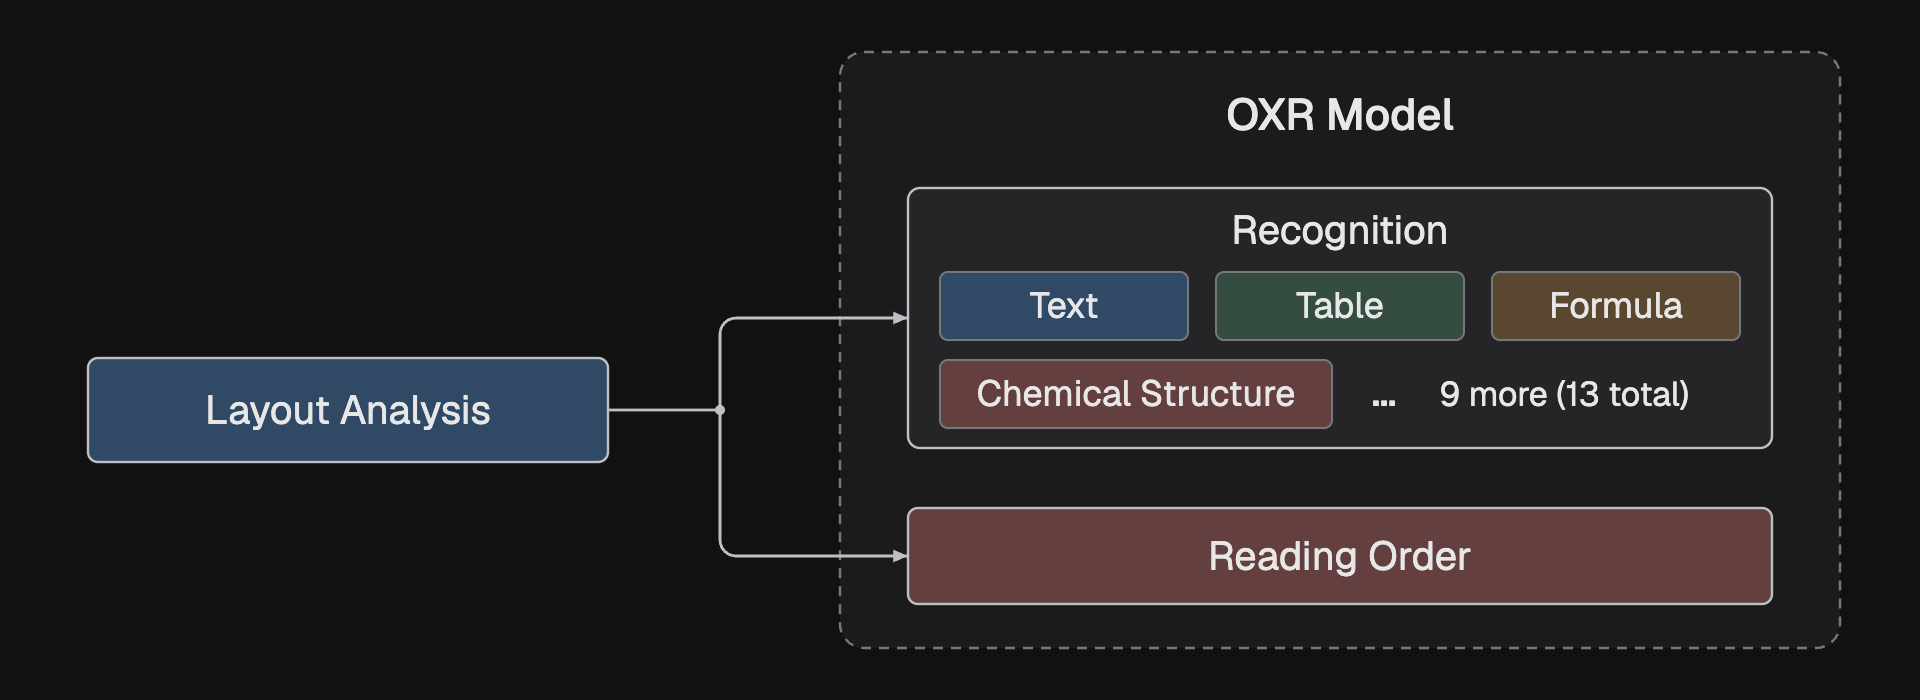
|
|
|
|
|
|
|
|
|
|
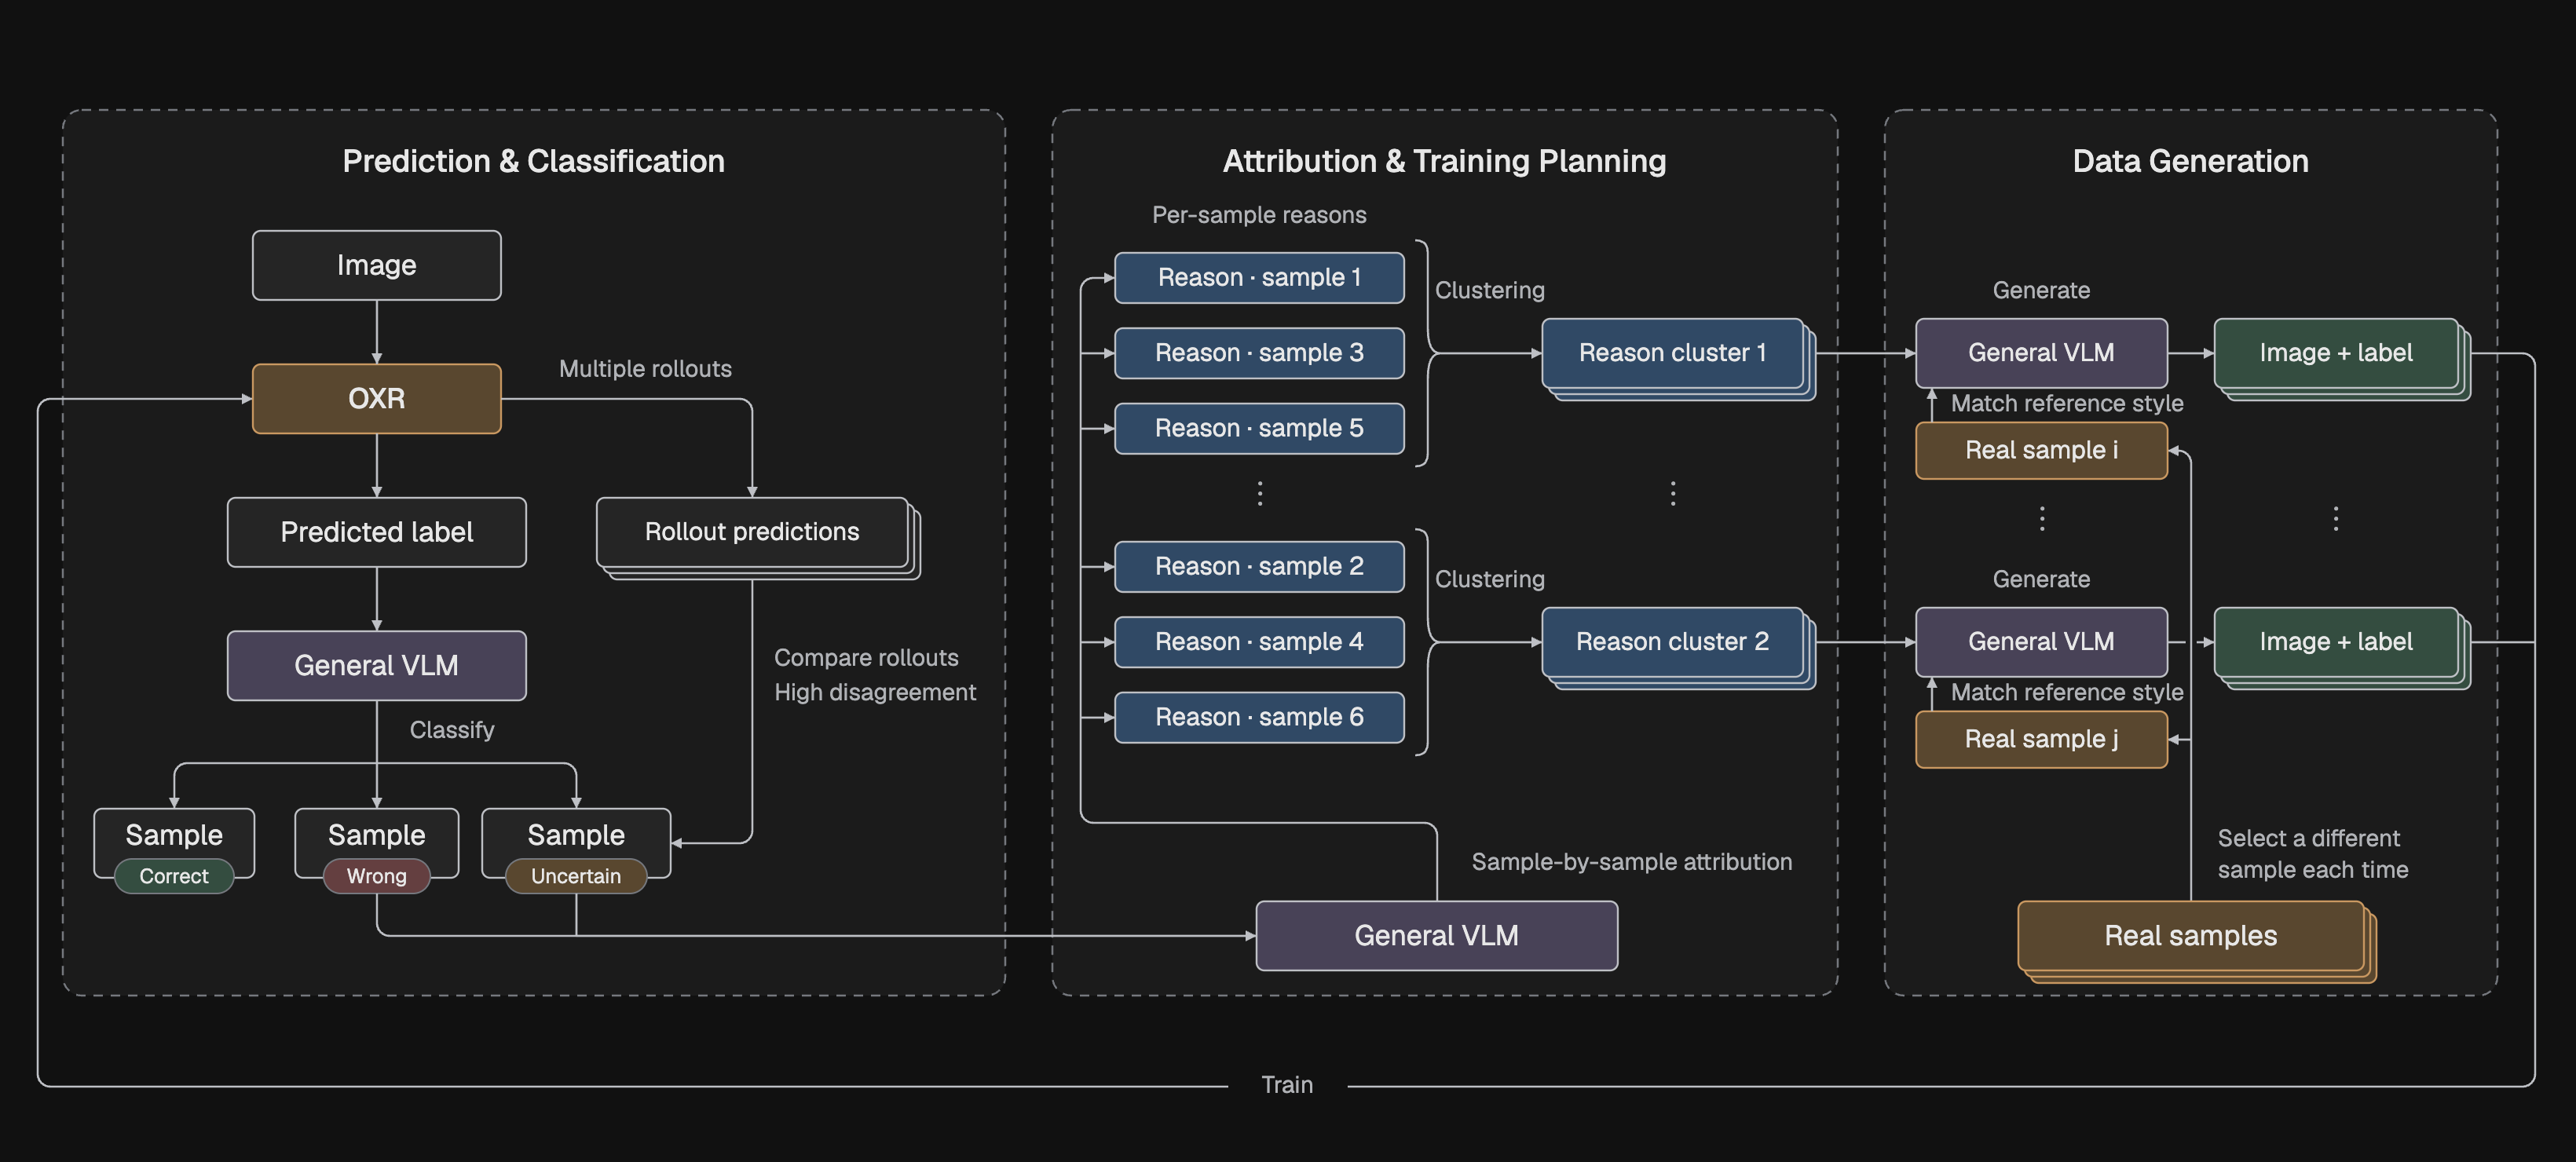
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
- dataset:
|
| 2 |
+
id: allenai/olmOCR-bench
|
| 3 |
+
task_id: overall
|
| 4 |
+
value: 87.84
|
| 5 |
+
|
| 6 |
+
- dataset:
|
| 7 |
+
id: allenai/olmOCR-bench
|
| 8 |
+
task_id: arxiv_math
|
| 9 |
+
value: 92.76
|
| 10 |
+
|
| 11 |
+
- dataset:
|
| 12 |
+
id: allenai/olmOCR-bench
|
| 13 |
+
task_id: baseline
|
| 14 |
+
value: 97.35
|
| 15 |
+
|
| 16 |
+
- dataset:
|
| 17 |
+
id: allenai/olmOCR-bench
|
| 18 |
+
task_id: headers_footers
|
| 19 |
+
value: 94.34
|
| 20 |
+
|
| 21 |
+
- dataset:
|
| 22 |
+
id: allenai/olmOCR-bench
|
| 23 |
+
task_id: long_tiny_text
|
| 24 |
+
value: 90.95
|
| 25 |
+
|
| 26 |
+
- dataset:
|
| 27 |
+
id: allenai/olmOCR-bench
|
| 28 |
+
task_id: multi_column
|
| 29 |
+
value: 85.18
|
| 30 |
+
|
| 31 |
+
- dataset:
|
| 32 |
+
id: allenai/olmOCR-bench
|
| 33 |
+
task_id: old_scans
|
| 34 |
+
value: 59.32
|
| 35 |
+
|
| 36 |
+
- dataset:
|
| 37 |
+
id: allenai/olmOCR-bench
|
| 38 |
+
task_id: old_scans_math
|
| 39 |
+
value: 89.74
|
| 40 |
+
|
| 41 |
+
- dataset:
|
| 42 |
+
id: allenai/olmOCR-bench
|
| 43 |
+
task_id: table_tests
|
| 44 |
+
value: 93.05
|
.gitattributes
ADDED
|
@@ -0,0 +1,3 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
*.safetensors filter=lfs diff=lfs merge=lfs -text
|
| 2 |
+
*.pth filter=lfs diff=lfs merge=lfs -text
|
| 3 |
+
tokenizer.json filter=lfs diff=lfs merge=lfs -text
|
.gitignore
ADDED
|
@@ -0,0 +1,44 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
# Ignore non-release weights; release checkpoints are tracked with Git LFS.
|
| 2 |
+
*.safetensors
|
| 3 |
+
*.bin
|
| 4 |
+
*.pt
|
| 5 |
+
*.pth
|
| 6 |
+
*.ckpt
|
| 7 |
+
*.gguf
|
| 8 |
+
*.onnx
|
| 9 |
+
|
| 10 |
+
# Weight index — references .safetensors, meaningless without them
|
| 11 |
+
model.safetensors.index.json
|
| 12 |
+
|
| 13 |
+
!model.safetensors
|
| 14 |
+
!layout_analysis/last.pth
|
| 15 |
+
|
| 16 |
+
# Training artifacts (not part of the modeling spec)
|
| 17 |
+
trainer_state.json
|
| 18 |
+
training_args.bin
|
| 19 |
+
zero_to_fp32.py
|
| 20 |
+
optimizer.pt
|
| 21 |
+
scheduler.pt
|
| 22 |
+
rng_state.pth
|
| 23 |
+
|
| 24 |
+
# Misc
|
| 25 |
+
*.bak
|
| 26 |
+
.DS_Store
|
| 27 |
+
__pycache__/
|
| 28 |
+
*.pyc
|
| 29 |
+
*.egg-info/
|
| 30 |
+
build/
|
| 31 |
+
dist/
|
| 32 |
+
.pytest_cache/
|
| 33 |
+
.venv/
|
| 34 |
+
|
| 35 |
+
# Local coding-assistant instructions are not model-release assets.
|
| 36 |
+
[Aa][Gg][Ee][Nn][Tt][Ss].md
|
| 37 |
+
[Aa][Gg][Ee][Nn][Tt][Ss].override.md
|
| 38 |
+
[Cc][Ll][Aa][Uu][Dd][Ee].md
|
| 39 |
+
[Gg][Ee][Mm][Ii][Nn][Ii].md
|
| 40 |
+
copilot-instructions.md
|
| 41 |
+
.claude/
|
| 42 |
+
.codex/
|
| 43 |
+
.agents/
|
| 44 |
+
.cursor/
|
LICENSE
ADDED
|
@@ -0,0 +1,140 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
# OXR License
|
| 2 |
+
|
| 3 |
+
Copyright (c) 2026 SoMark Team
|
| 4 |
+
|
| 5 |
+
OXR is licensed under the Apache License, Version 2.0, subject to the
|
| 6 |
+
additional terms below. These additional terms take precedence in the event
|
| 7 |
+
of a conflict; otherwise, Apache License 2.0 applies.
|
| 8 |
+
|
| 9 |
+
## 1. Commercial License and Thresholds
|
| 10 |
+
|
| 11 |
+
Commercial use of OXR and its Derivative Works is permitted without a
|
| 12 |
+
separate commercial license only while you and your Affiliates, on a
|
| 13 |
+
consolidated basis, do not exceed either of the following thresholds:
|
| 14 |
+
|
| 15 |
+
(a) USD 2,000,000 in Total Funding; or
|
| 16 |
+
(b) USD 2,000,000 in Annual Revenue.
|
| 17 |
+
|
| 18 |
+
If either threshold is exceeded, you must obtain a separate commercial
|
| 19 |
+
license from SoMark Team before commencing or continuing commercial use.
|
| 20 |
+
Being below these thresholds does not waive any other term of this License,
|
| 21 |
+
including the competing hosted API restriction in Section 3.
|
| 22 |
+
|
| 23 |
+
## 2. Online Service Attribution
|
| 24 |
+
|
| 25 |
+
When providing an online service to third parties using OXR or its Derivative
|
| 26 |
+
Works, you must prominently identify SoMark OXR in the service's user interface or
|
| 27 |
+
publicly accessible documentation.
|
| 28 |
+
|
| 29 |
+
## 3. Competing Hosted API Services
|
| 30 |
+
|
| 31 |
+
Unless expressly authorized in advance by a separate written license from
|
| 32 |
+
SoMark Team, you may not use OXR or its Derivative Works to offer, operate,
|
| 33 |
+
or make available to third parties a hosted API service that competes with
|
| 34 |
+
a hosted API service offered by SoMark Team or its Affiliates.
|
| 35 |
+
|
| 36 |
+
This restriction includes services offered through a reseller, a white-label
|
| 37 |
+
arrangement, or an intermediary interface, whether paid or free. A competing
|
| 38 |
+
hosted API service is one whose principal functionality provides document
|
| 39 |
+
parsing, optical character recognition (OCR), document layout analysis, or
|
| 40 |
+
document content extraction as a substitute for substantially similar
|
| 41 |
+
functionality of a hosted API service offered by SoMark Team or its Affiliates.
|
| 42 |
+
|
| 43 |
+
This restriction applies regardless of Total Funding or Annual Revenue.
|
| 44 |
+
Use solely within your organization and its Affiliates, without offering such
|
| 45 |
+
a service to third parties, is not prohibited by this Section; all other
|
| 46 |
+
terms of this License still apply.
|
| 47 |
+
|
| 48 |
+
## 4. Termination
|
| 49 |
+
|
| 50 |
+
Your rights under this License terminate automatically, without notice from
|
| 51 |
+
SoMark Team, if you fail to obtain a commercial license as required by
|
| 52 |
+
Section 1, fail to comply with Section 2, or violate Section 3.
|
| 53 |
+
|
| 54 |
+
## 5. Definitions and Scope
|
| 55 |
+
|
| 56 |
+
"Affiliates" are entities that directly or indirectly control you, are
|
| 57 |
+
controlled by you, or share common control with you. "Control" means the
|
| 58 |
+
power to direct an entity's management or operations through ownership,
|
| 59 |
+
voting rights, contractual rights, or other means.
|
| 60 |
+
|
| 61 |
+
"Total Funding" means cumulative equity and debt financing raised from all
|
| 62 |
+
sources by you and your Affiliates, on a consolidated basis, excluding
|
| 63 |
+
intra-group transactions to avoid double counting.
|
| 64 |
+
|
| 65 |
+
"Annual Revenue" means the gross revenue of you and your Affiliates for the
|
| 66 |
+
most recently completed fiscal year, on a consolidated basis, excluding
|
| 67 |
+
intra-group transactions to avoid double counting. Amounts in other
|
| 68 |
+
currencies are measured at their US dollar equivalent.
|
| 69 |
+
|
| 70 |
+
"Derivative Works" has the meaning given in Apache License 2.0. When
|
| 71 |
+
redistributing OXR or its Derivative Works, you must include these additional
|
| 72 |
+
terms together with Apache License 2.0. Third-party components separately
|
| 73 |
+
identified as being under other licenses remain governed by those licenses.
|
| 74 |
+
|
| 75 |
+
The full text of Apache License 2.0 is available at
|
| 76 |
+
https://www.apache.org/licenses/LICENSE-2.0 .
|
| 77 |
+
|
| 78 |
+
---
|
| 79 |
+
|
| 80 |
+
# OXR 许可协议
|
| 81 |
+
|
| 82 |
+
版权所有 (c) 2026 SoMark Team
|
| 83 |
+
|
| 84 |
+
OXR 依据 Apache License 2.0 进行许可,同时受下列附加条款约束。若存在冲突,
|
| 85 |
+
以本附加条款为准;其他事项适用 Apache License 2.0。
|
| 86 |
+
|
| 87 |
+
## 1. 商业许可与门槛
|
| 88 |
+
|
| 89 |
+
仅当您及您的关联方按合并口径计算,均未超过以下任一门槛时,方可无需另行
|
| 90 |
+
取得商业许可而将 OXR 及其衍生作品用于商业用途:
|
| 91 |
+
|
| 92 |
+
(a) 累计融资总额 2,000,000 美元;或
|
| 93 |
+
(b) 年度总收入 2,000,000 美元。
|
| 94 |
+
|
| 95 |
+
一旦超过任一门槛,您必须在开始或继续商业使用之前,从 SoMark Team 取得
|
| 96 |
+
单独的商业许可。未超过上述门槛并不免除本许可中的其他义务,包括第 3 条
|
| 97 |
+
关于竞争性托管 API 服务的限制。
|
| 98 |
+
|
| 99 |
+
## 2. 在线服务标识义务
|
| 100 |
+
|
| 101 |
+
如果您使用 OXR 或其衍生作品向第三方提供在线服务,必须在该服务的用户界面
|
| 102 |
+
或公开可访问的文档中,显著标明使用了 SoMark OXR。
|
| 103 |
+
|
| 104 |
+
## 3. 竞争性托管 API 服务限制
|
| 105 |
+
|
| 106 |
+
除非事先通过与 SoMark Team 签订单独的书面许可取得明确授权,否则您不得
|
| 107 |
+
使用 OXR 或其衍生作品,向第三方提供、运营或开放与 SoMark Team 或其关联方
|
| 108 |
+
所提供的托管 API 服务构成竞争的托管 API 服务。
|
| 109 |
+
|
| 110 |
+
本限制包括通过转售、白标或中间接口提供的服务,无论收费或免费。竞争性
|
| 111 |
+
托管 API 服务,是指以文档解析、光学字符识别(OCR)、文档版面分析或文档
|
| 112 |
+
内容提取为主要功能,并能够替代 SoMark Team 或其关联方提供的托管 API
|
| 113 |
+
服务中实质相似功能的服务。
|
| 114 |
+
|
| 115 |
+
本限制不受累计融资总额或年度总收入门槛影响。仅在您所属组织及其关联方内部
|
| 116 |
+
使用,且不向第三方提供上述服务的,不属于本条禁止的行为;本许可的其他
|
| 117 |
+
条款仍然适用。
|
| 118 |
+
|
| 119 |
+
## 4. 许可终止
|
| 120 |
+
|
| 121 |
+
如果您未按第 1 条要求取得商业许可、未遵守第 2 条标识义务,或违反第 3 条,
|
| 122 |
+
您在本许可项下的权利将自动终止,SoMark Team 无须另行通知。
|
| 123 |
+
|
| 124 |
+
## 5. 定义与适用范围
|
| 125 |
+
|
| 126 |
+
“关联方”是指直接或间接控制您、受您控制,或与您处于共同控制之下的实体。
|
| 127 |
+
“控制”是指通过所有权、表决权、合同权利或其他方式,决定某一实体管理或
|
| 128 |
+
经营事项的能力。
|
| 129 |
+
|
| 130 |
+
“累计融资总额”是指您及您的关联方按合并口径计算,从所有来源累计取得的
|
| 131 |
+
股权融资和债务融资总额,剔除集团内部交易以避免重复计算。
|
| 132 |
+
|
| 133 |
+
“年度总收入”是指您及您的关联方最近一个已结束财年的总收入,按合并口径
|
| 134 |
+
计算,并剔除集团内部交易以避免重复计算。其他币种金额按其等值美元计算。
|
| 135 |
+
|
| 136 |
+
“衍生作品”的含义与 Apache License 2.0 中的定义一致。再分发 OXR 或其
|
| 137 |
+
衍生作品时,必须同时附上本附加条款和 Apache License 2.0。单独标明适用
|
| 138 |
+
其他许可的第三方组件,仍受各自许可约束。
|
| 139 |
+
|
| 140 |
+
Apache License 2.0 全文见:https://www.apache.org/licenses/LICENSE-2.0 。
|
README.md
ADDED
|
@@ -0,0 +1,350 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
---
|
| 2 |
+
tags:
|
| 3 |
+
- document-parsing
|
| 4 |
+
- ocr
|
| 5 |
+
---
|
| 6 |
+
|
| 7 |
+
<div align="center">
|
| 8 |
+
|
| 9 |
+
<img src="https://raw.githubusercontent.com/SoMarkAI/image_bed/main/OXR_README/assets/header.png" alt="" />
|
| 10 |
+
|
| 11 |
+
<h1>SoMark|O<span style="color: #DE7802;">X</span>R</h1>
|
| 12 |
+
|
| 13 |
+
An open-source document parsing model with SOTA accuracy and speed, using an RSI loop during post-training.
|
| 14 |
+
|
| 15 |
+
---
|
| 16 |
+
|
| 17 |
+
**Turn documents into Agent-Friendly data.**
|
| 18 |
+
|
| 19 |
+
[🌐 Online Demo](https://free-oxr.somark.ai) | [🔥 🆓 Free API](#free-api)
|
| 20 |
+
|
| 21 |
+
[](https://github.com/SoMarkAI/OXR) [](https://huggingface.co/SoMarkAI/OXR-1.0) [](https://modelscope.cn/models/SoMark/OXR-1.0)
|
| 22 |
+
|
| 23 |
+
|
| 24 |
+
**English** · [简体中文](https://github.com/SoMarkAI/OXR/blob/main/README_CN.md)
|
| 25 |
+
|
| 26 |
+
</div>
|
| 27 |
+
|
| 28 |
+
OXR (Optical Everything Recognition) is an open-source model from the SoMark team. It turns PDFs and document images into Agent-Friendly data in Markdown or JSON, with layout coordinates included.
|
| 29 |
+
|
| 30 |
+
Pretrained from scratch, OXR uses a recursive self-improvement (RSI) loop during post-training—a first in document parsing. With just 1.3B parameters, OXR ranks #1 on olmOCR-Bench, OmniDocBench, and DocParsingBench while delivering industry-leading parsing speed.
|
| 31 |
+
|
| 32 |
+
OXR is the first to make its layout analysis module independent and pluggable. This design accelerates parsing and supports replacing the built-in layout model with a custom one. OXR continues to handle content recognition and reading order, enabling adaptation across diverse scenarios with minimal integration effort.
|
| 33 |
+
|
| 34 |
+
|
| 35 |
+
|
| 36 |
+
|
| 37 |
+
|
| 38 |
+
---
|
| 39 |
+
|
| 40 |
+
> If this project helps you, please click ⭐ Star in the top-right corner to support us. It's the best encouragement you can give the developers!
|
| 41 |
+
|
| 42 |
+
|
| 43 |
+
|
| 44 |
+
## Why OXR?
|
| 45 |
+
|
| 46 |
+
- 🎯 SOTA Accuracy. #1 Across Three Benchmarks.
|
| 47 |
+
|
| 48 |
+
- OXR ranks 🏆#1 on olmOCR-Bench, OmniDocBench, and DocParsingBench, with a particularly wide lead in table parsing.
|
| 49 |
+
- OXR can recognize 13 document element types, from formulas and tables to chemical equations, chemical structures, and code blocks, with bounding box coordinates included. It also performs well on challenging documents and layouts, including A3 exam papers, newspapers, vertical text, and handwriting.
|
| 50 |
+
- See [docs/benchmark.md](https://github.com/SoMarkAI/OXR/blob/main/docs/benchmark.md) for the full results and instructions to reproduce the evaluations.
|
| 51 |
+
- 🚀 1.3B Parameters. Top-Tier Parsing Speed.
|
| 52 |
+
|
| 53 |
+
- With only 1.3B parameters, OXR ranks 🏆#1 among open-source document parsing models in speed tests on the RTX PRO 6000.
|
| 54 |
+
- OXR redesign its processing architecture at the task level to improve parsing speed while maintaining accuracy.
|
| 55 |
+
- See [docs/benchmark.md](https://github.com/SoMarkAI/OXR/blob/main/docs/benchmark.md) for the full results and instructions to reproduce the evaluations.
|
| 56 |
+
- 🧩 Pluggable Layout Analysis. Document Structure on Your Terms.
|
| 57 |
+
|
| 58 |
+
- Layout analysis requirements vary widely across domains. Even for the same document, element types, region boundaries, and grouping rules can differ depending on the business use case.
|
| 59 |
+
- OXR is the first to make layout analysis independent and pluggable. Its built-in layout model can be replaced while retaining OXR’s recognition and reading order capabilities, enabling adaptation across document scenarios with minimal integration effort.
|
| 60 |
+
- See the [How it works](#how-to-works) section below for details.
|
| 61 |
+
|
| 62 |
+
|
| 63 |
+
<details>
|
| 64 |
+
<summary>Expand to see all 13 element types</summary>
|
| 65 |
+
|
| 66 |
+
| Name | JSON type value | Content or output format |
|
| 67 |
+
|-|-|-|
|
| 68 |
+
| Caption | Caption | Plain text |
|
| 69 |
+
| Footnote | Footnote | Plain text |
|
| 70 |
+
| Formula | Formula | LaTeX |
|
| 71 |
+
| Text | Text | Plain text |
|
| 72 |
+
| Footer | Page-footer | Plain text (filtered out by default) |
|
| 73 |
+
| Header | Page-header | Plain text (filtered out by default) |
|
| 74 |
+
| Figure | Picture | Image |
|
| 75 |
+
| Title | Title | Plain text |
|
| 76 |
+
| Table | Table | HTML / Markdown |
|
| 77 |
+
| Stamp | Stamp | Plain text / Image |
|
| 78 |
+
| Chemical Equation | Chemical Equation | LaTeX (starting with \ce, using mhchem syntax) |
|
| 79 |
+
| Code Block | Code Block | Markdown code block |
|
| 80 |
+
| Chemical Structure | Chemical Structure | SMILES / Image |
|
| 81 |
+
|
| 82 |
+
|
| 83 |
+
</details>
|
| 84 |
+
|
| 85 |
+
|
| 86 |
+
## Parsing Examples
|
| 87 |
+
|
| 88 |
+
The animation shows OXR's parsing process.
|
| 89 |
+
|
| 90 |
+
|
| 91 |
+
|
| 92 |
+
The examples below show OXR parsing different document types. Click an image to view the original.
|
| 93 |
+
|
| 94 |
+
<table>
|
| 95 |
+
<tr>
|
| 96 |
+
<td align="center" valign="top"><strong>A3 Exam Paper</strong><br/><a href="https://raw.githubusercontent.com/SoMarkAI/image_bed/main/OXR_README/assets/parsing_examples/a3_exam_paper.png"><img src="https://raw.githubusercontent.com/SoMarkAI/image_bed/main/OXR_README/assets/parsing_examples/a3_exam_paper.png" alt="A3 Exam Paper" width="280" /></a></td>
|
| 97 |
+
<td align="center" valign="top"><strong>Chinese Handwriting</strong><br/><a href="https://raw.githubusercontent.com/SoMarkAI/image_bed/main/OXR_README/assets/parsing_examples/chinese_handwriting.png"><img src="https://raw.githubusercontent.com/SoMarkAI/image_bed/main/OXR_README/assets/parsing_examples/chinese_handwriting.png" alt="Chinese Handwriting" width="280" /></a></td>
|
| 98 |
+
<td align="center" valign="top"><strong>Code Block</strong><br/><a href="https://raw.githubusercontent.com/SoMarkAI/image_bed/main/OXR_README/assets/parsing_examples/code_block.png"><img src="https://raw.githubusercontent.com/SoMarkAI/image_bed/main/OXR_README/assets/parsing_examples/code_block.png" alt="Code Block" width="280" /></a></td>
|
| 99 |
+
</tr>
|
| 100 |
+
<tr>
|
| 101 |
+
<td align="center" valign="top"><strong>Chemical Equation</strong><br/><a href="https://raw.githubusercontent.com/SoMarkAI/image_bed/main/OXR_README/assets/parsing_examples/chemical_equation.png"><img src="https://raw.githubusercontent.com/SoMarkAI/image_bed/main/OXR_README/assets/parsing_examples/chemical_equation.png" alt="Chemical Equation" width="280" /></a></td>
|
| 102 |
+
<td align="center" valign="top"><strong>Chemical Structure</strong><br/><a href="https://raw.githubusercontent.com/SoMarkAI/image_bed/main/OXR_README/assets/parsing_examples/chemical_structure.png"><img src="https://raw.githubusercontent.com/SoMarkAI/image_bed/main/OXR_README/assets/parsing_examples/chemical_structure.png" alt="Chemical Structure" width="280" /></a></td>
|
| 103 |
+
<td align="center" valign="top"><strong>Complex Formula</strong><br/><a href="https://raw.githubusercontent.com/SoMarkAI/image_bed/main/OXR_README/assets/parsing_examples/complex_formula.png"><img src="https://raw.githubusercontent.com/SoMarkAI/image_bed/main/OXR_README/assets/parsing_examples/complex_formula.png" alt="Complex Formula" width="280" /></a></td>
|
| 104 |
+
</tr>
|
| 105 |
+
<tr>
|
| 106 |
+
<td align="center" valign="top"><strong>Complex Table</strong><br/><a href="https://raw.githubusercontent.com/SoMarkAI/image_bed/main/OXR_README/assets/parsing_examples/complex_table.png"><img src="https://raw.githubusercontent.com/SoMarkAI/image_bed/main/OXR_README/assets/parsing_examples/complex_table.png" alt="Complex Table" width="280" /></a></td>
|
| 107 |
+
<td align="center" valign="top"><strong>Academic Paper</strong><br/><a href="https://raw.githubusercontent.com/SoMarkAI/image_bed/main/OXR_README/assets/parsing_examples/academic_paper.png"><img src="https://raw.githubusercontent.com/SoMarkAI/image_bed/main/OXR_README/assets/parsing_examples/academic_paper.png" alt="Academic Paper" width="280" /></a></td>
|
| 108 |
+
<td align="center" valign="top"><strong>Newspaper</strong><br/><a href="https://raw.githubusercontent.com/SoMarkAI/image_bed/main/OXR_README/assets/parsing_examples/newspaper.png"><img src="https://raw.githubusercontent.com/SoMarkAI/image_bed/main/OXR_README/assets/parsing_examples/newspaper.png" alt="Newspaper" width="280" /></a></td>
|
| 109 |
+
</tr>
|
| 110 |
+
<tr>
|
| 111 |
+
<td align="center" valign="top"><strong>Research Report</strong><br/><a href="https://raw.githubusercontent.com/SoMarkAI/image_bed/main/OXR_README/assets/parsing_examples/research_report.png"><img src="https://raw.githubusercontent.com/SoMarkAI/image_bed/main/OXR_README/assets/parsing_examples/research_report.png" alt="Research Report" width="280" /></a></td>
|
| 112 |
+
<td align="center" valign="top"><strong>Resume</strong><br/><a href="https://raw.githubusercontent.com/SoMarkAI/image_bed/main/OXR_README/assets/parsing_examples/resume.png"><img src="https://raw.githubusercontent.com/SoMarkAI/image_bed/main/OXR_README/assets/parsing_examples/resume.png" alt="Resume" width="280" /></a></td>
|
| 113 |
+
<td align="center" valign="top"><strong>English Handwriting</strong><br/><a href="https://raw.githubusercontent.com/SoMarkAI/image_bed/main/OXR_README/assets/parsing_examples/english_handwriting.png"><img src="https://raw.githubusercontent.com/SoMarkAI/image_bed/main/OXR_README/assets/parsing_examples/english_handwriting.png" alt="English Handwriting" width="280" /></a></td>
|
| 114 |
+
</tr>
|
| 115 |
+
</table>
|
| 116 |
+
|
| 117 |
+
## How it works
|
| 118 |
+
|
| 119 |
+
<a id="how-to-works"></a>
|
| 120 |
+
|
| 121 |
+
### Technical Architecture
|
| 122 |
+
|
| 123 |
+
The system consists of two models: a Layout Analysis model and OXR. We integrate Reading Order into the Recognition stage, with both tasks handled by the same model. This design improves both speed and accuracy.
|
| 124 |
+
|
| 125 |
+
We also designed the system this way to make customization easier. We have found that Layout Analysis varies more across document domains than any other module, and it is typically the part that document parsing providers need to customize most. Existing document parsing tools either assign it to the Recognition model or use a dedicated model that also handles Reading Order. OXR's design achieves the simplest access method for Layout Analysis, and any Layout Analysis model can work well with the OXR model.
|
| 126 |
+
|
| 127 |
+
|
| 128 |
+
|
| 129 |
+
|
| 130 |
+
|
| 131 |
+
### Improvement Through the RSI Loop
|
| 132 |
+
|
| 133 |
+
For a task like document parsing, where ground-truth answers exist, we have long wanted an engineering system that helps the core model improve itself. The diagram below shows OXR's RSI approach. It targets samples the model gets wrong or handles weakly, improving performance without human annotation. This has made our iteration faster than ever.
|
| 134 |
+
|
| 135 |
+
|
| 136 |
+
|
| 137 |
+
|
| 138 |
+
|
| 139 |
+
## Quick Start
|
| 140 |
+
|
| 141 |
+
<a id="free-api"></a>
|
| 142 |
+
|
| 143 |
+
### 0. 🔥 🆓 Free API
|
| 144 |
+
|
| 145 |
+
OXR provides a free API so you can test parsing on your own documents without registering or requesting an API key.
|
| 146 |
+
|
| 147 |
+
We'll keep the free API online until we can no longer afford to run it.
|
| 148 |
+
|
| 149 |
+
⚠️ Note: We do not recommend using the Free OXR API in production. We do not guarantee service stability, and requests are queued, so processing speed may vary slightly.
|
| 150 |
+
|
| 151 |
+
| Online Demo | https://free-oxr.somark.ai | https://free-oxr.somark.cn |
|
| 152 |
+
|-|-|-|
|
| 153 |
+
| API URL | https://free-oxr.somark.ai/api/v1 | https://free-oxr.somark.cn/api/v1 |
|
| 154 |
+
| API documentation | [https://docs.somark.ai/api-reference](https://docs.somark.ai/api-reference) | https://docs.somark.cn/api-reference |
|
| 155 |
+
|
| 156 |
+
> somark.cn is a mirror of somark.ai. Choose the domain that works best for your region.
|
| 157 |
+
|
| 158 |
+
OXR's document parsing API is compatible with SoMark's official document parsing API. You can use SoMark's official document parsing CLI tools, somark-py and somark-js, by changing the **Base URL**. See Section 1.4 for supported endpoints and output formats.
|
| 159 |
+
|
| 160 |
+
```Bash
|
| 161 |
+
# using python
|
| 162 |
+
pip install somark
|
| 163 |
+
# or using js
|
| 164 |
+
npm install -g somark-js
|
| 165 |
+
|
| 166 |
+
somark --base-url https://free-oxr.somark.ai/api/v1 --api-key dummy \
|
| 167 |
+
parse document.pdf --formats md,json --out ./parsed-output/
|
| 168 |
+
```
|
| 169 |
+
|
| 170 |
+
|
| 171 |
+
|
| 172 |
+
### 1. Run Locally
|
| 173 |
+
|
| 174 |
+
```Plain Text
|
| 175 |
+
Operating system: Linux
|
| 176 |
+
GPU: NVIDIA (with BF16 support)
|
| 177 |
+
Driver: NVIDIA driver (compatible with CUDA 13.0)
|
| 178 |
+
Python: 3.12 (for model downloads / running from source)
|
| 179 |
+
GPU memory to get started: 24GB on a single GPU (for low-concurrency testing)
|
| 180 |
+
Recommended GPU memory: ≥48GB on a single GPU (for long documents / higher concurrency)
|
| 181 |
+
```
|
| 182 |
+
|
| 183 |
+
#### 1.1 Download the Code and Models
|
| 184 |
+
|
| 185 |
+
| Model | Download links | Precision | Includes a lightweight layout analysis model? |
|
| 186 |
+
|-|-|-|-|
|
| 187 |
+
| OXR-1.0 | [🤗 Hugging Face ](https://huggingface.co/SoMarkAI/OXR-1.0) <br/>[🤖 ModelScope](https://modelscope.cn/models/SoMark/OXR-1.0) | BF16 | Yes, in the layout_analysis folder |
|
| 188 |
+
|
| 189 |
+
First, get the code and prepare the environment for downloading the models:
|
| 190 |
+
|
| 191 |
+
```Bash
|
| 192 |
+
git clone https://github.com/SoMarkAI/OXR.git
|
| 193 |
+
cd OXR
|
| 194 |
+
|
| 195 |
+
# pip install -U huggingface_hub
|
| 196 |
+
hf download SoMarkAI/OXR-1.0 --local-dir ./models/OXR-1.0
|
| 197 |
+
|
| 198 |
+
# or using ModelScope
|
| 199 |
+
# pip install -U modelscope-hub
|
| 200 |
+
modelscope download SoMark/OXR-1.0 --local_dir ./models/OXR-1.0
|
| 201 |
+
```
|
| 202 |
+
|
| 203 |
+
#### 1.2 Start the Services
|
| 204 |
+
|
| 205 |
+
##### 1.2.1 Run with Docker (Recommended)
|
| 206 |
+
|
| 207 |
+
We recommend Docker to configure and start all services together.
|
| 208 |
+
|
| 209 |
+
```Bash
|
| 210 |
+
docker build -f docker/Dockerfile.allinone -t oxr-1.0 .
|
| 211 |
+
docker run --rm --gpus all --ipc=host \
|
| 212 |
+
-p 127.0.0.1:8000:8000 \
|
| 213 |
+
-v "$PWD/models/OXR-1.0:/models/oxr-model:ro" \
|
| 214 |
+
oxr-1.0
|
| 215 |
+
```
|
| 216 |
+
|
| 217 |
+
Once the startup logs show that the services are ready, open http://localhost:8000/demo or http://localhost:8000/docs.
|
| 218 |
+
The first startup may take longer. The default startup timeout is 900 seconds.
|
| 219 |
+
See How to use OXR for more advanced options and usage examples.
|
| 220 |
+
|
| 221 |
+
|
| 222 |
+
##### 1.2.2 Run from Source
|
| 223 |
+
|
| 224 |
+
After downloading the code and models, start the following three services separately. Each service uses its own process and virtual environment. Run all commands from the OXR repository root. The document parsing API depends on both the OXR model service and the Layout Analysis model service, so start the two model APIs first.
|
| 225 |
+
|
| 226 |
+
**OXR Model Service (Port 8080)**
|
| 227 |
+
|
| 228 |
+
OXR supports vLLM, but the official vLLM release does not yet support OXR inference. We provide an out-of-tree plugin and a loading script in the model weights folder on Hugging Face. No recompilation is needed: you can use the plugin directly with the official vLLM Docker image or CLI.
|
| 229 |
+
|
| 230 |
+
```Bash
|
| 231 |
+
# pip install vllm==0.25.1 transformers==5.13.1
|
| 232 |
+
|
| 233 |
+
MODEL_PATH="$PWD/models/OXR-1.0" \
|
| 234 |
+
bash services/oxr/start_vllm.sh \
|
| 235 |
+
--gpu-memory-utilization 0.70 --max-num-seqs 16
|
| 236 |
+
```
|
| 237 |
+
|
| 238 |
+
**Layout Analysis Model Service (Port 8081)**
|
| 239 |
+
|
| 240 |
+
The Layout Analysis model weights are included in the OXR model weights folder downloaded earlier.
|
| 241 |
+
|
| 242 |
+
```Bash
|
| 243 |
+
# pip install torch==2.11.0 torchvision==0.26.0 --index-url https://download.pytorch.org/whl/cu130
|
| 244 |
+
# pip install -r services/layout_analyze/requirements.txt
|
| 245 |
+
|
| 246 |
+
MODEL_PATH="$PWD/models/OXR-1.0/layout_analysis/last.pth" \
|
| 247 |
+
DFINE_DEVICE=cuda \
|
| 248 |
+
python -m uvicorn dfine_la.api:app \
|
| 249 |
+
--app-dir services/layout_analyze \
|
| 250 |
+
--host 127.0.0.1 --port 8081 --workers 1
|
| 251 |
+
```
|
| 252 |
+
|
| 253 |
+
**Document Parsing API (Port 8000)**
|
| 254 |
+
|
| 255 |
+
Copy the provided `config.example.yaml` to `config.yaml`. Set the url fields under `layout_analyze_model` and `oxr_model` to the addresses of the two services you started above.
|
| 256 |
+
|
| 257 |
+
```Bash
|
| 258 |
+
# pip install -c docker/requirements.allinone.txt .
|
| 259 |
+
|
| 260 |
+
oxr serve --config config.yaml \
|
| 261 |
+
--host 127.0.0.1 --port 8000 --workers 1
|
| 262 |
+
```
|
| 263 |
+
|
| 264 |
+
Once all three services are running, use the demo and parsing API in the same way as with Docker. See Sections 1.3 and 1.4.
|
| 265 |
+
|
| 266 |
+
#### 1.3 Open the Visual Demo
|
| 267 |
+
|
| 268 |
+
Open http://localhost:8000/demo and upload a PDF or image. You can view the original file, Markdown preview, source, layout bounding boxes, and reading order, and download the Markdown.
|
| 269 |
+
|
| 270 |
+
The demo uses a temporary file cache that expires after 1 hour by default and is renewed during processing. Cached results become inaccessible once the cache expires or is cleared, so download your results promptly.
|
| 271 |
+
|
| 272 |
+
#### 1.4 Send a Parsing Request
|
| 273 |
+
|
| 274 |
+
OXR's API is compatible with the SoMark API. Although OXR does not support some specialized capabilities, SoMark's ecosystem fully supports deployed OXR services. Visit the [SoMark website](https://somark.ai) and refer to the [API documentation](https://docs.somark.ai/api-reference).
|
| 275 |
+
|
| 276 |
+
Call the parsing endpoint directly:
|
| 277 |
+
|
| 278 |
+
```Bash
|
| 279 |
+
curl --fail-with-body http://localhost:8000/v1/parse/sync \
|
| 280 |
+
-F 'file=@document.pdf' \
|
| 281 |
+
-F 'api_key=dummy' \
|
| 282 |
+
-F 'output_formats=markdown' \
|
| 283 |
+
-F 'output_formats=json'
|
| 284 |
+
```
|
| 285 |
+
|
| 286 |
+
SoMark provides a full set of CLI and SDK tools for document parsing in Python and JavaScript. OXR is compatible with their document parsing interfaces, so you can use them by changing the baseURL. For more information, see https://docs.somark.ai/en/cli-sdk.
|
| 287 |
+
|
| 288 |
+
```Bash
|
| 289 |
+
pip install somark
|
| 290 |
+
|
| 291 |
+
somark --base-url http://localhost:8000/v1 --api-key dummy \
|
| 292 |
+
parse document.pdf --formats md,json --out ./parsed-output/
|
| 293 |
+
```
|
| 294 |
+
|
| 295 |
+
## Ecosystem
|
| 296 |
+
|
| 297 |
+
The SoMark team has developed a range of tools for document parsing. If you find them helpful, please give them a ⭐ Star.
|
| 298 |
+
|
| 299 |
+
| | Description | Project URL |
|
| 300 |
+
|-|-|-|
|
| 301 |
+
| SoMarkDown | The official Markdown parsing and rendering library for SoMark and OXR | https://github.com/SoMarkAI/SoMarkDown |
|
| 302 |
+
| SoMarkDownViewer | A live editing application for SoMarkDown | https://github.com/SoMarkAI/SoMarkDownViewer |
|
| 303 |
+
| SoPDF | A high-performance PDF processing library with a permissive open-source license | https://github.com/SoMarkAI/SoPDF |
|
| 304 |
+
| Docision | MultiModal Jev for Document. | https://github.com/SoMarkAI/docision |
|
| 305 |
+
| somark-py | The official Python SDK & CLI for SoMark and OXR | [https://github.com/SoMarkAI/somark-py](https://github.com/SoMarkAI/somark-py) |
|
| 306 |
+
| somark-js | The official JS / TS SDK & CLI for SoMark and OXR | https://github.com/SoMarkAI/somark-js |
|
| 307 |
+
|
| 308 |
+
---
|
| 309 |
+
|
| 310 |
+
<div align="center">
|
| 311 |
+
<img src="https://raw.githubusercontent.com/SoMarkAI/image_bed/main/OXR_README/assets/OXR_Star_on_GitHub.gif" width="800" />
|
| 312 |
+
</div>
|
| 313 |
+
|
| 314 |
+
## Citation
|
| 315 |
+
|
| 316 |
+
For now, please cite the OXR-1.0 open-source project. We will add a paper citation once the technical report is published.
|
| 317 |
+
|
| 318 |
+
```bibtex
|
| 319 |
+
@misc{somark2026oxr,
|
| 320 |
+
author = {{SoMark}},
|
| 321 |
+
title = {{OXR-1.0}},
|
| 322 |
+
url = {https://github.com/SoMarkAI/OXR},
|
| 323 |
+
note = {GitHub repository}
|
| 324 |
+
}
|
| 325 |
+
```
|
| 326 |
+
|
| 327 |
+
## License
|
| 328 |
+
|
| 329 |
+
OXR is released under the [OXR Open Source License](./LICENSE), a custom license based on Apache 2.0 with additional terms.
|
| 330 |
+
|
| 331 |
+
For further services, contact the SoMark team at [somark.ai](http://somark.ai).
|
| 332 |
+
|
| 333 |
+
## Community
|
| 334 |
+
|
| 335 |
+
Join the OXR community to discuss document parsing, share feedback, and keep up with the latest updates.
|
| 336 |
+
|
| 337 |
+
- [Discord](https://discord.gg/msCPj2AtNN) — Discuss OXR, exchange tips, and share what you're building.
|
| 338 |
+
- [X / Twitter](https://x.com/somarkai) — Keep up with OXR releases and news from SoMark.
|
| 339 |
+
- [LinkedIn](https://www.linkedin.com/company/somarkai/posts/?feedView=all) — Follow SoMark for company news and product updates.
|
| 340 |
+
- [GitHub Issues](https://github.com/SoMarkAI/OXR/issues) — Report bugs, suggest features, and track progress.
|
| 341 |
+
- **WeChat** — Scan the QR codes below to follow the SoMark official account or join the OXR group and exchange ideas with other users.
|
| 342 |
+
|
| 343 |
+
<div align="center">
|
| 344 |
+
|
| 345 |
+
| WeChat Official Account | WeChat Group |
|
| 346 |
+
| :---: | :---: |
|
| 347 |
+
| <img src="https://raw.githubusercontent.com/SoMarkAI/OXR/main/assets/wechat-account.jpg" alt="QR code for the SoMark WeChat official account" width="200" /> | <img src="https://raw.githubusercontent.com/SoMarkAI/OXR/main/assets/wechat-community.png" alt="QR code for the OXR WeChat group" width="200" /> |
|
| 348 |
+
|
| 349 |
+
</div>
|
| 350 |
+
|
added_tokens.json
ADDED
|
@@ -0,0 +1,28 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
{
|
| 2 |
+
"</think>": 151668,
|
| 3 |
+
"</tool_call>": 151658,
|
| 4 |
+
"</tool_response>": 151666,
|
| 5 |
+
"<think>": 151667,
|
| 6 |
+
"<tool_call>": 151657,
|
| 7 |
+
"<tool_response>": 151665,
|
| 8 |
+
"<|box_end|>": 151649,
|
| 9 |
+
"<|box_start|>": 151648,
|
| 10 |
+
"<|endoftext|>": 151643,
|
| 11 |
+
"<|file_sep|>": 151664,
|
| 12 |
+
"<|fim_middle|>": 151660,
|
| 13 |
+
"<|fim_pad|>": 151662,
|
| 14 |
+
"<|fim_prefix|>": 151659,
|
| 15 |
+
"<|fim_suffix|>": 151661,
|
| 16 |
+
"<|im_end|>": 151645,
|
| 17 |
+
"<|im_start|>": 151644,
|
| 18 |
+
"<|image_pad|>": 151655,
|
| 19 |
+
"<|object_ref_end|>": 151647,
|
| 20 |
+
"<|object_ref_start|>": 151646,
|
| 21 |
+
"<|quad_end|>": 151651,
|
| 22 |
+
"<|quad_start|>": 151650,
|
| 23 |
+
"<|repo_name|>": 151663,
|
| 24 |
+
"<|video_pad|>": 151656,
|
| 25 |
+
"<|vision_end|>": 151653,
|
| 26 |
+
"<|vision_pad|>": 151654,
|
| 27 |
+
"<|vision_start|>": 151652
|
| 28 |
+
}
|
chat_template.jinja
ADDED
|
@@ -0,0 +1,18 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
{%- for message in messages -%}
|
| 2 |
+
{{- '<|im_start|>' + message['role'] + '\n' -}}
|
| 3 |
+
{%- if message['content'] is string -%}
|
| 4 |
+
{{- message['content'] -}}
|
| 5 |
+
{%- else -%}
|
| 6 |
+
{%- for content in message['content'] -%}
|
| 7 |
+
{%- if content['type'] == 'image_url' or content['type'] == 'image' -%}
|
| 8 |
+
{{- '<image>' -}}
|
| 9 |
+
{%- elif content['type'] == 'text' -%}
|
| 10 |
+
{{- content['text'] -}}
|
| 11 |
+
{%- endif -%}
|
| 12 |
+
{%- endfor -%}
|
| 13 |
+
{%- endif -%}
|
| 14 |
+
{{- '<|im_end|>\n' -}}
|
| 15 |
+
{%- endfor -%}
|
| 16 |
+
{%- if add_generation_prompt -%}
|
| 17 |
+
{{- '<|im_start|>assistant\n' -}}
|
| 18 |
+
{%- endif -%}
|
config.json
ADDED
|
@@ -0,0 +1,109 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
{
|
| 2 |
+
"architectures": [
|
| 3 |
+
"OXR"
|
| 4 |
+
],
|
| 5 |
+
"auto_map": {
|
| 6 |
+
"AutoConfig": "configuration_oxr.OXRConfig",
|
| 7 |
+
"AutoModelForCausalLM": "modeling_oxr.OXR"
|
| 8 |
+
},
|
| 9 |
+
"conversation_formatter_class": "Qwen3ConversationFormatter",
|
| 10 |
+
"dtype": "bfloat16",
|
| 11 |
+
"eos_token_id": 151643,
|
| 12 |
+
"hidden_size": 1024,
|
| 13 |
+
"keys_to_ignore_at_inference": [
|
| 14 |
+
"past_key_values"
|
| 15 |
+
],
|
| 16 |
+
"llm_config": {
|
| 17 |
+
"_name_or_path": "Qwen/Qwen3-0.6B-Base",
|
| 18 |
+
"architectures": [
|
| 19 |
+
"Qwen3ForCausalLM"
|
| 20 |
+
],
|
| 21 |
+
"attention_bias": false,
|
| 22 |
+
"attention_dropout": 0.0,
|
| 23 |
+
"bos_token_id": 151643,
|
| 24 |
+
"dtype": "bfloat16",
|
| 25 |
+
"eos_token_id": 151643,
|
| 26 |
+
"head_dim": 128,
|
| 27 |
+
"hidden_act": "silu",
|
| 28 |
+
"hidden_size": 1024,
|
| 29 |
+
"initializer_range": 0.02,
|
| 30 |
+
"intermediate_size": 3072,
|
| 31 |
+
"layer_types": [
|
| 32 |
+
"full_attention",
|
| 33 |
+
"full_attention",
|
| 34 |
+
"full_attention",
|
| 35 |
+
"full_attention",
|
| 36 |
+
"full_attention",
|
| 37 |
+
"full_attention",
|
| 38 |
+
"full_attention",
|
| 39 |
+
"full_attention",
|
| 40 |
+
"full_attention",
|
| 41 |
+
"full_attention",
|
| 42 |
+
"full_attention",
|
| 43 |
+
"full_attention",
|
| 44 |
+
"full_attention",
|
| 45 |
+
"full_attention",
|
| 46 |
+
"full_attention",
|
| 47 |
+
"full_attention",
|
| 48 |
+
"full_attention",
|
| 49 |
+
"full_attention",
|
| 50 |
+
"full_attention",
|
| 51 |
+
"full_attention",
|
| 52 |
+
"full_attention",
|
| 53 |
+
"full_attention",
|
| 54 |
+
"full_attention",
|
| 55 |
+
"full_attention",
|
| 56 |
+
"full_attention",
|
| 57 |
+
"full_attention",
|
| 58 |
+
"full_attention",
|
| 59 |
+
"full_attention"
|
| 60 |
+
],
|
| 61 |
+
"max_position_embeddings": 32768,
|
| 62 |
+
"max_window_layers": 28,
|
| 63 |
+
"model_type": "qwen3",
|
| 64 |
+
"num_attention_heads": 16,
|
| 65 |
+
"num_hidden_layers": 28,
|
| 66 |
+
"num_key_value_heads": 8,
|
| 67 |
+
"pad_token_id": 151643,
|
| 68 |
+
"rms_norm_eps": 1e-06,
|
| 69 |
+
"rope_scaling": null,
|
| 70 |
+
"rope_theta": 1000000,
|
| 71 |
+
"sliding_window": null,
|
| 72 |
+
"tie_word_embeddings": true,
|
| 73 |
+
"use_cache": false,
|
| 74 |
+
"use_sliding_window": false,
|
| 75 |
+
"vocab_size": 151936
|
| 76 |
+
},
|
| 77 |
+
"max_position_embeddings": 40960,
|
| 78 |
+
"model_type": "oxr",
|
| 79 |
+
"num_attention_heads": 32,
|
| 80 |
+
"pad_token_id": 151643,
|
| 81 |
+
"transformers_version": "5.6.2",
|
| 82 |
+
"use_cache": false,
|
| 83 |
+
"visual_vocab_size": 65536,
|
| 84 |
+
"vit_config": {
|
| 85 |
+
"_attn_implementation_autoset": true,
|
| 86 |
+
"_name_or_path": "google/siglip2-so400m-patch16-512",
|
| 87 |
+
"attention_dropout": 0.0,
|
| 88 |
+
"dtype": "bfloat16",
|
| 89 |
+
"fullatt_block_indexes": null,
|
| 90 |
+
"hidden_act": "gelu_pytorch_tanh",
|
| 91 |
+
"hidden_size": 1152,
|
| 92 |
+
"hidden_stride": 2,
|
| 93 |
+
"image_size": 512,
|
| 94 |
+
"intermediate_size": 4304,
|
| 95 |
+
"layer_norm_eps": 1e-06,
|
| 96 |
+
"model_type": "siglip2_navit",
|
| 97 |
+
"num_attention_heads": 16,
|
| 98 |
+
"num_channels": 3,
|
| 99 |
+
"num_hidden_layers": 27,
|
| 100 |
+
"num_patches": -1,
|
| 101 |
+
"pad_token_id": 151643,
|
| 102 |
+
"patch_size": 16,
|
| 103 |
+
"preserve_original_pe": true,
|
| 104 |
+
"temporal_patch_size": 1,
|
| 105 |
+
"use_rope": true,
|
| 106 |
+
"window_size": 112
|
| 107 |
+
},
|
| 108 |
+
"vocab_size": 151936
|
| 109 |
+
}
|
configuration_oxr.py
ADDED
|
@@ -0,0 +1,100 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
from typing import Any, Optional, List, Union
|
| 2 |
+
|
| 3 |
+
from transformers import AutoConfig, Qwen3Config
|
| 4 |
+
from transformers.configuration_utils import PretrainedConfig
|
| 5 |
+
|
| 6 |
+
__all__ = ["Siglip2NavitConfig", "OXRConfig"]
|
| 7 |
+
|
| 8 |
+
|
| 9 |
+
class Siglip2NavitConfig(PretrainedConfig):
|
| 10 |
+
"""This is the configuration class to store the configuration of an [`AIMv2Model`].
|
| 11 |
+
|
| 12 |
+
Instantiating a configuration with the defaults will yield a similar configuration
|
| 13 |
+
to that of the [apple/aimv2-large-patch14-224](https://huggingface.co/apple/aimv2-large-patch14-224).
|
| 14 |
+
|
| 15 |
+
Args:
|
| 16 |
+
hidden_size: Dimension of the hidden representations.
|
| 17 |
+
intermediate_size: Dimension of the SwiGLU representations.
|
| 18 |
+
num_hidden_layers: Number of hidden layers in the Transformer.
|
| 19 |
+
num_attention_heads: Number of attention heads for each attention layer
|
| 20 |
+
in the Transformer.
|
| 21 |
+
num_channels: Number of input channels.
|
| 22 |
+
image_size: Image size.
|
| 23 |
+
patch_size: Patch size.
|
| 24 |
+
rms_norm_eps: Epsilon value used for the RMS normalization layer.
|
| 25 |
+
attention_dropout: Dropout ratio for attention probabilities.
|
| 26 |
+
projection_dropout: Dropout ratio for the projection layer after the attention.
|
| 27 |
+
qkv_bias: Whether to add a bias to the queries, keys and values.
|
| 28 |
+
use_bias: Whether to add a bias in the feed-forward and projection layers.
|
| 29 |
+
kwargs: Keyword arguments for the [`PretrainedConfig`].
|
| 30 |
+
"""
|
| 31 |
+
|
| 32 |
+
model_type: str = "siglip2_navit"
|
| 33 |
+
|
| 34 |
+
def __init__(
|
| 35 |
+
self,
|
| 36 |
+
hidden_size: int = 1024,
|
| 37 |
+
intermediate_size: int = 4096,
|
| 38 |
+
num_hidden_layers: int = 24,
|
| 39 |
+
num_attention_heads: int = 16,
|
| 40 |
+
num_channels: int = 3,
|
| 41 |
+
num_patches: int = -1,
|
| 42 |
+
image_size: int = 512,
|
| 43 |
+
patch_size: int = 16,
|
| 44 |
+
hidden_act: str="gelu_pytorch_tanh",
|
| 45 |
+
layer_norm_eps: float = 1e-6,
|
| 46 |
+
attention_dropout: float = 0.0,
|
| 47 |
+
hidden_stride: int = 2,
|
| 48 |
+
window_size: int = 112,
|
| 49 |
+
fullatt_block_indexes: Optional[list] = None,
|
| 50 |
+
temporal_patch_size: int = 1,
|
| 51 |
+
preserve_original_pe: bool = True,
|
| 52 |
+
use_rope: bool = True,
|
| 53 |
+
**kwargs: Any,
|
| 54 |
+
):
|
| 55 |
+
super().__init__(**kwargs)
|
| 56 |
+
self.hidden_size = hidden_size
|
| 57 |
+
self.intermediate_size = intermediate_size
|
| 58 |
+
self.num_hidden_layers = num_hidden_layers
|
| 59 |
+
self.num_attention_heads = num_attention_heads
|
| 60 |
+
self.num_channels = num_channels
|
| 61 |
+
self.num_patches = num_patches
|
| 62 |
+
self.patch_size = patch_size
|
| 63 |
+
self.image_size = image_size
|
| 64 |
+
self.hidden_act = hidden_act
|
| 65 |
+
self.attention_dropout = attention_dropout
|
| 66 |
+
self.layer_norm_eps = layer_norm_eps
|
| 67 |
+
self.hidden_stride = hidden_stride
|
| 68 |
+
self.window_size = window_size
|
| 69 |
+
self.fullatt_block_indexes = fullatt_block_indexes
|
| 70 |
+
self.temporal_patch_size = temporal_patch_size
|
| 71 |
+
self.preserve_original_pe = preserve_original_pe
|
| 72 |
+
self.use_rope = use_rope
|
| 73 |
+
|
| 74 |
+
class OXRConfig(PretrainedConfig):
|
| 75 |
+
model_type = "oxr"
|
| 76 |
+
sub_configs = dict(llm_config=Qwen3Config, vit_config=Siglip2NavitConfig)
|
| 77 |
+
|
| 78 |
+
def __init__(self,
|
| 79 |
+
llm_config: Optional[Union[Qwen3Config, dict]] = None,
|
| 80 |
+
vit_config: Optional[Union[Siglip2NavitConfig, dict]] = None,
|
| 81 |
+
visual_vocab_size=65536,
|
| 82 |
+
hidden_size=None,
|
| 83 |
+
**kwargs
|
| 84 |
+
):
|
| 85 |
+
super().__init__(**kwargs)
|
| 86 |
+
if isinstance(llm_config, dict):
|
| 87 |
+
if "model_type" in llm_config:
|
| 88 |
+
config_kwargs = {k: v for k, v in llm_config.items() if k != "model_type"}
|
| 89 |
+
llm_config = AutoConfig.for_model(llm_config["model_type"], **config_kwargs)
|
| 90 |
+
else:
|
| 91 |
+
llm_config = Qwen3Config(**llm_config)
|
| 92 |
+
self.llm_config = llm_config
|
| 93 |
+
if isinstance(vit_config, dict):
|
| 94 |
+
vit_config = Siglip2NavitConfig(**vit_config)
|
| 95 |
+
self.vit_config = vit_config
|
| 96 |
+
self.visual_vocab_size = visual_vocab_size
|
| 97 |
+
self.hidden_size = hidden_size
|
| 98 |
+
if kwargs.get('attn_implementation'):
|
| 99 |
+
self.llm_config._attn_implementation = kwargs['attn_implementation']
|
| 100 |
+
self.vit_config._attn_implementation = kwargs['attn_implementation']
|
generation_config.json
ADDED
|
@@ -0,0 +1,8 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
{
|
| 2 |
+
"_from_model_config": true,
|
| 3 |
+
"eos_token_id": [
|
| 4 |
+
151643,
|
| 5 |
+
151645
|
| 6 |
+
],
|
| 7 |
+
"transformers_version": "4.57.1"
|
| 8 |
+
}
|
layout_analysis/README.md
ADDED
|
@@ -0,0 +1,33 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
# Layout Analysis
|
| 2 |
+
|
| 3 |
+
D-FINE Stage-2 B2 layout model with 12 classes. Detects page regions;
|
| 4 |
+
text recognition and reading order are handled by OXR.
|
| 5 |
+
|
| 6 |
+
## Files
|
| 7 |
+
|
| 8 |
+
- `last.pth`: inference-only model weights (no optimizer or training state).
|
| 9 |
+
- `metadata.json`: model identity, architecture, preprocessing, class IDs,
|
| 10 |
+
checkpoint size and SHA-256 (schema version 1).
|
| 11 |
+
|
| 12 |
+
`model_version` is a public release version (`major.minor.patch`), not a
|
| 13 |
+
training-run identifier.
|
| 14 |
+
|
| 15 |
+
## Usage
|
| 16 |
+
|
| 17 |
+
Use the LA inference service in the OXR code repository at
|
| 18 |
+
`services/layout_analyze/`. Mount this directory into the service and set
|
| 19 |
+
`MODEL_PATH` to the mounted `last.pth` path.
|
| 20 |
+
|
| 21 |
+
The matching LA service reads `metadata.json` next to the checkpoint at startup
|
| 22 |
+
and validates its supported architecture, preprocessing, class IDs and weight
|
| 23 |
+
integrity. Both files must be mounted. `MODEL_METADATA_PATH` can override the
|
| 24 |
+
metadata path. Unsupported metadata or a mismatched checkpoint fails startup.
|
| 25 |
+
This is not a Transformers `AutoModel` configuration. Device, precision and
|
| 26 |
+
CUDA Graph settings are selected by the service, not by the model metadata.
|
| 27 |
+
|
| 28 |
+
Checkpoint verification:
|
| 29 |
+
|
| 30 |
+
```bash
|
| 31 |
+
shasum -a 256 layout_analysis/last.pth
|
| 32 |
+
# dff78ccf18439955362ca44a69eb28fb0b40222a7d278860589682de0176dc17
|
| 33 |
+
```
|
layout_analysis/last.pth
ADDED
|
@@ -0,0 +1,3 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
version https://git-lfs.github.com/spec/v1
|
| 2 |
+
oid sha256:dff78ccf18439955362ca44a69eb28fb0b40222a7d278860589682de0176dc17
|
| 3 |
+
size 78791307
|
layout_analysis/metadata.json
ADDED
|
@@ -0,0 +1,29 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
{
|
| 2 |
+
"schema_version": 1,
|
| 3 |
+
"model_type": "dfine",
|
| 4 |
+
"model_version": "1.0.0",
|
| 5 |
+
"architecture": "stage2_b2",
|
| 6 |
+
"checkpoint": "last.pth",
|
| 7 |
+
"checkpoint_size_bytes": 78791307,
|
| 8 |
+
"checkpoint_sha256": "dff78ccf18439955362ca44a69eb28fb0b40222a7d278860589682de0176dc17",
|
| 9 |
+
"num_classes": 12,
|
| 10 |
+
"image_size": 960,
|
| 11 |
+
"color_order": "rgb",
|
| 12 |
+
"resize_backend": "opencv_lanczos4",
|
| 13 |
+
"postprocess": "model_letterbox",
|
| 14 |
+
"provides_reading_order": false,
|
| 15 |
+
"id2label": {
|
| 16 |
+
"0": "Caption",
|
| 17 |
+
"1": "Footnote",
|
| 18 |
+
"2": "Formula",
|
| 19 |
+
"3": "Text",
|
| 20 |
+
"4": "Page-footer",
|
| 21 |
+
"5": "Page-header",
|
| 22 |
+
"6": "Picture",
|
| 23 |
+
"7": "Title",
|
| 24 |
+
"8": "Table",
|
| 25 |
+
"9": "Code Block",
|
| 26 |
+
"10": "Stamp",
|
| 27 |
+
"11": "Chemical Structure"
|
| 28 |
+
}
|
| 29 |
+
}
|
merges.txt
ADDED
|
The diff for this file is too large to render.
See raw diff
|
|
|
model.safetensors
ADDED
|
@@ -0,0 +1,3 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
version https://git-lfs.github.com/spec/v1
|
| 2 |
+
oid sha256:795bb2f1faac579f58829913f2c606202531a96c1203e19ef7a70b103fb7ea51
|
| 3 |
+
size 3068857520
|
modeling_oxr.py
ADDED
|
@@ -0,0 +1,1037 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
import math
|
| 2 |
+
from typing import Dict, List, Optional, Tuple, Union
|
| 3 |
+
|
| 4 |
+
import PIL.Image
|
| 5 |
+
import numpy as np
|
| 6 |
+
import torch
|
| 7 |
+
from torch import Tensor, nn
|
| 8 |
+
from torch.nn import functional as F
|
| 9 |
+
from transformers import (
|
| 10 |
+
AutoConfig,
|
| 11 |
+
AutoImageProcessor,
|
| 12 |
+
AutoModel,
|
| 13 |
+
AutoModelForCausalLM,
|
| 14 |
+
AutoTokenizer,
|
| 15 |
+
__version__ as TRANSFORMERS_VERSION,
|
| 16 |
+
)
|
| 17 |
+
from transformers.activations import ACT2FN
|
| 18 |
+
from transformers.generation.utils import GenerateOutput
|
| 19 |
+
from transformers.modeling_outputs import BaseModelOutputWithNoAttention
|
| 20 |
+
from transformers.modeling_utils import PreTrainedModel
|
| 21 |
+
from transformers.utils import is_flash_attn_2_available
|
| 22 |
+
|
| 23 |
+
from .configuration_oxr import Siglip2NavitConfig, OXRConfig
|
| 24 |
+
|
| 25 |
+
|
| 26 |
+
if is_flash_attn_2_available() :
|
| 27 |
+
from flash_attn import flash_attn_varlen_func
|
| 28 |
+
from flash_attn.layers.rotary import apply_rotary_emb
|
| 29 |
+
|
| 30 |
+
|
| 31 |
+
IMAGE_PLACEHOLDER = "<image>"
|
| 32 |
+
IMAGE_PLACEHOLDER_ID = -200
|
| 33 |
+
VIDEO_PLACEHOLDER = "<video>"
|
| 34 |
+
VIDEO_PLACEHOLDER_ID = -201
|
| 35 |
+
|
| 36 |
+
VISUAL_ATOM_ID = -300
|
| 37 |
+
INDICATOR_IDS = [-301, -302, -303, -304]
|
| 38 |
+
|
| 39 |
+
|
| 40 |
+
# copied from qwen2.5-vl
|
| 41 |
+
class VisionRotaryEmbedding(nn.Module):
|
| 42 |
+
def __init__(self, dim: int, theta: float = 10000.0) -> None:
|
| 43 |
+
super().__init__()
|
| 44 |
+
self.dim = dim
|
| 45 |
+
self.theta = theta
|
| 46 |
+
inv_freq = 1.0 / (theta ** (torch.arange(0, dim, 2, dtype=torch.float) / dim))
|
| 47 |
+
self.register_buffer("inv_freq", inv_freq, persistent=False)
|
| 48 |
+
|
| 49 |
+
def forward(self, seqlen: int) -> torch.Tensor:
|
| 50 |
+
inv_freq = 1.0 / (
|
| 51 |
+
self.theta ** (torch.arange(0, self.dim, 2, device=self.inv_freq.device, dtype=torch.float) / self.dim)
|
| 52 |
+
)
|
| 53 |
+
seq = torch.arange(seqlen, device=inv_freq.device, dtype=inv_freq.dtype)
|
| 54 |
+
freqs = torch.outer(seq, inv_freq)
|
| 55 |
+
return freqs
|
| 56 |
+
|
| 57 |
+
|
| 58 |
+
class Siglip2VisionEmbeddings(nn.Module):
|
| 59 |
+
def __init__(self, config: Siglip2NavitConfig):
|
| 60 |
+
super().__init__()
|
| 61 |
+
self.config = config
|
| 62 |
+
self.embed_dim = config.hidden_size
|
| 63 |
+
self.patch_size = config.patch_size
|
| 64 |
+
self.image_size = config.image_size
|
| 65 |
+
self.num_patches = config.num_patches
|
| 66 |
+
self.preserve_original_pe = config.preserve_original_pe
|
| 67 |
+
self.hidden_stride = config.hidden_stride
|
| 68 |
+
|
| 69 |
+
|
| 70 |
+
# siglip2 naflex
|
| 71 |
+
if self.num_patches > 0:
|
| 72 |
+
self.patch_embedding = nn.Linear(
|
| 73 |
+
in_features=config.num_channels * self.patch_size * self.patch_size,
|
| 74 |
+
out_features=self.embed_dim,
|
| 75 |
+
)
|
| 76 |
+
if self.preserve_original_pe:
|
| 77 |
+
self.position_embedding_size = int(self.num_patches**0.5)
|
| 78 |
+
self.position_embedding = nn.Embedding(self.num_patches, self.embed_dim)
|
| 79 |
+
|
| 80 |
+
else:
|
| 81 |
+
self.patch_embedding = nn.Conv2d(
|
| 82 |
+
in_channels=config.num_channels,
|
| 83 |
+
out_channels=self.embed_dim,
|
| 84 |
+
kernel_size=self.patch_size,
|
| 85 |
+
stride=self.patch_size,
|
| 86 |
+
padding="valid",
|
| 87 |
+
)
|
| 88 |
+
if self.preserve_original_pe:
|
| 89 |
+
self.num_patches = (self.image_size // self.patch_size) ** 2
|
| 90 |
+
self.position_embedding_size = self.image_size // self.patch_size
|
| 91 |
+
self.position_embedding = nn.Embedding(self.num_patches, self.embed_dim)
|
| 92 |
+
|
| 93 |
+
@staticmethod
|
| 94 |
+
def resize_positional_embeddings(
|
| 95 |
+
positional_embeddings: torch.Tensor,
|
| 96 |
+
spatial_shapes: torch.LongTensor,
|
| 97 |
+
max_length: int,
|
| 98 |
+
) -> torch.Tensor:
|
| 99 |
+
"""
|
| 100 |
+
Resize positional embeddings to image-specific size and pad to a fixed size.
|
| 101 |
+
|
| 102 |
+
Args:
|
| 103 |
+
positional_embeddings (`torch.Tensor`):
|
| 104 |
+
Position embeddings of shape (height, width, embed_dim)
|
| 105 |
+
spatial_shapes (`torch.LongTensor`):
|
| 106 |
+
Spatial shapes of shape (batch_size, 2) to resize the positional embeddings to
|
| 107 |
+
max_length (`int`):
|
| 108 |
+
Maximum length of the positional embeddings to pad resized positional embeddings to
|
| 109 |
+
|
| 110 |
+
Returns:
|
| 111 |
+
`torch.Tensor`: Embeddings of shape (batch_size, max_length, embed_dim)
|
| 112 |
+
"""
|
| 113 |
+
batch_size = spatial_shapes.shape[0]
|
| 114 |
+
embed_dim = positional_embeddings.shape[-1]
|
| 115 |
+
source_dtype = positional_embeddings.dtype
|
| 116 |
+
|
| 117 |
+
resulted_positional_embeddings = torch.empty(
|
| 118 |
+
(batch_size, max_length, embed_dim),
|
| 119 |
+
device=positional_embeddings.device,
|
| 120 |
+
dtype=source_dtype,
|
| 121 |
+
)
|
| 122 |
+
|
| 123 |
+
# (height, width, embed_dim) -> (1, embed_dim, height, width) for interpolation
|
| 124 |
+
positional_embeddings = positional_embeddings.permute(2, 0, 1).unsqueeze(0)
|
| 125 |
+
|
| 126 |
+
# Upcast to float32 on CPU because antialias is not supported for bfloat16/float16 on CPU
|
| 127 |
+
if positional_embeddings.device.type == "cpu":
|
| 128 |
+
positional_embeddings = positional_embeddings.to(torch.float32)
|
| 129 |
+
|
| 130 |
+
for i in range(batch_size):
|
| 131 |
+
# (1, dim, height, width) -> (1, dim, target_height, target_width)
|
| 132 |
+
height, width = spatial_shapes[i]
|
| 133 |
+
resized_embeddings = F.interpolate(
|
| 134 |
+
positional_embeddings,
|
| 135 |
+
size=(height, width),
|
| 136 |
+
mode="bilinear",
|
| 137 |
+
align_corners=False,
|
| 138 |
+
antialias=True,
|
| 139 |
+
)
|
| 140 |
+
|
| 141 |
+
# (1, dim, target_height, target_width) -> (target_height * target_width, dim)
|
| 142 |
+
resized_embeddings = resized_embeddings.reshape(embed_dim, height * width).transpose(0, 1)
|
| 143 |
+
|
| 144 |
+
# Cast to original dtype
|
| 145 |
+
resized_embeddings = resized_embeddings.to(source_dtype)
|
| 146 |
+
|
| 147 |
+
resulted_positional_embeddings[i, : height * width] = resized_embeddings
|
| 148 |
+
resulted_positional_embeddings[i, height * width :] = resized_embeddings[0]
|
| 149 |
+
|
| 150 |
+
return resulted_positional_embeddings
|
| 151 |
+
|
| 152 |
+
def forward(self, pixel_values: torch.FloatTensor,
|
| 153 |
+
grid_thws: Optional[torch.LongTensor] = None) -> torch.Tensor:
|
| 154 |
+
"""
|
| 155 |
+
Args:
|
| 156 |
+
pixel_values (`torch.FloatTensor`):
|
| 157 |
+
Pixel values of shape (num_patches, num_channels * temporal_patch_size * patch_size * patch_size)
|
| 158 |
+
grid_thws: (`torch.LongTensor`):
|
| 159 |
+
grid shape (num_patches, 3)
|
| 160 |
+
"""
|
| 161 |
+
|
| 162 |
+
# Apply patch embeddings to already patchified pixel values
|
| 163 |
+
target_dtype = self.patch_embedding.weight.dtype
|
| 164 |
+
if isinstance(self.patch_embedding, nn.Linear):
|
| 165 |
+
patch_embeds = self.patch_embedding(pixel_values.to(dtype=target_dtype))
|
| 166 |
+
elif isinstance(self.patch_embedding, nn.Conv2d):
|
| 167 |
+
pixel_values = pixel_values.view(-1, self.config.num_channels * self.config.temporal_patch_size, self.patch_size,
|
| 168 |
+
self.patch_size)
|
| 169 |
+
patch_embeds = self.patch_embedding(pixel_values.to(dtype=target_dtype))
|
| 170 |
+
patch_embeds = patch_embeds.reshape(-1, self.embed_dim)
|
| 171 |
+
|
| 172 |
+
|
| 173 |
+
if self.preserve_original_pe:
|
| 174 |
+
assert grid_thws is not None
|
| 175 |
+
pos_embed_new = torch.zeros_like(patch_embeds)
|
| 176 |
+
ori_h = ori_w = self.position_embedding_size
|
| 177 |
+
positional_embeddings = self.position_embedding.weight.reshape(
|
| 178 |
+
self.position_embedding_size, self.position_embedding_size, -1
|
| 179 |
+
).unsqueeze(0).permute(0,3,1,2)
|
| 180 |
+
# pos_embed = self.pos_embed.reshape(1, ori_h, ori_w, -1).permute(0, 3, 1, 2)
|
| 181 |
+
cnt = 0
|
| 182 |
+
for t, h, w in grid_thws:
|
| 183 |
+
thw = t * h * w
|
| 184 |
+
pe = F.interpolate(positional_embeddings, size=(h, w), mode='bicubic', align_corners=False)
|
| 185 |
+
pe = pe.permute(0, 2, 3, 1).reshape(1, h * w, -1)
|
| 186 |
+
pe = pe[0].repeat(t, 1)
|
| 187 |
+
pe = pe.reshape(t, h // self.hidden_stride, self.hidden_stride, w // self.hidden_stride,
|
| 188 |
+
self.hidden_stride, -1)
|
| 189 |
+
pe = pe.permute(0, 1, 3, 2, 4, 5).reshape(thw, -1)
|
| 190 |
+
pos_embed_new[cnt:cnt + thw] = pe
|
| 191 |
+
cnt += thw
|
| 192 |
+
patch_embeds = patch_embeds + pos_embed_new
|
| 193 |
+
|
| 194 |
+
return patch_embeds
|
| 195 |
+
|
| 196 |
+
|
| 197 |
+
# copied from qwen2.5-vl
|
| 198 |
+
def apply_rotary_pos_emb_flashatt(
|
| 199 |
+
q: torch.Tensor, k: torch.Tensor, cos: torch.Tensor, sin: torch.Tensor
|
| 200 |
+
) -> Tuple[torch.Tensor, torch.Tensor]:
|
| 201 |
+
cos = cos.chunk(2, dim=-1)[0].contiguous()
|
| 202 |
+
sin = sin.chunk(2, dim=-1)[0].contiguous()
|
| 203 |
+
q_embed = apply_rotary_emb(q.float(), cos.float(), sin.float()).type_as(q)
|
| 204 |
+
k_embed = apply_rotary_emb(k.float(), cos.float(), sin.float()).type_as(k)
|
| 205 |
+
return q_embed, k_embed
|
| 206 |
+
|
| 207 |
+
|
| 208 |
+
# Copied from transformers.models.llama.modeling_llama.rotate_half
|
| 209 |
+
def rotate_half(x):
|
| 210 |
+
"""Rotates half the hidden dims of the input."""
|
| 211 |
+
x1 = x[..., : x.shape[-1] // 2]
|
| 212 |
+
x2 = x[..., x.shape[-1] // 2 :]
|
| 213 |
+
return torch.cat((-x2, x1), dim=-1)
|
| 214 |
+
|
| 215 |
+
|
| 216 |
+
def apply_rotary_pos_emb_vision(
|
| 217 |
+
q: torch.Tensor, k: torch.Tensor, cos: torch.Tensor, sin: torch.Tensor
|
| 218 |
+
) -> tuple[torch.Tensor, torch.Tensor]:
|
| 219 |
+
orig_q_dtype = q.dtype
|
| 220 |
+
orig_k_dtype = k.dtype
|
| 221 |
+
q, k = q.float(), k.float()
|
| 222 |
+
cos, sin = cos.unsqueeze(-2).float(), sin.unsqueeze(-2).float()
|
| 223 |
+
q_embed = (q * cos) + (rotate_half(q) * sin)
|
| 224 |
+
k_embed = (k * cos) + (rotate_half(k) * sin)
|
| 225 |
+
q_embed = q_embed.to(orig_q_dtype)
|
| 226 |
+
k_embed = k_embed.to(orig_k_dtype)
|
| 227 |
+
return q_embed, k_embed
|
| 228 |
+
|
| 229 |
+
|
| 230 |
+
class Siglip2Attention(nn.Module):
|
| 231 |
+
"""Multi-headed attention from 'Attention Is All You Need' paper"""
|
| 232 |
+
|
| 233 |
+
def __init__(self, config):
|
| 234 |
+
super().__init__()
|
| 235 |
+
self.config = config
|
| 236 |
+
self.embed_dim = config.hidden_size
|
| 237 |
+
self.num_heads = config.num_attention_heads
|
| 238 |
+
self.head_dim = self.embed_dim // self.num_heads
|
| 239 |
+
if self.head_dim * self.num_heads != self.embed_dim:
|
| 240 |
+
raise ValueError(
|
| 241 |
+
f"embed_dim must be divisible by num_heads (got `embed_dim`: {self.embed_dim} and `num_heads`:"
|
| 242 |
+
f" {self.num_heads})."
|
| 243 |
+
)
|
| 244 |
+
self.scale = self.head_dim**-0.5
|
| 245 |
+
self.dropout = config.attention_dropout
|
| 246 |
+
self.is_causal = False
|
| 247 |
+
|
| 248 |
+
self.k_proj = nn.Linear(self.embed_dim, self.embed_dim)
|
| 249 |
+
self.v_proj = nn.Linear(self.embed_dim, self.embed_dim)
|
| 250 |
+
self.q_proj = nn.Linear(self.embed_dim, self.embed_dim)
|
| 251 |
+
self.out_proj = nn.Linear(self.embed_dim, self.embed_dim)
|
| 252 |
+
|
| 253 |
+
self.use_rope = config.use_rope
|
| 254 |
+
|
| 255 |
+
def forward(
|
| 256 |
+
self,
|
| 257 |
+
hidden_states: torch.Tensor,
|
| 258 |
+
cu_seqlens: torch.Tensor,
|
| 259 |
+
position_embeddings: Optional[Tuple[torch.Tensor, torch.Tensor]] = None,
|
| 260 |
+
) -> tuple[torch.Tensor, Optional[torch.Tensor]]:
|
| 261 |
+
"""Input shape: Batch x Time x Channel"""
|
| 262 |
+
|
| 263 |
+
seq_length, embed_dim = hidden_states.shape
|
| 264 |
+
|
| 265 |
+
queries = self.q_proj(hidden_states)
|
| 266 |
+
keys = self.k_proj(hidden_states)
|
| 267 |
+
values = self.v_proj(hidden_states)
|
| 268 |
+
|
| 269 |
+
queries = queries.view(seq_length, self.num_heads, self.head_dim)
|
| 270 |
+
keys = keys.view(seq_length, self.num_heads, self.head_dim)
|
| 271 |
+
values = values.view(seq_length, self.num_heads, self.head_dim)
|
| 272 |
+
|
| 273 |
+
if self.use_rope:
|
| 274 |
+
cos, sin = position_embeddings
|
| 275 |
+
if is_flash_attn_2_available() :
|
| 276 |
+
queries, keys = apply_rotary_pos_emb_flashatt(queries.unsqueeze(0), keys.unsqueeze(0), cos, sin)
|
| 277 |
+
else:
|
| 278 |
+
queries, keys = apply_rotary_pos_emb_vision(queries.unsqueeze(0), keys.unsqueeze(0), cos, sin)
|
| 279 |
+
queries = queries.squeeze(0)
|
| 280 |
+
keys = keys.squeeze(0)
|
| 281 |
+
|
| 282 |
+
max_seqlen = (cu_seqlens[1:] - cu_seqlens[:-1]).max().item()
|
| 283 |
+
if is_flash_attn_2_available() :
|
| 284 |
+
attn_output = flash_attn_varlen_func(queries, keys, values, cu_seqlens, cu_seqlens, max_seqlen, max_seqlen).reshape(
|
| 285 |
+
seq_length, -1
|
| 286 |
+
)
|
| 287 |
+
else:
|
| 288 |
+
batch_size = cu_seqlens.shape[0] - 1
|
| 289 |
+
outputs = []
|
| 290 |
+
cu = cu_seqlens.tolist()
|
| 291 |
+
for i in range(batch_size):
|
| 292 |
+
start_idx = cu[i]
|
| 293 |
+
end_idx = cu[i + 1]
|
| 294 |
+
# Each sequence is processed independently.
|
| 295 |
+
q_i = queries[start_idx:end_idx].unsqueeze(0)
|
| 296 |
+
k_i = keys[start_idx:end_idx].unsqueeze(0)
|
| 297 |
+
v_i = values[start_idx:end_idx].unsqueeze(0)
|
| 298 |
+
# (1, seq_len, num_heads, head_dim) ->
|
| 299 |
+
# (1, num_heads, seq_len, head_dim)
|
| 300 |
+
q_i, k_i, v_i = [x.transpose(1, 2) for x in (q_i, k_i, v_i)]
|
| 301 |
+
output_i = F.scaled_dot_product_attention(q_i,
|
| 302 |
+
k_i,
|
| 303 |
+
v_i,
|
| 304 |
+
dropout_p=0.0)
|
| 305 |
+
# (1, num_heads, seq_len, head_dim) -> (seq_len, embed_dim)
|
| 306 |
+
output_i = output_i.transpose(1, 2).reshape(-1, self.embed_dim)
|
| 307 |
+
outputs.append(output_i)
|
| 308 |
+
attn_output = torch.cat(outputs, dim=0)
|
| 309 |
+
|
| 310 |
+
attn_output = self.out_proj(attn_output)
|
| 311 |
+
return attn_output
|
| 312 |
+
|
| 313 |
+
class Siglip2MLP(nn.Module):
|
| 314 |
+
def __init__(self, config):
|
| 315 |
+
super().__init__()
|
| 316 |
+
self.config = config
|
| 317 |
+
self.activation_fn = ACT2FN[config.hidden_act]
|
| 318 |
+
self.fc1 = nn.Linear(config.hidden_size, config.intermediate_size)
|
| 319 |
+
self.fc2 = nn.Linear(config.intermediate_size, config.hidden_size)
|
| 320 |
+
|
| 321 |
+
def forward(self, hidden_states: torch.Tensor) -> torch.Tensor:
|
| 322 |
+
hidden_states = self.fc1(hidden_states)
|
| 323 |
+
hidden_states = self.activation_fn(hidden_states)
|
| 324 |
+
hidden_states = self.fc2(hidden_states)
|
| 325 |
+
return hidden_states
|
| 326 |
+
|
| 327 |
+
|
| 328 |
+
class Siglip2EncoderLayer(nn.Module):
|
| 329 |
+
def __init__(self, config: Siglip2NavitConfig):
|
| 330 |
+
super().__init__()
|
| 331 |
+
self.embed_dim = config.hidden_size
|
| 332 |
+
self.layer_norm1 = nn.LayerNorm(self.embed_dim, eps=config.layer_norm_eps)
|
| 333 |
+
self.self_attn = Siglip2Attention(config)
|
| 334 |
+
self.layer_norm2 = nn.LayerNorm(self.embed_dim, eps=config.layer_norm_eps)
|
| 335 |
+
self.mlp = Siglip2MLP(config)
|
| 336 |
+
|
| 337 |
+
def forward(
|
| 338 |
+
self,
|
| 339 |
+
hidden_states: torch.Tensor,
|
| 340 |
+
cu_seqlens: torch.Tensor,
|
| 341 |
+
position_embeddings: torch.Tensor
|
| 342 |
+
) -> tuple[torch.FloatTensor]:
|
| 343 |
+
"""
|
| 344 |
+
Args:
|
| 345 |
+
hidden_states (`torch.FloatTensor`):
|
| 346 |
+
Input to the layer of shape `(batch, seq_len, embed_dim)`.
|
| 347 |
+
attention_mask (`torch.FloatTensor`):
|
| 348 |
+
Attention mask of shape `(batch, 1, q_len, k_v_seq_len)` where padding elements are indicated by very large negative values.
|
| 349 |
+
output_attentions (`bool`, *optional*, defaults to `False`):
|
| 350 |
+
Whether or not to return the attentions tensors of all attention layers. See `attentions` under
|
| 351 |
+
returned tensors for more detail.
|
| 352 |
+
"""
|
| 353 |
+
residual = hidden_states
|
| 354 |
+
|
| 355 |
+
hidden_states = self.layer_norm1(hidden_states)
|
| 356 |
+
hidden_states = self.self_attn(
|
| 357 |
+
hidden_states=hidden_states,
|
| 358 |
+
cu_seqlens=cu_seqlens,
|
| 359 |
+
position_embeddings=position_embeddings
|
| 360 |
+
)
|
| 361 |
+
hidden_states = residual + hidden_states
|
| 362 |
+
|
| 363 |
+
residual = hidden_states
|
| 364 |
+
hidden_states = self.layer_norm2(hidden_states)
|
| 365 |
+
hidden_states = self.mlp(hidden_states)
|
| 366 |
+
hidden_states = residual + hidden_states
|
| 367 |
+
|
| 368 |
+
return hidden_states
|
| 369 |
+
|
| 370 |
+
class Siglip2Encoder(nn.Module):
|
| 371 |
+
"""
|
| 372 |
+
Transformer encoder consisting of `config.num_hidden_layers` self attention layers. Each layer is a
|
| 373 |
+
[`Siglip2EncoderLayer`].
|
| 374 |
+
|
| 375 |
+
Args:
|
| 376 |
+
config: Siglip2NavitConfig
|
| 377 |
+
"""
|
| 378 |
+
|
| 379 |
+
def __init__(self, config: Siglip2NavitConfig):
|
| 380 |
+
super().__init__()
|
| 381 |
+
self.config = config
|
| 382 |
+
self.layers = nn.ModuleList([Siglip2EncoderLayer(config) for _ in range(config.num_hidden_layers)])
|
| 383 |
+
self.gradient_checkpointing = False
|
| 384 |
+
|
| 385 |
+
self.rotary_pos_emb = VisionRotaryEmbedding(config.hidden_size // config.num_attention_heads // 2)
|
| 386 |
+
self.patch_size = config.patch_size
|
| 387 |
+
self.hidden_stride = config.hidden_stride
|
| 388 |
+
self.window_size = config.window_size
|
| 389 |
+
self.spatial_merge_unit = config.hidden_stride * config.hidden_stride
|
| 390 |
+
self.fullatt_block_indexes = None if config.fullatt_block_indexes is None else [int(i) for i in config.fullatt_block_indexes.split('|')]
|
| 391 |
+
|
| 392 |
+
|
| 393 |
+
# copied from qwen2.5_vl
|
| 394 |
+
def rot_pos_emb(self, grid_thw):
|
| 395 |
+
pos_ids = []
|
| 396 |
+
for t, h, w in grid_thw:
|
| 397 |
+
hpos_ids = torch.arange(h).unsqueeze(1).expand(-1, w)
|
| 398 |
+
hpos_ids = hpos_ids.reshape(
|
| 399 |
+
h // self.hidden_stride,
|
| 400 |
+
self.hidden_stride,
|
| 401 |
+
w // self.hidden_stride,
|
| 402 |
+
self.hidden_stride,
|
| 403 |
+
)
|
| 404 |
+
hpos_ids = hpos_ids.permute(0, 2, 1, 3)
|
| 405 |
+
hpos_ids = hpos_ids.flatten()
|
| 406 |
+
|
| 407 |
+
wpos_ids = torch.arange(w).unsqueeze(0).expand(h, -1)
|
| 408 |
+
wpos_ids = wpos_ids.reshape(
|
| 409 |
+
h // self.hidden_stride,
|
| 410 |
+
self.hidden_stride,
|
| 411 |
+
w // self.hidden_stride,
|
| 412 |
+
self.hidden_stride,
|
| 413 |
+
)
|
| 414 |
+
wpos_ids = wpos_ids.permute(0, 2, 1, 3)
|
| 415 |
+
wpos_ids = wpos_ids.flatten()
|
| 416 |
+
pos_ids.append(torch.stack([hpos_ids, wpos_ids], dim=-1).repeat(t, 1))
|
| 417 |
+
pos_ids = torch.cat(pos_ids, dim=0)
|
| 418 |
+
max_grid_size = grid_thw[:, 1:].max()
|
| 419 |
+
rotary_pos_emb_full = self.rotary_pos_emb(max_grid_size)
|
| 420 |
+
rotary_pos_emb = rotary_pos_emb_full[pos_ids].flatten(1)
|
| 421 |
+
return rotary_pos_emb
|
| 422 |
+
|
| 423 |
+
def get_window_index(self, grid_thw):
|
| 424 |
+
window_index: list = []
|
| 425 |
+
cu_window_seqlens: list = [0]
|
| 426 |
+
window_index_id = 0
|
| 427 |
+
vit_merger_window_size = self.window_size // self.hidden_stride // self.patch_size # patch (after merge) number in each window
|
| 428 |
+
|
| 429 |
+
for grid_t, grid_h, grid_w in grid_thw:
|
| 430 |
+
llm_grid_h, llm_grid_w = (
|
| 431 |
+
grid_h // self.hidden_stride, # number of patch after merge
|
| 432 |
+
grid_w // self.hidden_stride,
|
| 433 |
+
)
|
| 434 |
+
index = torch.arange(grid_t * llm_grid_h * llm_grid_w).reshape(grid_t, llm_grid_h, llm_grid_w)
|
| 435 |
+
pad_h = vit_merger_window_size - llm_grid_h % vit_merger_window_size
|
| 436 |
+
pad_w = vit_merger_window_size - llm_grid_w % vit_merger_window_size
|
| 437 |
+
num_windows_h = (llm_grid_h + pad_h) // vit_merger_window_size
|
| 438 |
+
num_windows_w = (llm_grid_w + pad_w) // vit_merger_window_size
|
| 439 |
+
index_padded = F.pad(index, (0, pad_w, 0, pad_h), "constant", -100)
|
| 440 |
+
index_padded = index_padded.reshape(
|
| 441 |
+
grid_t,
|
| 442 |
+
num_windows_h,
|
| 443 |
+
vit_merger_window_size,
|
| 444 |
+
num_windows_w,
|
| 445 |
+
vit_merger_window_size,
|
| 446 |
+
)
|
| 447 |
+
index_padded = index_padded.permute(0, 1, 3, 2, 4).reshape(
|
| 448 |
+
grid_t,
|
| 449 |
+
num_windows_h * num_windows_w,
|
| 450 |
+
vit_merger_window_size,
|
| 451 |
+
vit_merger_window_size,
|
| 452 |
+
)
|
| 453 |
+
seqlens = (index_padded != -100).sum([2, 3]).reshape(-1)
|
| 454 |
+
index_padded = index_padded.reshape(-1)
|
| 455 |
+
index_new = index_padded[index_padded != -100]
|
| 456 |
+
window_index.append(index_new + window_index_id)
|
| 457 |
+
cu_seqlens_tmp = seqlens.cumsum(0) * self.spatial_merge_unit + cu_window_seqlens[-1]
|
| 458 |
+
cu_window_seqlens.extend(cu_seqlens_tmp.tolist())
|
| 459 |
+
window_index_id += (grid_t * llm_grid_h * llm_grid_w).item()
|
| 460 |
+
window_index = torch.cat(window_index, dim=0)
|
| 461 |
+
|
| 462 |
+
return window_index, cu_window_seqlens
|
| 463 |
+
|
| 464 |
+
# Ignore copy
|
| 465 |
+
def forward(
|
| 466 |
+
self,
|
| 467 |
+
inputs_embeds,
|
| 468 |
+
grid_thws: torch.Tensor,
|
| 469 |
+
output_hidden_states: bool = False,
|
| 470 |
+
) -> Tuple[torch.Tensor, Optional[Tuple[torch.Tensor, ...]]]:
|
| 471 |
+
r"""
|
| 472 |
+
Args:
|
| 473 |
+
inputs_embeds (`torch.FloatTensor` of shape `(batch_size, sequence_length, hidden_size)`):
|
| 474 |
+
Optionally, instead of passing `input_ids` you can choose to directly pass an embedded representation.
|
| 475 |
+
This is useful if you want more control over how to convert `input_ids` indices into associated vectors
|
| 476 |
+
than the model's internal embedding lookup matrix.
|
| 477 |
+
attention_mask (`torch.Tensor` of shape `(batch_size, sequence_length)`, *optional*):
|
| 478 |
+
Mask to avoid performing attention on padding token indices. Mask values selected in `[0, 1]`:
|
| 479 |
+
|
| 480 |
+
- 1 for tokens that are **not masked**,
|
| 481 |
+
- 0 for tokens that are **masked**.
|
| 482 |
+
|
| 483 |
+
[What are attention masks?](../glossary#attention-mask)
|
| 484 |
+
output_attentions (`bool`, *optional*):
|
| 485 |
+
Whether or not to return the attentions tensors of all attention layers. See `attentions` under
|
| 486 |
+
returned tensors for more detail.
|
| 487 |
+
output_hidden_states (`bool`, *optional*):
|
| 488 |
+
Whether or not to return the hidden states of all layers. See `hidden_states` under returned tensors
|
| 489 |
+
for more detail.
|
| 490 |
+
return_dict (`bool`, *optional*):
|
| 491 |
+
Whether or not to return a [`~utils.ModelOutput`] instead of a plain tuple.
|
| 492 |
+
"""
|
| 493 |
+
|
| 494 |
+
rotary_pos_emb = self.rot_pos_emb(grid_thws)
|
| 495 |
+
window_index, cu_window_seqlens = self.get_window_index(grid_thws)
|
| 496 |
+
cu_window_seqlens = torch.tensor(
|
| 497 |
+
cu_window_seqlens,
|
| 498 |
+
device=inputs_embeds.device,
|
| 499 |
+
dtype=grid_thws.dtype if torch.jit.is_tracing() else torch.int32,
|
| 500 |
+
)
|
| 501 |
+
cu_window_seqlens = torch.unique_consecutive(cu_window_seqlens)
|
| 502 |
+
|
| 503 |
+
seq_len, _ = inputs_embeds.size()
|
| 504 |
+
inputs_embeds = inputs_embeds.reshape(seq_len // self.spatial_merge_unit, self.spatial_merge_unit, -1)
|
| 505 |
+
inputs_embeds = inputs_embeds[window_index, :, :]
|
| 506 |
+
inputs_embeds = inputs_embeds.reshape(seq_len, -1)
|
| 507 |
+
rotary_pos_emb = rotary_pos_emb.reshape(seq_len // self.spatial_merge_unit, self.spatial_merge_unit, -1)
|
| 508 |
+
rotary_pos_emb = rotary_pos_emb[window_index, :, :]
|
| 509 |
+
rotary_pos_emb = rotary_pos_emb.reshape(seq_len, -1)
|
| 510 |
+
emb = torch.cat((rotary_pos_emb, rotary_pos_emb), dim=-1)
|
| 511 |
+
position_embeddings = (emb.cos(), emb.sin())
|
| 512 |
+
|
| 513 |
+
cu_seqlens = torch.repeat_interleave(grid_thws[:, 1] * grid_thws[:, 2], grid_thws[:, 0]).cumsum(
|
| 514 |
+
dim=0,
|
| 515 |
+
# Select dtype based on the following factors:
|
| 516 |
+
# - FA2 requires that cu_seqlens_q must have dtype int32
|
| 517 |
+
# - torch.onnx.export requires that cu_seqlens_q must have same dtype as grid_thw
|
| 518 |
+
# See https://github.com/huggingface/transformers/pull/34852 for more information
|
| 519 |
+
dtype=grid_thws.dtype if torch.jit.is_tracing() else torch.int32,
|
| 520 |
+
)
|
| 521 |
+
cu_seqlens = F.pad(cu_seqlens, (1, 0), value=0)
|
| 522 |
+
|
| 523 |
+
reverse_indices = torch.argsort(window_index)
|
| 524 |
+
encoder_states = () if output_hidden_states else None
|
| 525 |
+
|
| 526 |
+
hidden_states = inputs_embeds
|
| 527 |
+
for index, block in enumerate(self.layers):
|
| 528 |
+
if self.fullatt_block_indexes is None or index in self.fullatt_block_indexes:
|
| 529 |
+
cu_seqlens_tmp = cu_seqlens
|
| 530 |
+
else:
|
| 531 |
+
cu_seqlens_tmp = cu_window_seqlens
|
| 532 |
+
if self.gradient_checkpointing and self.training:
|
| 533 |
+
hidden_states = self._gradient_checkpointing_func(block.__call__, hidden_states, cu_seqlens_tmp, position_embeddings)
|
| 534 |
+
else:
|
| 535 |
+
hidden_states = block(hidden_states, cu_seqlens_tmp, position_embeddings)
|
| 536 |
+
if output_hidden_states:
|
| 537 |
+
hidden_states_ = hidden_states.reshape(seq_len // self.spatial_merge_unit, self.spatial_merge_unit, -1)
|
| 538 |
+
encoder_states += (hidden_states_[reverse_indices, :].reshape(seq_len, -1),)
|
| 539 |
+
# tokens = self.post_trunk_norm(tokens)
|
| 540 |
+
hidden_states = hidden_states.reshape(seq_len // self.spatial_merge_unit, self.spatial_merge_unit, -1)
|
| 541 |
+
hidden_states = hidden_states[reverse_indices, :].reshape(seq_len, -1)
|
| 542 |
+
|
| 543 |
+
return hidden_states, encoder_states
|
| 544 |
+
|
| 545 |
+
class Siglip2VisionTransformer(nn.Module):
|
| 546 |
+
def __init__(self, config: Siglip2NavitConfig):
|
| 547 |
+
super().__init__()
|
| 548 |
+
self.config = config
|
| 549 |
+
embed_dim = config.hidden_size
|
| 550 |
+
|
| 551 |
+
self.embeddings = Siglip2VisionEmbeddings(config)
|
| 552 |
+
self.encoder = Siglip2Encoder(config)
|
| 553 |
+
self.post_layernorm = nn.LayerNorm(embed_dim, eps=config.layer_norm_eps)
|
| 554 |
+
self._use_flash_attention_2 = config._attn_implementation == "flash_attention_2"
|
| 555 |
+
|
| 556 |
+
def forward(
|
| 557 |
+
self,
|
| 558 |
+
pixel_values: torch.FloatTensor,
|
| 559 |
+
grid_thws: torch.LongTensor,
|
| 560 |
+
output_hidden_states: Optional[bool] = True,
|
| 561 |
+
return_dict: Optional[bool] = True,
|
| 562 |
+
) -> Union[
|
| 563 |
+
Tuple[torch.Tensor],
|
| 564 |
+
Tuple[torch.Tensor, Tuple[torch.Tensor, ...]],
|
| 565 |
+
BaseModelOutputWithNoAttention,
|
| 566 |
+
]:
|
| 567 |
+
r"""
|
| 568 |
+
spatial_shapes (`torch.LongTensor` of shape `(batch_size, 2)`):
|
| 569 |
+
Tensor containing the spatial dimensions (height, width) of the input images.
|
| 570 |
+
"""
|
| 571 |
+
# output_attentions = output_attentions if output_attentions is not None else self.config.output_attentions
|
| 572 |
+
# output_hidden_states = (
|
| 573 |
+
# output_hidden_states if output_hidden_states is not None else self.config.output_hidden_states
|
| 574 |
+
# )
|
| 575 |
+
|
| 576 |
+
hidden_states = self.embeddings(pixel_values, grid_thws)
|
| 577 |
+
|
| 578 |
+
last_hidden_state, hidden_states = self.encoder(hidden_states, grid_thws, output_hidden_states)
|
| 579 |
+
last_hidden_state = self.post_layernorm(last_hidden_state)
|
| 580 |
+
|
| 581 |
+
if not return_dict:
|
| 582 |
+
output = (last_hidden_state,)
|
| 583 |
+
output += (hidden_states,) if output_hidden_states else ()
|
| 584 |
+
return output
|
| 585 |
+
|
| 586 |
+
return BaseModelOutputWithNoAttention(
|
| 587 |
+
last_hidden_state=last_hidden_state,
|
| 588 |
+
hidden_states=hidden_states
|
| 589 |
+
)
|
| 590 |
+
|
| 591 |
+
class Siglip2PreTrainedModel(PreTrainedModel):
|
| 592 |
+
config_class = Siglip2NavitConfig
|
| 593 |
+
base_model_prefix = "siglip2_navit"
|
| 594 |
+
supports_gradient_checkpointing = True
|
| 595 |
+
|
| 596 |
+
_no_split_modules = [
|
| 597 |
+
"Siglip2VisionEmbeddings",
|
| 598 |
+
"Siglip2EncoderLayer",
|
| 599 |
+
]
|
| 600 |
+
_supports_flash_attn_2 = True
|
| 601 |
+
_supports_sdpa = False
|
| 602 |
+
_supports_flex_attn = False
|
| 603 |
+
_supports_attention_backend = True
|
| 604 |
+
|
| 605 |
+
|
| 606 |
+
class Siglip2NavitModel(Siglip2PreTrainedModel):
|
| 607 |
+
config_class = Siglip2NavitConfig
|
| 608 |
+
main_input_name = "pixel_values"
|
| 609 |
+
|
| 610 |
+
def __init__(self, config: Siglip2NavitConfig):
|
| 611 |
+
super().__init__(config)
|
| 612 |
+
|
| 613 |
+
self.vision_model = Siglip2VisionTransformer(config)
|
| 614 |
+
|
| 615 |
+
def get_input_embeddings(self) -> nn.Module:
|
| 616 |
+
return self.vision_model.embeddings.patch_embedding
|
| 617 |
+
|
| 618 |
+
def forward(
|
| 619 |
+
self,
|
| 620 |
+
pixel_values: torch.FloatTensor,
|
| 621 |
+
grid_thws: torch.LongTensor,
|
| 622 |
+
output_hidden_states: Optional[bool] = None,
|
| 623 |
+
return_dict: Optional[bool] = None,
|
| 624 |
+
) -> Union[
|
| 625 |
+
Tuple[torch.Tensor],
|
| 626 |
+
Tuple[torch.Tensor, Tuple[torch.Tensor, ...]],
|
| 627 |
+
BaseModelOutputWithNoAttention,
|
| 628 |
+
]:
|
| 629 |
+
|
| 630 |
+
if output_hidden_states is None:
|
| 631 |
+
output_hidden_states = self.config.output_hidden_states
|
| 632 |
+
if return_dict is None:
|
| 633 |
+
return_dict = self.config.use_return_dict
|
| 634 |
+
|
| 635 |
+
return self.vision_model(
|
| 636 |
+
pixel_values=pixel_values,
|
| 637 |
+
grid_thws=grid_thws,
|
| 638 |
+
output_hidden_states=output_hidden_states,
|
| 639 |
+
return_dict=return_dict,
|
| 640 |
+
)
|
| 641 |
+
|
| 642 |
+
class OXREmbedding(torch.nn.Embedding):
|
| 643 |
+
"""
|
| 644 |
+
A visual embedding layer that can handle both discrete token IDs (long) and continuous
|
| 645 |
+
soft-token probabilities (float).
|
| 646 |
+
"""
|
| 647 |
+
|
| 648 |
+
def forward(self, visual_tokens: Tensor) -> Tensor:
|
| 649 |
+
if visual_tokens.dtype in [torch.int8, torch.int16, torch.int32, torch.int64, torch.long]:
|
| 650 |
+
return super().forward(visual_tokens)
|
| 651 |
+
# Handle soft tokens (probabilities) by matrix multiplication with the embedding weight
|
| 652 |
+
return torch.matmul(visual_tokens, self.weight)
|
| 653 |
+
|
| 654 |
+
|
| 655 |
+
class OXRVisualTokenizer(torch.nn.Module):
|
| 656 |
+
"""
|
| 657 |
+
Tokenizes images or videos into a sequence of continuous visual tokens.
|
| 658 |
+
"""
|
| 659 |
+
|
| 660 |
+
def __init__(self, vit, visual_vocab_size, image_processor_name_or_path, *args, **kwargs):
|
| 661 |
+
super().__init__(*args, **kwargs)
|
| 662 |
+
self.vit = vit
|
| 663 |
+
image_processor_kwargs = {"do_center_crop": False}
|
| 664 |
+
if int(TRANSFORMERS_VERSION.split(".", 1)[0]) >= 5:
|
| 665 |
+
image_processor_kwargs["backend"] = "pil"
|
| 666 |
+
else:
|
| 667 |
+
image_processor_kwargs["use_fast"] = False
|
| 668 |
+
self.image_processor = AutoImageProcessor.from_pretrained(
|
| 669 |
+
image_processor_name_or_path,
|
| 670 |
+
**image_processor_kwargs,
|
| 671 |
+
)
|
| 672 |
+
head_dim = visual_vocab_size - len(INDICATOR_IDS)
|
| 673 |
+
self.head = torch.nn.Sequential(
|
| 674 |
+
torch.nn.Linear(self.vit.config.hidden_size * self.vit.config.hidden_stride ** 2, head_dim, bias=False),
|
| 675 |
+
torch.nn.LayerNorm(head_dim)
|
| 676 |
+
)
|
| 677 |
+
|
| 678 |
+
def _encode(self, pixel_values, grid_thws):
|
| 679 |
+
output = self.vit(pixel_values, grid_thws, output_hidden_states=True, return_dict=True)
|
| 680 |
+
features = output.hidden_states[-1]
|
| 681 |
+
seq_len, _ = features.shape
|
| 682 |
+
features = features.reshape(seq_len // (self.vit.config.hidden_stride ** 2), -1)
|
| 683 |
+
return features
|
| 684 |
+
|
| 685 |
+
# Adapted from qwen2_vl
|
| 686 |
+
@staticmethod
|
| 687 |
+
def smart_resize(
|
| 688 |
+
height: int, width: int, factor: int = 28, min_pixels: int = 448 * 448, max_pixels: int = 1344 * 1792
|
| 689 |
+
):
|
| 690 |
+
"""Rescales the image so that the following conditions are met:
|
| 691 |
+
1. Both dimensions are divisible by 'factor'.
|
| 692 |
+
2. The total number of pixels is within ['min_pixels', 'max_pixels'].
|
| 693 |
+
3. The aspect ratio is maintained as closely as possible.
|
| 694 |
+
"""
|
| 695 |
+
if height < factor or width < factor:
|
| 696 |
+
if height < width:
|
| 697 |
+
width = round(factor / height * width)
|
| 698 |
+
height = factor
|
| 699 |
+
else:
|
| 700 |
+
height = round(factor / width * height)
|
| 701 |
+
width = factor
|
| 702 |
+
|
| 703 |
+
elif max(height, width) / min(height, width) > 200:
|
| 704 |
+
if height > width:
|
| 705 |
+
height = 200 * width
|
| 706 |
+
else:
|
| 707 |
+
width = 200 * height
|
| 708 |
+
|
| 709 |
+
h_bar = round(height / factor) * factor
|
| 710 |
+
w_bar = round(width / factor) * factor
|
| 711 |
+
if h_bar * w_bar > max_pixels:
|
| 712 |
+
beta = math.sqrt((height * width) / max_pixels)
|
| 713 |
+
h_bar = math.floor(height / beta / factor) * factor
|
| 714 |
+
w_bar = math.floor(width / beta / factor) * factor
|
| 715 |
+
elif h_bar * w_bar < min_pixels:
|
| 716 |
+
beta = math.sqrt(min_pixels / (height * width))
|
| 717 |
+
h_bar = math.ceil(height * beta / factor) * factor
|
| 718 |
+
w_bar = math.ceil(width * beta / factor) * factor
|
| 719 |
+
return h_bar, w_bar
|
| 720 |
+
|
| 721 |
+
def preprocess(
|
| 722 |
+
self,
|
| 723 |
+
image: Optional[PIL.Image.Image] = None,
|
| 724 |
+
video: Optional[List[PIL.Image.Image]] = None,
|
| 725 |
+
min_pixels: Optional[int] = None,
|
| 726 |
+
max_pixels: Optional[int] = None
|
| 727 |
+
):
|
| 728 |
+
patch_size = self.vit.config.patch_size
|
| 729 |
+
temporal_patch_size = self.vit.config.temporal_patch_size
|
| 730 |
+
hidden_stride = self.vit.config.hidden_stride
|
| 731 |
+
assert (image is None) ^ (video is None), "Invalid input: expect either image or video"
|
| 732 |
+
if image is not None:
|
| 733 |
+
images = [image]
|
| 734 |
+
else:
|
| 735 |
+
images = video
|
| 736 |
+
images = [image.convert("RGB") if image.mode != 'RGB' else image for image in images]
|
| 737 |
+
width, height = images[0].size
|
| 738 |
+
processed_images = []
|
| 739 |
+
for image in images:
|
| 740 |
+
resized_height, resized_width = self.smart_resize(
|
| 741 |
+
height,
|
| 742 |
+
width,
|
| 743 |
+
factor=patch_size * hidden_stride,
|
| 744 |
+
min_pixels=min_pixels,
|
| 745 |
+
max_pixels=max_pixels,
|
| 746 |
+
)
|
| 747 |
+
new_size = dict(height=resized_height, width=resized_width)
|
| 748 |
+
new_image = self.image_processor.preprocess(image, size=new_size, return_tensors="np")['pixel_values'][0]
|
| 749 |
+
processed_images.append(new_image)
|
| 750 |
+
|
| 751 |
+
patches = np.array(processed_images)
|
| 752 |
+
if patches.shape[0] % temporal_patch_size != 0:
|
| 753 |
+
repeats = np.repeat(patches[-1][np.newaxis], temporal_patch_size - 1, axis=0)
|
| 754 |
+
patches = np.concatenate([patches, repeats], axis=0)
|
| 755 |
+
channel = patches.shape[1]
|
| 756 |
+
grid_t = patches.shape[0] // temporal_patch_size
|
| 757 |
+
grid_h, grid_w = resized_height // patch_size, resized_width // patch_size
|
| 758 |
+
grid_thw = torch.tensor([[grid_t, grid_h, grid_w]])
|
| 759 |
+
|
| 760 |
+
patches = patches.reshape(
|
| 761 |
+
grid_t, temporal_patch_size, channel,
|
| 762 |
+
grid_h // hidden_stride, hidden_stride, patch_size,
|
| 763 |
+
grid_w // hidden_stride, hidden_stride, patch_size,
|
| 764 |
+
)
|
| 765 |
+
patches = patches.transpose(0, 3, 6, 4, 7, 2, 1, 5, 8)
|
| 766 |
+
flatten_patches = patches.reshape(
|
| 767 |
+
grid_t * grid_h * grid_w, channel * temporal_patch_size * patch_size * patch_size
|
| 768 |
+
)
|
| 769 |
+
flatten_patches = torch.tensor(flatten_patches)
|
| 770 |
+
|
| 771 |
+
return flatten_patches, grid_thw
|
| 772 |
+
|
| 773 |
+
def forward(
|
| 774 |
+
self, pixel_values, grid_thws
|
| 775 |
+
) -> torch.Tensor: # [BatchSize, ImageShape] -> [BatchSize, #Token, VocabSize]
|
| 776 |
+
features = self._encode(pixel_values, grid_thws)
|
| 777 |
+
logits = self.head(features)
|
| 778 |
+
tokens = torch.softmax(logits, dim=-1, dtype=torch.float32).to(logits.dtype)
|
| 779 |
+
|
| 780 |
+
token_len, _ = tokens.shape
|
| 781 |
+
padding_tensor = torch.zeros(size=(token_len, len(INDICATOR_IDS)),
|
| 782 |
+
dtype=tokens.dtype,
|
| 783 |
+
device=tokens.device,
|
| 784 |
+
layout=tokens.layout,
|
| 785 |
+
requires_grad=False)
|
| 786 |
+
tokens = torch.cat((tokens, padding_tensor), dim=1)
|
| 787 |
+
return tokens
|
| 788 |
+
|
| 789 |
+
|
| 790 |
+
class OXRPreTrainedModel(PreTrainedModel):
|
| 791 |
+
config_class = OXRConfig
|
| 792 |
+
base_model_prefix = "oxr"
|
| 793 |
+
|
| 794 |
+
|
| 795 |
+
class OXR(OXRPreTrainedModel):
|
| 796 |
+
_supports_flash_attn_2 = True
|
| 797 |
+
|
| 798 |
+
def __init__(self, config: OXRConfig, *inputs, **kwargs):
|
| 799 |
+
super().__init__(config, *inputs, **kwargs)
|
| 800 |
+
|
| 801 |
+
self.llm = AutoModelForCausalLM.from_config(self.config.llm_config)
|
| 802 |
+
assert self.config.hidden_size == self.llm.config.hidden_size, "hidden size mismatch"
|
| 803 |
+
self.text_tokenizer = AutoTokenizer.from_pretrained(
|
| 804 |
+
self.config.name_or_path,
|
| 805 |
+
trust_remote_code=True,
|
| 806 |
+
)
|
| 807 |
+
self.visual_tokenizer = OXRVisualTokenizer(vit=AutoModel.from_config(self.config.vit_config),
|
| 808 |
+
visual_vocab_size=self.config.visual_vocab_size,
|
| 809 |
+
image_processor_name_or_path=self.config.name_or_path)
|
| 810 |
+
|
| 811 |
+
self.vte = OXREmbedding(self.config.visual_vocab_size, self.config.hidden_size,
|
| 812 |
+
device=self.visual_tokenizer.vit.device, dtype=self.visual_tokenizer.vit.dtype)
|
| 813 |
+
indicator_token_indices = torch.arange(
|
| 814 |
+
self.config.visual_vocab_size - len(INDICATOR_IDS),
|
| 815 |
+
self.config.visual_vocab_size,
|
| 816 |
+
dtype=torch.long
|
| 817 |
+
)
|
| 818 |
+
self.register_buffer("indicator_token_indices", indicator_token_indices, persistent=False)
|
| 819 |
+
|
| 820 |
+
def _merge_modules(modules_list: tuple):
|
| 821 |
+
merged_modules = []
|
| 822 |
+
for modules in modules_list:
|
| 823 |
+
merged_modules.extend(modules if modules else [])
|
| 824 |
+
return merged_modules
|
| 825 |
+
|
| 826 |
+
# Standard model configurations for parallelism and device placement
|
| 827 |
+
self._no_split_modules = _merge_modules(
|
| 828 |
+
(self.llm._no_split_modules, self.visual_tokenizer.vit._no_split_modules))
|
| 829 |
+
self._skip_keys_device_placement = self.llm._skip_keys_device_placement
|
| 830 |
+
self._keep_in_fp32_modules = _merge_modules(
|
| 831 |
+
(self.llm._keep_in_fp32_modules, self.visual_tokenizer.vit._keep_in_fp32_modules))
|
| 832 |
+
self.is_parallelizable = all((
|
| 833 |
+
getattr(self.llm, "is_parallelizable", False),
|
| 834 |
+
getattr(self.visual_tokenizer.vit, "is_parallelizable", False),
|
| 835 |
+
))
|
| 836 |
+
self.supports_gradient_checkpointing = True
|
| 837 |
+
self.post_init()
|
| 838 |
+
|
| 839 |
+
def tie_weights(self, missing_keys: Optional[set[str]] = None, recompute_mapping: bool = True):
|
| 840 |
+
self.llm.tie_weights()
|
| 841 |
+
try:
|
| 842 |
+
return PreTrainedModel.tie_weights(
|
| 843 |
+
self,
|
| 844 |
+
missing_keys=missing_keys,
|
| 845 |
+
recompute_mapping=recompute_mapping,
|
| 846 |
+
)
|
| 847 |
+
except TypeError as exc:
|
| 848 |
+
if "unexpected keyword argument" not in str(exc):
|
| 849 |
+
raise
|
| 850 |
+
return PreTrainedModel.tie_weights(self)
|
| 851 |
+
|
| 852 |
+
def get_wte(self):
|
| 853 |
+
return self.llm.get_input_embeddings()
|
| 854 |
+
|
| 855 |
+
def forward(
|
| 856 |
+
self,
|
| 857 |
+
input_ids: torch.Tensor,
|
| 858 |
+
attention_mask: torch.Tensor,
|
| 859 |
+
pixel_values: Optional[torch.Tensor],
|
| 860 |
+
grid_thws: Optional[torch.Tensor],
|
| 861 |
+
labels: Optional[torch.Tensor] = None,
|
| 862 |
+
**kwargs
|
| 863 |
+
):
|
| 864 |
+
inputs_embeds = self.merge_multimodal(
|
| 865 |
+
input_ids=input_ids,
|
| 866 |
+
pixel_values=pixel_values,
|
| 867 |
+
grid_thws=grid_thws,
|
| 868 |
+
)
|
| 869 |
+
return self.llm(inputs_embeds=inputs_embeds, attention_mask=attention_mask, labels=labels, **kwargs)
|
| 870 |
+
|
| 871 |
+
def merge_multimodal(
|
| 872 |
+
self,
|
| 873 |
+
input_ids: torch.Tensor,
|
| 874 |
+
pixel_values: Optional[torch.Tensor],
|
| 875 |
+
grid_thws: Optional[torch.Tensor],
|
| 876 |
+
):
|
| 877 |
+
placeholder_token_mask = torch.lt(input_ids, 0)
|
| 878 |
+
multimodal_embeds = self.get_wte()(torch.masked_fill(input_ids, placeholder_token_mask, 0))
|
| 879 |
+
|
| 880 |
+
if pixel_values is not None:
|
| 881 |
+
visual_indicator_embeds = self.vte(self.indicator_token_indices).to(
|
| 882 |
+
dtype=multimodal_embeds.dtype, device=multimodal_embeds.device
|
| 883 |
+
)
|
| 884 |
+
visual_tokens = self.visual_tokenizer(pixel_values, grid_thws)
|
| 885 |
+
visual_embeds = self.vte(visual_tokens).to(dtype=multimodal_embeds.dtype, device=multimodal_embeds.device)
|
| 886 |
+
|
| 887 |
+
for i, indicator_id in enumerate(INDICATOR_IDS):
|
| 888 |
+
multimodal_embeds[input_ids == indicator_id] = visual_indicator_embeds[i]
|
| 889 |
+
multimodal_embeds[input_ids == VISUAL_ATOM_ID] = visual_embeds
|
| 890 |
+
|
| 891 |
+
return multimodal_embeds
|
| 892 |
+
|
| 893 |
+
def _merge_inputs(
|
| 894 |
+
self, raw_input_ids, placeholder_id, grid_thws, indicator_begin_id, indicator_end_id
|
| 895 |
+
):
|
| 896 |
+
input_ids = []
|
| 897 |
+
prev_index = 0
|
| 898 |
+
placeholder_indexes = [i for i, v in enumerate(raw_input_ids) if v == placeholder_id]
|
| 899 |
+
for placeholder_index, grid_thw in zip(placeholder_indexes, grid_thws):
|
| 900 |
+
input_ids.extend(raw_input_ids[prev_index:placeholder_index])
|
| 901 |
+
num_image_atoms = grid_thw.prod().item()
|
| 902 |
+
num_image_atoms //= self.visual_tokenizer.vit.config.hidden_stride ** 2
|
| 903 |
+
num_image_atoms //= self.visual_tokenizer.vit.config.temporal_patch_size
|
| 904 |
+
input_ids.extend([indicator_begin_id] + [VISUAL_ATOM_ID] * num_image_atoms + [indicator_end_id])
|
| 905 |
+
prev_index = placeholder_index + 1
|
| 906 |
+
input_ids.extend(raw_input_ids[prev_index:])
|
| 907 |
+
return input_ids
|
| 908 |
+
|
| 909 |
+
def _tokenize_with_visual_placeholder(self, text):
|
| 910 |
+
placeholder = VIDEO_PLACEHOLDER if VIDEO_PLACEHOLDER in text else IMAGE_PLACEHOLDER
|
| 911 |
+
placeholder_id = VIDEO_PLACEHOLDER_ID if VIDEO_PLACEHOLDER in text else IMAGE_PLACEHOLDER_ID
|
| 912 |
+
chunks = [self.text_tokenizer(chunk, add_special_tokens=False).input_ids for chunk in text.split(placeholder)]
|
| 913 |
+
input_ids = chunks[0]
|
| 914 |
+
for chunk in chunks[1:]:
|
| 915 |
+
input_ids.append(placeholder_id)
|
| 916 |
+
input_ids.extend(chunk)
|
| 917 |
+
return input_ids
|
| 918 |
+
|
| 919 |
+
def preprocess_inputs(
|
| 920 |
+
self,
|
| 921 |
+
messages: List[Union[str, Dict]],
|
| 922 |
+
min_pixels=448 * 448,
|
| 923 |
+
max_pixels=1344 * 1792,
|
| 924 |
+
add_generation_prompt=True,
|
| 925 |
+
enable_thinking=False
|
| 926 |
+
):
|
| 927 |
+
text = self.text_tokenizer.apply_chat_template(
|
| 928 |
+
messages,
|
| 929 |
+
tokenize=False,
|
| 930 |
+
add_generation_prompt=add_generation_prompt,
|
| 931 |
+
enable_thinking=enable_thinking
|
| 932 |
+
)
|
| 933 |
+
input_ids = self._tokenize_with_visual_placeholder(text)
|
| 934 |
+
images = []
|
| 935 |
+
videos = []
|
| 936 |
+
for message in messages:
|
| 937 |
+
content = message["content"]
|
| 938 |
+
if isinstance(content, list):
|
| 939 |
+
images.extend([item["image"] for item in content if item.get("image") is not None])
|
| 940 |
+
videos.extend([item["video"] for item in content if item.get("video") is not None])
|
| 941 |
+
if images and videos:
|
| 942 |
+
raise ValueError(
|
| 943 |
+
"Multiple visual input data types detected (both image and video provided). "
|
| 944 |
+
"This model supports only one type of visual input data at a time. "
|
| 945 |
+
"Please provide either image or video, but not both."
|
| 946 |
+
)
|
| 947 |
+
|
| 948 |
+
pixel_values, grid_thws = None, None
|
| 949 |
+
if images:
|
| 950 |
+
pixel_values, grid_thws = zip(
|
| 951 |
+
*(self.visual_tokenizer.preprocess(image=image, min_pixels=min_pixels, max_pixels=max_pixels)
|
| 952 |
+
for image in images)
|
| 953 |
+
)
|
| 954 |
+
input_ids = self._merge_inputs(
|
| 955 |
+
input_ids, IMAGE_PLACEHOLDER_ID, grid_thws, INDICATOR_IDS[0], INDICATOR_IDS[1]
|
| 956 |
+
)
|
| 957 |
+
pixel_values = torch.cat(pixel_values, dim=0)
|
| 958 |
+
grid_thws = torch.cat(grid_thws, dim=0)
|
| 959 |
+
elif videos:
|
| 960 |
+
assert len(videos) == 1, "only support single video"
|
| 961 |
+
pixel_values, grid_thws = self.visual_tokenizer.preprocess(
|
| 962 |
+
video=videos[0], min_pixels=min_pixels, max_pixels=max_pixels
|
| 963 |
+
)
|
| 964 |
+
input_ids = self._merge_inputs(
|
| 965 |
+
input_ids, VIDEO_PLACEHOLDER_ID, grid_thws, INDICATOR_IDS[2], INDICATOR_IDS[3]
|
| 966 |
+
)
|
| 967 |
+
|
| 968 |
+
input_ids = torch.tensor(input_ids, dtype=torch.long).unsqueeze(0)
|
| 969 |
+
|
| 970 |
+
return input_ids, pixel_values, grid_thws
|
| 971 |
+
|
| 972 |
+
def generate(
|
| 973 |
+
self,
|
| 974 |
+
inputs: Optional[torch.Tensor] = None,
|
| 975 |
+
**kwargs,
|
| 976 |
+
) -> Union[GenerateOutput, torch.LongTensor]:
|
| 977 |
+
attention_mask = torch.ne(inputs, self.text_tokenizer.pad_token_id).to(device=inputs.device)
|
| 978 |
+
inputs_embeds = self.merge_multimodal(
|
| 979 |
+
input_ids=inputs,
|
| 980 |
+
pixel_values=kwargs.pop('pixel_values', None),
|
| 981 |
+
grid_thws=kwargs.pop('grid_thws', None)
|
| 982 |
+
)
|
| 983 |
+
enable_thinking = kwargs.pop('enable_thinking', False)
|
| 984 |
+
enable_thinking_budget = kwargs.pop('enable_thinking_budget', False)
|
| 985 |
+
thinking_budget = kwargs.pop('thinking_budget', 1024)
|
| 986 |
+
|
| 987 |
+
if enable_thinking and enable_thinking_budget:
|
| 988 |
+
actual_max_new_tokens = kwargs['max_new_tokens']
|
| 989 |
+
kwargs['max_new_tokens'] = thinking_budget
|
| 990 |
+
generated_ids = self.llm.generate(inputs=None, inputs_embeds=inputs_embeds, attention_mask=attention_mask, **kwargs)
|
| 991 |
+
output_ids = generated_ids
|
| 992 |
+
output_ids_list = generated_ids[0]
|
| 993 |
+
|
| 994 |
+
# check if the generation has already finished (151645 is <|im_end|>)
|
| 995 |
+
if 151645 not in output_ids_list:
|
| 996 |
+
# check if the thinking process has finished (151668 is </think>)
|
| 997 |
+
# and prepare the second model input
|
| 998 |
+
if 151668 not in output_ids_list:
|
| 999 |
+
early_stopping_text = "\n\nConsidering the limited time by the user, I have to give the solution based on the thinking directly now.\n</think>\n\n"
|
| 1000 |
+
early_stopping_ids = self.text_tokenizer(early_stopping_text, return_tensors="pt", return_attention_mask=False).input_ids.to(inputs.device)
|
| 1001 |
+
input_ids_appendent = torch.cat([output_ids, early_stopping_ids], dim=-1)
|
| 1002 |
+
kwargs['streamer'].put(early_stopping_ids) if 'streamer' in kwargs else None
|
| 1003 |
+
else:
|
| 1004 |
+
input_ids_appendent = output_ids
|
| 1005 |
+
|
| 1006 |
+
|
| 1007 |
+
# second generation
|
| 1008 |
+
new_inputs = torch.cat([inputs, input_ids_appendent], dim=-1)
|
| 1009 |
+
attention_mask = torch.ne(new_inputs, self.text_tokenizer.pad_token_id).to(device=inputs.device)
|
| 1010 |
+
inputs_embeds_appendent = self.merge_multimodal(
|
| 1011 |
+
input_ids=input_ids_appendent,
|
| 1012 |
+
pixel_values=None,
|
| 1013 |
+
grid_thws=None
|
| 1014 |
+
)
|
| 1015 |
+
new_inputs_embeds = torch.cat([inputs_embeds, inputs_embeds_appendent], dim=-2)
|
| 1016 |
+
|
| 1017 |
+
kwargs['max_new_tokens'] = inputs_embeds.size(-2) + actual_max_new_tokens - new_inputs_embeds.size(-2)
|
| 1018 |
+
generated_ids2 = self.llm.generate(inputs=None, inputs_embeds=new_inputs_embeds, attention_mask=attention_mask, **kwargs)
|
| 1019 |
+
kwargs['streamer'].manual_end() if 'streamer' in kwargs else None
|
| 1020 |
+
return torch.cat([input_ids_appendent, generated_ids2], dim=-1)
|
| 1021 |
+
|
| 1022 |
+
else:
|
| 1023 |
+
kwargs['streamer'].manual_end() if 'streamer' in kwargs else None
|
| 1024 |
+
return generated_ids
|
| 1025 |
+
|
| 1026 |
+
else:
|
| 1027 |
+
generated_ids = self.llm.generate(inputs=None, inputs_embeds=inputs_embeds, attention_mask=attention_mask, **kwargs)
|
| 1028 |
+
kwargs['streamer'].manual_end() if 'streamer' in kwargs else None
|
| 1029 |
+
return generated_ids
|
| 1030 |
+
|
| 1031 |
+
|
| 1032 |
+
AutoConfig.register('siglip2_navit', Siglip2NavitConfig)
|
| 1033 |
+
AutoModel.register(Siglip2NavitConfig, Siglip2NavitModel)
|
| 1034 |
+
try:
|
| 1035 |
+
AutoModelForCausalLM.register(OXRConfig, OXR)
|
| 1036 |
+
except ValueError:
|
| 1037 |
+
pass
|
plugins/vllm/README.md
ADDED
|
@@ -0,0 +1,30 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
# OXR vLLM plugin
|
| 2 |
+
|
| 3 |
+
Registers the OXR architecture through `vllm.general_plugins`. Requires
|
| 4 |
+
Python 3.12+, vLLM 0.25.1 and Transformers 5.13.1. It does not modify the
|
| 5 |
+
vLLM installation. The supported Docker runtime uses PyTorch 2.11.0+cu130.
|
| 6 |
+
|
| 7 |
+
Install from the model repository root in a Linux CUDA environment:
|
| 8 |
+
|
| 9 |
+
```bash
|
| 10 |
+
python -m pip install ./plugins/vllm
|
| 11 |
+
```
|
| 12 |
+
|
| 13 |
+
Start with the model files and weights in the repository root:
|
| 14 |
+
|
| 15 |
+
```bash
|
| 16 |
+
VLLM_PLUGINS=oxr vllm serve . \
|
| 17 |
+
--trust-remote-code \
|
| 18 |
+
--served-model-name oxr \
|
| 19 |
+
--chat-template ./chat_template.jinja \
|
| 20 |
+
--dtype bfloat16 \
|
| 21 |
+
--attention-config '{"backend":"TRITON_ATTN"}' \
|
| 22 |
+
--max-model-len 16384
|
| 23 |
+
```
|
| 24 |
+
|
| 25 |
+
The LA model in `layout_analysis/` is served separately by the OXR layout
|
| 26 |
+
analysis service, not by this plugin.
|
| 27 |
+
|
| 28 |
+
To roll back to vLLM 0.19.1, use the previous model plugin together with the
|
| 29 |
+
matching previous OXR launcher and Docker image. Do not install this plugin
|
| 30 |
+
into the old runtime.
|
plugins/vllm/oxr_vllm/__init__.py
ADDED
|
@@ -0,0 +1,11 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
"""Out-of-tree OXR model registration for vLLM."""
|
| 2 |
+
|
| 3 |
+
|
| 4 |
+
def register() -> None:
|
| 5 |
+
"""Register lazily so plugin discovery does not initialize CUDA."""
|
| 6 |
+
from vllm.model_executor.models.registry import ModelRegistry
|
| 7 |
+
|
| 8 |
+
ModelRegistry.register_model("OXR", "oxr_vllm.oxr_model:OXR")
|
| 9 |
+
|
| 10 |
+
|
| 11 |
+
__all__ = ["register"]
|
plugins/vllm/oxr_vllm/oxr_model.py
ADDED
|
@@ -0,0 +1,660 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
"""OXR model implementation for vLLM 0.25.1."""
|
| 2 |
+
|
| 3 |
+
from collections.abc import Iterable, Mapping
|
| 4 |
+
from functools import partial
|
| 5 |
+
from typing import Annotated, Literal
|
| 6 |
+
|
| 7 |
+
import torch
|
| 8 |
+
import torch.nn as nn
|
| 9 |
+
from transformers import BaseImageProcessor, BatchFeature, PretrainedConfig
|
| 10 |
+
|
| 11 |
+
from vllm.config import VllmConfig
|
| 12 |
+
from vllm.config.multimodal import BaseDummyOptions
|
| 13 |
+
from vllm.inputs import MultiModalDataDict
|
| 14 |
+
from vllm.model_executor.layers.linear import ReplicatedLinear
|
| 15 |
+
from vllm.model_executor.layers.quantization import QuantizationConfig
|
| 16 |
+
from vllm.model_executor.models.interfaces import (
|
| 17 |
+
MultiModalEmbeddings,
|
| 18 |
+
SupportsMultiModal,
|
| 19 |
+
SupportsPP,
|
| 20 |
+
)
|
| 21 |
+
from vllm.model_executor.models.siglip2navit import Siglip2NavitModel
|
| 22 |
+
from vllm.model_executor.models.utils import (
|
| 23 |
+
AutoWeightsLoader,
|
| 24 |
+
flatten_bn,
|
| 25 |
+
init_vllm_registered_model,
|
| 26 |
+
maybe_prefix,
|
| 27 |
+
)
|
| 28 |
+
from vllm.multimodal import MULTIMODAL_REGISTRY
|
| 29 |
+
from vllm.multimodal.inputs import MultiModalFieldConfig, MultiModalKwargsItems
|
| 30 |
+
from vllm.multimodal.parse import ImageSize, MultiModalDataItems
|
| 31 |
+
from vllm.multimodal.processing import (
|
| 32 |
+
BaseDummyInputsBuilder,
|
| 33 |
+
BaseMultiModalProcessor,
|
| 34 |
+
BaseProcessingInfo,
|
| 35 |
+
PromptReplacement,
|
| 36 |
+
)
|
| 37 |
+
from vllm.renderers import TokenizeParams
|
| 38 |
+
from vllm.sequence import IntermediateTensors
|
| 39 |
+
from vllm.utils.tensor_schema import TensorSchema, TensorShape
|
| 40 |
+
|
| 41 |
+
from .oxr_processor import OXRProcessor
|
| 42 |
+
|
| 43 |
+
IMAGE_TOKEN = "<image>"
|
| 44 |
+
VIDEO_TOKEN = "<video>"
|
| 45 |
+
IMAGE_PLACEHOLDER_ID = -200
|
| 46 |
+
VIDEO_PLACEHOLDER_ID = -201
|
| 47 |
+
VISUAL_ATOM_ID = -300
|
| 48 |
+
OXR_INDICATOR_IDS = [-301, -302, -303, -304]
|
| 49 |
+
|
| 50 |
+
IMAGE_PAD_TOKEN_MAP = {
|
| 51 |
+
"gemma2": "<unused0>",
|
| 52 |
+
"llama": "<|reserved_special_token_0|>",
|
| 53 |
+
"qwen2": "<|image_pad|>",
|
| 54 |
+
"qwen3": "<|image_pad|>",
|
| 55 |
+
}
|
| 56 |
+
IMAGE_PAD_TOKEN_ID_MAP = {
|
| 57 |
+
"gemma2": 7,
|
| 58 |
+
"llama": 128002,
|
| 59 |
+
"qwen2": 151655,
|
| 60 |
+
"qwen3": 151655,
|
| 61 |
+
}
|
| 62 |
+
|
| 63 |
+
|
| 64 |
+
def get_llm_config(config: PretrainedConfig) -> PretrainedConfig:
|
| 65 |
+
llm_config = getattr(config, "llm_config", None)
|
| 66 |
+
if llm_config is not None:
|
| 67 |
+
return llm_config
|
| 68 |
+
|
| 69 |
+
text_config = getattr(config, "text_config", None)
|
| 70 |
+
if text_config is not None:
|
| 71 |
+
return text_config
|
| 72 |
+
|
| 73 |
+
get_text_config = getattr(config, "get_text_config", None)
|
| 74 |
+
if get_text_config is not None:
|
| 75 |
+
candidate = get_text_config()
|
| 76 |
+
if candidate is not config:
|
| 77 |
+
return candidate
|
| 78 |
+
|
| 79 |
+
raise ValueError("OXR config does not expose an LLM sub-config")
|
| 80 |
+
|
| 81 |
+
|
| 82 |
+
def _oxr_field_config() -> Mapping[str, MultiModalFieldConfig]:
|
| 83 |
+
return dict(
|
| 84 |
+
pixel_values=MultiModalFieldConfig.batched("image"),
|
| 85 |
+
grids=MultiModalFieldConfig.batched("image"),
|
| 86 |
+
indicator_tokens=MultiModalFieldConfig.batched("image"),
|
| 87 |
+
video_pixel_values=MultiModalFieldConfig.batched("video"),
|
| 88 |
+
video_indicator_tokens=MultiModalFieldConfig.batched("video"),
|
| 89 |
+
video_grids=MultiModalFieldConfig.batched("video"),
|
| 90 |
+
)
|
| 91 |
+
|
| 92 |
+
|
| 93 |
+
class OXRImagePatchInputs(TensorSchema):
|
| 94 |
+
type: Literal["image_patches"]
|
| 95 |
+
flat_data: Annotated[torch.Tensor, TensorShape("bnp", "patch_size")]
|
| 96 |
+
indicator_tokens: Annotated[torch.Tensor, TensorShape("indicators")]
|
| 97 |
+
patches_per_item: Annotated[list[int], TensorShape("bn")]
|
| 98 |
+
grids: Annotated[torch.Tensor, TensorShape("bn", 3)]
|
| 99 |
+
|
| 100 |
+
|
| 101 |
+
class OXRVideoPatchInputs(TensorSchema):
|
| 102 |
+
type: Literal["video_patches"]
|
| 103 |
+
flat_data: Annotated[torch.Tensor, TensorShape("bnp", "patch_size")]
|
| 104 |
+
indicator_tokens: Annotated[torch.Tensor, TensorShape("indicators")]
|
| 105 |
+
patches_per_item: Annotated[list[int], TensorShape("bn")]
|
| 106 |
+
grids: Annotated[torch.Tensor, TensorShape("bn", 3)]
|
| 107 |
+
|
| 108 |
+
|
| 109 |
+
class OXREmbedding(torch.nn.Embedding):
|
| 110 |
+
def forward(self, visual_tokens: torch.Tensor) -> torch.Tensor:
|
| 111 |
+
if visual_tokens.dtype in (
|
| 112 |
+
torch.int8,
|
| 113 |
+
torch.int16,
|
| 114 |
+
torch.int32,
|
| 115 |
+
torch.int64,
|
| 116 |
+
torch.long,
|
| 117 |
+
):
|
| 118 |
+
return super().forward(visual_tokens)
|
| 119 |
+
return torch.matmul(visual_tokens, self.weight)
|
| 120 |
+
|
| 121 |
+
@property
|
| 122 |
+
def device(self) -> torch.device:
|
| 123 |
+
return self.weight.device
|
| 124 |
+
|
| 125 |
+
@property
|
| 126 |
+
def dtype(self) -> torch.dtype:
|
| 127 |
+
return self.weight.dtype
|
| 128 |
+
|
| 129 |
+
|
| 130 |
+
class OXRVisualTokenizer(torch.nn.Module):
|
| 131 |
+
def __init__(
|
| 132 |
+
self,
|
| 133 |
+
config: PretrainedConfig,
|
| 134 |
+
visual_vocab_size: int,
|
| 135 |
+
quant_config: QuantizationConfig | None = None,
|
| 136 |
+
prefix: str = "",
|
| 137 |
+
):
|
| 138 |
+
super().__init__()
|
| 139 |
+
self.config = config
|
| 140 |
+
self.vit = self._init_backbone(
|
| 141 |
+
config=config,
|
| 142 |
+
quant_config=quant_config,
|
| 143 |
+
prefix=f"{prefix}.vit",
|
| 144 |
+
)
|
| 145 |
+
head_dim = visual_vocab_size - len(OXR_INDICATOR_IDS)
|
| 146 |
+
self.head = torch.nn.Sequential(
|
| 147 |
+
ReplicatedLinear(
|
| 148 |
+
self.config.hidden_size * self.config.hidden_stride**2,
|
| 149 |
+
head_dim,
|
| 150 |
+
bias=False,
|
| 151 |
+
return_bias=False,
|
| 152 |
+
quant_config=quant_config,
|
| 153 |
+
prefix=f"{prefix}.head.0",
|
| 154 |
+
),
|
| 155 |
+
torch.nn.LayerNorm(head_dim),
|
| 156 |
+
)
|
| 157 |
+
|
| 158 |
+
def _init_backbone(
|
| 159 |
+
self,
|
| 160 |
+
config: PretrainedConfig,
|
| 161 |
+
quant_config: QuantizationConfig | None = None,
|
| 162 |
+
prefix: str = "",
|
| 163 |
+
):
|
| 164 |
+
if config.model_type == "siglip2_navit":
|
| 165 |
+
return Siglip2NavitModel(
|
| 166 |
+
config=config,
|
| 167 |
+
quant_config=quant_config,
|
| 168 |
+
prefix=prefix,
|
| 169 |
+
)
|
| 170 |
+
raise ValueError(f"Unsupported visual tokenizer model_type: {config.model_type}")
|
| 171 |
+
|
| 172 |
+
@property
|
| 173 |
+
def dtype(self) -> torch.dtype:
|
| 174 |
+
return next(self.head.parameters()).dtype
|
| 175 |
+
|
| 176 |
+
@property
|
| 177 |
+
def device(self) -> torch.device:
|
| 178 |
+
return next(self.head.parameters()).device
|
| 179 |
+
|
| 180 |
+
def tokenize(self, logits: torch.Tensor) -> torch.Tensor:
|
| 181 |
+
return torch.softmax(logits, dim=-1, dtype=torch.float32).to(logits.dtype)
|
| 182 |
+
|
| 183 |
+
def encode(
|
| 184 |
+
self,
|
| 185 |
+
pixel_values: torch.Tensor,
|
| 186 |
+
grid_thws: torch.Tensor,
|
| 187 |
+
) -> torch.Tensor:
|
| 188 |
+
features = self.vit(pixel_values, grid_thws)
|
| 189 |
+
seq_len, _ = features.shape
|
| 190 |
+
return features.reshape(seq_len // (self.config.hidden_stride**2), -1)
|
| 191 |
+
|
| 192 |
+
def forward(
|
| 193 |
+
self,
|
| 194 |
+
pixel_values: torch.Tensor,
|
| 195 |
+
grid_thws: torch.Tensor,
|
| 196 |
+
) -> torch.Tensor:
|
| 197 |
+
features = self.encode(pixel_values, grid_thws)
|
| 198 |
+
logits = self.head(features)
|
| 199 |
+
tokens = self.tokenize(logits)
|
| 200 |
+
return torch.nn.functional.pad(
|
| 201 |
+
tokens,
|
| 202 |
+
(0, len(OXR_INDICATOR_IDS)),
|
| 203 |
+
mode="constant",
|
| 204 |
+
value=0,
|
| 205 |
+
)
|
| 206 |
+
|
| 207 |
+
|
| 208 |
+
class OXRProcessingInfo(BaseProcessingInfo):
|
| 209 |
+
def get_hf_config(self):
|
| 210 |
+
return self.ctx.get_hf_config()
|
| 211 |
+
|
| 212 |
+
def get_hf_processor(self, **kwargs):
|
| 213 |
+
vit_config = self.get_hf_config().vit_config
|
| 214 |
+
return self.ctx.get_hf_processor(
|
| 215 |
+
OXRProcessor,
|
| 216 |
+
image_pad_token=self.get_image_pad_token(),
|
| 217 |
+
patch_size=vit_config.patch_size,
|
| 218 |
+
hidden_stride=vit_config.hidden_stride,
|
| 219 |
+
temporal_patch_size=vit_config.temporal_patch_size,
|
| 220 |
+
**kwargs,
|
| 221 |
+
)
|
| 222 |
+
|
| 223 |
+
def get_default_tok_params(self) -> TokenizeParams:
|
| 224 |
+
return super().get_default_tok_params().with_kwargs(add_special_tokens=False)
|
| 225 |
+
|
| 226 |
+
def get_image_pad_token(self) -> str:
|
| 227 |
+
text_model_type = get_llm_config(self.get_hf_config()).model_type
|
| 228 |
+
return IMAGE_PAD_TOKEN_MAP[text_model_type]
|
| 229 |
+
|
| 230 |
+
def get_image_processor(self) -> BaseImageProcessor:
|
| 231 |
+
return self.get_hf_processor().image_processor # type: ignore[return-value]
|
| 232 |
+
|
| 233 |
+
def get_supported_mm_limits(self) -> Mapping[str, int | None]:
|
| 234 |
+
return {"image": None, "video": 1}
|
| 235 |
+
|
| 236 |
+
def get_image_size_with_most_features(self) -> ImageSize:
|
| 237 |
+
return ImageSize(width=1792, height=1792)
|
| 238 |
+
|
| 239 |
+
def get_num_image_tokens(
|
| 240 |
+
self,
|
| 241 |
+
*,
|
| 242 |
+
image_width: int,
|
| 243 |
+
image_height: int,
|
| 244 |
+
num_frames: int = 1,
|
| 245 |
+
) -> int:
|
| 246 |
+
vit_config = self.get_hf_config().vit_config
|
| 247 |
+
padded_num_frames = num_frames + (-num_frames % vit_config.temporal_patch_size)
|
| 248 |
+
grid_t = max(padded_num_frames // vit_config.temporal_patch_size, 1)
|
| 249 |
+
grid_h = image_height // vit_config.patch_size
|
| 250 |
+
grid_w = image_width // vit_config.patch_size
|
| 251 |
+
return grid_t * grid_h * grid_w
|
| 252 |
+
|
| 253 |
+
def get_max_image_tokens(self) -> int:
|
| 254 |
+
target_width, target_height = self.get_image_size_with_most_features()
|
| 255 |
+
return self.get_num_image_tokens(
|
| 256 |
+
image_width=target_width,
|
| 257 |
+
image_height=target_height,
|
| 258 |
+
)
|
| 259 |
+
|
| 260 |
+
def _get_max_video_frames(self, max_tokens: int) -> int:
|
| 261 |
+
target_width, target_height = self.get_image_size_with_most_features()
|
| 262 |
+
num_frames = 0
|
| 263 |
+
while True:
|
| 264 |
+
next_num_frames = num_frames + 1
|
| 265 |
+
next_max_tokens = self.get_num_video_tokens(
|
| 266 |
+
image_width=target_width,
|
| 267 |
+
image_height=target_height,
|
| 268 |
+
num_frames=next_num_frames,
|
| 269 |
+
)
|
| 270 |
+
if next_max_tokens > max_tokens:
|
| 271 |
+
break
|
| 272 |
+
num_frames = next_num_frames
|
| 273 |
+
return num_frames
|
| 274 |
+
|
| 275 |
+
def get_num_frames_with_most_features(
|
| 276 |
+
self,
|
| 277 |
+
seq_len: int,
|
| 278 |
+
mm_counts: Mapping[str, int],
|
| 279 |
+
) -> int:
|
| 280 |
+
max_images = mm_counts.get("image", 0)
|
| 281 |
+
max_videos = mm_counts.get("video", 0)
|
| 282 |
+
max_image_tokens = self.get_max_image_tokens() * max_images
|
| 283 |
+
max_total_frames = self._get_max_video_frames(seq_len - max_image_tokens)
|
| 284 |
+
max_frames_per_video = max_total_frames // max(max_videos, 1)
|
| 285 |
+
return max(max_frames_per_video, 1)
|
| 286 |
+
|
| 287 |
+
def get_num_video_tokens(
|
| 288 |
+
self,
|
| 289 |
+
*,
|
| 290 |
+
image_width: int,
|
| 291 |
+
image_height: int,
|
| 292 |
+
num_frames: int,
|
| 293 |
+
) -> int:
|
| 294 |
+
return self.get_num_image_tokens(
|
| 295 |
+
image_width=image_width,
|
| 296 |
+
image_height=image_height,
|
| 297 |
+
num_frames=num_frames,
|
| 298 |
+
)
|
| 299 |
+
|
| 300 |
+
def get_max_video_tokens(
|
| 301 |
+
self,
|
| 302 |
+
seq_len: int,
|
| 303 |
+
mm_counts: Mapping[str, int],
|
| 304 |
+
) -> int:
|
| 305 |
+
target_width, target_height = self.get_image_size_with_most_features()
|
| 306 |
+
return self.get_num_video_tokens(
|
| 307 |
+
image_width=target_width,
|
| 308 |
+
image_height=target_height,
|
| 309 |
+
num_frames=self.get_num_frames_with_most_features(seq_len, mm_counts),
|
| 310 |
+
)
|
| 311 |
+
|
| 312 |
+
def get_mm_max_tokens_per_item(
|
| 313 |
+
self,
|
| 314 |
+
seq_len: int,
|
| 315 |
+
mm_counts: Mapping[str, int],
|
| 316 |
+
) -> Mapping[str, int]:
|
| 317 |
+
# Return a conservative upper bound so vLLM does not profile the
|
| 318 |
+
# visual tower with dozens of maximum-sized dummy images/videos.
|
| 319 |
+
return {
|
| 320 |
+
"image": self.get_max_image_tokens() + 2,
|
| 321 |
+
"video": self.get_max_video_tokens(seq_len, mm_counts) + 2,
|
| 322 |
+
}
|
| 323 |
+
|
| 324 |
+
|
| 325 |
+
class OXRDummyInputsBuilder(BaseDummyInputsBuilder[OXRProcessingInfo]):
|
| 326 |
+
def get_dummy_text(self, mm_counts: Mapping[str, int]) -> str:
|
| 327 |
+
return IMAGE_TOKEN * mm_counts.get("image", 0) + VIDEO_TOKEN * mm_counts.get(
|
| 328 |
+
"video", 0
|
| 329 |
+
)
|
| 330 |
+
|
| 331 |
+
def get_dummy_mm_data(
|
| 332 |
+
self,
|
| 333 |
+
seq_len: int,
|
| 334 |
+
mm_counts: Mapping[str, int],
|
| 335 |
+
mm_options: Mapping[str, BaseDummyOptions],
|
| 336 |
+
) -> MultiModalDataDict:
|
| 337 |
+
num_images = mm_counts.get("image", 0)
|
| 338 |
+
num_videos = mm_counts.get("video", 0)
|
| 339 |
+
target_width, target_height = self.info.get_image_size_with_most_features()
|
| 340 |
+
target_num_frames = self.info.get_num_frames_with_most_features(
|
| 341 |
+
seq_len, mm_counts
|
| 342 |
+
)
|
| 343 |
+
|
| 344 |
+
return {
|
| 345 |
+
"image": self._get_dummy_images(
|
| 346 |
+
width=target_width,
|
| 347 |
+
height=target_height,
|
| 348 |
+
num_images=num_images,
|
| 349 |
+
overrides=mm_options.get("image"),
|
| 350 |
+
),
|
| 351 |
+
"video": self._get_dummy_videos(
|
| 352 |
+
width=target_width,
|
| 353 |
+
height=target_height,
|
| 354 |
+
num_frames=target_num_frames,
|
| 355 |
+
num_videos=num_videos,
|
| 356 |
+
overrides=mm_options.get("video"),
|
| 357 |
+
),
|
| 358 |
+
}
|
| 359 |
+
|
| 360 |
+
|
| 361 |
+
class OXRMultiModalProcessor(BaseMultiModalProcessor[OXRProcessingInfo]):
|
| 362 |
+
def visual_indicators_to_visual_tokens(
|
| 363 |
+
self,
|
| 364 |
+
visual_indicators: list[int],
|
| 365 |
+
) -> list[int]:
|
| 366 |
+
vocab_size = self.info.get_hf_config().visual_vocab_size
|
| 367 |
+
indicator_by_id = {token_id: idx for idx, token_id in enumerate(OXR_INDICATOR_IDS)}
|
| 368 |
+
return [
|
| 369 |
+
vocab_size - len(OXR_INDICATOR_IDS) + indicator_by_id[token_id]
|
| 370 |
+
for token_id in visual_indicators
|
| 371 |
+
if token_id in indicator_by_id
|
| 372 |
+
]
|
| 373 |
+
|
| 374 |
+
def _call_hf_processor(
|
| 375 |
+
self,
|
| 376 |
+
prompt: str,
|
| 377 |
+
mm_data: Mapping[str, object],
|
| 378 |
+
mm_kwargs: Mapping[str, object],
|
| 379 |
+
tok_kwargs: Mapping[str, object],
|
| 380 |
+
) -> BatchFeature:
|
| 381 |
+
if not mm_data:
|
| 382 |
+
tokenizer = self.info.get_tokenizer()
|
| 383 |
+
prompt_ids = tokenizer.encode(prompt, add_special_tokens=False)
|
| 384 |
+
return BatchFeature(dict(input_ids=[prompt_ids]), tensor_type="pt")
|
| 385 |
+
|
| 386 |
+
processed_outputs = super()._call_hf_processor(
|
| 387 |
+
prompt=prompt,
|
| 388 |
+
mm_data=mm_data,
|
| 389 |
+
mm_kwargs=mm_kwargs,
|
| 390 |
+
tok_kwargs=tok_kwargs,
|
| 391 |
+
)
|
| 392 |
+
hf_processor = self.info.get_hf_processor()
|
| 393 |
+
|
| 394 |
+
if "videos" in mm_data:
|
| 395 |
+
visual_indicators = [
|
| 396 |
+
hf_processor.construct_visual_indicators((1, 1, 1), True)
|
| 397 |
+
for _ in processed_outputs["video_grids"]
|
| 398 |
+
]
|
| 399 |
+
processed_outputs["video_indicator_tokens"] = torch.tensor(
|
| 400 |
+
[
|
| 401 |
+
self.visual_indicators_to_visual_tokens(indicators)
|
| 402 |
+
for indicators in visual_indicators
|
| 403 |
+
],
|
| 404 |
+
dtype=torch.long,
|
| 405 |
+
)
|
| 406 |
+
|
| 407 |
+
if "images" in mm_data:
|
| 408 |
+
visual_indicators = [
|
| 409 |
+
hf_processor.construct_visual_indicators((1, 1, 1), False)
|
| 410 |
+
for _ in processed_outputs["grids"]
|
| 411 |
+
]
|
| 412 |
+
processed_outputs["indicator_tokens"] = torch.tensor(
|
| 413 |
+
[
|
| 414 |
+
self.visual_indicators_to_visual_tokens(indicators)
|
| 415 |
+
for indicators in visual_indicators
|
| 416 |
+
],
|
| 417 |
+
dtype=torch.long,
|
| 418 |
+
)
|
| 419 |
+
|
| 420 |
+
return processed_outputs
|
| 421 |
+
|
| 422 |
+
def _apply_hf_processor_tokens_only(self, prompt_tokens: list[int]) -> list[int]:
|
| 423 |
+
return prompt_tokens
|
| 424 |
+
|
| 425 |
+
def _get_mm_fields_config(
|
| 426 |
+
self,
|
| 427 |
+
hf_inputs: BatchFeature,
|
| 428 |
+
hf_processor_mm_kwargs: Mapping[str, object],
|
| 429 |
+
) -> Mapping[str, MultiModalFieldConfig]:
|
| 430 |
+
return _oxr_field_config()
|
| 431 |
+
|
| 432 |
+
def _get_prompt_updates(
|
| 433 |
+
self,
|
| 434 |
+
mm_items: MultiModalDataItems,
|
| 435 |
+
hf_processor_mm_kwargs: Mapping[str, object],
|
| 436 |
+
out_mm_kwargs: MultiModalKwargsItems,
|
| 437 |
+
) -> list[PromptReplacement]:
|
| 438 |
+
def get_replacement(item_idx: int, modality: str) -> list[int]:
|
| 439 |
+
if modality == "image":
|
| 440 |
+
grid = out_mm_kwargs["image"][item_idx]["grids"].data
|
| 441 |
+
elif modality == "video":
|
| 442 |
+
grid = out_mm_kwargs["video"][item_idx]["video_grids"].data
|
| 443 |
+
else:
|
| 444 |
+
raise ValueError(f"Unsupported modality: {modality}")
|
| 445 |
+
|
| 446 |
+
hf_processor = self.info.get_hf_processor()
|
| 447 |
+
return hf_processor.construct_visual_placeholders(
|
| 448 |
+
grid[0],
|
| 449 |
+
is_video=(modality == "video"),
|
| 450 |
+
)
|
| 451 |
+
|
| 452 |
+
return [
|
| 453 |
+
PromptReplacement(
|
| 454 |
+
modality=modality,
|
| 455 |
+
target=IMAGE_TOKEN if modality == "image" else VIDEO_TOKEN,
|
| 456 |
+
replacement=partial(get_replacement, modality=modality),
|
| 457 |
+
)
|
| 458 |
+
for modality in ("image", "video")
|
| 459 |
+
]
|
| 460 |
+
|
| 461 |
+
|
| 462 |
+
@MULTIMODAL_REGISTRY.register_processor(
|
| 463 |
+
OXRMultiModalProcessor,
|
| 464 |
+
info=OXRProcessingInfo,
|
| 465 |
+
dummy_inputs=OXRDummyInputsBuilder,
|
| 466 |
+
)
|
| 467 |
+
class OXR(nn.Module, SupportsMultiModal, SupportsPP):
|
| 468 |
+
@classmethod
|
| 469 |
+
def get_placeholder_str(cls, modality: str, i: int) -> str | None:
|
| 470 |
+
if modality.startswith("image"):
|
| 471 |
+
return IMAGE_TOKEN
|
| 472 |
+
if modality.startswith("video"):
|
| 473 |
+
return VIDEO_TOKEN
|
| 474 |
+
raise ValueError("Only image or video modality is supported")
|
| 475 |
+
|
| 476 |
+
def __init__(self, *, vllm_config: VllmConfig, prefix: str = ""):
|
| 477 |
+
super().__init__()
|
| 478 |
+
config = vllm_config.model_config.hf_config
|
| 479 |
+
quant_config = vllm_config.quant_config
|
| 480 |
+
|
| 481 |
+
self.config: PretrainedConfig = config
|
| 482 |
+
|
| 483 |
+
with self._mark_language_model(vllm_config):
|
| 484 |
+
self.llm = init_vllm_registered_model(
|
| 485 |
+
vllm_config=vllm_config.with_hf_config(get_llm_config(config)),
|
| 486 |
+
prefix=maybe_prefix(prefix, "llm"),
|
| 487 |
+
)
|
| 488 |
+
|
| 489 |
+
with self._mark_tower_model(vllm_config, {"image", "video"}):
|
| 490 |
+
self.visual_tokenizer = OXRVisualTokenizer(
|
| 491 |
+
config=config.vit_config,
|
| 492 |
+
visual_vocab_size=config.visual_vocab_size,
|
| 493 |
+
quant_config=quant_config,
|
| 494 |
+
prefix=f"{prefix}.visual_tokenizer",
|
| 495 |
+
)
|
| 496 |
+
self.vte = OXREmbedding(config.visual_vocab_size, config.hidden_size)
|
| 497 |
+
|
| 498 |
+
text_model_type = get_llm_config(config).model_type
|
| 499 |
+
self.image_pad_token_id = IMAGE_PAD_TOKEN_ID_MAP[text_model_type]
|
| 500 |
+
|
| 501 |
+
self.make_empty_intermediate_tensors = (
|
| 502 |
+
self.get_language_model().make_empty_intermediate_tensors
|
| 503 |
+
)
|
| 504 |
+
|
| 505 |
+
def _parse_and_validate_image_input(
|
| 506 |
+
self,
|
| 507 |
+
**kwargs: object,
|
| 508 |
+
) -> OXRImagePatchInputs | None:
|
| 509 |
+
pixel_values = kwargs.pop("pixel_values", None)
|
| 510 |
+
indicator_tokens = kwargs.pop("indicator_tokens", None)
|
| 511 |
+
grids = kwargs.pop("grids", None)
|
| 512 |
+
if pixel_values is None and indicator_tokens is None:
|
| 513 |
+
return None
|
| 514 |
+
|
| 515 |
+
if pixel_values is not None and indicator_tokens is not None:
|
| 516 |
+
if not isinstance(pixel_values, (torch.Tensor, list)):
|
| 517 |
+
raise ValueError(f"Incorrect type of pixel values: {type(pixel_values)}")
|
| 518 |
+
if not isinstance(indicator_tokens, (torch.Tensor, list)):
|
| 519 |
+
raise ValueError(
|
| 520 |
+
f"Incorrect type of indicator_tokens: {type(indicator_tokens)}"
|
| 521 |
+
)
|
| 522 |
+
if grids is None:
|
| 523 |
+
raise ValueError("Missing grids for image input")
|
| 524 |
+
|
| 525 |
+
return OXRImagePatchInputs(
|
| 526 |
+
type="image_patches",
|
| 527 |
+
flat_data=flatten_bn(pixel_values, concat=True),
|
| 528 |
+
patches_per_item=[
|
| 529 |
+
x.shape[0] // (self.config.vit_config.hidden_stride**2)
|
| 530 |
+
for x in pixel_values
|
| 531 |
+
],
|
| 532 |
+
indicator_tokens=flatten_bn(indicator_tokens, concat=True),
|
| 533 |
+
grids=flatten_bn(grids, concat=True),
|
| 534 |
+
)
|
| 535 |
+
|
| 536 |
+
raise AssertionError("This line should be unreachable.")
|
| 537 |
+
|
| 538 |
+
def _parse_and_validate_video_input(
|
| 539 |
+
self,
|
| 540 |
+
**kwargs: object,
|
| 541 |
+
) -> OXRVideoPatchInputs | None:
|
| 542 |
+
pixel_values = kwargs.pop("video_pixel_values", None)
|
| 543 |
+
indicator_tokens = kwargs.pop("video_indicator_tokens", None)
|
| 544 |
+
grids = kwargs.pop("video_grids", None)
|
| 545 |
+
if pixel_values is None and indicator_tokens is None:
|
| 546 |
+
return None
|
| 547 |
+
|
| 548 |
+
if pixel_values is not None and indicator_tokens is not None:
|
| 549 |
+
if not isinstance(pixel_values, (torch.Tensor, list)):
|
| 550 |
+
raise ValueError(f"Incorrect type of pixel values: {type(pixel_values)}")
|
| 551 |
+
if not isinstance(indicator_tokens, (torch.Tensor, list)):
|
| 552 |
+
raise ValueError(
|
| 553 |
+
f"Incorrect type of indicator_tokens: {type(indicator_tokens)}"
|
| 554 |
+
)
|
| 555 |
+
if grids is None:
|
| 556 |
+
raise ValueError("Missing grids for video input")
|
| 557 |
+
|
| 558 |
+
return OXRVideoPatchInputs(
|
| 559 |
+
type="video_patches",
|
| 560 |
+
flat_data=flatten_bn(pixel_values, concat=True),
|
| 561 |
+
patches_per_item=[
|
| 562 |
+
x.shape[0] // (self.config.vit_config.hidden_stride**2)
|
| 563 |
+
for x in pixel_values
|
| 564 |
+
],
|
| 565 |
+
indicator_tokens=flatten_bn(indicator_tokens, concat=True),
|
| 566 |
+
grids=flatten_bn(grids, concat=True),
|
| 567 |
+
)
|
| 568 |
+
|
| 569 |
+
raise AssertionError("This line should be unreachable.")
|
| 570 |
+
|
| 571 |
+
def _process_visual_input(
|
| 572 |
+
self,
|
| 573 |
+
visual_input: OXRImagePatchInputs | OXRVideoPatchInputs,
|
| 574 |
+
) -> MultiModalEmbeddings:
|
| 575 |
+
image_patches_flat = visual_input["flat_data"]
|
| 576 |
+
patches_per_item = visual_input["patches_per_item"]
|
| 577 |
+
indicator_tokens = visual_input["indicator_tokens"]
|
| 578 |
+
grid_thws = visual_input["grids"]
|
| 579 |
+
|
| 580 |
+
visual_tokens = self.visual_tokenizer(
|
| 581 |
+
image_patches_flat.to(self.visual_tokenizer.dtype),
|
| 582 |
+
grid_thws,
|
| 583 |
+
)
|
| 584 |
+
visual_embeds = self.vte(visual_tokens)
|
| 585 |
+
indicator_embeds = self.vte(indicator_tokens)
|
| 586 |
+
|
| 587 |
+
visual_embeds_per_item = visual_embeds.split(patches_per_item, dim=0)
|
| 588 |
+
indicator_embeds_per_item = indicator_embeds.split(
|
| 589 |
+
[2] * len(patches_per_item)
|
| 590 |
+
)
|
| 591 |
+
|
| 592 |
+
return tuple(
|
| 593 |
+
torch.cat([indicator[:1], visual, indicator[1:]], dim=0)
|
| 594 |
+
for indicator, visual in zip(
|
| 595 |
+
indicator_embeds_per_item,
|
| 596 |
+
visual_embeds_per_item,
|
| 597 |
+
)
|
| 598 |
+
)
|
| 599 |
+
|
| 600 |
+
def _parse_and_validate_multimodal_inputs(self, **kwargs: object) -> dict:
|
| 601 |
+
modalities = {}
|
| 602 |
+
for input_key in kwargs:
|
| 603 |
+
if (
|
| 604 |
+
input_key in ("pixel_values", "indicator_tokens", "grids")
|
| 605 |
+
and "images" not in modalities
|
| 606 |
+
):
|
| 607 |
+
modalities["images"] = self._parse_and_validate_image_input(**kwargs)
|
| 608 |
+
if (
|
| 609 |
+
input_key
|
| 610 |
+
in ("video_pixel_values", "video_indicator_tokens", "video_grids")
|
| 611 |
+
and "videos" not in modalities
|
| 612 |
+
):
|
| 613 |
+
modalities["videos"] = self._parse_and_validate_video_input(**kwargs)
|
| 614 |
+
return modalities
|
| 615 |
+
|
| 616 |
+
def embed_multimodal(self, **kwargs: object) -> MultiModalEmbeddings:
|
| 617 |
+
modalities = self._parse_and_validate_multimodal_inputs(**kwargs)
|
| 618 |
+
if not modalities:
|
| 619 |
+
return []
|
| 620 |
+
|
| 621 |
+
multimodal_embeddings: tuple[torch.Tensor, ...] = ()
|
| 622 |
+
for modality in modalities:
|
| 623 |
+
if modality == "images":
|
| 624 |
+
image_input = modalities["images"]
|
| 625 |
+
multimodal_embeddings += tuple(self._process_visual_input(image_input))
|
| 626 |
+
if modality == "videos":
|
| 627 |
+
video_input = modalities["videos"]
|
| 628 |
+
multimodal_embeddings += tuple(self._process_visual_input(video_input))
|
| 629 |
+
return multimodal_embeddings
|
| 630 |
+
|
| 631 |
+
def forward(
|
| 632 |
+
self,
|
| 633 |
+
input_ids: torch.Tensor | None,
|
| 634 |
+
positions: torch.Tensor,
|
| 635 |
+
intermediate_tensors: IntermediateTensors | None = None,
|
| 636 |
+
inputs_embeds: torch.Tensor | None = None,
|
| 637 |
+
**kwargs: object,
|
| 638 |
+
) -> torch.Tensor | IntermediateTensors:
|
| 639 |
+
if intermediate_tensors is not None:
|
| 640 |
+
inputs_embeds = None
|
| 641 |
+
|
| 642 |
+
return self.llm(
|
| 643 |
+
input_ids=input_ids,
|
| 644 |
+
positions=positions,
|
| 645 |
+
intermediate_tensors=intermediate_tensors,
|
| 646 |
+
inputs_embeds=inputs_embeds,
|
| 647 |
+
)
|
| 648 |
+
|
| 649 |
+
def compute_logits(
|
| 650 |
+
self,
|
| 651 |
+
hidden_states: torch.Tensor,
|
| 652 |
+
) -> torch.Tensor | None:
|
| 653 |
+
return self.llm.compute_logits(hidden_states)
|
| 654 |
+
|
| 655 |
+
def load_weights(self, weights: Iterable[tuple[str, torch.Tensor]]) -> set[str]:
|
| 656 |
+
loader = AutoWeightsLoader(self)
|
| 657 |
+
return loader.load_weights(weights)
|
| 658 |
+
|
| 659 |
+
def get_language_model(self) -> torch.nn.Module:
|
| 660 |
+
return self.llm
|
plugins/vllm/oxr_vllm/oxr_processor.py
ADDED
|
@@ -0,0 +1,384 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
"""OXR processor for the vLLM 0.25.1 plugin."""
|
| 2 |
+
|
| 3 |
+
import math
|
| 4 |
+
from functools import cached_property
|
| 5 |
+
from typing import Optional, Union
|
| 6 |
+
|
| 7 |
+
import numpy as np
|
| 8 |
+
import PIL.Image
|
| 9 |
+
import torch
|
| 10 |
+
from transformers import AutoProcessor, BatchFeature
|
| 11 |
+
from transformers.image_utils import ImageInput
|
| 12 |
+
from transformers.processing_utils import ProcessingKwargs, ProcessorMixin, Unpack
|
| 13 |
+
from transformers.tokenization_utils_base import PreTokenizedInput, TextInput
|
| 14 |
+
|
| 15 |
+
IMAGE_TOKEN = "<image>"
|
| 16 |
+
VIDEO_TOKEN = "<video>"
|
| 17 |
+
MIN_PIXELS = 200704
|
| 18 |
+
MAX_PIXELS = 921600
|
| 19 |
+
|
| 20 |
+
|
| 21 |
+
class OXRProcessorKwargs(ProcessingKwargs, total=False): # type: ignore[call-arg]
|
| 22 |
+
_defaults = {
|
| 23 |
+
"text_kwargs": {
|
| 24 |
+
"padding": False,
|
| 25 |
+
},
|
| 26 |
+
"images_kwargs": {
|
| 27 |
+
"do_convert_rgb": True,
|
| 28 |
+
},
|
| 29 |
+
"videos_kwargs": {
|
| 30 |
+
"do_convert_rgb": True,
|
| 31 |
+
},
|
| 32 |
+
}
|
| 33 |
+
|
| 34 |
+
|
| 35 |
+
class OXRProcessor(ProcessorMixin):
|
| 36 |
+
attributes = ["image_processor", "tokenizer"]
|
| 37 |
+
valid_kwargs = ["chat_template", "image_pad_token"]
|
| 38 |
+
|
| 39 |
+
image_processor_class = "AutoImageProcessor"
|
| 40 |
+
tokenizer_class = "AutoTokenizer"
|
| 41 |
+
|
| 42 |
+
def __init__(
|
| 43 |
+
self,
|
| 44 |
+
image_processor=None,
|
| 45 |
+
tokenizer=None,
|
| 46 |
+
chat_template=None,
|
| 47 |
+
image_pad_token=None,
|
| 48 |
+
patch_size=16,
|
| 49 |
+
hidden_stride=2,
|
| 50 |
+
temporal_patch_size=1,
|
| 51 |
+
**kwargs,
|
| 52 |
+
):
|
| 53 |
+
self.image_token = IMAGE_TOKEN
|
| 54 |
+
self.video_token = VIDEO_TOKEN
|
| 55 |
+
self.image_pad_token = image_pad_token or "<|image_pad|>"
|
| 56 |
+
self.patch_size = patch_size
|
| 57 |
+
self.hidden_stride = hidden_stride
|
| 58 |
+
self.temporal_patch_size = temporal_patch_size
|
| 59 |
+
super().__init__(image_processor, tokenizer, chat_template=chat_template)
|
| 60 |
+
|
| 61 |
+
@cached_property
|
| 62 |
+
def extra_special_tokens(self):
|
| 63 |
+
image_pad_token_id = self.tokenizer.get_vocab()[self.image_pad_token]
|
| 64 |
+
return {
|
| 65 |
+
"image_token": -200,
|
| 66 |
+
"video_token": -201,
|
| 67 |
+
"visual_atom": -300,
|
| 68 |
+
"image_start": -301,
|
| 69 |
+
"image_end": -302,
|
| 70 |
+
"video_start": -303,
|
| 71 |
+
"video_end": -304,
|
| 72 |
+
"image_pad": image_pad_token_id,
|
| 73 |
+
}
|
| 74 |
+
|
| 75 |
+
def __call__(
|
| 76 |
+
self,
|
| 77 |
+
images: ImageInput = None,
|
| 78 |
+
videos: Union[np.ndarray, list[ImageInput]] = None,
|
| 79 |
+
text: Union[
|
| 80 |
+
TextInput,
|
| 81 |
+
PreTokenizedInput,
|
| 82 |
+
list[TextInput],
|
| 83 |
+
list[PreTokenizedInput],
|
| 84 |
+
] = None,
|
| 85 |
+
**kwargs: Unpack[OXRProcessorKwargs],
|
| 86 |
+
) -> BatchFeature:
|
| 87 |
+
output_kwargs = self._merge_kwargs(
|
| 88 |
+
OXRProcessorKwargs,
|
| 89 |
+
tokenizer_init_kwargs=self.tokenizer.init_kwargs,
|
| 90 |
+
**kwargs,
|
| 91 |
+
)
|
| 92 |
+
visual_features = {}
|
| 93 |
+
output = BatchFeature()
|
| 94 |
+
|
| 95 |
+
if images is not None:
|
| 96 |
+
processed_images = []
|
| 97 |
+
image_placeholders_list = []
|
| 98 |
+
grids = []
|
| 99 |
+
for image in images if isinstance(images, list) else [images]:
|
| 100 |
+
pixel_values, image_placeholders, grid = self.preprocess_multidata(
|
| 101 |
+
images=image,
|
| 102 |
+
**output_kwargs["images_kwargs"],
|
| 103 |
+
)
|
| 104 |
+
processed_images.append(pixel_values)
|
| 105 |
+
image_placeholders_list.append(image_placeholders)
|
| 106 |
+
grids.append(grid)
|
| 107 |
+
|
| 108 |
+
if processed_images:
|
| 109 |
+
visual_features["image_placeholders"] = image_placeholders_list
|
| 110 |
+
output["pixel_values"] = processed_images
|
| 111 |
+
output["grids"] = grids
|
| 112 |
+
|
| 113 |
+
if videos is not None:
|
| 114 |
+
processed_videos = []
|
| 115 |
+
video_placeholders_list = []
|
| 116 |
+
grids = []
|
| 117 |
+
for video in videos if isinstance(videos, list) else [videos]:
|
| 118 |
+
pixel_values, video_placeholders, grid = self.preprocess_multidata(
|
| 119 |
+
video=video,
|
| 120 |
+
**output_kwargs["videos_kwargs"],
|
| 121 |
+
)
|
| 122 |
+
processed_videos.append(pixel_values)
|
| 123 |
+
video_placeholders_list.append(video_placeholders)
|
| 124 |
+
grids.append(grid)
|
| 125 |
+
|
| 126 |
+
if processed_videos:
|
| 127 |
+
visual_features["video_placeholders"] = video_placeholders_list
|
| 128 |
+
output["video_pixel_values"] = processed_videos
|
| 129 |
+
output["video_grids"] = grids
|
| 130 |
+
|
| 131 |
+
if text is None:
|
| 132 |
+
return BatchFeature(data=visual_features)
|
| 133 |
+
|
| 134 |
+
if not isinstance(text, list):
|
| 135 |
+
text = [text]
|
| 136 |
+
tokenized_batched_text = self._tokenize_with_visual_symbol(text)
|
| 137 |
+
image_token_id = self.get_token_value("image_token")
|
| 138 |
+
video_token_id = self.get_token_value("video_token")
|
| 139 |
+
replaced_ids_list = []
|
| 140 |
+
image_idx = 0
|
| 141 |
+
video_idx = 0
|
| 142 |
+
for ids_tensor in tokenized_batched_text:
|
| 143 |
+
has_image_tokens = (
|
| 144 |
+
image_token_id in ids_tensor
|
| 145 |
+
and "image_placeholders" in visual_features
|
| 146 |
+
and image_idx < len(visual_features["image_placeholders"])
|
| 147 |
+
)
|
| 148 |
+
has_video_tokens = (
|
| 149 |
+
video_token_id in ids_tensor
|
| 150 |
+
and "video_placeholders" in visual_features
|
| 151 |
+
and video_idx < len(visual_features["video_placeholders"])
|
| 152 |
+
)
|
| 153 |
+
if has_image_tokens or has_video_tokens:
|
| 154 |
+
new_ids = []
|
| 155 |
+
for token_id in ids_tensor.tolist():
|
| 156 |
+
if token_id == image_token_id:
|
| 157 |
+
new_ids.extend(visual_features["image_placeholders"][image_idx])
|
| 158 |
+
image_idx += 1
|
| 159 |
+
elif token_id == video_token_id:
|
| 160 |
+
new_ids.extend(visual_features["video_placeholders"][video_idx])
|
| 161 |
+
video_idx += 1
|
| 162 |
+
else:
|
| 163 |
+
new_ids.append(token_id)
|
| 164 |
+
ids_tensor = torch.tensor(new_ids, dtype=torch.long)
|
| 165 |
+
replaced_ids_list.append(ids_tensor)
|
| 166 |
+
|
| 167 |
+
if replaced_ids_list:
|
| 168 |
+
output["input_ids"] = torch.stack(replaced_ids_list)
|
| 169 |
+
else:
|
| 170 |
+
output["input_ids"] = torch.tensor([], dtype=torch.long)
|
| 171 |
+
return output
|
| 172 |
+
|
| 173 |
+
def _tokenize_with_visual_symbol(self, text_list: list[str]) -> torch.LongTensor:
|
| 174 |
+
batch_token_ids = []
|
| 175 |
+
for text in text_list:
|
| 176 |
+
token_ids = []
|
| 177 |
+
video_token_id = self.get_token_value("video_token")
|
| 178 |
+
image_token_id = self.get_token_value("image_token")
|
| 179 |
+
video_split_texts = text.split(self.video_token)
|
| 180 |
+
|
| 181 |
+
for j, video_segment in enumerate(video_split_texts):
|
| 182 |
+
image_split_texts = video_segment.split(self.image_token)
|
| 183 |
+
text_chunks = [
|
| 184 |
+
self.tokenizer(chunk, add_special_tokens=False).input_ids
|
| 185 |
+
for chunk in image_split_texts
|
| 186 |
+
]
|
| 187 |
+
segment_tokens = []
|
| 188 |
+
for i, chunk in enumerate(text_chunks):
|
| 189 |
+
segment_tokens.extend(chunk)
|
| 190 |
+
if i < len(text_chunks) - 1:
|
| 191 |
+
segment_tokens.append(image_token_id)
|
| 192 |
+
token_ids.extend(segment_tokens)
|
| 193 |
+
if j < len(video_split_texts) - 1:
|
| 194 |
+
token_ids.append(video_token_id)
|
| 195 |
+
batch_token_ids.append(token_ids)
|
| 196 |
+
return torch.tensor(batch_token_ids, dtype=torch.long)
|
| 197 |
+
|
| 198 |
+
def smart_resize(
|
| 199 |
+
self,
|
| 200 |
+
height: int,
|
| 201 |
+
width: int,
|
| 202 |
+
factor: int = 32,
|
| 203 |
+
min_pixels: int = MIN_PIXELS,
|
| 204 |
+
max_pixels: int = MAX_PIXELS,
|
| 205 |
+
):
|
| 206 |
+
if height < factor or width < factor:
|
| 207 |
+
if height < width:
|
| 208 |
+
width = round(factor / height * width)
|
| 209 |
+
height = factor
|
| 210 |
+
else:
|
| 211 |
+
height = round(factor / width * height)
|
| 212 |
+
width = factor
|
| 213 |
+
elif max(height, width) / min(height, width) > 200:
|
| 214 |
+
if height > width:
|
| 215 |
+
height = 200 * width
|
| 216 |
+
else:
|
| 217 |
+
width = 200 * height
|
| 218 |
+
|
| 219 |
+
h_bar = round(height / factor) * factor
|
| 220 |
+
w_bar = round(width / factor) * factor
|
| 221 |
+
if h_bar * w_bar > max_pixels:
|
| 222 |
+
beta = math.sqrt((height * width) / max_pixels)
|
| 223 |
+
h_bar = math.floor(height / beta / factor) * factor
|
| 224 |
+
w_bar = math.floor(width / beta / factor) * factor
|
| 225 |
+
elif h_bar * w_bar < min_pixels:
|
| 226 |
+
beta = math.sqrt(min_pixels / (height * width))
|
| 227 |
+
h_bar = math.ceil(height * beta / factor) * factor
|
| 228 |
+
w_bar = math.ceil(width * beta / factor) * factor
|
| 229 |
+
return h_bar, w_bar
|
| 230 |
+
|
| 231 |
+
def get_token_value(self, token_name: str):
|
| 232 |
+
return self.extra_special_tokens[token_name]
|
| 233 |
+
|
| 234 |
+
def construct_visual_indicators(self, grid, is_video: bool = False):
|
| 235 |
+
if is_video:
|
| 236 |
+
start_token = self.get_token_value("video_start")
|
| 237 |
+
end_token = self.get_token_value("video_end")
|
| 238 |
+
else:
|
| 239 |
+
start_token = self.get_token_value("image_start")
|
| 240 |
+
end_token = self.get_token_value("image_end")
|
| 241 |
+
|
| 242 |
+
visual_indicators = [start_token, self.get_token_value("visual_atom")]
|
| 243 |
+
if grid[0] * grid[1] > 1:
|
| 244 |
+
for _ in range(grid[0]):
|
| 245 |
+
for _ in range(grid[1]):
|
| 246 |
+
visual_indicators.append(self.get_token_value("visual_atom"))
|
| 247 |
+
visual_indicators.append(end_token)
|
| 248 |
+
return visual_indicators
|
| 249 |
+
|
| 250 |
+
def construct_visual_placeholders(self, grid, is_video: bool = False):
|
| 251 |
+
visual_placeholders = self.construct_visual_indicators((1, 1), is_video)
|
| 252 |
+
visual_atom_token_id = self.get_token_value("visual_atom")
|
| 253 |
+
image_padding_token_id = self.get_token_value("image_pad")
|
| 254 |
+
|
| 255 |
+
num_image_atoms = grid[0] * grid[1] * grid[2]
|
| 256 |
+
num_image_atoms //= self.hidden_stride**2
|
| 257 |
+
num_image_atoms //= self.temporal_patch_size
|
| 258 |
+
|
| 259 |
+
vision_start_token_id = self.tokenizer.get_vocab().get(
|
| 260 |
+
"<|vision_start|>",
|
| 261 |
+
image_padding_token_id,
|
| 262 |
+
)
|
| 263 |
+
vision_end_token_id = self.tokenizer.get_vocab().get(
|
| 264 |
+
"<|vision_end|>",
|
| 265 |
+
image_padding_token_id,
|
| 266 |
+
)
|
| 267 |
+
|
| 268 |
+
padded_placeholder_tokens = []
|
| 269 |
+
for token in visual_placeholders:
|
| 270 |
+
if token == visual_atom_token_id:
|
| 271 |
+
padded_placeholder_tokens.extend(
|
| 272 |
+
[image_padding_token_id] * num_image_atoms
|
| 273 |
+
)
|
| 274 |
+
elif token in (
|
| 275 |
+
self.get_token_value("image_start"),
|
| 276 |
+
self.get_token_value("video_start"),
|
| 277 |
+
):
|
| 278 |
+
padded_placeholder_tokens.append(vision_start_token_id)
|
| 279 |
+
elif token in (
|
| 280 |
+
self.get_token_value("image_end"),
|
| 281 |
+
self.get_token_value("video_end"),
|
| 282 |
+
):
|
| 283 |
+
padded_placeholder_tokens.append(vision_end_token_id)
|
| 284 |
+
else:
|
| 285 |
+
padded_placeholder_tokens.append(image_padding_token_id)
|
| 286 |
+
return padded_placeholder_tokens
|
| 287 |
+
|
| 288 |
+
def preprocess_multidata(
|
| 289 |
+
self,
|
| 290 |
+
images: Optional[Union[PIL.Image.Image, list[PIL.Image.Image]]] = None,
|
| 291 |
+
video: Optional[Union[list[PIL.Image.Image], np.ndarray]] = None,
|
| 292 |
+
do_convert_rgb: Optional[bool] = True,
|
| 293 |
+
convert_to_rgb: Optional[bool] = None,
|
| 294 |
+
min_pixels: int = MIN_PIXELS,
|
| 295 |
+
max_pixels: int = MAX_PIXELS,
|
| 296 |
+
return_tensors: Optional[str] = "pt",
|
| 297 |
+
):
|
| 298 |
+
if convert_to_rgb is not None:
|
| 299 |
+
do_convert_rgb = convert_to_rgb
|
| 300 |
+
|
| 301 |
+
is_video = False
|
| 302 |
+
if images is not None:
|
| 303 |
+
if not isinstance(images, list):
|
| 304 |
+
images = [images]
|
| 305 |
+
elif video is not None:
|
| 306 |
+
is_video = True
|
| 307 |
+
if isinstance(video, np.ndarray):
|
| 308 |
+
images = [
|
| 309 |
+
PIL.Image.fromarray(video[i].astype(np.uint8))
|
| 310 |
+
for i in range(video.shape[0])
|
| 311 |
+
]
|
| 312 |
+
elif isinstance(video, list):
|
| 313 |
+
images = video
|
| 314 |
+
else:
|
| 315 |
+
raise ValueError("Expected either images or video")
|
| 316 |
+
|
| 317 |
+
min_pixels = min(
|
| 318 |
+
max_pixels if max_pixels is not None else MAX_PIXELS,
|
| 319 |
+
min_pixels if min_pixels is not None else MIN_PIXELS,
|
| 320 |
+
)
|
| 321 |
+
images = [
|
| 322 |
+
image.convert("RGB") if do_convert_rgb and image.mode != "RGB" else image
|
| 323 |
+
for image in images
|
| 324 |
+
]
|
| 325 |
+
|
| 326 |
+
width, height = images[0].size
|
| 327 |
+
resized_height, resized_width = height, width
|
| 328 |
+
processed_images = []
|
| 329 |
+
for image in images:
|
| 330 |
+
resized_height, resized_width = self.smart_resize(
|
| 331 |
+
height,
|
| 332 |
+
width,
|
| 333 |
+
factor=self.patch_size * self.hidden_stride,
|
| 334 |
+
min_pixels=min_pixels,
|
| 335 |
+
max_pixels=max_pixels,
|
| 336 |
+
)
|
| 337 |
+
image_pt = self.image_processor.preprocess(
|
| 338 |
+
image,
|
| 339 |
+
size=dict(height=resized_height, width=resized_width),
|
| 340 |
+
return_tensors="np",
|
| 341 |
+
)["pixel_values"][0]
|
| 342 |
+
processed_images.append(image_pt)
|
| 343 |
+
|
| 344 |
+
patches = np.array(processed_images)
|
| 345 |
+
frame_remainder = patches.shape[0] % self.temporal_patch_size
|
| 346 |
+
if frame_remainder != 0:
|
| 347 |
+
num_to_pad = self.temporal_patch_size - frame_remainder
|
| 348 |
+
repeats = np.repeat(patches[-1][np.newaxis], num_to_pad, axis=0)
|
| 349 |
+
patches = np.concatenate([patches, repeats], axis=0)
|
| 350 |
+
|
| 351 |
+
channel = patches.shape[1]
|
| 352 |
+
grid_t = patches.shape[0] // self.temporal_patch_size
|
| 353 |
+
grid_h = resized_height // self.patch_size
|
| 354 |
+
grid_w = resized_width // self.patch_size
|
| 355 |
+
|
| 356 |
+
patches = patches.reshape(
|
| 357 |
+
grid_t,
|
| 358 |
+
self.temporal_patch_size,
|
| 359 |
+
channel,
|
| 360 |
+
grid_h // self.hidden_stride,
|
| 361 |
+
self.hidden_stride,
|
| 362 |
+
self.patch_size,
|
| 363 |
+
grid_w // self.hidden_stride,
|
| 364 |
+
self.hidden_stride,
|
| 365 |
+
self.patch_size,
|
| 366 |
+
)
|
| 367 |
+
patches = patches.transpose(0, 3, 6, 4, 7, 2, 1, 5, 8)
|
| 368 |
+
flatten_patches = patches.reshape(
|
| 369 |
+
grid_t * grid_h * grid_w,
|
| 370 |
+
channel * self.temporal_patch_size * self.patch_size * self.patch_size,
|
| 371 |
+
)
|
| 372 |
+
|
| 373 |
+
visual_placeholders = self.construct_visual_placeholders(
|
| 374 |
+
[grid_t, grid_h, grid_w],
|
| 375 |
+
is_video,
|
| 376 |
+
)
|
| 377 |
+
return (
|
| 378 |
+
torch.tensor(flatten_patches),
|
| 379 |
+
visual_placeholders,
|
| 380 |
+
torch.tensor([[grid_t, grid_h, grid_w]]),
|
| 381 |
+
)
|
| 382 |
+
|
| 383 |
+
|
| 384 |
+
AutoProcessor.register("OXRProcessor", OXRProcessor)
|
plugins/vllm/pyproject.toml
ADDED
|
@@ -0,0 +1,16 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
[build-system]
|
| 2 |
+
requires = ["setuptools>=69", "wheel"]
|
| 3 |
+
build-backend = "setuptools.build_meta"
|
| 4 |
+
|
| 5 |
+
[project]
|
| 6 |
+
name = "oxr-vllm-plugin"
|
| 7 |
+
version = "0.2.0"
|
| 8 |
+
description = "Out-of-tree OXR model plugin for vLLM 0.25.1"
|
| 9 |
+
requires-python = ">=3.12"
|
| 10 |
+
dependencies = ["vllm==0.25.1", "transformers==5.13.1"]
|
| 11 |
+
|
| 12 |
+
[project.entry-points."vllm.general_plugins"]
|
| 13 |
+
oxr = "oxr_vllm:register"
|
| 14 |
+
|
| 15 |
+
[tool.setuptools.packages.find]
|
| 16 |
+
include = ["oxr_vllm", "oxr_vllm.*"]
|
preprocessor_config.json
ADDED
|
@@ -0,0 +1,24 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
{
|
| 2 |
+
"do_convert_rgb": null,
|
| 3 |
+
"do_normalize": true,
|
| 4 |
+
"do_rescale": true,
|
| 5 |
+
"do_resize": true,
|
| 6 |
+
"image_mean": [
|
| 7 |
+
0.5,
|
| 8 |
+
0.5,
|
| 9 |
+
0.5
|
| 10 |
+
],
|
| 11 |
+
"image_processor_type": "SiglipImageProcessor",
|
| 12 |
+
"image_std": [
|
| 13 |
+
0.5,
|
| 14 |
+
0.5,
|
| 15 |
+
0.5
|
| 16 |
+
],
|
| 17 |
+
"processor_class": "SiglipProcessor",
|
| 18 |
+
"resample": 2,
|
| 19 |
+
"rescale_factor": 0.00392156862745098,
|
| 20 |
+
"size": {
|
| 21 |
+
"height": 512,
|
| 22 |
+
"width": 512
|
| 23 |
+
}
|
| 24 |
+
}
|
special_tokens_map.json
ADDED
|
@@ -0,0 +1,31 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
{
|
| 2 |
+
"additional_special_tokens": [
|
| 3 |
+
"<|im_start|>",
|
| 4 |
+
"<|im_end|>",
|
| 5 |
+
"<|object_ref_start|>",
|
| 6 |
+
"<|object_ref_end|>",
|
| 7 |
+
"<|box_start|>",
|
| 8 |
+
"<|box_end|>",
|
| 9 |
+
"<|quad_start|>",
|
| 10 |
+
"<|quad_end|>",
|
| 11 |
+
"<|vision_start|>",
|
| 12 |
+
"<|vision_end|>",
|
| 13 |
+
"<|vision_pad|>",
|
| 14 |
+
"<|image_pad|>",
|
| 15 |
+
"<|video_pad|>"
|
| 16 |
+
],
|
| 17 |
+
"eos_token": {
|
| 18 |
+
"content": "<|endoftext|>",
|
| 19 |
+
"lstrip": false,
|
| 20 |
+
"normalized": false,
|
| 21 |
+
"rstrip": false,
|
| 22 |
+
"single_word": false
|
| 23 |
+
},
|
| 24 |
+
"pad_token": {
|
| 25 |
+
"content": "<|endoftext|>",
|
| 26 |
+
"lstrip": false,
|
| 27 |
+
"normalized": false,
|
| 28 |
+
"rstrip": false,
|
| 29 |
+
"single_word": false
|
| 30 |
+
}
|
| 31 |
+
}
|
tokenizer.json
ADDED
|
@@ -0,0 +1,3 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
version https://git-lfs.github.com/spec/v1
|
| 2 |
+
oid sha256:aeb13307a71acd8fe81861d94ad54ab689df773318809eed3cbe794b4492dae4
|
| 3 |
+
size 11422654
|
tokenizer_config.json
ADDED
|
@@ -0,0 +1,240 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
{
|
| 2 |
+
"add_bos_token": false,
|
| 3 |
+
"add_prefix_space": false,
|
| 4 |
+
"added_tokens_decoder": {
|
| 5 |
+
"151643": {
|
| 6 |
+
"content": "<|endoftext|>",
|
| 7 |
+
"lstrip": false,
|
| 8 |
+
"normalized": false,
|
| 9 |
+
"rstrip": false,
|
| 10 |
+
"single_word": false,
|
| 11 |
+
"special": true
|
| 12 |
+
},
|
| 13 |
+
"151644": {
|
| 14 |
+
"content": "<|im_start|>",
|
| 15 |
+
"lstrip": false,
|
| 16 |
+
"normalized": false,
|
| 17 |
+
"rstrip": false,
|
| 18 |
+
"single_word": false,
|
| 19 |
+
"special": true
|
| 20 |
+
},
|
| 21 |
+
"151645": {
|
| 22 |
+
"content": "<|im_end|>",
|
| 23 |
+
"lstrip": false,
|
| 24 |
+
"normalized": false,
|
| 25 |
+
"rstrip": false,
|
| 26 |
+
"single_word": false,
|
| 27 |
+
"special": true
|
| 28 |
+
},
|
| 29 |
+
"151646": {
|
| 30 |
+
"content": "<|object_ref_start|>",
|
| 31 |
+
"lstrip": false,
|
| 32 |
+
"normalized": false,
|
| 33 |
+
"rstrip": false,
|
| 34 |
+
"single_word": false,
|
| 35 |
+
"special": true
|
| 36 |
+
},
|
| 37 |
+
"151647": {
|
| 38 |
+
"content": "<|object_ref_end|>",
|
| 39 |
+
"lstrip": false,
|
| 40 |
+
"normalized": false,
|
| 41 |
+
"rstrip": false,
|
| 42 |
+
"single_word": false,
|
| 43 |
+
"special": true
|
| 44 |
+
},
|
| 45 |
+
"151648": {
|
| 46 |
+
"content": "<|box_start|>",
|
| 47 |
+
"lstrip": false,
|
| 48 |
+
"normalized": false,
|
| 49 |
+
"rstrip": false,
|
| 50 |
+
"single_word": false,
|
| 51 |
+
"special": true
|
| 52 |
+
},
|
| 53 |
+
"151649": {
|
| 54 |
+
"content": "<|box_end|>",
|
| 55 |
+
"lstrip": false,
|
| 56 |
+
"normalized": false,
|
| 57 |
+
"rstrip": false,
|
| 58 |
+
"single_word": false,
|
| 59 |
+
"special": true
|
| 60 |
+
},
|
| 61 |
+
"151650": {
|
| 62 |
+
"content": "<|quad_start|>",
|
| 63 |
+
"lstrip": false,
|
| 64 |
+
"normalized": false,
|
| 65 |
+
"rstrip": false,
|
| 66 |
+
"single_word": false,
|
| 67 |
+
"special": true
|
| 68 |
+
},
|
| 69 |
+
"151651": {
|
| 70 |
+
"content": "<|quad_end|>",
|
| 71 |
+
"lstrip": false,
|
| 72 |
+
"normalized": false,
|
| 73 |
+
"rstrip": false,
|
| 74 |
+
"single_word": false,
|
| 75 |
+
"special": true
|
| 76 |
+
},
|
| 77 |
+
"151652": {
|
| 78 |
+
"content": "<|vision_start|>",
|
| 79 |
+
"lstrip": false,
|
| 80 |
+
"normalized": false,
|
| 81 |
+
"rstrip": false,
|
| 82 |
+
"single_word": false,
|
| 83 |
+
"special": true
|
| 84 |
+
},
|
| 85 |
+
"151653": {
|
| 86 |
+
"content": "<|vision_end|>",
|
| 87 |
+
"lstrip": false,
|
| 88 |
+
"normalized": false,
|
| 89 |
+
"rstrip": false,
|
| 90 |
+
"single_word": false,
|
| 91 |
+
"special": true
|
| 92 |
+
},
|
| 93 |
+
"151654": {
|
| 94 |
+
"content": "<|vision_pad|>",
|
| 95 |
+
"lstrip": false,
|
| 96 |
+
"normalized": false,
|
| 97 |
+
"rstrip": false,
|
| 98 |
+
"single_word": false,
|
| 99 |
+
"special": true
|
| 100 |
+
},
|
| 101 |
+
"151655": {
|
| 102 |
+
"content": "<|image_pad|>",
|
| 103 |
+
"lstrip": false,
|
| 104 |
+
"normalized": false,
|
| 105 |
+
"rstrip": false,
|
| 106 |
+
"single_word": false,
|
| 107 |
+
"special": true
|
| 108 |
+
},
|
| 109 |
+
"151656": {
|
| 110 |
+
"content": "<|video_pad|>",
|
| 111 |
+
"lstrip": false,
|
| 112 |
+
"normalized": false,
|
| 113 |
+
"rstrip": false,
|
| 114 |
+
"single_word": false,
|
| 115 |
+
"special": true
|
| 116 |
+
},
|
| 117 |
+
"151657": {
|
| 118 |
+
"content": "<tool_call>",
|
| 119 |
+
"lstrip": false,
|
| 120 |
+
"normalized": false,
|
| 121 |
+
"rstrip": false,
|
| 122 |
+
"single_word": false,
|
| 123 |
+
"special": false
|
| 124 |
+
},
|
| 125 |
+
"151658": {
|
| 126 |
+
"content": "</tool_call>",
|
| 127 |
+
"lstrip": false,
|
| 128 |
+
"normalized": false,
|
| 129 |
+
"rstrip": false,
|
| 130 |
+
"single_word": false,
|
| 131 |
+
"special": false
|
| 132 |
+
},
|
| 133 |
+
"151659": {
|
| 134 |
+
"content": "<|fim_prefix|>",
|
| 135 |
+
"lstrip": false,
|
| 136 |
+
"normalized": false,
|
| 137 |
+
"rstrip": false,
|
| 138 |
+
"single_word": false,
|
| 139 |
+
"special": false
|
| 140 |
+
},
|
| 141 |
+
"151660": {
|
| 142 |
+
"content": "<|fim_middle|>",
|
| 143 |
+
"lstrip": false,
|
| 144 |
+
"normalized": false,
|
| 145 |
+
"rstrip": false,
|
| 146 |
+
"single_word": false,
|
| 147 |
+
"special": false
|
| 148 |
+
},
|
| 149 |
+
"151661": {
|
| 150 |
+
"content": "<|fim_suffix|>",
|
| 151 |
+
"lstrip": false,
|
| 152 |
+
"normalized": false,
|
| 153 |
+
"rstrip": false,
|
| 154 |
+
"single_word": false,
|
| 155 |
+
"special": false
|
| 156 |
+
},
|
| 157 |
+
"151662": {
|
| 158 |
+
"content": "<|fim_pad|>",
|
| 159 |
+
"lstrip": false,
|
| 160 |
+
"normalized": false,
|
| 161 |
+
"rstrip": false,
|
| 162 |
+
"single_word": false,
|
| 163 |
+
"special": false
|
| 164 |
+
},
|
| 165 |
+
"151663": {
|
| 166 |
+
"content": "<|repo_name|>",
|
| 167 |
+
"lstrip": false,
|
| 168 |
+
"normalized": false,
|
| 169 |
+
"rstrip": false,
|
| 170 |
+
"single_word": false,
|
| 171 |
+
"special": false
|
| 172 |
+
},
|
| 173 |
+
"151664": {
|
| 174 |
+
"content": "<|file_sep|>",
|
| 175 |
+
"lstrip": false,
|
| 176 |
+
"normalized": false,
|
| 177 |
+
"rstrip": false,
|
| 178 |
+
"single_word": false,
|
| 179 |
+
"special": false
|
| 180 |
+
},
|
| 181 |
+
"151665": {
|
| 182 |
+
"content": "<tool_response>",
|
| 183 |
+
"lstrip": false,
|
| 184 |
+
"normalized": false,
|
| 185 |
+
"rstrip": false,
|
| 186 |
+
"single_word": false,
|
| 187 |
+
"special": false
|
| 188 |
+
},
|
| 189 |
+
"151666": {
|
| 190 |
+
"content": "</tool_response>",
|
| 191 |
+
"lstrip": false,
|
| 192 |
+
"normalized": false,
|
| 193 |
+
"rstrip": false,
|
| 194 |
+
"single_word": false,
|
| 195 |
+
"special": false
|
| 196 |
+
},
|
| 197 |
+
"151667": {
|
| 198 |
+
"content": "<think>",
|
| 199 |
+
"lstrip": false,
|
| 200 |
+
"normalized": false,
|
| 201 |
+
"rstrip": false,
|
| 202 |
+
"single_word": false,
|
| 203 |
+
"special": false
|
| 204 |
+
},
|
| 205 |
+
"151668": {
|
| 206 |
+
"content": "</think>",
|
| 207 |
+
"lstrip": false,
|
| 208 |
+
"normalized": false,
|
| 209 |
+
"rstrip": false,
|
| 210 |
+
"single_word": false,
|
| 211 |
+
"special": false
|
| 212 |
+
}
|
| 213 |
+
},
|
| 214 |
+
"additional_special_tokens": [
|
| 215 |
+
"<|im_start|>",
|
| 216 |
+
"<|im_end|>",
|
| 217 |
+
"<|object_ref_start|>",
|
| 218 |
+
"<|object_ref_end|>",
|
| 219 |
+
"<|box_start|>",
|
| 220 |
+
"<|box_end|>",
|
| 221 |
+
"<|quad_start|>",
|
| 222 |
+
"<|quad_end|>",
|
| 223 |
+
"<|vision_start|>",
|
| 224 |
+
"<|vision_end|>",
|
| 225 |
+
"<|vision_pad|>",
|
| 226 |
+
"<|image_pad|>",
|
| 227 |
+
"<|video_pad|>"
|
| 228 |
+
],
|
| 229 |
+
"bos_token": null,
|
| 230 |
+
"clean_up_tokenization_spaces": false,
|
| 231 |
+
"eos_token": "<|endoftext|>",
|
| 232 |
+
"errors": "replace",
|
| 233 |
+
"extra_special_tokens": {},
|
| 234 |
+
"model_max_length": 131072,
|
| 235 |
+
"pad_token": "<|endoftext|>",
|
| 236 |
+
"processor_class": "SiglipProcessor",
|
| 237 |
+
"split_special_tokens": false,
|
| 238 |
+
"tokenizer_class": "Qwen2Tokenizer",
|
| 239 |
+
"unk_token": null
|
| 240 |
+
}
|
vocab.json
ADDED
|
The diff for this file is too large to render.
See raw diff
|
|
|