


update README
Browse files- README-cn.md +0 -50
- README.md +2 -7
README-cn.md
CHANGED
|
@@ -147,7 +147,6 @@ datasets:
|
|
| 147 |
|
| 148 |
📂 **开放高质量数据**:与模型一同开源其背后的高质量训练数据,均属于 [UltraData](https://ultradata.openbmb.cn/) 数据体系:[UltraX](https://huggingface.co/datasets/openbmb/UltraX-Preview),高质量网页预训练数据集;[UltraData-Code](https://huggingface.co/datasets/openbmb/UltraData-Code),L0–L3 分级代码治理,推动代码能力显著跃升;[UltraData-SFT-Agent-2609](https://huggingface.co/datasets/openbmb/UltraData-SFT-Agent-2609),50 万 Agent 训练样本,赋能端侧 Agent 综合能力提升;[UltraData-RL-2609](https://huggingface.co/datasets/openbmb/UltraData-RL-2609),超 8 万条高质量 RL 训练样本,覆盖数学、代码、通用知识与长文本推理。
|
| 149 |
|
| 150 |
-
|
| 151 |
## 模型列表
|
| 152 |
|
| 153 |
你可以按运行环境选择对应模型格式:
|
|
@@ -183,8 +182,6 @@ MiniCPM5-2B 具有以下特性:
|
|
| 183 |
- **注意力头(GQA)**:16 个 Q heads / 2 个 KV heads
|
| 184 |
- **上下文长度**:131,072
|
| 185 |
|
| 186 |
-
|
| 187 |
-
|
| 188 |
## 简介
|
| 189 |
|
| 190 |
MiniCPM5-2B 是 MiniCPM5 系列的第二个模型,面向本地助手、coding agent、工具调用流程以及需要紧凑模型的推理场景。它在较小部署成本下提供原生长上下文能力。
|
|
@@ -195,7 +192,6 @@ MiniCPM5-2B 是 MiniCPM5 系列的第二个模型,面向本地助手、coding
|
|
| 195 |
|
| 196 |
在这组对比中,MiniCPM5-2B 达到同尺寸开源模型 SOTA 水平(平均分 53.9 ),也超过了参与对比的全部更大规模模型(最高 51.1)。其优势主要体现在代码推理、数学推理、长文本、工具调用与多个智能体任务上。
|
| 197 |
|
| 198 |
-
|
| 199 |
<div style="width:100%;max-width:1080px;margin:0 auto;padding:16px 0;background:#fff;
|
| 200 |
font-family:-apple-system,BlinkMacSystemFont,'Segoe UI',Roboto,'PingFang SC',
|
| 201 |
'Hiragino Sans GB','Microsoft YaHei',sans-serif;color:#171717">
|
|
@@ -258,26 +254,18 @@ MiniCPM5-2B 的训练过程是 **[UltraData 分级数据管理体系](https://ar
|
|
| 258 |
|
| 259 |
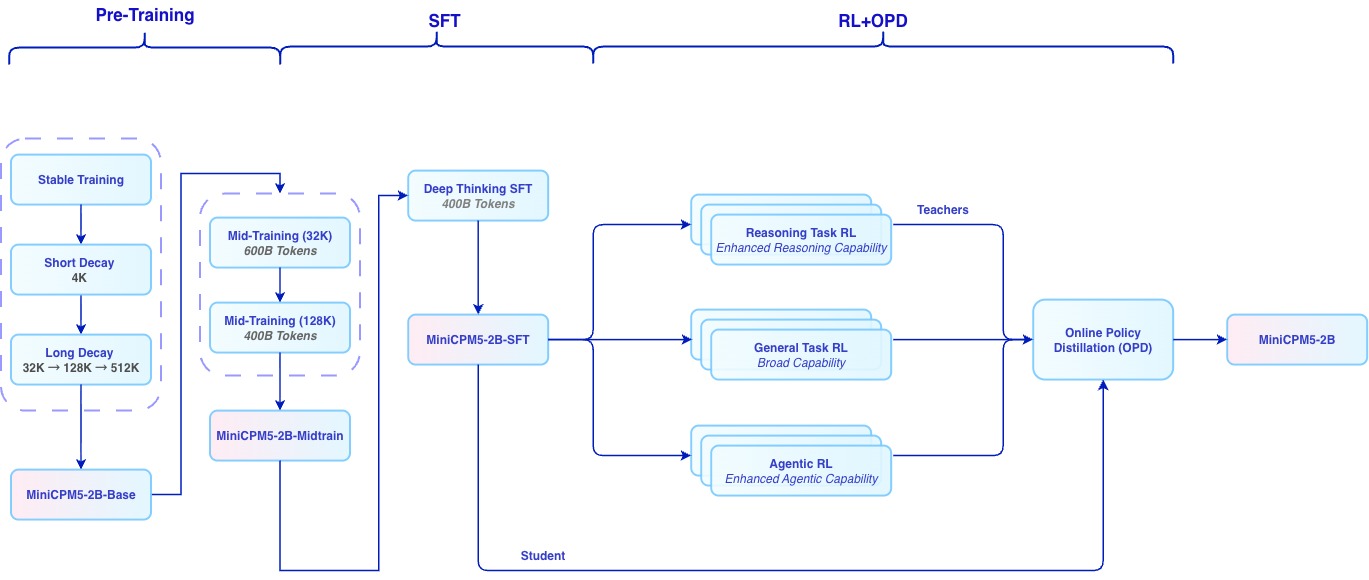
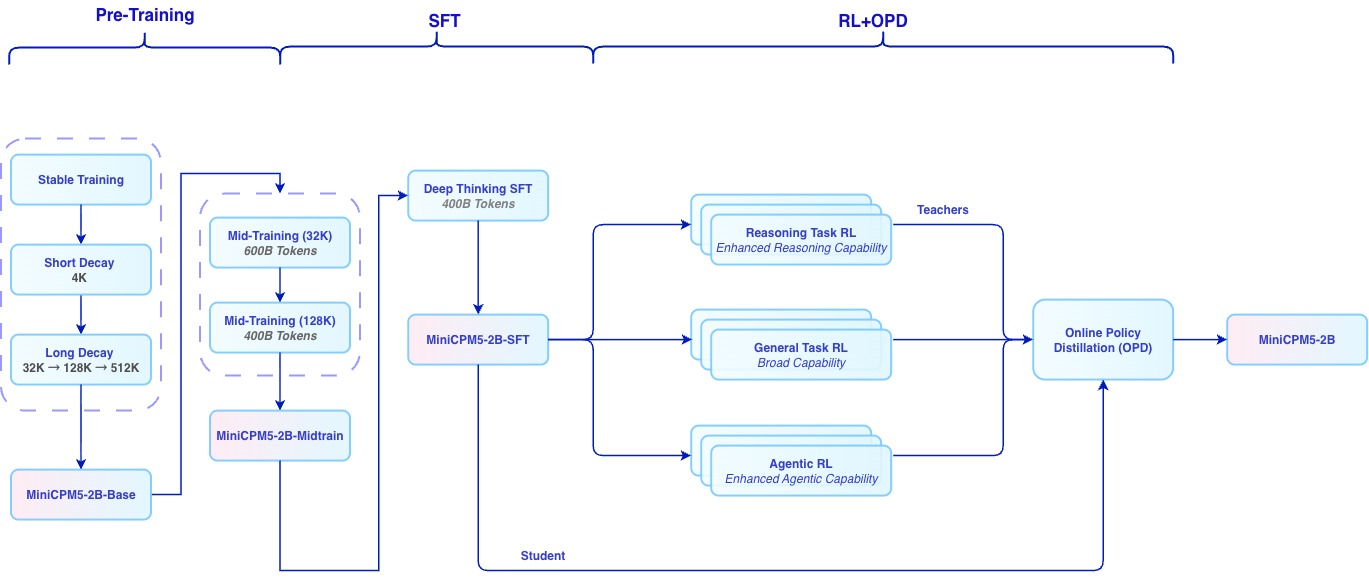
**后训练阶段**分为 **SFT**、**RL** 与 **OPD** 三步。我们先使用 **400B tokens deep-thinking SFT** 建立深度思考和通用对话能力,相关 SFT 数据已同步开源为 [UltraData-SFT-2605](https://huggingface.co/datasets/openbmb/UltraData-SFT-2605)与[UltraData-SFT-Agent-2609](https://huggingface.co/datasets/openbmb/UltraData-SFT-Agent-2609)。随后针对数学、代码、Agent 和写作等方向训练专用 **RL teacher**(相关数据已同步开源为[UltraData-RL-2609](https://huggingface.co/datasets/openbmb/UltraData-RL-2609)),并通过 **On-Policy Distillation (OPD)** 将这些 teacher 的能力蒸馏回同一个发布模型。
|
| 260 |
|
| 261 |
-
|
| 262 |
-
|
| 263 |
|
| 264 |
|
| 265 |
### RL + OPD 带来了什么?
|
| 266 |
|
| 267 |
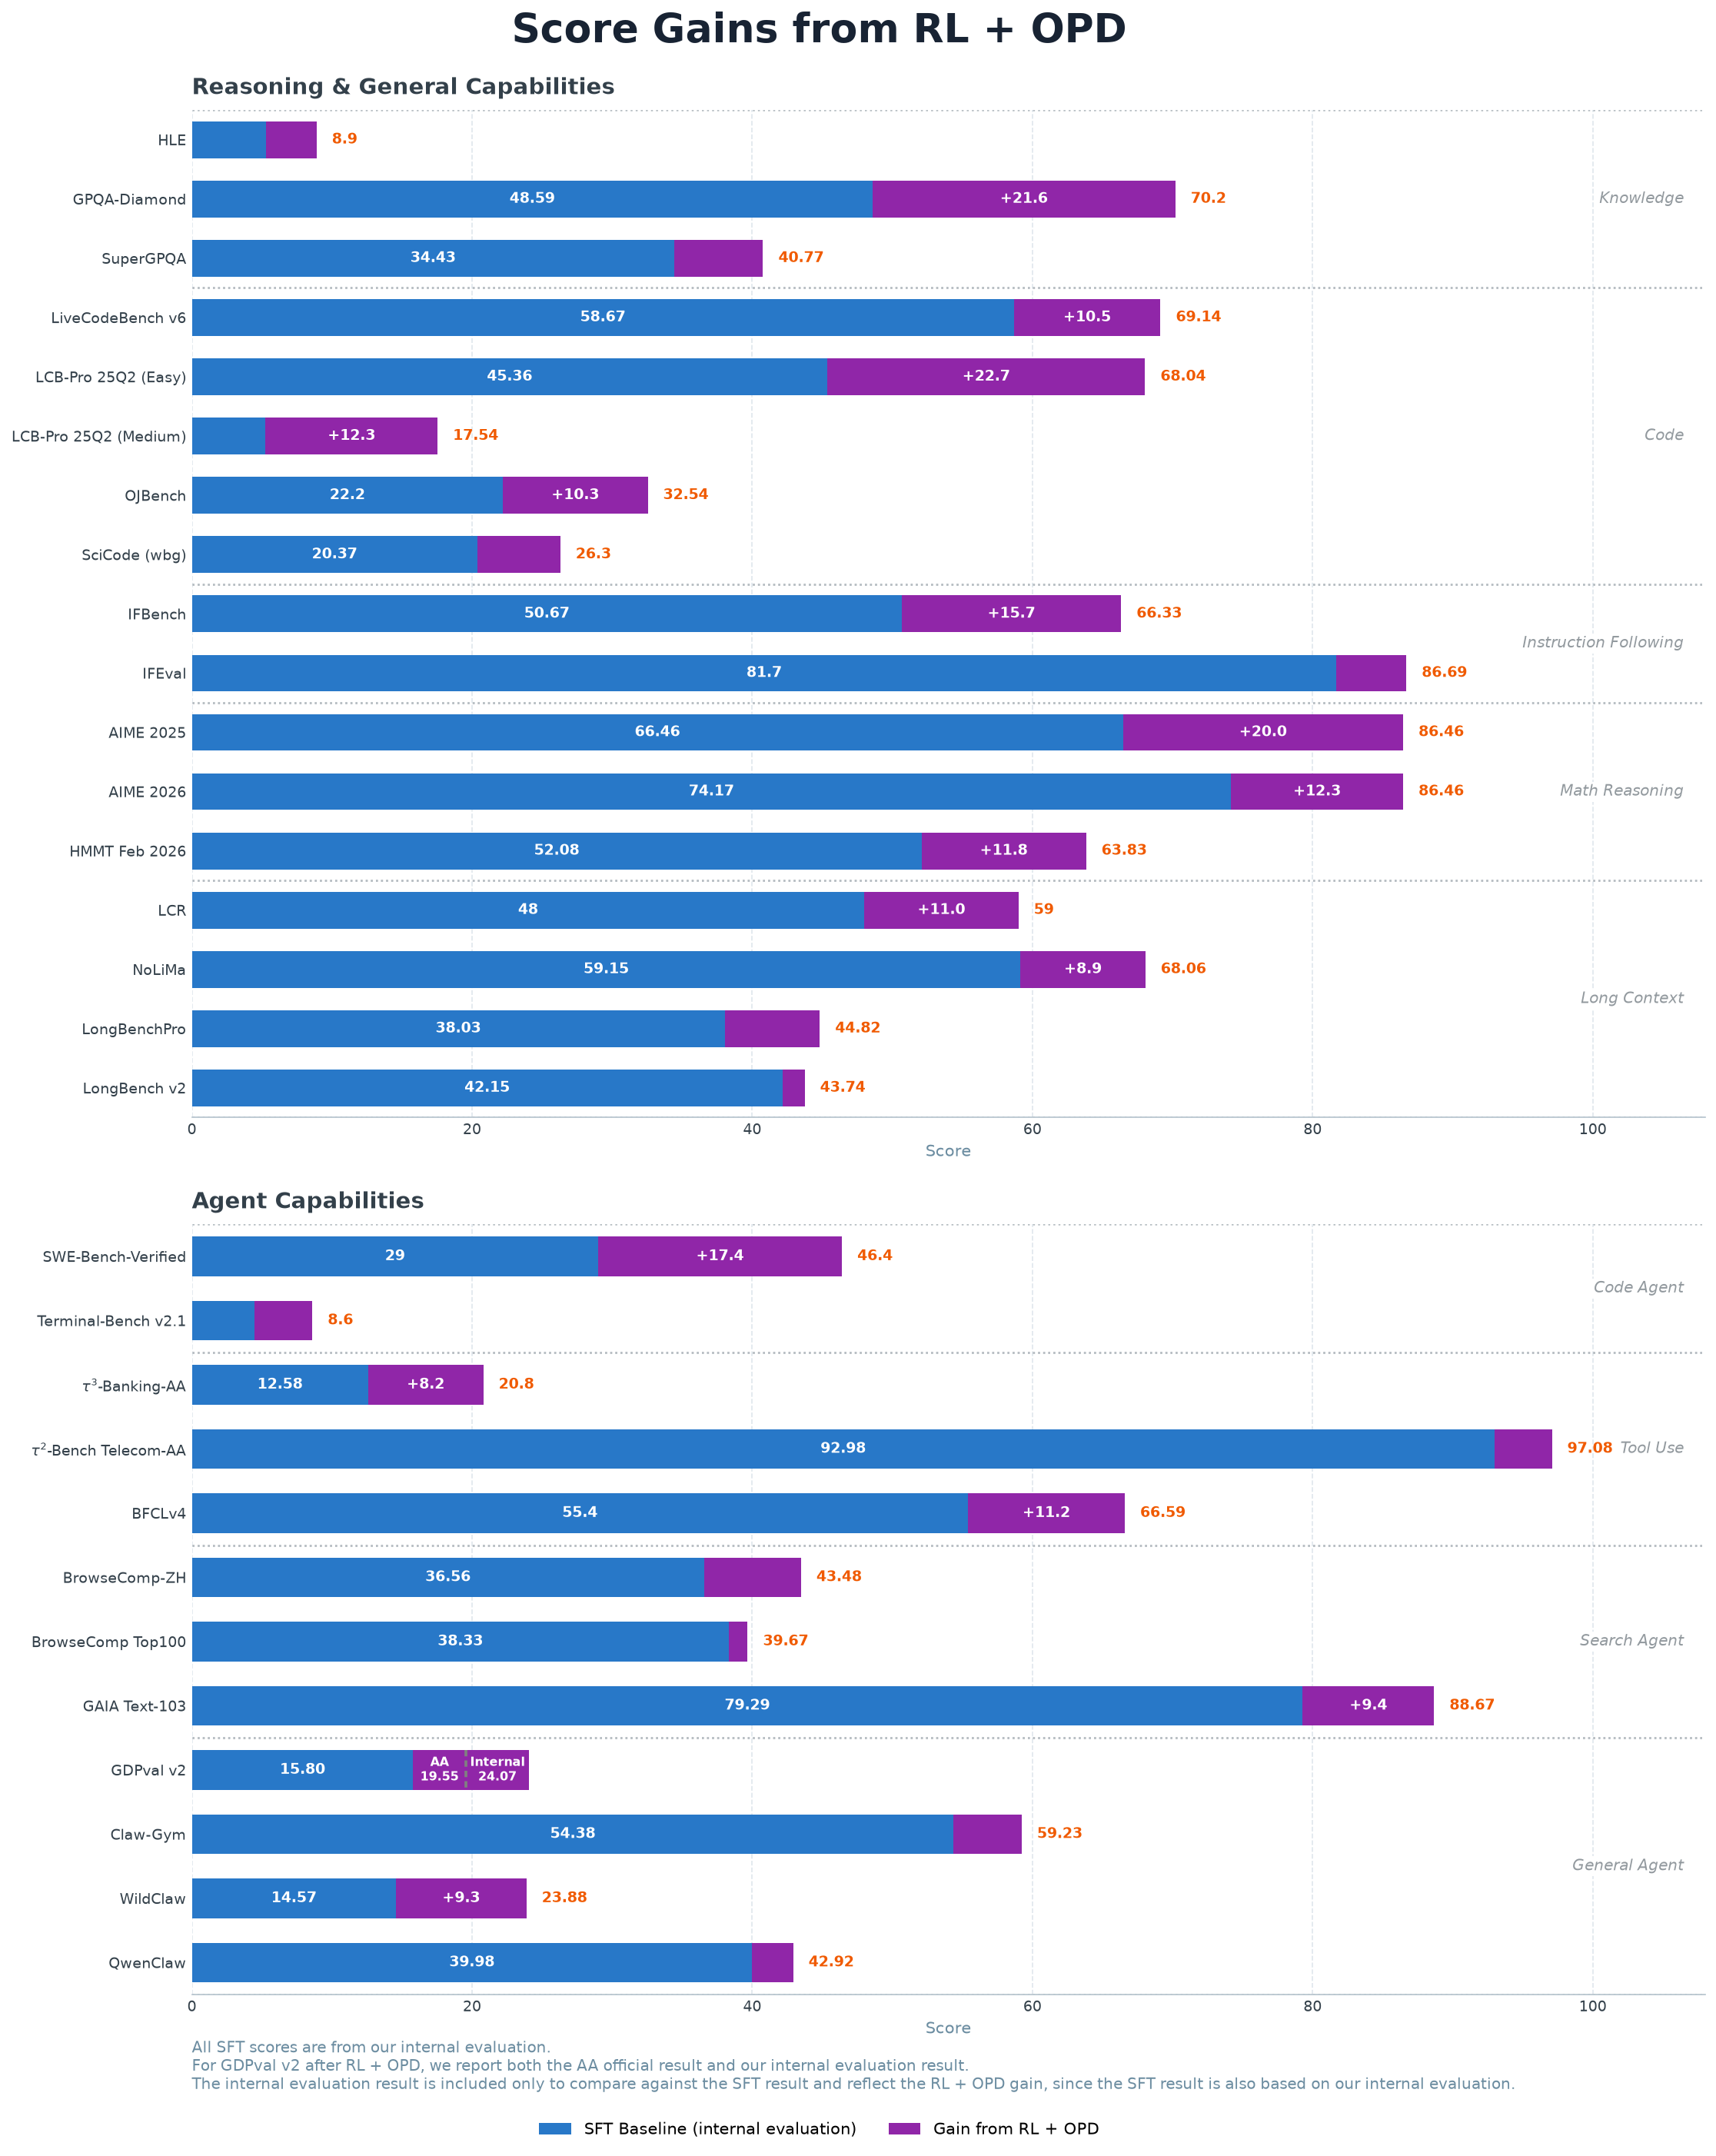
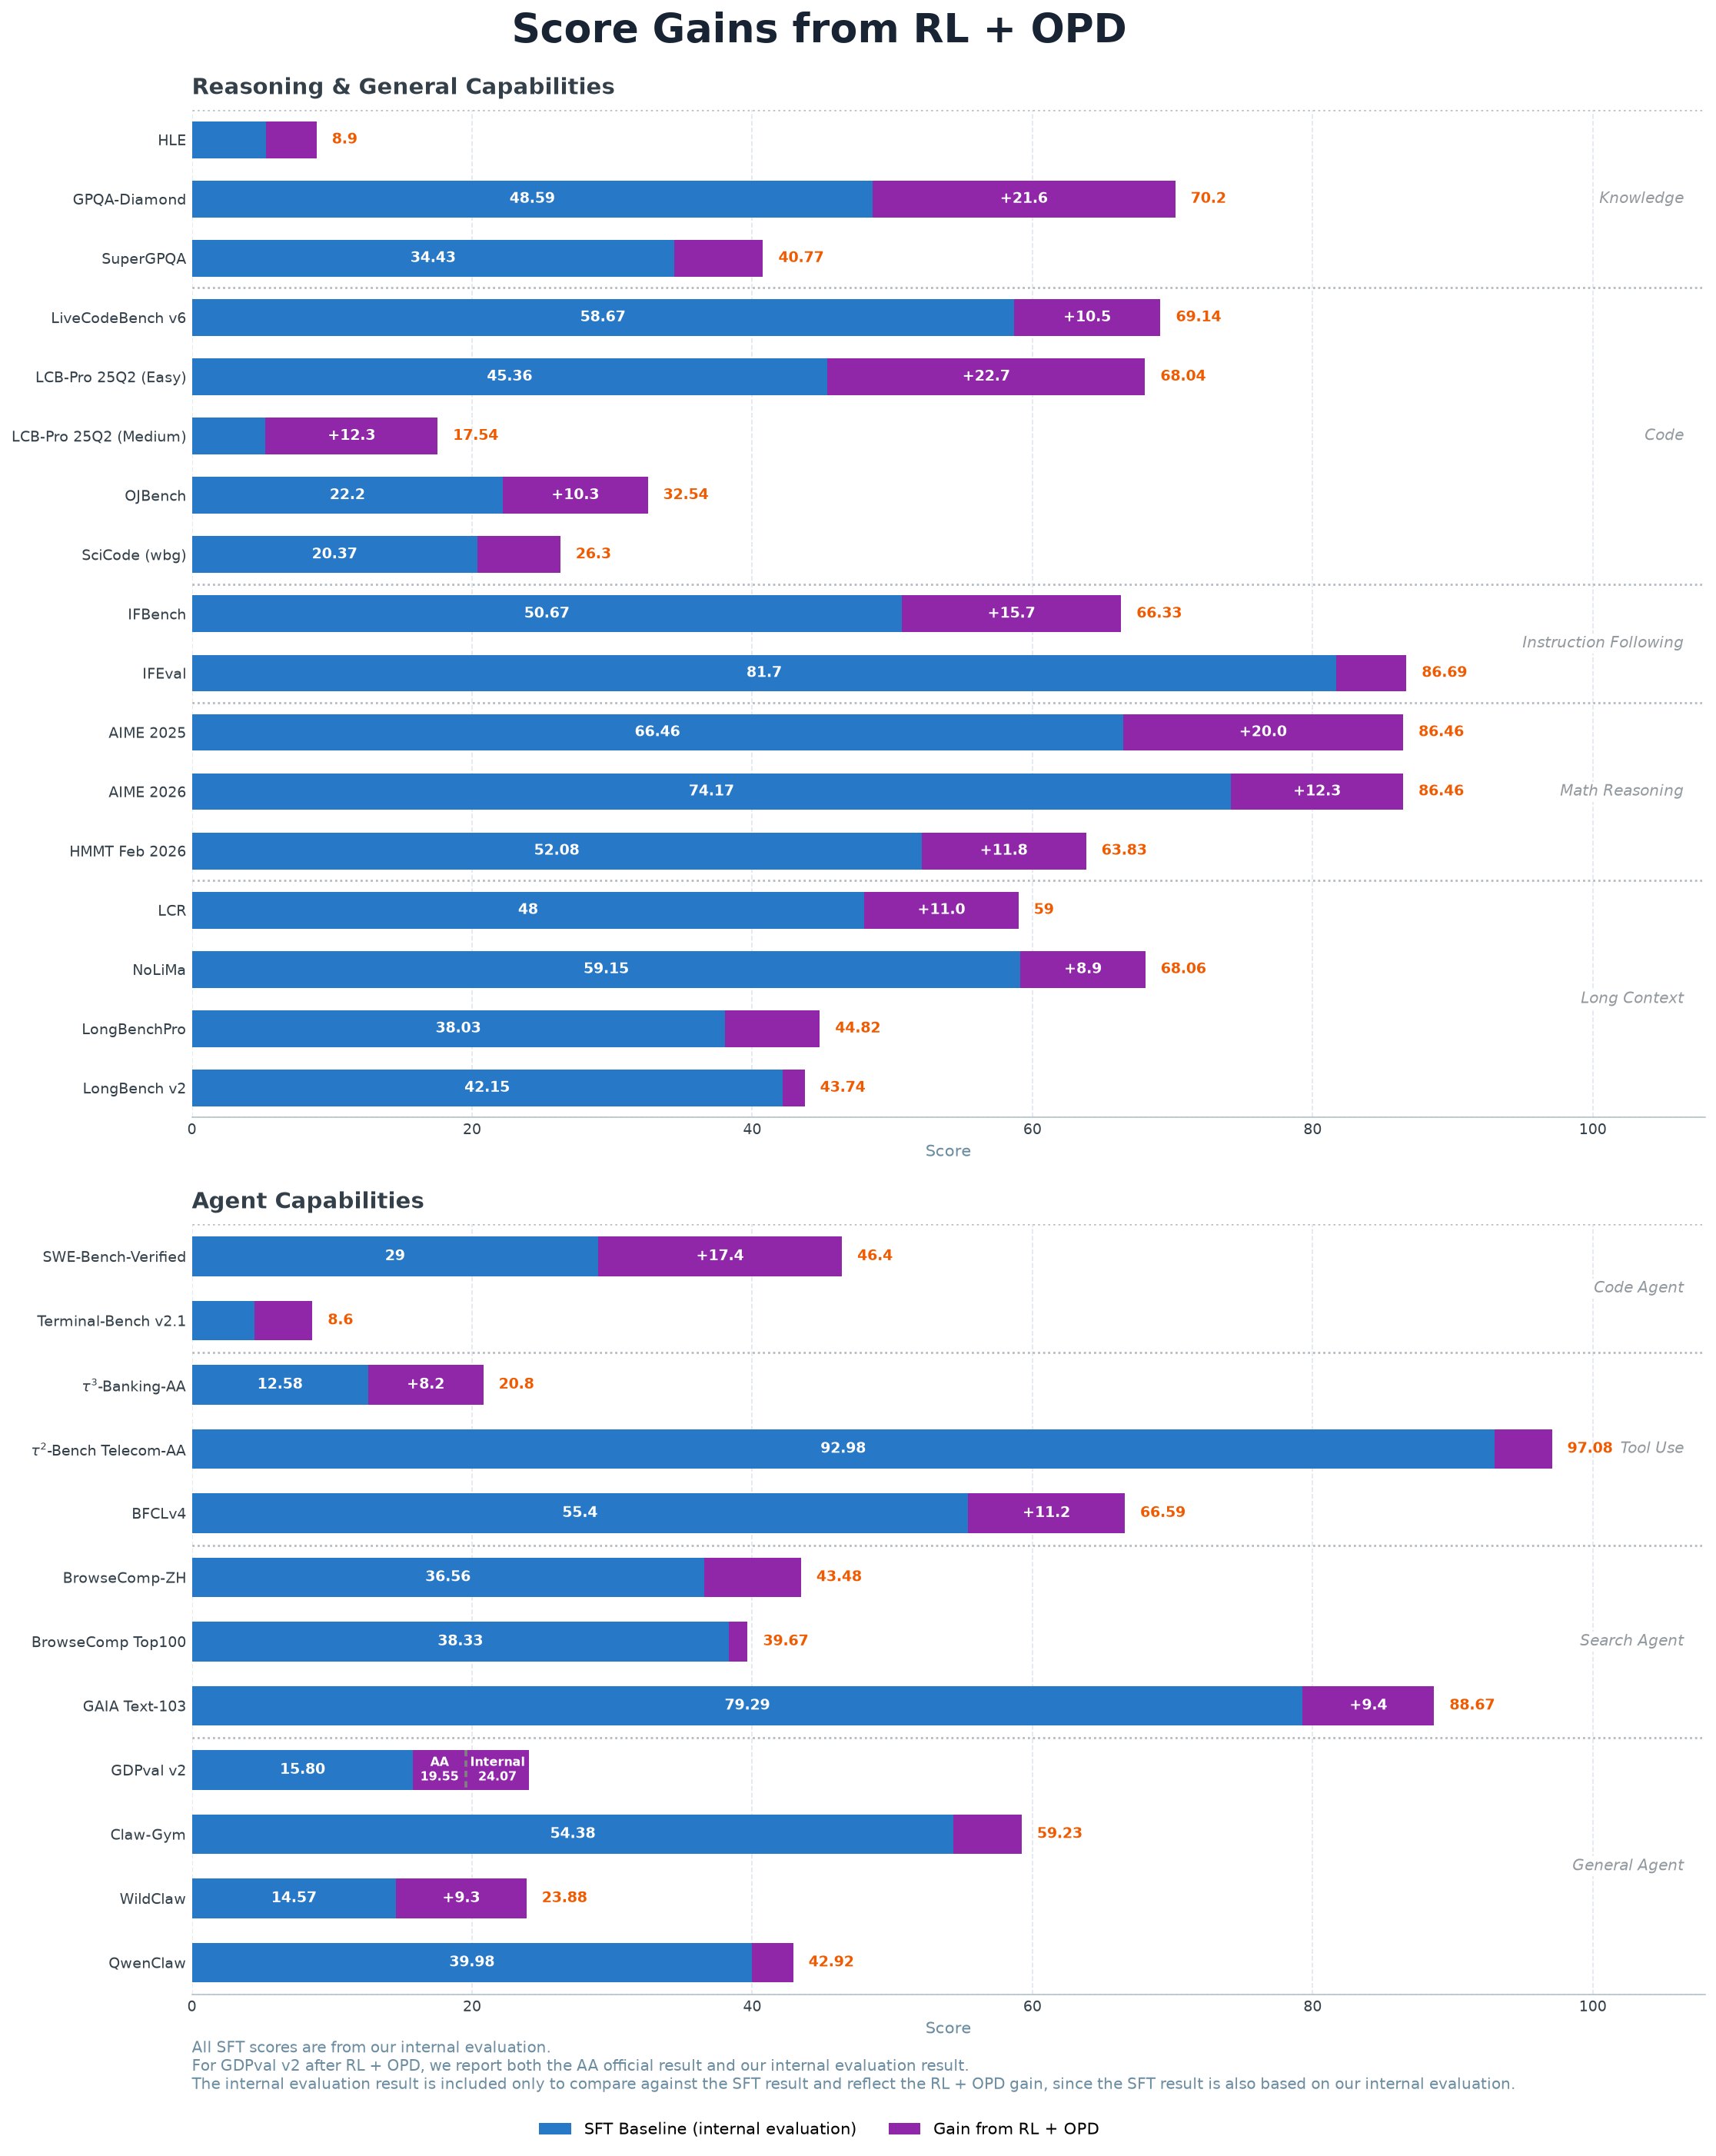
**RL + OPD** 是 MiniCPM5-2B 后训练中的关键环节。**RL** 阶段,使用了 [JustRL II](https://app.notion.com/p/panhaoxuan/JustRL-II-Scaling-Small-LLMs-to-128K-Reasoning-with-a-Critic-3c77e972297c80adb8b5f4b05d267012#5f3eb56b29f048ebab5f71138f12e36f) 阐述的 critic-based 算法,大幅提升训练稳定性,并在多个领域取得了显著的收益。在下面列出的基准中,RL + OPD 在推理与通用能力上平均提升 **↑ 10.96 分**,Agent 能力平均提升 **↑ 6.96 分**。
|
| 268 |
|
| 269 |
-
|
| 270 |
**OPD** 阶段对 16 个 RL 训练所得到的专家模型(含 5 个 agentic 专家模型)实现了能力合并。训练方式上,我们在 response 序列的每个位置分别对学生模型和教师模型 logits 计算全词表的反向 KL 散度作为优势估计值,替代原有的 verification-based advantage;训练数据上,我们的 OPD 直接复用各 RL teacher 训练时 prompt 作为蒸馏数据,无需额外构造语料。
|
| 271 |
|
| 272 |
-
|
| 273 |
-
|
| 274 |
|
| 275 |
|
| 276 |
-
|
| 277 |
## 快速上手
|
| 278 |
|
| 279 |
-
|
| 280 |
-
|
| 281 |
### vLLM
|
| 282 |
|
| 283 |
```bash
|
|
@@ -296,8 +284,6 @@ curl http://localhost:8000/v1/chat/completions \
|
|
| 296 |
}'
|
| 297 |
```
|
| 298 |
|
| 299 |
-
|
| 300 |
-
|
| 301 |
### SGLang
|
| 302 |
|
| 303 |
```bash
|
|
@@ -328,8 +314,6 @@ python -m sglang.launch_server \
|
|
| 328 |
--port 30000
|
| 329 |
```
|
| 330 |
|
| 331 |
-
|
| 332 |
-
|
| 333 |
### Transformers
|
| 334 |
|
| 335 |
```bash
|
|
@@ -369,15 +353,12 @@ python -m sglang.launch_server --model-path openbmb/MiniCPM5-2B --port 30000 \
|
|
| 369 |
--tool-call-parser minicpm5 # 或:--tool-call-parser auto
|
| 370 |
```
|
| 371 |
|
| 372 |
-
|
| 373 |
-
|
| 374 |
## GitHub Cookbooks 与 Agent Skills
|
| 375 |
|
| 376 |
MiniCPM5-2B 使用**标准** `LlamaForCausalLM` **架构**,主流推理引擎可直接加载,**无需自定义算子,也无模型代码 fork**。逐步部署和微调说明请参考下方 GitHub cookbooks;Agent Skills 作为 GitHub 资源提供给使用 Cursor / Claude Code 类 coding agent 的用户。
|
| 377 |
|
| 378 |
### 部署
|
| 379 |
|
| 380 |
-
|
| 381 |
| 后端 | 模型格式 / 适用场景 | Cookbook | Agent Skill |
|
| 382 |
| ------------ | ------------------------------------------- | ----------------------------------------------------------------------------------------------- | ------------------------------------------------------------------------------------------------------------------------- |
|
| 383 |
| Transformers | BF16 / FP16,本地 Python 推理,GPU + CPU | [transformers.md](https://github.com/OpenBMB/MiniCPM/blob/main/docs/deployment/transformers.md) | [minicpm5-deploy-transformers](https://github.com/OpenBMB/MiniCPM/blob/main/skills/minicpm5-deploy-transformers/SKILL.md) |
|
|
@@ -390,12 +371,8 @@ MiniCPM5-2B 使用**标准** `LlamaForCausalLM` **架构**,主流推理引擎
|
|
| 390 |
| ArcLight | GGUF 本地端侧 / CPU / 桌面 / 服务器 | [arclight.md](https://github.com/OpenBMB/MiniCPM/blob/main/docs/deployment/arclight.md) | [minicpm5-deploy-arclight](https://github.com/OpenBMB/MiniCPM/blob/main/skills/minicpm5-deploy-arclight/SKILL.md) |
|
| 391 |
| vLLM Ascend | BF16 / FP16 OpenAI server | [vllm_ascend.md](https://github.com/OpenBMB/MiniCPM/blob/main/docs/deployment/vllm_ascend.md) | [minicpm5-deploy-vllm-ascend](https://github.com/OpenBMB/MiniCPM/blob/main/skills/minicpm5-deploy-vllm-ascend/SKILL.md) |
|
| 392 |
|
| 393 |
-
|
| 394 |
-
|
| 395 |
-
|
| 396 |
### 微调
|
| 397 |
|
| 398 |
-
|
| 399 |
| 框架 | 适用场景 | Cookbook | Agent Skill |
|
| 400 |
| ------------- | ------------- | --------------------------------------------------------------------------------------------- | ----------------------------------------------------------------------------------------------------------------------------- |
|
| 401 |
| TRL + PEFT | LoRA / SFT 微调 | [trl.md](https://github.com/OpenBMB/MiniCPM/blob/main/docs/finetune/trl.md) | [minicpm5-finetune-trl](https://github.com/OpenBMB/MiniCPM/blob/main/skills/minicpm5-finetune-trl/SKILL.md) |
|
|
@@ -403,9 +380,6 @@ MiniCPM5-2B 使用**标准** `LlamaForCausalLM` **架构**,主流推理引擎
|
|
| 403 |
| ms-swift | 微调 | [ms_swift.md](https://github.com/OpenBMB/MiniCPM/blob/main/docs/finetune/ms_swift.md) | [minicpm5-finetune-ms-swift](https://github.com/OpenBMB/MiniCPM/blob/main/skills/minicpm5-finetune-ms-swift/SKILL.md) |
|
| 404 |
| unsloth | 微调 | [unsloth.md](https://github.com/OpenBMB/MiniCPM/blob/main/docs/finetune/unsloth.md) | [minicpm5-finetune-unsloth](https://github.com/OpenBMB/MiniCPM/blob/main/skills/minicpm5-finetune-unsloth/SKILL.md) |
|
| 405 |
|
| 406 |
-
|
| 407 |
-
|
| 408 |
-
|
| 409 |
### 其他支持的框架
|
| 410 |
|
| 411 |
除上文列出的部署与微调框架外,MiniCPM5-2B 也支持通过 FlagOS 进行多芯片部署。
|
|
@@ -418,7 +392,6 @@ FlagOS 社区致力于打造面向多种 AI 芯片的统一、开源的系统软
|
|
| 418 |
|
| 419 |
官网速递:[https://flagos.io](https://flagos.io/)
|
| 420 |
|
| 421 |
-
|
| 422 |
<details>
|
| 423 |
<summary>FlagOS 多 AI 芯片支持与使用方式</summary>
|
| 424 |
|
|
@@ -426,7 +399,6 @@ FlagOS 社区致力于打造面向多种 AI 芯片的统一、开源的系统软
|
|
| 426 |
|
| 427 |
基于 FlagOS 极短时间内适配 MiniCPM5-2B 到 9 种不同的 AI 芯片,得益于众智 FlagOS 的多芯片统一 AI 系统软件栈的能力。目前,在 FlagOS 团队构建的面向多架构人工智能芯片的大模型自动迁移、适配与发布平台 FlagRelease 上,已发布 MiniCPM5-2B 的多芯片版本。细节如下:
|
| 428 |
|
| 429 |
-
|
| 430 |
| Vendor | ModelScope | Huggingface |
|
| 431 |
| --------- | ------------------------------------------------------------------------------------------------------------- | --------------------------------------------------------------------------------------------------- |
|
| 432 |
| Nvidia | [MiniCPM5-2B-nvidia-FlagOS](https://www.modelscope.cn/models/FlagRelease/MiniCPM5-2B-nvidia-FlagOS) | [MiniCPM5-2B-nvidia-FlagOS](https://huggingface.co/FlagRelease/MiniCPM5-2B-nvidia-FlagOS) |
|
|
@@ -439,28 +411,18 @@ FlagOS 社区致力于打造面向多种 AI 芯片的统一、开源的系统软
|
|
| 439 |
| Ascend | [MiniCPM5-2B-ascend-FlagOS](https://modelscope.cn/models/FlagRelease/MiniCPM5-2B-ascend-FlagOS) | [MiniCPM5-2B-ascend-FlagOS](https://huggingface.co/FlagRelease/MiniCPM5-2B-ascend-FlagOS) |
|
| 440 |
| ARM-v9 | [MiniCPM5-2B-Armv9-FlagOS](https://modelscope.cn/models/FlagRelease/MiniCPM5-2B-Armv9-FlagOS) | [MiniCPM5-2B-Armv9-FlagOS](https://huggingface.co/FlagRelease/MiniCPM5-2B-Armv9-FlagOS) |
|
| 441 |
|
| 442 |
-
|
| 443 |
-
|
| 444 |
-
|
| 445 |
#### FlagOS 使用方式
|
| 446 |
|
| 447 |
-
|
| 448 |
-
|
| 449 |
##### 使用 FlagOS 在 Nvidia 体验性能加速
|
| 450 |
|
| 451 |
-
|
| 452 |
-
|
| 453 |
###### From FlagRelease(**推荐**)
|
| 454 |
|
| 455 |
FlagRelease是FlagOS团队构建的一套面向多架构人工智能芯片的大模型自动迁移、适配与发布平台,已发布MiniCPM5-2B的多芯片版本。FlagRelease 已内置相关软件包,无需用户安装。
|
| 456 |
|
| 457 |
###### FlagRelease 镜像关键版本信息
|
| 458 |
|
| 459 |
-
|
| 460 |
-
|
| 461 |
###### FlagRelease 使用速递
|
| 462 |
|
| 463 |
-
|
| 464 |
| Vendor | ModelScope | Huggingface |
|
| 465 |
| --------- | ------------------------------------------------------------------------------------------------------------- | --------------------------------------------------------------------------------------------------- |
|
| 466 |
| Nvidia | [MiniCPM5-2B-nvidia-FlagOS](https://www.modelscope.cn/models/FlagRelease/MiniCPM5-2B-nvidia-FlagOS) | [MiniCPM5-2B-nvidia-FlagOS](https://huggingface.co/FlagRelease/MiniCPM5-2B-nvidia-FlagOS) |
|
|
@@ -473,19 +435,12 @@ FlagRelease是FlagOS团队构建的一套面向多架构人工智能芯片的大
|
|
| 473 |
| Ascend | [MiniCPM5-2B-ascend-FlagOS](https://modelscope.cn/models/FlagRelease/MiniCPM5-2B-ascend-FlagOS) | [MiniCPM5-2B-ascend-FlagOS](https://huggingface.co/FlagRelease/MiniCPM5-2B-ascend-FlagOS) |
|
| 474 |
| ARM-v9 | [MiniCPM5-2B-Armv9-FlagOS](https://modelscope.cn/models/FlagRelease/MiniCPM5-2B-Armv9-FlagOS) | [MiniCPM5-2B-Armv9-FlagOS](https://huggingface.co/FlagRelease/MiniCPM5-2B-Armv9-FlagOS) |
|
| 475 |
|
| 476 |
-
|
| 477 |
-
|
| 478 |
-
|
| 479 |
###### 从零开始
|
| 480 |
|
| 481 |
- 依赖Python3.12, GLIBC_2.39, GLIBCXX_3.4.33, CXXABI_1.3.15 环境
|
| 482 |
|
| 483 |
-
|
| 484 |
-
|
| 485 |
###### Vllm 版本
|
| 486 |
|
| 487 |
-
|
| 488 |
-
|
| 489 |
###### 安装 FlagOS 算子库
|
| 490 |
|
| 491 |
官方仓库:[https://github.com/flagos-ai/FlagGems](https://github.com/flagos-ai/FlagGems)
|
|
@@ -495,8 +450,6 @@ pip install flag-gems==4.2.1rc0
|
|
| 495 |
pip install triton==3.5.1
|
| 496 |
```
|
| 497 |
|
| 498 |
-
|
| 499 |
-
|
| 500 |
###### 开启加速
|
| 501 |
|
| 502 |
通过在vllm执行推理的源码中增加flagGems的导入即可开启flagGems加速
|
|
@@ -516,15 +469,12 @@ vllm serve ${model_path} \
|
|
| 516 |
--gpu-memory-utilization 0.85
|
| 517 |
```
|
| 518 |
|
| 519 |
-
|
| 520 |
-
|
| 521 |
##### 使用 FlagOS 统一多芯片后端插件
|
| 522 |
|
| 523 |
**[vllm-plugin-FL](https://github.com/flagos-ai/vllm-plugin-FL)** 是一个为 **vLLM** 推理/服务框架构建的插件,它基于 **FlagOS 的统一多芯片后端**开发,旨在扩展 vLLM 在多种硬件环境下的功能和性能表现。
|
| 524 |
|
| 525 |
###### vllm-plugin-FL 使用
|
| 526 |
|
| 527 |
-
|
| 528 |
| 厂商 | 从零开始 | 从 FlagRelease 开始 | |
|
| 529 |
| --- | ---------------------------------------------------------------------------------------------------------------- | ---------------------------------------------------------------------------------------------------- | --------------------------------------------------------------------------------------------- |
|
| 530 |
| 英伟达 | [vllm-plugin-FL/MiniCPM5-2B](https://github.com/flagos-ai/vllm-plugin-FL/blob/main/examples/minicpm/README.md) | [MiniCPM5-2B-ModelScope](https://www.modelscope.cn/models/FlagRelease/MiniCPM5-2B-nvidia-FlagOS) | [MiniCPM5-2B-nvidia-FlagOS](https://huggingface.co/FlagRelease/MiniCPM5-2B-nvidia-FlagOS) |
|
|
|
|
| 147 |
|
| 148 |
📂 **开放高质量数据**:与模型一同开源其背后的高质量训练数据,均属于 [UltraData](https://ultradata.openbmb.cn/) 数据体系:[UltraX](https://huggingface.co/datasets/openbmb/UltraX-Preview),高质量网页预训练数据集;[UltraData-Code](https://huggingface.co/datasets/openbmb/UltraData-Code),L0–L3 分级代码治理,推动代码能力显著跃升;[UltraData-SFT-Agent-2609](https://huggingface.co/datasets/openbmb/UltraData-SFT-Agent-2609),50 万 Agent 训练样本,赋能端侧 Agent 综合能力提升;[UltraData-RL-2609](https://huggingface.co/datasets/openbmb/UltraData-RL-2609),超 8 万条高质量 RL 训练样本,覆盖数学、代码、通用知识与长文本推理。
|
| 149 |
|
|
|
|
| 150 |
## 模型列表
|
| 151 |
|
| 152 |
你可以按运行环境选择对应模型格式:
|
|
|
|
| 182 |
- **注意力头(GQA)**:16 个 Q heads / 2 个 KV heads
|
| 183 |
- **上下文长度**:131,072
|
| 184 |
|
|
|
|
|
|
|
| 185 |
## 简介
|
| 186 |
|
| 187 |
MiniCPM5-2B 是 MiniCPM5 系列的第二个模型,面向本地助手、coding agent、工具调用流程以及需要紧凑模型的推理场景。它在较小部署成本下提供原生长上下文能力。
|
|
|
|
| 192 |
|
| 193 |
在这组对比中,MiniCPM5-2B 达到同尺寸开源模型 SOTA 水平(平均分 53.9 ),也超过了参与对比的全部更大规模模型(最高 51.1)。其优势主要体现在代码推理、数学推理、长文本、工具调用与多个智能体任务上。
|
| 194 |
|
|
|
|
| 195 |
<div style="width:100%;max-width:1080px;margin:0 auto;padding:16px 0;background:#fff;
|
| 196 |
font-family:-apple-system,BlinkMacSystemFont,'Segoe UI',Roboto,'PingFang SC',
|
| 197 |
'Hiragino Sans GB','Microsoft YaHei',sans-serif;color:#171717">
|
|
|
|
| 254 |
|
| 255 |
**后训练阶段**分为 **SFT**、**RL** 与 **OPD** 三步。我们先使用 **400B tokens deep-thinking SFT** 建立深度思考和通用对话能力,相关 SFT 数据已同步开源为 [UltraData-SFT-2605](https://huggingface.co/datasets/openbmb/UltraData-SFT-2605)与[UltraData-SFT-Agent-2609](https://huggingface.co/datasets/openbmb/UltraData-SFT-Agent-2609)。随后针对数学、代码、Agent 和写作等方向训练专用 **RL teacher**(相关数据已同步开源为[UltraData-RL-2609](https://huggingface.co/datasets/openbmb/UltraData-RL-2609)),并通过 **On-Policy Distillation (OPD)** 将这些 teacher 的能力蒸馏回同一个发布模型。
|
| 256 |
|
|
|
|
|
|
|
| 257 |

|
| 258 |
|
| 259 |
### RL + OPD 带来了什么?
|
| 260 |
|
| 261 |
**RL + OPD** 是 MiniCPM5-2B 后训练中的关键环节。**RL** 阶段,使用了 [JustRL II](https://app.notion.com/p/panhaoxuan/JustRL-II-Scaling-Small-LLMs-to-128K-Reasoning-with-a-Critic-3c77e972297c80adb8b5f4b05d267012#5f3eb56b29f048ebab5f71138f12e36f) 阐述的 critic-based 算法,大幅提升训练稳定性,并在多个领域取得了显著的收益。在下面列出的基准中,RL + OPD 在推理与通用能力上平均提升 **↑ 10.96 分**,Agent 能力平均提升 **↑ 6.96 分**。
|
| 262 |
|
|
|
|
| 263 |
**OPD** 阶段对 16 个 RL 训练所得到的专家模型(含 5 个 agentic 专家模型)实现了能力合并。训练方式上,我们在 response 序列的每个位置分别对学生模型和教师模型 logits 计算全词表的反向 KL 散度作为优势估计值,替代原有的 verification-based advantage;训练数据上,我们的 OPD 直接复用各 RL teacher 训练时 prompt 作为蒸馏数据,无需额外构造语料。
|
| 264 |
|
|
|
|
|
|
|
| 265 |

|
| 266 |
|
|
|
|
| 267 |
## 快速上手
|
| 268 |
|
|
|
|
|
|
|
| 269 |
### vLLM
|
| 270 |
|
| 271 |
```bash
|
|
|
|
| 284 |
}'
|
| 285 |
```
|
| 286 |
|
|
|
|
|
|
|
| 287 |
### SGLang
|
| 288 |
|
| 289 |
```bash
|
|
|
|
| 314 |
--port 30000
|
| 315 |
```
|
| 316 |
|
|
|
|
|
|
|
| 317 |
### Transformers
|
| 318 |
|
| 319 |
```bash
|
|
|
|
| 353 |
--tool-call-parser minicpm5 # 或:--tool-call-parser auto
|
| 354 |
```
|
| 355 |
|
|
|
|
|
|
|
| 356 |
## GitHub Cookbooks 与 Agent Skills
|
| 357 |
|
| 358 |
MiniCPM5-2B 使用**标准** `LlamaForCausalLM` **架构**,主流推理引擎可直接加载,**无需自定义算子,也无模型代码 fork**。逐步部署和微调说明请参考下方 GitHub cookbooks;Agent Skills 作为 GitHub 资源提供给使用 Cursor / Claude Code 类 coding agent 的用户。
|
| 359 |
|
| 360 |
### 部署
|
| 361 |
|
|
|
|
| 362 |
| 后端 | 模型格式 / 适用场景 | Cookbook | Agent Skill |
|
| 363 |
| ------------ | ------------------------------------------- | ----------------------------------------------------------------------------------------------- | ------------------------------------------------------------------------------------------------------------------------- |
|
| 364 |
| Transformers | BF16 / FP16,本地 Python 推理,GPU + CPU | [transformers.md](https://github.com/OpenBMB/MiniCPM/blob/main/docs/deployment/transformers.md) | [minicpm5-deploy-transformers](https://github.com/OpenBMB/MiniCPM/blob/main/skills/minicpm5-deploy-transformers/SKILL.md) |
|
|
|
|
| 371 |
| ArcLight | GGUF 本地端侧 / CPU / 桌面 / 服务器 | [arclight.md](https://github.com/OpenBMB/MiniCPM/blob/main/docs/deployment/arclight.md) | [minicpm5-deploy-arclight](https://github.com/OpenBMB/MiniCPM/blob/main/skills/minicpm5-deploy-arclight/SKILL.md) |
|
| 372 |
| vLLM Ascend | BF16 / FP16 OpenAI server | [vllm_ascend.md](https://github.com/OpenBMB/MiniCPM/blob/main/docs/deployment/vllm_ascend.md) | [minicpm5-deploy-vllm-ascend](https://github.com/OpenBMB/MiniCPM/blob/main/skills/minicpm5-deploy-vllm-ascend/SKILL.md) |
|
| 373 |
|
|
|
|
|
|
|
|
|
|
| 374 |
### 微调
|
| 375 |
|
|
|
|
| 376 |
| 框架 | 适用场景 | Cookbook | Agent Skill |
|
| 377 |
| ------------- | ------------- | --------------------------------------------------------------------------------------------- | ----------------------------------------------------------------------------------------------------------------------------- |
|
| 378 |
| TRL + PEFT | LoRA / SFT 微调 | [trl.md](https://github.com/OpenBMB/MiniCPM/blob/main/docs/finetune/trl.md) | [minicpm5-finetune-trl](https://github.com/OpenBMB/MiniCPM/blob/main/skills/minicpm5-finetune-trl/SKILL.md) |
|
|
|
|
| 380 |
| ms-swift | 微调 | [ms_swift.md](https://github.com/OpenBMB/MiniCPM/blob/main/docs/finetune/ms_swift.md) | [minicpm5-finetune-ms-swift](https://github.com/OpenBMB/MiniCPM/blob/main/skills/minicpm5-finetune-ms-swift/SKILL.md) |
|
| 381 |
| unsloth | 微调 | [unsloth.md](https://github.com/OpenBMB/MiniCPM/blob/main/docs/finetune/unsloth.md) | [minicpm5-finetune-unsloth](https://github.com/OpenBMB/MiniCPM/blob/main/skills/minicpm5-finetune-unsloth/SKILL.md) |
|
| 382 |
|
|
|
|
|
|
|
|
|
|
| 383 |
### 其他支持的框架
|
| 384 |
|
| 385 |
除上文列出的部署与微调框架外,MiniCPM5-2B 也支持通过 FlagOS 进行多芯片部署。
|
|
|
|
| 392 |
|
| 393 |
官网速递:[https://flagos.io](https://flagos.io/)
|
| 394 |
|
|
|
|
| 395 |
<details>
|
| 396 |
<summary>FlagOS 多 AI 芯片支持与使用方式</summary>
|
| 397 |
|
|
|
|
| 399 |
|
| 400 |
基于 FlagOS 极短时间内适配 MiniCPM5-2B 到 9 种不同的 AI 芯片,得益于众智 FlagOS 的多芯片统一 AI 系统软件栈的能力。目前,在 FlagOS 团队构建的面向多架构人工智能芯片的大模型自动迁移、适配与发布平台 FlagRelease 上,已发布 MiniCPM5-2B 的多芯片版本。细节如下:
|
| 401 |
|
|
|
|
| 402 |
| Vendor | ModelScope | Huggingface |
|
| 403 |
| --------- | ------------------------------------------------------------------------------------------------------------- | --------------------------------------------------------------------------------------------------- |
|
| 404 |
| Nvidia | [MiniCPM5-2B-nvidia-FlagOS](https://www.modelscope.cn/models/FlagRelease/MiniCPM5-2B-nvidia-FlagOS) | [MiniCPM5-2B-nvidia-FlagOS](https://huggingface.co/FlagRelease/MiniCPM5-2B-nvidia-FlagOS) |
|
|
|
|
| 411 |
| Ascend | [MiniCPM5-2B-ascend-FlagOS](https://modelscope.cn/models/FlagRelease/MiniCPM5-2B-ascend-FlagOS) | [MiniCPM5-2B-ascend-FlagOS](https://huggingface.co/FlagRelease/MiniCPM5-2B-ascend-FlagOS) |
|
| 412 |
| ARM-v9 | [MiniCPM5-2B-Armv9-FlagOS](https://modelscope.cn/models/FlagRelease/MiniCPM5-2B-Armv9-FlagOS) | [MiniCPM5-2B-Armv9-FlagOS](https://huggingface.co/FlagRelease/MiniCPM5-2B-Armv9-FlagOS) |
|
| 413 |
|
|
|
|
|
|
|
|
|
|
| 414 |
#### FlagOS 使用方式
|
| 415 |
|
|
|
|
|
|
|
| 416 |
##### 使用 FlagOS 在 Nvidia 体验性能加速
|
| 417 |
|
|
|
|
|
|
|
| 418 |
###### From FlagRelease(**推荐**)
|
| 419 |
|
| 420 |
FlagRelease是FlagOS团队构建的一套面向多架构人工智能芯片的大模型自动迁移、适配与发布平台,已发布MiniCPM5-2B的多芯片版本。FlagRelease 已内置相关软件包,无需用户安装。
|
| 421 |
|
| 422 |
###### FlagRelease 镜像关键版本信息
|
| 423 |
|
|
|
|
|
|
|
| 424 |
###### FlagRelease 使用速递
|
| 425 |
|
|
|
|
| 426 |
| Vendor | ModelScope | Huggingface |
|
| 427 |
| --------- | ------------------------------------------------------------------------------------------------------------- | --------------------------------------------------------------------------------------------------- |
|
| 428 |
| Nvidia | [MiniCPM5-2B-nvidia-FlagOS](https://www.modelscope.cn/models/FlagRelease/MiniCPM5-2B-nvidia-FlagOS) | [MiniCPM5-2B-nvidia-FlagOS](https://huggingface.co/FlagRelease/MiniCPM5-2B-nvidia-FlagOS) |
|
|
|
|
| 435 |
| Ascend | [MiniCPM5-2B-ascend-FlagOS](https://modelscope.cn/models/FlagRelease/MiniCPM5-2B-ascend-FlagOS) | [MiniCPM5-2B-ascend-FlagOS](https://huggingface.co/FlagRelease/MiniCPM5-2B-ascend-FlagOS) |
|
| 436 |
| ARM-v9 | [MiniCPM5-2B-Armv9-FlagOS](https://modelscope.cn/models/FlagRelease/MiniCPM5-2B-Armv9-FlagOS) | [MiniCPM5-2B-Armv9-FlagOS](https://huggingface.co/FlagRelease/MiniCPM5-2B-Armv9-FlagOS) |
|
| 437 |
|
|
|
|
|
|
|
|
|
|
| 438 |
###### 从零开始
|
| 439 |
|
| 440 |
- 依赖Python3.12, GLIBC_2.39, GLIBCXX_3.4.33, CXXABI_1.3.15 环境
|
| 441 |
|
|
|
|
|
|
|
| 442 |
###### Vllm 版本
|
| 443 |
|
|
|
|
|
|
|
| 444 |
###### 安装 FlagOS 算子库
|
| 445 |
|
| 446 |
官方仓库:[https://github.com/flagos-ai/FlagGems](https://github.com/flagos-ai/FlagGems)
|
|
|
|
| 450 |
pip install triton==3.5.1
|
| 451 |
```
|
| 452 |
|
|
|
|
|
|
|
| 453 |
###### 开启加速
|
| 454 |
|
| 455 |
通过在vllm执行推理的源码中增加flagGems的导入即可开启flagGems加速
|
|
|
|
| 469 |
--gpu-memory-utilization 0.85
|
| 470 |
```
|
| 471 |
|
|
|
|
|
|
|
| 472 |
##### 使用 FlagOS 统一多芯片后端插件
|
| 473 |
|
| 474 |
**[vllm-plugin-FL](https://github.com/flagos-ai/vllm-plugin-FL)** 是一个为 **vLLM** 推理/服务框架构建的插件,它基于 **FlagOS 的统一多芯片后端**开发,旨在扩展 vLLM 在多种硬件环境下的功能和性能表现。
|
| 475 |
|
| 476 |
###### vllm-plugin-FL 使用
|
| 477 |
|
|
|
|
| 478 |
| 厂商 | 从零开始 | 从 FlagRelease 开始 | |
|
| 479 |
| --- | ---------------------------------------------------------------------------------------------------------------- | ---------------------------------------------------------------------------------------------------- | --------------------------------------------------------------------------------------------- |
|
| 480 |
| 英伟达 | [vllm-plugin-FL/MiniCPM5-2B](https://github.com/flagos-ai/vllm-plugin-FL/blob/main/examples/minicpm/README.md) | [MiniCPM5-2B-ModelScope](https://www.modelscope.cn/models/FlagRelease/MiniCPM5-2B-nvidia-FlagOS) | [MiniCPM5-2B-nvidia-FlagOS](https://huggingface.co/FlagRelease/MiniCPM5-2B-nvidia-FlagOS) |
|
README.md
CHANGED
|
@@ -155,8 +155,7 @@ We are releasing **MiniCPM5-2B**, the second model in the **MiniCPM5** series, f
|
|
| 155 |
</svg>
|
| 156 |
</div>
|
| 157 |
|
| 158 |
-
📂 **Open High-Quality Data**: Alongside the model, we are releasing the high-quality training datasets behind it as part of the [UltraData](https://ultradata.openbmb.cn/) family: [UltraX](https://huggingface.co/datasets/openbmb/UltraX-Preview), a high-quality web pre-training dataset; [UltraData-Code](https://huggingface.co/datasets/openbmb/UltraData-Code), featuring L0–L3 tiered code data
|
| 159 |
-
|
| 160 |
|
| 161 |
## Model List
|
| 162 |
|
|
@@ -263,9 +262,7 @@ The training of MiniCPM5-2B is a full-stack practice of **[UltraData Tiered Data
|
|
| 263 |
|
| 264 |
During **base training**, the model goes through stable training and decay training to build core language capability and training stability. It then enters **mid-training** to further strengthen target capabilities and adapt to the target data distribution. The training corpus is released alongside the model as [Ultra-FineWeb](https://huggingface.co/datasets/openbmb/Ultra-FineWeb), [Ultra-FineWeb-L3](https://huggingface.co/datasets/openbmb/Ultra-FineWeb-L3), [UltraX](https://huggingface.co/datasets/openbmb/UltraX-Preview), [UltraData-Code](https://huggingface.co/datasets/openbmb/UltraData-Code) and [UltraData-Math](https://huggingface.co/datasets/openbmb/UltraData-Math).
|
| 265 |
|
| 266 |
-
During **post-training**, we proceed in three steps: **SFT**, **RL**, and **OPD**. We first use **400B tokens of deep-thinking SFT** to establish deep-thinking and general chat abilities; the SFT data is released as [UltraData-SFT-2605](https://huggingface.co/datasets/openbmb/UltraData-SFT-2605). We then train specialized **RL teachers** for math, code, agentic tasks, writing, and related domains(with the corresponding data also open-sourced as [UltraData-RL-2609](https://huggingface.co/datasets/openbmb/UltraData-RL-2609)), and use **On-Policy Distillation (OPD)** to distill these teachers back into one release model.
|
| 267 |
-
|
| 268 |
-

|
| 269 |
|
| 270 |

|
| 271 |
|
|
@@ -275,8 +272,6 @@ During **post-training**, we proceed in three steps: **SFT**, **RL**, and **OPD*
|
|
| 275 |
|
| 276 |
**OPD** merges the capabilities of 16 expert models produced by RL training, including 5 agentic expert models. At each response position, we compute the full-vocabulary reverse KL divergence between student and teacher logits as the advantage estimate, replacing the original verification-based advantage. OPD directly reuses the prompts used to train each RL teacher as distillation data, so no additional corpus construction is required.
|
| 277 |
|
| 278 |
-

|
| 279 |
-
|
| 280 |

|
| 281 |
|
| 282 |
## Quickstart
|
|
|
|
| 155 |
</svg>
|
| 156 |
</div>
|
| 157 |
|
| 158 |
+
📂 **Open High-Quality Data**: Alongside the model, we are releasing the high-quality training datasets behind it as part of the [UltraData](https://ultradata.openbmb.cn/) family: [UltraX](https://huggingface.co/datasets/openbmb/UltraX-Preview), a high-quality web pre-training dataset; [UltraData-Code](https://huggingface.co/datasets/openbmb/UltraData-Code), featuring L0–L3 tiered code data management to drive a significant leap in coding capabilities; [UltraData-SFT-Agent-2609](https://huggingface.co/datasets/openbmb/UltraData-SFT-Agent-2609), comprising 500K agent training samples to enhance comprehensive on-device agent capabilities; and [UltraData-RL-2609](https://huggingface.co/datasets/openbmb/UltraData-RL-2609), with 80K+ high-quality RL training samples covering mathematics, code, general knowledge, and long-context reasoning.
|
|
|
|
| 159 |
|
| 160 |
## Model List
|
| 161 |
|
|
|
|
| 262 |
|
| 263 |
During **base training**, the model goes through stable training and decay training to build core language capability and training stability. It then enters **mid-training** to further strengthen target capabilities and adapt to the target data distribution. The training corpus is released alongside the model as [Ultra-FineWeb](https://huggingface.co/datasets/openbmb/Ultra-FineWeb), [Ultra-FineWeb-L3](https://huggingface.co/datasets/openbmb/Ultra-FineWeb-L3), [UltraX](https://huggingface.co/datasets/openbmb/UltraX-Preview), [UltraData-Code](https://huggingface.co/datasets/openbmb/UltraData-Code) and [UltraData-Math](https://huggingface.co/datasets/openbmb/UltraData-Math).
|
| 264 |
|
| 265 |
+
During **post-training**, we proceed in three steps: **SFT**, **RL**, and **OPD**. We first use **400B tokens of deep-thinking SFT** to establish deep-thinking and general chat abilities; the SFT data is released as [UltraData-SFT-2605](https://huggingface.co/datasets/openbmb/UltraData-SFT-2605) and the Agent SFT data is released as [UltraData-SFT-Agent-2609](https://huggingface.co/datasets/openbmb/UltraData-SFT-Agent-2609). We then train specialized **RL teachers** for math, code, agentic tasks, writing, and related domains (with the corresponding data also open-sourced as [UltraData-RL-2609](https://huggingface.co/datasets/openbmb/UltraData-RL-2609)), and use **On-Policy Distillation (OPD)** to distill these teachers back into one release model.
|
|
|
|
|
|
|
| 266 |
|
| 267 |

|
| 268 |
|
|
|
|
| 272 |
|
| 273 |
**OPD** merges the capabilities of 16 expert models produced by RL training, including 5 agentic expert models. At each response position, we compute the full-vocabulary reverse KL divergence between student and teacher logits as the advantage estimate, replacing the original verification-based advantage. OPD directly reuses the prompts used to train each RL teacher as distillation data, so no additional corpus construction is required.
|
| 274 |
|
|
|
|
|
|
|
| 275 |

|
| 276 |
|
| 277 |
## Quickstart
|