
Model-Based Online Decision Making via Generative Trajectory Planning



Abstract
Generative Trajectory Planning learns a diffusion-based proposal distribution over action sequences to enable efficient long-horizon reasoning by sampling and refining candidates with learned dynamics and value models.
Online decision-making faces a tension between efficient inference and long-horizon reasoning. Value-based methods rely on short-horizon bootstrapping that limits the propagation of long-term information, while trajectory optimization methods plan explicitly but must solve a high-dimensional optimization problem at every decision step. We propose Generative Trajectory Planning (GTP), a model-based framework that addresses this tension by learning a generative model as a proposal distribution over action sequences. Instead of optimizing sequences from scratch, GTP samples candidate sequences from a diffusion prior and refines them using learned dynamics, reward, and value models, enabling efficient trajectory-level reasoning. Across continuous control and long-horizon manipulation tasks, GTP matches or exceeds state-of-the-art model-free, diffusion-policy, and model-based baselines, and remains stable in regimes where strong baselines degrade. Our results suggest that generative models are best understood not as policies, but as structured proposal distributions for planning, offering a new perspective on how to integrate generative modeling with model-based decision-making.
Community
🧭 Introducing Generative Trajectory Planning (GTP), a model-based framework for online decision making that plans with a learned diffusion prior over action sequences.
Instead of optimizing action sequences from scratch at every step, GTP samples candidate sequences from the diffusion prior, refines them with beam search, and scores them with learned dynamics, reward and value models, all learned online from scratch in a self-improving loop.
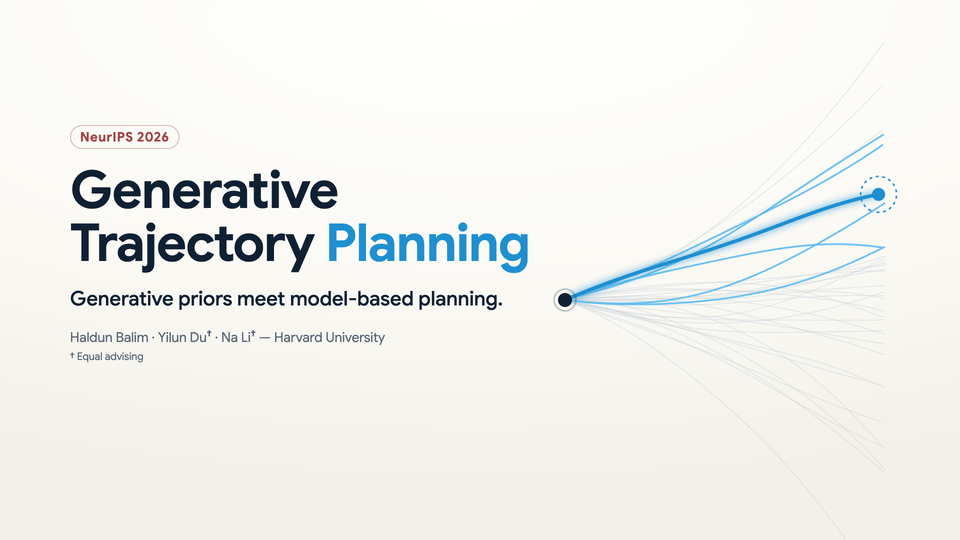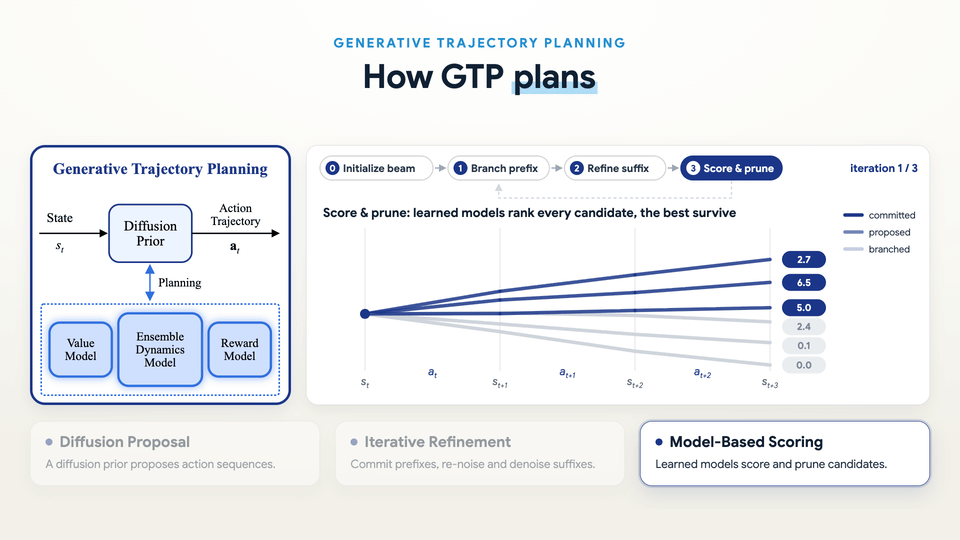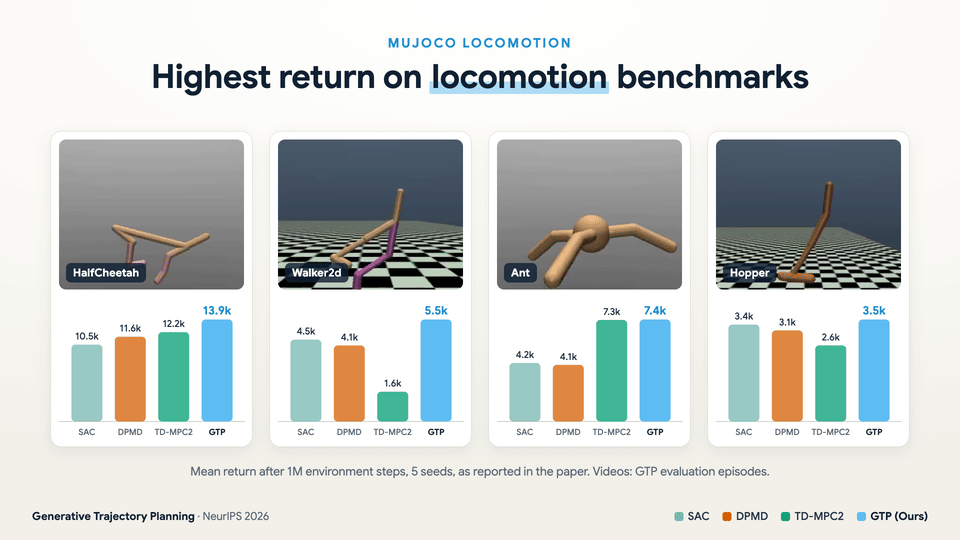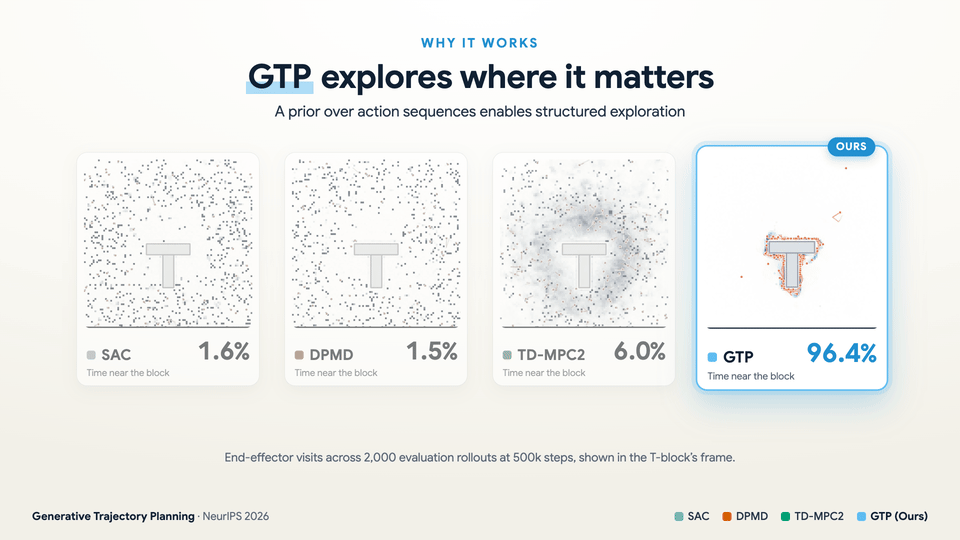
- 🏃 Locomotion: highest return on all five MuJoCo tasks against model-free, diffusion-policy and model-based baselines
- 🦾 Long-horizon manipulation: GTP solves PushT from pixels, where every baseline fails, and matches or beats every baseline on the Fetch tasks.
- 🔍 Structured exploration: the prior over action sequences steers exploration toward the states that matter for the task, instead of scattering the agent's visits across the state space.
- 🔭 Long-horizon training: by reasoning over whole action sequences, GTP keeps training stably on long-horizon tasks where policy-centric methods, limited by short-horizon bootstrapping, break down.
Code and trained models for every environment are available!
🌐 Project page · 💻 Code · 🤗 Models
We welcome your questions and feedback!

Get this paper in your agent:
hf papers read 2610.18677 Don't have the latest CLI?
curl -LsSf https://hf.co/cli/install.sh | bash Models citing this paper 1
Datasets citing this paper 0
No dataset linking this paper
Spaces citing this paper 0
No Space linking this paper
Collections including this paper 0
No Collection including this paper