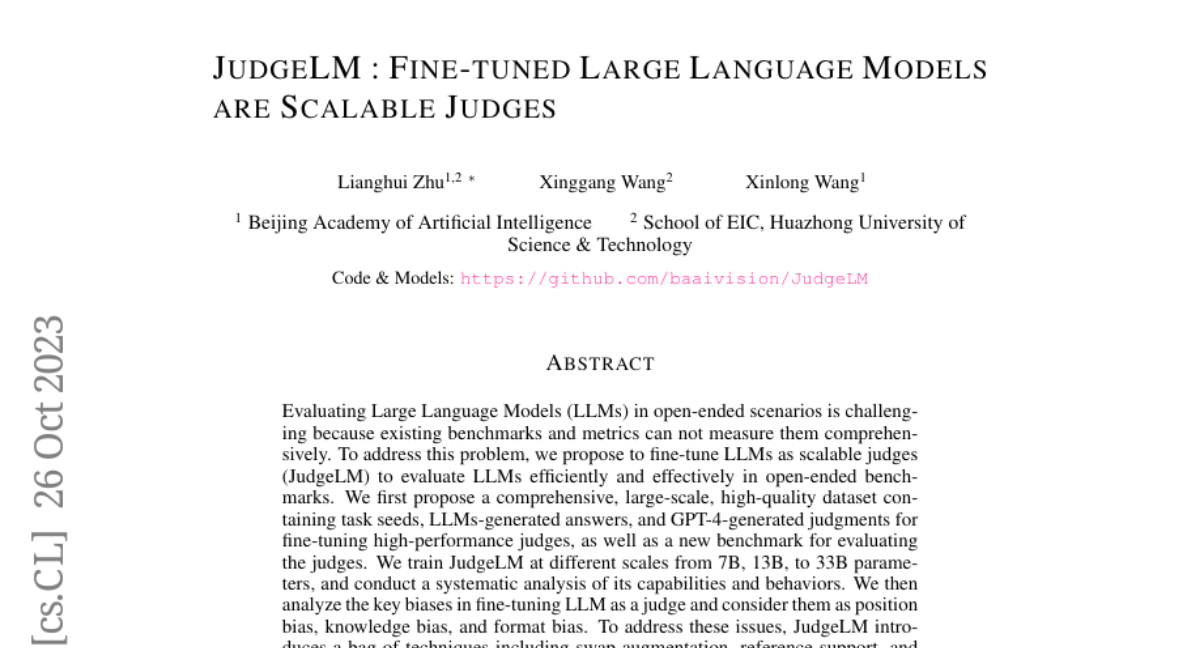
Submitted by akhaliq 35 JudgeLM: Fine-tuned Large Language Models are Scalable Judges · 3 authors 447 6
Submitted by akhaliq 12 Deja Vu: Contextual Sparsity for Efficient LLMs at Inference Time · 11 authors 365 1


 akhaliq