

File size: 4,319 Bytes
a935b56 c4d01dd 077527e 10c1ceb 077527e a935b56 7d21502 a935b56 7d21502 a935b56 7d21502 a935b56 7d21502 a935b56 | 1 2 3 4 5 6 7 8 9 10 11 12 13 14 15 16 17 18 19 20 21 22 23 24 25 26 27 28 29 30 31 32 33 34 35 36 37 38 39 40 41 42 43 44 45 46 47 48 49 50 51 52 53 54 55 56 57 58 59 60 61 62 63 64 65 66 67 68 69 70 71 72 73 74 75 76 77 78 79 80 81 82 83 84 85 86 87 88 89 90 91 92 93 94 95 96 97 98 99 100 101 102 103 104 105 | ---
license: apache-2.0
base_model: Qwen/Qwen3.5-4B
language:
- en
- ja
- zh
- de
- es
- fr
- ko
tags:
- decision-model
- distillation
- classification
- jev
pipeline_tag: text-classification
---
# fern
A 4B decision model with a Jev-compatible API. Send a `state` and up to 50 questions
(`choice` / `score` / `noul`); get probability distributions back from a single forward
pass — no text generation, ~30 ms per request on one GPU.
Distilled from [DeepSeek-V4-Flash](https://huggingface.co/deepseek-ai/DeepSeek-V4-Flash)
(2-bit GGUF teacher on one 96 GB GPU) into [Qwen3.5-4B](https://huggingface.co/Qwen/Qwen3.5-4B)
by matching the teacher's next-token distribution over the answer options.
Code and serving: https://github.com/reoring/fern
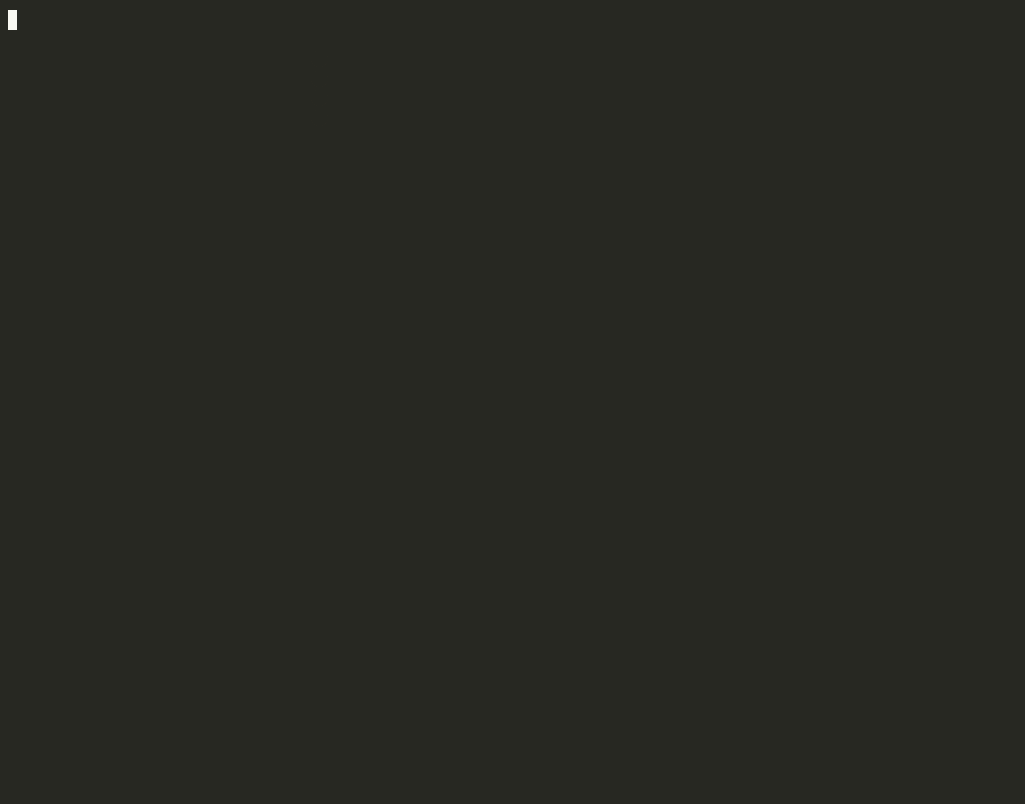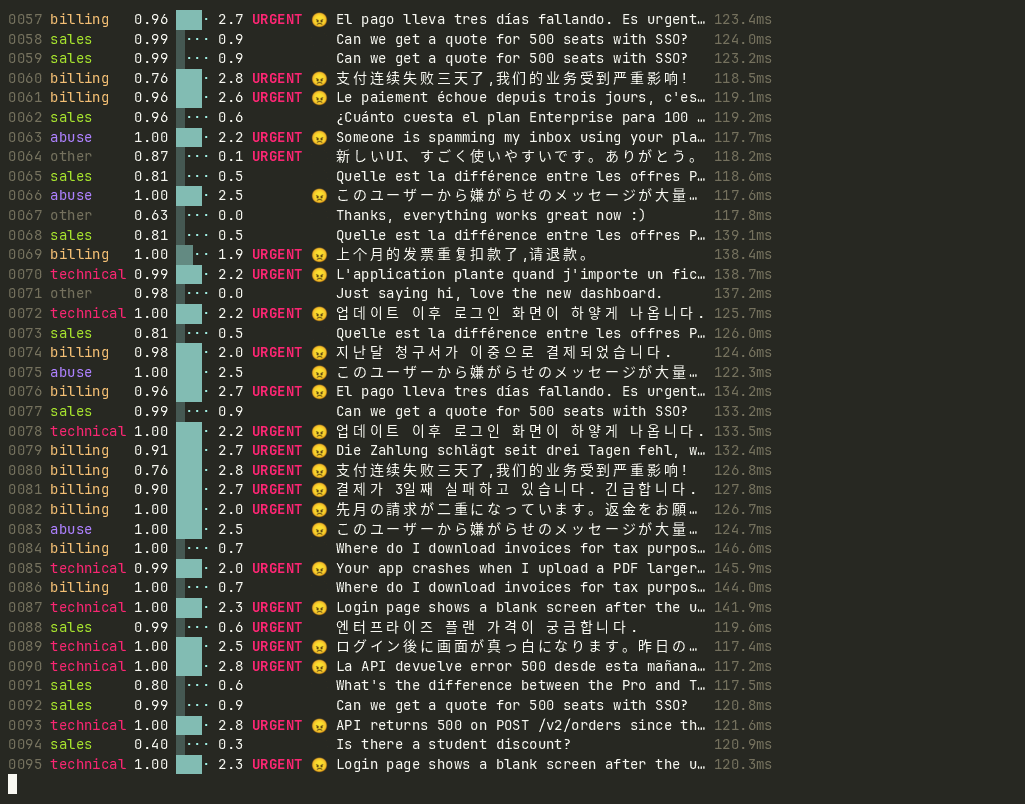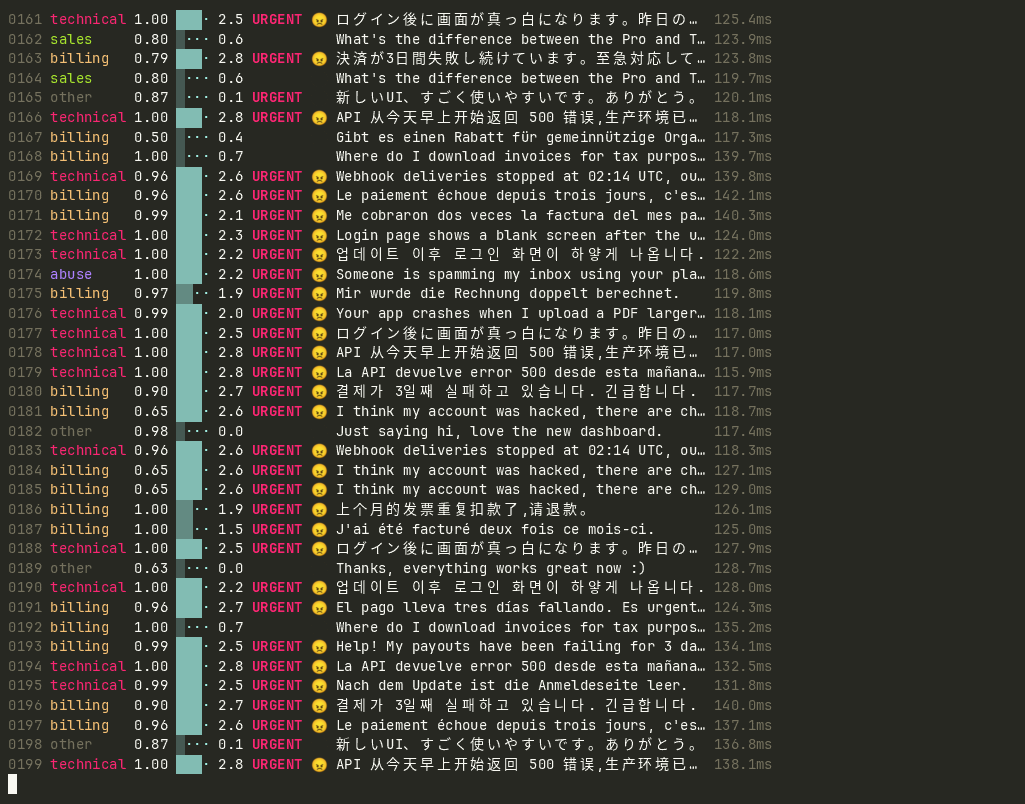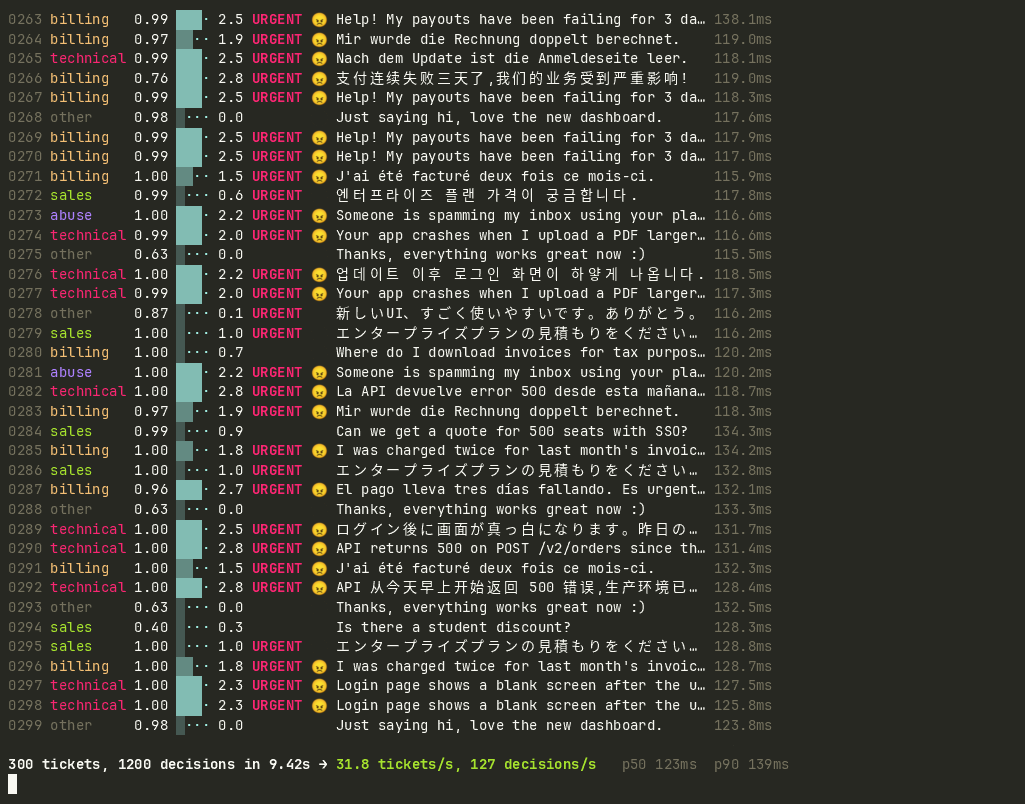
300 multilingual support tickets, each routed to a team with severity, urgency and
sentiment — 1,200 decisions in 9 s on one GPU (`scripts/demo.py` in the repo,
[asciinema](https://asciinema.org/a/m2qY1wX8DlhFroxx)).
## Usage
```bash
uv sync
uv run hf download reoring/fern --local-dir runs/fern
uv run fern serve runs/fern # POST http://127.0.0.1:8000/v1/systemone
```
```bash
curl -sS http://127.0.0.1:8000/v1/systemone -H 'Content-Type: application/json' -d '{
"state": "Help! My payouts have been failing for 3 days.",
"questions": {
"team": {"type": "choice", "instructions": "Which team should handle this?",
"criteria": {"billing": "Payments, invoicing, refunds", "technical": "Bugs, outages, integrations", "sales": "Pricing, upgrades"}},
"severity": {"type": "score", "instructions": "How severe is this?", "criteria": ["Low", "Medium", "High", "Critical"]},
"urgent": {"type": "noul", "instructions": "Does this need a reply today?"}
}
}'
# → team: billing (0.93), severity: 2.5 of 0..3, urgent: 0.97
```
The checkpoint is a plain `Qwen3_5ForCausalLM`; the API reads the logits of the option
codes (A–Z / 0–9 / yes,no) at the answer position. See the repo for the prompt template
(`fern.prompting.render`) if you want to call it without the server.
## Limits
- Max 26 options per `choice`, 10 levels per `score`, 1–50 questions per request.
- Prompts over 1,024 tokens are left-truncated (the start of `state` is dropped); the
server reports `usage.truncated: true`.
- Best on short states with clear criteria (routing, triage, labeling, safety flags).
Multi-step reasoning and long documents are out of range: MMLU-Pro accuracy is 0.42.
- Training is mostly English. Non-English inputs work (XNLI in 10 languages and ~25k
synthetic requests in ja/zh/de/es/fr/ko were in the mix) with lower agreement.
## Evaluation
Agreement = argmax matches the teacher's argmax on held-out label files.
| | v3b |
|---|---|
| Held-out training distribution (7.7k) | 0.94 |
| Thinking teacher, MMLU-Pro (2k, 10-way) | 0.49 |
| MMLU-Pro accuracy (2k) | 0.42 |
| 11–26-way choice (920) | 0.85 |
| XNLI, 10 languages (740) | 0.84 |
| Synthetic requests, 6 non-English languages (1.5k) | 0.78 |
| Synthetic requests, English (1.9k, in-distribution) | 0.90 |
| Latency, 1 / 10 questions (p50, RTX PRO 6000, bf16) | 28 / 48 ms |
## Training
- Teacher: DeepSeek-V4-Flash UD-IQ2_M via llama-server, prefill only (`n_probs`), thinking
budget 512 tokens for knowledge sources, none elsewhere.
- Student: full fine-tune, bf16, AdamW lr 1e-5 cosine, batch 64, 2 epochs + 1 continued epoch at lr 5e-6, max_len 1,024,
loss `KL(p_teacher ‖ p_student)` over the option codes. 379k rows (after weighting), 17.6 h + 8.8 h.
- Sources: HellaSwag, MNLI, XNLI, Yelp reviews, CommonsenseQA, BoolQ, ARC, TweetEval, MMLU
(+ auxiliary_train), OpenBookQA, SciQ, GSM8K (multiple-choice form), 11–26-way variants
padded with same-source distractors, ~40k synthetic Jev-style requests in 7 languages
written by the teacher.
## License and attribution
Apache-2.0. Derived from Qwen3.5-4B (Apache-2.0) with soft labels from DeepSeek-V4-Flash
(MIT). Training data includes Yelp reviews, whose dataset terms are non-commercial; check
them before commercial use of the weights. "Jev" refers to the API shape this model is
compatible with; this is an independent project.
|