

Commit ·
19f6edb
0
Parent(s):
Duplicate from OFA-Sys/small-stable-diffusion-v0
Browse filesCo-authored-by: lu <cq@users.noreply.huggingface.co>
- .gitattributes +35 -0
- README.md +171 -0
- feature_extractor/preprocessor_config.json +28 -0
- model_index.json +32 -0
- safety_checker/config.json +180 -0
- safety_checker/pytorch_model.bin +3 -0
- sample_images.jpg +3 -0
- sample_images_compressed.jpg +0 -0
- scheduler/scheduler_config.json +17 -0
- text_encoder/config.json +24 -0
- text_encoder/pytorch_model.bin +3 -0
- tokenizer/merges.txt +0 -0
- tokenizer/special_tokens_map.json +24 -0
- tokenizer/tokenizer_config.json +34 -0
- tokenizer/vocab.json +0 -0
- unet/config.json +36 -0
- unet/diffusion_pytorch_model.bin +3 -0
- vae/config.json +30 -0
- vae/diffusion_pytorch_model.bin +3 -0
.gitattributes
ADDED
|
@@ -0,0 +1,35 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
*.7z filter=lfs diff=lfs merge=lfs -text
|
| 2 |
+
*.arrow filter=lfs diff=lfs merge=lfs -text
|
| 3 |
+
*.bin filter=lfs diff=lfs merge=lfs -text
|
| 4 |
+
*.bz2 filter=lfs diff=lfs merge=lfs -text
|
| 5 |
+
*.ckpt filter=lfs diff=lfs merge=lfs -text
|
| 6 |
+
*.ftz filter=lfs diff=lfs merge=lfs -text
|
| 7 |
+
*.gz filter=lfs diff=lfs merge=lfs -text
|
| 8 |
+
*.h5 filter=lfs diff=lfs merge=lfs -text
|
| 9 |
+
*.joblib filter=lfs diff=lfs merge=lfs -text
|
| 10 |
+
*.lfs.* filter=lfs diff=lfs merge=lfs -text
|
| 11 |
+
*.mlmodel filter=lfs diff=lfs merge=lfs -text
|
| 12 |
+
*.model filter=lfs diff=lfs merge=lfs -text
|
| 13 |
+
*.msgpack filter=lfs diff=lfs merge=lfs -text
|
| 14 |
+
*.npy filter=lfs diff=lfs merge=lfs -text
|
| 15 |
+
*.npz filter=lfs diff=lfs merge=lfs -text
|
| 16 |
+
*.onnx filter=lfs diff=lfs merge=lfs -text
|
| 17 |
+
*.ot filter=lfs diff=lfs merge=lfs -text
|
| 18 |
+
*.parquet filter=lfs diff=lfs merge=lfs -text
|
| 19 |
+
*.pb filter=lfs diff=lfs merge=lfs -text
|
| 20 |
+
*.pickle filter=lfs diff=lfs merge=lfs -text
|
| 21 |
+
*.pkl filter=lfs diff=lfs merge=lfs -text
|
| 22 |
+
*.pt filter=lfs diff=lfs merge=lfs -text
|
| 23 |
+
*.pth filter=lfs diff=lfs merge=lfs -text
|
| 24 |
+
*.rar filter=lfs diff=lfs merge=lfs -text
|
| 25 |
+
*.safetensors filter=lfs diff=lfs merge=lfs -text
|
| 26 |
+
saved_model/**/* filter=lfs diff=lfs merge=lfs -text
|
| 27 |
+
*.tar.* filter=lfs diff=lfs merge=lfs -text
|
| 28 |
+
*.tflite filter=lfs diff=lfs merge=lfs -text
|
| 29 |
+
*.tgz filter=lfs diff=lfs merge=lfs -text
|
| 30 |
+
*.wasm filter=lfs diff=lfs merge=lfs -text
|
| 31 |
+
*.xz filter=lfs diff=lfs merge=lfs -text
|
| 32 |
+
*.zip filter=lfs diff=lfs merge=lfs -text
|
| 33 |
+
*.zst filter=lfs diff=lfs merge=lfs -text
|
| 34 |
+
*tfevents* filter=lfs diff=lfs merge=lfs -text
|
| 35 |
+
sample_images.jpg filter=lfs diff=lfs merge=lfs -text
|
README.md
ADDED
|
@@ -0,0 +1,171 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
---
|
| 2 |
+
thumbnail: >-
|
| 3 |
+
https://huggingface.co/OFA-Sys/small-stable-diffusion-v0/resolve/main/sample_images_compressed.jpg
|
| 4 |
+
datasets:
|
| 5 |
+
- ChristophSchuhmann/improved_aesthetics_6plus
|
| 6 |
+
license: openrail
|
| 7 |
+
tags:
|
| 8 |
+
- stable-diffusion
|
| 9 |
+
- stable-diffusion-diffusers
|
| 10 |
+
- text-to-image
|
| 11 |
+
language:
|
| 12 |
+
- en
|
| 13 |
+
pipeline_tag: text-to-image
|
| 14 |
+
---
|
| 15 |
+
|
| 16 |
+
# Small Stable Diffusion Model Card
|
| 17 |
+
【Update 2023/02/07】 Recently, we have released [a diffusion deployment repo](https://github.com/OFA-Sys/diffusion-deploy) to speedup the inference on both GPU (\~4x speedup, based on TensorRT) and CPU (\~12x speedup, based on IntelOpenVINO).
|
| 18 |
+
Integrated with this repo, small-stable-diffusion could generate images in just **5 seconds on the CPU**\*.
|
| 19 |
+
|
| 20 |
+
*\* Test on Intel(R) Xeon(R) Platinum 8369B CPU, DPMSolverMultistepScheduler 10 steps, fix channel/height/width when converting to Onnx*
|
| 21 |
+
|
| 22 |
+
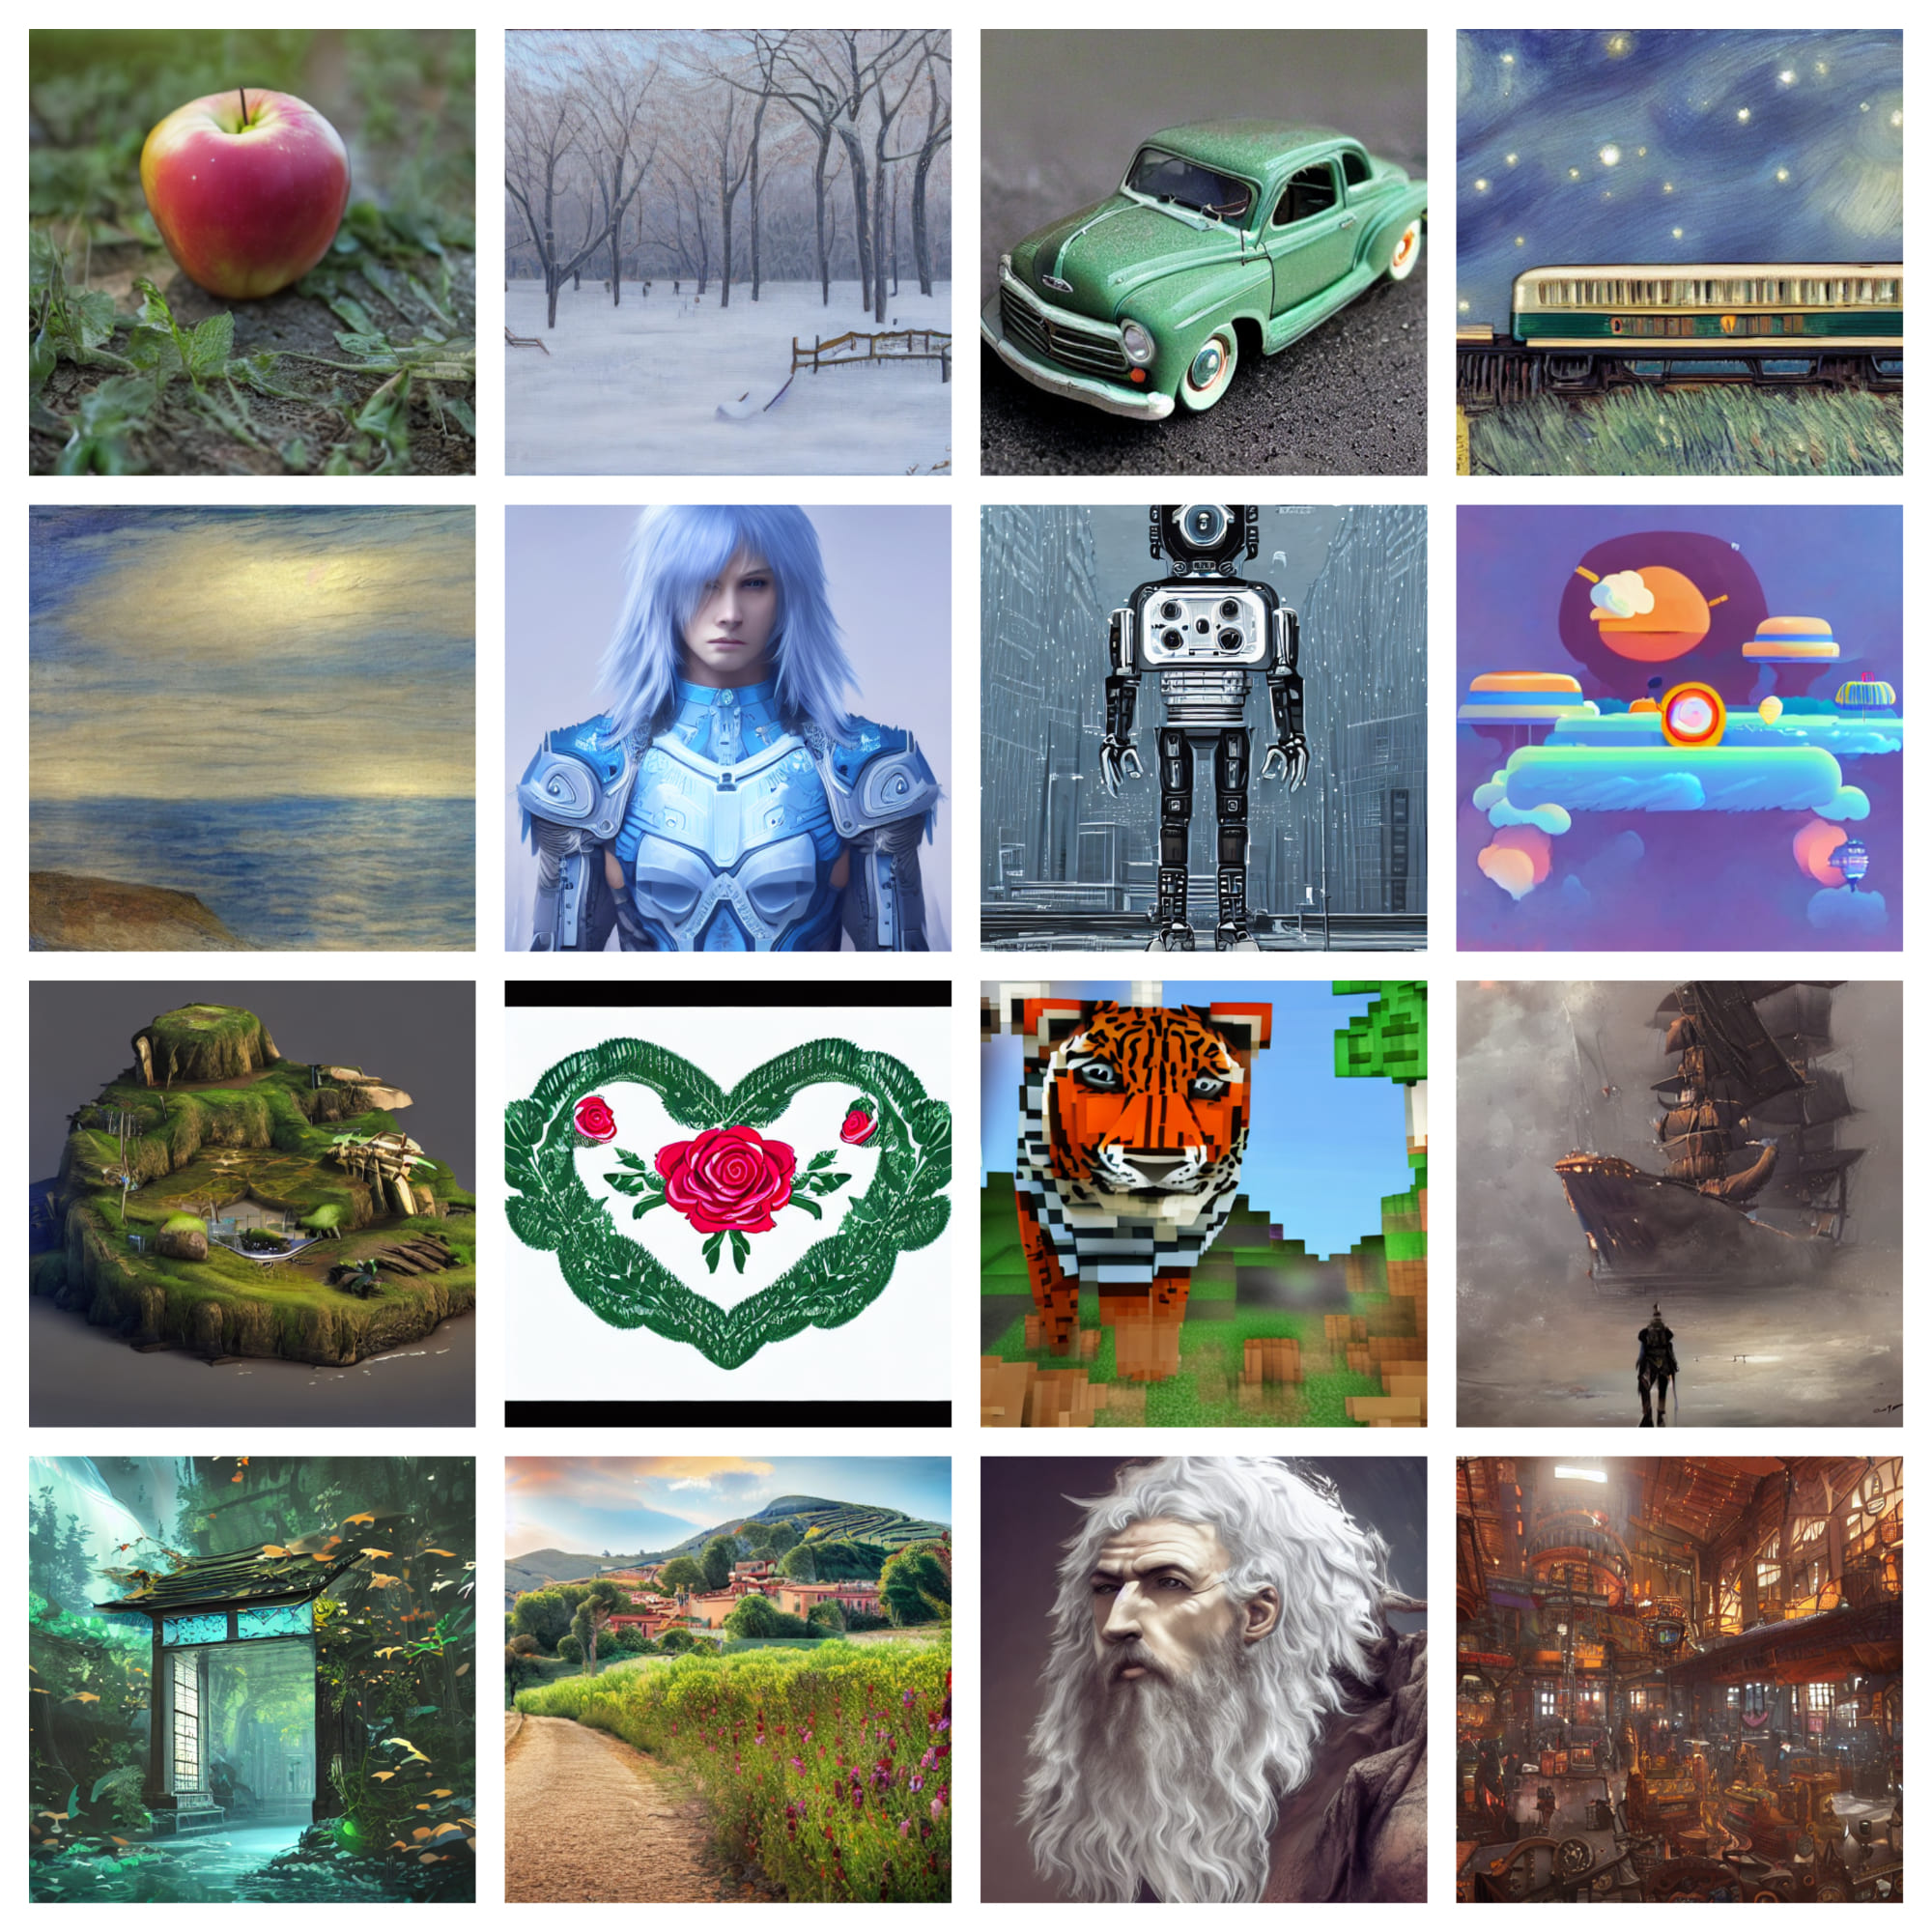
Similar image generation quality, but is nearly 1/2 smaller!
|
| 23 |
+
Here are some samples:
|
| 24 |
+
|
| 25 |
+
|
| 26 |
+
|
| 27 |
+
# Gradio
|
| 28 |
+
|
| 29 |
+
We support a [Gradio](https://github.com/gradio-app/gradio) Web UI to run small-stable-diffusion-v0:
|
| 30 |
+
[](https://huggingface.co/spaces/akhaliq/small-stable-diffusion-v0)
|
| 31 |
+
We also provide a space demo for [`small-stable-diffusion-v0 + diffusion-deploy`](https://huggingface.co/spaces/OFA-Sys/FAST-CPU-small-stable-diffusion-v0).
|
| 32 |
+
*As huggingface provides AMD CPU for the space demo, it costs about 35 seconds to generate an image with 15 steps, which is much slower than the Intel CPU environment as diffusion-deploy is based on Intel's OpenVINO.*
|
| 33 |
+
## Example
|
| 34 |
+
|
| 35 |
+
*Use `Diffusers` >=0.8.0, do not support lower versions.*
|
| 36 |
+
|
| 37 |
+
```python
|
| 38 |
+
import torch
|
| 39 |
+
from diffusers import StableDiffusionPipeline
|
| 40 |
+
|
| 41 |
+
|
| 42 |
+
model_id = "OFA-Sys/small-stable-diffusion-v0/"
|
| 43 |
+
pipe = StableDiffusionPipeline.from_pretrained(model_id, torch_dtype=torch.float16)
|
| 44 |
+
pipe = pipe.to("cuda")
|
| 45 |
+
|
| 46 |
+
prompt = "an apple, 4k"
|
| 47 |
+
image = pipe(prompt).images[0]
|
| 48 |
+
|
| 49 |
+
image.save("apple.png")
|
| 50 |
+
```
|
| 51 |
+
|
| 52 |
+
# Training
|
| 53 |
+
|
| 54 |
+
### Initialization
|
| 55 |
+
|
| 56 |
+
This model is initialized from stable-diffusion v1-4. As the model structure is not the same as stable-diffusion and the number of parameters is smaller, the parameters of stable diffusion could not be utilized directly. Therefore, small stable diffusion set `layers_per_block=1` and select the first layer of each block in original stable diffusion to initilize the small model.
|
| 57 |
+
|
| 58 |
+
### Training Procedure
|
| 59 |
+
|
| 60 |
+
After the initialization, the model has been trained for 1100k steps in 8xA100 GPUS. The training progress consists of three stages. The first stage is a simple pre-training precedure. In the last two stages, the original stable diffusion was utilized to distill knowledge to small model as a teacher model. In all stages, only the parameters in unet were trained and other parameters were frozen.
|
| 61 |
+
|
| 62 |
+
|
| 63 |
+
- **Hardware:** 8 x A100-80GB GPUs
|
| 64 |
+
- **Optimizer:** AdamW
|
| 65 |
+
|
| 66 |
+
- **Stage 1** - Pretrain the unet part of the model.
|
| 67 |
+
- **Steps**: 500,000
|
| 68 |
+
- **Batch:** batch size=8, GPUs=8, Gradient Accumulations=2. Total batch size=128
|
| 69 |
+
- **Learning rate:** warmup to 1e-5 for 10,000 steps and then kept constant
|
| 70 |
+
- **Stage 2** - Distill the model using stable-diffusion v1-4 as the teacher. Besides the ground truth, the training in this stage uses the soft-label (`pred_noise`) generated by teacher model as well.
|
| 71 |
+
- **Steps**: 400,000
|
| 72 |
+
- **Batch:** batch size=8, GPUs=8, Gradient Accumulations=2. Total batch size=128
|
| 73 |
+
- **Learning rate:** warmup to 1e-5 for 5,000 steps and then kept constant
|
| 74 |
+
- **Soft label weight:** 0.5
|
| 75 |
+
- **Hard label weight:** 0.5
|
| 76 |
+
- **Stage 3** - Distill the model using stable-diffusion v1-5 as the teacher. Use several techniques in `Knowledge Distillation of Transformer-based Language Models Revisited`, including similarity-based layer match apart from soft label.
|
| 77 |
+
- **Steps**: 200,000
|
| 78 |
+
- **Batch:** batch size=8, GPUs=8, Gradient Accumulations=2. Total batch size=128
|
| 79 |
+
- **Learning rate:** warmup to 1e-5 for 5,000 steps and then kept constant
|
| 80 |
+
- **Softlabel weight:** 0.5
|
| 81 |
+
- **Hard label weight:** 0.5
|
| 82 |
+
|
| 83 |
+
### Training Data
|
| 84 |
+
The model developers used the following dataset for training the model:
|
| 85 |
+
1. [LAION-2B en aesthetic](https://huggingface.co/datasets/laion/laion2B-en-aesthetic)
|
| 86 |
+
2. [LAION-Art](https://huggingface.co/datasets/laion/laion-art)
|
| 87 |
+
3. [LAION-HD](https://huggingface.co/datasets/laion/laion-high-resolution)
|
| 88 |
+
|
| 89 |
+
### Citation
|
| 90 |
+
|
| 91 |
+
```bibtex
|
| 92 |
+
@article{Lu2022KnowledgeDO,
|
| 93 |
+
title={Knowledge Distillation of Transformer-based Language Models Revisited},
|
| 94 |
+
author={Chengqiang Lu and Jianwei Zhang and Yunfei Chu and Zhengyu Chen and Jingren Zhou and Fei Wu and Haiqing Chen and Hongxia Yang},
|
| 95 |
+
journal={ArXiv},
|
| 96 |
+
year={2022},
|
| 97 |
+
volume={abs/2206.14366}
|
| 98 |
+
}
|
| 99 |
+
```
|
| 100 |
+
|
| 101 |
+
# Uses
|
| 102 |
+
_The following section is adapted from the [Stable Diffusion model card](https://huggingface.co/CompVis/stable-diffusion-v1-4)_
|
| 103 |
+
|
| 104 |
+
## Direct Use
|
| 105 |
+
The model is intended for research purposes only. Possible research areas and
|
| 106 |
+
tasks include
|
| 107 |
+
|
| 108 |
+
- Safe deployment of models which have the potential to generate harmful content.
|
| 109 |
+
- Probing and understanding the limitations and biases of generative models.
|
| 110 |
+
- Generation of artworks and use in design and other artistic processes.
|
| 111 |
+
- Applications in educational or creative tools.
|
| 112 |
+
- Research on generative models.
|
| 113 |
+
|
| 114 |
+
Excluded uses are described below.
|
| 115 |
+
|
| 116 |
+
### Misuse, Malicious Use, and Out-of-Scope Use
|
| 117 |
+
|
| 118 |
+
The model should not be used to intentionally create or disseminate images that create hostile or alienating environments for people. This includes generating images that people would foreseeably find disturbing, distressing, or offensive; or content that propagates historical or current stereotypes.
|
| 119 |
+
|
| 120 |
+
#### Out-of-Scope Use
|
| 121 |
+
The model was not trained to be factual or true representations of people or events, and therefore using the model to generate such content is out-of-scope for the abilities of this model.
|
| 122 |
+
|
| 123 |
+
#### Misuse and Malicious Use
|
| 124 |
+
Using the model to generate content that is cruel to individuals is a misuse of this model. This includes, but is not limited to:
|
| 125 |
+
|
| 126 |
+
- Generating demeaning, dehumanizing, or otherwise harmful representations of people or their environments, cultures, religions, etc.
|
| 127 |
+
- Intentionally promoting or propagating discriminatory content or harmful stereotypes.
|
| 128 |
+
- Impersonating individuals without their consent.
|
| 129 |
+
- Sexual content without consent of the people who might see it.
|
| 130 |
+
- Mis- and disinformation
|
| 131 |
+
- Representations of egregious violence and gore
|
| 132 |
+
- Sharing of copyrighted or licensed material in violation of its terms of use.
|
| 133 |
+
- Sharing content that is an alteration of copyrighted or licensed material in violation of its terms of use.
|
| 134 |
+
|
| 135 |
+
## Limitations and Bias
|
| 136 |
+
|
| 137 |
+
### Limitations
|
| 138 |
+
|
| 139 |
+
- The model does not achieve perfect photorealism
|
| 140 |
+
- The model cannot render legible text
|
| 141 |
+
- The model does not perform well on more difficult tasks which involve compositionality, such as rendering an image corresponding to “A red cube on top of a blue sphere”
|
| 142 |
+
- Faces and people in general may not be generated properly.
|
| 143 |
+
- The model was trained mainly with English captions and will not work as well in other languages.
|
| 144 |
+
- The autoencoding part of the model is lossy
|
| 145 |
+
- The model was trained on a large-scale dataset
|
| 146 |
+
[LAION-5B](https://laion.ai/blog/laion-5b/) which contains adult material
|
| 147 |
+
and is not fit for product use without additional safety mechanisms and
|
| 148 |
+
considerations.
|
| 149 |
+
- No additional measures were used to deduplicate the dataset. As a result, we observe some degree of memorization for images that are duplicated in the training data.
|
| 150 |
+
The training data can be searched at [https://rom1504.github.io/clip-retrieval/](https://rom1504.github.io/clip-retrieval/) to possibly assist in the detection of memorized images.
|
| 151 |
+
|
| 152 |
+
### Bias
|
| 153 |
+
|
| 154 |
+
While the capabilities of image generation models are impressive, they can also reinforce or exacerbate social biases.
|
| 155 |
+
Stable Diffusion v1 was trained on subsets of [LAION-2B(en)](https://laion.ai/blog/laion-5b/),
|
| 156 |
+
which consists of images that are primarily limited to English descriptions.
|
| 157 |
+
Texts and images from communities and cultures that use other languages are likely to be insufficiently accounted for.
|
| 158 |
+
This affects the overall output of the model, as white and western cultures are often set as the default. Further, the
|
| 159 |
+
ability of the model to generate content with non-English prompts is significantly worse than with English-language prompts.
|
| 160 |
+
|
| 161 |
+
### Safety Module
|
| 162 |
+
|
| 163 |
+
The intended use of this model is with the [Safety Checker](https://github.com/huggingface/diffusers/blob/main/src/diffusers/pipelines/stable_diffusion/safety_checker.py) in Diffusers.
|
| 164 |
+
This checker works by checking model outputs against known hard-coded NSFW concepts.
|
| 165 |
+
The concepts are intentionally hidden to reduce the likelihood of reverse-engineering this filter.
|
| 166 |
+
Specifically, the checker compares the class probability of harmful concepts in the embedding space of the `CLIPModel` *after generation* of the images.
|
| 167 |
+
The concepts are passed into the model with the generated image and compared to a hand-engineered weight for each NSFW concept.
|
| 168 |
+
|
| 169 |
+
|
| 170 |
+
|
| 171 |
+
*This model card was written by: Justin Pinkney and is based on the [Stable Diffusion model card](https://huggingface.co/CompVis/stable-diffusion-v1-4).*
|
feature_extractor/preprocessor_config.json
ADDED
|
@@ -0,0 +1,28 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
{
|
| 2 |
+
"crop_size": {
|
| 3 |
+
"height": 224,
|
| 4 |
+
"width": 224
|
| 5 |
+
},
|
| 6 |
+
"do_center_crop": true,
|
| 7 |
+
"do_convert_rgb": true,
|
| 8 |
+
"do_normalize": true,
|
| 9 |
+
"do_rescale": true,
|
| 10 |
+
"do_resize": true,
|
| 11 |
+
"feature_extractor_type": "CLIPFeatureExtractor",
|
| 12 |
+
"image_mean": [
|
| 13 |
+
0.48145466,
|
| 14 |
+
0.4578275,
|
| 15 |
+
0.40821073
|
| 16 |
+
],
|
| 17 |
+
"image_processor_type": "CLIPImageProcessor",
|
| 18 |
+
"image_std": [
|
| 19 |
+
0.26862954,
|
| 20 |
+
0.26130258,
|
| 21 |
+
0.27577711
|
| 22 |
+
],
|
| 23 |
+
"resample": 3,
|
| 24 |
+
"rescale_factor": 0.00392156862745098,
|
| 25 |
+
"size": {
|
| 26 |
+
"shortest_edge": 224
|
| 27 |
+
}
|
| 28 |
+
}
|
model_index.json
ADDED
|
@@ -0,0 +1,32 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
{
|
| 2 |
+
"_class_name": "StableDiffusionPipeline",
|
| 3 |
+
"_diffusers_version": "0.8.0.dev0",
|
| 4 |
+
"feature_extractor": [
|
| 5 |
+
"transformers",
|
| 6 |
+
"CLIPImageProcessor"
|
| 7 |
+
],
|
| 8 |
+
"safety_checker": [
|
| 9 |
+
"stable_diffusion",
|
| 10 |
+
"StableDiffusionSafetyChecker"
|
| 11 |
+
],
|
| 12 |
+
"scheduler": [
|
| 13 |
+
"diffusers",
|
| 14 |
+
"DPMSolverMultistepScheduler"
|
| 15 |
+
],
|
| 16 |
+
"text_encoder": [
|
| 17 |
+
"transformers",
|
| 18 |
+
"CLIPTextModel"
|
| 19 |
+
],
|
| 20 |
+
"tokenizer": [
|
| 21 |
+
"transformers",
|
| 22 |
+
"CLIPTokenizer"
|
| 23 |
+
],
|
| 24 |
+
"unet": [
|
| 25 |
+
"diffusers",
|
| 26 |
+
"UNet2DConditionModel"
|
| 27 |
+
],
|
| 28 |
+
"vae": [
|
| 29 |
+
"diffusers",
|
| 30 |
+
"AutoencoderKL"
|
| 31 |
+
]
|
| 32 |
+
}
|
safety_checker/config.json
ADDED
|
@@ -0,0 +1,180 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
{
|
| 2 |
+
"_commit_hash": null,
|
| 3 |
+
"architectures": [
|
| 4 |
+
"StableDiffusionSafetyChecker"
|
| 5 |
+
],
|
| 6 |
+
"initializer_factor": 1.0,
|
| 7 |
+
"logit_scale_init_value": 2.6592,
|
| 8 |
+
"model_type": "clip",
|
| 9 |
+
"projection_dim": 768,
|
| 10 |
+
"text_config": {
|
| 11 |
+
"_name_or_path": "",
|
| 12 |
+
"add_cross_attention": false,
|
| 13 |
+
"architectures": null,
|
| 14 |
+
"attention_dropout": 0.0,
|
| 15 |
+
"bad_words_ids": null,
|
| 16 |
+
"begin_suppress_tokens": null,
|
| 17 |
+
"bos_token_id": 0,
|
| 18 |
+
"chunk_size_feed_forward": 0,
|
| 19 |
+
"cross_attention_hidden_size": null,
|
| 20 |
+
"decoder_start_token_id": null,
|
| 21 |
+
"diversity_penalty": 0.0,
|
| 22 |
+
"do_sample": false,
|
| 23 |
+
"dropout": 0.0,
|
| 24 |
+
"early_stopping": false,
|
| 25 |
+
"encoder_no_repeat_ngram_size": 0,
|
| 26 |
+
"eos_token_id": 2,
|
| 27 |
+
"exponential_decay_length_penalty": null,
|
| 28 |
+
"finetuning_task": null,
|
| 29 |
+
"forced_bos_token_id": null,
|
| 30 |
+
"forced_eos_token_id": null,
|
| 31 |
+
"hidden_act": "quick_gelu",
|
| 32 |
+
"hidden_size": 768,
|
| 33 |
+
"id2label": {
|
| 34 |
+
"0": "LABEL_0",
|
| 35 |
+
"1": "LABEL_1"
|
| 36 |
+
},
|
| 37 |
+
"initializer_factor": 1.0,
|
| 38 |
+
"initializer_range": 0.02,
|
| 39 |
+
"intermediate_size": 3072,
|
| 40 |
+
"is_decoder": false,
|
| 41 |
+
"is_encoder_decoder": false,
|
| 42 |
+
"label2id": {
|
| 43 |
+
"LABEL_0": 0,
|
| 44 |
+
"LABEL_1": 1
|
| 45 |
+
},
|
| 46 |
+
"layer_norm_eps": 1e-05,
|
| 47 |
+
"length_penalty": 1.0,
|
| 48 |
+
"max_length": 20,
|
| 49 |
+
"max_position_embeddings": 77,
|
| 50 |
+
"min_length": 0,
|
| 51 |
+
"model_type": "clip_text_model",
|
| 52 |
+
"no_repeat_ngram_size": 0,
|
| 53 |
+
"num_attention_heads": 12,
|
| 54 |
+
"num_beam_groups": 1,
|
| 55 |
+
"num_beams": 1,
|
| 56 |
+
"num_hidden_layers": 12,
|
| 57 |
+
"num_return_sequences": 1,
|
| 58 |
+
"output_attentions": false,
|
| 59 |
+
"output_hidden_states": false,
|
| 60 |
+
"output_scores": false,
|
| 61 |
+
"pad_token_id": 1,
|
| 62 |
+
"prefix": null,
|
| 63 |
+
"problem_type": null,
|
| 64 |
+
"projection_dim": 512,
|
| 65 |
+
"pruned_heads": {},
|
| 66 |
+
"remove_invalid_values": false,
|
| 67 |
+
"repetition_penalty": 1.0,
|
| 68 |
+
"return_dict": true,
|
| 69 |
+
"return_dict_in_generate": false,
|
| 70 |
+
"sep_token_id": null,
|
| 71 |
+
"suppress_tokens": null,
|
| 72 |
+
"task_specific_params": null,
|
| 73 |
+
"temperature": 1.0,
|
| 74 |
+
"tf_legacy_loss": false,
|
| 75 |
+
"tie_encoder_decoder": false,
|
| 76 |
+
"tie_word_embeddings": true,
|
| 77 |
+
"tokenizer_class": null,
|
| 78 |
+
"top_k": 50,
|
| 79 |
+
"top_p": 1.0,
|
| 80 |
+
"torch_dtype": null,
|
| 81 |
+
"torchscript": false,
|
| 82 |
+
"transformers_version": "4.25.1",
|
| 83 |
+
"typical_p": 1.0,
|
| 84 |
+
"use_bfloat16": false,
|
| 85 |
+
"vocab_size": 49408
|
| 86 |
+
},
|
| 87 |
+
"text_config_dict": {
|
| 88 |
+
"hidden_size": 768,
|
| 89 |
+
"intermediate_size": 3072,
|
| 90 |
+
"num_attention_heads": 12,
|
| 91 |
+
"num_hidden_layers": 12
|
| 92 |
+
},
|
| 93 |
+
"torch_dtype": "float32",
|
| 94 |
+
"transformers_version": null,
|
| 95 |
+
"vision_config": {
|
| 96 |
+
"_name_or_path": "",
|
| 97 |
+
"add_cross_attention": false,
|
| 98 |
+
"architectures": null,
|
| 99 |
+
"attention_dropout": 0.0,
|
| 100 |
+
"bad_words_ids": null,
|
| 101 |
+
"begin_suppress_tokens": null,
|
| 102 |
+
"bos_token_id": null,
|
| 103 |
+
"chunk_size_feed_forward": 0,
|
| 104 |
+
"cross_attention_hidden_size": null,
|
| 105 |
+
"decoder_start_token_id": null,
|
| 106 |
+
"diversity_penalty": 0.0,
|
| 107 |
+
"do_sample": false,
|
| 108 |
+
"dropout": 0.0,
|
| 109 |
+
"early_stopping": false,
|
| 110 |
+
"encoder_no_repeat_ngram_size": 0,
|
| 111 |
+
"eos_token_id": null,
|
| 112 |
+
"exponential_decay_length_penalty": null,
|
| 113 |
+
"finetuning_task": null,
|
| 114 |
+
"forced_bos_token_id": null,
|
| 115 |
+
"forced_eos_token_id": null,
|
| 116 |
+
"hidden_act": "quick_gelu",
|
| 117 |
+
"hidden_size": 1024,
|
| 118 |
+
"id2label": {
|
| 119 |
+
"0": "LABEL_0",
|
| 120 |
+
"1": "LABEL_1"
|
| 121 |
+
},
|
| 122 |
+
"image_size": 224,
|
| 123 |
+
"initializer_factor": 1.0,
|
| 124 |
+
"initializer_range": 0.02,
|
| 125 |
+
"intermediate_size": 4096,
|
| 126 |
+
"is_decoder": false,
|
| 127 |
+
"is_encoder_decoder": false,
|
| 128 |
+
"label2id": {
|
| 129 |
+
"LABEL_0": 0,
|
| 130 |
+
"LABEL_1": 1
|
| 131 |
+
},
|
| 132 |
+
"layer_norm_eps": 1e-05,
|
| 133 |
+
"length_penalty": 1.0,
|
| 134 |
+
"max_length": 20,
|
| 135 |
+
"min_length": 0,
|
| 136 |
+
"model_type": "clip_vision_model",
|
| 137 |
+
"no_repeat_ngram_size": 0,
|
| 138 |
+
"num_attention_heads": 16,
|
| 139 |
+
"num_beam_groups": 1,
|
| 140 |
+
"num_beams": 1,
|
| 141 |
+
"num_channels": 3,
|
| 142 |
+
"num_hidden_layers": 24,
|
| 143 |
+
"num_return_sequences": 1,
|
| 144 |
+
"output_attentions": false,
|
| 145 |
+
"output_hidden_states": false,
|
| 146 |
+
"output_scores": false,
|
| 147 |
+
"pad_token_id": null,
|
| 148 |
+
"patch_size": 14,
|
| 149 |
+
"prefix": null,
|
| 150 |
+
"problem_type": null,
|
| 151 |
+
"projection_dim": 512,
|
| 152 |
+
"pruned_heads": {},
|
| 153 |
+
"remove_invalid_values": false,
|
| 154 |
+
"repetition_penalty": 1.0,
|
| 155 |
+
"return_dict": true,
|
| 156 |
+
"return_dict_in_generate": false,
|
| 157 |
+
"sep_token_id": null,
|
| 158 |
+
"suppress_tokens": null,
|
| 159 |
+
"task_specific_params": null,
|
| 160 |
+
"temperature": 1.0,
|
| 161 |
+
"tf_legacy_loss": false,
|
| 162 |
+
"tie_encoder_decoder": false,
|
| 163 |
+
"tie_word_embeddings": true,
|
| 164 |
+
"tokenizer_class": null,
|
| 165 |
+
"top_k": 50,
|
| 166 |
+
"top_p": 1.0,
|
| 167 |
+
"torch_dtype": null,
|
| 168 |
+
"torchscript": false,
|
| 169 |
+
"transformers_version": "4.25.1",
|
| 170 |
+
"typical_p": 1.0,
|
| 171 |
+
"use_bfloat16": false
|
| 172 |
+
},
|
| 173 |
+
"vision_config_dict": {
|
| 174 |
+
"hidden_size": 1024,
|
| 175 |
+
"intermediate_size": 4096,
|
| 176 |
+
"num_attention_heads": 16,
|
| 177 |
+
"num_hidden_layers": 24,
|
| 178 |
+
"patch_size": 14
|
| 179 |
+
}
|
| 180 |
+
}
|
safety_checker/pytorch_model.bin
ADDED
|
@@ -0,0 +1,3 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
version https://git-lfs.github.com/spec/v1
|
| 2 |
+
oid sha256:75f5f098f12e0b765dd8f917182dccbea8c87d269265f3e616cf67282c426940
|
| 3 |
+
size 1216067303
|
sample_images.jpg
ADDED

|
Git LFS Details
|
sample_images_compressed.jpg
ADDED

|
scheduler/scheduler_config.json
ADDED
|
@@ -0,0 +1,17 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
{
|
| 2 |
+
"_class_name": "DPMSolverMultistepScheduler",
|
| 3 |
+
"_diffusers_version": "0.8.0.dev0",
|
| 4 |
+
"algorithm_type": "dpmsolver++",
|
| 5 |
+
"beta_end": 0.012,
|
| 6 |
+
"beta_schedule": "scaled_linear",
|
| 7 |
+
"beta_start": 0.00085,
|
| 8 |
+
"dynamic_thresholding_ratio": 0.995,
|
| 9 |
+
"lower_order_final": true,
|
| 10 |
+
"num_train_timesteps": 1000,
|
| 11 |
+
"predict_epsilon": true,
|
| 12 |
+
"sample_max_value": 1.0,
|
| 13 |
+
"solver_order": 2,
|
| 14 |
+
"solver_type": "midpoint",
|
| 15 |
+
"thresholding": false,
|
| 16 |
+
"trained_betas": null
|
| 17 |
+
}
|
text_encoder/config.json
ADDED
|
@@ -0,0 +1,24 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
{
|
| 2 |
+
"architectures": [
|
| 3 |
+
"CLIPTextModel"
|
| 4 |
+
],
|
| 5 |
+
"attention_dropout": 0.0,
|
| 6 |
+
"bos_token_id": 0,
|
| 7 |
+
"dropout": 0.0,
|
| 8 |
+
"eos_token_id": 2,
|
| 9 |
+
"hidden_act": "quick_gelu",
|
| 10 |
+
"hidden_size": 768,
|
| 11 |
+
"initializer_factor": 1.0,
|
| 12 |
+
"initializer_range": 0.02,
|
| 13 |
+
"intermediate_size": 3072,
|
| 14 |
+
"layer_norm_eps": 1e-05,
|
| 15 |
+
"max_position_embeddings": 77,
|
| 16 |
+
"model_type": "clip_text_model",
|
| 17 |
+
"num_attention_heads": 12,
|
| 18 |
+
"num_hidden_layers": 12,
|
| 19 |
+
"pad_token_id": 1,
|
| 20 |
+
"projection_dim": 512,
|
| 21 |
+
"torch_dtype": "float32",
|
| 22 |
+
"transformers_version": "4.25.1",
|
| 23 |
+
"vocab_size": 49408
|
| 24 |
+
}
|
text_encoder/pytorch_model.bin
ADDED
|
@@ -0,0 +1,3 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
version https://git-lfs.github.com/spec/v1
|
| 2 |
+
oid sha256:2de7a84d9501053703047206ad888d6e9814081444dcc5debb316bd1db06a232
|
| 3 |
+
size 492308087
|
tokenizer/merges.txt
ADDED
|
The diff for this file is too large to render.
See raw diff
|
|
|
tokenizer/special_tokens_map.json
ADDED
|
@@ -0,0 +1,24 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
{
|
| 2 |
+
"bos_token": {
|
| 3 |
+
"content": "<|startoftext|>",
|
| 4 |
+
"lstrip": false,
|
| 5 |
+
"normalized": true,
|
| 6 |
+
"rstrip": false,
|
| 7 |
+
"single_word": false
|
| 8 |
+
},
|
| 9 |
+
"eos_token": {
|
| 10 |
+
"content": "<|endoftext|>",
|
| 11 |
+
"lstrip": false,
|
| 12 |
+
"normalized": true,
|
| 13 |
+
"rstrip": false,
|
| 14 |
+
"single_word": false
|
| 15 |
+
},
|
| 16 |
+
"pad_token": "<|endoftext|>",
|
| 17 |
+
"unk_token": {
|
| 18 |
+
"content": "<|endoftext|>",
|
| 19 |
+
"lstrip": false,
|
| 20 |
+
"normalized": true,
|
| 21 |
+
"rstrip": false,
|
| 22 |
+
"single_word": false
|
| 23 |
+
}
|
| 24 |
+
}
|
tokenizer/tokenizer_config.json
ADDED
|
@@ -0,0 +1,34 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
{
|
| 2 |
+
"add_prefix_space": false,
|
| 3 |
+
"bos_token": {
|
| 4 |
+
"__type": "AddedToken",
|
| 5 |
+
"content": "<|startoftext|>",
|
| 6 |
+
"lstrip": false,
|
| 7 |
+
"normalized": true,
|
| 8 |
+
"rstrip": false,
|
| 9 |
+
"single_word": false
|
| 10 |
+
},
|
| 11 |
+
"do_lower_case": true,
|
| 12 |
+
"eos_token": {
|
| 13 |
+
"__type": "AddedToken",
|
| 14 |
+
"content": "<|endoftext|>",
|
| 15 |
+
"lstrip": false,
|
| 16 |
+
"normalized": true,
|
| 17 |
+
"rstrip": false,
|
| 18 |
+
"single_word": false
|
| 19 |
+
},
|
| 20 |
+
"errors": "replace",
|
| 21 |
+
"model_max_length": 77,
|
| 22 |
+
"name_or_path": "/mnt/workspace/workgroup/lulu/st_lite/1140k_pixiv/tokenizer",
|
| 23 |
+
"pad_token": "<|endoftext|>",
|
| 24 |
+
"special_tokens_map_file": "./special_tokens_map.json",
|
| 25 |
+
"tokenizer_class": "CLIPTokenizer",
|
| 26 |
+
"unk_token": {
|
| 27 |
+
"__type": "AddedToken",
|
| 28 |
+
"content": "<|endoftext|>",
|
| 29 |
+
"lstrip": false,
|
| 30 |
+
"normalized": true,
|
| 31 |
+
"rstrip": false,
|
| 32 |
+
"single_word": false
|
| 33 |
+
}
|
| 34 |
+
}
|
tokenizer/vocab.json
ADDED
|
The diff for this file is too large to render.
See raw diff
|
|
|
unet/config.json
ADDED
|
@@ -0,0 +1,36 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
{
|
| 2 |
+
"_class_name": "UNet2DConditionModel",
|
| 3 |
+
"_diffusers_version": "0.8.0.dev0",
|
| 4 |
+
"act_fn": "silu",
|
| 5 |
+
"attention_head_dim": 8,
|
| 6 |
+
"block_out_channels": [
|
| 7 |
+
320,
|
| 8 |
+
640,
|
| 9 |
+
1280,
|
| 10 |
+
1280
|
| 11 |
+
],
|
| 12 |
+
"center_input_sample": false,
|
| 13 |
+
"cross_attention_dim": 768,
|
| 14 |
+
"down_block_types": [
|
| 15 |
+
"CrossAttnDownBlock2D",
|
| 16 |
+
"CrossAttnDownBlock2D",
|
| 17 |
+
"CrossAttnDownBlock2D",
|
| 18 |
+
"DownBlock2D"
|
| 19 |
+
],
|
| 20 |
+
"downsample_padding": 1,
|
| 21 |
+
"flip_sin_to_cos": true,
|
| 22 |
+
"freq_shift": 0,
|
| 23 |
+
"in_channels": 4,
|
| 24 |
+
"layers_per_block": 1,
|
| 25 |
+
"mid_block_scale_factor": 1,
|
| 26 |
+
"norm_eps": 1e-05,
|
| 27 |
+
"norm_num_groups": 32,
|
| 28 |
+
"out_channels": 4,
|
| 29 |
+
"sample_size": 64,
|
| 30 |
+
"up_block_types": [
|
| 31 |
+
"UpBlock2D",
|
| 32 |
+
"CrossAttnUpBlock2D",
|
| 33 |
+
"CrossAttnUpBlock2D",
|
| 34 |
+
"CrossAttnUpBlock2D"
|
| 35 |
+
]
|
| 36 |
+
}
|
unet/diffusion_pytorch_model.bin
ADDED
|
@@ -0,0 +1,3 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
version https://git-lfs.github.com/spec/v1
|
| 2 |
+
oid sha256:2cb22aebb48a8ba4f44bde337f5a0dc6fc251dd889829da2a54bc9e6e94fef41
|
| 3 |
+
size 2317720013
|
vae/config.json
ADDED
|
@@ -0,0 +1,30 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
{
|
| 2 |
+
"_class_name": "AutoencoderKL",
|
| 3 |
+
"_diffusers_version": "0.8.0.dev0",
|
| 4 |
+
"act_fn": "silu",
|
| 5 |
+
"block_out_channels": [
|
| 6 |
+
128,
|
| 7 |
+
256,
|
| 8 |
+
512,
|
| 9 |
+
512
|
| 10 |
+
],
|
| 11 |
+
"down_block_types": [
|
| 12 |
+
"DownEncoderBlock2D",
|
| 13 |
+
"DownEncoderBlock2D",
|
| 14 |
+
"DownEncoderBlock2D",
|
| 15 |
+
"DownEncoderBlock2D"
|
| 16 |
+
],
|
| 17 |
+
"in_channels": 3,
|
| 18 |
+
"latent_channels": 4,
|
| 19 |
+
"layers_per_block": 2,
|
| 20 |
+
"norm_num_groups": 32,
|
| 21 |
+
"out_channels": 3,
|
| 22 |
+
"sample_size": 512,
|
| 23 |
+
"scaling_factor": 0.18215,
|
| 24 |
+
"up_block_types": [
|
| 25 |
+
"UpDecoderBlock2D",
|
| 26 |
+
"UpDecoderBlock2D",
|
| 27 |
+
"UpDecoderBlock2D",
|
| 28 |
+
"UpDecoderBlock2D"
|
| 29 |
+
]
|
| 30 |
+
}
|
vae/diffusion_pytorch_model.bin
ADDED
|
@@ -0,0 +1,3 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
version https://git-lfs.github.com/spec/v1
|
| 2 |
+
oid sha256:d16a79cb6c6127b8965341d585af620c4fd9362c4d33d561213d2bdd2f0727fb
|
| 3 |
+
size 334710673
|