
Spaces:
Sleeping

Sleeping
here2rule commited on
Commit ·
f7952dd
1
Parent(s): afa3cc4
docs: add training-proof screenshot to README
Browse files
README.md
CHANGED
|
@@ -1,13 +1,3 @@
|
|
| 1 |
-
---
|
| 2 |
-
title: Oceanus Mission Control
|
| 3 |
-
emoji: 🌊
|
| 4 |
-
colorFrom: green
|
| 5 |
-
colorTo: blue
|
| 6 |
-
sdk: docker
|
| 7 |
-
pinned: true
|
| 8 |
-
app_port: 7860
|
| 9 |
-
---
|
| 10 |
-
|
| 11 |
# 🌊 Oceanus: Multi-Layer Ghost-Gear Recovery & Treaty Arena
|
| 12 |
|
| 13 |
> *The first multi-modal RL arena where LLM policy negotiations directly control the physics of ocean restoration.*
|
|
@@ -85,6 +75,10 @@ The environment operates on **three simultaneous layers**:
|
|
| 85 |
```
|
| 86 |
Untrained model outputs: *"I think I should navigate toward the detected anomaly..."* → reward: -1.0
|
| 87 |
|
|
|
|
|
|
|
|
|
|
|
|
|
| 88 |
---
|
| 89 |
|
| 90 |
## 🚀 Quick Start
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
# 🌊 Oceanus: Multi-Layer Ghost-Gear Recovery & Treaty Arena
|
| 2 |
|
| 3 |
> *The first multi-modal RL arena where LLM policy negotiations directly control the physics of ocean restoration.*
|
|
|
|
| 75 |
```
|
| 76 |
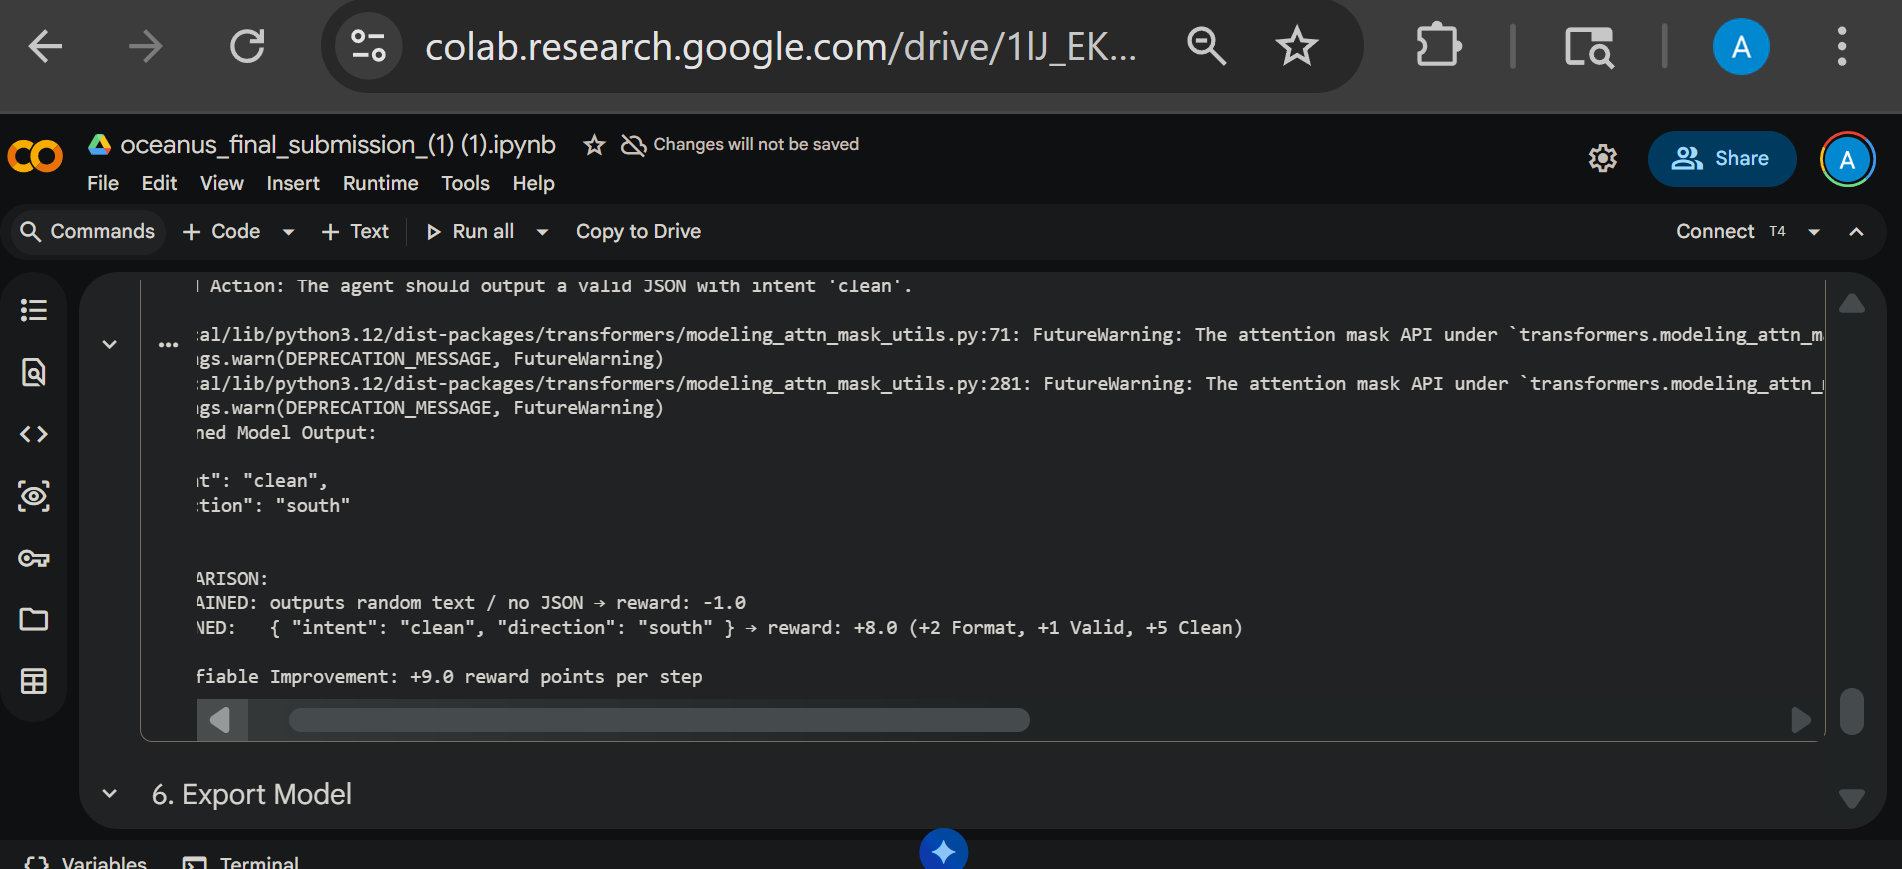
Untrained model outputs: *"I think I should navigate toward the detected anomaly..."* → reward: -1.0
|
| 77 |
|
| 78 |
+
|
| 79 |
+
|
| 80 |
+
*Screenshot from Colab Cell 13: trained model correctly outputs `{"intent": "clean"}` when net is visible in sonar. Untrained baseline reward: -1.0 → Trained reward: +8.0*
|
| 81 |
+
|
| 82 |
---
|
| 83 |
|
| 84 |
## 🚀 Quick Start
|