| --- |
| license: apache-2.0 |
| pipeline_tag: image-to-video |
| library_name: astronex-world |
| base_model: Wan-AI/Wan2.2-TI2V-5B |
| base_model_relation: finetune |
| tags: |
| - world-model |
| - video-generation |
| - image-to-video |
| - text-to-video |
| - diffusion |
| - video-diffusion-transformer |
| - interactive |
| - real-time |
| - camera-control |
| - action-conditioned |
| - embodied-ai |
| - robotics |
| - autonomous-driving |
| - wan2.2 |
| --- |
| |
| # Astronex-World-5B |
|
|
| **Astronex-World 1.0**, a 5B controllable video world-model foundation on the Wan2.2-TI2V-5B prior. Given a text prompt |
| or a first frame it predicts future visual states under frame-aligned camera trajectories, a 64-D continuous action |
| stream with an embodiment identifier, and text events inserted partway through a rollout. One trunk, two forms — a |
| *bidirectional* form with full temporal attention, and a *causal* form with block-causal attention and cross-block KV |
| caching that streams block by block. 832x480 and 1280x704 at 24 fps. |
|
|
| All five training stages ran on two NVIDIA L20 48 GB GPUs, and the causal form streams 832x480 at 24 fps in real time on |
| one. On WBench Full 289 it scores 70.0, above the 13.6B LongCat-Video and the 14B Helios and within one point of the 22B |
| LTX-2.3. |
|
|
| [Project page](https://world.astronex.com.cn/) | |
| [Technical report](https://world.astronex.com.cn/assets/paper/astronex-world-technical-report.pdf) | |
| [Code](https://github.com/Astronex-Robotics/Astronex-World) |
|
|
| ## Gallery |
|
|
| Every clip is generated by these weights. Click a frame to play it on the [project page](https://world.astronex.com.cn/). |
|
|
| | | | | |
| |:---:|:---:|:---:| |
| | [](https://world.astronex.com.cn/assets/videos/Astronex_01_720p24.mp4) | [](https://world.astronex.com.cn/assets/videos/Astronex_04_720p24.mp4) | [](https://world.astronex.com.cn/assets/videos/Astronex_08_480p.mp4) | |
| | [](https://world.astronex.com.cn/assets/videos/Astronex_09_480p.mp4) | [](https://world.astronex.com.cn/assets/videos/Astronex_10_480p.mp4) | [](https://world.astronex.com.cn/assets/videos/Astronex_11_480p.mp4) | |
| | [](https://world.astronex.com.cn/assets/videos/Astronex_12_480p.mp4) | [](https://world.astronex.com.cn/assets/videos/Astronex_13_480p.mp4) | [](https://world.astronex.com.cn/assets/videos/cosmos-coast.mp4) | |
|
|
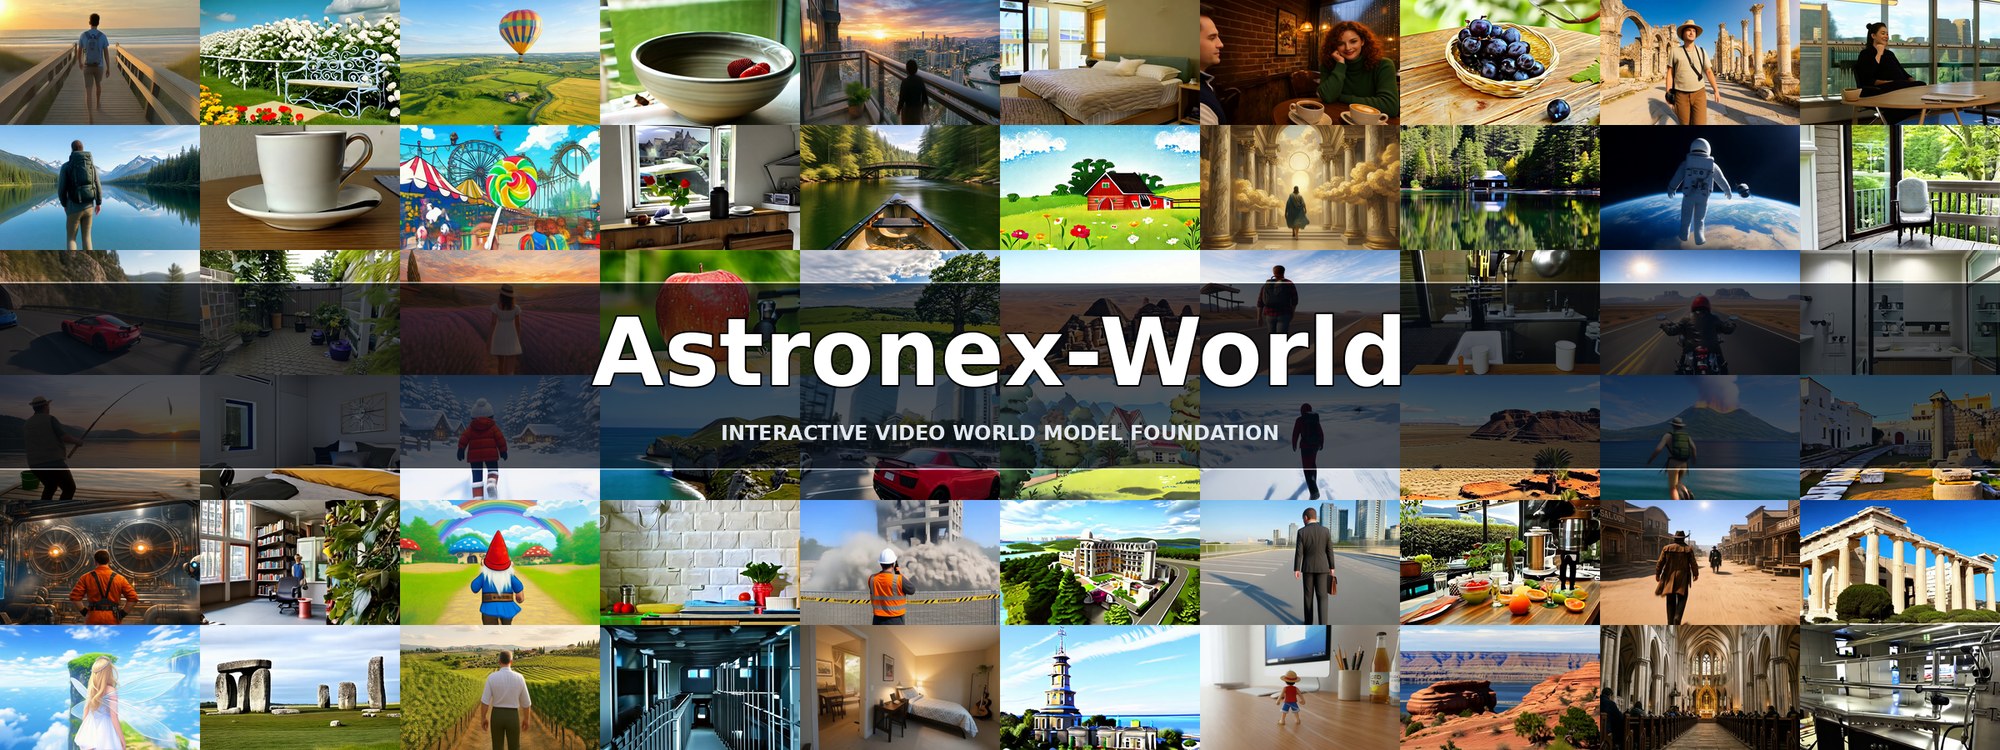
| Each frame in the montage below is a separate project output; the full gallery, including 33-second rollouts and |
| action-controlled driving, is on the [project page](https://world.astronex.com.cn/). |
|
|
|  |
|
|
| ## The model |
|
|
| Given text or a first frame, the model consumes frame-aligned camera trajectories, a 64-dimensional continuous action |
| stream and an embodiment identifier to predict future visual states under control. Cameras are injected with PRoPE in |
| all 30 Transformer layers; actions modulate every layer. Beyond steering a rollout, the framework exposes an open |
| action-sequence output head — see [Action-sequence output](#action-sequence-output-open-post-training-head). |
|
|
| | | Value | |
| | --- | --- | |
| | Parameters | 5.35B | |
| | Backbone | Wan2.2-TI2V-5B, 30 layers, hidden 3072, 24 heads, FFN 14,336 | |
| | Latent | 48 channels, VAE 4x temporal, 16x16 spatial | |
| | Conditioning | text, first frame, camera intrinsics/extrinsics (PRoPE), 64-D continuous action + 32 embodiment IDs, event text | |
| | Causal form | block-causal attention with cross-block KV cache, 8 latent frames per block, 20-frame local window + 4 persistent sink frames, frustum-overlap retrieval for revisit trajectories | |
| | Bidirectional form | full spatiotemporal attention over the clip, 20 latent frames | |
| | Output | 832x480 at 24 fps; a 1280x704 preset uses the same weights | |
| | Hardware | trained on 2x NVIDIA L20 48 GB, runs on 1x L20 48 GB | |
|
|
| Five training stages, all on two L20 48 GB GPUs (Section 6 of the report): bidirectional control adaptation, |
| block-causal conversion, online UniPC trajectory distillation, mixed-domain causal SFT, and asymmetric DMD/DMD2. |
|
|
| ## What is in this repository |
|
|
| Everything the model loads is here, so nothing has to be fetched from the Wan2.2 release separately. |
|
|
| | Path | Contents | |
| | --- | --- | |
| | `model-0000{1,2,3}-of-00003.safetensors`, `model.safetensors.index.json` | the denoiser, bf16, 5.35B parameters, ~10.7 GB — one set of weights for both sampling modes | |
| | `transformer/config.json` | the module definition the denoiser is built from | |
| | `vae/` | Wan2.2 VAE, 48 channels, 4x16x16 | |
| | `text_encoder/`, `tokenizer/` | UMT5-xxl | |
| | `config.json` | this release's metadata: model kwargs, validated inference settings, provenance | |
|
|
| The export is merged: the LoRA adapters are folded into the weights, so there is no adapter file to load alongside and |
| no `lora` entry in the configuration. The checkpoint carries 898 tensors — the 825 of the Wan2.2 backbone, the camera |
| (PRoPE) and action-*input* grafts, and the 6 action-*output* head tensors described below — so both sampling forms load |
| it with no missing weights. `config.json` records the head under `action_output_head`. |
|
|
| The VAE, the text encoder and the tokenizer are the Wan2.2-TI2V-5B components, redistributed here under the same |
| Apache-2.0 licence for convenience. |
|
|
| ## Quick start |
|
|
| The code release ships the streaming pipeline, the sampling presets and the post-training recipes. It loads everything |
| from this directory: |
|
|
| ```bash |
| git clone https://github.com/Astronex-Robotics/Astronex-World |
| cd Astronex-World |
| pip install -r requirements.txt |
| |
| huggingface-cli download Astronex-Lab/Astronex-World --local-dir ../Astronex |
| python scripts/check_weights.py # denoiser, module definition, VAE, text encoder |
| |
| bash scripts/infer_t2v.sh # text-to-video, no reference image |
| bash scripts/infer_causal.sh # image-to-video, streaming rollout, 8 steps |
| bash scripts/infer_bidirectional.sh # full-attention form, same weights |
| bash scripts/infer_event.sh # caption switch partway through a rollout |
| bash scripts/infer_causal_consumer.sh # same output inside 24 GB of VRAM |
| ``` |
|
|
| Or build the denoiser directly and load the shards into it: |
|
|
| ```python |
| import glob, json |
| from safetensors.torch import load_file |
| from models.wan_wrapper import WanDiffusionWrapper # from the code release |
| |
| cfg = json.load(open("config.json")) |
| model = WanDiffusionWrapper(**cfg["model_kwargs"], model_root=".", |
| model_name="transformer", base_dtype="bfloat16") |
| |
| state = {} |
| for shard in sorted(glob.glob("model-*-of-*.safetensors")): |
| state.update(load_file(shard)) |
| model.load_state_dict(state) # 898 tensors, exact match |
| ``` |
|
|
| ## Sampling settings that matter |
|
|
| `config.json` carries the settings these weights were validated under: |
|
|
| - **8 UniPC steps** is the validated setting, with CFG 3.0 and an 8-frame inference block. The sampler also accepts 4 |
| steps for latency experiments; quality is lower and 8 steps is what the released material uses. |
| - **Window 20 + sink 4 + retrieval.** The KV window is `sink + recent history + current block`, and the retrieval path |
| scores evicted history frames by camera-frustum overlap so a revisited place can be redrawn. Sink and window are |
| properties of the weights: sampling them with a different geometry changes the model's behaviour, so change them |
| together rather than one at a time. |
| - **Frames arrive in whole blocks.** Generate in multiples of 8 latent frames (23 pixel-frame steps, not 20, once the |
| i2v reference frame is counted). |
|
|
| Generation runs in the compressed video latent space; the VAE is used only for input encoding and final decoding. |
| Cameras enter PRoPE as intrinsics plus world-to-camera transforms, with pixel-space intrinsics normalised by the source |
| width and height. |
|
|
| ## Action-sequence output (open post-training head) |
|
|
| The action pathway is bidirectional by design. One direction is action *input*: a commanded 64-D action steers the |
| rollout. The other — `action_output` — is public in this framework and lets the model report the action it depicted, |
| which is what makes the representation usable as an inverse-dynamics readout for driving and robot control. |
|
|
| | | Interface | |
| | --- | --- | |
| | Head | `LayerNorm -> Linear(dim, hidden) -> SiLU -> Linear(hidden, 64)`, output layer zero-initialised so inserting it leaves the model unchanged | |
| | Input | spatial hidden tokens mean-pooled per latent frame: `(B, L, dim) -> (B, F, 64)` | |
| | Output | 64-D action vector per latent frame; trained with MSE on masked samples so the head cannot copy its input | |
| | Install / train | `model_kwargs.action_output: true` installs the head; the `action` recipe in the code release trains it | |
|
|
| ```bash |
| bash scripts/post_train_action.sh --data <lmdb dir> # action in and out, backbone frozen |
| ``` |
|
|
| One setting decides whether the run means anything: `action_output_input_dropout: 1.0` withholds the commanded action |
| from the head's input, so the head has to read the frames rather than its own conditioning. Embodiment-specific adapters |
| then connect the generic 64-D interface to joints, end effectors, grippers or a mobile base — for driving, ego |
| trajectory, steering, speed and throttle/brake go into the same 64-D stream. |
|
|
| The head ships in this repository as six zero-initialised tensors, so the parameters exist and are trainable as they |
| stand. Untrained it returns zeros; once trained it doubles as a probe, since a head that recovers the action from |
| generated frames is direct evidence that the action conditioning is steering the rollout. |
|
|
| ## Benchmarks |
|
|
| **WBench** — 289 cases, 1,058 interaction rounds, official evaluation code and default VLM judge, 8-step causal form. |
| Each case is generated as one continuous sequence rather than restarted as i2v after every round. |
|
|
| | Split | Average | Quality | Setting | Interaction | Consistency | Physical | |
| | --- | --- | --- | --- | --- | --- | --- | |
| | Navi 158 | **73.5** | 78.2 | 73.5 | 63.4 | 83.6 | 68.6 | |
| | Full 289 | **70.0** | 78.3 | 73.8 | 47.6 | 82.4 | 68.1 | |
|
|
| Navi 158 measures navigation only; Full 289 also covers event editing, subject action and perspective switching. Against the open models on the WBench leaderboard (snapshot of 13 September 2026; peer scores from |
| the leaderboard, Astronex-World evaluated by us with the official code), † post-trained from a Wan prior: |
|
|
| | Model | Params | Training GPUs | Avg. | Qual. | Set. | Inter. | Cons. | Phys. | |
| | --- | --- | --- | --- | --- | --- | --- | --- | --- | |
| | Kairos 3.0 | 4B | n/r | 65.7 | 73.1 | 70.3 | 41.6 | 83.2 | 60.5 | |
| | YUME 1.5† | 5B | NVIDIA A100 | 68.9 | 77.6 | 72.4 | 48.4 | 80.9 | 65.4 | |
| | **Astronex-World 1.0†** | **5B** | **2x L20 48 GB** | **70.0** | **78.3** | 73.8 | 47.6 | 82.4 | 68.1 | |
| | HY-Video 1.5 | 8.3B | n/r | 74.3 | 76.6 | 85.6 | 54.7 | 87.5 | 67.1 | |
| | LongCat-Video | 13.6B | n/r | 69.9 | 77.2 | 72.3 | 45.1 | 86.6 | 68.4 | |
| | Helios (distilled)† | 14B | 64-128x H100 | 69.7 | 73.3 | 75.3 | 41.6 | 82.2 | 76.1 | |
| | LTX-2.3 | 22B | n/r | 70.9 | 77.0 | 85.2 | 49.4 | 78.0 | 65.1 | |
|
|
| Among 5B-class models this one is above YUME 1.5, post-trained from the same Wan2.2 prior on A100s, and above the 4B |
| Kairos 3.0 by 4.3 points. With a third or less of the parameters it is above LongCat-Video (13.6B) and Helios (14B) — |
| Helios uses 64 to 128 H100s per training stage — and within 0.9 points of LTX-2.3 (22B). Quality 78.3 is the highest in |
| the table, on two L20 48 GB GPUs. |
|
|
| **VBench 1.0** — official evaluation code, official prompt order, no sampling or selection. A *partial* run: 240 of |
| 6,220 text-to-video and 118 of 5,590 image-to-video videos had been generated and scored at the time of the report |
| (125 frames, 832x480, 24 fps, 8-step UniPC). |
|
|
| | Dimension | Text-to-video | Image-to-video | |
| | --- | --- | --- | |
| | Imaging quality | 0.715 | 0.738 | |
| | Aesthetic quality | 0.508 | 0.473 | |
| | Motion smoothness | 0.990 | — | |
| | Temporal flickering | 0.987 | 0.995 | |
| | Dynamic degree | 0.254 | — | |
| | Overall consistency | 0.220 | — | |
| | Background consistency | — | 0.985 | |
| | I2V background | — | 0.997 | |
| | Camera motion | — | 0.485 | |
|
|
| Smoothness, flicker and background preservation are the strongest axes, which is what block-causal KV caching, the |
| local window and the persistent sink frames are built for. Both forms ship: causal for interaction and length, |
| bidirectional when the motion has to be exact. |
|
|
| ## Speed |
|
|
| Real-time on a single NVIDIA L20 48 GB: the causal form streams block by block with cross-block KV caching and few-step |
| UniPC sampling, so frames leave the sampler as the rollout is produced instead of after the whole clip is denoised. The |
| 4-step path and the 720p preset (same weights, larger frame) are the levers for trading quality against latency. |
|
|
| ## Citation |
|
|
| ```bibtex |
| @techreport{astronexworld2026, |
| title = {Astronex-World 1.0: Real-Time Interactive World Model Foundation}, |
| author = {Zhou, Xin and Miao, Cong}, |
| year = {2026}, |
| institution = {Astronex Robotics}, |
| url = {https://world.astronex.com.cn/assets/paper/astronex-world-technical-report.pdf} |
| } |
| ``` |
|
|
| ## License |
|
|
| Released under the Apache License, Version 2.0 — see [LICENSE](LICENSE). Copyright 2026 Astronex Robotics. |
|
|


