

Enhancing Retinal Vessel Segmentation Generalization via Layout-Aware Generative Modelling
Paper • 2503.01190 • Published
Jonathan Fhima • Jan Van Eijgen • Lennert Beeckmans • Thomas Jacob • Moti Freiman
Luis Filipe Nakayama • Ingeborg Stalmans • Chaim Baskin • Joachim A. Behar

The strongest open-weight model for retinal artery/vein segmentation we know of, trained with RLAD-generated images and the REYIA dataset. Internally also known as LUNetV2.

python3 -m venv lunetv2_env && source lunetv2_env/bin/activate
pip install -r requirements.txt
python infer.py fundus.png out/
Writes out/mask.png (arteries red, veins blue) and out/overlay.png
(blended with the input). Runs in bfloat16, the precision the model was trained in.
For a full pipeline from a raw fundus image to vasculature biomarkers, see the RLAD + PVBM end-to-end tutorial, which feeds this model's output into PVBM.

If you plan to use this model or compare against it, we recommend
scoring against our benchmark rather than re-running every baseline
yourself. The scorer that produced these numbers lives in the
REYIA repo
(scripts/eval/dice_score.py).
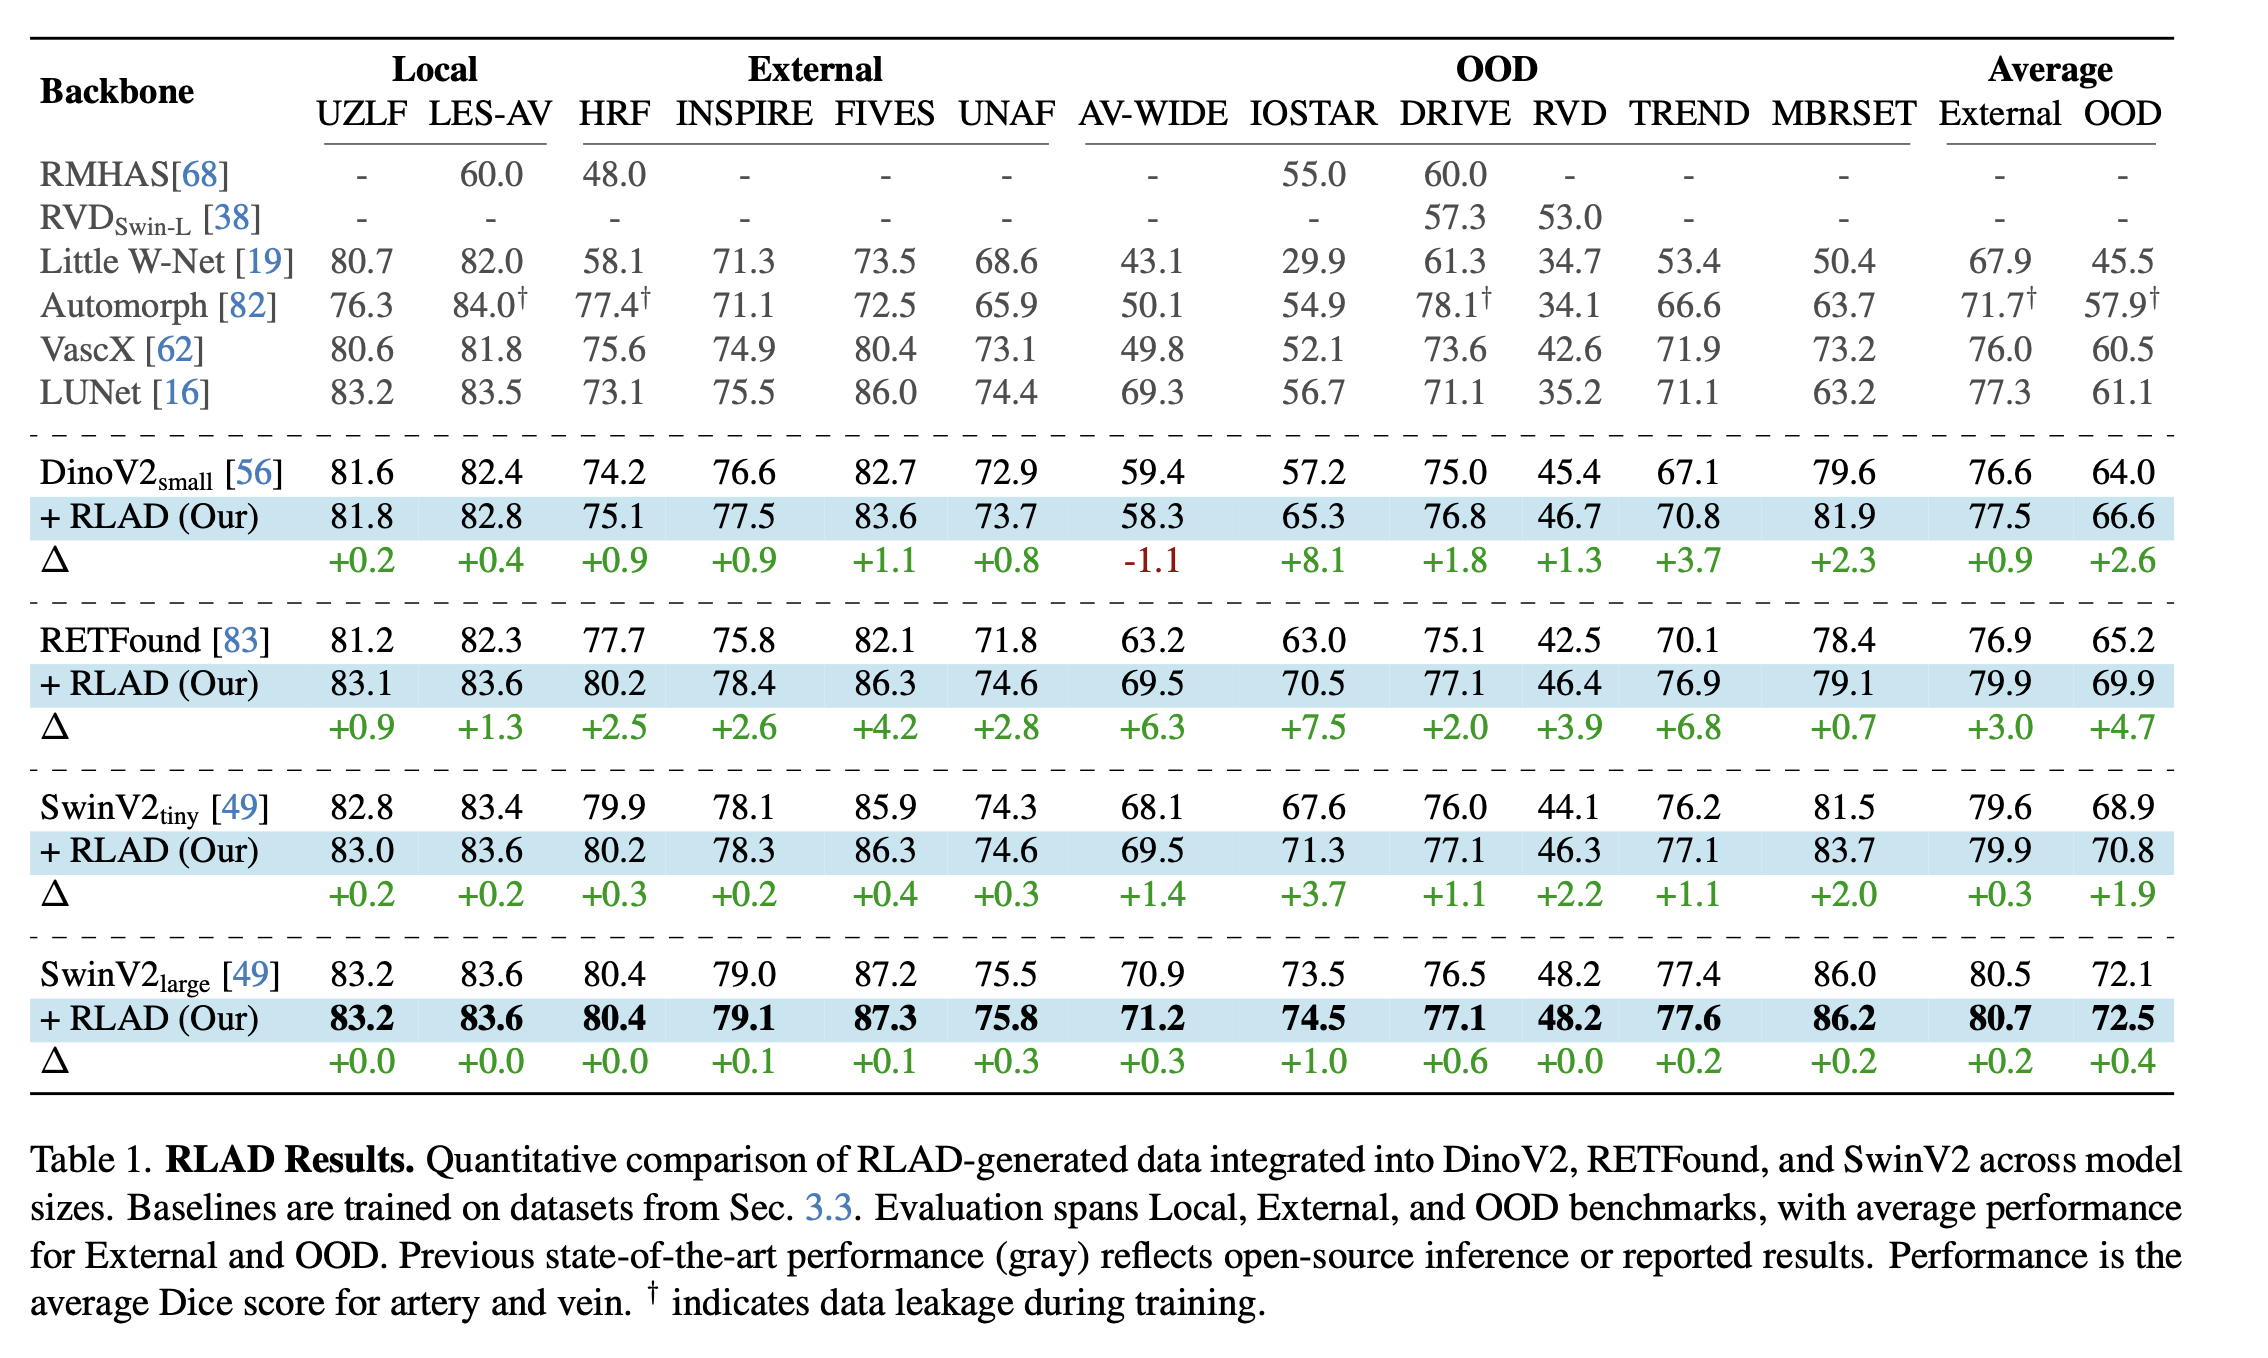
Artery/vein Dice score, averaged across the same local, external, and out-of-distribution (OOD) test sets; ∆ rows show the improvement RLAD adds on top of each backbone, and † marks results with data leakage during training — this release is the SwinV2-large row.


The code (LUNetv2.py, infer.py) is Apache 2.0. The weights
(weights/model.safetensors) are non-commercial, research use only — the
training set mixes in subsets that are themselves non-commercial or
restricted:
| Source | Status |
|---|---|
| UZLF | KU Leuven dataset |
| GRAPE | CC0 1.0 — see REYIA |
| MAGRABIA | CC BY-NC 4.0 — see REYIA |
| MESSIDOR | redistribution and commercial use explicitly prohibited — see REYIA |
| PAPILA | figshare license field reads GPL 3.0+ — likely a depositor mis-click, not corrected as of this writing — see REYIA |
| ENRICH | non-commercial use only, KU Leuven data-sharing protocol — see REYIA |
Fhima, J., Van Eijgen, J., Beeckmans, L., Jacob, T., Freiman, M., Nakayama, L.F., Stalmans, I., Baskin, C., Behar, J.A. Enhancing Retinal Vessel Segmentation Generalization via Layout-Aware Generative Modelling. arXiv:2503.01190, 2025. https://arxiv.org/abs/2503.01190