

This card is the project's README, mirrored here so the numbers live in one place (
scripts/sync_model_card.py). The folder layout and the licenses that travel with these weights are at the end.
Lilly
An offline Bosnian–English translator you can type, talk, photograph, and hear back.


▶ Try it live — type Bosnian, talk to it, or point a camera at a sign. Nothing to install.
On a phone, open the Space in its own tab (safak11-lilly-api.hf.space) before using the live camera.
Or run the whole thing offline on your own machine →
Try it · Why · Examples · Run it · Inside · Results · Limits · Paper · Training · Docs · Data · Contribute · Cite
At a glance
Lilly is a public, offline artifact: a live demo, downloadable weights, a reproducible app path, and the failed experiments are all part of the release. These are the shipped paths, measured on held-out data unless marked otherwise.
| Ability | Shipped result | Evidence |
|---|---|---|
| Translate · Bosnian → English | 43.25 BLEU / 68.10 chrF2, 0 leaked tags | 1,012 held-out FLORES-200 devtest sentences |
| Reply · English → Bosnian | 32.22 BLEU / 61.55 chrF2; 99.2% Bosnian forms (244/246) | 2,009 held-out FLORES-200 pairs, served int8 path |
| Listen · speech → text | 11.9% word error | 200 held-out FLEURS clips; shipped by the owner's decision after failing its pre-registered variety gate |
| Read · photograph → text | 67.0% found / 65 invented; 57.8% / 450 on test-v2 | 40 Commons photographs; 132 held-out photographs with text |
The numbers are not marketing estimates: the bars were written before the runs, the model files are fingerprint-bound, and the limitations stay beside the wins. The stock Bosnian reply voice is measured separately at 22.3% word error through Lilly's listener; it is a regional Piper voice, not a native Bosnian voice.
Why I built it
I applied to a lot of internships and kept getting turned down for the same reason: I did not know Bosnian.
I could not learn a language in a week, so I built the thing I needed instead. Lilly is a translator I made for myself. In class and at work I press the microphone, say what I just heard, and get it back in English. I point the camera at a whiteboard or a sign and read it. I type what I want to say in English and Lilly gives me the Bosnian to say back.
I tried the tools that already existed. Google Translate and the rest kept getting my sentences wrong — close enough to look right, wrong enough to leave me lost in the room. They also treat Bosnian as one more entry in a South Slavic bucket, and that is not the same thing as understanding it.
So I trained the models myself. The first versions were bad — under 30% of the words on a sign, more than half the words of a sentence heard wrong — and I kept the numbers as they climbed, measured every change against the untuned model underneath it, and published all of them, including the ones that say a change did nothing. Lilly is how I show that I can work in Bosnian and that I can build something serious when I hit a wall.
The longer version is in docs/STORY.md. The measured write-up
— architecture, data, every number including the failures — is
docs/WHITE-PAPER.md.
See it work
Real output from the running app, not hand-picked from a benchmark.
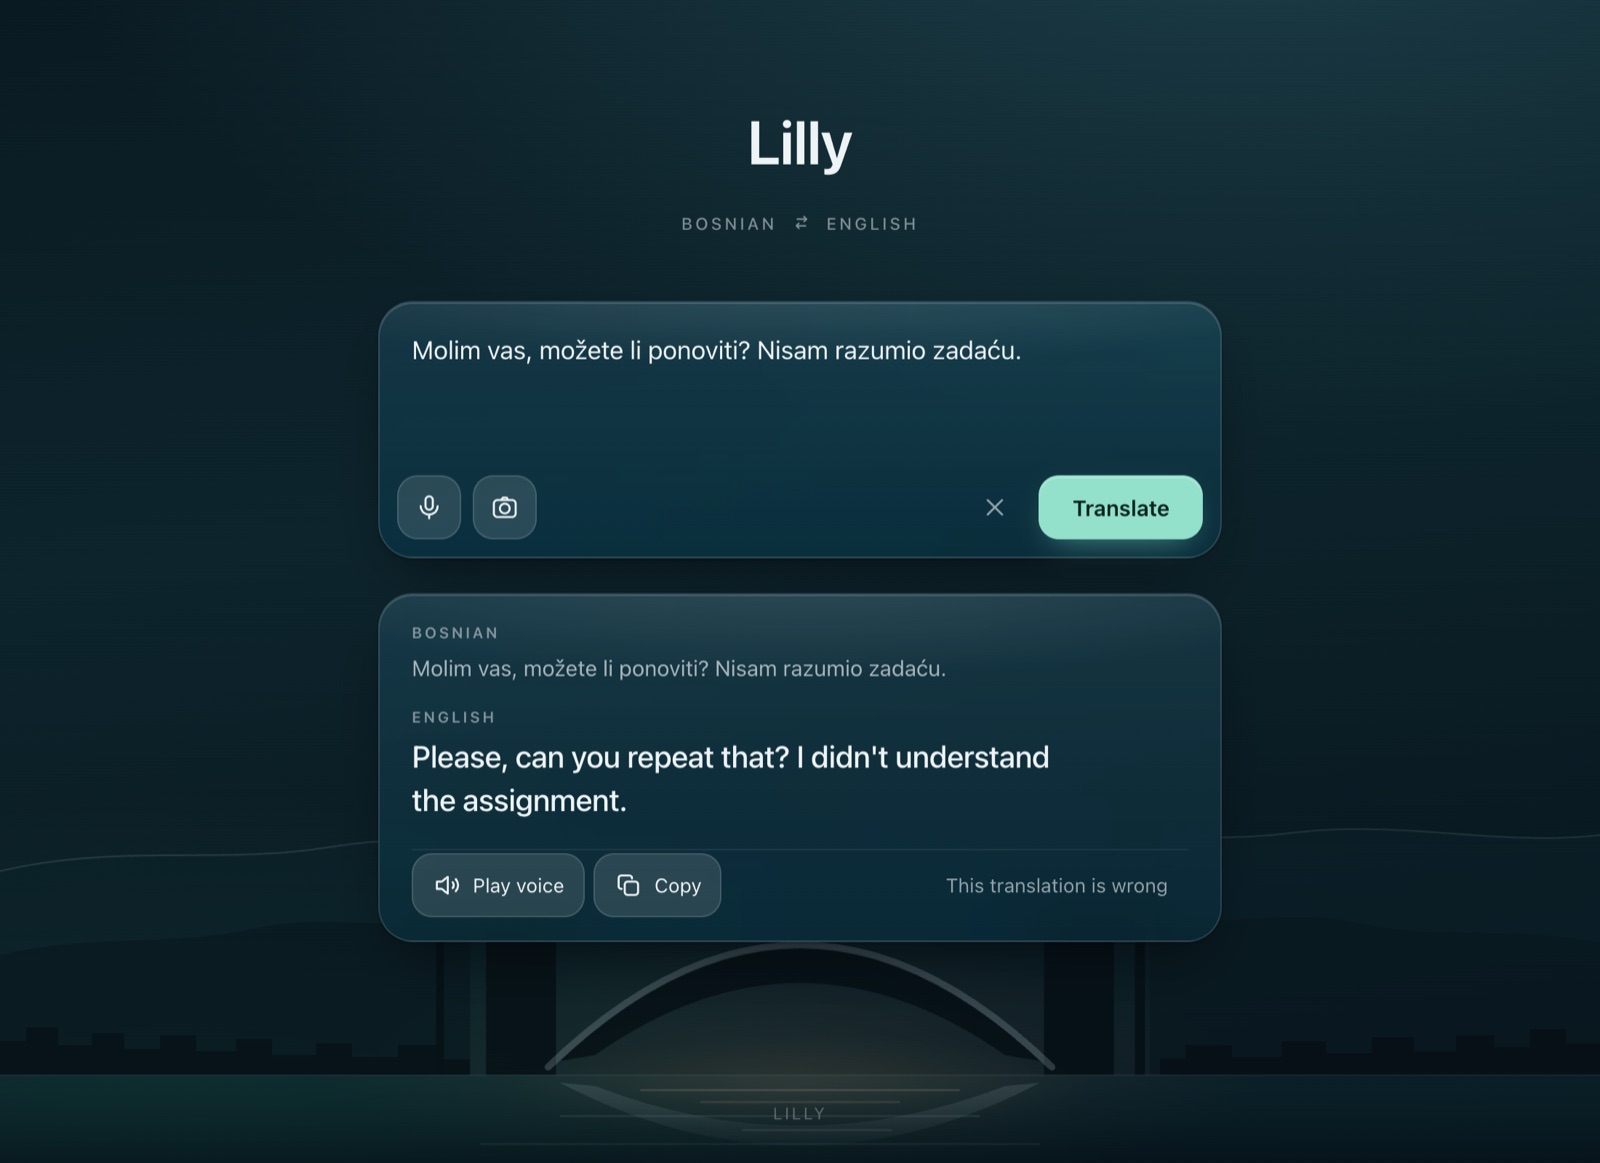
Bosnian → English
| You type | Lilly returns |
|---|---|
| Molim vas, možete li ponoviti? Nisam razumio zadaću. | Please, can you repeat that? I didn't understand the assignment. |
| Sastanak je sutra u devet u kancelariji na drugom spratu. | The meeting is tomorrow at nine in the office on the second floor. |
| Rok za predaju projekta je sljedeći petak. | The deadline for handing over the project is next Friday. |
English → Bosnian, for saying something back
| You type | Lilly returns |
|---|---|
| Could you send me the file before the meeting? | Možete li mi poslati dosje prije sastanka? |
| I am still learning Bosnian, please be patient with me. | Još učim bosanski, molim vas budite strpljivi sa mnom. |
Speech and photographs go through the same translator, so a spoken sentence and a photographed sign come back the same way a typed one does.
Run it
uv venv .venv --python 3.12
uv pip install --python .venv/bin/python -r requirements.txt
.venv/bin/python scripts/fetch_models.py        # the bundle, then the reader's own weights
.venv/bin/uvicorn app.server:app --port 8000
Open http://localhost:8000. Allow the microphone, or photograph something with a đ in it.
That gives you all five abilities. The translator arrives already fine-tuned
and quantised, so there is nothing to build for the forward direction, and the
bundle has carried the reply direction (English in, Bosnian out, the swap
button in the UI) since 8 September 2026, so fetch_models.py pulls it as
translator-en-bs/. The fetch also pulls PP-OCRv6 into PaddleX's cache
through the app's own reader, so the first photograph does not wait on a
download, and it checks the listener it was handed against the gated one,
saying so out loud if an older fetch left the closed whisper-large-v3 behind.
To rebuild the reply direction yourself from the upstream base instead:
.venv/bin/python scripts/fetch_translate_base.py --direction en-bs
.venv/bin/python scripts/build_translator.py --direction en-bs
Without translator-en-bs/ the app still runs and /api/reply answers 503.
.venv/bin/python app/lilly.py prints which parts are installed.
Every ability runs both ways. The arrow between the two language names is a
button: swap it and Lilly hears English, reads an English photograph, answers
in Bosnian, and says the answer out loud. The listener and the reader are the
same weights either way; the one new part is the Bosnian voice, speak-bs/,
which fetch_models.py pulls from rhasspy/piper-voices rather than from the
bundle. Piper has no Bosnian voice; this is a stock regional checkpoint with
its own upstream label and phoneme inventory (so numbers can come out
differently, "dve" for "dvije"), and its own card says the recordings behind
it are the Sorbian Institute's Lower Sorbian data — intelligible, accented,
and worth hearing before relying on. Without it the app still runs and /api/speak with
"language": "bs" answers 503. How well Lilly hears and reads English has not
been measured here — see What it cannot do yet.
Startup is instant because each model loads on first use. Once
fetch_models.py has finished, nothing reaches the network again.
.venv/bin/python -m pytest tests checks the parts that need no model: the sentence
splitter, the batch grouping, the correction store and the server's answers
to bad input.
What's inside
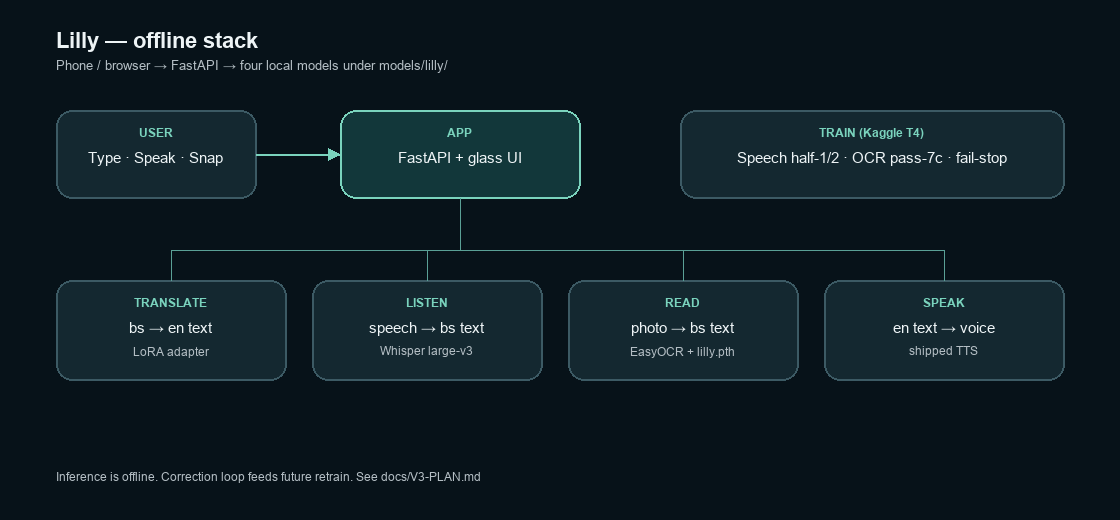
Every ability sits behind one object and one API.
from app.lilly import lilly
lilly.translate("Dobar dan")          # Bosnian text   -> English text
lilly.reply("Good morning")           # English text   -> Bosnian text
lilly.listen("clip.m4a")              # spoken Bosnian -> Bosnian text
lilly.read("sign.jpg")                # photo          -> Bosnian text
lilly.speak("Good day", "out.wav")    # English text   -> spoken English

# and the other way round, for answering back
lilly.listen("clip.m4a", language="en")               # spoken English -> English text
lilly.speak("Dobar dan", "out.wav", language="bs")    # Bosnian text   -> spoken Bosnian
lilly.translate_audio("clip.m4a", direction="en-bs")  # spoken English -> (Bosnian, English)
lilly.translate_photo("sign.jpg", direction="en-bs")  # English photo  -> (Bosnian, English)
| Endpoint | Body | Returns |
|---|---|---|
POST /api/translate |
{"text": "..."} |
Bosnian in, English out |
POST /api/reply |
{"text": "..."} |
English in, Bosnian out |
POST /api/detect |
{"text": "..."} |
which language the text is in — {"language": "bs"} or {"language": "en"} — so the page can route it without asking |
POST /api/speech |
audio upload, optional direction field |
transcribes, then translates: Bosnian heard → English (bs-en, the default), English heard → Bosnian (en-bs), or auto, where the listener decides the language and the answer adds "heard"; the answer is {"bosnian", "english"} otherwise |
POST /api/photo |
image upload, optional direction field |
reads the text off the image, then translates it, the same two ways |
POST /api/photo-boxes |
image upload, optional direction field |
the same read-and-translate as /api/photo, plus one box per region with its own source text and translation, so the page can draw the answer over the photograph |
POST /api/speak |
{"text": "...", "language": "en"} |
speech as WAV; "bs" reads the Bosnian answer with the Bosnian voice |
POST /api/document |
.docx or .pdf upload, optional direction field |
extracts the text and translates it through the same sentence-split path |
POST /api/feedback |
a correction | stored for review and retraining |
GET /health |
— | liveness |
Every request is bounded before it reaches a model — uploads by size, text by how much work it asks for, images by pixel count — because the server is written to face the open internet.
On top of the five abilities the page carries the flow a general translator
has: it detects the language unless you pick one (the swap arrow is the manual
override), translates as you type, keeps a local history and a phrasebook in
the browser, offers a conversation mode that hears either language from one
microphone, opens a live camera that draws each region's translation over the
sign, and reads a .docx or .pdf you hand it. Detection is a small committed
classifier (app/detect.py), not a download; the camera overlay is region-level,
one box per paragraph group, not word by word.
The correction button
When a translation is wrong, you press This translation is wrong, say what it should have been, and the correction is stored for review. Verified corrections go back into the training pool, so the model improves on the sentences people actually hit rather than the ones a benchmark happens to contain.
Weights it is built from
Lilly is a bundle, not a new architecture. The translator and the listener are
fine-tuned here. The reader and the voice are off the shelf: the reader is
PP-OCRv6, chosen over the fine-tuned EasyOCR reader by a rule written before the
comparison ran, and four later attempts to fine-tune it never beat it. Full
attribution and licenses are in models/lilly/NOTICE.md.
| Ability | Built from | Fine-tuned here |
|---|---|---|
| Translate | OPUS-MT opus-mt-tc-big-zls-en (Helsinki-NLP), CTranslate2 int8 |
yes — LoRA merged into the weights |
| Reply | OPUS-MT opus-mt-tc-base-en-sh (Helsinki-NLP), CTranslate2 int8 |
yes — LoRA merged into the weights; cleared its gate and published 8 Sep 2026 |
| Listen | whisper-large-v3 (OpenAI), converted to CTranslate2 int8 here |
yes — LoRA. Shipped by the owner's decision, refused at its gate (see Speech); the gated faster-whisper-small fine-tune stays the baseline |
| Read | PaddleOCR PP-OCRv6 (PP-OCRv6_medium_det + _medium_rec, PaddlePaddle), fetched at run time; EasyOCR + CRAFT stays as the LILLY_READER=easyocr way back |
no — stock, chosen by a pre-registered rule; the EasyOCR fallback is fine-tuned |
| Speak | English: Kokoro-82M (hexgrad). Bosnian: Piper sr_RS-serbski_institut-medium (rhasspy) — a stock regional voice from upstream, used because Piper has no Bosnian checkpoint; fetched at runtime, not bundled |
no — stock weights |
How well it works
Results
Every "Lilly today" figure is held-out data, through the app's own path. The fairest thing to measure a change against is the untuned model it is built on. Pass marks were written down before each run (see thresholds). The first-builds column is the owner's notes from that time, written as a bound — no measurement of those builds sits in the repository. Next is the first number written down. Then the untuned base, scored the fair way. Last is today.
| Ability | Metric | Measured on | First builds | First recorded | Untuned base | Lilly today |
|---|---|---|---|---|---|---|
| Translate | BLEU | 1,012 FLORES-200 devtest, as the user sees it | 30< | 37.72, tag in 308/1,012 (training/RESULTS-devtest.md) |
42.08, tag stripped | 43.25, 0 leaks |
| Translate | chrF2 | same 1,012 | 30< | 67.15 | 67.85 | 68.10 |
| Translate | BLEU / chrF2 | 2,009 FLORES pairs, served path, tags stripped | 30< / 30< | — | 41.77 / 67.66 | 43.03 / 67.81 (+1.26 BLEU p = 0.001; +0.15 chrF2 p = 0.074) |
| Translate | language tag in the output | 2,009 pairs | — | 576 / 2,009 (28.7%) | same | 0 |
| Reply | BLEU / chrF2 | 2,009 FLORES pairs, served int8 | 30< | 58.96 chrF2, first training (training/RESULTS-en-bs.md) |
31.23 / 60.93 | 32.22 / 61.55, 0 leaks |
| Reply | BLEU / chrF2 | adapter, whole rows (the bars) | — | 29.57 / 58.96 | same | 30.73 / 60.00 |
| Reply | Bosnian form rate | 246 decided targets | — | — | 94.3% | 99.2% (244/246) |
| Listen | word error | 200 held-out FLEURS | 55%> | 38.5% (training/RESULTS-speech.md) |
38.5% stock small; gated small 34.9% | 11.9% large-v3 (refused at its gate, shipped) |
| Listen | words heard right | 925 clean FLEURS, product path | **8476< / 18836** (same 55%> bound) | — | — | 16666 / 18836 (11.52% wrong) |
| Listen | Regional-form substitution | 925 clean FLEURS | — | — | gated small 0.96% | 6.25% (p = 0.0175, FAIL) |
| Read | words found / invented | 40 Commons (6 blurry + 1 unreadable + 12 empty) | 30%< / 280> | 36.0% / 224 (training/RESULTS-ocr.md) |
EasyOCR fine-tune 54.5% / 182 | 67.0% / 65 PP-OCRv6 floor 0.9 |
| Read | words found | 21 outdoor shots a human can still read | 30%< | — | — | 82.5% (273/331) |
| Read | words found, pooled | the 40 | 10%< | 16.9% (63 of 373) | — | 69.4% |
| Read | words found / invented | test-v2, 132 photographs | — | — | EasyOCR fine-tune 34.6% / 2,071 | 57.8% / 450 |
| Speak | word error, heard by Lilly | FLEURS prefix, 200 clips | — | — | human 11.7% | 22.3% (Piper sr_RS, stock) |
One recorded moment says what the early period was like: the reader scored
about 75% on synthetic text and 36% the first time it was pointed at real
photographs (training/RESULTS-ocr-dataset.md). The 75% was never a real
number. Everything after that was measured on real photographs, real audio and
held-out sentences.
How to read the numbers
- Word error rate (speech): the share of words heard wrong. Lower is better.
- BLEU and chrF2 (translation): how much the output overlaps a professional translation. Higher is better. chrF2 counts characters, so it is the fairer measure for a heavily inflected language, and it is the one that decides here. A difference of a point or so is noise unless a paired bootstrap says otherwise; every gain in Results has one.
- Words found and invented (photographs): the share of the words on the signs that the reader read correctly, and how many words it produced that are on no sign at all. The second number matters as much as the first, because recall can always be bought by guessing more. 67% and 82.5% are the same reader, two mixes — see Photographs below. 11.9% and 16666/18836 are the same large ear — see Speech below.
- Published: the public bundle
Safak11/lillycarries exactly the builds these numbers were measured on. The publisher checks each one by content fingerprint and refuses any other; the listener goes up only under a fingerprint named on the command line, because it did not clear its gate.
Translation
The numbers are in Results. The "first recorded" column is the
untuned model as downloaded. Scored with its leaked tags stripped, so the
defect cannot take credit, the fine-tuning is worth +1.26 BLEU at
p = 0.001 and +0.15 chrF2 at p = 0.074, which does not clear 0.05, on all
2,009 pairs (training/RESULTS-product.md; on the devtest half +1.17 / +0.25).
In plain terms: it makes word-level accuracy better, it removes a defect from
every third output, and it does not move chrF2 by an amount the bootstrap can
see. The first builds, 30< BLEU, did not manage any of that.
Re-measured on 8 September 2026 after the splitter fix. Until that day
app.translate.Engine cut a Bosnian date into pieces (5. maja 1990. godine
became three sentences) and translated each alone. The fix was pre-registered
(training/PREREGISTRATION.md, "v4 — translate — ordinals") and then measured
on Kaggle with both splitters on the same T4: the new rule is worth
+0.89 BLEU / +0.37 chrF2 to the fine-tune and +1.05 / +0.38 to the base
(p = 0.001, 167 of 2,009 rows changed), and the difference between the Mac's
CPU and the T4 on the old rule is inside noise (−0.04 BLEU, p = 0.25). The
figures above are the new ones; the old ones (42.49 / 67.69) are in the
records, not erased.
The reply direction (English → Bosnian) was fine-tuned on 8 September and
cleared all four of its pre-registered bars on the same 2,009 pairs: chrF2
58.96 → 60.00, BLEU 29.57 → 30.73 (a paired bootstrap over sentences
puts the gains at +1.04 [+0.69, +1.35] chrF2 and +1.16 [+0.67, +1.65] BLEU, 0
of 1,000 resamples at or below zero); the Bosnian form rate on 338 audited bench
targets 94.3% → 99.2% (244 of 246 decided,
training/RESULTS-en-bs-formrate.md); and the >>bos_Latn<< label still
steers, its gap against >>hrv<< going 21.8 → 22.5 points. The served build
was rebuilt with the adapter merged and published on 8 September;
scripts/fetch_models.py pulls it as translator-en-bs/. Its base, tc-base,
is a smaller model than the forward direction's, so the two directions are not
of comparable quality. Those four figures and both intervals come back out of
the stored outputs with .venv/bin/python training/verify_published_en_bs.py, which
exits non-zero if any of them stops reproducing.
Those bars were measured the way they were pre-registered: the PyTorch base plus
its adapter, each row fed in whole. That is not the path a reader meets, and
on 12 September the served int8 build was scored through app.translate.Engine
for the first time, on the same 2,009 pairs — the same treatment the forward
direction already had. It reads 32.22 BLEU / 61.55 chrF2 against an int8
base at 31.23 / 60.93, a gap of +0.99 BLEU [+0.47, +1.46] and +0.62 chrF2
[+0.33, +0.89] with 0 of 1,000 resamples at or below zero; on the devtest half
alone, 31.49 / 61.03 → 32.45 / 61.75. Both moves matter and they point
opposite ways: what a user's sentence actually gets is 1.49 BLEU above the
figure the bars were cleared on, while the fine-tuning's own share of it is
smaller than those bars suggest (+0.99 against +1.16 BLEU). The sentence
splitter lifts both columns and lifts the untuned base more, because part of
what the fine-tune learned was how to survive multi-sentence rows the app never
hands it — the forward direction found the same shape. One caveat belongs beside
this number rather than under it: training/RESULTS-bosnian-audit.md measures
FLORES's Bosnian side at 49% Bosnian by lexical marker against this project's
training data at 77%, and in this direction the Bosnian text is the reference,
so part of any chrF2 movement here measures which standard the reference was
written in. The form-rate instrument is the one that tests that question head-on
and is unaffected by it. Full report: training/RESULTS-product-en-bs.md and
docs/REPORT-reverse-direction-2026-09-12.md.
Speech
The numbers are in Results. "Today" is the listener the bundle ships, whisper-large-v3, shipped by the owner's decision and refused at its gate; the gated whisper-small stays beside it as the baseline.
11.9% is not a worse listener. It is the 200-clip headline. 16666/18836 is
the same large ear on every clean test recording (Kaggle listen-clean-eval,
17 Sep 2026, training/RESULTS-speech-listen-clean-eval.md). The variety gate
still FAILS (0.96% → 6.25%, p = 0.0175). The earlier 14.1% on 925 was a
different instrument, not this product-path run.
The two listeners against each other on the same 200 clips, one scorer, one
process (training/SPEECHBENCH-gate.txt, 7 September):
| whisper-small, the gated listener | whisper-large-v3, shipped | |
|---|---|---|
| Word error | 34.9% | 11.9% |
| Bosnian term recall | 60.0% | 89.1% (+29.1, p = 0.0000) |
| Regional form written where Bosnian was said | 5.3% | 6.5% (+1.2, p = 0.48; on all 925 clips 1.1% → 6.1%, p = 0.018) |
The gated small's own fine-tune, stock to tuned on those clips under the earlier scorer: word error 38.5% → 34.9%, Bosnian term recall 65.9% → 68.2%, wrong-variety substitutions 5.1% → 3.3%.
The larger listener: refused at its gate, shipped by decision. A whisper-large-v3
fine-tune reads 11.9% word error against the gated whisper-small's 34.9% on the
same 200 clips (training/SPEECHBENCH-gate.txt). It has to clear three rows,
not one: word error, Bosnian term recall, and regional-form substitution — how
often it writes a neighboring-standard form where the Bosnian one was said.
- Its gate, run 7 September, refused it by one word on the regional-form row.
- The pre-registered last look, all 925 clips and both listeners on
8 September (
training/speech-instrument/), refused it again, and not by one word: regional-form substitution 1.1% → 6.1% (1 of 87 against 8 of 131 decided targets, p = 0.018), the same two words over and over (Europom for evropom, vjerojatno for vjerovatno). Word error and term recall passed by wide margins. - On the project's own scale (
training/RUBRIC.md, computed for the first time in that run) the two listeners read 39.5% and 14.1%: band 3 against band 8. - By rule 3 of that pre-registration whisper-large-v3 is closed to any further look: no other split, normaliser or instrument. That closes the question of whether it passes. What ships is a separate decision.
- The owner's decision, 8 September, evening: it ships anyway. With both
readings on the table, the owner chose the larger listener for what it gets
right, 14.1% against 39.5% of words wrong and 72% against 50% of
Bosnian-specific words recovered, and accepted what it gets wrong: two
neighboring-standard spellings, Europom and vjerojatno, in 8 of 131 decided targets.
The gate's result stands as written, in
training/PREREGISTRATION.mdwith the reason. The bundle carries this listener only under its fingerprint named on the publish command (--allow-listen e6bb58483586b06c), every fresh install is told it is not the gated listener, and the gated whisper-small (34.9%) stays beside it as the baseline every listener is measured against. - How it got there, not tidied. The 4–5 September reader publish swept the
Mac's
models/lilly/listen, already large-v3, intoSafak11/lillybefore any gate had run. That is the failure the fail-stop rules exist to prevent. It was taken out at 11:31 UTC on 8 September and put back that evening by the decision above, with the numbers on the table this time.
Photographs
The numbers are in Results. Two sets of Bosnian signs from
Wikimedia Commons, each transcribed by two readers independently, seeing
neither each other's work nor any model's guess; only words both of them saw
are in the answer key. The 40 are the original set (373 agreed words).
test-v2 is 280 photographs drawn from the same pool, 132 with text, 2,907
agreed words, never trained on by anything.
| the 40 | test-v2 (132 photographs) |
|
|---|---|---|
| the first builds (unrecorded) | 30%< found, 280> invented | — |
first recorded — the first reader (training/RESULTS-ocr.md) |
36.0% found, 224 invented | — |
| EasyOCR, stock | 48.0% found, 188 invented | 30.0% found |
| EasyOCR fine-tuned on real crops (the reader until 5 Sep 2026) | 54.5% found, 182 invented | 34.6% found, 2,071 invented |
| PaddleOCR PP-OCRv6, untrained, confidence floor 0.9 — the reader now | 67.0% found, 65 invented | 57.8% found, 450 invented |
The confidence floor is there because without it PP-OCRv6 read 60.0% and
invented 2,373. The engine was chosen by a rule written before the run
(training/PREREGISTRATION.md), on the big set, not the small one: the 40
alone had said the fine-tuned reader read 54.7%, and the 132 say 34.6%.
Same shipped reader, two ways of counting the 40 (Kaggle read-clean-eval,
17 Sep 2026, training/RESULTS-ocr-read-clean-eval.md):
| photographs in the mix | words found | invented | |
|---|---|---|---|
| All 40 — why it reads 67% | 21 clean + 6 blurry-but-a-person-can-still-read + 1 a person cannot read + 12 empty (no text) | 67.0% per photograph (re-run 67.9%, 72 invented) | 65 on the published floor run |
| Outdoor photos the person building this app actually takes | the street shots that person gets outside: normal frames and slightly blurry ones a human can still read (21 in this set) | 82.5% (273 / 331 words), 53 invented | — |
67% is not a worse model. It is the 40 including those 6 + 1 + 12 frames
that pull the average down. 82.5% is the same reader on the outdoor photographs
the person building this app actually shoots — the normal ones and the slightly
blurry ones you still get a reading from — not empty frames and not the one
nobody can read. Neither number replaces test-v2 (132 photographs, 57.8% / 450).
Speak
The numbers are in Results. English is Kokoro-82M, stock. Bosnian
is Piper sr_RS, a stock regional checkpoint from upstream.
Two voices trained here did not ship (FLEURS 53.9%, parliament 51.9%). A
control held the same recipe within four points of the checkpoint, so the
recordings were the fault, not the pipeline. Details under
What it cannot do yet.
Thresholds are written before the run
Deciding measurements and their pass marks live in
training/PREREGISTRATION.md, fixed before any
number exists. Two retraining arms were run for the translator and the
pre-written tie-break chose the one with the lower headline BLEU, because the
rule said chrF2 decides. Published scores are bound to the weights by content
hash, so the numbers and the model cannot drift apart.
What it cannot do yet
This section exists because a README that only lists wins is not worth trusting.
- The Bosnian-specific claim is not proven for the forward direction. A benchmark of 346 cases built from terms that distinguish Bosnian from neighboring standards returns 91.7% → 92.2% at p = 0.360. The base model is already trained across South Slavic and arrives at 91.7% on its own, so there is very little room above it. (The reply direction is the first place this claim can be tested head-on, and there it holds: 94.3% → 99.2%.)
- The gain is concentrated in news prose. Broken out by corpus, the fine-tuning is worth +3.05 BLEU on news text and −0.82 BLEU on talks. Nothing measured here separates learned better Bosnian from adapted to news style.
- Against an outside system Lilly wins, and mostly not on its own merit.
facebook/nllb-200-distilled-600Mon the same 2,009 FLORES-200 pairs scores 36.49 BLEU bs→en against Lilly's 42.14 (whole rows throughtraining/evaluate.py, not the served path), and 26.07 en→bs against 29.57 — a model 2.6× and 8× larger, beaten in both directions (training/RESULTS-outside-baseline.md). But the untouched Helsinki base already accounts for +5.11 of that +5.65 BLEU. What the fine-tune itself adds is small and its sign depends on the path: −0.79 chrF2 on whole rows, +0.15 on the path the product serves (43.03 / 67.81 against a tag-stripped base at 41.77 / 67.66 on all 2,009 pairs, re-measured 8 September;training/RESULTS-product.md). Its clearest win is not in either column: 308 of 1,012 base outputs leaked the model's language tag into the text, and 0 do after. In the reply direction that row was measured on the base (29.57 BLEU / 58.96 chrF2), before the 8 September fine-tune (30.73 / 60.00), so that margin is the base's. The win belongs largely to OPUS-MT, which this project builds on and did not train. And NLLB-600M is the distilled small variant: Google, DeepL, the 3.3B NLLB and the large general models were not tested, so none of this is a claim about the state of the art. - English in is unmeasured. Since 8 September the listener hears English
and the reader reads English photographs, because Whisper is multilingual and
PP-OCRv6 reads Latin script whatever the language — but no held-out English
set has been scored here, so there is no number for either. And the voice
that says the Bosnian answer is not Bosnian: Piper's
sr_RSregional voice, upstream phonemes over recordings its card attributes to the Sorbian Institute, with numbers spelled out differently. Nobody has yet measured how a Bosnian speaker hears it. Through Lilly's own listener it is heard with 22.3% of words wrong on the 200-clip test prefix, against 11.7% for the human recordings. Two voices trained here did not ship: one on the FLEURS recordings themselves (53.9%,training/RESULTS-speak-bs.md) and one on fifteen hours of parliamentary speech served as the mean of five speakers (51.9%,training/RESULTS-speak-parla.md), both pre-registered, both judged by the same ear. A control run then fine-tuned the same checkpoint on its own studio recordings and held it within four points (training/RESULTS-speak-control.md), so the recipe is not the fault: the recordings were. The one path left is a clean hour from a native speaker. - English → Bosnian stays the weaker direction. The fine-tune cleared its bars (above) and has been in the bundle since 8 September, but it starts from a smaller base than the forward direction and reads 61.55 chrF2 through the app's own path where the forward direction reads 68.10.
- The photograph scores are recognition, not phone reality. The evaluated images come from Wikimedia Commons. Real photographs taken on a phone in Bosnia would be the honest test, and there is not a labelled set of them yet. The Commons images are also downscaled: a sign whose Commons original is 3968 px wide is scored here at 1280 px, and the app reads at up to 2 MP, so these numbers, if anything, understate what the reader does on a full-resolution photo. Measuring that is pre-registered and not yet run.
- The photograph score is not yet a valid score by the project's own scale.
training/RUBRIC.mdrefuses to grade the reader below 200 real photographs with text;test-v2has 132. Another 160 photographs (test-v2b) are fetched and waiting for two blind transcriptions. - One test set. FLORES is professionally translated and even in register. Real user input is not.
The full write-up of every limit is on the
model card and in
training/.
Training
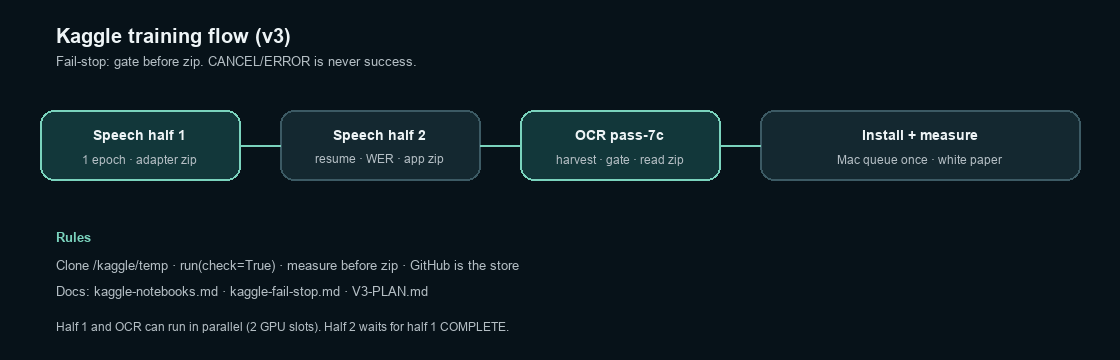
Training runs on Kaggle GPUs. This Mac commits, launches, polls, and installs
the result; it does not run multi-hour fine-tunes. The boundary is written down
in docs/V2-BOUNDARIES.md.
| Lane | What it does | Gate before anything ships |
|---|---|---|
| Translation | LoRA or full fine-tune, either direction → adapter zip | pre-registered bars on FLORES, form rate and label steering |
| Speech half 1 | one epoch → lilly-listen-half1.zip |
training exits 0; no quality claim here |
| Speech half 2 | resumes for epoch 2, then scores WER → lilly-listen.zip |
AFTER WER on the 200 held-out clips, never skipped; shipping is decided by the instrument below |
| Speech instrument | scores two listeners on all 925 clips | the three gate rows, both not either |
| OCR | harvest, real crops, synthetic crops → lilly-read.zip |
install gate must pass; the line is paused, see the roadmap |
A known failure stops the kernel. A COMPLETE status, a leftover zip from an
earlier run, or hitting the 12-hour wall does not override a gate.
python3 scripts/preflight_kaggle.py
python3 scripts/kaggle_train.py speech          # half 1
python3 scripts/kaggle_train.py ocr             # in parallel if a GPU slot is free
python3 scripts/kaggle_train.py speech-half2    # only after half 1 is COMPLETE
python3 scripts/kaggle_train.py speech-instrument   # 925 clips, both listeners: the last look at large-v3
python3 scripts/kaggle_train.py translation-en-bs   # the reply direction, LoRA, pre-registered bars
python3 scripts/kaggle_train.py speak-bs            # a Bosnian voice from FLEURS (Piper, warm-started); refused, see RESULTS-speak-bs.md
python3 scripts/kaggle_train.py speak-parla         # a voice from ParlaSpeech-HR, served as the mean of its speakers; refused
python3 scripts/kaggle_train.py speak-control       # the pipeline on the sr_RS voice's own recordings: sound, the recipe holds
python3 scripts/kaggle_train.py speak-youtube       # a voice from Creative-Commons Bosnian YouTube lectures, same judge
python3 scripts/kaggle_train.py outside-baseline    # NLLB-200 on the same FLORES pairs
python3 scripts/kaggle_poll.py                  # CANCEL or ERROR counts as failure
What gets trained next, and what does not, is in docs/V4-PLAN.md.
The reader's queue and do-not-repeat list are in
docs/OCR-ROADMAP.md. How to write a notebook that
fails loudly: docs/kaggle-notebooks.md. The list
of failures already paid for: docs/kaggle-fail-stop.md.
Repo map
| Path | What is in it |
|---|---|
app/ |
FastAPI server, the five abilities in both directions, the web UI |
models/lilly/ |
Offline weights, model card, attribution notice |
training/ |
Notebooks, training and evaluation scripts, every results file |
bench/ |
The Bosnian-versus-neighbours benchmark and how its cases are built |
scripts/ |
kaggle_train.py, preflight, poll, fetch, publish, pack_datasets.py |
docs/ |
Plans, fail-stop rules, and the white paper — index in docs/README.md |
data/ |
Lists, keys and credits in git; photographs and cleaned parallel sentences on Safak11/lilly-data |
space/ |
Hugging Face Space packaging |
CITATION.cff |
Citation metadata for the software and the measured artifact |
CONTRIBUTING.md |
Evidence-first contribution and review guide |
Status
- Translate, listen, speak, read, web app, correction pipeline
- Web app flow — detect-language by default, translate-as-you-type, a local history and phrasebook, a conversation loop, a live camera that draws each region's translation over the sign, and
.docx/.pdfin - Published weights and model card with every score and every limit
- Pre-registered thresholds and hash-bound results
- English → Bosnian fine-tune — all four pre-registered bars cleared 8 Sep (chrF2 +1.04, BLEU +1.16, form rate 99.2%, label gap 22.5); built and published 8 Sep
- Larger speech model — trained (11.9% word error); refused at the gate 7 Sep and at the pre-registered last look 8 Sep (regional-form substitution 1.1% → 6.1%, p = 0.018); closed to further looks by rule 3; shipped 8 Sep evening by the owner's decision, refused row and all, under a fingerprint named on the publish command
- A valid photograph score:
test-v2b's 160 photographs transcribed blind, then one score on the union - Re-measure the served translation path after the ordinal splitter fix — done 8 Sep on Kaggle, both splitters on one T4: devtest 42.49 → 43.25 BLEU, 67.69 → 68.10 chrF2 (p = 0.001); device drift within noise
- A labelled set of real phone photographs from Bosnia
Credits
The weights come from Helsinki-NLP and the OPUS-MT project, OpenAI and SYSTRAN,
JaidedAI and Clova AI Research, PaddlePaddle, and hexgrad. CTranslate2 and peft
shape the build. Please credit them rather than this repository. Every license
was checked against the project's own page and is listed in
models/lilly/NOTICE.md. The OPUS-MT authors ask to be
cited; the citation is on the model card.
Built by @ssaaffaakk.
Layout
| Folder | Ability | Built from | Format | Fine-tuned here? |
|---|---|---|---|---|
translator/ |
Bosnian text → English text | OPUS-MT opus-mt-tc-big-zls-en |
CTranslate2, int8 | yes — LoRA merged into the weights |
translator-en-bs/ |
English text → Bosnian text (the reply) | OPUS-MT opus-mt-tc-base-en-sh |
CTranslate2, int8 | yes — LoRA merged into the weights, 8 Sep 2026 |
listen/ |
spoken Bosnian → Bosnian text | whisper-large-v3 (OpenAI), converted to CTranslate2 here |
CTranslate2, int8 | yes — LoRA. Shipped by the owner's decision on 8 September 2026, knowing its pre-registered gate refused it: on all 925 test clips it reads 14.1% of words wrong against the gated whisper-small's 39.5%, recovers 72% of Bosnian-specific words against 50%, and writes a neighboring-standard form in 6.1% of decided targets against 1.1% (p = 0.018), the row it failed. Details under "Measured quality". |
read/ |
photo of Bosnian text → text | EasyOCR (CRAFT detector + Latin recogniser) | PyTorch checkpoints | yes — recogniser only, words 69.5% → 88.3%. Since 5 Sep 2026 the app does not read with these weights: it reads with PaddleOCR PP-OCRv6 (Baidu's published weights, untrained, at a recogniser confidence floor of 0.9), fetched at run time by PaddleX from its Hugging Face mirror and not part of this bundle. read/ is the way back — LILLY_READER=easyocr — and the "before" build every comparison is measured against. |
speak/ |
English text → spoken English | Kokoro-82M | PyTorch checkpoint + one voice | no — stock weights |
translator/built.json records what went into the build (fine_tuned, quantization),
so the served model can say which it is rather than leaving you to guess from the folder
name.
from app.lilly import lilly

lilly.translate("Dobar dan")          # Bosnian text   -> English text
lilly.reply("Good morning")           # English text   -> Bosnian text
lilly.listen("clip.m4a")              # spoken Bosnian -> Bosnian text
lilly.speak("Good day", "out.wav")    # English text   -> spoken English
lilly.read("sign.jpg")                # photo          -> Bosnian text
Credits and licenses
Every weight here comes from one of these projects, and the two tools below shaped the build. The bundle exists because of their work — please credit them rather than this repository. Licenses were checked against each project's own page, not assumed.
Weights
| Folder | Source | Author | License |
|---|---|---|---|
translator/ |
opus-mt-tc-big-zls-en | Helsinki-NLP / the OPUS-MT project, University of Helsinki | CC-BY-4.0 |
listen/ |
Whisper large-v3, converted to CTranslate2 int8 by this project | OpenAI | MIT |
read/ |
EasyOCR; detector from CRAFT | JaidedAI; CRAFT by Clova AI Research, NAVER Corp. | Apache-2.0 (EasyOCR); MIT (CRAFT) |
| (engine, not bundled) | PaddleOCR PP-OCRv6 — what the app reads with since 5 Sep 2026, fetched at run time | PaddlePaddle Authors, Baidu | Apache-2.0 |
speak/ |
Kokoro-82M | hexgrad | Apache-2.0 |
Tools
Neither contributes weights; both are why the served models are the shape they are.
| Tool | Author | License | Used for |
|---|---|---|---|
| CTranslate2 | OpenNMT | MIT | quantising and serving translator/ and listen/ |
| peft | Hugging Face | Apache-2.0 | the LoRA fine-tuning merged into translator/ |
The OPUS-MT authors ask that their papers be cited:
@inproceedings{tiedemann-thottingal-2020-opus,
  title = "{OPUS}-{MT} {--} Building open translation services for the World",
  author = {Tiedemann, J{\"o}rg and Thottingal, Santhosh},
  booktitle = "Proceedings of the 22nd Annual Conference of the European Association
               for Machine Translation",
  year = "2020", address = "Lisboa, Portugal"
}

@inproceedings{tiedemann-2020-tatoeba,
  title = "The Tatoeba Translation Challenge {--} Realistic Data Sets for Low Resource
           and Multilingual {MT}",
  author = {Tiedemann, J{\"o}rg},
  booktitle = "Proceedings of the Fifth Conference on Machine Translation",
  year = "2020"
}
NOTICE.md carries the full attribution notice, and takes it one level
further back — to the datasets these models were themselves trained on, where those
datasets ask for it (Koniwa and SIWIS behind speak/, the Tatoeba Challenge and OPUS
collections behind translate/, SynthText and the ICDAR sets behind read/). Note that
NOTICE.md was written when the translation folder was named translate/; its
translate/ entry is the source of what is now served as translator/.
What was changed
translator/— the OPUS-MT weights with this project's LoRA fine-tuning merged in, then converted to CTranslate2 int8. Not byte-identical to upstream, by design.translator-en-bs/— the OPUS-MTtc-base-en-shweights with this project's LoRA fine-tuning merged in, then converted to CTranslate2 int8. Not byte-identical to upstream, by design.listen/— the Whisper large-v3 weights fine-tuned on Bosnian audio (LoRA merged), then converted to CTranslate2 int8. Not byte-identical to upstream.read/,speak/— weight files byte-identical to the originals. Two files inspeak/were renamed so the app can load them by a stable path:kokoro-v1_0.pth→model.pth, andvoices/af_heart.pt→voices/default.pt. Only theaf_heartvoice is included; the rest are in the upstream repository.
Model tree for Safak11/lilly
Base model
Helsinki-NLP/opus-mt-tc-base-en-sh