

Sors-2B
Sors-2B is a 2B decision model that turns a state and a set of typed questions into decisions. It reads the state as text or JSON and returns a probability for every allowed option of every question. There is no free-form text generation and no output parsing.
The Sors API follows the Jev / SystemOne request and response format.
Sors-2B is fine-tuned from Qwen/Qwen3.5-2B-Base.
Model
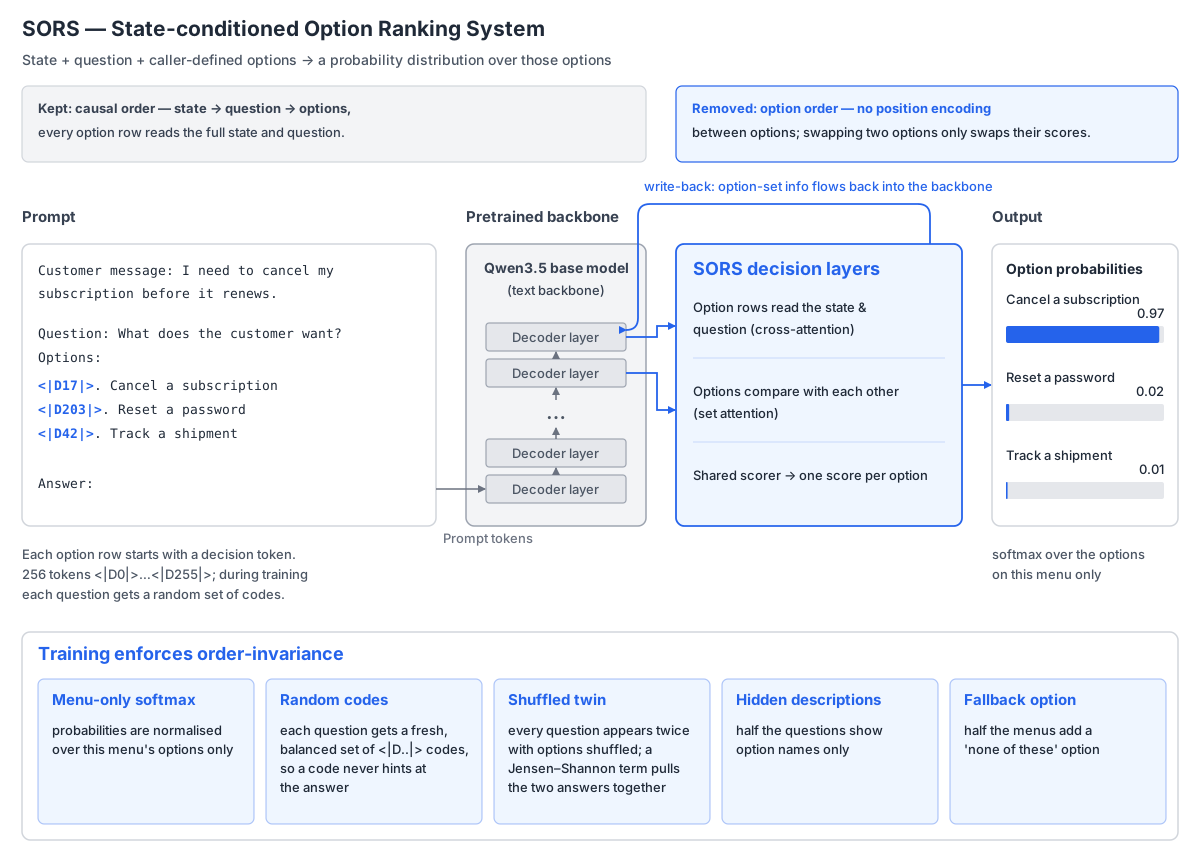
- Backbone: Qwen/Qwen3.5-2B-Base text backbone, fully fine-tuned.
- One branch per option: each question becomes a shared prefix (state, then question) plus one short suffix per option,
Option: <|D1|> <option text>andAnswer:. The prefix is encoded once and shared; no branch sees another option. - Readout: a scalar head on the backbone's final hidden state at
Answer:gives one score per option. It starts as the language model's log-odds that the next token is<|D1|>("this option fits") rather than<|D2|>("it does not"). - Output: one probability per allowed option, a softmax over that question's options only. Options are defined per request, up to 255 per question, with no retraining.
Because options are scored independently, reordering the menu only reorders the scores. Training first teaches the backbone
the <|D1|> / <|D2|> choice for every option on its own (the first 1,650 steps), then switches the head on and trains the
softmax over the menu together with the same per-option term. Ambiguous questions train toward a probability distribution,
half the questions hide option descriptions, and half the menus add a "none of these" option.
Training data
Sors-2B is trained only on our own synthetic dataset, synth-intents-v5.17: 370,639 questions over 184,138 materials in 26 domains, with yes/no, named-option and ordered-score questions (to be open-sourced once it is cleaned up). None of the evaluation sets below take part in training. The synthetic data is written from scratch, contains no content from existing datasets, and stays out of Banking77's banking domain and MASSIVE's voice-assistant scenarios. Compared against every evaluation set below, no text is identical after normalisation, and only 5 of Banking77's 3,080 items share a run of 8 consecutive words with the training material, all of them everyday phrases.
Files
| File | Purpose |
|---|---|
model.safetensors |
All weights (3.76 GB): backbone in BF16, scalar head in FP32, learned `< |
config.json |
Sors architecture, text-model configuration, decision-token IDs and per-parameter precision |
tokenizer.json, tokenizer_config.json, chat_template.jinja |
Training tokenizer, including its 261 added special tokens |
LICENSE |
Apache-2.0 license |
Usage
Sors-2B runs with the SORS runtime from the code repository. Tested with torch 2.14 and transformers 5.17 on a single
A100 40GB.
git clone https://github.com/madousho-ai/sors && cd sors
uv sync
PYTHONPATH=src .venv/bin/python scripts/serve.py \
  --init SakuraYuyuko/Sors-2B --warmup --port 8000
--init downloads this repository into the standard Hugging Face cache on first start.
Jev / SystemOne API
The server answers POST /v1/systemone. The response has model, answers keyed by question ID, and usage. A choice
answer has choice, confidence and probabilities; a score answer has the expected score, confidence, legend and
probabilities; a noul answer has the probability of true.
curl -s http://127.0.0.1:8000/v1/systemone \
  -H 'Content-Type: application/json' \
  -d '{
    "model": "Sors-2B",
    "state": "I need to cancel my subscription before it renews.",
    "questions": {
      "intent": {
        "type": "choice",
        "instructions": "What does the customer want?",
        "criteria": {"Cancel a subscription": null, "Reset a password": null, "Track a shipment": null}
      },
      "urgent": {"type": "noul", "instructions": "Does the customer need this done right away?"}
    }
  }'
Python
from pathlib import Path

from huggingface_hub import snapshot_download
from sors.serve.api import Choice
from sors.serve.engine import load_engine

engine = load_engine(Path(snapshot_download("SakuraYuyuko/Sors-2B")), device="cuda", local_files_only=True)
question = Choice(
    type="choice",
    instructions="What does the customer want?",
    criteria={"Cancel a subscription": None, "Reset a password": None, "Track a shipment": None},
)
result = engine.evaluate("I need to cancel my subscription before it renews.", {"intent": question})
print(dict(zip(question.criteria, result.probs["intent"])))
Input format
| Field | Description |
|---|---|
model |
Served model name, Sors-2B by default |
state |
Any string or JSON value describing the situation to decide on |
questions |
Mapping of question ID to question; several questions share one state |
Each question has:
type:noul(yes/no),choice(named options), orscore(ordered options)instructions: what to decide, as a string or JSONcriteria: forchoice, a mapping of option name to an optional description (2–255 options); forscore, a list of ordered levels; fornoul, optional descriptions fortrueandfalse
Inputs are limited to 8,192 tokens.
Results
Accuracy (%). Banking77 and MASSIVE are answered against the full intent menu: all 77 and all 60 intents on every question, with no top-K shortlist. "+ descriptions" adds a one-line description after each intent name.
| Benchmark | Questions | Sors-2B |
|---|---|---|
| Banking77 | 3,080 | 67.0 |
| Banking77 + descriptions | 3,080 | 79.7 |
| MASSIVE | 2,974 | 68.6 |
| MASSIVE + descriptions | 2,974 | 80.4 |
| BoolQ | 3,270 | 81.1 |
| Public JevBench easy | 48 | 100.0 |
| Public JevBench original | 72 | 97.2 |
| Public JevBench hard | 111 | 66.7 |
| Public JevBench overall | 231 | 83.1 |
- With options shuffled into 5 random orders, accuracy stays within 0.1 points of the table, and the 5 orders pick the same option on 99.7–99.8% of Banking77 and MASSIVE questions and on every BoolQ question.
- Public JevBench is JevBench's public question set, scored with the official JevBench CLI and its
typesafeadapter. Its tiers are small, so differences of a few points there are noise. Results from the JevBench leaderboard will be added once available. - The weights released on 2026-10-08 (trained on synth-intents-v5.3) remain available as revision
v5.3-2026-10-08.
License
Model weights are released under Apache-2.0, following the Qwen base model. The API format follows TypeSafe's System One; this project is not affiliated with TypeSafe AI.
- Downloads last month
- 57
Model tree for SakuraYuyuko/Sors-2B
Base model
Qwen/Qwen3.5-2B-Base