

HyperClick: Advancing Reliable GUI Grounding via Uncertainty Calibration
Paper • 2510.27266 • Published • 21
Paper · Code · 3B model · 7B model
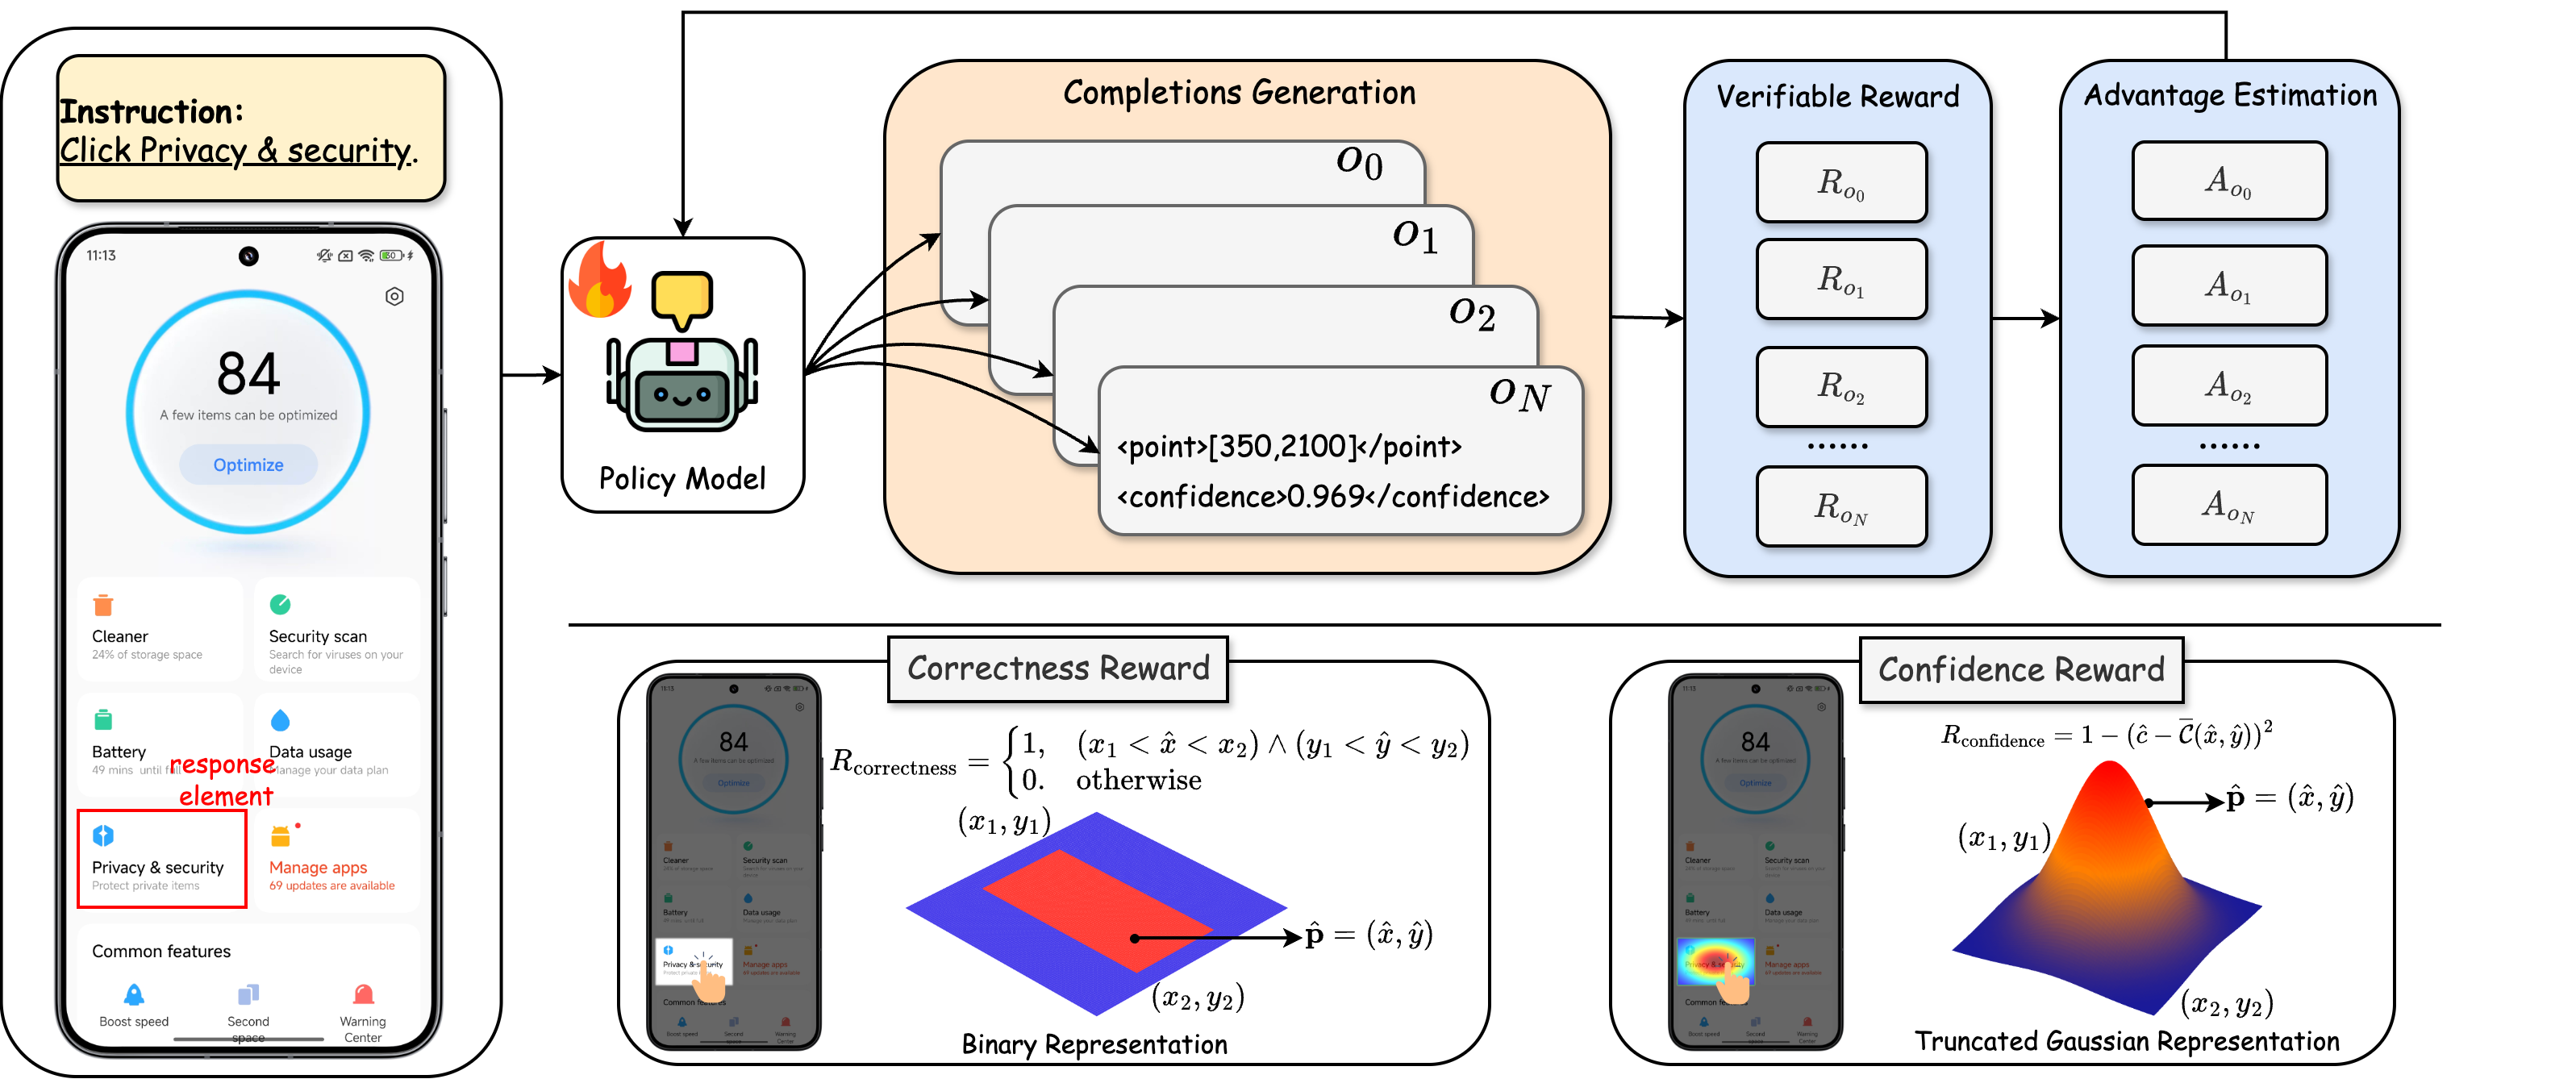
HyperClick grounds natural-language instructions in GUI screenshots and predicts a click point together with an explicit confidence score. This repository contains the 3B checkpoint, based on Qwen2.5-VL-3B-Instruct, with full model weights in Safetensors format.
The training framework combines supervised fine-tuning with reinforcement fine-tuning. Its rewards check output format, grounding correctness, and confidence alignment using a truncated Gaussian spatial target and the Brier score. See the training code for details.
Grounding accuracy (%) from the project evaluation table. These are the project's reported results, not a new evaluation of the uploaded files.
| Model | ScreenSpot | ScreenSpot-v2 | ScreenSpot-Pro | MMBench-GUI | UI-I2E-Bench | CAGUI | UI-Vision |
|---|---|---|---|---|---|---|---|
| HyperClick-3B | 88.5 | 90.6 | 41.3 | 71.4 | 71.8 | 81.0 | 19.6 |
| HyperClick-7B | 91.5 | 93.7 | 48.2 | 79.6 | 76.5 | 82.9 | 25.7 |
The example below uses Transformers on a CUDA GPU. Install PyTorch for your CUDA environment, then install the inference dependencies:
pip install "transformers==4.49.0" "accelerate==1.10.0" "qwen-vl-utils==0.0.11" pillow
Replace screenshot.png and the instruction with your own input. The prompt follows the HyperClick training template.
import torch
from PIL import Image
from transformers import AutoProcessor, Qwen2_5_VLForConditionalGeneration
from qwen_vl_utils import process_vision_info

model_id = "SeerRay-Lab/Qwen2.5-VL-3B-HyperClick"
model = Qwen2_5_VLForConditionalGeneration.from_pretrained(
    model_id, torch_dtype=torch.bfloat16, device_map="auto"
).eval()
processor = AutoProcessor.from_pretrained(
    model_id, min_pixels=3136, max_pixels=4390400, use_fast=False
)

screenshot = Image.open("screenshot.png").convert("RGB")
instruction = "Click the search button"
messages = [dict(role="user", content=[
    dict(type="image", image=screenshot, min_pixels=3136, max_pixels=4390400),
    dict(type="text", text=(
        f'Point to the element related to the instruction "{instruction}" '
        'on the screenshot with your confidence.'
    )),
])]
prompt = processor.apply_chat_template(
    messages, tokenize=False, add_generation_prompt=True
)
images, _ = process_vision_info(messages)
inputs = processor(text=[prompt], images=images, return_tensors="pt").to(model.device)
with torch.inference_mode():
    generated = model.generate(**inputs, max_new_tokens=128, do_sample=False)
answer = processor.batch_decode(
    generated[:, inputs.input_ids.shape[1]:], skip_special_tokens=True
)[0]
print(answer)

# Dimensions of the image coordinate space used by the model.
patch_size = processor.image_processor.patch_size
_, grid_h, grid_w = inputs.image_grid_thw[0].tolist()
input_width, input_height = grid_w * patch_size, grid_h * patch_size
print("Model image size:", input_width, input_height)
The expected output format is:
<point>[x,y]</point><confidence>conf</confidence>
x and y are pixel coordinates in the processed image; conf is a confidence estimate between 0 and 1. To map a predicted point back to the original screenshot, use:
# x and y are parsed from the model response.
x_original = x * screenshot.width / input_width
y_original = y * screenshot.height / input_height
Image resizing affects the coordinate system. Validate the response format and point bounds before using a prediction. Confidence is a learned estimate and can be incorrect, especially for unfamiliar interfaces or ambiguous instructions.
The GitHub repository provides training setup, example annotation formats, and the reinforcement fine-tuning entry points:
bash src/open-r1-multimodal/run_hyperclick_3b.sh
This model is derived from Qwen2.5-VL-3B-Instruct. See the upstream Qwen Research License for the base model terms.
The latest arXiv version is titled Enhancing Trustworthy GUI Grounding via Self-Critiqued Reinforcement Learning.
@misc{zhang2025hyperclick,
  title={Enhancing Trustworthy GUI Grounding via Self-Critiqued Reinforcement Learning},
  author={Shaojie Zhang and Pei Fu and Ruoceng Zhang and Jiahui Yang and Anan Du and Xiuwen Xi and Shaokang Wang and Ying Huang and Bin Qin and Zhenbo Luo and Jian Luan},
  year={2025},
  eprint={2510.27266},
  archivePrefix={arXiv},
  primaryClass={cs.CV},
  url={https://arxiv.org/abs/2510.27266}
}
Base model
Qwen/Qwen2.5-VL-3B-Instruct