

Upload folder using huggingface_hub
Browse files- .gitattributes +0 -34
- LICENSE +202 -0
- README.md +201 -0
- text_encoder/config.json +6 -0
- transformer/config.json +22 -0
- transformer/model.safetensors +3 -0
- vae/config.json +22 -0
- vae/model.safetensors +3 -0
.gitattributes
CHANGED
|
@@ -1,35 +1 @@
|
|
| 1 |
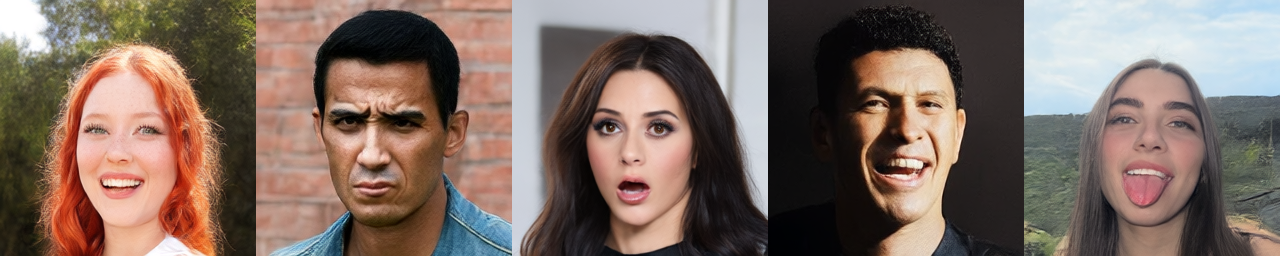
-
*.7z filter=lfs diff=lfs merge=lfs -text
|
| 2 |
-
*.arrow filter=lfs diff=lfs merge=lfs -text
|
| 3 |
-
*.bin filter=lfs diff=lfs merge=lfs -text
|
| 4 |
-
*.bz2 filter=lfs diff=lfs merge=lfs -text
|
| 5 |
-
*.ckpt filter=lfs diff=lfs merge=lfs -text
|
| 6 |
-
*.ftz filter=lfs diff=lfs merge=lfs -text
|
| 7 |
-
*.gz filter=lfs diff=lfs merge=lfs -text
|
| 8 |
-
*.h5 filter=lfs diff=lfs merge=lfs -text
|
| 9 |
-
*.joblib filter=lfs diff=lfs merge=lfs -text
|
| 10 |
-
*.lfs.* filter=lfs diff=lfs merge=lfs -text
|
| 11 |
-
*.mlmodel filter=lfs diff=lfs merge=lfs -text
|
| 12 |
-
*.model filter=lfs diff=lfs merge=lfs -text
|
| 13 |
-
*.msgpack filter=lfs diff=lfs merge=lfs -text
|
| 14 |
-
*.npy filter=lfs diff=lfs merge=lfs -text
|
| 15 |
-
*.npz filter=lfs diff=lfs merge=lfs -text
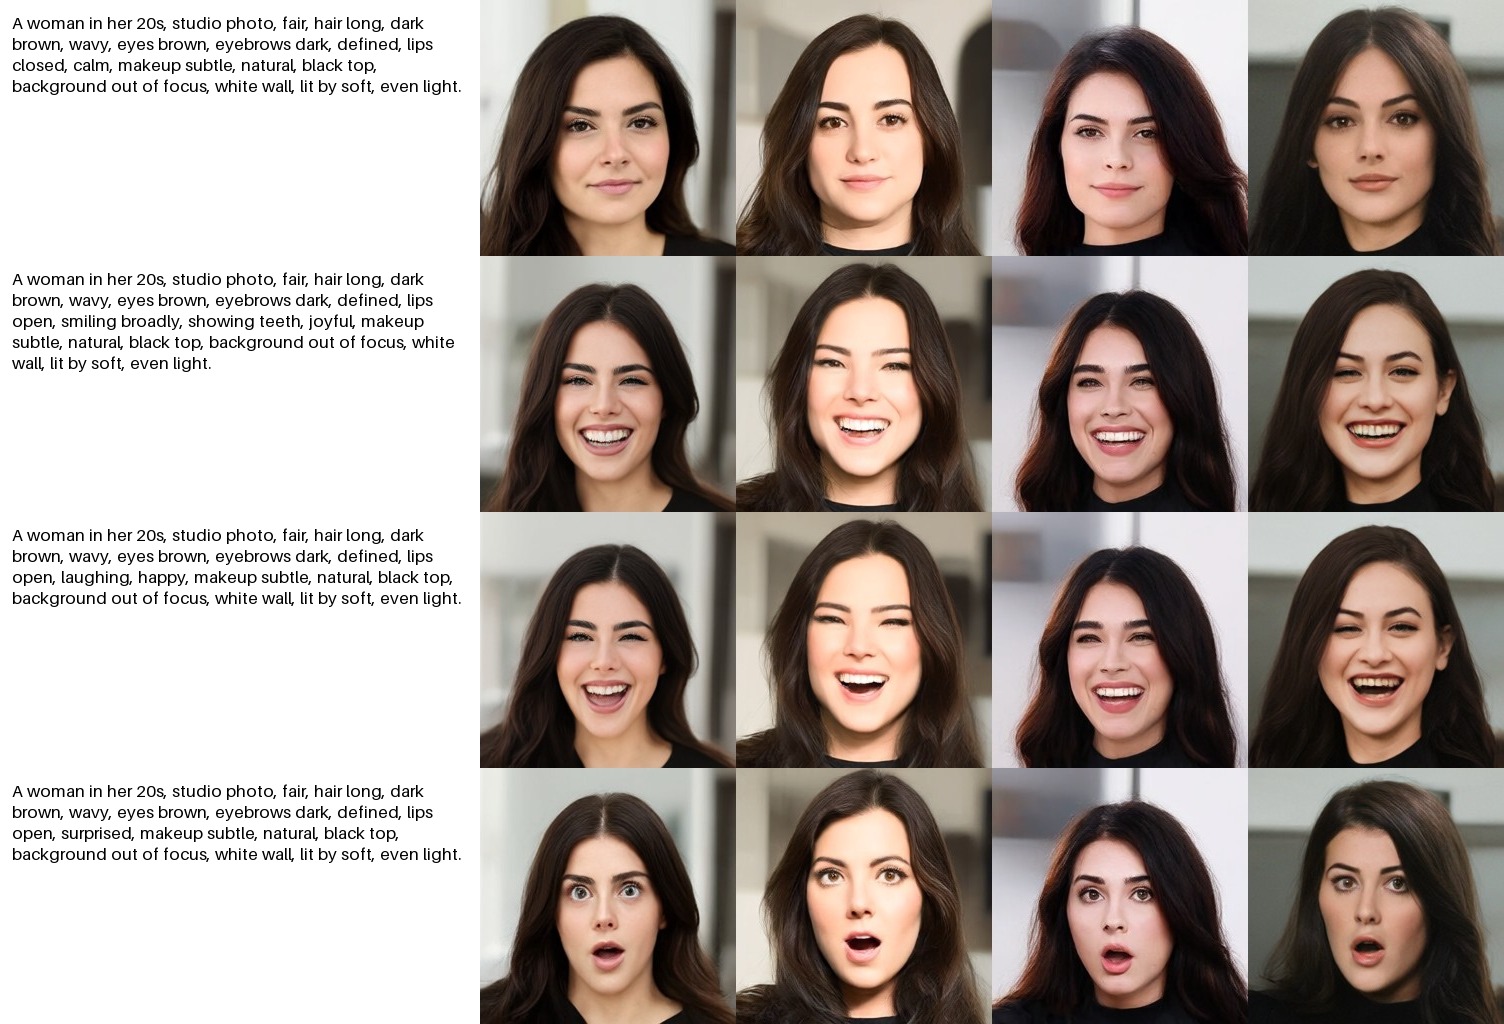
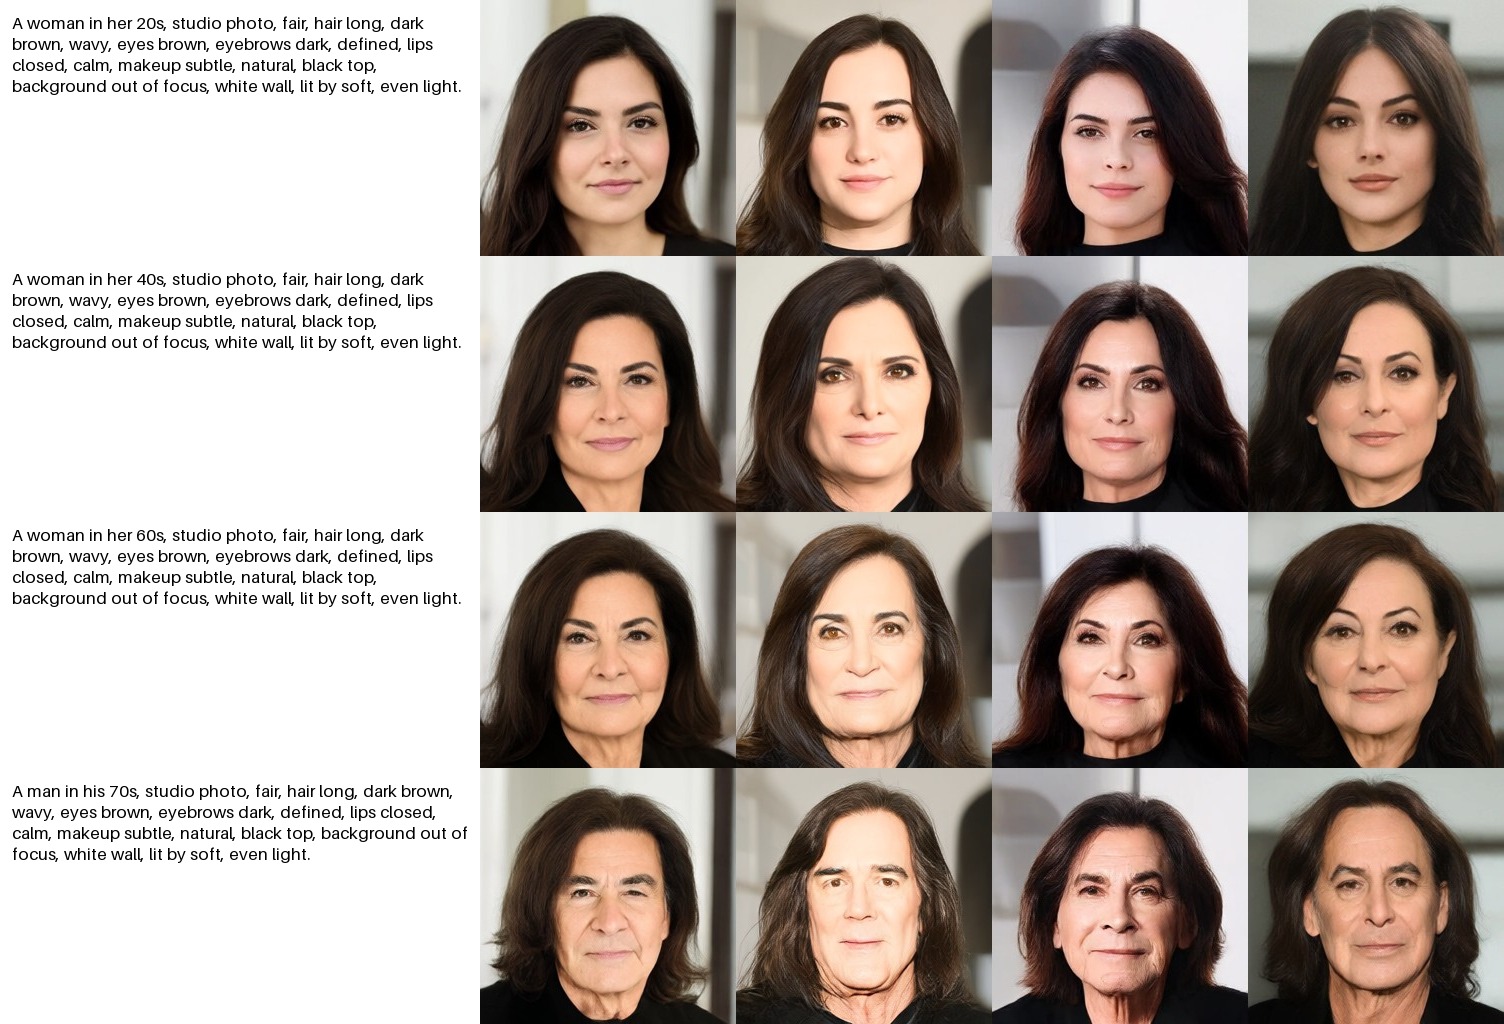
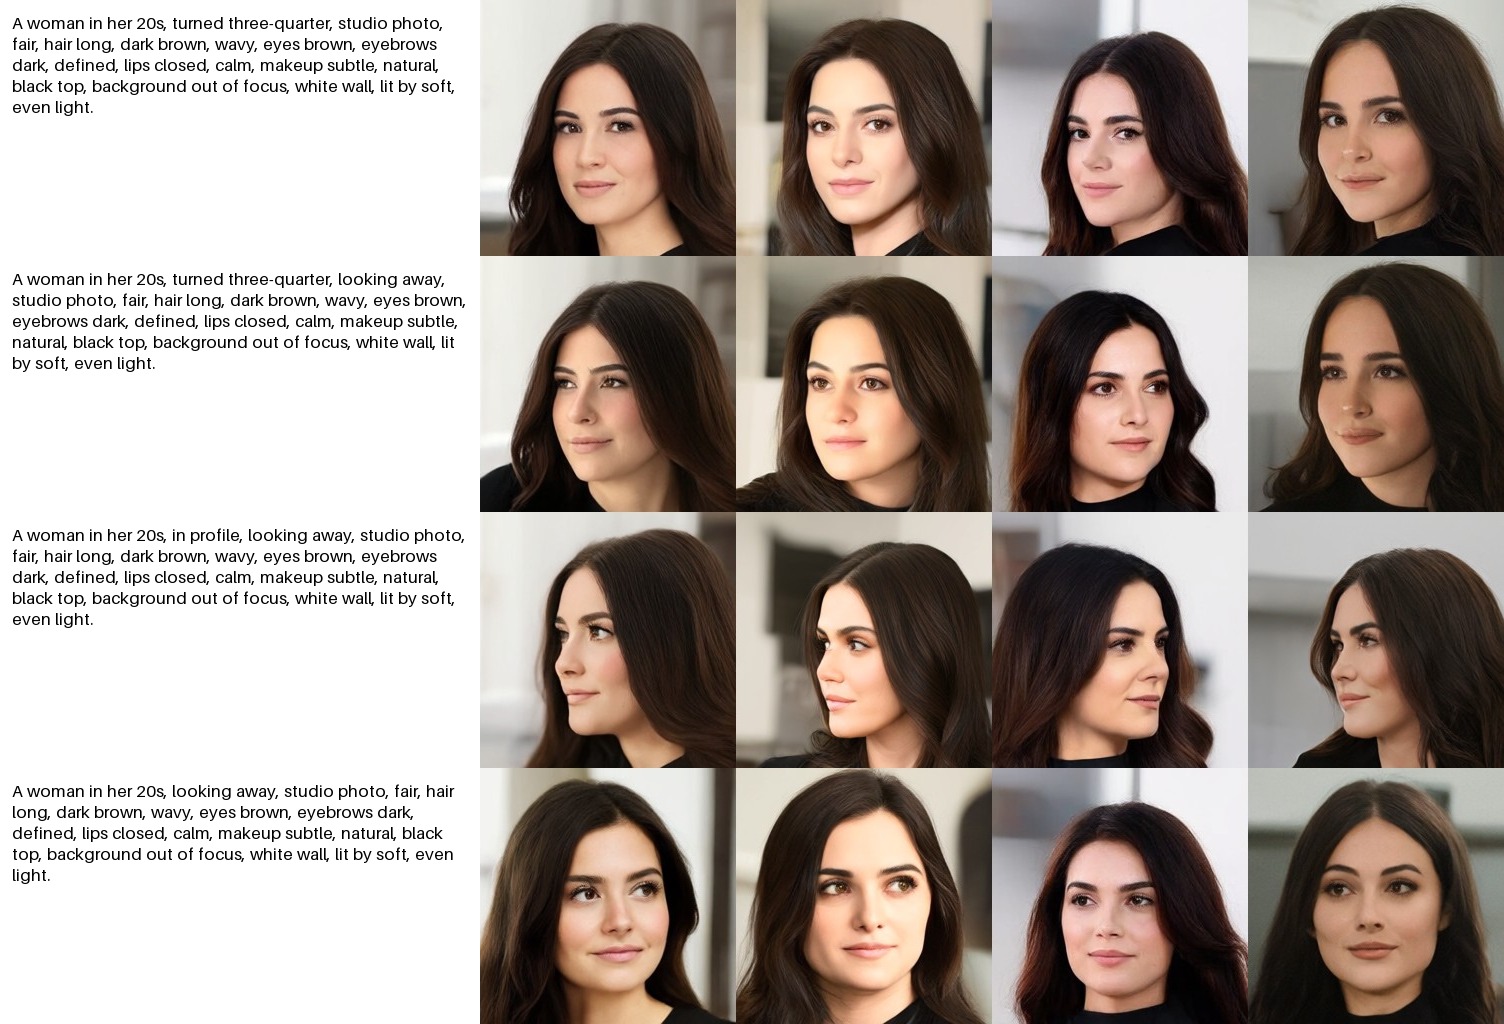
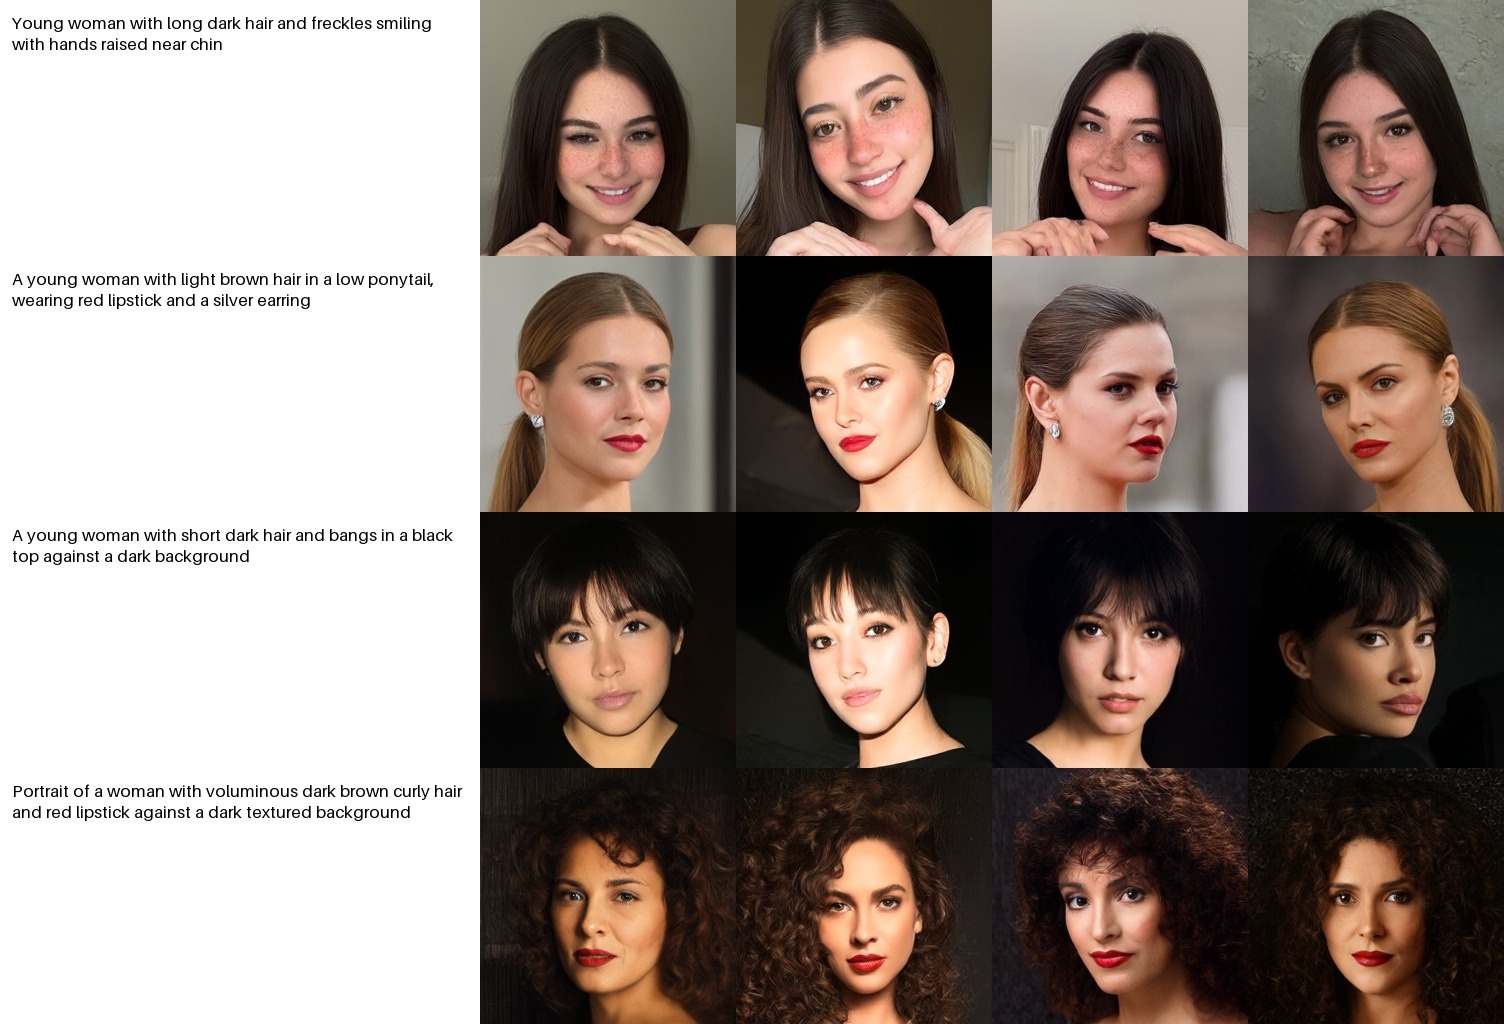
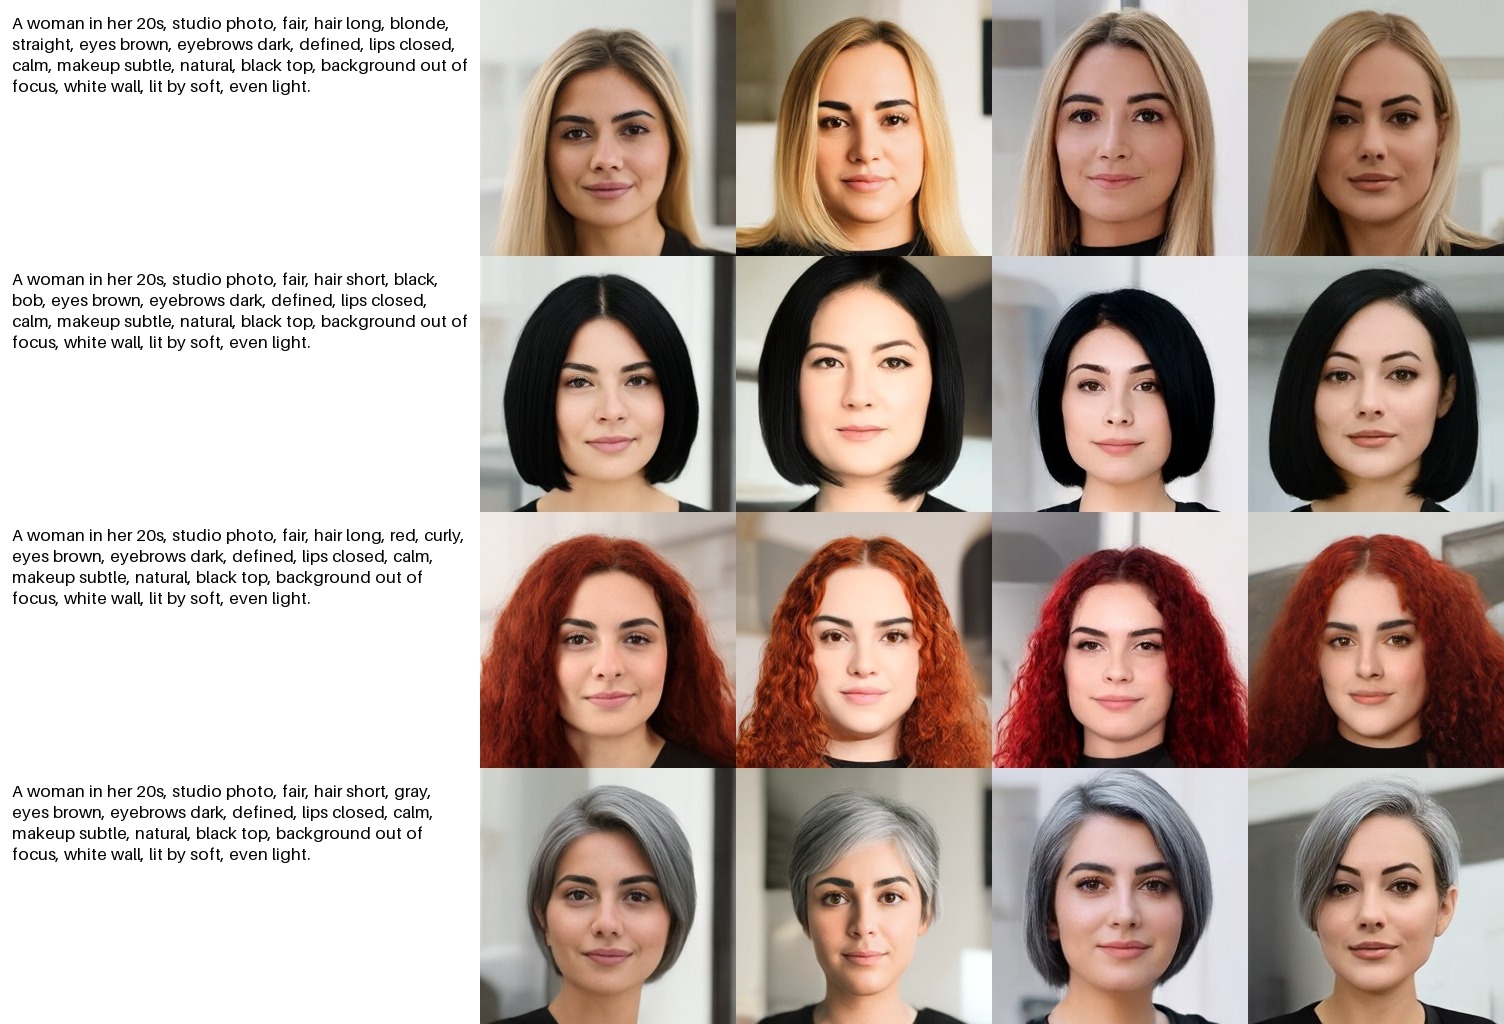
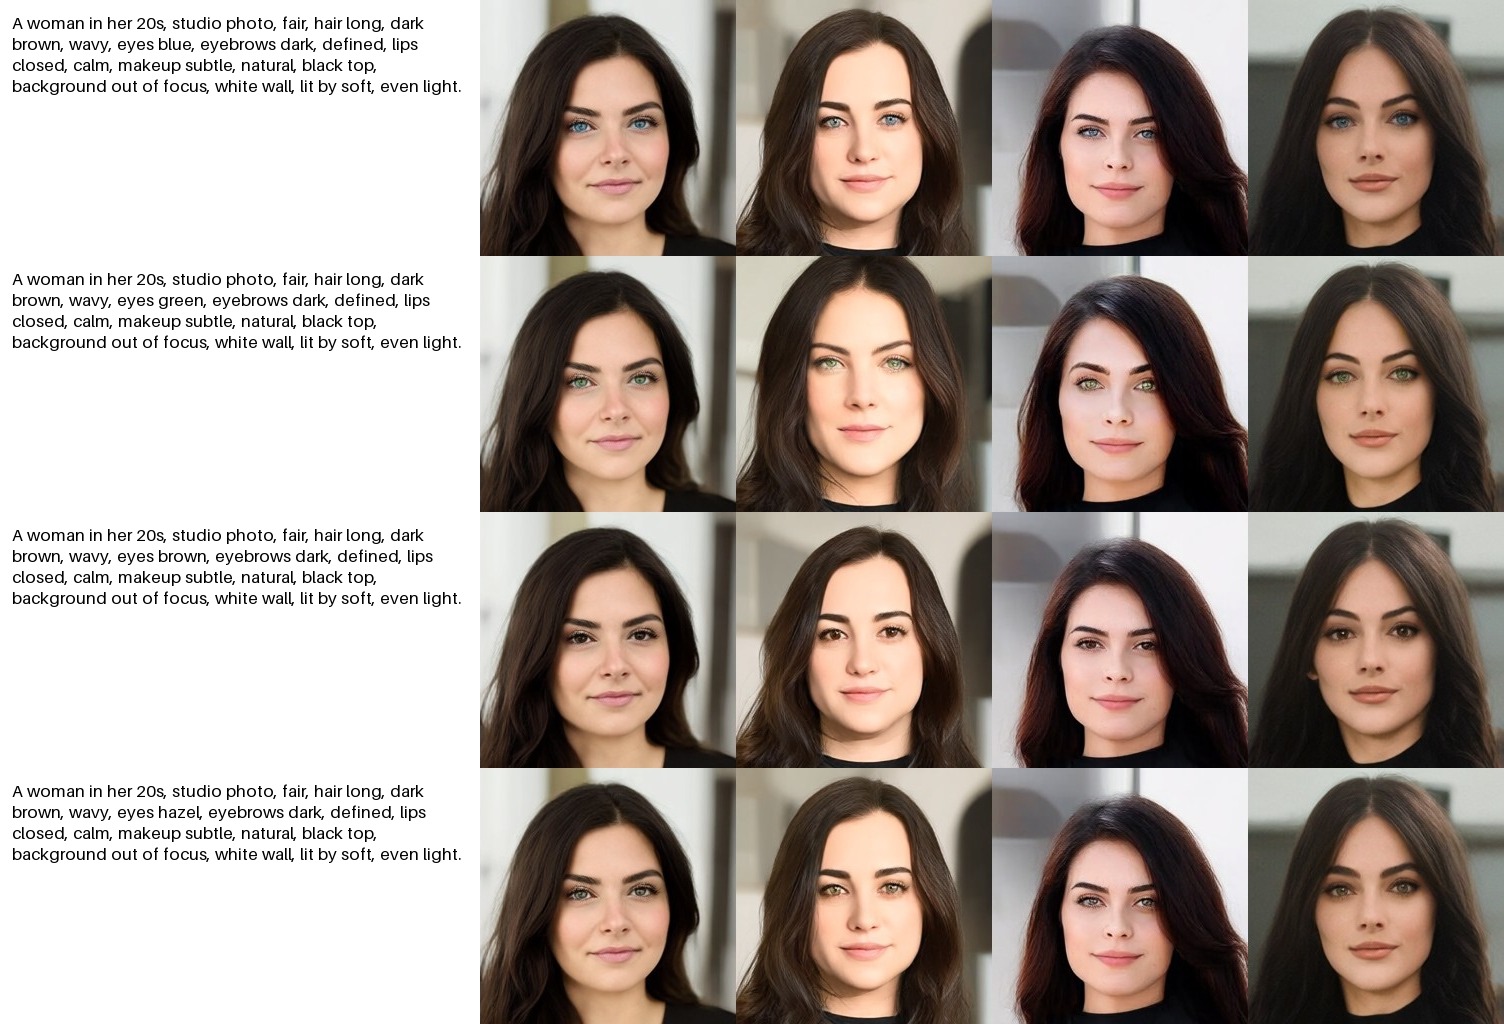
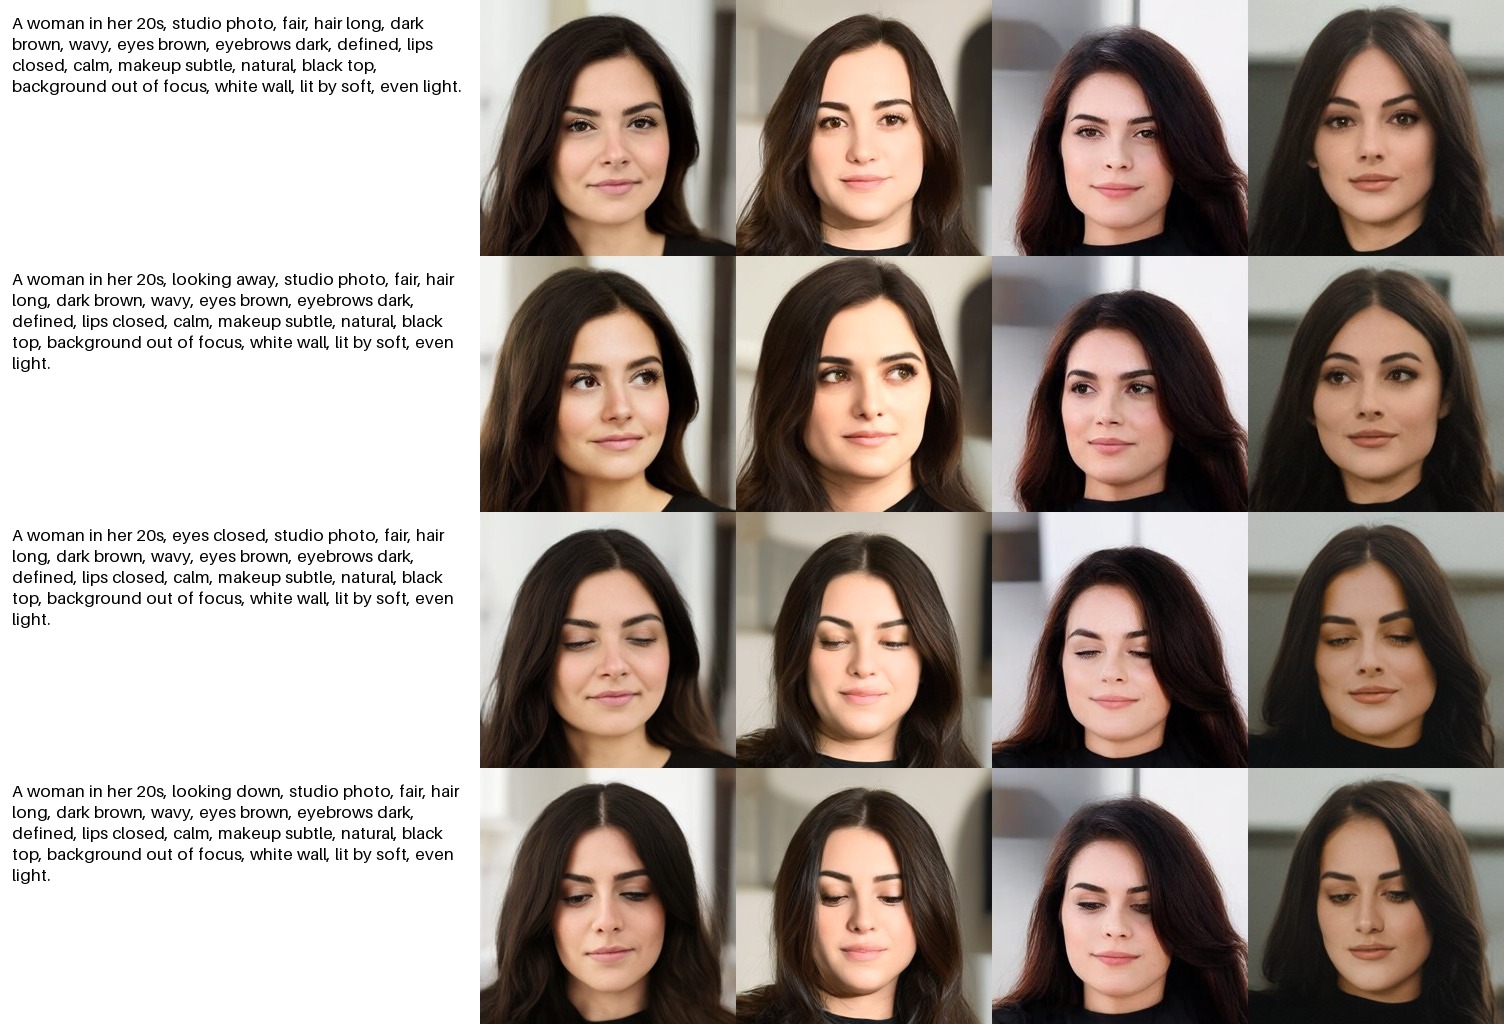
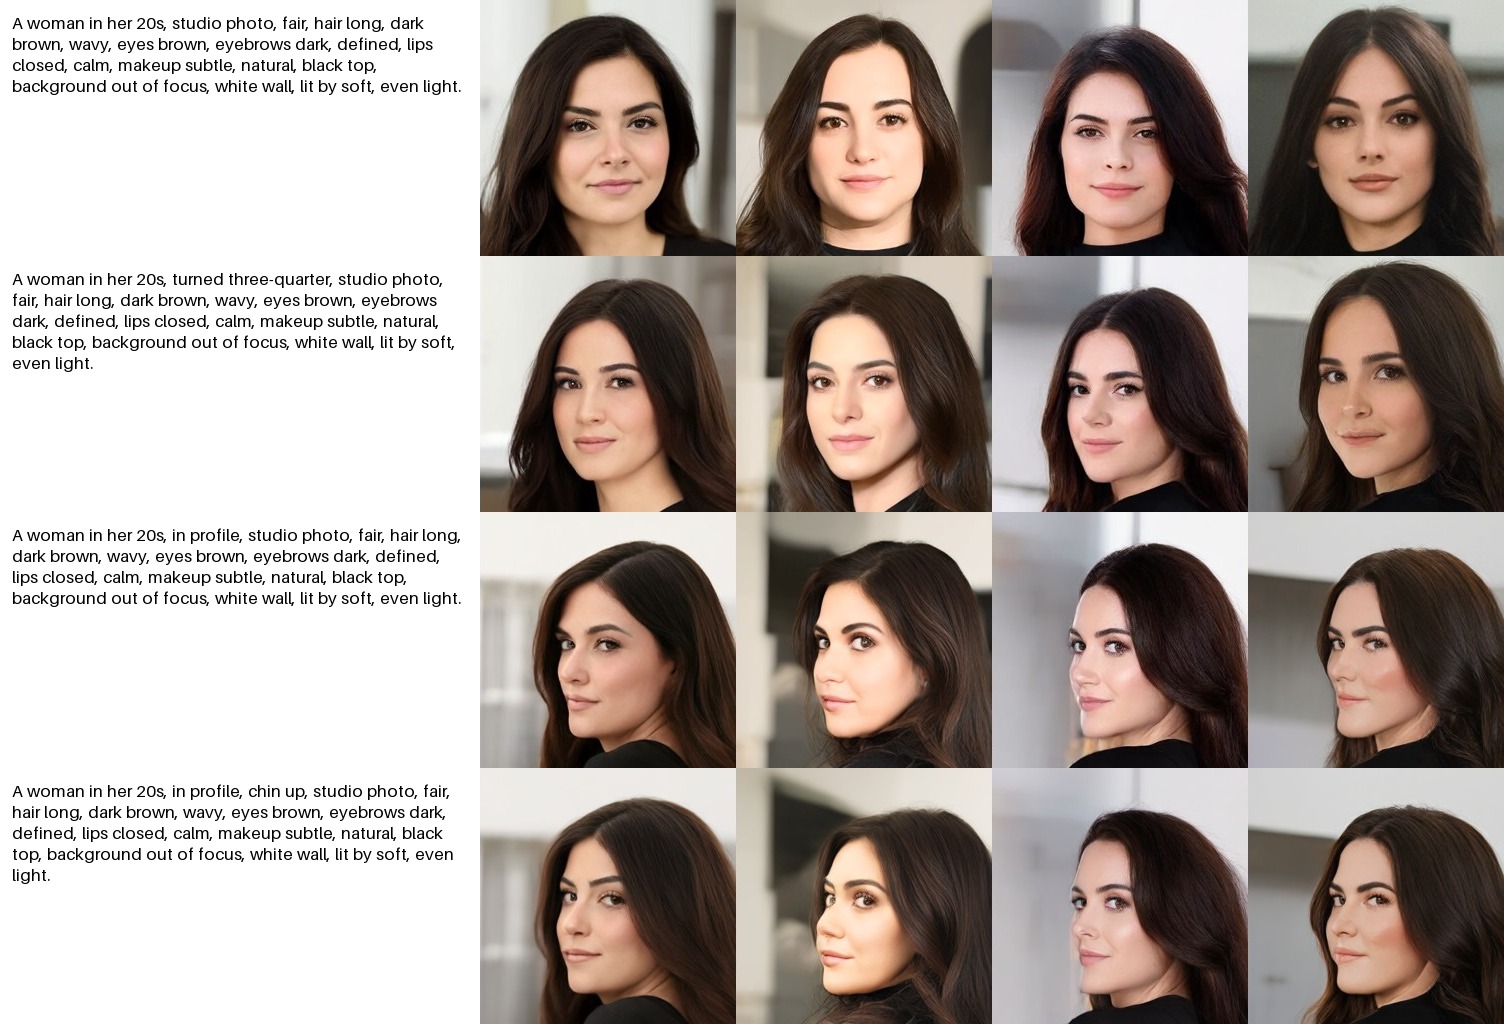
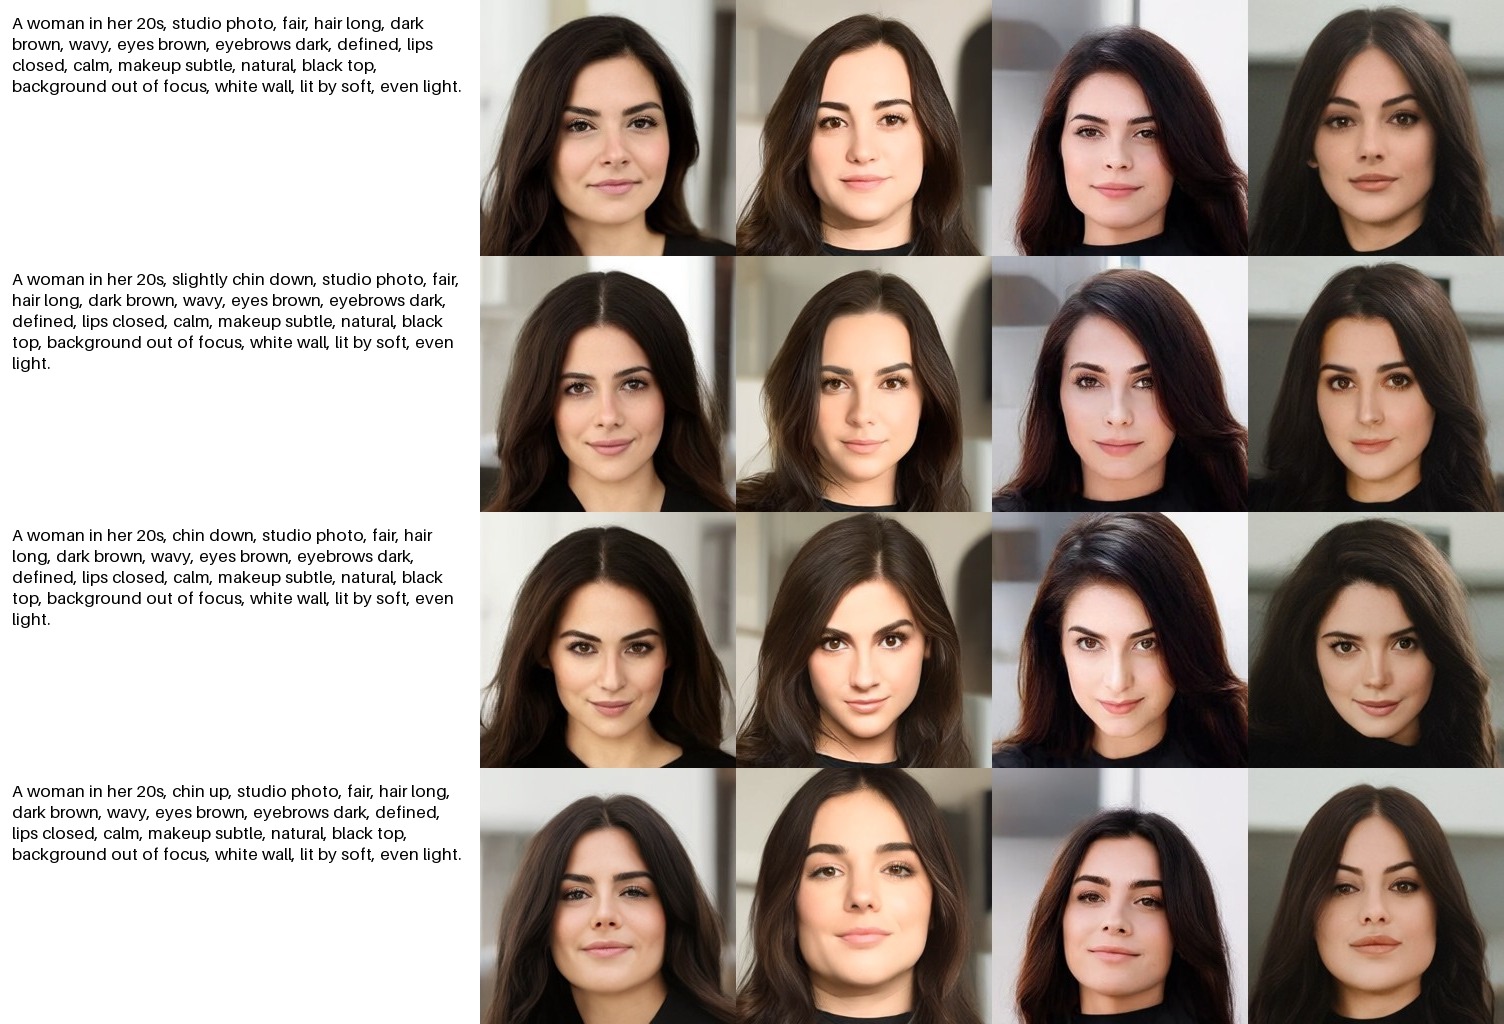
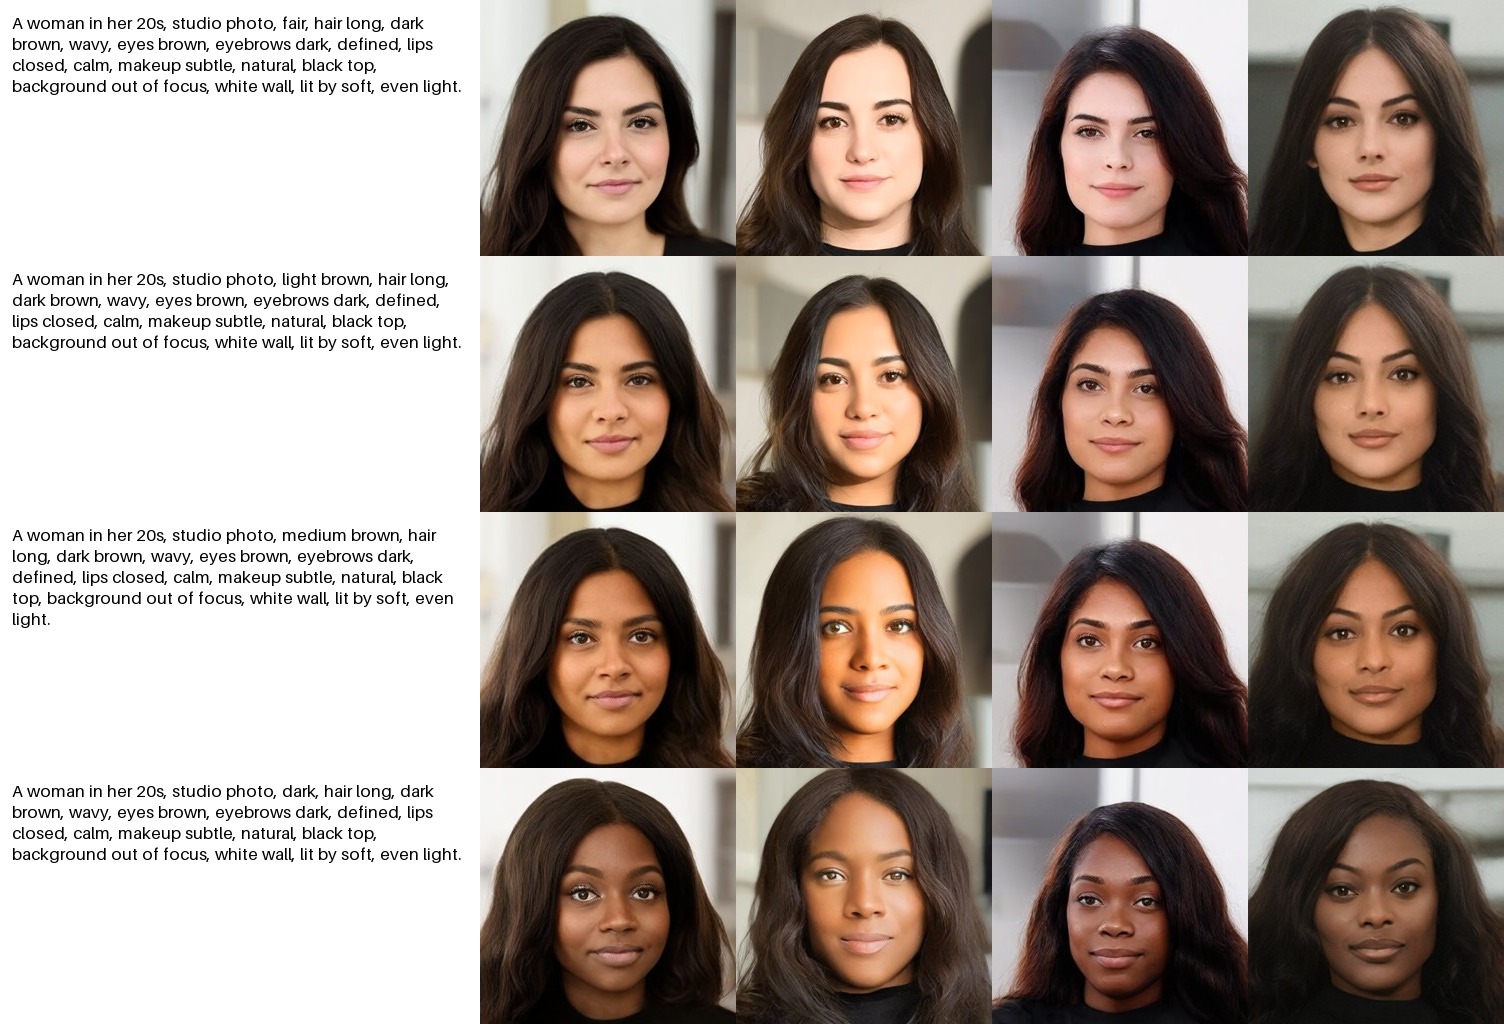
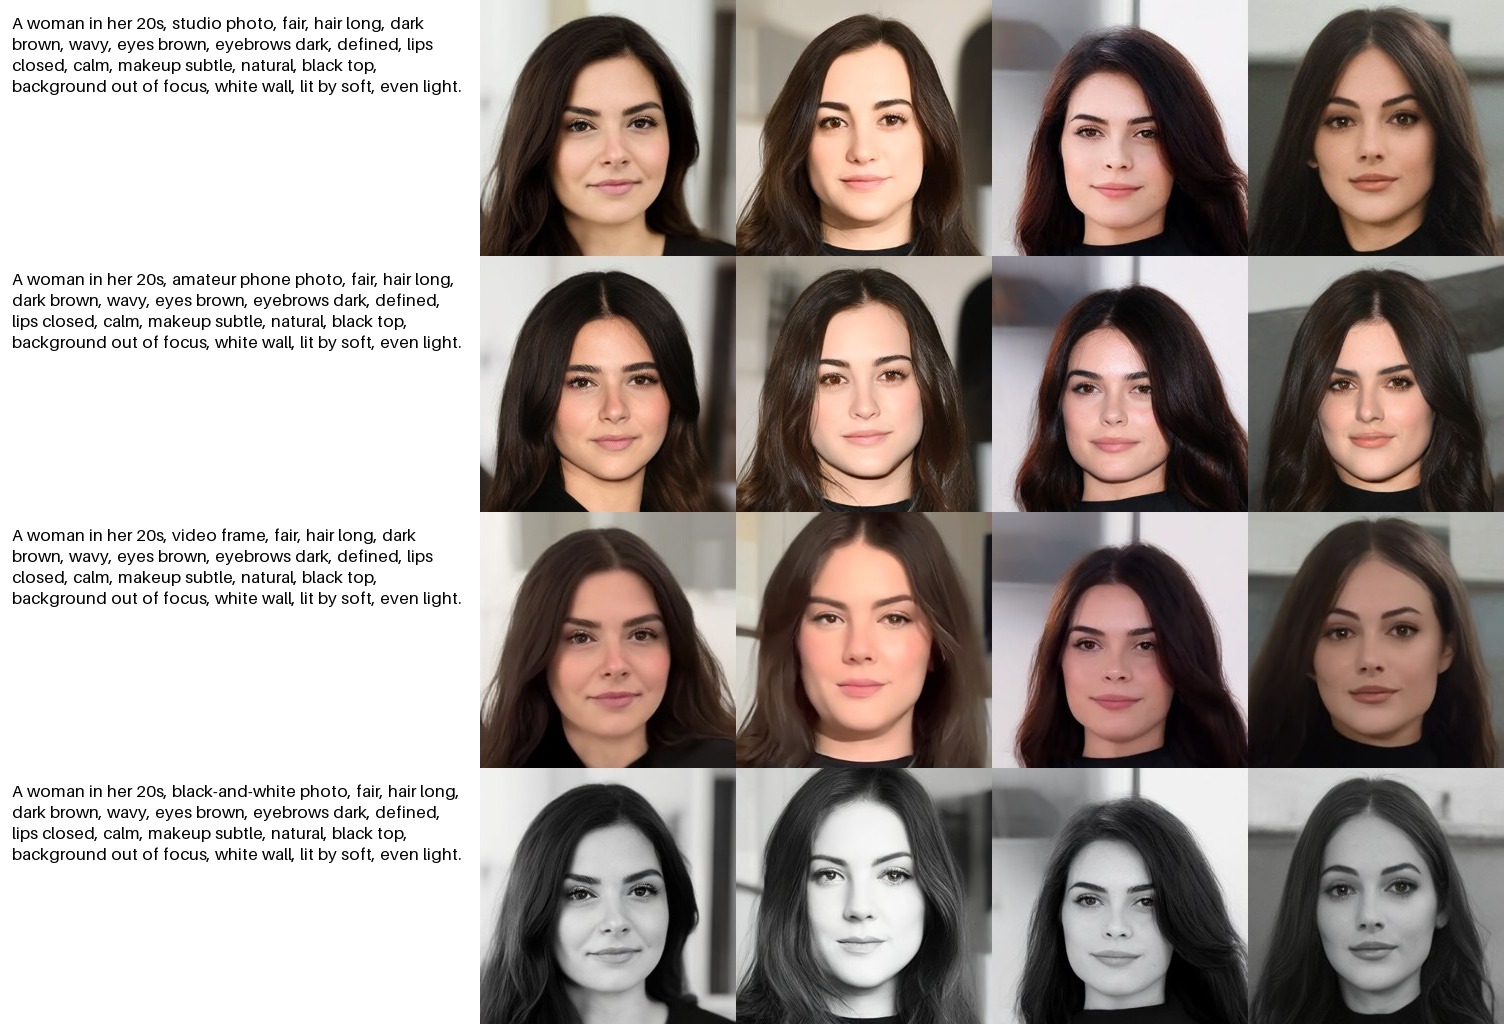
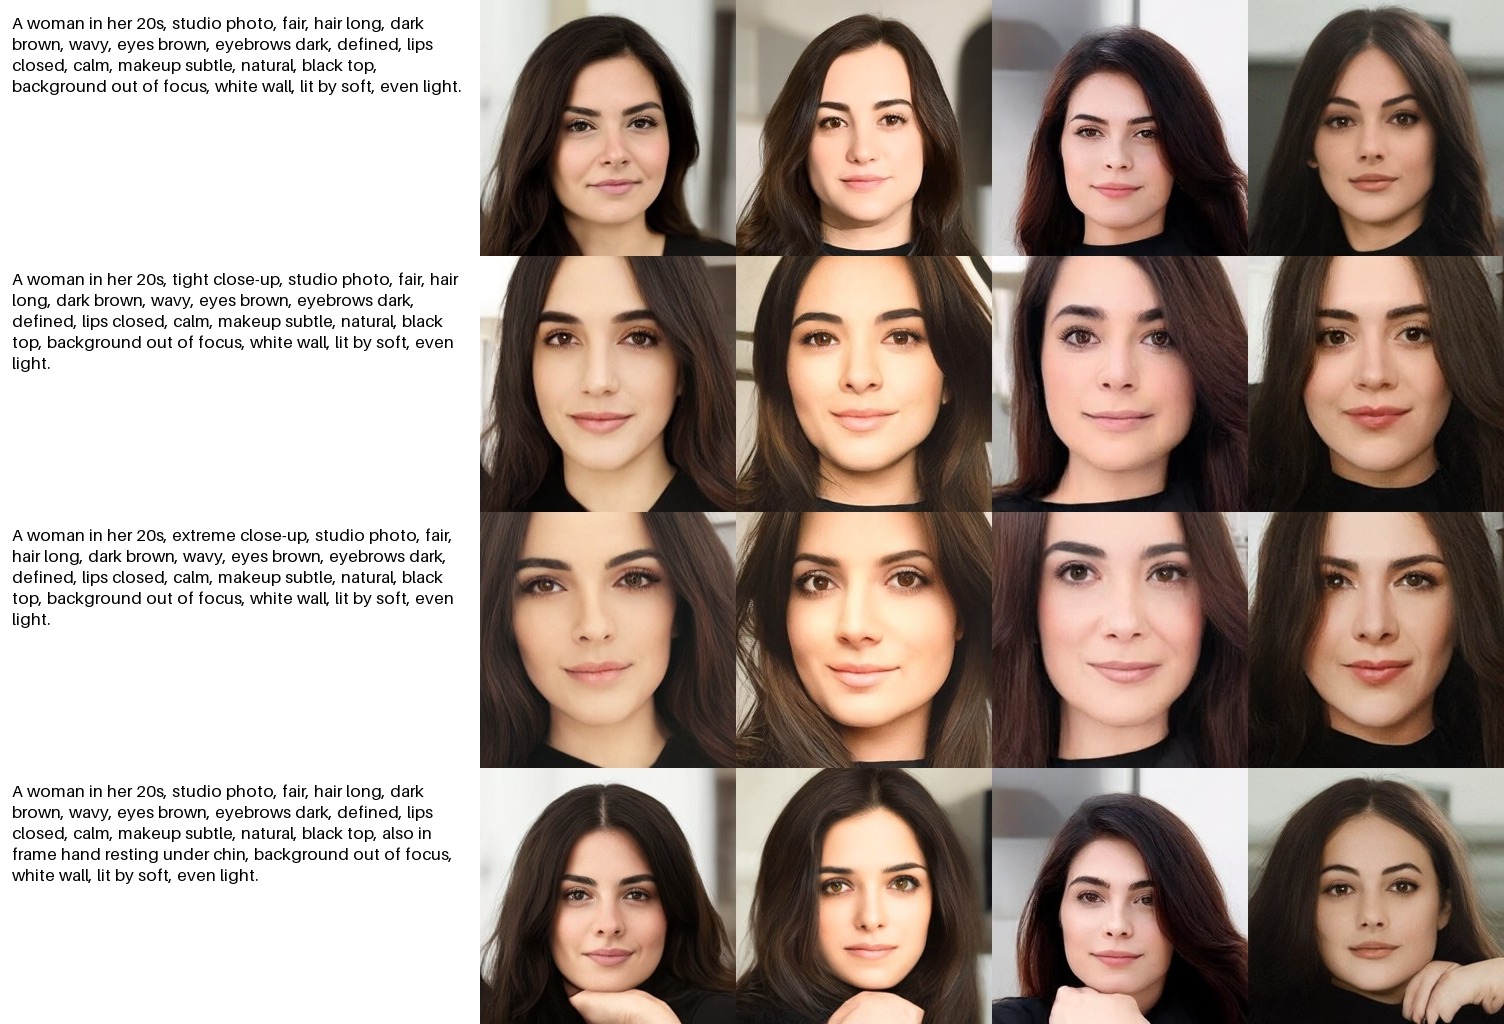
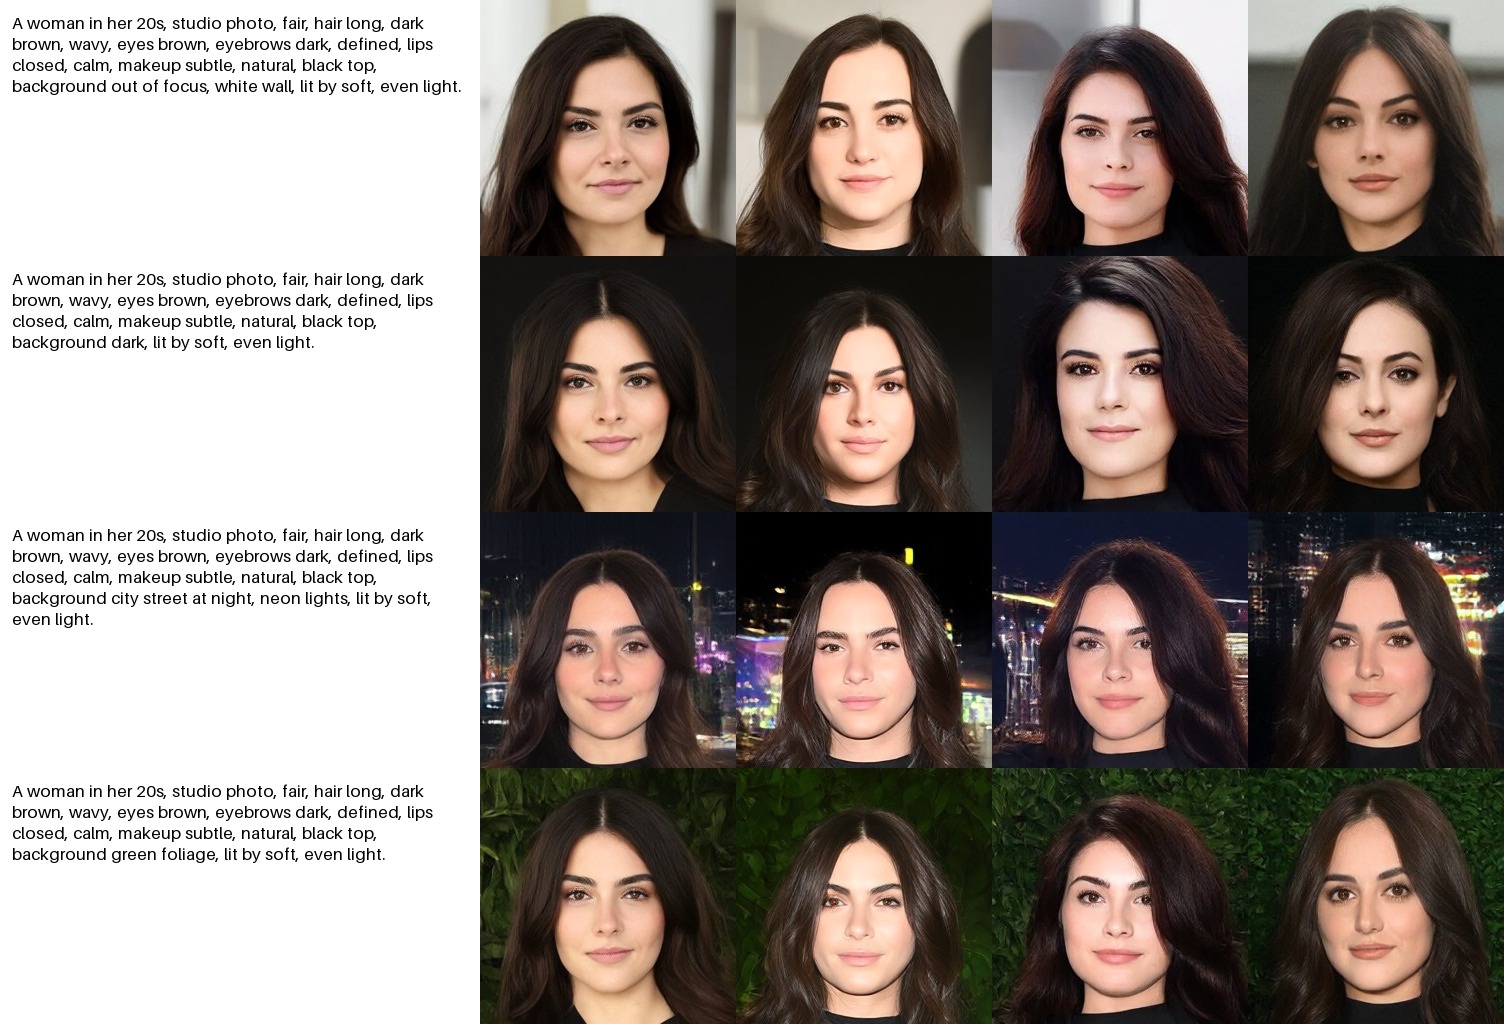
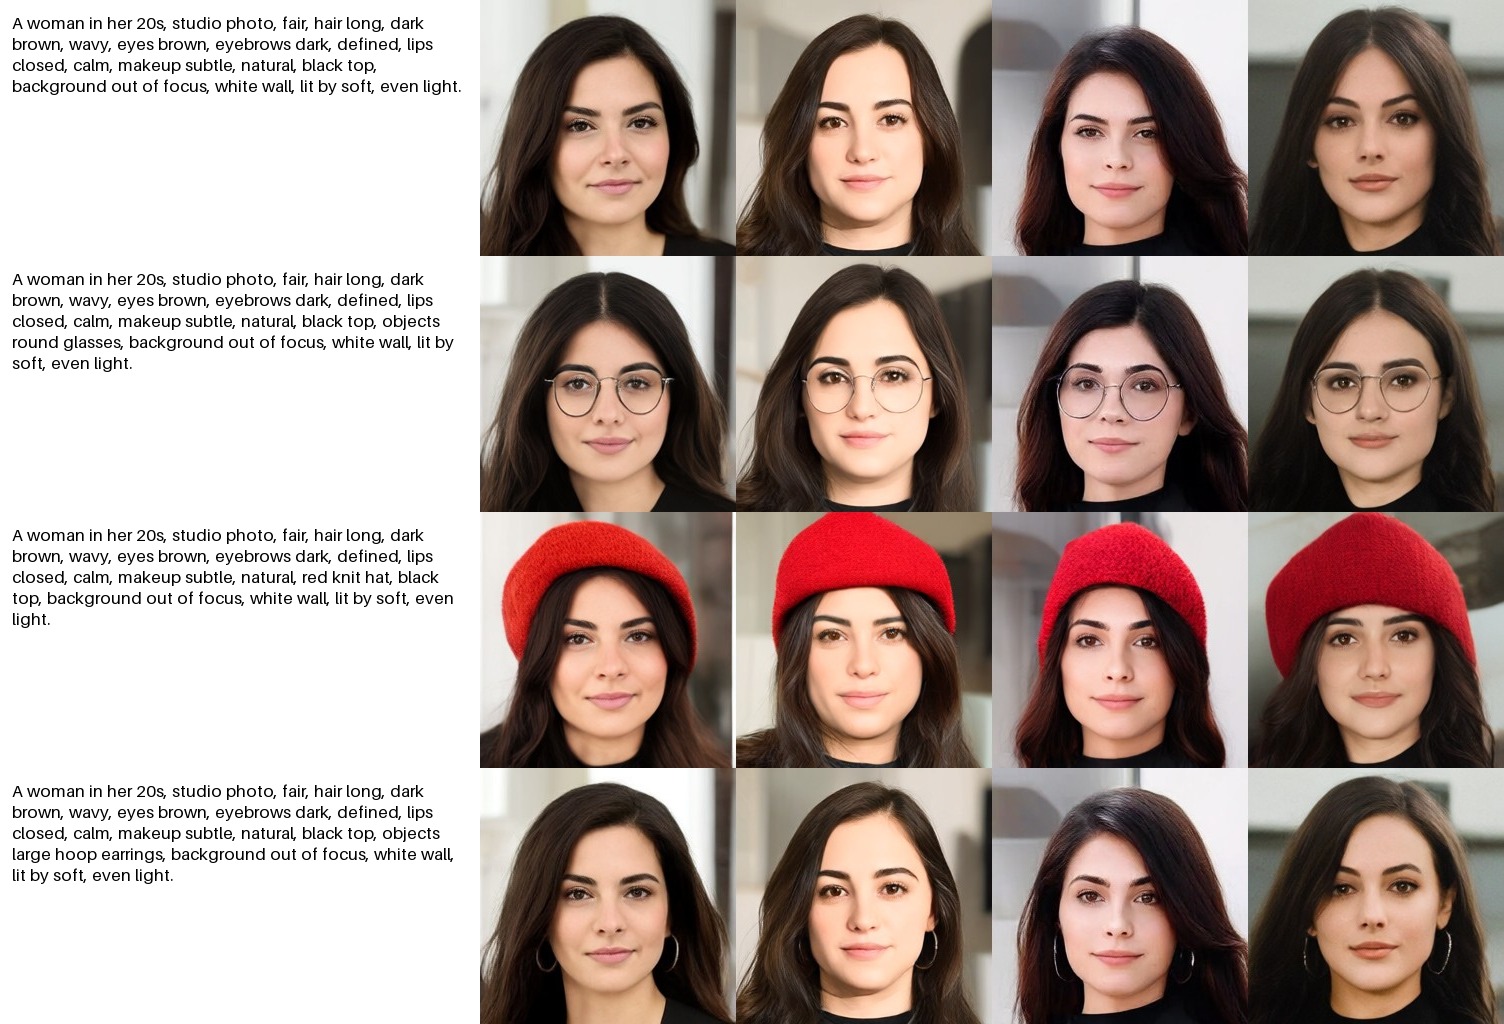
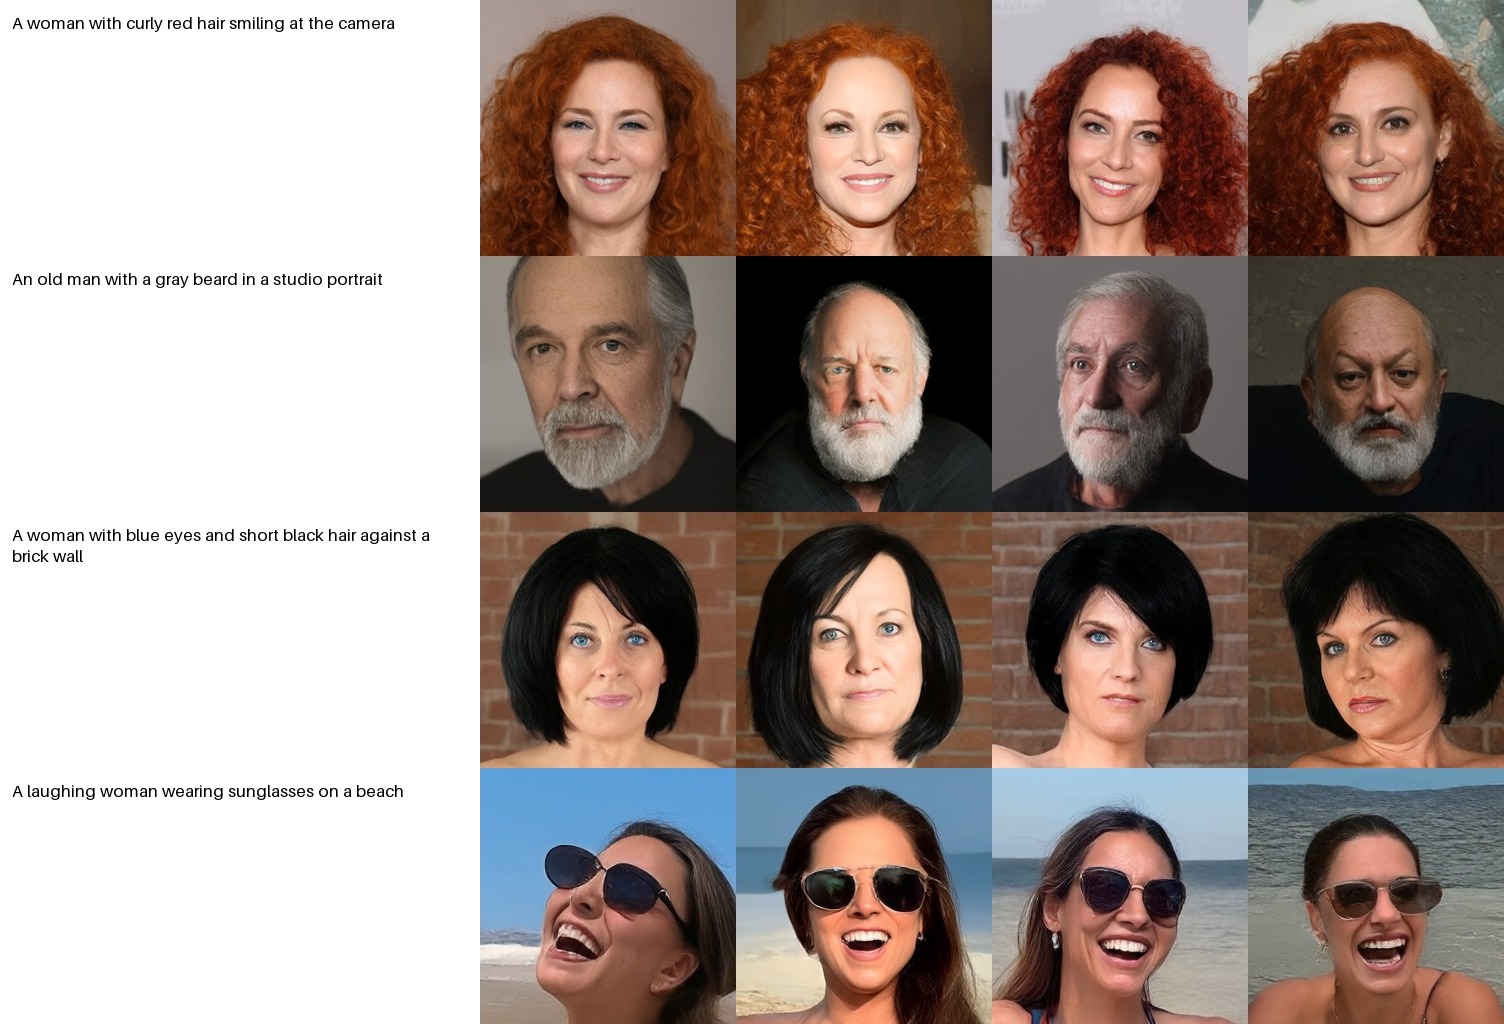
|
| 16 |
-
*.onnx filter=lfs diff=lfs merge=lfs -text
|
| 17 |
-
*.ot filter=lfs diff=lfs merge=lfs -text
|
| 18 |
-
*.parquet filter=lfs diff=lfs merge=lfs -text
|
| 19 |
-
*.pb filter=lfs diff=lfs merge=lfs -text
|
| 20 |
-
*.pickle filter=lfs diff=lfs merge=lfs -text
|
| 21 |
-
*.pkl filter=lfs diff=lfs merge=lfs -text
|
| 22 |
-
*.pt filter=lfs diff=lfs merge=lfs -text
|
| 23 |
-
*.pth filter=lfs diff=lfs merge=lfs -text
|
| 24 |
-
*.rar filter=lfs diff=lfs merge=lfs -text
|
| 25 |
*.safetensors filter=lfs diff=lfs merge=lfs -text
|
| 26 |
-
saved_model/**/* filter=lfs diff=lfs merge=lfs -text
|
| 27 |
-
*.tar.* filter=lfs diff=lfs merge=lfs -text
|
| 28 |
-
*.tar filter=lfs diff=lfs merge=lfs -text
|
| 29 |
-
*.tflite filter=lfs diff=lfs merge=lfs -text
|
| 30 |
-
*.tgz filter=lfs diff=lfs merge=lfs -text
|
| 31 |
-
*.wasm filter=lfs diff=lfs merge=lfs -text
|
| 32 |
-
*.xz filter=lfs diff=lfs merge=lfs -text
|
| 33 |
-
*.zip filter=lfs diff=lfs merge=lfs -text
|
| 34 |
-
*.zst filter=lfs diff=lfs merge=lfs -text
|
| 35 |
-
*tfevents* filter=lfs diff=lfs merge=lfs -text
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
*.safetensors filter=lfs diff=lfs merge=lfs -text
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
LICENSE
ADDED
|
@@ -0,0 +1,202 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
Apache License
|
| 2 |
+
Version 2.0, January 2004
|
| 3 |
+
http://www.apache.org/licenses/
|
| 4 |
+
|
| 5 |
+
TERMS AND CONDITIONS FOR USE, REPRODUCTION, AND DISTRIBUTION
|
| 6 |
+
|
| 7 |
+
1. Definitions.
|
| 8 |
+
|
| 9 |
+
"License" shall mean the terms and conditions for use, reproduction,
|
| 10 |
+
and distribution as defined by Sections 1 through 9 of this document.
|
| 11 |
+
|
| 12 |
+
"Licensor" shall mean the copyright owner or entity authorized by
|
| 13 |
+
the copyright owner that is granting the License.
|
| 14 |
+
|
| 15 |
+
"Legal Entity" shall mean the union of the acting entity and all
|
| 16 |
+
other entities that control, are controlled by, or are under common
|
| 17 |
+
control with that entity. For the purposes of this definition,
|
| 18 |
+
"control" means (i) the power, direct or indirect, to cause the
|
| 19 |
+
direction or management of such entity, whether by contract or
|
| 20 |
+
otherwise, or (ii) ownership of fifty percent (50%) or more of the
|
| 21 |
+
outstanding shares, or (iii) beneficial ownership of such entity.
|
| 22 |
+
|
| 23 |
+
"You" (or "Your") shall mean an individual or Legal Entity
|
| 24 |
+
exercising permissions granted by this License.
|
| 25 |
+
|
| 26 |
+
"Source" form shall mean the preferred form for making modifications,
|
| 27 |
+
including but not limited to software source code, documentation
|
| 28 |
+
source, and configuration files.
|
| 29 |
+
|
| 30 |
+
"Object" form shall mean any form resulting from mechanical
|
| 31 |
+
transformation or translation of a Source form, including but
|
| 32 |
+
not limited to compiled object code, generated documentation,
|
| 33 |
+
and conversions to other media types.
|
| 34 |
+
|
| 35 |
+
"Work" shall mean the work of authorship, whether in Source or
|
| 36 |
+
Object form, made available under the License, as indicated by a
|
| 37 |
+
copyright notice that is included in or attached to the work
|
| 38 |
+
(an example is provided in the Appendix below).
|
| 39 |
+
|
| 40 |
+
"Derivative Works" shall mean any work, whether in Source or Object
|
| 41 |
+
form, that is based on (or derived from) the Work and for which the
|
| 42 |
+
editorial revisions, annotations, elaborations, or other modifications
|
| 43 |
+
represent, as a whole, an original work of authorship. For the purposes
|
| 44 |
+
of this License, Derivative Works shall not include works that remain
|
| 45 |
+
separable from, or merely link (or bind by name) to the interfaces of,
|
| 46 |
+
the Work and Derivative Works thereof.
|
| 47 |
+
|
| 48 |
+
"Contribution" shall mean any work of authorship, including
|
| 49 |
+
the original version of the Work and any modifications or additions
|
| 50 |
+
to that Work or Derivative Works thereof, that is intentionally
|
| 51 |
+
submitted to Licensor for inclusion in the Work by the copyright owner
|
| 52 |
+
or by an individual or Legal Entity authorized to submit on behalf of
|
| 53 |
+
the copyright owner. For the purposes of this definition, "submitted"
|
| 54 |
+
means any form of electronic, verbal, or written communication sent
|
| 55 |
+
to the Licensor or its representatives, including but not limited to
|
| 56 |
+
communication on electronic mailing lists, source code control systems,
|
| 57 |
+
and issue tracking systems that are managed by, or on behalf of, the
|
| 58 |
+
Licensor for the purpose of discussing and improving the Work, but
|
| 59 |
+
excluding communication that is conspicuously marked or otherwise
|
| 60 |
+
designated in writing by the copyright owner as "Not a Contribution."
|
| 61 |
+
|
| 62 |
+
"Contributor" shall mean Licensor and any individual or Legal Entity
|
| 63 |
+
on behalf of whom a Contribution has been received by Licensor and
|
| 64 |
+
subsequently incorporated within the Work.
|
| 65 |
+
|
| 66 |
+
2. Grant of Copyright License. Subject to the terms and conditions of
|
| 67 |
+
this License, each Contributor hereby grants to You a perpetual,
|
| 68 |
+
worldwide, non-exclusive, no-charge, royalty-free, irrevocable
|
| 69 |
+
copyright license to reproduce, prepare Derivative Works of,
|
| 70 |
+
publicly display, publicly perform, sublicense, and distribute the
|
| 71 |
+
Work and such Derivative Works in Source or Object form.
|
| 72 |
+
|
| 73 |
+
3. Grant of Patent License. Subject to the terms and conditions of
|
| 74 |
+
this License, each Contributor hereby grants to You a perpetual,
|
| 75 |
+
worldwide, non-exclusive, no-charge, royalty-free, irrevocable
|
| 76 |
+
(except as stated in this section) patent license to make, have made,
|
| 77 |
+
use, offer to sell, sell, import, and otherwise transfer the Work,
|
| 78 |
+
where such license applies only to those patent claims licensable
|
| 79 |
+
by such Contributor that are necessarily infringed by their
|
| 80 |
+
Contribution(s) alone or by combination of their Contribution(s)
|
| 81 |
+
with the Work to which such Contribution(s) was submitted. If You
|
| 82 |
+
institute patent litigation against any entity (including a
|
| 83 |
+
cross-claim or counterclaim in a lawsuit) alleging that the Work
|
| 84 |
+
or a Contribution incorporated within the Work constitutes direct
|
| 85 |
+
or contributory patent infringement, then any patent licenses
|
| 86 |
+
granted to You under this License for that Work shall terminate
|
| 87 |
+
as of the date such litigation is filed.
|
| 88 |
+
|
| 89 |
+
4. Redistribution. You may reproduce and distribute copies of the
|
| 90 |
+
Work or Derivative Works thereof in any medium, with or without
|
| 91 |
+
modifications, and in Source or Object form, provided that You
|
| 92 |
+
meet the following conditions:
|
| 93 |
+
|
| 94 |
+
(a) You must give any other recipients of the Work or
|
| 95 |
+
Derivative Works a copy of this License; and
|
| 96 |
+
|
| 97 |
+
(b) You must cause any modified files to carry prominent notices
|
| 98 |
+
stating that You changed the files; and
|
| 99 |
+
|
| 100 |
+
(c) You must retain, in the Source form of any Derivative Works
|
| 101 |
+
that You distribute, all copyright, patent, trademark, and
|
| 102 |
+
attribution notices from the Source form of the Work,
|
| 103 |
+
excluding those notices that do not pertain to any part of
|
| 104 |
+
the Derivative Works; and
|
| 105 |
+
|
| 106 |
+
(d) If the Work includes a "NOTICE" text file as part of its
|
| 107 |
+
distribution, then any Derivative Works that You distribute must
|
| 108 |
+
include a readable copy of the attribution notices contained
|
| 109 |
+
within such NOTICE file, excluding those notices that do not
|
| 110 |
+
pertain to any part of the Derivative Works, in at least one
|
| 111 |
+
of the following places: within a NOTICE text file distributed
|
| 112 |
+
as part of the Derivative Works; within the Source form or
|
| 113 |
+
documentation, if provided along with the Derivative Works; or,
|
| 114 |
+
within a display generated by the Derivative Works, if and
|
| 115 |
+
wherever such third-party notices normally appear. The contents
|
| 116 |
+
of the NOTICE file are for informational purposes only and
|
| 117 |
+
do not modify the License. You may add Your own attribution
|
| 118 |
+
notices within Derivative Works that You distribute, alongside
|
| 119 |
+
or as an addendum to the NOTICE text from the Work, provided
|
| 120 |
+
that such additional attribution notices cannot be construed
|
| 121 |
+
as modifying the License.
|
| 122 |
+
|
| 123 |
+
You may add Your own copyright statement to Your modifications and
|
| 124 |
+
may provide additional or different license terms and conditions
|
| 125 |
+
for use, reproduction, or distribution of Your modifications, or
|
| 126 |
+
for any such Derivative Works as a whole, provided Your use,
|
| 127 |
+
reproduction, and distribution of the Work otherwise complies with
|
| 128 |
+
the conditions stated in this License.
|
| 129 |
+
|
| 130 |
+
5. Submission of Contributions. Unless You explicitly state otherwise,
|
| 131 |
+
any Contribution intentionally submitted for inclusion in the Work
|
| 132 |
+
by You to the Licensor shall be under the terms and conditions of
|
| 133 |
+
this License, without any additional terms or conditions.
|
| 134 |
+
Notwithstanding the above, nothing herein shall supersede or modify
|
| 135 |
+
the terms of any separate license agreement you may have executed
|
| 136 |
+
with Licensor regarding such Contributions.
|
| 137 |
+
|
| 138 |
+
6. Trademarks. This License does not grant permission to use the trade
|
| 139 |
+
names, trademarks, service marks, or product names of the Licensor,
|
| 140 |
+
except as required for reasonable and customary use in describing the
|
| 141 |
+
origin of the Work and reproducing the content of the NOTICE file.
|
| 142 |
+
|
| 143 |
+
7. Disclaimer of Warranty. Unless required by applicable law or
|
| 144 |
+
agreed to in writing, Licensor provides the Work (and each
|
| 145 |
+
Contributor provides its Contributions) on an "AS IS" BASIS,
|
| 146 |
+
WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or
|
| 147 |
+
implied, including, without limitation, any warranties or conditions
|
| 148 |
+
of TITLE, NON-INFRINGEMENT, MERCHANTABILITY, or FITNESS FOR A
|
| 149 |
+
PARTICULAR PURPOSE. You are solely responsible for determining the
|
| 150 |
+
appropriateness of using or redistributing the Work and assume any
|
| 151 |
+
risks associated with Your exercise of permissions under this License.
|
| 152 |
+
|
| 153 |
+
8. Limitation of Liability. In no event and under no legal theory,
|
| 154 |
+
whether in tort (including negligence), contract, or otherwise,
|
| 155 |
+
unless required by applicable law (such as deliberate and grossly
|
| 156 |
+
negligent acts) or agreed to in writing, shall any Contributor be
|
| 157 |
+
liable to You for damages, including any direct, indirect, special,
|
| 158 |
+
incidental, or consequential damages of any character arising as a
|
| 159 |
+
result of this License or out of the use or inability to use the
|
| 160 |
+
Work (including but not limited to damages for loss of goodwill,
|
| 161 |
+
work stoppage, computer failure or malfunction, or any and all
|
| 162 |
+
other commercial damages or losses), even if such Contributor
|
| 163 |
+
has been advised of the possibility of such damages.
|
| 164 |
+
|
| 165 |
+
9. Accepting Warranty or Additional Liability. While redistributing
|
| 166 |
+
the Work or Derivative Works thereof, You may choose to offer,
|
| 167 |
+
and charge a fee for, acceptance of support, warranty, indemnity,
|
| 168 |
+
or other liability obligations and/or rights consistent with this
|
| 169 |
+
License. However, in accepting such obligations, You may act only
|
| 170 |
+
on Your own behalf and on Your sole responsibility, not on behalf
|
| 171 |
+
of any other Contributor, and only if You agree to indemnify,
|
| 172 |
+
defend, and hold each Contributor harmless for any liability
|
| 173 |
+
incurred by, or claims asserted against, such Contributor by reason
|
| 174 |
+
of your accepting any such warranty or additional liability.
|
| 175 |
+
|
| 176 |
+
END OF TERMS AND CONDITIONS
|
| 177 |
+
|
| 178 |
+
APPENDIX: How to apply the Apache License to your work.
|
| 179 |
+
|
| 180 |
+
To apply the Apache License to your work, attach the following
|
| 181 |
+
boilerplate notice, with the fields enclosed by brackets "{}"
|
| 182 |
+
replaced with your own identifying information. (Don't include
|
| 183 |
+
the brackets!) The text should be enclosed in the appropriate
|
| 184 |
+
comment syntax for the file format. We also recommend that a
|
| 185 |
+
file or class name and description of purpose be included on the
|
| 186 |
+
same "printed page" as the copyright notice for easier
|
| 187 |
+
identification within third-party archives.
|
| 188 |
+
|
| 189 |
+
Copyright 2026 Nikita Sherstnev
|
| 190 |
+
|
| 191 |
+
Licensed under the Apache License, Version 2.0 (the "License");
|
| 192 |
+
you may not use this file except in compliance with the License.
|
| 193 |
+
You may obtain a copy of the License at
|
| 194 |
+
|
| 195 |
+
http://www.apache.org/licenses/LICENSE-2.0
|
| 196 |
+
|
| 197 |
+
Unless required by applicable law or agreed to in writing, software
|
| 198 |
+
distributed under the License is distributed on an "AS IS" BASIS,
|
| 199 |
+
WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
|
| 200 |
+
See the License for the specific language governing permissions and
|
| 201 |
+
limitations under the License.
|
| 202 |
+
|
README.md
ADDED
|
@@ -0,0 +1,201 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
---
|
| 2 |
+
license: apache-2.0
|
| 3 |
+
library_name: pytorch
|
| 4 |
+
pipeline_tag: text-to-image
|
| 5 |
+
tags: [text-to-image, diffusion, rectified-flow, dit, vae, faces]
|
| 6 |
+
---
|
| 7 |
+
|
| 8 |
+
# Visage-Image
|
| 9 |
+
|
| 10 |
+
**[GitHub](https://github.com/Nikita-Sherstnev/Visage-Image)** · **[Architecture](https://github.com/Nikita-Sherstnev/Visage-Image/blob/main/ARCHITECTURE.md)** · **[Prompting](https://github.com/Nikita-Sherstnev/Visage-Image/blob/main/PROMPTING.md)** · **[Data](https://github.com/Nikita-Sherstnev/Visage-Image/blob/main/DATA.md)**
|
| 11 |
+
|
| 12 |
+
|
| 13 |
+
|
| 14 |
+
## Introduction
|
| 15 |
+
|
| 16 |
+
Visage-Image is a 256px text-to-image model for face generation. It has three parts:
|
| 17 |
+
|
| 18 |
+
- **DiT** (236.8M parameters): a single-stream rectified-flow transformer.
|
| 19 |
+
- **VAE** (128.4M parameters): an f16 autoencoder that turns each 256px image into a 16×16×96 latent.
|
| 20 |
+
- **Text encoder** (frozen, not included): the first 8 layers of [Qwen3-0.6B](https://huggingface.co/Qwen/Qwen3-0.6B), at the hub revision recorded in `text_encoder/config.json`.
|
| 21 |
+
|
| 22 |
+
The code and the weights are released under Apache-2.0.
|
| 23 |
+
|
| 24 |
+
### Highlights
|
| 25 |
+
|
| 26 |
+
**A transformer VAE decoder.** The VAEs that latent diffusion usually runs on (Stable Diffusion, SDXL, FLUX.1/FLUX.2, Qwen-Image, Sana's DC-AE) all decode with convolutions, and their last layers run at full image resolution. The Visage-Image decoder is a ViT. It works on the 16×16 latent grid, splits each token into its 2×2 children for a second ViT stage at 32×32, and emits pixels only at the end, through a linear head that paints each 8×8 patch. Two small residual conv refiners then smooth across patch seams. In a head-to-head test with the encoder and losses held fixed, the ViT decoder beat the conv decoder on every validation metric and trained about 5× faster.
|
| 27 |
+
|
| 28 |
+
**A wavelet encoder.** Following [LiteVAE](https://arxiv.org/abs/2405.14477), the 26M-parameter encoder is given a three-level Haar wavelet pyramid instead of learning frequency decomposition from raw pixels. Two parameter-free shortcuts fold the pixels straight into the deepest stage and into the latent.
|
| 29 |
+
|
| 30 |
+
**No KL.** The latent is deterministic. DINOv2 feature alignment keeps it organised in place of a KL penalty.
|
| 31 |
+
|
| 32 |
+
**The result.** At 25% lower rate (f16×96 against FLUX.2's f8×32), the VAE ties the FLUX.2 VAE on reconstruction, eye detail included, and beats it on iFID. It loses on rFID (see the table below).
|
| 33 |
+
|
| 34 |
+
**A small single-stream DiT.** Text and image tokens share one sequence and one set of weights. Captions come from a mid-layer of a small LLM (layer 8 of Qwen3-0.6B) rather than T5 or CLIP. They are padded with learned per-position embeddings to fixed length buckets, so a sample never depends on what it is batched with. Sixteen register tokens and a 2D spiral RoPE complete the design.
|
| 35 |
+
|
| 36 |
+
[ARCHITECTURE.md](https://github.com/Nikita-Sherstnev/Visage-Image/blob/main/ARCHITECTURE.md) covers each choice, the measurements behind it and what was tried instead.
|
| 37 |
+
|
| 38 |
+
## Quick Start
|
| 39 |
+
|
| 40 |
+
The code is on [GitHub](https://github.com/Nikita-Sherstnev/Visage-Image). The weights in this repository download on first use.
|
| 41 |
+
|
| 42 |
+
```bash
|
| 43 |
+
git clone https://github.com/Nikita-Sherstnev/Visage-Image visage && cd visage
|
| 44 |
+
pip install -e .
|
| 45 |
+
```
|
| 46 |
+
|
| 47 |
+
```python
|
| 48 |
+
import torch
|
| 49 |
+
from torchvision.utils import save_image
|
| 50 |
+
|
| 51 |
+
from visage import load_dit, load_text_encoder, load_vae, sample
|
| 52 |
+
|
| 53 |
+
prompt = "a young woman with long red hair and freckles, soft window light"
|
| 54 |
+
text, mask = load_text_encoder()([prompt] * 4) # Qwen3-0.6B, first 8 layers
|
| 55 |
+
dit = load_dit()
|
| 56 |
+
latents = sample(dit, text, mask, seed=0) # SDE, churn 0.3, CFG 3, 50 steps, shift 3.3
|
| 57 |
+
with torch.no_grad():
|
| 58 |
+
images = load_vae().decode(latents).float()
|
| 59 |
+
save_image((images + 1) / 2, "visage.png", nrow=4, padding=0)
|
| 60 |
+
```
|
| 61 |
+
|
| 62 |
+
Or from the command line: `python scripts/generate.py "<prompt>" --n 4`. [PROMPTING.md](https://github.com/Nikita-Sherstnev/Visage-Image/blob/main/PROMPTING.md) lists the caption format and example prompts.
|
| 63 |
+
|
| 64 |
+
| folder | contents |
|
| 65 |
+
|---|---|
|
| 66 |
+
| `transformer/` | DiT EMA weights, step 222k (220k + 2k adversarial post-training steps), and its config |
|
| 67 |
+
| `vae/` | VAE step 400k, with per-channel latent statistics, and its config |
|
| 68 |
+
| `text_encoder/` | the frozen encoder's record: model, layer, caption length and hub revision; its weights come from [Qwen3-0.6B](https://huggingface.co/Qwen/Qwen3-0.6B) |
|
| 69 |
+
|
| 70 |
+
The text states were stored in float8 (e4m3) during training, and the text encoder rounds through float8 the same way, so inference sees exactly what training saw.
|
| 71 |
+
|
| 72 |
+
## Showcase
|
| 73 |
+
|
| 74 |
+
Most sheets vary one caption slot from row to row; the short sheets use short prompts. The full prompt is printed on the left of each row. Four seeds per row, shared across rows, with the default sampler (SDE, churn 0.3, CFG 3, 50 steps).
|
| 75 |
+
|
| 76 |
+
**expression**
|
| 77 |
+
|
| 78 |
+
|
| 79 |
+
|
| 80 |
+
**age**
|
| 81 |
+
|
| 82 |
+
|
| 83 |
+
|
| 84 |
+
**turn gaze**
|
| 85 |
+
|
| 86 |
+
|
| 87 |
+
|
| 88 |
+
**short common**
|
| 89 |
+
|
| 90 |
+
|
| 91 |
+
|
| 92 |
+
<details>
|
| 93 |
+
<summary>More sample sheets</summary>
|
| 94 |
+
|
| 95 |
+
**hair**
|
| 96 |
+
|
| 97 |
+
|
| 98 |
+
|
| 99 |
+
**eyes**
|
| 100 |
+
|
| 101 |
+
|
| 102 |
+
|
| 103 |
+
**gaze**
|
| 104 |
+
|
| 105 |
+
|
| 106 |
+
|
| 107 |
+
**turn**
|
| 108 |
+
|
| 109 |
+
|
| 110 |
+
|
| 111 |
+
**pitch**
|
| 112 |
+
|
| 113 |
+
|
| 114 |
+
|
| 115 |
+
**skin**
|
| 116 |
+
|
| 117 |
+
|
| 118 |
+
|
| 119 |
+
**photo**
|
| 120 |
+
|
| 121 |
+
|
| 122 |
+
|
| 123 |
+
**shot**
|
| 124 |
+
|
| 125 |
+
|
| 126 |
+
|
| 127 |
+
**background**
|
| 128 |
+
|
| 129 |
+
|
| 130 |
+
|
| 131 |
+
**extras**
|
| 132 |
+
|
| 133 |
+
|
| 134 |
+
|
| 135 |
+
**short**
|
| 136 |
+
|
| 137 |
+
|
| 138 |
+
|
| 139 |
+
</details>
|
| 140 |
+
|
| 141 |
+
## Evaluation
|
| 142 |
+
|
| 143 |
+
### VAE vs FLUX.2 VAE
|
| 144 |
+
|
| 145 |
+
The Visage-Image VAE is f16×96, or 0.375 latent floats per pixel. FLUX.2 is f8×32, or 0.5 floats per pixel, so the Visage-Image VAE works at 25% lower rate. All numbers are at 256px.
|
| 146 |
+
|
| 147 |
+
| metric | Visage-Image VAE | FLUX.2 VAE | |
|
| 148 |
+
|---|---|---|---|
|
| 149 |
+
| whole-image PSNR (512 held-out images) | **38.69** | 38.67 | tie (+0.01 ± 0.05 dB) |
|
| 150 |
+
| whole-image MAE | **0.00802** | 0.00837 | Visage-Image; better on 74% of images |
|
| 151 |
+
| eye-crop PSNR, paired (990 crops) | −0.02 dB | 0 (reference) | tie |
|
| 152 |
+
| iFID ↓ (10,016 images) | **17.96** | 21.99 | Visage-Image |
|
| 153 |
+
| rFID ↓ (10,016 images) | 1.77 | **0.93** | FLUX.2 |
|
| 154 |
+
| parameters | 128.4M | 84.0M | |
|
| 155 |
+
|
| 156 |
+
**The eye-crop metric** is the paired PSNR difference on tight eye crops from images neither VAE was trained on. That's where fine face detail fails first and where whole-image metrics are least sensitive.
|
| 157 |
+
|
| 158 |
+
**iFID** is FID on images decoded from the midpoint between a latent and its nearest neighbour ([arXiv:2603.05630](https://arxiv.org/abs/2603.05630)). It measures latent-space smoothness. It does **not** predict how fast a DiT learns: in short DiT screens trained on each latent, FLUX.2's latent still reaches a lower generation FID (101.3 vs 190.7 for this VAE), despite losing on iFID.
|
| 159 |
+
|
| 160 |
+
**Not at 512px.** The decoder runs at 512, but the quality doesn't carry over: −3.2 dB on eye crops and iFID 28.6 vs 25.5 against FLUX.2. At 128px, rFID rises to 5.46.
|
| 161 |
+
|
| 162 |
+
#### Other properties
|
| 163 |
+
|
| 164 |
+
- **Deterministic latent:** there's no KL term and no sampling. `encode` returns the posterior mean, so there's no noise tax on reconstruction.
|
| 165 |
+
- **DiT-friendly grid:** f16 gives 256 tokens at 256px with patch size 1, so the DiT needs no patchify.
|
| 166 |
+
- **Pre-normalized latents:** per-channel latent statistics are stored in the checkpoint. `encode` returns zero-mean, unit-std latents and `decode` accepts them.
|
| 167 |
+
- **Stable across training:** iFID was 17.73 at 50k, 17.71 at 170k, 17.89 at 230k and 17.96 at 400k steps, while eye-crop PSNR went from −2.27 to −0.02 dB against FLUX.2. Earlier recipes lost latent-space quality as reconstruction improved.
|
| 168 |
+
|
| 169 |
+
### DiT
|
| 170 |
+
|
| 171 |
+
- **Sharp anneal:** ties a casual-prompt fine-tune of the 200k model by eye overall and gives better eyes.
|
| 172 |
+
- **Bare prompts default to sharp.** Sharp training captions carry no sharpness word, and caption dropout draws only from sharp images, so an unspecified prompt defaults to sharp. An earlier internal model needed a "Very sharp," prefix; this one doesn't.
|
| 173 |
+
- **Adversarial post-training is a clear win by eye.** 222k beat 220k 16–0 (4 ties) in a blind A/B on 20 random training-style captions, same seed per pair. The difference is sharpness; conditioning sheets for every prompt slot came out the same. Running it longer (224k, 226k) started to change layout and identity, and the held-out flow loss rose only at high noise, so 222k is the release.
|
| 174 |
+
- **Held-out FID** (2,048 held-out images, default sampler): 22.04 at 222k vs 23.46 at 220k; KID ×10³ 5.15 vs 6.04 (std ~0.3). The adversarial step improved both, by more than the checkpoint-to-checkpoint noise (~0.25 FID).
|
| 175 |
+
- **Attribute benchmark** (28 targets, SigLIP-scored): 77.0% mean pass at 222k (75.8% at 220k). Known weak spots: sunglasses (35%, often drawn pushed up on the head), angry (38%, rendered as yelling rather than a furrowed brow), wet hair (46%).
|
| 176 |
+
|
| 177 |
+
## Training
|
| 178 |
+
|
| 179 |
+
- **VAE:** Charbonnier + 3·LPIPS + 0.4·DINOv2 alignment (Qwen-Image-VAE-2.0 losses), no KL, no GAN. The alignment margins loosen over 200k steps to 0.2 of their slack, then hold. From step 80k, a phase-template penalty removes a faint fixed 2×4 px hatch from the decoder's patch head. Muon on the decoder, horizontal flips, batch 8, 400k steps.
|
| 180 |
+
- **DiT:**
|
| 181 |
+
- rectified flow, logit-normal timesteps with a resolution shift, 20% caption dropout
|
| 182 |
+
- Muon + AdamW, EMA 0.999 every 10 steps, batch 128 (64 × 2 accumulation); step counts, checkpoint names included, count batches of 64
|
| 183 |
+
- 200k steps at 256px from scratch, with long, short and casual prompts mixed 50/50 from step 0
|
| 184 |
+
- then a 20k-step cosine anneal on the sharp and very-sharp images only
|
| 185 |
+
- then 2k steps of latent adversarial post-training ([LADD](https://arxiv.org/abs/2403.12015)-style): a critic made of small trainable heads on blocks 5, 11 and 17 of a frozen copy of the 220k DiT, run on the noised, mean-centred one-step prediction, at weight 0.006 next to the flow loss, flat LR, same sharp subset ([`configs/dit_adversarial.yaml`](https://github.com/Nikita-Sherstnev/Visage-Image/blob/main/configs/dit_adversarial.yaml)).
|
| 186 |
+
- **Compute:** one NVIDIA RTX 5090 (32 GB), about 23 GPU-hours in total.
|
| 187 |
+
- VAE: about 10.5 hours (400k steps at about 10.7 it/s, batch 8)
|
| 188 |
+
- DiT: about 12.5 hours (11 hours for the 200k base run at about 5.1 batches of 64 per second, or about 330 images/s, plus 1.1 hours for the anneal and about 0.3 hours of adversarial post-training), on cached latents and text states
|
| 189 |
+
|
| 190 |
+
Long captions are structured descriptions of the subject: age, pose, gaze, expression, hair, lighting, background. They are rendered from per-image attributes, several of them measured by dedicated models (head pose, gaze, eye closure, age) rather than read off by a VLM. The remaining slots come from Qwen3.5-4B fine-tuned on hand-corrected labels to write the caption format. [DATA.md](https://github.com/Nikita-Sherstnev/Visage-Image/blob/main/DATA.md) has the full pipeline.
|
| 191 |
+
|
| 192 |
+
## Limitations and intended use
|
| 193 |
+
|
| 194 |
+
- **Scope:** trained on face crops at 256px only. It is not a general text-to-image model, and the VAE does not hold up at 512px.
|
| 195 |
+
- **Real people:** captions contain no names, and each identity was capped at 1000 images per training epoch. Prompting with the name of a public figure does not reproduce their face: each seed gives a different person, as it does with no name in the prompt.
|
| 196 |
+
- **Out-of-scope uses:** impersonation, non-consensual intimate imagery, harassment, deceptive media, and any sexual content depicting minors.
|
| 197 |
+
- **Prompt adherence:** pose, gaze and expression follow the prompt less reliably than appearance attributes do. See the attribute benchmark above for known weak spots. For tongues, write "tongue out" or "sticking tongue out"; "tongue visible" mostly fails. "Biting lip" does not work: no training caption describes it.
|
| 198 |
+
|
| 199 |
+
## License
|
| 200 |
+
|
| 201 |
+
The code and the weights are released under [Apache-2.0](LICENSE).
|
text_encoder/config.json
ADDED
|
@@ -0,0 +1,6 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
{
|
| 2 |
+
"name": "Qwen/Qwen3-0.6B",
|
| 3 |
+
"layer": 8,
|
| 4 |
+
"max_length": 128,
|
| 5 |
+
"revision": "c1899de289a04d12100db370d81485cdf75e47ca"
|
| 6 |
+
}
|
transformer/config.json
ADDED
|
@@ -0,0 +1,22 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
{
|
| 2 |
+
"image_size": 16,
|
| 3 |
+
"in_channels": 96,
|
| 4 |
+
"patch_size": 1,
|
| 5 |
+
"width": 768,
|
| 6 |
+
"depth": 18,
|
| 7 |
+
"mlp_ratio": 4,
|
| 8 |
+
"text_dim": 1024,
|
| 9 |
+
"noise_embed_dims": 256,
|
| 10 |
+
"time_min_freq": 0.01,
|
| 11 |
+
"time_max_freq": 100.0,
|
| 12 |
+
"text_length_buckets": [
|
| 13 |
+
32,
|
| 14 |
+
64,
|
| 15 |
+
96,
|
| 16 |
+
128
|
| 17 |
+
],
|
| 18 |
+
"n_text_registers": 16,
|
| 19 |
+
"schedule_shift": 3.3,
|
| 20 |
+
"training_step": 222000,
|
| 21 |
+
"weights": "EMA"
|
| 22 |
+
}
|
transformer/model.safetensors
ADDED
|
@@ -0,0 +1,3 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
version https://git-lfs.github.com/spec/v1
|
| 2 |
+
oid sha256:96b1abd305cb467a36de2d8694049da65dc0381a1d00ec871f26c16a25f10df9
|
| 3 |
+
size 473609504
|
vae/config.json
ADDED
|
@@ -0,0 +1,22 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
{
|
| 2 |
+
"latent_channels": 96,
|
| 3 |
+
"resolution": 256,
|
| 4 |
+
"encoder_widths": [
|
| 5 |
+
120,
|
| 6 |
+
240,
|
| 7 |
+
376,
|
| 8 |
+
496
|
| 9 |
+
],
|
| 10 |
+
"encoder_attention": 2,
|
| 11 |
+
"encoder_attention_f16": 2,
|
| 12 |
+
"decoder_width": 768,
|
| 13 |
+
"decoder_depth": 6,
|
| 14 |
+
"decoder_heads": 12,
|
| 15 |
+
"hires_width": 768,
|
| 16 |
+
"hires_depth": 6,
|
| 17 |
+
"hires_heads": 12,
|
| 18 |
+
"refiner_width": 48,
|
| 19 |
+
"refiner2_width": 96,
|
| 20 |
+
"layer_scale": 0.0001,
|
| 21 |
+
"training_step": 400000
|
| 22 |
+
}
|
vae/model.safetensors
ADDED
|
@@ -0,0 +1,3 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
version https://git-lfs.github.com/spec/v1
|
| 2 |
+
oid sha256:dfa2612f97d051384a7b6d0eb7d292511875b23991e662940bac21571aabbd35
|
| 3 |
+
size 256754148
|