
All Models — Orbit Quant
Collection
Public WaveCut OrbitQuant releases across all model families. Use the family collections to compare variants of the same model. • 35 items • Updated • 1
OrbitQuant 4-bit weights for MiniMax-H3-Image, MiniMax's 33.1B text-to-image and image-editing model that makes images of up to 16 megapixels in 6 steps. The diffusion transformer and the MiniMax-H3 Qwen3-VL text encoder both run 8-bit activations over 4-bit weights. The 4-bit codes were chosen with GPTQ rounding against calibration prompts that are not in the evaluation set. The runtime is the official MiniMax-H3-Image modular pipeline of Diffusers with fused OrbitQuant kernels, and the ComfyUI-OrbitQuant nodes. The download is 27.5 GB. The original needs 135.4 GB: the 66.3 GB transformer and the 66.7 GB text encoder of MiniMax-H3, which it downloads separately.
On one RTX PRO 6000 a 4096×4096 image takes 13.5 s with a 29.8 GiB device peak, and a 2048×2048 image takes 2.4 s. The BF16 original needs 22.4 s and 4.4 s for the same work even when each of its models is resident alone. With model offload the release also runs in 23.4 GiB of free device memory (a simulated 24 GB card).

Left: the BF16 original. Right: this release. Same prompt, seed and size; the panels are downscaled to 1024 pixels wide. LPIPS against the BF16 image is in parentheses (lower is closer, see Quality).
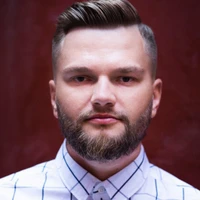
Portrait photograph, 2048×2048 (0.089):

Art Deco travel poster, 1792×2368 (0.163):

Chalkboard menu, 2048×2048 (0.238):

Moscow street with a Cyrillic shop sign, 2368×1792 (0.175):

Fashion editorial, 1792×2368 (0.114):

Infographic poster, 2368×1792 (0.129):

Four-panel comic page, 2048×2048 (0.230):

Editing with the example of the original card. Left to right: the reference, BF16, this release, 2048×2048 (0.015):

16 MP: the frog prompt at 4096×4096 (0.234) and the text-to-image example of the original card at 4736×3552 (0.221):


A 1024×1024 crop of the 4096×4096 frog at full resolution:

Use Linux, Python 3.12 and an NVIDIA GPU. The tested stack is Torch 2.12.1 with CUDA 13.0 on an RTX PRO 6000 Blackwell.
python3.12 -m venv .venv && . .venv/bin/activate
pip install torch==2.12.1 torchvision==0.27.1 --index-url https://download.pytorch.org/whl/cu130
pip install huggingface_hub
hf download WaveCut/MiniMax-H3-Image-OrbitQuant-W4A8 --local-dir minimax-h3-image-orbitquant
cd minimax-h3-image-orbitquant
pip install -r requirements.txt
requirements.txt installs orbitquant 0.18.0 and Diffusers at the commit of the MiniMax-H3-Image pull request. The repository holds every component; nothing else is downloaded.
Text to image:
python run_minimax_h3_image.py --prompt-file prompt.txt --size 4096x4096 --out image.png
Image editing (the references are <Picture 1>, <Picture 2>, ... in the prompt, in the order of --image):
python run_minimax_h3_image.py --prompt-file edit.txt --image reference1.png --size 4096x4096 --out edit.png
Python, inside minimax-h3-image-orbitquant:
import torch
from minimax_h3_image_orbitquant import load_pipeline

pipe = load_pipeline(".")  # offload=True keeps the models in host memory; attention="int8" for INT8 attention
image = pipe(prompt=open("prompt.txt").read(), height=4096, width=4096,
             generator=torch.Generator().manual_seed(42), output="images")[0]
image.save("image.png")
load_pipeline returns the official ModularPipeline with the W4A8 transformer and text encoder. Pass image= (one PIL image or a list) for editing. Options of run_minimax_h3_image.py:
--profile offload: keep the models in host memory; each moves to the GPU for its own stage.--profile int8-attention: INT8 Q·K attention. At 4096×4096 it is 4 % faster (13.0 s against 13.5 s); the mean LPIPS against BF16 rises from 0.182 to 0.195 (see Quality).--size WIDTHxHEIGHT (multiples of 32), --seed, --image (repeat for more references, up to 16).The model is distilled to 6 steps without classifier-free guidance; the release supports only that schedule (the transformer stores the modulation of its six timesteps, see Components). Sizes follow the original: about 4 to 20 MP, best at about 16 MP (4096×4096, 4736×3552, 5024×3360, 5472×3072, 6272×2688 and their portrait versions). The model expects a detailed English description of the whole image. Short prompts give plain images. The original card describes how to write one with the MiniMax API or the local MiniMax-H3-Image-PE prompt expander.
ComfyUI-OrbitQuant 0.11.0 or later lists this release as WaveCut/MiniMax-H3-Image-OrbitQuant-W4A8.
Connect OrbitQuant Model Loader to OrbitQuant Generate Image and save the result with the standard Save Image node. Connect up to 16 images to reference_images for editing.
The generator runs in the Python environment that python_executable selects. Install the packages of the Usage section there.
Checked through ComfyUI v0.44.0's queue on the RTX PRO 6000 (frog prompt, 6 steps). Device memory is the NVML total and includes the 1.2 GiB of the idle ComfyUI server; times include loading when a request starts the worker or changes the profile.
| Request | Profile, worker | Device memory peak | Time |
|---|---|---|---|
| Text to image, 2048×2048, first request | default, kept | 29.8 GiB | 16.2 s |
| Text to image, 2048×2048, next request | default, kept | 29.8 GiB | 5.1 s |
| Edit with one reference, 2048×2048 | default, kept | 34.6 GiB | 9.1 s |
| Text to image, 4096×4096 | default, kept | not separated | 24.2 s |
| Text to image, 2048×2048, profile change | int8-attention, kept | not separated | 11.1 s |
| Text to image, 2048×2048 | model-offload, new worker | not separated | 35.6 s |
ComfyUI times include the PNG encoding in the worker and in Save Image. The first text-to-image image, the edit and the model-offload image were pixel-identical to the output of run_minimax_h3_image.py for the same prompt, image and seed.
The evaluation set has 16 text-to-image prompts (photographs, posters and signs with Latin and Cyrillic text, an ink painting, pixel art, a 3D render, a comic page; 1792×2368 to 2752×1536) and 2 edits. None of them is a calibration prompt. Each case ran with the same prompt, seed and size through the BF16 original and through each quantized variant. LPIPS (AlexNet, both images resized to 1024 pixels wide) and PSNR (full resolution) compare each image with the BF16 image.
| Variant | Mean LPIPS ↓ | Mean PSNR, dB ↑ |
|---|---|---|
| Round to nearest (the first proof of concept) | 0.302 | 16.93 |
| GPTQ, this release | 0.182 | 20.07 |
| GPTQ, INT8 attention | 0.195 | 19.72 |
GPTQ rounding lowered LPIPS on 17 of the 18 cases. LPIPS against BF16 measures the distance from the original image, not the quality of the image. With six steps and no guidance, a small change early in sampling can move the composition. The largest value, 0.604, is e12 (pixel-art bedroom): the W4A8 image mirrors the layout of the room, and keeps its objects and the pixel-art style.

| Case | Subject | Size | Round to nearest | GPTQ | GPTQ, INT8 attention |
|---|---|---|---|---|---|
| e01 | Portrait photograph | 2048×2048 | 0.246 / 18.3 | 0.089 / 24.0 | 0.077 / 24.9 |
| e02 | Bookstore interior | 2368×1792 | 0.425 / 13.5 | 0.157 / 18.9 | 0.168 / 18.5 |
| e03 | Art Deco travel poster | 1792×2368 | 0.484 / 10.6 | 0.163 / 16.7 | 0.395 / 12.1 |
| e04 | Macro photograph of a frog | 2048×2048 | 0.323 / 14.9 | 0.203 / 17.3 | 0.217 / 17.0 |
| e05 | Astronaut on Mars | 2752×1536 | 0.164 / 22.3 | 0.114 / 24.2 | 0.096 / 25.0 |
| e06 | Chalkboard menu with lettering | 2048×2048 | 0.455 / 13.2 | 0.238 / 16.1 | 0.234 / 15.9 |
| e07 | Chinese ink painting | 1792×2368 | 0.362 / 15.3 | 0.186 / 19.4 | 0.186 / 19.3 |
| e08 | Moscow street, Cyrillic shop sign | 2368×1792 | 0.306 / 14.8 | 0.175 / 17.9 | 0.200 / 17.6 |
| e09 | Isometric 3D island | 2048×2048 | 0.268 / 17.6 | 0.228 / 18.8 | 0.228 / 18.4 |
| e10 | Fashion editorial | 1792×2368 | 0.505 / 11.8 | 0.114 / 22.7 | 0.121 / 21.6 |
| e11 | Highland cattle in mist | 2752×1536 | 0.149 / 20.4 | 0.124 / 21.0 | 0.122 / 21.1 |
| e12 | Pixel-art bedroom | 2048×2048 | 0.446 / 14.0 | 0.604 / 12.1 | 0.610 / 12.1 |
| e13 | Infographic poster with captions | 2368×1792 | 0.219 / 15.0 | 0.129 / 16.6 | 0.128 / 16.9 |
| e14 | Old woman knitting | 1792×2368 | 0.402 / 16.7 | 0.331 / 18.5 | 0.305 / 18.8 |
| e15 | Thunderstorm over a field | 2752×1536 | 0.241 / 20.2 | 0.159 / 21.8 | 0.167 / 21.6 |
| e16 | Four-panel comic page | 2048×2048 | 0.357 / 12.8 | 0.230 / 14.8 | 0.224 / 15.0 |
| x01 | Edit: the example of the original card | 2048×2048 | 0.037 / 29.8 | 0.015 / 32.8 | 0.018 / 31.3 |
| x02 | Edit of the bookstore image (e02) | 2368×1792 | 0.048 / 23.6 | 0.025 / 27.6 | 0.024 / 27.7 |
Setup: one RTX PRO 6000 Blackwell Server Edition (96 GB), Torch 2.12.1, CUDA 13.0, the frog prompt (e04, 123 text tokens), 6 steps. Each configuration ran in its own process: a warm-up image, then the best of 2–3 images. The time runs from the pipeline call to the finished image tensor on the GPU: prompt encoding, six transformer steps and VAE decoding. The conversion to a PIL image is excluded: on the rented machine, memory pressure from other tenants made host-side work on 16 MP arrays slow and irregular.
| Configuration | 2048×2048 | 4096×4096 | Device peak, 4096×4096 |
|---|---|---|---|
| BF16 original, Diffusers model offload | 124.6 s | 136.5 s | 68.0 GiB |
| BF16 original, sum of the components resident alone | 4.38 s | 22.35 s | 66.4 GiB |
| OrbitQuant W4A8 | 2.40 s | 13.53 s | 29.8 GiB |
| OrbitQuant W4A8, INT8 attention | 2.43 s | 13.01 s | 29.8 GiB |
| OrbitQuant W4A8, simulated 32 GB card | 2.42 s | 13.64 s | 29.6 GiB |
| OrbitQuant W4A8, model offload, simulated 24 GB card | 13.95 s | 25.31 s | 17.2 GiB |
enable_auto_cpu_offload of the Diffusers components manager. It copies each model to the GPU for its stage; on this machine the copies were slow, so the offload times are upper bounds.Components, each resident alone:
| Component | BF16 original | This release | Speed-up |
|---|---|---|---|
| Transformer, 6 steps, 2048×2048 (4,219 tokens) | 3.59 s, 63.9 GiB | 2.16 s, 19.8 GiB | 1.66× |
| Transformer, 6 steps, 4096×4096 (16,507 tokens) | 19.62 s, 66.4 GiB | 12.99 s, 19.8 GiB | 1.51× |
| Transformer with INT8 attention, 2048×2048 / 4096×4096 | 2.18 s / 12.36 s | 1.64× / 1.59× | |
| Text encoder, 123 tokens | 0.065 s (64 layers) | 0.055 s (50 layers) | 1.17× |
| VAE decoding, 2048×2048 / 4096×4096 | 0.73 s / 2.66 s | 0.16 s / 0.58 s | 4.7× / 4.6× |
| VAE encoding of a reference, 2048×2048 / 4096×4096 | 1.15 s / 4.20 s | 0.41 s / 1.49 s | 2.8× / 2.8× |
The VAE weights are unchanged; the speed-up comes from the batched tiles of the loader (see Components). The batched convolutions use other cuDNN algorithms, so the decoded pixels differ from the per-tile loop by at most 5–7 levels of 255 (about 11 % of the pixels change).
Editing (x01, one reference image):
| Configuration | Time | Device peak |
|---|---|---|
| BF16 original, Diffusers model offload, 2048×2048 | 134.7 s | 66.6 GiB |
| OrbitQuant W4A8, 2048×2048 | 4.54 s | 33.2 GiB (29.9 GiB allocated) |
| OrbitQuant W4A8, 4096×4096, simulated 32 GB card | 17.23 s | 31.9 GiB |
On the 96 GB card the PyTorch allocator keeps freed blocks cached, so the NVML peak is above the allocated peak. On the simulated 32 GB card the allocator reuses them, and the 4096×4096 edit runs resident.
| Component | Original | This release | Size |
|---|---|---|---|
| Transformer | 33.1B parameters, BF16 | The 312 attention and feed-forward projections of the 50 blocks and the 2 token-refiner blocks: 4-bit OrbitQuant weights (RPBH rotation, Lloyd-Max codes, GPTQ rounding), INT8 activations. The per-block AdaLN projections, the timestep MLP and the output-norm projection (13.0B parameters) are replaced by their outputs for the 6 sampling timesteps and the reference-image noise level. Embedders, norms and the output heads stay BF16 or FP32. | 10.2 GB (66.3 GB) |
| Text encoder | MiniMax-H3 Qwen3-VL, 64 decoder layers, BF16 | The pipeline reads the hidden state after layer 49, so layers 50–63 and the language-model head are removed. Layers 0–49: 4-bit OrbitQuant weights with GPTQ rounding, INT8 activations. Token embeddings and the vision tower stay BF16. | 14.9 GB (66.7 GB) |
| VAE | BF16 | Unchanged weights. The loader runs its 256-pixel tiles in batches of 32 instead of one at a time, and the image encoder's causal 3D convolutions as 2D convolutions (one frame: the other kernel slices multiply zero padding). | 2.3 GB |
| Tokenizer, processor, scheduler | Unchanged. |
GPTQ used 90 transformer calls (12 text-to-image and 3 editing prompts at the six timesteps) and 72,619 text-encoder tokens (the calibration prompts and image captions). None of the calibration prompts is in the evaluation set.
The rounding lowered the mean relative output error of a projection group from 0.0059 (round to nearest) to 0.00081 in the transformer and from 0.0044 to 0.00095 in the text encoder (quantization-report.json in each folder). The text encoder's hidden state 50, which the transformer reads, differs from the BF16 original by 1.2–2.0 % (relative L2) on 8 evaluation prompts, against 4.3–4.8 % with round to nearest.
transformer/: the packed transformer (model.safetensors), its OrbitQuant configuration and manifest, modulation.json (the tabulated timesteps), the original config.json and quantization-report.json (the error of each projection group before and after GPTQ rounding).text_encoder/: the quantized MiniMax-H3 text encoder (decoder layers 0–49, the vision tower) and its quantization-report.json.vae/, tokenizer/, processor/, scheduler/, modular_model_index.json: the original components in the Diffusers layout.minimax_h3_image_orbitquant.py: the loader. run_minimax_h3_image.py: the command-line entry point. requirements.txt: the runtime pins.manifest.json: the components, the source revisions and the runtime pins. SHA256SUMS: the checksums of all files.LICENSE, LICENSE-MiniMax-H3, NOTICE: the license agreements and the notice of the modified files.assets/: the chart and images of this card.--profile offload in 23.4 GiB. Offloaded edits, edits with more reference images and real 32 GB or 24 GB cards were not tested. Other GPUs were not tested.This release is a quantized version of MiniMax-H3-Image and of the MiniMax-H3 text encoder by MiniMax. MiniMax did not create, endorse or validate this release.
MiniMax-H3-Image is licensed under the MiniMax-H3-Image Community License Agreement, Copyright © 2026 MiniMax. All Rights Reserved.
MiniMax H3 is licensed under the MiniMax H3 Community License Agreement, Copyright © 2026 MiniMax. All Rights Reserved.
The agreements (LICENSE, LICENSE-MiniMax-H3) apply to this release unchanged. They cover use only outside the European Union, the United Kingdom, the Republic of Korea and the United States of America. A licensee with more than USD 1 million of annualized revenue, or one that offers a hosted service to third parties, needs a separate written authorization from MiniMax (platform.minimax.io/license), and a commercial product must display "MiniMax-H3-Image" in its user interface. NOTICE lists the modified files.