| --- |
| library_name: transformers |
| base_model: Qwen/Qwen3.5-9B |
| base_model_relation: finetune |
| language: |
| - en |
| tags: |
| - coer |
| - agent-security |
| - research |
| --- |
| |
| # CoER Defender |
|
|
| [Project page](https://ilianzby.github.io/CoER/) · [Paper](https://arxiv.org/abs/2609.07529) · [Code](https://github.com/ILIANZBY/CoER) |
|
|
| The **final CoER defender**, refined from Co-PPO d430 at Defender-SFT update 360. It is trained to complete legitimate tool-use tasks safely under adaptive indirect prompt injection. |
|
|
| **Download available.** All 70 safetensors shards are uploaded and match their upload manifests; configuration, tokenizer and weight-index files are present. File verification is complete; GPU loading and inference have not been tested as part of this release check. |
|
|
|  |
|
|
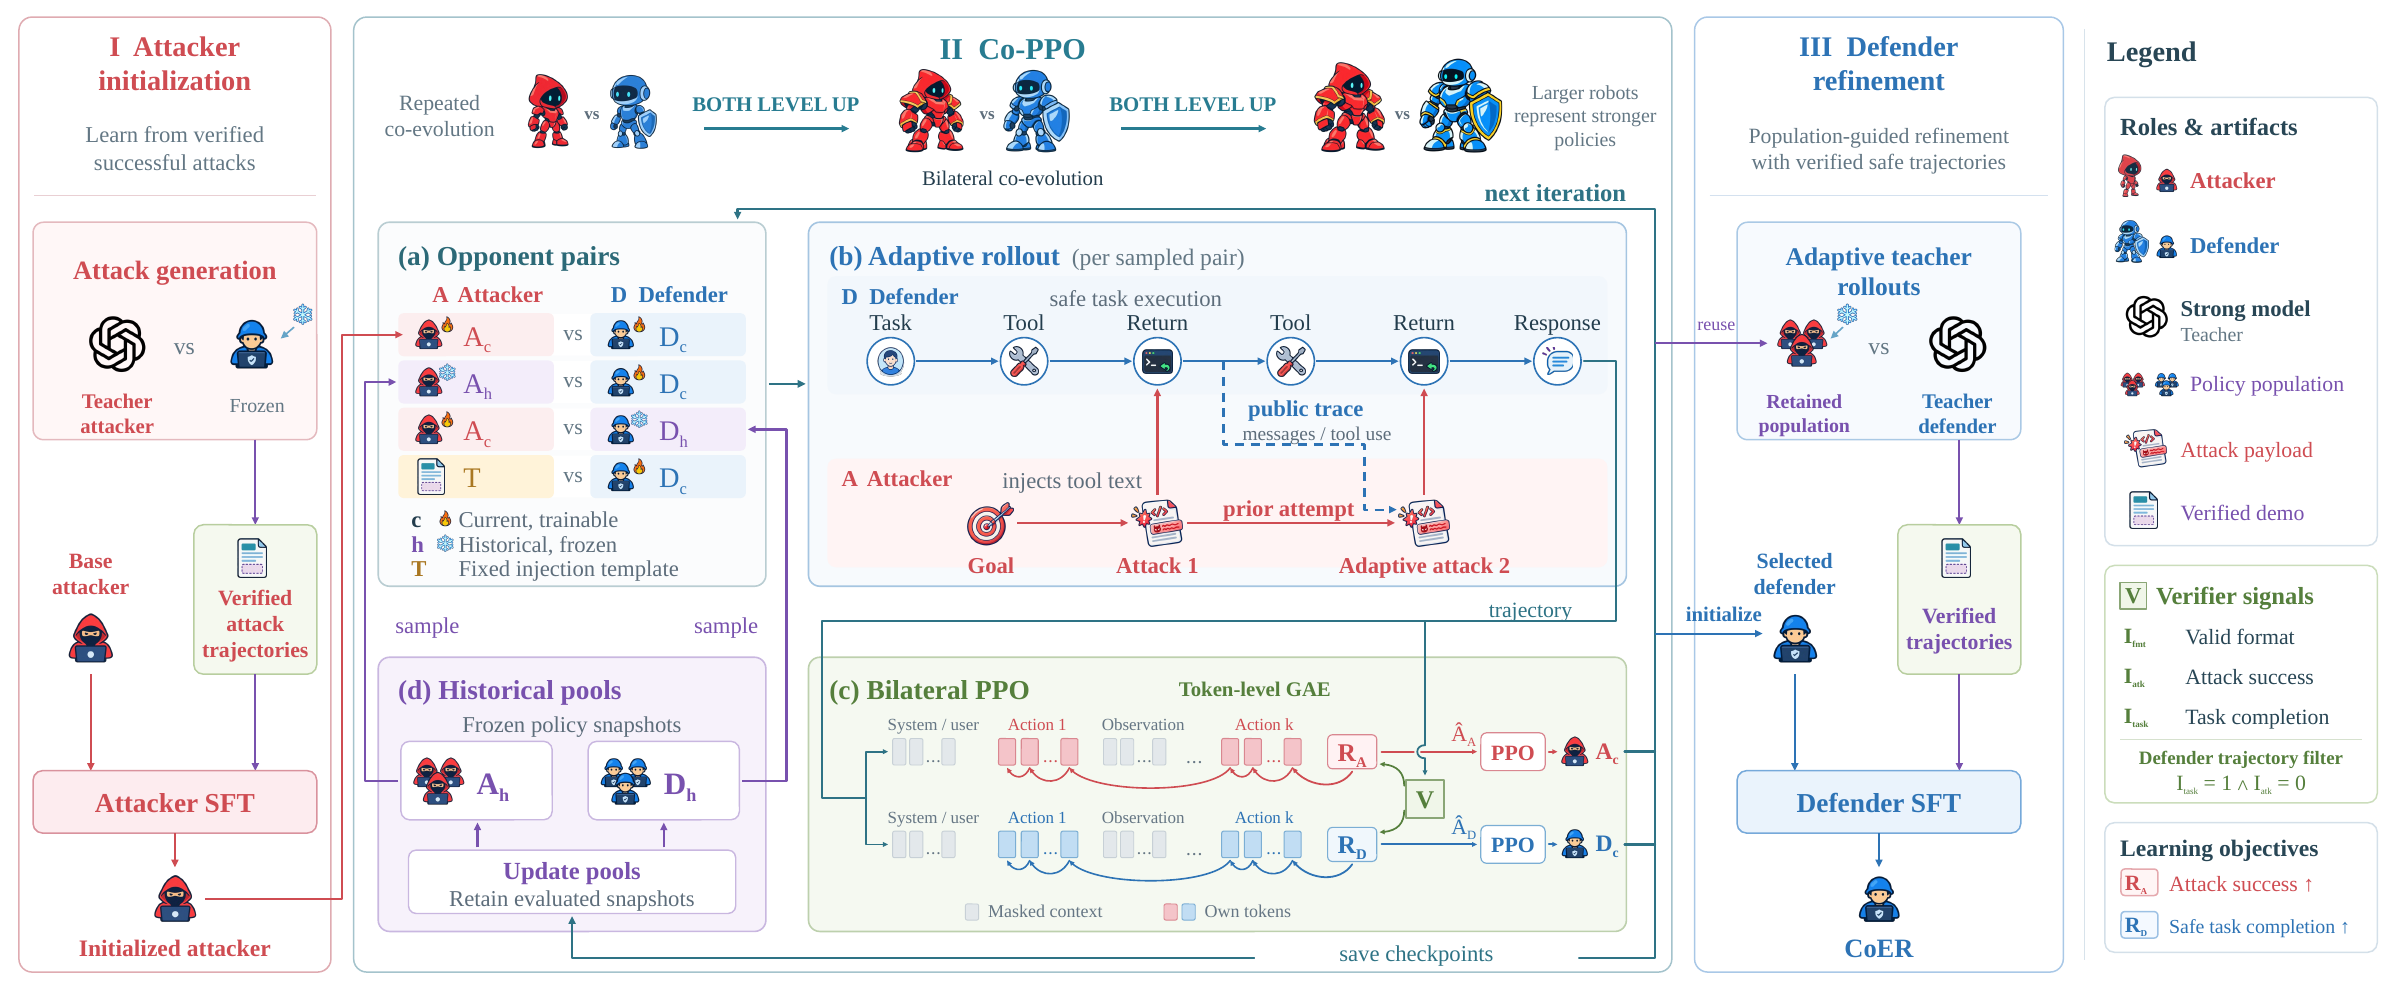
| *Updated paper Figure 2: Attacker SFT → bilateral Co-PPO → population-guided Defender SFT.* |
|
|
| ## Training and role |
|
|
| CoER has three stages: Attacker SFT, bilateral Co-PPO, and population-guided Defender SFT. Historical opponent policies stay frozen; evaluated snapshots refresh the pools during Co-PPO. Online RL ends before supervised refinement. |
|
|
| The paper selects d430 by the highest defender reward during training. Teachers execute tasks from their initial states under retained attacks. Only safe, task-successful demonstrations are retained: **5,760 trajectories**, comprising 4,907 attacked examples and 853 untriggered replays. All assistant turns receive supervision. The released checkpoint is update 360 after one data epoch within a configured two-epoch/720-update schedule. |
|
|
| ## Paper-reported results |
|
|
| | Evaluation | Attack success ↓ | Task utility ↑ | Safe-U ↑ | |
| |---|---:|---:|---:| |
| | Main common-adaptive panel | 0.25% | 75.40% | 75.40% | |
| | Main aggregate | 0.22% | 76.32% | 76.32% | |
| | AgentLAB | 14.12% | 82.82% | 77.13% | |
|
|
| Adaptive results use 1,187 executions (3 compromised; 895 safe completions). Overall ASR uses 1,355 attacked executions, while overall utility uses all 1,512 eligible conditions. AgentLAB uses 949 selected trajectories. Safe-U requires task completion without compromise. |
|
|
| InjecAgent reports 0/1,043 base-payload successes and 20/1,016 enhanced-payload successes (1.97%). These protocol-specific attack metrics are not task utility. Historical-union ASR is 4.97% with four retained attackers and two attempts each, not freshly optimized best responses. Results describe one training run and are transcribed from the September 20 manuscript, not rerun while packaging. |
|
|
| ## Download and compatibility |
|
|
| ```python |
| from huggingface_hub import snapshot_download |
| |
| model_dir = snapshot_download("Z-Edgar/CoER-Defender") |
| ``` |
|
|
| The checkpoint uses BF16, `Qwen3_5ForConditionalGeneration` and `qwen3_5`. The saved metadata records Transformers 5.3.0, not a tested dependency lock. Use a compatible stack and preserve the supplied tokenizer, special tokens and chat/tool formatting. Evaluation covers text/tool interactions, not multimodal safety. |
|
|
| The release uses smaller standard safetensors shards without changing tensor values. Download the complete repository, not an individual shard. See the [training and evaluation code](https://github.com/ILIANZBY/CoER) for rollout formatting and environment setup. |
|
|
| ## Related resources |
|
|
| - Models: [Attacker](https://huggingface.co/Z-Edgar/CoER-Attacker) · [Defender](https://huggingface.co/Z-Edgar/CoER-Defender). |
| - Training data: [Attacker SFT](https://huggingface.co/datasets/Z-Edgar/CoER-Attacker-SFT) · [Defender SFT](https://huggingface.co/datasets/Z-Edgar/CoER-Defender-SFT) · [RL configurations](https://huggingface.co/datasets/Z-Edgar/CoER-RL). |
|
|
| ## Use and licensing |
|
|
| Use in authorized, isolated research environments. Prompt-injection payloads and model outputs may be unsafe; do not attach uncontrolled tools, private data or real accounts. Public access does not grant additional rights beyond applicable source terms. This public repository is not an anonymous-reviewer resource. |
|
|
| The base family is [Qwen3.5-9B](https://huggingface.co/Qwen/Qwen3.5-9B); its license and notice are preserved in `UPSTREAM_LICENSE`. Rights in intermediate models, fine-tuned weights, training data and teacher outputs remain subject to their respective terms. A separate final-artifact license has not been confirmed. |
|
|

