

You need to agree to share your contact information to access this model
This repository is publicly accessible, but you have to accept the conditions to access its files and content.
Read the complete MiniMax H3 Community License and Acceptable Use Policy. Access is manually reviewed for territory eligibility.
Log in or Sign Up to review the conditions and access this model content.
Install the HFTrainer repository before running the commands below. This repository hosts the processed pretrained base; the public-data training outputs are separate. Artifact provenance.
Built with MiniMax H3.
MiniMax-H3 · Base FL2VA
Text-to-audio-video generation with repository-owned model, trainer and inference code.
Verified: 20 real-data training steps, saved checkpoint and native checkpoint-only base inference. Convergence is not established.
All models · Settings · Train · Infer · Evidence · Demos
At a glance
| Property | Released setting |
|---|---|
| Model | Base FL2VA · 33B denoiser + 32B conditioner |
| Training | Rank-2 LoRA on cached audio/video/text features |
| Training input | 128 × 128 × 56 frames; synchronized audio |
| Public dataset | crema_d_mini |
| Runtime | Local HFTrainer implementation; supporting PyTorch/media libraries and model assets remain dependencies |
Sources
Original technical overview · Original code
The original repository is provenance, not a runtime checkout requirement. Third-party notices preserve implementation and asset terms.
Settings and checkpoints
| Setting | Training config | Processed checkpoint | Access |
|---|---|---|---|
| Base FL2VA · 33B denoiser + 32B conditioner | config.py | HFTrainer-MiniMax-H3-Base-FL2VA | Manual access approval |
Only the setting above is a released HFTrainer artifact. Its root config.json, weights and all task-required component configs, processors and schedulers are included together. Inference needs only the checkpoint path or Hub ID, plus task inputs.
Pinned weight revision: a3b24b9d13fa. Original conversion evidence describes the initial export; the current revision adds checkpoint-only dispatch metadata without changing tensors.
Setup
Run from the repository root:
python -m pip install -e ".[minimax-h3]"
python -m pip install "huggingface_hub>=0.34,<2"
Verified on one NVIDIA H200 with PyTorch 2.8.0+cu128. This is the tested environment, not a measured minimum-memory requirement. The complete artifact is about 140 GB. Inference uses sequential component placement; substantial host RAM (the validation container has 230 GiB) is required as well as GPU memory. Install system FFmpeg (ffmpeg and ffprobe) for media preparation.
Access: Manual access approval. Open the checkpoint page, satisfy its model agreement, and run hf auth login before the commands below.
Data
The recipe downloads ZeyuLing/hftrainer_crema_d_mini to data/hftrainer_crema_d_mini. Split counts: 24 train / 8 validation / 0 test. Dataset source, license, transformations and checksum verification are documented in Public demo datasets.
Model features are cached locally. Remove this model's directory under data/hftrainer_crema_d_mini/.cache/ before changing the base checkpoint or preprocessing geometry. The script never substitutes synthetic samples for missing real media.
Train
One command downloads pinned data and weights, prepares required caches, and runs the 20-step recipe:
python tools/run_public_demo.py minimax_h3
Reuse downloaded weights with --checkpoint path/to/complete_bundle; change the output directory with --work-dir path/to/run. The underlying command is python tools/train.py configs/public_data/minimax_h3.py. Seed: 42. Training logs and checkpoints are saved under work_dirs/public_data/minimax_h3/. If you reused a custom checkpoint directory, set HFTRAINER_CHECKPOINT to that directory before directly invoking training, resume or export commands.
The final resumable checkpoint is work_dirs/public_data/minimax_h3/checkpoint-iter_20. For a longer resumed run, keep the same checkpoint/data setting:
python tools/train.py configs/public_data/minimax_h3.py --auto-resume \
  --cfg-options train_cfg.max_iters=40
Infer
Run the processed pretrained base, independently of any training config:
python tools/infer.py --model ZeyuLing/HFTrainer-MiniMax-H3-Base-FL2VA \
  --revision a3b24b9d13fac9c38949ef737e9cb4b98ffe2fb1 --device cuda --seed 42 \
  --prompt "A close-up of a woman speaking calmly to the camera, natural facial expressions, soft daylight, detailed face, steady camera." \
  --height 768 --width 768 --num-steps 50 --output outputs/h3.mp4
--model also accepts a local complete checkpoint directory. A resumable training checkpoint is not a standalone model: export with tools/export_model.py using the matching training config, then pass the exported directory to --model. Artifact and configuration contract.
To package this training run as a complete checkpoint (including its frozen base components):
python tools/export_model.py --config configs/pretrained/export_minimax_h3.py \
  --checkpoint work_dirs/public_data/minimax_h3/checkpoint-iter_20 --output exports/minimax_h3
Then run the inference command above with --model exports/minimax_h3 and omit --revision. Complete exports duplicate the base weights; allow sufficient disk space.
For the cached-feature H3 recipe, use configs/pretrained/export_minimax_h3.py for export so that the frozen conditioner and both VAEs are included. The training-only bundle omits these components.
Evidence and loss
Detailed implementation notes · Historical official comparison protocol and measurements.
Earlier independent official face-sample comparison matched text conditions and full denoising latents exactly. Local codec normalized-RGB RMSE was 0.000630 and audio RMSE 0.0000779; encoded MP4s were not bit-identical. Portable SDPA does not promise exact FA3 parity.
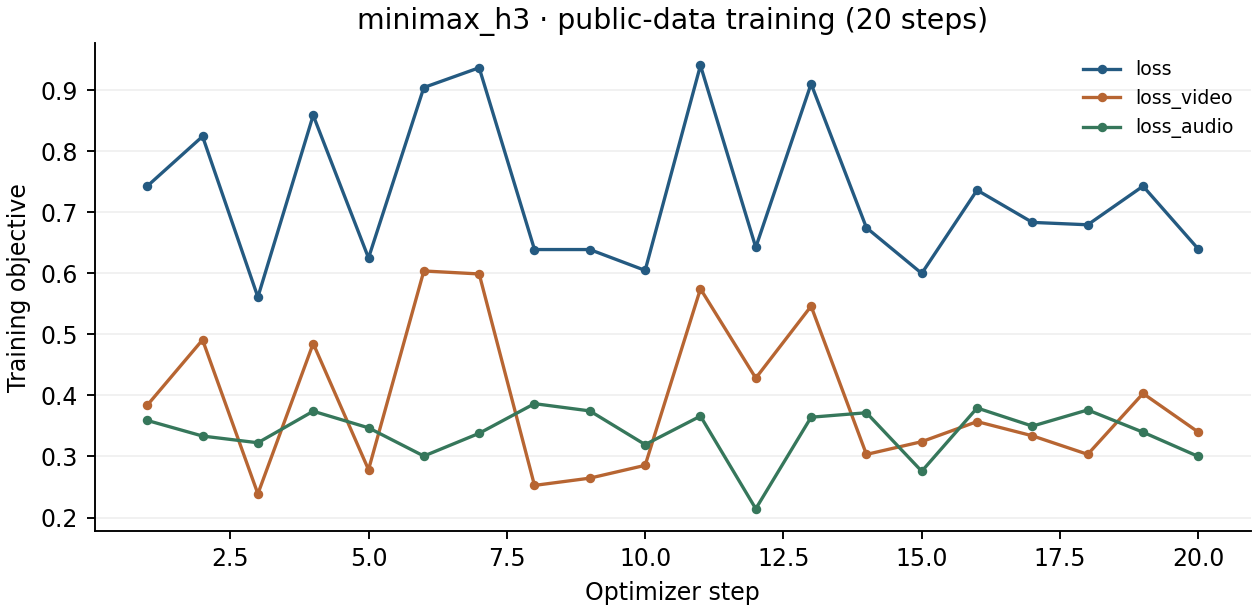
Raw training record · Training log
These are raw, unsmoothed objectives on the public dataset. Twenty steps establish pipeline execution, not convergence. Loss values are not comparable across models.
Held-out loss: 0.8745 across eight actor-disjoint validation clips, with newly sampled noise/timesteps. No fixed-noise decrease or perceptual benchmark is claimed.
Demos
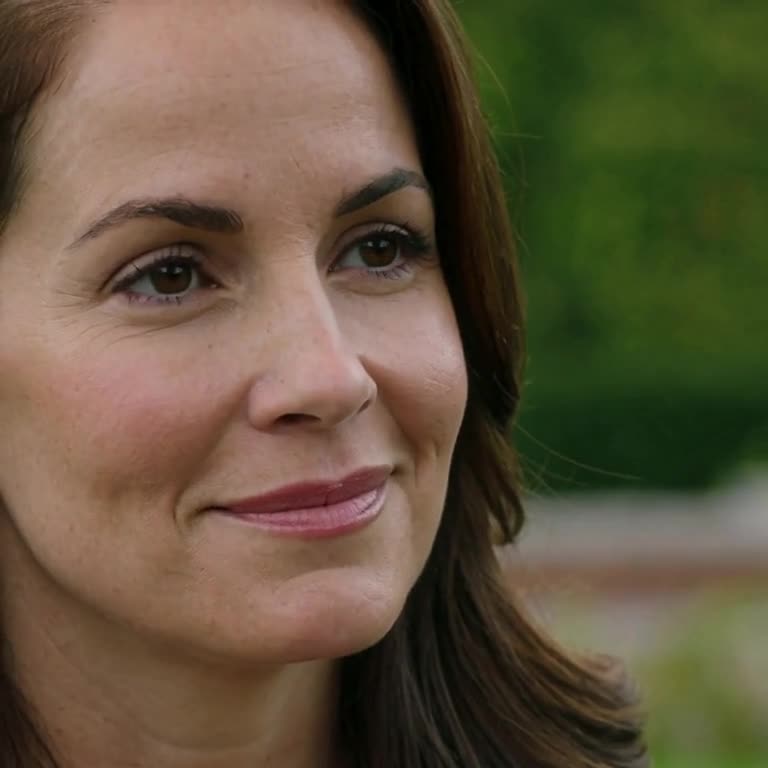
Play/download the generated video. Untouched published base, seed 42; prompt and sampler settings match the inference command above. Includes generated stereo audio. This is separate from the short public-data fine-tuning run.
Limitations
The original article link is the official technical overview; no standalone H3 paper is claimed. Full-weight verification covers T2VA. FL2VA keyframe conditioning and Ref2VA require separate full-run validation; Ref2VA is not a packaged checkpoint. Context-IR and Regenerate-2K are hosted components and are not implemented. Training is an experimental rectified-flow objective, not an official training recipe. The model agreement includes territorial exclusions (EU, UK, South Korea and USA) and applies to outputs. Access requires manual approval.
Citation
@misc{minimax2026h3,
  title = {MiniMax H3: Official Technical Overview and Reference Implementation},
  author = {{MiniMax}},
  year = {2026},
  url = {https://github.com/MiniMax-AI/MiniMax-H3#system-overview}
}
Also retain the dataset citation and attribution.
- Downloads last month
- 2