

High-Resolution Image Synthesis with Latent Diffusion Models
Paper • 2112.10752 • Published • 17
Install the HFTrainer repository before running the commands below. This repository hosts the processed pretrained base; the public-data training outputs are separate. Artifact provenance.
Text-to-image generation with repository-owned model, trainer and inference code.
Verified: 20 real-data training steps, saved checkpoint and native checkpoint-only base inference. Convergence is not established.
All models · Settings · Train · Infer · Evidence · Demos
| Property | Released setting |
|---|---|
| Model | SD 1.5 · 512 px |
| Training | Full UNet fine-tuning |
| Training input | 512 × 512 |
| Public dataset | smithsonian_butterflies |
| Runtime | Local HFTrainer implementation; supporting PyTorch/media libraries and model assets remain dependencies |
Original paper / report · Original code
The original repository is provenance, not a runtime checkout requirement. Third-party notices preserve implementation and asset terms.
| Setting | Training config | Processed checkpoint | Access |
|---|---|---|---|
| SD 1.5 · 512 px | config.py | HFTrainer-Stable-Diffusion-1.5 | Public |
Only the setting above is a released HFTrainer artifact. Its root config.json, weights and all task-required component configs, processors and schedulers are included together. Inference needs only the checkpoint path or Hub ID, plus task inputs.
Pinned weight revision: 717ea02695c7. Original conversion evidence describes the initial export; the current revision adds checkpoint-only dispatch metadata without changing tensors.
Run from the repository root:
python -m pip install -e "."
python -m pip install "huggingface_hub>=0.34,<2"
Verified on one NVIDIA H200 with PyTorch 2.8.0+cu128. This is the tested environment, not a measured minimum-memory requirement.
The recipe downloads ZeyuLing/hftrainer_smithsonian_butterflies to data/hftrainer_smithsonian_butterflies. Split counts: 900 train / 100 validation / 0 test. Dataset source, license, transformations and checksum verification are documented in Public demo datasets.
Model features are cached locally when required. The script never substitutes synthetic samples for missing real media.
One command downloads pinned data and weights, prepares required caches, and runs the 20-step recipe:
python tools/run_public_demo.py sd15
Reuse downloaded weights with --checkpoint path/to/complete_bundle; change the output directory with --work-dir path/to/run. The underlying command is python tools/train.py configs/public_data/sd15.py. Seed: 42. Training logs and checkpoints are saved under work_dirs/public_data/sd15/. If you reused a custom checkpoint directory, set HFTRAINER_CHECKPOINT to that directory before directly invoking training, resume or export commands.
The final resumable checkpoint is work_dirs/public_data/sd15/checkpoint-iter_20. For a longer resumed run, keep the same checkpoint/data setting:
python tools/train.py configs/public_data/sd15.py --auto-resume \
  --cfg-options train_cfg.max_iters=40
Run the processed pretrained base, independently of any training config:
python tools/infer.py --model ZeyuLing/HFTrainer-Stable-Diffusion-1.5 \
  --revision 717ea02695c7590af2df19193838887e44d1d448 --device cuda --seed 42 \
  --prompt "A photograph of a butterfly on a flower, detailed wings, natural daylight." \
  --num-steps 30 --output outputs/sd15.png
--model also accepts a local complete checkpoint directory. A resumable training checkpoint is not a standalone model: export with tools/export_model.py using the matching training config, then pass the exported directory to --model. Artifact and configuration contract.
To package this training run as a complete checkpoint (including its frozen base components):
python tools/export_model.py --config configs/public_data/sd15.py \
  --checkpoint work_dirs/public_data/sd15/checkpoint-iter_20 --output exports/sd15
Then run the inference command above with --model exports/sd15 and omit --revision. Complete exports duplicate the base weights; allow sufficient disk space.
Checkpoint schema, local numerical checks and native train/infer artifact round trips are covered by tests.
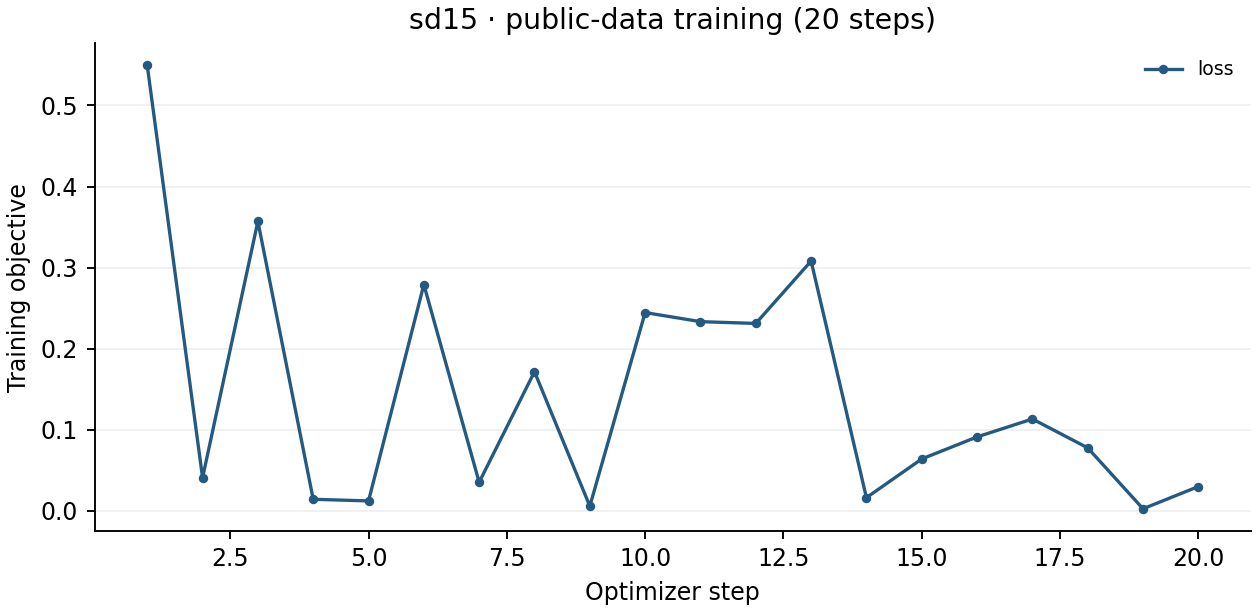
Raw training record · Training log
These are raw, unsmoothed objectives on the public dataset. Twenty steps establish pipeline execution, not convergence. Loss values are not comparable across models.
No held-out perceptual quality metric was measured for this short run.
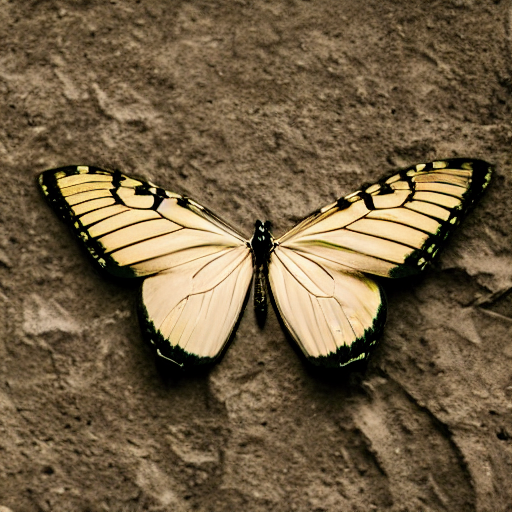
Untouched published base; seed 42. The prompt and sampler settings are the inference command above. This image is not an output of the 20-step fine-tuned model.
Captions are species-name templates, not human-written descriptions. No FID or text-image alignment benchmark is claimed. SD 2.x and SDXL are not this implementation.
@misc{rombach2022ldm,
  title = {High-Resolution Image Synthesis with Latent Diffusion Models},
  author = {Robin Rombach and Andreas Blattmann and Dominik Lorenz and Patrick Esser and Bjorn Ommer},
  year = {2022},
  eprint = {2112.10752},
  archivePrefix = {arXiv},
  url = {https://arxiv.org/abs/2112.10752}
}
Also retain the dataset citation and attribution.