| --- |
| pipeline_tag: text-to-speech |
| library_name: transformers |
| base_model: rumik-ai/rumik-oss-1-base |
| base_model_relation: finetune |
| license: cc-by-nc-4.0 |
| language: |
| - hi |
| - bn |
| - ta |
| - te |
| - mr |
| - gu |
| - kn |
| - ml |
| - pa |
| - or |
| - as |
| - ur |
| - ne |
| - sa |
| - mai |
| - mni |
| - brx |
| - doi |
| - kok |
| - sat |
| - ks |
| - en |
| tags: |
| - tts |
| - text-to-speech |
| - indic |
| - expressive |
| - mimi |
| - speech |
| --- |
| <p align="center"> |
| <img src="https://user42941.na.imgto.link/public/20261009/d7440c6e5230be5a24fa67e2-logo.avif?__imgto_raw=1" alt="MYRA" width="100%"> |
| </p> |
|
|
| <p align="center"> |
| <a href="https://rumik.ai/research/rumik-oss"><img src="https://img.shields.io/badge/blog-overview-555555" alt="blog"></a> |
| <a href="https://huggingface.co/spaces/rumik-ai/rumik-oss-1"><img src="https://img.shields.io/badge/hugging_face-demo-FFD21E" alt="hugging face demo"></a> |
| <!-- add report later--> |
| <img src="https://img.shields.io/badge/technical_report-coming_soon-3975B7" alt="technical report: coming soon"> |
| <a href="https://x.com/rumik_ai"><img src="https://img.shields.io/badge/x-rumik__ai-111111" alt="follow rumik ai on x"></a> |
| <a href="https://discord.gg/wa7sWvq8ty"><img src="https://img.shields.io/badge/discord-join_us-5865F2" alt="join our discord"></a> |
| </p> |
|
|
| # MYRA-oss 1 |
|
|
|  |
|
|
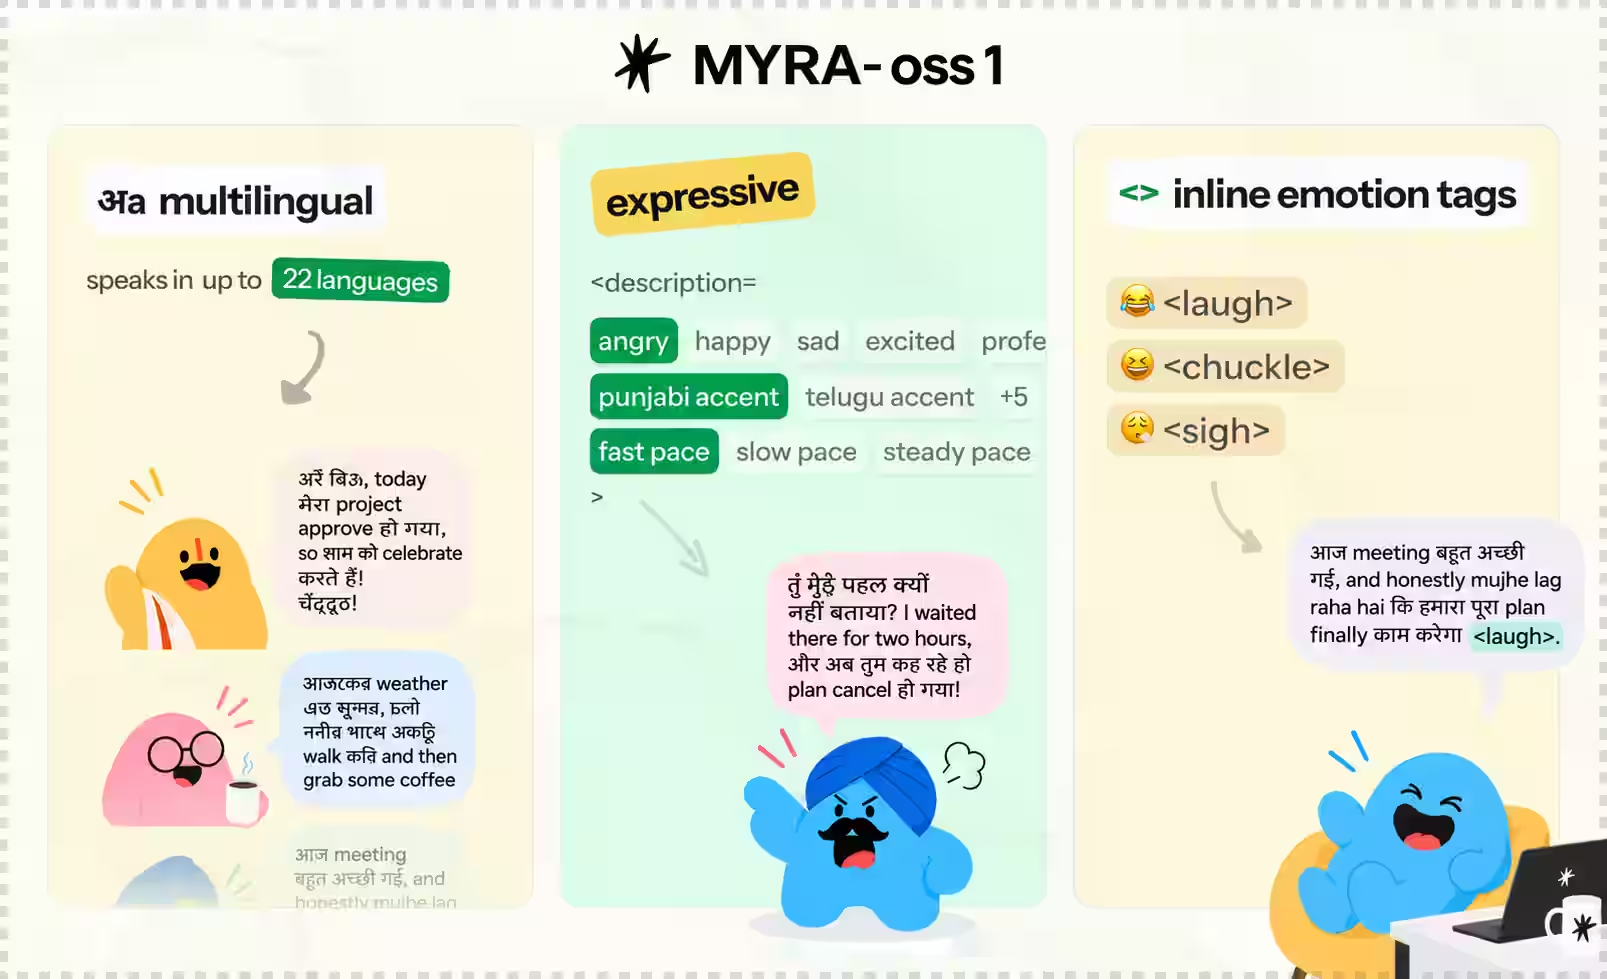
| MYRA-oss 1 is a **3b multilingual text-to-speech model** from MYRA AI, trained on **fewer than 70,000 hours of speech** while performing competitively with existing TTS models. it combines code-switched synthesis, description-conditioned delivery, and inline vocalization control, with **24 khz audio output**. |
|
|
| we also release [MYRA-oss 1 base](https://huggingface.co/rumik-ai/rumik-oss-1-base), our final speaker-conditioned checkpoint before post-training. it supports multilingual synthesis with ira, aisha, siya, and zoya and provides a starting point for the community to research and post-train the base model from scratch. |
|
|
| we describe the post-training of MYRA-oss 1 and the decisions behind its training curriculum in our [blog](https://rumik.ai/research/rumik-oss). our **technical report** will provide an in-depth account of the architecture, data preparation, training, and evaluation. |
|
|
| ## model overview |
|
|
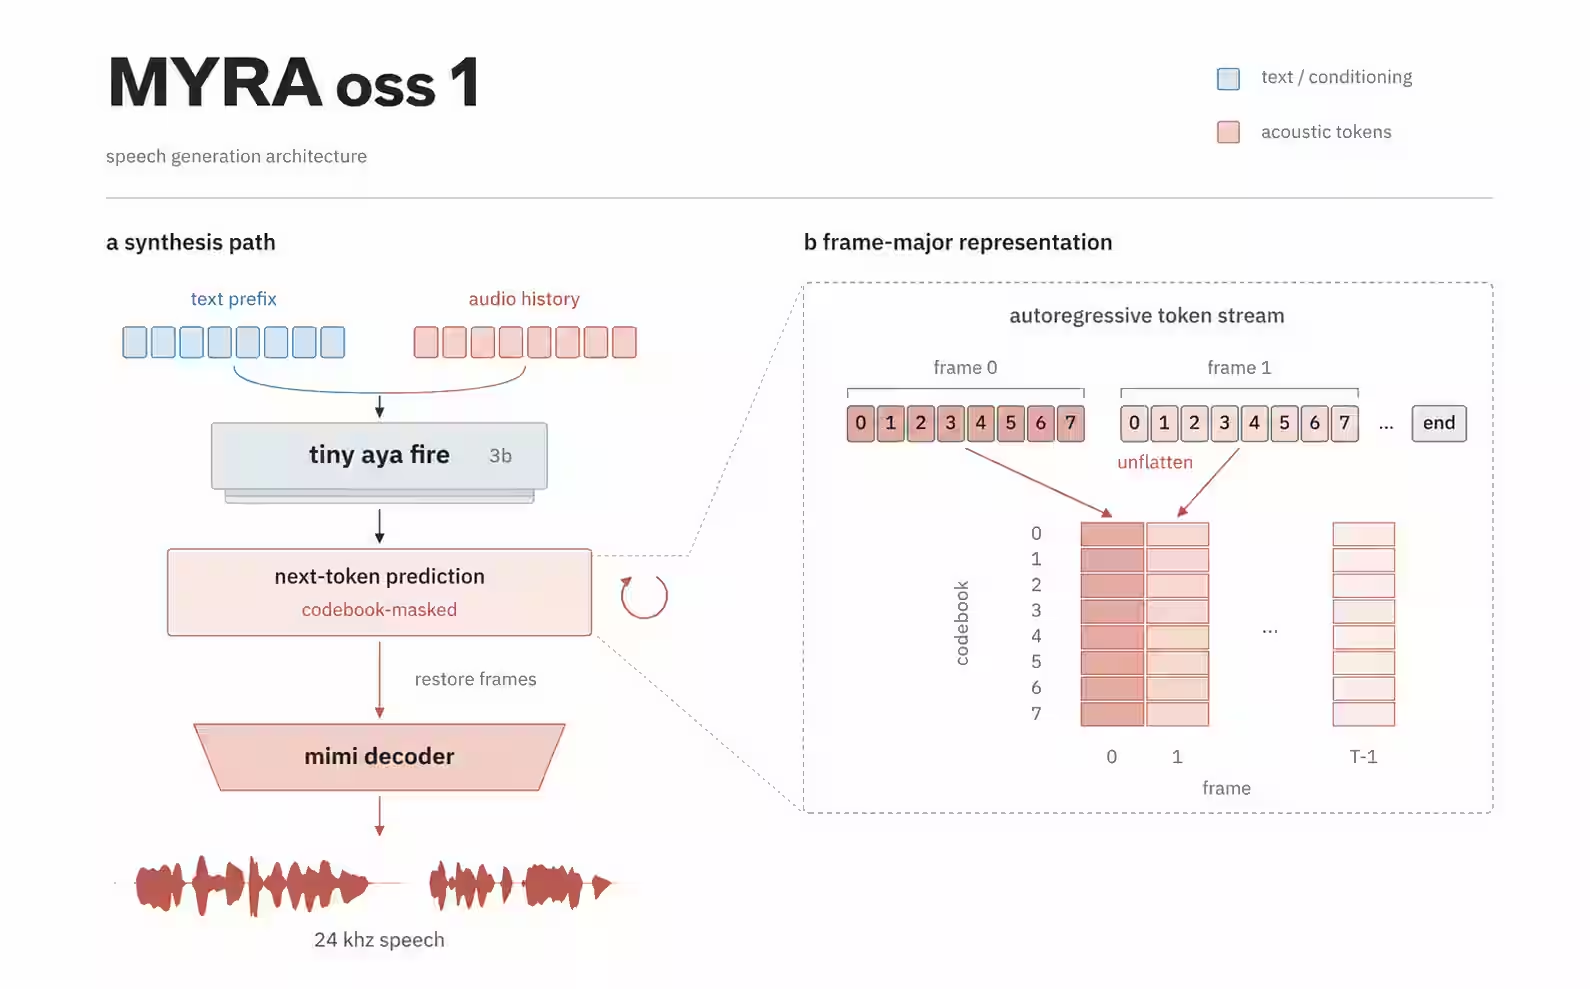
| MYRA-oss 1 extends tiny aya fire with discrete speech tokens from the mimi codec. following the flattened codec-token formulation used in [llama-mimi](https://arxiv.org/abs/2509.14882), text conditioning and audio generation share a single autoregressive sequence. the model predicts eight codebook tokens for each audio frame, in codebook order, before advancing to the next frame. generated tokens are regrouped into codec frames and reconstructed as a waveform by the frozen mimi decoder. |
|
|
| we release the model with 4 voices: |
|
|
| - Ira |
| - Aisha |
| - Siya |
| - Zoya |
|
|
| unlike other TTS models, where each voice is trained specifically for one language or performs best in one language, our voices perform equally well across all 22 languages. |
|
|
|  |
|
|
| ## capabilities |
|
|
| - **multilingual synthesis:** 22 indic languages in their native scripts and romanized forms, plus english, with support for single-language and code-switched synthesis. |
| - **delivery conditioning:** control tone, accent, and pace through the description format for various scenarios. |
| - **vocalization control:** inline tags for laughter, chuckles, and sighs. |
|
|
| ## delivery controls |
|
|
| the `<description="...">` prefix lets users control the global tone and pace of the audio, while inline tags let you insert `<laugh>`, `<chuckle>`, and `<sigh>` at the intended positions. |
|
|
|
|
| ```text |
| <description="excited, Hindi accent, fast pace"> जल्दी आओ, हमारा नाम लिस्ट में है! <laugh> आज घर में जश्न होगा। |
| ``` |
|
|
| | control | values | |
| |---|---| |
| | speaker | `Ira`, `Aisha`, `Siya`, `Zoya` | |
| | tone | happy, sad, angry, excited, professional | |
| | accent | `Hindi`, `Telugu`, `Tamil`, `Kannada`, `Bengali`, `Punjabi`, `Indian English` | |
| | pace | slow, fast, steady | |
| | inline vocalization | `<laugh>`, `<chuckle>`, `<sigh>` | |
|
|
| ## audio samples |
|
|
| **ira · hindi · sad · slow pace** |
|
|
| > माँ, आज फिर तुम्हारे लिए चाय बना दी। <sigh> कप ठंडा हो गया, पर तुम्हारा इंतज़ार नहीं। |
|
|
| <audio controls preload="none" src="https://huggingface.co/rumik-ai/rumik-oss-1/resolve/main/samples/showcase/01-the-second-cup.wav"><a href="https://huggingface.co/rumik-ai/rumik-oss-1/resolve/main/samples/showcase/01-the-second-cup.wav">listen</a></audio> |
|
|
| **aisha · english · sad · slow pace** |
|
|
| > I still play your last message, Dad. You only said, call me when you get home. I got home. I just never got to tell you. |
|
|
| <audio controls preload="none" src="https://huggingface.co/rumik-ai/rumik-oss-1/resolve/main/samples/showcase/02-one-last-message.wav"><a href="https://huggingface.co/rumik-ai/rumik-oss-1/resolve/main/samples/showcase/02-one-last-message.wav">listen</a></audio> |
|
|
| **siya · telugu · excited · fast pace** |
|
|
| > అమ్మా, నాకు ఉద్యోగం వచ్చింది! నిజంగా వచ్చింది! నువ్వు నా కోసం చేసిన ప్రతి త్యాగం నాకు గుర్తుంది. <laugh> ఈ రోజు నీకు నచ్చిన స్వీట్లు నేనే కొనిస్తాను! |
|
|
| <audio controls preload="none" src="https://huggingface.co/rumik-ai/rumik-oss-1/resolve/main/samples/showcase/03-we-made-it.wav"><a href="https://huggingface.co/rumik-ai/rumik-oss-1/resolve/main/samples/showcase/03-we-made-it.wav">listen</a></audio> |
|
|
| **zoya · tamil · angry · fast pace** |
|
|
| > நீ வருவேன்னு சொன்னதால்தான் இவ்வளவு நேரம் காத்திருந்தேன்! ஒரு போன் கூட பண்ண முடியலையா? ஒவ்வொரு முறையும் மன்னிப்பு கேட்டா மட்டும் எல்லாம் சரியாகிடாது! |
|
|
| <audio controls preload="none" src="https://huggingface.co/rumik-ai/rumik-oss-1/resolve/main/samples/showcase/04-a-broken-promise.wav"><a href="https://huggingface.co/rumik-ai/rumik-oss-1/resolve/main/samples/showcase/04-a-broken-promise.wav">listen</a></audio> |
|
|
| **ira · english · professional · steady pace** |
|
|
| > Good evening, passengers. Boarding for the flight to Bengaluru will begin shortly at gate twelve. Please keep your boarding pass ready. Thank you for your patience, and have a pleasant journey. |
|
|
| <audio controls preload="none" src="https://huggingface.co/rumik-ai/rumik-oss-1/resolve/main/samples/showcase/05-ready-for-departure.wav"><a href="https://huggingface.co/rumik-ai/rumik-oss-1/resolve/main/samples/showcase/05-ready-for-departure.wav">listen</a></audio> |
|
|
| **aisha · bengali · happy · steady pace** |
|
|
| > এত দিন পরে তোমাকে দেখে কী যে ভালো লাগছে! তোমার পছন্দের সব রান্না করেছি। আজ আর কোথাও যেতে দেব না, সবাই মিলে অনেক গল্প করব। |
|
|
| <audio controls preload="none" src="https://huggingface.co/rumik-ai/rumik-oss-1/resolve/main/samples/showcase/06-home-again.wav"><a href="https://huggingface.co/rumik-ai/rumik-oss-1/resolve/main/samples/showcase/06-home-again.wav">listen</a></audio> |
|
|
| **siya · kannada · professional · steady pace** |
|
|
| > ನಮ್ಮ ಹೊಸ ಗ್ರಂಥಾಲಯಕ್ಕೆ ಸ್ವಾಗತ. ಇಲ್ಲಿ ಕನ್ನಡ ಮತ್ತು ಇಂಗ್ಲಿಷ್ ಪುಸ್ತಕಗಳು ಲಭ್ಯವಿವೆ. ಸದಸ್ಯರಾಗಲು ನಿಮ್ಮ ಹೆಸರು ಮತ್ತು ವಿಳಾಸ ನೀಡಿ. ಓದಲು ಶಾಂತವಾದ ಸ್ಥಳವೂ ಇದೆ. |
|
|
| <audio controls preload="none" src="https://huggingface.co/rumik-ai/rumik-oss-1/resolve/main/samples/showcase/07-a-place-to-read.wav"><a href="https://huggingface.co/rumik-ai/rumik-oss-1/resolve/main/samples/showcase/07-a-place-to-read.wav">listen</a></audio> |
|
|
| **zoya · punjabi · excited · fast pace** |
|
|
| > ਮਾਂ, ਮੇਰਾ ਦਾਖ਼ਲਾ ਹੋ ਗਿਆ! ਸੱਚੀਂ, ਚਿੱਠੀ ਆ ਗਈ ਹੈ! ਜਿਹੜਾ ਸੁਪਨਾ ਅਸੀਂ ਇਕੱਠੇ ਵੇਖਿਆ ਸੀ, ਉਹ ਅੱਜ ਪੂਰਾ ਹੋ ਗਿਆ। ਹੁਣ ਸਭ ਨੂੰ ਫ਼ੋਨ ਕਰ! |
|
|
| <audio controls preload="none" src="https://huggingface.co/rumik-ai/rumik-oss-1/resolve/main/samples/showcase/08-the-acceptance-letter.wav"><a href="https://huggingface.co/rumik-ai/rumik-oss-1/resolve/main/samples/showcase/08-the-acceptance-letter.wav">listen</a></audio> |
|
|
| **ira · hindi + english · happy · steady pace** |
|
|
| > आज की meeting में सबको हमारा idea पसंद आया। I was so nervous, लेकिन तुमने कहा था ना, बस दिल से बोलो। <chuckle> अब coffee मेरी तरफ़ से, और cake तुम्हारी तरफ़ से! |
|
|
| <audio controls preload="none" src="https://huggingface.co/rumik-ai/rumik-oss-1/resolve/main/samples/showcase/09-a-small-celebration.wav"><a href="https://huggingface.co/rumik-ai/rumik-oss-1/resolve/main/samples/showcase/09-a-small-celebration.wav">listen</a></audio> |
|
|
| **aisha · telugu + english · professional · steady pace** |
|
|
| > మన కొత్త demo సిద్ధంగా ఉంది. You can choose a voice, change the pace, and try different languages. ముందుగా తెలుగులో ఒక వాక్యం విందాం, then we can switch to English. |
|
|
| <audio controls preload="none" src="https://huggingface.co/rumik-ai/rumik-oss-1/resolve/main/samples/showcase/10-the-demo-is-ready.wav"><a href="https://huggingface.co/rumik-ai/rumik-oss-1/resolve/main/samples/showcase/10-the-demo-is-ready.wav">listen</a></audio> |
|
|
| <details> |
| <summary>generation settings</summary> |
|
|
| temperature `0.8`, top-k `30`, top-p `1.0`, maximum `3072` tokens. [prompts and seeds](samples/showcase/manifest.json). |
|
|
| </details> |
|
|
| ## benchmarks |
|
|
| to evaluate our specific use case, we need new benchmarks across different axes: expressiveness, consistency of non-verbal vocalizations, and basic WER/CER. there aren't any standardized benchmarks for multilingual indic TTS across these axes, so we present 3 benchmarks: |
|
|
| - IndicEmo: evaluates expressiveness. |
| - NoVA: evaluates adherence to non-verbal vocalization requests. |
| - WER/CER: evaluates word and character error rates across 15 languages. |
|
|
|
|
|
|
| ### IndicEmo |
|
|
| [github](https://github.com/ira-rumik/IndicEmo) |
|
|
| we introduce IndicEmo to evaluate expressive delivery in code-switched speech. its 100 prompts combine two to five languages drawn from english, hindi, telugu, tamil, kannada, bengali, and punjabi, with equal coverage of happy, sad, angry, excited, and professional delivery. |
|
|
| three automated judges rate anonymized recordings on a five-point rubric covering tone, dynamics, phrasing, and sustained expression. results use the 98-prompt intersection with valid ratings from all judges, aggregating the median rating per recording into category means. MYRA-oss 1 scores **2.92/5 overall** and **3.03/5 on the four emotion categories**. |
|
|
|  |
|
|
| <details> |
| <summary>scores and emotion breakdown</summary> |
|
|
| | system | overall / 5 | emotions only / 5 | |
| |---|---:|---:| |
| | gemini 3.1 flash tts preview | 4.58 | 4.66 | |
| | **MYRA-oss 1** | **2.92** | **3.03** | |
| | cartesia sonic preview | 2.71 | 2.51 | |
| | cartesia sonic 3.5 | 2.32 | 2.18 | |
| | elevenlabs eleven v3 | 2.16 | 2.03 | |
|
|
|  |
|
|
| the emotions-only score excludes professional delivery. [evaluation protocol](benchmarks/evaluation.md#indicemo). |
|
|
| </details> |
|
|
| ### NoVA |
|
|
| [github](https://github.com/ira-rumik/nova-bench) |
|
|
| NoVA evaluates adherence to inline laughter, chuckle, and sigh requests in english speech. each of its 149 prompts places a single vocalization at a specified word position. seven systems are evaluated over three synthesis runs using provider-specific prompting. |
|
|
| silk-asr, scribe v2, and a gemini verifier assess position-correct rendering. laugh and chuckle are pooled into one category; the final score averages laughter and sigh rendering rates across detectors, with unsupported categories contributing zero. MYRA-oss 1 achieves a **0.884 rendering score**. |
|
|
|  |
|
|
| <details> |
| <summary>scores and detector breakdown</summary> |
|
|
| | system (voice) | rendering score | |
| |---|---:| |
| | grok tts (ara) | 0.972 | |
| | inworld tts-2 (ashley) | 0.941 | |
| | **MYRA-oss 1 (ira)** | **0.884** | |
| | orpheus 3b (tara) | 0.813 | |
| | elevenlabs v3 (jessica) | 0.705 | |
| | gemini 3.1 flash tts (kore) | 0.664 | |
| | cartesia sonic 3.6 (monica) | 0.498 | |
|
|
|  |
|
|
| [evaluation protocol](benchmarks/evaluation.md#nova). |
|
|
| </details> |
|
|
| ### WER / CER |
|
|
| [github](https://github.com/Demon-Sheriff/rumik-oss-bench) |
|
|
| we evaluate transcription fidelity using IndicConformer RNNT, comparing normalized ASR transcripts against the input text. the tables report WER and CER across 15 languages. we release the benchmark prompts, generation and scoring code, and per-sample results in [rumik-oss-bench](https://github.com/Demon-Sheriff/rumik-oss-bench), with normalization and scoring details in the [methodology](https://github.com/Demon-Sheriff/rumik-oss-bench/blob/main/METHODOLOGY.md). |
|
|
| #### WER (%) |
|
|
|  |
|
|
| <details> |
| <summary>all 15 languages · WER</summary> |
|
|
|  |
|
|
| [results](benchmarks/wer-reported-scores.json) · [evaluation protocol](benchmarks/evaluation.md#wer-and-cer) |
|
|
| </details> |
|
|
| #### CER (%) |
|
|
|  |
|
|
| <details> |
| <summary>all 15 languages · CER</summary> |
|
|
|  |
|
|
| [results](benchmarks/cer-reported-scores.json) · [evaluation protocol](benchmarks/evaluation.md#wer-and-cer) |
|
|
| </details> |
|
|
| ## limitations |
|
|
| - **long-form synthesis:** training utterances are limited to 30 seconds; speaker and prosodic continuity over longer passages have not been evaluated. we do not recommend generating utterances longer than 35 seconds. |
| - **vocalization precision:** NoVA detectors report unrequested vocalizations in 2.9-5.4% of MYRA-oss 1 outputs. NoVA evaluates english; equivalent tag adherence across languages has not been established. |
|
|
| ## inference |
|
|
| MYRA-oss 1 generates **audio tokens**. decoding them to a waveform is a |
| separate step that uses the [mimi](https://huggingface.co/kyutai/mimi) codec, |
| bundled in this repository under `codec/`. |
|
|
| `transformers.pipeline("text-to-speech")` is not supported for this model. |
| use the [one-shot example](#one-shot-example) to generate audio tokens with |
| `generate_audio()` and decode them into a waveform with mimi. |
|
|
| ### installation |
|
|
| ```bash |
| pip install -r requirements.txt |
| ``` |
|
|
| requires an nvidia gpu with cuda support. the one-shot example below also |
| needs `soundfile` to write a wav. `requirements-server.txt` adds the extras |
| needed only for the optional web ui. |
|
|
| ### one-shot example |
|
|
| text in, `speech.wav` out: |
|
|
| ```python |
| """MYRA-oss 1: text -> speech.wav""" |
| import soundfile as sf |
| import torch |
| from transformers import AutoModelForCausalLM, AutoTokenizer, MimiModel |
| |
| REPO = "arvindcodex11/MYRA-oss-1" |
| SPEAKER = "Ira" |
| DESCRIPTION = "happy, Hindi accent, steady pace" |
| TEXT = "नमस्ते, आज आपका दिन कैसा रहा?" |
| |
| tokenizer = AutoTokenizer.from_pretrained(REPO, trust_remote_code=True) |
| model = AutoModelForCausalLM.from_pretrained( |
| REPO, trust_remote_code=True, dtype=torch.bfloat16 |
| ).eval().cuda() |
| mimi = MimiModel.from_pretrained(REPO, subfolder="codec").eval().cuda() |
| |
| # [BOS] <text> Ira: <description="..."> text <audio> |
| # the tokenizer adds [BOS] itself, so it is not written here |
| prompt = f'<text>{SPEAKER}: <description="{DESCRIPTION}"> {TEXT}<audio>' |
| inputs = tokenizer(prompt, return_tensors="pt").to(model.device) |
| |
| # 1. text -> audio tokens |
| ids = model.generate_audio(**inputs, max_new_tokens=2048, |
| temperature=0.8, top_k=30, do_sample=True) |
| audio_tokens = ids[0].tolist()[inputs.input_ids.shape[1]:] |
| |
| # 2. audio tokens -> codec frames -> waveform |
| codes = model.audio_tokens_to_codes(audio_tokens) |
| with torch.inference_mode(): |
| wav = mimi.decode(codes.to(mimi.device)).audio_values[0, 0] |
| |
| sf.write("speech.wav", wav.float().cpu().numpy(), 24000) |
| print(f"{len(audio_tokens)} tokens -> {len(audio_tokens) / 100:.2f}s -> speech.wav") |
| ``` |
|
|
| ### web interface |
|
|
| an optional fastapi server with a browser ui is included: |
|
|
| ```bash |
| pip install -r requirements-server.txt |
| python server.py --repo-id arvindcodex11/MYRA-oss-1 --host 127.0.0.1 --port 6006 |
| ``` |
|
|
| open `http://127.0.0.1:6006/`, or post to it: |
|
|
| ```bash |
| curl http://127.0.0.1:6006/v1/audio/speech \ |
| -H 'Content-Type: application/json' \ |
| -d '{ |
| "speaker": "Ira", |
| "input": "<description=\"happy, Hindi accent, steady pace\"> नमस्ते, आज आपका दिन कैसा रहा?", |
| "temperature": 0.8, |
| "top_k": 30, |
| "max_new_tokens": 2048 |
| }' \ |
| --output speech.wav |
| ``` |
|
|
| ## license |
|
|
| MYRA-oss 1 is available for **research and non-commercial use** under [tiny aya fire's cc-by-nc 4.0 license with an acceptable-use addendum](https://cohere.com/cohere-labs-cc-by-nc-license). |
|
|
| permitted non-commercial uses include speech-synthesis research, benchmarking, teaching, and fine-tuning for research experiments. you may share the weights and adaptations under the applicable terms, retaining attribution, license links, upstream notices, and an indication of modifications. all use must comply with [cohere labs' acceptable-use policy](https://docs.cohere.com/docs/cohere-labs-acceptable-use-policy). |
|
|
| the license does not authorize commercial products, paid synthesis services, or other uses directed toward commercial advantage, including self-hosted deployments. those uses require separate permission from the relevant rights holders; a research label alone does not make a commercial activity non-commercial. |
|
|
| the [mimi codec](https://huggingface.co/kyutai/mimi) is licensed separately under [cc-by-4.0](https://creativecommons.org/licenses/by/4.0/), which permits reuse and adaptation, including commercially, with attribution and modification notices. that permission applies to the codec, not to the tiny aya-derived tts weights. |
|
|
| the full license text is in [`LICENSE`](LICENSE), and [`NOTICE`](NOTICE) |
| records the modifications made to tiny aya fire, as cc-by-nc 4.0 requires. |
|
|
| ## acknowledgments |
|
|
| MYRA-oss 1 builds on [rumik-oss 1](https://huggingface.co/rumik-ai/rumik-oss-1), [tiny aya fire](https://huggingface.co/CohereLabs/tiny-aya-fire), [mimi](https://huggingface.co/kyutai/mimi), [llama-mimi](https://arxiv.org/abs/2509.14882), and [torchtitan](https://github.com/pytorch/torchtitan). we thank their authors for making this work available. our work wouldn't be possible without these foundations. |
|
|
| ## training recipe |
|
|
| we plan to release the training recipe, including data manifests, preprocessing scripts, and training configurations, alongside the **technical report**. data releases are subject to source redistribution rights. |
|
|
| ## citation |
|
|
| if you find MYRA-oss 1 useful in your research, please cite our work: |
|
|
| ```bibtex |
| @unpublished{govindu2026rumikoss1, |
| title = {{rumik-oss 1 technical report}}, |
| author = {Govindu Pranav and Anant Shukla and Suryansh Shakya and Aman Anand and Vatsal Bharti}, |
| year = {2026}, |
| note = {In preparation} |
| } |
| ``` |
|
|

