
Buckets:

| license: apache-2.0 | |
| pipeline_tag: image-to-3d | |
| tags: | |
| - localmesh-engine | |
| - image-to-3d | |
| - mesh | |
| - gltf | |
| - trellis | |
| - multi-view | |
| - 3d-generation | |
| base_model: TencentARC/Pixal3D | |
| base_model_relation: quantized | |
|  | |
| # LocalMesh Engine weights | |
| LocalMesh Engine turns one photo, or four sides of the same subject, into a | |
| textured `.glb`. It runs on an 8 GB NVIDIA card. The code is Apache-2.0 and | |
| lives on [GitHub](https://github.com/Quentincls/localmesh-engine). The project | |
| page is [local-mesh.com/localmesh-engine](https://local-mesh.com/localmesh-engine/). | |
| TRELLIS.2 works from a single image. This engine adds a four view path and, | |
| since version 1.2, puts the photographs' own pixels on the texture. This | |
| repository holds every weight the engine needs, except DINOv3 and the cutout | |
| model, laid out like the folder the engine reads. Most of it is rehosted | |
| unchanged; the three fp8 conversions of the Pixal3D multi-view models exist | |
| nowhere else. | |
| ## New in engine 1.2: the photographs on the texture | |
|  | |
| **No new weights.** Engine [v1.2.0](https://github.com/Quentincls/localmesh-engine/releases/tag/v1.2.0) | |
| reads exactly the files in this repository. A folder downloaded for an earlier | |
| version works as it is: there is nothing to download again. | |
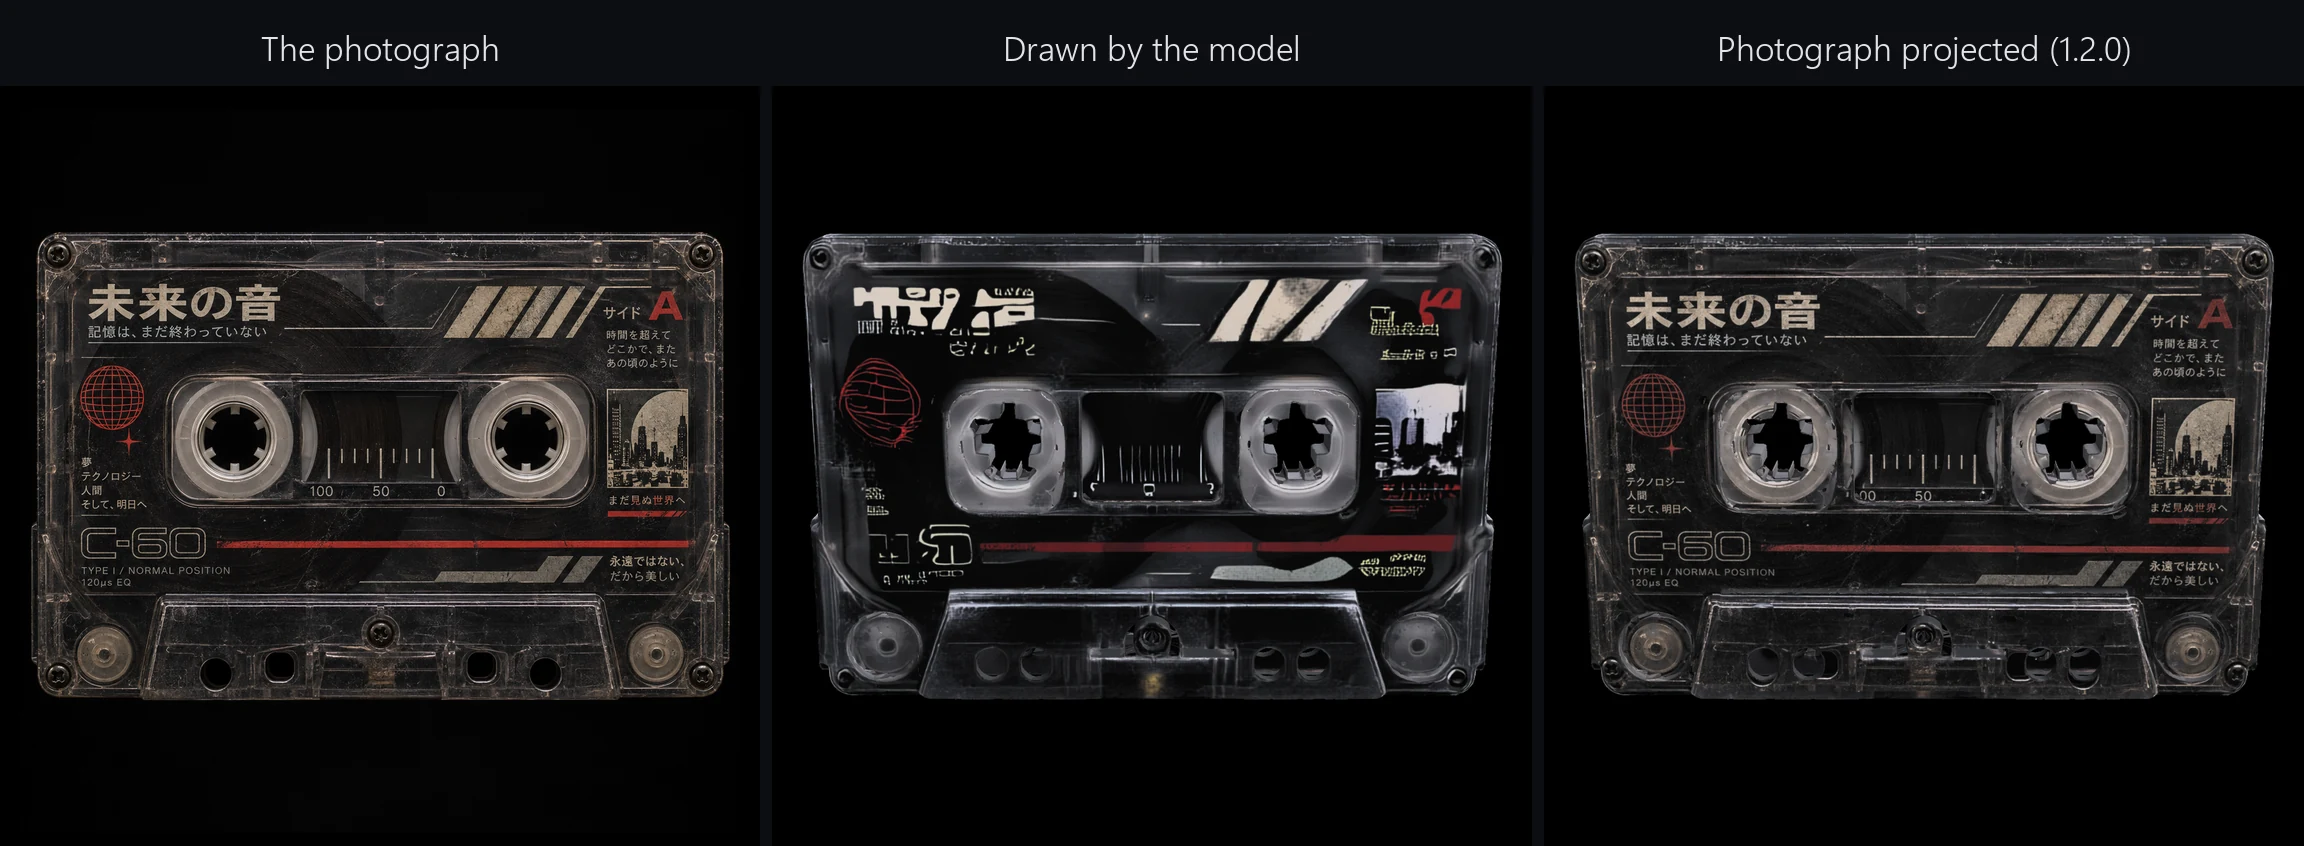
| The change is in the texture. The texture TRELLIS.2 returns is drawn by the | |
| model: close to the photograph in colour and shape, wrong in the detail, so | |
| printed text comes back as glyphs that read as nothing. After texturing, the | |
| engine now projects the photographs back onto the mesh. Every texel a | |
| photograph sees squarely takes that photograph's pixel, so a printed label, a | |
| logo or a fine pattern reads as it does on the photograph. Where no photograph | |
| sees the surface, underneath or on the back of a single photograph, the drawn | |
| texture stays, its colour pulled towards the photographed surface next to it. | |
| The photographs themselves are never retouched. | |
| The cameras are fitted to the images. With four photographs, the engine reuses | |
| the angles DA3-BASE (`multivue/cameras/`, listed below) measured for the shape; | |
| when the shape was made without that measurement, on the `max` tier or without | |
| DA3-BASE, it starts from quarter turns and checks whether the two profiles are | |
| swapped. With one photograph, it searches the whole turn for the angle that | |
| matches the silhouette and straightens a tilt of up to 20 degrees; nothing | |
| under `multivue/` is needed, so the single photo download gets the projection | |
| too. One elevation is shared by all views, and the mesh is never mirrored to | |
| fit. Each texel takes the one photograph that sees it most squarely, so | |
| nothing is averaged into a blur. On a cassette generated from four | |
| photographs, 59 % of the surface takes a photograph pixel, and its printed | |
| label reads as it does on the photographs. | |
| Beside `model_<seed>.glb`, the engine writes `model_<seed>.ai.glb`: the same | |
| mesh with the drawn texture alone, to compare or to fall back on. Expect about | |
| twice the disk per job. On an RTX 4060 Laptop 8 GB the projection adds 29 to 73 | |
| seconds per job, most of it spent fitting the cameras, and its memory peak, | |
| 3.3 GB, stays below that of the texture stage. | |
| What it cannot do is correct a shape. Where the reconstructed mesh departs from | |
| the photograph, a correct pixel lands on the wrong surface and that part shows | |
| twice. For such a subject, `--no-projection` keeps the drawn texture alone. A | |
| failure of this step never fails the job: the drawn texture is kept, and the | |
| result says why. | |
| ## What is in this repository | |
| Everything here is laid out exactly like the folder the engine reads, so one | |
| command places all of it: | |
| | Folder | Size | What it is | Whose | | |
| |---|---|---|---| | |
| | `TRELLIS.2-4B/` | 8.1 GB | the single photo path, in fp8 | [visualbruno](https://huggingface.co/visualbruno/TRELLIS.2-4B-FP8), MIT, rehosted unchanged | | |
| | `microsoft/` | 148 MB | the sparse structure decoder | [Microsoft](https://huggingface.co/microsoft/TRELLIS-image-large), MIT, rehosted unchanged | | |
| | `multivue/` | 4.8 GB | the four view path | ours, from Pixal3D, see below | | |
| Rehosted so that one `hf download` replaces six. Taking those two from their | |
| own repositories works exactly as well; nothing here is modified. | |
| ### What is ours, under `multivue/` | |
| | File | Size | Source | | |
| |---|---|---| | |
| | `multivue/structure_mv_fp8.safetensors` + `.json` | 1.39 GB | fp8 conversion of `ckpts/ss_flow_img_dit_1_3B_64_bf16_mv.safetensors`, TencentARC/Pixal3D | | |
| | `multivue/forme_512_mv_fp8.safetensors` + `.json` | 1.44 GB | fp8 conversion of `ckpts/slat_flow_img2shape_dit_1_3B_512_bf16_mv.safetensors`, TencentARC/Pixal3D | | |
| | `multivue/forme_1024_mv_fp8.safetensors` + `.json` | 1.44 GB | fp8 conversion of `ckpts/slat_flow_img2shape_dit_1_3B_1024_bf16_mv.safetensors`, TencentARC/Pixal3D | | |
| | `multivue/champ.safetensors` | 2.7 MB | valeoai/NAF, official checkpoint, tensors unchanged | | |
| **`structure_mv_fp8`** fuses the four encoded views into a sparse volume of | |
| cells. Each view is projected onto the shared grid by its own camera. | |
| **`forme_512_mv_fp8`** is the first shape pass, on the grid inherited from the | |
| structure. **`forme_1024_mv_fp8`** is the second, and the TRELLIS.2 shape | |
| decoder turns its latent into the mesh. | |
| **`champ`** is the NAF field network. It returns a 512 by 512 query map, which | |
| fills in the detail the token map loses: the token map is sixteen times coarser | |
| than the photo. | |
| 4.28 GB, seven files, plus `multivue/cameras/`, 544 MB, rehosted unchanged: | |
| DA3-BASE and the code that reads it (Apache-2.0), and the three small Python | |
| packages that code needs, each under its own licence (omegaconf and | |
| antlr4-python3-runtime BSD-3-Clause, addict MIT). Keep the three `.json` | |
| descriptors next to their `.safetensors`: the engine builds each flow model on | |
| the `meta` device from that descriptor, then loads the tensors in place, so the | |
| weights are never held twice. The descriptors declare `dtype: float8_e4m3fn`. | |
| The four view path serves the `draft`, `standard` and `high` tiers. The | |
| multi-view weights exist at 512 and 1024 only, so `max` falls back to the | |
| earlier way of blending the views rather than shipping a `standard` shape under | |
| another name. | |
| ## What is not in this repository | |
| Two sets. The engine needs both. | |
| | Weights | Where | Licence | Note | | |
| |---|---|---|---| | |
| | DINOv3 ViT-L/16 | https://huggingface.co/facebook/dinov3-vitl16-pretrain-lvd1689m | DINOv3 License, Meta | Image encoder, required on both paths. Access is gated and approved by hand, so ask for it first. | | |
| | BiRefNet_HR | https://huggingface.co/ZhengPeng7/BiRefNet_HR | MIT | Cutout, and the mask that tells the projection which pixels belong to the subject. The engine fetches it from the Hub on the first generation if the cache is empty, and loads it with `trust_remote_code=True`, so that first run executes code from the Hub. | | |
| TRELLIS.2-4B in fp8, the structure decoder and DA3-BASE are in this | |
| repository, rehosted unchanged. Their own repositories work just as well: | |
| [visualbruno/TRELLIS.2-4B-FP8](https://huggingface.co/visualbruno/TRELLIS.2-4B-FP8), | |
| [microsoft/TRELLIS-image-large](https://huggingface.co/microsoft/TRELLIS-image-large), | |
| [depth-anything/DA3-BASE](https://huggingface.co/depth-anything/DA3-BASE). | |
| Without DA3-BASE the engine guesses which side each profile is on, and says so | |
| in its result; a wrong guess puts a face at the front and at the back. | |
| ## Using them | |
| Set `LOCALMESH_ROOT` to the folder that holds `models/`, then: | |
| ```bash | |
| pip install -U huggingface_hub | |
| hf download Qtn-Cls/LocalMeshEngine --local-dir "$LOCALMESH_ROOT/models" | |
| ``` | |
| 13.1 GB, and every file lands exactly where the engine looks for it. There is | |
| nothing to move afterwards. For the single photo path alone, 8.3 GB, add | |
| `--exclude "multivue/*"`. | |
| **Then ask Meta for DINOv3**, the one set you have to fetch yourself: it is | |
| gated, and a human grants access. Nothing generates without it, and approval is | |
| not instant, so send the request before anything else: | |
| [facebook/dinov3-vitl16-pretrain-lvd1689m](https://huggingface.co/facebook/dinov3-vitl16-pretrain-lvd1689m). | |
| The layout the engine reads: | |
| ``` | |
| <LOCALMESH_ROOT>/models/ | |
| TRELLIS.2-4B/ this repository | |
| microsoft/TRELLIS-image-large/ckpts/ this repository | |
| multivue/ this repository | |
| multivue/cameras/ this repository, DA3-BASE | |
| facebook/dinov3-vitl16-pretrain-lvd1689m/ from Meta, gated | |
| hf/ Hugging Face cache (HF_HOME), where BiRefNet_HR lands | |
| ``` | |
| Then, from the four sides of one subject: | |
| ```bash | |
| python -m localmesh_engine face.png --right right.png --left left.png --back back.png --to out/ | |
| ``` | |
| `--tier` picks the tier: `draft`, `standard`, `high` or `max`, written | |
| Draft, Standard, Detailed and Extreme where these pages spell them out. | |
| `--seed` sets the seed, `--to` the output folder. The command assumes the package is installed. | |
| The four view path also needs `natten`. Installation, including the three CUDA | |
| extensions that are not on PyPI, is written up in `docs/INSTALL.md` in the | |
| GitHub repository; the four tiers, frozen, are in `docs/RECIPES.md`. | |
| The photographs are projected onto the texture unless you ask otherwise: | |
| ```bash | |
| python -m localmesh_engine photo.png --no-projection --to out/ | |
| ``` | |
| `--no-projection` keeps the drawn texture alone; `--sans-projection` is the | |
| same flag under its French name. | |
| ## Results | |
|  | |
|  | |
|  | |
| A full turn each. One pose can be chosen; a full turn cannot. | |
| Six subjects, four photos each, `high` tier, RTX 4060 Laptop 8 GB: samurai on a | |
| base, crowned stone head, sword in the stone, motorcycle, cassette with a clear | |
| shell, traffic light. | |
| | Tier | Four views, measured over the six subjects | | |
| |---|---| | |
| | Standard, `standard` | 6 min 30 to 8 min 30 | | |
| | Detailed, `high` | 9 min 20 to 13 min | | |
| Texture accounts for about 60 % of that time. These times were measured with | |
| engine 1.1, before the projection, which adds 51 to 67 seconds with four | |
| photographs. | |
| ## The conversion | |
| The three flow models start from the official `*_mv` weights of | |
| TencentARC/Pixal3D. Their tensors are stored in float32, despite the `bf16` in | |
| their filenames. The transformer blocks are cast to `float8_e4m3fn`, and the | |
| descriptor beside each file records that dtype, so the engine builds the model | |
| in fp8 rather than casting after the fact. Of each model, 480 tensors are | |
| converted; the input and output layers, the norms and modulations, and the | |
| structure model's complex rotary table are left as they were. | |
| Measured against the source: RMSE of 0.025 to 0.026 on the weights, and 0.027 | |
| on a projection probe. | |
| `champ.safetensors` is not converted. It carries the tensors of the official | |
| valeoai/NAF checkpoint, `naf_release.pth`, unchanged, re-serialised to | |
| safetensors. The file records the source URL and its SHA-256 in its own | |
| metadata. | |
| ## Licences and attribution | |
| The `license` field above is the repository tag. It is Apache-2.0, the licence | |
| of the engine code and of this card. The files themselves keep the licence of | |
| their own source: | |
| - The three fp8 conversions derive from **TencentARC/Pixal3D**, MIT License, | |
| Copyright (c) 2026 Tencent. Code: https://github.com/TencentARC/Pixal3D, | |
| weights: https://huggingface.co/TencentARC/Pixal3D | |
| - `champ.safetensors` comes from **valeoai/NAF**, Apache-2.0, | |
| https://github.com/valeoai/NAF | |
| - `multivue/cameras/` holds **DA3-BASE** and its source, Apache-2.0, | |
| https://huggingface.co/depth-anything/DA3-BASE, and under `deps/` three | |
| Python packages, unchanged: **omegaconf** 2.3.0 (BSD-3-Clause, Omry Yadan), | |
| **antlr4-python3-runtime** 4.9.3 (BSD-3-Clause, The ANTLR Project) and | |
| **addict** 2.4.0 (MIT, Mats Julian Olsen) | |
| The engine also builds on: | |
| - **TRELLIS.2**, Microsoft, MIT License, https://github.com/microsoft/TRELLIS.2 | |
| - **ComfyUI-Trellis2**, visualbruno, MIT License, for the ported multi-view path | |
| and the fp8 loading, https://github.com/visualbruno/ComfyUI-Trellis2 | |
| - **Depth Anything 3**, Apache-2.0, for the camera measurement, | |
| https://github.com/ByteDance-Seed/depth-anything-3 | |
| - **BiRefNet**, MIT License, for the cutout, | |
| https://github.com/ZhengPeng7/BiRefNet | |
| Built with DINOv3. DINOv3 is the image encoder on both paths. Its weights are | |
| not redistributed here: request them from Meta, and ship a copy of the DINOv3 | |
| License Agreement with any redistribution of your own. | |
| ## Citing | |
| ```bibtex | |
| @software{colus2026localmeshengine, | |
| author = {Colus, Quentin}, | |
| title = {LocalMesh Engine}, | |
| year = {2026}, | |
| version = {1.2.0}, | |
| license = {Apache-2.0}, | |
| url = {https://github.com/Quentincls/localmesh-engine} | |
| } | |
| ``` | |
| The upstream work these weights rest on: TRELLIS.2 (Microsoft, | |
| arXiv:2512.14692), Pixal3D (TencentARC, arXiv:2605.10922), NAF (valeoai), | |
| DINOv3 (Meta), Depth Anything 3 (arXiv:2511.10647). | |
| ## Code | |
| The engine is at **https://github.com/Quentincls/localmesh-engine**. Recipes, | |
| installation, measurements and the provenance of every vendored file are there. | |
| Open issues there, not here. | |
| ## The application | |
| These weights and this engine are the generation core of LocalMesh, a Windows | |
| application at [local-mesh.com](https://local-mesh.com): the same core with a | |
| board, a library and a viewer, installed in one step instead of fifteen. The | |
| engine is free and open; the application is what is sold. | |
|  | |
Xet Storage Details
- Size:
- 14.1 kB
- Xet hash:
- b32c70df7accb08eb32136b80168d3e8dd821b03d216aa4fceefbb9c9706e4c5
·
Xet efficiently stores files, intelligently splitting them into unique chunks and accelerating uploads and downloads. More info.